
An open-source document parsing model with SOTA accuracy and speed, using an RSI loop during post-training.
Update documentation and community resources
BinyangQiu0245ee0e321b
diff --git a/README.md b/README.mdindex 7c1adf6..03b1718 100644--- a/README.md+++ b/README.md@@ -1,32 +1,338 @@<div align="center">-<img src="assets/header.png" />+<img src="https://raw.githubusercontent.com/SoMarkAI/image_bed/main/OXR_README/assets/header.png" alt="" />-# SoMark|OXR+<h1>SoMark|O<span style="color: #DE7802;">X</span>R</h1>-**English** · [简体中文](README_CN.md)--An open-source document parsing model with SOTA accuracy and speed.+An open-source document parsing model with SOTA accuracy and speed, using an RSI loop during post-training.----Turn documents into Agent-Friendly data.+**Turn documents into Agent-Friendly data.**-[](https://huggingface.co/SoMarkAI/OXR-1.0)-[](https://modelscope.cn/models/SoMark/OXR-1.0)+[🌐 Online Demo](https://free-oxr.somark.ai) | [🔥 🆓 Free API](#free-api)++[](https://huggingface.co/SoMarkAI/OXR-1.0) [](https://modelscope.cn/models/SoMark/OXR-1.0)+++**English** · [简体中文](README_CN.md)</div>OXR (Optical Everything Recognition) is an open-source model from the SoMark team. It turns PDFs and document images into Agent-Friendly data in Markdown or JSON, with layout coordinates included.+Pretrained from scratch, OXR uses a recursive self-improvement (RSI) loop during post-training—a first in document parsing. With just 1.3B parameters, OXR ranks #1 on olmOCR-Bench, OmniDocBench, and DocParsingBench while delivering industry-leading parsing speed.+OXR is the first to make its layout analysis module independent and pluggable. This design accelerates parsing and supports replacing the built-in layout model with a custom one. OXR continues to handle content recognition and reading order, enabling adaptation across diverse scenarios with minimal integration effort.+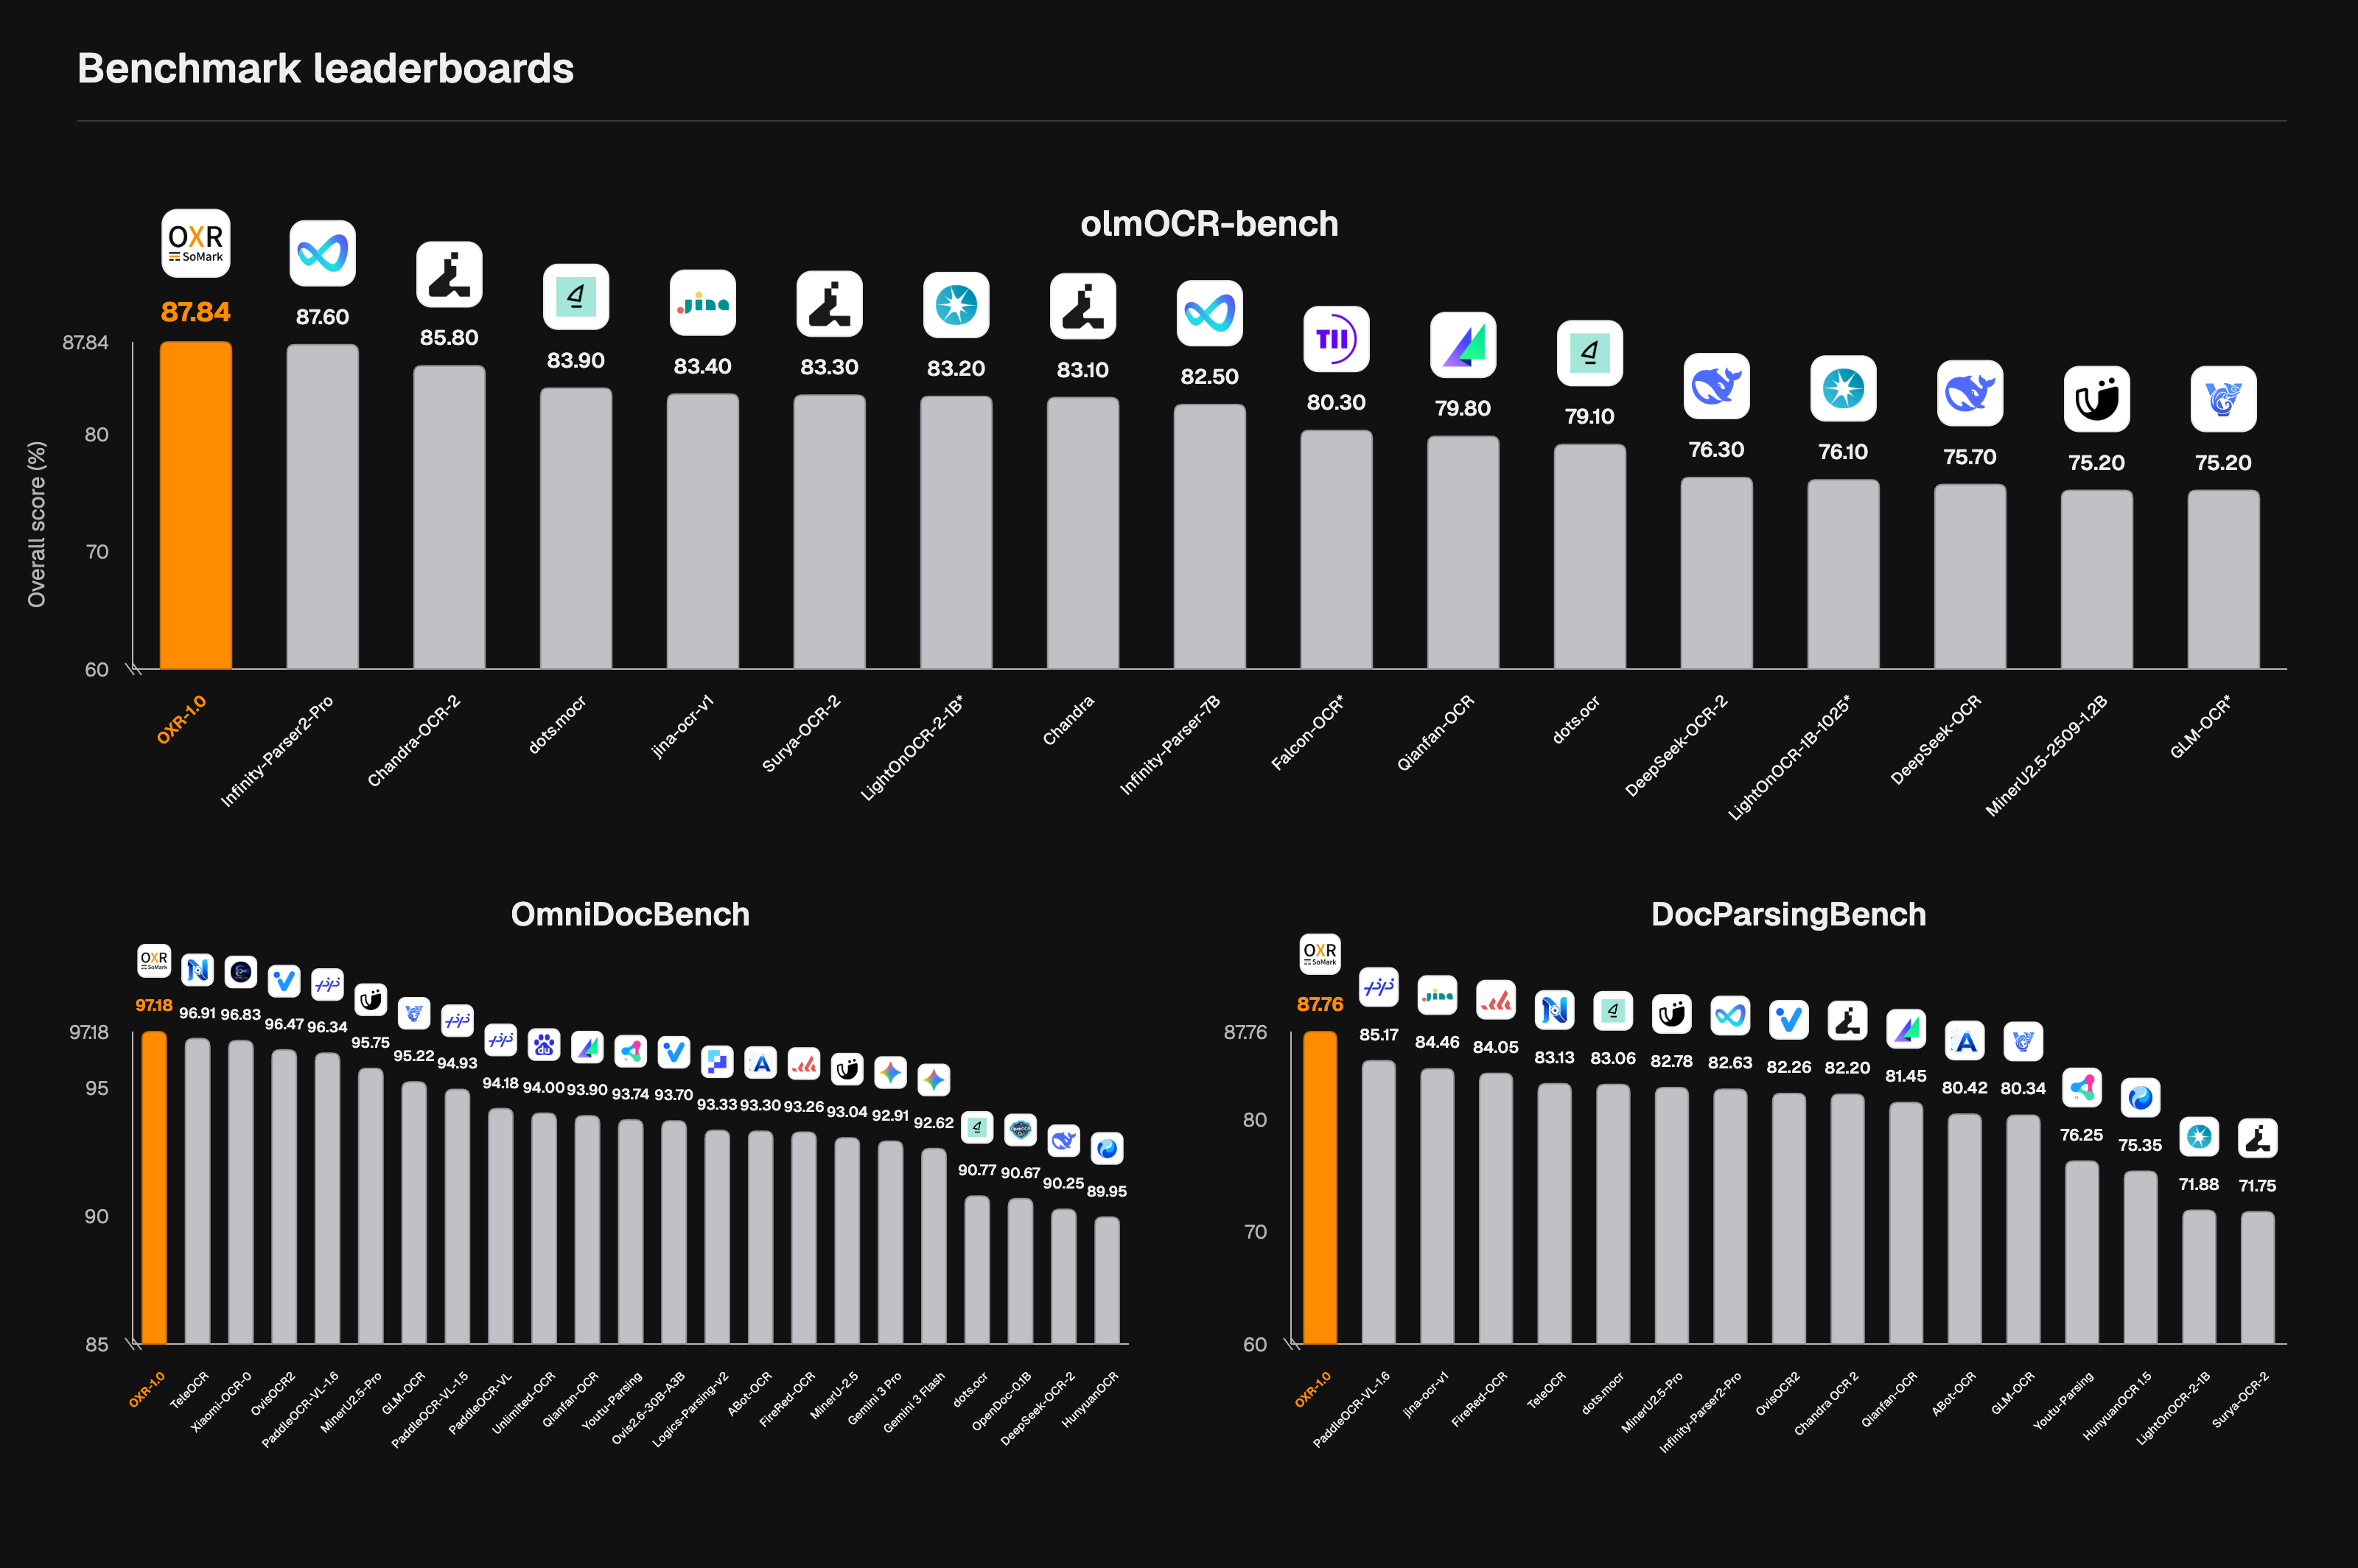++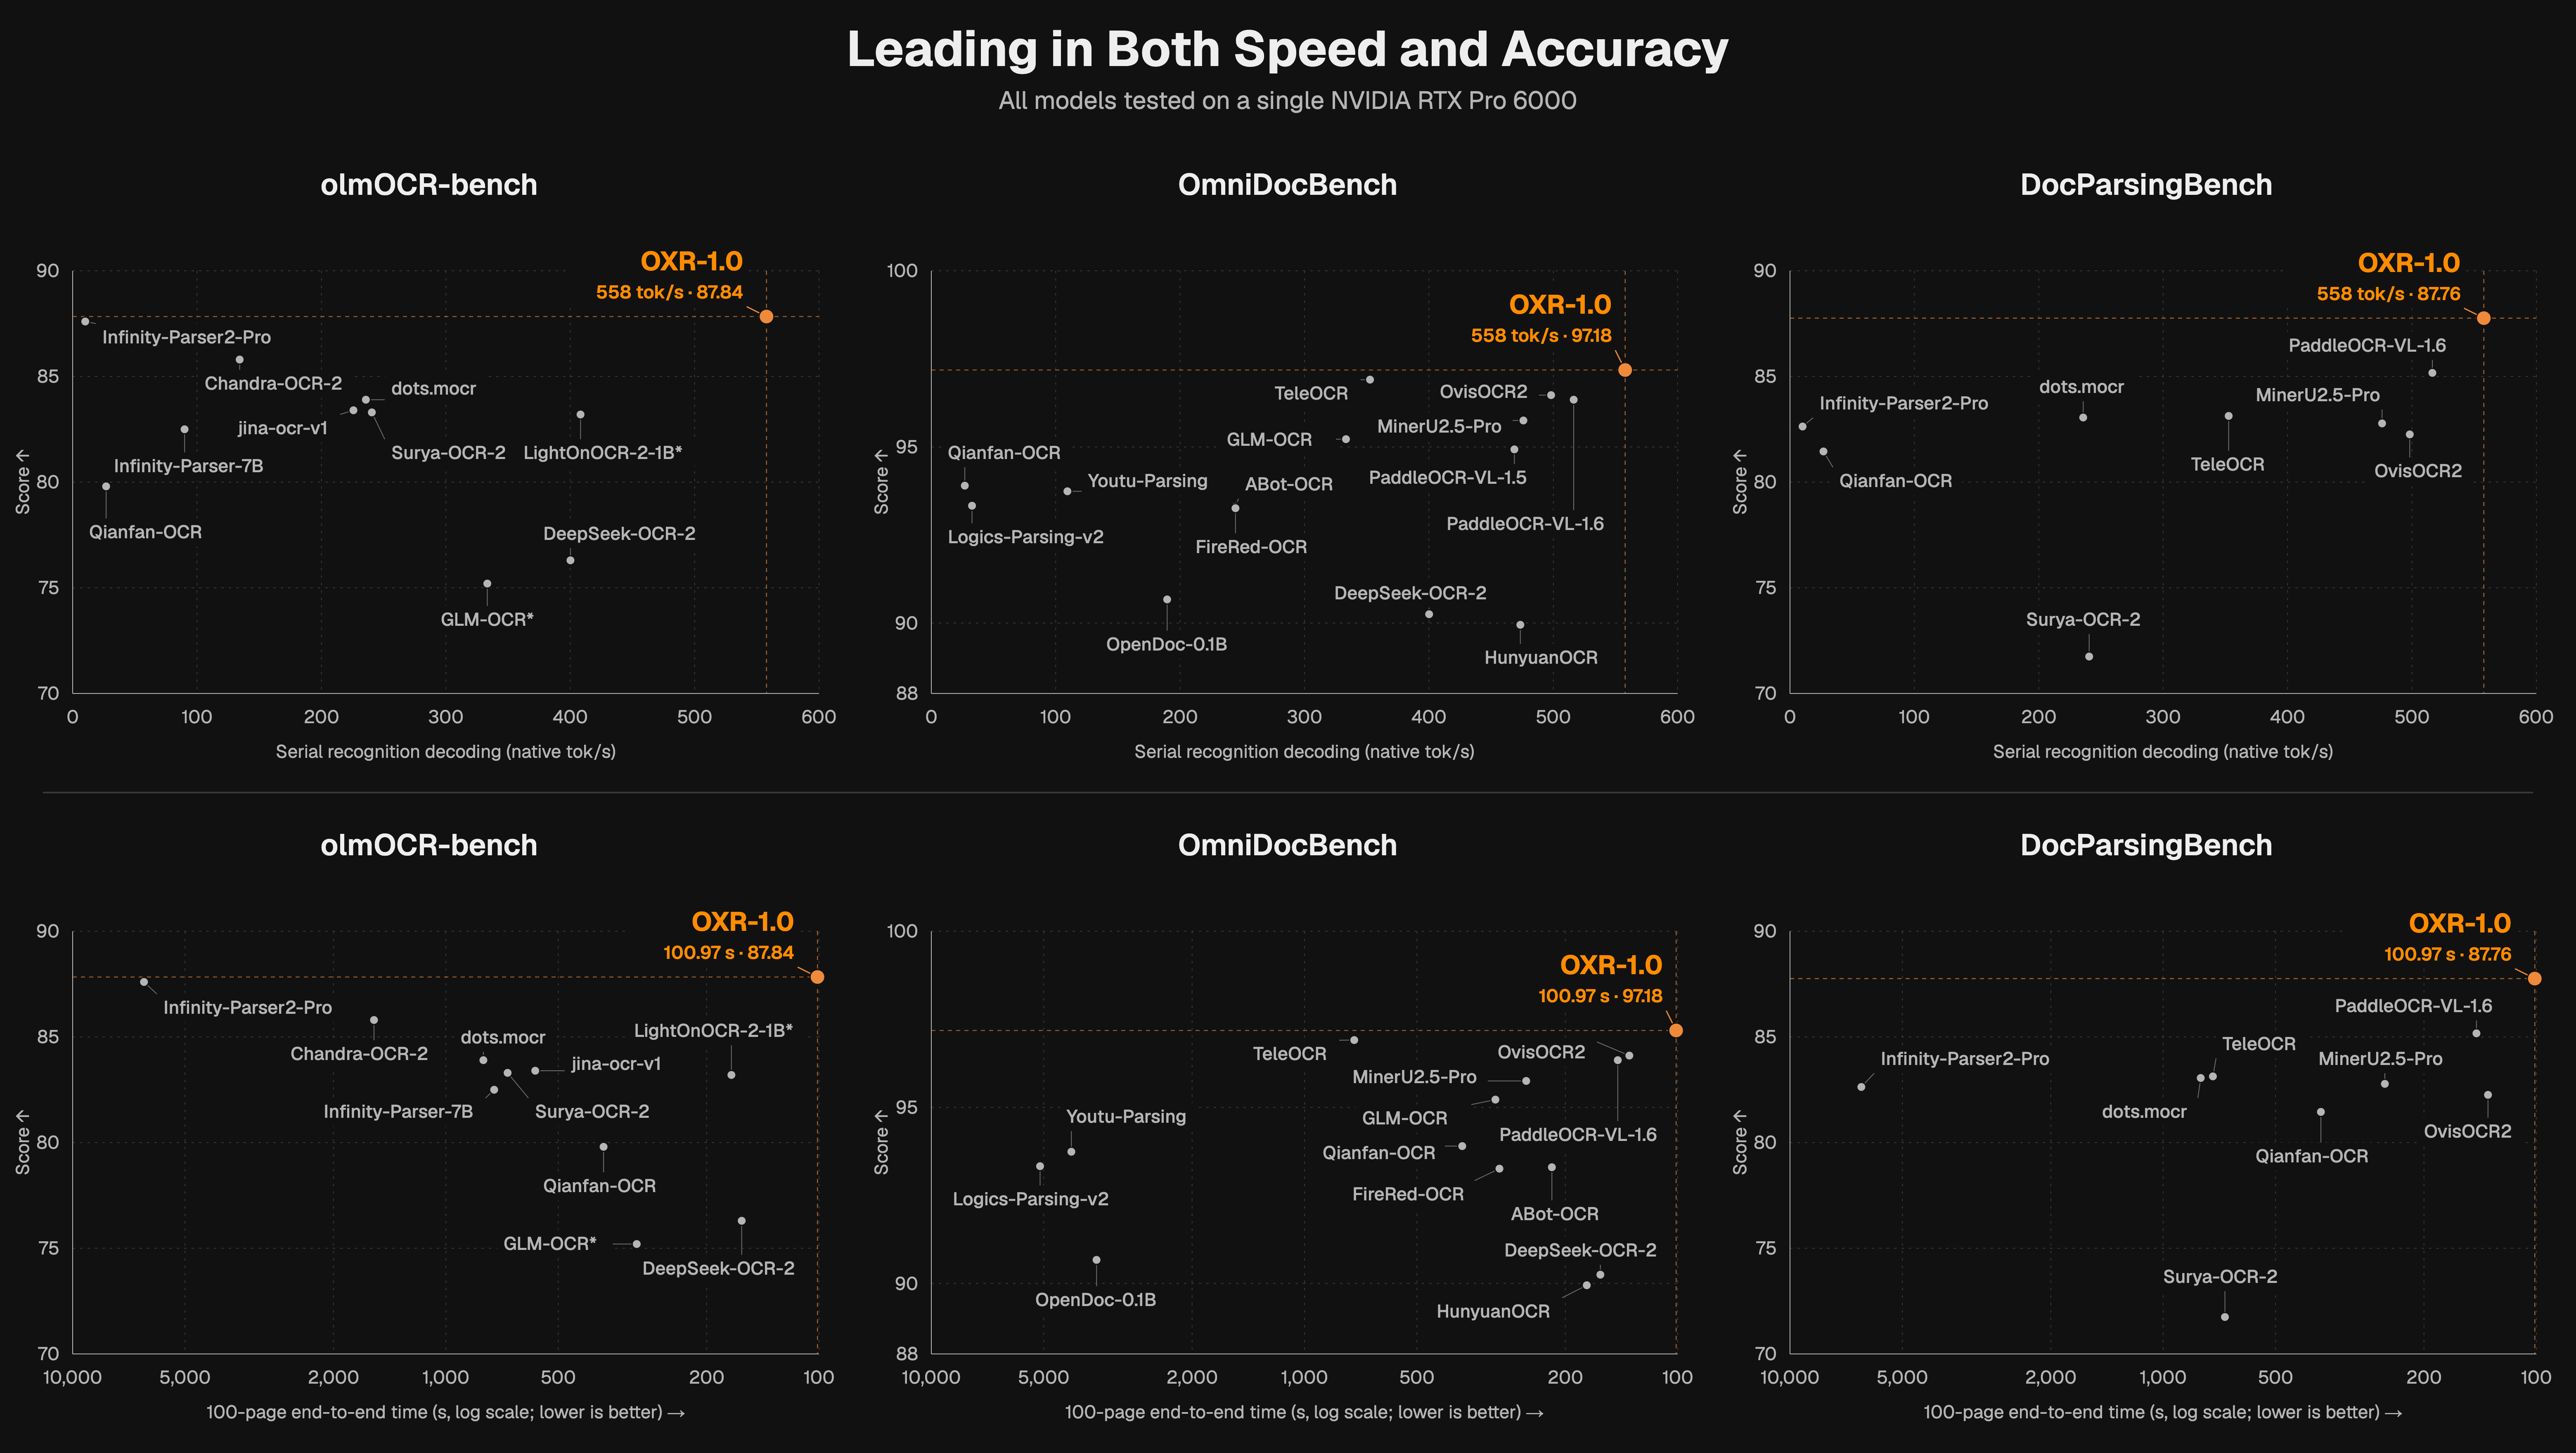++---++> If this project helps you, please click ⭐ Star in the top-right corner to support us. It's the best encouragement you can give the developers!++++## Why OXR?++- 🎯 SOTA Accuracy. #1 Across Three Benchmarks.++ - OXR ranks 🏆#1 on olmOCR-Bench, OmniDocBench, and DocParsingBench, with a particularly wide lead in table parsing.+ - OXR can recognize 13 document element types, from formulas and tables to chemical equations, chemical structures, and code blocks, with bounding box coordinates included. It also performs well on challenging documents and layouts, including A3 exam papers, newspapers, vertical text, and handwriting.+ - See [docs/benchmark.md](docs/benchmark.md) for the full results and instructions to reproduce the evaluations.+- 🚀 1.3B Parameters. Top-Tier Parsing Speed.++ - With only 1.3B parameters, OXR ranks 🏆#1 among open-source document parsing models in speed tests on the RTX PRO 6000.+ - OXR redesign its processing architecture at the task level to improve parsing speed while maintaining accuracy.+ - See [docs/benchmark.md](docs/benchmark.md) for the full results and instructions to reproduce the evaluations.+- 🧩 Pluggable Layout Analysis. Document Structure on Your Terms.++ - Layout analysis requirements vary widely across domains. Even for the same document, element types, region boundaries, and grouping rules can differ depending on the business use case.+ - OXR is the first to make layout analysis independent and pluggable. Its built-in layout model can be replaced while retaining OXR’s recognition and reading order capabilities, enabling adaptation across document scenarios with minimal integration effort.+ - See the [How it works](#how-to-works) section below for details.+++<details>+<summary>Expand to see all 13 element types</summary>++| Name | JSON type value | Content or output format |+|-|-|-|+| Caption | Caption | Plain text |+| Footnote | Footnote | Plain text |+| Formula | Formula | LaTeX |+| Text | Text | Plain text |+| Footer | Page-footer | Plain text (filtered out by default) |+| Header | Page-header | Plain text (filtered out by default) |+| Figure | Picture | Image |+| Title | Title | Plain text |+| Table | Table | HTML / Markdown |+| Stamp | Stamp | Plain text / Image |+| Chemical Equation | Chemical Equation | LaTeX (starting with \ce, using mhchem syntax) |+| Code Block | Code Block | Markdown code block |+| Chemical Structure | Chemical Structure | SMILES / Image |+++</details>+++## Parsing Examples++The animation shows OXR's parsing process.++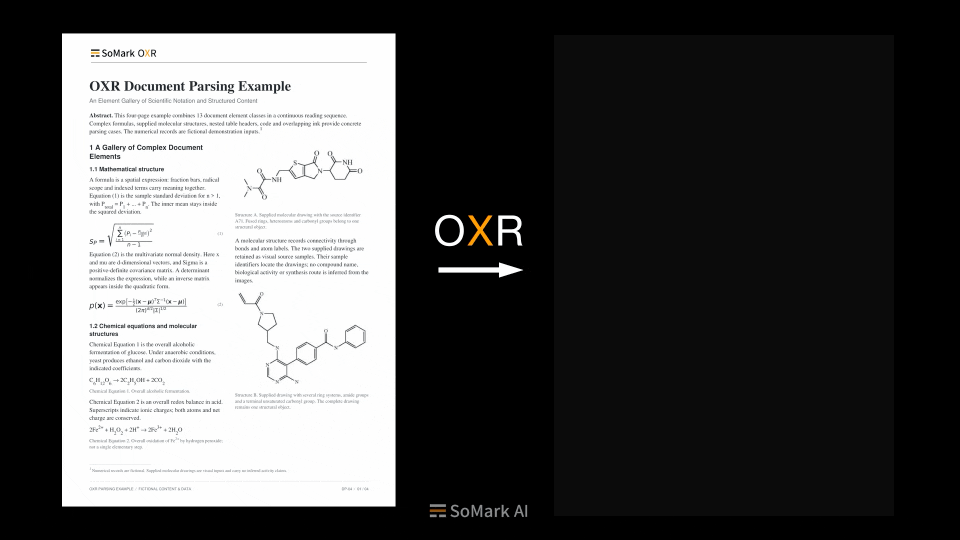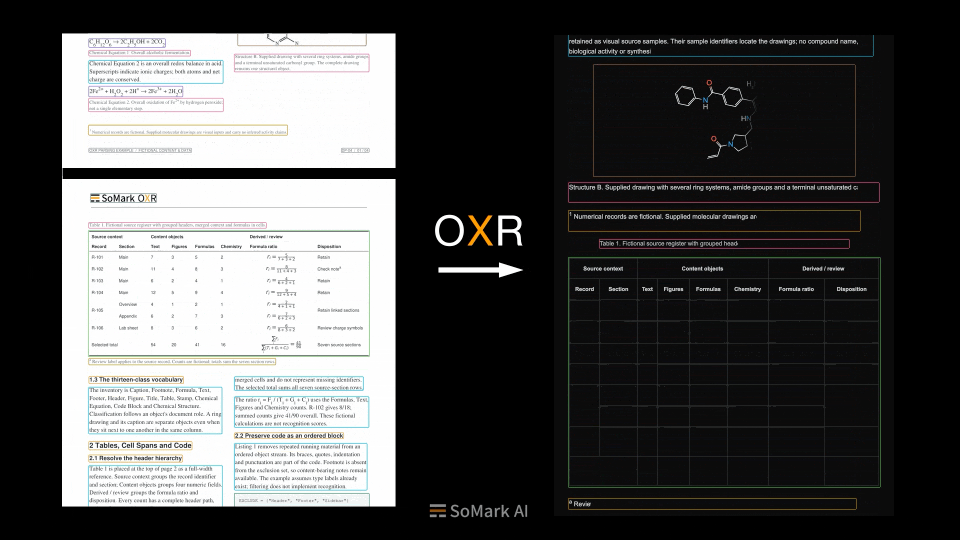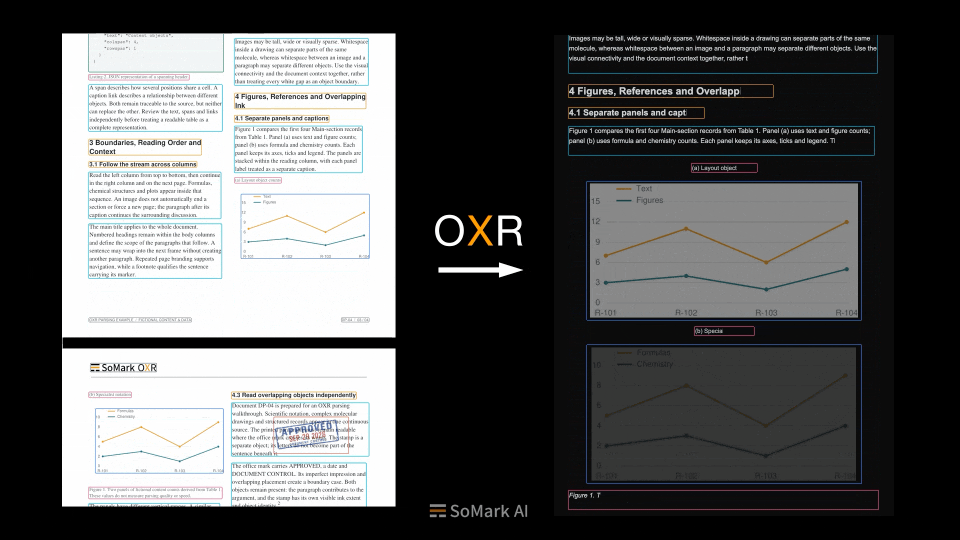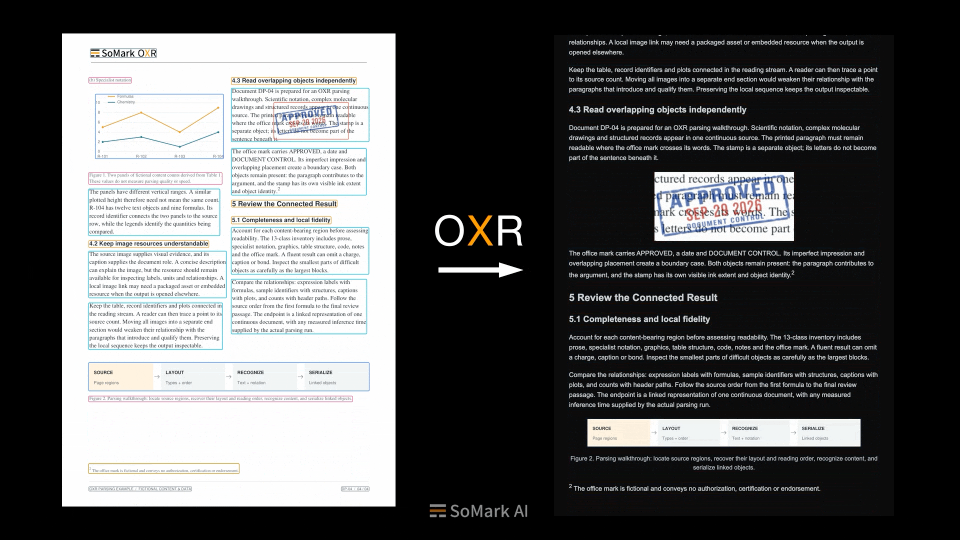++The examples below show OXR parsing different document types. Click an image to view the original.++<table>+ <tr>+ <td align="center" valign="top"><strong>A3 Exam Paper</strong><br/><a href="https://raw.githubusercontent.com/SoMarkAI/image_bed/main/OXR_README/assets/parsing_examples/a3_exam_paper.png"><img src="https://raw.githubusercontent.com/SoMarkAI/image_bed/main/OXR_README/assets/parsing_examples/a3_exam_paper.png" alt="A3 Exam Paper" width="280" /></a></td>+ <td align="center" valign="top"><strong>Chinese Handwriting</strong><br/><a href="https://raw.githubusercontent.com/SoMarkAI/image_bed/main/OXR_README/assets/parsing_examples/chinese_handwriting.png"><img src="https://raw.githubusercontent.com/SoMarkAI/image_bed/main/OXR_README/assets/parsing_examples/chinese_handwriting.png" alt="Chinese Handwriting" width="280" /></a></td>+ <td align="center" valign="top"><strong>Code Block</strong><br/><a href="https://raw.githubusercontent.com/SoMarkAI/image_bed/main/OXR_README/assets/parsing_examples/code_block.png"><img src="https://raw.githubusercontent.com/SoMarkAI/image_bed/main/OXR_README/assets/parsing_examples/code_block.png" alt="Code Block" width="280" /></a></td>+ </tr>+ <tr>+ <td align="center" valign="top"><strong>Chemical Equation</strong><br/><a href="https://raw.githubusercontent.com/SoMarkAI/image_bed/main/OXR_README/assets/parsing_examples/chemical_equation.png"><img src="https://raw.githubusercontent.com/SoMarkAI/image_bed/main/OXR_README/assets/parsing_examples/chemical_equation.png" alt="Chemical Equation" width="280" /></a></td>+ <td align="center" valign="top"><strong>Chemical Structure</strong><br/><a href="https://raw.githubusercontent.com/SoMarkAI/image_bed/main/OXR_README/assets/parsing_examples/chemical_structure.png"><img src="https://raw.githubusercontent.com/SoMarkAI/image_bed/main/OXR_README/assets/parsing_examples/chemical_structure.png" alt="Chemical Structure" width="280" /></a></td>+ <td align="center" valign="top"><strong>Complex Formula</strong><br/><a href="https://raw.githubusercontent.com/SoMarkAI/image_bed/main/OXR_README/assets/parsing_examples/complex_formula.png"><img src="https://raw.githubusercontent.com/SoMarkAI/image_bed/main/OXR_README/assets/parsing_examples/complex_formula.png" alt="Complex Formula" width="280" /></a></td>+ </tr>+ <tr>+ <td align="center" valign="top"><strong>Complex Table</strong><br/><a href="https://raw.githubusercontent.com/SoMarkAI/image_bed/main/OXR_README/assets/parsing_examples/complex_table.png"><img src="https://raw.githubusercontent.com/SoMarkAI/image_bed/main/OXR_README/assets/parsing_examples/complex_table.png" alt="Complex Table" width="280" /></a></td>+ <td align="center" valign="top"><strong>Academic Paper</strong><br/><a href="https://raw.githubusercontent.com/SoMarkAI/image_bed/main/OXR_README/assets/parsing_examples/academic_paper.png"><img src="https://raw.githubusercontent.com/SoMarkAI/image_bed/main/OXR_README/assets/parsing_examples/academic_paper.png" alt="Academic Paper" width="280" /></a></td>+ <td align="center" valign="top"><strong>Newspaper</strong><br/><a href="https://raw.githubusercontent.com/SoMarkAI/image_bed/main/OXR_README/assets/parsing_examples/newspaper.png"><img src="https://raw.githubusercontent.com/SoMarkAI/image_bed/main/OXR_README/assets/parsing_examples/newspaper.png" alt="Newspaper" width="280" /></a></td>+ </tr>+ <tr>+ <td align="center" valign="top"><strong>Research Report</strong><br/><a href="https://raw.githubusercontent.com/SoMarkAI/image_bed/main/OXR_README/assets/parsing_examples/research_report.png"><img src="https://raw.githubusercontent.com/SoMarkAI/image_bed/main/OXR_README/assets/parsing_examples/research_report.png" alt="Research Report" width="280" /></a></td>+ <td align="center" valign="top"><strong>Resume</strong><br/><a href="https://raw.githubusercontent.com/SoMarkAI/image_bed/main/OXR_README/assets/parsing_examples/resume.png"><img src="https://raw.githubusercontent.com/SoMarkAI/image_bed/main/OXR_README/assets/parsing_examples/resume.png" alt="Resume" width="280" /></a></td>+ <td align="center" valign="top"><strong>English Handwriting</strong><br/><a href="https://raw.githubusercontent.com/SoMarkAI/image_bed/main/OXR_README/assets/parsing_examples/english_handwriting.png"><img src="https://raw.githubusercontent.com/SoMarkAI/image_bed/main/OXR_README/assets/parsing_examples/english_handwriting.png" alt="English Handwriting" width="280" /></a></td>+ </tr>+</table>++## How it works++<a id="how-to-works"></a>++### Technical Architecture++The system consists of two models: a Layout Analysis model and OXR. We integrate Reading Order into the Recognition stage, with both tasks handled by the same model. This design improves both speed and accuracy.++We also designed the system this way to make customization easier. We have found that Layout Analysis varies more across document domains than any other module, and it is typically the part that document parsing providers need to customize most. Existing document parsing tools either assign it to the Recognition model or use a dedicated model that also handles Reading Order. OXR's design achieves the simplest access method for Layout Analysis, and any Layout Analysis model can work well with the OXR model.++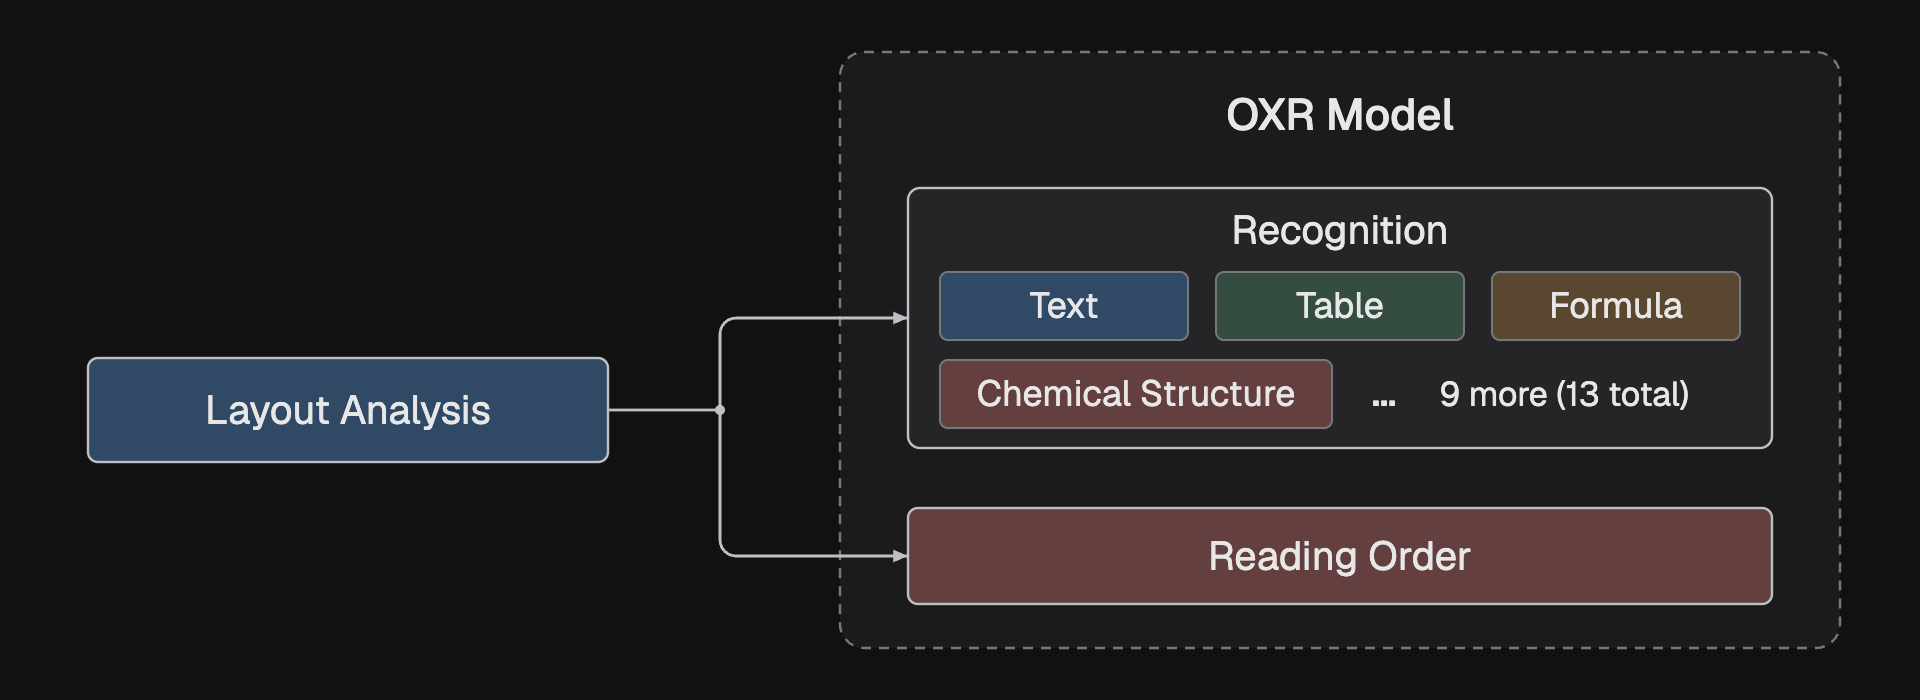++++### Improvement Through the RSI Loop++For a task like document parsing, where ground-truth answers exist, we have long wanted an engineering system that helps the core model improve itself. The diagram below shows OXR's RSI approach. It targets samples the model gets wrong or handles weakly, improving performance without human annotation. This has made our iteration faster than ever.++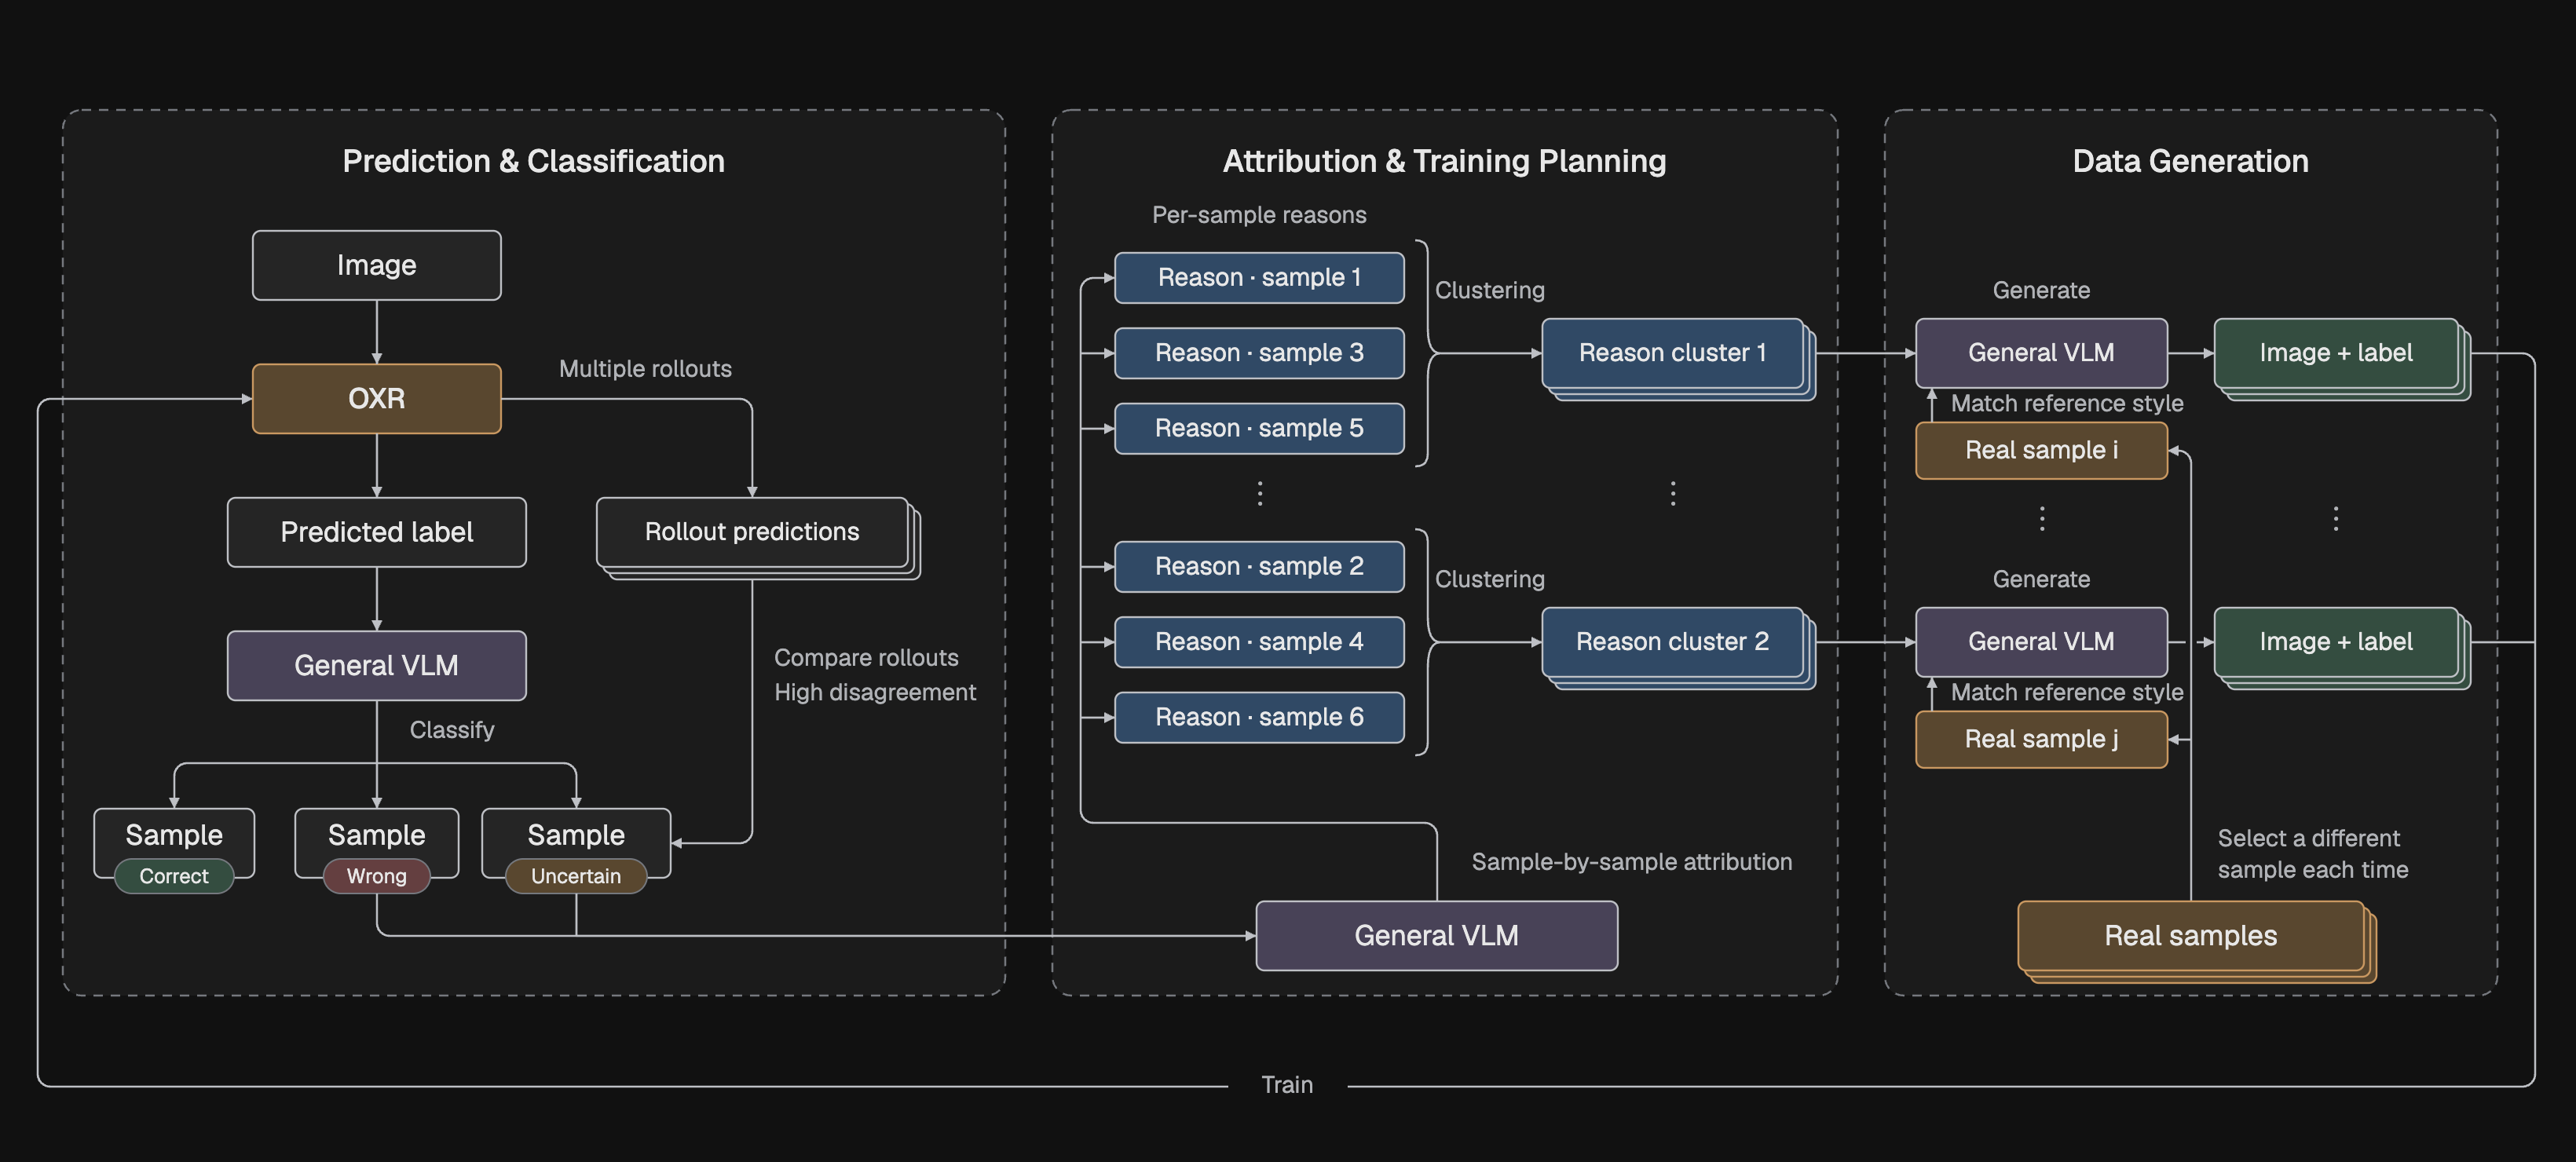++++## Quick Start++<a id="free-api"></a>++### 0. 🔥 🆓 Free API++OXR provides a free API so you can test parsing on your own documents without registering or requesting an API key.++We'll keep the free API online until we can no longer afford to run it.++⚠️ Note: We do not recommend using the Free OXR API in production. We do not guarantee service stability, and requests are queued, so processing speed may vary slightly.++| Online Demo | https://free-oxr.somark.ai | https://free-oxr.somark.cn |+|-|-|-|+| API URL | https://free-oxr.somark.ai/api/v1 | https://free-oxr.somark.cn/api/v1 |+| API documentation | [https://docs.somark.ai/api-reference](https://docs.somark.ai/api-reference) | https://docs.somark.cn/api-reference |++> somark.cn is a mirror of somark.ai. Choose the domain that works best for your region.++OXR's document parsing API is compatible with SoMark's official document parsing API. You can use SoMark's official document parsing CLI tools, somark-py and somark-js, by changing the **Base URL**. See Section 1.4 for supported endpoints and output formats.++```Bash+# using python+pip install somark+# or using js+npm install -g somark-js++somark --base-url https://free-oxr.somark.ai/api/v1 --api-key dummy \+ parse document.pdf --formats md,json --out ./parsed-output/+```++++### 1. Run Locally++```Plain Text+Operating system: Linux+GPU: NVIDIA (with BF16 support)+Driver: NVIDIA driver (compatible with CUDA 13.0)+Python: 3.12 (for model downloads / running from source)+GPU memory to get started: 24GB on a single GPU (for low-concurrency testing)+Recommended GPU memory: ≥48GB on a single GPU (for long documents / higher concurrency)+```++#### 1.1 Download the Code and Models++| Model | Download links | Precision | Includes a lightweight layout analysis model? |+|-|-|-|-|+| OXR-1.0 | [🤗 Hugging Face ](https://huggingface.co/SoMarkAI/OXR-1.0) <br/>[🤖 ModelScope](https://modelscope.cn/models/SoMark/OXR-1.0) | BF16 | Yes, in the layout_analysis folder |++First, get the code and prepare the environment for downloading the models:++```Bash+git clone https://github.com/SoMarkAI/OXR.git+cd OXR++# pip install -U huggingface_hub+hf download SoMarkAI/OXR-1.0 --local-dir ./models/OXR-1.0++# or using ModelScope+# pip install -U modelscope-hub+modelscope download SoMark/OXR-1.0 --local_dir ./models/OXR-1.0+```++#### 1.2 Start the Services++##### 1.2.1 Run with Docker (Recommended)++We recommend Docker to configure and start all services together.++```Bash+docker build -f docker/Dockerfile.allinone -t oxr-1.0 .+docker run --rm --gpus all --ipc=host \+ -p 127.0.0.1:8000:8000 \+ -v "$PWD/models/OXR-1.0:/models/oxr-model:ro" \+ oxr-1.0+```++Once the startup logs show that the services are ready, open http://localhost:8000/demo or http://localhost:8000/docs.+The first startup may take longer. The default startup timeout is 900 seconds.+See How to use OXR for more advanced options and usage examples.+++##### 1.2.2 Run from Source++After downloading the code and models, start the following three services separately. Each service uses its own process and virtual environment. Run all commands from the OXR repository root. The document parsing API depends on both the OXR model service and the Layout Analysis model service, so start the two model APIs first.++**OXR Model Service (Port 8080)**++OXR supports vLLM, but the official vLLM release does not yet support OXR inference. We provide an out-of-tree plugin and a loading script in the model weights folder on Hugging Face. No recompilation is needed: you can use the plugin directly with the official vLLM Docker image or CLI.++```Bash+# pip install vllm==0.25.1 transformers==5.13.1++MODEL_PATH="$PWD/models/OXR-1.0" \+ bash services/oxr/start_vllm.sh \+ --gpu-memory-utilization 0.70 --max-num-seqs 16+```++**Layout Analysis Model Service (Port 8081)**++The Layout Analysis model weights are included in the OXR model weights folder downloaded earlier.++```Bash+# pip install torch==2.11.0 torchvision==0.26.0 --index-url https://download.pytorch.org/whl/cu130+# pip install -r services/layout_analyze/requirements.txt++MODEL_PATH="$PWD/models/OXR-1.0/layout_analysis/last.pth" \+DFINE_DEVICE=cuda \+ python -m uvicorn dfine_la.api:app \+ --app-dir services/layout_analyze \+ --host 127.0.0.1 --port 8081 --workers 1+```++**Document Parsing API (Port 8000)**++Copy the provided `config.example.yaml` to `config.yaml`. Set the url fields under `layout_analyze_model` and `oxr_model` to the addresses of the two services you started above.++```Bash+# pip install -c docker/requirements.allinone.txt .++oxr serve --config config.yaml \+ --host 127.0.0.1 --port 8000 --workers 1+```++Once all three services are running, use the demo and parsing API in the same way as with Docker. See Sections 1.3 and 1.4.++#### 1.3 Open the Visual Demo++Open http://localhost:8000/demo and upload a PDF or image. You can view the original file, Markdown preview, source, layout bounding boxes, and reading order, and download the Markdown.++The demo uses a temporary file cache that expires after 1 hour by default and is renewed during processing. Cached results become inaccessible once the cache expires or is cleared, so download your results promptly.++#### 1.4 Send a Parsing Request++OXR's API is compatible with the SoMark API. Although OXR does not support some specialized capabilities, SoMark's ecosystem fully supports deployed OXR services. Visit the [SoMark website](https://somark.ai) and refer to the [API documentation](https://docs.somark.ai/api-reference).++Call the parsing endpoint directly:++```Bash+curl --fail-with-body http://localhost:8000/v1/parse/sync \+ -F '[email protected]' \+ -F 'api_key=dummy' \+ -F 'output_formats=markdown' \+ -F 'output_formats=json'+```++SoMark provides a full set of CLI and SDK tools for document parsing in Python and JavaScript. OXR is compatible with their document parsing interfaces, so you can use them by changing the baseURL. For more information, see https://docs.somark.ai/en/cli-sdk.++```Bash+pip install somark++somark --base-url http://localhost:8000/v1 --api-key dummy \+ parse document.pdf --formats md,json --out ./parsed-output/+```++## Ecosystem++The SoMark team has developed a range of tools for document parsing. If you find them helpful, please give them a ⭐ Star.++| | Description | Project URL |+|-|-|-|+| SoMarkDown | The official Markdown parsing and rendering library for SoMark and OXR | https://github.com/SoMarkAI/SoMarkDown |+| SoMarkDownViewer | A live editing application for SoMarkDown | https://github.com/SoMarkAI/SoMarkDownViewer |+| SoPDF | A high-performance PDF processing library with a permissive open-source license | https://github.com/SoMarkAI/SoPDF |+| Docision | MultiModal Jev for Document. | https://github.com/SoMarkAI/docision |+| somark-py | The official Python SDK & CLI for SoMark and OXR | [https://github.com/SoMarkAI/somark-py](https://github.com/SoMarkAI/somark-py) |+| somark-js | The official JS / TS SDK & CLI for SoMark and OXR | https://github.com/SoMarkAI/somark-js |+----> If this project helps you, please click the ⭐ Star in the top right corner — it's the greatest encouragement for the developers!+<div align="center">+<img src="https://raw.githubusercontent.com/SoMarkAI/image_bed/main/OXR_README/assets/OXR_Star_on_GitHub.gif" width="800" />+</div>++## Citation++For now, please cite the OXR-1.0 open-source project. We will add a paper citation once the technical report is published.++```bibtex+@misc{somark2026oxr,+ author = {{SoMark}},+ title = {{OXR-1.0}},+ url = {https://github.com/SoMarkAI/OXR},+ note = {GitHub repository}+}+```## License-OXR is licensed under a custom license based on Apache 2.0, with additional terms.+OXR is released under the [OXR Open Source License](./LICENSE), a custom license based on Apache 2.0 with additional terms.++For further services, contact the SoMark team at [somark.ai](http://somark.ai).++## Community++Join the OXR community to discuss document parsing, share feedback, and keep up with the latest updates.++- [Discord](https://discord.gg/msCPj2AtNN) — Discuss OXR, exchange tips, and share what you're building.+- [X / Twitter](https://x.com/somarkai) — Keep up with OXR releases and news from SoMark.+- [GitHub Issues](https://github.com/SoMarkAI/OXR/issues) — Report bugs, suggest features, and track progress.+- **WeChat** — Scan the QR code below to join the OXR group and exchange ideas with other users.-If you need further services, contact the SoMark team → [somark.ai](https://somark.ai/)+<p>+ <img src="./assets/wechat-community.png" alt="QR code for the OXR WeChat group" width="200" />+</p>diff --git a/README_CN.md b/README_CN.mdindex 75c01ea..e7784c5 100644--- a/README_CN.md+++ b/README_CN.md@@ -1,33 +1,337 @@<div align="center">-<img src="assets/header.png" />+<img src="https://raw.githubusercontent.com/SoMarkAI/image_bed/main/OXR_README/assets/header.png" alt="" />-# SoMark|OXR+<h1>SoMark|O<span style="color: #DE7802;">X</span>R</h1>-[English](README.md) · **简体中文**--精度与速度双 SOTA 的开源文档解析模型+采用RSI训练,精度与速度双 SOTA 的开源文档解析模型----让文档成为 Agent-Friendly 数据。+**让文档成为 Agent-Friendly 数据**-[](https://huggingface.co/SoMarkAI/OXR-1.0)-[](https://modelscope.cn/models/SoMark/OXR-1.0)+[🌐 Online Demo](https://free-oxr.somark.ai) | [🔥 🆓 Free API](#free-api)++[](https://huggingface.co/SoMarkAI/OXR-1.0) [](https://modelscope.cn/models/SoMark/OXR-1.0) ++[English](README.md) · **简体中文**</div>-OXR(Optical Everything Recognition)是 SoMark 团队开源的SOTA文档解析模型,参数量1.3B,可将 PDF 和文档图片解析为 Agent 友好数据(Markdown / JSON),并提供版面分析结果。+OXR(Optical Everything Recognition)是 SoMark 团队开源的SOTA文档解析模型,参数量1.3B,可将 PDF 和文档图片解析为 Agent-Friendly 数据(Markdown / JSON),并提供版面分析结果。++OXR从零开始预训练(Pretrained from Scratch),并在后训练阶段首次引入面向文档解析的递归自我改进(RSI)训练范式。在全球三大基准 OmniDocBench、olmOCR-Bench 和 DocParsingBench 测试中,OXR 均位列第一,同时解析速度也达到业内领先水平。在架构设计上,OXR 首次将版面分析模块设计为独立、可插拔模块。在提升解析效率的同时,也让业务适配更加灵活。用户可根据业务对文档结构的要求,用自有模型替换内置的版面分析模型,以最小成本实现多场景适配。+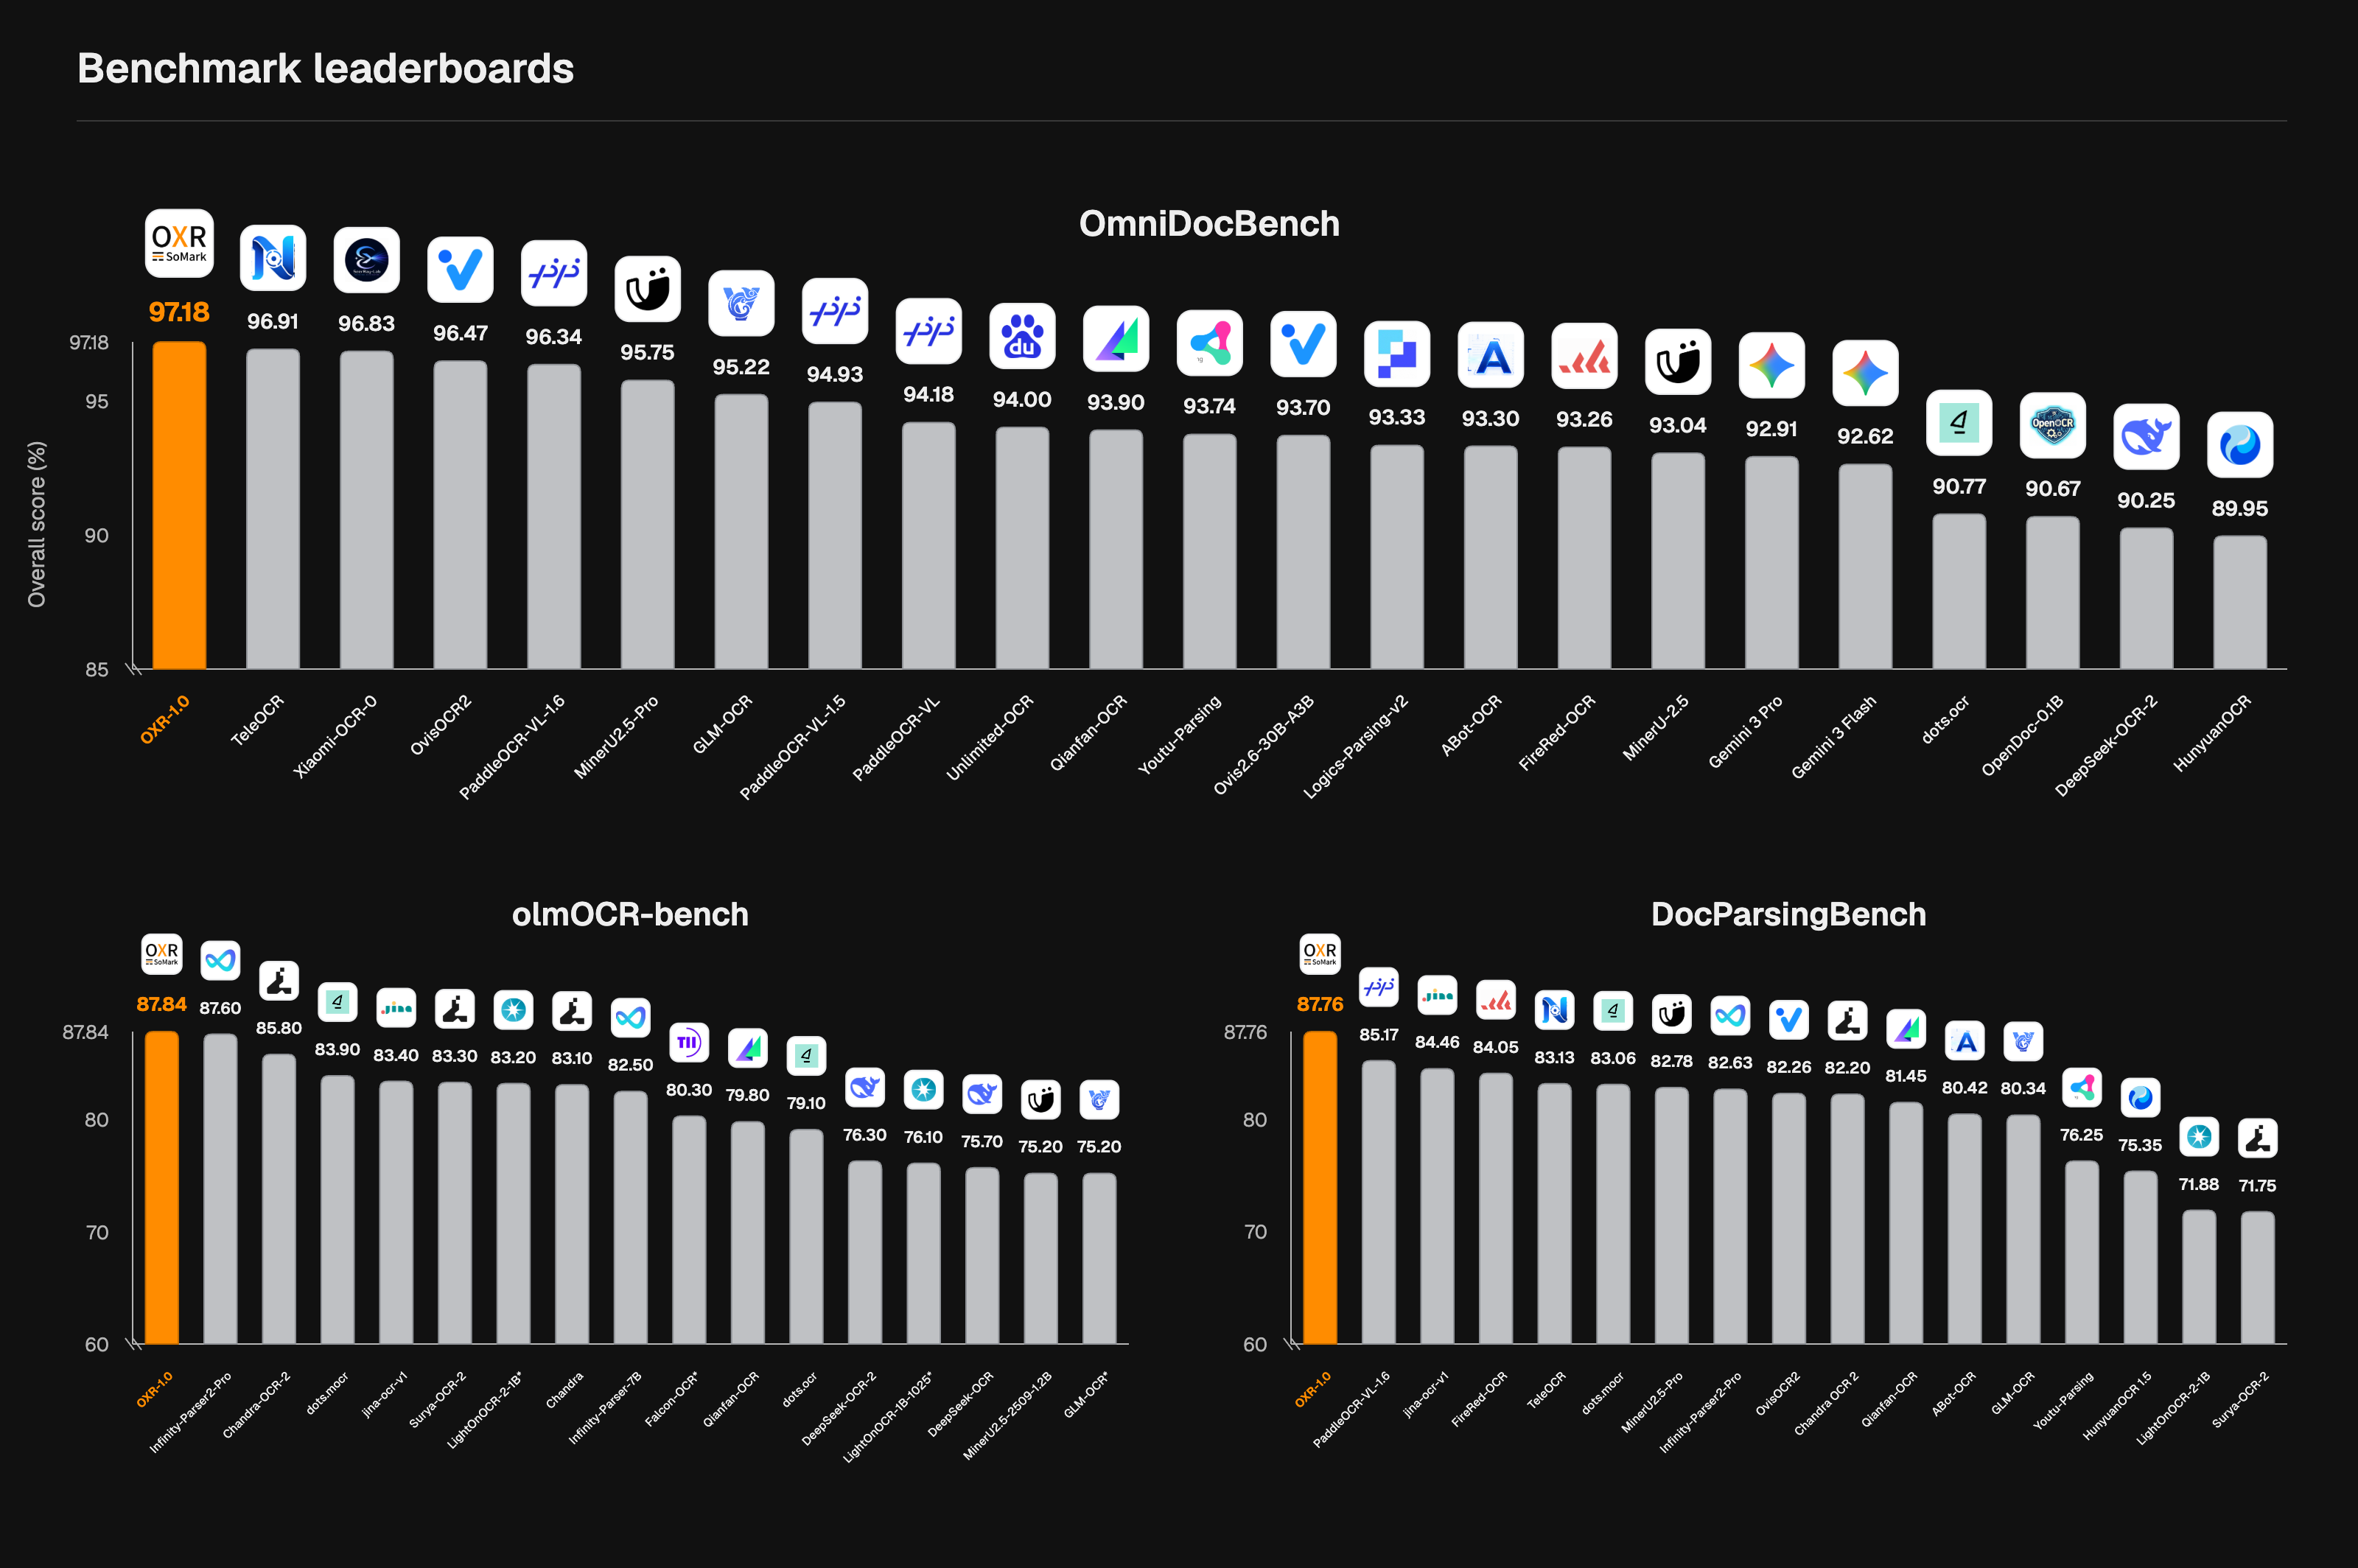+++---> 如果这个项目对你有帮助,请点击右上角 ⭐ Star 支持一下,这是对开发者最大的鼓励!-## 许可证-OXR 采用基于 Apache 2.0 的自定义许可证,附带额外条款。+## Why OXR?++- 🎯 高精度解析,全球三榜第一++ - 在全球三大基准 OmniDocBench、olmOCR-Bench 和 DocParsingBench 测试中,OXR 均位列第一🏆,其中表格解析子项的优势尤为突出。+ - OXR 可识别公式、表格、化学方程式、化学结构式和代码块等 13 类文档元素,并提供对应的版面坐标;面对 A3 试卷、报纸等复杂版面,以及竖排文字和手写内容,也能保持良好解析效果。+ - 可前往 [docs/benchmark.md](docs/benchmark.md) 中查阅完整数值并复现评测结果。+- 🚀 1.3B 参数,解析速度领先++ - OXR 仅 1.3B 参数,在 RTX PRO 6000 上的速度测试中位居开源文档解析模型第一🏆。+ - OXR 在任务层面重构了工作架构,实现在保持精度的同时解析速度的提升。+ - 可前往 [docs/benchmark.md](docs/benchmark.md) 中查阅完整数值并复现评测结果。+- 🧩 可插拔版面分析模块,按业务需求灵活替换++ - 版面分析一直是各个领域文档发生差异最大的模块。即使是同一份文档,不同业务对于元素类别、区域边界、内容分组的定义都会有所差异。+ - OXR 首次将版面分析设计为独立、可插拔模块。用户可以直接使用内置模型,也可以根据业务要求接入自有模型,再继续使用 OXR 的内容识别与阅读顺序判断能力,以最小成本实现多场景适配。+ - 可在下方“[How it works](#how-to-works)”章节了解详情+++<details>+<summary>展开查看13种组件</summary>++| 中文名称 | 英文名称 | JSON 类别值(type) | 内容或输出格式 |+|-|-|-|-|+| 图注/表注 | Caption | Caption | 纯文本 |+| 脚注 | Footnote | Footnote | 纯文本 |+| 公式 | Formula | Formula | LaTeX |+| 正文文本 | Text | Text | 纯文本 |+| 页脚 | Footer | Page-footer | 纯文本(默认过滤) |+| 页眉 | Header | Page-header | 纯文本(默认过滤) |+| 图片/图形 | Figure | Picture | 图片 |+| 标题 | Title | Title | 纯文本 |+| 表格 | Table | Table | HTML/Markdown |+| 印章 | Stamp | Stamp | 纯文本/图片 |+| 化学方程式 | Chemical Equation | Chemical Equation | LaTeX(以 \ce 开头,mhchem 语法) |+| 代码块 | Code Block | Code Block | Markdown 代码块 |+| 化学结构式 | Chemical Structure | Chemical Structure | SMILES/图片 |+++</details>+++## 效果展示++动图展示了 OXR 的解析过程。++++下方展示不同文档类型的 OXR 解析示例,点击图片可查看原图。++<table>+ <tr>+ <td align="center" valign="top"><strong>A3试卷</strong><br/><a href="https://raw.githubusercontent.com/SoMarkAI/image_bed/main/OXR_README/assets/parsing_examples/a3_exam_paper.png"><img src="https://raw.githubusercontent.com/SoMarkAI/image_bed/main/OXR_README/assets/parsing_examples/a3_exam_paper.png" alt="A3试卷" width="280" /></a></td>+ <td align="center" valign="top"><strong>中文手写</strong><br/><a href="https://raw.githubusercontent.com/SoMarkAI/image_bed/main/OXR_README/assets/parsing_examples/chinese_handwriting.png"><img src="https://raw.githubusercontent.com/SoMarkAI/image_bed/main/OXR_README/assets/parsing_examples/chinese_handwriting.png" alt="中文手写" width="280" /></a></td>+ <td align="center" valign="top"><strong>代码块</strong><br/><a href="https://raw.githubusercontent.com/SoMarkAI/image_bed/main/OXR_README/assets/parsing_examples/code_block.png"><img src="https://raw.githubusercontent.com/SoMarkAI/image_bed/main/OXR_README/assets/parsing_examples/code_block.png" alt="代码块" width="280" /></a></td>+ </tr>+ <tr>+ <td align="center" valign="top"><strong>化学方程式</strong><br/><a href="https://raw.githubusercontent.com/SoMarkAI/image_bed/main/OXR_README/assets/parsing_examples/chemical_equation.png"><img src="https://raw.githubusercontent.com/SoMarkAI/image_bed/main/OXR_README/assets/parsing_examples/chemical_equation.png" alt="化学方程式" width="280" /></a></td>+ <td align="center" valign="top"><strong>化学结构式</strong><br/><a href="https://raw.githubusercontent.com/SoMarkAI/image_bed/main/OXR_README/assets/parsing_examples/chemical_structure.png"><img src="https://raw.githubusercontent.com/SoMarkAI/image_bed/main/OXR_README/assets/parsing_examples/chemical_structure.png" alt="化学结构式" width="280" /></a></td>+ <td align="center" valign="top"><strong>复杂公式</strong><br/><a href="https://raw.githubusercontent.com/SoMarkAI/image_bed/main/OXR_README/assets/parsing_examples/complex_formula.png"><img src="https://raw.githubusercontent.com/SoMarkAI/image_bed/main/OXR_README/assets/parsing_examples/complex_formula.png" alt="复杂公式" width="280" /></a></td>+ </tr>+ <tr>+ <td align="center" valign="top"><strong>复杂表格</strong><br/><a href="https://raw.githubusercontent.com/SoMarkAI/image_bed/main/OXR_README/assets/parsing_examples/complex_table.png"><img src="https://raw.githubusercontent.com/SoMarkAI/image_bed/main/OXR_README/assets/parsing_examples/complex_table.png" alt="复杂表格" width="280" /></a></td>+ <td align="center" valign="top"><strong>学术论文</strong><br/><a href="https://raw.githubusercontent.com/SoMarkAI/image_bed/main/OXR_README/assets/parsing_examples/academic_paper.png"><img src="https://raw.githubusercontent.com/SoMarkAI/image_bed/main/OXR_README/assets/parsing_examples/academic_paper.png" alt="学术论文" width="280" /></a></td>+ <td align="center" valign="top"><strong>报纸</strong><br/><a href="https://raw.githubusercontent.com/SoMarkAI/image_bed/main/OXR_README/assets/parsing_examples/newspaper.png"><img src="https://raw.githubusercontent.com/SoMarkAI/image_bed/main/OXR_README/assets/parsing_examples/newspaper.png" alt="报纸" width="280" /></a></td>+ </tr>+ <tr>+ <td align="center" valign="top"><strong>研报</strong><br/><a href="https://raw.githubusercontent.com/SoMarkAI/image_bed/main/OXR_README/assets/parsing_examples/research_report.png"><img src="https://raw.githubusercontent.com/SoMarkAI/image_bed/main/OXR_README/assets/parsing_examples/research_report.png" alt="研报" width="280" /></a></td>+ <td align="center" valign="top"><strong>简历</strong><br/><a href="https://raw.githubusercontent.com/SoMarkAI/image_bed/main/OXR_README/assets/parsing_examples/resume.png"><img src="https://raw.githubusercontent.com/SoMarkAI/image_bed/main/OXR_README/assets/parsing_examples/resume.png" alt="简历" width="280" /></a></td>+ <td align="center" valign="top"><strong>英文手写</strong><br/><a href="https://raw.githubusercontent.com/SoMarkAI/image_bed/main/OXR_README/assets/parsing_examples/english_handwriting.png"><img src="https://raw.githubusercontent.com/SoMarkAI/image_bed/main/OXR_README/assets/parsing_examples/english_handwriting.png" alt="英文手写" width="280" /></a></td>+ </tr>+</table>++## How it works++<a id="how-to-works"></a>++### 技术架构++本系统分为Layout Analysis模型和OXR两个模型,我们将Reading Order并入了Recognition阶段,并且发生在同一个模型上。这样的设计对于速度、效果都更加有效。++且如此设计还有一个特别的目的,方便定制。我们发现Layout Analysis一直是各个领域文档发生差异最大的模块,文档解析服务商通常在提供服务时,这一部分是最需要定制开发的。而现在的文档解析工具要么将其交给Recognition模型承担,要么设计特殊模型带上Reading Order任务。我们如此设计实现了最简洁的Layout Analysis接入方式,任何Layout Analysis模型都可以和OXR模型工作的很好。++++++### RSI 闭环提升++对于文档解析这样一个有“标准答案”的任务,我们一直期待有一套工程系统能够帮助核心模型自我提升。OXR的RSI方案如下图所示。对于错样本、弱样本,这套RSI方案可以针对性的进行优化和提升,无需人类参与标注,这让我们的迭代速度空前的快。++++++## Quick Start++<a id="free-api"></a>++### 0. 🔥 🆓 Free API++OXR 提供免费 API,无需注册或申请 API 密钥,即可用自己的文档测试解析效果。++我们将持续提供免费API服务,直至我们的服务器顶不住压力。++⚠️ 注意:不建议将 Free OXR API 用于线上环境,我们没有稳定性保证,也设置了排队机制,速率略有浮动++| Online Demo | https://free-oxr.somark.ai | https://free-oxr.somark.cn |+|-|-|-|+| API地址 | https://free-oxr.somark.ai/api/v1 | https://free-oxr.somark.cn/api/v1 |+| 对接文档 | [https://docs.somark.ai/api-reference](https://docs.somark.ai/api-reference) | https://docs.somark.cn/api-reference |++> somark.cn是somark.ai的镜像源地址,可以根据所在地区自行选择++OXR 系统的 文档解析 API 接口和 SoMark 官方的文档解析 API 接口兼容,所以你可以直接使用somark-py、somark-js这些SoMark官方文档解析 CLI 工具替换 **Base URL** 后直接使用。支持的接口和输出格式见 1.4。++```Bash+# using python+pip install somark+# or using js+npm install -g somark-js++somark --base-url https://free-oxr.somark.ai/api/v1 --api-key dummy \+ parse document.pdf --formats md,json --out ./parsed-output/+```++++### 1. 本地启动++```Plain Text+操作系统:Linux+GPU:NVIDIA(支持 BF16)+驱动:NVIDIA 驱动(兼容 CUDA 13.0)+Python:3.12(模型下载/源码启动)+起步显存:单卡 24GB(低并发试用)+推荐显存:单卡 ≥48GB(长文档/较高并发)+```++#### 1.1 下载代码和模型++| 模型 | 下载链接 | 精度 | 是否带版面分析小模型 |+|-|-|-|-|+| OXR-1.0 | [🤗 Hugging Face ](https://huggingface.co/SoMarkAI/OXR-1.0) <br/>[🤖 ModelScope](https://modelscope.cn/models/SoMark/OXR-1.0) | BF16 | 是,在layout_analysis文件夹中 |++先获取代码并准备模型下载环境:++```Bash+git clone https://github.com/SoMarkAI/OXR.git+cd OXR++# pip install -U huggingface_hub+hf download SoMarkAI/OXR-1.0 --local-dir ./models/OXR-1.0++# or using ModelScope+# pip install -U modelscope-hub+modelscope download SoMark/OXR-1.0 --local_dir ./models/OXR-1.0+```++#### 1.2 启动服务++##### 1.2.1 Docker 启动(推荐)++推荐使用docker配置服务,一次性启动所有服务。++```Bash+docker build -f docker/Dockerfile.allinone -t oxr-1.0 .+docker run --rm --gpus all --ipc=host \+ -p 127.0.0.1:8000:8000 \+ -v "$PWD/models/OXR-1.0:/models/oxr-model:ro" \+ oxr-1.0+```++等待启动日志显示服务就绪后,打开 http://localhost:8000/demo 或 http://localhost:8000/docs 。+首次启动可能较慢,默认启动等待上限为 900 秒。+更多高级参数和使用示例,可以前往 How to use OXR 了解。+++##### 1.2.2 源码启动++完成代码和模型下载后,分别启动以下三个服务。各服务使用独立的进程和虚拟环境,所有命令均在 OXR 仓库根目录执行。文档解析 API 服务依赖于 OXR 模型和 Layout Analysis 模型这两个服务,因此启动顺序上,需要先启动两个模型服务API。++**OXR 模型服务(端口 8080)**++OXR 支持 vLLM,但当前 vLLM 官方还未支持OXR模型推理,我们在Huggingface权重文件夹中提供了 out-of-tree 的 plugin 以及加载脚本,无需重新编译,可以在 vLLM 官方 docker 或 CLI 中直接用 plugin 启动。++```Bash+# pip install vllm==0.25.1 transformers==5.13.1++MODEL_PATH="$PWD/models/OXR-1.0" \+ bash services/oxr/start_vllm.sh \+ --gpu-memory-utilization 0.70 --max-num-seqs 16+```++**Layout Analysis 模型服务(端口 8081)**++Layout Analysis 模型权重包含在前面下载的 OXR 模型权重文件夹中。++```Bash+# pip install torch==2.11.0 torchvision==0.26.0 --index-url https://download.pytorch.org/whl/cu130+# pip install -r services/layout_analyze/requirements.txt++MODEL_PATH="$PWD/models/OXR-1.0/layout_analysis/last.pth" \+DFINE_DEVICE=cuda \+ python -m uvicorn dfine_la.api:app \+ --app-dir services/layout_analyze \+ --host 127.0.0.1 --port 8081 --workers 1+```++**文档解析 API(端口 8000)**++把项目中提供的`config.example.yaml`复制一份为`config.yaml`,将前面两个启动好的服务地址填写在`layout_analyze_model`和`oxr_model`的 url 参数中。++```Bash+# pip install -c docker/requirements.allinone.txt .++oxr serve --config config.yaml \+ --host 127.0.0.1 --port 8000 --workers 1+```++三个服务启动后,Demo 和解析接口的使用方式与 Docker 启动相同,见 1.3 和 1.4。++#### 1.3 打开可视化 Demo++打开 http://localhost:8000/demo ,上传 PDF 或图片,可查看原文件、Markdown 预览、源码、版面框与阅读顺序,并下载 Markdown。++Demo 使用临时文件缓存,默认有效期为 1 小时,处理期间会续期。缓存过期或被清理后无法继续访问,需及时下载结果。++#### 1.4 请求解析++OXR 的 API 与 SoMark API 兼容,部分特殊能力 OXR 不支持,但 SoMark 的生态完全支持部署的 OXR 服务。可以前往 [SoMark 官网](https://somark.ai) 参考:[API 接口文档](https://docs.somark.ai/api-reference)。++直接访问解析接口:++```Bash+curl --fail-with-body http://localhost:8000/v1/parse/sync \+ -F '[email protected]' \+ -F 'api_key=dummy' \+ -F 'output_formats=markdown' \+ -F 'output_formats=json'+```++SoMark 为解析业务封装了完善的 CLI & SDK,并提供了 python 和 js 两种语言的支持。本 OXR 项目兼容该 CLI 和 SDK 的文档解析接口,可以直接替换baseURL后使用。更多信息可以查阅该文档:https://docs.somark.ai/en/cli-sdk++```Bash+pip install somark++somark --base-url http://localhost:8000/v1 --api-key dummy \+ parse document.pdf --formats md,json --out ./parsed-output/+```++## 生态支持++SoMark 团队围绕文档解析工作开发了一系列生态工具,如果能够提供到帮助,请帮忙点一个 ⭐ Star。++| | 一句话简介 | 项目地址 |+|-|-|-|+| SoMarkDown | SoMark、OXR 官方的 Markdown 解析与渲染库 | https://github.com/SoMarkAI/SoMarkDown |+| SoMarkDownViewer | SoMarkDown 的实时编辑应用 | https://github.com/SoMarkAI/SoMarkDownViewer |+| SoPDF | 高性能、宽松开源许可的 PDF 处理库 | https://github.com/SoMarkAI/SoPDF |+| Docision | 面向文档场景的多模态Jev | https://github.com/SoMarkAI/docision |+| somark-py | 服务SoMark、OXR的官方Python SDK & CLI | [https://github.com/SoMarkAI/somark-py](https://github.com/SoMarkAI/somark-py) |+| somark-js | 服务SoMark、OXR的官方JS / TS SDK & CLI | https://github.com/SoMarkAI/somark-js |++---++<div align="center">+<img src="https://raw.githubusercontent.com/SoMarkAI/image_bed/main/OXR_README/assets/OXR_Star_on_GitHub.gif" width="800" />+</div>++## 引用++当前可引用 OXR-1.0 开源项目,技术报告发布后再补充论文引用。++```bibtex+@misc{somark2026oxr,+ author = {{SoMark}},+ title = {{OXR-1.0}},+ url = {https://github.com/SoMarkAI/OXR},+ note = {GitHub repository}+}+```++## License++OXR 采用 [OXR Open Source License](./LICENSE),基于 Apache 2.0 的自定义许可证,附带额外条款。++如果您需要更进一步的服务,可联系SoMark团队→[somark.ai](http://somark.ai)++## 社区++欢迎加入 OXR 社区,交流文档解析实践、反馈使用问题,获取最新动态。++- [Discord](https://discord.gg/msCPj2AtNN) — 交流 OXR 使用经验、讨论技术问题,分享你正在做的项目。+- [X / Twitter](https://x.com/somarkai) — 关注 OXR 版本发布与 SoMark 最新动态。+- [GitHub Issues](https://github.com/SoMarkAI/OXR/issues) — 提交问题、提出功能建议,跟进处理进展。+- **微信** — 扫描下方二维码,加入 OXR 微信交流群,与其他用户交流实践心得。-如果您需要更进一步的服务,可联系SoMark团队 → [somark.ai](https://somark.ai/)+<p>+ <img src="./assets/wechat-community.png" alt="OXR 微信交流群二维码" width="200" />+</p>diff --git a/assets/wechat-community.png b/assets/wechat-community.pngnew file mode 100644index 0000000..d1c3809Binary files /dev/null and b/assets/wechat-community.png differdiff --git a/docs/benchmark.md b/docs/benchmark.mdnew file mode 100644index 0000000..558a55f--- /dev/null+++ b/docs/benchmark.md@@ -0,0 +1,183 @@+# OXR/docs/benchmark.md++## 1. Overview++OXR-1.0 ranks first in the displayed comparison snapshots: **87.84 on olmOCR-bench, 97.18 on OmniDocBench, and 87.76 on DocParsingBench**. It also leads the 21-model speed comparison, reaching **557.77 native tokens/s** and **0.990373 pages/s**.++Accuracy snapshot: 5 October 2026. Rankings apply to the displayed models and recorded evaluation protocols.++## 2. Accuracy Benchmarks++Tables follow the model order in Figure 1. ↑ Higher is better; ↓ lower is better; NR means not reported. Overall scores retain their original definitions; equal scores share a rank.++++*Figure 1. Overall scores on olmOCR-bench, OmniDocBench, and DocParsingBench. Panels use separate, truncated axes.*++### 2.1 olmOCR-bench++Official macro score using olmocr 0.4.27: 8,413 rules, eight categories, and 1,403 pages.++*Table 1. olmOCR-bench overall and all eight component scores (%).*++| **Rank** | **Model** | **Overall ↑** | **ArXiv Math ↑** | **Baseline ↑** | **Headers / Footers ↑** | **Long Tiny Text ↑** | **Multi Column ↑** | **Old Scans ↑** | **Old Scans Math ↑** | **Tables ↑** |+| --- | --- | --- | --- | --- | --- | --- | --- | --- | --- | --- |+| **1** | **OXR-1.0** | **87.84** | **92.76** | **97.35** | **94.34** | **90.95** | **85.18** | **59.32** | **89.74** | **93.05** |+| 2 | Infinity-Parser2-Pro | 87.60 | 88.10 | 99.90 | 95.80 | 92.50 | 83.70 | 58.20 | 91.30 | 91.20 |+| 3 | Chandra-OCR-2 | 85.80 | 86.90 | 99.90 | 91.40 | 93.70 | 82.10 | 51.10 | 89.10 | 92.10 |+| 4 | dots.mocr | 83.90 | 85.90 | 99.70 | 94.00 | 81.60 | 85.30 | 48.20 | 85.50 | 90.70 |+| 5 | jina-ocr-v1 | 83.40 | 86.10 | 99.90 | 88.70 | 93.20 | 85.50 | 42.60 | 82.30 | 88.80 |+| 6 | Surya-OCR-2 | 83.30 | 88.30 | 99.70 | 92.50 | 93.70 | 82.40 | 41.80 | 81.40 | 86.60 |+| 7 | LightOnOCR-2-1B\* | 83.20 | 89.60 | 99.60 | 19.70 | 91.40 | 84.80 | 42.20 | 85.60 | 89.00 |+| 8 | Chandra | 83.10 | 82.20 | 99.90 | 90.80 | 92.30 | 81.20 | 50.40 | 80.30 | 88.00 |+| 9 | Infinity-Parser-7B | 82.50 | 84.40 | 99.80 | 88.70 | 86.40 | 84.20 | 47.90 | 83.80 | 85.00 |+| 10 | Falcon-OCR\* | 80.30 | 80.50 | 99.50 | 94.00 | 78.50 | 87.10 | 43.50 | 69.20 | 90.30 |+| 11 | Qianfan-OCR | 79.80 | 80.10 | 99.60 | 92.20 | 89.10 | 80.40 | 42.00 | 73.10 | 81.60 |+| 12 | dots.ocr | 79.10 | 82.10 | 99.50 | 94.10 | 81.20 | 82.40 | 40.90 | 64.20 | 88.30 |+| 13 | DeepSeek-OCR-2 | 76.30 | 82.00 | NR | NR | 90.70 | 79.00 | 33.80 | 72.00 | 77.40 |+| 14 | LightOnOCR-1B-1025\* | 76.10 | 81.40 | 99.60 | 35.50 | 88.70 | 80.00 | 35.20 | 71.60 | 76.40 |+| 15 | DeepSeek-OCR | 75.70 | 77.20 | 99.80 | 96.10 | 79.40 | 66.40 | 33.30 | 73.60 | 80.20 |+| 16 | MinerU2.5-2509-1.2B | 75.20 | 76.60 | 93.70 | 96.60 | 83.50 | 78.20 | 33.70 | 54.60 | 84.90 |+| 16 | GLM-OCR\* | 75.20 | 80.70 | 98.80 | 95.80 | 86.90 | 76.70 | 37.60 | 68.30 | 77.60 |++Peer-model scores are sourced from published papers, model cards, and the [olmOCR-bench leaderboard](https://huggingface.co/datasets/allenai/olmOCR-bench).++### 2.2 OmniDocBench++Overall and component results on 1,651 pages. Xiaomi-OCR-0 uses the authors’ released Mix-RL results; other peer-model scores are sourced from the [v1.6_full table in opendatalab/OmniDocBench’s README](https://github.com/opendatalab/OmniDocBench/blob/f133a71e9e91c3621c7ce8994200a7b394a06eb3/README.md#end-to-end-evaluation), at commit [f133a71e9e91c3621c7ce8994200a7b394a06eb3](https://github.com/opendatalab/OmniDocBench/commit/f133a71e9e91c3621c7ce8994200a7b394a06eb3).++*Table 2. OmniDocBench results. Edit distances: four decimals; percentage scores: two decimals.*++| **Rank** | **Model** | **Overall ↑** | **Text Edit ↓** | **Formula CDM ↑** | **Table TEDS ↑** | **Table TEDS-S ↑** | **Reading Order Edit ↓** |+| --- | --- | --- | --- | --- | --- | --- | --- |+| **1** | **OXR-1.0** | **97.18** | **0.0251** | **97.44** | **96.62** | **98.44** | **0.1214** |+| 2 | TeleOCR | 96.91 | 0.0267 | 96.59 | 96.82 | 98.18 | 0.1184 |+| 3 | Xiaomi-OCR-0 | 96.83 | 0.0313 | 98.50 | 95.11 | 97.19 | 0.1221 |+| 4 | OvisOCR2 | 96.47 | 0.0265 | 97.49 | 94.58 | 96.98 | 0.1120 |+| 5 | PaddleOCR-VL-1.6 | 96.34 | 0.0326 | 97.53 | 94.76 | 97.10 | 0.1278 |+| 6 | MinerU2.5-Pro | 95.75 | 0.0360 | 97.45 | 93.42 | 95.92 | 0.1200 |+| 7 | GLM-OCR | 95.22 | 0.0440 | 97.18 | 92.83 | 95.39 | 0.1330 |+| 8 | PaddleOCR-VL-1.5 | 94.93 | 0.0380 | 96.89 | 91.67 | 94.37 | 0.1300 |+| 9 | PaddleOCR-VL | 94.18 | 0.0400 | 95.91 | 90.65 | 93.74 | 0.1350 |+| 10 | Unlimited-OCR | 94.00 | 0.0394 | 95.72 | 90.21 | 93.36 | 0.1281 |+| 11 | Qianfan-OCR | 93.90 | 0.0400 | 95.08 | 90.53 | 93.31 | 0.1300 |+| 12 | Youtu-Parsing | 93.74 | 0.0440 | 93.63 | 92.02 | 95.00 | 0.1160 |+| 13 | Ovis2.6-30B-A3B | 93.70 | 0.0350 | 95.17 | 89.44 | 92.40 | 0.1350 |+| 14 | Logics-Parsing-v2 | 93.33 | 0.0410 | 95.65 | 88.42 | 91.98 | 0.1370 |+| 15 | ABot-OCR | 93.30 | 0.0370 | 94.86 | 88.69 | 91.87 | 0.1370 |+| 16 | FireRed-OCR | 93.26 | 0.0370 | 95.44 | 88.04 | 91.06 | 0.1310 |+| 17 | MinerU-2.5 | 93.04 | 0.0450 | 95.77 | 87.88 | 91.47 | 0.1300 |+| 18 | Gemini 3 Pro | 92.91 | 0.0640 | 95.99 | 89.15 | 92.96 | 0.1650 |+| 19 | Gemini 3 Flash | 92.62 | 0.0660 | 95.16 | 89.29 | 93.51 | 0.1720 |+| 20 | dots.ocr | 90.77 | 0.0480 | 89.95 | 87.18 | 90.58 | 0.1380 |+| 21 | OpenDoc-0.1B | 90.67 | 0.0490 | 93.02 | 83.88 | 87.45 | 0.1400 |+| 22 | DeepSeek-OCR-2 | 90.25 | 0.0500 | 91.84 | 83.89 | 87.75 | 0.1440 |+| 23 | HunyuanOCR | 89.95 | 0.0880 | 87.68 | 91.01 | 93.23 | 0.1710 |++### 2.3 DocParsingBench++OXR-1.0 ranks first in Overall, Text, Formula, and Table among the 17 compared systems.++*Table 3. DocParsingBench overall and component scores (0–100).*++| **Rank** | **Model** | **Overall ↑** | **Text ↑** | **Formula ↑** | **Table ↑** |+| --- | --- | --- | --- | --- | --- |+| **1** | **OXR-1.0** | **87.76** | **90.60** | **85.76** | **80.04** |+| 2 | PaddleOCR-VL-1.6 | 85.17 | 88.86 | 75.59 | 74.95 |+| 3 | jina-ocr-v1 | 84.46 | 89.05 | 78.08 | 75.03 |+| 4 | FireRed-OCR | 84.05 | 88.02 | 74.77 | 69.30 |+| 5 | TeleOCR | 83.13 | 86.42 | 76.19 | 76.77 |+| 6 | dots.mocr | 83.06 | 86.73 | 81.99 | 75.18 |+| 7 | MinerU2.5-Pro | 82.78 | 86.22 | 82.06 | 76.73 |+| 8 | Infinity-Parser2-Pro | 82.63 | 86.43 | 78.52 | 72.48 |+| 9 | OvisOCR2 | 82.26 | 85.76 | 73.48 | 74.20 |+| 10 | Chandra OCR 2 | 82.20 | 86.24 | 81.82 | 77.69 |+| 11 | Qianfan-OCR | 81.45 | 85.30 | 69.36 | 69.54 |+| 12 | ABot-OCR | 80.42 | 84.98 | 71.35 | 60.92 |+| 13 | GLM-OCR | 80.34 | 83.72 | 75.94 | 71.85 |+| 14 | Youtu-Parsing | 76.25 | 81.34 | 73.17 | 72.48 |+| 15 | HunyuanOCR 1.5 | 75.35 | 78.73 | 74.62 | 63.65 |+| 16 | LightOnOCR-2-1B | 71.88 | 76.44 | 73.80 | 66.34 |+| 17 | Surya-OCR-2 | 71.75 | 75.44 | 76.19 | 66.95 |++OXR scores are averaged over three evaluation rounds. Each round attempts 1,400 pages; the fixed 58-page exclusion set leaves 1,342 pages for scoring.++## 3. Inference Performance++### 3.1 Hardware and measurement protocol++All speed tests use one NVIDIA RTX PRO 6000 Blackwell GPU (96 GB), a 24-CPU quota, and 96 GiB RAM with no swap. OXR uses vLLM 0.25.1. Serial recognition excludes the model reading-order stage; the end-to-end pipeline includes it.++The speed workload is a frozen, stratified, approximately uniform 100-page subset of the 1,651-page OmniDocBench source set. The same 100 unique pages are reused across models. The speed subset is separate from the full accuracy evaluations.++Frozen 100-page workload: the JSON attachment lists the dataset and all 100 filenames used for speed testing.++[frozen-100-pages.json](./frozen-100-pages.json)++Serial decode tok/s excludes each request’s first token and input prefill time, and uses native decode time. Native tokens vary by tokenizer. End-to-end pages/s is 100 divided by total wall time.++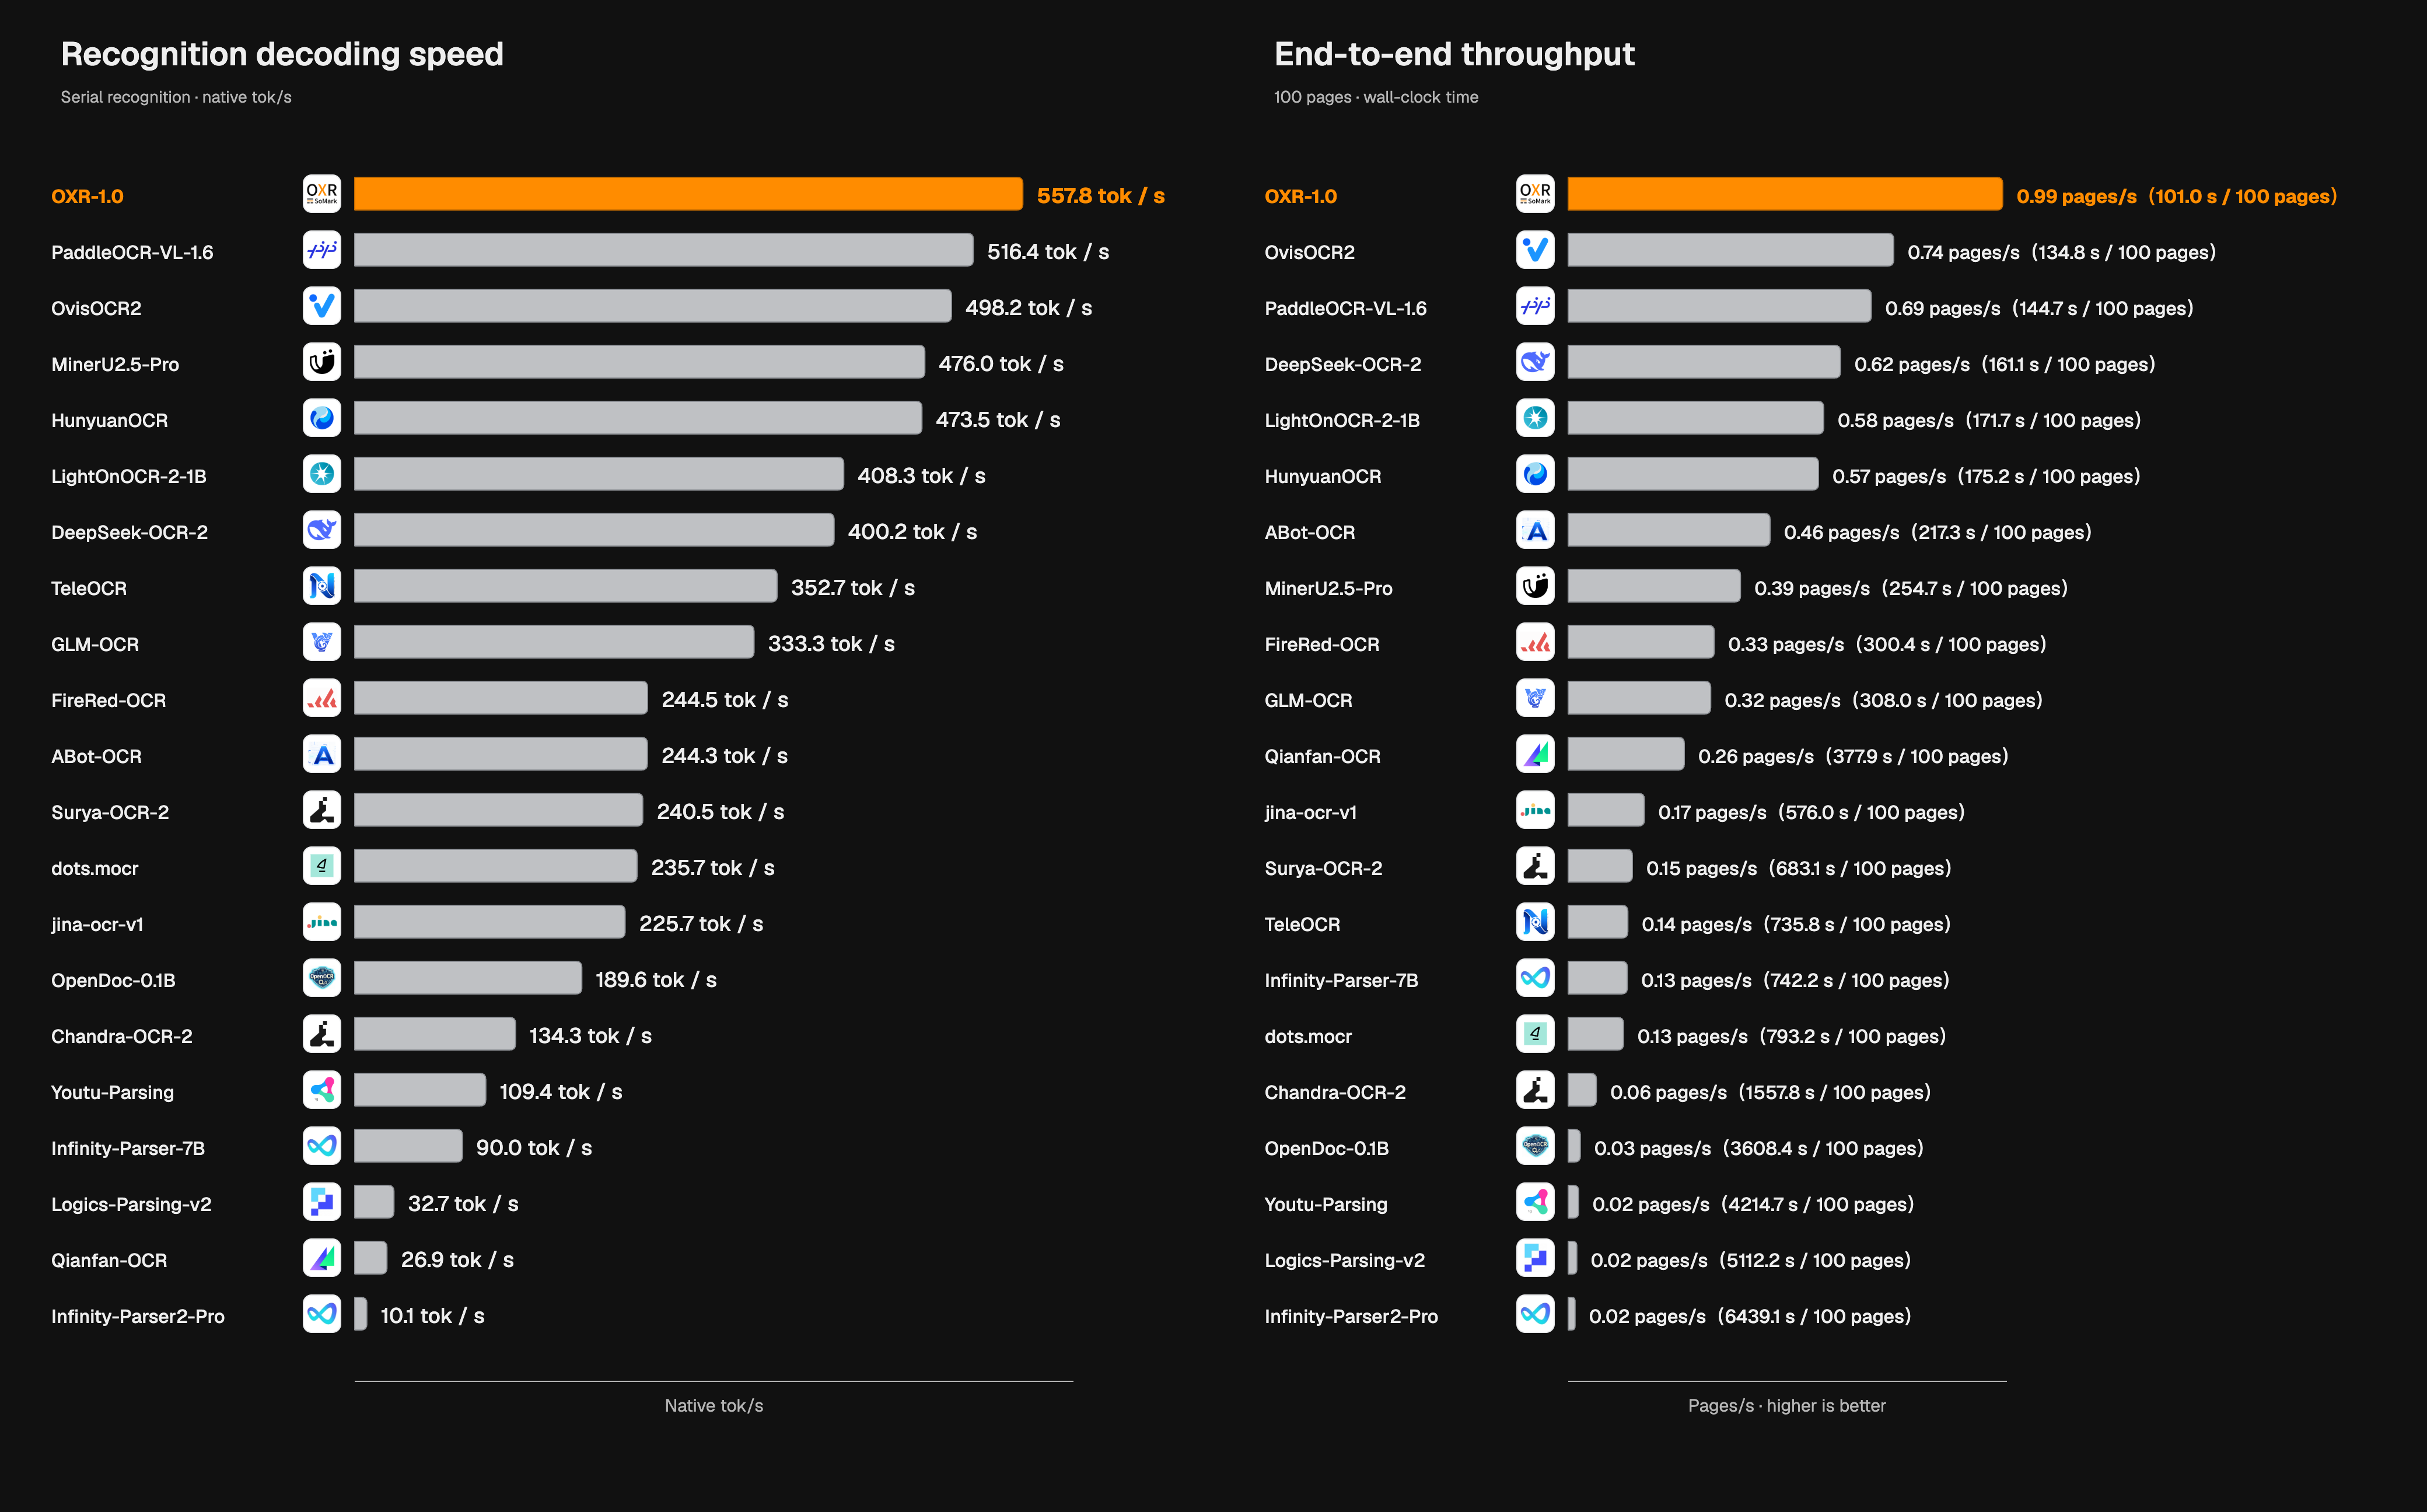++*Figure 2. Serial recognition decoding and end-to-end throughput; the same 21 models, ranked independently.*++### 3.2 Serial recognition decoding speed++OXR’s serial decode throughput is **8.0% higher** than the next-highest result, PaddleOCR-VL-1.6.++*Table 4. Serial recognition decoding speed, ranked from fastest to slowest; corresponds to Figure 2’s left panel.*++| **Rank** | **Model** | **Serial decode (tok/s) ↑** |+| --- | --- | --- |+| **1** | **OXR-1.0** | **557.77** |+| 2 | PaddleOCR-VL-1.6 | 516.39 |+| 3 | OvisOCR2 | 498.23 |+| 4 | MinerU2.5-Pro | 475.96 |+| 5 | HunyuanOCR | 473.50 |+| 6 | LightOnOCR-2-1B | 408.27 |+| 7 | DeepSeek-OCR-2 | 400.18 |+| 8 | TeleOCR | 352.66 |+| 9 | GLM-OCR | 333.33 |+| 10 | FireRed-OCR | 244.51 |+| 11 | ABot-OCR | 244.32 |+| 12 | Surya-OCR-2 | 240.51 |+| 13 | dots.mocr | 235.71 |+| 14 | jina-ocr-v1 | 225.73 |+| 15 | OpenDoc-0.1B | 189.58 |+| 16 | Chandra-OCR-2 | 134.25 |+| 17 | Youtu-Parsing | 109.40 |+| 18 | Infinity-Parser-7B | 89.98 |+| 19 | Logics-Parsing-v2 | 32.73 |+| 20 | Qianfan-OCR | 26.91 |+| 21 | Infinity-Parser2-Pro | 10.13 |++### 3.3 End-to-end page throughput++OXR averages **100.972 seconds per 100 pages** across two rounds, with **33.5% higher throughput** than the next-highest result, OvisOCR2.++*Table 5. End-to-end throughput and 100-page wall time, ranked from fastest to slowest; corresponds to Figure 2’s right panel.*++| **Rank** | **Model** | **Pages/s ↑** | **100 pages (s) ↓** |+| --- | --- | --- | --- |+| **1** | **OXR-1.0** | **0.990373** | **100.972** |+| 2 | OvisOCR2 | 0.741960 | 134.778 |+| 3 | PaddleOCR-VL-1.6 | 0.690952 | 144.728 |+| 4 | DeepSeek-OCR-2 | 0.620544 | 161.149 |+| 5 | LightOnOCR-2-1B | 0.582376 | 171.710 |+| 6 | HunyuanOCR | 0.570617 | 175.249 |+| 7 | ABot-OCR | 0.460113 | 217.338 |+| 8 | MinerU2.5-Pro | 0.392674 | 254.664 |+| 9 | FireRed-OCR | 0.332920 | 300.373 |+| 10 | GLM-OCR | 0.324711 | 307.966 |+| 11 | Qianfan-OCR | 0.264628 | 377.889 |+| 12 | jina-ocr-v1 | 0.173598 | 576.044 |+| 13 | Surya-OCR-2 | 0.146384 | 683.136 |+| 14 | TeleOCR | 0.135909 | 735.789 |+| 15 | Infinity-Parser-7B | 0.134736 | 742.192 |+| 16 | dots.mocr | 0.126064 | 793.250 |+| 17 | Chandra-OCR-2 | 0.064192 | 1557.821 |+| 18 | OpenDoc-0.1B | 0.027713 | 3608.370 |+| 19 | Youtu-Parsing | 0.023726 | 4214.749 |+| 20 | Logics-Parsing-v2 | 0.019561 | 5112.234 |+| 21 | Infinity-Parser2-Pro | 0.015530 | 6439.086 |++OXR repeats the same 100 unique pages twice. Its reported 100-page time is the mean of the two rounds (100.972 s); throughput is 200 completed page attempts divided by their combined wall time (201.944 s). These are 200 timed observations of the same 100 pages.diff --git a/docs/frozen-100-pages.json b/docs/frozen-100-pages.jsonnew file mode 100644index 0000000..c6a635f--- /dev/null+++ b/docs/frozen-100-pages.json@@ -0,0 +1,105 @@+{+ "dataset": "OpenDataLab/OmniDocBench",+ "files": [+ "images/PPT_B14_Claeys_Consistent Presentation of Images_v2_page_006.png",+ "images/PPT_Keuk Chan Narith_page_009.png",+ "images/PPT_LEP power point presentation-English-FINAL-10-31-07_page_006.png",+ "images/PPT_ch7_page_030.png",+ "images/PPT_ch7_page_034.png",+ "images/PPT_fundamental_theorem_of_calculus___page_005.png",+ "images/PPT_lay_linalg5_01_05_page_009.png",+ "images/book_en_国外数学教材-非数学专业教材-线性代数-Gilbert Strang—Linear Algebra and Its Applications 4e_0242.png",+ "images/book_en_搬书匠-3396-iPhone The Missing Manual 10th Edition-2017-英文版_page_126.png",+ "images/book_zh_CNASGL0092018_extracted_page_73.png",+ "images/book_zh_GB14536.11998_extracted_page_145.png",+ "images/book_zh_GB149361994_extracted_page_7.png",+ "images/color_textbook_zhonggaokao_小学_13.人教新起点英语(4-5年级)_人教新起点五年级英语下册_课本_人教新起点英语5B电子课本_page_043.png",+ "images/color_textbook_zhonggaokao_小学_13.人教新起点英语(4-5年级)_人教新起点四年级英语下册_课本_人教新起点英语4B电子课本_page_048.png",+ "images/color_textbook_zhonggaokao_小学_KET听说读写逐项突破_KET听说读写逐项突破之轻松搞定KET口语25分【10 褚连一】_第04讲第四课口语部分Part2详解下_第四课口语部分Part2详解下_page_001.png",+ "images/color_textbook_教材全解1+1二年级下册英语上海牛津版_page_081.png",+ "images/docstructbench_dianzishu_zhongwenzaixian-o.O-61521185.pdf_167.jpg",+ "images/docstructbench_dianzishu_zhongwenzaixian-o.O-61569294.pdf_128.jpg",+ "images/docstructbench_enbook-zlib-o.O-21882649.pdf_3.jpg",+ "images/docstructbench_llm-raw-scihub-o.O-hup.777.pdf_8.jpg",+ "images/docstructbench_llm-raw-scihub-o.O-j.apcata.2007.01.024.pdf_7.jpg",+ "images/docstructbench_llm-raw-scihub-o.O-s00396-003-0935-9.pdf_2.jpg",+ "images/eastmoney_5f75d8df19ab34c706ae823d8ed54f845b6a693e31c0fae19b16cdd94c32a636.pdf_3.jpg",+ "images/eastmoney_d08a4020e49029cf68b5dbf69e5ecaa40e969f918819c62579e5f4b1a357422f.pdf_3.jpg",+ "images/eastmoney_db7967d371df6e4fb5850f3583fcf255c2ed8ef153e11aa38e0bd020b65f13ac.pdf_1.jpg",+ "images/eastmoney_e480008a65ea31d8c1a5e86900788b67d07422f02dbc5296aedf9423e1a23b4e.pdf_6.jpg",+ "images/exam_paper_en-file-putnam-archive_1996_Solutions_1996s_page_001.png",+ "images/exam_paper_en-file-putnam-archive_2000_Solutions_2000s_page_002.png",+ "images/exam_paper_en-file-putnam-archive_2003_Solutions_2003s_page_008.png",+ "images/exam_paper_en-file-putnam-archive_2005_Solutions_2005s_page_006.png",+ "images/exam_paper_en-file-putnam-archive_2009_Solutions_2009s_page_003.png",+ "images/exam_paper_en-file-putnam-archive_2014_Solutions_2014s_page_003.png",+ "images/jiaocai_jiaocai_en_37.jpg",+ "images/jiaocai_jiaocai_en_932.jpg",+ "images/jiaocaineedrop_chem-436205.pdf_793.jpg",+ "images/jiaocaineedrop_chem-97961.pdf_128.jpg",+ "images/jiaocaineedrop_eng_gls.pdf_6.jpg",+ "images/jiaocaineedrop_geo-12644.pdf_353.jpg",+ "images/jiaocaineedrop_jiaocai_needrop_en_237.jpg",+ "images/jiaocaineedrop_jiaocai_needrop_en_2652.jpg",+ "images/jiaocaineedrop_jiaocai_needrop_en_3713.jpg",+ "images/jiaocaineedrop_jiaocai_needrop_en_453.jpg",+ "images/jiaocaineedrop_jiaocai_needrop_en_546.jpg",+ "images/jiaocaineedrop_unit2t03.pdf_63.jpg",+ "images/magazine_TheEconomist.2023.11.18_page_030.png",+ "images/newspaper_028a1dd5500fbd774e4d85df3c460c4d_1.jpg",+ "images/newspaper_2a6b4fa088699701a6fa9ccecfb5c25d_1.jpg",+ "images/newspaper_2de954934f60ac538c5bd5dc40833a61_1.jpg",+ "images/newspaper_35bdaa11dec104ccbdc9e19ac8527d21_1.jpg",+ "images/newspaper_4790b51e8fa793743699647c09a93ccb_1.jpg",+ "images/newspaper_5d4b8e73eacbc6ecac0d7b1396fd01d7_1.jpg",+ "images/newspaper_The Guardian UK_0801@magazinesclubnew_page_048.png",+ "images/newspaper_TheGuardianUS-2025-1-8@magazinesclubnew_page_041.png",+ "images/newspaper_baa51a22898f0d534a6c404ba8f12fb1_2.jpg",+ "images/newspaper_fe5ed29024932fad071afc53807b16ba_3.jpg",+ "images/notes_1ba14cb325bc448f7201b20502ecf2b5_12.jpg",+ "images/notes_1ba14cb325bc448f7201b20502ecf2b5_120.jpg",+ "images/notes_1ba14cb325bc448f7201b20502ecf2b5_14.jpg",+ "images/notes_1ba14cb325bc448f7201b20502ecf2b5_54.jpg",+ "images/notes_1ba14cb325bc448f7201b20502ecf2b5_79.jpg",+ "images/notes_f7f010b78016aeebd76e56d9283eb67f_112.jpg",+ "images/notes_f7f010b78016aeebd76e56d9283eb67f_23.jpg",+ "images/notes_f7f010b78016aeebd76e56d9283eb67f_7.jpg",+ "images/notes_f7f010b78016aeebd76e56d9283eb67f_95.jpg",+ "images/page-07088b2f-f9d6-4c38-9c97-d7f98bc3d556.png",+ "images/page-14cd673f-d86d-45a7-a13e-2b4e1d91c08f.png",+ "images/page-3ecc67a1-9b19-4fb9-b74d-acbb73db5c53.png",+ "images/page-3f872a77-3faf-47d6-8574-bd2e5806ff98.png",+ "images/page-47977c29-59ca-4534-9a00-becad3bfdaa4.png",+ "images/page-4b8f8a9d-e061-4207-a42e-ebf9b7090099.png",+ "images/page-8e2f7ce3-83c4-4977-b6dc-278394c4bd64.png",+ "images/page-942ac90d-4704-43f3-9286-719c7be9e655.png",+ "images/page-a70b2ec9-379a-4e83-9f64-852c343ec8cd.png",+ "images/page-b0bdb7a8-c7de-4e6c-9e9c-bf979f3a3227.png",+ "images/page-b21c7247-a843-4316-a44d-c3365077f077.png",+ "images/page-b527edec-3363-4d38-a390-2f3a307f2392.png",+ "images/page-bf3685a0-f0ea-46a7-bb99-1526da8f8077.png",+ "images/page-dad79c54-8125-4927-9988-ee1d2a139d7b.png",+ "images/page-ddb9d794-5230-4b43-b1ec-273b9e7ebc11.png",+ "images/page-e4053f20-e6e6-430e-83ef-db298a3199aa.png",+ "images/page-eff3dc3a-8d44-4c68-9c3a-55df4aaf1e36.png",+ "images/page-f3e750d8-8201-4a22-9419-9776798b7a32.png",+ "images/scihub_carcin%2Fbgh032.pdf_2.jpg",+ "images/scihub_ijop.12033.pdf_5.jpg",+ "images/scihub_jee%2Ftoaa103.pdf_2.jpg",+ "images/yanbaopptmerge_0dd24976bcc395ad595cf73b411d627e14c19ba0299bb3fa0d8108993d079545.pdf_8.jpg",+ "images/yanbaopptmerge_c75b0a56d8f1b31d04fbe97f776244f25f5238f6cada15fb4007f8bfb17bdf9f.pdf_1.jpg",+ "images/yanbaopptmerge_c894b375daca22d041c8a35946295d0a73d6589ad7c3d1d39d8664a2666372bf.pdf_10.jpg",+ "images/yanbaopptmerge_yanbaoPPT_1685.jpg",+ "images/yanbaopptmerge_yanbaoPPT_4115.jpg",+ "images/yanbaopptmerge_yanbaoPPT_4635.jpg",+ "images/yanbaor2_0ef01b835238626f3589faa671abdfb832f2b98987eadad53cb2e35699dcc039.pdf_13.jpg",+ "images/yanbaor2_1cb2b2a2c6e3a1157a6f2876205bbeaa4d3958d0482e9cdc88dd2c002ed1ffc1.pdf_61.jpg",+ "images/yanbaor2_965b491c51a8fcd511bcb12adcebca5836ab96fe8742a5d04d12669faec90531.pdf_2.jpg",+ "images/yanbaor2_bc193526614fd5857f7b5254e67bced76222cf3396b01e516303b92609a20075.pdf_14.jpg",+ "images/yanbaor2_bedda45af71c9703274cf8b2c62a772e6be615c355d2b255d9408b1b40b606de.pdf_3.jpg",+ "images/yanbaor2_ey-icl-harnessing-the-power-of-data.pdf_13.jpg",+ "images/yanbaor2_f832cad1f46c067198e9df95ae7b150213f16805037c1a5725e72245010d3e97.pdf_3.jpg",+ "images/yanbaor2_yanbaoPPT_2172.jpg",+ "images/yanbaor2_yanbaoPPT_6148.jpg"+ ]+}