
Open-Sora: Democratizing Efficient Video Production for All
Python
Update README.md
Yanjia01771664792a3
diff --git a/docs/zh_CN/README.md b/docs/zh_CN/README.mdindex 481c4b3..f1cbf49 100644--- a/docs/zh_CN/README.md+++ b/docs/zh_CN/README.md@@ -394,39 +394,37 @@ colossalai run --nproc_per_node 8 --hostfile hostfile scripts/train.py configs/o### VBench-i2v-See [here](eval/README.md) for more instructions.+请参阅 [c此处](/eval/README.md)了解更多说明。-## Contribution+## 贡献-Thanks goes to these wonderful contributors:+感谢以下出色的贡献者:<a href="https://github.com/hpcaitech/Open-Sora/graphs/contributors"><img src="https://contrib.rocks/image?repo=hpcaitech/Open-Sora" /></a>-If you wish to contribute to this project, please refer to the [Contribution Guideline](./CONTRIBUTING.md).+如果您希望为该项目做出贡献,请参阅[Contribution Guideline](./CONTRIBUTING.md)。-## Acknowledgement+## 致谢-Here we only list a few of the projects. For other works and datasets, please refer to our report.+这里我们仅列出了部分项目,其他研究成果及数据集请参考我们的报告。-* [ColossalAI](https://github.com/hpcaitech/ColossalAI): A powerful large model parallel acceleration and optimization- system.-* [DiT](https://github.com/facebookresearch/DiT): Scalable Diffusion Models with Transformers.-* [OpenDiT](https://github.com/NUS-HPC-AI-Lab/OpenDiT): An acceleration for DiT training. We adopt valuable acceleration- strategies for training progress from OpenDiT.-* [PixArt](https://github.com/PixArt-alpha/PixArt-alpha): An open-source DiT-based text-to-image model.-* [Latte](https://github.com/Vchitect/Latte): An attempt to efficiently train DiT for video.-* [StabilityAI VAE](https://huggingface.co/stabilityai/sd-vae-ft-mse-original): A powerful image VAE model.-* [CLIP](https://github.com/openai/CLIP): A powerful text-image embedding model.-* [T5](https://github.com/google-research/text-to-text-transfer-transformer): A powerful text encoder.-* [LLaVA](https://github.com/haotian-liu/LLaVA): A powerful image captioning model based on [Mistral-7B](https://huggingface.co/mistralai/Mistral-7B-v0.1) and [Yi-34B](https://huggingface.co/01-ai/Yi-34B).-* [PLLaVA](https://github.com/magic-research/PLLaVA): A powerful video captioning model.-* [MiraData](https://github.com/mira-space/MiraData): A large-scale video dataset with long durations and structured caption.+* [ColossalAI](https://github.com/hpcaitech/ColossalAI): 强大的大型模型并行加速与优化系统。+* [DiT](https://github.com/facebookresearch/DiT): 带有 Transformer 的可扩展扩散模型。+* [OpenDiT](https://github.com/NUS-HPC-AI-Lab/OpenDiT): DiT 训练的加速器。我们从 OpenDiT 中采用了有价值的训练进度加速策略。+* [PixArt](https://github.com/PixArt-alpha/PixArt-alpha): 一个基于 DiT 的开源文本转图像模型。+* [Latte](https://github.com/Vchitect/Latte): 尝试高效地训练视频的 DiT。+* [StabilityAI VAE](https://huggingface.co/stabilityai/sd-vae-ft-mse-original): 一个强大的图像 VAE 模型。+* [CLIP](https://github.com/openai/CLIP): 一个强大的文本图像嵌入模型。+* [T5](https://github.com/google-research/text-to-text-transfer-transformer): 强大的文本编码器。+* [LLaVA](https://github.com/haotian-liu/LLaVA): 基于[Mistral-7B](https://huggingface.co/mistralai/Mistral-7B-v0.1) 和 [Yi-34B](https://huggingface.co/01-ai/Yi-34B). 的强大图像字幕模型。+* [PLLaVA](https://github.com/magic-research/PLLaVA): 一个强大的视频字幕模型。+* [MiraData](https://github.com/mira-space/MiraData):具有长持续时间和结构化字幕的大规模视频数据集。-We are grateful for their exceptional work and generous contribution to open source.+我们感谢他们的出色工作和对开源的慷慨贡献。-## Citation+## 引用```bibtex@software{opensora,@@ -438,6 +436,6 @@ We are grateful for their exceptional work and generous contribution to open sou}```-## Star History+## Star增长[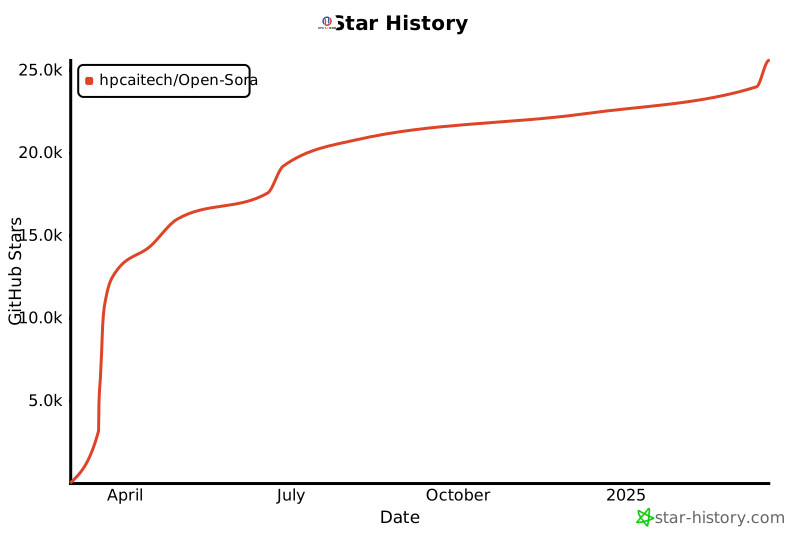](https://star-history.com/#hpcaitech/Open-Sora&Date)