
Open-Sora: Democratizing Efficient Video Production for All
Python
format (#69)
Zheng Zangwei (Alex Zheng)d851a855352b
diff --git a/.gitignore b/.gitignoreindex b5fc089..e99a5d9 100644--- a/.gitignore+++ b/.gitignore@@ -160,8 +160,14 @@ cython_debug/.idea/.vscode/+# macos+*.DS_Store+# misc filesdataset/runs/checkpoints/outputs/++# Secret files+hostfilediff --git a/README.md b/README.mdindex 3b632d0..6b642da 100644--- a/README.md+++ b/README.md@@ -1,149 +1,149 @@-<p align="center">- <img src="./assets/readme/icon_zw.png" width="250"/>-<p>--</p>-<div align="center">- <a href="https://github.com/hpcaitech/Open-Sora/stargazers"><img src="https://img.shields.io/github/stars/hpcaitech/Open-Sora?style=social"></a>- <a href="https://github.com/hpcaitech/public_assets/tree/main/colossalai/contact/slack"><img src="https://img.shields.io/badge/Slack-join-blueviolet?logo=slack&"></a>- <a href="https://raw.githubusercontent.com/hpcaitech/public_assets/main/colossalai/img/WeChat.png"><img src="https://img.shields.io/badge/微信-加入-green?logo=wechat&"></a>-</div>--## Open-Sora: Towards Open Reproduction of Sora--**Open-Sora** is an **open-source** initiative dedicated to **efficiently** reproducing OpenAI's Sora. Our project aims to cover **the full pipeline**, including video data preprocessing, training with acceleration, efficient inference and more. Operating on a limited budget, we prioritize the vibrant open-source community, providing access to text-to-image, image captioning, and language models. We hope to make a contribution to the community and make the project more accessible to everyone.--## 📰 News--* **[2024.03.18]** 🔥 We release **Open-Sora 1.0**, an open-source project to reproduce OpenAI Sora.-Open-Sora 1.0 supports a full pipeline of video data preprocessing, training with-<a href="https://github.com/hpcaitech/ColossalAI"><img src="assets/readme/colossal_ai.png" width="8%" ></a> acceleration,-inference, and more. Our provided checkpoint can produce 2s 512x512 videos.--## 🎥 Latest Demo--| **2s 512x512** | **2s 512x512** |-| ----------------------------------------------- | ----------------------------------------------- |-| <img src="assets/readme/sample_0.gif" width=""> | <img src="assets/readme/sample_0.gif" width=""> |--## 🔆 New Features/Updates--- 📍 Open-Sora-v1 is trained on xxx. We train the model in three stages. Model weights are available here. Training details can be found here.-- ✅ Support training acceleration including flash-attention, accelerated T5, mixed precision, gradient checkpointing, splitted VAE, sequence parallelism, etc. XXX times. See more discussions [here]().-- ✅ We provide video cutting and captioning tools for data preprocessing. Our data collection plan can be found [here]().-- ✅ We find VQ-VAE from [] has a low quality and thus adopt a better VAE from []. We also find patching in the time dimension deteriorates the quality. See more discussions [here]().-- ✅ We investigate different architectures including DiT, Latte, and our proposed STDiT. Our STDiT achieves a better trade-off between quality and speed. See more discussions [here]().-- ✅ Support clip and t5 text conditioning.-- ✅ By viewing images as one-frame videos, our project supports training DiT on both images and videos (e.g., ImageNet & UCF101).-- ✅ Support inference with official weights from [DiT](https://github.com/facebookresearch/DiT), [Latte](https://github.com/Vchitect/Latte), and [PixArt](https://pixart-alpha.github.io/).----### TODO list sorted by priority--- [ ] Complete the data processing pipeline (including dense optical flow, aesthetics scores, text-image similarity, deduplication, etc.). See [datasets.md]() for more information. **[WIP]**-- [ ] Training Video-VAE. **[WIP]**-- [ ] Support image and video conditioning.-- [ ] Evaluation pipeline.-- [ ] Incoporate a better scheduler, e.g., rectified flow in SD3.-- [ ] Support variable aspect ratios, resolutions, durations.-- [ ] Support SD3 when released.---## Contents--- [Open-Sora: Towards Open Reproduction of Sora](#open-sora-towards-open-reproduction-of-sora)-- [📰 News](#-news)-- [🎥 Latest Demo](#-latest-demo)-- [🔆 New Features/Updates](#-new-featuresupdates)- - [TODO list sorted by priority](#todo-list-sorted-by-priority)-- [Contents](#contents)-- [Installation](#installation)-- [Model Weights](#model-weights)-- [Inference](#inference)-- [Data Processing](#data-processing)- - [Split video into clips](#split-video-into-clips)- - [Generate video caption](#generate-video-caption)-- [Training](#training)-- [Acknowledgement](#acknowledgement)-- [Citation](#citation)-- [Star History](#star-history)-- [TODO](#todo)--## Installation--```bash-git clone https://github.com/hpcaitech/Open-Sora-cd Open-Sora-pip install xxx-```--After installation, to get fimilar with the project, you can check the [here]() for the project structure and how to use the config files.--## Model Weights--| Model | #Params | url |-| ---------- | ------- | --- |-| 16x256x256 | | |--## Inference--```bash-python scripts/inference.py configs/opensora/inference/16x256x256.py-```--## Data Processing--### Split video into clips--We provide code to split a long video into separate clips efficiently using `multiprocessing`. See `tools/data/scene_detect.py`.--### Generate video caption--## Training--## Acknowledgement--* [DiT](https://github.com/facebookresearch/DiT): Scalable Diffusion Models with Transformers.-* [OpenDiT](https://github.com/NUS-HPC-AI-Lab/OpenDiT): An acceleration for DiT training. OpenDiT's team provides valuable suggestions on acceleration of our training process.-* [PixArt](https://github.com/PixArt-alpha/PixArt-alpha): An open-source DiT-based text-to-image model.-* [Latte](https://github.com/Vchitect/Latte): An attempt to efficiently train DiT for video.-* [StabilityAI VAE](https://huggingface.co/stabilityai/sd-vae-ft-mse-original): A powerful image VAE model.-* [CLIP](https://github.com/openai/CLIP): A powerful text-image embedding model.-* [T5](https://github.com/google-research/text-to-text-transfer-transformer): The powerful text encoder.-* [LLaVA](https://github.com/haotian-liu/LLaVA): A powerful image captioning model based on [LLaMA](https://github.com/meta-llama/llama) and [Yi-34B](https://huggingface.co/01-ai/Yi-34B).-* [PySceneDetect](https://github.com/Breakthrough/PySceneDetect): A powerful tool to split video into clips.--We are grateful for their exceptional work and generous contribution to open source.--## Citation--```bibtex-@software{opensora,- author = {Zangwei Zheng and Xiangyu Peng and Shenggui Li and Yang You},- title = {Open-Sora: Towards Open Reproduction of Sora},- month = {March},- year = {2024},- url = {https://github.com/hpcaitech/Open-Sora}-}-```--Zangwei Zheng and Xiangyu Peng equally contributed to this work.--## Star History--[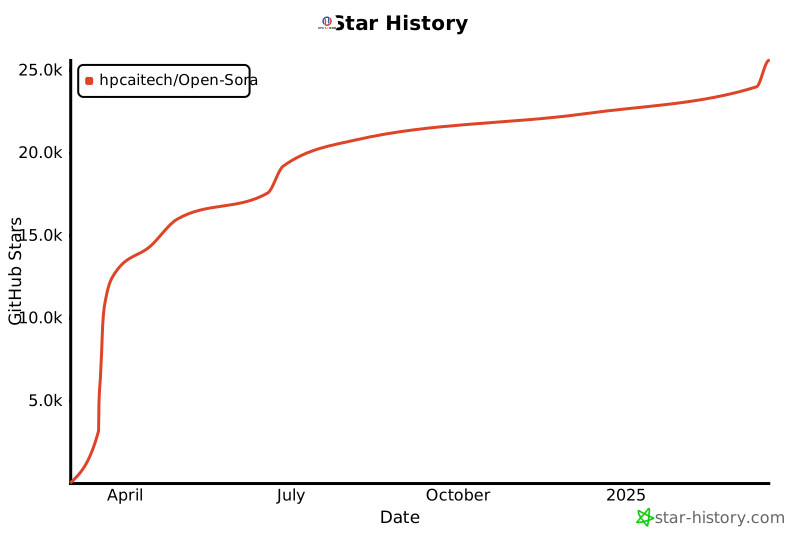](https://star-history.com/#hpcaitech/Open-Sora&Date)--## TODO--Modules for releasing:--* `configs`-* `opensora`-* `assets`-* `scripts`-* `tools`--packages for data processing--put all outputs under ./checkpoints/, including pretrained_models, checkpoints, samples+<p align="center">+ <img src="./assets/readme/icon_zw.png" width="250"/>+<p>++</p>+<div align="center">+ <a href="https://github.com/hpcaitech/Open-Sora/stargazers"><img src="https://img.shields.io/github/stars/hpcaitech/Open-Sora?style=social"></a>+ <a href="https://github.com/hpcaitech/public_assets/tree/main/colossalai/contact/slack"><img src="https://img.shields.io/badge/Slack-join-blueviolet?logo=slack&"></a>+ <a href="https://raw.githubusercontent.com/hpcaitech/public_assets/main/colossalai/img/WeChat.png"><img src="https://img.shields.io/badge/微信-加入-green?logo=wechat&"></a>+</div>++## Open-Sora: Towards Open Reproduction of Sora++**Open-Sora** is an **open-source** initiative dedicated to **efficiently** reproducing OpenAI's Sora. Our project aims to cover **the full pipeline**, including video data preprocessing, training with acceleration, efficient inference and more. Operating on a limited budget, we prioritize the vibrant open-source community, providing access to text-to-image, image captioning, and language models. We hope to make a contribution to the community and make the project more accessible to everyone.++## 📰 News++* **[2024.03.18]** 🔥 We release **Open-Sora 1.0**, an open-source project to reproduce OpenAI Sora.+Open-Sora 1.0 supports a full pipeline of video data preprocessing, training with+<a href="https://github.com/hpcaitech/ColossalAI"><img src="assets/readme/colossal_ai.png" width="8%" ></a> acceleration,+inference, and more. Our provided checkpoint can produce 2s 512x512 videos.++## 🎥 Latest Demo++| **2s 512x512** | **2s 512x512** |+| ----------------------------------------------- | ----------------------------------------------- |+| <img src="assets/readme/sample_0.gif" width=""> | <img src="assets/readme/sample_0.gif" width=""> |++## 🔆 New Features/Updates++- 📍 Open-Sora-v1 is trained on xxx. We train the model in three stages. Model weights are available here. Training details can be found here.+- ✅ Support training acceleration including flash-attention, accelerated T5, mixed precision, gradient checkpointing, splitted VAE, sequence parallelism, etc. XXX times. See more discussions [here]().+- ✅ We provide video cutting and captioning tools for data preprocessing. Our data collection plan can be found [here]().+- ✅ We find VQ-VAE from [] has a low quality and thus adopt a better VAE from []. We also find patching in the time dimension deteriorates the quality. See more discussions [here]().+- ✅ We investigate different architectures including DiT, Latte, and our proposed STDiT. Our STDiT achieves a better trade-off between quality and speed. See more discussions [here]().+- ✅ Support clip and t5 text conditioning.+- ✅ By viewing images as one-frame videos, our project supports training DiT on both images and videos (e.g., ImageNet & UCF101).+- ✅ Support inference with official weights from [DiT](https://github.com/facebookresearch/DiT), [Latte](https://github.com/Vchitect/Latte), and [PixArt](https://pixart-alpha.github.io/).++++### TODO list sorted by priority++- [ ] Complete the data processing pipeline (including dense optical flow, aesthetics scores, text-image similarity, deduplication, etc.). See [datasets.md]() for more information. **[WIP]**+- [ ] Training Video-VAE. **[WIP]**+- [ ] Support image and video conditioning.+- [ ] Evaluation pipeline.+- [ ] Incoporate a better scheduler, e.g., rectified flow in SD3.+- [ ] Support variable aspect ratios, resolutions, durations.+- [ ] Support SD3 when released.+++## Contents++- [Open-Sora: Towards Open Reproduction of Sora](#open-sora-towards-open-reproduction-of-sora)+- [📰 News](#-news)+- [🎥 Latest Demo](#-latest-demo)+- [🔆 New Features/Updates](#-new-featuresupdates)+ - [TODO list sorted by priority](#todo-list-sorted-by-priority)+- [Contents](#contents)+- [Installation](#installation)+- [Model Weights](#model-weights)+- [Inference](#inference)+- [Data Processing](#data-processing)+ - [Split video into clips](#split-video-into-clips)+ - [Generate video caption](#generate-video-caption)+- [Training](#training)+- [Acknowledgement](#acknowledgement)+- [Citation](#citation)+- [Star History](#star-history)+- [TODO](#todo)++## Installation++```bash+git clone https://github.com/hpcaitech/Open-Sora+cd Open-Sora+pip install xxx+```++After installation, to get fimilar with the project, you can check the [here]() for the project structure and how to use the config files.++## Model Weights++| Model | #Params | url |+| ---------- | ------- | --- |+| 16x256x256 | | |++## Inference++```bash+python scripts/inference.py configs/opensora/inference/16x256x256.py+```++## Data Processing++### Split video into clips++We provide code to split a long video into separate clips efficiently using `multiprocessing`. See `tools/data/scene_detect.py`.++### Generate video caption++## Training++## Acknowledgement++* [DiT](https://github.com/facebookresearch/DiT): Scalable Diffusion Models with Transformers.+* [OpenDiT](https://github.com/NUS-HPC-AI-Lab/OpenDiT): An acceleration for DiT training. OpenDiT's team provides valuable suggestions on acceleration of our training process.+* [PixArt](https://github.com/PixArt-alpha/PixArt-alpha): An open-source DiT-based text-to-image model.+* [Latte](https://github.com/Vchitect/Latte): An attempt to efficiently train DiT for video.+* [StabilityAI VAE](https://huggingface.co/stabilityai/sd-vae-ft-mse-original): A powerful image VAE model.+* [CLIP](https://github.com/openai/CLIP): A powerful text-image embedding model.+* [T5](https://github.com/google-research/text-to-text-transfer-transformer): The powerful text encoder.+* [LLaVA](https://github.com/haotian-liu/LLaVA): A powerful image captioning model based on [LLaMA](https://github.com/meta-llama/llama) and [Yi-34B](https://huggingface.co/01-ai/Yi-34B).+* [PySceneDetect](https://github.com/Breakthrough/PySceneDetect): A powerful tool to split video into clips.++We are grateful for their exceptional work and generous contribution to open source.++## Citation++```bibtex+@software{opensora,+ author = {Zangwei Zheng and Xiangyu Peng and Shenggui Li and Yang You},+ title = {Open-Sora: Towards Open Reproduction of Sora},+ month = {March},+ year = {2024},+ url = {https://github.com/hpcaitech/Open-Sora}+}+```++Zangwei Zheng and Xiangyu Peng equally contributed to this work.++## Star History++[](https://star-history.com/#hpcaitech/Open-Sora&Date)++## TODO++Modules for releasing:++* `configs`+* `opensora`+* `assets`+* `scripts`+* `tools`++packages for data processing++put all outputs under ./checkpoints/, including pretrained_models, checkpoints, samplesdiff --git a/assets/texts/t2i_samples.txt b/assets/texts/t2i_samples.txtindex 0fd1284..9b72952 100644--- a/assets/texts/t2i_samples.txt+++ b/assets/texts/t2i_samples.txt@@ -1,8 +1,8 @@-A small cactus with a happy face in the Sahara desert.-Bright scene, aerial view,ancient city, fantasy, gorgeous light, mirror reflection, high detail, wide angle lens.-Nature vs human nature, surreal, UHD, 8k, hyper details, rich colors, photograph.-Poster of a mechanical cat, techical Schematics viewed from front.-Luffy from ONEPIECE, handsome face, fantasy.-Real beautiful woman.-A alpaca made of colorful building blocks, cyberpunk.-artistic+A small cactus with a happy face in the Sahara desert.+Bright scene, aerial view,ancient city, fantasy, gorgeous light, mirror reflection, high detail, wide angle lens.+Nature vs human nature, surreal, UHD, 8k, hyper details, rich colors, photograph.+Poster of a mechanical cat, techical Schematics viewed from front.+Luffy from ONEPIECE, handsome face, fantasy.+Real beautiful woman.+A alpaca made of colorful building blocks, cyberpunk.+artisticdiff --git a/configs/dit/train/1x256x256.py b/configs/dit/train/1x256x256.pyindex ee9dde0..8cb8f9a 100644--- a/configs/dit/train/1x256x256.py+++ b/configs/dit/train/1x256x256.py@@ -47,5 +47,5 @@ ckpt_every = 1000load = Nonebatch_size = 128-lr = 1e-4 # according to DiT repo+lr = 1e-4 # according to DiT repograd_clip = 1.0diff --git a/configs/opensora/inference/16x256x256.py b/configs/opensora/inference/16x256x256.pyindex 1970635..8950f1a 100644--- a/configs/opensora/inference/16x256x256.py+++ b/configs/opensora/inference/16x256x256.py@@ -23,7 +23,7 @@ text_encoder = dict(scheduler = dict(# type="iddpm",# num_sampling_steps=250,- type = "dpm-solver",+ type="dpm-solver",num_sampling_steps=20,cfg_scale=7.0,)diff --git a/configs/pixart/inference/1x1024MS.py b/configs/pixart/inference/1x1024MS.pyindex 5795fbd..6392c9e 100644--- a/configs/pixart/inference/1x1024MS.py+++ b/configs/pixart/inference/1x1024MS.py@@ -22,7 +22,7 @@ text_encoder = dict(model_max_length=120,)scheduler = dict(- type = "dpm-solver",+ type="dpm-solver",num_sampling_steps=20,cfg_scale=7.0,)diff --git a/configs/pixart/inference/1x256x256.py b/configs/pixart/inference/1x256x256.pyindex fa89c56..5838c94 100644--- a/configs/pixart/inference/1x256x256.py+++ b/configs/pixart/inference/1x256x256.py@@ -15,7 +15,7 @@ vae = dict(# type="VideoAutoencoderKL",# from_pretrained="stabilityai/sd-vae-ft-ema",type="VideoAutoencoderKLTemporalDecoder",- from_pretrained="pretrained_models/vae_temporal_decoder"+ from_pretrained="pretrained_models/vae_temporal_decoder",)text_encoder = dict(type="t5",diff --git a/configs/pixart/inference/1x512x512.py b/configs/pixart/inference/1x512x512.pyindex 6e4daa0..f22d545 100644--- a/configs/pixart/inference/1x512x512.py+++ b/configs/pixart/inference/1x512x512.py@@ -21,7 +21,7 @@ text_encoder = dict(model_max_length=120,)scheduler = dict(- type = "dpm-solver",+ type="dpm-solver",num_sampling_steps=20,cfg_scale=7.0,)diff --git a/opensora/__init__.py b/opensora/__init__.pyindex 17a73fc..a3175b2 100644--- a/opensora/__init__.py+++ b/opensora/__init__.py@@ -1,4 +1,4 @@-from .acceleration import *-from .datasets import *-from .registry import *-from .models import *+from .acceleration import *+from .datasets import *+from .models import *+from .registry import *diff --git a/opensora/acceleration/communications.py b/opensora/acceleration/communications.pyindex b07d4c0..d0900d2 100644--- a/opensora/acceleration/communications.py+++ b/opensora/acceleration/communications.py@@ -12,13 +12,12 @@ def _all_to_all(scatter_dim: int,gather_dim: int,):- input_list = [- t.contiguous() for t in torch.tensor_split(input_, world_size, scatter_dim)- ]+ input_list = [t.contiguous() for t in torch.tensor_split(input_, world_size, scatter_dim)]output_list = [torch.empty_like(input_list[0]) for _ in range(world_size)]dist.all_to_all(output_list, input_list, group=group)return torch.cat(output_list, dim=gather_dim).contiguous()+class _AllToAll(torch.autograd.Function):"""All-to-all communication.@@ -35,20 +34,18 @@ class _AllToAll(torch.autograd.Function):ctx.scatter_dim = scatter_dimctx.gather_dim = gather_dimctx.world_size = dist.get_world_size(process_group)- output = _all_to_all(- input_, ctx.world_size, process_group, scatter_dim, gather_dim- )+ output = _all_to_all(input_, ctx.world_size, process_group, scatter_dim, gather_dim)return output@staticmethoddef backward(ctx, grad_output):grad_output = _all_to_all(- grad_output,- ctx.world_size,- ctx.process_group,- ctx.gather_dim,- ctx.scatter_dim,- )+ grad_output,+ ctx.world_size,+ ctx.process_group,+ ctx.gather_dim,+ ctx.scatter_dim,+ )return (grad_output,None,@@ -65,6 +62,7 @@ def all_to_all():return _AllToAll.apply(input_, process_group, scatter_dim, gather_dim)+def _gather(input_: torch.Tensor,world_size: int,@@ -76,10 +74,12 @@ def _gather(dist.gather(input_, gather_list, group=group, gather_dim=gather_dim)return gather_list+# ====================# Gather-Split# ====================+def _split(input_, pg: dist.ProcessGroup, dim=-1):# skip if only one rank involvedworld_size = dist.get_world_size(pg)@@ -104,7 +104,7 @@ def _gather(input_, pg: dist.ProcessGroup, dim=-1):# skip if only one rank involvedinput_ = input_.contiguous()world_size = dist.get_world_size(pg)- rank = dist.get_rank(pg)+ dist.get_rank(pg)if world_size == 1:return input_@@ -119,6 +119,7 @@ def _gather(input_, pg: dist.ProcessGroup, dim=-1):return output+class _GatherForwardSplitBackward(torch.autograd.Function):"""Gather the input from model parallel region and concatenate.@@ -130,7 +131,6 @@ class _GatherForwardSplitBackward(torch.autograd.Function):@staticmethoddef symbolic(graph, input_):-return _gather(input_)@staticmethod@@ -183,5 +183,6 @@ class _SplitForwardGatherBackward(torch.autograd.Function):def split_forward_gather_backward(input_, process_group, dim, grad_scale=1.0):return _SplitForwardGatherBackward.apply(input_, process_group, dim, grad_scale)+def gather_forward_split_backward(input_, process_group, dim, grad_scale=None):return _GatherForwardSplitBackward.apply(input_, process_group, dim, grad_scale)diff --git a/opensora/acceleration/parallel_states.py b/opensora/acceleration/parallel_states.pyindex a8d71e8..ff2893e 100644--- a/opensora/acceleration/parallel_states.py+++ b/opensora/acceleration/parallel_states.py@@ -2,14 +2,18 @@ import torch.distributed as dist_GLOBAL_PARALLEL_GROUPS = dict()+def set_data_parallel_group(group: dist.ProcessGroup):_GLOBAL_PARALLEL_GROUPS["data"] = group+def get_data_parallel_group():return _GLOBAL_PARALLEL_GROUPS.get("data", None)+def set_sequence_parallel_group(group: dist.ProcessGroup):_GLOBAL_PARALLEL_GROUPS["sequence"] = group+def get_sequence_parallel_group():- return _GLOBAL_PARALLEL_GROUPS.get("sequence", None)\ No newline at end of file+ return _GLOBAL_PARALLEL_GROUPS.get("sequence", None)diff --git a/opensora/acceleration/plugin.py b/opensora/acceleration/plugin.pyindex 7c9be5d..c657a95 100644--- a/opensora/acceleration/plugin.py+++ b/opensora/acceleration/plugin.py@@ -75,13 +75,11 @@ class ZeroSeqParallelPlugin(LowLevelZeroPlugin):pin_memory=False,num_workers=0,distributed_sampler_cls=None,- **kwargs+ **kwargs,):_kwargs = kwargs.copy()distributed_sampler_cls = distributed_sampler_cls or DistributedSampler- sampler = distributed_sampler_cls(- dataset, num_replicas=self.dp_size, rank=self.dp_rank, shuffle=shuffle- )+ sampler = distributed_sampler_cls(dataset, num_replicas=self.dp_size, rank=self.dp_rank, shuffle=shuffle)# Deterministic dataloaderdef seed_worker(worker_id):@@ -99,4 +97,4 @@ class ZeroSeqParallelPlugin(LowLevelZeroPlugin):pin_memory=pin_memory,num_workers=num_workers,**_kwargs,- )\ No newline at end of file+ )diff --git a/opensora/acceleration/shardformer/modeling/t5.py b/opensora/acceleration/shardformer/modeling/t5.pyindex d494c1c..9cfb808 100644--- a/opensora/acceleration/shardformer/modeling/t5.py+++ b/opensora/acceleration/shardformer/modeling/t5.py@@ -28,9 +28,10 @@ class T5LayerNorm(nn.Module):@staticmethoddef from_native_module(module, *args, **kwargs):- assert module.__class__.__name__ == "FusedRMSNorm", \- "Recovering T5LayerNorm requires the original layer to be apex's Fused RMS Norm." \+ assert module.__class__.__name__ == "FusedRMSNorm", (+ "Recovering T5LayerNorm requires the original layer to be apex's Fused RMS Norm.""Apex's fused norm is automatically used by Hugging Face Transformers https://github.com/huggingface/transformers/blob/main/src/transformers/models/t5/modeling_t5.py#L265C5-L265C48"+ )layer_norm = T5LayerNorm(module.normalized_shape, eps=module.eps)layer_norm.weight.data.copy_(module.weight.data)diff --git a/opensora/acceleration/shardformer/policy/t5_encoder.py b/opensora/acceleration/shardformer/policy/t5_encoder.pyindex e7ce3ac..85c994e 100644--- a/opensora/acceleration/shardformer/policy/t5_encoder.py+++ b/opensora/acceleration/shardformer/policy/t5_encoder.py@@ -1,12 +1,9 @@from colossalai.shardformer.modeling.jit import get_jit_fused_dropout_add_func-from colossalai.shardformer.modeling.t5 import (- get_jit_fused_T5_layer_ff_forward,- get_T5_layer_self_attention_forward,-)+from colossalai.shardformer.modeling.t5 import get_jit_fused_T5_layer_ff_forward, get_T5_layer_self_attention_forwardfrom colossalai.shardformer.policies.base_policy import Policy, SubModuleReplacementDescription+class T5EncoderPolicy(Policy):-def config_sanity_check(self):assert not self.shard_config.enable_tensor_parallelismassert not self.shard_config.enable_flash_attention@@ -15,17 +12,12 @@ class T5EncoderPolicy(Policy):return self.modeldef module_policy(self):- from transformers.models.t5.modeling_t5 import (- T5LayerFF,- T5LayerSelfAttention,- T5Stack,- )+ from transformers.models.t5.modeling_t5 import T5LayerFF, T5LayerSelfAttention, T5Stackpolicy = {}# check whether apex is installedtry:- from apex.normalization import FusedRMSNormfrom opensora.acceleration.shardformer.modeling.t5 import T5LayerNorm# recover hf from fused rms norm to T5 norm which is faster@@ -38,18 +30,12 @@ class T5EncoderPolicy(Policy):target_key=T5LayerFF,)self.append_or_create_submodule_replacement(- description=SubModuleReplacementDescription(- suffix="layer_norm",- target_module=T5LayerNorm- ),+ description=SubModuleReplacementDescription(suffix="layer_norm", target_module=T5LayerNorm),policy=policy,target_key=T5LayerSelfAttention,)self.append_or_create_submodule_replacement(- description=SubModuleReplacementDescription(- suffix="final_layer_norm",- target_module=T5LayerNorm- ),+ description=SubModuleReplacementDescription(suffix="final_layer_norm", target_module=T5LayerNorm),policy=policy,target_key=T5Stack,)diff --git a/opensora/datasets/utils.py b/opensora/datasets/utils.pyindex 00f8fe3..cd268ae 100644--- a/opensora/datasets/utils.py+++ b/opensora/datasets/utils.py@@ -117,6 +117,7 @@ def prepare_dataloader(**_kwargs,)+def center_crop_arr(pil_image, image_size):"""Center cropping implementation from ADM.diff --git a/opensora/models/__init__.py b/opensora/models/__init__.pyindex 2aa793a..6025349 100644--- a/opensora/models/__init__.py+++ b/opensora/models/__init__.py@@ -1,6 +1,6 @@-from .dit import *-from .latte import *-from .stdit import *-from .pixart import *-from .text_encoder import *-from .vae import *+from .dit import *+from .latte import *+from .pixart import *+from .stdit import *+from .text_encoder import *+from .vae import *diff --git a/opensora/models/dit/__init__.py b/opensora/models/dit/__init__.pyindex 2019831..94548a3 100644--- a/opensora/models/dit/__init__.py+++ b/opensora/models/dit/__init__.py@@ -1 +1 @@-from .dit import DiT, DiT_XL_2, DiT_XL_2x2+from .dit import DiT, DiT_XL_2, DiT_XL_2x2diff --git a/opensora/models/dit/dit.py b/opensora/models/dit/dit.pyindex 106f660..a23dd7b 100644--- a/opensora/models/dit/dit.py+++ b/opensora/models/dit/dit.py@@ -16,6 +16,7 @@ import torch.utils.checkpointfrom einops import rearrangefrom timm.models.vision_transformer import Mlp+from opensora.acceleration.checkpoint import auto_grad_checkpointfrom opensora.models.layers.blocks import (Attention,CaptionEmbedder,@@ -31,7 +32,6 @@ from opensora.models.layers.blocks import ()from opensora.registry import MODELSfrom opensora.utils.ckpt_utils import load_checkpoint-from opensora.acceleration.checkpoint import auto_grad_checkpointclass DiTBlock(nn.Module):@@ -209,7 +209,7 @@ class DiT(nn.Module):# blocksfor _, block in enumerate(self.blocks):c = condition- x = auto_grad_checkpoint(block, x, c) # (B, N, D)+ x = auto_grad_checkpoint(block, x, c) # (B, N, D)# final processx = self.final_layer(x, condition) # (B, N, num_patches * out_channels)diff --git a/opensora/models/latte/__init__.py b/opensora/models/latte/__init__.pyindex 3115f47..f9d918a 100644--- a/opensora/models/latte/__init__.py+++ b/opensora/models/latte/__init__.py@@ -1 +1 @@-from .latte import Latte, Latte_XL_2, Latte_XL_2x2+from .latte import Latte, Latte_XL_2, Latte_XL_2x2diff --git a/opensora/models/latte/latte.py b/opensora/models/latte/latte.pyindex 11259de..005cbac 100644--- a/opensora/models/latte/latte.py+++ b/opensora/models/latte/latte.py@@ -11,10 +11,10 @@import torchfrom einops import rearrange, repeat+from opensora.acceleration.checkpoint import auto_grad_checkpointfrom opensora.models.dit import DiTfrom opensora.registry import MODELSfrom opensora.utils.ckpt_utils import load_checkpoint-from opensora.acceleration.checkpoint import auto_grad_checkpoint@MODELS.register_module()@@ -56,7 +56,7 @@ class Latte(DiT):if i == 1:x = x + self.pos_embed_temporal- x = auto_grad_checkpoint(block, x, c) # (B, N, D)+ x = auto_grad_checkpoint(block, x, c) # (B, N, D)if i % 2 == 0:x = rearrange(x, "(b t) s d -> b (t s) d", t=self.num_temporal, s=self.num_spatial)diff --git a/opensora/models/layers/blocks.py b/opensora/models/layers/blocks.pyindex f06d696..8a91a41 100644--- a/opensora/models/layers/blocks.py+++ b/opensora/models/layers/blocks.py@@ -19,10 +19,9 @@ import torch.nn.functional as Fimport torch.utils.checkpointimport xformers.opsfrom einops import rearrange-from flash_attn import flash_attn_varlen_funcfrom timm.models.vision_transformer import Mlp-from opensora.acceleration.communications import all_to_all, split_forward_gather_backward+from opensora.acceleration.communications import all_to_allfrom opensora.acceleration.parallel_states import get_sequence_parallel_groupapprox_gelu = lambda: nn.GELU(approximate="tanh")@@ -179,7 +178,6 @@ class Attention(nn.Module):class SeqParallelAttention(Attention):-def __init__(self,dim: int,@@ -293,7 +291,6 @@ class MultiHeadCrossAttention(nn.Module):class SeqParallelMultiHeadCrossAttention(MultiHeadCrossAttention):-def __init__(self,d_model,diff --git a/opensora/models/pixart/__init__.py b/opensora/models/pixart/__init__.pyindex 622ad39..cf83202 100644--- a/opensora/models/pixart/__init__.py+++ b/opensora/models/pixart/__init__.py@@ -1 +1 @@-from .pixart import PixArt, PixArt_XL_2+from .pixart import PixArt, PixArt_XL_2diff --git a/opensora/models/pixart/pixart.py b/opensora/models/pixart/pixart.pyindex daad7dc..32785ff 100644--- a/opensora/models/pixart/pixart.py+++ b/opensora/models/pixart/pixart.py@@ -16,9 +16,7 @@ from timm.models.layers import DropPathfrom timm.models.vision_transformer import Mlp# from .builder import MODELS-from torch.utils.checkpoint import checkpointfrom opensora.acceleration.checkpoint import auto_grad_checkpoint-from opensora.models.layers.blocks import (Attention,CaptionEmbedder,diff --git a/opensora/models/stdit/__init__.py b/opensora/models/stdit/__init__.pyindex 3b089af..5ca2cc9 100644--- a/opensora/models/stdit/__init__.py+++ b/opensora/models/stdit/__init__.py@@ -1 +1 @@-from .stdit import STDiT+from .stdit import STDiTdiff --git a/opensora/models/stdit/stdit.py b/opensora/models/stdit/stdit.pyindex c8a2e95..e9dcf15 100644--- a/opensora/models/stdit/stdit.py+++ b/opensora/models/stdit/stdit.py@@ -1,4 +1,3 @@-import numpy as npimport torchimport torch.distributed as dist@@ -42,7 +41,6 @@ class STDiTBlock(nn.Module):enable_layernorm_kernel=False,enable_sequence_parallelism=False,):-super().__init__()self.hidden_size = hidden_sizeself.enable_flashattn = enable_flashattndiff --git a/opensora/models/text_encoder/__init__.py b/opensora/models/text_encoder/__init__.pyindex fa494a2..9fc6a99 100644--- a/opensora/models/text_encoder/__init__.py+++ b/opensora/models/text_encoder/__init__.py@@ -1,3 +1,3 @@-from .t5 import T5Encoder-from .classes import ClassEncoder-from .clip import ClipEncoder+from .classes import ClassEncoder+from .clip import ClipEncoder+from .t5 import T5Encoderdiff --git a/opensora/models/vae/__init__.py b/opensora/models/vae/__init__.pyindex 04a09c9..63510b0 100644--- a/opensora/models/vae/__init__.py+++ b/opensora/models/vae/__init__.py@@ -1 +1 @@-from .vae import VideoAutoencoderKL, VideoAutoencoderKLTemporalDecoder+from .vae import VideoAutoencoderKL, VideoAutoencoderKLTemporalDecoderdiff --git a/opensora/registry.py b/opensora/registry.pyindex af1bbc6..7797d36 100644--- a/opensora/registry.py+++ b/opensora/registry.py@@ -1,39 +1,39 @@-from copy import deepcopy--import torch.nn as nn-from mmengine.registry import Registry---def build_module(module, builder, **kwargs):- """Build module from config or return the module itself.-- Args:- module (Union[dict, nn.Module]): The module to build.- builder (Registry): The registry to build module.- *args, **kwargs: Arguments passed to build function.-- Returns:- Any: The built module.- """- if isinstance(module, dict):- cfg = deepcopy(module)- for k, v in kwargs.items():- cfg[k] = v- return builder.build(cfg)- elif isinstance(module, nn.Module):- return module- elif module is None:- return None- else:- raise TypeError(f"Only support dict and nn.Module, but got {type(module)}.")---MODELS = Registry(- "model",- locations=["opensora.models"],-)--SCHEDULERS = Registry(- "scheduler",- locations=["opensora.schedulers"],-)+from copy import deepcopy++import torch.nn as nn+from mmengine.registry import Registry+++def build_module(module, builder, **kwargs):+ """Build module from config or return the module itself.++ Args:+ module (Union[dict, nn.Module]): The module to build.+ builder (Registry): The registry to build module.+ *args, **kwargs: Arguments passed to build function.++ Returns:+ Any: The built module.+ """+ if isinstance(module, dict):+ cfg = deepcopy(module)+ for k, v in kwargs.items():+ cfg[k] = v+ return builder.build(cfg)+ elif isinstance(module, nn.Module):+ return module+ elif module is None:+ return None+ else:+ raise TypeError(f"Only support dict and nn.Module, but got {type(module)}.")+++MODELS = Registry(+ "model",+ locations=["opensora.models"],+)++SCHEDULERS = Registry(+ "scheduler",+ locations=["opensora.schedulers"],+)diff --git a/opensora/schedulers/__init__.py b/opensora/schedulers/__init__.pyindex f64aa25..97ea76f 100644--- a/opensora/schedulers/__init__.py+++ b/opensora/schedulers/__init__.py@@ -1,2 +1,2 @@-from .iddpm import IDDPM-from .dpms import DPMS+from .dpms import DPMS+from .iddpm import IDDPMdiff --git a/opensora/schedulers/dpms/dpm_solver.py b/opensora/schedulers/dpms/dpm_solver.pyindex d887398..37a9399 100644--- a/opensora/schedulers/dpms/dpm_solver.py+++ b/opensora/schedulers/dpms/dpm_solver.py@@ -700,7 +700,7 @@ class DPM_Solver:x_t: A pytorch tensor. The approximated solution at time `t`."""ns = self.noise_schedule- dims = x.dim()+ x.dim()lambda_s, lambda_t = ns.marginal_lambda(s), ns.marginal_lambda(t)h = lambda_t - lambda_slog_alpha_s, log_alpha_t = ns.marginal_log_mean_coeff(s), ns.marginal_log_mean_coeff(t)diff --git a/opensora/utils/misc.py b/opensora/utils/misc.pyindex 056b6ae..9d89c10 100644--- a/opensora/utils/misc.py+++ b/opensora/utils/misc.py@@ -1,339 +1,339 @@-import collections-import importlib-import logging-import os-import time-from collections import OrderedDict-from collections.abc import Sequence-from itertools import repeat--import numpy as np-import torch-import torch.distributed as dist---def print_rank(var_name, var_value, rank=0):- if dist.get_rank() == rank:- print(f"[Rank {rank}] {var_name}: {var_value}")---def print_0(*args, **kwargs):- if dist.get_rank() == 0:- print(*args, **kwargs)---def requires_grad(model: torch.nn.Module, flag: bool = True) -> None:- """- Set requires_grad flag for all parameters in a model.- """- for p in model.parameters():- p.requires_grad = flag---def format_numel_str(numel: int) -> str:- B = 1024**3- M = 1024**2- K = 1024- if numel >= B:- return f"{numel / B:.2f} B"- elif numel >= M:- return f"{numel / M:.2f} M"- elif numel >= K:- return f"{numel / K:.2f} K"- else:- return f"{numel}"---def all_reduce_mean(tensor: torch.Tensor) -> torch.Tensor:- dist.all_reduce(tensor=tensor, op=dist.ReduceOp.SUM)- tensor.div_(dist.get_world_size())- return tensor---def get_model_numel(model: torch.nn.Module) -> (int, int):- num_params = 0- num_params_trainable = 0- for p in model.parameters():- num_params += p.numel()- if p.requires_grad:- num_params_trainable += p.numel()- return num_params, num_params_trainable---def try_import(name):- """Try to import a module.-- Args:- name (str): Specifies what module to import in absolute or relative- terms (e.g. either pkg.mod or ..mod).- Returns:- ModuleType or None: If importing successfully, returns the imported- module, otherwise returns None.- """- try:- return importlib.import_module(name)- except ImportError:- return None---def transpose(x):- """- transpose a list of list- Args:- x (list[list]):- """- ret = list(map(list, zip(*x)))- return ret---def get_timestamp():- timestamp = time.strftime("%Y%m%d-%H%M%S", time.localtime(time.time()))- return timestamp---def format_time(seconds):- days = int(seconds / 3600 / 24)- seconds = seconds - days * 3600 * 24- hours = int(seconds / 3600)- seconds = seconds - hours * 3600- minutes = int(seconds / 60)- seconds = seconds - minutes * 60- secondsf = int(seconds)- seconds = seconds - secondsf- millis = int(seconds * 1000)-- f = ""- i = 1- if days > 0:- f += str(days) + "D"- i += 1- if hours > 0 and i <= 2:- f += str(hours) + "h"- i += 1- if minutes > 0 and i <= 2:- f += str(minutes) + "m"- i += 1- if secondsf > 0 and i <= 2:- f += str(secondsf) + "s"- i += 1- if millis > 0 and i <= 2:- f += str(millis) + "ms"- i += 1- if f == "":- f = "0ms"- return f---def to_tensor(data):- """Convert objects of various python types to :obj:`torch.Tensor`.-- Supported types are: :class:`numpy.ndarray`, :class:`torch.Tensor`,- :class:`Sequence`, :class:`int` and :class:`float`.-- Args:- data (torch.Tensor | numpy.ndarray | Sequence | int | float): Data to- be converted.- """-- if isinstance(data, torch.Tensor):- return data- elif isinstance(data, np.ndarray):- return torch.from_numpy(data)- elif isinstance(data, Sequence) and not isinstance(data, str):- return torch.tensor(data)- elif isinstance(data, int):- return torch.LongTensor([data])- elif isinstance(data, float):- return torch.FloatTensor([data])- else:- raise TypeError(f"type {type(data)} cannot be converted to tensor.")---def to_ndarray(data):- if isinstance(data, torch.Tensor):- return data.numpy()- elif isinstance(data, np.ndarray):- return data- elif isinstance(data, Sequence):- return np.array(data)- elif isinstance(data, int):- return np.ndarray([data], dtype=int)- elif isinstance(data, float):- return np.array([data], dtype=float)- else:- raise TypeError(f"type {type(data)} cannot be converted to ndarray.")---def to_torch_dtype(dtype):- if isinstance(dtype, torch.dtype):- return dtype- elif isinstance(dtype, str):- dtype_mapping = {- "float64": torch.float64,- "float32": torch.float32,- "float16": torch.float16,- "fp32": torch.float32,- "fp16": torch.float16,- "half": torch.float16,- "bf16": torch.bfloat16,- }- if dtype not in dtype_mapping:- raise ValueError- dtype = dtype_mapping[dtype]- return dtype- else:- raise ValueError---def count_params(model):- return sum(p.numel() for p in model.parameters() if p.requires_grad)---def _ntuple(n):- def parse(x):- if isinstance(x, collections.abc.Iterable) and not isinstance(x, str):- return x- return tuple(repeat(x, n))-- return parse---to_1tuple = _ntuple(1)-to_2tuple = _ntuple(2)-to_3tuple = _ntuple(3)-to_4tuple = _ntuple(4)-to_ntuple = _ntuple---def convert_SyncBN_to_BN2d(model_cfg):- for k in model_cfg:- v = model_cfg[k]- if k == "norm_cfg" and v["type"] == "SyncBN":- v["type"] = "BN2d"- elif isinstance(v, dict):- convert_SyncBN_to_BN2d(v)---def get_topk(x, dim=4, k=5):- x = to_tensor(x)- inds = x[..., dim].topk(k)[1]- return x[inds]---def param_sigmoid(x, alpha):- ret = 1 / (1 + (-alpha * x).exp())- return ret---def inverse_param_sigmoid(x, alpha, eps=1e-5):- x = x.clamp(min=0, max=1)- x1 = x.clamp(min=eps)- x2 = (1 - x).clamp(min=eps)- return torch.log(x1 / x2) / alpha---def inverse_sigmoid(x, eps=1e-5):- """Inverse function of sigmoid.-- Args:- x (Tensor): The tensor to do the- inverse.- eps (float): EPS avoid numerical- overflow. Defaults 1e-5.- Returns:- Tensor: The x has passed the inverse- function of sigmoid, has same- shape with input.- """- x = x.clamp(min=0, max=1)- x1 = x.clamp(min=eps)- x2 = (1 - x).clamp(min=eps)- return torch.log(x1 / x2)---def count_columns(df, columns):- cnt_dict = OrderedDict()- num_samples = len(df)-- for col in columns:- d_i = df[col].value_counts().to_dict()- for k in d_i:- d_i[k] = (d_i[k], d_i[k] / num_samples)- cnt_dict[col] = d_i-- return cnt_dict---def build_logger(work_dir, cfgname):- log_file = cfgname + ".log"- log_path = os.path.join(work_dir, log_file)-- logger = logging.getLogger(cfgname)- logger.setLevel(logging.INFO)- # formatter = logging.Formatter('%(asctime)s %(levelname)s %(message)s')- formatter = logging.Formatter("%(asctime)s: %(message)s", datefmt="%Y-%m-%d %H:%M:%S")-- handler1 = logging.FileHandler(log_path)- handler1.setFormatter(formatter)-- handler2 = logging.StreamHandler()- handler2.setFormatter(formatter)-- logger.addHandler(handler1)- logger.addHandler(handler2)- logger.propagate = False-- return logger---timings = {}-from contextlib import contextmanager---@contextmanager-def torch_timer(prefix):- import time-- import torch-- torch.cuda.synchronize()- start = time.time()- try:- yield- finally:- torch.cuda.synchronize()- t_diff = (time.time() - start) * 1000- if prefix not in timings:- timings[prefix] = []-- timings[prefix].append(t_diff)-- num_ignored = 10-- if len(timings[prefix]) > num_ignored:- # avg = sum(timings[prefix][num_ignored:]) / (len(timings[prefix]) - num_ignored)- avg = sum(timings[prefix][-num_ignored:]) / num_ignored- print("{}: {} ({})".format(prefix, t_diff, avg))- else:- print("{}: {}".format(prefix, t_diff))---def strip_dc(x):- """- strip DataContainer- """- try:- import mmcv- except ImportError:- pass-- if isinstance(x, dict):- res = {}- for k, v in x.items():- res[k] = strip_dc(v)- return res- if isinstance(x, (list, tuple)) and isinstance(x[0], mmcv.parallel.DataContainer):- return strip_dc(x[0])- elif isinstance(x, mmcv.parallel.DataContainer):- return strip_dc(x.data)- return x+import collections+import importlib+import logging+import os+import time+from collections import OrderedDict+from collections.abc import Sequence+from itertools import repeat++import numpy as np+import torch+import torch.distributed as dist+++def print_rank(var_name, var_value, rank=0):+ if dist.get_rank() == rank:+ print(f"[Rank {rank}] {var_name}: {var_value}")+++def print_0(*args, **kwargs):+ if dist.get_rank() == 0:+ print(*args, **kwargs)+++def requires_grad(model: torch.nn.Module, flag: bool = True) -> None:+ """+ Set requires_grad flag for all parameters in a model.+ """+ for p in model.parameters():+ p.requires_grad = flag+++def format_numel_str(numel: int) -> str:+ B = 1024**3+ M = 1024**2+ K = 1024+ if numel >= B:+ return f"{numel / B:.2f} B"+ elif numel >= M:+ return f"{numel / M:.2f} M"+ elif numel >= K:+ return f"{numel / K:.2f} K"+ else:+ return f"{numel}"+++def all_reduce_mean(tensor: torch.Tensor) -> torch.Tensor:+ dist.all_reduce(tensor=tensor, op=dist.ReduceOp.SUM)+ tensor.div_(dist.get_world_size())+ return tensor+++def get_model_numel(model: torch.nn.Module) -> (int, int):+ num_params = 0+ num_params_trainable = 0+ for p in model.parameters():+ num_params += p.numel()+ if p.requires_grad:+ num_params_trainable += p.numel()+ return num_params, num_params_trainable+++def try_import(name):+ """Try to import a module.++ Args:+ name (str): Specifies what module to import in absolute or relative+ terms (e.g. either pkg.mod or ..mod).+ Returns:+ ModuleType or None: If importing successfully, returns the imported+ module, otherwise returns None.+ """+ try:+ return importlib.import_module(name)+ except ImportError:+ return None+++def transpose(x):+ """+ transpose a list of list+ Args:+ x (list[list]):+ """+ ret = list(map(list, zip(*x)))+ return ret+++def get_timestamp():+ timestamp = time.strftime("%Y%m%d-%H%M%S", time.localtime(time.time()))+ return timestamp+++def format_time(seconds):+ days = int(seconds / 3600 / 24)+ seconds = seconds - days * 3600 * 24+ hours = int(seconds / 3600)+ seconds = seconds - hours * 3600+ minutes = int(seconds / 60)+ seconds = seconds - minutes * 60+ secondsf = int(seconds)+ seconds = seconds - secondsf+ millis = int(seconds * 1000)++ f = ""+ i = 1+ if days > 0:+ f += str(days) + "D"+ i += 1+ if hours > 0 and i <= 2:+ f += str(hours) + "h"+ i += 1+ if minutes > 0 and i <= 2:+ f += str(minutes) + "m"+ i += 1+ if secondsf > 0 and i <= 2:+ f += str(secondsf) + "s"+ i += 1+ if millis > 0 and i <= 2:+ f += str(millis) + "ms"+ i += 1+ if f == "":+ f = "0ms"+ return f+++def to_tensor(data):+ """Convert objects of various python types to :obj:`torch.Tensor`.++ Supported types are: :class:`numpy.ndarray`, :class:`torch.Tensor`,+ :class:`Sequence`, :class:`int` and :class:`float`.++ Args:+ data (torch.Tensor | numpy.ndarray | Sequence | int | float): Data to+ be converted.+ """++ if isinstance(data, torch.Tensor):+ return data+ elif isinstance(data, np.ndarray):+ return torch.from_numpy(data)+ elif isinstance(data, Sequence) and not isinstance(data, str):+ return torch.tensor(data)+ elif isinstance(data, int):+ return torch.LongTensor([data])+ elif isinstance(data, float):+ return torch.FloatTensor([data])+ else:+ raise TypeError(f"type {type(data)} cannot be converted to tensor.")+++def to_ndarray(data):+ if isinstance(data, torch.Tensor):+ return data.numpy()+ elif isinstance(data, np.ndarray):+ return data+ elif isinstance(data, Sequence):+ return np.array(data)+ elif isinstance(data, int):+ return np.ndarray([data], dtype=int)+ elif isinstance(data, float):+ return np.array([data], dtype=float)+ else:+ raise TypeError(f"type {type(data)} cannot be converted to ndarray.")+++def to_torch_dtype(dtype):+ if isinstance(dtype, torch.dtype):+ return dtype+ elif isinstance(dtype, str):+ dtype_mapping = {+ "float64": torch.float64,+ "float32": torch.float32,+ "float16": torch.float16,+ "fp32": torch.float32,+ "fp16": torch.float16,+ "half": torch.float16,+ "bf16": torch.bfloat16,+ }+ if dtype not in dtype_mapping:+ raise ValueError+ dtype = dtype_mapping[dtype]+ return dtype+ else:+ raise ValueError+++def count_params(model):+ return sum(p.numel() for p in model.parameters() if p.requires_grad)+++def _ntuple(n):+ def parse(x):+ if isinstance(x, collections.abc.Iterable) and not isinstance(x, str):+ return x+ return tuple(repeat(x, n))++ return parse+++to_1tuple = _ntuple(1)+to_2tuple = _ntuple(2)+to_3tuple = _ntuple(3)+to_4tuple = _ntuple(4)+to_ntuple = _ntuple+++def convert_SyncBN_to_BN2d(model_cfg):+ for k in model_cfg:+ v = model_cfg[k]+ if k == "norm_cfg" and v["type"] == "SyncBN":+ v["type"] = "BN2d"+ elif isinstance(v, dict):+ convert_SyncBN_to_BN2d(v)+++def get_topk(x, dim=4, k=5):+ x = to_tensor(x)+ inds = x[..., dim].topk(k)[1]+ return x[inds]+++def param_sigmoid(x, alpha):+ ret = 1 / (1 + (-alpha * x).exp())+ return ret+++def inverse_param_sigmoid(x, alpha, eps=1e-5):+ x = x.clamp(min=0, max=1)+ x1 = x.clamp(min=eps)+ x2 = (1 - x).clamp(min=eps)+ return torch.log(x1 / x2) / alpha+++def inverse_sigmoid(x, eps=1e-5):+ """Inverse function of sigmoid.++ Args:+ x (Tensor): The tensor to do the+ inverse.+ eps (float): EPS avoid numerical+ overflow. Defaults 1e-5.+ Returns:+ Tensor: The x has passed the inverse+ function of sigmoid, has same+ shape with input.+ """+ x = x.clamp(min=0, max=1)+ x1 = x.clamp(min=eps)+ x2 = (1 - x).clamp(min=eps)+ return torch.log(x1 / x2)+++def count_columns(df, columns):+ cnt_dict = OrderedDict()+ num_samples = len(df)++ for col in columns:+ d_i = df[col].value_counts().to_dict()+ for k in d_i:+ d_i[k] = (d_i[k], d_i[k] / num_samples)+ cnt_dict[col] = d_i++ return cnt_dict+++def build_logger(work_dir, cfgname):+ log_file = cfgname + ".log"+ log_path = os.path.join(work_dir, log_file)++ logger = logging.getLogger(cfgname)+ logger.setLevel(logging.INFO)+ # formatter = logging.Formatter('%(asctime)s %(levelname)s %(message)s')+ formatter = logging.Formatter("%(asctime)s: %(message)s", datefmt="%Y-%m-%d %H:%M:%S")++ handler1 = logging.FileHandler(log_path)+ handler1.setFormatter(formatter)++ handler2 = logging.StreamHandler()+ handler2.setFormatter(formatter)++ logger.addHandler(handler1)+ logger.addHandler(handler2)+ logger.propagate = False++ return logger+++timings = {}+from contextlib import contextmanager+++@contextmanager+def torch_timer(prefix):+ import time++ import torch++ torch.cuda.synchronize()+ start = time.time()+ try:+ yield+ finally:+ torch.cuda.synchronize()+ t_diff = (time.time() - start) * 1000+ if prefix not in timings:+ timings[prefix] = []++ timings[prefix].append(t_diff)++ num_ignored = 10++ if len(timings[prefix]) > num_ignored:+ # avg = sum(timings[prefix][num_ignored:]) / (len(timings[prefix]) - num_ignored)+ avg = sum(timings[prefix][-num_ignored:]) / num_ignored+ print("{}: {} ({})".format(prefix, t_diff, avg))+ else:+ print("{}: {}".format(prefix, t_diff))+++def strip_dc(x):+ """+ strip DataContainer+ """+ try:+ import mmcv+ except ImportError:+ pass++ if isinstance(x, dict):+ res = {}+ for k, v in x.items():+ res[k] = strip_dc(v)+ return res+ if isinstance(x, (list, tuple)) and isinstance(x[0], mmcv.parallel.DataContainer):+ return strip_dc(x[0])+ elif isinstance(x, mmcv.parallel.DataContainer):+ return strip_dc(x.data)+ return xdiff --git a/opensora/utils/train_utils.py b/opensora/utils/train_utils.pyindex 8a5c90f..f846043 100644--- a/opensora/utils/train_utils.py+++ b/opensora/utils/train_utils.py@@ -29,6 +29,3 @@ def update_ema(else:param_data = param.dataema_params[name].mul_(decay).add_(param_data, alpha=1 - decay)---diff --git a/requirements.txt b/requirements.txtindex 6e8196d..d2e02b8 100644--- a/requirements.txt+++ b/requirements.txt@@ -26,4 +26,3 @@ pyav# textclipftfy-diff --git a/scripts/train.py b/scripts/train.pyindex b750748..9f611b7 100644--- a/scripts/train.py+++ b/scripts/train.py@@ -11,13 +11,13 @@ from colossalai.nn.optimizer import HybridAdamfrom colossalai.utils import get_current_devicefrom tqdm import tqdm+from opensora.acceleration.checkpoint import set_grad_checkpointfrom opensora.acceleration.parallel_states import (get_data_parallel_group,set_data_parallel_group,set_sequence_parallel_group,)from opensora.acceleration.plugin import ZeroSeqParallelPlugin-from opensora.acceleration.checkpoint import set_grad_checkpointfrom opensora.datasets import DatasetFromCSV, get_transforms_image, get_transforms_video, prepare_dataloaderfrom opensora.registry import MODELS, SCHEDULERS, build_modulefrom opensora.utils.ckpt_utils import create_logger, load, model_sharding, record_model_param_shape, savediff --git a/setup.py b/setup.pyindex e1717af..1ac64d2 100644--- a/setup.py+++ b/setup.py@@ -39,7 +39,7 @@ setup("*.egg-info",)),- description="OpenDiT",+ description="OpenSora",long_description=fetch_readme(),long_description_content_type="text/markdown",license="Apache Software License 2.0",diff --git a/tests/test_seq_parallel_attention.py b/tests/test_seq_parallel_attention.pyindex 67ce7dc..7cae1f0 100644--- a/tests/test_seq_parallel_attention.py+++ b/tests/test_seq_parallel_attention.py@@ -18,12 +18,7 @@ def run_attention(rank, world_size):torch.manual_seed(1024)set_sequence_parallel_group(dist.group.WORLD)- seq_parallel_attention = SeqParallelAttention(- dim=256,- num_heads=4,- qkv_bias=True,- enable_flashattn=False- ).cuda()+ seq_parallel_attention = SeqParallelAttention(dim=256, num_heads=4, qkv_bias=True, enable_flashattn=False).cuda()torch.manual_seed(1024)attention = Attention(@@ -61,7 +56,7 @@ def run_attention(rank, world_size):if p.grad is not None:dist.all_reduce(p.grad, group=dist.group.WORLD)p.grad.div_(world_size)-+# check gradfor p1, p2 in zip(seq_parallel_attention.parameters(), attention.parameters()):assert torch.allclose(p1.grad, p2.grad, atol=1e-7), f"{p1.grad}\nvs\n{p2.grad}"@@ -126,27 +121,29 @@ def run_cross_attention(rank, world_size):p.grad.div_(world_size)else:print(f"grad of {name} is None")-+# # check gradfor p1, p2 in zip(seq_parallel_attention.named_parameters(), attention.named_parameters()):# if not torch.allclose(p1[1].grad, p2[1].grad, atol=1e-7):# print(p1[0], p2[0])- assert torch.allclose(p1[1].grad, p2[1].grad, atol=1e-7), f"\n{p1[0]}\nvs\n{p2[0]}:\n{p1[1].grad}\nvs\n{p2[1].grad}"-+ assert torch.allclose(+ p1[1].grad, p2[1].grad, atol=1e-7+ ), f"\n{p1[0]}\nvs\n{p2[0]}:\n{p1[1].grad}\nvs\n{p2[1].grad}"+# # check input gradassert torch.allclose(x.grad, seq_x.grad, atol=1e-7), f"{x.grad}\nvs\n{seq_x.grad}"assert torch.allclose(y.grad, seq_y.grad, atol=1e-7), f"{y.grad}\nvs\n{seq_y.grad}"--def run_dist(rank, world_size, port):colossalai.launch({}, rank=rank, world_size=world_size, host="localhost", port=port)# run_attention(rank, world_size)run_cross_attention(rank, world_size)+def test_seq_parallel_attention():spawn(run_dist, nprocs=2)-if __name__ == '__main__':++if __name__ == "__main__":test_seq_parallel_attention()diff --git a/tests/test_t5_shardformer.py b/tests/test_t5_shardformer.pyindex 7e32e98..68040ab 100644--- a/tests/test_t5_shardformer.py+++ b/tests/test_t5_shardformer.py@@ -19,14 +19,16 @@ def run_t5_encoder(rank, world_size, port):sf_t5 = deepcopy(hf_t5)# create huggingface model as normal- shard_config = ShardConfig(tensor_parallel_process_group=None,- pipeline_stage_manager=None,- enable_tensor_parallelism=False,- enable_fused_normalization=False,- enable_flash_attention=False,- enable_jit_fused=True,- enable_sequence_parallelism=False,- enable_sequence_overlap=False)+ shard_config = ShardConfig(+ tensor_parallel_process_group=None,+ pipeline_stage_manager=None,+ enable_tensor_parallelism=False,+ enable_fused_normalization=False,+ enable_flash_attention=False,+ enable_jit_fused=True,+ enable_sequence_parallelism=False,+ enable_sequence_overlap=False,+ )shard_former = ShardFormer(shard_config=shard_config)sharded_model, _ = shard_former.optimize(sf_t5.model, policy=T5EncoderPolicy())sf_t5.model = sharded_model@@ -65,5 +67,5 @@ def test_t5_encoder():spawn(run_t5_encoder)-if __name__ == '__main__':+if __name__ == "__main__":test_t5_encoder()diff --git a/tools/data/get_caption_llava.py b/tools/data/get_caption_llava.pyindex bb54974..ce26e5b 100644--- a/tools/data/get_caption_llava.py+++ b/tools/data/get_caption_llava.py@@ -6,7 +6,6 @@ import cv2import torchfrom llava.constants import DEFAULT_IMAGE_TOKEN, IGNORE_INDEX, IMAGE_TOKEN_INDEXfrom llava.conversation import conv_templates-from llava.eval.run_llava import eval_modelfrom llava.mm_utils import get_anyres_image_grid_shape, get_model_name_from_path, process_images, tokenizer_image_tokenfrom llava.model.builder import load_pretrained_modelfrom llava.model.llava_arch import unpad_image@@ -137,7 +136,6 @@ def prepare_inputs_labels_for_multimodal(labels = torch.full_like(input_ids, IGNORE_INDEX)# remove the padding using attention_mask -- FIXME- _input_ids = input_idsinput_ids = [cur_input_ids[cur_attention_mask] for cur_input_ids, cur_attention_mask in zip(input_ids, attention_mask)]diff --git a/tools/data/scene_detect.py b/tools/data/scene_detect.pyindex 115f683..c46e59d 100644--- a/tools/data/scene_detect.py+++ b/tools/data/scene_detect.py@@ -1,139 +1,138 @@-import os-from tqdm import tqdm-from multiprocessing import Pool-from mmengine.logging import MMLogger, print_log--from scenedetect import detect, ContentDetector--from .utils import check_mp4_integrity, split_video-from .utils import clone_folder_structure, iterate_files, iterate_folders-from opensora.utils.misc import get_timestamp---# config-target_fps = 30 # int-shorter_size = 512 # int-min_seconds = 1 # float-max_seconds = 5 # float-assert max_seconds > min_seconds-cfg = dict(- target_fps=target_fps,- min_seconds=min_seconds,- max_seconds=max_seconds,- shorter_size=shorter_size,-)---def process_folder(root_src, root_dst):- # create logger- folder_path_log = os.path.dirname(root_dst)- log_name = os.path.basename(root_dst)- timestamp = get_timestamp()- log_path = os.path.join(folder_path_log, f'{log_name}_{timestamp}.log')- logger = MMLogger.get_instance(log_name, log_file=log_path)-- # clone folder structure- clone_folder_structure(root_src, root_dst)-- # all source videos- mp4_list = [x for x in iterate_files(root_src) if x.endswith('.mp4')]- mp4_list = sorted(mp4_list)-- for idx, sample_path in tqdm(enumerate(mp4_list)):- folder_src = os.path.dirname(sample_path)- folder_dst = os.path.join(root_dst, os.path.relpath(folder_src, root_src))-- # check src video integrity- if not check_mp4_integrity(sample_path, logger=logger):- continue-- # detect scenes- scene_list = detect(sample_path, ContentDetector(), start_in_scene=True)-- # split scenes- save_path_list = split_video(sample_path, scene_list, save_dir=folder_dst, **cfg, logger=logger)-- # check integrity of generated clips- for x in save_path_list:- check_mp4_integrity(x, logger=logger)---def scene_detect():- """ detect & cut scenes using a single process- Expected dataset structure:- data/- your_dataset/- raw_videos/- xxx.mp4- yyy.mp4-- This function results in:- data/- your_dataset/- raw_videos/- xxx.mp4- yyy.mp4- zzz.mp4- clips/- xxx_scene-0.mp4- yyy_scene-0.mp4- yyy_scene-1.mp4- """- # TODO: specify your dataset root- root_src = f'./data/your_dataset/raw_videos'- root_dst = f'./data/your_dataset/clips'-- process_folder(root_src, root_dst)---def scene_detect_mp():- """ detect & cut scenes using multiple processes- Expected dataset structure:- data/- your_dataset/- raw_videos/- split_0/- xxx.mp4- yyy.mp4- split_1/- xxx.mp4- yyy.mp4-- This function results in:- data/- your_dataset/- raw_videos/- split_0/- xxx.mp4- yyy.mp4- split_1/- xxx.mp4- yyy.mp4- clips/- split_0/- xxx_scene-0.mp4- yyy_scene-0.mp4- split_1/- xxx_scene-0.mp4- yyy_scene-0.mp4- yyy_scene-1.mp4- """- # TODO: specify your dataset root- root_src = f'./data/your_dataset/raw_videos'- root_dst = f'./data/your_dataset/clips'-- # TODO: specify your splits- splits = ['split_0', 'split_1']-- # process folders- root_src_list = [os.path.join(root_src, x) for x in splits]- root_dst_list = [os.path.join(root_dst, x) for x in splits]-- with Pool(processes=len(splits)) as pool:- pool.starmap(process_folder, list(zip(root_src_list, root_dst_list)))---if __name__ == '__main__':- # TODO: choose single process or multiprocessing- scene_detect()- # scene_detect_mp()+import os+from multiprocessing import Pool++from mmengine.logging import MMLogger+from scenedetect import ContentDetector, detect+from tqdm import tqdm++from opensora.utils.misc import get_timestamp++from .utils import check_mp4_integrity, clone_folder_structure, iterate_files, split_video++# config+target_fps = 30 # int+shorter_size = 512 # int+min_seconds = 1 # float+max_seconds = 5 # float+assert max_seconds > min_seconds+cfg = dict(+ target_fps=target_fps,+ min_seconds=min_seconds,+ max_seconds=max_seconds,+ shorter_size=shorter_size,+)+++def process_folder(root_src, root_dst):+ # create logger+ folder_path_log = os.path.dirname(root_dst)+ log_name = os.path.basename(root_dst)+ timestamp = get_timestamp()+ log_path = os.path.join(folder_path_log, f"{log_name}_{timestamp}.log")+ logger = MMLogger.get_instance(log_name, log_file=log_path)++ # clone folder structure+ clone_folder_structure(root_src, root_dst)++ # all source videos+ mp4_list = [x for x in iterate_files(root_src) if x.endswith(".mp4")]+ mp4_list = sorted(mp4_list)++ for idx, sample_path in tqdm(enumerate(mp4_list)):+ folder_src = os.path.dirname(sample_path)+ folder_dst = os.path.join(root_dst, os.path.relpath(folder_src, root_src))++ # check src video integrity+ if not check_mp4_integrity(sample_path, logger=logger):+ continue++ # detect scenes+ scene_list = detect(sample_path, ContentDetector(), start_in_scene=True)++ # split scenes+ save_path_list = split_video(sample_path, scene_list, save_dir=folder_dst, **cfg, logger=logger)++ # check integrity of generated clips+ for x in save_path_list:+ check_mp4_integrity(x, logger=logger)+++def scene_detect():+ """detect & cut scenes using a single process+ Expected dataset structure:+ data/+ your_dataset/+ raw_videos/+ xxx.mp4+ yyy.mp4++ This function results in:+ data/+ your_dataset/+ raw_videos/+ xxx.mp4+ yyy.mp4+ zzz.mp4+ clips/+ xxx_scene-0.mp4+ yyy_scene-0.mp4+ yyy_scene-1.mp4+ """+ # TODO: specify your dataset root+ root_src = f"./data/your_dataset/raw_videos"+ root_dst = f"./data/your_dataset/clips"++ process_folder(root_src, root_dst)+++def scene_detect_mp():+ """detect & cut scenes using multiple processes+ Expected dataset structure:+ data/+ your_dataset/+ raw_videos/+ split_0/+ xxx.mp4+ yyy.mp4+ split_1/+ xxx.mp4+ yyy.mp4++ This function results in:+ data/+ your_dataset/+ raw_videos/+ split_0/+ xxx.mp4+ yyy.mp4+ split_1/+ xxx.mp4+ yyy.mp4+ clips/+ split_0/+ xxx_scene-0.mp4+ yyy_scene-0.mp4+ split_1/+ xxx_scene-0.mp4+ yyy_scene-0.mp4+ yyy_scene-1.mp4+ """+ # TODO: specify your dataset root+ root_src = f"./data/your_dataset/raw_videos"+ root_dst = f"./data/your_dataset/clips"++ # TODO: specify your splits+ splits = ["split_0", "split_1"]++ # process folders+ root_src_list = [os.path.join(root_src, x) for x in splits]+ root_dst_list = [os.path.join(root_dst, x) for x in splits]++ with Pool(processes=len(splits)) as pool:+ pool.starmap(process_folder, list(zip(root_src_list, root_dst_list)))+++if __name__ == "__main__":+ # TODO: choose single process or multiprocessing+ scene_detect()+ # scene_detect_mp()diff --git a/tools/data/utils.py b/tools/data/utils.pyindex b65270f..19eae31 100644--- a/tools/data/utils.py+++ b/tools/data/utils.py@@ -1,148 +1,145 @@-import os-import cv2-import subprocess-from mmengine.logging import print_log--from moviepy.editor import VideoFileClip-from imageio_ffmpeg import get_ffmpeg_exe-from scenedetect import FrameTimecode---def iterate_files(folder_path):- for root, dirs, files in os.walk(folder_path):- # root contains the current directory path- # dirs contains the list of subdirectories in the current directory- # files contains the list of files in the current directory-- # Process files in the current directory- for file in files:- file_path = os.path.join(root, file)- # print("File:", file_path)- yield file_path-- # Process subdirectories and recursively call the function- for subdir in dirs:- subdir_path = os.path.join(root, subdir)- # print("Subdirectory:", subdir_path)- iterate_files(subdir_path)---def iterate_folders(folder_path):- for root, dirs, files in os.walk(folder_path):- for subdir in dirs:- subdir_path = os.path.join(root, subdir)- yield subdir_path- # print("Subdirectory:", subdir_path)- iterate_folders(subdir_path)---def clone_folder_structure(root_src, root_dst, verbose=False):- src_path_list = iterate_folders(root_src)- src_relpath_list = [os.path.relpath(x, root_src) for x in src_path_list]-- os.makedirs(root_dst, exist_ok=True)- dst_path_list = [os.path.join(root_dst, x) for x in src_relpath_list]- for folder_path in dst_path_list:- os.makedirs(folder_path, exist_ok=True)- if verbose:- print(f'Create folder: \'{folder_path}\'')---def count_files(root, suffix='.mp4'):- files_list = iterate_files(root)- cnt = len([x for x in files_list if x.endswith(suffix)])- return cnt---def check_mp4_integrity(file_path, verbose=True, logger=None):- try:- video_clip = VideoFileClip(file_path)- if verbose:- print_log(f'The MP4 file \'{file_path}\' is intact.', logger=logger)- return True- except Exception as e:- if verbose:- print_log(f'Error: {e}', logger=logger)- print_log(f'The MP4 file \'{file_path}\' is not intact.', logger=logger)- return False---def count_frames(video_path):- cap = cv2.VideoCapture(video_path)-- if not cap.isOpened():- print(f"Error: Could not open video file '{video_path}'")- return-- total_frames = int(cap.get(cv2.CAP_PROP_FRAME_COUNT))- print(f"Total frames in the video '{video_path}': {total_frames}")-- cap.release()---def split_video(sample_path,- scene_list,- save_dir,- target_fps=30,- min_seconds=1,- max_seconds=10,- shorter_size=512,- verbose=False,- logger=None,- ):- FFMPEG_PATH = get_ffmpeg_exe()-- save_path_list = []- for idx, scene in enumerate(scene_list):- s, t = scene # FrameTimecode- fps = s.framerate- max_duration = FrameTimecode(timecode='00:00:00', fps=fps)- max_duration.frame_num = round(fps * max_seconds)- duration = min(max_duration, t - s)- if duration.get_frames() < round(min_seconds * fps):- continue-- # save path- fname = os.path.basename(sample_path)- fname_wo_ext = os.path.splitext(fname)[0]- # TODO: fname pattern- save_path = os.path.join(save_dir, f'{fname_wo_ext}_scene-{idx}.mp4')-- # ffmpeg cmd- cmd = [FFMPEG_PATH]-- # Only show ffmpeg output for the first call, which will display any- # errors if it fails, and then break the loop. We only show error messages- # for the remaining calls.- # cmd += ['-v', 'error']-- # input path- cmd += ['-i', sample_path]-- # clip to cut- cmd += [- '-nostdin', '-y',- '-ss', str(s.get_seconds()),- '-t', str(duration.get_seconds())- ]-- # target fps- # cmd += ['-vf', 'select=mod(n\,2)']- cmd += ['-r', f'{target_fps}']-- # aspect ratio- cmd += ['-vf', f"scale='if(gt(iw,ih),-2,{shorter_size})':'if(gt(iw,ih),{shorter_size},-2)'"]- # cmd += ['-vf', f"scale='if(gt(iw,ih),{shorter_size},trunc(ow/a/2)*2)':-2"]-- cmd += ['-map', '0', save_path]-- proc = subprocess.Popen(cmd, stdout=subprocess.PIPE, stderr=subprocess.STDOUT)- stdout, stderr = proc.communicate()- if verbose:- stdout = stdout.decode('utf-8')- print_log(stdout, logger=logger)-- save_path_list.append(sample_path)- print_log(f'Video clip saved to \'{save_path}\'', logger=logger)-- return save_path_list+import os+import subprocess++import cv2+from imageio_ffmpeg import get_ffmpeg_exe+from mmengine.logging import print_log+from moviepy.editor import VideoFileClip+from scenedetect import FrameTimecode+++def iterate_files(folder_path):+ for root, dirs, files in os.walk(folder_path):+ # root contains the current directory path+ # dirs contains the list of subdirectories in the current directory+ # files contains the list of files in the current directory++ # Process files in the current directory+ for file in files:+ file_path = os.path.join(root, file)+ # print("File:", file_path)+ yield file_path++ # Process subdirectories and recursively call the function+ for subdir in dirs:+ subdir_path = os.path.join(root, subdir)+ # print("Subdirectory:", subdir_path)+ iterate_files(subdir_path)+++def iterate_folders(folder_path):+ for root, dirs, files in os.walk(folder_path):+ for subdir in dirs:+ subdir_path = os.path.join(root, subdir)+ yield subdir_path+ # print("Subdirectory:", subdir_path)+ iterate_folders(subdir_path)+++def clone_folder_structure(root_src, root_dst, verbose=False):+ src_path_list = iterate_folders(root_src)+ src_relpath_list = [os.path.relpath(x, root_src) for x in src_path_list]++ os.makedirs(root_dst, exist_ok=True)+ dst_path_list = [os.path.join(root_dst, x) for x in src_relpath_list]+ for folder_path in dst_path_list:+ os.makedirs(folder_path, exist_ok=True)+ if verbose:+ print(f"Create folder: '{folder_path}'")+++def count_files(root, suffix=".mp4"):+ files_list = iterate_files(root)+ cnt = len([x for x in files_list if x.endswith(suffix)])+ return cnt+++def check_mp4_integrity(file_path, verbose=True, logger=None):+ try:+ VideoFileClip(file_path)+ if verbose:+ print_log(f"The MP4 file '{file_path}' is intact.", logger=logger)+ return True+ except Exception as e:+ if verbose:+ print_log(f"Error: {e}", logger=logger)+ print_log(f"The MP4 file '{file_path}' is not intact.", logger=logger)+ return False+++def count_frames(video_path):+ cap = cv2.VideoCapture(video_path)++ if not cap.isOpened():+ print(f"Error: Could not open video file '{video_path}'")+ return++ total_frames = int(cap.get(cv2.CAP_PROP_FRAME_COUNT))+ print(f"Total frames in the video '{video_path}': {total_frames}")++ cap.release()+++def split_video(+ sample_path,+ scene_list,+ save_dir,+ target_fps=30,+ min_seconds=1,+ max_seconds=10,+ shorter_size=512,+ verbose=False,+ logger=None,+):+ FFMPEG_PATH = get_ffmpeg_exe()++ save_path_list = []+ for idx, scene in enumerate(scene_list):+ s, t = scene # FrameTimecode+ fps = s.framerate+ max_duration = FrameTimecode(timecode="00:00:00", fps=fps)+ max_duration.frame_num = round(fps * max_seconds)+ duration = min(max_duration, t - s)+ if duration.get_frames() < round(min_seconds * fps):+ continue++ # save path+ fname = os.path.basename(sample_path)+ fname_wo_ext = os.path.splitext(fname)[0]+ # TODO: fname pattern+ save_path = os.path.join(save_dir, f"{fname_wo_ext}_scene-{idx}.mp4")++ # ffmpeg cmd+ cmd = [FFMPEG_PATH]++ # Only show ffmpeg output for the first call, which will display any+ # errors if it fails, and then break the loop. We only show error messages+ # for the remaining calls.+ # cmd += ['-v', 'error']++ # input path+ cmd += ["-i", sample_path]++ # clip to cut+ cmd += ["-nostdin", "-y", "-ss", str(s.get_seconds()), "-t", str(duration.get_seconds())]++ # target fps+ # cmd += ['-vf', 'select=mod(n\,2)']+ cmd += ["-r", f"{target_fps}"]++ # aspect ratio+ cmd += ["-vf", f"scale='if(gt(iw,ih),-2,{shorter_size})':'if(gt(iw,ih),{shorter_size},-2)'"]+ # cmd += ['-vf', f"scale='if(gt(iw,ih),{shorter_size},trunc(ow/a/2)*2)':-2"]++ cmd += ["-map", "0", save_path]++ proc = subprocess.Popen(cmd, stdout=subprocess.PIPE, stderr=subprocess.STDOUT)+ stdout, stderr = proc.communicate()+ if verbose:+ stdout = stdout.decode("utf-8")+ print_log(stdout, logger=logger)++ save_path_list.append(sample_path)+ print_log(f"Video clip saved to '{save_path}'", logger=logger)++ return save_path_list