
Open-Sora: Democratizing Efficient Video Production for All
Python
Docs/readme (#75)
Zheng Zangwei (Alex Zheng)faefeec53a89
diff --git a/README.md b/README.mdindex 869cd16..9e3c35c 100644--- a/README.md+++ b/README.md@@ -20,68 +20,57 @@ Open-Sora 1.0 supports a full pipeline of video data preprocessing, training wit<a href="https://github.com/hpcaitech/ColossalAI"><img src="assets/readme/colossal_ai.png" width="8%" ></a> acceleration,inference, and more. Our provided checkpoint can produce 2s 512x512 videos.-## 🎥 Latest Demo-| **2s 512x512** | **2s 512x512** | **2s 512x512** |-| ---------------------------------------------------------------------------------------------------------------------------------------------- | ---------------------------------------------------------------------------------------------------------------------------------------------- | ----------------------------------------------------------------------------------------------------------------------------------------------- |-| [<img src="assets/readme/sample_0.gif" width="">](https://github.com/hpcaitech/Open-Sora/assets/99191637/de1963d3-b43b-4e68-a670-bb821ebb6f80) | [<img src="assets/readme/sample_1.gif" width="">](https://github.com/hpcaitech/Open-Sora/assets/99191637/13f8338f-3d42-4b71-8142-d234fbd746cc) | [<img src="assets/readme/sample_2.gif" width=""> ](https://github.com/hpcaitech/Open-Sora/assets/99191637/fa6a65a6-e32a-4d64-9a9e-eabb0ebb8c16) |+| **2s 512x512** | **2s 512x512** | **2s 512x512** |+| ---------------------------------------------------------------------------------------------------------------------------------------------- | ---------------------------------------------------------------------------------------------------------------------------------------------- | ---------------------------------------------------------------------------------------------------------------------------------------------- |+| [<img src="assets/readme/sample_0.gif" width="">](https://github.com/hpcaitech/Open-Sora/assets/99191637/de1963d3-b43b-4e68-a670-bb821ebb6f80) | [<img src="assets/readme/sample_1.gif" width="">](https://github.com/hpcaitech/Open-Sora/assets/99191637/13f8338f-3d42-4b71-8142-d234fbd746cc) | [<img src="assets/readme/sample_2.gif" width="">](https://github.com/hpcaitech/Open-Sora/assets/99191637/fa6a65a6-e32a-4d64-9a9e-eabb0ebb8c16) |-Click for the original video.+Videos are downsampled to `.gif`. Click the video for original ones.## 🔆 New Features/Updates-- 📍 Open-Sora-v1 is trained on xxx. We train the model in three stages. Model weights are available here. Training details can be found here. [WIP]-- ✅ Support training acceleration including accelerated transformer, faster T5 and VAE, and sequence parallelism. Open-Sora improve **55%** training speed when training on 64x512x512 videos. Details locates at [acceleration.md](docs/acceleration.md).-- ✅ We provide video cutting and captioning tools for data preprocessing. Instructions can be found [here](tools/data/README.md) and our data collection plan can be found at [datasets.md](docs/datasets.md).-- ✅ We find VQ-VAE from [VideoGPT](https://wilson1yan.github.io/videogpt/index.html) has a low quality and thus adopt a better VAE from [Stability-AI](https://huggingface.co/stabilityai/sd-vae-ft-mse-original). We also find patching in the time dimension deteriorates the quality. See our **[report](docs/report_v1.md)** for more discussions.-- ✅ We investigate different architectures including DiT, Latte, and our proposed STDiT. Our **STDiT** achieves a better trade-off between quality and speed. See our **[report](docs/report_v1.md)** for more discussions.-- ✅ Support clip and T5 text conditioning.-- ✅ By viewing images as one-frame videos, our project supports training DiT on both images and videos (e.g., ImageNet & UCF101). See [command.md](docs/command.md) for more instructions.-- ✅ Support inference with official weights from [DiT](https://github.com/facebookresearch/DiT), [Latte](https://github.com/Vchitect/Latte), and [PixArt](https://pixart-alpha.github.io/).+* 📍 Open-Sora-v1 is trained on xxx. We train the model in three stages. Model weights are available here. Training details can be found here. [WIP]+* ✅ Support training acceleration including accelerated transformer, faster T5 and VAE, and sequence parallelism. Open-Sora improve **55%** training speed when training on 64x512x512 videos. Details locates at [acceleration.md](docs/acceleration.md).+* ✅ We provide video cutting and captioning tools for data preprocessing. Instructions can be found [here](tools/data/README.md) and our data collection plan can be found at [datasets.md](docs/datasets.md).+* ✅ We find VQ-VAE from [VideoGPT](https://wilson1yan.github.io/videogpt/index.html) has a low quality and thus adopt a better VAE from [Stability-AI](https://huggingface.co/stabilityai/sd-vae-ft-mse-original). We also find patching in the time dimension deteriorates the quality. See our **[report](docs/report_v1.md)** for more discussions.+* ✅ We investigate different architectures including DiT, Latte, and our proposed STDiT. Our **STDiT** achieves a better trade-off between quality and speed. See our **[report](docs/report_v1.md)** for more discussions.+* ✅ Support clip and T5 text conditioning.+* ✅ By viewing images as one-frame videos, our project supports training DiT on both images and videos (e.g., ImageNet & UCF101). See [command.md](docs/command.md) for more instructions.+* ✅ Support inference with official weights from [DiT](https://github.com/facebookresearch/DiT), [Latte](https://github.com/Vchitect/Latte), and [PixArt](https://pixart-alpha.github.io/).<details><summary>View more</summary>-- ✅ Refactor the codebase. See [structure.md](docs/structure.md) to learn the project structure and how to use the config files.+* ✅ Refactor the codebase. See [structure.md](docs/structure.md) to learn the project structure and how to use the config files.</details>### TODO list sorted by priority-- [ ] Complete the data processing pipeline (including dense optical flow, aesthetics scores, text-image similarity, deduplication, etc.). See [datasets.md]() for more information. **[WIP]**-- [ ] Training Video-VAE. **[WIP]**+* [ ] Complete the data processing pipeline (including dense optical flow, aesthetics scores, text-image similarity, deduplication, etc.). See [datasets.md]() for more information. **[WIP]**+* [ ] Training Video-VAE. **[WIP]**<details><summary>View more</summary>-- [ ] Support image and video conditioning.-- [ ] Evaluation pipeline.-- [ ] Incoporate a better scheduler, e.g., rectified flow in SD3.-- [ ] Support variable aspect ratios, resolutions, durations.-- [ ] Support SD3 when released.+* [ ] Support image and video conditioning.+* [ ] Evaluation pipeline.+* [ ] Incoporate a better scheduler, e.g., rectified flow in SD3.+* [ ] Support variable aspect ratios, resolutions, durations.+* [ ] Support SD3 when released.</details>-## Contents--- [Open-Sora: Towards Open Reproduction of Sora](#open-sora-towards-open-reproduction-of-sora)-- [📰 News](#-news)-- [🎥 Latest Demo](#-latest-demo)-- [🔆 New Features/Updates](#-new-featuresupdates)- - [TODO list sorted by priority](#todo-list-sorted-by-priority)-- [Contents](#contents)-- [Installation](#installation)-- [Model Weights](#model-weights)-- [Inference](#inference)-- [Data Processing](#data-processing)- - [Split video into clips](#split-video-into-clips)- - [Generate video caption](#generate-video-caption)-- [Training](#training)-- [Acknowledgement](#acknowledgement)-- [Citation](#citation)-- [Star History](#star-history)-- [TODO](#todo)+## Contentss++* [Installation](#installation)+* [Model Weights](#model-weights)+* [Inference](#inference)+* [Data Processing](#data-processing)+* [Training](#training)+* [Acknowledgement](#acknowledgement)+* [Citation](#citation)## Installation@@ -120,9 +109,7 @@ After installation, we suggest reading [structure.md](docs/structure.md) to lear## Inference-To run inference with our provided weights, first prepare the pretrained weights including XXX. [WIP]--Then run the following commands to generate samples. See [here](docs/structure.md#inference-config-demos) to customize the configuration.+To run inference with our provided weights, first download [T5](https://huggingface.co/DeepFloyd/t5-v1_1-xxl/tree/main) weights into `pretrained_models/t5_ckpts/t5-v1_1-xxl`. Then run the following commands to generate samples. See [here](docs/structure.md#inference-config-demos) to customize the configuration.```bash# Sample 16x256x256 (~2s)@@ -145,9 +132,7 @@ We provide code to split a long video into separate clips efficiently using `mul## Training-To launch training, first prepare the dataset and the pretrained weights. [WIP]--Then run the following commands to launch training on a single node.+To launch training, first download [T5](https://huggingface.co/DeepFloyd/t5-v1_1-xxl/tree/main) weights into `pretrained_models/t5_ckpts/t5-v1_1-xxl`. Then run the following commands to launch training on a single node.```bash# 1 GPU, 16x256x256@@ -181,7 +166,7 @@ We are grateful for their exceptional work and generous contribution to open sou```bibtex@software{opensora,- author = {Zangwei Zheng and Xiangyu Peng and Shenggui Li and Yang You},+ author = {Zangwei Zheng and Xiangyu Peng and Yang You},title = {Open-Sora: Towards Open Reproduction of Sora},month = {March},year = {2024},@@ -194,17 +179,3 @@ We are grateful for their exceptional work and generous contribution to open sou## Star History[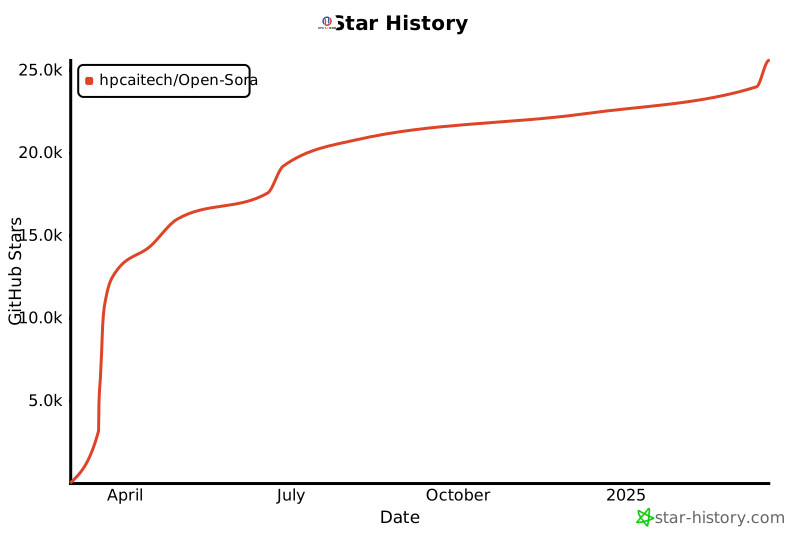](https://star-history.com/#hpcaitech/Open-Sora&Date)--## TODO--Modules for releasing:--* `configs`-* `opensora`-* `assets`-* `scripts`-* `tools`--packages for data processing--put all outputs under ./checkpoints/, including pretrained_models, checkpoints, samplesdiff --git a/configs/opensora/train/64x512x512.py b/configs/opensora/train/64x512x512.pyindex 81154c8..dfcdcc0 100644--- a/configs/opensora/train/64x512x512.py+++ b/configs/opensora/train/64x512x512.py@@ -26,7 +26,7 @@ model = dict(vae = dict(type="VideoAutoencoderKL",from_pretrained="stabilityai/sd-vae-ft-ema",- micro_batch_size=128,+ micro_batch_size=64,)text_encoder = dict(type="t5",diff --git a/configs/pixart/inference/1x256x256.py b/configs/pixart/inference/1x256x256.pyindex 6dcbbba..11e06d7 100644--- a/configs/pixart/inference/1x256x256.py+++ b/configs/pixart/inference/1x256x256.py@@ -11,10 +11,8 @@ model = dict(from_pretrained="PixArt-XL-2-256x256.pth",)vae = dict(- # type="VideoAutoencoderKL",- # from_pretrained="stabilityai/sd-vae-ft-ema",- type="VideoAutoencoderKLTemporalDecoder",- from_pretrained="pretrained_models/vae_temporal_decoder",+ type="VideoAutoencoderKL",+ from_pretrained="stabilityai/sd-vae-ft-ema",)text_encoder = dict(type="t5",diff --git a/docs/commands.md b/docs/commands.mdindex 261e179..3e4dece 100644--- a/docs/commands.md+++ b/docs/commands.md@@ -2,8 +2,83 @@## Inference+You can modify corresponding config files to change the inference settings. See more details [here](/docs/structure.md#inference-config-demos).+### Inference with DiT pretrained on ImageNet+The following command automatically downloads the pretrained weights on ImageNet and runs inference.++```bash+python scripts/inference.py configs/dit/inference/1x256x256-class.py --ckpt-path DiT-XL-2-256x256.pt+```++### Inference with Latte pretrained on UCF101++The following command automatically downloads the pretrained weights on UCF101 and runs inference.++```bash+python scripts/inference.py configs/latte/inference/16x256x256-class.py --ckpt-path Latte-XL-2-256x256-ucf101.pt+```++### Inference with PixArt-α pretrained weights++Download T5 into `./pretrained_models` and run the following command.++```bash+# 256x256+python scripts/inference.py configs/pixart/inference/1x256x256.py --ckpt-path PixArt-XL-2-256x256.pth+# 512x512+python scripts/inference.py configs/pixart/inference/1x512x512.py --ckpt-path PixArt-XL-2-512x512.pth+# 1024 multi-scale+python scripts/inference.py configs/pixart/inference/1x1024MS.py --ckpt-path PixArt-XL-2-1024MS.pth+```++### Inference with checkpoints saved during training++During training, an experiment logging folder is created in `outputs` directory. Under each checpoint folder, e.g. `epoch12-global_step2000`, there is a `ema.pt` and the shared `model` folder. Run the following command to perform inference.++```bash+# inference with ema model+python scripts/inference.py configs/opensora/inference/16x256x256.py --ckpt-path outputs/001-STDiT-XL-2/epoch12-global_step2000/ema.pt+# inference with model+python scripts/inference.py configs/opensora/inference/16x256x256.py --ckpt-path outputs/001-STDiT-XL-2/epoch12-global_step2000+```++The second command will automatically generate a `model_ckpt.pt` file in the checkpoint folder.+### Inference Hyperparameters++1. DPM-solver is good at fast inference for images. However, the video result is not satisfactory. You can use it for fast demo purpose.++```python+type="dmp-solver"+num_sampling_steps=20+```++1. You can use [SVD](https://huggingface.co/stabilityai/stable-video-diffusion-img2vid-xt)'s finetuned VAE decoder on videos for inference (consumes more memory). However, we do not see significant improvement in the video result. To use it, download [the pretrained weights](https://huggingface.co/maxin-cn/Latte/tree/main/t2v_required_models/vae_temporal_decoder) into `./pretrained_models/vae_temporal_decoder` and modify the config file as follows.++```python+vae = dict(+ type="VideoAutoencoderKLTemporalDecoder",+ from_pretrained="pretrained_models/vae_temporal_decoder",+)## Training++To resume training, run the following command. ``--load`` different from ``--ckpt-path`` as it loads the optimizer and dataloader states.++```bash+torchrun --nnodes=1 --nproc_per_node=8 scripts/train.py configs/opensora/train/64x512x512.py --data-path YOUR_CSV_PATH --load YOUR_PRETRAINED_CKPT+```++To enable wandb logging, add `--wandb` to the command.++```bash+WANDB_API_KEY=YOUR_WANDB_API_KEY torchrun --nnodes=1 --nproc_per_node=8 scripts/train.py configs/opensora/train/64x512x512.py --data-path YOUR_CSV_PATH --wandb True+```++You can modify corresponding config files to change the training settings. See more details [here](/docs/structure.md#training-config-demos).++### Training Hyperparameters++1. `dtype` is the data type for training. Only `fp16` and `bf16` are supported. ColossalAI automatically enables the mixed precision training for `fp16` and `bf16`. During training, we find `bf16` more stable.diff --git a/docs/structure.md b/docs/structure.mdindex 6a521ae..b0bba8f 100644--- a/docs/structure.md+++ b/docs/structure.md@@ -130,7 +130,7 @@ use_image_transform = False # True if training on imagesnum_workers = 4 # number of workers for dataloader# Define acceleration-dtype = "bf16" # Computation type (fp16, fp32, bf16)+dtype = "bf16" # Computation type (fp16, bf16)grad_checkpoint = True # Use gradient checkpointingplugin = "zero2" # Plugin for distributed training (zero2, zero2-seq)sp_size = 1 # Sequence parallelism size (1 for no sequence parallelism)diff --git a/opensora/utils/ckpt_utils.py b/opensora/utils/ckpt_utils.pyindex 7960f3e..3543f01 100644--- a/opensora/utils/ckpt_utils.py+++ b/opensora/utils/ckpt_utils.py@@ -20,10 +20,10 @@ pretrained_models = {"DiT-XL-2-512x512.pt": "https://dl.fbaipublicfiles.com/DiT/models/DiT-XL-2-512x512.pt","DiT-XL-2-256x256.pt": "https://dl.fbaipublicfiles.com/DiT/models/DiT-XL-2-256x256.pt","Latte-XL-2-256x256-ucf101.pt": "https://huggingface.co/maxin-cn/Latte/resolve/main/ucf101.pt",- "PixArt-XL-2-256x256.pth": "PixArt-XL-2-256x256.pth",- "PixArt-XL-2-SAM-256x256.pth": "PixArt-XL-2-SAM-256x256.pth",- "PixArt-XL-2-512x512.pth": "PixArt-XL-2-512x512.pth",- "PixArt-XL-2-1024-MS.pth": "PixArt-XL-2-1024-MS.pth",+ "PixArt-XL-2-256x256.pth": "https://huggingface.co/PixArt-alpha/PixArt-alpha/resolve/main/PixArt-XL-2-256x256.pth",+ "PixArt-XL-2-SAM-256x256.pth": "https://huggingface.co/PixArt-alpha/PixArt-alpha/resolve/main/PixArt-XL-2-SAM-256x256.pth",+ "PixArt-XL-2-512x512.pth": "https://huggingface.co/PixArt-alpha/PixArt-alpha/resolve/main/PixArt-XL-2-512x512.pth",+ "PixArt-XL-2-1024-MS.pth": "https://huggingface.co/PixArt-alpha/PixArt-alpha/resolve/main/PixArt-XL-2-1024-MS.pth",}