
Self-evolving Context Database for AI Agents. Unify Agent Memory, Knowledge RAG and Skills.
Python agent-contextagent-memoryagent-pluginsagentic-ragcontext-databasedsh-pluginknowledge-basememorymemory-managementself-evolvingvector-database
feat(vlm): add Codex, Kimi, and GLM VLM support (#1444)
Hao Zhe01403312eae7
diff --git a/.gitignore b/.gitignoreindex 82a3ca9c7..8b331ecd8 100644--- a/.gitignore+++ b/.gitignore@@ -119,6 +119,7 @@ docker-compose.override.yml*.code-workspace.openviking.pidexports/+.local-data/# API Test temporary filestests/api_test/api-test-report.htmldiff --git a/README.md b/README.mdindex 1a04b605f..908627d81 100644--- a/README.md+++ b/README.md@@ -12,12 +12,12 @@ English / [中文](README_CN.md) / [日本語](README_JA.md)<a href="https://www.openviking.ai">Website</a> · <a href="https://github.com/volcengine/OpenViking">GitHub</a> · <a href="https://github.com/volcengine/OpenViking/issues">Issues</a> · <a href="./docs">Docs</a>-[![][release-shield]][release-link]-[![][github-stars-shield]][github-stars-link]-[![][github-issues-shield]][github-issues-shield-link]-[![][github-contributors-shield]][github-contributors-link]-[![][license-shield]][license-shield-link]-[![][last-commit-shield]][last-commit-shield-link]+[](https://github.com/volcengine/OpenViking/releases)+[](https://github.com/volcengine/OpenViking)+[](https://github.com/volcengine/OpenViking/issues)+[](https://github.com/volcengine/OpenViking/graphs/contributors)+[](https://github.com/volcengine/OpenViking/blob/main/LICENSE)+[](https://github.com/volcengine/OpenViking/commits/main)👋 Join our Community@@ -27,7 +27,7 @@ English / [中文](README_CN.md) / [日本語](README_JA.md)</div>----+***## Overview@@ -55,7 +55,7 @@ With OpenViking, developers can build an Agent's brain just like managing local- **Visualized Retrieval Trajectory** → **Observable Context**: Supports visualization of directory retrieval trajectories, allowing users to clearly observe the root cause of issues and guide retrieval logic optimization.- **Automatic Session Management** → **Context Self-Iteration**: Automatically compresses content, resource references, tool calls, etc., in conversations, extracting long-term memory, making the Agent smarter with use.----+***## Quick Start@@ -92,22 +92,21 @@ cargo install --git https://github.com/volcengine/OpenViking ov_cli### 2. Model PreparationOpenViking requires the following model capabilities:+- **VLM Model**: For image and content understanding- **Embedding Model**: For vectorization and semantic retrieval#### Supported VLM Providers-OpenViking supports three VLM providers:--| Provider | Description | Get API Key |-|----------|-------------|-------------|-| `volcengine` | Volcengine Doubao Models | [Volcengine Console](https://console.volcengine.com/ark/region:ark+cn-beijing/overview?briefPage=0&briefType=introduce&type=new&utm_content=OpenViking&utm_medium=devrel&utm_source=OWO&utm_term=OpenViking) |-| `openai` | OpenAI Official API | [OpenAI Platform](https://platform.openai.com) |-| `litellm` | Unified access to various third-party models (Anthropic, DeepSeek, Gemini, vLLM, Ollama, etc.) | See [LiteLLM Providers](https://docs.litellm.ai/docs/providers) |+OpenViking supports multiple VLM providers:-> 💡 **Tip**:-> - `litellm` supports unified access to various models. The `model` field must follow the [LiteLLM format specification](https://docs.litellm.ai/docs/providers)-> - The system auto-detects common models (e.g., `claude-*`, `deepseek-*`, `gemini-*`, `hosted_vllm/*`, `ollama/*`, etc.). For other models, use the full prefix according to LiteLLM format+| Provider | Description | Setup |+| -------------- | ------------------------ | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ |+| `volcengine` | Volcengine Doubao Models | [Volcengine Console](https://console.volcengine.com/ark/region:ark+cn-beijing/overview?briefPage=0\&briefType=introduce\&type=new\&utm_content=OpenViking\&utm_medium=devrel\&utm_source=OWO\&utm_term=OpenViking) |+| `openai` | OpenAI Official API | [OpenAI Platform](https://platform.openai.com) |+| `openai-codex` | Codex VLM | Use `openviking-server init` |+| `kimi` | Kimi Code Membership | Use `openviking-server init` |+| `glm` | GLM Coding Plan | Use `openviking-server init` |#### Provider-Specific Notes@@ -127,7 +126,7 @@ Volcengine supports both model names and endpoint IDs. Using model names is reco}```-You can also use endpoint IDs (found in [Volcengine ARK Console](https://console.volcengine.com/ark/region:ark+cn-beijing/overview?briefPage=0&briefType=introduce&type=new&utm_content=OpenViking&utm_medium=devrel&utm_source=OWO&utm_term=OpenViking):+You can also use endpoint IDs (found in [Volcengine ARK Console](https://console.volcengine.com/ark/region:ark+cn-beijing/overview?briefPage=0\&briefType=introduce\&type=new\&utm_content=OpenViking\&utm_medium=devrel\&utm_source=OWO\&utm_term=OpenViking):```json{@@ -174,71 +173,97 @@ You can also use a custom OpenAI-compatible endpoint:</details><details>-<summary><b>LiteLLM (Anthropic, DeepSeek, Gemini, Qwen, vLLM, Ollama, etc.)</b></summary>+<summary><b>OpenAI Codex (OAuth)</b></summary>-LiteLLM provides unified access to various models. The `model` field should follow LiteLLM's naming convention. Here we use Claude and Qwen as examples:+Use this provider when you want OpenViking to call Codex VLM through your ChatGPT/Codex OAuth session instead of a standard OpenAI API key:-**Anthropic:**+```bash+openviking-server init+# choose OpenAI Codex when prompted+openviking-server doctor+``````json{"vlm": {- "provider": "litellm",- "model": "claude-3-5-sonnet-20240620",- "api_key": "your-anthropic-api-key"+ "provider": "openai-codex",+ "model": "gpt-5.3-codex",+ "api_base": "https://chatgpt.com/backend-api/codex",+ "temperature": 0.0,+ "max_retries": 2}}```-**Qwen (DashScope):**+> 💡 **Tip**:+>+> - `openai-codex` does not require `vlm.api_key` when Codex OAuth is available+> - OpenViking stores its own Codex auth state at `~/.openviking/codex_auth.json`+> - `openviking-server doctor` validates that the current Codex auth is usable++</details>++<details>+<summary><b>Kimi Coding (Subscription)</b></summary>++Use this provider when you want OpenViking to call the dedicated Kimi Coding subscription endpoint directly:++```bash+openviking-server init+# choose Kimi Coding when prompted+openviking-server doctor+``````json{"vlm": {- "provider": "litellm",- "model": "dashscope/qwen-turbo", // see https://docs.litellm.ai/docs/providers/dashscope for more details- "api_key": "your-dashscope-api-key",- "api_base": "https://dashscope.aliyuncs.com/compatible-mode/v1"+ "provider": "kimi",+ "model": "kimi-code",+ "api_key": "your-kimi-subscription-api-key",+ "api_base": "https://api.kimi.com/coding",+ "temperature": 0.0,+ "max_retries": 2}}```-> 💡 **Tip for Qwen**:-> - For **China/Beijing** region, use `api_base`: `https://dashscope.aliyuncs.com/compatible-mode/v1`-> - For **International** region, use `api_base`: `https://dashscope-intl.aliyuncs.com/compatible-mode/v1`+> 💡 **Tip**:+>+> - `kimi` applies the recommended Kimi Coding defaults automatically, including the default Kimi Coding user agent+> - `kimi-code` and `kimi-coding` are accepted aliases for the provider name+> - `kimi-code` is normalized to Kimi's upstream coding model automatically-**Common model formats:**+</details>-| Provider | Model Example | Notes |-|----------|---------------|-------|-| Anthropic | `claude-3-5-sonnet-20240620` | Auto-detected, uses `ANTHROPIC_API_KEY` |-| DeepSeek | `deepseek-chat` | Auto-detected, uses `DEEPSEEK_API_KEY` |-| Gemini | `gemini-pro` | Auto-detected, uses `GEMINI_API_KEY` |-| Qwen | `dashscope/qwen-turbo` | Set `api_base` based on region (see above) |-| OpenRouter | `openrouter/openai/gpt-4o` | Full prefix required |-| vLLM | `hosted_vllm/llama-3.1-8b` | Set `api_base` to vLLM server |-| Ollama | `ollama/llama3.1` | Set `api_base` to Ollama server |+<details>+<summary><b>GLM Coding Plan (Subscription)</b></summary>-**Local Models (vLLM / Ollama):**+Use this provider when you want OpenViking to call Z.AI's OpenAI-compatible Coding Plan endpoint directly:```bash--# Start Ollama-ollama serve+openviking-server init+# choose GLM Coding Plan when prompted+openviking-server doctor``````json-// Ollama{"vlm": {- "provider": "litellm",- "model": "ollama/llama3.1",- "api_base": "http://localhost:11434"+ "provider": "glm",+ "model": "glm-4.6v",+ "api_key": "your-zai-api-key",+ "api_base": "https://api.z.ai/api/coding/paas/v4",+ "temperature": 0.0,+ "max_retries": 2}}```-For complete model support, see [LiteLLM Providers Documentation](https://docs.litellm.ai/docs/providers).+> 💡 **Tip**:+>+> - `glm`, `zhipu`, `zai`, `z-ai`, and `z.ai` all resolve to the same first-class GLM provider+> - The default endpoint is the Coding Plan endpoint, not the general Z.AI endpoint+> - Use a vision-capable model such as `glm-4.6v` or `glm-5v-turbo` for multimodal parsing</details>@@ -253,6 +278,7 @@ openviking-server init```The wizard will:+- Detect and install Ollama if needed- Recommend and pull suitable embedding and VLM models for your hardware- Generate a ready-to-use `ov.conf` configuration file@@ -269,7 +295,16 @@ openviking-server doctor#### Server Configuration Template-Create a configuration file `~/.openviking/ov.conf`, remove the comments before copy:+The recommended first-time flow is:++```bash+openviking-server init+openviking-server doctor+```++If you choose `OpenAI Codex` inside `openviking-server init`, the wizard can import existing Codex auth or start the Codex sign-in flow for you.++If you prefer manual configuration, create `~/.openviking/ov.conf`, remove the comments before copy:```json{@@ -292,15 +327,15 @@ Create a configuration file `~/.openviking/ov.conf`, remove the comments before},"vlm": {"api_base" : "<api-endpoint>", // API endpoint address- "api_key" : "<your-api-key>", // Model service API Key- "provider" : "<provider-type>", // Provider type (volcengine, openai, deepseek, anthropic, etc.)+ "api_key" : "<your-api-key>", // Model service API Key (optional for openai-codex)+ "provider" : "<provider-type>", // Provider type (volcengine, openai, openai-codex, kimi, glm, etc.)"model" : "<model-name>", // VLM model name (e.g., doubao-seed-2-0-pro-260215 or gpt-4-vision-preview)"max_concurrent": 100 // Max concurrent LLM calls for semantic processing (default: 100)}}```-> **Note**: For embedding models, supported providers are `volcengine` (Doubao), `openai`, `jina`, `voyage`, `minimax`, `vikingdb`, and `gemini` (requires `pip install "google-genai>=1.0.0"`). For VLM models, we support three providers: `volcengine`, `openai`, and `litellm`. The `litellm` provider supports various models including Anthropic (Claude), DeepSeek, Gemini, Moonshot, Zhipu, DashScope, MiniMax, vLLM, Ollama, and more.+> **Note**: For embedding models, supported providers are `volcengine` (Doubao), `openai`, `jina`, `voyage`, `minimax`, `vikingdb`, and `gemini` (requires `pip install "google-genai>=1.0.0"`). For VLM models, common providers include `volcengine`, `openai`, `openai-codex`, `kimi`, and `glm`.#### Server Configuration Examples@@ -407,7 +442,37 @@ pip install "google-genai>=1.0.0"}```-Get your Google API key at https://aistudio.google.com/apikey+Get your Google API key at <https://aistudio.google.com/apikey>++</details>++<details>+<summary><b>Example 4: Using Volcengine Embedding + Codex VLM</b></summary>++Use `openviking-server init` and choose `OpenAI Codex`, then run `openviking-server doctor`.++```json+{+ "storage": {+ "workspace": "/home/your-name/openviking_workspace"+ },+ "embedding": {+ "dense": {+ "api_base" : "https://ark.cn-beijing.volces.com/api/v3",+ "api_key" : "your-volcengine-api-key",+ "provider" : "volcengine",+ "dimension": 1024,+ "model" : "doubao-embedding-vision-251215"+ }+ },+ "vlm": {+ "api_base" : "https://chatgpt.com/backend-api/codex",+ "provider" : "openai-codex",+ "model" : "gpt-5.3-codex",+ "max_concurrent": 100+ }+}+```</details>@@ -478,9 +543,12 @@ Now let's run a complete example to experience the core features of OpenViking.#### Launch Server```bash+openviking-server doctoropenviking-server```+If you configured `provider=openai-codex`, `openviking-server doctor` already validates Codex auth.+or you can run in background```bash@@ -521,7 +589,7 @@ ov chatIf you use the official Docker image, `vikingbot` is already bundled in the image and starts by default together with the OpenViking server and console UI. You can disable it at runtime with either `--without-bot` or `-e OPENVIKING_WITH_BOT=0`.----+***## Server Deployment Details@@ -532,26 +600,26 @@ To ensure optimal storage performance and data security, we recommend deploying👉 **[View: Server Deployment & ECS Setup Guide](./docs/en/getting-started/03-quickstart-server.md)**-## OpenClaw Context Plugin Details-* Test Dataset: Effect testing based on LoCoMo10 (https://github.com/snap-research/locomo) long-range dialogues (1,540 cases in total after removing category5 without ground truth)-* Experimental Groups: Since users may not disable OpenClaw's native memory when using OpenViking, we added experimental groups with native memory enabled or disabled-* OpenViking Version: 0.1.18-* Model: seed-2.0-code-* Evaluation Script: https://github.com/ZaynJarvis/openclaw-eval/tree/main+- Test Dataset: Effect testing based on LoCoMo10 (<https://github.com/snap-research/locomo>) long-range dialogues (1,540 cases in total after removing category5 without ground truth)+- Experimental Groups: Since users may not disable OpenClaw's native memory when using OpenViking, we added experimental groups with native memory enabled or disabled+- OpenViking Version: 0.1.18+- Model: seed-2.0-code+- Evaluation Script: <https://github.com/ZaynJarvis/openclaw-eval/tree/main>-| Experimental Group | Task Completion Rate | Cost: Input Tokens (Total) |-|----------|------------------|------------------|-| OpenClaw(memory-core) | 35.65% | 24,611,530 |-| OpenClaw + LanceDB (-memory-core) | 44.55% | 51,574,530 |-| OpenClaw + OpenViking Plugin (-memory-core) | 52.08% | 4,264,396 |-| OpenClaw + OpenViking Plugin (+memory-core) | 51.23% | 2,099,622 |+| Experimental Group | Task Completion Rate | Cost: Input Tokens (Total) |+| ------------------------------------------- | -------------------- | -------------------------- |+| OpenClaw(memory-core) | 35.65% | 24,611,530 |+| OpenClaw + LanceDB (-memory-core) | 44.55% | 51,574,530 |+| OpenClaw + OpenViking Plugin (-memory-core) | 52.08% | 4,264,396 |+| OpenClaw + OpenViking Plugin (+memory-core) | 51.23% | 2,099,622 |-* Experimental Conclusions:-After integrating OpenViking:-- With native memory enabled: 43% improvement over original OpenClaw with 91% reduction in input token cost; 15% improvement over LanceDB with 96% reduction in input token cost.-- With native memory disabled: 49% improvement over original OpenClaw with 83% reduction in input token cost; 17% improvement over LanceDB with 92% reduction in input token cost.+- Experimental Conclusions:+ After integrating OpenViking:++* With native memory enabled: 43% improvement over original OpenClaw with 91% reduction in input token cost; 15% improvement over LanceDB with 96% reduction in input token cost.+* With native memory disabled: 49% improvement over original OpenClaw with 83% reduction in input token cost; 17% improvement over LanceDB with 92% reduction in input token cost.👉 **[View: OpenClaw Context Plugin](examples/openclaw-plugin/README.md)**@@ -559,7 +627,7 @@ After integrating OpenViking:👉 **[View: Claude Code Memory Plugin Example](examples/claude-code-memory-plugin/README.md)**---+\--## Core Concepts@@ -598,6 +666,7 @@ viking://### 2. Tiered Context Loading → Reduces Token ConsumptionStuffing massive amounts of context into a prompt all at once is not only expensive but also prone to exceeding model windows and introducing noise. OpenViking automatically processes context into three levels upon writing:+- **L0 (Abstract)**: A one-sentence summary for quick retrieval and identification.- **L1 (Overview)**: Contains core information and usage scenarios for Agent decision-making during the planning phase.- **L2 (Details)**: The full original data, for deep reading by the Agent when absolutely necessary.@@ -648,7 +717,7 @@ OpenViking has a built-in memory self-iteration loop. At the end of each sessionThis allows the Agent to get "smarter with use" through interactions with the world, achieving self-evolution. Learn more: [Session Management](./docs/en/concepts/08-session.md)----+***## Advanced Reading@@ -665,7 +734,7 @@ For more details, please see: **[About Us](./docs/en/about/01-about-us.md)**OpenViking is still in its early stages, and there are many areas for improvement and exploration. We sincerely invite every developer passionate about AI Agent technology:- Light up a precious **Star** for us to give us the motivation to move forward.-- Visit our [**Website**](https://www.openviking.ai) to understand the philosophy we convey, and use it in your projects via the [**Documentation**](https://www.openviking.ai/docs). Feel the change it brings and give us feedback on your truest experience.+- Visit our **[Website](https://www.openviking.ai)** to understand the philosophy we convey, and use it in your projects via the **[Documentation](https://www.openviking.ai/docs)**. Feel the change it brings and give us feedback on your truest experience.- Join our community to share your insights, help answer others' questions, and jointly create an open and mutually helpful technical atmosphere:- 📱 **Lark Group**: Scan the QR code to join → [View QR Code](./docs/en/about/01-about-us.md#lark-group)- 💬 **WeChat Group**: Scan the QR code to add assistant → [View QR Code](./docs/en/about/01-about-us.md#wechat-group)@@ -677,29 +746,15 @@ Let's work together to define and build the future of AI Agent context managemen### Star Trend-[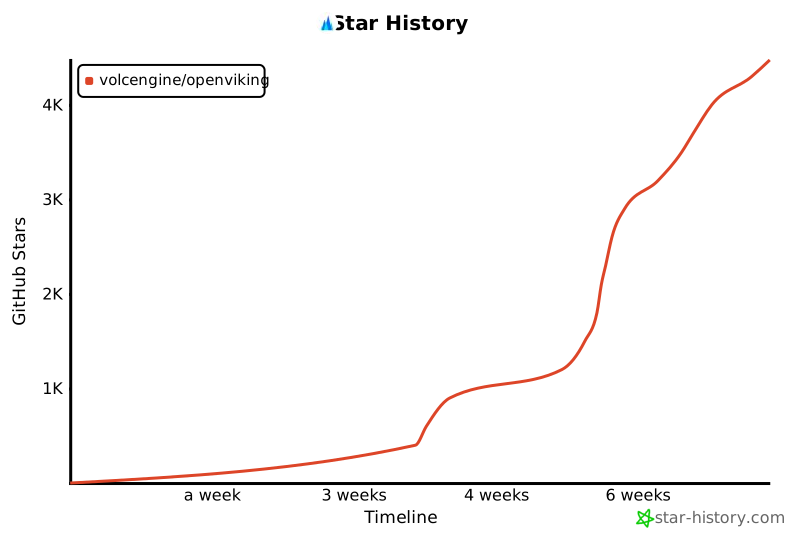](https://www.star-history.com/#volcengine/OpenViking&type=timeline&legend=top-left)+[](https://www.star-history.com/#volcengine/OpenViking\&type=timeline\&legend=top-left)## LicenseThe OpenViking project uses different licenses for different components:- **Main Project**: AGPLv3 - see the [LICENSE](./LICENSE) file for details-- **crates/ov_cli**: Apache 2.0 - see the [LICENSE](./crates/ov_cli/LICENSE) for details+- **crates/ov\_cli**: Apache 2.0 - see the [LICENSE](./crates/ov_cli/LICENSE) for details- **examples**: Apache 2.0 - see the [LICENSE](./examples/LICENSE) for details-- **third_party**: Respective original licenses of third-party projects-+- **third\_party**: Respective original licenses of third-party projects<!-- Link Definitions -->--[release-shield]: https://img.shields.io/github/v/release/volcengine/OpenViking?color=369eff&labelColor=black&logo=github&style=flat-square-[release-link]: https://github.com/volcengine/OpenViking/releases-[license-shield]: https://img.shields.io/badge/license-AGPLv3-white?labelColor=black&style=flat-square-[license-shield-link]: https://github.com/volcengine/OpenViking/blob/main/LICENSE-[last-commit-shield]: https://img.shields.io/github/last-commit/volcengine/OpenViking?color=c4f042&labelColor=black&style=flat-square-[last-commit-shield-link]: https://github.com/volcengine/OpenViking/commits/main-[github-stars-shield]: https://img.shields.io/github/stars/volcengine/OpenViking?labelColor&style=flat-square&color=ffcb47-[github-stars-link]: https://github.com/volcengine/OpenViking-[github-issues-shield]: https://img.shields.io/github/issues/volcengine/OpenViking?labelColor=black&style=flat-square&color=ff80eb-[github-issues-shield-link]: https://github.com/volcengine/OpenViking/issues-[github-contributors-shield]: https://img.shields.io/github/contributors/volcengine/OpenViking?color=c4f042&labelColor=black&style=flat-square-[github-contributors-link]: https://github.com/volcengine/OpenViking/graphs/contributorsdiff --git a/README_CN.md b/README_CN.mdindex 47d289665..e37d93574 100644--- a/README_CN.md+++ b/README_CN.md@@ -95,18 +95,14 @@ OpenViking 需要以下模型能力:#### 支持的 VLM 提供商-OpenViking 支持三种 VLM 提供商:+OpenViking 支持多种 VLM 提供商:-| 提供商 | 描述 | 获取 API Key |+| 提供商 | 描述 | 设置方式 ||----------|-------------|-------------|| `volcengine` | 火山引擎豆包模型 | [Volcengine 控制台](https://console.volcengine.com/ark/region:ark+cn-beijing/overview?briefPage=0&briefType=introduce&type=new&utm_content=OpenViking&utm_medium=devrel&utm_source=OWO&utm_term=OpenViking) || `openai` | OpenAI 官方 API | [OpenAI 平台](https://platform.openai.com) || `azure` | Azure OpenAI 服务 | [Azure OpenAI 服务](https://portal.azure.com) |-| `litellm` | 统一调用多种第三方模型 (Anthropic, DeepSeek, Gemini, vLLM, Ollama 等) | 参见 [LiteLLM 提供商](https://docs.litellm.ai/docs/providers) |--> 💡 **提示**:-> - `litellm` 支持通过统一接口调用多种模型,model 字段需遵循 [LiteLLM 格式规范](https://docs.litellm.ai/docs/providers)-> - 系统自动检测常见模型(如 `claude-*`, `deepseek-*`, `gemini-*`, `hosted_vllm/*`, `ollama/*` 等),其他模型需按 LiteLLM 格式填写完整前缀+| `openai-codex` | 通过 ChatGPT/Codex OAuth 使用 Codex VLM | 使用 `openviking-server init` |#### 提供商特定说明@@ -197,71 +193,32 @@ Volcengine 支持模型名称和端点 ID。为简单起见,建议使用模型</details><details>-<summary><b>LiteLLM (Anthropic, DeepSeek, Gemini, Qwen, vLLM, Ollama 等)</b></summary>--LiteLLM 提供对各种模型的统一访问。`model` 字段应遵循 LiteLLM 的命名约定。以下以 Claude 和 Qwen 为例:--**Anthropic:**--```json-{- "vlm": {- "provider": "litellm",- "model": "claude-3-5-sonnet-20240620",- "api_key": "your-anthropic-api-key"- }-}-```--**Qwen (DashScope):**+<summary><b>OpenAI Codex(OAuth)</b></summary>-```json-{- "vlm": {- "provider": "litellm",- "model": "dashscope/qwen-turbo",- "api_key": "your-dashscope-api-key",- "api_base": "https://dashscope.aliyuncs.com/compatible-mode/v1"- }-}-```--> 💡 **Qwen 提示**:-> - **中国/北京** 区域,使用 `api_base`:`https://dashscope.aliyuncs.com/compatible-mode/v1`-> - **国际** 区域,使用 `api_base`:`https://dashscope-intl.aliyuncs.com/compatible-mode/v1`--**常见模型格式:**--| 提供商 | 模型示例 | 说明 |-|----------|---------------|-------|-| Anthropic | `claude-3-5-sonnet-20240620` | 自动检测,使用 `ANTHROPIC_API_KEY` |-| DeepSeek | `deepseek-chat` | 自动检测,使用 `DEEPSEEK_API_KEY` |-| Gemini | `gemini-pro` | 自动检测,使用 `GEMINI_API_KEY` |-| Qwen | `dashscope/qwen-turbo` | 根据区域设置 `api_base`(见上方说明) |-| OpenRouter | `openrouter/openai/gpt-4o` | 需要完整前缀 |-| vLLM | `hosted_vllm/llama-3.1-8b` | 设置 `api_base` 为 vLLM 服务器 |-| Ollama | `ollama/llama3.1` | 设置 `api_base` 为 Ollama 服务器 |--**本地模型 (vLLM / Ollama):**+如果你希望通过 ChatGPT/Codex OAuth 会话来使用 Codex VLM,而不是标准 OpenAI API Key,可以这样配置:```bash--# 启动 Ollama-ollama serve+openviking-server init+# 在向导中选择 OpenAI Codex+openviking-server doctor``````json-// Ollama{"vlm": {- "provider": "litellm",- "model": "ollama/llama3.1",- "api_base": "http://localhost:11434"+ "provider": "openai-codex",+ "model": "gpt-5.3-codex",+ "api_base": "https://chatgpt.com/backend-api/codex",+ "temperature": 0.0,+ "max_retries": 2}}```-完整的模型支持,请参见 [LiteLLM 提供商文档](https://docs.litellm.ai/docs/providers)。+> 💡 **提示**:+> - 当 Codex OAuth 可用时,`openai-codex` 不需要 `vlm.api_key`+> - OpenViking 会把自己的 Codex 鉴权状态保存在 `~/.openviking/codex_auth.json`+> - 可以通过 `openviking-server doctor` 校验当前 Codex 鉴权是否可用</details>@@ -292,7 +249,16 @@ openviking-server doctor#### 服务器配置模板-创建配置文件 `~/.openviking/ov.conf`,复制前请删除注释:+推荐的首次配置流程是:++```bash+openviking-server init+openviking-server doctor+```++如果你在 `openviking-server init` 中选择了 `OpenAI Codex`,初始化向导会帮你导入已有 Codex 鉴权,或直接引导你完成登录。++如果你更想手动配置,再创建 `~/.openviking/ov.conf`,复制前请删除注释:```json{@@ -316,8 +282,8 @@ openviking-server doctor},"vlm": {"api_base" : "<api-endpoint>", // API 端点地址- "api_key" : "<your-api-key>", // 模型服务 API Key- "provider" : "<provider-type>", // 提供商类型 (volcengine, openai, azure, litellm 等)+ "api_key" : "<your-api-key>", // 模型服务 API Key(openai-codex 可选)+ "provider" : "<provider-type>", // 提供商类型 (volcengine, openai, azure, openai-codex 等)"api_version": "2025-01-01-preview", // (仅 azure)API 版本,可选,默认 "2025-01-01-preview""model" : "<model-name>", // VLM 模型名称或 Azure 部署名(如 doubao-seed-2-0-pro-260215 或 gpt-4-vision-preview)"max_concurrent": 100 // 语义处理的最大并发 LLM 调用(默认:100)@@ -325,7 +291,7 @@ openviking-server doctor}```-> **注意**:对于 embedding 模型,目前支持 `volcengine`(豆包)、`openai`、`azure`、`jina` 等提供商。对于 VLM 模型,我们支持 `volcengine`、`openai`、`azure` 和 `litellm` 提供商。`litellm` 提供商支持各种模型,包括 Anthropic (Claude)、DeepSeek、Gemini、Moonshot、Zhipu、DashScope、MiniMax、vLLM、Ollama 等。+> **注意**:对于 embedding 模型,目前支持 `volcengine`(豆包)、`openai`、`azure`、`jina` 等提供商。对于 VLM 模型,常见提供商包括 `volcengine`、`openai`、`azure`、`openai-codex`。#### 服务器配置示例@@ -507,9 +473,12 @@ set "OPENVIKING_CLI_CONFIG_FILE=%USERPROFILE%\.openviking\ovcli.conf"#### 启动服务器```bash+openviking-server doctoropenviking-server```+如果你的 `vlm.provider` 是 `openai-codex`,`openviking-server doctor` 已经会校验 Codex 鉴权。+或者您可以在后台运行```bashdiff --git a/README_JA.md b/README_JA.mdindex 35608aa3b..c81a9fd8d 100644--- a/README_JA.md+++ b/README_JA.md@@ -103,11 +103,6 @@ OpenVikingは3つのVLMプロバイダーをサポートしています:|----------|-------------|-------------|| `volcengine` | Volcengine Doubaoモデル | [Volcengineコンソール](https://console.volcengine.com/ark/region:ark+cn-beijing/overview?briefPage=0&briefType=introduce&type=new&utm_content=OpenViking&utm_medium=devrel&utm_source=OWO&utm_term=OpenViking) || `openai` | OpenAI公式API | [OpenAIプラットフォーム](https://platform.openai.com) |-| `litellm` | 様々なサードパーティモデルへの統合アクセス(Anthropic、DeepSeek、Gemini、vLLM、Ollamaなど) | [LiteLLMプロバイダー](https://docs.litellm.ai/docs/providers)を参照 |--> 💡 **ヒント**:-> - `litellm`は様々なモデルへの統合アクセスをサポートしています。`model`フィールドは[LiteLLMフォーマット仕様](https://docs.litellm.ai/docs/providers)に従う必要があります-> - システムは一般的なモデル(例:`claude-*`、`deepseek-*`、`gemini-*`、`hosted_vllm/*`、`ollama/*`など)を自動検出します。その他のモデルについては、LiteLLMフォーマットに従ったフルプレフィックスを使用してください#### プロバイダー固有の注意事項@@ -173,75 +168,6 @@ OpenAIの公式APIを使用:</details>-<details>-<summary><b>LiteLLM(Anthropic、DeepSeek、Gemini、Qwen、vLLM、Ollamaなど)</b></summary>--LiteLLMは様々なモデルへの統合アクセスを提供します。`model`フィールドはLiteLLMの命名規則に従う必要があります。ここではClaudeとQwenを例に説明します:--**Anthropic:**--```json-{- "vlm": {- "provider": "litellm",- "model": "claude-3-5-sonnet-20240620",- "api_key": "your-anthropic-api-key"- }-}-```--**Qwen(DashScope):**--```json-{- "vlm": {- "provider": "litellm",- "model": "dashscope/qwen-turbo", // 詳細は https://docs.litellm.ai/docs/providers/dashscope を参照- "api_key": "your-dashscope-api-key",- "api_base": "https://dashscope.aliyuncs.com/compatible-mode/v1"- }-}-```--> 💡 **Qwenのヒント**:-> - **中国/北京**リージョンの場合、`api_base`は `https://dashscope.aliyuncs.com/compatible-mode/v1` を使用-> - **国際**リージョンの場合、`api_base`は `https://dashscope-intl.aliyuncs.com/compatible-mode/v1` を使用--**一般的なモデルフォーマット:**--| プロバイダー | モデル例 | 備考 |-|----------|---------------|-------|-| Anthropic | `claude-3-5-sonnet-20240620` | 自動検出、`ANTHROPIC_API_KEY`を使用 |-| DeepSeek | `deepseek-chat` | 自動検出、`DEEPSEEK_API_KEY`を使用 |-| Gemini | `gemini-pro` | 自動検出、`GEMINI_API_KEY`を使用 |-| Qwen | `dashscope/qwen-turbo` | リージョンに基づいて`api_base`を設定(上記参照) |-| OpenRouter | `openrouter/openai/gpt-4o` | フルプレフィックスが必要 |-| vLLM | `hosted_vllm/llama-3.1-8b` | `api_base`をvLLMサーバーに設定 |-| Ollama | `ollama/llama3.1` | `api_base`をOllamaサーバーに設定 |--**ローカルモデル(vLLM / Ollama):**--```bash--# Ollamaの起動-ollama serve-```--```json-// Ollama-{- "vlm": {- "provider": "litellm",- "model": "ollama/llama3.1",- "api_base": "http://localhost:11434"- }-}-```--完全なモデルサポートについては、[LiteLLMプロバイダードキュメント](https://docs.litellm.ai/docs/providers)を参照してください。--</details>-### 3. 環境設定#### サーバー設定テンプレート@@ -277,7 +203,7 @@ ollama serve}```-> **注意**: Embeddingモデルについては、現在`volcengine`(Doubao)、`openai`、`jina`プロバイダーがサポートされています。VLMモデルについては、`volcengine`、`openai`、`litellm`の3つのプロバイダーをサポートしています。`litellm`プロバイダーは、Anthropic(Claude)、DeepSeek、Gemini、Moonshot、Zhipu、DashScope、MiniMax、vLLM、Ollamaなど様々なモデルをサポートしています。+> **注意**: Embeddingモデルについては、現在`volcengine`(Doubao)、`openai`、`jina`プロバイダーがサポートされています。VLMモデルについては、`volcengine`と`openai`をサポートしています。#### サーバー設定例diff --git a/benchmark/locomo/openclaw/eval.py b/benchmark/locomo/openclaw/eval.pyindex c24154ec2..2d6946096 100644--- a/benchmark/locomo/openclaw/eval.py+++ b/benchmark/locomo/openclaw/eval.py@@ -42,6 +42,7 @@ csv_lock = Lock()# Txt-based test file parsing (original format)# ---------------------------------------------------------------------------+def parse_test_file(path: str) -> list[dict]:"""Parse txt test file into sessions.@@ -71,7 +72,7 @@ def parse_test_file(path: str) -> list[dict]:evals = []for line in lines:if line.startswith("eval:"):- evals.append(line[len("eval:"):].strip())+ evals.append(line[len("eval:") :].strip())else:messages.append(line)@@ -85,6 +86,7 @@ def parse_test_file(path: str) -> list[dict]:# LoCoMo JSON parsing# ---------------------------------------------------------------------------+def format_locomo_message(msg: dict) -> str:"""Format a single LoCoMo message into a natural chat-style string.@@ -131,7 +133,10 @@ def load_locomo_data(if sample_index is not None:if sample_index < 0 or sample_index >= len(data):- print(f"Error: sample index {sample_index} out of range (0-{len(data)-1})", file=sys.stderr)+ print(+ f"Error: sample index {sample_index} out of range (0-{len(data) - 1})",+ file=sys.stderr,+ )sys.exit(1)return [data[sample_index]]return data@@ -172,15 +177,17 @@ def build_session_messages(parts.append(tail)combined = "\n\n".join(parts)- sessions.append({- "message": combined,- "meta": {- "sample_id": item["sample_id"],- "session_key": sk,- "date_time": date_time,- "speakers": speakers,- },- })+ sessions.append(+ {+ "message": combined,+ "meta": {+ "sample_id": item["sample_id"],+ "session_key": sk,+ "date_time": date_time,+ "speakers": speakers,+ },+ }+ )return sessions@@ -189,6 +196,7 @@ def build_session_messages(# Question time helpers# ---------------------------------------------------------------------------+def parse_locomo_datetime(date_str: str) -> datetime | None:"""解析 LoCoMo 时间格式,如 '1:56 pm on 8 May, 2023'"""try:@@ -239,6 +247,7 @@ def get_sample_question_time(sample: dict) -> str | None:# Ingest record helpers (avoid duplicate ingestion)# ---------------------------------------------------------------------------+def load_ingest_record(record_path: str = DEFAULT_INGEST_RECORD_PATH) -> dict:"""Load existing ingest record file, return empty dict if not exists."""try:@@ -296,6 +305,7 @@ def mark_ingested(# API helpers# ---------------------------------------------------------------------------+def extract_response_text(response_json: dict) -> str:"""Extract assistant text from the /v1/responses API response."""try:@@ -346,7 +356,10 @@ def get_session_id_from_key(session_key: str, user: str, agent_id: str = "main")if session_key in key and isinstance(value, dict):session_file = value.get("sessionFile")if session_file:- print(f" [session] Found sessionFile in agent '{agent_name}': {session_file}", file=sys.stderr)+ print(+ f" [session] Found sessionFile in agent '{agent_name}': {session_file}",+ file=sys.stderr,+ )return session_fileexcept json.JSONDecodeError as e:@@ -356,7 +369,10 @@ def get_session_id_from_key(session_key: str, user: str, agent_id: str = "main")print(f" [session] Error reading {sessions_file}: {e}", file=sys.stderr)continue- print(f" [session] session_key '{session_key}' not found in any agent's sessions.json", file=sys.stderr)+ print(+ f" [session] session_key '{session_key}' not found in any agent's sessions.json",+ file=sys.stderr,+ )return None@@ -435,7 +451,10 @@ def calculate_session_metrics_from_jsonl(jsonl_filename: str, agent_id: str = "mif not line.strip():continueentry = json.loads(line)- if entry.get("type") == "message" and entry.get("message", {}).get("role") == "assistant":+ if (+ entry.get("type") == "message"+ and entry.get("message", {}).get("role") == "assistant"+ ):usage["rounds"] += 1entry_usage = entry.get("message", {}).get("usage", {})usage["input_tokens"] += entry_usage.get("input", 0)@@ -452,8 +471,13 @@ def calculate_session_metrics_from_jsonl(jsonl_filename: str, agent_id: str = "mdef send_message_with_retry(- base_url: str, token: str, user: str, message: str, retries: int = 2,- agent_id: str = DEFAULT_AGENT_ID, session_key: str | None = None+ base_url: str,+ token: str,+ user: str,+ message: str,+ retries: int = 2,+ agent_id: str = DEFAULT_AGENT_ID,+ session_key: str | None = None,) -> tuple[str, dict]:"""Call send_message with up to `retries` retries on failure."""last_exc = None@@ -468,8 +492,12 @@ def send_message_with_retry(def send_message(- base_url: str, token: str, user: str, message: str,- agent_id: str = DEFAULT_AGENT_ID, session_key: str | None = None+ base_url: str,+ token: str,+ user: str,+ message: str,+ agent_id: str = DEFAULT_AGENT_ID,+ session_key: str | None = None,) -> tuple[str, dict]:"""Send a single message to the OpenClaw responses API.@@ -479,7 +507,7 @@ def send_message(headers = {"Content-Type": "application/json","Authorization": f"Bearer {token}",- "X-OpenClaw-Agent-ID": agent_id+ "X-OpenClaw-Agent-ID": agent_id,}if session_key:headers["X-OpenClaw-Session-Key"] = session_key@@ -505,7 +533,9 @@ def send_message(raise RuntimeError(f"Error parsing response from {base_url}: {e}")print(body)- usage = body.get("usage", {"input_tokens": 0, "output_tokens": 0, "cacheRead": 0, "total_tokens": 0})+ usage = body.get(+ "usage", {"input_tokens": 0, "output_tokens": 0, "cacheRead": 0, "total_tokens": 0}+ )return extract_response_text(body), usage@@ -513,6 +543,7 @@ def send_message(# Ingest: load conversations into openclaw# ---------------------------------------------------------------------------+def run_ingest(args: argparse.Namespace,) -> None:@@ -522,7 +553,7 @@ def run_ingest(if args.clear_ingest_record:ingest_record = {}save_ingest_record(ingest_record)- print(f"[INFO] All existing ingest records cleared", file=sys.stderr)+ print("[INFO] All existing ingest records cleared", file=sys.stderr)else:ingest_record = load_ingest_record()@@ -548,8 +579,13 @@ def run_ingest(label = f"{meta['session_key']} ({meta['date_time']})"# Skip already ingested sessions unless force-ingest is enabled- if not args.force_ingest and is_already_ingested(args.agent_id, user_key, sample_id, meta['session_key'], ingest_record):- print(f" [{label}] [SKIP] already ingested (use --force-ingest to reprocess)", file=sys.stderr)+ if not args.force_ingest and is_already_ingested(+ args.agent_id, user_key, sample_id, meta["session_key"], ingest_record+ ):+ print(+ f" [{label}] [SKIP] already ingested (use --force-ingest to reprocess)",+ file=sys.stderr,+ )skipped_count += 1continue@@ -557,30 +593,39 @@ def run_ingest(print(f" [{label}] {preview}...", file=sys.stderr)try:- reply, usage = send_message(args.base_url, args.token, user_key, msg, args.agent_id)+ reply, usage = send_message(+ args.base_url, args.token, user_key, msg, args.agent_id+ )print(f" -> {reply[:80]}{'...' if len(reply) > 80 else ''}", file=sys.stderr)- results.append({- "sample_id": sample_id,- "session": meta["session_key"],- "user": user_key,- "reply": reply,- "usage": usage,- })+ results.append(+ {+ "sample_id": sample_id,+ "session": meta["session_key"],+ "user": user_key,+ "reply": reply,+ "usage": usage,+ }+ )# Mark as successfully ingested- mark_ingested(args.agent_id, user_key, sample_id, meta['session_key'], ingest_record, {- "mode": "openclaw",- "date_time": meta['date_time'],- "usage": usage- })+ mark_ingested(+ args.agent_id,+ user_key,+ sample_id,+ meta["session_key"],+ ingest_record,+ {"mode": "openclaw", "date_time": meta["date_time"], "usage": usage},+ )except Exception as e:print(f" -> [ERROR] {e}", file=sys.stderr)- results.append({- "sample_id": sample_id,- "session": meta["session_key"],- "user": user_key,- "reply": f"[ERROR] {e}",- "usage": {},- })+ results.append(+ {+ "sample_id": sample_id,+ "session": meta["session_key"],+ "user": user_key,+ "reply": f"[ERROR] {e}",+ "usage": {},+ }+ )if session_id is None:session_id = get_session_id(user_key, args.agent_id)@@ -605,7 +650,7 @@ def run_ingest(# Save ingest recordsave_ingest_record(ingest_record)total_processed = len(results) + skipped_count- print(f"\n=== Ingest summary ===", file=sys.stderr)+ print("\n=== Ingest summary ===", file=sys.stderr)print(f"Total sessions: {total_processed}", file=sys.stderr)print(f"Completed: {len(results)}", file=sys.stderr)print(f"Skipped (already ingested): {skipped_count}", file=sys.stderr)@@ -625,8 +670,13 @@ def run_ingest(for msg in session["messages"]:print(f" [user] {msg}", file=sys.stderr)try:- reply, _usage = send_message(args.base_url, args.token, session_key, msg, args.agent_id)- print(f" [assistant] {reply[:80]}{'...' if len(reply) > 80 else ''}", file=sys.stderr)+ reply, _usage = send_message(+ args.base_url, args.token, session_key, msg, args.agent_id+ )+ print(+ f" [assistant] {reply[:80]}{'...' if len(reply) > 80 else ''}",+ file=sys.stderr,+ )turns.append(("user", msg))turns.append(("assistant", reply))except Exception as e:@@ -661,6 +711,7 @@ def run_ingest(# QA: run QA questions and compare with expected answers# ---------------------------------------------------------------------------+def process_single_question(sample_id: str,sample_idx: int,@@ -680,7 +731,10 @@ def process_single_question(session_key = f"qa-{sample_id}-q{original_qi}"user_key = args.user or f"eval-{sample_idx}"- print(f" [{sample_idx}] Q{original_qi}: {question[:60]}{'...' if len(question) > 60 else ''}", file=sys.stderr)+ print(+ f" [{sample_idx}] Q{original_qi}: {question[:60]}{'...' if len(question) > 60 else ''}",+ file=sys.stderr,+ )# 如果有 question_time,注入到 prompt 中if question_time:input_msg = f"Current date: {question_time}. Answer the question directly: {question}"@@ -696,7 +750,10 @@ def process_single_question(args.base_url, args.token, sample_id, input_msg, 2, args.agent_id, session_key)elapsed_seconds = time.perf_counter() - started_at- print(f" [{sample_idx}] A: {response[:60]}{'...' if len(response) > 60 else ''}", file=sys.stderr)+ print(+ f" [{sample_idx}] A: {response[:60]}{'...' if len(response) > 60 else ''}",+ file=sys.stderr,+ )# Get sessionFile path from sessions.json using session_keysession_file_path = get_session_id_from_key(session_key, user_key, args.agent_id)@@ -713,7 +770,10 @@ def process_single_question(args.agent_id,)rounds = usage.pop("rounds", 0)- print(f" [{sample_idx}] tokens (from JSONL): in={usage['input_tokens']} out={usage['output_tokens']} cacheRead={usage['cacheRead']} cacheWrite={usage['cacheWrite']} total={usage['total_tokens']} rounds={rounds}", file=sys.stderr)+ print(+ f" [{sample_idx}] tokens (from JSONL): in={usage['input_tokens']} out={usage['output_tokens']} cacheRead={usage['cacheRead']} cacheWrite={usage['cacheWrite']} total={usage['total_tokens']} rounds={rounds}",+ file=sys.stderr,+ )else:usage = {"input_tokens": api_usage.get("input_tokens", 0),@@ -723,7 +783,10 @@ def process_single_question("total_tokens": api_usage.get("total_tokens", 0),}rounds = 1 if response and not response.startswith("[ERROR]") else 0- print(f" [{sample_idx}] tokens (from API): in={usage['input_tokens']} out={usage['output_tokens']} cacheRead={usage['cacheRead']} cacheWrite={usage['cacheWrite']} total={usage['total_tokens']} rounds={rounds}", file=sys.stderr)+ print(+ f" [{sample_idx}] tokens (from API): in={usage['input_tokens']} out={usage['output_tokens']} cacheRead={usage['cacheRead']} cacheWrite={usage['cacheWrite']} total={usage['total_tokens']} rounds={rounds}",+ file=sys.stderr,+ )except Exception as e:elapsed_seconds = time.perf_counter() - started_at@@ -768,7 +831,7 @@ def run_sample_qa(question_time = get_sample_question_time(item)qas = [q for q in item.get("qa", []) if str(q.get("category", "")) != "5"]if args.count is not None:- qas = qas[:args.count]+ qas = qas[: args.count]# Filter out already executed questionsfiltered_qas = []@@ -781,16 +844,31 @@ def run_sample_qa(qas = filtered_qasif not qas:print(f"\n=== Sample {sample_id} [{sample_idx}] (user={user_key}) ===", file=sys.stderr)- print(f" All QA questions already executed, skipping sample.", file=sys.stderr)- return [], {"input_tokens": 0, "output_tokens": 0, "cacheRead": 0, "cacheWrite": 0, "total_tokens": 0}+ print(" All QA questions already executed, skipping sample.", file=sys.stderr)+ return [], {+ "input_tokens": 0,+ "output_tokens": 0,+ "cacheRead": 0,+ "cacheWrite": 0,+ "total_tokens": 0,+ }print(f"\n=== Sample {sample_id} [{sample_idx}] (user={user_key}) ===", file=sys.stderr)if question_time:print(f" Question time context: {question_time}", file=sys.stderr)- print(f" Running {len(qas)} QA question(s) with max {args.parallel} workers...", file=sys.stderr)+ print(+ f" Running {len(qas)} QA question(s) with max {args.parallel} workers...",+ file=sys.stderr,+ )records = []- sample_usage = {"input_tokens": 0, "output_tokens": 0, "cacheRead": 0, "cacheWrite": 0, "total_tokens": 0}+ sample_usage = {+ "input_tokens": 0,+ "output_tokens": 0,+ "cacheRead": 0,+ "cacheWrite": 0,+ "total_tokens": 0,+ }# Use ThreadPoolExecutor for concurrent question executionwith ThreadPoolExecutor(max_workers=args.parallel) as executor:@@ -798,7 +876,13 @@ def run_sample_qa(for original_qi, qa in qas:future = executor.submit(process_single_question,- sample_id, sample_idx, original_qi, qa, args, csv_path, question_time+ sample_id,+ sample_idx,+ original_qi,+ qa,+ args,+ csv_path,+ question_time,)futures.append(future)@@ -838,10 +922,25 @@ def save_record_to_csv(csv_path: str, record: dict) -> None:"""Save a single QA record to CSV file."""file_exists = os.path.exists(csv_path)fieldnames = [- "sample_id", "sample_idx", "qi", "question", "expected",- "response", "category", "evidence", "elapsed_seconds", "rounds", "input_tokens",- "output_tokens", "cacheRead", "cacheWrite", "total_tokens",- "timestamp", "jsonl_filename", "result", "reasoning"+ "sample_id",+ "sample_idx",+ "qi",+ "question",+ "expected",+ "response",+ "category",+ "evidence",+ "elapsed_seconds",+ "rounds",+ "input_tokens",+ "output_tokens",+ "cacheRead",+ "cacheWrite",+ "total_tokens",+ "timestamp",+ "jsonl_filename",+ "result",+ "reasoning",]# Flatten usage fields@@ -892,19 +991,31 @@ def run_qa(# 确保输出目录存在os.makedirs(os.path.dirname(csv_path), exist_ok=True)executed_records = load_executed_records(csv_path)- print(f" Loaded {len(executed_records)} already executed records from {csv_path}", file=sys.stderr)+ print(+ f" Loaded {len(executed_records)} already executed records from {csv_path}",+ file=sys.stderr,+ )results_list = []for idx, item in enumerate(samples):result = run_sample_qa(item, idx + 1, args, executed_records, csv_path)results_list.append(result)- total_usage = {"input_tokens": 0, "output_tokens": 0, "cacheRead": 0, "cacheWrite": 0, "total_tokens": 0}+ total_usage = {+ "input_tokens": 0,+ "output_tokens": 0,+ "cacheRead": 0,+ "cacheWrite": 0,+ "total_tokens": 0,+ }for _, sample_usage in results_list:for k in total_usage:total_usage[k] += sample_usage[k]- print(f"\n total tokens: in={total_usage['input_tokens']} out={total_usage['output_tokens']} total={total_usage['total_tokens']}", file=sys.stderr)+ print(+ f"\n total tokens: in={total_usage['input_tokens']} out={total_usage['output_tokens']} total={total_usage['total_tokens']}",+ file=sys.stderr,+ )# Generate timestamp once for all backupstimestamp = time.strftime("%Y%m%d_%H%M%S")@@ -913,7 +1024,9 @@ def run_qa(# Backup CSV file with timestampif os.path.exists(csv_path):csv_path_obj = Path(csv_path)- backup_csv_path = csv_path_obj.parent / f"{csv_path_obj.stem}_{timestamp}{csv_path_obj.suffix}"+ backup_csv_path = (+ csv_path_obj.parent / f"{csv_path_obj.stem}_{timestamp}{csv_path_obj.suffix}"+ )try:shutil.copy2(csv_path, backup_csv_path)print(f" CSV backed up to: {backup_csv_path}", file=sys.stderr)@@ -924,7 +1037,10 @@ def run_qa(# Backup output summary file tooif os.path.exists(args.output):output_path_obj = Path(args.output)- backup_output_path = output_path_obj.parent / f"{output_path_obj.stem}_{timestamp}{output_path_obj.suffix}"+ backup_output_path = (+ output_path_obj.parent+ / f"{output_path_obj.stem}_{timestamp}{output_path_obj.suffix}"+ )try:shutil.copy2(args.output, backup_output_path)print(f" Summary backed up to: {backup_output_path}", file=sys.stderr)@@ -948,6 +1064,7 @@ def run_qa(# CLI# ---------------------------------------------------------------------------+def parse_session_range(s: str) -> tuple[int, int]:"""Parse '1-4' or '3' into (lo, hi) inclusive tuple."""if "-" in s:@@ -963,7 +1080,11 @@ def main():default_csv_path = str(script_dir / "result" / "qa_results.csv")parser = argparse.ArgumentParser(description="Evaluate OpenClaw responses")- parser.add_argument("mode", choices=["ingest", "qa"], help="Mode: ingest (load conversations) or qa (run QA eval)")+ parser.add_argument(+ "mode",+ choices=["ingest", "qa"],+ help="Mode: ingest (load conversations) or qa (run QA eval)",+ )parser.add_argument("input", help="Path to test file (.txt or .json)")parser.add_argument("--output",@@ -1008,7 +1129,8 @@ def main():help="QA mode: user UUID from a prior ingest run to target.",)parser.add_argument(- "-p", "--parallel",+ "-p",+ "--parallel",type=int,default=10,metavar="N",diff --git a/benchmark/locomo/openclaw/import_to_ov.py b/benchmark/locomo/openclaw/import_to_ov.pyindex 2865b7fce..7e5973124 100644--- a/benchmark/locomo/openclaw/import_to_ov.py+++ b/benchmark/locomo/openclaw/import_to_ov.py@@ -20,7 +20,7 @@ import timeimport tracebackfrom datetime import datetime, timedeltafrom pathlib import Path-from typing import List, Dict, Any, Tuple, Optional+from typing import Any, Dict, List, Optional, Tupleimport openviking as ov@@ -306,7 +306,7 @@ async def viking_ingest(if task_id:# 轮询任务状态直到完成max_attempts = 3600 # 最多等待1小时- for attempt in range(max_attempts):+ for _attempt in range(max_attempts):task = await client.get_task(task_id)status = task.get("status") if task else "unknown"if status == "completed":@@ -391,7 +391,10 @@ async def process_single_session(except Exception as e:elapsed_seconds = time.perf_counter() - started_at- print(f" -> [ERROR] [{sample_id}/{session_key}] elapsed={elapsed_seconds:.3f}s, {e}", file=sys.stderr)+ print(+ f" -> [ERROR] [{sample_id}/{session_key}] elapsed={elapsed_seconds:.3f}s, {e}",+ file=sys.stderr,+ )traceback.print_exc(file=sys.stderr)# Write error record@@ -517,7 +520,7 @@ async def run_import(args: argparse.Namespace) -> None:# 不同 sample 之间并行执行tasks = [asyncio.create_task(process_sample(item)) for item in samples]- results = await asyncio.gather(*tasks, return_exceptions=True)+ await asyncio.gather(*tasks, return_exceptions=True)else:# Plain text format@@ -529,11 +532,9 @@ async def run_import(args: argparse.Namespace) -> None:print(f"\n=== Text Session {idx} ===", file=sys.stderr)# Skip already ingested sessions unless force-ingest is enabled- if not args.force_ingest and is_already_ingested(- "txt", session_key, success_keys- ):+ if not args.force_ingest and is_already_ingested("txt", session_key, success_keys):print(- f" [SKIP] already imported (use --force-ingest to reprocess)", file=sys.stderr+ " [SKIP] already imported (use --force-ingest to reprocess)", file=sys.stderr)skipped_count += 1continue@@ -579,12 +580,12 @@ async def run_import(args: argparse.Namespace) -> None:# Final summarytotal_processed = success_count + error_count + skipped_count- print(f"\n=== Import summary ===", file=sys.stderr)+ print("\n=== Import summary ===", file=sys.stderr)print(f"Total sessions: {total_processed}", file=sys.stderr)print(f"Successfully imported: {success_count}", file=sys.stderr)print(f"Failed: {error_count}", file=sys.stderr)print(f"Skipped (already imported): {skipped_count}", file=sys.stderr)- print(f"\n=== Token usage summary ===", file=sys.stderr)+ print("\n=== Token usage summary ===", file=sys.stderr)print(f"Total Embedding tokens: {total_embedding_tokens}", file=sys.stderr)print(f"Total VLM tokens: {total_vlm_tokens}", file=sys.stderr)if success_count > 0:@@ -593,7 +594,7 @@ async def run_import(args: argparse.Namespace) -> None:file=sys.stderr,)print(f"Average VLM per session: {total_vlm_tokens // success_count}", file=sys.stderr)- print(f"\nResults saved to:", file=sys.stderr)+ print("\nResults saved to:", file=sys.stderr)print(f" - Success records: {args.success_csv}", file=sys.stderr)print(f" - Error logs: {args.error_log}", file=sys.stderr)diff --git a/benchmark/locomo/openclaw/stat_judge_result.py b/benchmark/locomo/openclaw/stat_judge_result.pyindex b734970e0..c76a8e54b 100644--- a/benchmark/locomo/openclaw/stat_judge_result.py+++ b/benchmark/locomo/openclaw/stat_judge_result.py@@ -140,12 +140,12 @@ def process_qa_results(input_path: str) -> list[str]:f"Correct: {correct:,}",f"Wrong: {wrong:,}",f"Accuracy: {accuracy:.2%}",- f"\nElapsed time (QA):",+ "\nElapsed time (QA):",f" Total elapsed seconds: {total_elapsed_seconds:,.3f}",f" Avg elapsed seconds: {avg_elapsed_seconds:,.3f}",f" Min elapsed seconds: {(min_elapsed_seconds or 0.0):,.3f}",f" Max elapsed seconds: {(max_elapsed_seconds or 0.0):,.3f}",- f"\nToken usage (QA):",+ "\nToken usage (QA):",f" Total no-cache tokens (input_tokens): {total_no_cache_tokens:,}",f" Total cacheRead tokens: {total_cache_read_tokens:,}",f" Total output tokens: {total_output_tokens:,}",@@ -182,7 +182,7 @@ def process_import_csv(input_path: str) -> list[str]:return ["=== OpenViking Import Token Statistics ===",f"Total sessions: {valid_rows:,}",- f"\nToken usage (Import):",+ "\nToken usage (Import):",f" Total embedding tokens: {total_embedding:,}",f" Total VLM tokens: {total_vlm:,}",f" Total tokens: {total_total:,}",diff --git a/benchmark/vaka/vikingbot/import_to_ov.py b/benchmark/vaka/vikingbot/import_to_ov.pyindex 26cb5907c..87a556c73 100644--- a/benchmark/vaka/vikingbot/import_to_ov.py+++ b/benchmark/vaka/vikingbot/import_to_ov.py@@ -23,7 +23,6 @@ from vaka_utils import (select_cases,)-SCRIPT_DIR = Path(__file__).parent.resolve()DEFAULT_RESULT_DIR = SCRIPT_DIR / "result"DEFAULT_SUCCESS_CSV = str(DEFAULT_RESULT_DIR / "import_success.csv")@@ -323,7 +322,9 @@ async def viking_ingest("for example: uv run python benchmark/vaka/vikingbot/import_to_ov.py") from exc- client = ov.AsyncHTTPClient(url=openviking_url, account=account, user=user_id, agent_id=agent_id)+ client = ov.AsyncHTTPClient(+ url=openviking_url, account=account, user=user_id, agent_id=agent_id+ )await client.initialize()try:create_res = await client.create_session()diff --git a/benchmark/vaka/vikingbot/judge.py b/benchmark/vaka/vikingbot/judge.pyindex c4554a1f7..821bff7ba 100644--- a/benchmark/vaka/vikingbot/judge.py+++ b/benchmark/vaka/vikingbot/judge.py@@ -15,6 +15,7 @@ except ImportError:def load_dotenv(*args, **kwargs) -> bool:return False+try:from openai import AsyncOpenAIexcept ImportError:diff --git a/benchmark/vaka/vikingbot/run_eval.py b/benchmark/vaka/vikingbot/run_eval.pyindex a311b6f95..c090f1640 100644--- a/benchmark/vaka/vikingbot/run_eval.py+++ b/benchmark/vaka/vikingbot/run_eval.py@@ -22,7 +22,6 @@ from vaka_utils import (select_cases,)-SCRIPT_DIR = Path(__file__).parent.resolve()DEFAULT_OUTPUT = str(SCRIPT_DIR / "result" / "vaka_qa_result.csv")@@ -144,13 +143,9 @@ def main() -> None:for case in cases:if args.strict_complete_case and not case_has_all_sessions(case, args.case_size):present = ",".join(str(sid) for sid in sorted(present_session_ids(case)))- raise ValueError(- f"{case['case_id']} is incomplete. Present local sessions: {present}"- )+ raise ValueError(f"{case['case_id']} is incomplete. Present local sessions: {present}")- eval_rows = [- row for row in case["rows"] if row["_global_session_id"] in eval_sessions- ]+ eval_rows = [row for row in case["rows"] if row["_global_session_id"] in eval_sessions]eval_rows.sort(key=lambda row: row["_row_index"])for question_index, row in enumerate(eval_rows):if args.count is not None and len(output_rows) >= args.count:diff --git a/benchmark/vaka/vikingbot/stat_judge_result.py b/benchmark/vaka/vikingbot/stat_judge_result.pyindex 0b3ea124f..54492c474 100644--- a/benchmark/vaka/vikingbot/stat_judge_result.py+++ b/benchmark/vaka/vikingbot/stat_judge_result.py@@ -7,7 +7,6 @@ import sysfrom collections import defaultdictfrom pathlib import Path-SCRIPT_DIR = Path(__file__).parent.resolve()DEFAULT_INPUT = str(SCRIPT_DIR / "result" / "vaka_qa_result.csv")diff --git a/benchmark/vaka/vikingbot/vaka_utils.py b/benchmark/vaka/vikingbot/vaka_utils.pyindex 42bed417d..9f2880b51 100644--- a/benchmark/vaka/vikingbot/vaka_utils.py+++ b/benchmark/vaka/vikingbot/vaka_utils.py@@ -6,7 +6,6 @@ from collections import OrderedDictfrom pathlib import Pathfrom typing import Any-DEFAULT_INPUT = "data/vaka_locomo.csv"DEFAULT_CASE_SIZE = 10DEFAULT_MEMORY_SESSIONS = "1-70"diff --git a/bot/vikingbot/__init__.py b/bot/vikingbot/__init__.pyindex a9a34240e..885553496 100644--- a/bot/vikingbot/__init__.py+++ b/bot/vikingbot/__init__.py@@ -3,7 +3,8 @@ vikingbot - A lightweight AI agent framework"""import warnings-from importlib.metadata import PackageNotFoundError, version as _pkg_version+from importlib.metadata import PackageNotFoundError+from importlib.metadata import version as _pkg_versiontry:__version__ = _pkg_version("openviking")diff --git a/bot/vikingbot/agent/context.py b/bot/vikingbot/agent/context.pyindex 475f337a0..d4d2dfb1c 100644--- a/bot/vikingbot/agent/context.py+++ b/bot/vikingbot/agent/context.py@@ -70,7 +70,10 @@ class ContextBuilder:self._templates_ensured = Trueasync def build_system_prompt(- self, session_key: SessionKey, ov_tools_enable: bool = True, profile_user_list: list[str] | None = None+ self,+ session_key: SessionKey,+ ov_tools_enable: bool = True,+ profile_user_list: list[str] | None = None,) -> str:"""Build the system prompt from bootstrap files, memory, and skills.@@ -152,7 +155,12 @@ Skills with available="false" need dependencies installed first - you can try inreturn "\n\n---\n\n".join(parts)async def _build_user_memory(- self, session_key: SessionKey, current_message: str, sender_id: str, memory_user: str, ov_tools_enable: bool = True+ self,+ session_key: SessionKey,+ current_message: str,+ sender_id: str,+ memory_user: str,+ ov_tools_enable: bool = True,) -> str:"""Build the system prompt from bootstrap files, memory, and skills.@@ -189,18 +197,17 @@ Skills with available="false" need dependencies installed first - you can try inviking_memory = await self.memory.get_viking_memory_context(current_message=current_message, workspace_id=workspace_id, sender_id=user)- logger.info(f'viking_memory={viking_memory}')+ logger.info(f"viking_memory={viking_memory}")cost = round(_time.time() - start, 2)logger.info(f"[READ_USER_MEMORY]: cost {cost}s, memory={viking_memory[:50] if viking_memory else 'None'}")if viking_memory:- parts.append(- f"## openviking_search(query=[user_query])\n"- f"{viking_memory}"- )+ parts.append(f"## openviking_search(query=[user_query])\n{viking_memory}")- parts.append("Reply in the same language as the user's query, ignoring the language of the reference materials. User's query:")+ parts.append(+ "Reply in the same language as the user's query, ignoring the language of the reference materials. User's query:"+ )return "\n\n---\n\n".join(parts)@@ -238,7 +245,7 @@ You have two workspaces:2. OpenViking workspace: managed via OpenViking tools- Custom skills: {workspace_display}/skills/{{skill-name}}/SKILL.md-IMPORTANT:+IMPORTANT:- When responding to direct questions or conversations, reply directly with your text response.- Only use the 'message' tool when you need to send a message to a specific chat channel (like WhatsApp).For normal conversation, just respond with text - do not call the message tool.- Always be helpful, accurate, and concise. When using tools, think step by step: what you know, what you need, and why you chose this tool.@@ -299,7 +306,11 @@ IMPORTANT:# Useruser_info = await self._build_user_memory(- session_key, current_message, self._sender_id, memory_user, ov_tools_enable=ov_tools_enable+ session_key,+ current_message,+ self._sender_id,+ memory_user,+ ov_tools_enable=ov_tools_enable,)messages.append({"role": "user", "content": user_info})diff --git a/bot/vikingbot/agent/loop.py b/bot/vikingbot/agent/loop.pyindex 32c9cdfbb..d3cc26474 100644--- a/bot/vikingbot/agent/loop.py+++ b/bot/vikingbot/agent/loop.py@@ -14,7 +14,6 @@ from loguru import loggerfrom vikingbot.agent.context import ContextBuilderfrom vikingbot.agent.memory import MemoryStore-from vikingbot.heartbeat.service import HEARTBEAT_METADATA_KEY, is_heartbeat_noop_responsefrom vikingbot.agent.subagent import SubagentManagerfrom vikingbot.agent.tools import register_default_toolsfrom vikingbot.agent.tools.registry import ToolRegistry@@ -22,6 +21,7 @@ from vikingbot.bus.events import InboundMessage, OutboundEventType, OutboundMessfrom vikingbot.bus.queue import MessageBusfrom vikingbot.config import load_configfrom vikingbot.config.schema import BotMode, Config, SessionKey+from vikingbot.heartbeat.service import HEARTBEAT_METADATA_KEY, is_heartbeat_noop_responsefrom vikingbot.hooks import HookContextfrom vikingbot.hooks.manager import hook_managerfrom vikingbot.providers.base import LLMProvider@@ -169,7 +169,7 @@ class AgentLoop:if self._mcp_stack:try:await self._mcp_stack.aclose()- except (RuntimeError, BaseExceptionGroup):+ except Exception:pass # MCP SDK cancel scope cleanup is noisy but harmlessself._mcp_stack = Noneself._mcp_connected = False@@ -329,7 +329,7 @@ class AgentLoop:"arguments": json.dumps(args),},}- for tc, args in zip(response.tool_calls, args_list)+ for tc, args in zip(response.tool_calls, args_list, strict=False)]messages = self.context.add_assistant_message(messages,@@ -404,9 +404,7 @@ class AgentLoop:final_content = response.contentbreak- if final_content is None or (- isinstance(final_content, str) and not final_content.strip()- ):+ if final_content is None or (isinstance(final_content, str) and not final_content.strip()):if iteration >= self.max_iterations:final_content = f"Reached {self.max_iterations} iterations without completion."else:@@ -494,7 +492,7 @@ class AgentLoop:is_group_chat = msg.metadata.get("chat_type") == "group" if msg.metadata else Falseif is_group_chat:cmd = msg.content- cmd = re.sub(r'^\[[^\]]+\]:\s*', '', cmd)+ cmd = re.sub(r"^\[[^\]]+\]:\s*", "", cmd)cmd = cmd.replace(f"@{msg.sender_id}", "").strip().lower()else:cmd = msg.content.strip().lower()@@ -502,20 +500,24 @@ class AgentLoop:# Clone session for async consolidation, then immediately clear originalif not self._check_cmd_auth(msg):return OutboundMessage(- session_key=msg.session_key, content="🐈 Sorry, you are not authorized to use this command.",- metadata=msg.metadata+ session_key=msg.session_key,+ content="🐈 Sorry, you are not authorized to use this command.",+ metadata=msg.metadata,)session.clear()await self.sessions.save(session)return OutboundMessage(- session_key=msg.session_key, content="🐈 New session started. Session history droped.", metadata=msg.metadata+ session_key=msg.session_key,+ content="🐈 New session started. Session history droped.",+ metadata=msg.metadata,)elif cmd == "/compact":# Clone session for async consolidation, then immediately clear originalif not self._check_cmd_auth(msg):return OutboundMessage(- session_key=msg.session_key, content="🐈 Sorry, you are not authorized to use this command.",- metadata=msg.metadata+ session_key=msg.session_key,+ content="🐈 Sorry, you are not authorized to use this command.",+ metadata=msg.metadata,)session_clone = session.clone()session.clear()@@ -523,25 +525,30 @@ class AgentLoop:# Run consolidation in backgroundawait self._safe_consolidate_memory(session_clone, archive_all=True)return OutboundMessage(- session_key=msg.session_key, content="🐈 New session started. Memory consolidated.", metadata=msg.metadata+ session_key=msg.session_key,+ content="🐈 New session started. Memory consolidated.",+ metadata=msg.metadata,)if cmd == "/remember":if not self._check_cmd_auth(msg):return OutboundMessage(- session_key=msg.session_key, content="🐈 Sorry, you are not authorized to use this command.",- metadata=msg.metadata+ session_key=msg.session_key,+ content="🐈 Sorry, you are not authorized to use this command.",+ metadata=msg.metadata,)if ov_tools_enable:session_clone = session.clone()await self._consolidate_viking_memory(session_clone)return OutboundMessage(- session_key=msg.session_key, content="This conversation has been submitted to memory storage.", metadata=msg.metadata+ session_key=msg.session_key,+ content="This conversation has been submitted to memory storage.",+ metadata=msg.metadata,)if cmd == "/help":return OutboundMessage(session_key=msg.session_key,content="🐈 vikingbot commands:\n/new — Start a new conversation\n/remember — Submit current session to memories and start new session\n/help — Show available commands",- metadata=msg.metadata+ metadata=msg.metadata,)# Debug mode handling@@ -616,7 +623,10 @@ class AgentLoop:if not (is_heartbeat and is_heartbeat_noop_response(final_content)):session.add_message("user", msg.content, sender_id=msg.sender_id)session.add_message(- "assistant", final_content, tools_used=tools_used if tools_used else None, token_usage=token_usage,+ "assistant",+ final_content,+ tools_used=tools_used if tools_used else None,+ token_usage=token_usage,sender_id=msg.sender_id,)await self.sessions.save(session)@@ -633,7 +643,7 @@ class AgentLoop:token_usage=token_usage,time_cost=time_cost,iteration=iteration,- tools_used_names=tools_used_names+ tools_used_names=tools_used_names,)finally:long_running_notified = True@@ -701,9 +711,7 @@ class AgentLoop:ov_tools_enable=ov_tools_enable,)- if final_content is None or (- isinstance(final_content, str) and not final_content.strip()- ):+ if final_content is None or (isinstance(final_content, str) and not final_content.strip()):final_content = "Background task completed."# Save to session (mark as system message in history)@@ -818,7 +826,9 @@ Respond with ONLY valid JSON, no markdown fences.""""""Consolidate old messages into MEMORY.md + HISTORY.md. Works on a cloned session."""try:if not session.messages:- logger.info(f"No messages to commit openviking for session {session.key.safe_name()} (allow_from filter applied)")+ logger.info(+ f"No messages to commit openviking for session {session.key.safe_name()} (allow_from filter applied)"+ )return# use openviking tools to extract memory@@ -856,13 +866,15 @@ Respond with ONLY valid JSON, no markdown fences."""allow_from.append(self.config.ov_server.admin_user_id)channel_config = self._get_channel_config(msg.session_key)if channel_config:- allow_cmd = getattr(channel_config, 'allow_cmd_from', [])+ allow_cmd = getattr(channel_config, "allow_cmd_from", [])if allow_cmd:allow_from.extend(allow_cmd)# If channel not found or sender not in allow_from list, ignore messageif msg.sender_id not in allow_from:- logger.debug(f"Sender {msg.sender_id} not allowed in channel {msg.session_key.channel_key()}")+ logger.debug(+ f"Sender {msg.sender_id} not allowed in channel {msg.session_key.channel_key()}"+ )return Falsereturn Truediff --git a/bot/vikingbot/channels/base.py b/bot/vikingbot/channels/base.pyindex afa9c2747..6ad8cbb7d 100644--- a/bot/vikingbot/channels/base.py+++ b/bot/vikingbot/channels/base.py@@ -11,7 +11,7 @@ from loguru import loggerfrom vikingbot.bus.events import InboundMessage, OutboundMessagefrom vikingbot.bus.queue import MessageBus-from vikingbot.config.schema import SessionKey, BaseChannelConfig+from vikingbot.config.schema import BaseChannelConfig, SessionKeyfrom vikingbot.utils import get_data_path# Optional HTML processing librariesdiff --git a/bot/vikingbot/channels/feishu.py b/bot/vikingbot/channels/feishu.pyindex 8fe9187b8..66a60c0b5 100644--- a/bot/vikingbot/channels/feishu.py+++ b/bot/vikingbot/channels/feishu.py@@ -31,10 +31,15 @@ except ImportError:from vikingbot.bus.events import OutboundMessagefrom vikingbot.bus.queue import MessageBusfrom vikingbot.channels.base import BaseChannel-from vikingbot.config.schema import FeishuChannelConfig, BotMode+from vikingbot.config.schema import BotMode, FeishuChannelConfigtry:import lark_oapi as lark+ from lark_oapi.api.contact.v3 import (+ BatchGetIdUserRequest,+ BatchGetIdUserRequestBody,+ GetUserRequest,+ )from lark_oapi.api.im.v1 import (CreateMessageReactionRequest,CreateMessageReactionRequestBody,@@ -46,12 +51,7 @@ try:GetMessageResourceRequest,P2ImMessageReceiveV1,ReplyMessageRequest,- ReplyMessageRequestBody- )- from lark_oapi.api.contact.v3 import (- GetUserRequest,- BatchGetIdUserRequest,- BatchGetIdUserRequestBody+ ReplyMessageRequestBody,)FEISHU_AVAILABLE = True@@ -188,7 +188,7 @@ class FeishuChannel(BaseChannel):# Handle failed responseif not response.success():- raw_detail = getattr(getattr(response, 'raw', None), 'content', response.msg)+ raw_detail = getattr(getattr(response, "raw", None), "content", response.msg)raise Exception(f"Failed to download image: code={response.code}, msg={raw_detail}, log_id={response.get_log_id()}")@@ -215,14 +215,15 @@ class FeishuChannel(BaseChannel):return "group" # 默认普通群try:- request: GetChatRequest = GetChatRequest.builder() \- .chat_id(chat_id) \- .user_id_type("open_id") \- .build()+ request: GetChatRequest = (+ GetChatRequest.builder().chat_id(chat_id).user_id_type("open_id").build()+ )response = await self._client.im.v1.chat.aget(request)# 处理失败返回if not response.success():- logger.warning(f"client.im.v1.chat.get failed, code: {response.code}, msg: {response.msg}, log_id: {response.get_log_id()}")+ logger.warning(+ f"client.im.v1.chat.get failed, code: {response.code}, msg: {response.msg}, log_id: {response.get_log_id()}"+ )return "group"# 处理业务结果@@ -672,7 +673,9 @@ class FeishuChannel(BaseChannel):async def _download_and_save_image(self, image_key: str, message_id: str) -> str | None:"""Download single Feishu image and save to local, return file path or None if failed."""try:- logger.info(f"Downloading Feishu image with image_key: {image_key}, message_id: {message_id}")+ logger.info(+ f"Downloading Feishu image with image_key: {image_key}, message_id: {message_id}"+ )image_bytes = await self._download_feishu_image(image_key, message_id)if not image_bytes:logger.warning(f"Could not download image for image_key: {image_key}")@@ -682,6 +685,7 @@ class FeishuChannel(BaseChannel):media_dir.mkdir(parents=True, exist_ok=True)import uuid+file_path = media_dir / f"feishu_{uuid.uuid4().hex[:16]}.png"file_path.write_bytes(image_bytes)@@ -690,10 +694,13 @@ class FeishuChannel(BaseChannel):except Exception as e:logger.warning(f"Failed to download Feishu image {image_key}: {e}")import traceback+logger.debug(f"Stack trace: {traceback.format_exc()}")return None- async def _parse_message_content(self, message: Any, msg_type: str, message_id: str) -> tuple[str, list[str]]:+ async def _parse_message_content(+ self, message: Any, msg_type: str, message_id: str+ ) -> tuple[str, list[str]]:"""Parse message content and extract media files."""content = ""media = []@@ -737,8 +744,7 @@ class FeishuChannel(BaseChannel):# Download images in parallelif image_keys:download_tasks = [- self._download_and_save_image(img_key, message_id)- for img_key in image_keys+ self._download_and_save_image(img_key, message_id) for img_key in image_keys]results = await asyncio.gather(*download_tasks)media = [path for path in results if path is not None]@@ -750,7 +756,9 @@ class FeishuChannel(BaseChannel):return content, media- async def _check_should_process(self, chat_type: str, chat_id: str, message: Any, is_mentioned: bool) -> bool:+ async def _check_should_process(+ self, chat_type: str, chat_id: str, message: Any, is_mentioned: bool+ ) -> bool:"""Check if message should be processed based on group/thread rules."""if chat_type != "group":return True@@ -790,7 +798,9 @@ class FeishuChannel(BaseChannel):# Directly get user by open_idif GetUserRequest:# Use open_id directly with user_id_type="open_id"- user_request = GetUserRequest.builder().user_id(open_id).user_id_type("open_id").build()+ user_request = (+ GetUserRequest.builder().user_id(open_id).user_id_type("open_id").build()+ )user_response = self._client.contact.v3.user.get(user_request)if user_response.success() and user_response.data and user_response.data.user:@@ -904,7 +914,10 @@ class FeishuChannel(BaseChannel):self._processed_message_ids[message_id] = None# 定期清理去重缓存(每100条清理一次,减少开销)- if len(self._processed_message_ids) % 100 == 0 and len(self._processed_message_ids) > 1000:+ if (+ len(self._processed_message_ids) % 100 == 0+ and len(self._processed_message_ids) > 1000+ ):while len(self._processed_message_ids) > 500:self._processed_message_ids.popitem(last=False)@@ -930,14 +943,16 @@ class FeishuChannel(BaseChannel):# 5. 检查是否被@is_mentioned = Falsebot_name = self.config.bot_name- if hasattr(message, 'mentions') and message.mentions and bot_name:+ if hasattr(message, "mentions") and message.mentions and bot_name:for mention in message.mentions:- if hasattr(mention, 'name') and mention.name == bot_name:+ if hasattr(mention, "name") and mention.name == bot_name:is_mentioned = Truebreak# 6. 检查是否需要处理该消息- should_process = await self._check_should_process(chat_type, chat_id, message, is_mentioned)+ should_process = await self._check_should_process(+ chat_type, chat_id, message, is_mentioned+ )# 7. 添加已读表情if should_process:@@ -947,14 +962,14 @@ class FeishuChannel(BaseChannel):# 8. 处理@占位符:从 message.mentions 中直接获取 name 和 idmention_name_map = {}- if hasattr(message, 'mentions') and message.mentions:+ if hasattr(message, "mentions") and message.mentions:for idx, mention in enumerate(message.mentions):placeholder = f"@_user_{idx + 1}"- if hasattr(mention, 'id') and mention.id and placeholder in content:+ if hasattr(mention, "id") and mention.id and placeholder in content:# mention.id 是 UserId 对象,直接取 open_iduser_id = mention.id.open_id# 保存 name 供后续使用- if hasattr(mention, 'name') and mention.name:+ if hasattr(mention, "name") and mention.name:mention_name_map[user_id] = mention.name# 先替换成 @open_id 格式content = content.replace(placeholder, f"@{user_id}")diff --git a/docs/en/api/01-overview.md b/docs/en/api/01-overview.mdindex 19d74bd5d..5835e2ff6 100644--- a/docs/en/api/01-overview.md+++ b/docs/en/api/01-overview.md@@ -35,7 +35,7 @@ Minimal configuration example:"dense": {"api_base": "<api-endpoint>","api_key": "<your-api-key>",- "provider": "<volcengine|openai|jina>",+ "provider": "<volcengine|openai|jina|...>","dimension": 1024,"model": "<model-name>"}@@ -43,12 +43,14 @@ Minimal configuration example:"vlm": {"api_base": "<api-endpoint>","api_key": "<your-api-key>",- "provider": "<volcengine|openai|jina>",+ "provider": "<volcengine|openai|openai-codex|kimi|glm>","model": "<model-name>"}}```+For `provider: "openai-codex"`, `vlm.api_key` is optional once Codex OAuth is available through `openviking-server init`.+For full configuration options and provider-specific examples, see the [Configuration Guide](../guides/01-configuration.md).### HTTP Modediff --git a/docs/en/getting-started/02-quickstart.md b/docs/en/getting-started/02-quickstart.mdindex 4212a8172..710cc9af7 100644--- a/docs/en/getting-started/02-quickstart.md+++ b/docs/en/getting-started/02-quickstart.md@@ -82,13 +82,21 @@ OpenViking requires the following model capabilities:OpenViking supports multiple model services:- **Volcengine (Doubao Models)**: Recommended, cost-effective with good performance, free quota for new users. For purchase and activation, see: [Volcengine Purchase Guide](../guides/02-volcengine-purchase-guide.md)- **OpenAI Models**: Supports GPT-4V and other VLM models, plus OpenAI Embedding models+- **OpenAI Codex**: Supports Codex as the VLM provider through ChatGPT/Codex OAuth- **Other Custom Model Services**: Supports model services compatible with OpenAI API format## Configuration### Configuration File Template-Create a configuration file `~/.openviking/ov.conf`:+Recommended first-time setup:++```bash+openviking-server init+openviking-server doctor+```++If you prefer manual setup, create `~/.openviking/ov.conf`:```json{@@ -110,8 +118,12 @@ Create a configuration file `~/.openviking/ov.conf`:}```+`provider`, `model`, `api_base`, and `api_key` depend on the VLM service you choose. Some providers may use local OAuth state instead of a manually copied API key.+For complete examples for each model provider, see [Configuration Guide - Examples](../guides/01-configuration.md#configuration-examples).+For first-time setup, `openviking-server init` is the recommended path. It helps you pick a provider and writes a working config template for the selected setup.+### Environment VariablesWhen the config file is at the default path `~/.openviking/ov.conf`, no additional setup is needed — OpenViking loads it automatically.diff --git a/docs/en/getting-started/03-quickstart-server.md b/docs/en/getting-started/03-quickstart-server.mdindex 45ec3d28b..16664ed92 100644--- a/docs/en/getting-started/03-quickstart-server.md+++ b/docs/en/getting-started/03-quickstart-server.md@@ -11,6 +11,16 @@ Run OpenViking as a standalone HTTP server and connect from any client.Make sure you have a config file at `~/.openviking/ov.conf` with your model and storage settings (see [Configuration](../guides/01-configuration.md)).+For first-time setup, run `openviking-server init` first.++Before startup, validate local setup:++```bash+openviking-server doctor+```++`openviking-server doctor` validates that the configured local setup is usable, including provider-specific auth when required.+```bash# Config file at default path ~/.openviking/ov.conf — just startopenviking-server@@ -35,6 +45,8 @@ curl http://localhost:1933/health# {"status": "ok"}```+`openviking-server doctor` checks local configuration, model access, and auth readiness. `curl /health` only confirms that the server process is already running.+## Connect with Python SDK```pythondiff --git a/docs/en/guides/01-configuration.md b/docs/en/guides/01-configuration.mdindex f9dc0ce19..760e1897e 100644--- a/docs/en/guides/01-configuration.md+++ b/docs/en/guides/01-configuration.md@@ -2,6 +2,15 @@OpenViking uses a JSON configuration file (`~/.openviking/ov.conf`) for settings.+For a first-time setup, the recommended flow is:++```bash+openviking-server init+openviking-server doctor+```++`openviking-server init` prompts for embedding and VLM settings separately. For API-based VLM choices such as `OpenAI`, `Volcengine`, `Kimi`, and `GLM`, enter the VLM API key when prompted. If you want to use Codex as the VLM provider, choose `OpenAI Codex`; the wizard can import existing Codex auth or guide you through login directly.+## Configuration FileCreate `~/.openviking/ov.conf` in your project directory:@@ -36,6 +45,8 @@ Create `~/.openviking/ov.conf` in your project directory:}```+For `provider: "openai-codex"`, `vlm.api_key` is optional when Codex OAuth is already available.+## Configuration Examples<details>@@ -57,7 +68,7 @@ Create `~/.openviking/ov.conf` in your project directory:"api_base" : "https://ark.cn-beijing.volces.com/api/v3","api_key" : "your-volcengine-api-key","provider" : "volcengine",- "model" : "doubao-seed-2-0-pro-260215"+ "model" : "doubao-seed-2-0-code-preview-260215"}}```@@ -74,21 +85,101 @@ Create `~/.openviking/ov.conf` in your project directory:"api_base" : "https://api.openai.com/v1","api_key" : "your-openai-api-key","provider" : "openai",- "dimension": 3072,- "model" : "text-embedding-3-large"+ "dimension": 1536,+ "model" : "text-embedding-3-small"}},"vlm": {"api_base" : "https://api.openai.com/v1","api_key" : "your-openai-api-key","provider" : "openai",- "model" : "gpt-4-vision-preview"+ "model" : "gpt-5.4"}}```</details>+<details>+<summary><b>Volcengine Embedding + Codex VLM</b></summary>++Use `openviking-server init` to complete the Codex login/import step, then run `openviking-server doctor`.++```json+{+ "embedding": {+ "dense": {+ "api_base" : "https://ark.cn-beijing.volces.com/api/v3",+ "api_key" : "your-volcengine-api-key",+ "provider" : "volcengine",+ "dimension": 1024,+ "model" : "doubao-embedding-vision-251215"+ }+ },+ "vlm": {+ "provider" : "openai-codex",+ "model" : "gpt-5.4",+ "api_base" : "https://chatgpt.com/backend-api/codex"+ }+}+```++</details>++<details>+<summary><b>Volcengine Embedding + Kimi Coding VLM</b></summary>++```json+{+ "embedding": {+ "dense": {+ "api_base" : "https://ark.cn-beijing.volces.com/api/v3",+ "api_key" : "your-volcengine-api-key",+ "provider" : "volcengine",+ "dimension": 1024,+ "model" : "doubao-embedding-vision-251215"+ }+ },+ "vlm": {+ "provider" : "kimi",+ "model" : "kimi-code",+ "api_key" : "your-kimi-subscription-api-key",+ "api_base" : "https://api.kimi.com/coding"+ }+}+```++`kimi` applies the Kimi Coding defaults automatically, including the default Kimi Coding user agent.++</details>++<details>+<summary><b>Volcengine Embedding + GLM Coding Plan VLM</b></summary>++```json+{+ "embedding": {+ "dense": {+ "api_base" : "https://ark.cn-beijing.volces.com/api/v3",+ "api_key" : "your-volcengine-api-key",+ "provider" : "volcengine",+ "dimension": 1024,+ "model" : "doubao-embedding-vision-251215"+ }+ },+ "vlm": {+ "provider" : "glm",+ "model" : "glm-4.6v",+ "api_key" : "your-zai-api-key",+ "api_base" : "https://api.z.ai/api/coding/paas/v4"+ }+}+```++Use a vision-capable GLM model such as `glm-4.6v` or `glm-5v-turbo` when OpenViking needs image understanding.++</details>+## Configuration Sections### embedding@@ -439,14 +530,14 @@ Vision Language Model for semantic extraction (L0/L1 generation).| Parameter | Type | Description ||-----------|------|-------------|-| `api_key` | str | API key |+| `api_key` | str | API key. Optional for `openai-codex` when Codex OAuth is available || `model` | str | Model name || `api_base` | str | API endpoint (optional) || `thinking` | bool | Enable thinking mode for VolcEngine models (default: `false`) || `max_concurrent` | int | Maximum concurrent semantic LLM calls (default: `100`) || `max_retries` | int | Maximum retry attempts for transient VLM provider errors (default: `3`; `0` disables retry) || `timeout` | float | Per-request HTTP timeout in seconds passed to the underlying OpenAI/LiteLLM client. Increase for slow endpoints (e.g., DashScope, local inference). Must be `> 0` (default: `60.0`) |-| `extra_headers` | object | Custom HTTP headers (for OpenAI-compatible providers, optional) |+| `extra_headers` | object | Custom HTTP headers for compatible HTTP providers. `kimi` also accepts header overrides, but already injects the required subscription headers by default || `stream` | bool | Enable streaming mode (for OpenAI-compatible providers, default: `false`) |`vlm.max_retries` only applies to transient errors such as `429`, `5xx`, timeouts, and connection failures. Permanent authentication, authorization, and billing errors are not retried automatically. The backoff strategy is exponential backoff with jitter, starting at `0.5s` and capped at `8s`.@@ -465,6 +556,15 @@ When resources are added, VLM generates:If VLM is not configured, L0/L1 will be generated from content directly (less semantic), and multimodal resources may have limited descriptions.+**Supported providers:**+- `volcengine`: Volcengine VLM API+- `openai`: OpenAI-compatible VLM API+- `openai-codex`: Codex VLM via ChatGPT/Codex OAuth+- `kimi`: Kimi Coding subscription endpoint with built-in provider defaults+- `glm`: Z.AI GLM Coding Plan endpoint with OpenAI-compatible requests++For `openai-codex`, authenticate through `openviking-server init`, then verify with `openviking-server doctor`.+**Custom HTTP Headers**For OpenAI-compatible providers (e.g., OpenRouter), you can add custom HTTP headers via `extra_headers`:@@ -486,6 +586,7 @@ For OpenAI-compatible providers (e.g., OpenRouter), you can add custom HTTP headCommon use cases:- **OpenRouter**: Requires `HTTP-Referer` and `X-Title` to identify your application+- **Kimi Coding**: Override or extend the default subscription headers when you need a custom user agent- **Custom proxies**: Add authentication or tracing headers- **API gateways**: Add version or routing identifiers@@ -571,7 +672,7 @@ See [Code Skeleton Extraction](../concepts/06-extraction.md#code-skeleton-extrac### rerank-Reranking model for search result refinement. Supports VikingDB (Volcengine), Cohere, OpenAI-compatible APIs, and LiteLLM.+Reranking model for search result refinement. Supports VikingDB (Volcengine), Cohere, and OpenAI-compatible APIs.**Volcengine (VikingDB):**@@ -605,13 +706,13 @@ Reranking model for search result refinement. Supports VikingDB (Volcengine), Co| Parameter | Type | Description ||-----------|------|-------------|-| `provider` | str | `"vikingdb"`, `"cohere"`, `"openai"`, or `"litellm"`. Auto-detected if omitted. |+| `provider` | str | `"vikingdb"`, `"cohere"`, or `"openai"`. Auto-detected if omitted. || `ak` | str | VikingDB Access Key (vikingdb provider only) || `sk` | str | VikingDB Secret Key (vikingdb provider only) || `model_name` | str | Model name (vikingdb provider only, default: `doubao-seed-rerank`) |-| `api_key` | str | API key (for `openai`, `cohere`, or `litellm` providers) |+| `api_key` | str | API key (for `openai` or `cohere` providers) || `api_base` | str | Endpoint URL (for `openai` provider) |-| `model` | str | Model name (for `openai` or `litellm` providers) |+| `model` | str | Model name (for `openai` providers) || `threshold` | float | Score threshold between `0.0` and `1.0`; results below this are filtered out. Default: `0.1` || `extra_headers` | object | Custom HTTP headers (for OpenAI-compatible providers, optional) |@@ -619,7 +720,6 @@ Reranking model for search result refinement. Supports VikingDB (Volcengine), Co- `vikingdb`: Volcengine VikingDB Rerank API (uses AK/SK)- `cohere`: Cohere Rerank API- `openai`: OpenAI-compatible Rerank API-- `litellm`: Rerank services via LiteLLM (requires `litellm` package)If rerank is not configured, search uses vector similarity only.diff --git a/docs/en/guides/03-deployment.md b/docs/en/guides/03-deployment.mdindex 488d7fd34..6167f41e6 100644--- a/docs/en/guides/03-deployment.md+++ b/docs/en/guides/03-deployment.md@@ -5,6 +5,14 @@ OpenViking can run as a standalone HTTP server, allowing multiple clients to con## Quick Start```bash+# Create or refresh ~/.openviking/ov.conf with the setup wizard+openviking-server init++# If you select OpenAI Codex in the wizard, init can import/login Codex for you++# Validate local config, model access, and auth before starting+openviking-server doctor+# Start server (reads ~/.openviking/ov.conf by default)openviking-serverdiff --git a/docs/zh/api/01-overview.md b/docs/zh/api/01-overview.mdindex 7887400eb..5332cf3df 100644--- a/docs/zh/api/01-overview.md+++ b/docs/zh/api/01-overview.md@@ -35,7 +35,7 @@ export OPENVIKING_CONFIG_FILE=/path/to/ov.conf"dense": {"api_base": "<api-endpoint>","api_key": "<your-api-key>",- "provider": "<volcengine|openai|jina>",+ "provider": "<volcengine|openai|jina|...>","dimension": 1024,"model": "<model-name>"}@@ -43,12 +43,14 @@ export OPENVIKING_CONFIG_FILE=/path/to/ov.conf"vlm": {"api_base": "<api-endpoint>","api_key": "<your-api-key>",- "provider": "<volcengine|openai|jina>",+ "provider": "<volcengine|openai|openai-codex|kimi|glm>","model": "<model-name>"}}```+当 `provider: "openai-codex"` 时,只要通过 `openviking-server init` 完成 Codex OAuth,就可以不填写 `vlm.api_key`。+完整配置选项和各服务商示例见 [配置指南](../guides/01-configuration.md)。### HTTP 模式diff --git a/docs/zh/getting-started/02-quickstart.md b/docs/zh/getting-started/02-quickstart.mdindex 04a9fba9c..1f8830ed7 100644--- a/docs/zh/getting-started/02-quickstart.md+++ b/docs/zh/getting-started/02-quickstart.md@@ -82,13 +82,21 @@ OpenViking 需要以下模型能力:OpenViking 支持多种模型服务:- **火山引擎(豆包模型)**:推荐使用,成本低、性能好,新用户有免费额度。如需购买和开通,请参考:[火山引擎购买指南](../guides/02-volcengine-purchase-guide.md)- **OpenAI 模型**:支持 GPT-4V 等 VLM 模型和 OpenAI Embedding 模型+- **OpenAI Codex**:支持通过 ChatGPT/Codex OAuth 使用 Codex 作为 VLM- **其他自定义模型服务**:支持兼容 OpenAI API 格式的模型服务## 配置环境### 配置文件模版-创建配置文件 `~/.openviking/ov.conf`:+推荐首次配置使用:++```bash+openviking-server init+openviking-server doctor+```++如果你更希望手动创建,再编写 `~/.openviking/ov.conf`:```json{@@ -110,8 +118,12 @@ OpenViking 支持多种模型服务:}```+`provider`、`model`、`api_base` 和 `api_key` 取决于你选择的 VLM 服务;部分 provider 可能会使用本地 OAuth 状态,而不是手动填写 API key。+各模型服务的完整配置示例请参见 [配置指南 - 配置示例](../guides/01-configuration.md#配置示例)。+首次配置建议优先使用 `openviking-server init`,它会帮助你选择 provider,并生成对应场景可直接使用的配置模板。+### 设置环境变量配置文件放在默认路径 `~/.openviking/ov.conf` 时,无需额外设置,OpenViking 会自动加载。diff --git a/docs/zh/getting-started/03-quickstart-server.md b/docs/zh/getting-started/03-quickstart-server.mdindex 9cdf32f70..eb974eb84 100644--- a/docs/zh/getting-started/03-quickstart-server.md+++ b/docs/zh/getting-started/03-quickstart-server.md@@ -11,6 +11,16 @@确保 `ov.conf` 已配置好存储路径和模型信息(参见 [快速开始](02-quickstart.md)),然后启动服务:+如果是首次配置,建议先运行 `openviking-server init`。++启动前建议先做本地校验:++```bash+openviking-server doctor+```++`openviking-server doctor` 会校验当前本地配置是否可用,包括各 provider 需要的鉴权状态。+```bash# 配置文件在默认路径 ~/.openviking/ov.conf 时,直接启动openviking-server@@ -35,6 +45,8 @@ curl http://localhost:1933/health# {"status": "ok"}```+`openviking-server doctor` 用于校验本地配置、模型访问和鉴权状态;`curl /health` 只表示服务进程已经启动。+## 使用 Python SDK 连接```pythondiff --git a/docs/zh/guides/01-configuration.md b/docs/zh/guides/01-configuration.mdindex f0c90541e..554b2dcab 100644--- a/docs/zh/guides/01-configuration.md+++ b/docs/zh/guides/01-configuration.md@@ -2,6 +2,15 @@OpenViking 使用 JSON 配置文件(`ov.conf`)进行设置。配置文件支持 Embedding、VLM、Rerank、存储、解析器等多个模块的配置。+首次配置推荐优先使用:++```bash+openviking-server init+openviking-server doctor+```++`openviking-server init` 会分别引导你填写 Embedding 和 VLM 的配置。对于 `OpenAI`、`Volcengine`、`Kimi`、`GLM` 这类 API 型 VLM,按提示填写对应的 VLM API Key;如果要使用 Codex 作为 VLM,请选择 `OpenAI Codex`,向导会自动帮你处理已有 Codex 鉴权的导入,或直接引导你完成登录。+## 快速开始在项目目录创建 `~/.openviking/ov.conf`:@@ -37,6 +46,8 @@ OpenViking 使用 JSON 配置文件(`ov.conf`)进行设置。配置文件支```+如果 `provider` 是 `openai-codex`,并且 Codex OAuth 已经就绪,则 `vlm.api_key` 可以省略。+## 配置示例<details>@@ -58,7 +69,7 @@ OpenViking 使用 JSON 配置文件(`ov.conf`)进行设置。配置文件支"api_base" : "https://ark.cn-beijing.volces.com/api/v3","api_key" : "your-volcengine-api-key","provider" : "volcengine",- "model" : "doubao-seed-2-0-pro-260215"+ "model" : "doubao-seed-2-0-code-preview-260215"}}```@@ -75,21 +86,101 @@ OpenViking 使用 JSON 配置文件(`ov.conf`)进行设置。配置文件支"api_base" : "https://api.openai.com/v1","api_key" : "your-openai-api-key","provider" : "openai",- "dimension": 3072,- "model" : "text-embedding-3-large"+ "dimension": 1536,+ "model" : "text-embedding-3-small"}},"vlm": {"api_base" : "https://api.openai.com/v1","api_key" : "your-openai-api-key","provider" : "openai",- "model" : "gpt-4-vision-preview"+ "model" : "gpt-5.4"+ }+}+```++</details>++<details>+<summary><b>火山引擎 Embedding + Codex VLM</b></summary>++使用 `openviking-server init` 完成 Codex 登录/导入后,再执行 `openviking-server doctor`。++```json+{+ "embedding": {+ "dense": {+ "api_base" : "https://ark.cn-beijing.volces.com/api/v3",+ "api_key" : "your-volcengine-api-key",+ "provider" : "volcengine",+ "dimension": 1024,+ "model" : "doubao-embedding-vision-251215"+ }+ },+ "vlm": {+ "provider" : "openai-codex",+ "model" : "gpt-5.4",+ "api_base" : "https://chatgpt.com/backend-api/codex"}}```</details>+<details>+<summary><b>火山引擎 Embedding + Kimi Coding VLM</b></summary>++```json+{+ "embedding": {+ "dense": {+ "api_base" : "https://ark.cn-beijing.volces.com/api/v3",+ "api_key" : "your-volcengine-api-key",+ "provider" : "volcengine",+ "dimension": 1024,+ "model" : "doubao-embedding-vision-251215"+ }+ },+ "vlm": {+ "provider" : "kimi",+ "model" : "kimi-code",+ "api_key" : "your-kimi-subscription-api-key",+ "api_base" : "https://api.kimi.com/coding"+ }+}+```++`kimi` 会自动应用 Kimi Coding 的默认配置,包括默认的 Kimi Coding User-Agent。++</details>++<details>+<summary><b>火山引擎 Embedding + GLM Coding Plan VLM</b></summary>++```json+{+ "embedding": {+ "dense": {+ "api_base" : "https://ark.cn-beijing.volces.com/api/v3",+ "api_key" : "your-volcengine-api-key",+ "provider" : "volcengine",+ "dimension": 1024,+ "model" : "doubao-embedding-vision-251215"+ }+ },+ "vlm": {+ "provider" : "glm",+ "model" : "glm-4.6v",+ "api_key" : "your-zai-api-key",+ "api_base" : "https://api.z.ai/api/coding/paas/v4"+ }+}+```++如果 OpenViking 需要处理图片,请使用 `glm-4.6v` 或 `glm-5v-turbo` 这类支持视觉输入的模型。++</details>+## 配置部分### embedding@@ -418,7 +509,7 @@ OpenViking 使用 JSON 配置文件(`ov.conf`)进行设置。配置文件支| `max_concurrent` | int | 语义处理阶段 LLM 最大并发调用数(默认:`100`) || `max_retries` | int | VLM provider 瞬时错误的最大重试次数(默认:`3`;`0` 表示禁用重试) || `timeout` | float | 单次 VLM API 请求的 HTTP 超时时间(秒),传递给底层 OpenAI/LiteLLM 客户端。慢端点(如 DashScope、本地推理)可调大。必须 `> 0`(默认:`60.0`) |-| `extra_headers` | object | 自定义 HTTP 请求头(OpenAI 兼容 provider 可用,可选) |+| `extra_headers` | object | 兼容 HTTP provider 的自定义请求头。`kimi` 默认已注入所需订阅请求头,也支持在这里覆盖或扩展 || `stream` | bool | 启用流式模式(OpenAI 兼容 provider 可用,默认:`false`) |`vlm.max_retries` 仅对瞬时错误生效,例如 `429`、`5xx`、超时和连接错误;认证、鉴权、欠费等永久错误不会自动重试。退避策略为指数退避,初始延迟 `0.5s`,上限 `8s`,并带随机抖动。@@ -437,6 +528,15 @@ OpenViking 使用 JSON 配置文件(`ov.conf`)进行设置。配置文件支如果未配置 VLM,L0/L1 将直接从内容生成(语义性较弱),多模态资源的描述可能有限。+**支持的 provider:**+- `volcengine`:火山引擎 VLM API+- `openai`:OpenAI 兼容 VLM API+- `openai-codex`:通过 ChatGPT/Codex OAuth 使用 Codex VLM+- `kimi`:Kimi Coding 订阅端点,内置 provider 默认配置+- `glm`:Z.AI GLM Coding Plan 端点,使用 OpenAI 兼容请求格式++对于 `openai-codex`,请通过 `openviking-server init` 完成鉴权,再使用 `openviking-server doctor` 做校验。+**自定义 HTTP Headers**对于 OpenAI 兼容的 provider(如 OpenRouter),可以通过 `extra_headers` 添加自定义 HTTP 请求头:@@ -458,6 +558,7 @@ OpenViking 使用 JSON 配置文件(`ov.conf`)进行设置。配置文件支常见使用场景:- **OpenRouter**: 需要 `HTTP-Referer` 和 `X-Title` 来标识应用+- **Kimi Coding**: 需要自定义 user agent 或追加订阅请求头时可以在这里覆盖- **自定义代理**: 添加认证头或追踪头- **API 网关**: 添加版本或路由标识@@ -543,7 +644,7 @@ AST 提取支持:Python、JavaScript/TypeScript、Rust、Go、Java、C/C++。### rerank-用于搜索结果精排的 Rerank 模型。支持 VikingDB (火山引擎)、Cohere、OpenAI 兼容接口和 LiteLLM。+用于搜索结果精排的 Rerank 模型。支持 VikingDB (火山引擎)、Cohere 和 OpenAI 兼容接口。**火山引擎 (VikingDB):**@@ -577,13 +678,13 @@ AST 提取支持:Python、JavaScript/TypeScript、Rust、Go、Java、C/C++。| 参数 | 类型 | 说明 ||------|------|------|-| `provider` | str | `"vikingdb"`、`"cohere"`、`"openai"` 或 `"litellm"`。省略时基于字段自动识别。 |+| `provider` | str | `"vikingdb"`、`"cohere"` 或 `"openai"`。省略时基于字段自动识别。 || `ak` | str | VikingDB Access Key(仅 `vikingdb` 提供方使用) || `sk` | str | VikingDB Secret Key(仅 `vikingdb` 提供方使用) || `model_name` | str | 模型名称(仅 `vikingdb` 提供方使用,默认:`doubao-seed-rerank`) |-| `api_key` | str | API Key(用于 `openai`、`cohere` 或 `litellm` 提供方) |+| `api_key` | str | API Key(用于 `openai` 或 `cohere` 提供方) || `api_base` | str | 接口地址(用于 `openai` 提供方) |-| `model` | str | 模型名称(用于 `openai` 或 `litellm` 提供方) |+| `model` | str | 模型名称(用于 `openai` 提供方) || `threshold` | float | 分数阈值,范围为 `0.0` 到 `1.0`。低于此值的结果会被过滤。默认:`0.1` || `extra_headers` | object | 自定义 HTTP 请求头(OpenAI 兼容 provider 可用,可选) |@@ -591,7 +692,6 @@ AST 提取支持:Python、JavaScript/TypeScript、Rust、Go、Java、C/C++。- `vikingdb`: 火山引擎 VikingDB Rerank API (使用 AK/SK)- `cohere`: Cohere Rerank API- `openai`: OpenAI 兼容的 Rerank 接口-- `litellm`: 通过 LiteLLM 调用的 Rerank 服务 (需安装 `litellm`)如果未配置 Rerank,搜索仅使用向量相似度。diff --git a/docs/zh/guides/03-deployment.md b/docs/zh/guides/03-deployment.mdindex d5f7fbf27..b4db77426 100644--- a/docs/zh/guides/03-deployment.md+++ b/docs/zh/guides/03-deployment.md@@ -5,6 +5,14 @@ OpenViking 可以作为独立的 HTTP 服务器运行,允许多个客户端通## 快速开始```bash+# 使用初始化向导创建或刷新 ~/.openviking/ov.conf+openviking-server init++# 如果你在向导中选择 OpenAI Codex,init 会帮你处理 Codex 登录/导入++# 启动前校验本地配置、模型访问和鉴权状态+openviking-server doctor+# 配置文件在默认路径 ~/.openviking/ov.conf 时,直接启动openviking-serverdiff --git a/examples/basic-usage/README.md b/examples/basic-usage/README.mdindex 3bfc2fb76..a85d43f9e 100644--- a/examples/basic-usage/README.md+++ b/examples/basic-usage/README.md@@ -244,7 +244,7 @@ Create `~/.openviking/ov.conf` with storage, embedding, and VLM settings. A mini}```-You can also use Volcengine, Azure OpenAI, or LiteLLM-backed providers. For current provider-specific examples, check the main [README](../../README.md) and the [Configuration Guide](../../docs/en/guides/01-configuration.md).+You can also use Volcengine or Azure OpenAI. For current provider-specific examples, check the main [README](../../README.md) and the [Configuration Guide](../../docs/en/guides/01-configuration.md).## Recommended Next Stepsdiff --git a/examples/basic-usage/README_CN.md b/examples/basic-usage/README_CN.mdindex 19667fb83..3f0e12227 100644--- a/examples/basic-usage/README_CN.md+++ b/examples/basic-usage/README_CN.md@@ -246,7 +246,7 @@ memories = client.find(}```-你也可以使用火山引擎、Azure OpenAI、LiteLLM 等提供商。当前配置示例请以主 [README](../../README_CN.md) 和 [配置指南](../../docs/zh/guides/01-configuration.md) 为准。+你也可以使用火山引擎、Azure OpenAI 等提供商。当前配置示例请以主 [README](../../README_CN.md) 和 [配置指南](../../docs/zh/guides/01-configuration.md) 为准。## 推荐下一步diff --git a/examples/ov.conf.example b/examples/ov.conf.exampleindex 3e19929bf..cb319b220 100644--- a/examples/ov.conf.example+++ b/examples/ov.conf.example@@ -79,6 +79,32 @@"provider": "volcengine","thinking": false},+ "vlm_codex_example": {+ "_comment": "For Codex OAuth via subscription. Complete sign-in from `openviking-server init`. OV stores tokens in ~/.openviking/codex_auth.json and can bootstrap from an existing Codex CLI auth file if needed.",+ "provider": "openai-codex",+ "model": "gpt-5.3-codex",+ "api_base": "https://chatgpt.com/backend-api/codex",+ "temperature": 0.0,+ "max_retries": 2+ },+ "vlm_kimi_example": {+ "_comment": "For Kimi Coding subscription. OpenViking applies the recommended provider defaults automatically.",+ "provider": "kimi",+ "model": "kimi-code",+ "api_key": "{your-kimi-subscription-api-key}",+ "api_base": "https://api.kimi.com/coding",+ "temperature": 0.0,+ "max_retries": 2+ },+ "vlm_glm_example": {+ "_comment": "For GLM Coding Plan via Z.AI subscription API key. Use a vision-capable model for multimodal parsing.",+ "provider": "glm",+ "model": "glm-4.6v",+ "api_key": "{your-zai-api-key}",+ "api_base": "https://api.z.ai/api/coding/paas/v4",+ "temperature": 0.0,+ "max_retries": 2+ },"rerank": {"provider": "vikingdb","ak": "{your-ak}",diff --git a/openviking/models/embedder/vikingdb_embedders.py b/openviking/models/embedder/vikingdb_embedders.pyindex e61f18db7..a661be751 100644--- a/openviking/models/embedder/vikingdb_embedders.py+++ b/openviking/models/embedder/vikingdb_embedders.py@@ -487,7 +487,9 @@ class VikingDBHybridEmbedder(HybridEmbedderBase, VikingDBClientMixin):def _call() -> EmbedResult:results = self._call_api(- [text], dense_model=self.dense_model, sparse_model=self.sparse_model,+ [text],+ dense_model=self.dense_model,+ sparse_model=self.sparse_model,input_type=input_type,)if not results:@@ -525,7 +527,9 @@ class VikingDBHybridEmbedder(HybridEmbedderBase, VikingDBClientMixin):def _call() -> List[EmbedResult]:raw_results = self._call_api(- texts, dense_model=self.dense_model, sparse_model=self.sparse_model,+ texts,+ dense_model=self.dense_model,+ sparse_model=self.sparse_model,input_type=input_type,)results = []diff --git a/openviking/models/vlm/__init__.py b/openviking/models/vlm/__init__.pyindex 7808098bb..fda37f840 100644--- a/openviking/models/vlm/__init__.py+++ b/openviking/models/vlm/__init__.py@@ -2,6 +2,9 @@# SPDX-License-Identifier: AGPL-3.0"""VLM (Vision-Language Model) module"""+from .backends.codex_vlm import CodexVLM+from .backends.glm_vlm import GLMVLM+from .backends.kimi_vlm import KimiVLMfrom .backends.litellm_vlm import LiteLLMVLMProviderfrom .backends.openai_vlm import OpenAIVLMfrom .backends.volcengine_vlm import VolcEngineVLM@@ -12,6 +15,9 @@ __all__ = ["VLMBase","VLMFactory","OpenAIVLM",+ "CodexVLM",+ "KimiVLM",+ "GLMVLM","VolcEngineVLM","LiteLLMVLMProvider","get_all_provider_names",diff --git a/openviking/models/vlm/backends/codex_auth.py b/openviking/models/vlm/backends/codex_auth.pynew file mode 100644index 000000000..49e4c3b6a--- /dev/null+++ b/openviking/models/vlm/backends/codex_auth.py@@ -0,0 +1,737 @@+# Copyright (c) 2026 Beijing Volcano Engine Technology Co., Ltd.+# SPDX-License-Identifier: AGPL-3.0++from __future__ import annotations++import asyncio+import base64+import json+import os+import stat+import tempfile+import threading+import time+from contextlib import contextmanager+from datetime import datetime, timezone+from pathlib import Path+from typing import Any, Dict, Optional++import httpx++from openviking_cli.utils.config.consts import DEFAULT_CONFIG_DIR++try:+ import fcntl+except ImportError:+ fcntl = None++try:+ import msvcrt+except ImportError:+ msvcrt = None++DEFAULT_CODEX_BASE_URL = "https://chatgpt.com/backend-api/codex"+CODEX_OAUTH_ISSUER = "https://auth.openai.com"+# Public Codex device-auth client_id, not a secret; env or existing auth is preferred, and this is only a compatibility fallback.+DEFAULT_CODEX_OAUTH_CLIENT_ID = "app_EMoamEEZ73f0CkXaXp7hrann"+CODEX_ACCESS_TOKEN_REFRESH_SKEW_SECONDS = 300+CODEX_AUTH_OWNER_OPENVIKING = "openviking"+CODEX_AUTH_OWNER_EXTERNAL = "external"+_auth_lock_holder = threading.local()+++class CodexAuthError(RuntimeError):+ pass+++def _resolve_base_url() -> str:+ return os.getenv("OPENVIKING_CODEX_BASE_URL", "").strip().rstrip("/") or DEFAULT_CODEX_BASE_URL+++def _resolve_codex_oauth_issuer() -> str:+ return os.getenv("OPENVIKING_CODEX_OAUTH_ISSUER", "").strip().rstrip("/") or CODEX_OAUTH_ISSUER+++def _resolve_codex_oauth_token_url() -> str:+ override = os.getenv("OPENVIKING_CODEX_OAUTH_TOKEN_URL", "").strip()+ if override:+ return override+ return f"{_resolve_codex_oauth_issuer()}/oauth/token"+++def _decode_jwt_claims(token: Any) -> Dict[str, Any]:+ if not isinstance(token, str) or token.count(".") != 2:+ return {}+ payload = token.split(".")[1]+ payload += "=" * ((4 - len(payload) % 4) % 4)+ try:+ raw = base64.urlsafe_b64decode(payload.encode("utf-8"))+ claims = json.loads(raw.decode("utf-8"))+ except Exception:+ return {}+ return claims if isinstance(claims, dict) else {}+++def _codex_access_token_is_expiring(access_token: Any, skew_seconds: int) -> bool:+ claims = _decode_jwt_claims(access_token)+ exp = claims.get("exp")+ if not isinstance(exp, (int, float)):+ return True+ return float(exp) <= (time.time() + max(0, int(skew_seconds)))+++def _default_codex_auth_path() -> Path:+ codex_home = os.getenv("CODEX_HOME", "").strip()+ if not codex_home:+ codex_home = str(Path.home() / ".codex")+ return Path(codex_home).expanduser() / "auth.json"+++def _default_openviking_auth_path() -> Path:+ return DEFAULT_CONFIG_DIR / "codex_auth.json"+++def get_codex_auth_store_path() -> Path:+ override = os.getenv("OPENVIKING_CODEX_AUTH_PATH", "").strip()+ if override:+ return Path(override).expanduser()+ return _default_openviking_auth_path()+++def _auth_lock_path() -> Path:+ return get_codex_auth_store_path().with_suffix(".lock")+++def _acquire_windows_file_lock(handle) -> None:+ handle.seek(0, os.SEEK_END)+ if handle.tell() == 0:+ handle.write(b"\0")+ handle.flush()+ handle.seek(0)+ msvcrt.locking(handle.fileno(), msvcrt.LK_LOCK, 1)+++def _release_windows_file_lock(handle) -> None:+ handle.seek(0)+ msvcrt.locking(handle.fileno(), msvcrt.LK_UNLCK, 1)+++@contextmanager+def _auth_store_lock():+ if getattr(_auth_lock_holder, "depth", 0) > 0:+ _auth_lock_holder.depth += 1+ try:+ yield+ finally:+ _auth_lock_holder.depth -= 1+ return+ lock_path = _auth_lock_path()+ lock_path.parent.mkdir(parents=True, exist_ok=True)+ if fcntl is None and msvcrt is None:+ _auth_lock_holder.depth = 1+ try:+ yield+ finally:+ _auth_lock_holder.depth = 0+ return+ open_mode = "a+b" if msvcrt is not None and fcntl is None else "a+"+ open_kwargs = {} if open_mode == "a+b" else {"encoding": "utf-8"}+ with open(lock_path, open_mode, **open_kwargs) as handle:+ _auth_lock_holder.depth = 1+ try:+ if fcntl is not None:+ fcntl.flock(handle.fileno(), fcntl.LOCK_EX)+ else:+ # Windows needs an explicit byte-range lock to coordinate access+ # across separate processes writing the shared auth store.+ _acquire_windows_file_lock(handle)+ yield+ finally:+ try:+ if fcntl is not None:+ fcntl.flock(handle.fileno(), fcntl.LOCK_UN)+ else:+ _release_windows_file_lock(handle)+ except OSError:+ pass+ _auth_lock_holder.depth = 0+++def _candidate_auth_sources() -> list[tuple[str, Path]]:+ sources: list[tuple[str, Path]] = []+ sources.append(("openviking", get_codex_auth_store_path()))+ import_override = os.getenv("OPENVIKING_CODEX_BOOTSTRAP_PATH", "").strip()+ if import_override:+ sources.append(("codex-cli", Path(import_override).expanduser()))+ else:+ sources.append(("codex-cli", _default_codex_auth_path()))+ return sources+++def _read_json_file(path: Path) -> Dict[str, Any]:+ if not path.is_file():+ return {}+ try:+ payload = json.loads(path.read_text(encoding="utf-8"))+ except Exception:+ return {}+ return payload if isinstance(payload, dict) else {}+++def _atomic_write_json_file(path: Path, payload: Dict[str, Any]) -> None:+ path.parent.mkdir(parents=True, exist_ok=True)+ fd, tmp_name = tempfile.mkstemp(+ prefix=f"{path.name}.",+ suffix=".tmp",+ dir=str(path.parent),+ )+ try:+ with os.fdopen(fd, "w", encoding="utf-8") as handle:+ handle.write(json.dumps(payload, indent=2) + "\n")+ handle.flush()+ os.fsync(handle.fileno())+ try:+ os.chmod(tmp_name, stat.S_IRUSR | stat.S_IWUSR)+ except OSError:+ pass+ os.replace(tmp_name, path)+ except Exception:+ try:+ os.unlink(tmp_name)+ except OSError:+ pass+ raise+++def _format_expires_at(token: str) -> Optional[str]:+ claims = _decode_jwt_claims(token)+ exp = claims.get("exp")+ if not isinstance(exp, (int, float)):+ return None+ return datetime.fromtimestamp(float(exp), tz=timezone.utc).isoformat().replace("+00:00", "Z")+++def _extract_codex_oauth_client_id(payload: Dict[str, Any]) -> Optional[str]:+ for key in ("client_id", "oauth_client_id", "clientId"):+ value = payload.get(key)+ if isinstance(value, str) and value.strip():+ return value.strip()+ tokens = payload.get("tokens")+ if isinstance(tokens, dict):+ for token_key in ("access_token", "id_token"):+ claims = _decode_jwt_claims(tokens.get(token_key))+ for claim_key in ("azp", "client_id"):+ value = claims.get(claim_key)+ if isinstance(value, str) and value.strip():+ return value.strip()+ return None+++def _extract_codex_auth_owner(payload: Dict[str, Any]) -> str:+ owner = payload.get("auth_owner")+ if isinstance(owner, str) and owner.strip() in {+ CODEX_AUTH_OWNER_OPENVIKING,+ CODEX_AUTH_OWNER_EXTERNAL,+ }:+ return owner.strip()+ imported_from = payload.get("imported_from")+ if isinstance(imported_from, str) and imported_from.strip():+ return CODEX_AUTH_OWNER_EXTERNAL+ return CODEX_AUTH_OWNER_OPENVIKING+++def _resolve_codex_oauth_client_id() -> str:+ override = os.getenv("OPENVIKING_CODEX_OAUTH_CLIENT_ID", "").strip()+ if override:+ return override+ for _, path in _candidate_auth_sources():+ payload = _read_json_file(path)+ if not payload:+ continue+ client_id = _extract_codex_oauth_client_id(payload)+ if client_id:+ return client_id+ return DEFAULT_CODEX_OAUTH_CLIENT_ID+++def _load_tokens_from_source(source: str, path: Path) -> Optional[Dict[str, Any]]:+ payload = _read_json_file(path)+ if not payload:+ return None+ client_id = _extract_codex_oauth_client_id(payload)+ auth_owner = _extract_codex_auth_owner(payload)+ imported_from = payload.get("imported_from")+ tokens = payload.get("tokens")+ if not isinstance(tokens, dict):+ return None+ access_token = str(tokens.get("access_token", "") or "").strip()+ refresh_token = str(tokens.get("refresh_token", "") or "").strip()+ if not access_token or not refresh_token:+ return None+ return {+ "access_token": access_token,+ "refresh_token": refresh_token,+ "last_refresh": payload.get("last_refresh"),+ "source": source,+ "path": path,+ "client_id": client_id,+ "auth_owner": auth_owner,+ "imported_from": imported_from,+ }+++def _write_tokens_to_ov_store(+ path: Path,+ access_token: str,+ refresh_token: str,+ *,+ last_refresh: Optional[str] = None,+ imported_from: Optional[str] = None,+ client_id: Optional[str] = None,+ auth_owner: str = CODEX_AUTH_OWNER_OPENVIKING,+) -> None:+ with _auth_store_lock():+ payload = _read_json_file(path)+ payload["provider"] = "openai-codex"+ payload["auth_mode"] = "chatgpt"+ payload["auth_owner"] = (+ CODEX_AUTH_OWNER_EXTERNAL+ if auth_owner == CODEX_AUTH_OWNER_EXTERNAL+ else CODEX_AUTH_OWNER_OPENVIKING+ )+ payload["tokens"] = {+ "access_token": access_token,+ "refresh_token": refresh_token,+ }+ if last_refresh is not None:+ payload["last_refresh"] = last_refresh+ if imported_from:+ payload["imported_from"] = imported_from+ else:+ payload.pop("imported_from", None)+ resolved_client_id = client_id+ if not resolved_client_id:+ existing_client_id = payload.get("client_id")+ if isinstance(existing_client_id, str) and existing_client_id.strip():+ resolved_client_id = existing_client_id.strip()+ if resolved_client_id:+ payload["client_id"] = resolved_client_id+ _atomic_write_json_file(path, payload)+++def delete_codex_auth_store() -> bool:+ path = get_codex_auth_store_path()+ with _auth_store_lock():+ if not path.exists():+ return False+ path.unlink()+ return True+++def save_codex_tokens(+ access_token: str,+ refresh_token: str,+ *,+ imported_from: Optional[str] = None,+ last_refresh: Optional[str] = None,+ client_id: Optional[str] = None,+ auth_owner: str = CODEX_AUTH_OWNER_OPENVIKING,+) -> Path:+ path = get_codex_auth_store_path()+ _write_tokens_to_ov_store(+ path,+ access_token,+ refresh_token,+ imported_from=imported_from,+ last_refresh=last_refresh or datetime.now(timezone.utc).isoformat().replace("+00:00", "Z"),+ client_id=client_id,+ auth_owner=auth_owner,+ )+ return path+++def get_codex_auth_status() -> Dict[str, Any]:+ store_path = get_codex_auth_store_path()+ store_payload = _load_tokens_from_source("openviking", store_path)+ bootstrap_path = None+ for source, path in _candidate_auth_sources():+ if source == "codex-cli":+ bootstrap_path = path+ break+ status: Dict[str, Any] = {+ "store_path": str(store_path),+ "store_exists": store_payload is not None,+ "bootstrap_path": str(bootstrap_path) if bootstrap_path else None,+ "bootstrap_available": bool(+ bootstrap_path and _load_tokens_from_source("codex-cli", bootstrap_path)+ ),+ "provider": "openai-codex",+ }+ if store_payload:+ status["last_refresh"] = store_payload.get("last_refresh")+ status["expires_at"] = _format_expires_at(store_payload["access_token"])+ payload = _read_json_file(store_path)+ status["imported_from"] = payload.get("imported_from")+ status["auth_owner"] = _extract_codex_auth_owner(payload)+ status["expiring"] = _codex_access_token_is_expiring(+ store_payload["access_token"],+ CODEX_ACCESS_TOKEN_REFRESH_SKEW_SECONDS,+ )+ return status+++def bootstrap_codex_auth() -> Optional[Path]:+ bootstrap_path = None+ for source, path in _candidate_auth_sources():+ if source == "codex-cli":+ bootstrap_path = path+ break+ if bootstrap_path is None:+ return None+ payload = _load_tokens_from_source("codex-cli", bootstrap_path)+ if payload is None:+ return None+ return save_codex_tokens(+ payload["access_token"],+ payload["refresh_token"],+ imported_from=str(bootstrap_path),+ last_refresh=payload.get("last_refresh"),+ client_id=payload.get("client_id"),+ auth_owner=CODEX_AUTH_OWNER_EXTERNAL,+ )+++def login_codex_with_device_code(+ *,+ timeout_seconds: float = 15.0,+ max_wait_seconds: int = 900,+) -> Path:+ issuer = _resolve_codex_oauth_issuer()+ client_id = _resolve_codex_oauth_client_id()+ token_url = _resolve_codex_oauth_token_url()+ with httpx.Client(timeout=httpx.Timeout(timeout_seconds)) as client:+ response = client.post(+ f"{issuer}/api/accounts/deviceauth/usercode",+ json={"client_id": client_id},+ headers={"Content-Type": "application/json"},+ )+ if response.status_code != 200:+ raise CodexAuthError(+ f"Codex device login request failed with status {response.status_code}."+ )+ payload = response.json()+ user_code = str(payload.get("user_code", "") or "").strip()+ device_auth_id = str(payload.get("device_auth_id", "") or "").strip()+ if not user_code or not device_auth_id:+ raise CodexAuthError("Codex device login response is missing required fields.")+ poll_interval = max(3, int(payload.get("interval", "5")))+ print("Open this URL in your browser:")+ print(f" {issuer}/codex/device")+ print("Enter this code:")+ print(f" {user_code}")+ print("Waiting for sign-in...")+ start = time.monotonic()+ auth_code_payload = None+ try:+ with httpx.Client(timeout=httpx.Timeout(timeout_seconds)) as client:+ while time.monotonic() - start < max_wait_seconds:+ time.sleep(poll_interval)+ poll = client.post(+ f"{issuer}/api/accounts/deviceauth/token",+ json={"device_auth_id": device_auth_id, "user_code": user_code},+ headers={"Content-Type": "application/json"},+ )+ if poll.status_code == 200:+ auth_code_payload = poll.json()+ break+ if poll.status_code in (403, 404):+ continue+ raise CodexAuthError(+ f"Codex device auth polling failed with status {poll.status_code}."+ )+ except KeyboardInterrupt as exc:+ raise CodexAuthError("Codex device login cancelled.") from exc+ if auth_code_payload is None:+ raise CodexAuthError("Codex device login timed out.")+ authorization_code = str(auth_code_payload.get("authorization_code", "") or "").strip()+ code_verifier = str(auth_code_payload.get("code_verifier", "") or "").strip()+ if not authorization_code or not code_verifier:+ raise CodexAuthError(+ "Codex device login response is missing authorization_code or code_verifier."+ )+ with httpx.Client(timeout=httpx.Timeout(timeout_seconds)) as client:+ token_response = client.post(+ token_url,+ data={+ "grant_type": "authorization_code",+ "code": authorization_code,+ "redirect_uri": f"{issuer}/deviceauth/callback",+ "client_id": client_id,+ "code_verifier": code_verifier,+ },+ headers={"Content-Type": "application/x-www-form-urlencoded"},+ )+ if token_response.status_code != 200:+ raise CodexAuthError(+ f"Codex token exchange failed with status {token_response.status_code}."+ )+ tokens = token_response.json()+ access_token = str(tokens.get("access_token", "") or "").strip()+ refresh_token = str(tokens.get("refresh_token", "") or "").strip()+ if not access_token or not refresh_token:+ raise CodexAuthError(+ "Codex token exchange did not return both access_token and refresh_token."+ )+ return save_codex_tokens(+ access_token,+ refresh_token,+ client_id=client_id,+ auth_owner=CODEX_AUTH_OWNER_OPENVIKING,+ )+++def refresh_codex_oauth(+ refresh_token: str,+ *,+ client_id: str,+ timeout_seconds: float = 20.0,+) -> Dict[str, str]:+ client_id = str(client_id or "").strip()+ if not client_id:+ raise CodexAuthError("Codex OAuth client_id is missing.")+ if not isinstance(refresh_token, str) or not refresh_token.strip():+ raise CodexAuthError("Codex OAuth refresh_token is missing.")+ try:+ response = httpx.post(+ _resolve_codex_oauth_token_url(),+ headers={+ "Content-Type": "application/x-www-form-urlencoded",+ "Accept": "application/json",+ },+ data={+ "grant_type": "refresh_token",+ "refresh_token": refresh_token.strip(),+ "client_id": client_id,+ },+ timeout=timeout_seconds,+ )+ except Exception as exc:+ raise CodexAuthError(f"Codex OAuth refresh failed: {exc}") from exc+ if response.status_code != 200:+ message = f"Codex OAuth refresh failed with status {response.status_code}."+ try:+ payload = response.json()+ except Exception:+ payload = None+ if isinstance(payload, dict):+ detail = (+ payload.get("error_description") or payload.get("message") or payload.get("error")+ )+ if isinstance(detail, str) and detail.strip():+ message = f"Codex OAuth refresh failed: {detail.strip()}"+ raise CodexAuthError(message)+ try:+ payload = response.json()+ except Exception as exc:+ raise CodexAuthError("Codex OAuth refresh returned invalid JSON.") from exc+ access = str(payload.get("access_token", "") or "").strip()+ if not access:+ raise CodexAuthError("Codex OAuth refresh response is missing access_token.")+ next_refresh = str(payload.get("refresh_token", "") or "").strip() or refresh_token.strip()+ return {+ "access_token": access,+ "refresh_token": next_refresh,+ "last_refresh": datetime.now(timezone.utc).isoformat().replace("+00:00", "Z"),+ }+++def has_codex_auth_available() -> bool:+ return any(+ _load_tokens_from_source(source, path) is not None+ for source, path in _candidate_auth_sources()+ )+++def _sync_external_codex_auth(+ external_path: Path,+ ov_auth_path: Path,+ *,+ fallback_payload: Optional[Dict[str, Any]] = None,+) -> Dict[str, Any]:+ external_payload = _load_tokens_from_source("codex-cli", external_path)+ if external_payload is not None:+ _write_tokens_to_ov_store(+ ov_auth_path,+ external_payload["access_token"],+ external_payload["refresh_token"],+ last_refresh=external_payload.get("last_refresh"),+ imported_from=str(external_path),+ client_id=external_payload.get("client_id"),+ auth_owner=CODEX_AUTH_OWNER_EXTERNAL,+ )+ return external_payload+ if fallback_payload is not None:+ return fallback_payload+ raise CodexAuthError(+ f"Externally managed Codex auth is unavailable at {external_path}. Re-run Codex CLI login or openviking-server init."+ )+++def resolve_codex_runtime_credentials(+ *,+ force_refresh: bool = False,+ refresh_if_expiring: bool = True,+ refresh_skew_seconds: int = CODEX_ACCESS_TOKEN_REFRESH_SKEW_SECONDS,+) -> Dict[str, Any]:+ ov_auth_path = get_codex_auth_store_path()+ payload = _load_tokens_from_source("openviking", ov_auth_path)+ if payload is None:+ for source, path in _candidate_auth_sources():+ if source == "openviking":+ continue+ payload = _load_tokens_from_source(source, path)+ if payload is None:+ continue+ _write_tokens_to_ov_store(+ ov_auth_path,+ payload["access_token"],+ payload["refresh_token"],+ last_refresh=payload.get("last_refresh"),+ imported_from=str(path),+ client_id=payload.get("client_id"),+ auth_owner=CODEX_AUTH_OWNER_EXTERNAL,+ )+ payload = _load_tokens_from_source("openviking", ov_auth_path)+ break+ if payload is not None:+ auth_owner = payload.get("auth_owner") or CODEX_AUTH_OWNER_OPENVIKING+ imported_from = payload.get("imported_from")+ access_token = payload["access_token"]+ refresh_token = payload["refresh_token"]+ if auth_owner == CODEX_AUTH_OWNER_EXTERNAL:+ external_path = None+ if isinstance(imported_from, str) and imported_from.strip():+ external_path = Path(imported_from).expanduser()+ elif os.getenv("OPENVIKING_CODEX_BOOTSTRAP_PATH", "").strip():+ external_path = Path(+ os.getenv("OPENVIKING_CODEX_BOOTSTRAP_PATH", "").strip()+ ).expanduser()+ elif _default_codex_auth_path().exists():+ external_path = _default_codex_auth_path()+ external_missing = False+ should_resync = force_refresh or (+ refresh_if_expiring+ and _codex_access_token_is_expiring(access_token, refresh_skew_seconds)+ )+ if should_resync:+ if external_path is not None:+ external_payload = _load_tokens_from_source("codex-cli", external_path)+ if external_payload is not None:+ _write_tokens_to_ov_store(+ ov_auth_path,+ external_payload["access_token"],+ external_payload["refresh_token"],+ last_refresh=external_payload.get("last_refresh"),+ imported_from=str(external_path),+ client_id=external_payload.get("client_id"),+ auth_owner=CODEX_AUTH_OWNER_EXTERNAL,+ )+ payload = external_payload+ access_token = payload["access_token"]+ refresh_token = payload["refresh_token"]+ else:+ external_missing = True+ else:+ external_missing = True++ should_refresh = force_refresh or (+ refresh_if_expiring+ and _codex_access_token_is_expiring(access_token, refresh_skew_seconds)+ )+ if should_refresh and external_missing:+ refreshed = refresh_codex_oauth(+ refresh_token,+ client_id=str(payload.get("client_id", "") or ""),+ )+ access_token = refreshed["access_token"]+ refresh_token = refreshed["refresh_token"]+ _write_tokens_to_ov_store(+ ov_auth_path,+ access_token,+ refresh_token,+ last_refresh=refreshed.get("last_refresh"),+ imported_from=None,+ client_id=payload.get("client_id"),+ auth_owner=CODEX_AUTH_OWNER_OPENVIKING,+ )+ return {+ "provider": "openai-codex",+ "api_key": access_token,+ "refresh_token": refresh_token,+ "base_url": _resolve_base_url(),+ "source": "openviking",+ "path": str(ov_auth_path),+ "auth_owner": CODEX_AUTH_OWNER_OPENVIKING,+ }++ if should_refresh:+ raise CodexAuthError(+ "Externally managed Codex auth is expiring. Refresh it via Codex CLI or re-run openviking-server init."+ )++ return {+ "provider": "openai-codex",+ "api_key": access_token,+ "refresh_token": refresh_token,+ "base_url": _resolve_base_url(),+ "source": "codex-cli",+ "path": str(ov_auth_path),+ "auth_owner": CODEX_AUTH_OWNER_EXTERNAL,+ }+ should_refresh = force_refresh or (+ refresh_if_expiring+ and _codex_access_token_is_expiring(access_token, refresh_skew_seconds)+ )+ if should_refresh:+ refreshed = refresh_codex_oauth(+ refresh_token,+ client_id=str(payload.get("client_id", "") or ""),+ )+ access_token = refreshed["access_token"]+ refresh_token = refreshed["refresh_token"]+ _write_tokens_to_ov_store(+ ov_auth_path,+ access_token,+ refresh_token,+ last_refresh=refreshed.get("last_refresh"),+ imported_from=None,+ client_id=payload.get("client_id"),+ auth_owner=CODEX_AUTH_OWNER_OPENVIKING,+ )+ return {+ "provider": "openai-codex",+ "api_key": access_token,+ "refresh_token": refresh_token,+ "base_url": _resolve_base_url(),+ "source": "openviking",+ "path": str(ov_auth_path),+ "auth_owner": CODEX_AUTH_OWNER_OPENVIKING,+ }++ raise CodexAuthError(+ "No Codex OAuth credentials found. Run openviking-server init or populate ~/.openviking/codex_auth.json."+ )+++async def resolve_codex_runtime_credentials_async(+ *,+ force_refresh: bool = False,+ refresh_if_expiring: bool = True,+ refresh_skew_seconds: int = CODEX_ACCESS_TOKEN_REFRESH_SKEW_SECONDS,+) -> Dict[str, Any]:+ return await asyncio.to_thread(+ resolve_codex_runtime_credentials,+ force_refresh=force_refresh,+ refresh_if_expiring=refresh_if_expiring,+ refresh_skew_seconds=refresh_skew_seconds,+ )diff --git a/openviking/models/vlm/backends/codex_responses_adapter.py b/openviking/models/vlm/backends/codex_responses_adapter.pynew file mode 100644index 000000000..5388be29e--- /dev/null+++ b/openviking/models/vlm/backends/codex_responses_adapter.py@@ -0,0 +1,279 @@+# Copyright (c) 2026 Beijing Volcano Engine Technology Co., Ltd.+# SPDX-License-Identifier: AGPL-3.0++from __future__ import annotations++import asyncio+import json+from types import SimpleNamespace+from typing import Any, Callable, Dict, List, Optional+++def _convert_content_for_responses(content: Any) -> Any:+ if isinstance(content, str):+ return content+ if not isinstance(content, list):+ return str(content) if content else ""+ converted: List[Dict[str, Any]] = []+ for part in content:+ if not isinstance(part, dict):+ continue+ part_type = part.get("type")+ if part_type == "text":+ converted.append({"type": "input_text", "text": part.get("text", "")})+ continue+ if part_type == "image_url":+ image_value = part.get("image_url", {})+ url = image_value.get("url", "") if isinstance(image_value, dict) else str(image_value)+ entry: Dict[str, Any] = {"type": "input_image", "image_url": url}+ if isinstance(image_value, dict) and image_value.get("detail"):+ entry["detail"] = image_value["detail"]+ converted.append(entry)+ continue+ if part_type in {"input_text", "input_image"}:+ converted.append(part)+ continue+ text_value = part.get("text")+ if text_value:+ converted.append({"type": "input_text", "text": text_value})+ return converted or ""+++def _convert_tools_for_responses(tools: Any) -> Optional[List[Dict[str, Any]]]:+ if not isinstance(tools, list):+ return None+ converted: List[Dict[str, Any]] = []+ for tool in tools:+ if not isinstance(tool, dict):+ continue+ function = tool.get("function")+ if not isinstance(function, dict):+ continue+ name = str(function.get("name", "") or "").strip()+ if not name:+ continue+ converted.append(+ {+ "type": "function",+ "name": name,+ "description": function.get("description", ""),+ "parameters": function.get("parameters", {}),+ }+ )+ return converted or None+++def _stringify_response_payload(value: Any, *, default: str = "") -> str:+ if value is None:+ return default+ if isinstance(value, str):+ return value+ if isinstance(value, list):+ text_parts: List[str] = []+ for part in value:+ if not isinstance(part, dict):+ continue+ part_type = part.get("type")+ if part_type in {"text", "input_text", "output_text"}:+ text = part.get("text")+ if text is not None:+ text_parts.append(str(text))+ if text_parts:+ return "".join(text_parts)+ try:+ return json.dumps(value, ensure_ascii=False)+ except TypeError:+ return str(value)+++def _convert_tool_call_history(tool_calls: Any) -> List[Dict[str, Any]]:+ if not isinstance(tool_calls, list):+ return []+ converted: List[Dict[str, Any]] = []+ for tool_call in tool_calls:+ if not isinstance(tool_call, dict):+ continue+ function = tool_call.get("function")+ if not isinstance(function, dict):+ continue+ name = str(function.get("name", "") or "").strip()+ if not name:+ continue+ converted.append(+ {+ "type": "function_call",+ "call_id": str(tool_call.get("id", "") or tool_call.get("call_id", "") or ""),+ "name": name,+ "arguments": _stringify_response_payload(function.get("arguments"), default="{}"),+ }+ )+ return converted+++def _convert_message_for_responses(message: Dict[str, Any]) -> List[Dict[str, Any]]:+ role = str(message.get("role", "user") or "user")+ content = message.get("content")+ if role == "tool":+ return [+ {+ "type": "function_call_output",+ "call_id": str(message.get("tool_call_id", "") or message.get("call_id", "") or ""),+ "output": _stringify_response_payload(content),+ }+ ]+ if role == "assistant":+ converted: List[Dict[str, Any]] = []+ converted_content = _convert_content_for_responses(content)+ if converted_content not in ("", []):+ converted.append({"role": "assistant", "content": converted_content})+ converted.extend(_convert_tool_call_history(message.get("tool_calls")))+ return converted+ normalized_role = role if role in {"user", "assistant"} else "user"+ return [{"role": normalized_role, "content": _convert_content_for_responses(content)}]+++def _item_get(obj: Any, key: str, default: Any = None) -> Any:+ value = getattr(obj, key, None)+ if value is None and isinstance(obj, dict):+ value = obj.get(key, default)+ return default if value is None else value+++def _build_chat_completion_like_response(final_response: Any, model: str) -> Any:+ text_parts: List[str] = []+ tool_calls: List[Any] = []+ for item in getattr(final_response, "output", []) or []:+ item_type = _item_get(item, "type")+ if item_type == "message":+ for part in _item_get(item, "content", []) or []:+ if _item_get(part, "type") in {"output_text", "text"}:+ text_parts.append(str(_item_get(part, "text", "")))+ continue+ if item_type == "function_call":+ tool_calls.append(+ SimpleNamespace(+ id=_item_get(item, "call_id", ""),+ type="function",+ function=SimpleNamespace(+ name=_item_get(item, "name", ""),+ arguments=_item_get(item, "arguments", "{}"),+ ),+ )+ )+ usage_raw = getattr(final_response, "usage", None)+ usage = None+ if usage_raw is not None:+ usage = SimpleNamespace(+ prompt_tokens=getattr(usage_raw, "input_tokens", 0),+ completion_tokens=getattr(usage_raw, "output_tokens", 0),+ total_tokens=getattr(usage_raw, "total_tokens", 0),+ )+ message = SimpleNamespace(+ role="assistant",+ content="".join(text_parts).strip() or None,+ tool_calls=tool_calls or None,+ )+ choice = SimpleNamespace(+ index=0,+ message=message,+ finish_reason="tool_calls" if tool_calls else "stop",+ )+ return SimpleNamespace(+ choices=[choice],+ model=model,+ usage=usage,+ )+++class CodexCompletionsAdapter:+ def __init__(self, client_factory: Callable[[], Any], model: str):+ self._client_factory = client_factory+ self._model = model++ def _create_response(self, **kwargs) -> Any:+ client = self._client_factory()+ messages = kwargs.get("messages") or []+ model = kwargs.get("model") or self._model+ instructions_parts: List[str] = []+ input_messages: List[Dict[str, Any]] = []+ for message in messages:+ if not isinstance(message, dict):+ continue+ role = str(message.get("role", "user") or "user")+ content = message.get("content") or ""+ if role in {"system", "developer"}:+ instructions_parts.append(content if isinstance(content, str) else str(content))+ continue+ input_messages.extend(_convert_message_for_responses(message))+ response_kwargs: Dict[str, Any] = {+ "model": model,+ "instructions": "\n\n".join(part for part in instructions_parts if part).strip()+ or "You are a helpful assistant.",+ "input": input_messages or [{"role": "user", "content": ""}],+ "store": False,+ }+ tools = _convert_tools_for_responses(kwargs.get("tools"))+ if tools:+ response_kwargs["tools"] = tools+ collected_output_items: List[Any] = []+ collected_text_deltas: List[str] = []+ has_function_calls = False+ with client.responses.stream(**response_kwargs) as stream:+ for event in stream:+ event_type = getattr(event, "type", "")+ if event_type == "response.output_item.done":+ item = getattr(event, "item", None)+ if item is not None:+ collected_output_items.append(item)+ continue+ if "output_text.delta" in event_type:+ delta = getattr(event, "delta", "")+ if delta:+ collected_text_deltas.append(delta)+ continue+ if "function_call" in event_type:+ has_function_calls = True+ final_response = stream.get_final_response()+ output = getattr(final_response, "output", None)+ if not output:+ if collected_output_items:+ final_response.output = list(collected_output_items)+ elif collected_text_deltas and not has_function_calls:+ final_response.output = [+ SimpleNamespace(+ type="message",+ role="assistant",+ status="completed",+ content=[+ SimpleNamespace(type="output_text", text="".join(collected_text_deltas))+ ],+ )+ ]+ return _build_chat_completion_like_response(final_response, model)++ def create(self, **kwargs) -> Any:+ if kwargs.get("stream"):+ raise NotImplementedError("Streaming is not supported for openai-codex.")+ response = self._create_response(**kwargs)+ return response+++class CodexChatShim:+ def __init__(self, adapter: CodexCompletionsAdapter):+ self.completions = adapter+++class CodexAsyncCompletionsAdapter:+ def __init__(self, sync_adapter: CodexCompletionsAdapter):+ self._sync_adapter = sync_adapter++ async def create(self, **kwargs) -> Any:+ if kwargs.get("stream"):+ raise NotImplementedError("Streaming is not supported for openai-codex.")+ response = await asyncio.to_thread(self._sync_adapter._create_response, **kwargs)+ return response+++class CodexAsyncChatShim:+ def __init__(self, adapter: CodexAsyncCompletionsAdapter):+ self.completions = adapterdiff --git a/openviking/models/vlm/backends/codex_vlm.py b/openviking/models/vlm/backends/codex_vlm.pynew file mode 100644index 000000000..71d5c2424--- /dev/null+++ b/openviking/models/vlm/backends/codex_vlm.py@@ -0,0 +1,110 @@+# Copyright (c) 2026 Beijing Volcano Engine Technology Co., Ltd.+# SPDX-License-Identifier: AGPL-3.0++"""+Codex VLM Backend Integration++This module implements the integration with the Codex provider for Vision-Language Models (VLM).+Unlike standard OpenAI API billing endpoints which use the Chat Completions API, Codex's+subscription-based endpoints process multimodal (vision/VLM) requests primarily through+the auxiliary Responses API (`client.responses`).++The complexity in this file arises from the need to shim/adapt standard Chat Completions+requests (used by OpenViking) into Responses API requests. This involves:+1. Converting `text` and `image_url` parts into `input_text` and `input_image`.+2. Adapting tool calls and schemas.+3. Translating the `client.responses.stream` event stream back into a format+ compatible with standard Chat Completion responses.+"""++from __future__ import annotations++from types import SimpleNamespace+from typing import Any, Dict++try:+ import openai+except ImportError:+ openai = None++from .codex_auth import DEFAULT_CODEX_BASE_URL, resolve_codex_runtime_credentials+from .codex_responses_adapter import (+ CodexAsyncChatShim,+ CodexAsyncCompletionsAdapter,+ CodexChatShim,+ CodexCompletionsAdapter,+)+from .openai_vlm import OpenAIVLM, _build_openai_client_kwargs+++class CodexVLM(OpenAIVLM):+ def __init__(self, config: Dict[str, Any]):+ normalized = dict(config)+ normalized["provider"] = "openai-codex"+ if not normalized.get("api_base"):+ normalized["api_base"] = DEFAULT_CODEX_BASE_URL+ super().__init__(normalized)++ def _build_responses_client(self, api_key: str, api_base: str):+ kwargs = _build_openai_client_kwargs(+ "openai",+ api_key,+ api_base,+ self.api_version,+ self.extra_headers,+ self.timeout,+ )+ return openai.OpenAI(**kwargs)++ def _get_or_create_sync_responses_client(self):+ if self._sync_client is None:+ adapter = CodexCompletionsAdapter(+ lambda: self._build_responses_client(*self._resolve_runtime_credentials()),+ self.model or "gpt-5.3-codex",+ )+ self._sync_client = SimpleNamespace(chat=CodexChatShim(adapter))+ return self._sync_client++ def _get_or_create_async_responses_client(self):+ # The async path uses a sync Responses client behind asyncio.to_thread so+ # credential refresh and auth-store I/O do not block the event loop.+ if self._async_client is None:+ sync_adapter = CodexCompletionsAdapter(+ lambda: self._build_responses_client(*self._resolve_runtime_credentials()),+ self.model or "gpt-5.3-codex",+ )+ self._async_client = SimpleNamespace(+ chat=CodexAsyncChatShim(CodexAsyncCompletionsAdapter(sync_adapter))+ )+ return self._async_client++ def _resolve_runtime_credentials(self) -> tuple[str, str]:+ explicit_api_key = str(self.config.get("api_key", "") or "").strip()+ explicit_api_base = str(self.config.get("api_base", "") or "").strip().rstrip("/")+ if explicit_api_key:+ self.api_key = explicit_api_key+ self.api_base = explicit_api_base or DEFAULT_CODEX_BASE_URL+ return self.api_key, self.api_base+ credentials = resolve_codex_runtime_credentials()+ self.api_key = credentials["api_key"]+ self.api_base = explicit_api_base or credentials["base_url"]+ return self.api_key, self.api_base++ def get_client(self):+ if openai is None:+ raise ImportError("Please install openai: pip install openai")+ return self._get_or_create_sync_responses_client()++ def get_async_client(self):+ if openai is None:+ raise ImportError("Please install openai: pip install openai")+ return self._get_or_create_async_responses_client()++ def is_available(self) -> bool:+ if str(self.config.get("api_key", "") or "").strip():+ return True+ try:+ resolve_codex_runtime_credentials(refresh_if_expiring=False)+ except Exception:+ return False+ return Truediff --git a/openviking/models/vlm/backends/glm_vlm.py b/openviking/models/vlm/backends/glm_vlm.pynew file mode 100644index 000000000..8c80788ac--- /dev/null+++ b/openviking/models/vlm/backends/glm_vlm.py@@ -0,0 +1,23 @@+# Copyright (c) 2026 Beijing Volcano Engine Technology Co., Ltd.+# SPDX-License-Identifier: AGPL-3.0+"""GLM Coding Plan VLM backend."""++from __future__ import annotations++from typing import Any, Dict++from .openai_vlm import OpenAIVLM++DEFAULT_GLM_API_BASE = "https://api.z.ai/api/coding/paas/v4"+DEFAULT_GLM_MODEL = "glm-4.6v"+++class GLMVLM(OpenAIVLM):+ """First-class GLM backend with Coding Plan defaults."""++ def __init__(self, config: Dict[str, Any]):+ normalized = dict(config)+ normalized["provider"] = "glm"+ normalized.setdefault("model", DEFAULT_GLM_MODEL)+ normalized["api_base"] = str(normalized.get("api_base") or DEFAULT_GLM_API_BASE).rstrip("/")+ super().__init__(normalized)diff --git a/openviking/models/vlm/backends/kimi_vlm.py b/openviking/models/vlm/backends/kimi_vlm.pynew file mode 100644index 000000000..9dc49e6e7--- /dev/null+++ b/openviking/models/vlm/backends/kimi_vlm.py@@ -0,0 +1,38 @@+# Copyright (c) 2026 Beijing Volcano Engine Technology Co., Ltd.+# SPDX-License-Identifier: AGPL-3.0++from __future__ import annotations++from typing import Any, Dict++from .openai_vlm import OpenAIVLM++DEFAULT_KIMI_API_BASE = "https://api.kimi.com/coding"+DEFAULT_KIMI_MODEL = "kimi-code"+DEFAULT_KIMI_MAX_TOKENS = 32768+DEFAULT_KIMI_USER_AGENT = "KimiCLI/1.30.0"+KIMI_LEGACY_MODEL_ALIASES = {+ "kimi-code": "kimi-for-coding",+ "k2p5": "kimi-for-coding",+}+++def _normalize_kimi_api_base(api_base: str | None) -> str:+ normalized = str(api_base or DEFAULT_KIMI_API_BASE).rstrip("/")+ if normalized.endswith("/v1"):+ return normalized+ return f"{normalized}/v1"+++class KimiVLM(OpenAIVLM):+ def __init__(self, config: Dict[str, Any]):+ normalized = dict(config)+ model = str(normalized.get("model") or DEFAULT_KIMI_MODEL).strip() or DEFAULT_KIMI_MODEL+ normalized["provider"] = "kimi"+ normalized["api_base"] = _normalize_kimi_api_base(normalized.get("api_base"))+ normalized["model"] = KIMI_LEGACY_MODEL_ALIASES.get(model, model)+ normalized.setdefault("max_tokens", DEFAULT_KIMI_MAX_TOKENS)+ extra_headers = dict(normalized.get("extra_headers") or {})+ extra_headers.setdefault("User-Agent", DEFAULT_KIMI_USER_AGENT)+ normalized["extra_headers"] = extra_headers+ super().__init__(normalized)diff --git a/openviking/models/vlm/base.py b/openviking/models/vlm/base.pyindex bf210e60b..dc9017dfa 100644--- a/openviking/models/vlm/base.py+++ b/openviking/models/vlm/base.py@@ -302,6 +302,21 @@ class VLMFactory:return OpenAIVLM(config)+ elif provider == "openai-codex":+ from .backends.codex_vlm import CodexVLM++ return CodexVLM(config)++ elif provider == "kimi":+ from .backends.kimi_vlm import KimiVLM++ return KimiVLM(config)++ elif provider == "glm":+ from .backends.glm_vlm import GLMVLM++ return GLMVLM(config)+else:from .backends.litellm_vlm import LiteLLMVLMProviderdiff --git a/openviking/models/vlm/registry.py b/openviking/models/vlm/registry.pyindex d69154764..e4f68e544 100644--- a/openviking/models/vlm/registry.py+++ b/openviking/models/vlm/registry.py@@ -1,14 +1,20 @@# Copyright (c) 2026 Beijing Volcano Engine Technology Co., Ltd.# SPDX-License-Identifier: AGPL-3.0"""-Provider Registry — single source of truth for LLM provider metadata.--Supported providers: volcengine, openai, litellm+Provider Registry — single source of truth for canonical LLM provider metadata."""from __future__ import annotations-VALID_PROVIDERS: tuple[str, ...] = ("volcengine", "openai", "azure", "litellm")+VALID_PROVIDERS: tuple[str, ...] = (+ "volcengine",+ "openai",+ "azure",+ "kimi",+ "glm",+ "litellm",+ "openai-codex",+)DEFAULT_AZURE_API_VERSION: str = "2025-01-01-preview"diff --git a/openviking/server/error_mapping.py b/openviking/server/error_mapping.pyindex 8df4d64e7..7aa6ab5e9 100644--- a/openviking/server/error_mapping.py+++ b/openviking/server/error_mapping.py@@ -58,7 +58,9 @@ def map_exception(if exc.status_code == 409:return ConflictError(str(exc), resource=resource)if exc.status_code == 400:- return InvalidArgumentError(str(exc), details={"resource": resource} if resource else None)+ return InvalidArgumentError(+ str(exc), details={"resource": resource} if resource else None+ )if exc.status_code in {500, 502, 503, 504}:return UnavailableError("storage backend", reason=str(exc))if isinstance(exc, AGFSClientError):diff --git a/openviking/session/memory/dataclass.py b/openviking/session/memory/dataclass.pyindex dcf7873e0..171ab13b7 100644--- a/openviking/session/memory/dataclass.py+++ b/openviking/session/memory/dataclass.py@@ -118,7 +118,7 @@ class FaultTolerantBaseModel(BaseModel):origin = get_origin(annotation)if origin is Union:args = get_args(annotation)- if len(args) == 2 and args[1] == type(None):+ if len(args) == 2 and args[1] is type(None):return cls.get_origin_type(args[0])elif origin is list:return list@@ -130,7 +130,7 @@ class FaultTolerantBaseModel(BaseModel):origin = get_origin(annotation)if origin is Union:args = get_args(annotation)- if len(args) == 2 and args[1] == type(None):+ if len(args) == 2 and args[1] is type(None):return cls.get_arg_type(args[0])elif origin is list:args = get_args(annotation)@@ -240,11 +240,7 @@ class StructuredMemoryOperations(FaultTolerantBaseModel):def is_empty(self) -> bool:"""Check if there are any operations."""- return (- len(self.write_uris) == 0- and len(self.edit_uris) == 0- and len(self.delete_uris) == 0- )+ return len(self.write_uris) == 0 and len(self.edit_uris) == 0 and len(self.delete_uris) == 0def to_legacy_operations(self) -> Dict[str, Any]:"""Convert to legacy format (identity for fallback)."""diff --git a/openviking/session/memory/memory_updater.py b/openviking/session/memory/memory_updater.pyindex ebc065c58..4a3ec986d 100644--- a/openviking/session/memory/memory_updater.py+++ b/openviking/session/memory/memory_updater.py@@ -26,8 +26,8 @@ from openviking.session.memory.utils import ()from openviking.storage.viking_fs import get_viking_fsfrom openviking.telemetry import tracer-from openviking.utils.time_utils import parse_iso_datetimefrom openviking.telemetry.request_wait_tracker import get_request_wait_tracker+from openviking.utils.time_utils import parse_iso_datetimefrom openviking_cli.exceptions import NotFoundErrorfrom openviking_cli.utils import get_loggerdiff --git a/openviking/session/memory/utils/uri.py b/openviking/session/memory/utils/uri.pyindex 85c5628f0..47132ceee 100644--- a/openviking/session/memory/utils/uri.py+++ b/openviking/session/memory/utils/uri.py@@ -12,6 +12,7 @@ import jinja2from openviking.session.memory.dataclass import MemoryTypeSchemafrom openviking.session.memory.memory_type_registry import MemoryTypeRegistry+from openviking.session.memory.utils.model import model_to_dictfrom openviking_cli.utils import get_loggerlogger = get_logger(__name__)@@ -303,9 +304,6 @@ def is_uri_allowed_for_schema(return is_uri_allowed(uri, allowed_dirs, allowed_patterns)-from openviking.session.memory.utils.model import model_to_dict--def extract_uri_fields_from_flat_model(model: Any, schema: MemoryTypeSchema) -> Dict[str, Any]:"""Extract URI-friendly fields from a flat model, ignoring patch objects.diff --git a/openviking/session/session.py b/openviking/session/session.pyindex c05a8646e..6f303794b 100644--- a/openviking/session/session.py+++ b/openviking/session/session.py@@ -641,7 +641,9 @@ class Session:if self._viking_fs:for usage in usage_records:try:- await self._viking_fs.link(self._session_uri, usage.uri, ctx=self.ctx)+ await self._viking_fs.link(+ self._session_uri, usage.uri, ctx=self.ctx+ )except Exception as e:logger.warning(f"Failed to create relation to {usage.uri}: {e}")@@ -651,8 +653,8 @@ class Session:if self._vikingdb_manager:uris = [u.uri for u in usage_records if u.uri]try:- active_count_updated = await self._vikingdb_manager.increment_active_count(- self.ctx, uris+ active_count_updated = (+ await self._vikingdb_manager.increment_active_count(self.ctx, uris))except Exception as e:logger.debug(f"Could not update active_count for usage URIs: {e}")diff --git a/openviking/storage/vectordb/utils/stale_lock.py b/openviking/storage/vectordb/utils/stale_lock.pyindex a46b6f7b5..7c1cf3f65 100644--- a/openviking/storage/vectordb/utils/stale_lock.py+++ b/openviking/storage/vectordb/utils/stale_lock.py@@ -26,8 +26,8 @@ import globimport osimport sys-from openviking_cli.utils import get_loggerfrom openviking.storage.vectordb.utils.path_safety import resolve_storage_path+from openviking_cli.utils import get_loggerlogger = get_logger(__name__)_LOG_ESCAPE_TABLE = str.maketrans(diff --git a/openviking_cli/doctor.py b/openviking_cli/doctor.pyindex 8317ebdea..8a21f5e71 100644--- a/openviking_cli/doctor.py+++ b/openviking_cli/doctor.py@@ -20,6 +20,7 @@ from typing import Optionalfrom openviking_cli.utils.config.config_loader import resolve_config_pathfrom openviking_cli.utils.config.consts import OPENVIKING_CONFIG_ENV+from openviking_cli.utils.config.vlm_config import VLMConfig# ANSI helpers (disabled when stdout is not a terminal)_USE_COLOR = hasattr(sys.stdout, "isatty") and sys.stdout.isatty()@@ -226,18 +227,43 @@ def check_vlm() -> tuple[bool, str, Optional[str]]:if data is None:return False, "Cannot check (config unreadable)", None- vlm = data.get("vlm", {})- provider = vlm.get("provider", "")- model = vlm.get("model", "")+ raw_vlm = data.get("vlm", {})+ normalized_vlm = VLMConfig.sync_provider_backend(dict(raw_vlm))+ vlm = VLMConfig.model_construct(**normalized_vlm)+ _, provider = vlm.get_provider_config()+ model = vlm.model or ""if not provider:return False, "No VLM provider configured", "Add vlm section to ov.conf"+ if provider == "openai-codex":+ api_key = vlm._get_effective_api_key()+ if api_key and not api_key.startswith("{"):+ return True, f"openai-codex/{model} (explicit api_key)", None++ importlib.import_module("openviking.models.vlm")+ codex_auth = importlib.import_module("openviking.models.vlm.backends.codex_auth")++ try:+ creds = codex_auth.resolve_codex_runtime_credentials()+ source = creds.get("source", "unknown")+ return True, f"openai-codex/{model} (oauth via {source})", None+ except Exception as exc:+ status = codex_auth.get_codex_auth_status()+ store_path = status.get("store_path") or "~/.openviking/codex_auth.json"+ bootstrap_path = status.get("bootstrap_path") or "~/.codex/auth.json"+ return (+ False,+ f"openai-codex/{model} ({exc})",+ "Run `openviking-server init` and choose `OpenAI Codex` to create OV-owned auth state\n"+ f"Or bootstrap once from {bootstrap_path} into {store_path}",+ )+# Ollama via LiteLLM doesn't need a real API keyif provider == "litellm" and model.startswith("ollama/"):return True, f"{provider}/{model}", None- api_key = vlm.get("api_key", "")+ api_key = vlm._get_effective_api_key()if not api_key or api_key.startswith("{"):return (False,@@ -342,7 +368,7 @@ def run_doctor() -> int:try:ok, detail, fix = check_fn()except Exception as exc:- ok, detail, fix = False, f"Unexpected error: {exc}", None+ ok, detail, fix = False, f"Unexpected error: {type(exc).__name__}: {exc}", Nonepad = " " * (max_label - len(label) + 1)if ok:diff --git a/openviking_cli/setup_wizard.py b/openviking_cli/setup_wizard.pyindex d9ca1eea2..b0a9a4a12 100644--- a/openviking_cli/setup_wizard.py+++ b/openviking_cli/setup_wizard.py@@ -26,6 +26,13 @@ from openviking_cli.utils.ollama import (start_ollama,)+_DEFAULT_CODEX_BASE_URL = "https://chatgpt.com/backend-api/codex"+_DEFAULT_KIMI_BASE_URL = "https://api.kimi.com/coding"+_DEFAULT_GLM_BASE_URL = "https://api.z.ai/api/coding/paas/v4"+_DEFAULT_CODEX_MODEL = "gpt-5.4"+_DEFAULT_KIMI_MODEL = "kimi-code"+_DEFAULT_GLM_MODEL = "glm-4.6v"+# ---------------------------------------------------------------------------# ANSI helpers (same pattern as doctor.py)# ---------------------------------------------------------------------------@@ -88,14 +95,38 @@ def _prompt_choice(prompt: str, options: list[tuple[str, str]], default: int = 1print(f" {_red('Please enter a number between 1 and ' + str(len(options)))}")-def _prompt_input(prompt: str, default: str = "") -> str:- """Prompt for free-text input with optional default."""- suffix = f" [{default}]" if default else ""- try:- raw = input(f" {prompt}{suffix}: ").strip()- except EOFError:- return default- return raw or default+def _prompt_required_input(prompt: str, default: str | None = None) -> str:+ """Prompt for a required free-text value."""+ while True:+ try:+ prompt_text = f" {prompt} [{default}]: " if default is not None else f" {prompt}: "+ raw = input(prompt_text).strip()+ except EOFError:+ return default or ""+ if not raw and default is not None:+ return default+ if raw:+ return raw+ print(f" {_red(prompt + ' is required')}")+++def _prompt_required_int(prompt: str, default: int | None = None) -> int | None:+ """Prompt for a required integer value."""+ while True:+ try:+ prompt_text = f" {prompt} [{default}]: " if default is not None else f" {prompt}: "+ raw = input(prompt_text).strip()+ except EOFError:+ return default+ if not raw:+ if default is not None:+ return default+ print(f" {_red(prompt + ' is required')}")+ continue+ try:+ return int(raw)+ except ValueError:+ print(f" {_red('Please enter a valid integer')}")def _prompt_confirm(prompt: str, default: bool = True) -> bool:@@ -201,6 +232,50 @@ def _ensure_ollama() -> bool:return result.success+def _ensure_codex_auth() -> bool:+ import importlib++ importlib.import_module("openviking.models.vlm")+ codex_auth = importlib.import_module("openviking.models.vlm.backends.codex_auth")++ print("\n Checking Codex OAuth...", end=" ", flush=True)+ try:+ creds = codex_auth.resolve_codex_runtime_credentials(refresh_if_expiring=False)+ source = creds.get("source", "unknown")+ print(_green(f"ready via {source}"))+ return True+ except Exception:+ print(_yellow("not ready"))++ status = codex_auth.get_codex_auth_status()+ bootstrap_path = status.get("bootstrap_path")++ if status.get("bootstrap_available") and bootstrap_path:+ if _prompt_confirm(f"Import existing Codex CLI auth from {bootstrap_path}?"):+ try:+ path = codex_auth.bootstrap_codex_auth()+ except codex_auth.CodexAuthError as exc:+ print(f" {_yellow(str(exc))}")+ else:+ if path is not None:+ print(f" {_green('OK')} Imported Codex OAuth into {path}")+ return True++ if _prompt_confirm("Sign in to Codex now?"):+ try:+ path = codex_auth.login_codex_with_device_code()+ except codex_auth.CodexAuthError as exc:+ print(f" {_yellow(str(exc))}")+ else:+ print(f" {_green('OK')} Codex OAuth stored in {path}")+ return True++ print(+ f" {_dim('You can finish setup now and re-run `openviking-server init` later to complete Codex sign-in.')}"+ )+ return False++# ---------------------------------------------------------------------------# Model presets# ---------------------------------------------------------------------------@@ -286,7 +361,7 @@ CLOUD_PROVIDERS: list[CloudProvider] = ["https://api.openai.com/v1","text-embedding-3-small",1536,- "gpt-4o-mini",+ "gpt-5.4",),CloudProvider("Volcengine (Doubao)",@@ -294,11 +369,27 @@ CLOUD_PROVIDERS: list[CloudProvider] = ["https://ark.cn-beijing.volces.com/api/v3","doubao-embedding-vision-251215",1024,- "doubao-seed-2-0-pro-260215",+ "doubao-seed-2-0-code-preview-260215",),]+def _get_cloud_provider(provider_name: str) -> CloudProvider:+ for provider in CLOUD_PROVIDERS:+ if provider.provider == provider_name:+ return provider+ raise ValueError(f"Unknown cloud provider: {provider_name}")+++_WIZARD_VLM_OPTIONS: list[tuple[str, str]] = [+ ("OpenAI", "(API)"),+ ("Volcengine", "(API)"),+ ("OpenAI Codex", "(Subscription)"),+ ("Kimi", "(Subscription API Key)"),+ ("GLM", "(Subscription API Key)"),+]++# ---------------------------------------------------------------------------# llama.cpp local embedding presets# ---------------------------------------------------------------------------@@ -424,13 +515,25 @@ def _build_cloud_config(embedding_api_key: str,embedding_model: str,embedding_dim: int,- vlm_api_key: str,vlm_model: str,workspace: str,embedding_api_base: str | None = None,+ vlm_provider: str | None = None,+ vlm_api_key: str | None = None,vlm_api_base: str | None = None,) -> dict[str, Any]:- """Build ov.conf dict for cloud API setup."""+ resolved_vlm_provider = vlm_provider or provider.provider+ resolved_vlm_api_base = vlm_api_base or provider.default_api_base+ vlm_config: dict[str, Any] = {+ "provider": resolved_vlm_provider,+ "model": vlm_model,+ "api_base": resolved_vlm_api_base,+ "temperature": 0.0,+ "max_retries": 2,+ }+ if vlm_api_key:+ vlm_config["api_key"] = vlm_api_key+return {"storage": {"workspace": workspace},"embedding": {@@ -442,14 +545,7 @@ def _build_cloud_config("dimension": embedding_dim,},},- "vlm": {- "provider": provider.provider,- "model": vlm_model,- "api_key": vlm_api_key,- "api_base": vlm_api_base or provider.default_api_base,- "temperature": 0.0,- "max_retries": 2,- },+ "vlm": vlm_config,}@@ -560,10 +656,7 @@ def _wizard_ollama() -> dict[str, Any] | None:else:print(f" {_green('OK')} {vlm.ollama_model} pulled successfully")- # Workspace- workspace = _prompt_input("Workspace", default=_DEFAULT_WORKSPACE)-- return _build_ollama_config(embedding, vlm, workspace)+ return _build_ollama_config(embedding, vlm, _DEFAULT_WORKSPACE)def _wizard_llamacpp() -> dict[str, Any] | None:@@ -721,12 +814,12 @@ def _wizard_llamacpp() -> dict[str, Any] | None:choice = _prompt_choice("Cloud provider for VLM:", provider_options, default=1)provider = CLOUD_PROVIDERS[choice - 1]- vlm_api_key = _prompt_input("VLM API Key")+ vlm_api_key = _prompt_required_input("VLM API Key")if not vlm_api_key:print(f" {_red('API key is required')}")return None- vlm_model = _prompt_input("VLM Model", default=provider.default_vlm_model)- vlm_api_base = _prompt_input("API Base", default=provider.default_api_base)+ vlm_model = _prompt_required_input("Vision Model")+ vlm_api_base = provider.default_api_basevlm_config = {"provider": provider.provider,@@ -737,13 +830,10 @@ def _wizard_llamacpp() -> dict[str, Any] | None:"max_retries": 2,}- # --- Step 4: workspace ---- workspace = _prompt_input("Workspace", default=_DEFAULT_WORKSPACE)-return _build_local_config(model_name=model_name,dimension=dimension,- workspace=workspace,+ workspace=_DEFAULT_WORKSPACE,model_path=custom_model_path,vlm_config=vlm_config,)@@ -754,7 +844,7 @@ def _wizard_cloud() -> dict[str, Any] | None:# Provider selectionprovider_options = [(p.label, "") for p in CLOUD_PROVIDERS]provider_options.append(("Other (manual)", ""))- choice = _prompt_choice("Cloud provider:", provider_options, default=1)+ choice = _prompt_choice("Embedding provider:", provider_options, default=1)if choice > len(CLOUD_PROVIDERS):# Manual / Other@@ -766,37 +856,81 @@ def _wizard_cloud() -> dict[str, Any] | None:# Embedding configprint(f"\n {_bold('Embedding configuration')}")- embedding_api_key = _prompt_input("API Key")+ embedding_api_key = _prompt_required_input("API Key")if not embedding_api_key:print(f" {_red('API key is required')}")return None- embedding_model = _prompt_input("Model", default=provider.default_embedding_model)- embedding_dim_str = _prompt_input("Dimension", default=str(provider.default_embedding_dim))- try:- embedding_dim = int(embedding_dim_str)- except ValueError:- embedding_dim = provider.default_embedding_dim- embedding_api_base = _prompt_input("API Base", default=provider.default_api_base)+ embedding_model = _prompt_required_input("Model", default=provider.default_embedding_model)+ embedding_dim = _prompt_required_int("Dimension", default=provider.default_embedding_dim)+ if embedding_dim is None:+ print(f" {_red('Dimension is required')}")+ return None+ embedding_api_base = provider.default_api_base- # VLM config- print(f"\n {_bold('VLM configuration')}")- vlm_api_key = _prompt_input("API Key (same as above?)", default=embedding_api_key)- vlm_model = _prompt_input("Model", default=provider.default_vlm_model)- vlm_api_base = _prompt_input("API Base", default=provider.default_api_base)+ vlm_mode = _prompt_choice("VLM provider:", _WIZARD_VLM_OPTIONS, default=1)- # Workspace- workspace = _prompt_input("Workspace", default=_DEFAULT_WORKSPACE)+ if vlm_mode == 1:+ vlm_choice = _get_cloud_provider("openai")+ print(f"\n {_bold('VLM configuration')}")+ vlm_api_key = _prompt_required_input("API Key")+ if not vlm_api_key:+ print(f" {_red('API key is required')}")+ return None+ vlm_model = _prompt_required_input("Model", default=vlm_choice.default_vlm_model)+ vlm_api_base = vlm_choice.default_api_base+ vlm_provider = vlm_choice.provider+ workspace = _DEFAULT_WORKSPACE+ elif vlm_mode == 2:+ vlm_choice = _get_cloud_provider("volcengine")+ print(f"\n {_bold('VLM configuration')}")+ vlm_api_key = _prompt_required_input("API Key")+ if not vlm_api_key:+ print(f" {_red('API key is required')}")+ return None+ vlm_model = _prompt_required_input("Model", default=vlm_choice.default_vlm_model)+ vlm_api_base = vlm_choice.default_api_base+ vlm_provider = vlm_choice.provider+ workspace = _DEFAULT_WORKSPACE+ elif vlm_mode == 3:+ _ensure_codex_auth()+ print(f"\n {_bold('Codex VLM configuration')}")+ vlm_model = _prompt_required_input("Model", default=_DEFAULT_CODEX_MODEL)+ vlm_api_base = _DEFAULT_CODEX_BASE_URL+ vlm_api_key = None+ vlm_provider = "openai-codex"+ workspace = _DEFAULT_WORKSPACE+ elif vlm_mode == 4:+ print(f"\n {_bold('Kimi VLM configuration')}")+ vlm_api_key = _prompt_required_input("API Key")+ if not vlm_api_key:+ print(f" {_red('API key is required')}")+ return None+ vlm_model = _prompt_required_input("Model", default=_DEFAULT_KIMI_MODEL)+ vlm_api_base = _DEFAULT_KIMI_BASE_URL+ vlm_provider = "kimi"+ workspace = _DEFAULT_WORKSPACE+ else:+ print(f"\n {_bold('GLM VLM configuration')}")+ vlm_api_key = _prompt_required_input("API Key")+ if not vlm_api_key:+ print(f" {_red('API key is required')}")+ return None+ vlm_model = _prompt_required_input("Model", default=_DEFAULT_GLM_MODEL)+ vlm_api_base = _DEFAULT_GLM_BASE_URL+ vlm_provider = "glm"+ workspace = _DEFAULT_WORKSPACEreturn _build_cloud_config(provider,embedding_api_key,embedding_model,embedding_dim,- vlm_api_key,vlm_model,workspace,- embedding_api_base,- vlm_api_base,+ embedding_api_base=embedding_api_base,+ vlm_provider=vlm_provider,+ vlm_api_key=vlm_api_key,+ vlm_api_base=vlm_api_base,)@@ -834,6 +968,9 @@ def run_init() -> int:"""Run the interactive setup wizard."""print(f"\n {_bold('OpenViking Setup')}")print(f" {'=' * 16}\n")+ print(+ f" {_dim('Data will be stored under ~/.openviking/data unless you edit ov.conf later.')}\n"+ )# Check for existing configif _DEFAULT_CONFIG_PATH.exists():diff --git a/openviking_cli/utils/config/vlm_config.py b/openviking_cli/utils/config/vlm_config.pyindex 5b1791e3e..8e32a80aa 100644--- a/openviking_cli/utils/config/vlm_config.py+++ b/openviking_cli/utils/config/vlm_config.py@@ -1,10 +1,23 @@# Copyright (c) 2026 Beijing Volcano Engine Technology Co., Ltd.# SPDX-License-Identifier: AGPL-3.0+import importlibfrom typing import Any, Dict, List, Optional, Unionfrom pydantic import BaseModel, Field, model_validator+def _load_codex_auth_module():+ importlib.import_module("openviking.models.vlm")+ return importlib.import_module("openviking.models.vlm.backends.codex_auth")+++def _normalize_provider_name(name: Optional[str]) -> Optional[str]:+ if not isinstance(name, str):+ return name+ cleaned = name.strip().lower()+ return cleaned or None++class VLMConfig(BaseModel):"""VLM configuration, supports multiple provider backends."""@@ -72,6 +85,24 @@ class VLMConfig(BaseModel):if backend is not None and provider is None:data["provider"] = backend+ data["provider"] = _normalize_provider_name(data.get("provider"))+ data["backend"] = _normalize_provider_name(data.get("backend"))+ data["default_provider"] = _normalize_provider_name(data.get("default_provider"))+ providers = data.get("providers")+ if isinstance(providers, dict):+ normalized: Dict[str, Dict[str, Any]] = {}+ provider_sources: Dict[str, str] = {}+ for name, config in providers.items():+ normalized_name = _normalize_provider_name(name) or str(name)+ existing_name = provider_sources.get(normalized_name)+ if existing_name is not None and existing_name != str(name):+ raise ValueError(+ "Duplicate VLM provider config after normalization: "+ f"{existing_name} and {name}"+ )+ normalized[normalized_name] = config+ provider_sources[normalized_name] = str(name)+ data["providers"] = normalizedreturn data@model_validator(mode="after")@@ -82,7 +113,15 @@ class VLMConfig(BaseModel):if self._has_any_config():if not self.model:raise ValueError("VLM configuration requires 'model' to be set")- if not self._get_effective_api_key():+ provider_name = self._resolve_provider_name()+ if provider_name == "openai-codex":+ has_codex_auth_available = _load_codex_auth_module().has_codex_auth_available++ if not self._get_effective_api_key() and not has_codex_auth_available():+ raise ValueError(+ "VLM configuration requires Codex OAuth credentials in ~/.openviking/codex_auth.json or an importable Codex CLI auth file"+ )+ elif not self._get_effective_api_key():raise ValueError("VLM configuration requires 'api_key' to be set")return self@@ -102,12 +141,10 @@ class VLMConfig(BaseModel):def _has_any_config(self) -> bool:"""Check if any config is provided."""- if self.api_key or self.model or self.api_base:+ if self.api_key or self.model or self.api_base or self.provider or self.default_provider:return Trueif self.providers:- for p in self.providers.values():- if p.get("api_key"):- return True+ return Truereturn Falsedef _get_effective_api_key(self) -> str | None:@@ -119,23 +156,58 @@ class VLMConfig(BaseModel):return config["api_key"]return None+ def _get_provider_config_by_name(self, provider_name: str) -> Dict[str, Any]:+ config = dict(self.providers.get(provider_name) or {})+ if self.api_key and "api_key" not in config:+ config["api_key"] = self.api_key+ if self.api_base and "api_base" not in config:+ config["api_base"] = self.api_base+ if self.extra_headers and "extra_headers" not in config:+ config["extra_headers"] = self.extra_headers+ if self.stream and "stream" not in config:+ config["stream"] = self.stream+ return config++ def _provider_has_usable_credentials(self, provider_name: str, config: Dict[str, Any]) -> bool:+ if config.get("api_key"):+ return True+ if provider_name == "openai-codex":+ has_codex_auth_available = _load_codex_auth_module().has_codex_auth_available++ return has_codex_auth_available()+ return False+def _match_provider(self, model: str | None = None) -> tuple[Dict[str, Any] | None, str | None]:"""Match provider config.Returns:(provider_config_dict, provider_name)"""+ del modelif self.provider:- p = self.providers.get(self.provider)- if p and p.get("api_key"):- return p, self.provider+ return self._get_provider_config_by_name(self.provider) or {}, self.provider- for name, config in self.providers.items():- if config.get("api_key"):- return config, name+ if self.default_provider:+ return (+ self._get_provider_config_by_name(self.default_provider) or {},+ self.default_provider,+ )++ if len(self.providers) == 1:+ provider_name = next(iter(self.providers))+ return self._get_provider_config_by_name(provider_name), provider_name++ for provider_name in self.providers:+ config = self._get_provider_config_by_name(provider_name)+ if self._provider_has_usable_credentials(provider_name, config):+ return config, provider_namereturn None, None+ def _resolve_provider_name(self) -> str | None:+ _, name = self._match_provider()+ return name+def get_provider_config(self, model: str | None = None) -> tuple[Dict[str, Any] | None, str | None]:@@ -168,6 +240,7 @@ class VLMConfig(BaseModel):"model": self.model,"temperature": self.temperature,"max_retries": self.max_retries,+ "timeout": self.timeout,"provider": name,"thinking": self.thinking,"max_tokens": self.max_tokens,@@ -176,9 +249,12 @@ class VLMConfig(BaseModel):}if config:- result["api_key"] = config.get("api_key")- result["api_base"] = config.get("api_base")- result["extra_headers"] = config.get("extra_headers")+ if config.get("api_key"):+ result["api_key"] = config.get("api_key")+ if config.get("api_base"):+ result["api_base"] = config.get("api_base")+ if config.get("extra_headers"):+ result["extra_headers"] = config.get("extra_headers")return result@@ -214,6 +290,10 @@ class VLMConfig(BaseModel):def is_available(self) -> bool:"""Check if LLM is configured."""+ if self._resolve_provider_name() == "openai-codex":+ has_codex_auth_available = _load_codex_auth_module().has_codex_auth_available++ return bool(self._get_effective_api_key() or has_codex_auth_available())return self._get_effective_api_key() is not Nonedef get_vision_completion(diff --git a/tests/cli/test_doctor.py b/tests/cli/test_doctor.pyindex e0fa09071..922829d87 100644--- a/tests/cli/test_doctor.py+++ b/tests/cli/test_doctor.py@@ -170,9 +170,9 @@ class TestCheckEmbedding:with patch.object(Path, "exists", autospec=True, return_value=True):with patch("openviking_cli.doctor.importlib.import_module",- side_effect=lambda name: object()- if name == "llama_cpp"- else real_import(name),+ side_effect=lambda name: (+ object() if name == "llama_cpp" else real_import(name)+ ),):ok, detail, fix = check_embedding()@@ -318,6 +318,65 @@ class TestCheckVlm:assert not okassert "unreadable" in detail+ def test_pass_with_codex_oauth(self, tmp_path: Path):+ config = tmp_path / "ov.conf"+ config.write_text(+ json.dumps({"vlm": {"provider": "openai-codex", "model": "gpt-5.3-codex"}})+ )+ with patch("openviking_cli.doctor._find_config", return_value=config):+ with patch(+ "openviking.models.vlm.backends.codex_auth.resolve_codex_runtime_credentials",+ return_value={"source": "openviking"},+ ):+ ok, detail, fix = check_vlm()+ assert ok+ assert "oauth via openviking" in detail++ def test_fail_with_codex_oauth_missing_auth(self, tmp_path: Path):+ config = tmp_path / "ov.conf"+ config.write_text(+ json.dumps({"vlm": {"provider": "openai-codex", "model": "gpt-5.3-codex"}})+ )+ with patch("openviking_cli.doctor._find_config", return_value=config):+ with patch(+ "openviking.models.vlm.backends.codex_auth.resolve_codex_runtime_credentials",+ side_effect=RuntimeError("missing auth"),+ ):+ with patch(+ "openviking.models.vlm.backends.codex_auth.get_codex_auth_status",+ return_value={+ "store_path": "/tmp/ov-codex.json",+ "bootstrap_path": "/tmp/codex/auth.json",+ },+ ):+ ok, detail, fix = check_vlm()+ assert not ok+ assert "missing auth" in detail+ assert "openviking-server init" in fix++ def test_pass_with_default_provider_codex_oauth(self, tmp_path: Path):+ config = tmp_path / "ov.conf"+ config.write_text(+ json.dumps(+ {+ "vlm": {+ "model": "gpt-5.3-codex",+ "default_provider": "openai-codex",+ "providers": {"openai": {"api_key": "sk-test"}, "openai-codex": {}},+ }+ }+ )+ )+ with patch("openviking_cli.doctor._find_config", return_value=config):+ with patch(+ "openviking.models.vlm.backends.codex_auth.resolve_codex_runtime_credentials",+ return_value={"source": "openviking"},+ ):+ ok, detail, fix = check_vlm()+ assert ok+ assert "openai-codex/gpt-5.3-codex" in detail+ assert "oauth via openviking" in detail+class TestCheckOllama:def test_pass_when_config_is_missing(self):@@ -364,7 +423,9 @@ class TestCheckOllama:))with patch("openviking_cli.doctor._find_config", return_value=config):- with patch("openviking_cli.utils.ollama.check_ollama_running", return_value=True) as running:+ with patch(+ "openviking_cli.utils.ollama.check_ollama_running", return_value=True+ ) as running:ok, detail, fix = check_ollama()running.assert_called_once_with("embedding-host", 11435)assert ok@@ -385,7 +446,9 @@ class TestCheckOllama:))with patch("openviking_cli.doctor._find_config", return_value=config):- with patch("openviking_cli.utils.ollama.check_ollama_running", return_value=True) as running:+ with patch(+ "openviking_cli.utils.ollama.check_ollama_running", return_value=True+ ) as running:ok, detail, fix = check_ollama()running.assert_called_once_with("vlm-host", 11436)assert okdiff --git a/tests/cli/test_setup_wizard.py b/tests/cli/test_setup_wizard.pyindex de6a02c9d..f272ed3ad 100644--- a/tests/cli/test_setup_wizard.py+++ b/tests/cli/test_setup_wizard.py@@ -6,6 +6,10 @@ import jsonfrom unittest.mock import MagicMock, patchfrom openviking_cli.setup_wizard import (+ _DEFAULT_CODEX_MODEL,+ _DEFAULT_GLM_MODEL,+ _DEFAULT_KIMI_MODEL,+ _DEFAULT_WORKSPACE,CLOUD_PROVIDERS,EMBEDDING_PRESETS,LOCAL_GGUF_PRESETS,@@ -15,6 +19,9 @@ from openviking_cli.setup_wizard import (_build_ollama_config,_get_recommended_indices,_is_llamacpp_installed,+ _prompt_required_input,+ _prompt_required_int,+ _wizard_cloud,_write_config,run_init,)@@ -134,15 +141,285 @@ class TestConfigBuilding:embedding_api_key="sk-test",embedding_model="text-embedding-3-small",embedding_dim=1536,- vlm_api_key="sk-test",vlm_model="gpt-4o-mini",workspace="/tmp/ov_test",+ vlm_api_key="sk-test",)assert config["embedding"]["dense"]["api_key"] == "sk-test"assert config["vlm"]["api_key"] == "sk-test"assert config["vlm"]["provider"] == "openai"+ def test_cloud_config_supports_codex_vlm(self):+ provider = CLOUD_PROVIDERS[1] # Volcengine++ config = _build_cloud_config(+ provider,+ embedding_api_key="ve-test",+ embedding_model="doubao-embedding-vision-250615",+ embedding_dim=1024,+ vlm_model="gpt-5.3-codex",+ workspace="/tmp/ov_test",+ vlm_provider="openai-codex",+ vlm_api_base="https://chatgpt.com/backend-api/codex",+ )++ assert config["embedding"]["dense"]["provider"] == "volcengine"+ assert config["embedding"]["dense"]["api_key"] == "ve-test"+ assert config["vlm"]["provider"] == "openai-codex"+ assert config["vlm"]["model"] == "gpt-5.3-codex"+ assert config["vlm"]["api_base"] == "https://chatgpt.com/backend-api/codex"+ assert "api_key" not in config["vlm"]++ def test_cloud_wizard_codex_uses_default_base_and_workspace(self):+ with patch(+ "openviking_cli.setup_wizard._prompt_choice",+ side_effect=[2, 3],+ ):+ with patch(+ "openviking_cli.setup_wizard._prompt_required_input",+ side_effect=[+ "ve-test",+ "doubao-embedding-vision-250615",+ "gpt-5.3-codex",+ ],+ ):+ with patch(+ "openviking_cli.setup_wizard._prompt_required_int",+ return_value=1024,+ ):+ with patch("openviking_cli.setup_wizard._ensure_codex_auth", return_value=True):+ config = _wizard_cloud()++ assert config is not None+ assert config["storage"]["workspace"] == _DEFAULT_WORKSPACE+ assert config["vlm"]["provider"] == "openai-codex"+ assert config["vlm"]["api_base"] == "https://chatgpt.com/backend-api/codex"+ assert "api_key" not in config["vlm"]++ def test_cloud_wizard_supports_openai_vlm_option(self):+ with patch(+ "openviking_cli.setup_wizard._prompt_choice",+ side_effect=[1, 1],+ ):+ with patch(+ "openviking_cli.setup_wizard._prompt_required_input",+ side_effect=[+ "embed-test",+ "text-embedding-3-small",+ "openai-vlm-test",+ "gpt-5.4",+ ],+ ):+ with patch(+ "openviking_cli.setup_wizard._prompt_required_int",+ return_value=1536,+ ):+ config = _wizard_cloud()++ assert config is not None+ assert config["storage"]["workspace"] == _DEFAULT_WORKSPACE+ assert config["vlm"]["provider"] == "openai"+ assert config["vlm"]["api_key"] == "openai-vlm-test"+ assert config["vlm"]["api_base"] == CLOUD_PROVIDERS[0].default_api_base++ def test_cloud_wizard_supports_volcengine_vlm_option(self):+ with patch(+ "openviking_cli.setup_wizard._prompt_choice",+ side_effect=[1, 2],+ ):+ with patch(+ "openviking_cli.setup_wizard._prompt_required_input",+ side_effect=[+ "embed-test",+ "text-embedding-3-small",+ "ve-vlm-test",+ "doubao-seed-2-0-code-preview-260215",+ ],+ ):+ with patch(+ "openviking_cli.setup_wizard._prompt_required_int",+ return_value=1536,+ ):+ config = _wizard_cloud()++ assert config is not None+ assert config["storage"]["workspace"] == _DEFAULT_WORKSPACE+ assert config["vlm"]["provider"] == "volcengine"+ assert config["vlm"]["api_key"] == "ve-vlm-test"+ assert config["vlm"]["api_base"] == CLOUD_PROVIDERS[1].default_api_base+ assert config["vlm"]["model"] == "doubao-seed-2-0-code-preview-260215"++ def test_cloud_wizard_supports_kimi_vlm(self):+ with patch(+ "openviking_cli.setup_wizard._prompt_choice",+ side_effect=[2, 4],+ ):+ with patch(+ "openviking_cli.setup_wizard._prompt_required_input",+ side_effect=[+ "ve-test",+ "doubao-embedding-vision-250615",+ "kimi-test",+ "kimi-code",+ ],+ ):+ with patch(+ "openviking_cli.setup_wizard._prompt_required_int",+ return_value=1024,+ ):+ config = _wizard_cloud()++ assert config is not None+ assert config["vlm"]["provider"] == "kimi"+ assert config["vlm"]["api_key"] == "kimi-test"+ assert config["vlm"]["model"] == "kimi-code"+ assert config["vlm"]["api_base"] == "https://api.kimi.com/coding"+ assert config["storage"]["workspace"] == _DEFAULT_WORKSPACE++ def test_cloud_wizard_supports_glm_vlm(self):+ with patch(+ "openviking_cli.setup_wizard._prompt_choice",+ side_effect=[2, 5],+ ):+ with patch(+ "openviking_cli.setup_wizard._prompt_required_input",+ side_effect=[+ "ve-test",+ "doubao-embedding-vision-250615",+ "glm-test",+ "glm-4.6v",+ ],+ ):+ with patch(+ "openviking_cli.setup_wizard._prompt_required_int",+ return_value=1024,+ ):+ config = _wizard_cloud()++ assert config is not None+ assert config["vlm"]["provider"] == "glm"+ assert config["vlm"]["api_key"] == "glm-test"+ assert config["vlm"]["model"] == "glm-4.6v"+ assert config["vlm"]["api_base"] == "https://api.z.ai/api/coding/paas/v4"+ assert config["storage"]["workspace"] == _DEFAULT_WORKSPACE++ def test_prompt_required_input_uses_default_on_empty(self):+ with patch("builtins.input", return_value=""):+ value = _prompt_required_input("Model", default=_DEFAULT_KIMI_MODEL)++ assert value == _DEFAULT_KIMI_MODEL++ def test_prompt_required_int_uses_default_on_empty(self):+ with patch("builtins.input", return_value=""):+ value = _prompt_required_int("Dimension", default=1024)++ assert value == 1024++ def test_cloud_wizard_uses_requested_defaults_when_inputs_are_empty(self):+ with patch(+ "openviking_cli.setup_wizard._prompt_choice",+ side_effect=[2, 3],+ ):+ with patch(+ "openviking_cli.setup_wizard._prompt_required_input",+ side_effect=[+ "ve-test",+ CLOUD_PROVIDERS[1].default_embedding_model,+ _DEFAULT_CODEX_MODEL,+ ],+ ) as prompt_input:+ with patch(+ "openviking_cli.setup_wizard._prompt_required_int",+ return_value=CLOUD_PROVIDERS[1].default_embedding_dim,+ ) as prompt_int:+ with patch("openviking_cli.setup_wizard._ensure_codex_auth", return_value=True):+ config = _wizard_cloud()++ assert config is not None+ assert config["embedding"]["dense"]["model"] == CLOUD_PROVIDERS[1].default_embedding_model+ assert config["embedding"]["dense"]["dimension"] == CLOUD_PROVIDERS[1].default_embedding_dim+ assert config["vlm"]["model"] == _DEFAULT_CODEX_MODEL+ prompt_input.assert_any_call("Model", default=CLOUD_PROVIDERS[1].default_embedding_model)+ prompt_input.assert_any_call("Model", default=_DEFAULT_CODEX_MODEL)+ prompt_int.assert_called_once_with(+ "Dimension", default=CLOUD_PROVIDERS[1].default_embedding_dim+ )++ def test_cloud_wizard_kimi_uses_requested_default_model(self):+ with patch(+ "openviking_cli.setup_wizard._prompt_choice",+ side_effect=[2, 4],+ ):+ with patch(+ "openviking_cli.setup_wizard._prompt_required_input",+ side_effect=[+ "ve-test",+ CLOUD_PROVIDERS[1].default_embedding_model,+ "kimi-test",+ _DEFAULT_KIMI_MODEL,+ ],+ ) as prompt_input:+ with patch(+ "openviking_cli.setup_wizard._prompt_required_int",+ return_value=CLOUD_PROVIDERS[1].default_embedding_dim,+ ):+ config = _wizard_cloud()++ assert config is not None+ assert config["vlm"]["model"] == _DEFAULT_KIMI_MODEL+ prompt_input.assert_any_call("Model", default=_DEFAULT_KIMI_MODEL)++ def test_cloud_wizard_glm_uses_requested_default_model(self):+ with patch(+ "openviking_cli.setup_wizard._prompt_choice",+ side_effect=[2, 5],+ ):+ with patch(+ "openviking_cli.setup_wizard._prompt_required_input",+ side_effect=[+ "ve-test",+ CLOUD_PROVIDERS[1].default_embedding_model,+ "glm-test",+ _DEFAULT_GLM_MODEL,+ ],+ ) as prompt_input:+ with patch(+ "openviking_cli.setup_wizard._prompt_required_int",+ return_value=CLOUD_PROVIDERS[1].default_embedding_dim,+ ):+ config = _wizard_cloud()++ assert config is not None+ assert config["vlm"]["model"] == _DEFAULT_GLM_MODEL+ prompt_input.assert_any_call("Model", default=_DEFAULT_GLM_MODEL)++ def test_cloud_wizard_volcengine_uses_requested_default_model(self):+ with patch(+ "openviking_cli.setup_wizard._prompt_choice",+ side_effect=[1, 2],+ ):+ with patch(+ "openviking_cli.setup_wizard._prompt_required_input",+ side_effect=[+ "embed-test",+ CLOUD_PROVIDERS[0].default_embedding_model,+ "ve-vlm-test",+ CLOUD_PROVIDERS[1].default_vlm_model,+ ],+ ) as prompt_input:+ with patch(+ "openviking_cli.setup_wizard._prompt_required_int",+ return_value=CLOUD_PROVIDERS[0].default_embedding_dim,+ ):+ config = _wizard_cloud()++ assert config is not None+ assert config["vlm"]["provider"] == "volcengine"+ assert config["vlm"]["api_key"] == "ve-vlm-test"+ assert config["vlm"]["model"] == CLOUD_PROVIDERS[1].default_vlm_model+ prompt_input.assert_any_call("Model", default=CLOUD_PROVIDERS[1].default_vlm_model)+def test_all_presets_valid(self):"""Every preset should produce a config with required fields."""for emb in EMBEDDING_PRESETS:@@ -232,13 +509,14 @@ class TestConfigWriting:},}- with patch("openviking_cli.setup_wizard._DEFAULT_CONFIG_PATH", config_path), patch(- "openviking_cli.setup_wizard._prompt_choice", return_value=2- ), patch("openviking_cli.setup_wizard._wizard_ollama", return_value=config), patch(- "openviking_cli.setup_wizard._prompt_confirm", return_value=True- ), patch("openviking_cli.setup_wizard._write_config", return_value=True), patch(- "builtins.print"- ) as mock_print:+ with (+ patch("openviking_cli.setup_wizard._DEFAULT_CONFIG_PATH", config_path),+ patch("openviking_cli.setup_wizard._prompt_choice", return_value=2),+ patch("openviking_cli.setup_wizard._wizard_ollama", return_value=config),+ patch("openviking_cli.setup_wizard._prompt_confirm", return_value=True),+ patch("openviking_cli.setup_wizard._write_config", return_value=True),+ patch("builtins.print") as mock_print,+ ):assert run_init() == 0output = "\n".join(diff --git a/tests/models/vlm/test_timeout_config.py b/tests/models/vlm/test_timeout_config.pyindex 1f09a2551..15613792b 100644--- a/tests/models/vlm/test_timeout_config.py+++ b/tests/models/vlm/test_timeout_config.py@@ -100,3 +100,40 @@ def test_litellm_build_kwargs_includes_timeout():)kwargs = vlm._build_text_kwargs(prompt="hi")assert kwargs["timeout"] == 90.0+++def test_vlm_config_propagates_timeout_to_codex_backend():+ cfg = VLMConfig(+ provider="openai-codex",+ model="gpt-5.3-codex",+ api_key="oauth-token",+ api_base="https://example.invalid/codex",+ timeout=45.0,+ )++ vlm = cfg.get_vlm_instance()++ assert vlm.timeout == 45.0+++def test_codex_vlm_propagates_config_timeout():+ from openviking.models.vlm.backends.codex_vlm import CodexVLM+ from tests.unit.test_codex_vlm import _build_final_response, _MockResponsesStream++ vlm = CodexVLM(+ {+ "provider": "openai-codex",+ "model": "gpt-5.3-codex",+ "api_key": "oauth-token",+ "api_base": "https://example.invalid/codex",+ "timeout": 45.0,+ }+ )++ with mock.patch("openviking.models.vlm.backends.codex_vlm.openai.OpenAI") as fake:+ fake.return_value.responses.stream.return_value = _MockResponsesStream(+ _build_final_response("timeout ok")+ )+ assert vlm.get_completion("hello") == "timeout ok"++ assert fake.call_args.kwargs.get("timeout") == 45.0diff --git a/tests/server/test_api_filesystem.py b/tests/server/test_api_filesystem.pyindex 6d0c26571..88d653fd9 100644--- a/tests/server/test_api_filesystem.py+++ b/tests/server/test_api_filesystem.py@@ -116,7 +116,9 @@ async def test_stat_not_found(client: httpx.AsyncClient):assert body["status"] == "error"-async def test_rm_directory_without_recursive_returns_failed_precondition(client: httpx.AsyncClient):+async def test_rm_directory_without_recursive_returns_failed_precondition(+ client: httpx.AsyncClient,+):await client.post("/api/v1/fs/mkdir",json={"uri": "viking://resources/rm_dir_without_recursive/"},diff --git a/tests/session/memory/test_compressor_v2.py b/tests/session/memory/test_compressor_v2.pyindex d7facd72b..74db3a400 100644--- a/tests/session/memory/test_compressor_v2.py+++ b/tests/session/memory/test_compressor_v2.py@@ -282,7 +282,6 @@ class TestCompressorV2:user = UserIdentifier.the_default_user()ctx = RequestContext(user=user, role=Role.ROOT)messages = [Message.create_user("Current task")]- captured: dict[str, str] = {}class DummyOrchestrator:registry = object()diff --git a/tests/session/memory/test_memory_extractor_flow.py b/tests/session/memory/test_memory_extractor_flow.pyindex a50ffa800..fe2884cc8 100644--- a/tests/session/memory/test_memory_extractor_flow.py+++ b/tests/session/memory/test_memory_extractor_flow.py@@ -17,15 +17,6 @@ from unittest.mock import patchimport pytest-# 让 openviking logger 的日志 propagate 到 pytest-for logger_name in ["openviking", "openviking.session.memory"]:- logger = logging.getLogger(logger_name)- logger.propagate = True- logger.setLevel(logging.DEBUG)--# Module logger for this test-logger = logging.getLogger(__name__)-from openviking.message import Message, TextPartfrom openviking.server.identity import RequestContext, Rolefrom openviking.session.memory import (@@ -36,6 +27,15 @@ from openviking.session.memory import (from openviking_cli.session.user_id import UserIdentifierfrom openviking_cli.utils.config import get_openviking_config, initialize_openviking_config+# 让 openviking logger 的日志 propagate 到 pytest+for logger_name in ["openviking", "openviking.session.memory"]:+ logger = logging.getLogger(logger_name)+ logger.propagate = True+ logger.setLevel(logging.DEBUG)++# Module logger for this test+logger = logging.getLogger(__name__)+class MockVikingFS:"""Mock VikingFS for testing with unified memory storage."""@@ -307,9 +307,6 @@ def _print_inline_diff(def create_test_conversation() -> List[Message]:"""Create a test conversation focused on cards and events."""- user = UserIdentifier.the_default_user()- ctx = RequestContext(user=user, role=Role.ROOT)-messages = []# Message 1: User starts talking about a project@@ -430,9 +427,6 @@ Today we started working on the memory extraction feature for the OpenViking prodef create_update_conversation() -> List[Message]:"""Create a conversation for updating existing cards and events."""- user = UserIdentifier.the_default_user()- ctx = RequestContext(user=user, role=Role.ROOT)-messages = []# Message 1: User corrects and adds details to existing OpenViking project carddiff --git a/tests/unit/test_codex_vlm.py b/tests/unit/test_codex_vlm.pynew file mode 100644index 000000000..b96a714ee--- /dev/null+++ b/tests/unit/test_codex_vlm.py@@ -0,0 +1,504 @@+# Copyright (c) 2026 Beijing Volcano Engine Technology Co., Ltd.+# SPDX-License-Identifier: AGPL-3.0++import base64+import json+from types import SimpleNamespace+from unittest.mock import MagicMock, patch++import pytest++from openviking.models.vlm.backends import codex_auth+from openviking.models.vlm.backends.codex_auth import resolve_codex_runtime_credentials+from openviking.models.vlm.backends.codex_vlm import CodexVLM+from openviking_cli.utils.config.vlm_config import VLMConfig+++class _MockResponsesStream:+ def __init__(self, final_response):+ self._final_response = final_response++ def __enter__(self):+ return self++ def __exit__(self, exc_type, exc, tb):+ return False++ def __iter__(self):+ return iter(())++ def get_final_response(self):+ return self._final_response+++def _build_final_response(text: str):+ return SimpleNamespace(+ output=[+ SimpleNamespace(+ type="message",+ content=[SimpleNamespace(type="output_text", text=text)],+ )+ ],+ usage=SimpleNamespace(input_tokens=11, output_tokens=7, total_tokens=18),+ )+++def _build_fake_openai_client(text: str):+ client = MagicMock()+ client.responses.stream.return_value = _MockResponsesStream(_build_final_response(text))+ return client+++@patch("openviking.models.vlm.backends.codex_vlm.openai.OpenAI")+@patch("openviking.models.vlm.backends.codex_vlm.resolve_codex_runtime_credentials")+def test_codex_text_completion_uses_responses_api(mock_resolve, mock_openai_class):+ mock_resolve.return_value = {+ "api_key": "oauth-token",+ "base_url": "https://chatgpt.com/backend-api/codex",+ }+ mock_real_client = MagicMock()+ mock_real_client.responses.stream.return_value = _MockResponsesStream(+ _build_final_response("hello from codex")+ )+ mock_openai_class.return_value = mock_real_client++ vlm = CodexVLM({"provider": "openai-codex", "model": "gpt-5.3-codex"})+ result = vlm.get_completion("hello")++ assert result == "hello from codex"+ call_kwargs = mock_real_client.responses.stream.call_args.kwargs+ assert call_kwargs["model"] == "gpt-5.3-codex"+ assert call_kwargs["input"] == [{"role": "user", "content": "hello"}]+ assert "messages" not in call_kwargs+++@patch("openviking.models.vlm.backends.codex_vlm.openai.OpenAI")+@patch("openviking.models.vlm.backends.codex_vlm.resolve_codex_runtime_credentials")+def test_codex_vision_completion_converts_images(mock_resolve, mock_openai_class):+ mock_resolve.return_value = {+ "api_key": "oauth-token",+ "base_url": "https://chatgpt.com/backend-api/codex",+ }+ mock_real_client = MagicMock()+ mock_real_client.responses.stream.return_value = _MockResponsesStream(+ _build_final_response("image result")+ )+ mock_openai_class.return_value = mock_real_client++ vlm = CodexVLM({"provider": "openai-codex", "model": "gpt-5.3-codex"})+ result = vlm.get_vision_completion("describe", [b"\x89PNG\r\n\x1a\n0000"])++ assert result == "image result"+ call_kwargs = mock_real_client.responses.stream.call_args.kwargs+ content = call_kwargs["input"][0]["content"]+ assert content[0]["type"] == "input_image"+ assert content[0]["image_url"].startswith("data:image/png;base64,")+ assert content[1] == {"type": "input_text", "text": "describe"}+++@patch("openviking.models.vlm.backends.codex_vlm.openai.OpenAI")+@patch("openviking.models.vlm.backends.codex_vlm.resolve_codex_runtime_credentials")+async def test_codex_async_client_defers_runtime_credential_resolution(+ mock_resolve,+ mock_openai_class,+):+ mock_resolve.return_value = {+ "api_key": "oauth-token",+ "base_url": "https://chatgpt.com/backend-api/codex",+ }+ mock_real_client = MagicMock()+ mock_real_client.responses.stream.return_value = _MockResponsesStream(+ _build_final_response("async hello")+ )+ mock_openai_class.return_value = mock_real_client++ vlm = CodexVLM({"provider": "openai-codex", "model": "gpt-5.3-codex"})+ client = vlm.get_async_client()++ mock_resolve.assert_not_called()+ response = await client.chat.completions.create(+ messages=[{"role": "user", "content": "hello"}],+ model="gpt-5.3-codex",+ )++ assert response.choices[0].message.content == "async hello"+ mock_resolve.assert_called_once()+++@patch("openviking.models.vlm.backends.codex_auth.has_codex_auth_available", return_value=True)+def test_vlm_config_accepts_codex_without_api_key(_mock_auth_available):+ config = VLMConfig(provider="openai-codex", model="gpt-5.3-codex")++ assert config.is_available() is True+ assert config.get_vlm_instance().__class__.__name__ == "CodexVLM"+++@patch("openviking.models.vlm.backends.codex_auth.has_codex_auth_available", return_value=True)+def test_vlm_config_default_provider_resolves_codex(_mock_auth_available):+ config = VLMConfig(+ model="gpt-5.3-codex",+ default_provider="openai-codex",+ providers={"openai": {"api_key": "sk-test"}, "openai-codex": {}},+ )++ provider_config, provider_name = config.get_provider_config()++ assert provider_name == "openai-codex"+ assert provider_config == {}+++@patch("openviking.models.vlm.backends.codex_auth.has_codex_auth_available", return_value=True)+def test_vlm_config_mixed_providers_do_not_auto_pick_codex(_mock_auth_available):+ config = VLMConfig(+ model="gpt-5.3-codex",+ providers={"openai": {"api_key": "sk-test"}, "openai-codex": {}},+ )++ provider_config, provider_name = config.get_provider_config()++ assert provider_name == "openai"+ assert provider_config["api_key"] == "sk-test"+++def test_vlm_config_default_provider_without_model_fails_validation():+ with pytest.raises(ValueError, match="requires 'model' to be set"):+ VLMConfig(default_provider="openai-codex", providers={"openai-codex": {}})+++def test_vlm_config_empty_provider_block_without_model_fails_validation():+ with pytest.raises(ValueError, match="requires 'model' to be set"):+ VLMConfig(providers={"openai-codex": {}})+++def test_codex_auth_bootstraps_into_openviking_store(tmp_path, monkeypatch):+ ov_auth_path = tmp_path / "codex_auth.json"+ bootstrap_path = tmp_path / "codex_cli_auth.json"+ bootstrap_path.write_text(+ json.dumps(+ {+ "tokens": {+ "access_token": "header.payload.signature",+ "refresh_token": "refresh-token",+ },+ "last_refresh": "2026-04-13T00:00:00Z",+ }+ ),+ encoding="utf-8",+ )+ monkeypatch.setenv("OPENVIKING_CODEX_AUTH_PATH", str(ov_auth_path))+ monkeypatch.setenv("OPENVIKING_CODEX_BOOTSTRAP_PATH", str(bootstrap_path))++ creds = resolve_codex_runtime_credentials(refresh_if_expiring=False)++ assert creds["path"] == str(ov_auth_path)+ assert ov_auth_path.exists()+ persisted = json.loads(ov_auth_path.read_text(encoding="utf-8"))+ assert persisted["provider"] == "openai-codex"+ assert persisted["auth_owner"] == "external"+ assert persisted["tokens"]["refresh_token"] == "refresh-token"+ assert persisted["imported_from"] == str(bootstrap_path)+++def test_codex_auth_native_login_defaults_to_openviking_owner(tmp_path, monkeypatch):+ ov_auth_path = tmp_path / "codex_auth.json"+ monkeypatch.setenv("OPENVIKING_CODEX_AUTH_PATH", str(ov_auth_path))++ codex_auth.save_codex_tokens("header.payload.signature", "refresh-token")++ persisted = json.loads(ov_auth_path.read_text(encoding="utf-8"))+ assert persisted["auth_owner"] == "openviking"+ assert "imported_from" not in persisted+++def test_codex_auth_atomic_write_replaces_file_in_place(tmp_path):+ auth_path = tmp_path / "codex_auth.json"+ auth_path.write_text('{"old": true}\n', encoding="utf-8")++ codex_auth._atomic_write_json_file(auth_path, {"new": True})++ assert json.loads(auth_path.read_text(encoding="utf-8")) == {"new": True}+ assert not list(tmp_path.glob("codex_auth.json.*.tmp"))+++def test_codex_auth_store_uses_windows_lock_when_fcntl_is_unavailable(tmp_path, monkeypatch):+ ov_auth_path = tmp_path / "codex_auth.json"+ lock_calls: list[tuple[int, int]] = []++ class _FakeMsvcrt:+ LK_LOCK = 1+ LK_UNLCK = 2++ @staticmethod+ def locking(fd: int, mode: int, size: int) -> None:+ lock_calls.append((mode, size))++ monkeypatch.setenv("OPENVIKING_CODEX_AUTH_PATH", str(ov_auth_path))+ monkeypatch.setattr(codex_auth, "fcntl", None)+ monkeypatch.setattr(codex_auth, "msvcrt", _FakeMsvcrt)++ codex_auth.save_codex_tokens("header.payload.signature", "refresh-token")++ assert ov_auth_path.exists()+ assert lock_calls == [(_FakeMsvcrt.LK_LOCK, 1), (_FakeMsvcrt.LK_UNLCK, 1)]+++def _make_jwt_token(payload: dict) -> str:+ encoded = (+ base64.urlsafe_b64encode(json.dumps(payload).encode("utf-8")).decode("utf-8").rstrip("=")+ )+ return f"header.{encoded}.signature"+++def test_codex_auth_takeover_refreshes_when_external_store_missing(tmp_path, monkeypatch):+ ov_auth_path = tmp_path / "codex_auth.json"+ missing_external = tmp_path / "codex_cli_auth.json"+ expiring_access_token = _make_jwt_token({"exp": 0, "aud": "app_testclient"})+ ov_auth_path.write_text(+ json.dumps(+ {+ "provider": "openai-codex",+ "auth_mode": "chatgpt",+ "auth_owner": "external",+ "imported_from": str(missing_external),+ "client_id": "app_testclient",+ "tokens": {+ "access_token": expiring_access_token,+ "refresh_token": "refresh-token",+ },+ }+ )+ + "\n",+ encoding="utf-8",+ )+ monkeypatch.setenv("OPENVIKING_CODEX_AUTH_PATH", str(ov_auth_path))++ class _Response:+ status_code = 200++ @staticmethod+ def json():+ return {+ "access_token": _make_jwt_token({"exp": 9999999999}),+ "refresh_token": "new-refresh",+ }++ monkeypatch.setattr(codex_auth.httpx, "post", lambda *_args, **_kwargs: _Response())++ creds = resolve_codex_runtime_credentials(force_refresh=True)++ assert creds["source"] == "openviking"+ assert creds["auth_owner"] == "openviking"+ persisted = json.loads(ov_auth_path.read_text(encoding="utf-8"))+ assert persisted["auth_owner"] == "openviking"+ assert "imported_from" not in persisted+ assert persisted["tokens"]["refresh_token"] == "new-refresh"+++def test_codex_auth_refresh_uses_persisted_client_id(tmp_path, monkeypatch):+ ov_auth_path = tmp_path / "codex_auth.json"+ access_token = _make_jwt_token({"exp": 0, "aud": "app_from_aud"})+ ov_auth_path.write_text(+ json.dumps(+ {+ "provider": "openai-codex",+ "auth_mode": "chatgpt",+ "auth_owner": "openviking",+ "client_id": "app_persisted_client",+ "tokens": {+ "access_token": access_token,+ "refresh_token": "refresh-token",+ },+ }+ )+ + "\n",+ encoding="utf-8",+ )+ monkeypatch.setenv("OPENVIKING_CODEX_AUTH_PATH", str(ov_auth_path))+ recorded: dict[str, str] = {}++ class _Response:+ status_code = 200++ @staticmethod+ def json():+ return {+ "access_token": _make_jwt_token({"exp": 9999999999}),+ "refresh_token": "new-refresh",+ }++ def _fake_post(*_args, **kwargs):+ recorded["client_id"] = kwargs["data"]["client_id"]+ return _Response()++ monkeypatch.setattr(codex_auth.httpx, "post", _fake_post)++ creds = resolve_codex_runtime_credentials(force_refresh=True)++ assert creds["source"] == "openviking"+ assert recorded["client_id"] == "app_persisted_client"+++def test_codex_auth_refresh_requires_persisted_client_id(tmp_path, monkeypatch):+ ov_auth_path = tmp_path / "codex_auth.json"+ access_token = _make_jwt_token({"exp": 0, "aud": "app_from_aud"})+ ov_auth_path.write_text(+ json.dumps(+ {+ "provider": "openai-codex",+ "auth_mode": "chatgpt",+ "auth_owner": "openviking",+ "tokens": {+ "access_token": access_token,+ "refresh_token": "refresh-token",+ },+ }+ )+ + "\n",+ encoding="utf-8",+ )+ monkeypatch.setenv("OPENVIKING_CODEX_AUTH_PATH", str(ov_auth_path))++ with pytest.raises(codex_auth.CodexAuthError, match="client_id"):+ resolve_codex_runtime_credentials(force_refresh=True)+++@patch("openviking.models.vlm.backends.codex_vlm.openai.OpenAI")+@patch("openviking.models.vlm.backends.codex_vlm.resolve_codex_runtime_credentials")+def test_codex_streaming_is_rejected(mock_resolve, mock_openai_class):+ mock_resolve.return_value = {+ "api_key": "oauth-token",+ "base_url": "https://chatgpt.com/backend-api/codex",+ }+ mock_real_client = MagicMock()+ mock_openai_class.return_value = mock_real_client++ vlm = CodexVLM(+ {+ "provider": "openai-codex",+ "model": "gpt-5.3-codex",+ "stream": True,+ }+ )++ with pytest.raises(NotImplementedError, match="Streaming is not supported"):+ vlm.get_completion("hello")++ mock_real_client.responses.stream.assert_not_called()+++@patch("openviking.models.vlm.backends.codex_vlm.openai.OpenAI")+@patch("openviking.models.vlm.backends.codex_vlm.resolve_codex_runtime_credentials")+def test_codex_sync_client_re_resolves_credentials_per_request(mock_resolve, mock_openai_class):+ mock_resolve.side_effect = [+ {+ "api_key": "oauth-token-a",+ "base_url": "https://chatgpt.com/backend-api/codex",+ },+ {+ "api_key": "oauth-token-b",+ "base_url": "https://chatgpt.com/backend-api/codex",+ },+ ]+ mock_openai_class.side_effect = [+ _build_fake_openai_client("first"),+ _build_fake_openai_client("second"),+ ]++ vlm = CodexVLM({"provider": "openai-codex", "model": "gpt-5.3-codex"})+ client = vlm.get_client()++ first = client.chat.completions.create(+ messages=[{"role": "user", "content": "hello"}],+ model="gpt-5.3-codex",+ )+ second = client.chat.completions.create(+ messages=[{"role": "user", "content": "hello again"}],+ model="gpt-5.3-codex",+ )++ assert first.choices[0].message.content == "first"+ assert second.choices[0].message.content == "second"+ assert mock_openai_class.call_args_list[0].kwargs["api_key"] == "oauth-token-a"+ assert mock_openai_class.call_args_list[1].kwargs["api_key"] == "oauth-token-b"+++@patch("openviking.models.vlm.backends.codex_vlm.openai.OpenAI")+@patch("openviking.models.vlm.backends.codex_vlm.resolve_codex_runtime_credentials")+def test_codex_translates_tool_history_into_responses_input(mock_resolve, mock_openai_class):+ mock_resolve.return_value = {+ "api_key": "oauth-token",+ "base_url": "https://chatgpt.com/backend-api/codex",+ }+ mock_real_client = MagicMock()+ mock_real_client.responses.stream.return_value = _MockResponsesStream(+ _build_final_response("final answer")+ )+ mock_openai_class.return_value = mock_real_client++ vlm = CodexVLM({"provider": "openai-codex", "model": "gpt-5.3-codex"})+ response = vlm.get_completion(+ messages=[+ {"role": "user", "content": "What is the weather?"},+ {+ "role": "assistant",+ "content": None,+ "tool_calls": [+ {+ "id": "call_1",+ "type": "function",+ "function": {+ "name": "get_weather",+ "arguments": '{"city":"SF"}',+ },+ }+ ],+ },+ {+ "role": "tool",+ "tool_call_id": "call_1",+ "content": '{"temperature":72}',+ },+ ],+ tools=[+ {+ "type": "function",+ "function": {+ "name": "get_weather",+ "description": "Get weather",+ "parameters": {+ "type": "object",+ "properties": {"city": {"type": "string"}},+ },+ },+ }+ ],+ )++ assert response.content == "final answer"+ input_items = mock_real_client.responses.stream.call_args.kwargs["input"]+ assert input_items == [+ {"role": "user", "content": "What is the weather?"},+ {+ "type": "function_call",+ "call_id": "call_1",+ "name": "get_weather",+ "arguments": '{"city":"SF"}',+ },+ {+ "type": "function_call_output",+ "call_id": "call_1",+ "output": '{"temperature":72}',+ },+ ]+++def test_codex_auth_invalid_exp_claim_is_treated_as_expiring():+ assert codex_auth._codex_access_token_is_expiring("not-a-jwt", skew_seconds=60) is True+ assert (+ codex_auth._codex_access_token_is_expiring(+ _make_jwt_token({"exp": "not-a-number"}),+ skew_seconds=60,+ )+ is True+ )diff --git a/tests/unit/test_kimi_glm_vlm.py b/tests/unit/test_kimi_glm_vlm.pynew file mode 100644index 000000000..f09928642--- /dev/null+++ b/tests/unit/test_kimi_glm_vlm.py@@ -0,0 +1,117 @@+# Copyright (c) 2026 Beijing Volcano Engine Technology Co., Ltd.+# SPDX-License-Identifier: AGPL-3.0++from __future__ import annotations++from unittest.mock import MagicMock, patch++from openviking.models.vlm import VLMFactory+from openviking.models.vlm.backends.glm_vlm import DEFAULT_GLM_API_BASE, GLMVLM+from openviking.models.vlm.backends.kimi_vlm import (+ DEFAULT_KIMI_MAX_TOKENS,+ DEFAULT_KIMI_USER_AGENT,+ KimiVLM,+)+from openviking_cli.utils.config.vlm_config import VLMConfig+++def _build_openai_response(text: str = "ok", finish_reason: str = "stop") -> MagicMock:+ response = MagicMock()+ response.choices = [MagicMock(message=MagicMock(content=text), finish_reason=finish_reason)]+ response.usage = MagicMock(prompt_tokens=12, completion_tokens=7, total_tokens=19)+ return response+++@patch("openviking.models.vlm.backends.openai_vlm.openai.OpenAI")+def test_kimi_vision_completion_uses_openai_messages_and_headers(mock_openai_class):+ mock_client = MagicMock()+ mock_client.chat.completions.create.return_value = _build_openai_response("vision ok")+ mock_openai_class.return_value = mock_client++ vlm = KimiVLM(+ {+ "provider": "kimi",+ "model": "kimi-code",+ "api_key": "kimi-test-key",+ }+ )++ result = vlm.get_vision_completion(prompt="describe", images=[b"\x89PNG\r\n\x1a\n0000"])++ assert result == "vision ok"+ client_kwargs = mock_openai_class.call_args.kwargs+ assert client_kwargs["base_url"] == "https://api.kimi.com/coding/v1"+ assert client_kwargs["api_key"] == "kimi-test-key"+ assert client_kwargs["default_headers"]["User-Agent"] == DEFAULT_KIMI_USER_AGENT+ call_kwargs = mock_client.chat.completions.create.call_args.kwargs+ assert call_kwargs["model"] == "kimi-for-coding"+ content = call_kwargs["messages"][0]["content"]+ assert content[0]["type"] == "image_url"+ assert content[0]["image_url"]["url"].startswith("data:image/png;base64,")+ assert content[1] == {"type": "text", "text": "describe"}+++def test_kimi_backend_sets_openai_compatible_defaults():+ vlm = KimiVLM({"provider": "kimi", "model": "kimi-code", "api_key": "kimi-test-key"})++ assert vlm.provider == "kimi"+ assert vlm.api_base == "https://api.kimi.com/coding/v1"+ assert vlm.model == "kimi-for-coding"+ assert vlm.max_tokens == DEFAULT_KIMI_MAX_TOKENS+ assert vlm.extra_headers == {"User-Agent": DEFAULT_KIMI_USER_AGENT}+++def test_glm_backend_sets_coding_plan_defaults():+ vlm = GLMVLM({"provider": "glm", "api_key": "glm-key"})++ assert vlm.provider == "glm"+ assert vlm.api_base == DEFAULT_GLM_API_BASE+ assert vlm.model == "glm-4.6v"+++def test_vlm_factory_routes_first_class_kimi_and_glm_providers():+ kimi_vlm = VLMFactory.create({"provider": "kimi", "api_key": "kimi-key", "model": "kimi-code"})+ glm_vlm = VLMFactory.create({"provider": "glm", "api_key": "glm-key", "model": "glm-4.6v"})++ assert kimi_vlm.__class__.__name__ == "KimiVLM"+ assert glm_vlm.__class__.__name__ == "GLMVLM"+++def test_vlm_factory_exposes_canonical_provider_names():+ assert VLMFactory.get_available_providers() == [+ "volcengine",+ "openai",+ "azure",+ "kimi",+ "glm",+ "litellm",+ "openai-codex",+ ]+++def test_vlm_config_uses_canonical_provider_names():+ config = VLMConfig(+ model="glm-4.6v",+ default_provider="glm",+ providers={"kimi": {"api_key": "kimi-key"}, "glm": {"api_key": "glm-key"}},+ )++ provider_config, provider_name = config.get_provider_config()++ assert "kimi" in config.providers+ assert "glm" in config.providers+ assert provider_name == "glm"+ assert provider_config == {"api_key": "glm-key"}+++@patch("openviking.models.vlm.backends.openai_vlm.openai.OpenAI")+def test_glm_backend_reuses_openai_client_with_coding_endpoint(mock_openai_class):+ mock_client = MagicMock()+ mock_openai_class.return_value = mock_client++ vlm = GLMVLM({"provider": "glm", "api_key": "glm-key"})+ _ = vlm.get_client()++ call_kwargs = mock_openai_class.call_args.kwargs+ assert call_kwargs["base_url"] == DEFAULT_GLM_API_BASE+ assert call_kwargs["api_key"] == "glm-key"diff --git a/uv.lock b/uv.lockindex e79cc887c..77594d811 100644--- a/uv.lock+++ b/uv.lock@@ -2396,6 +2396,19 @@ wheels = [{ url = "https://files.pythonhosted.org/packages/28/89/eb28bfcf97d6b045c400e72eb047c381594467048c237dbb6c227764084c/litellm-1.82.0-py3-none-any.whl", hash = "sha256:5496b5d4532cccdc7a095c21cbac4042f7662021c57bc1d17be4e39838929e80", size = 14911978, upload-time = "2026-03-01T02:35:26.844Z" },]+[[package]]+name = "llama-cpp-python"+version = "0.3.20"+source = { registry = "https://pypi.org/simple" }+dependencies = [+ { name = "diskcache" },+ { name = "jinja2" },+ { name = "numpy", version = "2.2.6", source = { registry = "https://pypi.org/simple" }, marker = "python_full_version < '3.11'" },+ { name = "numpy", version = "2.4.3", source = { registry = "https://pypi.org/simple" }, marker = "python_full_version >= '3.11'" },+ { name = "typing-extensions" },+]+sdist = { url = "https://files.pythonhosted.org/packages/45/95/c69c47c9c8dda97f712f5864688d13a22b0159aa9adae91a69067a728532/llama_cpp_python-0.3.20.tar.gz", hash = "sha256:70f01b7d915d31c617dc66610a332cb2d51cde84c8b152d09a352206323616f5", size = 59323017, upload-time = "2026-04-03T06:56:32.455Z" }+[[package]]name = "loguru"version = "0.7.3"@@ -3657,6 +3670,9 @@ gemini-async = [{ name = "anyio" },{ name = "google-genai" },]+local-embed = [+ { name = "llama-cpp-python" },+]ocr = [{ name = "pytesseract" },]@@ -3715,6 +3731,7 @@ requires-dist = [{ name = "lark-oapi", specifier = ">=1.5.3" },{ name = "lark-oapi", marker = "extra == 'bot-feishu'", specifier = ">=1.0.0" },{ name = "litellm", specifier = ">=1.0.0,<1.83.1" },+ { name = "llama-cpp-python", marker = "extra == 'local-embed'", specifier = ">=0.3.0" },{ name = "loguru", specifier = ">=0.7.3" },{ name = "markdownify", specifier = ">=0.11.0" },{ name = "mcp", marker = "extra == 'bot'", specifier = ">=1.0.0" },@@ -3795,7 +3812,7 @@ requires-dist = [{ name = "xlrd", specifier = ">=2.0.1" },{ name = "xxhash", specifier = ">=3.0.0" },]-provides-extras = ["test", "dev", "doc", "eval", "gemini", "gemini-async", "ocr", "build", "bot", "bot-langfuse", "bot-telegram", "bot-feishu", "bot-dingtalk", "bot-slack", "bot-qq", "bot-sandbox", "bot-fuse", "bot-opencode", "bot-full", "benchmark"]+provides-extras = ["test", "dev", "doc", "eval", "gemini", "gemini-async", "ocr", "build", "bot", "bot-langfuse", "bot-telegram", "bot-feishu", "bot-dingtalk", "bot-slack", "bot-qq", "bot-sandbox", "bot-fuse", "bot-opencode", "bot-full", "benchmark", "local-embed"][package.metadata.requires-dev]dev = [{ name = "pytest", specifier = ">=9.0.2" }]@@ -6119,6 +6136,14 @@ version = "0.23.1"source = { registry = "https://pypi.org/simple" }sdist = { url = "https://files.pythonhosted.org/packages/22/85/a61c782afbb706a47d990eaee6977e7c2bd013771c5bf5c81c617684f286/tree_sitter_c_sharp-0.23.1.tar.gz", hash = "sha256:322e2cfd3a547a840375276b2aea3335fa6458aeac082f6c60fec3f745c967eb", size = 1317728, upload-time = "2024-11-11T05:25:32.535Z" }wheels = [+ { url = "https://files.pythonhosted.org/packages/4c/dc/d4a0ad9e466263728f80f9dac399609473af01c1aba2ea3ea8879ce56276/tree_sitter_c_sharp-0.23.1-cp310-abi3-macosx_10_9_x86_64.whl", hash = "sha256:e87be7572991552606a3155d2f6c2045ded8bce94bfd9f74bf521d949c219a1c", size = 333661, upload-time = "2026-04-14T15:11:14.227Z" },+ { url = "https://files.pythonhosted.org/packages/61/7a/5c862770460a2e27079e725585ad2718100373c09448c14e36934ef44414/tree_sitter_c_sharp-0.23.1-cp310-abi3-macosx_11_0_arm64.whl", hash = "sha256:86c2fdf178c66474a1be2965602818d30780e4e3ed890e3c206931f65d9a154c", size = 376295, upload-time = "2026-04-14T15:11:15.346Z" },+ { url = "https://files.pythonhosted.org/packages/67/18/0571a3a34c0feda60a9c37cf6dd5edfdbc24f8fcb1e48b6b6eb0f324ad2a/tree_sitter_c_sharp-0.23.1-cp310-abi3-manylinux1_x86_64.manylinux_2_28_x86_64.manylinux_2_5_x86_64.whl", hash = "sha256:035d259e64c41d02cc45afc3b8b46388b232e7d16d84734d851cca7334761da5", size = 358331, upload-time = "2026-04-14T15:11:16.418Z" },+ { url = "https://files.pythonhosted.org/packages/44/65/0f7e1f50f6365338eb700f01710da0adc49a49fa9a8443e5a90ea4f29491/tree_sitter_c_sharp-0.23.1-cp310-abi3-manylinux2014_aarch64.manylinux_2_17_aarch64.manylinux_2_28_aarch64.whl", hash = "sha256:fa472cb9de7e14fee9408e144f29f68384cd8e9c677dff0002da19f361a59bdf", size = 359444, upload-time = "2026-04-14T15:11:17.509Z" },+ { url = "https://files.pythonhosted.org/packages/98/60/129bd56d5ef22b4ae254940a09b6d3ed873093218868a3f9635d571d514e/tree_sitter_c_sharp-0.23.1-cp310-abi3-musllinux_1_2_aarch64.whl", hash = "sha256:1a0ea86eccff74e85ab4a2cf77c813fad7c84162962ce242dff0c51601028832", size = 358143, upload-time = "2026-04-14T15:11:18.755Z" },+ { url = "https://files.pythonhosted.org/packages/7c/cd/e12cdca47e0c56151cb4b156d48091b7bc1d968e072c1656cf6b73fe7218/tree_sitter_c_sharp-0.23.1-cp310-abi3-musllinux_1_2_x86_64.whl", hash = "sha256:8ab26dc998bbd4b4287b129f67c10ca715deb402ed77d0645674490ea509097e", size = 357524, upload-time = "2026-04-14T15:11:19.717Z" },+ { url = "https://files.pythonhosted.org/packages/6a/2c/f742d60f818cba83760f4975c7158d1c96c36b5807e95a843db7fb8c64b7/tree_sitter_c_sharp-0.23.1-cp310-abi3-win_amd64.whl", hash = "sha256:d4486653feaff3314ef45534dcb6f9ea8ab3aa160896287c6473788f88eb38be", size = 338755, upload-time = "2026-04-14T15:11:20.883Z" },+ { url = "https://files.pythonhosted.org/packages/5b/e4/8a8642b9bba86248ac2facc81ffb187c06c6768efa56c79d61fab70d736b/tree_sitter_c_sharp-0.23.1-cp310-abi3-win_arm64.whl", hash = "sha256:e7a14b76ec23cc8386cf662d5ea602d81331376c93ca6299a97b174047790345", size = 337261, upload-time = "2026-04-14T15:11:22.111Z" },{ url = "https://files.pythonhosted.org/packages/58/04/f6c2df4c53a588ccd88d50851155945cff8cd887bd70c175e00aaade7edf/tree_sitter_c_sharp-0.23.1-cp39-abi3-macosx_10_9_x86_64.whl", hash = "sha256:2b612a6e5bd17bb7fa2aab4bb6fc1fba45c94f09cb034ab332e45603b86e32fd", size = 372235, upload-time = "2024-11-11T05:25:19.424Z" },{ url = "https://files.pythonhosted.org/packages/99/10/1aa9486f1e28fc22810fa92cbdc54e1051e7f5536a5e5b5e9695f609b31e/tree_sitter_c_sharp-0.23.1-cp39-abi3-macosx_11_0_arm64.whl", hash = "sha256:1a8b98f62bc53efcd4d971151950c9b9cd5cbe3bacdb0cd69fdccac63350d83e", size = 419046, upload-time = "2024-11-11T05:25:20.679Z" },{ url = "https://files.pythonhosted.org/packages/0f/21/13df29f8fcb9ba9f209b7b413a4764b673dfd58989a0dd67e9c7e19e9c2e/tree_sitter_c_sharp-0.23.1-cp39-abi3-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:986e93d845a438ec3c4416401aa98e6a6f6631d644bbbc2e43fcb915c51d255d", size = 415999, upload-time = "2024-11-11T05:25:22.359Z" },