
⭐AI-driven public opinion & trend monitor with multi-platform aggregation, RSS, and smart alerts.🎯 告别信息过载,你的 AI 舆情监控助手与热点筛选工具!聚合多平台热点 + RSS 订阅,支持关键词精准筛选。AI 智能筛选新闻 + AI 翻译 + AI 分析简报直推手机,也支持接入 MCP 架构,赋能 AI 自然语言对话分析、情感洞察与趋势预测等。支持 Docker ,数据本地/云端自持。集成微信/飞书/钉钉/Telegram/邮件/ntfy/bark/slack 等渠道智能推送。
Python aibarkdata-analysisdockerhot-newsllmmailmcpmcp-servernewsntfypythonrsstrending-topicswechatwework
feat: v2.0.0 重大重构
sansan3fbbfeff10d4
diff --git a/.dockerignore b/.dockerignorenew file mode 100644index 0000000000..905b0b0b89--- /dev/null+++ b/.dockerignore@@ -0,0 +1,35 @@+.git/+.gitignore+*.md+README.md++output/++__pycache__/+*.pyc+*.pyo+*.pyd+.Python+*.so+.pytest_cache/++.vscode/+.idea/+*.swp+*.swo+*~++.DS_Store+Thumbs.db++docker/.env++_image/++.github/++*.log+.env.local+.env.*.local+version+index.html\ No newline at end of filediff --git a/.github/ISSUE_TEMPLATE/01-bug-report.yml b/.github/ISSUE_TEMPLATE/01-bug-report.ymlnew file mode 100644index 0000000000..46f3d4e715--- /dev/null+++ b/.github/ISSUE_TEMPLATE/01-bug-report.yml@@ -0,0 +1,123 @@+# yaml-language-server: $schema=https://json.schemastore.org/github-issue-forms.json++name: 🐛 Bug 报告+description: 报告程序错误或异常行为+title: "[Bug] "+labels: ["bug"]+assignees:+ - sansan0+body:+ - type: markdown+ attributes:+ value: |+ 感谢你的反馈!详细的 Bug 报告有助于快速定位和修复问题。++ - type: dropdown+ id: bug-category+ attributes:+ label: 🏷️ 问题类型+ options:+ - 数据抓取失败+ - 频率词匹配异常+ - 通知发送失败+ - 配置解析错误+ - Docker 部署问题+ - 报告生成错误+ - 性能问题+ - 其他+ validations:+ required: true++ - type: textarea+ id: bug-description+ attributes:+ label: 📝 问题描述+ description: 详细描述遇到的问题+ placeholder: |+ 请清楚地描述:+ - 发生了什么问题+ - 问题的具体表现+ - 影响范围+ validations:+ required: true++ - type: textarea+ id: reproduction-steps+ attributes:+ label: 🔄 复现步骤+ description: 如何重现这个问题?+ placeholder: |+ 1. 运行命令:python main.py+ 2. 配置设置:...+ 3. 观察到的现象:...+ validations:+ required: true++ - type: textarea+ id: expected-behavior+ attributes:+ label: ✅ 期望行为+ description: 正常情况下应该发生什么?+ placeholder: 描述期望的正常行为...+ validations:+ required: true++ - type: dropdown+ id: environment+ attributes:+ label: 🖥️ 运行环境+ options:+ - 本地 Python 环境+ - Docker 容器+ - GitHub Actions+ - 其他+ validations:+ required: true++ - type: input+ id: python-version+ attributes:+ label: 🐍 Python 版本+ description: 使用的 Python 版本+ placeholder: 如:3.10.0+ validations:+ required: true++ - type: textarea+ id: error-logs+ attributes:+ label: 📋 错误日志+ description: 相关的错误信息或日志+ placeholder: |+ 请粘贴完整的错误堆栈信息或相关日志:++ ```+ 错误信息...+ ```+ validations:+ required: true++ - type: textarea+ id: config-info+ attributes:+ label: ⚙️ 配置信息+ description: 相关的配置设置(请隐藏敏感信息)+ placeholder: |+ 相关的配置片段(请移除敏感信息如 webhook URL):++ ```yaml+ crawler:+ request_interval: 1000+ enable_crawler: true+ ```++ - type: textarea+ id: additional-context+ attributes:+ label: 📎 其他信息+ description: 其他可能有用的信息+ placeholder: |+ - 网络环境+ - 使用的平台配置+ - 频率词配置+ - 其他相关信息\ No newline at end of filediff --git a/.github/ISSUE_TEMPLATE/02-feature-request.yml b/.github/ISSUE_TEMPLATE/02-feature-request.ymlnew file mode 100644index 0000000000..db4c375c95--- /dev/null+++ b/.github/ISSUE_TEMPLATE/02-feature-request.yml@@ -0,0 +1,98 @@+# yaml-language-server: $schema=https://json.schemastore.org/github-issue-forms.json++name: 💡 功能建议+description: 提出新功能想法或改进建议+title: "[功能] "+labels: ["enhancement"]+assignees:+ - sansan0+body:+ - type: markdown+ attributes:+ value: |+ 感谢你的创意!好的想法让这个项目变得更加实用。++ - type: dropdown+ id: feature-category+ attributes:+ label: 🏷️ 功能类别+ options:+ - 数据抓取增强+ - 分析算法改进+ - 通知方式扩展+ - 配置管理优化+ - 部署便利性+ - 数据可视化+ - 监控与告警+ - 其他+ validations:+ required: true++ - type: textarea+ id: feature-description+ attributes:+ label: 💭 功能描述+ description: 详细描述你希望添加的功能+ placeholder: |+ 请详细描述:+ - 功能的具体内容+ - 如何使用这个功能+ - 期望的效果+ validations:+ required: true++ - type: textarea+ id: use-case+ attributes:+ label: 🎯 使用场景+ description: 这个功能会在什么情况下使用?+ placeholder: |+ 例如:+ - 当用户需要...的时候+ - 在...场景下会很有帮助+ - 可以解决...问题+ validations:+ required: true++ - type: textarea+ id: current-workaround+ attributes:+ label: 🔄 现有解决方案+ description: 目前是如何处理这个需求的?+ placeholder: |+ - 目前的替代方案+ - 现有方案的不足+ - 为什么需要新功能++ - type: dropdown+ id: feature-priority+ attributes:+ label: ⭐ 优先级+ description: 你认为这个功能的重要程度+ options:+ - 高 - 非常重要,强烈建议+ - 中 - 会很有用,建议考虑+ - 低 - 锦上添花,有时间可做+ validations:+ required: true++ - type: textarea+ id: implementation-ideas+ attributes:+ label: 🛠️ 实现想法(可选)+ description: 如果你有实现思路,欢迎分享+ placeholder: |+ - 技术实现方案+ - 配置设计建议+ - 用户界面设计+ - 参考项目或工具++ - type: textarea+ id: additional-context+ attributes:+ label: 📎 其他信息+ description: 其他想要补充的内容+ placeholder: |+ - 相关截图或示例+ - 类似功能的参考+ - 其他相关想法\ No newline at end of filediff --git a/.github/ISSUE_TEMPLATE/03-config-help.yml b/.github/ISSUE_TEMPLATE/03-config-help.ymlnew file mode 100644index 0000000000..3d54a1a934--- /dev/null+++ b/.github/ISSUE_TEMPLATE/03-config-help.yml@@ -0,0 +1,108 @@+# yaml-language-server: $schema=https://json.schemastore.org/github-issue-forms.json++name: ⚙️ 配置帮助+description: 配置相关的问题或优化建议+title: "[配置] "+labels: ["配置", "帮助"]+assignees:+ - sansan0+body:+ - type: markdown+ attributes:+ value: |+ 遇到配置问题?我们来帮你解决!++ 📖 **建议先查看 README 文档和配置文件注释**++ - type: dropdown+ id: config-type+ attributes:+ label: 🏷️ 配置类型+ options:+ - 基础配置问题+ - Webhook 配置+ - Docker 部署配置+ - 频率词配置+ - 平台配置+ - 定时任务配置+ - 其他+ validations:+ required: true++ - type: dropdown+ id: problem-type+ attributes:+ label: 🔍 问题类型+ options:+ - 配置不生效+ - 不知道如何配置+ - 配置优化建议+ - 配置文档改进+ - 配置验证问题+ validations:+ required: true++ - type: textarea+ id: config-content+ attributes:+ label: 📄 相关配置+ description: 请提供相关的配置内容(请隐藏敏感信息)+ placeholder: |+ 请贴出相关的配置片段(记得隐藏敏感信息):++ ```yaml+ notification:+ enable_notification: true+ webhooks:+ feishu_url: "***"+ ```+ validations:+ required: true++ - type: textarea+ id: problem-description+ attributes:+ label: 📝 问题描述+ description: 详细描述遇到的配置问题+ placeholder: |+ 请详细描述:+ - 遇到的具体问题+ - 期望的效果+ - 已经尝试的方法+ validations:+ required: true++ - type: textarea+ id: error-messages+ attributes:+ label: ❌ 错误信息(如果有)+ description: 相关的错误信息或日志+ placeholder: |+ 如果有错误信息,请贴出来:++ ```+ 错误信息...+ ```++ - type: dropdown+ id: environment+ attributes:+ label: 🖥️ 运行环境+ options:+ - 本地 Python 环境+ - Docker 容器+ - GitHub Actions+ - 其他+ validations:+ required: true++ - type: textarea+ id: additional-info+ attributes:+ label: 📎 其他信息+ description: 其他可能有用的信息+ placeholder: |+ - 操作系统版本+ - 网络环境+ - 使用场景+ - 其他相关信息\ No newline at end of filediff --git a/.github/ISSUE_TEMPLATE/config.yml b/.github/ISSUE_TEMPLATE/config.ymlnew file mode 100644index 0000000000..0443cb2b73--- /dev/null+++ b/.github/ISSUE_TEMPLATE/config.yml@@ -0,0 +1,3 @@+# yaml-language-server: $schema=https://json.schemastore.org/github-issue-config.json++blank_issues_enabled: false\ No newline at end of filediff --git a/.github/workflows/crawler.yml b/.github/workflows/crawler.ymlindex 147359f2de..c4f6d4f8d8 100644--- a/.github/workflows/crawler.yml+++ b/.github/workflows/crawler.yml@@ -2,7 +2,7 @@ name: Hot News Crawleron:schedule:- - cron: '*/50 * * * *' # 每50分钟运行一次+ - cron: "*/30 * * * *" # 每 30 分钟运行一次workflow_dispatch:# 添加权限设置@@ -12,41 +12,52 @@ permissions:jobs:crawl:runs-on: ubuntu-latest-+steps:- - name: Checkout repository- uses: actions/checkout@v3-- - name: Set up Python- uses: actions/setup-python@v4- with:- python-version: '3.9'-- - name: Install dependencies- run: |- python -m pip install --upgrade pip- pip install requests pytz-- - name: Create frequency_words.txt if not exists- run: |- if [ ! -f frequency_words.txt ]; then- echo "Creating empty frequency_words.txt file"- touch frequency_words.txt- fi-- - name: Run crawler- env:- FEISHU_WEBHOOK_URL: ${{ secrets.FEISHU_WEBHOOK_URL }}- TELEGRAM_BOT_TOKEN: ${{ secrets.TELEGRAM_BOT_TOKEN }}- TELEGRAM_CHAT_ID: ${{ secrets.TELEGRAM_CHAT_ID }}- DINGTALK_WEBHOOK_URL: ${{ secrets.DINGTALK_WEBHOOK_URL }}- WEWORK_WEBHOOK_URL: ${{ secrets.WEWORK_WEBHOOK_URL }}- GITHUB_ACTIONS: true- run: python main.py-- - name: Commit and push if changes- run: |- git config --global user.name 'GitHub Actions'- git config --global user.email '[email protected]'- git add -A- git diff --quiet && git diff --staged --quiet || (git commit -m "Auto update by GitHub Actions at $(TZ=Asia/Shanghai date)" && git push)+ - name: Checkout repository+ uses: actions/checkout@v3++ - name: Set up Python+ uses: actions/setup-python@v4+ with:+ python-version: "3.9"++ - name: Install dependencies+ run: |+ python -m pip install --upgrade pip+ pip install -r requirements.txt++ - name: Verify required files+ run: |+ echo "🔍 检查必需的配置文件..."++ if [ ! -f config/config.yaml ]; then+ echo "❌ 错误: config/config.yaml 文件不存在"+ echo "请参考项目文档创建配置文件"+ exit 1+ fi++ if [ ! -f config/frequency_words.txt ]; then+ echo "❌ 错误: config/frequency_words.txt 文件不存在"+ echo "请参考项目文档创建频率词配置文件"+ exit 1+ fi++ echo "✅ 配置文件检查通过"++ - name: Run crawler+ env:+ FEISHU_WEBHOOK_URL: ${{ secrets.FEISHU_WEBHOOK_URL }}+ TELEGRAM_BOT_TOKEN: ${{ secrets.TELEGRAM_BOT_TOKEN }}+ TELEGRAM_CHAT_ID: ${{ secrets.TELEGRAM_CHAT_ID }}+ DINGTALK_WEBHOOK_URL: ${{ secrets.DINGTALK_WEBHOOK_URL }}+ WEWORK_WEBHOOK_URL: ${{ secrets.WEWORK_WEBHOOK_URL }}+ GITHUB_ACTIONS: true+ run: python main.py++ - name: Commit and push if changes+ run: |+ git config --global user.name 'GitHub Actions'+ git config --global user.email '[email protected]'+ git add -A+ git diff --quiet && git diff --staged --quiet || (git commit -m "Auto update by GitHub Actions at $(TZ=Asia/Shanghai date)" && git push)diff --git a/config/config.yaml b/config/config.yamlnew file mode 100644index 0000000000..cb52abf3fd--- /dev/null+++ b/config/config.yaml@@ -0,0 +1,72 @@+app:+ version: "2.0.0"+ version_check_url: "https://raw.githubusercontent.com/sansan0/TrendRadar/refs/heads/master/version"+ show_version_update: true # 控制显示版本更新提示,改成 false 将不接受新版本提示++crawler:+ request_interval: 1000 # 请求间隔(毫秒)+ enable_crawler: true # 是否启用爬取新闻功能,false 时直接停止程序+ use_proxy: false # 是否启用代理,false 时为关闭+ default_proxy: "http://127.0.0.1:10086"++# 🔸 daily(当日汇总模式)+# • 推送时机:按时推送+# • 显示内容:当日所有匹配新闻 + 新增新闻区域+# • 适用场景:日报总结、全面了解当日热点趋势+#+# 🔸 current(当前榜单模式)+# • 推送时机:按时推送+# • 显示内容:当前榜单匹配新闻 + 新增新闻区域+# • 适用场景:实时热点追踪、了解当前最火的内容+#+# 🔸 incremental(增量监控模式)+# • 推送时机:有新增才推送+# • 显示内容:新出现的匹配频率词新闻+# • 适用场景:避免重复信息干扰++report:+ mode: "daily" # 可选: "daily"|"incremental"|"current"+ rank_threshold: 5 # 排名高亮阈值++notification:+ enable_notification: true # 是否启用通知功能,false 时不发送手机通知+ message_batch_size: 4000 # 消息分批大小(字节)(这个配置别动)+ batch_send_interval: 1 # 批次发送间隔(秒)+ feishu_message_separator: "━━━━━━━━━━━━━━━━━━━" # feishu 消息分割线++ webhooks:+ feishu_url: "" # 飞书机器人的 webhook URL+ dingtalk_url: "" # 钉钉机器人的 webhook URL+ wework_url: "" # 企业微信机器人的 webhook URL+ telegram_bot_token: "" # Telegram Bot Token+ telegram_chat_id: "" # Telegram Chat ID++# 用于让关注度更高的新闻在更前面显示,合起来是 1 就行+weight:+ rank_weight: 0.6 # 排名权重+ frequency_weight: 0.3 # 频次权重+ hotness_weight: 0.1 # 热度权重++platforms:+ - id: "toutiao"+ name: "今日头条"+ - id: "baidu"+ name: "百度热搜"+ - id: "wallstreetcn-hot"+ name: "华尔街见闻"+ - id: "thepaper"+ name: "澎湃新闻"+ - id: "bilibili-hot-search"+ name: "bilibili 热搜"+ - id: "cls-hot"+ name: "财联社热门"+ - id: "ifeng"+ name: "凤凰网"+ - id: "tieba"+ name: "贴吧"+ - id: "weibo"+ name: "微博"+ - id: "douyin"+ name: "抖音"+ - id: "zhihu"+ name: "知乎"diff --git a/frequency_words.txt b/config/frequency_words.txtsimilarity index 85%rename from frequency_words.txtrename to config/frequency_words.txtindex ac145a480c..3cb77aea06 100644--- a/frequency_words.txt+++ b/config/frequency_words.txt@@ -41,6 +41,10 @@ HarmonyOS字节张一鸣+小米+雷军+xiaomi+马斯克特斯拉@@ -59,11 +63,14 @@ geminideepmindchatgpt+Sam AltmanopenaiclaudeAnthropic+苹果+库克iphoneipadmac@@ -75,18 +82,25 @@ ai汽车自动驾驶-l3++手机机器人+国产+中国++美国+芯片-半导体光刻机科技核能+新质生产力+月球登月火星diff --git a/docker/.env b/docker/.envnew file mode 100644index 0000000000..c9cc6b6105--- /dev/null+++ b/docker/.env@@ -0,0 +1,11 @@+# Webhook 配置+FEISHU_WEBHOOK_URL=+TELEGRAM_BOT_TOKEN=+TELEGRAM_CHAT_ID=+DINGTALK_WEBHOOK_URL=+WEWORK_WEBHOOK_URL=++# 运行配置+CRON_SCHEDULE=*/30 * * * * # 定时任务表达式,每 30 分钟执行一次(比如 8点,8点半,9点,9点半这种时间规律执行)+RUN_MODE=cron # 运行模式:cron/once+IMMEDIATE_RUN=true # 启动时立即执行一次\ No newline at end of filediff --git a/docker/Dockerfile b/docker/Dockerfilenew file mode 100644index 0000000000..55591f8470--- /dev/null+++ b/docker/Dockerfile@@ -0,0 +1,36 @@+FROM python:3.10-slim++WORKDIR /app++# https://github.com/aptible/supercronic/releases+ENV SUPERCRONIC_URL=https://github.com/aptible/supercronic/releases/download/v0.2.34/supercronic-linux-amd64 \+ SUPERCRONIC_SHA1SUM=e8631edc1775000d119b70fd40339a7238eece14 \+ SUPERCRONIC=supercronic-linux-amd64++RUN apt-get update && \+ apt-get install -y --no-install-recommends curl && \+ curl -fsSLO "$SUPERCRONIC_URL" && \+ echo "${SUPERCRONIC_SHA1SUM} ${SUPERCRONIC}" | sha1sum -c - && \+ chmod +x "$SUPERCRONIC" && \+ mv "$SUPERCRONIC" "/usr/local/bin/${SUPERCRONIC}" && \+ ln -s "/usr/local/bin/${SUPERCRONIC}" /usr/local/bin/supercronic && \+ apt-get remove -y curl && \+ apt-get clean && \+ rm -rf /var/lib/apt/lists/*++COPY requirements.txt .+RUN pip install --no-cache-dir -r requirements.txt++COPY main.py .+COPY docker/manage.py .+COPY docker/entrypoint.sh /entrypoint.sh++RUN chmod +x /entrypoint.sh && \+ chmod +x manage.py && \+ mkdir -p /app/config /app/output++ENV PYTHONUNBUFFERED=1 \+ CONFIG_PATH=/app/config/config.yaml \+ FREQUENCY_WORDS_PATH=/app/config/frequency_words.txt++ENTRYPOINT ["/entrypoint.sh"]\ No newline at end of filediff --git a/docker/docker-compose.yml b/docker/docker-compose.ymlnew file mode 100644index 0000000000..263bd2c814--- /dev/null+++ b/docker/docker-compose.yml@@ -0,0 +1,22 @@+services:+ trend-radar:+ build:+ context: ..+ dockerfile: docker/Dockerfile+ container_name: trend-radar+ restart: unless-stopped++ volumes:+ - ../config:/app/config:ro+ - ../output:/app/output++ environment:+ - TZ=Asia/Shanghai+ - FEISHU_WEBHOOK_URL=${FEISHU_WEBHOOK_URL:-}+ - TELEGRAM_BOT_TOKEN=${TELEGRAM_BOT_TOKEN:-}+ - TELEGRAM_CHAT_ID=${TELEGRAM_CHAT_ID:-}+ - DINGTALK_WEBHOOK_URL=${DINGTALK_WEBHOOK_URL:-}+ - WEWORK_WEBHOOK_URL=${WEWORK_WEBHOOK_URL:-}+ - CRON_SCHEDULE=${CRON_SCHEDULE:-*/5 * * * *}+ - RUN_MODE=${RUN_MODE:-cron}+ - IMMEDIATE_RUN=${IMMEDIATE_RUN:-true}diff --git a/docker/entrypoint.sh b/docker/entrypoint.shnew file mode 100644index 0000000000..08a8e81e62--- /dev/null+++ b/docker/entrypoint.sh@@ -0,0 +1,44 @@+#!/bin/bash+set -e++# 检查配置文件+if [ ! -f "/app/config/config.yaml" ] || [ ! -f "/app/config/frequency_words.txt" ]; then+ echo "❌ 配置文件缺失"+ exit 1+fi++# 保存环境变量+env >> /etc/environment++case "${RUN_MODE:-cron}" in+"once")+ echo "🔄 单次执行"+ exec /usr/local/bin/python main.py+ ;;+"cron")+ # 生成 crontab+ echo "${CRON_SCHEDULE:-*/30 * * * *} cd /app && /usr/local/bin/python main.py" > /tmp/crontab++ echo "📅 生成的crontab内容:"+ cat /tmp/crontab++ if ! /usr/local/bin/supercronic-linux-amd64 -test /tmp/crontab; then+ echo "❌ crontab格式验证失败"+ exit 1+ fi++ # 立即执行一次(如果配置了)+ if [ "${IMMEDIATE_RUN:-false}" = "true" ]; then+ echo "▶️ 立即执行一次"+ /usr/local/bin/python main.py+ fi++ echo "⏰ 启动supercronic: ${CRON_SCHEDULE:-*/30 * * * *}"+ echo "🎯 supercronic 将作为 PID 1 运行"++ exec /usr/local/bin/supercronic-linux-amd64 -passthrough-logs /tmp/crontab+ ;;+*)+ exec "$@"+ ;;+esac\ No newline at end of filediff --git a/docker/manage.py b/docker/manage.pynew file mode 100644index 0000000000..e72d553e04--- /dev/null+++ b/docker/manage.py@@ -0,0 +1,472 @@+#!/usr/bin/env python3+# -*- coding: utf-8 -*-+"""+新闻爬虫容器管理工具 - supercronic+"""++import os+import sys+import subprocess+import time+from pathlib import Path+++def run_command(cmd, shell=True, capture_output=True):+ """执行系统命令"""+ try:+ result = subprocess.run(+ cmd, shell=shell, capture_output=capture_output, text=True+ )+ return result.returncode == 0, result.stdout, result.stderr+ except Exception as e:+ return False, "", str(e)+++def manual_run():+ """手动执行一次爬虫"""+ print("🔄 手动执行爬虫...")+ try:+ result = subprocess.run(+ ["python", "main.py"], cwd="/app", capture_output=False, text=True+ )+ if result.returncode == 0:+ print("✅ 执行完成")+ else:+ print(f"❌ 执行失败,退出码: {result.returncode}")+ except Exception as e:+ print(f"❌ 执行出错: {e}")+++def parse_cron_schedule(cron_expr):+ """解析cron表达式并返回人类可读的描述"""+ if not cron_expr or cron_expr == "未设置":+ return "未设置"++ try:+ parts = cron_expr.strip().split()+ if len(parts) != 5:+ return f"原始表达式: {cron_expr}"++ minute, hour, day, month, weekday = parts++ # 分析分钟+ if minute == "*":+ minute_desc = "每分钟"+ elif minute.startswith("*/"):+ interval = minute[2:]+ minute_desc = f"每{interval}分钟"+ elif "," in minute:+ minute_desc = f"在第{minute}分钟"+ else:+ minute_desc = f"在第{minute}分钟"++ # 分析小时+ if hour == "*":+ hour_desc = "每小时"+ elif hour.startswith("*/"):+ interval = hour[2:]+ hour_desc = f"每{interval}小时"+ elif "," in hour:+ hour_desc = f"在{hour}点"+ else:+ hour_desc = f"在{hour}点"++ # 分析日期+ if day == "*":+ day_desc = "每天"+ elif day.startswith("*/"):+ interval = day[2:]+ day_desc = f"每{interval}天"+ else:+ day_desc = f"每月{day}号"++ # 分析月份+ if month == "*":+ month_desc = "每月"+ else:+ month_desc = f"在{month}月"++ # 分析星期+ weekday_names = {+ "0": "周日", "1": "周一", "2": "周二", "3": "周三",+ "4": "周四", "5": "周五", "6": "周六", "7": "周日"+ }+ if weekday == "*":+ weekday_desc = ""+ else:+ weekday_desc = f"在{weekday_names.get(weekday, weekday)}"++ # 组合描述+ if minute.startswith("*/") and hour == "*" and day == "*" and month == "*" and weekday == "*":+ # 简单的间隔模式,如 */30 * * * *+ return f"每{minute[2:]}分钟执行一次"+ elif hour != "*" and minute != "*" and day == "*" and month == "*" and weekday == "*":+ # 每天特定时间,如 0 9 * * *+ return f"每天{hour}:{minute.zfill(2)}执行"+ elif weekday != "*" and day == "*":+ # 每周特定时间+ return f"{weekday_desc}{hour}:{minute.zfill(2)}执行"+ else:+ # 复杂模式,显示详细信息+ desc_parts = [part for part in [month_desc, day_desc, weekday_desc, hour_desc, minute_desc] if part and part != "每月" and part != "每天" and part != "每小时"]+ if desc_parts:+ return " ".join(desc_parts) + "执行"+ else:+ return f"复杂表达式: {cron_expr}"++ except Exception as e:+ return f"解析失败: {cron_expr}"+++def show_status():+ """显示容器状态"""+ print("📊 容器状态:")++ # 检查 PID 1 状态+ supercronic_is_pid1 = False+ pid1_cmdline = ""+ try:+ with open('/proc/1/cmdline', 'r') as f:+ pid1_cmdline = f.read().replace('\x00', ' ').strip()+ print(f" 🔍 PID 1 进程: {pid1_cmdline}")++ if "supercronic" in pid1_cmdline.lower():+ print(" ✅ supercronic 正确运行为 PID 1")+ supercronic_is_pid1 = True+ else:+ print(" ❌ PID 1 不是 supercronic")+ print(f" 📋 实际的 PID 1: {pid1_cmdline}")+ except Exception as e:+ print(f" ❌ 无法读取 PID 1 信息: {e}")++ # 检查环境变量+ cron_schedule = os.environ.get("CRON_SCHEDULE", "未设置")+ run_mode = os.environ.get("RUN_MODE", "未设置")+ immediate_run = os.environ.get("IMMEDIATE_RUN", "未设置")++ print(f" ⚙️ 运行配置:")+ print(f" CRON_SCHEDULE: {cron_schedule}")++ # 解析并显示cron表达式的含义+ cron_description = parse_cron_schedule(cron_schedule)+ print(f" ⏰ 执行频率: {cron_description}")++ print(f" RUN_MODE: {run_mode}")+ print(f" IMMEDIATE_RUN: {immediate_run}")++ # 检查配置文件+ config_files = ["/app/config/config.yaml", "/app/config/frequency_words.txt"]+ print(" 📁 配置文件:")+ for file_path in config_files:+ if Path(file_path).exists():+ print(f" ✅ {Path(file_path).name}")+ else:+ print(f" ❌ {Path(file_path).name} 缺失")++ # 检查关键文件+ key_files = [+ ("/usr/local/bin/supercronic-linux-amd64", "supercronic二进制文件"),+ ("/usr/local/bin/supercronic", "supercronic软链接"),+ ("/tmp/crontab", "crontab文件"),+ ("/entrypoint.sh", "启动脚本")+ ]++ print(" 📂 关键文件检查:")+ for file_path, description in key_files:+ if Path(file_path).exists():+ print(f" ✅ {description}: 存在")+ # 对于crontab文件,显示内容+ if file_path == "/tmp/crontab":+ try:+ with open(file_path, 'r') as f:+ crontab_content = f.read().strip()+ print(f" 内容: {crontab_content}")+ except:+ pass+ else:+ print(f" ❌ {description}: 不存在")++ # 检查容器运行时间+ print(" ⏱️ 容器时间信息:")+ try:+ # 检查 PID 1 的启动时间+ with open('/proc/1/stat', 'r') as f:+ stat_content = f.read().strip().split()+ if len(stat_content) >= 22:+ # starttime 是第22个字段(索引21)+ starttime_ticks = int(stat_content[21])++ # 读取系统启动时间+ with open('/proc/stat', 'r') as stat_f:+ for line in stat_f:+ if line.startswith('btime'):+ boot_time = int(line.split()[1])+ break+ else:+ boot_time = 0++ # 读取系统时钟频率+ clock_ticks = os.sysconf(os.sysconf_names['SC_CLK_TCK'])++ if boot_time > 0:+ pid1_start_time = boot_time + (starttime_ticks / clock_ticks)+ current_time = time.time()+ uptime_seconds = int(current_time - pid1_start_time)+ uptime_minutes = uptime_seconds // 60+ uptime_hours = uptime_minutes // 60++ if uptime_hours > 0:+ print(f" PID 1 运行时间: {uptime_hours} 小时 {uptime_minutes % 60} 分钟")+ else:+ print(f" PID 1 运行时间: {uptime_minutes} 分钟 ({uptime_seconds} 秒)")+ else:+ print(f" PID 1 运行时间: 无法精确计算")+ else:+ print(" ❌ 无法解析 PID 1 统计信息")+ except Exception as e:+ print(f" ❌ 时间检查失败: {e}")++ # 状态总结和建议+ print(" 📊 状态总结:")+ if supercronic_is_pid1:+ print(" ✅ supercronic 正确运行为 PID 1")+ print(" ✅ 定时任务应该正常工作")++ # 显示当前的调度信息+ if cron_schedule != "未设置":+ print(f" ⏰ 当前调度: {cron_description}")++ # 提供一些常见的调度建议+ if "分钟" in cron_description and "每30分钟" not in cron_description and "每60分钟" not in cron_description:+ print(" 💡 频繁执行模式,适合实时监控")+ elif "小时" in cron_description:+ print(" 💡 按小时执行模式,适合定期汇总")+ elif "天" in cron_description:+ print(" 💡 每日执行模式,适合日报生成")++ print(" 💡 如果定时任务不执行,检查:")+ print(" • crontab 格式是否正确")+ print(" • 时区设置是否正确")+ print(" • 应用程序是否有错误")+ else:+ print(" ❌ supercronic 状态异常")+ if pid1_cmdline:+ print(f" 📋 当前 PID 1: {pid1_cmdline}")+ print(" 💡 建议操作:")+ print(" • 重启容器: docker restart trend-radar")+ print(" • 检查容器日志: docker logs trend-radar")++ # 显示日志检查建议+ print(" 📋 运行状态检查:")+ print(" • 查看完整容器日志: docker logs trend-radar")+ print(" • 查看实时日志: docker logs -f trend-radar")+ print(" • 手动执行测试: python manage.py run")+ print(" • 重启容器服务: docker restart trend-radar")+++def show_config():+ """显示当前配置"""+ print("⚙️ 当前配置:")++ env_vars = [+ "CRON_SCHEDULE",+ "RUN_MODE",+ "IMMEDIATE_RUN",+ "FEISHU_WEBHOOK_URL",+ "DINGTALK_WEBHOOK_URL",+ "WEWORK_WEBHOOK_URL",+ "TELEGRAM_BOT_TOKEN",+ "TELEGRAM_CHAT_ID",+ "CONFIG_PATH",+ "FREQUENCY_WORDS_PATH",+ ]++ for var in env_vars:+ value = os.environ.get(var, "未设置")+ # 隐藏敏感信息+ if any(sensitive in var for sensitive in ["WEBHOOK", "TOKEN", "KEY"]):+ if value and value != "未设置":+ masked_value = value[:10] + "***" if len(value) > 10 else "***"+ print(f" {var}: {masked_value}")+ else:+ print(f" {var}: {value}")+ else:+ print(f" {var}: {value}")++ crontab_file = "/tmp/crontab"+ if Path(crontab_file).exists():+ print(" 📅 Crontab内容:")+ try:+ with open(crontab_file, "r") as f:+ content = f.read().strip()+ print(f" {content}")+ except Exception as e:+ print(f" 读取失败: {e}")+ else:+ print(" 📅 Crontab文件不存在")+++def show_files():+ """显示输出文件"""+ print("📁 输出文件:")++ output_dir = Path("/app/output")+ if not output_dir.exists():+ print(" 📭 输出目录不存在")+ return++ # 显示最近的文件+ date_dirs = sorted([d for d in output_dir.iterdir() if d.is_dir()], reverse=True)++ if not date_dirs:+ print(" 📭 输出目录为空")+ return++ # 显示最近2天的文件+ for date_dir in date_dirs[:2]:+ print(f" 📅 {date_dir.name}:")+ for subdir in ["html", "txt"]:+ sub_path = date_dir / subdir+ if sub_path.exists():+ files = list(sub_path.glob("*"))+ if files:+ recent_files = sorted(+ files, key=lambda x: x.stat().st_mtime, reverse=True+ )[:3]+ print(f" 📂 {subdir}: {len(files)} 个文件")+ for file in recent_files:+ mtime = time.ctime(file.stat().st_mtime)+ size_kb = file.stat().st_size // 1024+ print(+ f" 📄 {file.name} ({size_kb}KB, {mtime.split()[3][:5]})"+ )+ else:+ print(f" 📂 {subdir}: 空")+++def show_logs():+ """显示实时日志"""+ print("📋 实时日志 (按 Ctrl+C 退出):")+ print("💡 提示: 这将显示 PID 1 进程的输出")+ try:+ # 尝试多种方法查看日志+ log_files = [+ "/proc/1/fd/1", # PID 1 的标准输出+ "/proc/1/fd/2", # PID 1 的标准错误+ ]++ for log_file in log_files:+ if Path(log_file).exists():+ print(f"📄 尝试读取: {log_file}")+ subprocess.run(["tail", "-f", log_file], check=True)+ break+ else:+ print("📋 无法找到标准日志文件,建议使用: docker logs trend-radar")++ except KeyboardInterrupt:+ print("\n👋 退出日志查看")+ except Exception as e:+ print(f"❌ 查看日志失败: {e}")+ print("💡 建议使用: docker logs trend-radar")+++def restart_supercronic():+ """重启supercronic进程"""+ print("🔄 重启supercronic...")+ print("⚠️ 注意: supercronic 是 PID 1,无法直接重启")++ # 检查当前 PID 1+ try:+ with open('/proc/1/cmdline', 'r') as f:+ pid1_cmdline = f.read().replace('\x00', ' ').strip()+ print(f" 🔍 当前 PID 1: {pid1_cmdline}")++ if "supercronic" in pid1_cmdline.lower():+ print(" ✅ PID 1 是 supercronic")+ print(" 💡 要重启 supercronic,需要重启整个容器:")+ print(" docker restart trend-radar")+ else:+ print(" ❌ PID 1 不是 supercronic,这是异常状态")+ print(" 💡 建议重启容器以修复问题:")+ print(" docker restart trend-radar")+ except Exception as e:+ print(f" ❌ 无法检查 PID 1: {e}")+ print(" 💡 建议重启容器: docker restart trend-radar")+++def show_help():+ """显示帮助信息"""+ help_text = """+🐳 TrendRadar 容器管理工具++📋 命令列表:+ run - 手动执行一次爬虫+ status - 显示容器运行状态+ config - 显示当前配置+ files - 显示输出文件+ logs - 实时查看日志+ restart - 重启说明+ help - 显示此帮助++📖 使用示例:+ # 在容器中执行+ python manage.py run+ python manage.py status+ python manage.py logs++ # 在宿主机执行+ docker exec -it trend-radar python manage.py run+ docker exec -it trend-radar python manage.py status+ docker logs trend-radar++💡 常用操作指南:+ 1. 检查运行状态: status+ - 查看 supercronic 是否为 PID 1+ - 检查配置文件和关键文件+ - 查看 cron 调度设置++ 2. 手动执行测试: run+ - 立即执行一次新闻爬取+ - 测试程序是否正常工作++ 3. 查看日志: logs+ - 实时监控运行情况+ - 也可使用: docker logs trend-radar++ 4. 重启服务: restart+ - 由于 supercronic 是 PID 1,需要重启整个容器+ - 使用: docker restart trend-radar+"""+ print(help_text)+++def main():+ if len(sys.argv) < 2:+ show_help()+ return++ command = sys.argv[1]+ commands = {+ "run": manual_run,+ "status": show_status,+ "config": show_config,+ "files": show_files,+ "logs": show_logs,+ "restart": restart_supercronic,+ "help": show_help,+ }++ if command in commands:+ try:+ commands[command]()+ except KeyboardInterrupt:+ print("\n👋 操作已取消")+ except Exception as e:+ print(f"❌ 执行出错: {e}")+ else:+ print(f"❌ 未知命令: {command}")+ print("运行 'python manage.py help' 查看可用命令")+++if __name__ == "__main__":+ main()\ No newline at end of filediff --git a/main.py b/main.pyindex 82dfd4efe5..dfdd87af3e 100644--- a/main.py+++ b/main.py@@ -1,52 +1,151 @@# coding=utf-8import json-import time+import osimport randomimport re-from datetime import datetime+import timeimport webbrowser-from typing import Dict, List, Tuple, Optional, Union+from dataclasses import dataclass+from datetime import datetimefrom pathlib import Path-import os+from typing import Dict, List, Tuple, Optional, Union-import requestsimport pytz+import requests+import yaml+++class ConfigManager:+ """配置管理器"""++ @staticmethod+ def _load_config_file() -> Dict:+ """加载配置文件"""+ config_path = os.environ.get("CONFIG_PATH", "config/config.yaml")++ if not Path(config_path).exists():+ raise FileNotFoundError(f"配置文件 {config_path} 不存在")++ try:+ with open(config_path, "r", encoding="utf-8") as f:+ config_data = yaml.safe_load(f)++ print(f"配置文件加载成功: {config_path}")+ return config_data++ except Exception as e:+ raise RuntimeError(f"配置文件解析失败: {e}")-CONFIG = {- "VERSION": "1.4.1",- "VERSION_CHECK_URL": "https://raw.githubusercontent.com/sansan0/TrendRadar/refs/heads/master/version",- "SHOW_VERSION_UPDATE": True, # 控制显示版本更新提示,改成 False 将不接受新版本提示- "FEISHU_MESSAGE_SEPARATOR": "━━━━━━━━━━━━━━━━━━━", # feishu消息分割线- "REQUEST_INTERVAL": 1000, # 请求间隔(毫秒)- "REPORT_TYPE": "daily", # 报告类型: "current"|"daily"|"both"- "RANK_THRESHOLD": 5, # 排名高亮阈值- "USE_PROXY": True, # 是否启用代理- "DEFAULT_PROXY": "http://127.0.0.1:10086",- "ENABLE_CRAWLER": True, # 是否启用爬取新闻功能,False时直接停止程序- "ENABLE_NOTIFICATION": True, # 是否启用通知功能,False时不发送手机通知- "FOCUS_NEW_ONLY": False, # 是否只关注新增新闻,True时只统计和推送新增的新闻(增量推送)- # FOCUS_NEW_ONLY 增量推送开关:避免重复推送相同内容,只在有新内容时才发通知- # 优点:1.减少重复推送噪音 2.专注最新动态 3.避免通知疲劳- # 适用场景:1.高频监控(≤30分钟间隔) 2.实时热点追踪 3.只关心新话题而非持续热度- "MESSAGE_BATCH_SIZE": 4000, # 消息分批大小(字节)- "BATCH_SEND_INTERVAL": 1, # 批次发送间隔(秒)- # 飞书机器人的 webhook URL- "FEISHU_WEBHOOK_URL": "",- # 钉钉机器人的 webhook URL- "DINGTALK_WEBHOOK_URL": "",- # 企业微信机器人的 webhook URL- "WEWORK_WEBHOOK_URL": "",- # Telegram 要填两个- "TELEGRAM_BOT_TOKEN": "",- "TELEGRAM_CHAT_ID": "",- # 用于让关注度更高的新闻在更前面显示,这里是权重排序配置,合起来是 1 就行- "WEIGHT_CONFIG": {- "RANK_WEIGHT": 0.6, # 排名- "FREQUENCY_WEIGHT": 0.3, # 频次- "HOTNESS_WEIGHT": 0.1, # 热度- },-}+ def __init__(self):+ self.config_data = self._load_config_file()+ self.config = self._build_config()+ self.platforms = self.config_data["platforms"]++ def _get_webhook_config(self, config_key: str, env_key: str) -> str:+ """获取 Webhook 配置"""+ env_value = os.environ.get(env_key, "").strip()+ if env_value:+ return env_value++ return (+ self.config_data.get("notification", {})+ .get("webhooks", {})+ .get(config_key, "")+ )++ def _build_config(self) -> Dict:+ """构建配置字典,环境变量优先级高于配置文件"""++ feishu_url = self._get_webhook_config("feishu_url", "FEISHU_WEBHOOK_URL")+ dingtalk_url = self._get_webhook_config("dingtalk_url", "DINGTALK_WEBHOOK_URL")+ wework_url = self._get_webhook_config("wework_url", "WEWORK_WEBHOOK_URL")+ telegram_token = self._get_webhook_config(+ "telegram_bot_token", "TELEGRAM_BOT_TOKEN"+ )+ telegram_chat_id = self._get_webhook_config(+ "telegram_chat_id", "TELEGRAM_CHAT_ID"+ )++ # 输出配置来源信息+ webhook_sources = []+ if feishu_url:+ source = "环境变量" if os.environ.get("FEISHU_WEBHOOK_URL") else "配置文件"+ webhook_sources.append(f"飞书({source})")+ if dingtalk_url:+ source = (+ "环境变量" if os.environ.get("DINGTALK_WEBHOOK_URL") else "配置文件"+ )+ webhook_sources.append(f"钉钉({source})")+ if wework_url:+ source = "环境变量" if os.environ.get("WEWORK_WEBHOOK_URL") else "配置文件"+ webhook_sources.append(f"企业微信({source})")+ if telegram_token and telegram_chat_id:+ token_source = (+ "环境变量" if os.environ.get("TELEGRAM_BOT_TOKEN") else "配置文件"+ )+ chat_source = (+ "环境变量" if os.environ.get("TELEGRAM_CHAT_ID") else "配置文件"+ )+ webhook_sources.append(f"Telegram({token_source}/{chat_source})")++ if webhook_sources:+ print(f"Webhook 配置来源: {', '.join(webhook_sources)}")+ else:+ print("未配置任何 Webhook")++ config = {+ "VERSION": self.config_data["app"]["version"],+ "VERSION_CHECK_URL": self.config_data["app"]["version_check_url"],+ "SHOW_VERSION_UPDATE": self.config_data["app"]["show_version_update"],+ "FEISHU_MESSAGE_SEPARATOR": self.config_data["notification"][+ "feishu_message_separator"+ ],+ "REQUEST_INTERVAL": self.config_data["crawler"]["request_interval"],+ "REPORT_MODE": self.config_data["report"]["mode"],+ "RANK_THRESHOLD": self.config_data["report"]["rank_threshold"],+ "USE_PROXY": self.config_data["crawler"]["use_proxy"],+ "DEFAULT_PROXY": self.config_data["crawler"]["default_proxy"],+ "ENABLE_CRAWLER": self.config_data["crawler"]["enable_crawler"],+ "ENABLE_NOTIFICATION": self.config_data["notification"][+ "enable_notification"+ ],+ "MESSAGE_BATCH_SIZE": self.config_data["notification"][+ "message_batch_size"+ ],+ "BATCH_SEND_INTERVAL": self.config_data["notification"][+ "batch_send_interval"+ ],+ "FEISHU_WEBHOOK_URL": feishu_url,+ "DINGTALK_WEBHOOK_URL": dingtalk_url,+ "WEWORK_WEBHOOK_URL": wework_url,+ "TELEGRAM_BOT_TOKEN": telegram_token,+ "TELEGRAM_CHAT_ID": telegram_chat_id,+ "WEIGHT_CONFIG": {+ "RANK_WEIGHT": self.config_data["weight"]["rank_weight"],+ "FREQUENCY_WEIGHT": self.config_data["weight"]["frequency_weight"],+ "HOTNESS_WEIGHT": self.config_data["weight"]["hotness_weight"],+ },+ }++ return config++ def get_config(self) -> Dict:+ """获取配置字典"""+ return self.config++ def get_platforms(self) -> List:+ """获取平台列表"""+ return self.platforms+++print("正在加载配置...")+config_manager = ConfigManager()+CONFIG = config_manager.get_config()+PLATFORMS = config_manager.get_platforms()++print(f"TrendRadar v{CONFIG['VERSION']} 配置加载完成")+print(f"监控平台数量: {len(PLATFORMS)}")class TimeHelper:@@ -75,10 +174,10 @@ class VersionChecker:parts = version_str.strip().split(".")if len(parts) != 3:raise ValueError("版本号格式不正确")- return tuple(int(part) for part in parts)+ return int(parts[0]), int(parts[1]), int(parts[2])except (ValueError, AttributeError):print(f"无法解析版本号: {version_str}")- return (0, 0, 0)+ return 0, 0, 0@staticmethoddef compare_versions(current: str, remote: str) -> int:@@ -220,17 +319,17 @@ class DataFetcher:) -> Tuple[Dict, Dict, List]:"""爬取多个网站数据"""results = {}- id_to_alias = {}+ id_to_name = {}failed_ids = []for i, id_info in enumerate(ids_list):if isinstance(id_info, tuple):- id_value, alias = id_info+ id_value, name = id_infoelse:id_value = id_info- alias = id_value+ name = id_value- id_to_alias[id_value] = alias+ id_to_name[id_value] = nameresponse, _, _ = self.fetch_data(id_info)if response:@@ -265,7 +364,7 @@ class DataFetcher:time.sleep(actual_interval / 1000)print(f"成功: {list(results.keys())}, 失败: {failed_ids}")- return results, id_to_alias, failed_ids+ return results, id_to_name, failed_idsclass DataProcessor:@@ -277,10 +376,7 @@ class DataProcessor:if not isinstance(title, str):title = str(title)- # 移除或替换常见的特殊字符- cleaned_title = title.replace("\n", " ").replace( # 换行符替换为空格- "\r", " "- ) # 回车符替换为空格+ cleaned_title = title.replace("\n", " ").replace("\r", " ")cleaned_title = re.sub(r"\s+", " ", cleaned_title)@@ -301,8 +397,10 @@ class DataProcessor:return len(files) <= 1 # 0个文件或1个文件都算第一次@staticmethod- def detect_latest_new_titles(id_to_alias: Dict) -> Dict:- """检测当日最新批次的新增标题"""+ def detect_latest_new_titles(+ current_platform_ids: Optional[List[str]] = None,+ ) -> Dict:+ """检测当日最新批次的新增标题,支持按当前监控平台过滤"""date_folder = TimeHelper.format_date_folder()txt_dir = Path("output") / date_folder / "txt"@@ -311,26 +409,43 @@ class DataProcessor:files = sorted([f for f in txt_dir.iterdir() if f.suffix == ".txt"])if len(files) < 2:- # 如果只有一个文件(第一次爬取),没有"新增"的概念,返回空字典return {}+ # 解析最新文件latest_file = files[-1]- latest_titles = DataProcessor._parse_file_titles(latest_file)+ latest_titles, _ = DataProcessor._parse_file_titles(latest_file)- # 汇总历史标题+ # 如果指定了当前平台列表,过滤最新文件数据+ if current_platform_ids is not None:+ filtered_latest_titles = {}+ for source_id, title_data in latest_titles.items():+ if source_id in current_platform_ids:+ filtered_latest_titles[source_id] = title_data+ latest_titles = filtered_latest_titles++ # 汇总历史标题(按平台过滤)historical_titles = {}for file_path in files[:-1]:- historical_data = DataProcessor._parse_file_titles(file_path)- for source_name, titles_data in historical_data.items():- if source_name not in historical_titles:- historical_titles[source_name] = set()+ historical_data, _ = DataProcessor._parse_file_titles(file_path)++ # 过滤历史数据+ if current_platform_ids is not None:+ filtered_historical_data = {}+ for source_id, title_data in historical_data.items():+ if source_id in current_platform_ids:+ filtered_historical_data[source_id] = title_data+ historical_data = filtered_historical_data++ for source_id, titles_data in historical_data.items():+ if source_id not in historical_titles:+ historical_titles[source_id] = set()for title in titles_data.keys():- historical_titles[source_name].add(title)+ historical_titles[source_id].add(title)# 找出新增标题new_titles = {}- for source_name, latest_source_titles in latest_titles.items():- historical_set = historical_titles.get(source_name, set())+ for source_id, latest_source_titles in latest_titles.items():+ historical_set = historical_titles.get(source_id, set())source_new_titles = {}for title, title_data in latest_source_titles.items():@@ -338,21 +453,15 @@ class DataProcessor:source_new_titles[title] = title_dataif source_new_titles:- source_id = None- for id_val, alias in id_to_alias.items():- if alias == source_name:- source_id = id_val- break-- if source_id:- new_titles[source_id] = source_new_titles+ new_titles[source_id] = source_new_titlesreturn new_titles@staticmethod- def _parse_file_titles(file_path: Path) -> Dict:- """解析单个txt文件的标题数据"""- titles_by_source = {}+ def _parse_file_titles(file_path: Path) -> Tuple[Dict, Dict]:+ """解析单个txt文件的标题数据,返回(titles_by_id, id_to_name)"""+ titles_by_id = {}+ id_to_name = {}with open(file_path, "r", encoding="utf-8") as f:content = f.read()@@ -366,8 +475,18 @@ class DataProcessor:if len(lines) < 2:continue- source_name = lines[0].strip()- titles_by_source[source_name] = {}+ # id | name 或 id+ header_line = lines[0].strip()+ if " | " in header_line:+ parts = header_line.split(" | ", 1)+ source_id = parts[0].strip()+ name = parts[1].strip()+ id_to_name[source_id] = name+ else:+ source_id = header_line+ id_to_name[source_id] = source_id++ titles_by_id[source_id] = {}for line in lines[1:]:if line.strip():@@ -383,7 +502,7 @@ class DataProcessor:rank_str, title_part = title_part.split(". ", 1)rank = int(rank_str)- # 提取MOBILE URL+ # 提取 MOBILE URLmobile_url = ""if " [MOBILE:" in title_part:title_part, mobile_part = title_part.rsplit(@@ -392,7 +511,7 @@ class DataProcessor:if mobile_part.endswith("]"):mobile_url = mobile_part[:-1]- # 提取URL+ # 提取 URLurl = ""if " [URL:" in title_part:title_part, url_part = title_part.rsplit(" [URL:", 1)@@ -402,7 +521,7 @@ class DataProcessor:title = DataProcessor.clean_title(title_part.strip())ranks = [rank] if rank is not None else [1]- titles_by_source[source_name][title] = {+ titles_by_id[source_id][title] = {"ranks": ranks,"url": url,"mobileUrl": mobile_url,@@ -411,10 +530,10 @@ class DataProcessor:except Exception as e:print(f"解析标题行出错: {line}, 错误: {e}")- return titles_by_source+ return titles_by_id, id_to_name@staticmethod- def save_titles_to_file(results: Dict, id_to_alias: Dict, failed_ids: List) -> str:+ def save_titles_to_file(results: Dict, id_to_name: Dict, failed_ids: List) -> str:"""保存标题到文件"""file_path = FileHelper.get_output_path("txt", f"{TimeHelper.format_time_filename()}.txt"@@ -422,8 +541,12 @@ class DataProcessor:with open(file_path, "w", encoding="utf-8") as f:for id_value, title_data in results.items():- display_name = id_to_alias.get(id_value, id_value)- f.write(f"{display_name}\n")+ # id | name 或 id+ name = id_to_name.get(id_value)+ if name and name != id_value:+ f.write(f"{id_value} | {name}\n")+ else:+ f.write(f"{id_value}\n")# 按排名排序标题sorted_titles = []@@ -457,20 +580,23 @@ class DataProcessor:if failed_ids:f.write("==== 以下ID请求失败 ====\n")for id_value in failed_ids:- display_name = id_to_alias.get(id_value, id_value)- f.write(f"{display_name} (ID: {id_value})\n")+ f.write(f"{id_value}\n")return file_path@staticmethoddef load_frequency_words(- frequency_file: str = "frequency_words.txt",+ frequency_file: Optional[str] = None,) -> Tuple[List[Dict], List[str]]:"""加载频率词配置"""+ if frequency_file is None:+ frequency_file = os.environ.get(+ "FREQUENCY_WORDS_PATH", "config/frequency_words.txt"+ )+frequency_path = Path(frequency_file)if not frequency_path.exists():- print(f"频率词文件 {frequency_file} 不存在")- return [], []+ raise FileNotFoundError(f"频率词文件 {frequency_file} 不存在")with open(frequency_path, "r", encoding="utf-8") as f:content = f.read()@@ -515,8 +641,10 @@ class DataProcessor:return processed_groups, filter_words@staticmethod- def read_all_today_titles() -> Tuple[Dict, Dict, Dict]:- """读取当天所有标题文件"""+ def read_all_today_titles(+ current_platform_ids: Optional[List[str]] = None,+ ) -> Tuple[Dict, Dict, Dict]:+ """读取当天所有标题文件,支持按当前监控平台过滤"""date_folder = TimeHelper.format_date_folder()txt_dir = Path("output") / date_folder / "txt"@@ -524,7 +652,7 @@ class DataProcessor:return {}, {}, {}all_results = {}- id_to_alias = {}+ final_id_to_name = {}title_info = {}files = sorted([f for f in txt_dir.iterdir() if f.suffix == ".txt"])@@ -532,109 +660,55 @@ class DataProcessor:for file_path in files:time_info = file_path.stem- with open(file_path, "r", encoding="utf-8") as f:- content = f.read()-- sections = content.split("\n\n")- for section in sections:- if not section.strip() or "==== 以下ID请求失败 ====" in section:- continue-- lines = section.strip().split("\n")- if len(lines) < 2:- continue-- source_name = lines[0].strip()- title_data = {}-- for line in lines[1:]:- if line.strip():- try:- rank = None- title_part = line.strip()-- # 提取行首的排名数字- if (- ". " in title_part- and title_part.split(". ")[0].isdigit()- ):- parts = title_part.split(". ", 1)- rank = int(parts[0])- title_part = parts[1]-- # 提取 MOBILE URL- mobile_url = ""- if " [MOBILE:" in title_part:- title_part, mobile_part = title_part.rsplit(- " [MOBILE:", 1- )- if mobile_part.endswith("]"):- mobile_url = mobile_part[:-1]-- # 提取 URL- url = ""- if " [URL:" in title_part:- title_part, url_part = title_part.rsplit(- " [URL:", 1- )- if url_part.endswith("]"):- url = url_part[:-1]-- title = title_part.strip()- ranks = [rank] if rank is not None else [1]-- title_data[title] = {- "ranks": ranks,- "url": url,- "mobileUrl": mobile_url,- }-- except Exception as e:- print(f"解析标题行出错: {line}, 错误: {e}")-- DataProcessor._process_source_data(- source_name,- title_data,- time_info,- all_results,- title_info,- id_to_alias,- )+ titles_by_id, file_id_to_name = DataProcessor._parse_file_titles(file_path)- # 转换为ID格式- id_results = {}- id_title_info = {}- for name, titles in all_results.items():- for id_value, alias in id_to_alias.items():- if alias == name:- id_results[id_value] = titles- id_title_info[id_value] = title_info[name]- break+ if current_platform_ids is not None:+ filtered_titles_by_id = {}+ filtered_id_to_name = {}++ for source_id, title_data in titles_by_id.items():+ if source_id in current_platform_ids:+ filtered_titles_by_id[source_id] = title_data+ if source_id in file_id_to_name:+ filtered_id_to_name[source_id] = file_id_to_name[source_id]++ titles_by_id = filtered_titles_by_id+ file_id_to_name = filtered_id_to_name- return id_results, id_to_alias, id_title_info+ final_id_to_name.update(file_id_to_name)++ for source_id, title_data in titles_by_id.items():+ DataProcessor._process_source_data(+ source_id,+ title_data,+ time_info,+ all_results,+ title_info,+ )++ return all_results, final_id_to_name, title_info@staticmethoddef _process_source_data(- source_name: str,+ source_id: str,title_data: Dict,time_info: str,all_results: Dict,title_info: Dict,- id_to_alias: Dict,) -> None:"""处理来源数据,合并重复标题"""- if source_name not in all_results:- all_results[source_name] = title_data+ if source_id not in all_results:+ all_results[source_id] = title_data- if source_name not in title_info:- title_info[source_name] = {}+ if source_id not in title_info:+ title_info[source_id] = {}for title, data in title_data.items():ranks = data.get("ranks", [])url = data.get("url", "")mobile_url = data.get("mobileUrl", "")- title_info[source_name][title] = {+ title_info[source_id][title] = {"first_time": time_info,"last_time": time_info,"count": 1,@@ -642,22 +716,19 @@ class DataProcessor:"url": url,"mobileUrl": mobile_url,}-- reversed_id = source_name.lower().replace(" ", "-")- id_to_alias[reversed_id] = source_nameelse:for title, data in title_data.items():ranks = data.get("ranks", [])url = data.get("url", "")mobile_url = data.get("mobileUrl", "")- if title not in all_results[source_name]:- all_results[source_name][title] = {+ if title not in all_results[source_id]:+ all_results[source_id][title] = {"ranks": ranks,"url": url,"mobileUrl": mobile_url,}- title_info[source_name][title] = {+ title_info[source_id][title] = {"first_time": time_info,"last_time": time_info,"count": 1,@@ -666,7 +737,7 @@ class DataProcessor:"mobileUrl": mobile_url,}else:- existing_data = all_results[source_name][title]+ existing_data = all_results[source_id][title]existing_ranks = existing_data.get("ranks", [])existing_url = existing_data.get("url", "")existing_mobile_url = existing_data.get("mobileUrl", "")@@ -676,19 +747,19 @@ class DataProcessor:if rank not in merged_ranks:merged_ranks.append(rank)- all_results[source_name][title] = {+ all_results[source_id][title] = {"ranks": merged_ranks,"url": existing_url or url,"mobileUrl": existing_mobile_url or mobile_url,}- title_info[source_name][title]["last_time"] = time_info- title_info[source_name][title]["ranks"] = merged_ranks- title_info[source_name][title]["count"] += 1- if not title_info[source_name][title].get("url"):- title_info[source_name][title]["url"] = url- if not title_info[source_name][title].get("mobileUrl"):- title_info[source_name][title]["mobileUrl"] = mobile_url+ title_info[source_id][title]["last_time"] = time_info+ title_info[source_id][title]["ranks"] = merged_ranks+ title_info[source_id][title]["count"] += 1+ if not title_info[source_id][title].get("url"):+ title_info[source_id][title]["url"] = url+ if not title_info[source_id][title].get("mobileUrl"):+ title_info[source_id][title]["mobileUrl"] = mobile_urlclass StatisticsCalculator:@@ -722,7 +793,6 @@ class StatisticsCalculator:hotness_ratio = high_rank_count / len(ranks) if ranks else 0hotness_weight = hotness_ratio * 100- # 综合权重计算total_weight = (rank_weight * weight_config["RANK_WEIGHT"]+ frequency_weight * weight_config["FREQUENCY_WEIGHT"]@@ -746,12 +816,12 @@ class StatisticsCalculator:# 主要按权重排序,权重相同时按最高排名排序,再相同时按出现次数排序min_rank = min(ranks) if ranks else 999- return (-weight, min_rank, -count)+ return -weight, min_rank, -countreturn sorted(titles_list, key=get_sort_key)@staticmethod- def _matches_word_groups(+ def matches_word_groups(title: str, word_groups: List[Dict], filter_words: List[str]) -> bool:"""检查标题是否匹配词组规则"""@@ -791,44 +861,65 @@ class StatisticsCalculator:results: Dict,word_groups: List[Dict],filter_words: List[str],- id_to_alias: Dict,+ id_to_name: Dict,title_info: Optional[Dict] = None,rank_threshold: int = CONFIG["RANK_THRESHOLD"],new_titles: Optional[Dict] = None,- focus_new_only: bool = False,+ mode: str = "daily",) -> Tuple[List[Dict], int]:"""统计词频,支持必须词、频率词、过滤词,并标记新增标题"""- # 检测是否是当天第一次爬取is_first_today = DataProcessor.is_first_crawl_today()# 确定处理的数据源和新增标记逻辑- if focus_new_only:+ if mode == "incremental":if is_first_today:- # 新增模式 + 当天第一次:处理所有新闻,都标记为新增+ # 增量模式 + 当天第一次:处理所有新闻,都标记为新增results_to_process = resultsall_news_are_new = True- total_input_news = sum(len(titles) for titles in results.values())- print(- f"新增模式:当天第一次爬取,处理 {total_input_news} 条新闻(所有匹配的新闻都视为新增)"- )else:- # 新增模式 + 当天非第一次:只处理新增的新闻+ # 增量模式 + 当天非第一次:只处理新增的新闻results_to_process = new_titles if new_titles else {}- all_news_are_new = True # 处理的都是新增新闻- if new_titles:- total_new_count = sum(len(titles) for titles in new_titles.values())+ all_news_are_new = True+ elif mode == "current":+ # current 模式:只处理当前时间批次的新闻,但统计信息来自全部历史+ if title_info:+ latest_time = None+ for source_titles in title_info.values():+ for title_data in source_titles.values():+ last_time = title_data.get("last_time", "")+ if last_time:+ if latest_time is None or last_time > latest_time:+ latest_time = last_time++ # 只处理 last_time 等于最新时间的新闻+ if latest_time:+ results_to_process = {}+ for source_id, source_titles in results.items():+ if source_id in title_info:+ filtered_titles = {}+ for title, title_data in source_titles.items():+ if title in title_info[source_id]:+ info = title_info[source_id][title]+ if info.get("last_time") == latest_time:+ filtered_titles[title] = title_data+ if filtered_titles:+ results_to_process[source_id] = filtered_titles+print(- f"新增模式:检测到 {total_new_count} 条新增新闻,开始进行频率词匹配..."+ f"当前榜单模式:最新时间 {latest_time},筛选出 {sum(len(titles) for titles in results_to_process.values())} 条当前榜单新闻")else:- print("新增模式:未检测到新增新闻")+ results_to_process = results+ else:+ results_to_process = results+ all_news_are_new = Falseelse:- # 正常模式:处理所有新闻+ # 当日汇总模式:处理所有新闻results_to_process = resultsall_news_are_new = Falsetotal_input_news = sum(len(titles) for titles in results.values())- print(f"正常模式:处理 {total_input_news} 条新闻")+ print(f"当日汇总模式:处理 {total_input_news} 条新闻")word_stats = {}total_titles = 0@@ -855,15 +946,17 @@ class StatisticsCalculator:continue# 使用统一的匹配逻辑- matches_frequency_words = StatisticsCalculator._matches_word_groups(+ matches_frequency_words = StatisticsCalculator.matches_word_groups(title, word_groups, filter_words)if not matches_frequency_words:continue- # 如果是新增模式,统计匹配的新增新闻数量- if focus_new_only and all_news_are_new:+ # 如果是增量模式或 current 模式第一次,统计匹配的新增新闻数量+ if (mode == "incremental" and all_news_are_new) or (+ mode == "current" and is_first_today+ ):matched_new_count += 1source_ranks = title_data.get("ranks", [])@@ -905,7 +998,22 @@ class StatisticsCalculator:url = source_urlmobile_url = source_mobile_url+ # 对于 current 模式,从历史统计信息中获取完整数据if (+ mode == "current"+ and title_info+ and source_id in title_info+ and title in title_info[source_id]+ ):+ info = title_info[source_id][title]+ first_time = info.get("first_time", "")+ last_time = info.get("last_time", "")+ count_info = info.get("count", 1)+ if "ranks" in info and info["ranks"]:+ ranks = info["ranks"]+ url = info.get("url", source_url)+ mobile_url = info.get("mobileUrl", source_mobile_url)+ elif (title_infoand source_id in title_infoand title in title_info[source_id]@@ -926,30 +1034,22 @@ class StatisticsCalculator:first_time, last_time)- source_alias = id_to_alias.get(source_id, source_id)+ source_name = id_to_name.get(source_id, source_id)# 判断是否为新增is_new = Falseif all_news_are_new:- # 新增模式下所有处理的新闻都是新增,或者当天第一次的所有新闻都是新增+ # 增量模式下所有处理的新闻都是新增,或者当天第一次的所有新闻都是新增is_new = Trueelif new_titles and source_id in new_titles:- # 正常模式下,检查是否在新增列表中+ # 检查是否在新增列表中new_titles_for_source = new_titles[source_id]- if title in new_titles_for_source:- is_new = True- else:- # 如果直接匹配失败,尝试去除首尾空格后匹配- title_stripped = title.strip()- for new_title in new_titles_for_source.keys():- if title_stripped == new_title.strip():- is_new = True- break+ is_new = title in new_titles_for_sourceword_stats[group_key]["titles"][source_id].append({"title": title,- "source_alias": source_alias,+ "source_name": source_name,"first_time": first_time,"last_time": last_time,"time_display": time_display,@@ -967,20 +1067,36 @@ class StatisticsCalculator:processed_titles[source_id][title] = Truebreak- if focus_new_only and not is_first_today:- if new_titles:- total_new_count = sum(len(titles) for titles in new_titles.values())+ # 最后统一打印汇总信息+ if mode == "incremental":+ if is_first_today:+ total_input_news = sum(len(titles) for titles in results.values())print(- f"新增模式:{total_new_count} 条新增新闻中,有 {matched_new_count} 条匹配频率词"+ f"增量模式:当天第一次爬取,{total_input_news} 条新闻中有 {matched_new_count} 条匹配频率词")- if matched_new_count == 0:- print("新增模式:没有新增新闻匹配频率词,将不会发送通知")else:- print("新增模式:未检测到新增新闻")- elif focus_new_only and is_first_today:- print(- f"新增模式:当天第一次爬取,{matched_new_count} 条新闻匹配频率词并将推送"+ if new_titles:+ total_new_count = sum(len(titles) for titles in new_titles.values())+ print(+ f"增量模式:{total_new_count} 条新增新闻中,有 {matched_new_count} 条匹配频率词"+ )+ if matched_new_count == 0:+ print("增量模式:没有新增新闻匹配频率词,将不会发送通知")+ else:+ print("增量模式:未检测到新增新闻")+ elif mode == "current":+ total_input_news = sum(+ len(titles) for titles in results_to_process.values())+ if is_first_today:+ print(+ f"当前榜单模式:当天第一次爬取,{total_input_news} 条当前榜单新闻中有 {matched_new_count} 条匹配频率词"+ )+ else:+ matched_count = sum(stat["count"] for stat in word_stats.values())+ print(+ f"当前榜单模式:{total_input_news} 条当前榜单新闻中有 {matched_count} 条匹配频率词"+ )stats = []for group_key, data in word_stats.items():@@ -988,7 +1104,6 @@ class StatisticsCalculator:for source_id, title_list in data["titles"].items():all_titles.extend(title_list)- # 按权重排序标题sorted_titles = StatisticsCalculator.sort_titles_by_weight(all_titles, rank_threshold)@@ -1021,7 +1136,6 @@ class StatisticsCalculator:min_rank = unique_ranks[0]max_rank = unique_ranks[-1]- # 根据格式类型选择不同的标记方式if format_type == "html":highlight_start = "<font color='red'><strong>"highlight_end = "</strong></font>"@@ -1041,7 +1155,6 @@ class StatisticsCalculator:highlight_start = "**"highlight_end = "**"- # 格式化排名显示if min_rank <= rank_threshold:if min_rank == max_rank:return f"{highlight_start}[{min_rank}]{highlight_end}"@@ -1054,27 +1167,27 @@ class StatisticsCalculator:return f"[{min_rank} - {max_rank}]"@staticmethod- def _format_rank_for_html(ranks: List[int], rank_threshold: int = 5) -> str:+ def format_rank_for_html(ranks: List[int], rank_threshold: int = 5) -> str:"""格式化HTML排名显示"""return StatisticsCalculator._format_rank_base(ranks, rank_threshold, "html")@staticmethod- def _format_rank_for_feishu(ranks: List[int], rank_threshold: int = 5) -> str:+ def format_rank_for_feishu(ranks: List[int], rank_threshold: int = 5) -> str:"""格式化飞书排名显示"""return StatisticsCalculator._format_rank_base(ranks, rank_threshold, "feishu")@staticmethod- def _format_rank_for_dingtalk(ranks: List[int], rank_threshold: int = 5) -> str:+ def format_rank_for_dingtalk(ranks: List[int], rank_threshold: int = 5) -> str:"""格式化钉钉排名显示"""return StatisticsCalculator._format_rank_base(ranks, rank_threshold, "dingtalk")@staticmethod- def _format_rank_for_wework(ranks: List[int], rank_threshold: int = 5) -> str:+ def format_rank_for_wework(ranks: List[int], rank_threshold: int = 5) -> str:"""格式化企业微信排名显示"""return StatisticsCalculator._format_rank_base(ranks, rank_threshold, "wework")@staticmethod- def _format_rank_for_telegram(ranks: List[int], rank_threshold: int = 5) -> str:+ def format_rank_for_telegram(ranks: List[int], rank_threshold: int = 5) -> str:"""格式化Telegram排名显示"""return StatisticsCalculator._format_rank_base(ranks, rank_threshold, "telegram")@@ -1097,32 +1210,36 @@ class ReportGenerator:stats: List[Dict],total_titles: int,failed_ids: Optional[List] = None,- is_daily: bool = False,new_titles: Optional[Dict] = None,- id_to_alias: Optional[Dict] = None,+ id_to_name: Optional[Dict] = None,+ mode: str = "daily",+ is_daily_summary: bool = False,) -> str:"""生成HTML报告"""- if is_daily:- filename = "当日统计.html"+ if is_daily_summary:+ if mode == "current":+ filename = "当前榜单汇总.html"+ elif mode == "incremental":+ filename = "当日增量.html"+ else:+ filename = "当日汇总.html"else:filename = f"{TimeHelper.format_time_filename()}.html"file_path = FileHelper.get_output_path("html", filename)- # 数据处理层report_data = ReportGenerator._prepare_report_data(- stats, failed_ids, new_titles, id_to_alias+ stats, failed_ids, new_titles, id_to_name, mode)- # 渲染层html_content = ReportGenerator._render_html_content(- report_data, total_titles, is_daily+ report_data, total_titles, is_daily_summary, mode)with open(file_path, "w", encoding="utf-8") as f:f.write(html_content)- if is_daily:+ if is_daily_summary:root_file_path = Path("index.html")with open(root_file_path, "w", encoding="utf-8") as f:f.write(html_content)@@ -1134,16 +1251,19 @@ class ReportGenerator:stats: List[Dict],failed_ids: Optional[List] = None,new_titles: Optional[Dict] = None,- id_to_alias: Optional[Dict] = None,- hide_new_section: bool = False,+ id_to_name: Optional[Dict] = None,+ mode: str = "daily",) -> Dict:"""准备报告数据"""processed_new_titles = []+ # 在增量模式下隐藏新增新闻区域+ hide_new_section = mode == "incremental"+# 只有在非隐藏模式下才处理新增新闻部分if not hide_new_section:filtered_new_titles = {}- if new_titles and id_to_alias:+ if new_titles and id_to_name:word_groups, filter_words = DataProcessor.load_frequency_words()for source_id, titles_data in new_titles.items():filtered_titles = ReportGenerator._apply_frequency_filter(@@ -1152,9 +1272,9 @@ class ReportGenerator:if filtered_titles:filtered_new_titles[source_id] = filtered_titles- if filtered_new_titles and id_to_alias:+ if filtered_new_titles and id_to_name:for source_id, titles_data in filtered_new_titles.items():- source_alias = id_to_alias.get(source_id, source_id)+ source_name = id_to_name.get(source_id, source_id)source_titles = []for title, title_data in titles_data.items():@@ -1164,7 +1284,7 @@ class ReportGenerator:processed_title = {"title": title,- "source_alias": source_alias,+ "source_name": source_name,"time_display": "","count": 1,"ranks": ranks,@@ -1179,7 +1299,7 @@ class ReportGenerator:processed_new_titles.append({"source_id": source_id,- "source_alias": source_alias,+ "source_name": source_name,"titles": source_titles,})@@ -1193,7 +1313,7 @@ class ReportGenerator:for title_data in stat["titles"]:processed_title = {"title": title_data["title"],- "source_alias": title_data["source_alias"],+ "source_name": title_data["source_name"],"time_display": title_data["time_display"],"count": title_data["count"],"ranks": title_data["ranks"],@@ -1239,7 +1359,7 @@ class ReportGenerator:filtered_titles = {}for title, title_data in titles_data.items():- if StatisticsCalculator._matches_word_groups(+ if StatisticsCalculator.matches_word_groups(title, word_groups, filter_words):filtered_titles[title] = title_data@@ -1263,7 +1383,7 @@ class ReportGenerator:@staticmethoddef _format_title_html(title_data: Dict) -> str:"""格式化HTML标题显示"""- rank_display = StatisticsCalculator._format_rank_for_html(+ rank_display = StatisticsCalculator.format_rank_for_html(title_data["ranks"], title_data["rank_threshold"])@@ -1271,14 +1391,14 @@ class ReportGenerator:cleaned_title = DataProcessor.clean_title(title_data["title"])escaped_title = ReportGenerator._html_escape(cleaned_title)- escaped_source_alias = ReportGenerator._html_escape(title_data["source_alias"])+ escaped_source_name = ReportGenerator._html_escape(title_data["source_name"])if link_url:escaped_url = ReportGenerator._html_escape(link_url)- formatted_title = f'[{escaped_source_alias}] <a href="{escaped_url}" target="_blank" class="news-link">{escaped_title}</a>'+ formatted_title = f'[{escaped_source_name}] <a href="{escaped_url}" target="_blank" class="news-link">{escaped_title}</a>'else:formatted_title = (- f'[{escaped_source_alias}] <span class="no-link">{escaped_title}</span>'+ f'[{escaped_source_name}] <span class="no-link">{escaped_title}</span>')if rank_display:@@ -1296,7 +1416,10 @@ class ReportGenerator:@staticmethoddef _render_html_content(- report_data: Dict, total_titles: int, is_daily: bool = False+ report_data: Dict,+ total_titles: int,+ is_daily_summary: bool = False,+ mode: str = "daily",) -> str:"""渲染HTML内容"""html = """@@ -1357,14 +1480,20 @@ class ReportGenerator:<h1>频率词统计报告</h1>"""- if is_daily:- html += "<p>报告类型: 当日汇总</p>"+ if is_daily_summary:+ if mode == "current":+ html += "<p>报告类型: 当前榜单模式</p>"+ elif mode == "incremental":+ html += "<p>报告类型: 增量模式</p>"+ else:+ html += "<p>报告类型: 当日汇总</p>"+ else:+ html += "<p>报告类型: 实时分析</p>"now = TimeHelper.get_beijing_time()html += f"<p>总标题数: {total_titles}</p>"html += f"<p>生成时间: {now.strftime('%Y-%m-%d %H:%M:%S')}</p>"- # 渲染失败平台if report_data["failed_ids"]:html += """<div class="error">@@ -1378,7 +1507,6 @@ class ReportGenerator:</div>"""- # 渲染统计表格html += """<table><tr>@@ -1412,7 +1540,6 @@ class ReportGenerator:</table>"""- # 渲染新增新闻部分if report_data["new_titles"]:html += f"""<div class="new-section">@@ -1421,7 +1548,7 @@ class ReportGenerator:for source_data in report_data["new_titles"]:escaped_source = ReportGenerator._html_escape(- source_data["source_alias"]+ source_data["source_name"])html += (f"<h4>{escaped_source} ({len(source_data['titles'])} 条)</h4><ul>"@@ -1433,7 +1560,6 @@ class ReportGenerator:formatted_title = ReportGenerator._format_title_html(title_data_copy)- # 移除来源标签if "] " in formatted_title:formatted_title = formatted_title.split("] ", 1)[1]html += f"<li>{formatted_title}</li>"@@ -1452,7 +1578,7 @@ class ReportGenerator:@staticmethoddef _format_title_feishu(title_data: Dict, show_source: bool = True) -> str:"""格式化飞书标题显示"""- rank_display = StatisticsCalculator._format_rank_for_feishu(+ rank_display = StatisticsCalculator.format_rank_for_feishu(title_data["ranks"], title_data["rank_threshold"])@@ -1468,7 +1594,7 @@ class ReportGenerator:title_prefix = "🆕 " if title_data["is_new"] else ""if show_source:- result = f"<font color='grey'>[{title_data['source_alias']}]</font> {title_prefix}{formatted_title}"+ result = f"<font color='grey'>[{title_data['source_name']}]</font> {title_prefix}{formatted_title}"else:result = f"{title_prefix}{formatted_title}"@@ -1484,7 +1610,7 @@ class ReportGenerator:@staticmethoddef _format_title_dingtalk(title_data: Dict, show_source: bool = True) -> str:"""格式化钉钉标题显示"""- rank_display = StatisticsCalculator._format_rank_for_dingtalk(+ rank_display = StatisticsCalculator.format_rank_for_dingtalk(title_data["ranks"], title_data["rank_threshold"])@@ -1500,7 +1626,7 @@ class ReportGenerator:title_prefix = "🆕 " if title_data["is_new"] else ""if show_source:- result = f"[{title_data['source_alias']}] {title_prefix}{formatted_title}"+ result = f"[{title_data['source_name']}] {title_prefix}{formatted_title}"else:result = f"{title_prefix}{formatted_title}"@@ -1516,7 +1642,7 @@ class ReportGenerator:@staticmethoddef _format_title_wework(title_data: Dict, show_source: bool = True) -> str:"""格式化企业微信标题显示"""- rank_display = StatisticsCalculator._format_rank_for_wework(+ rank_display = StatisticsCalculator.format_rank_for_wework(title_data["ranks"], title_data["rank_threshold"])@@ -1532,7 +1658,7 @@ class ReportGenerator:title_prefix = "🆕 " if title_data["is_new"] else ""if show_source:- result = f"[{title_data['source_alias']}] {title_prefix}{formatted_title}"+ result = f"[{title_data['source_name']}] {title_prefix}{formatted_title}"else:result = f"{title_prefix}{formatted_title}"@@ -1548,7 +1674,7 @@ class ReportGenerator:@staticmethoddef _format_title_telegram(title_data: Dict, show_source: bool = True) -> str:"""格式化Telegram标题显示"""- rank_display = StatisticsCalculator._format_rank_for_telegram(+ rank_display = StatisticsCalculator.format_rank_for_telegram(title_data["ranks"], title_data["rank_threshold"])@@ -1564,7 +1690,7 @@ class ReportGenerator:title_prefix = "🆕 " if title_data["is_new"] else ""if show_source:- result = f"[{title_data['source_alias']}] {title_prefix}{formatted_title}"+ result = f"[{title_data['source_name']}] {title_prefix}{formatted_title}"else:result = f"{title_prefix}{formatted_title}"@@ -1579,14 +1705,13 @@ class ReportGenerator:@staticmethoddef _render_feishu_content(- report_data: Dict, update_info: Optional[Dict] = None+ report_data: Dict, update_info: Optional[Dict] = None, mode: str = "daily") -> str:"""渲染飞书内容"""text_content = ""- # 渲染热点词汇统计if report_data["stats"]:- text_content += "📊 **热点词汇统计**\n\n"+ text_content += f"📊 **热点词汇统计**\n\n"total_count = len(report_data["stats"])@@ -1616,9 +1741,14 @@ class ReportGenerator:text_content += f"\n{CONFIG['FEISHU_MESSAGE_SEPARATOR']}\n\n"if not text_content:- text_content = "📭 暂无匹配的热点词汇\n\n"+ if mode == "incremental":+ mode_text = "增量模式下暂无新增匹配的热点词汇"+ elif mode == "current":+ mode_text = "当前榜单模式下暂无匹配的热点词汇"+ else:+ mode_text = "暂无匹配的热点词汇"+ text_content = f"📭 {mode_text}\n\n"- # 渲染新增新闻部分if report_data["new_titles"]:if text_content and "暂无匹配" not in text_content:text_content += f"\n{CONFIG['FEISHU_MESSAGE_SEPARATOR']}\n\n"@@ -1628,7 +1758,7 @@ class ReportGenerator:)for source_data in report_data["new_titles"]:- text_content += f"**{source_data['source_alias']}** ({len(source_data['titles'])} 条):\n"+ text_content += f"**{source_data['source_name']}** ({len(source_data['titles'])} 条):\n"for j, title_data in enumerate(source_data["titles"], 1):title_data_copy = title_data.copy()@@ -1640,7 +1770,6 @@ class ReportGenerator:text_content += "\n"- # 渲染失败平台if report_data["failed_ids"]:if text_content and "暂无匹配" not in text_content:text_content += f"\n{CONFIG['FEISHU_MESSAGE_SEPARATOR']}\n\n"@@ -1649,11 +1778,9 @@ class ReportGenerator:for i, id_value in enumerate(report_data["failed_ids"], 1):text_content += f" • <font color='red'>{id_value}</font>\n"- # 添加时间戳now = TimeHelper.get_beijing_time()text_content += f"\n\n<font color='grey'>更新时间:{now.strftime('%Y-%m-%d %H:%M:%S')}</font>"- # 版本更新提示if update_info:text_content += f"\n<font color='grey'>TrendRadar 发现新版本 {update_info['remote_version']},当前 {update_info['current_version']}</font>"@@ -1661,27 +1788,24 @@ class ReportGenerator:@staticmethoddef _render_dingtalk_content(- report_data: Dict, update_info: Optional[Dict] = None+ report_data: Dict, update_info: Optional[Dict] = None, mode: str = "daily") -> str:"""渲染钉钉内容"""text_content = ""- # 计算总标题数total_titles = sum(len(stat["titles"]) for stat in report_data["stats"] if stat["count"] > 0)now = TimeHelper.get_beijing_time()- # 顶部统计信息text_content += f"**总新闻数:** {total_titles}\n\n"text_content += f"**时间:** {now.strftime('%Y-%m-%d %H:%M:%S')}\n\n"text_content += f"**类型:** 热点分析报告\n\n"text_content += "---\n\n"- # 渲染热点词汇统计if report_data["stats"]:- text_content += "📊 **热点词汇统计**\n\n"+ text_content += f"📊 **热点词汇统计**\n\n"total_count = len(report_data["stats"])@@ -1715,9 +1839,14 @@ class ReportGenerator:text_content += f"\n---\n\n"if not report_data["stats"]:- text_content += "📭 暂无匹配的热点词汇\n\n"+ if mode == "incremental":+ mode_text = "增量模式下暂无新增匹配的热点词汇"+ elif mode == "current":+ mode_text = "当前榜单模式下暂无匹配的热点词汇"+ else:+ mode_text = "暂无匹配的热点词汇"+ text_content += f"📭 {mode_text}\n\n"- # 渲染新增新闻部分if report_data["new_titles"]:if text_content and "暂无匹配" not in text_content:text_content += f"\n---\n\n"@@ -1727,7 +1856,7 @@ class ReportGenerator:)for source_data in report_data["new_titles"]:- text_content += f"**{source_data['source_alias']}** ({len(source_data['titles'])} 条):\n\n"+ text_content += f"**{source_data['source_name']}** ({len(source_data['titles'])} 条):\n\n"for j, title_data in enumerate(source_data["titles"], 1):title_data_copy = title_data.copy()@@ -1739,7 +1868,6 @@ class ReportGenerator:text_content += "\n"- # 渲染失败平台if report_data["failed_ids"]:if text_content and "暂无匹配" not in text_content:text_content += f"\n---\n\n"@@ -1748,10 +1876,8 @@ class ReportGenerator:for i, id_value in enumerate(report_data["failed_ids"], 1):text_content += f" • **{id_value}**\n"- # 添加时间戳text_content += f"\n\n> 更新时间:{now.strftime('%Y-%m-%d %H:%M:%S')}"- # 版本更新提示if update_info:text_content += f"\n> TrendRadar 发现新版本 **{update_info['remote_version']}**,当前 **{update_info['current_version']}**"@@ -1763,11 +1889,11 @@ class ReportGenerator:format_type: str,update_info: Optional[Dict] = None,max_bytes: int = CONFIG["MESSAGE_BATCH_SIZE"],+ mode: str = "daily",) -> List[str]:"""分批处理消息内容,确保词组标题+至少第一条新闻的完整性"""batches = []- # 基础信息构建total_titles = sum(len(stat["titles"]) for stat in report_data["stats"] if stat["count"] > 0)@@ -1792,20 +1918,25 @@ class ReportGenerator:stats_header = ""if report_data["stats"]:if format_type == "wework":- stats_header = "📊 **热点词汇统计**\n\n"+ stats_header = f"📊 **热点词汇统计**\n\n"elif format_type == "telegram":- stats_header = "📊 热点词汇统计\n\n"+ stats_header = f"📊 热点词汇统计\n\n"current_batch = base_headercurrent_batch_has_content = False- # 空内容处理if (not report_data["stats"]and not report_data["new_titles"]and not report_data["failed_ids"]):- simple_content = "📭 暂无匹配的热点词汇\n\n"+ if mode == "incremental":+ mode_text = "增量模式下暂无新增匹配的热点词汇"+ elif mode == "current":+ mode_text = "当前榜单模式下暂无匹配的热点词汇"+ else:+ mode_text = "暂无匹配的热点词汇"+ simple_content = f"📭 {mode_text}\n\n"final_content = base_header + simple_content + base_footerbatches.append(final_content)return batches@@ -1970,9 +2101,9 @@ class ReportGenerator:for source_data in report_data["new_titles"]:source_header = ""if format_type == "wework":- source_header = f"**{source_data['source_alias']}** ({len(source_data['titles'])} 条):\n\n"+ source_header = f"**{source_data['source_name']}** ({len(source_data['titles'])} 条):\n\n"elif format_type == "telegram":- source_header = f"{source_data['source_alias']} ({len(source_data['titles'])} 条):\n\n"+ source_header = f"{source_data['source_name']} ({len(source_data['titles'])} 条):\n\n"# 构建第一条新增新闻first_news_line = ""@@ -2049,7 +2180,6 @@ class ReportGenerator:current_batch += "\n"- # 处理失败平台if report_data["failed_ids"]:failed_header = ""if format_type == "wework":@@ -2095,55 +2225,62 @@ class ReportGenerator:def send_to_webhooks(stats: List[Dict],failed_ids: Optional[List] = None,- report_type: str = "单次爬取",+ report_type: str = "当日汇总",new_titles: Optional[Dict] = None,- id_to_alias: Optional[Dict] = None,+ id_to_name: Optional[Dict] = None,update_info: Optional[Dict] = None,proxy_url: Optional[str] = None,- hide_new_section: bool = False,+ mode: str = "daily",) -> Dict[str, bool]:"""发送数据到多个webhook平台"""results = {}- # 数据处理层report_data = ReportGenerator._prepare_report_data(- stats, failed_ids, new_titles, id_to_alias, hide_new_section+ stats, failed_ids, new_titles, id_to_name, mode)- # 获取环境变量中的webhook配置- feishu_url = os.environ.get("FEISHU_WEBHOOK_URL", CONFIG["FEISHU_WEBHOOK_URL"])- dingtalk_url = os.environ.get(- "DINGTALK_WEBHOOK_URL", CONFIG["DINGTALK_WEBHOOK_URL"]- )- wework_url = os.environ.get("WEWORK_WEBHOOK_URL", CONFIG["WEWORK_WEBHOOK_URL"])- telegram_token = os.environ.get(- "TELEGRAM_BOT_TOKEN", CONFIG["TELEGRAM_BOT_TOKEN"]- )- telegram_chat_id = os.environ.get(- "TELEGRAM_CHAT_ID", CONFIG["TELEGRAM_CHAT_ID"]- )+ feishu_url = CONFIG["FEISHU_WEBHOOK_URL"]+ dingtalk_url = CONFIG["DINGTALK_WEBHOOK_URL"]+ wework_url = CONFIG["WEWORK_WEBHOOK_URL"]+ telegram_token = CONFIG["TELEGRAM_BOT_TOKEN"]+ telegram_chat_id = CONFIG["TELEGRAM_CHAT_ID"]update_info_to_send = update_info if CONFIG["SHOW_VERSION_UPDATE"] else None# 发送到飞书if feishu_url:results["feishu"] = ReportGenerator._send_to_feishu(- feishu_url, report_data, report_type, update_info_to_send, proxy_url+ feishu_url,+ report_data,+ report_type,+ update_info_to_send,+ proxy_url,+ mode,)# 发送到钉钉if dingtalk_url:results["dingtalk"] = ReportGenerator._send_to_dingtalk(- dingtalk_url, report_data, report_type, update_info_to_send, proxy_url+ dingtalk_url,+ report_data,+ report_type,+ update_info_to_send,+ proxy_url,+ mode,)# 发送到企业微信if wework_url:results["wework"] = ReportGenerator._send_to_wework(- wework_url, report_data, report_type, update_info_to_send, proxy_url+ wework_url,+ report_data,+ report_type,+ update_info_to_send,+ proxy_url,+ mode,)- # 发送到Telegram+ # 发送到 Telegramif telegram_token and telegram_chat_id:results["telegram"] = ReportGenerator._send_to_telegram(telegram_token,@@ -2152,6 +2289,7 @@ class ReportGenerator:report_type,update_info_to_send,proxy_url,+ mode,)if not results:@@ -2166,11 +2304,14 @@ class ReportGenerator:report_type: str,update_info: Optional[Dict] = None,proxy_url: Optional[str] = None,+ mode: str = "daily",) -> bool:"""发送到飞书"""headers = {"Content-Type": "application/json"}- text_content = ReportGenerator._render_feishu_content(report_data, update_info)+ text_content = ReportGenerator._render_feishu_content(+ report_data, update_info, mode+ )total_titles = sum(len(stat["titles"]) for stat in report_data["stats"] if stat["count"] > 0)@@ -2213,12 +2354,13 @@ class ReportGenerator:report_type: str,update_info: Optional[Dict] = None,proxy_url: Optional[str] = None,+ mode: str = "daily",) -> bool:"""发送到钉钉"""headers = {"Content-Type": "application/json"}text_content = ReportGenerator._render_dingtalk_content(- report_data, update_info+ report_data, update_info, mode)payload = {@@ -2263,6 +2405,7 @@ class ReportGenerator:report_type: str,update_info: Optional[Dict] = None,proxy_url: Optional[str] = None,+ mode: str = "daily",) -> bool:"""发送到企业微信(支持分批发送)"""headers = {"Content-Type": "application/json"}@@ -2272,7 +2415,7 @@ class ReportGenerator:# 获取分批内容batches = ReportGenerator._split_content_into_batches(- report_data, "wework", update_info+ report_data, "wework", update_info, mode=mode)print(f"企业微信消息分为 {len(batches)} 批次发送 [{report_type}]")@@ -2335,6 +2478,7 @@ class ReportGenerator:report_type: str,update_info: Optional[Dict] = None,proxy_url: Optional[str] = None,+ mode: str = "daily",) -> bool:"""发送到Telegram(支持分批发送)"""headers = {"Content-Type": "application/json"}@@ -2346,7 +2490,7 @@ class ReportGenerator:# 获取分批内容batches = ReportGenerator._split_content_into_batches(- report_data, "telegram", update_info+ report_data, "telegram", update_info, mode=mode)print(f"Telegram消息分为 {len(batches)} 批次发送 [{report_type}]")@@ -2403,21 +2547,98 @@ class ReportGenerator:return True+@dataclass+class ModeStrategy:+ """模式策略配置"""++ mode_name: str+ description: str+ realtime_report_type: str+ summary_report_type: str+ should_send_realtime: bool+ should_generate_summary: bool+ summary_mode: str++ def get_log_messages(self) -> Dict[str, str]:+ """返回该模式的各种日志消息"""+ return {+ "mode_description": self.description,+ "realtime_skip": f"跳过实时推送通知:{self.mode_name}下未检测到匹配的新闻",+ "summary_skip": f"跳过{self.summary_report_type}通知:未匹配到有效的新闻内容",+ }++class NewsAnalyzer:"""新闻分析器"""+ MODE_STRATEGIES = {+ "incremental": ModeStrategy(+ mode_name="增量模式",+ description="增量模式(只关注新增新闻,无新增时不推送)",+ realtime_report_type="实时增量",+ summary_report_type="当日汇总",+ should_send_realtime=True,+ should_generate_summary=True,+ summary_mode="daily",+ ),+ "current": ModeStrategy(+ mode_name="当前榜单模式",+ description="当前榜单模式(当前榜单匹配新闻 + 新增新闻区域 + 按时推送)",+ realtime_report_type="实时当前榜单",+ summary_report_type="当前榜单汇总",+ should_send_realtime=True,+ should_generate_summary=True,+ summary_mode="current",+ ),+ "daily": ModeStrategy(+ mode_name="当日汇总模式",+ description="当日汇总模式(所有匹配新闻 + 新增新闻区域 + 按时推送)",+ realtime_report_type="",+ summary_report_type="当日汇总",+ should_send_realtime=False,+ should_generate_summary=True,+ summary_mode="daily",+ ),+ }+def __init__(self,request_interval: int = CONFIG["REQUEST_INTERVAL"],- report_type: str = CONFIG["REPORT_TYPE"],+ report_mode: str = CONFIG["REPORT_MODE"],rank_threshold: int = CONFIG["RANK_THRESHOLD"],):self.request_interval = request_interval- self.report_type = report_type+ self.report_mode = report_modeself.rank_threshold = rank_thresholdself.is_github_actions = os.environ.get("GITHUB_ACTIONS") == "true"+ self.is_docker_container = self._detect_docker_environment()self.update_info = Noneself.proxy_url = None+ self._setup_proxy()+ self.data_fetcher = DataFetcher(self.proxy_url)++ if self.is_github_actions:+ self._check_version_update()++ def _detect_docker_environment(self) -> bool:+ """检测是否运行在 Docker 容器中"""+ try:+ if os.environ.get("DOCKER_CONTAINER") == "true":+ return True++ if os.path.exists("/.dockerenv"):+ return True++ return False+ except Exception:+ return False++ def _should_open_browser(self) -> bool:+ """判断是否应该打开浏览器"""+ return not self.is_github_actions and not self.is_docker_container++ def _setup_proxy(self) -> None:+ """设置代理配置"""if not self.is_github_actions and CONFIG["USE_PROXY"]:self.proxy_url = CONFIG["DEFAULT_PROXY"]print("本地环境,使用代理")@@ -2426,11 +2647,6 @@ class NewsAnalyzer:else:print("GitHub Actions环境,不使用代理")- self.data_fetcher = DataFetcher(self.proxy_url)-- if self.is_github_actions:- self._check_version_update()-def _check_version_update(self) -> None:"""检查版本更新"""try:@@ -2449,106 +2665,251 @@ class NewsAnalyzer:except Exception as e:print(f"版本检查出错: {e}")+ def _get_mode_strategy(self) -> ModeStrategy:+ """获取当前模式的策略配置"""+ return self.MODE_STRATEGIES.get(self.report_mode, self.MODE_STRATEGIES["daily"])++ def _has_webhook_configured(self) -> bool:+ """检查是否配置了webhook"""+ return any(+ [+ CONFIG["FEISHU_WEBHOOK_URL"],+ CONFIG["DINGTALK_WEBHOOK_URL"],+ CONFIG["WEWORK_WEBHOOK_URL"],+ (CONFIG["TELEGRAM_BOT_TOKEN"] and CONFIG["TELEGRAM_CHAT_ID"]),+ ]+ )+def _has_valid_content(self, stats: List[Dict], new_titles: Optional[Dict] = None) -> bool:"""检查是否有有效的新闻内容"""- if CONFIG["FOCUS_NEW_ONLY"]:- # 新增模式下,只要stats有内容就说明有新增的匹配新闻+ if self.report_mode in ["incremental", "current"]:+ # 增量模式和current模式下,只要stats有内容就说明有匹配的新闻return any(stat["count"] > 0 for stat in stats)else:- # 正常模式下,检查是否有匹配的频率词新闻或新增新闻+ # 当日汇总模式下,检查是否有匹配的频率词新闻或新增新闻has_matched_news = any(stat["count"] > 0 for stat in stats)has_new_news = bool(new_titles and any(len(titles) > 0 for titles in new_titles.values()))return has_matched_news or has_new_news- def generate_daily_summary(self) -> Optional[str]:- """生成当日统计报告"""- print("生成当日统计报告...")+ def _load_analysis_data(+ self,+ ) -> Optional[Tuple[Dict, Dict, Dict, Dict, List, List]]:+ """统一的数据加载和预处理,使用当前监控平台列表过滤历史数据"""+ try:+ # 获取当前配置的监控平台ID列表+ current_platform_ids = []+ for platform in PLATFORMS:+ current_platform_ids.append(platform["id"])- all_results, id_to_alias, title_info = DataProcessor.read_all_today_titles()+ print(f"当前监控平台: {current_platform_ids}")- if not all_results:- print("没有找到当天的数据")+ all_results, id_to_name, title_info = DataProcessor.read_all_today_titles(+ current_platform_ids+ )++ if not all_results:+ print("没有找到当天的数据")+ return None++ total_titles = sum(len(titles) for titles in all_results.values())+ print(f"读取到 {total_titles} 个标题(已按当前监控平台过滤)")++ new_titles = DataProcessor.detect_latest_new_titles(current_platform_ids)+ word_groups, filter_words = DataProcessor.load_frequency_words()++ return (+ all_results,+ id_to_name,+ title_info,+ new_titles,+ word_groups,+ filter_words,+ )+ except Exception as e:+ print(f"数据加载失败: {e}")return None- total_titles = sum(len(titles) for titles in all_results.values())- print(f"读取到 {total_titles} 个标题")+ def _prepare_current_title_info(self, results: Dict, time_info: str) -> Dict:+ """从当前抓取结果构建标题信息"""+ title_info = {}+ for source_id, titles_data in results.items():+ title_info[source_id] = {}+ for title, title_data in titles_data.items():+ ranks = title_data.get("ranks", [])+ url = title_data.get("url", "")+ mobile_url = title_data.get("mobileUrl", "")- new_titles = DataProcessor.detect_latest_new_titles(id_to_alias)- word_groups, filter_words = DataProcessor.load_frequency_words()+ title_info[source_id][title] = {+ "first_time": time_info,+ "last_time": time_info,+ "count": 1,+ "ranks": ranks,+ "url": url,+ "mobileUrl": mobile_url,+ }+ return title_info++ def _run_analysis_pipeline(+ self,+ data_source: Dict,+ mode: str,+ title_info: Dict,+ new_titles: Dict,+ word_groups: List[Dict],+ filter_words: List[str],+ id_to_name: Dict,+ failed_ids: Optional[List] = None,+ is_daily_summary: bool = False,+ ) -> Tuple[List[Dict], str]:+ """统一的分析流水线:数据处理 → 统计计算 → HTML生成"""+ # 统计计算stats, total_titles = StatisticsCalculator.count_word_frequency(- all_results,+ data_source,word_groups,filter_words,- id_to_alias,+ id_to_name,title_info,self.rank_threshold,new_titles,- focus_new_only=CONFIG["FOCUS_NEW_ONLY"],+ mode=mode,)+ # HTML生成html_file = ReportGenerator.generate_html_report(stats,total_titles,- is_daily=True,+ failed_ids=failed_ids,new_titles=new_titles,- id_to_alias=id_to_alias,+ id_to_name=id_to_name,+ mode=mode,+ is_daily_summary=is_daily_summary,)- print(f"当日HTML统计报告已生成: {html_file}")- # 检查通知配置- has_webhook = any(- [- os.environ.get("FEISHU_WEBHOOK_URL", CONFIG["FEISHU_WEBHOOK_URL"]),- os.environ.get("DINGTALK_WEBHOOK_URL", CONFIG["DINGTALK_WEBHOOK_URL"]),- os.environ.get("WEWORK_WEBHOOK_URL", CONFIG["WEWORK_WEBHOOK_URL"]),- (- os.environ.get("TELEGRAM_BOT_TOKEN", CONFIG["TELEGRAM_BOT_TOKEN"])- and os.environ.get("TELEGRAM_CHAT_ID", CONFIG["TELEGRAM_CHAT_ID"])- ),- ]- )+ return stats, html_file++ def _send_notification_if_needed(+ self,+ stats: List[Dict],+ report_type: str,+ mode: str,+ failed_ids: Optional[List] = None,+ new_titles: Optional[Dict] = None,+ id_to_name: Optional[Dict] = None,+ ) -> bool:+ """统一的通知发送逻辑,包含所有判断条件"""+ has_webhook = self._has_webhook_configured()if (CONFIG["ENABLE_NOTIFICATION"]and has_webhook- and self.report_type in ["daily", "both"]and self._has_valid_content(stats, new_titles)):- hide_new_section = CONFIG["FOCUS_NEW_ONLY"]-ReportGenerator.send_to_webhooks(stats,- [],- "当日汇总",+ failed_ids or [],+ report_type,new_titles,- id_to_alias,+ id_to_name,self.update_info,self.proxy_url,- hide_new_section=hide_new_section,+ mode=mode,)+ return Trueelif CONFIG["ENABLE_NOTIFICATION"] and not has_webhook:print("⚠️ 警告:通知功能已启用但未配置webhook URL,将跳过通知发送")elif not CONFIG["ENABLE_NOTIFICATION"]:- print("跳过当日汇总通知:通知功能已禁用")+ print(f"跳过{report_type}通知:通知功能已禁用")elif (CONFIG["ENABLE_NOTIFICATION"]and has_webhookand not self._has_valid_content(stats, new_titles)):- if CONFIG["FOCUS_NEW_ONLY"]:- print("跳过当日汇总通知:新增模式下未检测到匹配的新增新闻")+ mode_strategy = self._get_mode_strategy()+ log_messages = mode_strategy.get_log_messages()+ if "实时" in report_type:+ print(log_messages["realtime_skip"])else:- print("跳过当日汇总通知:未匹配到有效的新闻内容")+ print(log_messages["summary_skip"])++ return False++ def _generate_summary_report(self, mode_strategy: ModeStrategy) -> Optional[str]:+ """生成汇总报告(带通知)"""+ summary_type = (+ "当前榜单汇总" if mode_strategy.summary_mode == "current" else "当日汇总"+ )+ print(f"生成{summary_type}报告...")++ # 加载分析数据+ analysis_data = self._load_analysis_data()+ if not analysis_data:+ return None++ all_results, id_to_name, title_info, new_titles, word_groups, filter_words = (+ analysis_data+ )++ # 运行分析流水线+ stats, html_file = self._run_analysis_pipeline(+ all_results,+ mode_strategy.summary_mode,+ title_info,+ new_titles,+ word_groups,+ filter_words,+ id_to_name,+ is_daily_summary=True,+ )++ print(f"{summary_type}报告已生成: {html_file}")++ # 发送通知+ self._send_notification_if_needed(+ stats,+ mode_strategy.summary_report_type,+ mode_strategy.summary_mode,+ new_titles=new_titles,+ id_to_name=id_to_name,+ )return html_file- def run(self) -> None:- """执行分析流程"""+ def _generate_summary_html(self, mode: str = "daily") -> Optional[str]:+ """生成汇总HTML"""+ summary_type = "当前榜单汇总" if mode == "current" else "当日汇总"+ print(f"生成{summary_type}HTML...")++ # 加载分析数据+ analysis_data = self._load_analysis_data()+ if not analysis_data:+ return None++ all_results, id_to_name, title_info, new_titles, word_groups, filter_words = (+ analysis_data+ )++ # 运行分析流水线+ _, html_file = self._run_analysis_pipeline(+ all_results,+ mode,+ title_info,+ new_titles,+ word_groups,+ filter_words,+ id_to_name,+ is_daily_summary=True,+ )++ print(f"{summary_type}HTML已生成: {html_file}")+ return html_file++ def _initialize_and_check_config(self) -> None:+ """通用初始化和配置检查"""now = TimeHelper.get_beijing_time()print(f"当前北京时间: {now.strftime('%Y-%m-%d %H:%M:%S')}")@@ -2556,20 +2917,7 @@ class NewsAnalyzer:print("爬虫功能已禁用(ENABLE_CRAWLER=False),程序退出")return- # 检查是否配置了任何webhook URL- has_webhook = any(- [- os.environ.get("FEISHU_WEBHOOK_URL", CONFIG["FEISHU_WEBHOOK_URL"]),- os.environ.get("DINGTALK_WEBHOOK_URL", CONFIG["DINGTALK_WEBHOOK_URL"]),- os.environ.get("WEWORK_WEBHOOK_URL", CONFIG["WEWORK_WEBHOOK_URL"]),- (- os.environ.get("TELEGRAM_BOT_TOKEN", CONFIG["TELEGRAM_BOT_TOKEN"])- and os.environ.get("TELEGRAM_CHAT_ID", CONFIG["TELEGRAM_CHAT_ID"])- ),- ]- )-- # 通知功能状态检查和提示+ has_webhook = self._has_webhook_configured()if not CONFIG["ENABLE_NOTIFICATION"]:print("通知功能已禁用(ENABLE_NOTIFICATION=False),将只进行数据抓取")elif not has_webhook:@@ -2577,129 +2925,183 @@ class NewsAnalyzer:else:print("通知功能已启用,将发送webhook通知")- print(f"报告类型: {self.report_type}")+ mode_strategy = self._get_mode_strategy()+ print(f"报告模式: {self.report_mode}")+ print(f"运行模式: {mode_strategy.description}")- if CONFIG["FOCUS_NEW_ONLY"]:- print("运行模式: 新增检测模式(只关注新增新闻)")- else:- print("运行模式: 正常模式(频率词统计 + 新增检测)")-- ids = [- ("toutiao", "今日头条"),- ("baidu", "百度热搜"),- ("wallstreetcn-hot", "华尔街见闻"),- ("thepaper", "澎湃新闻"),- ("bilibili-hot-search", "bilibili 热搜"),- ("cls-hot", "财联社热门"),- ("ifeng", "凤凰网"),- "tieba",- "weibo",- "douyin",- "zhihu",- ]+ def _crawl_data(self) -> Tuple[Dict, Dict, List]:+ """执行数据爬取"""+ ids = []+ for platform in PLATFORMS:+ if "name" in platform:+ ids.append((platform["id"], platform["name"]))+ else:+ ids.append(platform["id"])+ print(f"配置的监控平台: {[p.get('name', p['id']) for p in PLATFORMS]}")print(f"开始爬取数据,请求间隔 {self.request_interval} 毫秒")FileHelper.ensure_directory_exists("output")- results, id_to_alias, failed_ids = self.data_fetcher.crawl_websites(+ results, id_to_name, failed_ids = self.data_fetcher.crawl_websites(ids, self.request_interval)- title_file = DataProcessor.save_titles_to_file(results, id_to_alias, failed_ids)+ title_file = DataProcessor.save_titles_to_file(results, id_to_name, failed_ids)print(f"标题已保存到: {title_file}")- new_titles = DataProcessor.detect_latest_new_titles(id_to_alias)+ return results, id_to_name, failed_ids- # 构建标题信息- time_info = Path(title_file).stem- title_info = {}- for source_id, titles_data in results.items():- title_info[source_id] = {}- for title, title_data in titles_data.items():- ranks = title_data.get("ranks", [])- url = title_data.get("url", "")- mobile_url = title_data.get("mobileUrl", "")+ def _execute_mode_strategy(+ self,+ mode_strategy: ModeStrategy,+ results: Dict,+ id_to_name: Dict,+ failed_ids: List,+ ) -> Optional[str]:+ """执行模式特定逻辑"""+ # 获取当前监控平台ID列表+ current_platform_ids = [platform["id"] for platform in PLATFORMS]++ new_titles = DataProcessor.detect_latest_new_titles(current_platform_ids)+ time_info = Path(+ DataProcessor.save_titles_to_file(results, id_to_name, failed_ids)+ ).stem+ word_groups, filter_words = DataProcessor.load_frequency_words()- title_info[source_id][title] = {- "first_time": time_info,- "last_time": time_info,- "count": 1,- "ranks": ranks,- "url": url,- "mobileUrl": mobile_url,- }+ # current模式下,实时推送需要使用完整的历史数据来保证统计信息的完整性+ if self.report_mode == "current":+ # 加载完整的历史数据(已按当前平台过滤)+ analysis_data = self._load_analysis_data()+ if analysis_data:+ (+ all_results,+ historical_id_to_name,+ historical_title_info,+ historical_new_titles,+ _,+ _,+ ) = analysis_data- word_groups, filter_words = DataProcessor.load_frequency_words()+ print(+ f"current模式:使用过滤后的历史数据,包含平台:{list(all_results.keys())}"+ )- stats, total_titles = StatisticsCalculator.count_word_frequency(- results,- word_groups,- filter_words,- id_to_alias,- title_info,- self.rank_threshold,- new_titles,- focus_new_only=CONFIG["FOCUS_NEW_ONLY"],- )+ stats, html_file = self._run_analysis_pipeline(+ all_results,+ self.report_mode,+ historical_title_info,+ historical_new_titles,+ word_groups,+ filter_words,+ historical_id_to_name,+ failed_ids=failed_ids,+ )- # 只有启用通知且配置了webhook且有有效内容时才发送通知- if (- CONFIG["ENABLE_NOTIFICATION"]- and has_webhook- and self.report_type in ["current", "both"]- and self._has_valid_content(stats, new_titles)- ):- hide_new_section = CONFIG["FOCUS_NEW_ONLY"]+ combined_id_to_name = {**historical_id_to_name, **id_to_name}- ReportGenerator.send_to_webhooks(- stats,- failed_ids,- "单次爬取",+ print(f"HTML报告已生成: {html_file}")++ # 发送实时通知(使用完整历史数据的统计结果)+ summary_html = None+ if mode_strategy.should_send_realtime:+ self._send_notification_if_needed(+ stats,+ mode_strategy.realtime_report_type,+ self.report_mode,+ failed_ids=failed_ids,+ new_titles=historical_new_titles,+ id_to_name=combined_id_to_name,+ )+ else:+ print("❌ 严重错误:无法读取刚保存的数据文件")+ raise RuntimeError("数据一致性检查失败:保存后立即读取失败")+ else:+ title_info = self._prepare_current_title_info(results, time_info)+ stats, html_file = self._run_analysis_pipeline(+ results,+ self.report_mode,+ title_info,new_titles,- id_to_alias,- self.update_info,- self.proxy_url,- hide_new_section=hide_new_section,+ word_groups,+ filter_words,+ id_to_name,+ failed_ids=failed_ids,)- elif CONFIG["ENABLE_NOTIFICATION"] and not has_webhook:- print("⚠️ 警告:通知功能已启用但未配置webhook URL,将跳过通知发送")- elif not CONFIG["ENABLE_NOTIFICATION"]:- print("跳过单次爬取通知:通知功能已禁用")- elif (- CONFIG["ENABLE_NOTIFICATION"]- and has_webhook- and not self._has_valid_content(stats, new_titles)- ):- if CONFIG["FOCUS_NEW_ONLY"]:- print("跳过单次爬取通知:新增模式下未检测到匹配的新增新闻")+ print(f"HTML报告已生成: {html_file}")++ # 发送实时通知(如果需要)+ summary_html = None+ if mode_strategy.should_send_realtime:+ self._send_notification_if_needed(+ stats,+ mode_strategy.realtime_report_type,+ self.report_mode,+ failed_ids=failed_ids,+ new_titles=new_titles,+ id_to_name=id_to_name,+ )++ # 生成汇总报告(如果需要)+ summary_html = None+ if mode_strategy.should_generate_summary:+ if mode_strategy.should_send_realtime:+ # 如果已经发送了实时通知,汇总只生成HTML不发送通知+ summary_html = self._generate_summary_html(mode_strategy.summary_mode)+ else:+ # daily模式:直接生成汇总报告并发送通知+ summary_html = self._generate_summary_report(mode_strategy)++ # 打开浏览器(仅在非容器环境)+ if self._should_open_browser() and html_file:+ if summary_html:+ summary_url = "file://" + str(Path(summary_html).resolve())+ print(f"正在打开汇总报告: {summary_url}")+ webbrowser.open(summary_url)+ else:+ file_url = "file://" + str(Path(html_file).resolve())+ print(f"正在打开HTML报告: {file_url}")+ webbrowser.open(file_url)+ elif self.is_docker_container and html_file:+ if summary_html:+ print(f"汇总报告已生成(Docker环境): {summary_html}")else:- print("跳过单次爬取通知:未匹配到有效的新闻内容")+ print(f"HTML报告已生成(Docker环境): {html_file}")- html_file = ReportGenerator.generate_html_report(- stats, total_titles, failed_ids, False, new_titles, id_to_alias- )- print(f"HTML报告已生成: {html_file}")+ return summary_html- daily_html = self.generate_daily_summary()+ def run(self) -> None:+ """执行分析流程"""+ try:+ self._initialize_and_check_config()- if not self.is_github_actions and html_file:- file_url = "file://" + str(Path(html_file).resolve())- print(f"正在打开HTML报告: {file_url}")- webbrowser.open(file_url)+ mode_strategy = self._get_mode_strategy()- if daily_html:- daily_url = "file://" + str(Path(daily_html).resolve())- print(f"正在打开当日统计报告: {daily_url}")- webbrowser.open(daily_url)+ results, id_to_name, failed_ids = self._crawl_data()++ self._execute_mode_strategy(mode_strategy, results, id_to_name, failed_ids)++ except Exception as e:+ print(f"分析流程执行出错: {e}")+ raisedef main():- analyzer = NewsAnalyzer(- request_interval=CONFIG["REQUEST_INTERVAL"],- report_type=CONFIG["REPORT_TYPE"],- rank_threshold=CONFIG["RANK_THRESHOLD"],- )- analyzer.run()+ try:+ analyzer = NewsAnalyzer(+ request_interval=CONFIG["REQUEST_INTERVAL"],+ report_mode=CONFIG["REPORT_MODE"],+ rank_threshold=CONFIG["RANK_THRESHOLD"],+ )+ analyzer.run()+ except FileNotFoundError as e:+ print(f"❌ 配置文件错误: {e}")+ print("\n请确保以下文件存在:")+ print(" • config/config.yaml")+ print(" • config/frequency_words.txt")+ print("\n参考项目文档进行正确配置")+ except Exception as e:+ print(f"❌ 程序运行错误: {e}")+ raiseif __name__ == "__main__":diff --git a/readme.md b/readme.mdindex 4d6e965e1e..9d6ab25010 100644--- a/readme.md+++ b/readme.md@@ -1,6 +1,6 @@<div align="center">-# 🎯 TrendRadar+# 🎯TrendRadar**你的专属热点助手 —— 让手机只推送你真正关心的新闻**@@ -10,7 +10,7 @@[](https://github.com/sansan0/TrendRadar/network/members)[](LICENSE)[](https://www.python.org/)-[](https://github.com/sansan0/TrendRadar)+[](https://github.com/sansan0/TrendRadar)[](https://work.weixin.qq.com/)[](https://telegram.org/)@@ -18,34 +18,50 @@[](https://www.feishu.cn/)[](https://github.com/sansan0/TrendRadar)[](https://sansan0.github.io/TrendRadar)+[](https://hub.docker.com/)</div>----> 如果本项目对你有所帮助,**点个 Star ⭐** 就是对我最大的支持。>-> 遇到问题可以直接提 issues,我会认真回复每一个。也可以关注【硅基茶水间】公众号,那里我会分享开源项目的思路和经验。->-> 我从 2025 年 4 月末开始经常开源项目,之前一直各种使用其他大佬的开源项目,虽然也勤于 star, 但确实更多的是在"白嫖"。现在想通过自己的项目回馈开源社区,同时记录这个过程中的收获和思考。->-> 本账号专门用来维护开源项目。如果你也在做开源,或者对开源感兴趣,**欢迎一起交流**。+> 遇到问题可以直接提 issues。也可以【硅基茶水间】公众号留言问题。+----## ✨ 核心功能### **全网热点聚合**-一次监控 11+ 个主流平台(微博、知乎、抖音、百度等),再也不用逐个 APP 刷新闻)+默认监控 11 个主流平台++- 今日头条+- 百度热搜+- 华尔街见闻+- 澎湃新闻+- bilibili 热搜+- 财联社热门+- 凤凰网+- 贴吧+- 微博+- 抖音+- 知乎-> _理论上支持 35 个左右的平台,我默认只放了 11 个,想增加什么股票等金融相关资讯的,需要你自己手动添加,有需求的看最下方的**高级用法**_+> _理论上支持 35 个左右,如果你想增加额外的金融类等相关资讯推送,可看最下方的**自定义监控平台**_### **智能推送策略**-提供两种工作模式满足不同需求:**默认模式**持续追踪热点排名变化、出现频次和时间跨度,定时推送完整分析报告(也包括新增热点);**增量模式**仅检测新增热点,无新内容时不推送,避免信息噪音+提供三种工作模式满足不同需求:-> _默认模式适合全面了解热点趋势,增量模式适合高频监控(≤30 分钟)场景,专注最新动态而非持续热度_+| 模式 | 推送时机 | 显示内容 | 适用场景 |+|------|----------|----------|----------|+| **当日汇总模式**<br/>`daily` | 按时推送 | 当日所有匹配新闻<br/>+ 新增新闻区域 | 日报总结<br/>全面了解当日热点趋势 |+| **当前榜单模式**<br/>`current` | 按时推送 | 当前榜单匹配新闻<br/>+ 新增新闻区域 | 实时热点追踪<br/>了解当前最火的内容 |+| **增量监控模式**<br/>`incremental` | 有新增才推送 | 新出现的匹配频率词新闻 | 避免重复信息干扰<br/>高频监控场景 |++- **📈 投资者/交易员** → 选择 `incremental`,及时获取新增资讯(建议自建服务器进行 docker 部署,提高检测频率)+- **📰 自媒体人/内容创作者** → 选择 `current`,掌握实时热点趋势+- **📋 企业管理者/普通用户** → 选择 `daily`,定时获取完整日报### **精准内容筛选**@@ -59,9 +75,9 @@### **零技术门槛部署**-GitHub 一键 Fork 即可使用,无需服务器,无需编程基础。如果要手机接收通知, 要达到 1 分钟部署完毕的效果,请选择**企业微信**+GitHub 一键 Fork 即可使用,无需编程基础。-> _就,很快_+> _如果要手机接收通知, 要达到 1 分钟部署完毕的效果,请选择**企业微信**_### **减少 APP 依赖**@@ -73,7 +89,7 @@ GitHub 一键 Fork 即可使用,无需服务器,无需编程基础。如果**典型场景:** 股市投资监控、品牌舆情追踪、行业动态关注、生活资讯获取-**💡 提示:** 想要网页版?启用 GitHub Pages 即可获得自动更新的新闻页面。进入你的仓库 Settings → Pages,启用后就能获得专属链接,比如我这里[TrendRadar](https://sansan0.github.io/TrendRadar/)。+**💡 提示:** 想要网页版?进入你的仓库 Settings → Pages,启用 GitHub Pages 即可获得自动更新的新闻页面链接。比如我这里[TrendRadar](https://sansan0.github.io/TrendRadar/)。<p align="center"><img src="_image/2025-06-14.jpg" alt="最新推送效果" width="400"/>@@ -81,7 +97,24 @@ GitHub 一键 Fork 即可使用,无需服务器,无需编程基础。如果## 📝 更新日志-**升级说明:** 已**fork**的同学,如果想获得最新功能:只需把本项目中 main.py 的所有代码替换掉你的旧代码即可(直接 GitHub 网页上编辑)。+**升级说明:**+- **小版本更新**:直接在 GitHub 网页编辑器中,用本项目的 `main.py` 代码替换你 fork 仓库中的对应文件+- **大版本升级**:从 v1.x 升级到 v2.0 建议删除现有 fork 后重新 fork,这样更省力且避免配置冲突++### 2025/07/17 - v2.0.0++**重大重构**:+- 配置管理重构:所有配置现在通过 `config/config.yaml` 文件管理(main.py 我依旧没拆分,方便你们复制升级)+- 运行模式升级:支持三种模式 - `daily`(当日汇总)、`current`(当前榜单)、`incremental`(增量监控)+- Docker 支持:完整的 Docker 部署方案,支持容器化运行++**配置文件说明**:+- `config/config.yaml` - 主配置文件(应用设置、爬虫配置、通知配置、平台配置等)+- `config/frequency_words.txt` - 关键词配置(监控词汇设置)+++<details>+<summary><strong>📝 点击查看历史更新</strong></summary>### 2025/07/09 - v1.4.1@@ -89,9 +122,6 @@ GitHub 一键 Fork 即可使用,无需服务器,无需编程基础。如果**修复问题**: 某些情况下,由于新闻本身含有特殊符号导致的偶发性排版异常。-<details>-<summary><strong>📝 查看历史更新</strong></summary>-### 2025/06/23 - v1.3.0企业微信 和 Telegram 的推送消息有长度限制,对此我采用将消息拆分推送的方式。开发文档详见[企业微信](https://developer.work.weixin.qq.com/document/path/91770) 和 [Telegram](https://core.telegram.org/bots/api)@@ -168,21 +198,6 @@ frequency_words.txt 文件增加了一个【必须词】功能,使用 + 号</details>-## 🔍 支持的平台--目前已支持以下 11 个热门平台:--- 今日头条-- 百度热搜-- 华尔街见闻-- 澎湃新闻-- bilibili 热搜-- 财联社热门-- 凤凰网-- 贴吧-- 微博-- 抖音-- 知乎## 🚀 使用方式@@ -286,7 +301,7 @@ frequency_words.txt 文件增加了一个【必须词】功能,使用 + 号</details><details>- <summary>🟣 <strong>Telegram Bot</strong>(配置最复杂)</summary>+ <summary>🟣 <strong>Telegram Bot</strong></summary>**GitHub Secret 配置:**- 名称:`TELEGRAM_BOT_TOKEN` - 你的 Telegram Bot Token@@ -316,12 +331,16 @@ frequency_words.txt 文件增加了一个【必须词】功能,使用 + 号- `TELEGRAM_CHAT_ID`:填入第 2 步获得的 Chat ID</details>-3. **自定义关键词**:+3. **配置关键词和设置**:- - 修改`frequency_words.txt`文件,添加你关心的关键词+ - **关键词配置**: 修改 `config/frequency_words.txt` 文件,添加你关心的关键词+ - **运行模式配置**: 在 `config/config.yaml` 中修改 `report.mode` 设置:+ - `"daily"` - 当日汇总模式(默认)+ - `"current"` - 当前榜单模式+ - `"incremental"` - 增量监控模式<details>- <summary><strong>⚙️ 点击查看 frequency_words.txt 完整配置教程</strong></summary>+ <summary><strong>⚙️ 点击查看 frequency_words.txt 配置教程</strong></summary>在 `frequency_words.txt` 文件中配置监控的关键词,支持三种语法和词组功能。@@ -472,7 +491,7 @@ frequency_words.txt 文件增加了一个【必须词】功能,使用 + 号4. **自动运行**:- - 项目已包含`.github/workflows/crawler.yml`配置文件,默认每 50 分钟自动运行一次+ - 项目已包含`.github/workflows/crawler.yml`配置文件,默认每 30 分钟自动运行一次- 你也可以在 GitHub 仓库的 Actions 页面手动触发运行5. **查看结果**:@@ -508,64 +527,128 @@ frequency_words.txt 文件增加了一个【必须词】功能,使用 + 号| [时间 ~ 时间] | [12 时 30 分 ~ 14 时 00 分] | 时间范围 | 标题出现的时间范围(首次~最后) || (N 次) | (4 次) | 出现次数 | 标题在监控期间出现的总次数 |-## 🔧 高级用法--### 自定义监控平台--本项目的数据来源于 [newsnow](https://github.com/ourongxing/newsnow) 项目,你可以点击[这个网站](https://newsnow.busiyi.world/),点击里面的【更多】,可以看到所有支持的平台。如果你想支持更多平台或者不想看某些平台,可以访问 https://github.com/ourongxing/newsnow/tree/main/server/sources ,根据里面的文件名来调整 main.py 中的下面代码(如果不懂怎么看这些代码,也可以去我公众号留言):--```python-ids = [- ("toutiao", "今日头条"),- ("baidu", "百度热搜"),- ("wallstreetcn-hot", "华尔街见闻"),- ("thepaper", "澎湃新闻"),- ("bilibili-hot-search", "bilibili 热搜"),- ("cls-hot", "财联社热门"),- ("ifeng", "凤凰网"),- "tieba",- "weibo",- "douyin",- "zhihu",-]++### 🔧 自定义监控平台++本项目的资讯数据来源于 [newsnow](https://github.com/ourongxing/newsnow) ,你可以点击[网站](https://newsnow.busiyi.world/),点击[更多],查看是否有你想要的平台。++具体添加可访问 [项目源代码](https://github.com/ourongxing/newsnow/tree/main/server/sources),根据里面的文件名,在 `config/config.yaml` 文件中修改 `platforms` 配置:++```yaml+platforms:+ - id: "toutiao"+ name: "今日头条"+ - id: "baidu"+ name: "百度热搜"+ - id: "wallstreetcn-hot"+ name: "华尔街见闻"+ # 添加更多平台...```-## ❓ 常见问题+### 🐳 Docker 部署-1. **GitHub Actions 不执行怎么办?**+1. **克隆项目并进入目录**:+ ```bash+ git clone https://github.com/sansan0/TrendRadar.git+ cd TrendRadar+ ```- - 检查`.github/workflows/crawler.yml`文件是否存在- - 在 Actions 页面手动触发一次 workflow- - 确认你有足够的 GitHub Actions 免费分钟数+2. **配置文件**:+ - 修改 `config/config.yaml` 和 `config/frequency_words.txt`+ - **推送链接填写**,**设置推送定时**可通过 .env 进行配置-2. **没有收到飞书通知怎么办?**+3. **启动服务**:+ ```bash+ cd docker+ docker-compose up -d+ ```- - 检查`FEISHU_WEBHOOK_URL`是否正确设置(环境变量或 CONFIG 中)- - 检查飞书机器人是否仍在群内且启用- - 查看程序输出中是否有发送失败的错误信息- - 确认飞书流程配置中的参数结构正确+4. **管理服务**:+ ```bash+ # 查看运行状态+ docker exec -it trend-radar python manage.py status++ # 手动执行一次爬虫+ docker exec -it trend-radar python manage.py run++ # 查看实时日志+ docker exec -it trend-radar python manage.py logs++ # 显示当前配置+ docker exec -it trend-radar python manage.py config++ # 显示输出文件+ docker exec -it trend-radar python manage.py files++ # 重启定时服务+ docker exec -it trend-radar python manage.py restart++ # 显示帮助信息+ docker exec -it trend-radar python manage.py help+ ```-3. **想要停止手机接收新闻通知消息?**- - 将`ENABLE_NOTIFICATION`设置为`False`+## ☕ 赞助让代码更香.jpg-4. **想要停止在本地继续生成新闻数据?**+<div align="center">- - 将`ENABLE_CRAWLER`设置为`False`+| Wechat | Alipay |+|:---:|:---:|+| <img src="https://cdn-1258574687.cos.ap-shanghai.myqcloud.com/img/%2F2025%2F07%2F17%2F2ae0a88d98079f7e876c2b4dc85233c6-9e8025.JPG" width="300" title="微信支付"/> | <img src="https://cdn-1258574687.cos.ap-shanghai.myqcloud.com/img/%2F2025%2F07%2F17%2Fed4f20ab8e35be51f8e84c94e6e239b4-fe4947.JPG" width="300" title="支付宝支付"/> |-## 📧 学习交流+</div>-扫码关注微信公众号,里面有文章是讲我写的这些项目的,咳如果对你有了点帮助,献上【点赞,转发,推荐】三连,就算支持了俺这个作者的开发了,顺便也可以反馈使用问题:++## 📧 学习交流<div align="center">-+<img src="_image/support.jpg" title="硅基茶水间留言"/>+<br>+<img src="_image/weixin.png" width="600" title="硅基茶水间"/></div>--## Star History+```mermaid+flowchart TD+ A[👤 用户开始] --> B[🍴 Fork 项目]+ B --> C[⚙️ 选择通知方式]++ C --> D1[📱 企业微信群机器人<br/>最简单快速]+ C --> D2[💬 飞书机器人<br/>显示效果最佳]+ C --> D3[🔔 钉钉机器人<br/>]+ C --> D4[📟 Telegram Bot<br/>]++ D1 --> E[🔑 配置 GitHub Secrets<br/>填入机器人 Webhook 地址]+ D2 --> E+ D3 --> E+ D4 --> E++ E --> F[📝 编辑关键词配置<br/>config/frequency_words.txt<br/>添加你关心的词汇]+ F --> G[🎯 选择运行模式<br/>config/config.yaml<br/>daily/current/incremental]++ G --> H[✅ 配置完成]+ H --> I[🤖 系统每30分钟自动运行]++ I --> J[📊 爬取各大平台热点]+ J --> K[🔍 根据关键词筛选]+ K --> L[📱 推送到你的手机]++ L --> M[📈 查看推送结果]+ M --> N{满意效果?}+ N -->|不满意| F+ N -->|满意| O[🎉 持续接收精准推送]++ style A fill:#e1f5fe+ style B fill:#f3e5f5+ style E fill:#fff3e0+ style F fill:#e8f5e8+ style G fill:#e8f5e8+ style L fill:#ffebee+ style O fill:#e8f5e8+```+[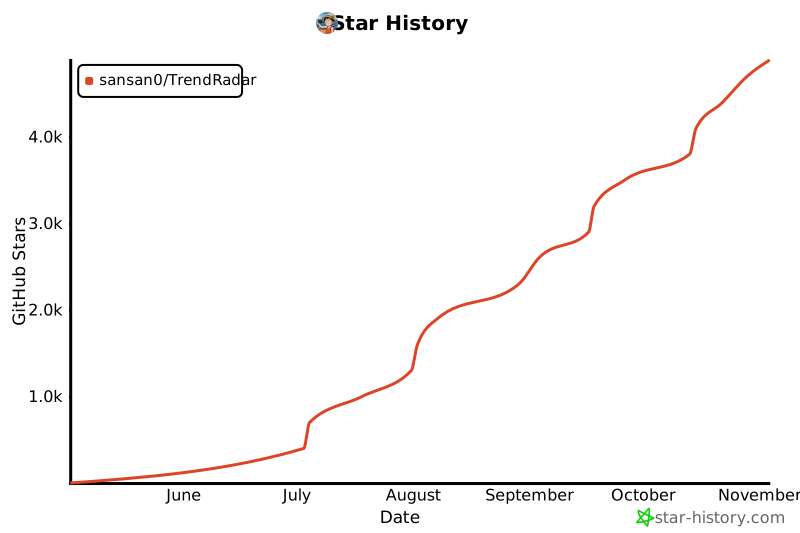](https://www.star-history.com/#sansan0/TrendRadar&Date)@@ -583,6 +666,6 @@ GPL-3.0 License**⭐ 如果这个工具对你有帮助,请给项目点个 Star 支持开发!**-[🔝 回到顶部](#TrendRadar-多平台热点资讯监控分析系统)+[🔝 回到顶部](#trendradar)</div>diff --git a/requirements.txt b/requirements.txtnew file mode 100644index 0000000000..bef336ff69--- /dev/null+++ b/requirements.txt@@ -0,0 +1,3 @@+requests==2.32.4+pytz==2025.2+PyYAML==6.0.2\ No newline at end of filediff --git a/version b/versionindex 347f5833ee..227cea2156 100644--- a/version+++ b/version@@ -1 +1 @@-1.4.1+2.0.0