
Building AI agents, atomically
Add streaming support
KennyVaneetvelde32263d43375a
diff --git a/atomic-agents/README.md b/atomic-agents/README.mddeleted file mode 100644index 53c86c8..0000000--- a/atomic-agents/README.md+++ /dev/null@@ -1,80 +0,0 @@-# Atomic Agents-<img src="./.assets/logo.png" alt="Atomic Agents" width="600"/>--[](https://badge.fury.io/py/atomic-agents)--## Philosophy-The Atomic Agents framework is designed to be modular, extensible, and easy to use. Components in the Atomic Agents Framework should always be as small and single-purpose as possible, similar to design system components in [Atomic Design](https://bradfrost.com/blog/post/atomic-web-design/). Even though Atomic Design cannot be directly applied to AI agent architecture, a lot of ideas were taken from it. The resulting framework provides a set of tools and agents that can be combined to create powerful applications. The framework is built on top of [Instructor](https://github.com/jxnl/instructor) and leverages the power of [Pydantic](https://docs.pydantic.dev/latest/) for data validation and serialization.--[A more detailed deep-dive article can be found on Medium](https://medium.com/generative-ai/an-in-depth-introduction-to-the-atomic-agents-multi-agent-ai-framework-b621f14df454)--<!--  -->-<img src="./.assets/architecture_highlevel_overview.png" alt="Atomic Agents Architecture" width="600"/>-<img src="./.assets/what_is_sent_in_prompt.png" alt="What is sent to the LLM in the prompt?" width="600"/>--## Installation-To install Atomic Agents, you can use pip:--```bash-pip install atomic-agents-```--Alternatively, for local development, to install the necessary dependencies from the repository, run the following commands in the root of the repository:--```bash-python -m venv venv-source venv/bin/activate # On Windows, use `venv\Scripts\activate.bat`-pip install -r requirements.txt-pip install -e .-```--## Quickstart-A quickstart guide is available in the [quickstart notebook](./examples/notebooks/quickstart.ipynb). More guides and tutorials will be added soon!-In the meanwhile, have a look at the other examples in the [examples](./examples/) directory.--## Usage examples & Docs-<img src="./.assets/docs.png" alt="open source docs bad" width="350"/>--While we do our best to provide excellent documentation, we are aware that it is not perfect. If you see anything missing or anything that could be improved, please don't hesitate to open an issue or a pull request.--### Examples-All examples can be found in the [examples](./examples/) directory. We do our best to thoroughly document each example, but if something is unclear, please don't hesitate to open an issue or a pull request in order to improve the documentation.--### Docs-The documentation can be found in the [docs](./docs/) directory. Here you will find both API documentation and some general guides such as [How to create a new tool](./docs/guides/creating_a_new_tool.md).--## Instructor & Model Compatibility-Atomic Agents depends on the [Instructor](https://github.com/jxnl/instructor) package. This means that in all examples where OpenAI is used, any other API supported by Instructor can be used, such as Cohere, Anthropic, Gemini, and more. For a complete list please refer to the instructor documentation on its [GitHub page](https://github.com/jxnl/instructor).--Additionally, Atomic Agents should work with Ollama or LMStudio. If the default settings do not work due to your local server not supporting tool-calling, you can set the `mode` to JSON.--## Formatting and Linting-To format & lint the code before committing, you must run the following two commands:--`black atomic_agents`--`flake8 atomic_agents`--## Testing-To run the tests, run the following command:-`pytest --cov atomic_agents`--To view the coverage report, run the following command:-`coverage html`--## Contributing-We welcome contributions! Please follow these steps to contribute:--1. Fork the repository-2. Create a new branch (`git checkout -b feature-branch`)-3. Make your changes-4. Commit your changes (`git commit -m 'Add some feature'`)-5. Push to the branch (`git push origin feature-branch`)-6. Open a pull request--## License-This project is licensed under the MIT License - see the [LICENSE](LICENSE) file for details.--## Star History--[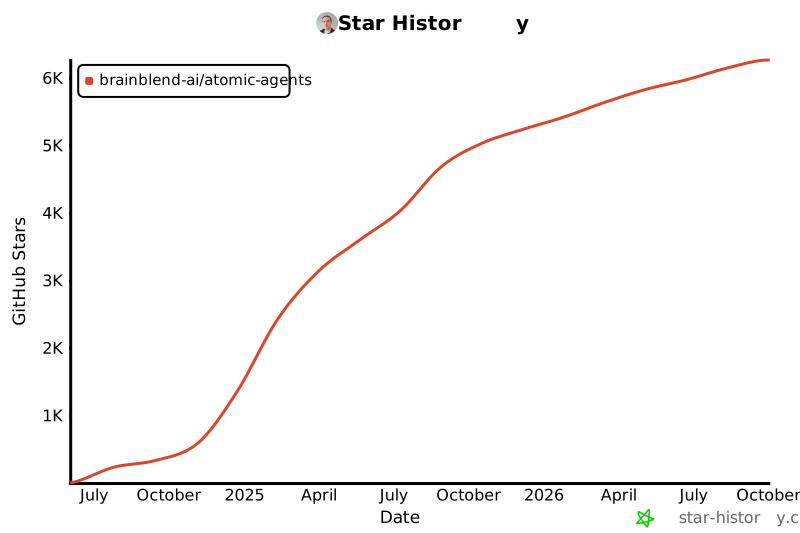](https://star-history.com/#BrainBlend-AI/atomic-agents&Date)diff --git a/atomic-agents/atomic_agents/agents/base_agent.py b/atomic-agents/atomic_agents/agents/base_agent.pyindex 50c25d6..d8b7e2b 100644--- a/atomic-agents/atomic_agents/agents/base_agent.py+++ b/atomic-agents/atomic_agents/agents/base_agent.py@@ -1,11 +1,40 @@import instructorfrom pydantic import BaseModel, Fieldfrom typing import Optional, Type-from atomic_agents.lib.components.agent_memory import AgentMemory-from atomic_agents.lib.components.system_prompt_generator import SystemPromptContextProviderBase, SystemPromptGenerator+from atomic_agents.lib.components.system_prompt_generator import (+ SystemPromptContextProviderBase,+ SystemPromptGenerator,+)from atomic_agents.lib.base.base_io_schema import BaseIOSchema+from instructor.dsl.partial import PartialBase+from jiter import from_json+++def model_from_chunks_patched(cls, json_chunks, **kwargs):+ potential_object = ""+ partial_model = cls.get_partial_model()+ for chunk in json_chunks:+ potential_object += chunk+ obj = from_json((potential_object or "{}").encode(), partial_mode="trailing-strings")+ obj = partial_model.model_validate(obj, strict=None, **kwargs)+ yield obj+++async def model_from_chunks_async_patched(cls, json_chunks, **kwargs):+ potential_object = ""+ partial_model = cls.get_partial_model()+ async for chunk in json_chunks:+ potential_object += chunk+ obj = from_json((potential_object or "{}").encode(), partial_mode="trailing-strings")+ obj = partial_model.model_validate(obj, strict=None, **kwargs)+ yield obj+++PartialBase.model_from_chunks = classmethod(model_from_chunks_patched)+PartialBase.model_from_chunks_async = classmethod(model_from_chunks_async_patched)+class BaseAgentInputSchema(BaseIOSchema):"""This schema represents the input from the user to the AI agent."""@@ -38,7 +67,10 @@ class BaseAgentConfig(BaseModel):input_schema: Optional[Type[BaseModel]] = Field(None, description="The schema for the input data.")output_schema: Optional[Type[BaseModel]] = Field(None, description="The schema for the output data.")model_config = {"arbitrary_types_allowed": True}- temperature: Optional[float] = Field(0, description="Temperature for response generation, typically ranging from 0 to 1.")+ temperature: Optional[float] = Field(+ 0,+ description="Temperature for response generation, typically ranging from 0 to 1.",+ )class BaseAgent:@@ -86,7 +118,7 @@ class BaseAgent:def get_response(self, response_model=None) -> Type[BaseModel]:"""- Obtains a response from the language model.+ Obtains a response from the language model synchronously.Args:response_model (Type[BaseModel], optional):@@ -105,13 +137,16 @@ class BaseAgent:}] + self.memory.get_history()response = self.client.chat.completions.create(- model=self.model, messages=messages, response_model=response_model, temperature=self.temperature+ model=self.model,+ messages=messages,+ response_model=response_model,+ temperature=self.temperature,)return responsedef run(self, user_input: Optional[Type[BaseIOSchema]] = None) -> Type[BaseIOSchema]:"""- Runs the chat agent with the given user input.+ Runs the chat agent with the given user input synchronously.Args:user_input (Optional[Type[BaseIOSchema]]): The input from the user. If not provided, skips adding to memory.@@ -129,6 +164,90 @@ class BaseAgent:return response+ async def get_response_async(self, response_model=None) -> Type[BaseModel]:+ """+ Obtains a response from the language model asynchronously.++ Args:+ response_model (Type[BaseModel], optional):+ The schema for the response data. If not set, self.output_schema is used.++ Returns:+ Type[BaseModel]: The response from the language model.+ """+ if response_model is None:+ response_model = self.output_schema++ messages = [+ {+ "role": "system",+ "content": self.system_prompt_generator.generate_prompt(),+ }+ ] + self.memory.get_history()+ response = await self.client.chat.completions.create(+ model=self.model,+ messages=messages,+ response_model=response_model,+ temperature=self.temperature,+ )+ return response++ async def run_async(self, user_input: Optional[Type[BaseIOSchema]] = None) -> Type[BaseIOSchema]:+ """+ Runs the chat agent with the given user input asynchronously.++ Args:+ user_input (Optional[Type[BaseIOSchema]]): The input from the user. If not provided, skips adding to memory.++ Returns:+ Type[BaseIOSchema]: The response from the chat agent.+ """+ if user_input:+ self.memory.initialize_turn()+ self.current_user_input = user_input+ self.memory.add_message("user", user_input)++ response = await self.get_response_async(response_model=self.output_schema)+ self.memory.add_message("assistant", response)++ return response++ async def stream_response_async(self, user_input: Optional[Type[BaseIOSchema]] = None):+ """+ Runs the chat agent with the given user input, supporting streaming output asynchronously.++ Args:+ user_input (Optional[Type[BaseIOSchema]]): The input from the user. If not provided, skips adding to memory.++ Yields:+ BaseModel: Partial responses from the chat agent.+ """+ if user_input:+ self.memory.initialize_turn()+ self.current_user_input = user_input+ self.memory.add_message("user", user_input)++ messages = [+ {+ "role": "system",+ "content": self.system_prompt_generator.generate_prompt(),+ }+ ] + self.memory.get_history()++ response_stream = self.client.chat.completions.create_partial(+ model=self.model,+ messages=messages,+ response_model=self.output_schema,+ temperature=self.temperature,+ stream=True,+ )++ async for partial_response in response_stream:+ yield partial_response++ full_response_content = self.output_schema(**partial_response.model_dump())+ self.memory.add_message("assistant", full_response_content)+def get_context_provider(self, provider_name: str) -> Type[SystemPromptContextProviderBase]:"""Retrieves a context provider by name.@@ -175,25 +294,73 @@ if __name__ == "__main__":from rich.table import Tablefrom rich.syntax import Syntaxfrom rich import box+ from openai import OpenAI, AsyncOpenAIimport instructor- import openai- from pydantic import BaseModel, Field-- # Initialize the agent- client = instructor.from_openai(openai.OpenAI())- config = BaseAgentConfig(- client=client,- model="gpt-4o-mini",- )- agent = BaseAgent(config)+ import asyncio+ from rich.live import Live+ import json++ async def chat_loop(streaming: bool = False):+ """Interactive chat loop with the AI agent.++ Args:+ streaming (bool): Whether to use streaming mode for responses+ """+ if streaming:+ client = instructor.from_openai(AsyncOpenAI())+ config = BaseAgentConfig(client=client, model="gpt-4o-mini")+ agent = BaseAgent(config)+ else:+ client = instructor.from_openai(OpenAI())+ config = BaseAgentConfig(client=client, model="gpt-4o-mini")+ agent = BaseAgent(config)++ console = Console()+ console.print(+ Panel.fit(+ "[bold blue]Interactive Chat Mode[/bold blue]\n"+ f"[cyan]Streaming: {streaming}[/cyan]\n"+ "Type 'exit' to quit",+ border_style="blue",+ padding=(1, 1),+ )+ )++ while True:+ user_message = console.input("\n[bold green]You:[/bold green] ")++ if user_message.lower() == "exit":+ console.print("[yellow]Goodbye![/yellow]")+ break++ user_input = agent.input_schema(chat_message=user_message)++ console.print("[bold blue]Assistant:[/bold blue]")+ if streaming:+ with Live(console=console, refresh_per_second=4) as live:+ async for partial_response in agent.stream_response_async(user_input):+ response_json = partial_response.model_dump()+ json_str = json.dumps(response_json, indent=2)+ live.update(json_str)+ else:+ response = agent.run(user_input)+ response_json = response.model_dump()+ json_str = json.dumps(response_json, indent=2)+ console.print(json_str)- # Create a Rich consoleconsole = Console()+ client = instructor.from_openai(OpenAI())+ config = BaseAgentConfig(client=client, model="gpt-4o-mini")+ agent = BaseAgent(config)- # Print agent information- console.print(Panel.fit("[bold blue]Agent Information[/bold blue]", border_style="blue", padding=(1, 1)))+ console.print(+ Panel.fit(+ "[bold blue]Agent Information[/bold blue]",+ border_style="blue",+ padding=(1, 1),+ )+ )- # Print input schemainput_schema_table = Table(title="Input Schema", box=box.ROUNDED)input_schema_table.add_column("Field", style="cyan")input_schema_table.add_column("Type", style="magenta")@@ -204,7 +371,6 @@ if __name__ == "__main__":console.print(input_schema_table)- # Print output schemaoutput_schema_table = Table(title="Output Schema", box=box.ROUNDED)output_schema_table.add_column("Field", style="cyan")output_schema_table.add_column("Type", style="magenta")@@ -215,7 +381,6 @@ if __name__ == "__main__":console.print(output_schema_table)- # Print other agent informationinfo_table = Table(title="Agent Configuration", box=box.ROUNDED)info_table.add_column("Property", style="cyan")info_table.add_column("Value", style="yellow")@@ -226,7 +391,6 @@ if __name__ == "__main__":console.print(info_table)- # Print a sample of the system promptsystem_prompt = agent.system_prompt_generator.generate_prompt()console.print(Panel(@@ -237,9 +401,6 @@ if __name__ == "__main__":))- console.print("\n[bold]Agent initialized and ready to use![/bold]")+ console.print("\n[bold]Starting chat loop...[/bold]")- # Run the agent with a sample input- sample_input = agent.input_schema(chat_message="Please give me 3 cute squirrel facts")- response = agent.run(sample_input)- console.print(f"[bold]Response:[/bold] {response.chat_message}")+ asyncio.run(chat_loop(streaming=True))diff --git a/atomic-agents/atomic_agents/lib/base/base_io_schema.py b/atomic-agents/atomic_agents/lib/base/base_io_schema.pyindex 5f95bc6..33c8bf6 100644--- a/atomic-agents/atomic_agents/lib/base/base_io_schema.py+++ b/atomic-agents/atomic_agents/lib/base/base_io_schema.py@@ -23,7 +23,7 @@ class BaseIOSchema(BaseModel):description = cls.__doc__if not description or not description.strip():- if cls.__module__ != "instructor.function_calls":+ if cls.__module__ != "instructor.function_calls" and not hasattr(cls, "from_streaming_response"):raise ValueError(f"{cls.__name__} must have a non-empty docstring to serve as its description")@classmethoddiff --git a/atomic-agents/tests/agents/test_base_agent.py b/atomic-agents/tests/agents/test_base_agent.pyindex 3b32d31..a3c423b 100644--- a/atomic-agents/tests/agents/test_base_agent.py+++ b/atomic-agents/tests/agents/test_base_agent.py@@ -1,5 +1,5 @@import pytest-from unittest.mock import Mock, call, patch+from unittest.mock import AsyncMock, Mock, call, patchfrom pydantic import BaseModelimport instructorfrom atomic_agents.agents.base_agent import (@@ -12,12 +12,14 @@ from atomic_agents.agents.base_agent import (AgentMemory,SystemPromptContextProviderBase,)+from instructor.dsl.partial import PartialBase@pytest.fixturedef mock_instructor():mock = Mock(spec=instructor.Instructor)mock.chat.completions.create = Mock()+ mock.chat.completions.create_partial = Mock()return mock@@ -27,6 +29,7 @@ def mock_memory():mock.get_history.return_value = []mock.add_message = Mock()mock.copy = Mock(return_value=Mock(spec=AgentMemory))+ mock.initialize_turn = Mock()return mock@@ -41,7 +44,10 @@ def mock_system_prompt_generator():@pytest.fixturedef agent_config(mock_instructor, mock_memory, mock_system_prompt_generator):return BaseAgentConfig(- client=mock_instructor, model="gpt-4o-mini", memory=mock_memory, system_prompt_generator=mock_system_prompt_generator+ client=mock_instructor,+ model="gpt-4o-mini",+ memory=mock_memory,+ system_prompt_generator=mock_system_prompt_generator,)@@ -124,7 +130,10 @@ def test_custom_input_output_schemas(mock_instructor):result: strcustom_config = BaseAgentConfig(- client=mock_instructor, model="gpt-4o-mini", input_schema=CustomInputSchema, output_schema=CustomOutputSchema+ client=mock_instructor,+ model="gpt-4o-mini",+ input_schema=CustomInputSchema,+ output_schema=CustomOutputSchema,)custom_agent = BaseAgent(custom_config)@@ -179,3 +188,107 @@ def test_base_io_schema_model_json_schema_no_description():assert "description" in schemaassert schema["description"] == "Test schema docstring."+++async def test_get_response_async(agent, mock_instructor, mock_memory, mock_system_prompt_generator):+ mock_memory.get_history.return_value = [{"role": "user", "content": "Hello"}]+ mock_system_prompt_generator.generate_prompt.return_value = "System prompt"++ mock_response = Mock(spec=BaseAgentOutputSchema)+ mock_instructor.chat.completions.create = AsyncMock(return_value=mock_response)++ response = await agent.get_response_async()++ assert response == mock_response++ mock_instructor.chat.completions.create.assert_awaited_once_with(+ model="gpt-4o-mini",+ messages=[{"role": "system", "content": "System prompt"}, {"role": "user", "content": "Hello"}],+ response_model=BaseAgentOutputSchema,+ temperature=0,+ )+++async def test_run_async(agent, mock_memory):+ mock_input = BaseAgentInputSchema(chat_message="Test input")+ mock_output = BaseAgentOutputSchema(chat_message="Test output")++ agent.get_response_async = AsyncMock(return_value=mock_output)++ result = await agent.run_async(mock_input)++ assert result == mock_output+ assert agent.current_user_input == mock_input++ mock_memory.add_message.assert_has_calls([call("user", mock_input), call("assistant", mock_output)])+++async def test_stream_response_async(agent, mock_memory, mock_instructor, mock_system_prompt_generator):+ mock_input = BaseAgentInputSchema(chat_message="Test input")+ mock_memory.get_history.return_value = [{"role": "user", "content": "Hello"}]+ mock_system_prompt_generator.generate_prompt.return_value = "System prompt"++ partial_responses = [+ BaseAgentOutputSchema(chat_message="Partial response 1"),+ BaseAgentOutputSchema(chat_message="Partial response 2"),+ BaseAgentOutputSchema(chat_message="Final response"),+ ]++ async def mock_create_partial(*args, **kwargs):+ for response in partial_responses:+ yield response++ mock_instructor.chat.completions.create_partial = mock_create_partial++ responses = []+ async for partial_response in agent.stream_response_async(mock_input):+ responses.append(partial_response)++ assert responses == partial_responses++ mock_memory.add_message.assert_called_with("assistant", partial_responses[-1])+++def test_model_from_chunks_patched():+ class TestPartialModel(PartialBase):+ @classmethod+ def get_partial_model(cls):+ class PartialModel(BaseModel):+ field: str++ return PartialModel++ chunks = ['{"field": "hel', 'lo"}']+ expected_values = ["hel", "hello"]++ generator = TestPartialModel.model_from_chunks(chunks)+ results = [result.field for result in generator]++ assert results == expected_values+++async def test_model_from_chunks_async_patched():+ class TestPartialModel(PartialBase):+ @classmethod+ def get_partial_model(cls):+ class PartialModel(BaseModel):+ field: str++ return PartialModel++ async def async_gen():+ yield '{"field": "hel'+ yield 'lo"}'++ expected_values = ["hel", "hello"]++ generator = TestPartialModel.model_from_chunks_async(async_gen())+ results = []+ async for result in generator:+ results.append(result.field)++ assert results == expected_valuesdiff --git a/poetry.lock b/poetry.lockindex de8cb23..9786444 100644--- a/poetry.lock+++ b/poetry.lock@@ -1373,6 +1373,24 @@ pluggy = ">=1.5,<2"[package.extras]dev = ["argcomplete", "attrs (>=19.2)", "hypothesis (>=3.56)", "mock", "pygments (>=2.7.2)", "requests", "setuptools", "xmlschema"]+[[package]]+name = "pytest-asyncio"+version = "0.24.0"+description = "Pytest support for asyncio"+optional = false+python-versions = ">=3.8"+files = [+ {file = "pytest_asyncio-0.24.0-py3-none-any.whl", hash = "sha256:a811296ed596b69bf0b6f3dc40f83bcaf341b155a269052d82efa2b25ac7037b"},+ {file = "pytest_asyncio-0.24.0.tar.gz", hash = "sha256:d081d828e576d85f875399194281e92bf8a68d60d72d1a2faf2feddb6c46b276"},+]++[package.dependencies]+pytest = ">=8.2,<9"++[package.extras]+docs = ["sphinx (>=5.3)", "sphinx-rtd-theme (>=1.0)"]+testing = ["coverage (>=6.2)", "hypothesis (>=5.7.1)"]+[[package]]name = "pytest-cov"version = "5.0.0"@@ -1724,4 +1742,4 @@ propcache = ">=0.2.0"[metadata]lock-version = "2.0"python-versions = ">=3.11,<4.0"-content-hash = "5a5bab24c495090ab5b1c2fa746acf97ab09f54cd0b85494d05736ecfc21a992"+content-hash = "da599d8341683f65c96dc0113abfd40bdfd3b536fe9be59c5e83665af251707a"diff --git a/pyproject.toml b/pyproject.tomlindex 256c5b7..27edbdc 100644--- a/pyproject.toml+++ b/pyproject.toml@@ -25,6 +25,7 @@ textual = ">=0.82.0,<1.0.0"pyyaml = ">=6.0.2,<7.0.0"python-dotenv = "^1.0.1"pdoc3 = "^0.11.1"+pytest-asyncio = "^0.24.0"[tool.poetry.group.dev.dependencies]black = ">=24.8.0,<25.0.0"