
🐫 CAMEL: The first and the best multi-agent framework. Finding the Scaling Law of Agents. https://www.camel-ai.org
Python agentai-societiesartificial-intelligencecommunicative-aicooperative-aideep-learninglarge-language-modelsmulti-agent-systemsnatural-language-processing
feat: implementing STaR: Self Taught Reasoner (#1478)
Rishabh88160be84327
diff --git a/camel/agents/chat_agent.py b/camel/agents/chat_agent.pyindex 72743bb8a..03cd20b3d 100644--- a/camel/agents/chat_agent.py+++ b/camel/agents/chat_agent.py@@ -573,9 +573,8 @@ class ChatAgent(BaseAgent):self.model_backend.model_config_dict.get("response_format")and response_format):- raise ValueError(- "The `response_format` parameter cannot be set both in "- "the model configuration and in the ChatAgent step."+ logger.warning(+ f"Overriding the response format with {response_format}.")self.original_model_dict = self.model_backend.model_config_dictdiff --git a/camel/datagen/__init__.py b/camel/datagen/__init__.pyindex aabc9131e..b044e8705 100644--- a/camel/datagen/__init__.py+++ b/camel/datagen/__init__.py@@ -12,10 +12,12 @@# limitations under the License.# ========= Copyright 2023-2024 @ CAMEL-AI.org. All Rights Reserved. =========-from .cotdatagen import CoTDataGenerator+from .cot_datagen import CoTDataGenerator+from .self_improving_cot import SelfImprovingCoTPipelinefrom .self_instruct import SelfInstructPipeline__all__ = ["CoTDataGenerator","SelfInstructPipeline",+ "SelfImprovingCoTPipeline",]diff --git a/camel/datagen/cotdatagen.py b/camel/datagen/cot_datagen.pysimilarity index 100%rename from camel/datagen/cotdatagen.pyrename to camel/datagen/cot_datagen.pydiff --git a/camel/datagen/self_improving_cot.py b/camel/datagen/self_improving_cot.pynew file mode 100644index 000000000..b9e5df260--- /dev/null+++ b/camel/datagen/self_improving_cot.py@@ -0,0 +1,821 @@+# ========= Copyright 2023-2024 @ CAMEL-AI.org. All Rights Reserved. =========+# Licensed under the Apache License, Version 2.0 (the "License");+# you may not use this file except in compliance with the License.+# You may obtain a copy of the License at+#+# http://www.apache.org/licenses/LICENSE-2.0+#+# Unless required by applicable law or agreed to in writing, software+# distributed under the License is distributed on an "AS IS" BASIS,+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.+# See the License for the specific language governing permissions and+# limitations under the License.+# ========= Copyright 2023-2024 @ CAMEL-AI.org. All Rights Reserved. =========++import asyncio+import json+import math+import os+import threading+import time+from concurrent.futures import ThreadPoolExecutor, as_completed+from typing import Any, Dict, List, Optional, Union++from pydantic import BaseModel++from camel.agents import ChatAgent+from camel.logger import get_logger+from camel.models.reward import BaseRewardModel, Evaluator+from camel.utils import BatchProcessor, retry_on_error++logger = get_logger(__name__)+++class AgentTraceEvaluation(BaseModel):+ correctness: float+ clarity: float+ completeness: float+ feedback: str+++class RewardTraceEvaluation(BaseModel):+ feedback: str++ def __init__(self, **data):+ # Allow dynamic score fields while ensuring feedback is present+ super().__init__(**data)++ class Config:+ extra = (+ "allow" # Allow extra fields for different reward model dimensions+ )+++class TraceIteration(BaseModel):+ iteration: int+ trace: str+ evaluation: Union[AgentTraceEvaluation, RewardTraceEvaluation]+++class ProblemResult(BaseModel):+ id: Optional[str] = None+ type: Optional[str] = None+ problem: str+ solution: Optional[str] = None+ final_trace: str+ agent_evaluate_success: Optional[bool] = None+ boxed_answer_success: bool = False+ improvement_history: List[TraceIteration]+++class SelfImprovingCoTPipeline:+ r"""Pipeline for generating self-taught reasoning traces+ using the self-improving methodology.++ This implements the STaR paper's approach of:+ 1. Initial reasoning trace generation+ 2. Self-evaluation+ 3. Feedback-based improvement+ 4. Iterative refinement+ """++ def __init__(+ self,+ reason_agent: ChatAgent,+ problems: List[Dict],+ max_iterations: int = 3,+ score_threshold: Union[float, Dict[str, float]] = 0.7,+ evaluate_agent: Optional[ChatAgent] = None,+ reward_model: Optional[BaseRewardModel] = None,+ output_path: Optional[str] = None,+ few_shot_examples: Optional[str] = None,+ batch_size: Optional[int] = None,+ max_workers: Optional[int] = None,+ solution_pattern: str = r'\\boxed{(.*?)}',+ trace_pattern: Optional[str] = None,+ ):+ r"""Initialize the self-improving cot pipeline.++ Args:+ reason_agent (ChatAgent): The chat agent used for generating and+ improving reasoning traces.+ problems (List[Dict]): List of problem dictionaries to process.+ max_iterations (int, optional): Maximum number of improvement+ iterations. If set to `0`, the pipeline will generate an+ initial trace without any improvement iterations.+ (default: :obj:`3`)+ score_threshold (Union[float, Dict[str, float]], optional):+ Quality threshold. Can be either a single float value applied+ to average score, or a dictionary mapping score dimensions to+ their thresholds. For example: {"correctness": 0.8,+ "coherence": 0.7}. If using reward model and threshold for a+ dimension is not specified, will use the default value 0.7.+ (default: :obj:`0.7`)+ evaluate_agent (Optional[ChatAgent]): The chat agent used for+ evaluating reasoning traces. (default: :obj:`None`)+ reward_model (BaseRewardModel, optional): Model used to evaluate+ reasoning traces. If `None`, uses Agent self-evaluation.+ (default: :obj:`None`)+ output_path (str, optional): Output path for saving traces. If+ `None`, results will only be returned without saving to file.+ (default: :obj:`None`)+ few_shot_examples (str, optional): Examples to use for few-shot+ generation. (default: :obj:`None`)+ batch_size (int, optional): Batch size for parallel processing.+ (default: :obj:`None`)+ max_workers (int, optional): Maximum number of worker threads.+ (default: :obj:`None`)+ solution_pattern (str, optional): Regular expression pattern with+ one capture group to extract answers from solution text.+ (default: :obj:`r'\\boxed{(.*?)}'`)+ trace_pattern (str, optional): Regular expression pattern with one+ capture group to extract answers from trace text. If `None`,+ uses the same pattern as solution_pattern.+ (default: :obj:`None`)+ """+ self.reason_agent = reason_agent+ self.evaluate_agent = evaluate_agent+ self.problems = problems+ self.output_path = output_path+ self.max_iterations = max_iterations+ self.score_threshold = score_threshold+ self.reward_model = reward_model+ self.evaluator = (+ Evaluator(reward_model=reward_model) if reward_model else None+ )+ self.reasoning_traces: List[Dict[str, Any]] = []+ self.few_shot_examples = few_shot_examples+ self.batch_processor = BatchProcessor(max_workers, batch_size)+ self.solution_pattern = solution_pattern+ self.trace_pattern = (+ trace_pattern if trace_pattern is not None else solution_pattern+ )++ # Initialize output file with empty results if path is specified+ if self.output_path:+ with open(self.output_path, 'w') as f:+ json.dump({'traces': []}, f, indent=2)+ self.lock = threading.Lock()++ def safe_write_json(self, file_path, data):+ temp_path = file_path + ".tmp"+ with open(temp_path, "w") as f:+ json.dump(data, f, indent=2)+ os.replace(temp_path, file_path)++ def clean_json(self, data):+ if isinstance(data, dict):+ return {k: self.clean_json(v) for k, v in data.items()}+ elif isinstance(data, list):+ return [self.clean_json(v) for v in data]+ elif isinstance(data, float) and (+ math.isnan(data) or math.isinf(data)+ ):+ return None+ return data++ async def _batch_process_problems(+ self, problems: List[Dict], rationalization: bool+ ) -> List[ProblemResult]:+ r"""Process multiple problems in parallel batches with dynamic sizing.++ Args:+ problems (List[Dict]): List of problem dictionaries to process.+ rationalization (bool): Whether to use rationalization.++ Returns:+ List[ProblemResult]: List of problem results.+ """+ results = []+ total_problems = len(problems)+ processed = 0++ while processed < total_problems:+ batch_size = self.batch_processor.batch_size+ batch = problems[processed : processed + batch_size]+ batch_start_time = time.time()++ try:+ with ThreadPoolExecutor(+ max_workers=self.batch_processor.max_workers+ ) as executor:+ # Create futures with rationalization parameter+ futures = [+ executor.submit(+ self.process_problem,+ problem=problem,+ rationalization=rationalization,+ )+ for problem in batch+ ]++ batch_results = []+ batch_success = True+ for future in as_completed(futures):+ try:+ result = future.result()+ batch_results.append(result)+ except Exception as e:+ logger.error(f"Error processing problem: {e}")+ batch_success = False+ continue++ results.extend(batch_results)+ processed += len(batch)++ # Calculate processing time and adjust batch size+ processing_time = time.time() - batch_start_time+ self.batch_processor.adjust_batch_size(+ batch_success, processing_time+ )++ # Log progress and performance metrics+ metrics = self.batch_processor.get_performance_metrics()+ logger.info(+ f"Processed {processed}/{total_problems} problems "+ f"(batch size: {batch_size}, workers: "+ f"{metrics['current_workers']}, "+ f"CPU: {metrics['current_cpu']:.1f}%, "+ f"Memory: {metrics['current_memory']:.1f}%)"+ )+ except Exception as e:+ logger.error(f"Batch processing error: {e}")+ self.batch_processor.adjust_batch_size(False)+ continue++ return results++ async def _batch_evaluate_traces(+ self,+ problems: List[Dict[str, Any]],+ traces: List[str],+ solutions: Optional[List[str]] = None,+ ) -> List[Dict[str, Any]]:+ r"""Evaluate multiple traces in parallel batches with resource+ monitoring.++ Args:+ problems (List[Dict[str, Any]]): List of problem dictionaries+ traces (List[str]): List of reasoning traces to evaluate+ solutions (Optional[List[str]]): Optional list of solutions++ Returns:+ List[Dict[str, Any]]: List of evaluation results+ """+ if solutions is None:+ solutions = ["null"] * len(problems)++ results = []+ total_traces = len(traces)+ processed = 0++ while processed < total_traces:+ batch_size = self.batch_processor.batch_size+ problem_batch = problems[processed : processed + batch_size]+ trace_batch = traces[processed : processed + batch_size]+ solution_batch = solutions[processed : processed + batch_size]+ batch_start_time = time.time()++ try:+ with ThreadPoolExecutor(+ max_workers=self.batch_processor.max_workers+ ) as executor:+ futures = [+ executor.submit(+ self.evaluate_trace,+ problem=problem["problem"],+ trace=trace,+ solution=solution,+ )+ for problem, trace, solution in zip(+ problem_batch, trace_batch, solution_batch+ )+ ]++ batch_results = []+ batch_success = True+ for future in as_completed(futures):+ try:+ result = future.result()+ batch_results.append(result)+ except Exception as e:+ logger.error(f"Error evaluating trace: {e}")+ batch_success = False+ continue++ results.extend(batch_results)+ processed += len(batch_results)++ # Calculate processing time and adjust batch size+ processing_time = time.time() - batch_start_time+ self.batch_processor.adjust_batch_size(+ batch_success, processing_time+ )++ # Log progress and performance metrics+ metrics = self.batch_processor.get_performance_metrics()+ logger.info(+ f"Evaluated {processed}/{total_traces} traces "+ f"(batch size: {batch_size}, workers: "+ f"{metrics['current_workers']}, "+ f"avg time: {metrics['avg_processing_time']:.2f}s, "+ f"error rate: {metrics['error_rate']:.1f}%)"+ )+ except Exception as e:+ logger.error(f"Batch evaluation error: {e}")+ self.batch_processor.adjust_batch_size(False)+ continue++ return results++ def _check_score_threshold(self, scores: Dict[str, float]) -> bool:+ r"""Check if scores meet the threshold requirements.++ Args:+ scores (Dict[str, float]): Dictionary of scores for different+ dimensions.++ Returns:+ bool: True if scores meet threshold requirements, False otherwise.+ """+ # If score_threshold is a float, apply it to all dimensions+ if isinstance(self.score_threshold, float):+ return all(+ score >= self.score_threshold for score in scores.values()+ )++ # If score_threshold is a dict, check each dimension with its threshold+ # Use 0 as default threshold for unspecified dimensions+ if isinstance(self.score_threshold, dict):+ for dim, score in scores.items():+ threshold = self.score_threshold.get(dim, 0)+ if score < threshold:+ return False+ return True++ # If score_threshold is None or invalid type, pass the check+ return True++ def _generate_feedback(self, scores: Dict[str, float]) -> str:+ r"""Generate feedback based on which dimensions need improvement.++ Args:+ scores (Dict[str, float]): Dictionary of scores for different+ dimensions.++ Returns:+ str: Feedback message indicating which dimensions need improvement.+ """+ if isinstance(self.score_threshold, float):+ below_threshold = [+ dim+ for dim, score in scores.items()+ if score < self.score_threshold+ ]+ if not below_threshold:+ return "All dimensions meet the required threshold"+ dims = ", ".join(below_threshold)+ return f"Need improvement in: {dims}"++ if isinstance(self.score_threshold, dict):+ default_threshold = 0+ below_threshold = [+ dim+ for dim, score in scores.items()+ if score < self.score_threshold.get(dim, default_threshold)+ ]+ if not below_threshold:+ return "All dimensions meet their respective thresholds"+ dims = ", ".join(below_threshold)+ return f"Need improvement in: {dims}"++ # If no threshold set, just list all dimensions and their scores+ dims = ", ".join(+ f"{dim}: {score:.2f}" for dim, score in scores.items()+ )+ return f"Current scores - {dims}"++ @retry_on_error()+ def generate_reasoning_trace(self, problem: str) -> str:+ r"""Generate initial reasoning trace for a given problem.++ Args:+ problem (str): The problem text to generate reasoning for.++ Returns:+ str: Generated reasoning trace.+ """+ self.reason_agent.reset()+ few_shot_examples = (+ f"Examples: {self.few_shot_examples}"+ if self.few_shot_examples+ else ""+ )+ prompt = self.REASONING_TEMPLATE.format(+ problem=problem, few_shot_examples=few_shot_examples+ )+ response = self.reason_agent.step(prompt)+ return response.msg.content++ @retry_on_error()+ def evaluate_trace(+ self, problem: str, trace: str, solution: Optional[str] = None+ ) -> Dict[str, Any]:+ r"""Evaluate the quality of a reasoning trace.++ Args:+ problem (str): The original problem text to evaluate against.+ trace (str): The reasoning trace to evaluate.+ solution (Optional[str]): The solution to the problem, if provided.+ (default: :obj:`None`)++ Returns:+ Dict[str, Any]: Evaluation results containing:+ - scores: Dict of evaluation dimensions and their scores+ - feedback: Detailed feedback for improvement++ For Agent self-evaluation, the scores will include:+ - correctness: Score for logical correctness+ - clarity: Score for clarity of explanation+ - completeness: Score for completeness of reasoning++ For reward model evaluation, the scores will depend on+ the model's evaluation dimensions.+ """+ self.evaluate_agent.reset() # type: ignore[union-attr]+ if self.evaluator:+ # Use reward model evaluation+ messages = [+ {"role": "user", "content": problem},+ {"role": "assistant", "content": trace},+ ]+ scores = self.evaluator.evaluate(messages)++ # For models that return a single score+ if isinstance(scores, (int, float)) or (+ isinstance(scores, dict) and len(scores) == 1+ ):+ if isinstance(scores, dict):+ score = next(iter(scores.values()))+ else:+ score = scores+ scores_dict = {"overall": score}+ return {+ **scores_dict,+ "feedback": self._generate_feedback(scores_dict),+ }++ # For models that return multiple dimensions+ return {**scores, "feedback": self._generate_feedback(scores)}+ else:+ # Fallback to original Agent self-evaluation+ solution_text = f"Solution: {solution}" if solution else ""+ prompt = self.EVALUATION_TEMPLATE.format(+ problem=problem, trace=trace, solution=solution_text+ )+ response = self.evaluate_agent.step( # type: ignore[union-attr]+ prompt, response_format=AgentTraceEvaluation+ )+ if response.msg.parsed is None:+ raise AttributeError("Failed to parse evaluation response")+ # Convert dict to AgentTraceEvaluation if needed+ if isinstance(response.msg.parsed, dict):+ evaluation = AgentTraceEvaluation(**response.msg.parsed)+ else:+ evaluation = response.msg.parsed++ return evaluation.model_dump()++ @retry_on_error()+ def improve_trace(+ self,+ problem: str,+ trace: str,+ feedback: str,+ solution: Optional[str] = None,+ ) -> str:+ r"""Generate improved reasoning trace based on feedback.++ Args:+ problem (str): The original problem text.+ trace (str): The current reasoning trace.+ feedback (str): Feedback for improving the trace.+ solution (Optional[str]): The solution to the problem, if provided.+ (default: :obj:`None`)++ Returns:+ str: Improved reasoning trace.+ """+ self.reason_agent.reset()+ solution_text = f"Solution: {solution}" if solution else ""+ prompt = self.IMPROVEMENT_TEMPLATE.format(+ problem=problem,+ trace=trace,+ feedback=feedback,+ solution=solution_text,+ )+ response = self.reason_agent.step(prompt)+ return response.msg.content++ def validate_problem_format(self, problem: Dict) -> None:+ r"""Validate that a problem dictionary has the required format.++ Args:+ problem (Dict): Problem dictionary to validate.++ Raises:+ ValueError: If the problem format is invalid.+ """+ if not isinstance(problem, dict):+ raise ValueError("Problem must be a dictionary.")++ # Check required problem field+ if "problem" not in problem:+ raise ValueError("Problem dictionary must contain 'problem' key.")+ if not isinstance(problem["problem"], str):+ raise ValueError("Problem 'problem' field must be a string.")++ # Optional fields validation+ optional_fields: dict[str, type | tuple[type, ...]] = {+ "id": (str, int, type(None)),+ "type": str,+ "solution": str,+ }++ for field, expected_type in optional_fields.items():+ if field in problem and not isinstance(+ problem[field], expected_type+ ):+ type_name = (+ expected_type.__name__+ if hasattr(expected_type, '__name__')+ else str(expected_type)+ )+ raise ValueError(+ f"Problem '{field}' must be of "+ f"type {type_name} if present."+ )++ def _check_boxed_answers(self, solution: str, trace: str) -> bool:+ r"""Check if the answer in the trace matches the solution using the+ configured patterns.++ Args:+ solution (str): The problem solution string.+ trace (str): The reasoning trace string.++ Returns:+ bool: True if answers match, False otherwise+ """+ import re++ # Extract content using the configured patterns+ solution_match = re.search(self.solution_pattern, solution, re.DOTALL)+ trace_match = re.search(self.trace_pattern, trace, re.DOTALL)++ if solution_match and trace_match:+ # Clean up whitespace and normalize content+ solution_answer = solution_match.group(1).strip()+ trace_answer = trace_match.group(1).strip()+ return solution_answer == trace_answer++ return False++ def process_problem(+ self, problem: Dict, rationalization: bool = False+ ) -> ProblemResult:+ r"""Process a single problem through the self-improving cot pipeline.++ Args:+ problem (Dict): Problem dictionary containing the problem text.+ rationalization (bool, optional): Whether to use rationalization.+ (default: :obj:`False`)++ Returns:+ ProblemResult: Results with final trace and history.++ Raises:+ ValueError: If the problem format is invalid.+ """+ # Validate problem format before processing+ self.validate_problem_format(problem)++ problem_text = problem["problem"]+ solution_text = problem.get("solution", "")+ current_trace = self.generate_reasoning_trace(problem_text)+ improvement_history = []+ scores = {}++ # Only evaluate if evaluate_agent or reward_model is set+ if self.evaluate_agent or self.reward_model:+ # Create batches for parallel evaluation+ batch_problems = [problem]+ batch_traces = [current_trace]+ batch_solutions = [solution_text]++ # Evaluate current trace batch+ loop = asyncio.new_event_loop()+ asyncio.set_event_loop(loop)+ try:+ eval_results = loop.run_until_complete(+ self._batch_evaluate_traces(+ batch_problems, batch_traces, batch_solutions+ )+ )+ finally:+ loop.close()++ # Process evaluation results+ eval_dict = eval_results[-1] # Get latest evaluation+ scores = {k: v for k, v in eval_dict.items() if k != "feedback"}++ # Record initial evaluation+ if self.evaluator:+ improvement_history.append(+ TraceIteration(+ iteration=0,+ trace=current_trace,+ evaluation=RewardTraceEvaluation(**eval_dict),+ )+ )+ else:+ improvement_history.append(+ TraceIteration(+ iteration=0,+ trace=current_trace,+ evaluation=AgentTraceEvaluation(+ **scores, feedback=eval_dict["feedback"]+ ),+ )+ )++ # Only do improvement iterations if max_iterations > 0+ if self.max_iterations > 0:+ for iteration in range(0, self.max_iterations):+ # Check if quality threshold met+ if self._check_score_threshold(scores):+ break++ # Generate improved trace+ if rationalization:+ current_trace = self.improve_trace(+ problem_text,+ current_trace,+ eval_dict["feedback"],+ solution_text,+ )+ else:+ current_trace = self.improve_trace(+ problem_text, current_trace, eval_dict["feedback"]+ )++ # Evaluate improved trace+ batch_traces = [current_trace]+ loop = asyncio.new_event_loop()+ asyncio.set_event_loop(loop)+ try:+ eval_results = loop.run_until_complete(+ self._batch_evaluate_traces(+ batch_problems, batch_traces, batch_solutions+ )+ )+ finally:+ loop.close()++ eval_dict = eval_results[-1]+ scores = {+ k: v for k, v in eval_dict.items() if k != "feedback"+ }++ # Record iteration history+ if self.evaluator:+ improvement_history.append(+ TraceIteration(+ iteration=iteration + 1,+ trace=current_trace,+ evaluation=RewardTraceEvaluation(**eval_dict),+ )+ )+ else:+ improvement_history.append(+ TraceIteration(+ iteration=iteration + 1,+ trace=current_trace,+ evaluation=AgentTraceEvaluation(+ **scores, feedback=eval_dict["feedback"]+ ),+ )+ )++ boxed_answer_success = self._check_boxed_answers(+ problem.get("solution", ""), current_trace+ )++ result = ProblemResult(+ id=problem.get("id", ""),+ type=problem.get("type", ""),+ problem=problem_text,+ solution=problem.get("solution", ""),+ final_trace=current_trace,+ agent_evaluate_success=self._check_score_threshold(scores)+ if scores+ else None,+ boxed_answer_success=boxed_answer_success,+ improvement_history=improvement_history,+ )++ # Write result to file immediately if output path is specified+ if self.output_path:+ with self.lock:+ try:+ # Read existing results+ with open(self.output_path, 'r') as f:+ data = json.load(f)++ cleaned_result = self.clean_json(result.model_dump())+ data['traces'].append(cleaned_result)+ self.safe_write_json(self.output_path, data)++ except Exception as e:+ logger.error(f"Error writing result to file: {e}")++ return result++ def generate(self, rationalization: bool = False) -> List[Dict[str, Any]]:+ r"""Execute the self-improving cot pipeline on all problems.++ Process problems and return results. If output_path is specified,+ also save results to file.++ Args:+ rationalization (bool, optional): Whether to use rationalization.+ (default: :obj:`False`)++ Returns:+ List[Dict[str, Any]]: List of processed results+ """+ # Pre-allocate results list+ self.reasoning_traces = []++ # Process problems in batches+ loop = asyncio.new_event_loop()+ asyncio.set_event_loop(loop)++ try:+ results = loop.run_until_complete(+ self._batch_process_problems(self.problems, rationalization)+ )+ finally:+ loop.close()++ self.reasoning_traces = [result.model_dump() for result in results]+ return self.reasoning_traces++ # Templates for generating reasoning, evaluation and improving them.+ REASONING_TEMPLATE = """Let's solve this step by step:+Problem: {problem}+1. First, let's understand what we're asked+2. Let's break this down into parts+3. Let's solve each part systematically+4. Finally, let's verify our solution++{few_shot_examples}++Please show your complete reasoning process."""++ EVALUATION_TEMPLATE = """Please evaluate this reasoning trace and+provide scores and feedback in valid JSON format.++Problem: {problem}++{solution}++Reasoning Trace:+{trace}++Evaluate for:+1. Correctness (Is each step logically sound?)+2. Clarity (Is the explanation clear and well-structured?)+3. Completeness (Are all necessary steps included?)++Respond ONLY with a JSON object in this exact format:+{{+ "correctness": <score between 0 and 1>,+ "clarity": <score between 0 and 1>,+ "completeness": <score between 0 and 1>,+ "feedback": "<specific feedback for improvement>"+}}"""++ IMPROVEMENT_TEMPLATE = """Based on this feedback, generate an+improved reasoning trace:+Problem: {problem}++{solution}++Previous Trace:+{trace}++Feedback:+{feedback}++Generate a new, improved reasoning trace that addresses the feedback."""diff --git a/camel/toolkits/reddit_toolkit.py b/camel/toolkits/reddit_toolkit.pyindex 1415a578b..6d8f8778b 100644--- a/camel/toolkits/reddit_toolkit.py+++ b/camel/toolkits/reddit_toolkit.py@@ -16,10 +16,9 @@ import osimport timefrom typing import Any, Dict, List, Union-from requests.exceptions import RequestException-from camel.toolkits import FunctionToolfrom camel.toolkits.base import BaseToolkit+from camel.utils import retry_on_errorclass RedditToolkit(BaseToolkit):@@ -61,30 +60,7 @@ class RedditToolkit(BaseToolkit):request_timeout=30, # Set a timeout to handle delays)- def _retry_request(self, func, *args, **kwargs):- r"""Retries a function in case of network-related errors.-- Args:- func (callable): The function to be retried.- *args: Arguments to pass to the function.- **kwargs: Keyword arguments to pass to the function.-- Returns:- Any: The result of the function call if successful.-- Raises:- RequestException: If all retry attempts fail.- """- for attempt in range(self.retries):- try:- return func(*args, **kwargs)- except RequestException as e:- print(f"Attempt {attempt + 1}/{self.retries} failed: {e}")- if attempt < self.retries - 1:- time.sleep(self.delay)- else:- raise-+ @retry_on_error()def collect_top_posts(self,subreddit_name: str,@@ -113,8 +89,8 @@ class RedditToolkit(BaseToolkit):"Please set the environment variables.")- subreddit = self._retry_request(self.reddit.subreddit, subreddit_name)- top_posts = self._retry_request(subreddit.top, limit=post_limit)+ subreddit = self.reddit.subreddit(subreddit_name)+ top_posts = subreddit.top(limit=post_limit)data = []for post in top_posts:@@ -122,9 +98,7 @@ class RedditToolkit(BaseToolkit):"Post Title": post.title,"Comments": [{"Comment Body": comment.body, "Upvotes": comment.score}- for comment in self._retry_request(- lambda post=post: list(post.comments)- )[:comment_limit]+ for comment in list(post.comments)[:comment_limit]],}data.append(post_data)@@ -192,15 +166,11 @@ class RedditToolkit(BaseToolkit):data = []for subreddit_name in subreddits:- subreddit = self._retry_request(- self.reddit.subreddit, subreddit_name- )- top_posts = self._retry_request(subreddit.top, limit=post_limit)+ subreddit = self.reddit.subreddit(subreddit_name)+ top_posts = subreddit.top(limit=post_limit)for post in top_posts:- for comment in self._retry_request(- lambda post=post: list(post.comments)- )[:comment_limit]:+ for comment in list(post.comments)[:comment_limit]:# Print comment body for debuggingif any(keyword.lower() in comment.body.lower()diff --git a/camel/toolkits/whatsapp_toolkit.py b/camel/toolkits/whatsapp_toolkit.pyindex 80f778cfa..f2859e675 100644--- a/camel/toolkits/whatsapp_toolkit.py+++ b/camel/toolkits/whatsapp_toolkit.py@@ -19,7 +19,7 @@ import requestsfrom camel.toolkits import FunctionToolfrom camel.toolkits.base import BaseToolkit-from camel.utils.commons import retry_request+from camel.utils import retry_on_errorclass WhatsAppToolkit(BaseToolkit):@@ -36,18 +36,8 @@ class WhatsAppToolkit(BaseToolkit):version (str): API version."""- def __init__(self, retries: int = 3, delay: int = 1):- r"""Initializes the WhatsAppToolkit with the specified number of- retries and delay.-- Args:- retries (int): Number of times to retry the request in case of- failure. (default: :obj:`3`)- delay (int): Time in seconds to wait between retries.- (default: :obj:`1`)- """- self.retries = retries- self.delay = delay+ def __init__(self):+ r"""Initializes the WhatsAppToolkit."""self.base_url = "https://graph.facebook.com"self.version = "v17.0"@@ -61,6 +51,7 @@ class WhatsAppToolkit(BaseToolkit):"WHATSAPP_PHONE_NUMBER_ID environment variables.")+ @retry_on_error()def send_message(self, to: str, message: str) -> Union[Dict[str, Any], str]:@@ -88,19 +79,15 @@ class WhatsAppToolkit(BaseToolkit):}try:- response = retry_request(- requests.post,- retries=self.retries,- delay=self.delay,- url=url,- headers=headers,- json=data,- )+ response = requests.post(url=url, headers=headers, json=data)response.raise_for_status()return response.json()+ except requests.exceptions.RequestException as e:+ raise eexcept Exception as e:return f"Failed to send message: {e!s}"+ @retry_on_error()def get_message_templates(self) -> Union[List[Dict[str, Any]], str]:r"""Retrieves all message templates for the WhatsApp Business account.@@ -116,18 +103,13 @@ class WhatsAppToolkit(BaseToolkit):headers = {"Authorization": f"Bearer {self.access_token}"}try:- response = retry_request(- requests.get,- retries=self.retries,- delay=self.delay,- url=url,- headers=headers,- )+ response = requests.get(url=url, headers=headers)response.raise_for_status()return response.json().get("data", [])except Exception as e:return f"Failed to retrieve message templates: {e!s}"+ @retry_on_error()def get_business_profile(self) -> Union[Dict[str, Any], str]:r"""Retrieves the WhatsApp Business profile information.@@ -149,10 +131,7 @@ class WhatsAppToolkit(BaseToolkit):}try:- response = retry_request(- requests.get,- retries=self.retries,- delay=self.delay,+ response = requests.get(url=url,headers=headers,params=params,diff --git a/camel/types/enums.py b/camel/types/enums.pyindex dc5c0501b..b549b8d9a 100644--- a/camel/types/enums.py+++ b/camel/types/enums.py@@ -218,7 +218,11 @@ class ModelType(UnifiedModelType, Enum):@propertydef support_native_structured_output(self) -> bool:- return self.is_openai+ return any(+ [+ self.is_openai,+ ]+ )@propertydef support_native_tool_calling(self) -> bool:diff --git a/camel/utils/__init__.py b/camel/utils/__init__.pyindex 448670c27..481471f3c 100644--- a/camel/utils/__init__.py+++ b/camel/utils/__init__.py@@ -14,6 +14,7 @@from .commons import (AgentOpsMeta,+ BatchProcessor,agentops_decorator,api_keys_required,check_server_running,@@ -33,6 +34,7 @@ from .commons import (is_docker_running,json_to_function_code,print_text_animated,+ retry_on_error,text_extract_from_web,to_pascal,track_agent,@@ -80,4 +82,6 @@ __all__ = ["get_pydantic_model","download_github_subdirectory","generate_prompt_for_structured_output",+ "retry_on_error",+ "BatchProcessor",]diff --git a/camel/utils/commons.py b/camel/utils/commons.pyindex a131f4177..29a82f86a 100644--- a/camel/utils/commons.py+++ b/camel/utils/commons.py@@ -11,7 +11,9 @@# See the License for the specific language governing permissions and# limitations under the License.# ========= Copyright 2023-2024 @ CAMEL-AI.org. All Rights Reserved. =========+import functoolsimport importlib+import loggingimport osimport platformimport re@@ -47,6 +49,8 @@ from .constants import ConstantsF = TypeVar('F', bound=Callable[..., Any])+logger = logging.getLogger(__name__)+def print_text_animated(text, delay: float = 0.02, end: str = ""):r"""Prints the given text with an animated effect.@@ -620,33 +624,206 @@ def handle_http_error(response: requests.Response) -> str:return "HTTP Error"-def retry_request(- func: Callable, retries: int = 3, delay: int = 1, *args: Any, **kwargs: Any-) -> Any:- r"""Retries a function in case of any errors.+def retry_on_error(+ max_retries: int = 3, initial_delay: float = 1.0+) -> Callable:+ r"""Decorator to retry function calls on exception with exponential+ backoff.Args:- func (Callable): The function to be retried.- retries (int): Number of retry attempts. (default: :obj:`3`)- delay (int): Delay between retries in seconds. (default: :obj:`1`)- *args: Arguments to pass to the function.- **kwargs: Keyword arguments to pass to the function.+ max_retries (int): Maximum number of retry attempts+ initial_delay (float): Initial delay between retries in secondsReturns:- Any: The result of the function call if successful.+ Callable: Decorated function with retry logic+ """- Raises:- Exception: If all retry attempts fail.+ def decorator(func: Callable) -> Callable:+ @functools.wraps(func)+ def wrapper(*args, **kwargs):+ delay = initial_delay+ last_exception = None++ for attempt in range(max_retries + 1):+ try:+ return func(*args, **kwargs)+ except Exception as e:+ last_exception = e+ if attempt == max_retries:+ logger.error(+ f"Failed after {max_retries} retries: {e!s}"+ )+ raise++ logger.warning(+ f"Attempt {attempt + 1} failed: {e!s}. "+ f"Retrying in {delay:.1f}s..."+ )+ time.sleep(delay)+ delay *= 2 # Exponential backoff++ raise last_exception++ return wrapper++ return decorator+++class BatchProcessor:+ r"""Handles batch processing with dynamic sizing and error handling based+ on system load."""- for attempt in range(retries):- try:- return func(*args, **kwargs)- except Exception as e:- print(f"Attempt {attempt + 1}/{retries} failed: {e}")- if attempt < retries - 1:- time.sleep(delay)- else:- raise++ def __init__(+ self,+ max_workers: Optional[int] = None,+ initial_batch_size: Optional[int] = None,+ monitoring_interval: float = 5.0,+ cpu_threshold: float = 80.0,+ memory_threshold: float = 85.0,+ ):+ r"""Initialize the BatchProcessor with dynamic worker allocation.++ Args:+ max_workers: Maximum number of workers. If None, will be+ determined dynamically based on system resources.+ (default: :obj:`None`)+ initial_batch_size: Initial size of each batch. If `None`,+ defaults to `10`. (default: :obj:`None`)+ monitoring_interval: Interval in seconds between resource checks.+ (default: :obj:`5.0`)+ cpu_threshold: CPU usage percentage threshold for scaling down.+ (default: :obj:`80.0`)+ memory_threshold: Memory usage percentage threshold for scaling+ down. (default: :obj:`85.0`)+ """+ import psutil++ self.monitoring_interval = monitoring_interval+ self.cpu_threshold = cpu_threshold+ self.memory_threshold = memory_threshold+ self.last_check_time = time.time()+ self.psutil = psutil++ # Initialize performance metrics+ self.total_processed = 0+ self.total_errors = 0+ self.processing_times: List = []++ if max_workers is None:+ self.max_workers = self._calculate_optimal_workers()+ else:+ self.max_workers = max_workers++ self.batch_size = (+ 10 if initial_batch_size is None else initial_batch_size+ )+ self.min_batch_size = 1+ self.max_batch_size = 20+ self.backoff_factor = 0.8+ self.success_factor = 1.2++ # Initial resource check+ self._update_resource_metrics()++ def _calculate_optimal_workers(self) -> int:+ r"""Calculate optimal number of workers based on system resources."""+ cpu_count = self.psutil.cpu_count()+ cpu_percent = self.psutil.cpu_percent(interval=1)+ memory = self.psutil.virtual_memory()++ # Base number of workers on CPU count and current load+ if cpu_percent > self.cpu_threshold:+ workers = max(1, cpu_count // 4)+ elif cpu_percent > 60:+ workers = max(1, cpu_count // 2)+ else:+ workers = max(1, cpu_count - 1)++ # Further reduce if memory is constrained+ if memory.percent > self.memory_threshold:+ workers = max(1, workers // 2)++ return workers++ def _update_resource_metrics(self) -> None:+ r"""Update current resource usage metrics."""+ self.current_cpu = self.psutil.cpu_percent()+ self.current_memory = self.psutil.virtual_memory().percent+ self.last_check_time = time.time()++ def _should_check_resources(self) -> bool:+ r"""Determine if it's time to check resource usage again."""+ return time.time() - self.last_check_time >= self.monitoring_interval++ def adjust_batch_size(+ self, success: bool, processing_time: Optional[float] = None+ ) -> None:+ r"""Adjust batch size based on success/failure and system resources.++ Args:+ success (bool): Whether the last batch completed successfully+ processing_time (Optional[float]): Time taken to process the last+ batch. (default: :obj:`None`)+ """+ # Update metrics+ self.total_processed += 1+ if not success:+ self.total_errors += 1+ if processing_time is not None:+ self.processing_times.append(processing_time)++ # Check system resources if interval has elapsed+ if self._should_check_resources():+ self._update_resource_metrics()++ # Adjust based on resource usage+ if (+ self.current_cpu > self.cpu_threshold+ or self.current_memory > self.memory_threshold+ ):+ self.batch_size = max(+ int(self.batch_size * self.backoff_factor),+ self.min_batch_size,+ )+ self.max_workers = max(1, self.max_workers - 1)+ return++ # Adjust based on success/failure+ if success:+ self.batch_size = min(+ int(self.batch_size * self.success_factor), self.max_batch_size+ )+ else:+ self.batch_size = max(+ int(self.batch_size * self.backoff_factor), self.min_batch_size+ )++ def get_performance_metrics(self) -> Dict[str, Any]:+ r"""Get current performance metrics.++ Returns:+ Dict containing performance metrics including:+ - total_processed: Total number of batches processed+ - error_rate: Percentage of failed batches+ - avg_processing_time: Average time per batch+ - current_batch_size: Current batch size+ - current_workers: Current number of workers+ - current_cpu: Current CPU usage percentage+ - current_memory: Current memory usage percentage+ """+ metrics = {+ "total_processed": self.total_processed,+ "error_rate": (self.total_errors / max(1, self.total_processed))+ * 100,+ "avg_processing_time": sum(self.processing_times)+ / max(1, len(self.processing_times)),+ "current_batch_size": self.batch_size,+ "current_workers": self.max_workers,+ "current_cpu": self.current_cpu,+ "current_memory": self.current_memory,+ }+ return metricsdef download_github_subdirectory(diff --git a/docs/camel.rst b/docs/camel.rstindex 449642d53..740b64a11 100644--- a/docs/camel.rst+++ b/docs/camel.rst@@ -9,6 +9,7 @@ Subpackagescamel.agentscamel.configs+ camel.datagencamel.embeddingscamel.interpreterscamel.loadersdiff --git a/docs/cookbooks/data_generation/index.rst b/docs/cookbooks/data_generation/index.rstindex 91fa5114a..1cda3b317 100644--- a/docs/cookbooks/data_generation/index.rst+++ b/docs/cookbooks/data_generation/index.rst@@ -21,3 +21,4 @@ Agentic Data Generationdata_model_generation_and_structured_output_with_qwendistill_math_reasoning_data_from_deepseek_r1self_improving_math_reasoning_data_distillation_from_deepSeek_r1+ self_improving_cot_generationdiff --git a/docs/cookbooks/data_generation/self_improving_cot_generation.md b/docs/cookbooks/data_generation/self_improving_cot_generation.mdnew file mode 100644index 000000000..33382503b--- /dev/null+++ b/docs/cookbooks/data_generation/self_improving_cot_generation.md@@ -0,0 +1,345 @@+# Deep Dive into CAMEL’s Practices for Self-Improving CoT Generation 🚀++The field of AI is rapidly evolving, with reasoning models playing a crucial role in enhancing the problem-solving capabilities of large language models (LLMs). Recent developments, such as DeepSeek's R1 and OpenAI's o3-mini, demonstrate the industry's commitment to advancing reasoning through innovative approaches.++DeepSeek's R1 model, introduced in January 2025, has shown remarkable proficiency in tasks that require complex reasoning and code generation. Its exceptional performance in areas like mathematics, science, and programming is particularly noteworthy.++By distilling Chain-of-Thought (CoT) data from reasoning models, we can generate high-quality reasoning traces that are more accurate in solving complex problems. These generated data can be used to further fine-tune another LLM with less parameters, thereby enhancing its reasoning ability.++CAMEL developed an approach leverages iterative refinement, self-assessment, and efficient batch processing to enable the continuous improvement of reasoning traces. In this blog, we will delve into how CAMEL implements its self-improving CoT pipeline.++---++## 1. Overview of the End-to-End Pipeline 🔍++### 1.1 Why an Iterative CoT Pipeline?++One-time CoT generation often leads to incomplete or suboptimal solutions. CAMEL addresses this challenge by employing a multi-step, iterative approach:++1. **Generate** an initial reasoning trace.+2. **Evaluate** the trace through either a dedicated evaluation agent or a specialized reward model.+3. **Refine** the trace based on the feedback provided.++This self-improving methodology ensures that the reasoning process improves progressively, meeting specific thresholds for correctness, clarity, and completeness. Each iteration enhances the model's ability to solve the problem by learning from the previous outputs and evaluations.++### 1.2 Core Components++The self-improving pipeline consists of three key components:+1. **`reason_agent`:** This agent is responsible for generating or improving reasoning traces.+2. **`evaluate_agent`:** An optional agent that evaluates the quality of the reasoning trace. This can be replaced by a reward model if needed.+3. **`reward_model`:** An optional model that provides numerical feedback on the trace, evaluating dimensions such as correctness, coherence, complexity, and verbosity.++Here's a high-level diagram of the pipeline:++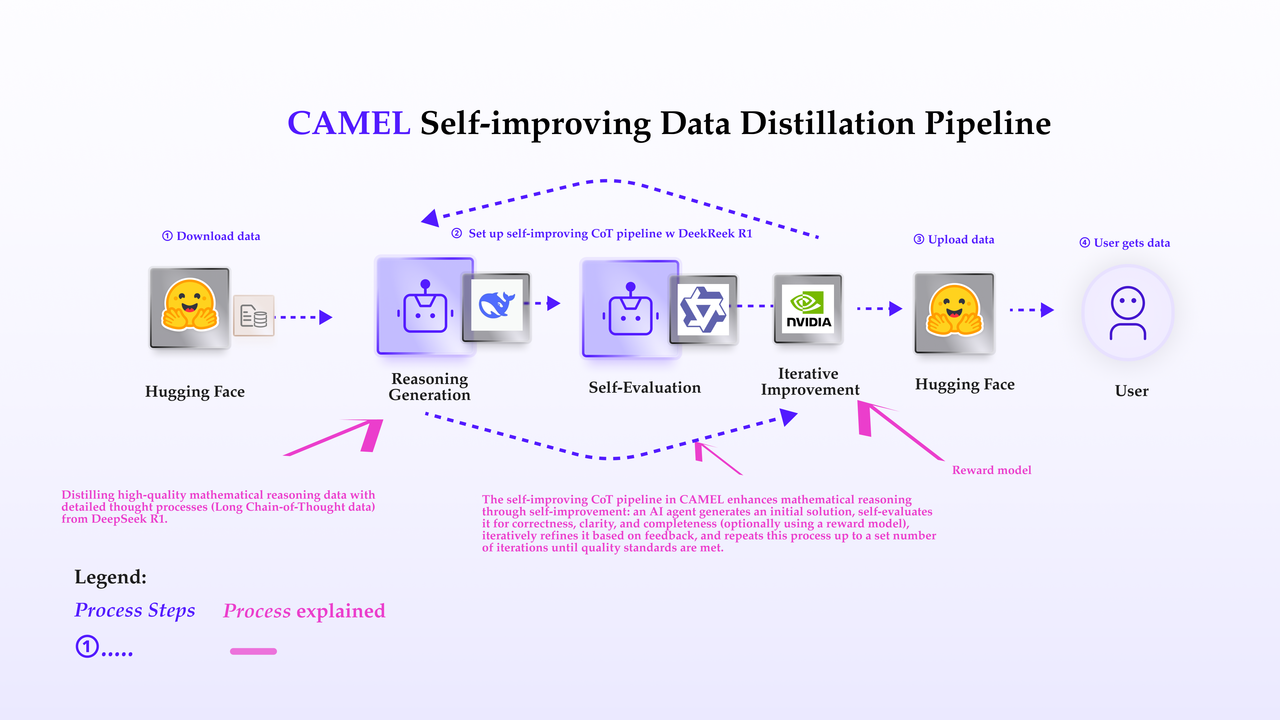++---++## 2. Generation of CoT Data: The Heart of the Pipeline 🤖++Generating CoT data is at the core of the pipeline. Below, we outline the process in detail.++### 2.1 Initial Trace Generation 🐣++The first step in the process is the generation of an initial reasoning trace. The **`reason_agent`** plays a central role here, creating a coherent and logical explanation of how to solve a given problem. The agent breaks down the problem into smaller steps, illustrating the thought process at each stage. We also support the use of non-reasoning LLMs to generate traces through prompt engineering.++The generation could also guided by **few-shot examples**, which provide context and help the agent understand the desired reasoning style. Here’s how this is accomplished:++- **Input**: The problem statement is provided to the **`reason_agent`**, we can optionally provide the ground truth to guide the reasoning process.+- **Output**: The agent generates a sequence of reasoning content.++This initial generation serves as a foundational reasoning process that can be directly useful or further refined.++### 2.2 Evaluation of the Initial Trace 📒++Once the reasoning trace is generated, it is evaluated for its quality. This evaluation serves two purposes:++- **Detecting weaknesses**: The evaluation identifies areas where the reasoning trace could be further improved.+- **Providing feedback**: The evaluation produces feedback that guides the agent in refining the reasoning trace. This feedback can come from either the **`evaluate_agent`** or a **`reward_model`**.++#### 2.2.1 Agent-Based Evaluation++If an **`evaluate_agent`** is available, it examines the reasoning trace for:+1. **Correctness**: Does the trace logically solve the problem?+2. **Clarity**: Is the reasoning easy to follow and well-structured?+3. **Completeness**: Are all necessary steps included in the reasoning?++The feedback from the agent provides insights into areas for improvement, such as unclear reasoning or incorrect answers, offering a more generalized approach compared to rule-based matching.++#### 2.2.2 Reward Model Evaluation++Alternatively, the pipeline supports using a **reward model** to evaluate the trace. The reward model outputs scores based on predefined dimensions such as correctness, coherence, complexity, and verbosity.++---++### 2.3 Iterative Refinement: The Self-Improving Cycle 🔁++The key to CAMEL's success in CoT generation is its **self-improving loop**. After the initial trace is generated and evaluated, the model refines the trace based on the evaluation feedback. This process is repeated in a loop.++#### How does this iterative refinement work?++1. **Feedback Integration**: The feedback from the evaluation phase is used to refine the reasoning. This could involve rewording unclear parts, adding missing steps, or adjusting the logic to make it more correct or complete.++2. **Improvement through Reasoning**: After receiving feedback, the **`reason_agent`** is used again to generate an improved version of the reasoning trace. This trace incorporates the feedback provided, refining the earlier steps and enhancing the overall reasoning.++3. **Re-evaluation**: Once the trace is improved, the new version is evaluated again using the same process (either agent-based evaluation or reward model). This new trace is assessed against the same criteria to ensure the improvements have been made.++4. **Threshold Check**: The iterative process continues until the desired quality thresholds are met or reached the maximum number of iterations.++---++## 3. Pipeline Setup in Code 💻++Below is a truncated version of our pipeline initialization. We encapsulate logic in a class called `SelfImprovingCoTPipeline`:++```python+class SelfImprovingCoTPipeline:+ def __init__(+ self,+ reason_agent: ChatAgent,+ problems: List[Dict],+ max_iterations: int = 3,+ score_threshold: Union[float, Dict[str, float]] = 0.7,+ evaluate_agent: Optional[ChatAgent] = None,+ reward_model: Optional[BaseRewardModel] = None,+ output_path: Optional[str] = None,+ few_shot_examples: Optional[str] = None,+ batch_size: Optional[int] = None,+ max_workers: Optional[int] = None,+ solution_pattern: str = r'\\boxed{(.*?)}',+ trace_pattern: Optional[str] = None,+ ):+ r"""Initialize the STaR pipeline.++ Args:+ reason_agent (ChatAgent): The chat agent used for generating and+ improving reasoning traces.+ problems (List[Dict]): List of problem dictionaries to process.+ max_iterations (int, optional): Maximum number of improvement+ iterations. If set to `0`, the pipeline will generate an+ initial trace without any improvement iterations.+ (default: :obj:`3`)+ score_threshold (Union[float, Dict[str, float]], optional):+ Quality threshold. Can be either a single float value applied+ to average score, or a dictionary mapping score dimensions to+ their thresholds. For example: {"correctness": 0.8,+ "coherence": 0.7}. If using reward model and threshold for a+ dimension is not specified, will use the default value 0.7.+ (default: :obj:`0.7`)+ evaluate_agent (Optional[ChatAgent]): The chat agent used for+ evaluating reasoning traces. (default: :obj:`None`)+ reward_model (BaseRewardModel, optional): Model used to evaluate+ reasoning traces. If `None`, uses Agent self-evaluation.+ (default: :obj:`None`)+ output_path (str, optional): Output path for saving traces. If+ `None`, results will only be returned without saving to file.+ (default: :obj:`None`)+ few_shot_examples (str, optional): Examples to use for few-shot+ generation. (default: :obj:`None`)+ batch_size (int, optional): Batch size for parallel processing.+ (default: :obj:`None`)+ max_workers (int, optional): Maximum number of worker threads.+ (default: :obj:`None`)+ solution_pattern (str, optional): Regular expression pattern with+ one capture group to extract answers from solution text.+ (default: :obj:`r'\\boxed{(.*?)}'`)+ trace_pattern (str, optional): Regular expression pattern with one+ capture group to extract answers from trace text. If `None`,+ uses the same pattern as solution_pattern.+ (default: :obj:`None`)+ """+ ...+```++**Example usage:**++```python+from camel.agents import ChatAgent+from camel.datagen import SelfImprovingCoTPipeline++# Initialize agents+reason_agent = ChatAgent(+ "You are a struggling student who finds solving math problems challenging. "+ "Your reasoning process is often flawed or lacks clarity when explaining "+ "your answers to others."+)++evaluate_agent = ChatAgent(+ "You are a highly critical teacher who evaluates the student's answers "+ "with a meticulous and demanding approach."+)++# Prepare your problems+problems = [+ {"problem": "Your problem text here"},+ # Add more problems...+]++# Create and run the pipeline+pipeline = SelfImprovingCoTPipeline(+ reason_agent=reason_agent,+ evaluate_agent=evaluate_agent,+ problems=problems,+ max_iterations=3,+ output_path="star_output.json"+)++results = pipeline.generate()+```++---++## 4. Batch Processing & API Request Handling 📦++### 4.1 The Need for Batch Processing ⏰++Early on, we tried generating CoT reasoning for each problem one by one. This approach quickly revealed two major issues:++1. **Time consumption**: Sequential processing doesn't scale to large problem sets.+2. **API request bottlenecks**: Slowdowns or occasional disconnections occurred when handling numerous calls.++Hence, we introduced a parallel **`BatchProcessor`** to:++- Split the tasks into manageable batches.+- Dynamically adjust batch size (`batch_size`) based on the success/failure rates and system resource usage (CPU/memory).+- Retry on transient errors or API timeouts to maintain a stable flow.++Below shows how we batch-process multiple problems:++```python+async def _batch_process_problems(+ self, problems: List[Dict], rationalization: bool+) -> List[ProblemResult]:+ results = []+ total_problems = len(problems)+ processed = 0++ while processed < total_problems:+ batch_size = self.batch_processor.batch_size+ batch = problems[processed : processed + batch_size]+ batch_start_time = time.time()++ with ThreadPoolExecutor(max_workers=self.batch_processor.max_workers) as executor:+ futures = [+ executor.submit(+ self.process_problem,+ problem=problem,+ rationalization=rationalization,+ )+ for problem in batch+ ]+ ...+ processed += len(batch)+ ...+ # Log progress & performance+```++### 4.2 Handling API Instability 🚨++Even with batching, API requests for LLMs can fail due to network fluctuations or remote server instability. We implemented a `retry_on_error` decorator:++```python+def retry_on_error(+ max_retries: int = 3, initial_delay: float = 1.0+) -> Callable:+ def decorator(func: Callable) -> Callable:+ @functools.wraps(func)+ def wrapper(*args, **kwargs):+ delay = initial_delay+ for attempt in range(max_retries + 1):+ try:+ return func(*args, **kwargs)+ except Exception as e:+ if attempt == max_retries:+ raise+ time.sleep(delay)+ delay *= 2+ raise+ return wrapper+ return decorator+```++Whenever we invoke LLM calls for generation, evaluation, or improvement, these decorated methods gracefully handle transient errors by retrying with exponential backoff (doubling the wait time after each failed attempt).++---++## 5. Model Switching & Dynamic File Writing 📝++### 5.1 Flexible Model Scheduling 🕒++In CAMEL's CoT pipeline, adding models to the `ChatAgent` is useful for handling errors and ensuring smooth operation. This setup allows the system to switch between models as needed, maintaining reasoning continuity.++To add models to a `ChatAgent`, you can create instances of models and include them in the agent's model list:++```python+model1 = ModelFactory.create(+ model_platform=ModelPlatformType.DEEPSEEK,+ model_type="deepseek-reasoner",+ ...+)++model2 = ModelFactory.create(+ model_platform=ModelPlatformType.TOGETHER,+ model_type="deepseek-reasoner",+ ...+)++agent = ChatAgent(+ system_message,+ model=[model1, model2]+)+```++By incorporating multiple models, CAMEL can effectively manage model availability and ensure robust error handling.++### 5.2 Real-Time JSON Updates 🔄++As soon as a problem’s results are ready, we lock the file (`output_path`) and update it in-place—rather than saving everything at the very end. This ensures data integrity if the process is interrupted partway through.++```python+def safe_write_json(self, file_path, data):+ temp_path = file_path + ".tmp"+ with open(temp_path, "w") as f:+ json.dump(data, f, indent=2)+ os.replace(temp_path, file_path)+```++This two-step write (to a `.tmp` file then replace) prevents partial writes from corrupting the output file.++---++## 6. CAMEL’s Next Steps in CoT Data Generation 🚀++1. **Real-Time Monitoring Dashboard**: Visualize throughput, error rates, running cost, data quality, etc. for smooth operational oversight.+2. **Performance Enhancements**: Further improve performance and add more error handling to make the system more robust.+3. **Cutting-Edge Research Solutions**: Integrate more cutting-edge research solutions for synthetic data generation.+4. **Rejection Sampling**: Integrate rejection sampling method to the SelfImprovingCoT pipeline.++---++## Conclusion 📚++CAMEL’s self-improving pipeline exemplifies a comprehensive approach to Chain-of-Thought data generation:++- **Flexible Evaluation**: Utilizing agent-based or reward-model-based evaluation provides adaptable scoring and feedback loops.+- **Continuous Improvement**: Iterative refinement ensures each reasoning trace is enhanced until it meets the desired quality.+- **Efficient Processing**: Batched concurrency increases throughput while maintaining system balance.+- **Robust Stability**: Error-tolerant mechanisms with retries enhance system reliability.+- **Consistent Output**: Dynamic file writing ensures partial results are consistently preserved and valid.++Looking ahead, CAMEL’s roadmap is dedicated to pioneering advanced synthetic data generation methods, integrating cutting-edge research and technology.++_Stay tuned for more updates on CAMEL's journey in advancing agentic synthetic data generation!_++---++**Further Reading & Resources**++- **CAMEL GitHub**: Explore our open-source projects on [GitHub](https://github.com/camel-ai/camel) and give us a 🌟star.++**Data Generation Cookbooks**++- [Self-Improving Math Reasoning Data Distillation](https://docs.camel-ai.org/cookbooks/data_generation/self_improving_math_reasoning_data_distillation_from_deepSeek_r1.html)+- [Generating High-Quality SFT Data with CAMEL](https://docs.camel-ai.org/cookbooks/data_generation/sft_data_generation_and_unsloth_finetuning_Qwen2_5_7B.html)+- [Function Call Data Generation and Evaluation](https://docs.camel-ai.org/cookbooks/data_generation/data_gen_with_real_function_calls_and_hermes_format.html)+- [Agentic Data Generation, Evaluation & Filtering with Reward Models](https://docs.camel-ai.org/cookbooks/data_generation/synthetic_dataevaluation%26filter_with_reward_model.html)\ No newline at end of filediff --git a/docs/key_modules/datagen.md b/docs/key_modules/datagen.mdnew file mode 100644index 000000000..25f15bddb--- /dev/null+++ b/docs/key_modules/datagen.md@@ -0,0 +1,493 @@+# Data Generation Modules++This document describes the key data generation modules in CAMEL: Chain of Thought (CoT), Self-Instruct, Source2Synth, and STaR.++## Chain of Thought (CoT) Data Generation++### Overview++The Chain of Thought (CoT) data generation module implements a sophisticated system for generating high-quality reasoning paths through chat agent interactions. It combines several advanced algorithms to produce and validate reasoning chains.++### Key Features++- Monte Carlo Tree Search (MCTS) for solution exploration+- Binary Search Error Detection for precise error localization+- Dual-Agent Verification System for quality assurance+- Solution Tree Management for tracking reasoning paths++### Core Components++#### CoTDataGenerator Class++The main class that implements the CoT generation system with the following capabilities:++- **Dual-Agent Architecture**: Supports both single-agent (legacy) and dual-agent modes+- **Answer Generation**: Sophisticated answer generation with MCTS+- **Answer Verification**: Robust verification system using golden answers+- **Error Detection**: Binary search-based error detection in solutions+- **Solution Management**: Comprehensive solution tree management and export++### Usage++#### Basic Example++```python+from camel.agents import ChatAgent+from camel.datagen import CoTDataGenerator++# Initialize agents+generator_agent = ChatAgent("System message for generator")+verifier_agent = ChatAgent("System message for verifier")++# Define golden answers+golden_answers = {+ "question1": "answer1",+ "question2": "answer2"+}++# Create generator+cot_generator = CoTDataGenerator(+ generator_agent=generator_agent,+ verifier_agent=verifier_agent,+ golden_answers=golden_answers,+ search_limit=100+)++# Generate solution+solution = cot_generator.solve("question1")+```++#### Data Import/Export++```python+# Import QA pairs from JSON+cot_generator.import_qa_from_json("qa_pairs.json")++# Export solutions+cot_generator.export_solutions("solutions.json")+```++### Solution Generation Process++1. **Direct Solution Attempt**+ - First tries to solve the problem directly+ - Verifies against golden answer++2. **MCTS-based Exploration**+ - If direct solution fails, uses MCTS to explore solution space+ - Builds solution tree based on previous attempts++3. **Error Detection and Correction**+ - Uses binary search to locate errors in solutions+ - Generates new solutions based on correct parts++4. **Solution Verification**+ - Verifies solutions using dual-agent system or golden answers+ - Maintains solution quality through strict verification++### Configuration Options++- `search_limit`: Maximum number of search iterations (default: 100)+- `generator_agent`: Specialized agent for answer generation+- `verifier_agent`: Specialized agent for answer verification+- `golden_answers`: Pre-defined correct answers for validation++### Output Format++The solution tree is exported in JSON format containing:+- Solutions with intermediate steps+- Golden answers used for verification+- Export timestamp+- Solution scores and verification results+++## Self-Instruct: Instruction Generation++### Overview++The Self-Instruct module implements a pipeline for generating and managing machine-generated instructions for tasks. It combines human-written seed instructions with machine-generated ones to create diverse, high-quality task instructions, while ensuring quality through configurable filtering mechanisms.++### Core Components++#### Self Instruct Pipeline++The main pipeline class that orchestrates the instruction generation process.++Key Features:+- Combines human-written and machine-generated instructions using configurable ratios+- Supports classification and non-classification task types+- Built-in instruction filtering and validation+- Automatic instance generation for tasks+- JSON-based data input/output++#### Instruction Filter++A comprehensive filtering system for validating and filtering generated instructions.++Features:+- Length-based filtering+- Keyword filtering+- Punctuation checks+- Non-English text detection+- ROUGE similarity filtering for deduplication+- Extensible filter registry for custom filters++### Usage++#### Basic Example++```python+from camel.agents import ChatAgent+from camel.datagen.self_instruct import SelfInstructPipeline++# Initialize agent+agent = ChatAgent()++# Create pipeline with default settings+pipeline = SelfInstructPipeline(+ agent=agent,+ seed='seed_tasks.jsonl', # Path to human-written seed tasks+ num_machine_instructions=5,+ data_output_path='./data_output.json',+ human_to_machine_ratio=(6, 2) # Use 6 human tasks and 2 machine tasks for generation+)++# Generate instructions+pipeline.generate()+```++#### Custom Filtering++```python+from camel.datagen.self_instruct import SelfInstructPipeline+from camel.datagen.self_instruct.filter import InstructionFilter++# Configure filters+filter_config = {+ "length": {}, # Default length constraints+ "keyword": {}, # Keyword-based filtering+ "punctuation": {}, # Punctuation checks+ "non_english": {}, # Non-English text detection+ "rouge_similarity": { # ROUGE-based similarity filtering+ "threshold": 0.7,+ "metric": "rouge-l"+ }+}++# Create pipeline with custom filter configuration+pipeline = SelfInstructPipeline(+ agent=agent,+ seed='seed_tasks.jsonl',+ instruction_filter=InstructionFilter(filter_config),+ num_machine_instructions=5+)+```++### Configuration Options++#### Pipeline Parameters++- `agent`: ChatAgent instance for generating instructions+- `seed`: Path to human-written seed tasks in JSONL format+- `num_machine_instructions`: Number of machine-generated instructions to generate (default: 5)+- `data_output_path`: Path for saving generated data (default: './data_output.json')+- `human_to_machine_ratio`: Ratio of human to machine tasks for generation (default: (6, 2))+- `instruction_filter`: Custom InstructionFilter instance (optional)+- `filter_config`: Configuration dictionary for default filters (optional)++#### Filter Configuration++The default filter configuration includes:+- `length`: Configure length constraints for instructions+- `keyword`: Set up keyword-based filtering rules+- `punctuation`: Define punctuation validation rules+- `non_english`: Configure non-English text detection+- `rouge_similarity`: Set ROUGE similarity thresholds for deduplication++### Pipeline Stages++1. **Seed Loading**+ - Load human-written instructions from JSONL file+ - Validate seed format+ - Initialize task storage++2. **Instruction Generation**+ - Sample human and machine tasks based on ratio+ - Generate new instructions using ChatAgent+ - Apply instruction filters++3. **Task Classification**+ - Identify if tasks are classification or non-classification+ - Generate appropriate prompts based on task type++4. **Instance Generation**+ - Generate input-output pairs for each task+ - Parse and format instances based on task type+ - Apply quality filters++5. **Data Output**+ - Save generated tasks and instances to JSON+ - Include metadata and configuration details+ - Maintain structured output format++### Input/Output Format++#### Seed Tasks (Input)+```jsonl+{"instruction": "Classify the sentiment of this text as positive or negative."}+{"instruction": "Generate a summary of the given paragraph."}+```++#### Generated Data (Output)+```json+{+ "machine_instructions": [+ {+ "instruction": "...",+ "is_classification": true,+ "instances": [+ {+ "input": "...",+ "output": "..."+ }+ ]+ }+ ]+}+```+++## Source2Synth: Multi-hop Question-Answer Generation++### Overview++Source2Synth is a sophisticated data generation system designed to create multi-hop question-answer pairs from source text data. It implements a pipeline that processes raw text, extracts information pairs, and generates complex, multi-hop reasoning questions with configurable complexity thresholds.++### Core Components++#### UserDataProcessor++The main orchestrator class that manages the entire pipeline from text processing to dataset generation.++Features:+- Single text and batch processing capabilities+- Configurable AI model or rule-based processing+- Integration with MultiHopGeneratorAgent for QA generation+- Random seed control for reproducibility++#### ExampleConstructor++Handles the construction of training examples from raw text data.++Features:+- Text preprocessing and quality validation+- Information pair extraction with premise-intermediate-conclusion relationships+- Multi-hop QA pair generation using AI or rule-based approaches+- Complexity scoring for generated examples++#### DataCurator++Manages and curates datasets of multi-hop question-answer pairs.++Features:+- Quality filtering based on configurable criteria+- Complexity threshold filtering+- Deduplication of similar examples+- Dataset sampling to achieve target size+- Random seed control for reproducible sampling++### Usage++#### Basic Example++```python+from camel.datagen.source2synth import (+ UserDataProcessor,+ ProcessorConfig+)++# Create configuration+config = ProcessorConfig(+ seed=42,+ min_length=50,+ max_length=1000,+ complexity_threshold=0.5,+ dataset_size=10,+ use_ai_model=True,+)++# Initialize processor+processor = UserDataProcessor(config)++# Process a single text+result = processor.process_text(+ "Your source text here",+ source="example_source"+)++# Process multiple texts+texts = ["Text 1", "Text 2", "Text 3"]+sources = ["source1", "source2", "source3"]+batch_results = processor.process_batch(texts, sources)+```++### Configuration Options++#### ProcessorConfig++Key parameters:+- `seed`: Random seed for reproducibility+- `min_length`: Minimum text length for processing+- `max_length`: Maximum text length for processing+- `complexity_threshold`: Minimum complexity score (0.0-1.0)+- `dataset_size`: Target size for the final dataset+- `use_ai_model`: Toggle between AI model and rule-based processing+- `hop_generating_agent`: Custom MultiHopGeneratorAgent instance (optional)++### Pipeline Stages++1. **Text Preprocessing**+ - Length validation+ - Quality checks+ - Text standardization++2. **Information Extraction**+ - Premise identification+ - Intermediate relationship extraction+ - Conclusion formation++3. **QA Generation**+ - Multi-hop question generation+ - Answer validation+ - Complexity scoring++4. **Dataset Curation**+ - Quality filtering+ - Complexity thresholding+ - Deduplication+ - Target size sampling+++## Self-Improving CoT Data Generation++### Overview++The Self-Improving CoT Data Generation pipeline implements an iterative approach to generate and improve reasoning traces for problem-solving tasks. This implementation is based on the methodology of self-taught reasoning, where an AI agent learns to improve its reasoning process through self-evaluation and feedback.++### Architecture++The pipeline consists of four main stages:+1. Initial reasoning trace generation+2. Self-evaluation+3. Feedback-based improvement+4. Iterative refinement++### Key Components++#### SelfImprovingCoTPipeline Class++The core class that implements the STaR methodology with the following features:+- Customizable reasoning and evaluation agents+- Support for both agent-based evaluation and external reward models+- Configurable quality thresholds for different evaluation dimensions+- Iterative improvement process with customizable maximum iterations+- Optional few-shot examples for better reasoning generation+- Flexible output formats and file saving options++### Usage++#### Basic Example++```python+from camel.agents import ChatAgent+from camel.datagen import SelfImprovingCoTPipeline++# Initialize agents+reason_agent = ChatAgent(+ "You are a struggling student who finds solving math problems challenging. "+ "Your reasoning process is often flawed or lacks clarity when explaining "+ "your answers to others."+)++evaluate_agent = ChatAgent(+ "You are a highly critical teacher who evaluates the student's answers "+ "with a meticulous and demanding approach."+)++# Prepare your problems+problems = [+ {"problem": "Your problem text here"},+ # Add more problems...+]++# Create and run the pipeline+pipeline = SelfImprovingCoTPipeline(+ reason_agent=reason_agent,+ evaluate_agent=evaluate_agent,+ problems=problems,+ max_iterations=3,+ output_path="star_output.json"+)++results = pipeline.generate()+```++#### Advanced Usage with External Reward Models++```python+from camel.models.reward import NemotronRewardModel++# Initialize reward model+reward_model = NemotronRewardModel(+ model_type=ModelType.NVIDIA_NEMOTRON_340B_REWARD,+ url="https://integrate.api.nvidia.com/v1",+ api_key="your_api_key"+)++# Create pipeline with reward model+pipeline = SelfImprovingCoTPipeline(+ reason_agent=reason_agent,+ evaluate_agent=evaluate_agent,+ problems=problems,+ reward_model=reward_model,+ score_threshold={+ "correctness": 0.8,+ "clarity": 0.7,+ "completeness": 0.7+ }+)+```++### Input/Output Formats++#### Input Format++The pipeline expects problems in a JSON format:++```json+{+ "problems": [+ {+ "problem": "Problem text here",+ "solution": "Optional solution text"+ }+ ]+}+```++#### Output Format++The pipeline generates output in JSON format containing:+- Original problem+- Final reasoning trace+- Improvement history with iterations+- Evaluation scores and feedback for each iteration++### Configuration Options++- `max_iterations`: Maximum number of improvement iterations (default: 3)+- `score_threshold`: Quality thresholds for evaluation dimensions (default: 0.7)+- `few_shot_examples`: Optional examples for few-shot learning+- `output_path`: Path for saving results (optional)++diff --git a/examples/datagen/self_improving_cot/download_math_datasets.py b/examples/datagen/self_improving_cot/download_math_datasets.pynew file mode 100644index 000000000..1765216b6--- /dev/null+++ b/examples/datagen/self_improving_cot/download_math_datasets.py@@ -0,0 +1,121 @@+# ========= Copyright 2023-2024 @ CAMEL-AI.org. All Rights Reserved. =========+# Licensed under the Apache License, Version 2.0 (the "License");+# you may not use this file except in compliance with the License.+# You may obtain a copy of the License at+#+# http://www.apache.org/licenses/LICENSE-2.0+#+# Unless required by applicable law or agreed to in writing, software+# distributed under the License is distributed on an "AS IS" BASIS,+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.+# See the License for the specific language governing permissions and+# limitations under the License.+# ========= Copyright 2023-2024 @ CAMEL-AI.org. All Rights Reserved. =========++import json+import uuid+from pathlib import Path++from datasets import load_dataset+++def download_gsm8k_dataset():+ try:+ # Load the dataset using the datasets library+ dataset = load_dataset("openai/gsm8k", "main")++ # Get only 20 items from train split+ data = dataset['train'].select(range(10))++ # Convert to the desired format+ formatted_data = []+ for item in data:+ # Extract the final answer from the solution+ solution = item['answer']+ if solution:+ # GSM8K solutions typically end with "#### number"+ import re++ match = re.search(r'####\s*(\d+)', solution)+ if match:+ number = match.group(1)+ # Replace the "#### number" with "\boxed{number}"+ solution = re.sub(+ r'####\s*\d+', f'\\\\boxed{{{number}}}', solution+ )++ formatted_item = {+ "id": str(uuid.uuid4()), # GSM8K doesn't provide IDs+ "problem": item['question'],+ "type": "openai/gsm8k", # All problems are from GSM8K+ "solution": solution, # Use the modified solution with \boxed+ "evaluate_success": False,+ "boxed_answer_success": True,+ "improvement_history": [],+ }+ formatted_data.append(formatted_item)++ # Create output directory if it doesn't exist+ output_dir = Path("examples/datagen/star")+ output_dir.mkdir(exist_ok=True)++ # Save all data to a single JSON file+ output_file = output_dir / "gsm8k_dataset.json"+ with open(output_file, "w", encoding="utf-8") as f:+ json.dump(formatted_data, f, indent=4, ensure_ascii=False)+ print(+ f"Successfully saved {len(formatted_data)} records "+ f"to {output_file}"+ )++ return formatted_data++ except Exception as e:+ print(f"Error downloading GSM8K dataset: {e}")+++def download_amc_aime_dataset():+ try:+ # Load the dataset using the datasets library+ dataset = load_dataset(+ "mlfoundations-dev/bespokelabs-sky-t1-numina-amc-aime-subset-unfiltered"+ )++ # Get the first 4070 items from train split+ data = dataset['train'].select(range(4069))++ # Convert to the desired format+ formatted_data = []+ for item in data:+ formatted_item = {+ "id": str(uuid.uuid4()),+ "problem": item['problem'],+ "type": "amc_aime",+ "solution": item['ground_truth_solution'],+ }+ formatted_data.append(formatted_item)++ # Create output directory if it doesn't exist+ output_dir = Path("examples/datagen/star")+ output_dir.mkdir(exist_ok=True)++ # Save all data to a single JSON file+ output = formatted_data+ output_file = output_dir / "star_r1_output_amc_aime.json"+ with open(output_file, "w", encoding="utf-8") as f:+ json.dump(output, f, indent=4, ensure_ascii=False)+ print(+ f"Successfully saved {len(formatted_data)} records "+ f"to {output_file}"+ )++ return formatted_data++ except Exception as e:+ print(f"Error downloading AMC/AIME dataset: {e}")+ return None+++if __name__ == "__main__":+ download_gsm8k_dataset()+ # download_amc_aime_dataset()diff --git a/examples/datagen/self_improving_cot/gsm8k_dataset.json b/examples/datagen/self_improving_cot/gsm8k_dataset.jsonnew file mode 100644index 000000000..be68dad05--- /dev/null+++ b/examples/datagen/self_improving_cot/gsm8k_dataset.json@@ -0,0 +1,92 @@+[+ {+ "id": "d400221b-9ae5-48af-bde3-9e76573bfdb6",+ "problem": "Natalia sold clips to 48 of her friends in April, and then she sold half as many clips in May. How many clips did Natalia sell altogether in April and May?",+ "type": "openai/gsm8k",+ "solution": "Natalia sold 48/2 = <<48/2=24>>24 clips in May.\nNatalia sold 48+24 = <<48+24=72>>72 clips altogether in April and May.\n\\boxed{72}",+ "evaluate_success": false,+ "boxed_answer_success": true,+ "improvement_history": []+ },+ {+ "id": "3b1a60e0-92fc-4714-8dba-2f96bfdd0a1c",+ "problem": "Weng earns $12 an hour for babysitting. Yesterday, she just did 50 minutes of babysitting. How much did she earn?",+ "type": "openai/gsm8k",+ "solution": "Weng earns 12/60 = $<<12/60=0.2>>0.2 per minute.\nWorking 50 minutes, she earned 0.2 x 50 = $<<0.2*50=10>>10.\n\\boxed{10}",+ "evaluate_success": false,+ "boxed_answer_success": true,+ "improvement_history": []+ },+ {+ "id": "ce6d4527-1a77-454b-b13c-434578aae277",+ "problem": "Betty is saving money for a new wallet which costs $100. Betty has only half of the money she needs. Her parents decided to give her $15 for that purpose, and her grandparents twice as much as her parents. How much more money does Betty need to buy the wallet?",+ "type": "openai/gsm8k",+ "solution": "In the beginning, Betty has only 100 / 2 = $<<100/2=50>>50.\nBetty's grandparents gave her 15 * 2 = $<<15*2=30>>30.\nThis means, Betty needs 100 - 50 - 30 - 15 = $<<100-50-30-15=5>>5 more.\n\\boxed{5}",+ "evaluate_success": false,+ "boxed_answer_success": true,+ "improvement_history": []+ },+ {+ "id": "2373553d-eb17-43e7-8be2-e718c81b86a0",+ "problem": "Julie is reading a 120-page book. Yesterday, she was able to read 12 pages and today, she read twice as many pages as yesterday. If she wants to read half of the remaining pages tomorrow, how many pages should she read?",+ "type": "openai/gsm8k",+ "solution": "Maila read 12 x 2 = <<12*2=24>>24 pages today.\nSo she was able to read a total of 12 + 24 = <<12+24=36>>36 pages since yesterday.\nThere are 120 - 36 = <<120-36=84>>84 pages left to be read.\nSince she wants to read half of the remaining pages tomorrow, then she should read 84/2 = <<84/2=42>>42 pages.\n\\boxed{42}",+ "evaluate_success": false,+ "boxed_answer_success": true,+ "improvement_history": []+ },+ {+ "id": "9e450c49-fcd4-4ed9-8d99-5bba64e12370",+ "problem": "James writes a 3-page letter to 2 different friends twice a week. How many pages does he write a year?",+ "type": "openai/gsm8k",+ "solution": "He writes each friend 3*2=<<3*2=6>>6 pages a week\nSo he writes 6*2=<<6*2=12>>12 pages every week\nThat means he writes 12*52=<<12*52=624>>624 pages a year\n\\boxed{624}",+ "evaluate_success": false,+ "boxed_answer_success": true,+ "improvement_history": []+ },+ {+ "id": "0234a9a9-257c-4292-9685-09f8599ac069",+ "problem": "Mark has a garden with flowers. He planted plants of three different colors in it. Ten of them are yellow, and there are 80% more of those in purple. There are only 25% as many green flowers as there are yellow and purple flowers. How many flowers does Mark have in his garden?",+ "type": "openai/gsm8k",+ "solution": "There are 80/100 * 10 = <<80/100*10=8>>8 more purple flowers than yellow flowers.\nSo in Mark's garden, there are 10 + 8 = <<10+8=18>>18 purple flowers.\nPurple and yellow flowers sum up to 10 + 18 = <<10+18=28>>28 flowers.\nThat means in Mark's garden there are 25/100 * 28 = <<25/100*28=7>>7 green flowers.\nSo in total Mark has 28 + 7 = <<28+7=35>>35 plants in his garden.\n\\boxed{35}",+ "evaluate_success": false,+ "boxed_answer_success": true,+ "improvement_history": []+ },+ {+ "id": "3147dbfb-bbc5-4323-ac12-b768fe225cc8",+ "problem": "Albert is wondering how much pizza he can eat in one day. He buys 2 large pizzas and 2 small pizzas. A large pizza has 16 slices and a small pizza has 8 slices. If he eats it all, how many pieces does he eat that day?",+ "type": "openai/gsm8k",+ "solution": "He eats 32 from the largest pizzas because 2 x 16 = <<2*16=32>>32\nHe eats 16 from the small pizza because 2 x 8 = <<2*8=16>>16\nHe eats 48 pieces because 32 + 16 = <<32+16=48>>48\n\\boxed{48}",+ "evaluate_success": false,+ "boxed_answer_success": true,+ "improvement_history": []+ },+ {+ "id": "9ea57ccc-1bf0-4a6e-b449-12061324057d",+ "problem": "Ken created a care package to send to his brother, who was away at boarding school. Ken placed a box on a scale, and then he poured into the box enough jelly beans to bring the weight to 2 pounds. Then, he added enough brownies to cause the weight to triple. Next, he added another 2 pounds of jelly beans. And finally, he added enough gummy worms to double the weight once again. What was the final weight of the box of goodies, in pounds?",+ "type": "openai/gsm8k",+ "solution": "To the initial 2 pounds of jelly beans, he added enough brownies to cause the weight to triple, bringing the weight to 2*3=<<2*3=6>>6 pounds.\nNext, he added another 2 pounds of jelly beans, bringing the weight to 6+2=<<6+2=8>>8 pounds.\nAnd finally, he added enough gummy worms to double the weight once again, to a final weight of 8*2=<<8*2=16>>16 pounds.\n\\boxed{16}",+ "evaluate_success": false,+ "boxed_answer_success": true,+ "improvement_history": []+ },+ {+ "id": "b1f0b087-72e7-4b68-a344-1d8965e646a9",+ "problem": "Alexis is applying for a new job and bought a new set of business clothes to wear to the interview. She went to a department store with a budget of $200 and spent $30 on a button-up shirt, $46 on suit pants, $38 on a suit coat, $11 on socks, and $18 on a belt. She also purchased a pair of shoes, but lost the receipt for them. She has $16 left from her budget. How much did Alexis pay for the shoes?",+ "type": "openai/gsm8k",+ "solution": "Let S be the amount Alexis paid for the shoes.\nShe spent S + 30 + 46 + 38 + 11 + 18 = S + <<+30+46+38+11+18=143>>143.\nShe used all but $16 of her budget, so S + 143 = 200 - 16 = 184.\nThus, Alexis paid S = 184 - 143 = $<<184-143=41>>41 for the shoes.\n\\boxed{41}",+ "evaluate_success": false,+ "boxed_answer_success": true,+ "improvement_history": []+ },+ {+ "id": "5bb003cb-8705-48e2-92fc-20dee5912f75",+ "problem": "Tina makes $18.00 an hour. If she works more than 8 hours per shift, she is eligible for overtime, which is paid by your hourly wage + 1/2 your hourly wage. If she works 10 hours every day for 5 days, how much money does she make?",+ "type": "openai/gsm8k",+ "solution": "She works 8 hours a day for $18 per hour so she makes 8*18 = $<<8*18=144.00>>144.00 per 8-hour shift\nShe works 10 hours a day and anything over 8 hours is eligible for overtime, so she gets 10-8 = <<10-8=2>>2 hours of overtime\nOvertime is calculated as time and a half so and she makes $18/hour so her overtime pay is 18*.5 = $<<18*.5=9.00>>9.00\nHer overtime pay is 18+9 = $<<18+9=27.00>>27.00\nHer base pay is $144.00 per 8-hour shift and she works 5 days and makes 5 * $144 = $<<144*5=720.00>>720.00\nHer overtime pay is $27.00 per hour and she works 2 hours of overtime per day and makes 27*2 = $<<27*2=54.00>>54.00 in overtime pay\n2 hours of overtime pay for 5 days means she makes 54*5 = $270.00\nIn 5 days her base pay is $720.00 and she makes $270.00 in overtime pay so she makes $720 + $270 = $<<720+270=990.00>>990.00\n\\boxed{990}",+ "evaluate_success": false,+ "boxed_answer_success": true,+ "improvement_history": []+ }+]\ No newline at end of filediff --git a/examples/datagen/self_improving_cot/self_improving_cot_example.py b/examples/datagen/self_improving_cot/self_improving_cot_example.pynew file mode 100644index 000000000..f5dea4ea6--- /dev/null+++ b/examples/datagen/self_improving_cot/self_improving_cot_example.py@@ -0,0 +1,98 @@+# ========= Copyright 2023-2024 @ CAMEL-AI.org. All Rights Reserved. =========+# Licensed under the Apache License, Version 2.0 (the "License");+# you may not use this file except in compliance with the License.+# You may obtain a copy of the License at+#+# http://www.apache.org/licenses/LICENSE-2.0+#+# Unless required by applicable law or agreed to in writing, software+# distributed under the License is distributed on an "AS IS" BASIS,+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.+# See the License for the specific language governing permissions and+# limitations under the License.+# ========= Copyright 2023-2024 @ CAMEL-AI.org. All Rights Reserved. =========++import json+import os+import time++from camel.agents import ChatAgent+from camel.configs import DeepSeekConfig+from camel.datagen import SelfImprovingCoTPipeline+from camel.models import ModelFactory+from camel.types import ModelPlatformType, ModelType++# from camel.models.reward import NemotronRewardModel++"""+please set the below os environment:+export DEEPSEEK_API_KEY=""+"""+++model = ModelFactory.create(+ model_platform=ModelPlatformType.DEEPSEEK,+ model_type=ModelType.DEEPSEEK_CHAT,+ model_config_dict=DeepSeekConfig(temperature=0).as_dict(),+)+++def main():+ start_time = time.time()++ current_dir = os.path.dirname(os.path.abspath(__file__))+ problems_path = os.path.join(current_dir, 'gsm8k_dataset.json')+ output_path = os.path.join(current_dir, 'self_improving_cot_output.json')++ # Load problems from JSON file+ with open(problems_path, 'r') as f:+ problems = json.load(f)++ # Initialize agent+ reason_agent_system_message = """Please reason step by step, and put your+ final answer within \\boxed{}."""+ evaluate_agent_system_message = """You are a highly critical teacher who+ evaluates the student's answers with a meticulous and demanding approach.+ """+ reason_agent = ChatAgent(reason_agent_system_message, model=model)+ evaluate_agent = ChatAgent(evaluate_agent_system_message)++ # Initialize reward model (optional)+ # reward_model = NemotronRewardModel(+ # model_type=ModelType.NVIDIA_NEMOTRON_340B_REWARD,+ # url="https://integrate.api.nvidia.com/v1",+ # api_key=os.environ.get("NVIDIA_API_KEY"),+ # )++ # Set score thresholds for different dimensions (optional)+ score_threshold = {+ "correctness": 0.9,+ "clarity": 0.9,+ "completeness": 0.6,+ }+ # Or use a single threshold for all dimensions:+ # score_threshold = 0.9++ # Create and run pipeline+ pipeline = SelfImprovingCoTPipeline(+ reason_agent=reason_agent,+ evaluate_agent=evaluate_agent,+ problems=problems, # Pass problems list directly+ output_path=output_path,+ max_iterations=3,+ score_threshold=score_threshold,+ # reward_model=reward_model, # To use a reward model (optional)+ )++ results = pipeline.generate(rationalization=False)++ end_time = time.time()+ execution_time = end_time - start_time++ print(f"\nProcessed {len(results)} problems")+ print(f"Results saved to: {output_path}")+ print(f"Total execution time: {execution_time:.2f} seconds")+++if __name__ == "__main__":+ main()diff --git a/examples/datagen/self_improving_cot/self_improving_cot_example_with_r1.py b/examples/datagen/self_improving_cot/self_improving_cot_example_with_r1.pynew file mode 100644index 000000000..472602997--- /dev/null+++ b/examples/datagen/self_improving_cot/self_improving_cot_example_with_r1.py@@ -0,0 +1,133 @@+# ========= Copyright 2023-2024 @ CAMEL-AI.org. All Rights Reserved. =========+# Licensed under the Apache License, Version 2.0 (the "License");+# you may not use this file except in compliance with the License.+# You may obtain a copy of the License at+#+# http://www.apache.org/licenses/LICENSE-2.0+#+# Unless required by applicable law or agreed to in writing, software+# distributed under the License is distributed on an "AS IS" BASIS,+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.+# See the License for the specific language governing permissions and+# limitations under the License.+# ========= Copyright 2023-2024 @ CAMEL-AI.org. All Rights Reserved. =========++import json+import os+import time++from camel.agents import ChatAgent+from camel.datagen import SelfImprovingCoTPipeline+from camel.models import ModelFactory+from camel.types import ModelPlatformType, ModelType++"""+please set the below os environment:+export DEEPSEEK_API_KEY=""+export GET_REASONING_CONTENT="true"+"""++evaluate_model = ModelFactory.create(+ model_platform=ModelPlatformType.DEFAULT,+ model_type=ModelType.DEFAULT,+)++reason_model_1 = ModelFactory.create(+ model_platform=ModelPlatformType.DEEPSEEK,+ model_type=ModelType.DEEPSEEK_REASONER,+)++reason_model_2 = ModelFactory.create(+ model_platform=ModelPlatformType.OPENAI_COMPATIBLE_MODEL,+ model_type="accounts/fireworks/models/deepseek-r1",+ api_key=os.getenv("FIREWORKS_API_KEY"),+ url="https://api.fireworks.ai/inference/v1",+ model_config_dict={"max_tokens": 4096},+)++reason_model_3 = ModelFactory.create(+ model_platform=ModelPlatformType.OPENAI_COMPATIBLE_MODEL,+ model_type="deepseek-ai/DeepSeek-R1",+ api_key=os.getenv("HYPERBOLIC_API_KEY"),+ url="https://api.hyperbolic.xyz/v1",+)++reason_model_4 = ModelFactory.create(+ model_platform=ModelPlatformType.TOGETHER,+ model_type="deepseek-ai/DeepSeek-R1",+ api_key=os.getenv("TOGETHER_API_KEY"),+)+# from camel.models.reward import NemotronRewardModel+++def main():+ start_time = time.time()++ current_dir = os.path.dirname(os.path.abspath(__file__))+ problems_path = os.path.join(current_dir, 'outputs/gsm8k_dataset.json')+ output_path = os.path.join(+ current_dir, 'outputs/self_improving_cot_r1_output.json'+ )++ # Load problems from JSON file+ with open(problems_path, 'r') as f:+ problems = json.load(f)++ # Initialize agent+ reason_agent_system_message = """Answer my question and give your+ final answer within \\boxed{}."""+ evaluate_agent_system_message = """You are a highly critical teacher who+ evaluates the student's answers with a meticulous and demanding approach.+ """+ reason_agent = ChatAgent(+ system_message=reason_agent_system_message,+ model=[+ # reason_model_1,+ reason_model_2,+ # reason_model_3,+ # reason_model_4,+ ],+ )+ evaluate_agent = ChatAgent(+ system_message=evaluate_agent_system_message, model=evaluate_model+ )++ # Initialize reward model (optional)+ # reward_model = NemotronRewardModel(+ # model_type=ModelType.NVIDIA_NEMOTRON_340B_REWARD,+ # url="https://integrate.api.nvidia.com/v1",+ # api_key=os.environ.get("NVIDIA_API_KEY"),+ # )++ # Set score thresholds for different dimensions (optional)+ score_threshold = {+ "correctness": 1.0,+ "clarity": 0.0,+ "completeness": 0.0,+ }+ # Or use a single threshold for all dimensions:+ # score_threshold = 0.9++ # Create and run pipeline+ pipeline = SelfImprovingCoTPipeline(+ reason_agent=reason_agent,+ evaluate_agent=evaluate_agent,+ problems=problems, # Pass problems list directly+ output_path=output_path,+ max_iterations=0,+ score_threshold=score_threshold,+ # reward_model=reward_model, # To use a reward model (optional)+ )++ results = pipeline.generate(rationalization=False)++ end_time = time.time()+ execution_time = end_time - start_time++ print(f"\nProcessed {len(results)} problems")+ print(f"Results saved to: {output_path}")+ print(f"Total execution time: {execution_time:.2f} seconds")+++if __name__ == "__main__":+ main()diff --git a/poetry.lock b/poetry.lockindex 5903b6b98..67303807d 100644--- a/poetry.lock+++ b/poetry.lock@@ -82,13 +82,13 @@ files = [[[package]]name = "aiohappyeyeballs"-version = "2.4.5"+version = "2.4.6"description = "Happy Eyeballs for asyncio"optional = falsepython-versions = ">=3.9"files = [- {file = "aiohappyeyeballs-2.4.5-py3-none-any.whl", hash = "sha256:67b5c2033c60048046863ed377f450bceb74634dc0f9abe4723b60ba12bfe135"},- {file = "aiohappyeyeballs-2.4.5.tar.gz", hash = "sha256:950d95733a9c09011e75cf58550c68eb834ee5211106ad1a686b7259d3110bc4"},+ {file = "aiohappyeyeballs-2.4.6-py3-none-any.whl", hash = "sha256:147ec992cf873d74f5062644332c539fcd42956dc69453fe5204195e560517e1"},+ {file = "aiohappyeyeballs-2.4.6.tar.gz", hash = "sha256:9b05052f9042985d32ecbe4b59a77ae19c006a78f1344d7fdad69d28ded3d0b0"},][[package]]@@ -4050,23 +4050,23 @@ files = [[[package]]name = "langchain"-version = "0.3.17"+version = "0.3.18"description = "Building applications with LLMs through composability"optional = truepython-versions = "<4.0,>=3.9"files = [- {file = "langchain-0.3.17-py3-none-any.whl", hash = "sha256:4d6d3cf454cc261a5017fd1fa5014cffcc7aeaccd0ec0530fc10c5f71e6e97a0"},- {file = "langchain-0.3.17.tar.gz", hash = "sha256:cef56f0a7c8369f35f1fa2690ecf0caa4504a36a5383de0eb29b8a5e26f625a0"},+ {file = "langchain-0.3.18-py3-none-any.whl", hash = "sha256:1a6e629f02a25962aa5b16932e8f073248104a66804ed5af1f78618ad7c1d38d"},+ {file = "langchain-0.3.18.tar.gz", hash = "sha256:311ac227a995545ff7c3f74c7767930c5349edef0b39f19d3105b86d39316b69"},][package.dependencies]aiohttp = ">=3.8.3,<4.0.0"async-timeout = {version = ">=4.0.0,<5.0.0", markers = "python_version < \"3.11\""}-langchain-core = ">=0.3.33,<0.4.0"-langchain-text-splitters = ">=0.3.3,<0.4.0"+langchain-core = ">=0.3.34,<1.0.0"+langchain-text-splitters = ">=0.3.6,<1.0.0"langsmith = ">=0.1.17,<0.4"numpy = [- {version = ">=1.22.4,<2", markers = "python_version < \"3.12\""},+ {version = ">=1.26.4,<2", markers = "python_version < \"3.12\""},{version = ">=1.26.2,<3", markers = "python_version >= \"3.12\""},]pydantic = ">=2.7.4,<3.0.0"@@ -4075,26 +4075,42 @@ requests = ">=2,<3"SQLAlchemy = ">=1.4,<3"tenacity = ">=8.1.0,<8.4.0 || >8.4.0,<10"+[package.extras]+anthropic = ["langchain-anthropic"]+aws = ["langchain-aws"]+cohere = ["langchain-cohere"]+community = ["langchain-community"]+deepseek = ["langchain-deepseek"]+fireworks = ["langchain-fireworks"]+google-genai = ["langchain-google-genai"]+google-vertexai = ["langchain-google-vertexai"]+groq = ["langchain-groq"]+huggingface = ["langchain-huggingface"]+mistralai = ["langchain-mistralai"]+ollama = ["langchain-ollama"]+openai = ["langchain-openai"]+together = ["langchain-together"]+[[package]]name = "langchain-community"-version = "0.3.16"+version = "0.3.17"description = "Community contributed LangChain integrations."optional = truepython-versions = "<4.0,>=3.9"files = [- {file = "langchain_community-0.3.16-py3-none-any.whl", hash = "sha256:a702c577b048d48882a46708bb3e08ca9aec79657c421c3241a305409040c0d6"},- {file = "langchain_community-0.3.16.tar.gz", hash = "sha256:825709bc328e294942b045d0b7f55053e8e88f7f943576306d778cf56417126c"},+ {file = "langchain_community-0.3.17-py3-none-any.whl", hash = "sha256:13bbd87d681b0df67bafa294321613b13ac524f173c92f11048d40c74e585f0b"},+ {file = "langchain_community-0.3.17.tar.gz", hash = "sha256:d8547a3d4f8307950be88ca638cd6ab1abe2440d0012e401a172ba4a39aa8044"},][package.dependencies]aiohttp = ">=3.8.3,<4.0.0"dataclasses-json = ">=0.5.7,<0.7"-httpx-sse = ">=0.4.0,<0.5.0"-langchain = ">=0.3.16,<0.4.0"-langchain-core = ">=0.3.32,<0.4.0"+httpx-sse = ">=0.4.0,<1.0.0"+langchain = ">=0.3.18,<1.0.0"+langchain-core = ">=0.3.34,<1.0.0"langsmith = ">=0.1.125,<0.4"numpy = [- {version = ">=1.22.4,<2", markers = "python_version < \"3.12\""},+ {version = ">=1.26.4,<2", markers = "python_version < \"3.12\""},{version = ">=1.26.2,<3", markers = "python_version >= \"3.12\""},]pydantic-settings = ">=2.4.0,<3.0.0"@@ -7616,28 +7632,27 @@ files = [[[package]]name = "psutil"-version = "6.0.0"+version = "5.9.8"description = "Cross-platform lib for process and system monitoring in Python."-optional = true-python-versions = "!=3.0.*,!=3.1.*,!=3.2.*,!=3.3.*,!=3.4.*,!=3.5.*,>=2.7"+optional = false+python-versions = ">=2.7, !=3.0.*, !=3.1.*, !=3.2.*, !=3.3.*, !=3.4.*, !=3.5.*"files = [- {file = "psutil-6.0.0-cp27-cp27m-macosx_10_9_x86_64.whl", hash = "sha256:a021da3e881cd935e64a3d0a20983bda0bb4cf80e4f74fa9bfcb1bc5785360c6"},- {file = "psutil-6.0.0-cp27-cp27m-manylinux2010_i686.whl", hash = "sha256:1287c2b95f1c0a364d23bc6f2ea2365a8d4d9b726a3be7294296ff7ba97c17f0"},- {file = "psutil-6.0.0-cp27-cp27m-manylinux2010_x86_64.whl", hash = "sha256:a9a3dbfb4de4f18174528d87cc352d1f788b7496991cca33c6996f40c9e3c92c"},- {file = "psutil-6.0.0-cp27-cp27mu-manylinux2010_i686.whl", hash = "sha256:6ec7588fb3ddaec7344a825afe298db83fe01bfaaab39155fa84cf1c0d6b13c3"},- {file = "psutil-6.0.0-cp27-cp27mu-manylinux2010_x86_64.whl", hash = "sha256:1e7c870afcb7d91fdea2b37c24aeb08f98b6d67257a5cb0a8bc3ac68d0f1a68c"},- {file = "psutil-6.0.0-cp27-none-win32.whl", hash = "sha256:02b69001f44cc73c1c5279d02b30a817e339ceb258ad75997325e0e6169d8b35"},- {file = "psutil-6.0.0-cp27-none-win_amd64.whl", hash = "sha256:21f1fb635deccd510f69f485b87433460a603919b45e2a324ad65b0cc74f8fb1"},- {file = "psutil-6.0.0-cp36-abi3-macosx_10_9_x86_64.whl", hash = "sha256:c588a7e9b1173b6e866756dde596fd4cad94f9399daf99ad8c3258b3cb2b47a0"},- {file = "psutil-6.0.0-cp36-abi3-manylinux_2_12_i686.manylinux2010_i686.manylinux_2_17_i686.manylinux2014_i686.whl", hash = "sha256:6ed2440ada7ef7d0d608f20ad89a04ec47d2d3ab7190896cd62ca5fc4fe08bf0"},- {file = "psutil-6.0.0-cp36-abi3-manylinux_2_12_x86_64.manylinux2010_x86_64.manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:5fd9a97c8e94059b0ef54a7d4baf13b405011176c3b6ff257c247cae0d560ecd"},- {file = "psutil-6.0.0-cp36-abi3-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:e2e8d0054fc88153ca0544f5c4d554d42e33df2e009c4ff42284ac9ebdef4132"},- {file = "psutil-6.0.0-cp36-cp36m-win32.whl", hash = "sha256:fc8c9510cde0146432bbdb433322861ee8c3efbf8589865c8bf8d21cb30c4d14"},- {file = "psutil-6.0.0-cp36-cp36m-win_amd64.whl", hash = "sha256:34859b8d8f423b86e4385ff3665d3f4d94be3cdf48221fbe476e883514fdb71c"},- {file = "psutil-6.0.0-cp37-abi3-win32.whl", hash = "sha256:a495580d6bae27291324fe60cea0b5a7c23fa36a7cd35035a16d93bdcf076b9d"},- {file = "psutil-6.0.0-cp37-abi3-win_amd64.whl", hash = "sha256:33ea5e1c975250a720b3a6609c490db40dae5d83a4eb315170c4fe0d8b1f34b3"},- {file = "psutil-6.0.0-cp38-abi3-macosx_11_0_arm64.whl", hash = "sha256:ffe7fc9b6b36beadc8c322f84e1caff51e8703b88eee1da46d1e3a6ae11b4fd0"},- {file = "psutil-6.0.0.tar.gz", hash = "sha256:8faae4f310b6d969fa26ca0545338b21f73c6b15db7c4a8d934a5482faa818f2"},+ {file = "psutil-5.9.8-cp27-cp27m-macosx_10_9_x86_64.whl", hash = "sha256:26bd09967ae00920df88e0352a91cff1a78f8d69b3ecabbfe733610c0af486c8"},+ {file = "psutil-5.9.8-cp27-cp27m-manylinux2010_i686.whl", hash = "sha256:05806de88103b25903dff19bb6692bd2e714ccf9e668d050d144012055cbca73"},+ {file = "psutil-5.9.8-cp27-cp27m-manylinux2010_x86_64.whl", hash = "sha256:611052c4bc70432ec770d5d54f64206aa7203a101ec273a0cd82418c86503bb7"},+ {file = "psutil-5.9.8-cp27-cp27mu-manylinux2010_i686.whl", hash = "sha256:50187900d73c1381ba1454cf40308c2bf6f34268518b3f36a9b663ca87e65e36"},+ {file = "psutil-5.9.8-cp27-cp27mu-manylinux2010_x86_64.whl", hash = "sha256:02615ed8c5ea222323408ceba16c60e99c3f91639b07da6373fb7e6539abc56d"},+ {file = "psutil-5.9.8-cp27-none-win32.whl", hash = "sha256:36f435891adb138ed3c9e58c6af3e2e6ca9ac2f365efe1f9cfef2794e6c93b4e"},+ {file = "psutil-5.9.8-cp27-none-win_amd64.whl", hash = "sha256:bd1184ceb3f87651a67b2708d4c3338e9b10c5df903f2e3776b62303b26cb631"},+ {file = "psutil-5.9.8-cp36-abi3-macosx_10_9_x86_64.whl", hash = "sha256:aee678c8720623dc456fa20659af736241f575d79429a0e5e9cf88ae0605cc81"},+ {file = "psutil-5.9.8-cp36-abi3-manylinux_2_12_i686.manylinux2010_i686.manylinux_2_17_i686.manylinux2014_i686.whl", hash = "sha256:8cb6403ce6d8e047495a701dc7c5bd788add903f8986d523e3e20b98b733e421"},+ {file = "psutil-5.9.8-cp36-abi3-manylinux_2_12_x86_64.manylinux2010_x86_64.manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:d06016f7f8625a1825ba3732081d77c94589dca78b7a3fc072194851e88461a4"},+ {file = "psutil-5.9.8-cp36-cp36m-win32.whl", hash = "sha256:7d79560ad97af658a0f6adfef8b834b53f64746d45b403f225b85c5c2c140eee"},+ {file = "psutil-5.9.8-cp36-cp36m-win_amd64.whl", hash = "sha256:27cc40c3493bb10de1be4b3f07cae4c010ce715290a5be22b98493509c6299e2"},+ {file = "psutil-5.9.8-cp37-abi3-win32.whl", hash = "sha256:bc56c2a1b0d15aa3eaa5a60c9f3f8e3e565303b465dbf57a1b730e7a2b9844e0"},+ {file = "psutil-5.9.8-cp37-abi3-win_amd64.whl", hash = "sha256:8db4c1b57507eef143a15a6884ca10f7c73876cdf5d51e713151c1236a0e68cf"},+ {file = "psutil-5.9.8-cp38-abi3-macosx_11_0_arm64.whl", hash = "sha256:d16bbddf0693323b8c6123dd804100241da461e41d6e332fb0ba6058f630f8c8"},+ {file = "psutil-5.9.8.tar.gz", hash = "sha256:6be126e3225486dff286a8fb9a06246a5253f4c7c53b475ea5f5ac934e64194c"},][package.extras]@@ -12484,4 +12499,4 @@ web-tools = ["apify_client", "asknews", "dappier", "duckduckgo-search", "firecra[metadata]lock-version = "2.0"python-versions = ">=3.10,<3.13"-content-hash = "f90dc798e70cb314de13e76955341cfce2131528c9f1570debcd5ea6fbd85a58"+content-hash = "ccd7845251187d9c2bd3831125c486c75a62e259f6306a3ad92dba5d87892d4c"diff --git a/pyproject.toml b/pyproject.tomlindex faa9c8530..ddfe39ada 100644--- a/pyproject.toml+++ b/pyproject.toml@@ -42,6 +42,7 @@ eval-type-backport = "0.2.0"curl_cffi = "0.6.2"pandoc = "*"httpx = ">=0.23.0,<0.27.3"+psutil = "^5.9.8"# Model platformslitellm = { version = "^1.38.1", optional = true }@@ -460,6 +461,7 @@ module = ["openai.error","anthropic","pytest",+ "psutil","_pytest.config","_pytest.nodes","numpy",diff --git a/test/datagen/test_self_improving_cot_pipeline.py b/test/datagen/test_self_improving_cot_pipeline.pynew file mode 100644index 000000000..69722fed0--- /dev/null+++ b/test/datagen/test_self_improving_cot_pipeline.py@@ -0,0 +1,478 @@+# ========= Copyright 2023-2024 @ CAMEL-AI.org. All Rights Reserved. =========+# Licensed under the Apache License, Version 2.0 (the "License");+# you may not use this file except in compliance with the License.+# You may obtain a copy of the License at+#+# http://www.apache.org/licenses/LICENSE-2.0+#+# Unless required by applicable law or agreed to in writing, software+# distributed under the License is distributed on an "AS IS" BASIS,+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.+# See the License for the specific language governing permissions and+# limitations under the License.+# ========= Copyright 2023-2024 @ CAMEL-AI.org. All Rights Reserved. =========++import unittest+from unittest.mock import MagicMock, patch++from camel.agents import ChatAgent+from camel.datagen import SelfImprovingCoTPipeline+from camel.datagen.self_improving_cot import (+ ProblemResult,+ TraceIteration,+)+from camel.models.reward import BaseRewardModel+++class TestSelfImprovingCoTPipeline(unittest.TestCase):+ def setUp(self):+ self.mock_reason_agent = MagicMock(spec=ChatAgent)+ self.mock_reason_agent.step.return_value = MagicMock(+ msg=MagicMock(content="Mock reasoning trace")+ )++ self.mock_evaluate_agent = MagicMock(spec=ChatAgent)+ self.mock_evaluate_agent.step.return_value = MagicMock(+ msg=MagicMock(+ parsed={+ "correctness": 0.8,+ "clarity": 0.9,+ "completeness": 0.85,+ "feedback": "Good explanation",+ }+ )+ )++ self.test_problems = [+ {+ "id": "problem_0",+ "problem": (+ "If John has 5 apples and gives 2 to Mary, "+ "how many does he have left?"+ ),+ "type": "arithmetic",+ "solution": "3",+ }+ ]++ def test_pipeline_initialization(self):+ pipeline = SelfImprovingCoTPipeline(+ reason_agent=self.mock_reason_agent,+ evaluate_agent=self.mock_evaluate_agent,+ problems=self.test_problems,+ batch_size=10,+ max_workers=4,+ )+ self.assertEqual(len(pipeline.problems), 1)+ self.assertEqual(pipeline.max_iterations, 3)+ self.assertEqual(pipeline.score_threshold, 0.7)+ self.assertIsNone(pipeline.reward_model)+ self.assertIsNone(pipeline.evaluator)+ self.assertIsNone(pipeline.few_shot_examples)+ self.assertEqual(pipeline.batch_processor.batch_size, 10)+ self.assertEqual(pipeline.batch_processor.max_workers, 4)++ def test_pipeline_initialization_with_few_shot(self):+ few_shot = "Example: 2 + 2 = 4"+ pipeline = SelfImprovingCoTPipeline(+ reason_agent=self.mock_reason_agent,+ evaluate_agent=self.mock_evaluate_agent,+ problems=self.test_problems,+ few_shot_examples=few_shot,+ )+ self.assertEqual(pipeline.few_shot_examples, few_shot)++ def test_generate_reasoning_trace(self):+ pipeline = SelfImprovingCoTPipeline(+ reason_agent=self.mock_reason_agent,+ evaluate_agent=self.mock_evaluate_agent,+ problems=self.test_problems,+ )+ trace = pipeline.generate_reasoning_trace(+ self.test_problems[0]["problem"]+ )+ self.assertEqual(trace, "Mock reasoning trace")+ self.mock_reason_agent.reset.assert_called_once()+ self.mock_reason_agent.step.assert_called_once()++ def test_agent_evaluate_trace(self):+ evaluation_response = {+ "correctness": 0.8,+ "clarity": 0.9,+ "completeness": 0.85,+ "feedback": "Good explanation, but could be more detailed",+ }+ self.mock_evaluate_agent.step.return_value = MagicMock(+ msg=MagicMock(parsed=evaluation_response)+ )++ pipeline = SelfImprovingCoTPipeline(+ reason_agent=self.mock_reason_agent,+ evaluate_agent=self.mock_evaluate_agent,+ problems=self.test_problems,+ )++ evaluation = pipeline.evaluate_trace(+ self.test_problems[0]["problem"],+ "Test reasoning trace",+ )++ self.assertIsInstance(evaluation, dict)+ self.assertEqual(evaluation["correctness"], 0.8)+ self.assertEqual(evaluation["clarity"], 0.9)+ self.assertEqual(evaluation["completeness"], 0.85)+ self.assertEqual(+ evaluation["feedback"],+ "Good explanation, but could be more detailed",+ )++ def test_reward_model_single_score_evaluation(self):+ mock_reward_model = MagicMock(spec=BaseRewardModel)+ mock_evaluator = MagicMock()+ mock_evaluator.evaluate.return_value = 0.85++ pipeline = SelfImprovingCoTPipeline(+ reason_agent=self.mock_reason_agent,+ evaluate_agent=self.mock_evaluate_agent,+ problems=self.test_problems,+ reward_model=mock_reward_model,+ )+ pipeline.evaluator = mock_evaluator++ evaluation = pipeline.evaluate_trace(+ self.test_problems[0]["problem"],+ "Test reasoning trace",+ )++ self.assertIsInstance(evaluation, dict)+ self.assertEqual(evaluation["overall"], 0.85)+ self.assertIn("feedback", evaluation)++ def test_reward_model_multi_score_evaluation(self):+ mock_reward_model = MagicMock(spec=BaseRewardModel)+ mock_evaluator = MagicMock()+ mock_evaluator.evaluate.return_value = {+ "correctness": 0.8,+ "coherence": 0.9,+ "helpfulness": 0.85,+ }++ pipeline = SelfImprovingCoTPipeline(+ reason_agent=self.mock_reason_agent,+ evaluate_agent=self.mock_evaluate_agent,+ problems=self.test_problems,+ reward_model=mock_reward_model,+ )+ pipeline.evaluator = mock_evaluator++ evaluation = pipeline.evaluate_trace(+ self.test_problems[0]["problem"],+ "Test reasoning trace",+ )++ self.assertIsInstance(evaluation, dict)+ self.assertEqual(evaluation["correctness"], 0.8)+ self.assertEqual(evaluation["coherence"], 0.9)+ self.assertEqual(evaluation["helpfulness"], 0.85)+ self.assertIn("feedback", evaluation)++ def test_improve_trace(self):+ improved_trace = "Improved reasoning with more details"+ self.mock_reason_agent.step.return_value = MagicMock(+ msg=MagicMock(content=improved_trace)+ )++ pipeline = SelfImprovingCoTPipeline(+ reason_agent=self.mock_reason_agent,+ evaluate_agent=self.mock_evaluate_agent,+ problems=self.test_problems,+ )++ result = pipeline.improve_trace(+ self.test_problems[0]["problem"],+ "Original trace",+ "Add more details",+ )++ self.assertEqual(result, improved_trace)+ self.mock_reason_agent.reset.assert_called_once()+ self.mock_reason_agent.step.assert_called_once()++ def test_process_problem(self):+ # Mock responses for the process_problem pipeline+ mock_reason_responses = [+ MagicMock(msg=MagicMock(content="Initial reasoning trace")),+ ]+ mock_evaluate_responses = [+ MagicMock(+ msg=MagicMock(+ parsed={+ "correctness": 0.95,+ "clarity": 0.9,+ "completeness": 0.95,+ "feedback": "Excellent explanation",+ }+ )+ ),+ ]+ self.mock_reason_agent.step.side_effect = mock_reason_responses+ self.mock_evaluate_agent.step.side_effect = mock_evaluate_responses++ pipeline = SelfImprovingCoTPipeline(+ reason_agent=self.mock_reason_agent,+ evaluate_agent=self.mock_evaluate_agent,+ problems=self.test_problems,+ )++ result = pipeline.process_problem(self.test_problems[0])++ self.assertIsInstance(result, ProblemResult)+ self.assertEqual(result.problem, self.test_problems[0]["problem"])+ self.assertEqual(result.final_trace, "Initial reasoning trace")+ self.assertEqual(len(result.improvement_history), 1)+ self.assertIsInstance(result.improvement_history[0], TraceIteration)++ def test_score_threshold_dict(self):+ pipeline = SelfImprovingCoTPipeline(+ reason_agent=self.mock_reason_agent,+ evaluate_agent=self.mock_evaluate_agent,+ problems=self.test_problems,+ score_threshold={"correctness": 0.8, "clarity": 0.7},+ )++ # Test with scores meeting thresholds+ scores = {"correctness": 0.9, "clarity": 0.8, "completeness": 0.6}+ self.assertTrue(pipeline._check_score_threshold(scores))++ # Test with scores below thresholds+ scores = {"correctness": 0.7, "clarity": 0.6, "completeness": 0.9}+ self.assertFalse(pipeline._check_score_threshold(scores))++ @patch("psutil.cpu_times")+ @patch("psutil.cpu_count")+ @patch("psutil.cpu_percent")+ @patch("psutil.virtual_memory")+ @patch("builtins.open")+ @patch("json.dump")+ @patch("json.load")+ def test_generate_with_output(+ self,+ mock_load,+ mock_dump,+ mock_open,+ mock_virtual_memory,+ mock_cpu_percent,+ mock_cpu_count,+ mock_cpu_times,+ ):+ mock_load.return_value = {"traces": []}+ mock_open.return_value.__enter__ = mock_open+ mock_open.return_value.__exit__ = MagicMock()++ # Mock psutil functions+ mock_cpu_times.return_value = MagicMock(+ user=100.0,+ nice=0.0,+ system=50.0,+ idle=200.0,+ iowait=0.0,+ irq=0.0,+ softirq=0.0,+ steal=0.0,+ guest=0.0,+ guest_nice=0.0,+ )+ mock_cpu_count.return_value = 8+ mock_cpu_percent.return_value = 50.0+ mock_virtual_memory.return_value = MagicMock(percent=60.0)++ mock_reason_responses = [+ MagicMock(msg=MagicMock(content="Initial reasoning trace")),+ MagicMock(msg=MagicMock(content="Improved reasoning trace")),+ ]+ mock_evaluate_responses = [+ MagicMock(+ msg=MagicMock(+ parsed={+ "correctness": 0.95,+ "clarity": 0.9,+ "completeness": 0.95,+ "feedback": "Excellent explanation",+ }+ )+ ),+ MagicMock(+ msg=MagicMock(+ parsed={+ "correctness": 0.98,+ "clarity": 0.95,+ "completeness": 0.98,+ "feedback": "Perfect explanation",+ }+ )+ ),+ ]+ self.mock_reason_agent.step.side_effect = mock_reason_responses+ self.mock_evaluate_agent.step.side_effect = mock_evaluate_responses++ pipeline = SelfImprovingCoTPipeline(+ reason_agent=self.mock_reason_agent,+ evaluate_agent=self.mock_evaluate_agent,+ problems=self.test_problems,+ output_path="test_output.json",+ max_iterations=1,+ score_threshold=0.99,+ )++ results = pipeline.generate()++ # Verify the results structure+ self.assertIsInstance(results, list)+ self.assertEqual(len(results), 1)+ result = results[0]+ self.assertIn("problem", result)+ self.assertIn("final_trace", result)+ self.assertIn("improvement_history", result)++ # Verify output was written+ mock_dump.assert_called()+ args = mock_dump.call_args_list[-1][0] # Get last call args+ expected_result = {+ "traces": [+ {+ "id": "problem_0",+ "type": "arithmetic",+ "problem": "If John has 5 apples and gives 2 to Mary, "+ "how many does he have left?",+ "solution": "3",+ "final_trace": "Improved reasoning trace",+ "agent_evaluate_success": False,+ "boxed_answer_success": False,+ "improvement_history": [+ {+ "iteration": 0,+ "trace": "Initial reasoning trace",+ "evaluation": {+ "correctness": 0.95,+ "clarity": 0.9,+ "completeness": 0.95,+ "feedback": "Excellent explanation",+ },+ },+ {+ "iteration": 1,+ "trace": "Improved reasoning trace",+ "evaluation": {+ "correctness": 0.98,+ "clarity": 0.95,+ "completeness": 0.98,+ "feedback": "Perfect explanation",+ },+ },+ ],+ }+ ]+ }+ self.assertEqual(args[0], expected_result)++ def test_invalid_problem_format(self):+ test_cases = [+ (+ {"id": "problem_0", "type": "arithmetic"},+ "Problem dictionary must contain 'problem' key.",+ ),+ ({"problem": 123}, "Problem 'problem' field must be a string."),+ (+ {"problem": "test", "id": []},+ "Problem 'id' must be of type (<class 'str'>, <class 'int'>"+ ", <class 'NoneType'>) if present.",+ ),+ (+ {"problem": "test", "type": 123},+ "Problem 'type' must be of type str if present.",+ ),+ (+ {"problem": "test", "solution": 123},+ "Problem 'solution' must be of type str if present.",+ ),+ ]++ pipeline = SelfImprovingCoTPipeline(+ reason_agent=self.mock_reason_agent,+ evaluate_agent=self.mock_evaluate_agent,+ problems=[],+ )++ for invalid_problem, expected_error in test_cases:+ with self.assertRaises(ValueError) as context:+ pipeline.validate_problem_format(invalid_problem)+ self.assertIn(expected_error, str(context.exception))++ def test_batch_processing(self):+ # Test with multiple problems+ test_problems = [+ {+ "id": f"problem_{i}",+ "problem": f"Test problem {i}",+ "type": "test",+ "solution": str(i),+ }+ for i in range(3)+ ]++ # Create enough mock responses for all iterations+ mock_reason_responses = [+ MagicMock(+ msg=MagicMock(+ content=f"Reasoning trace for {problem['problem']}"+ )+ )+ for problem in test_problems+ ]+ mock_evaluate_responses = [+ MagicMock(+ msg=MagicMock(+ parsed={+ "correctness": 0.9,+ "clarity": 0.9,+ "completeness": 0.9,+ "feedback": f"Feedback for {problem['problem']}",+ }+ )+ )+ for problem in test_problems+ ]++ self.mock_reason_agent.step.side_effect = mock_reason_responses+ self.mock_evaluate_agent.step.side_effect = mock_evaluate_responses++ pipeline = SelfImprovingCoTPipeline(+ reason_agent=self.mock_reason_agent,+ evaluate_agent=self.mock_evaluate_agent,+ problems=test_problems,+ batch_size=2, # Small batch size to test batching+ max_workers=2,+ )++ results = pipeline.generate()++ # Verify results+ self.assertEqual(len(results), 3)++ # Create a map of problem text to expected trace+ expected_traces = {+ problem["problem"]: f"Reasoning trace for {problem['problem']}"+ for problem in test_problems+ }++ # Verify each result matches its corresponding problem+ for result in results:+ problem_text = result["problem"]+ self.assertIn(problem_text, expected_traces)+ self.assertEqual(+ result["final_trace"], expected_traces[problem_text]+ )+++if __name__ == "__main__":+ unittest.main()diff --git a/test/utils/test_commons.py b/test/utils/test_commons.pyindex 138a22235..9a8e9cfff 100644--- a/test/utils/test_commons.py+++ b/test/utils/test_commons.py@@ -18,11 +18,13 @@ from unittest.mock import patchimport pytestfrom camel.utils import (+ BatchProcessor,api_keys_required,dependencies_required,get_system_information,get_task_list,is_docker_running,+ retry_on_error,to_pascal,)@@ -230,3 +232,89 @@ class TestApiKeysRequired(TestCase):"Missing or empty required API keys in environment ""variables: API_KEY" in str(context.exception))+++class TestRetryOnError(TestCase):+ def test_successful_execution(self):+ @retry_on_error()+ def successful_func():+ return "success"++ result = successful_func()+ self.assertEqual(result, "success")++ def test_retry_on_failure(self):+ attempts = []++ @retry_on_error(max_retries=2, initial_delay=0.1)+ def failing_func():+ attempts.append(1)+ if len(attempts) < 2:+ raise ValueError("Test error")+ return "success"++ result = failing_func()+ self.assertEqual(result, "success")+ self.assertEqual(len(attempts), 2)++ def test_max_retries_exceeded(self):+ attempts = []++ @retry_on_error(max_retries=2, initial_delay=0.1)+ def always_failing_func():+ attempts.append(1)+ raise ValueError("Test error")++ with self.assertRaises(ValueError):+ always_failing_func()+ self.assertEqual(len(attempts), 3) # Initial attempt + 2 retries+++class TestBatchProcessor(TestCase):+ def setUp(self):+ self.processor = BatchProcessor(+ max_workers=2,+ initial_batch_size=5,+ monitoring_interval=0.0, # Set to 0 to force resource check+ cpu_threshold=90.0,+ memory_threshold=90.0,+ )++ @patch('psutil.cpu_percent')+ @patch('psutil.virtual_memory')+ def test_resource_based_adjustment(self, mock_memory, mock_cpu):+ mock_cpu.return_value = 95.0+ mock_memory.return_value.percent = 95.0++ self.assertEqual(self.processor.batch_size, 5)++ self.processor.last_check_time = 0++ self.processor.adjust_batch_size(True)++ expected_size = int(5 * self.processor.backoff_factor)+ self.assertEqual(self.processor.batch_size, expected_size)+ self.assertEqual(self.processor.max_workers, 1)++ def test_success_based_adjustment(self):+ initial_size = self.processor.batch_size++ self.processor.adjust_batch_size(True)+ self.assertGreater(self.processor.batch_size, initial_size)++ self.processor.adjust_batch_size(False)+ self.assertLess(+ self.processor.batch_size, self.processor.batch_size * 1.2+ )++ def test_performance_metrics(self):+ self.processor.adjust_batch_size(True, 1.0)+ self.processor.adjust_batch_size(False, 2.0)+ self.processor.adjust_batch_size(True, 1.5)++ metrics = self.processor.get_performance_metrics()++ self.assertEqual(metrics['total_processed'], 3)+ self.assertAlmostEqual(metrics['error_rate'], 33.33333333333333)+ self.assertAlmostEqual(metrics['avg_processing_time'], 1.5)+ self.assertEqual(metrics['current_workers'], 2)