
🐫 CAMEL: The first and the best multi-agent framework. Finding the Scaling Law of Agents. https://www.camel-ai.org
Python agentai-societiesartificial-intelligencecommunicative-aicooperative-aideep-learninglarge-language-modelsmulti-agent-systemsnatural-language-processing
Auto-update documentation after merge
camel-docs-botb33b0bc1190e
diff --git a/docs/cookbooks/data_processing/summarisation_agent_with_mistral_ocr.md b/docs/cookbooks/data_processing/summarisation_agent_with_mistral_ocr.mdnew file mode 100644index 000000000..30d49578b--- /dev/null+++ b/docs/cookbooks/data_processing/summarisation_agent_with_mistral_ocr.md@@ -0,0 +1,218 @@+---+title: "Create Document Summarization Agents with Mistral OCR & CAMEL-AI 🐫"+---++You can also check this cookbook in Colab [here](https://colab.research.google.com/drive/1ZwVmqa5vjpZ0C3H7k1XIseFfbCR4mq17?usp=sharing)++In this cookbook, we’ll explore [**Mistral OCR**](https://mistral.ai/news/mistral-ocr)—a state-of-the-art Optical Character Recognition API that understands complex document layouts and extracts text, tables, images, and equations with unprecedented accuracy. We’ll show you how to:++- Use the Mistral OCR API to convert scanned or image-based PDFs into structured Markdown+- Leverage a Mistral LLM agent within CAMEL to summarize and analyze the extracted content+- Build a seamless, end-to-end pipeline for retrieval-augmented generation (RAG), research, or business automation++## Table of Contents++1. 🧑🏻💻 Introduction+2. ⚡️ Step-by-step Guide: Mistral OCR Extraction+3. 💫 Quick Demo with Mistral Agent+4. 🧑🏻💻 Conclusion++<div style={{ display: "flex", justifyContent: "center", alignItems: "center", gap: "1rem", marginBottom: "2rem" }}>+ <a href="https://www.camel-ai.org/">+ <img src="https://i.postimg.cc/KzQ5rfBC/button.png" width="150" alt="CAMEL Homepage"/>+ </a>+ <a href="https://discord.camel-ai.org">+ <img src="https://i.postimg.cc/L4wPdG9N/join-2.png" width="150" alt="Join Discord"/>+ </a>+</div>+++⭐ *Star us on [GitHub](https://github.com/camel-ai/camel), join our [Discord](https://discord.camel-ai.org), or follow us on [X](https://x.com/camelaiorg)*++---++++++## **Introduction to Mistral OCR**++Throughout history, advancements in information abstraction and retrieval have driven human progress—from hieroglyphs to digitization. Today, over 90% of organizational data lives in documents, often locked in complex layouts and multiple languages. **Mistral OCR** ushers in the next leap in document understanding: a multimodal API that comprehends every element—text, images, tables, equations—and outputs ordered, structured Markdown with embedded media references.++#### **Key Features of Mistral OCR:**++1. **State-of-the-art complex document understanding**+ - Extracts interleaved text, figures, tables, and mathematical expressions with high fidelity.++2. **Natively multilingual & multimodal**+ - Parses scripts and fonts from across the globe, handling right-to-left layouts and non-Latin characters seamlessly.++3. **Doc-as-prompt, structured output**+ - Returns ordered Markdown, embedding images and bounding-box metadata ready for RAG and downstream AI workflows.++4. **Top-tier benchmarks & speed**+ - Outperforms leading OCR systems in accuracy—especially in math, tables, and multilingual tests—while delivering fast batch inference (∼2000 pages/min).++5. **Scalable & flexible deployment**+ - Available via `mistral-ocr-latest` on Mistral’s developer suite, cloud partners, and on-premises self-hosting for sensitive data.++Ready to unlock your documents? Let’s dive into the extraction guide.+++First, install the CAMEL package with all its dependencies.+++```python+!pip install "camel-ai[all]==0.2.61"+```++## ⚡️ Step-by-step Guide: Mistral OCR Loader++**Step 1: Set up your Mistral API key**++If you don’t have a Mistral API key, you can obtain one by following these steps:++1. **Create an account:**+ Go to [Mistral Console](https://console.mistral.ai/home) and sign up for an organization account.++2. **Get your API key:**+ Once logged in, navigate to **Organization** → **API Keys**, generate a new key, copy it, and store it securely.++++```python+import os+from getpass import getpass++mistral_api_key = getpass('Enter your Mistral API key: ')+os.environ['MISTRAL_API_KEY'] = mistral_api_key++```++**Step 2: Upload your PDF or image file for OCR**++In a Colab or Jupyter environment, you can upload any PDF file directly:++++```python+# Colab file upload+from google.colab import files++uploaded = files.upload()+# Grab the first uploaded filename+file_path = next(iter(uploaded))+```++**Step 3: Import and initialize the Mistral OCR loader**+++```python+# Importing the MistralReader class from the camel.loaders module+# This class handles document processing using Mistral OCR capabilities+from camel.loaders import MistralReader++# Initializing an instance of MistralReader+# This object will be used to submit tasks and manage OCR processing+mistral_reader = MistralReader()+```++## Step 4: Obtain OCR output from Mistral++Once the task completes, retrieve its output using the returned `task.id`.++The output of **Mistral OCR** is a structured object:++++```python+# Retrieve the OCR output+# CORRECT: Just use extract_text for local files or URLs+ocr_response = mistral_reader.extract_text(file_path)+print(ocr_response)+```++## 💫 Quick Demo with CAMEL Agent++Here we choose Mistral model for our demo. If you'd like to explore different models or tools to suit your needs, feel free to visit the [CAMEL documentation page](https://docs.camel-ai.org/), where you'll find guides and tutorials.+++If you don't have a Mistral API key, you can obtain one by following these steps:++1. Visit the Mistral Console (https://console.mistral.ai/)++2. In the left panel, click on API keys under API section++3. Choose your plan++For more details, you can also check the Mistral documentation: https://docs.mistral.ai/getting-started/quickstart/+++```python+from camel.configs import MistralConfig+from camel.models import ModelFactory+from camel.types import ModelPlatformType, ModelType++mistral_model = ModelFactory.create(+ model_platform=ModelPlatformType.MISTRAL,+ model_type=ModelType.MISTRAL_LARGE,+ model_config_dict=MistralConfig(temperature=0.0).as_dict(),+)++# Use Mistral model+model = mistral_model+```+++```python+from camel.agents import ChatAgent++# Initialize a ChatAgent+agent = ChatAgent(+ system_message="You are a helpful document assistant.", # Define the agent's role+ model=mistral_model+)++# Use the ChatAgent to generate insights based on the OCR output+response = agent.step(+ f"Based on the following OCR-extracted content, give me a concise conclusion of the document:\n{ocr_response}"+)+print(response.msgs[0].content)+```++**For advanced usage of RAG capabilities with large files, please refer to our [RAG cookbook](https://docs.camel-ai.org/cookbooks/advanced_features/agents_with_rag#rag-cookbook).**++## 🧑🏻💻 Conclusion++In conclusion, integrating **Mistral OCR** within CAMEL-AI revolutionizes the process of document data extraction and preparation, enhancing your capabilities for AI-driven applications. With Mistral OCR’s robust features—state-of-the-art complex document understanding, natively multilingual & multimodal parsing, and doc-as-prompt structured Markdown output—you can seamlessly process complex PDFs and images into machine-readable formats optimized for LLMs, directly feeding into CAMEL-AI’s multi-agent workflows. This integration not only simplifies data preparation but also empowers intelligent and accurate analytics at scale. With these tools at your disposal, you’re equipped to transform raw document data into actionable insights, unlocking new possibilities in automation and AI-powered decision-making.+++That's everything: Got questions about 🐫 CAMEL-AI? Join us on [Discord](https://discord.camel-ai.org)! Whether you want to share feedback, explore the latest in multi-agent systems, get support, or connect with others on exciting projects, we’d love to have you in the community! 🤝++Check out some of our other work:++1. 🐫 Creating Your First CAMEL Agent [free Colab](https://colab.research.google.com/drive/1cmWPxXEsyMbmjPhD2bWfHuhd_Uz6FaJQ?usp=sharing)++2. Graph RAG Cookbook [free Colab](https://colab.research.google.com/drive/1uZKQSuu0qW6ukkuSv9TukLB9bVaS1H0U?usp=sharing)++3. 🧑⚖️ Create A Hackathon Judge Committee with Workforce [free Colab](https://colab.research.google.com/drive/18ajYUMfwDx3WyrjHow3EvUMpKQDcrLtr?usp=sharing)++4. 🔥 3 ways to ingest data from websites with Firecrawl & CAMEL [free Colab](https://colab.research.google.com/drive/1lOmM3VmgR1hLwDKdeLGFve_75RFW0R9I?usp=sharing)++5. 🦥 Agentic SFT Data Generation with CAMEL and Mistral Models, Fine-Tuned with Unsloth [free Colab](https://colab.research.google.com/drive/1lYgArBw7ARVPSpdwgKLYnp_NEXiNDOd-?usp=sharingg)++Thanks from everyone at 🐫 CAMEL-AI+++<div style={{ display: "flex", justifyContent: "center", alignItems: "center", gap: "1rem", marginBottom: "2rem" }}>+ <a href="https://www.camel-ai.org/">+ <img src="https://i.postimg.cc/KzQ5rfBC/button.png" width="150" alt="CAMEL Homepage"/>+ </a>+ <a href="https://discord.camel-ai.org">+ <img src="https://i.postimg.cc/L4wPdG9N/join-2.png" width="150" alt="Join Discord"/>+ </a>+</div>++⭐ *Star us on [GitHub](https://github.com/camel-ai/camel), join our [Discord](https://discord.camel-ai.org), or follow us on [X](https://x.com/camelaiorg)*++diff --git a/docs/key_modules/agents.md b/docs/key_modules/agents.mdindex 4b9138f0e..f23f1daa1 100644--- a/docs/key_modules/agents.md+++ b/docs/key_modules/agents.md@@ -1,13 +1,32 @@-## 1. Concept+---+title: "Agents"+description: "Learn about CAMEL's agent types, with a focus on ChatAgent and advanced agent architectures for AI-powered automation."+icon: user-helmet-safety+----Agents in CAMEL are autonomous entities capable of performing specific tasks through interaction with language models and other components. Each agent is designed with a particular role and capability, allowing them to work independently or collaboratively to achieve complex goals.-### 1.1. Base Agent Architecture-All CAMEL agents inherit from the `BaseAgent` abstract class, which defines two core methods:-- `reset()`: Resets the agent to its initial state-- `step()`: Performs a single step of the agent's operation+## Concept++Agents in CAMEL are autonomous entities capable of performing specific tasks through interaction with language models and other components.+Each agent is designed with a particular role and capability, allowing them to work independently or collaboratively to achieve complex goals.++<Note type="info" title="What is an Agent?">+<strong>Think of an agent as an AI-powered teammate</strong> one that brings a defined role, memory, and tool-using abilities to every workflow. CAMEL’s agents are composable, robust, and can be extended with custom logic.+</Note>++## Base Agent Architecture++All CAMEL agents inherit from the <code>BaseAgent</code> abstract class, which defines two essential methods:++| Method | Purpose | Description |+|-------------|---------------------|----------------------------------------------|+| <code>reset()</code> | State Management | Resets the agent to its initial state |+| <code>step()</code> | Task Execution | Performs a single step of the agent's operation |++## Types++### ChatAgent-### 1.2. Chat AgentThe `ChatAgent` is the primary implementation that handles conversations with language models. It supports:- System message configuration for role definition- Memory management for conversation history@@ -16,40 +35,39 @@ The `ChatAgent` is the primary implementation that handles conversations with la- Multiple model backend support with scheduling strategies- Async operation support-## 2. Types+<AccordionGroup>++ <Accordion title="Other Agent Types (When to Use)">++ **`CriticAgent`**+ Specialized agent for evaluating and critiquing responses or solutions. Used in scenarios requiring quality assessment or validation.++ **`DeductiveReasonerAgent`**+ Focused on logical reasoning and deduction. Breaks down complex problems into smaller, manageable steps.-### 2.1. `ChatAgent`-The main agent implementation for handling conversations with language models. Features include:-- Tool integration and management-- Memory management with customizable window sizes-- Output language control-- Response termination handling-- Structured output support via Pydantic models+ **`EmbodiedAgent`**+ Designed for embodied AI scenarios, capable of understanding and responding to physical world contexts.-### 2.2. `CriticAgent`-Specialized agent for evaluating and critiquing responses or solutions. Used in scenarios requiring quality assessment or validation.+ **`KnowledgeGraphAgent`**+ Specialized in building and utilizing knowledge graphs for enhanced reasoning and information management.-### 2.3. `DeductiveReasonerAgent`-Agent focused on logical reasoning and deduction. Breaks down complex problems into smaller, manageable steps.+ **`MultiHopGeneratorAgent`**+ Handles multi-hop reasoning tasks, generating intermediate steps to reach conclusions.-### 2.4. `EmbodiedAgent`-Agent designed for embodied AI scenarios, capable of understanding and responding to physical world contexts.+ **`SearchAgent`**+ Focused on information retrieval and search tasks across various data sources.-### 2.5. `KnowledgeGraphAgent`-Specialized in building and utilizing knowledge graphs for enhanced reasoning and information management.+ **`TaskAgent`**+ Handles task decomposition and management, breaking down complex tasks into manageable subtasks.-### 2.6. `MultiHopGeneratorAgent`-Agent designed for handling multi-hop reasoning tasks, generating intermediate steps to reach conclusions.+ </Accordion>-### 2.7. `SearchAgent`-Focused on information retrieval and search tasks across various data sources.+</AccordionGroup>-### 2.8. `TaskAgent`-Handles task decomposition and management, breaking down complex tasks into manageable subtasks.+## Usage-## 3. Usage+### Basic ChatAgent Usage-### 3.1. Basic Chat Agent Usage```pythonfrom camel.agents import ChatAgent@@ -60,7 +78,8 @@ agent = ChatAgent(system_message="You are a helpful assistant.")response = agent.step("Hello, can you help me?")```-### 3.2. Simplified Agent Creation+### Simplified Agent Creation+The `ChatAgent` supports multiple ways to specify the model:```python@@ -101,7 +120,8 @@ model = ModelFactory.create(agent_7 = ChatAgent("You are a helpful assistant.", model=model)```-### 3.3. Using Tools with Chat Agent+### Using Tools with Chat Agent+```pythonfrom camel.agents import ChatAgentfrom camel.toolkits import FunctionTool@@ -117,7 +137,8 @@ agent = ChatAgent(tools=[calculator])response = agent.step("What is 5 + 3?")```-### 3.4. Structured Output+### Structured Output+```pythonfrom pydantic import BaseModelfrom typing import List@@ -131,43 +152,70 @@ agent = ChatAgent()response = agent.step("List benefits of exercise", response_format=ResponseFormat)```-## 4. Best Practices--### 4.1. Memory Management-- Use appropriate window sizes to manage conversation history-- Consider token limits when dealing with long conversations-- Utilize the memory system for maintaining context--### 4.2. Tool Integration-- Keep tool functions focused and well-documented-- Handle tool errors gracefully-- Use external tools for operations that should be handled by the user--### 4.3. Response Handling-- Implement appropriate response terminators for conversation control-- Use structured outputs when specific response formats are needed-- Handle async operations properly when dealing with long-running tasks--### 4.4. Model Specification-- Use the simplified model specification methods for cleaner code-- For default platform models, just specify the model name as a string-- For specific platforms, use the tuple format (platform, model)-- Use enums for better type safety and IDE support--## 5. Advanced Features--### 5.1. Model Scheduling-The agent supports multiple model backends with customizable scheduling strategies:-```python-def custom_strategy(models):- # Custom model selection logic- return models[0]--agent.add_model_scheduling_strategy("custom", custom_strategy)-```--### 5.2. Output Language Control-Control the language of agent responses:-```python-agent.set_output_language("Spanish")-```+## Best Practices++<AccordionGroup>++ <Accordion title="Memory Management">+ <ul>+ <li>Use appropriate window sizes to manage conversation history</li>+ <li>Consider token limits when dealing with long conversations</li>+ <li>Utilize the memory system for maintaining context</li>+ </ul>+ </Accordion>++ <Accordion title="Tool Integration">+ <ul>+ <li>Keep tool functions focused and well-documented</li>+ <li>Handle tool errors gracefully</li>+ <li>Use external tools for operations that should be handled by the user</li>+ </ul>+ </Accordion>++ <Accordion title="Response Handling">+ <ul>+ <li>Implement appropriate response terminators for conversation control</li>+ <li>Use structured outputs when specific response formats are needed</li>+ <li>Handle async operations properly when dealing with long-running tasks</li>+ </ul>+ </Accordion>++ <Accordion title="Model Specification">+ <ul>+ <li>Use the simplified model specification methods for cleaner code</li>+ <li>For default platform models, just specify the model name as a string</li>+ <li>For specific platforms, use the tuple format (platform, model)</li>+ <li>Use enums for better type safety and IDE support</li>+ </ul>+ </Accordion>++</AccordionGroup>++## Advanced Features++<Tabs>+ <Tab title="Model Scheduling">+ <Note type="info" title="Custom Model Selection">+ You can dynamically select which model an agent uses for each step by adding your own scheduling strategy.+ </Note>+ <CodeGroup>+ ```python title="Custom Model Scheduling"+ def custom_strategy(models):+ # Custom model selection logic+ return models[0]++ agent.add_model_scheduling_strategy("custom", custom_strategy)+ ```+ </CodeGroup>+ </Tab>+ <Tab title="Output Language Control">+ <Note type="tip" title="Multilingual Output">+ Agents can respond in any language. Set the output language on-the-fly during conversations.+ </Note>+ <CodeGroup>+ ```python title="Set Output Language"+ agent.set_output_language("Spanish")+ ```+ </CodeGroup>+ </Tab>+</Tabs>diff --git a/docs/key_modules/datagen.md b/docs/key_modules/datagen.mdindex 1c8276b04..45247ad6d 100644--- a/docs/key_modules/datagen.md+++ b/docs/key_modules/datagen.md@@ -1,26 +1,33 @@-This document describes CAMEL's key data generation modules that enable high-quality training data creation through advanced reasoning and instruction tuning techniques. The modules include:+---+title: "Datagen"+description: "CAMEL’s data generation modules for high-quality, instruction-tuned, and reasoning-rich datasets."+icon: arrow-progress+----- Chain of Thought (CoT): Generates explicit reasoning paths-- Self-Instruct: Creates diverse instruction-following data-- Source2Synth: Converts source code into natural language-- Self-Improving CoT: Iteratively refines reasoning chains through self-critique+This page introduces CAMEL's **data generation modules** for creating high-quality training data with explicit reasoning, diverse instructions, and advanced automated refinement.-## Chain of Thought (CoT) Data Generation+- **Chain of Thought (CoT):** Generates explicit reasoning paths+- **Self-Instruct:** Produces instruction-following data from both humans and machines+- **Source2Synth:** Synthesizes multi-hop QA from source text or code+- **Self-Improving CoT:** Iteratively improves reasoning through agent self-critique-### Overview+## Chain of Thought (CoT) Data Generation-The Chain of Thought (CoT) data generation module implements a sophisticated system for generating high-quality reasoning paths through chat agent interactions. It combines several advanced algorithms to produce and validate reasoning chains.+<Note type="info" title="What is CoT?">+ Chain of Thought (CoT) data generation creates step-by-step reasoning paths for problem solving, leveraging dual agents and advanced search/verification logic.+</Note>-### Key Features+<AccordionGroup>+<Accordion title = "Key Features">- Monte Carlo Tree Search (MCTS) for solution exploration- Binary Search Error Detection for precise error localization- Dual-Agent Verification System for quality assurance- Solution Tree Management for tracking reasoning paths+</Accordion>+<Accordion title="Core Components">-### Core Components--#### CoTDataGenerator Class+**CoTDataGenerator Class**The main class that implements the CoT generation system with the following capabilities:@@ -29,467 +36,458 @@ The main class that implements the CoT generation system with the following capa- **Answer Verification**: Robust verification system using golden answers- **Error Detection**: Binary search-based error detection in solutions- **Solution Management**: Comprehensive solution tree management and export--### Usage--#### Basic Example--```python-from camel.agents import ChatAgent-from camel.datagen import CoTDataGenerator--# Initialize agents-generator_agent = ChatAgent("System message for generator")-verifier_agent = ChatAgent("System message for verifier")--# Define golden answers-golden_answers = {- "question1": "answer1",- "question2": "answer2"-}--# Create generator-cot_generator = CoTDataGenerator(- generator_agent=generator_agent,- verifier_agent=verifier_agent,- golden_answers=golden_answers,- search_limit=100-)--# Generate solution-solution = cot_generator.solve("question1")-```--#### Data Import/Export--```python-# Import QA pairs from JSON-cot_generator.import_qa_from_json("qa_pairs.json")--# Export solutions-cot_generator.export_solutions("solutions.json")-```--### Solution Generation Process--1. **Direct Solution Attempt**- - First tries to solve the problem directly- - Verifies against golden answer--2. **MCTS-based Exploration**- - If direct solution fails, uses MCTS to explore solution space- - Builds solution tree based on previous attempts--3. **Error Detection and Correction**- - Uses binary search to locate errors in solutions- - Generates new solutions based on correct parts--4. **Solution Verification**- - Verifies solutions using dual-agent system or golden answers- - Maintains solution quality through strict verification--### Configuration Options--- `search_limit`: Maximum number of search iterations (default: 100)-- `generator_agent`: Specialized agent for answer generation-- `verifier_agent`: Specialized agent for answer verification-- `golden_answers`: Pre-defined correct answers for validation--### Output Format--The solution tree is exported in JSON format containing:-- Solutions with intermediate steps-- Golden answers used for verification-- Export timestamp-- Solution scores and verification results-+</Accordion>+</AccordionGroup>++<Card icon="zap" title="Quick Start: CoT Data Generation" className="my-6">+ Spin up chain-of-thought data generation with dual agents, golden answers, and CoT solution generation:++ ```python+ from camel.agents import ChatAgent+ from camel.datagen import CoTDataGenerator++ # Initialize agents+ generator_agent = ChatAgent("System message for generator")+ verifier_agent = ChatAgent("System message for verifier")++ # Define golden answers+ golden_answers = {+ "question1": "answer1",+ "question2": "answer2"+ }++ # Create generator+ cot_generator = CoTDataGenerator(+ generator_agent=generator_agent,+ verifier_agent=verifier_agent,+ golden_answers=golden_answers,+ search_limit=100+ )++ # Generate solution+ solution = cot_generator.solve("question1")+ ```+</Card>++<Card icon="database" title="Data Import/Export for CoT" className="my-6">+ Easily import question-answer pairs or export generated solutions for further use:++ ```python+ # Import QA pairs from JSON+ cot_generator.import_qa_from_json("qa_pairs.json")++ # Export solutions+ cot_generator.export_solutions("solutions.json")+ ```+</Card>+++<AccordionGroup>++<Accordion title = "Solution Generation Process">++ <Steps>+ <Step title="Direct Solution Attempt">+ First, the agent attempts to solve the problem directly and checks the result against the golden answer for correctness.+ </Step>+ <Step title="MCTS-Based Exploration">+ If the direct attempt fails, a Monte Carlo Tree Search (MCTS) explores alternative reasoning paths, building a solution tree from previous attempts.+ </Step>+ <Step title="Error Detection & Correction">+ Binary search is used to efficiently pinpoint and isolate errors in the solution. New solutions are then generated, reusing verified-correct parts.+ </Step>+ <Step title="Solution Verification">+ All candidate solutions are strictly verified using a dual-agent system or comparison against golden answers to ensure high quality and accuracy.+ </Step>+ </Steps>+ </Accordion>+ <Accordion title="Configuration Options">+ <ul>+ <li><code>search_limit</code>: Maximum number of search iterations (default: <b>100</b>)</li>+ <li><code>generator_agent</code>: Specialized agent for answer generation</li>+ <li><code>verifier_agent</code>: Specialized agent for answer verification</li>+ <li><code>golden_answers</code>: Pre-defined correct answers for validation</li>+ </ul>+ </Accordion>+ <Accordion title="Output Format">+ The solution tree is exported in <b>JSON format</b> containing:+ <ul>+ <li>Solutions with intermediate steps</li>+ <li>Golden answers used for verification</li>+ <li>Export timestamp</li>+ <li>Solution scores and verification results</li>+ </ul>+ </Accordion>+</AccordionGroup>++---## Self-Instruct: Instruction Generation-### Overview--The Self-Instruct module implements a pipeline for generating and managing machine-generated instructions for tasks. It combines human-written seed instructions with machine-generated ones to create diverse, high-quality task instructions, while ensuring quality through configurable filtering mechanisms.--### Core Components--#### Self Instruct Pipeline--The main pipeline class that orchestrates the instruction generation process.--Key Features:-- Combines human-written and machine-generated instructions using configurable ratios-- Supports classification and non-classification task types-- Built-in instruction filtering and validation-- Automatic instance generation for tasks-- JSON-based data input/output--#### Instruction Filter--A comprehensive filtering system for validating and filtering generated instructions.--Features:-- Length-based filtering-- Keyword filtering-- Punctuation checks-- Non-English text detection-- ROUGE similarity filtering for deduplication-- Extensible filter registry for custom filters--### Usage--#### Basic Example--```python-from camel.agents import ChatAgent-from camel.datagen.self_instruct import SelfInstructPipeline--# Initialize agent-agent = ChatAgent()--# Create pipeline with default settings-pipeline = SelfInstructPipeline(- agent=agent,- seed='seed_tasks.jsonl', # Path to human-written seed tasks- num_machine_instructions=5,- data_output_path='./data_output.json',- human_to_machine_ratio=(6, 2) # Use 6 human tasks and 2 machine tasks for generation-)--# Generate instructions-pipeline.generate()-```--#### Custom Filtering--```python-from camel.datagen.self_instruct import SelfInstructPipeline-from camel.datagen.self_instruct.filter import InstructionFilter--# Configure filters-filter_config = {- "length": {}, # Default length constraints- "keyword": {}, # Keyword-based filtering- "punctuation": {}, # Punctuation checks- "non_english": {}, # Non-English text detection- "rouge_similarity": { # ROUGE-based similarity filtering- "threshold": 0.7,- "metric": "rouge-l"- }-}--# Create pipeline with custom filter configuration-pipeline = SelfInstructPipeline(- agent=agent,- seed='seed_tasks.jsonl',- instruction_filter=InstructionFilter(filter_config),- num_machine_instructions=5-)-```--### Configuration Options--#### Pipeline Parameters--- `agent`: ChatAgent instance for generating instructions-- `seed`: Path to human-written seed tasks in JSONL format-- `num_machine_instructions`: Number of machine-generated instructions to generate (default: 5)-- `data_output_path`: Path for saving generated data (default: './data_output.json')-- `human_to_machine_ratio`: Ratio of human to machine tasks for generation (default: (6, 2))-- `instruction_filter`: Custom InstructionFilter instance (optional)-- `filter_config`: Configuration dictionary for default filters (optional)--#### Filter Configuration--The default filter configuration includes:-- `length`: Configure length constraints for instructions-- `keyword`: Set up keyword-based filtering rules-- `punctuation`: Define punctuation validation rules-- `non_english`: Configure non-English text detection-- `rouge_similarity`: Set ROUGE similarity thresholds for deduplication--### Pipeline Stages--1. **Seed Loading**- - Load human-written instructions from JSONL file- - Validate seed format- - Initialize task storage--2. **Instruction Generation**- - Sample human and machine tasks based on ratio- - Generate new instructions using ChatAgent- - Apply instruction filters--3. **Task Classification**- - Identify if tasks are classification or non-classification- - Generate appropriate prompts based on task type--4. **Instance Generation**- - Generate input-output pairs for each task- - Parse and format instances based on task type- - Apply quality filters--5. **Data Output**- - Save generated tasks and instances to JSON- - Include metadata and configuration details- - Maintain structured output format--### Input/Output Format--#### Seed Tasks (Input)-```jsonl-{"instruction": "Classify the sentiment of this text as positive or negative."}-{"instruction": "Generate a summary of the given paragraph."}-```--#### Generated Data (Output)-```json-{- "machine_instructions": [+<Note type="info" title="What is Self-Instruct?">+ Self-Instruct is a pipeline for generating high-quality, diverse instructions by combining human-written seed tasks and machine-generated prompts, all filtered for quality and diversity.+</Note>++<AccordionGroup>+ <Accordion title="Key Features">+ <ul>+ <li>Combines human-written and machine-generated instructions using configurable ratios</li>+ <li>Supports both classification and non-classification task types</li>+ <li>Built-in instruction filtering and validation</li>+ <li>Automatic instance generation for tasks</li>+ <li>JSON-based data input/output</li>+ </ul>+ </Accordion>+ <Accordion title="Core Components">+ <b>SelfInstructPipeline</b> – Orchestrates the end-to-end instruction generation, mixing seeds and machine prompts, filtering, and outputting results.<br/>+ <br/>+ <b>InstructionFilter</b> – Handles validation and filtering of all generated instructions:<br/>+ <ul>+ <li>Length-based, keyword, and punctuation checks</li>+ <li>Non-English text detection</li>+ <li>ROUGE similarity filtering for deduplication</li>+ <li>Extensible registry for custom filters</li>+ </ul>+ </Accordion>+</AccordionGroup>++<Card icon="zap" title="Quick Start: Self-Instruct Generation" className="my-6">+ Quickly set up an instruction generation pipeline with both human and machine prompts:++ ```python+ from camel.agents import ChatAgent+ from camel.datagen.self_instruct import SelfInstructPipeline++ # Initialize agent+ agent = ChatAgent()++ # Create pipeline with default settings+ pipeline = SelfInstructPipeline(+ agent=agent,+ seed='seed_tasks.jsonl', # Path to human-written seed tasks+ num_machine_instructions=5,+ data_output_path='./data_output.json',+ human_to_machine_ratio=(6, 2)+ )++ # Generate instructions+ pipeline.generate()+ ```+</Card>++<Card icon="filter" title="Custom Filtering Example" className="my-6">+ Use custom filters to refine and deduplicate instructions as needed:++ ```python+ from camel.datagen.self_instruct import SelfInstructPipeline+ from camel.datagen.self_instruct.filter import InstructionFilter++ # Configure filters+ filter_config = {+ "length": {},+ "keyword": {},+ "punctuation": {},+ "non_english": {},+ "rouge_similarity": {+ "threshold": 0.7,+ "metric": "rouge-l"+ }+ }++ pipeline = SelfInstructPipeline(+ agent=agent,+ seed='seed_tasks.jsonl',+ instruction_filter=InstructionFilter(filter_config),+ num_machine_instructions=5+ )+ ```+</Card>++<AccordionGroup>+<Accordion title = "Pipeline Stages">++<Steps>+ <Step title="Seed Loading">+ Load and validate human-written instructions from JSONL file; initialize task storage.+ </Step>+ <Step title="Instruction Generation">+ Sample both human and machine tasks based on your chosen ratio, then generate new instructions with ChatAgent and apply filters.+ </Step>+ <Step title="Task Classification">+ Automatically determine if tasks are classification or not, and generate the right prompts for each type.+ </Step>+ <Step title="Instance Generation">+ Generate input-output pairs, format and parse instances, and apply quality filters.+ </Step>+ <Step title="Data Output">+ Save all generated instructions and their instances to JSON, with metadata and configuration details.+ </Step>+</Steps>+</Accordion>+ <Accordion title="Pipeline Parameters">+ <ul>+ <li><code>agent</code>: ChatAgent instance for generating instructions</li>+ <li><code>seed</code>: Path to human-written seed tasks in JSONL format</li>+ <li><code>num_machine_instructions</code>: Number of machine-generated instructions (default: 5)</li>+ <li><code>data_output_path</code>: Path for saving generated data (default: <code>./data_output.json</code>)</li>+ <li><code>human_to_machine_ratio</code>: Ratio of human to machine tasks (default: <b>(6, 2)</b>)</li>+ <li><code>instruction_filter</code>: Custom <code>InstructionFilter</code> instance (optional)</li>+ <li><code>filter_config</code>: Configuration dictionary for default filters (optional)</li>+ </ul>+ </Accordion>+ <Accordion title="Filter Configuration">+ The default filter configuration supports:+ <ul>+ <li><b>length</b>: Configure length constraints for instructions</li>+ <li><b>keyword</b>: Set up keyword-based filtering rules</li>+ <li><b>punctuation</b>: Define punctuation validation rules</li>+ <li><b>non_english</b>: Non-English text detection</li>+ <li><b>rouge_similarity</b>: Set ROUGE similarity thresholds for deduplication</li>+ </ul>+ </Accordion>+<Accordion title="Input/Output Format">+ <b>Seed Tasks (Input):</b>+ ```json+ {"instruction": "Classify the sentiment of this text as positive or negative."}+ {"instruction": "Generate a summary of the given paragraph."}+ ```+ <b>Generated Data (Output):</b>+ ```json{- "instruction": "...",- "is_classification": true,- "instances": [+ "machine_instructions": [{- "input": "...",- "output": "..."+ "instruction": "...",+ "is_classification": true,+ "instances": [+ {+ "input": "...",+ "output": "..."+ }+ ]}]}- ]-}-```+ ```+ </Accordion>+</AccordionGroup>+----## Source2Synth: Multi-hop Question-Answer Generation--### Overview--Source2Synth is a sophisticated data generation system designed to create multi-hop question-answer pairs from source text data. It implements a pipeline that processes raw text, extracts information pairs, and generates complex, multi-hop reasoning questions with configurable complexity thresholds.--### Core Components--#### UserDataProcessor--The main orchestrator class that manages the entire pipeline from text processing to dataset generation.--Features:-- Single text and batch processing capabilities-- Configurable AI model or rule-based processing-- Integration with MultiHopGeneratorAgent for QA generation-- Random seed control for reproducibility--#### ExampleConstructor--Handles the construction of training examples from raw text data.--Features:-- Text preprocessing and quality validation-- Information pair extraction with premise-intermediate-conclusion relationships-- Multi-hop QA pair generation using AI or rule-based approaches-- Complexity scoring for generated examples--#### DataCurator--Manages and curates datasets of multi-hop question-answer pairs.--Features:-- Quality filtering based on configurable criteria-- Complexity threshold filtering-- Deduplication of similar examples-- Dataset sampling to achieve target size-- Random seed control for reproducible sampling--### Usage--#### Basic Example--```python-from camel.datagen.source2synth import (- UserDataProcessor,- ProcessorConfig-)--# Create configuration-config = ProcessorConfig(- seed=42,- min_length=50,- max_length=1000,- complexity_threshold=0.5,- dataset_size=10,- use_ai_model=True,-)--# Initialize processor-processor = UserDataProcessor(config)--# Process a single text-result = processor.process_text(- "Your source text here",- source="example_source"-)--# Process multiple texts-texts = ["Text 1", "Text 2", "Text 3"]-sources = ["source1", "source2", "source3"]-batch_results = processor.process_batch(texts, sources)-```--### Configuration Options-#### ProcessorConfig--Key parameters:-- `seed`: Random seed for reproducibility-- `min_length`: Minimum text length for processing-- `max_length`: Maximum text length for processing-- `complexity_threshold`: Minimum complexity score (0.0-1.0)-- `dataset_size`: Target size for the final dataset-- `use_ai_model`: Toggle between AI model and rule-based processing-- `hop_generating_agent`: Custom MultiHopGeneratorAgent instance (optional)--### Pipeline Stages--1. **Text Preprocessing**- - Length validation- - Quality checks- - Text standardization--2. **Information Extraction**- - Premise identification- - Intermediate relationship extraction- - Conclusion formation--3. **QA Generation**- - Multi-hop question generation- - Answer validation- - Complexity scoring--4. **Dataset Curation**- - Quality filtering- - Complexity thresholding- - Deduplication- - Target size sampling+## Source2Synth: Multi-hop Question-Answer Generation+<Note type="info" title="What is Source2Synth?">+ <b>Source2Synth</b> generates complex multi-hop QA pairs from source text (or code) via an orchestrated pipeline of AI-driven and rule-based steps, with curation and complexity control.+</Note>++<AccordionGroup>+ <Accordion title="Core Components">+ <b>UserDataProcessor</b>: Orchestrates the full pipeline, from raw text through QA generation and curation.<br/><br/>+ <b>ExampleConstructor</b>: Builds multi-hop QA examples, extracting premise, intermediate steps, and conclusions. <br/><br/>+ <b>DataCurator</b>: Filters, deduplicates, and samples the final dataset to match quality and complexity requirements.+ </Accordion>+ <Accordion title="Key Features">+ <ul>+ <li>Batch or single text processing</li>+ <li>Switchable AI or rule-based question generation</li>+ <li>Multi-hop QA and complexity scoring</li>+ <li>Integrated curation, deduplication, and reproducible sampling</li>+ <li>Seamless MultiHopGeneratorAgent integration</li>+ </ul>+ </Accordion>+</AccordionGroup>++<Card icon="zap" title="Quick Start: Source2Synth Pipeline" className="my-6">+ Rapidly generate a multi-hop QA dataset from your own text or source files:++ ```python+ from camel.datagen.source2synth import (+ UserDataProcessor,+ ProcessorConfig+ )++ # Create configuration+ config = ProcessorConfig(+ seed=42,+ min_length=50,+ max_length=1000,+ complexity_threshold=0.5,+ dataset_size=10,+ use_ai_model=True,+ )++ # Initialize processor+ processor = UserDataProcessor(config)++ # Process a single text+ result = processor.process_text(+ "Your source text here",+ source="example_source"+ )++ # Process multiple texts+ texts = ["Text 1", "Text 2", "Text 3"]+ sources = ["source1", "source2", "source3"]+ batch_results = processor.process_batch(texts, sources)+ ```+</Card>++<AccordionGroup>+ <Accordion title="ProcessorConfig Parameters">+ <ul>+ <li><code>seed</code>: Random seed for reproducibility</li>+ <li><code>min_length</code>: Minimum text length for processing</li>+ <li><code>max_length</code>: Maximum text length for processing</li>+ <li><code>complexity_threshold</code>: Minimum complexity score (0.0–1.0)</li>+ <li><code>dataset_size</code>: Target size for the final dataset</li>+ <li><code>use_ai_model</code>: Toggle between AI model and rule-based generation</li>+ <li><code>hop_generating_agent</code>: Custom <code>MultiHopGeneratorAgent</code> (optional)</li>+ </ul>+ </Accordion>+ <Accordion title="Pipeline Stages">+ <Steps>+ <Step title="Text Preprocessing">+ Validate text length and quality; standardize for processing.+ </Step>+ <Step title="Information Extraction">+ Identify premises, extract intermediate facts, and form conclusions.+ </Step>+ <Step title="QA Generation">+ Generate multi-hop questions, validate answers, and score for complexity.+ </Step>+ <Step title="Dataset Curation">+ Filter for quality, enforce complexity thresholds, deduplicate, and sample to target size.+ </Step>+ </Steps>+ </Accordion>+</AccordionGroup>+++---## Self-Improving CoT Data Generation-### Overview--The Self-Improving CoT Data Generation pipeline implements an iterative approach to generate and improve reasoning traces for problem-solving tasks. This implementation is based on the methodology of self-taught reasoning, where an AI agent learns to improve its reasoning process through self-evaluation and feedback.--### Architecture--The pipeline consists of four main stages:-1. Initial reasoning trace generation-2. Self-evaluation-3. Feedback-based improvement-4. Iterative refinement--### Key Components--#### SelfImprovingCoTPipeline Class--The core class that implements the STaR methodology with the following features:-- Customizable reasoning and evaluation agents-- Support for both agent-based evaluation and external reward models-- Configurable quality thresholds for different evaluation dimensions-- Iterative improvement process with customizable maximum iterations-- Optional few-shot examples for better reasoning generation-- Flexible output formats and file saving options--### Usage--#### Basic Example--```python-from camel.agents import ChatAgent-from camel.datagen import SelfImprovingCoTPipeline--# Initialize agents-reason_agent = ChatAgent(- """Answer my question and give your- final answer within \\boxed{}."""-)--evaluate_agent = ChatAgent(- "You are a highly critical teacher who evaluates the student's answers "- "with a meticulous and demanding approach."-)--# Prepare your problems-problems = [- {"problem": "Your problem text here"},- # Add more problems...-]--# Create and run the pipeline-pipeline = SelfImprovingCoTPipeline(- reason_agent=reason_agent,- evaluate_agent=evaluate_agent,- problems=problems,- max_iterations=3,- output_path="star_output.json"-)--results = pipeline.generate()-```--#### Advanced Usage with External Reward Models--```python-from camel.models.reward import NemotronRewardModel--# Initialize reward model-reward_model = NemotronRewardModel(- model_type=ModelType.NVIDIA_NEMOTRON_340B_REWARD,- url="https://integrate.api.nvidia.com/v1",- api_key="your_api_key"-)--# Create pipeline with reward model-pipeline = SelfImprovingCoTPipeline(- reason_agent=reason_agent,- evaluate_agent=evaluate_agent,- problems=problems,- reward_model=reward_model,- score_threshold={- "correctness": 0.8,- "clarity": 0.7,- "completeness": 0.7- }-)-```--### Input/Output Formats--#### Input Format--The pipeline expects problems in a JSON format:+<Note type="info" title="What is Self-Improving CoT?">+ This pipeline implements <b>self-taught reasoning</b>—an iterative process where an AI agent refines its own reasoning traces via self-evaluation, feedback, and reward models for continual improvement.+</Note>++<AccordionGroup>+ <Accordion title="Key Components">+ <b>SelfImprovingCoTPipeline</b>: Implements the STaR (Self-Taught Reasoning) methodology, supporting both agent-based and external reward model evaluation, iterative feedback loops, and flexible output formats.<br/><br/>+ - Customizable reasoning and evaluation agents<br/>+ - Support for reward models and custom thresholds<br/>+ - Few-shot learning and rich output options+ </Accordion>+ <Accordion title="Architecture Stages">+ <Steps>+ <Step title="Initial Reasoning Trace Generation">+ The pipeline generates an initial reasoning path for each problem using the designated agent.+ </Step>+ <Step title="Self-Evaluation">+ An evaluator agent (or reward model) critically reviews each reasoning trace for quality, clarity, and correctness.+ </Step>+ <Step title="Feedback-Based Improvement">+ The system refines and re-generates reasoning steps using the evaluation feedback.+ </Step>+ <Step title="Iterative Refinement">+ This evaluation-feedback loop is repeated for a configurable number of iterations to reach optimal performance.+ </Step>+ </Steps>+ </Accordion>+</AccordionGroup>++<Card icon="zap" title="Quick Start: Self-Improving CoT Pipeline" className="my-6">+ Launch a self-improving reasoning workflow with just a few lines:++ ```python+ from camel.agents import ChatAgent+ from camel.datagen import SelfImprovingCoTPipeline++ # Initialize agents+ reason_agent = ChatAgent(+ """Answer my question and give your+ final answer within \\boxed{}."""+ )++ evaluate_agent = ChatAgent(+ "You are a highly critical teacher who evaluates the student's answers "+ "with a meticulous and demanding approach."+ )++ # Prepare your problems+ problems = [+ {"problem": "Your problem text here"},+ # Add more problems...+ ]-```json-{- "problems": [+ # Create and run the pipeline+ pipeline = SelfImprovingCoTPipeline(+ reason_agent=reason_agent,+ evaluate_agent=evaluate_agent,+ problems=problems,+ max_iterations=3,+ output_path="star_output.json"+ )++ results = pipeline.generate()+ ```+</Card>++<Card icon="trophy" title="Advanced: External Reward Model Integration" className="my-6">+ Evaluate and guide reasoning traces with an external reward model, such as Nemotron:++ ```python+ from camel.models.reward import NemotronRewardModel++ # Initialize reward model+ reward_model = NemotronRewardModel(+ model_type=ModelType.NVIDIA_NEMOTRON_340B_REWARD,+ url="https://integrate.api.nvidia.com/v1",+ api_key="your_api_key"+ )++ # Create pipeline with reward model+ pipeline = SelfImprovingCoTPipeline(+ reason_agent=reason_agent,+ evaluate_agent=evaluate_agent,+ problems=problems,+ reward_model=reward_model,+ score_threshold={+ "correctness": 0.8,+ "clarity": 0.7,+ "completeness": 0.7+ }+ )+ ```+</Card>++<AccordionGroup>+ <Accordion title="Input/Output Format">+ <b>Input Format (JSON):</b>+ ```json+ {+ "problems": [{- "problem": "Problem text here",- "solution": "Optional solution text"+ "problem": "Problem text here",+ "solution": "Optional solution text"}- ]-}-```--#### Output Format--The pipeline generates output in JSON format containing:-- Original problem-- Final reasoning trace-- Improvement history with iterations-- Evaluation scores and feedback for each iteration--### Configuration Options--- `max_iterations`: Maximum number of improvement iterations (default: 3)-- `score_threshold`: Quality thresholds for evaluation dimensions (default: 0.7)-- `few_shot_examples`: Optional examples for few-shot learning-- `output_path`: Path for saving results (optional)--+ ]+ }+ ```+ <b>Output Format (JSON):</b>+ <ul>+ <li>Original problem</li>+ <li>Final reasoning trace</li>+ <li>Improvement history with iterations</li>+ <li>Evaluation scores and feedback per iteration</li>+ </ul>+ </Accordion>+ <Accordion title="Configuration Options">+ <ul>+ <li><code>max_iterations</code>: Maximum number of improvement iterations (default: <b>3</b>)</li>+ <li><code>score_threshold</code>: Minimum quality thresholds for evaluation dimensions (default: <b>0.7</b>)</li>+ <li><code>few_shot_examples</code>: (Optional) Examples for few-shot learning</li>+ <li><code>output_path</code>: (Optional) Path for saving generated results</li>+ </ul>+ </Accordion>+</AccordionGroup>diff --git a/docs/key_modules/embeddings.md b/docs/key_modules/embeddings.mdindex 67bc17528..27f5094f7 100644--- a/docs/key_modules/embeddings.md+++ b/docs/key_modules/embeddings.md@@ -1,114 +1,167 @@-## 1. Concept-Creating embeddings for different types of data (text, images, videos) involves transforming these inputs into a numerical form that machines can understand and process efficiently. Each type of embedding focuses on capturing the essential features of its respective data type.--### 1.1. Text Embeddings-Text embeddings convert textual data into numerical vectors. Each vector represents the semantic meaning of the text, enabling us to process and compare texts based on their meaning rather than just their raw form. Techniques like OpenAI Embedding use large-scale language models to understand context and nuances in language. SentenceTransformerEncoder, on the other hand, is specifically designed to create sentence embeddings, often using BERT-like models.--Consider two sentences:--- "A young boy is playing soccer in a park."--- "A child is kicking a football on a playground."--Text embedding models would transform these sentences into two high-dimensional vector (*e.g.*, 1536 dimension if using `text-embedding-3-small`). Despite different wordings, the vectors will be similar, capturing the shared concept of a child playing a ball game outdoors. This transformation into vectors allows machines to understand and compare the semantic similarities between the context.--### 1.2. Image Embeddings-Image embeddings convert images into numerical vectors, capturing essential features like shapes, colors, textures, and spatial hierarchies. This transformation is typically performed by Convolutional Neural Networks (CNNs) or other advanced neural network architectures designed for image processing. The resulting embeddings can be used for tasks like image classification, similarity comparison, and retrieval.--Suppose we have an image of a cat. An image embedding model would analyze the visual content (e.g., the shape of the ears, the pattern of the fur) and convert it into a vector. This vector encapsulates the essence of the image, allowing the model to recognize it as a cat and differentiate it from other images.---## 2. Types--### 2.1. `OpenAIEmbedding`-Utilizes OpenAI's models for generating text embeddings. This will requires OpenAI API Key.--### 2.2. `MistralEmbedding`-Utilizes Mistral's models for generating text embeddings. This will requires Mistral API Key.--### 2.3. `SentenceTransformerEncoder`-Utilizes open-source models from the Sentence Transformers library for generating text embeddings.--### 2.4. `VisionLanguageEmbedding`-Utilizes OpenAI's models for generating image embeddings. This will requires OpenAI API Key.--### 2.5. `AzureOpenAI`-Utilizes OpenAI's models for generating text embeddings. This will requires Azure OpenAI API Key.--### 2.6. `TogetherEmbedding`-Utilizes Together AI's models for generating text embeddings. This will requires Together AI API Key.---## 3. Get Started-To use the embedding functionalities, you need to import the necessary classes.--### 3.1. Using `OpenAIEmbedding`-```python+---+title: "Embeddings"+icon: vector-square+---++<Card title="What Are Embeddings??" icon="file-vector">+ Embeddings transform text, images, and other media into dense numeric vectors+ that capture their underlying meaning. This makes it possible for machines to+ perform semantic search, similarity, recommendations, clustering, RAG, and+ more.+</Card>++<Card title="How Text & Image Embeddings Work" icon="question">+Text embeddings turn sentences or documents into high-dimensional vectors that capture meaning.+Example:+<ul>+ <li>“A young boy is playing soccer in a park.”</li>+ <li>“A child is kicking a football on a playground.”</li>+</ul>+These sentences get mapped to similar vectors, letting your AI recognize their meaning, regardless of wording.++Image embeddings use neural networks (like CNNs) or vision-language models to turn images into numeric vectors, capturing shapes, colors, and features. For example: A cat image → vector that is “close” to other cats and “far” from cars in vector space.++</Card>++## Supported Embedding Types++<CardGroup cols={2}>+ <Card title="OpenAIEmbedding" icon="cloud">+ Use OpenAI’s API to generate text embeddings.+ <br />+ <b>Requires:</b> OpenAI API Key.+ </Card>+ <Card title="MistralEmbedding" icon="wind">+ Use Mistral’s API for text embeddings.+ <br />+ <b>Requires:</b> Mistral API Key.+ </Card>+ <Card title="SentenceTransformerEncoder" icon="align-left">+ Local, open-source transformer models from the{" "}+ <a href="https://www.sbert.net" target="_blank">+ Sentence Transformers+ </a>{" "}+ library.+ </Card>+ <Card title="VisionLanguageEmbedding" icon="image">+ OpenAI’s vision models for image embeddings.+ <br />+ <b>Requires:</b> OpenAI API Key.+ </Card>+ <Card title="AzureOpenAI" icon="cloud">+ Text embeddings from OpenAI models on Azure.+ <br />+ <b>Requires:</b> Azure OpenAI API Key.+ </Card>+ <Card title="TogetherEmbedding" icon="users">+ Together AI’s hosted models for text embeddings.+ <br />+ <b>Requires:</b> Together AI API Key.+ </Card>+</CardGroup>++## Usage Examples++<Note>+ Make sure you have the right API key set (OpenAI, Mistral, Azure, or Together)+ for the embedding backend you want to use.+</Note>++<Card title="Text Embeddings with OpenAI" icon="cloud">+<CodeGroup>+```python openai_embed.pyfrom camel.embeddings import OpenAIEmbeddingfrom camel.types import EmbeddingModelType-# Initialize the OpenAI embedding with a specific modelopenai_embedding = OpenAIEmbedding(model_type=EmbeddingModelType.TEXT_EMBEDDING_3_SMALL)--# Generate embeddings for a list of textsembeddings = openai_embedding.embed_list(["Hello, world!", "Another example"])-```-### 3.2. Using `MistralEmbedding`-```python+````+</CodeGroup>+</Card>++<Card title="Text Embeddings with Mistral" icon="wind">+<CodeGroup>+```python mistral_embed.pyfrom camel.embeddings import MistralEmbeddingfrom camel.types import EmbeddingModelType-# Initialize the OpenAI embedding with a specific modelmistral_embedding = MistralEmbedding(model_type=EmbeddingModelType.MISTRAL_EMBED)--# Generate embeddings for a list of textsembeddings = mistral_embedding.embed_list(["Hello, world!", "Another example"])-```+````-### 3.3. Using `SentenceTransformerEncoder`-```python+</CodeGroup>+</Card>++<Card title="Local Sentence Transformers" icon="align-left">+<CodeGroup>+```python sentence_transformer_embed.pyfrom camel.embeddings import SentenceTransformerEncoder-# Initialize the Sentence Transformer Encoder with a specific modelsentence_encoder = SentenceTransformerEncoder(model_name='intfloat/e5-large-v2')--# Generate embeddings for a list of textsembeddings = sentence_encoder.embed_list(["Hello, world!", "Another example"])-```-### 3.4. Using `VisionLanguageEmbedding`-```python+````+</CodeGroup>+</Card>++<Card title="Image Embeddings with Vision-Language Models" icon="image">+<CodeGroup>+```python image_embed.pyfrom camel.embeddings import VisionLanguageEmbedding+from PIL import Image+import requestsvlm_embedding = VisionLanguageEmbedding()-url = "http://images.cocodataset.org/val2017/000000039769.jpg"image = Image.open(requests.get(url, stream=True).raw)test_images = [image, image]-embeddings = vlm_embedding.embed_list(test_images)-```+````++</CodeGroup>+</Card>-### 3.5. Using `AzureOpenAI`-```python+<Card title="Text Embeddings with Azure OpenAI" icon="cloud">+<CodeGroup>+```python azure_embed.pyfrom camel.embeddings import AzureEmbeddingfrom camel.types import EmbeddingModelType-# Initialize the OpenAI embedding with a specific modelazure_openai_embedding = AzureEmbedding(model_type=EmbeddingModelType.TEXT_EMBEDDING_ADA_2)--# Generate embeddings for a list of textsembeddings = azure_openai_embedding.embed_list(["Hello, world!", "Another example"])-```-### 3.6. Using `TogetherEmbedding`-```python+````+</CodeGroup>+</Card>++<Card title="Text Embeddings with Together AI" icon="users">+<CodeGroup>+```python together_embed.pyfrom camel.embeddings import TogetherEmbedding-# Initialize the Together AI embedding with a specific modeltogether_embedding = TogetherEmbedding(model_type="togethercomputer/m2-bert-80M-8k-retrieval")--# Generate embeddings for a list of textsembeddings = together_embedding.embed_list(["Hello, world!", "Another example"])-```+````++</CodeGroup>+</Card>++<Tip>+ Pick a text embedding that matches your language, latency, and privacy needs.+ For multimodal use cases, use image or vision-language embeddings.+</Tip>++<CardGroup cols={2}>+ <Card title="See Example Workflows" icon="rocket" href="/cookbooks/">+ Explore retrieval-augmented generation (RAG) and search recipes using+ embeddings.+ </Card>+ <Card+ title="All Supported Embedding APIs"+ icon="link"+ href="/reference/#embeddings"+ >+ Full API docs and all configuration options.+ </Card>+</CardGroup>diff --git a/docs/key_modules/interpreters.md b/docs/key_modules/interpreters.mdindex 6db8c398b..f90576db4 100644--- a/docs/key_modules/interpreters.md+++ b/docs/key_modules/interpreters.md@@ -1,66 +1,140 @@-## 1. Concept-Interpreters are tools that empower agents to execute given code snippets on the local machine or in isolated environments. CAMEL supports several types of interpreters to cater to different needs and security considerations.--### 1.1. Internal Python Interpreter-The Internal Python Interpreter executes Python code directly within the same process as the agent. This is the simplest interpreter and is suitable for trusted code execution. In its default (safe) mode, it evaluates expressions and executes statements in a controlled environment; `print()` is not directly available as a side effect, so code should evaluate to a string for output.--**Example Usage:**-```python-from camel.interpreters import InternalPythonInterpreter+---+title: "Interpreters"+description: "Execute code safely and flexibly with CAMEL’s suite of interpreters: local, isolated, and cloud-based execution environments."+icon: terminal+---++Interpreters allow CAMEL agents to **execute code snippets** in various secure and flexible environments—from local safe execution to isolated Docker containers and managed cloud sandboxes.++## What are Interpreters?++<Note type="info" title="Interpreter Concept">+ Interpreters empower agents to run code dynamically—enabling evaluation,+ testing, task automation, and rich feedback loops. Choose your interpreter+ based on trust, isolation, and supported languages.+</Note>++<div className="grid grid-cols-1 md:grid-cols-2 xl:grid-cols-3 gap-4 my-6">++{" "}+<Card icon="python" title="Internal Python Interpreter">+ <b>Fast, local, safe</b> execution for trusted Python code within the agent+ process.+ <br />+ <small>+ <b>Best for:</b> Trusted code, quick Python evaluation.+ </small>+</Card>++{" "}+<Card icon="code" title="Subprocess Interpreter">+ <b>Isolated execution</b> in a subprocess. Supports Bash, Python, shell+ scripts.+ <br />+ <small>+ <b>Best for:</b> Shell commands, scripts, process isolation.+ </small>+</Card>++{" "}+<Card icon="docker" title="Docker Interpreter">+ <b>Fully sandboxed</b> in Docker containers.+ <br />+ <small>+ <b>Best for:</b> Untrusted code, dependency isolation, safe experimentation.+ </small>+ <br />+ <a href="https://docs.docker.com/get-docker/" target="_blank" rel="noopener">+ Install Docker+ </a>+</Card>++{" "}+<Card icon="book-open" title="IPython Interpreter">+ <b>Interactive, stateful</b> execution via Jupyter/IPython kernel.+ <br />+ <small>+ <b>Best for:</b> Multi-step reasoning, persistent variables, rich outputs.+ </small>+</Card>++{" "}+<Card icon="cloud" title="E2B Interpreter">+ <b>Cloud-based sandboxing</b> for scalable, secure remote execution.+ <br />+ <small>+ <b>Best for:</b> Managed, scalable tasks. No local setup needed.+ </small>+ <br />+ <a href="https://e2b.dev/docs" target="_blank" rel="noopener">+ E2B Docs+ </a>+</Card>++</div>++---++<Card icon="python" title="Internal Python Interpreter" className="my-6">+ <b>Fast, local, and safe</b>—executes trusted Python code directly within the CAMEL agent process.<br/>+ <b>Note:</b> Only expressions (not statements) are allowed in strict safe mode; for output, your code should evaluate to a string.+ <br/><br/>+ ```python+ from camel.interpreters import InternalPythonInterpreter# Initialize the interpreter+interpreter = InternalPythonInterpreter()-# Code to execute (must be an expression that evaluates to a string in safe mode)+# Code to execute (should evaluate to a string)+python_code = "'Hello from InternalPythonInterpreter!'"-# Execute the code+# Run code+result_str = interpreter.run(code=python_code, code_type="python")print(f"Result: {result_str}")-```-### 1.2. Subprocess Interpreter-The Subprocess Interpreter runs code in a separate subprocess. This provides a degree of isolation from the main agent process. It can execute various shell commands and scripts in addition to Python code.+````+</Card>-**Example Usage:**+<Card icon="code" title="Subprocess Interpreter" className="my-6">+Execute shell commands or scripts in a separate process for isolation and flexibility.<br/>+Supports multiple languages, including Bash and Python.+<br/><br/>```pythonfrom camel.interpreters import SubprocessInterpreter-# Initialize the interpreterinterpreter = SubprocessInterpreter()--# Command to execute (e.g., bash)shell_command = "echo 'Hello from SubprocessInterpreter!'"-# Execute the commandresult_str = interpreter.run(code=shell_command, code_type="bash")print(f"Result: {result_str.strip()}")-```--### 1.3. Docker Interpreter-The Docker Interpreter executes code snippets within a Docker container. This offers a high level of isolation, ensuring that code runs in a controlled and sandboxed environment. This is particularly useful for running untrusted code or code with specific dependencies.+````-**To utilize this interpreter, you need to have Docker installed on your system.** For more information on Docker installation, visit [Docker's official website](https://docs.docker.com/get-docker/).+</Card>-**Example Usage:**-```python-from camel.interpreters import DockerInterpreter+<Card icon="docker" title="Docker Interpreter" className="my-6">+ Provides full isolation—code runs in a Docker container, protecting your host system and supporting any dependencies.<br/>+ <b>Requires Docker installed.</b>+ <br/>+ <a href="https://docs.docker.com/get-docker/" target="_blank">Install Docker</a>+ <br/><br/>+ ```python+ from camel.interpreters import DockerInterpreter-# Initialize the interpreter (assumes a basic python image is available)interpreter = DockerInterpreter()--# Code to execute in Dockerpython_code_in_docker = "print('Hello from DockerInterpreter!')"-# Execute the coderesult_str = interpreter.run(code=python_code_in_docker, code_type="python")print(f"Result: {result_str.strip()}")-```-### 1.4. IPython Interpreter-The IPython Interpreter (JupyterKernelInterpreter) leverages an IPython kernel to execute code. This allows for a rich, interactive execution environment, similar to using a Jupyter notebook. It supports features like state persistence across code executions within a session.+````+</Card>-**Example Usage:**+<Card icon="book-open" title="IPython Interpreter (JupyterKernel)" className="my-6">+Interactive, stateful execution in a Jupyter-like Python kernel—maintains session state and supports rich outputs.+<br/><br/>```pythonfrom camel.interpreters import JupyterKernelInterpreter@@ -68,25 +142,46 @@ interpreter = JupyterKernelInterpreter(require_confirm=False, print_stdout=True, print_stderr=True)-python_code_in_jupyter_kernel = "print('Hello from JupyterKernelInterpreter!')"result = interpreter.run(code=python_code_in_jupyter_kernel, code_type="python")print(result)-```--### 1.5. E2B Interpreter-The E2B Interpreter utilizes the E2B cloud-based sandboxed environments for code execution. This provides a secure and managed environment for running code without requiring local setup of complex dependencies or risking local system integrity.+````-For more information, visit the [E2B official documentation](https://e2b.dev/docs).+</Card>-**Example Usage:**-```python-from camel.interpreters import E2BInterpreter+<Card icon="cloud" title="E2B Interpreter (Cloud Sandbox)" className="my-6">+ Run code in a secure, scalable, cloud-based environment—no local setup needed, great for running untrusted or complex code.<br/>+ <a href="https://e2b.dev/docs" target="_blank">E2B Documentation</a>+ <br/><br/>+ ```python+ from camel.interpreters import E2BInterpreterinterpreter = E2BInterpreter()--python_code_in_e2b = "print('Hello from E2BInterpreter!')"result = interpreter.run(code=python_code_in_e2b, code_type="python")print(result)-```\ No newline at end of file++```+</Card>++<AccordionGroup>+<Accordion title="Best Practices">+ <ul>+ <li>Use <b>InternalPythonInterpreter</b> only for trusted and simple Python code.</li>+ <li><b>Subprocess</b> and <b>Docker</b> interpreters are better for code isolation and dependency management.</li>+ <li>Prefer <b>Docker</b> for any untrusted code or when extra libraries are needed.</li>+ <li><b>E2B Interpreter</b> is ideal for scalable, managed, and safe cloud execution—no local risk.</li>+ <li>For interactive, multi-step logic, leverage <b>JupyterKernelInterpreter</b> for persistent session state.</li>+ <li>Always validate and sanitize user inputs if agents dynamically construct code for execution.</li>+ </ul>+</Accordion>+<Accordion title="Troubleshooting & Tips">+ <ul>+ <li>If Docker isn’t working, verify your Docker daemon is running and you have the correct permissions.</li>+ <li>For E2B, check API key and account limits if code doesn’t execute.</li>+ <li>Long-running scripts are best managed in <b>Subprocess</b> or <b>Docker</b> interpreters with timeout controls.</li>+ <li>Use session resets (where supported) to avoid cross-task state bleed in Jupyter/IPython interpreters.</li>+ </ul>+</Accordion>+</AccordionGroup>+```diff --git a/docs/key_modules/loaders.md b/docs/key_modules/loaders.mdindex e42234753..fd06347a0 100644--- a/docs/key_modules/loaders.md+++ b/docs/key_modules/loaders.md@@ -1,244 +1,298 @@-## 1. Concept-CAMEL introduced two IO modules, `Base IO` and `Unstructured IO` which are designed for handling various file types and unstructured data processing.-Additionally, several data readers were added, including `Apify Reader`, `Chunkr Reader`, `Firecrawl Reader`, `Jina_url Reader`, and `Mistral Reader`, which enable retrieval of external data for improved data integration and analysis.--## 2. Types--### 2.1. Base IO-Base IO module is focused on fundamental input/output operations related to files. It includes functionalities for representing, reading, and processing different file formats.--### 2.2. Unstructured IO-Unstructured IO module deals with the handling, parsing, and processing of unstructured data. It provides tools for parsing files or URLs, cleaning data, extracting specific information, staging elements for different platforms, and chunking elements. The core of this module lies in its advanced ETL capabilities to manipulate unstructured data to make it usable for various applications like Retrieval-Augmented Generation(RAG).--### 2.3. Apify Reader-Apify Reader provides a Python interface to interact with the Apify platform for automating web workflows. It allows users to authenticate via an API key and offers methods to execute and manage actors (automated web tasks) and datasets on the platform.-It includes functionalities for client initialization, actor management, dataset operation.--### 2.4. Chunkr Reader-Chunkr Reader is a Python client for interacting with the Chunkr API, which processes documents and returns content in various formats. It includes functionalities for client initialization, task management, formatting response.--### 2.5. Firecrawl Reader-Firecrawl Reader provides a Python interface to interact with the Firecrawl API, allowing users to turn websites into large language model (LLM)-ready markdown format.--### 2.6. Jina_url Reader-JinaURL Reader is a Python client for Jina AI's URL reading service, optimized to provide cleaner, LLM-friendly content from URLs.--### 2.7 MarkitDown Reader-MarkItDown is a lightweight Python utility for converting various files to Markdown for use with LLMs and related text analysis pipelines.--### 2.8 Mistral Reader-Mistral Reader is a Python client for interacting with Mistral AI's OCR service, which can extract text from PDFs and images. It provides capabilities to process both local files and remote URLs, supporting various file formats.--## 3. Get Started--### 3.1. Using `Base IO`-+---+title: "Loaders"+icon: loader+---++<Card title="What are Loaders?" icon="loader">+ CAMEL’s Loaders provide flexible ways to ingest and process all kinds of data+ structured files, unstructured text, web content, and even OCR from images.+ They power your agent’s ability to interact with the outside world. itionally,+ several data readers were added, including `Apify Reader`, `Chunkr Reader`,+ `Firecrawl Reader`, `Jina_url Reader`, and `Mistral Reader`, which enable+ retrieval of external data for improved data integration and analysis.+</Card>+## Types++<AccordionGroup>++{" "}+<Accordion title="Base IO" icon="file">+ Handles core file input/output for formats like PDF, DOCX, HTML, and more.<br></br>+ Lets you represent, read, and process structured files.+</Accordion>++{" "}+<Accordion title="Unstructured IO" icon="puzzle">+ Powerful ETL for parsing, cleaning, extracting, chunking, and staging+ unstructured data.<br></br>+ Perfect for RAG pipelines and pre-processing.+</Accordion>++{" "}+<Accordion title="Apify Reader" icon="robot">+ Integrates with Apify to automate web workflows and scraping.<br></br>+ Supports authentication, actor management, and dataset operations via API.+</Accordion>++{" "}+<Accordion title="Chunkr Reader" icon="scissors">+ Connects to the Chunkr API for document chunking, segmentation, and OCR.<br></br>+ Handles everything from simple docs to scanned PDFs.+</Accordion>++{" "}+<Accordion title="Firecrawl Reader" icon="fire">+ Converts entire websites into LLM-ready markdown using the Firecrawl API.<br></br>+ Useful for quickly ingesting web content as clean text.+</Accordion>++{" "}+<Accordion title="JinaURL Reader" icon="globe">+ Uses Jina AI’s URL reading service to cleanly extract web content.<br></br>+ Designed for LLM-friendly extraction from any URL.+</Accordion>++{" "}+<Accordion title="MarkitDown Reader" icon="note">+ Lightweight tool to convert files (HTML, DOCX, PDF, etc.) into Markdown.<br></br>+ Ideal for prepping documents for LLM ingestion or analysis.+</Accordion>++{" "}+<Accordion title="Mistral Reader" icon="book-open-reader">+ Integrates Mistral AI’s OCR service for extracting text from images and PDFs.+ <br></br>+ Supports both local and remote file processing for various formats.+</Accordion>++</AccordionGroup>++## Get Started++<Card title="Using Base IO" icon="file">This module is designed to read files of various formats, extract their contents, and represent them as `File` objects, each tailored to handle a specific file type.-```python+<CodeGroup>+```python base_io_example.pyfrom io import BytesIOfrom camel.loaders import create_file_from_raw_bytes# Read a pdf file from disk+with open("test.pdf", "rb") as file:- file_content = file.read()+file_content = file.read()# Use the create_file function to create an object based on the file extension+file_obj = create_file_from_raw_bytes(file_content, "test.pdf")# Once you have the File object, you can access its content+print(file_obj.docs[0]["page_content"])-```-### 3.2. Using `Unstructured IO`+````+</CodeGroup>+</Card>-To get started with the `Unstructured IO` module, you first need to import the module and initialize an instance of it. Once initialized, you can utilize this module to handle a variety of functionalities such as parsing, cleaning, extracting data, and integrating with cloud services like AWS S3 and Azure. Here's a basic guide to help you begin:+----Utilize `parse_file_or_url` to load and parse unstructured data from a file or URL-```python+<Card title="Using Unstructured IO" icon="puzzle">+To get started with the <code>Unstructured IO</code> module, just import and initialize it. You can parse, clean, extract, chunk, and stage data from files or URLs. Here’s how you use it step by step:++<br />++<strong>1. Parse unstructured data from a file or URL:</strong>+<CodeGroup>+```python unstructured_io_parse.pyfrom camel.loaders import UnstructuredIOuio = UnstructuredIO()-# Set example urlexample_url = ("https://www.cnn.com/2023/01/30/sport/empire-state-building-green-"- "philadelphia-eagles-spt-intl/index.html")+ "philadelphia-eagles-spt-intl/index.html"+)elements = uio.parse_file_or_url(example_url)print(("\n\n".join([str(el) for el in elements])))+````++```markdown parsed_elements.md+> > > The Empire State Building was lit in green and white to celebrate the Philadelphia Eagles’ victory in the NFC Championship game on Sunday – a decision that’s sparked a bit of a backlash in the Big Apple.+> > > The Eagles advanced to the Super Bowl for the first time since 2018 after defeating the San Francisco 49ers 31-7, and the Empire State Building later tweeted how it was marking the occasion.+> > > Fly @Eagles Fly! We’re going Green and White in honor of the Eagles NFC Championship Victory. pic.twitter.com/RNiwbCIkt7— Empire State Building (@EmpireStateBldg)+> > > January 29, 2023...```-```markdown->>> The Empire State Building was lit in green and white to celebrate the Philadelphia Eagles’ victory in the NFC Championship game on Sunday – a decision that’s sparked a bit of a backlash in the Big Apple.->>> The Eagles advanced to the Super Bowl for the first time since 2018 after defeating the San Francisco 49ers 31-7, and the Empire State Building later tweeted how it was marking the occasion.+</CodeGroup>->>> Fly @Eagles Fly! We’re going Green and White in honor of the Eagles NFC Championship Victory. pic.twitter.com/RNiwbCIkt7— Empire State Building (@EmpireStateBldg)+<br />->>> January 29, 2023...-```+<strong>2. Clean unstructured text data:</strong>+<CodeGroup>+ ```python unstructured_io_clean.py example_dirty_text = ("\x93Some dirty text+ ’ with extra spaces and – dashes.") options = [ ('replace_unicode_quotes',{" "}+ {}), ('clean_dashes', {}), ('clean_non_ascii_chars', {}),+ ('clean_extra_whitespace', {}), ] cleaned_text =+ uio.clean_text_data(text=example_dirty_text, clean_options=options)+ print(cleaned_text) ``` ```markdown cleaned_text.md >>> Some dirty text with+ extra spaces and dashes. ```+</CodeGroup>-Utilize `clean_text_data` to do various text cleaning operations-```python-# Set example dirty text-example_dirty_text = ("\x93Some dirty text ’ with extra spaces and – dashes.")--# Set clean options-options = [- ('replace_unicode_quotes', {}),- ('clean_dashes', {}),- ('clean_non_ascii_chars', {}),- ('clean_extra_whitespace', {}),-]--cleaned_text = uio.clean_text_data(text=example_dirty_text,clean_options=options)-print(cleaned_text)-```-```markdown->>> Some dirty text with extra spaces and dashes.-```+<br />-Utilize `extract_data_from_text` to do text extraction operation-```python-# Set example email to extract+<strong>3. Extract data from text (for example, emails):</strong>+<CodeGroup>+```python unstructured_io_extract.pyexample_email_text = "Contact me at [email protected]."-extracted_text = uio.extract_data_from_text(text=example_email_text,-extract_type="extract_email_address")-+extracted_text = uio.extract_data_from_text(+text=example_email_text,+extract_type="extract_email_address"+)print(extracted_text)-```-```markdown++````+```markdown extracted_email.md>>> ['[email protected]']-```+````-Utilize `chunk_elements` to chunk the content-```python-chunks = uio.chunk_elements(elements=elements,chunk_type="chunk_by_title")+</CodeGroup>-for chunk in chunks:- print(chunk)- print("\n" + "-" * 80)-```-```markdown->>> The Empire State Building was lit in green and white to celebrate the Philadelphia Eagles’ victory in the NFC Championship game on Sunday – a decision that’s sparked a bit of a backlash in the Big Apple.+<br />->>> The Eagles advanced to the Super Bowl for the first time since 2018 after defeating the San Francisco 49ers 31-7, and the Empire State Building later tweeted how it was marking the occasion.+<strong>4. Chunk content by title:</strong>+<CodeGroup>+```python unstructured_io_chunk.py+chunks = uio.chunk_elements(elements=elements, chunk_type="chunk_by_title")->>> --------------------------------------------------------------------------------->>> Fly @Eagles Fly! We’re going Green and White in honor of the Eagles NFC Championship Victory. pic.twitter.com/RNiwbCIkt7— Empire State Building (@EmpireStateBldg)+for chunk in chunks:+print(chunk)+print("\n" + "-" \* 80)->>> --------------------------------------------------------------------------------->>> January 29, 2023-```+````+```markdown chunked_content.md+>>> The Empire State Building was lit in green and white to celebrate the Philadelphia Eagles’ victory in the NFC Championship game on Sunday – a decision that’s sparked a bit of a backlash in the Big Apple.+>>> --------------------------------------------------------------------------------+>>> Fly @Eagles Fly! We’re going Green and White in honor of the Eagles NFC Championship Victory. pic.twitter.com/RNiwbCIkt7— Empire State Building (@EmpireStateBldg)+>>> --------------------------------------------------------------------------------+>>> January 29, 2023+````-Utilize `stage_elements` to do element staging-```python-staged_element = uio.stage_elements(elements=elements,stage_type="stage_for_baseplate")+</CodeGroup>+<br />++<strong>5. Stage elements for use with other platforms:</strong>+<CodeGroup>+```python unstructured_io_stage.py+staged_element = uio.stage_elements(elements=elements, stage_type="stage_for_baseplate")print(staged_element)```-```markdown+```markdown staged_elements.md>>> {'rows': [{'data': {'type': 'UncategorizedText', 'element_id': 'e78902d05b0cb1e4c38fc7a79db450d5', 'text': 'CNN\n \xa0—'}, 'metadata': {'filetype': 'text/html', 'languages': ['eng'], 'page_number': 1, 'url': 'https://www.cnn.com/2023/01/30/sport/empire-state-building-green-philadelphia-eagles-spt-intl/index.html', 'emphasized_text_contents': ['CNN'], 'emphasized_text_tags': ['span']}}, ...```-This is a basic guide to get you started with the `Unstructured IO` module. For more advanced usage, refer to the specific method documentation and the [Unstructured IO Documentation](https://docs.unstructured.io).+</CodeGroup>-### 3.3. Using `Apify Reader`+<br />+This guide gets you started with <code>Unstructured IO</code>. For more, see the <a href="https://docs.unstructured.io" target="_blank">Unstructured IO Documentation</a>.+</Card>-Initialize the client, set up the required actors and parameters.-```python+---++<Card title="Using Apify Reader" icon="robot">+Initialize the Apify client, set up the required actors and parameters, and run the actor.++<CodeGroup>+```python apify_reader.pyfrom camel.loaders import Apifyapify = Apify()run_input = {- "startUrls": [{"url": "https://www.camel-ai.org/"}],- "maxCrawlDepth": 0,- "maxCrawlPages": 1,+"startUrls": [{"url": "https://www.camel-ai.org/"}],+"maxCrawlDepth": 0,+"maxCrawlPages": 1,}actor_result = apify.run_actor(- actor_id="apify/website-content-crawler", run_input=run_input+actor_id="apify/website-content-crawler", run_input=run_input)-```--Retrieve the result database ID and access it using the get_dataset_items method.-```pythondataset_result = apify.get_dataset_items(- dataset_id=actor_result["defaultDatasetId"]+dataset_id=actor_result["defaultDatasetId"])-```-```markdown->>>[{'url': 'https://www.camel-ai.org/', 'crawl': {'loadedUrl': 'https://www.camel--ai.org/', 'loadedTime': '2024-10-27T04:51:16.651Z', 'referrerUrl': 'https://ww-w.camel-ai.org/', 'depth': 0, 'httpStatusCode': 200}, 'metadata': {'canonicalUr-l': 'https://www.camel-ai.org/', 'title': 'CAMEL-AI', 'description': 'CAMEL-AI.-org is the 1st LLM multi-agent framework and an open-source community dedicated- to finding the scaling law of agents.', 'author': None, 'keywords': None, 'lan- guageCode': 'en', 'openGraph': [{'property': 'og:title', 'content': 'CAMEL-AI'- }, {'property': 'og:description', 'content': 'CAMEL-AI.org is the 1st LLM mult- i-agent framework and an open-source community dedicated to finding the scaling- g law of agents.'}, {'property': 'twitter:title', 'content': 'CAMEL-AI'}, {'pr- operty': 'twitter:description', 'content': 'CAMEL-AI.org is the 1st LLM multi-- agent framework and an open-source community dedicated to finding the scaling- law of agents.'}, {'property': 'og:type', 'content': 'website'}], 'jsonLd': No- ne, 'headers': {'date': 'Sun, 27 Oct 2024 04:50:18 GMT', 'content-type': 'text- /html', 'cf-ray': '8d901082dae7efbe-PDX', 'cf-cache-status': 'HIT', 'age': '10- 81', 'content-encoding': 'gzip', 'last-modified': 'Sat, 26 Oct 2024 11:51:32 G- MT', 'strict-transport-security': 'max-age=31536000', 'surrogate-control': 'ma- x-age=432000', 'surrogate-key': 'www.camel-ai.org 6659a154491a54a40551bc78 pag- eId:6686a2bcb7ece5fb40457491 668181a0a818ade34e653b24 6659a155491a54a40551bd7e- ', 'x-lambda-id': 'd6c4424b-ac67-4c54-b52a-cb2a22ca09f0', 'vary': 'Accept-Enco- ding', 'set-cookie': '__cf_bm=oX5EmZ2SNJDOBQXI8dL_reCYlCpp1FMzu40qCNxiopU-1730- 004618-1.0.1.1-3teEeqUoemzHWAeGCtlPJVqdmAbiFkyu3JxopKfQFFndSCi_Z56RR.UDjLGZiq.- L_4LvAZYmNKxQ.k6VRhbA7g; path=/; expires=Sun, 27-Oct-24 05:20:18 GMT; domain=.- cdn.webflow.com; HttpOnly; Secure; SameSite=None\n_cfuvid=om_8lj9jNMIh.HEIxEAq- gszhEWaKlyS2kdXKwqGedSM-1730004618924-0.0.1.1-604800000; path=/; domain=.cdn.w- ebflow.com; HttpOnly; Secure; SameSite=None', 'alt-svc': 'h3=":443"; ma=86400'- , 'x-cluster-name': 'us-west-2-prod-hosting-red', 'x-firefox-spdy': 'h2'}}, 's- creenshotUrl': None, 'text': 'Build Multi-Agent Systems for _\nFEATURES & Inte- grations\nSeamless integrations with\npopular platforms \nScroll to explore ou- r features & integrations.', 'markdown': '# Build Multi-Agent Systems for \\_- \n\nFEATURES & Integrations\n\n## Seamless integrations with \npopular platfo- rms\n\nScroll to explore our features & integrations.'}]-```+print(dataset_result)-### 3.4. Using `Firecrawl Reader`+````+```markdown apify_output.md+>>>[{'url': 'https://www.camel-ai.org/', 'crawl': {'loadedUrl': 'https://www.camel-ai.org/', ...}, 'metadata': {'canonicalUrl': 'https://www.camel-ai.org/', ...}, ... }]+````-Initialize the client and set the URL from which we want to retrieve information. When the status is "completed," the information retrieval is finished and ready for reading.-```python-firecrawl = Firecrawl()+</CodeGroup>+</Card>-response = firecrawl.crawl(url="https://www.camel-ai.org/about")-print(response["status"])-```-```markdown->>>completed-```+----Directly retrieve information from the returned results.-```python-print(response["data"][0]["markdown"])-```-```markdown->>>Camel-AI Team+<Card title="Using Firecrawl Reader" icon="fire">+Firecrawl Reader provides a simple way to turn any website into LLM-ready markdown format. Here’s how you can use it step by step:-We are finding the-scaling law of agent+<Steps>+ <Step title="Initialize the Firecrawl client and start a crawl">+ First, create a Firecrawl client and crawl a specific URL.-🐫 CAMEL is an open-source library designed for the study of autonomous and-communicative agents. We believe that studying these agents on a large scale-offers valuable insights into their behaviors, capabilities, and potential-risks. To facilitate research in this field, we implement and support various-types of agents, tasks, prompts, models, and simulated environments.+ <CodeGroup>+ ```python firecrawl_crawl.py+ from camel.loaders import Firecrawl-**We are** always looking for more **contributors** and **collaborators**.-Contact us to join forces via [Slack](https://join.slack.com/t/camel-kwr1314/-shared_invite/zt-1vy8u9lbo-ZQmhIAyWSEfSwLCl2r2eKA)- or [Discord](https://discord.gg/CNcNpquyDc)...-```+ firecrawl = Firecrawl()+ response = firecrawl.crawl(url="https://www.camel-ai.org/about")+ print(response["status"]) # Should print "completed" when done+ ```+ ```markdown crawl_status.md+ >>>completed+ ```+ </CodeGroup>+ When the status is <code>"completed"</code>, the content extraction is done and you can retrieve the results.++ </Step>++ <Step title="Retrieve the extracted markdown content">+ Once finished, access the LLM-ready markdown directly from the response:++ <CodeGroup>+ ```python firecrawl_markdown.py+ print(response["data"][0]["markdown"])+ ```+ ```markdown extracted_markdown.md+ >>>Camel-AI Team++ We are finding the+ scaling law of agent++ 🐫 CAMEL is an open-source library designed for the study of autonomous and+ communicative agents. We believe that studying these agents on a large scale+ offers valuable insights into their behaviors, capabilities, and potential+ risks. To facilitate research in this field, we implement and support various+ types of agents, tasks, prompts, models, and simulated environments.++ **We are** always looking for more **contributors** and **collaborators**.+ Contact us to join forces via [Slack](https://join.slack.com/t/camel-kwr1314/+ shared_invite/zt-1vy8u9lbo-ZQmhIAyWSEfSwLCl2r2eKA)+ or [Discord](https://discord.gg/CNcNpquyDc)...+ ```+ </CodeGroup>-### 3.5. Using `Chunkr Reader`+ </Step>+</Steps>-Initialize the `ChunkrReader` and `ChunkrReaderConfig`. Set the local PDF file path and configuration, then submit the task. Use the generated task ID to fetch the output.-The `submit_task` and `get_task_output` methods are asynchronous, so you'll need to run them using an event loop (e.g., `asyncio.run()`).+<br />+That’s it. With just a couple of lines, you can turn any website into clean markdown, ready for LLM pipelines or further processing.+</Card>++---++<Card title="Using Chunkr Reader" icon="cuttlefish">+Chunkr Reader allows you to process PDFs (and other docs) in chunks, with built-in OCR and format control.+Below is a basic usage pattern:++Initialize the `ChunkrReader` and `ChunkrReaderConfig`, set the file path and chunking options, then submit your task and fetch results:```pythonimport asyncio@@ -250,11 +304,10 @@ async def main():config = ChunkrReaderConfig(chunk_processing=512, # Example: target chunk lengthocr_strategy="Auto", # Example: OCR strategy- high_resolution=False # Example: False for faster processing (maps to old "Fast" model)+ high_resolution=False # False for faster processing (old "Fast" model))- # Submit the task- # Replace "/path/to/your/document.pdf" with your actual file path.+ # Replace with your actual file path.file_path = "/path/to/your/document.pdf"try:task_id = await chunkr.submit_task(@@ -263,39 +316,40 @@ async def main():)print(f"Task ID: {task_id}")- # Fetch the output- # The get_task_output method handles polling until completion, failure, or cancellation.+ # Poll and fetch the output.if task_id:task_output_json_str = await chunkr.get_task_output(task_id=task_id)if task_output_json_str:print("Task Output:")- # The output is a JSON string, already pretty-printed by the SDK.- # You can parse it using json.loads() if you need to work with the dictionary object.print(task_output_json_str)else:- # This case occurs if the task failed or was cancelled after polling.print(f"Failed to get output for task {task_id}, or task did not succeed/was cancelled.")except ValueError as e:print(f"An error occurred during task submission or retrieval: {e}")except FileNotFoundError:print(f"Error: File not found at {file_path}. Please check the path.")except Exception as e:- # Catch any other unexpected errorsprint(f"An unexpected error occurred: {e}")if __name__ == "__main__":- # To actually run, uncomment the asyncio.run(main()) line below.print("To run this example, replace '/path/to/your/document.pdf' with a real file path, ensure CHUNKR_API_KEY is set, and uncomment 'asyncio.run(main())'.")# asyncio.run(main()) # Uncomment to run the example```++A successful task returns a chunked structure like this:+```markdown->>>Task ID: 7becf001-6f07-4f63-bddf-5633df363bbb->>>Task Output:->>>{ "task_id": "7becf001-6f07-4f63-bddf-5633df363bbb", "status": "Succeeded", "created_at": "2024-11-08T12:45:04.260765Z", "finished_at": "2024-11-08T12:45:48.942365Z", "expires_at": null, "message": "Task succeeded", "output": { "chunks": [ { "segments": [ { "segment_id": "d53ec931-3779-41be-a220-3fe4da2770c5", "bbox": { "left": 224.16666, "top": 370.0, "width": 2101.6665, "height": 64.166664 }, "page_number": 1, "page_width": 2550.0, "page_height": 3300.0, "content": "Large Language Model based Multi-Agents: A Survey of Progress and Challenges", "segment_type": "Title", "ocr": null, "image": "https://chunkmydocs-bucket-prod.storage.googleapis.com/.../d53ec931-3779-41be-a220-3fe4da2770c5.jpg?...", "html": "<h1>Large Language Model based Multi-Agents: A Survey of Progress and Challenges</h1>", "markdown": "# Large Language Model based Multi-Agents: A Survey of Progress and Challenges\n\n" } ], "chunk_length": 11 }, { "segments": [ { "segment_id": "7bb38fc7-c1b3-4153-a3cc-116c0b9caa0a", "bbox": { "left": 432.49997, "top": 474.16666, "width": 1659.9999, "height": 122.49999 }, "page_number": 1, "page_width": 2550.0, "page_height": 3300.0, "content": "Taicheng Guo 1 , Xiuying Chen 2 , Yaqi Wang 3 \u2217 , Ruidi Chang , Shichao Pei 4 , Nitesh V. Chawla 1 , Olaf Wiest 1 , Xiangliang Zhang 1 \u2020", "segment_type": "Text", "ocr": null, "image": "https://chunkmydocs-bucket-prod.storage.googleapis.com/.../7bb38fc7-c1b3-4153-a3cc-116c0b9caa0a.jpg?...", "html": "<p>Taicheng Guo 1 , Xiuying Chen 2 , Yaqi Wang 3 \u2217 , Ruidi Chang , Shichao Pei 4 , Nitesh V. Chawla 1 , Olaf Wiest 1 , Xiangliang Zhang 1 \u2020</p>", "markdown": "Taicheng Guo 1 , Xiuying Chen 2 , Yaqi Wang 3 \u2217 , Ruidi Chang , Shichao Pei 4 , Nitesh V. Chawla 1 , Olaf Wiest 1 , Xiangliang Zhang 1 \u2020\n\n" } ], "chunk_length": 100 # Example, actual length may vary } // ... other chunks and segments truncated for brevity ... ] }}```+> > > Task ID: 7becf001-6f07-4f63-bddf-5633df363bbb+> > > Task Output:+> > > { "task_id": "7becf001-6f07-4f63-bddf-5633df363bbb", "status": "Succeeded", "created_at": "2024-11-08T12:45:04.260765Z", "finished_at": "2024-11-08T12:45:48.942365Z", "expires_at": null, "message": "Task succeeded", "output": { "chunks": [ { "segments": [ { "segment_id": "d53ec931-3779-41be-a220-3fe4da2770c5", "bbox": { "left": 224.16666, "top": 370.0, "width": 2101.6665, "height": 64.166664 }, "page_number": 1, "page_width": 2550.0, "page_height": 3300.0, "content": "Large Language Model based Multi-Agents: A Survey of Progress and Challenges", "segment_type": "Title", "ocr": null, "image": "https://chunkmydocs-bucket-prod.storage.googleapis.com/.../d53ec931-3779-41be-a220-3fe4da2770c5.jpg?...", "html": "<h1>Large Language Model based Multi-Agents: A Survey of Progress and Challenges</h1>", "markdown": "# Large Language Model based Multi-Agents: A Survey of Progress and Challenges\n\n" } ], "chunk_length": 11 }, { "segments": [ { "segment_id": "7bb38fc7-c1b3-4153-a3cc-116c0b9caa0a", "bbox": { "left": 432.49997, "top": 474.16666, "width": 1659.9999, "height": 122.49999 }, "page_number": 1, "page_width": 2550.0, "page_height": 3300.0, "content": "Taicheng Guo 1 , Xiuying Chen 2 , Yaqi Wang 3 \u2217 , Ruidi Chang , Shichao Pei 4 , Nitesh V. Chawla 1 , Olaf Wiest 1 , Xiangliang Zhang 1 \u2020", "segment_type": "Text", "ocr": null, "image": "https://chunkmydocs-bucket-prod.storage.googleapis.com/.../7bb38fc7-c1b3-4153-a3cc-116c0b9caa0a.jpg?...", "html": "<p>Taicheng Guo 1 , Xiuying Chen 2 , Yaqi Wang 3 \u2217 , Ruidi Chang , Shichao Pei 4 , Nitesh V. Chawla 1 , Olaf Wiest 1 , Xiangliang Zhang 1 \u2020</p>", "markdown": "Taicheng Guo 1 , Xiuying Chen 2 , Yaqi Wang 3 \u2217 , Ruidi Chang , Shichao Pei 4 , Nitesh V. Chawla 1 , Olaf Wiest 1 , Xiangliang Zhang 1 \u2020\n\n" } ], "chunk_length": 100 } ] } }+```-### 3.6. Using `Jina Reader`+</Card>-Initialize the client and set the URL from which we want to retrieve information, then print the response.+---++<Card title="Using Jina Reader" icon="link">+Jina Reader provides a convenient interface to extract clean, LLM-friendly content from any URL in a chosen format (like markdown):```pythonfrom camel.loaders import JinaURLReader@@ -303,54 +357,40 @@ from camel.types.enums import JinaReturnFormatjina_reader = JinaURLReader(return_format=JinaReturnFormat.MARKDOWN)response = jina_reader.read_content("https://docs.camel-ai.org/")-print(response)```-### 3.6. Using `MarkitDown Reader`+</Card>++----Initialize the loader and pass in the path of the file to retrieve information, then print the response.+<Card title="Using MarkitDown Reader" icon="notebook">+MarkitDown Reader lets you convert files (like HTML or docs) into LLM-ready markdown with a single line.```pythonfrom camel.loaders import MarkItDownLoaderloader = MarkItDownLoader()-response = converter.convert_file("demo.html")+response = loader.convert_file("demo.html")print(response)```+Example output:+```markdown->>>Welcome to CAMEL’s documentation! — CAMEL 0.2.61 documentation+> > > Welcome to CAMEL’s documentation! — CAMEL 0.2.61 documentation[Skip to main content](https://docs.camel-ai.org/#main-content)--Back to top Ctrl+K-- [ CAMEL 0.2.61](https://docs.camel-ai.org/#)--Search Ctrl+K--Get Started--* [Installation](https://docs.camel-ai.org/get_started/installation.html)-* [API Setup](https://docs.camel-ai.org/get_started/setup.html)--Agents--* [Creating Your First Agent](https://docs.camel-ai.org/cookbooks/create_your_first_agent.html)-* [Creating Your First Agent Society](https://docs.camel-ai.org/cookbooks/create_your_first_agents_society.html)-* [Embodied Agents](https://docs.camel-ai.org/cookbooks/embodied_agents.html)-* [Critic Agents and Tree Search](https://docs.camel-ai.org/cookbooks/critic_agents_and_tree_search.html)--Key Modules--* [Models](https://docs.camel-ai...)+...```-### 3.7. Using `Mistral Reader`+</Card>++----Initialize the Mistral Reader client with your API key (or it will use the MISTRAL_API_KEY environment variable) and extract text from a PDF URL:+<Card title="Using Mistral Reader" icon="book-open-reader">+Mistral Reader offers OCR and text extraction from both PDFs and images, whether local or remote. Just specify the file path or URL:```pythonfrom camel.loaders import MistralReader@@ -364,7 +404,7 @@ url_ocr_response = mistral_reader.extract_text(print(url_ocr_response)```-Extract text from an image URL by setting `is_image=True`:+You can also extract from images or local files:```python# Extract text from an image URL@@ -375,18 +415,17 @@ image_ocr_response = mistral_reader.extract_text(print(image_ocr_response)```-Process a local PDF file:-```python# Extract text from a local PDF filelocal_ocr_response = mistral_reader.extract_text("path/to/your/document.pdf")print(local_ocr_response)```-The response contains structured information about the extracted text, including the markdown-formatted content, page dimensions, and usage information:+Response includes structured page data, markdown content, and usage details.```markdown->>>pages=[OCRPageObject(index=5, markdown='\n\nFigure 2: Scatter plot of predicted accuracy versus (true) OOD accuracy. Each point denotes a dif...',--images=[OCRImageObject(id='img-0.jpeg', top_left_x=294, top_left_y=180, bottom_right_x=1387, bottom_right_y=558, image_base64=None, image_annotation=None)], dimensions=OCRPageDimensions(dpi=200, height=2200, width=1700))] model='mistral-ocr-2505-completion' usage_info=OCRUsageInfo(pages_processed=1, doc_size_bytes=3002783) document_annotation=None+> > > pages=[OCRPageObject(index=5, markdown='\n\nFigure 2: Scatter plot of predicted accuracy versus (true) OOD accuracy. Each point denotes a dif...',+> > > images=[OCRImageObject(id='img-0.jpeg', ...)], dimensions=OCRPageDimensions(...))] model='mistral-ocr-2505-completion' usage_info=...```++</Card>diff --git a/docs/key_modules/memory.md b/docs/key_modules/memory.mdindex 83289d13a..fd06347a0 100644--- a/docs/key_modules/memory.md+++ b/docs/key_modules/memory.md@@ -1,377 +1,431 @@-For more detailed usage information, please refer to our cookbook: [Memory Cookbook](../cookbooks/advanced_features/agents_with_memory.ipynb)--## 1. Concept-The Memory module in CAMEL provides a flexible and powerful system for storing, retrieving, and managing information for AI agents. It enables agents to maintain context across conversations and retrieve relevant information from past interactions, enhancing the coherence and relevance of AI responses.--## 2. Get Started--### 2.1 Basic Usage--Here's a quick example of how to use the `LongtermAgentMemory`:--```python-from camel.memories import (- ChatHistoryBlock,- LongtermAgentMemory,- MemoryRecord,- ScoreBasedContextCreator,- VectorDBBlock,+---+title: "Loaders"+icon: loader+---++<Card title="What are Loaders?" icon="loader">+ CAMEL’s Loaders provide flexible ways to ingest and process all kinds of data+ structured files, unstructured text, web content, and even OCR from images.+ They power your agent’s ability to interact with the outside world. itionally,+ several data readers were added, including `Apify Reader`, `Chunkr Reader`,+ `Firecrawl Reader`, `Jina_url Reader`, and `Mistral Reader`, which enable+ retrieval of external data for improved data integration and analysis.+</Card>+## Types++<AccordionGroup>++{" "}+<Accordion title="Base IO" icon="file">+ Handles core file input/output for formats like PDF, DOCX, HTML, and more.<br></br>+ Lets you represent, read, and process structured files.+</Accordion>++{" "}+<Accordion title="Unstructured IO" icon="puzzle">+ Powerful ETL for parsing, cleaning, extracting, chunking, and staging+ unstructured data.<br></br>+ Perfect for RAG pipelines and pre-processing.+</Accordion>++{" "}+<Accordion title="Apify Reader" icon="robot">+ Integrates with Apify to automate web workflows and scraping.<br></br>+ Supports authentication, actor management, and dataset operations via API.+</Accordion>++{" "}+<Accordion title="Chunkr Reader" icon="scissors">+ Connects to the Chunkr API for document chunking, segmentation, and OCR.<br></br>+ Handles everything from simple docs to scanned PDFs.+</Accordion>++{" "}+<Accordion title="Firecrawl Reader" icon="fire">+ Converts entire websites into LLM-ready markdown using the Firecrawl API.<br></br>+ Useful for quickly ingesting web content as clean text.+</Accordion>++{" "}+<Accordion title="JinaURL Reader" icon="globe">+ Uses Jina AI’s URL reading service to cleanly extract web content.<br></br>+ Designed for LLM-friendly extraction from any URL.+</Accordion>++{" "}+<Accordion title="MarkitDown Reader" icon="note">+ Lightweight tool to convert files (HTML, DOCX, PDF, etc.) into Markdown.<br></br>+ Ideal for prepping documents for LLM ingestion or analysis.+</Accordion>++{" "}+<Accordion title="Mistral Reader" icon="book-open-reader">+ Integrates Mistral AI’s OCR service for extracting text from images and PDFs.+ <br></br>+ Supports both local and remote file processing for various formats.+</Accordion>++</AccordionGroup>++## Get Started++<Card title="Using Base IO" icon="file">+This module is designed to read files of various formats, extract their contents, and represent them as `File` objects, each tailored to handle a specific file type.++<CodeGroup>+```python base_io_example.py+from io import BytesIO+from camel.loaders import create_file_from_raw_bytes++# Read a pdf file from disk++with open("test.pdf", "rb") as file:+file_content = file.read()++# Use the create_file function to create an object based on the file extension++file_obj = create_file_from_raw_bytes(file_content, "test.pdf")++# Once you have the File object, you can access its content++print(file_obj.docs[0]["page_content"])++````+</CodeGroup>+</Card>++---++<Card title="Using Unstructured IO" icon="puzzle">+To get started with the <code>Unstructured IO</code> module, just import and initialize it. You can parse, clean, extract, chunk, and stage data from files or URLs. Here’s how you use it step by step:++<br />++<strong>1. Parse unstructured data from a file or URL:</strong>+<CodeGroup>+```python unstructured_io_parse.py+from camel.loaders import UnstructuredIO++uio = UnstructuredIO()+example_url = (+ "https://www.cnn.com/2023/01/30/sport/empire-state-building-green-"+ "philadelphia-eagles-spt-intl/index.html")-from camel.messages import BaseMessage-from camel.types import ModelType, OpenAIBackendRole-from camel.utils import OpenAITokenCounter--# Initialize the memory-memory = LongtermAgentMemory(- context_creator=ScoreBasedContextCreator(- token_counter=OpenAITokenCounter(ModelType.GPT_4O_MINI),- token_limit=1024,- ),- chat_history_block=ChatHistoryBlock(),- vector_db_block=VectorDBBlock(),-)--# Create and write new records-records = [- MemoryRecord(- message=BaseMessage.make_user_message(- role_name="User",- meta_dict=None,- content="What is CAMEL AI?",- ),- role_at_backend=OpenAIBackendRole.USER,- ),- MemoryRecord(- message=BaseMessage.make_assistant_message(- role_name="Agent",- meta_dict=None,- content="CAMEL-AI.org is the 1st LLM multi-agent framework and "- "an open-source community dedicated to finding the scaling law "- "of agents.",- ),- role_at_backend=OpenAIBackendRole.ASSISTANT,- ),-]-memory.write_records(records)--# Get context for the agent-context, token_count = memory.get_context()--print(context)-print(f"Retrieved context (token count: {token_count}):")-for message in context:- print(f"{message}")+elements = uio.parse_file_or_url(example_url)+print(("\n\n".join([str(el) for el in elements])))+````++```markdown parsed_elements.md+> > > The Empire State Building was lit in green and white to celebrate the Philadelphia Eagles’ victory in the NFC Championship game on Sunday – a decision that’s sparked a bit of a backlash in the Big Apple.+> > > The Eagles advanced to the Super Bowl for the first time since 2018 after defeating the San Francisco 49ers 31-7, and the Empire State Building later tweeted how it was marking the occasion.+> > > Fly @Eagles Fly! We’re going Green and White in honor of the Eagles NFC Championship Victory. pic.twitter.com/RNiwbCIkt7— Empire State Building (@EmpireStateBldg)+> > > January 29, 2023...```-```markdown->>> Retrieved context (token count: 49):-{'role': 'user', 'content': 'What is AI?'}-{'role': 'assistant', 'content': 'AI refers to systems that mimic human intelligence.'}-```--Adding `LongtermAgentMemory` to your `ChatAgent`:--```python-from camel.agents import ChatAgent+</CodeGroup>-# Define system message for the agent-sys_msg = BaseMessage.make_assistant_message(- role_name='Agent',- content='You are a curious agent wondering about the universe.',-)+<br />-# Initialize agent-agent = ChatAgent(system_message=sys_msg)+<strong>2. Clean unstructured text data:</strong>+<CodeGroup>+ ```python unstructured_io_clean.py example_dirty_text = ("\x93Some dirty text+ ’ with extra spaces and – dashes.") options = [ ('replace_unicode_quotes',{" "}+ {}), ('clean_dashes', {}), ('clean_non_ascii_chars', {}),+ ('clean_extra_whitespace', {}), ] cleaned_text =+ uio.clean_text_data(text=example_dirty_text, clean_options=options)+ print(cleaned_text) ``` ```markdown cleaned_text.md >>> Some dirty text with+ extra spaces and dashes. ```+</CodeGroup>-# Set memory to the agent-agent.memory = memory+<br />+<strong>3. Extract data from text (for example, emails):</strong>+<CodeGroup>+```python unstructured_io_extract.py+example_email_text = "Contact me at [email protected]."-# Define a user message-usr_msg = BaseMessage.make_user_message(- role_name='User',- content="Tell me which is the 1st LLM multi-agent framework based on what we have discussed",+extracted_text = uio.extract_data_from_text(+text=example_email_text,+extract_type="extract_email_address")+print(extracted_text)-# Sending the message to the agent-response = agent.step(usr_msg)+````+```markdown extracted_email.md+>>> ['[email protected]']+````-# Check the response (just for illustrative purpose)-print(response.msgs[0].content)-```+</CodeGroup>-```markdown->>> CAMEL AI is recognized as the first LLM (Large Language Model) multi-agent framework. It is an open-source community initiative focused on exploring the scaling laws of agents, enabling the development and interaction of multiple AI agents in a collaborative environment. This framework allows researchers and developers to experiment with various configurations and interactions among agents, facilitating advancements in AI capabilities and understanding.+<br />-```--## 3. Core Components--### 3.1 MemoryRecord--The basic data unit in the `CAMEL` memory system.--Attributes:--- `message`: The main content of the record (`BaseMessage`)-- `role_at_backend`: The role this message played at the OpenAI backend (`OpenAIBackendRole`)-- `uuid`: A unique identifier for the record-- `extra_info`: Additional key-value pairs for extra information--Methods:--- `from_dict()`: Static method to construct a `MemoryRecord` from a dictionary-- `to_dict()`: Convert the `MemoryRecord` to a dictionary for serialization-- `to_openai_message()`: Convert the record to an `OpenAIMessage` object+<strong>4. Chunk content by title:</strong>+<CodeGroup>+```python unstructured_io_chunk.py+chunks = uio.chunk_elements(elements=elements, chunk_type="chunk_by_title")-### 3.2 ContextRecord+for chunk in chunks:+print(chunk)+print("\n" + "-" \* 80)-The result of memory retrieval from `AgentMemory`, which is used by `ContextCreator` to select records for creating the context for the agent.+````+```markdown chunked_content.md+>>> The Empire State Building was lit in green and white to celebrate the Philadelphia Eagles’ victory in the NFC Championship game on Sunday – a decision that’s sparked a bit of a backlash in the Big Apple.+>>> --------------------------------------------------------------------------------+>>> Fly @Eagles Fly! We’re going Green and White in honor of the Eagles NFC Championship Victory. pic.twitter.com/RNiwbCIkt7— Empire State Building (@EmpireStateBldg)+>>> --------------------------------------------------------------------------------+>>> January 29, 2023+````-Attributes:+</CodeGroup>-- `memory_record`: A `MemoryRecord`-- `score`: A float value representing the relevance or importance of the record+<br />-### 3.3 MemoryBlock (Abstract Base Class)--Serves as the fundamental component within the agent memory system. `MemoryBlock` class follows the "Composite Design pattern" so that you can compose objects into tree structures and then work with these structures as if they were individual objects.+<strong>5. Stage elements for use with other platforms:</strong>+<CodeGroup>+```python unstructured_io_stage.py+staged_element = uio.stage_elements(elements=elements, stage_type="stage_for_baseplate")+print(staged_element)+```+```markdown staged_elements.md+>>> {'rows': [{'data': {'type': 'UncategorizedText', 'element_id': 'e78902d05b0cb1e4c38fc7a79db450d5', 'text': 'CNN\n \xa0—'}, 'metadata': {'filetype': 'text/html', 'languages': ['eng'], 'page_number': 1, 'url': 'https://www.cnn.com/2023/01/30/sport/empire-state-building-green-philadelphia-eagles-spt-intl/index.html', 'emphasized_text_contents': ['CNN'], 'emphasized_text_tags': ['span']}}, ...+```+</CodeGroup>-- `write_records()`: Write multiple records to memory-- `write_record()`: Write a single record to memory-- `clear()`: Remove all records from memory+<br />+This guide gets you started with <code>Unstructured IO</code>. For more, see the <a href="https://docs.unstructured.io" target="_blank">Unstructured IO Documentation</a>.+</Card>-### 3.4 BaseContextCreator (Abstract Base Class)+----Defines the context creation strategies when retrieval messages exceed the model's context length.+<Card title="Using Apify Reader" icon="robot">+Initialize the Apify client, set up the required actors and parameters, and run the actor.-- `token_counter`: For counting tokens in a message-- `token_limit`: The maximum number of tokens allowed in the generated context-- `create_context()`: Create conversational context from chat history+<CodeGroup>+```python apify_reader.py+from camel.loaders import Apify-### 3.5 AgentMemory (Abstract Base Class)+apify = Apify()-A specialized form of MemoryBlock designed for direct integration with an agent.+run_input = {+"startUrls": [{"url": "https://www.camel-ai.org/"}],+"maxCrawlDepth": 0,+"maxCrawlPages": 1,+}+actor_result = apify.run_actor(+actor_id="apify/website-content-crawler", run_input=run_input+)+dataset_result = apify.get_dataset_items(+dataset_id=actor_result["defaultDatasetId"]+)+print(dataset_result)-- `retrieve()`: Get a list of `ContextRecords` from memory-- `get_context_creator()`: Get a context creator-- `get_context()`: Get chat context with a proper size for the agent+````+```markdown apify_output.md+>>>[{'url': 'https://www.camel-ai.org/', 'crawl': {'loadedUrl': 'https://www.camel-ai.org/', ...}, 'metadata': {'canonicalUrl': 'https://www.camel-ai.org/', ...}, ... }]+````-## 4. Memory Block Implementations+</CodeGroup>+</Card>-### 4.1 ChatHistoryBlock+----Stores all the chat histories and retrieves with optional window size.+<Card title="Using Firecrawl Reader" icon="fire">+Firecrawl Reader provides a simple way to turn any website into LLM-ready markdown format. Here’s how you can use it step by step:-Initialization:+<Steps>+ <Step title="Initialize the Firecrawl client and start a crawl">+ First, create a Firecrawl client and crawl a specific URL.-- `storage`: Optional `BaseKeyValueStorage` (default: `InMemoryKeyValueStorage`)-- `keep_rate`: Float value for scoring historical messages (default: `0.9`)+ <CodeGroup>+ ```python firecrawl_crawl.py+ from camel.loaders import Firecrawl-Methods:+ firecrawl = Firecrawl()+ response = firecrawl.crawl(url="https://www.camel-ai.org/about")+ print(response["status"]) # Should print "completed" when done+ ```+ ```markdown crawl_status.md+ >>>completed+ ```+ </CodeGroup>+ When the status is <code>"completed"</code>, the content extraction is done and you can retrieve the results.-- `retrieve()`: Get recent chat history with optional window size-- `write_records()`: Write new records to chat history-- `clear()`: Remove all chat messages+ </Step>-Use Case: Ideal for maintaining recent conversation context and flow.+ <Step title="Retrieve the extracted markdown content">+ Once finished, access the LLM-ready markdown directly from the response:-### 4.2 VectorDBBlock+ <CodeGroup>+ ```python firecrawl_markdown.py+ print(response["data"][0]["markdown"])+ ```+ ```markdown extracted_markdown.md+ >>>Camel-AI Team-Uses vector embeddings for maintaining and retrieving information.+ We are finding the+ scaling law of agent-Initialization:+ 🐫 CAMEL is an open-source library designed for the study of autonomous and+ communicative agents. We believe that studying these agents on a large scale+ offers valuable insights into their behaviors, capabilities, and potential+ risks. To facilitate research in this field, we implement and support various+ types of agents, tasks, prompts, models, and simulated environments.-- `storage`: Optional BaseVectorStorage (default: `QdrantStorage`)-- `embedding`: Optional BaseEmbedding (default: `OpenAIEmbedding`)+ **We are** always looking for more **contributors** and **collaborators**.+ Contact us to join forces via [Slack](https://join.slack.com/t/camel-kwr1314/+ shared_invite/zt-1vy8u9lbo-ZQmhIAyWSEfSwLCl2r2eKA)+ or [Discord](https://discord.gg/CNcNpquyDc)...+ ```+ </CodeGroup>-Methods:+ </Step>+</Steps>-- `retrieve()`: Get similar records based on a keyword-- `write_records()`: Convert and write new records to the vector database-- `clear()`: Remove all records from the vector database+<br />+That’s it. With just a couple of lines, you can turn any website into clean markdown, ready for LLM pipelines or further processing.+</Card>-Use Case: Better for retrieving semantically relevant information across a large set of messages.+----Key Differences:+<Card title="Using Chunkr Reader" icon="cuttlefish">+Chunkr Reader allows you to process PDFs (and other docs) in chunks, with built-in OCR and format control.+Below is a basic usage pattern:-1. Storage Mechanism: `ChatHistoryBlock` uses key-value storage, `VectorDBBlock` uses vector database storage.-2. Retrieval Method: `ChatHistoryBlock` retrieves based on recency, `VectorDBBlock` retrieves based on semantic similarity.-3. Data Representation: `ChatHistoryBlock` stores messages in original form, `VectorDBBlock` converts to vector embeddings.+Initialize the `ChunkrReader` and `ChunkrReaderConfig`, set the file path and chunking options, then submit your task and fetch results:-## 5. Agent Memory Implementations+```python+import asyncio+from camel.loaders import ChunkrReader, ChunkrReaderConfig++async def main():+ chunkr = ChunkrReader()++ config = ChunkrReaderConfig(+ chunk_processing=512, # Example: target chunk length+ ocr_strategy="Auto", # Example: OCR strategy+ high_resolution=False # False for faster processing (old "Fast" model)+ )++ # Replace with your actual file path.+ file_path = "/path/to/your/document.pdf"+ try:+ task_id = await chunkr.submit_task(+ file_path=file_path,+ chunkr_config=config,+ )+ print(f"Task ID: {task_id}")++ # Poll and fetch the output.+ if task_id:+ task_output_json_str = await chunkr.get_task_output(task_id=task_id)+ if task_output_json_str:+ print("Task Output:")+ print(task_output_json_str)+ else:+ print(f"Failed to get output for task {task_id}, or task did not succeed/was cancelled.")+ except ValueError as e:+ print(f"An error occurred during task submission or retrieval: {e}")+ except FileNotFoundError:+ print(f"Error: File not found at {file_path}. Please check the path.")+ except Exception as e:+ print(f"An unexpected error occurred: {e}")++if __name__ == "__main__":+ print("To run this example, replace '/path/to/your/document.pdf' with a real file path, ensure CHUNKR_API_KEY is set, and uncomment 'asyncio.run(main())'.")+ # asyncio.run(main()) # Uncomment to run the example+```-### 5.1 ChatHistoryMemory+A successful task returns a chunked structure like this:-An AgentMemory implementation that wraps ChatHistoryBlock.+```markdown+> > > Task ID: 7becf001-6f07-4f63-bddf-5633df363bbb+> > > Task Output:+> > > { "task_id": "7becf001-6f07-4f63-bddf-5633df363bbb", "status": "Succeeded", "created_at": "2024-11-08T12:45:04.260765Z", "finished_at": "2024-11-08T12:45:48.942365Z", "expires_at": null, "message": "Task succeeded", "output": { "chunks": [ { "segments": [ { "segment_id": "d53ec931-3779-41be-a220-3fe4da2770c5", "bbox": { "left": 224.16666, "top": 370.0, "width": 2101.6665, "height": 64.166664 }, "page_number": 1, "page_width": 2550.0, "page_height": 3300.0, "content": "Large Language Model based Multi-Agents: A Survey of Progress and Challenges", "segment_type": "Title", "ocr": null, "image": "https://chunkmydocs-bucket-prod.storage.googleapis.com/.../d53ec931-3779-41be-a220-3fe4da2770c5.jpg?...", "html": "<h1>Large Language Model based Multi-Agents: A Survey of Progress and Challenges</h1>", "markdown": "# Large Language Model based Multi-Agents: A Survey of Progress and Challenges\n\n" } ], "chunk_length": 11 }, { "segments": [ { "segment_id": "7bb38fc7-c1b3-4153-a3cc-116c0b9caa0a", "bbox": { "left": 432.49997, "top": 474.16666, "width": 1659.9999, "height": 122.49999 }, "page_number": 1, "page_width": 2550.0, "page_height": 3300.0, "content": "Taicheng Guo 1 , Xiuying Chen 2 , Yaqi Wang 3 \u2217 , Ruidi Chang , Shichao Pei 4 , Nitesh V. Chawla 1 , Olaf Wiest 1 , Xiangliang Zhang 1 \u2020", "segment_type": "Text", "ocr": null, "image": "https://chunkmydocs-bucket-prod.storage.googleapis.com/.../7bb38fc7-c1b3-4153-a3cc-116c0b9caa0a.jpg?...", "html": "<p>Taicheng Guo 1 , Xiuying Chen 2 , Yaqi Wang 3 \u2217 , Ruidi Chang , Shichao Pei 4 , Nitesh V. Chawla 1 , Olaf Wiest 1 , Xiangliang Zhang 1 \u2020</p>", "markdown": "Taicheng Guo 1 , Xiuying Chen 2 , Yaqi Wang 3 \u2217 , Ruidi Chang , Shichao Pei 4 , Nitesh V. Chawla 1 , Olaf Wiest 1 , Xiangliang Zhang 1 \u2020\n\n" } ], "chunk_length": 100 } ] } }+```-Initialization:+</Card>-- `context_creator`: `BaseContextCreator`-- `storage`: Optional `BaseKeyValueStorage`-- `window_size`: Optional int for retrieval window+----Methods:+<Card title="Using Jina Reader" icon="link">+Jina Reader provides a convenient interface to extract clean, LLM-friendly content from any URL in a chosen format (like markdown):-- `retrieve()`: Get recent chat messages-- `write_records()`: Write new records to chat history-- `get_context_creator()`: Get the context creator-- `clear()`: Remove all chat messages+```python+from camel.loaders import JinaURLReader+from camel.types.enums import JinaReturnFormat-### 5.2 VectorDBMemory+jina_reader = JinaURLReader(return_format=JinaReturnFormat.MARKDOWN)+response = jina_reader.read_content("https://docs.camel-ai.org/")+print(response)+```-An `AgentMemory` implementation that wraps `VectorDBBlock`.+</Card>-Initialization:+----- `context_creator`: `BaseContextCreator`-- `storage`: Optional `BaseVectorStorage`-- `retrieve_limit`: int for maximum number of retrieved messages (default:`3`)+<Card title="Using MarkitDown Reader" icon="notebook">+MarkitDown Reader lets you convert files (like HTML or docs) into LLM-ready markdown with a single line.-Methods:+```python+from camel.loaders import MarkItDownLoader-- `retrieve()`: Get relevant messages from the vector database-- `write_records()`: Write new records and update current topic-- `get_context_creator()`: Get the context creator+loader = MarkItDownLoader()+response = loader.convert_file("demo.html")-### 5.3 LongtermAgentMemory+print(response)+```-Combines ChatHistoryMemory and VectorDBMemory for comprehensive memory management.+Example output:-Initialization:+```markdown+> > > Welcome to CAMEL’s documentation! — CAMEL 0.2.61 documentation-- `context_creator`: `BaseContextCreator`-- `chat_history_block`: Optional `ChatHistoryBlock`-- `vector_db_block`: Optional `VectorDBBlock`-- `retrieve_limit`: int for maximum number of retrieved messages (default: `3`)+[Skip to main content](https://docs.camel-ai.org/#main-content)+...+```-Methods:+</Card>-- `retrieve()`: Get context from both chat history and vector database-- `write_records()`: Write new records to both chat history and vector database-- `get_context_creator()`: Get the context creator-- `clear()`: Remove all records from both memory blocks+----### 5.4 Mem0Storage Integration+<Card title="Using Mistral Reader" icon="book-open-reader">+Mistral Reader offers OCR and text extraction from both PDFs and images, whether local or remote. Just specify the file path or URL:-[Mem0](https://mem0.ai/) offers cloud-based memory management capabilities that can be seamlessly integrated with CAMEL.+```python+from camel.loaders import MistralReader-Initialization params of `Mem0Storage`:+mistral_reader = MistralReader()-- `api_key`: Optional str for Mem0 API authentication-- `agent_id`: Optional str to associate memories with an agent-- `user_id`: Optional str to associate memories with a user-- `metadata`: Optional dictionary of metadata to include with all memories+# Extract text from a PDF URL+url_ocr_response = mistral_reader.extract_text(+ file_path="https://arxiv.org/pdf/2201.04234", pages=[5]+)+print(url_ocr_response)+```-The simplest way to use Mem0 is through its `Mem0Storage` backend with `ChatHistoryMemory`:+You can also extract from images or local files:```python-from camel.memories import ChatHistoryMemory, ScoreBasedContextCreator-from camel.storages import Mem0Storage-from camel.types import ModelType-from camel.utils import OpenAITokenCounter--# Initialize ChatHistoryMemory with Mem0Storage-memory = ChatHistoryMemory(- context_creator=ScoreBasedContextCreator(- token_counter=OpenAITokenCounter(ModelType.GPT_4O_MINI),- token_limit=1024,- ),- storage=Mem0Storage(- api_key="your_mem0_api_key", # Or set MEM0_API_KEY environment variable- agent_id="agent123" # Unique identifier for this agent- ),- agent_id="agent123" # Should match the storage agent_id+# Extract text from an image URL+image_ocr_response = mistral_reader.extract_text(+ file_path="https://raw.githubusercontent.com/mistralai/cookbook/refs/heads/main/mistral/ocr/receipt.png",+ is_image=True,)--# Create and write new records-records = [- MemoryRecord(- message=BaseMessage.make_user_message(- role_name="User",- content="What is CAMEL AI?",- ),- role_at_backend=OpenAIBackendRole.USER,- ),- MemoryRecord(- message=BaseMessage.make_assistant_message(- role_name="Agent",- content="CAMEL-AI.org is the 1st LLM multi-agent framework and "- "an open-source community dedicated to finding the scaling law "- "of agents.",- ),- role_at_backend=OpenAIBackendRole.ASSISTANT,- ),-]-memory.write_records(records)---# Get context for the agent-context, token_count = memory.get_context()--print(context)-print(f"Retrieved context (token count: {token_count}):")-for message in context:- print(f"{message}")+print(image_ocr_response)```-```markdown->>> Retrieved context (token count: 49):-{'role': 'user', 'content': 'What is CAMEL AI?'}-{'role': 'assistant', 'content': 'CAMEL-AI.org is the 1st LLM multi-agent framework and an open-source community dedicated to finding the scaling law of agents.'}-```--This approach provides cloud persistence for chat history while maintaining the simple sequential retrieval of `ChatHistoryMemory`. The key features include:--1. Cloud persistence of chat history-2. Simple setup and configuration-3. Sequential retrieval based on conversation order-4. Automatic synchronization across sessions--Choose this approach when you need reliable cloud storage for your chat history without complex semantic search requirements.--## 6. Advanced Topics--### 6.1 Customizing Context Creator--You can create custom context creators by subclassing `BaseContextCreator`:-```python-from camel.memories import BaseContextCreator--class MyCustomContextCreator(BaseContextCreator):- @property- def token_counter(self):- # Implement your token counting logic- return-- @property- def token_limit(self):- return 1000 # Or any other limit-- def create_context(self, records):- # Implement your context creation logic- pass-+# Extract text from a local PDF file+local_ocr_response = mistral_reader.extract_text("path/to/your/document.pdf")+print(local_ocr_response)```-### 6.2 Customizing Vector Database Block--For `VectorDBBlock`, you can customize it by adjusting the embedding models or vector storages:--```python-from camel.embeddings import OpenAIEmbedding-from camel.memories import VectorDBBlock-from camel.storages import QdrantStorage+Response includes structured page data, markdown content, and usage details.-vector_db = VectorDBBlock(- embedding=OpenAIEmbedding(),- storage=QdrantStorage(vector_dim=OpenAIEmbedding().get_output_dim()),-)+```markdown+> > > pages=[OCRPageObject(index=5, markdown='\n\nFigure 2: Scatter plot of predicted accuracy versus (true) OOD accuracy. Each point denotes a dif...',+> > > images=[OCRImageObject(id='img-0.jpeg', ...)], dimensions=OCRPageDimensions(...))] model='mistral-ocr-2505-completion' usage_info=...```-### 6.3 Performance Considerations--- For large-scale applications, consider using persistent storage backends instead of in-memory storage.-- Optimize your context creator to balance between context relevance and token limits.-- When using `VectorDBMemory`, be mindful of the trade-off between retrieval accuracy and speed as the database grows.\ No newline at end of file+</Card>diff --git a/docs/key_modules/messages.md b/docs/key_modules/messages.mdindex 65c4aea76..4adff636f 100644--- a/docs/key_modules/messages.md+++ b/docs/key_modules/messages.md@@ -1,156 +1,152 @@-## 1. Concept--The `BaseMessage` class is the base class for message objects used in the CAMEL chat system. It is designed to provide a consistent structure for the messages in the system and allow for easy conversion between different message types.--All the codes are also available on colab notebook [here](https://colab.research.google.com/drive/1qyi4bnAbnYink-FKaAlJG9OipyEWXEsT?usp=sharing).--## 2. Get Started--### 2.1 Creating a `BaseMessage` Instance--To create a `BaseMessage` instance, you need to provide the following arguments:--- `role_name`: The name of the user or assistant role.-- `role_type`: The type of role, either `RoleType.ASSISTANT` or `RoleType.USER`.-- `meta_dict`: An optional metadata dictionary for the message.-- `content`: The content of the message.--Below are optional arguments you can pass:--- `video_bytes`: Optional bytes of a video associated with the message.-- `image_list`: Optional list of PIL Image objects associated with the message.-- `image_detail`: Detail level of the images associated with the message. Default is "auto".-- `video_detail`: Detail level of the videos associated with the message. Default is "low".--Here's an example of creating a `BaseMessage` instance:--```python-from camel.messages import BaseMessage-from camel.types import RoleType+---+title: "Messages"+icon: messages+---++<Card title="What is BaseMessage?" icon="message">+ The <code>BaseMessage</code> class is the backbone for all message objects in+ the CAMEL chat system. It offers a consistent structure for agent+ communication and easy conversion between message types.+</Card>++Explore and run every code sample directly in this <a href="https://colab.research.google.com/drive/1qyi4bnAbnYink-FKaAlJG9OipyEWXEsT?usp=sharing" target="_blank"><b>Colab notebook</b></a>.++---++## Get Started++<Card title="Creating a `BaseMessage`" icon="terminal">+ To create a <code>BaseMessage</code> instance, supply these arguments:+ <ul>+ <li><b>role_name</b>: Name of the user or assistant</li>+ <li><b>role_type</b>: <code>RoleType.ASSISTANT</code> or <code>RoleType.USER</code></li>+ <li><b>content</b>: The actual message text</li>+ <li><b>meta_dict</b> (optional): Additional metadata</li>+ <li><b>video_bytes</b> (optional): Attach video bytes</li>+ <li><b>image_list</b> (optional): List of PIL Image objects</li>+ <li><b>image_detail</b> (optional): Level of image detail (default: "auto")</li>+ <li><b>video_detail</b> (optional): Level of video detail (default: "low")</li>+ </ul>+ <b>Example:</b>+ ```python+ from camel.messages import BaseMessage+ from camel.types import RoleTypemessage = BaseMessage(- role_name="test_user",- role_type=RoleType.USER,- content="test content"+role_name="test_user",+role_type=RoleType.USER,+content="test content")-```--Additionally, the BaseMessage class provides class methods to easily create user and assistant agent messages:--1. Creating a user agent message:-- ```python- from camel.messages import BaseMessage-- user_message = BaseMessage.make_user_message(- role_name="user_name",- content="test content for user",- )- ```--2. Creating an assistant agent message:-- ```python- from camel.messages import BaseMessage-- assistant_message = BaseMessage.make_assistant_message(- role_name="assistant_name",- content="test content for assistant",- )- ```--### 2.2 Using the Methods of the `BaseMessage` Class--The `BaseMessage` class offers several methods:--1. Creating a new instance with updated content:- ```python- new_message = message.create_new_instance("new test content")- print(isinstance(new_message, BaseMessage))- >>> True- ```--2. Converting to an `OpenAIMessage` object:-- ```python- openai_message = message.to_openai_message(role_at_backend=OpenAIBackendRole.USER)- print(openai_message == {"role": "user", "content": "test content"})- >>> True- ```--3. Converting to an `OpenAISystemMessage` object:-- ```python- openai_system_message = message.to_openai_system_message()- print(openai_system_message == {"role": "system", "content": "test content"})- >>> True- ```--4. Converting to an `OpenAIUserMessage` object:-- ```python- openai_user_message = message.to_openai_user_message()- print(openai_user_message == {"role": "user", "content": "test content"})- >>> True- ```--5. Converting to an `OpenAIAssistantMessage` object:-- ```python- openai_assistant_message = message.to_openai_assistant_message()- print(openai_assistant_message == {"role": "assistant", "content": "test content"})- >>> True- ```--6. Converting to a dictionary:-- ```python- message_dict = message.to_dict()- print(message_dict == {- "role_name": "test_user",- "role_type": "USER",- "content": "test content"- })- >>> True- ```+````+</Card>+<Card title="Convenient Constructors" icon="user">+Easily create messages for user or assistant agents:+```python+user_message = BaseMessage.make_user_message(+ role_name="user_name",+ content="test content for user",+)-These methods allow you to convert a `BaseMessage` instance into different message types depending on your needs.+assistant_message = BaseMessage.make_assistant_message(+ role_name="assistant_name",+ content="test content for assistant",+)+````++</Card>++---++## Methods in the `BaseMessage` Class++<Card title="Flexible Message Manipulation" icon="shuffle">+ The <code>BaseMessage</code> class lets you:+ <ul>+ <li>+ Create a new instance with updated content:+ <br />+ <code>new_message = message.create_new_instance("new test content")</code>+ </li>+ <li>+ Convert to OpenAI message formats:+ <br />+ <code>+ openai_message =+ message.to_openai_message(role_at_backend=OpenAIBackendRole.USER)+ </code>+ <br />+ <code>openai_system_message = message.to_openai_system_message()</code>+ <br />+ <code>openai_user_message = message.to_openai_user_message()</code>+ <br />+ <code>+ openai_assistant_message = message.to_openai_assistant_message()+ </code>+ </li>+ <li>+ Convert to a Python dictionary:+ <br />+ <code>message_dict = message.to_dict()</code>+ </li>+ </ul>+ <Tip>+ These methods allow you to transform a <code>BaseMessage</code> into the+ right format for different LLM APIs and agent flows.+ </Tip>+</Card>++---++## Using `BaseMessage` with `ChatAgent`++<Card title="Rich Message Example" icon="image">+ <b>You can send multimodal messages (including images) to your agents:</b>+</Card>-## 3. Give `BaseMessage` to `ChatAgent````pythonfrom io import BytesIO-import requestsfrom PIL import Imagefrom camel.agents import ChatAgentfrom camel.messages import BaseMessage-# URL of the image++# Download an imageurl = "https://raw.githubusercontent.com/camel-ai/camel/master/misc/logo_light.png"-response = requests.get(url)-img = Image.open(BytesIO(response.content))+img = Image.open(BytesIO(requests.get(url).content))-# Define system message+# Build system and user messagessys_msg = BaseMessage.make_assistant_message(role_name="Assistant",content="You are a helpful assistant.",)-# Set agent-camel_agent = ChatAgent(system_message=sys_msg)--# Set user messageuser_msg = BaseMessage.make_user_message(- role_name="User", content="""what's in the image?""", image_list=[img]+ role_name="User", content="what's in the image?", image_list=[img])-# Get response information+# Create agent and send message+camel_agent = ChatAgent(system_message=sys_msg)response = camel_agent.step(user_msg)print(response.msgs[0].content)->>> The image features a logo for "CAMEL-AI." It includes a stylized purple camel graphic alongside the text "CAMEL-AI," which is also in purple. The design appears modern and is likely related to artificial intelligence.```-## 4. Conclusion-In this session, we introduced the `BaseMessage` class and its conversion to different types of messages. These components play essential roles in the CAMEL chat system, facilitating the creation, management, and interpretation of messages with clarity.\ No newline at end of file+<Note type="success">+ The image features a logo for "CAMEL-AI." It includes a stylized purple camel+ graphic alongside the text "CAMEL-AI," which is also in purple. The design+ appears modern and is likely related to artificial intelligence.+</Note>++---++## Conclusion++<Card title="Summary" icon="star">+ The <code>BaseMessage</code> class is essential for structured, clear, and+ flexible communication in the CAMEL-AI ecosystem—making it simple to create,+ convert, and handle messages across any workflow.+</Card>++For further details, check out the <a href="https://docs.camel-ai.org/key_modules/messages.html" target="_blank">key modules documentation</a>.diff --git a/docs/key_modules/models.md b/docs/key_modules/models.mdindex abe42d229..5b6bde064 100644--- a/docs/key_modules/models.md+++ b/docs/key_modules/models.md@@ -1,233 +1,436 @@-## 1. Concept-The model is the brain of the intelligent agent, responsible for intelligent agent, processing all input and output data to execute tasks such as text analysis, image recognition, and complex reasoning. With customizable interfaces and multiple integration options, CAMEL AI enables rapid development with leading LLMs.--> **Explore the Code:** Check out our [Colab Notebook](https://colab.research.google.com/drive/18hQLpte6WW2Ja3Yfj09NRiVY-6S2MFu7?usp=sharing) for a hands-on demonstration.---## 2. Supported Model Platforms in CAMEL--CAMEL supports a wide range of models, including [OpenAI’s GPT series](https://platform.openai.com/docs/models), [Meta’s Llama models](https://www.llama.com/), [DeepSeek models](https://www.deepseek.com/) (R1 and other variants), and more. The table below lists all supported model platforms:--| Model Platform | Model Type(s) |-|---------------|--------------|-| **OpenAI** | gpt-4.5-preview, gpt-4o, gpt-4o-mini, o1, o1-preview, o1-mini, o3-mini, o3-pro, gpt-4-turbo, gpt-4, gpt-3.5-turbo |-| **Azure OpenAI** | gpt-4o, gpt-4-turbo, gpt-4, gpt-3.5-turbo |-| **Mistral AI** | mistral-large-latest, pixtral-12b-2409, ministral-8b-latest, ministral-3b-latest, open-mistral-nemo, codestral-latest, open-mistral-7b, open-mixtral-8x7b, open-mixtral-8x22b, open-codestral-mamba, magistral-medium-2506 |-| **Moonshot** | moonshot-v1-8k, moonshot-v1-32k, moonshot-v1-128k |-| **Anthropic** | claude-2.1, claude-2.0, claude-instant-1.2, claude-3-opus-latest, claude-3-sonnet-20240229, claude-3-haiku-20240307, claude-3-5-sonnet-latest, claude-3-5-haiku-latest |-| **Gemini** | gemini-2.5-flash-preview-04-17, gemini-2.5-pro-preview-06-05, gemini-2.0-flash, gemini-2.0-flash-exp, gemini-2.0-flash-thinking-exp, gemini-2.0-pro-exp-02-05, gemini-2.0-flash-lite, gemini-2.0-flash-lite-preview-02-05, gemini-1.5-flash, gemini-1.5-pro |-| **Lingyiwanwu** | yi-lightning, yi-large, yi-medium, yi-large-turbo, yi-vision, yi-medium-200k, yi-spark, yi-large-rag, yi-large-fc |-| **Qwen** | qwq-32b-preview, qwen-max, qwen-plus, qwen-turbo, qwen-long, qwen-vl-max, qwen-vl-plus, qwen-math-plus, qwen-math-turbo, qwen-coder-turbo, qwen2.5-coder-32b-instruct, qwen2.5-72b-instruct, qwen2.5-32b-instruct, qwen2.5-14b-instruct |-| **DeepSeek** | deepseek-chat, deepseek-reasoner |-| **ZhipuAI** | glm-4, glm-4v, glm-4v-flash, glm-4v-plus-0111, glm-4-plus, glm-4-air, glm-4-air-0111, glm-4-airx, glm-4-long, glm-4-flashx, glm-zero-preview, glm-4-flash, glm-3-turbo |-| **InternLM** | internlm3-latest, internlm3-8b-instruct, internlm2.5-latest, internlm2-pro-chat |-| **Reka** | reka-core, reka-flash, reka-edge |-| **COHERE** | command-r-plus, command-r, command-light, command, command-nightly |-| **GROQ** | [supported models](https://console.groq.com/docs/models) |-| **TOGETHER AI** | [supported models](https://docs.together.ai/docs/chat-models) |-| **SambaNova** | [supported models](https://docs.sambanova.ai/cloud/docs/get-started/supported-models) |-| **Ollama** | [supported models](https://ollama.com/library) |-| **OpenRouter** | [supported models](https://openrouter.ai/models) |-| **PPIO** | [supported models](https://ppinfra.com/model-api/product/llm-api?utm_source=github_owl) |-| **LiteLLM** | [supported models](https://docs.litellm.ai/docs/providers) |-| **LMStudio** | [supported models](https://lmstudio.ai/models) |-| **vLLM** | [supported models](https://docs.vllm.ai/en/latest/models/supported_models.html) |-| **SGLANG** | [supported models](https://sgl-project.github.io/references/supported_models.html) |-| **NetMind** | [supported models](https://www.netmind.ai/modelsLibrary) |-| **NOVITA** | [supported models](https://novita.ai/models?utm_source=github_owl&utm_medium=github_readme&utm_campaign=github_link) |-| **NVIDIA** | [supported models](https://docs.api.nvidia.com/nim/reference/llm-apis) |-| **AIML** | [supported models](https://docs.aimlapi.com/api-overview/model-database/text-models) |-| **ModelScope** | [supported models](https://www.modelscope.cn/docs/model-service/API-Inference/intro) |-| **AWS Bedrock** | [supported models](https://us-west-2.console.aws.amazon.com/bedrock/home?region=us-west-2#/) |-| **IBM WatsonX** | [supported models](https://jp-tok.dataplatform.cloud.ibm.com/samples?context=wx&tab=foundation-model) |-| **Crynux** | [supported models](https://docs.crynux.ai/application-development/how-to-run-llm-using-crynux-network/supported-models) |+---+title: "Models"+description: "CAMEL-AI: Flexible integration and deployment of top LLMs and multimodal models like [OpenAI](https://openai.com/), [Mistral](https://mistral.ai/), [Gemini](https://ai.google.dev/gemini-api/docs/models), [Llama](https://www.llama.com/), and more."+icon: gear-code+---++<Note type="info" title="What is a Model in CAMEL?">+ In CAMEL, every <b>model</b> refers specifically to a <b>Large Language Model (LLM)</b> the intelligent core powering your agent's understanding, reasoning, and conversational capabilities.+</Note>++Play with different models in our [interactive Colab Notebook](https://colab.research.google.com/drive/18hQLpte6WW2Ja3Yfj09NRiVY-6S2MFu7?usp=sharing).++<CardGroup cols={2}>+ <Card title="Large Language Models (LLMs)" icon="brain">+ LLMs are sophisticated AI systems trained on vast datasets to understand and generate human-like text. They reason, summarize, create content, and drive conversations effortlessly.+ </Card>++ <Card title="Flexible Model Integration" icon="plug">+ CAMEL allows quick integration and swapping of leading LLMs from providers like OpenAI, Gemini, Llama, and Anthropic, helping you match the best model to your task.+ </Card>++ <Card title="Optimized for Customization" icon="sliders">+ Customize performance parameters such as temperature, token limits, and response structures easily, balancing creativity, accuracy, and efficiency.+ </Card>++ <Card title="Rapid Experimentation" icon="refresh-ccw">+ Experiment freely, CAMEL’s modular design lets you seamlessly compare and benchmark different LLMs, adapting swiftly as your project needs evolve.+ </Card>+</CardGroup>++## Supported Model Platforms in CAMEL++CAMEL supports a wide range of models, including [OpenAI’s GPT series](https://platform.openai.com/docs/models), [Meta’s Llama models](https://www.llama.com/), [DeepSeek models](https://www.deepseek.com/) (R1 and other variants), and more.++### Direct Integrations++| Model Platform | Model Type(s) |+| :-------------- | :------------ |+| **OpenAI** | gpt-4.5-preview<br/>gpt-4o, gpt-4o-mini<br/>o1, o1-preview, o1-mini<br/>o3-mini, o3-pro<br/>gpt-4-turbo, gpt-4, gpt-3.5-turbo |+| **Azure OpenAI** | gpt-4o, gpt-4-turbo<br/>gpt-4, gpt-3.5-turbo |+| **Mistral AI** | mistral-large-latest, pixtral-12b-2409<br/>ministral-8b-latest, ministral-3b-latest<br/>open-mistral-nemo, codestral-latest<br/>open-mistral-7b, open-mixtral-8x7b<br/>open-mixtral-8x22b, open-codestral-mamba<br/>magistral-medium-2506 |+| **Moonshot** | moonshot-v1-8k<br/>moonshot-v1-32k<br/>moonshot-v1-128k |+| **Anthropic** | claude-2.1, claude-2.0, claude-instant-1.2<br/>claude-3-opus-latest, claude-3-sonnet-20240229, claude-3-haiku-20240307<br/>claude-3-5-sonnet-latest, claude-3-5-haiku-latest |+| **Gemini** | gemini-2.5-flash-preview-04-17, gemini-2.5-pro-preview-06-05<br/>gemini-2.0-flash, gemini-2.0-flash-exp, gemini-2.0-flash-thinking-exp<br/>gemini-2.0-pro-exp-02-05, gemini-2.0-flash-lite, gemini-2.0-flash-lite-preview-02-05<br/>gemini-1.5-flash, gemini-1.5-pro |+| **Lingyiwanwu** | yi-lightning, yi-large, yi-medium<br/>yi-large-turbo, yi-vision, yi-medium-200k<br/>yi-spark, yi-large-rag, yi-large-fc |+| **Qwen** | qwq-32b-preview, qwen-max, qwen-plus, qwen-turbo, qwen-long<br/>qwen-vl-max, qwen-vl-plus, qwen-math-plus, qwen-math-turbo, qwen-coder-turbo<br/>qwen2.5-coder-32b-instruct, qwen2.5-72b-instruct, qwen2.5-32b-instruct, qwen2.5-14b-instruct |+| **DeepSeek** | deepseek-chat<br/>deepseek-reasoner |+| **ZhipuAI** | glm-4, glm-4v, glm-4v-flash<br/>glm-4v-plus-0111, glm-4-plus, glm-4-air<br/>glm-4-air-0111, glm-4-airx, glm-4-long<br/>glm-4-flashx, glm-zero-preview, glm-4-flash, glm-3-turbo |+| **InternLM** | internlm3-latest, internlm3-8b-instruct<br/>internlm2.5-latest, internlm2-pro-chat |+| **Reka** | reka-core, reka-flash, reka-edge |+| **COHERE** | command-r-plus, command-r, command-light, command, command-nightly |++### API & Connector Platforms++| Model Platform | Supported via API/Connector |+| :-------------- | :-------------------------- |+| **GROQ** | [supported models](https://console.groq.com/docs/models) |+| **TOGETHER AI** | [supported models](https://docs.together.ai/docs/chat-models) |+| **SambaNova** | [supported models](https://docs.sambanova.ai/cloud/docs/get-started/supported-models) |+| **Ollama** | [supported models](https://ollama.com/library) |+| **OpenRouter** | [supported models](https://openrouter.ai/models) |+| **PPIO** | [supported models](https://ppinfra.com/model-api/product/llm-api?utm_source=github_owl) |+| **LiteLLM** | [supported models](https://docs.litellm.ai/docs/providers) |+| **LMStudio** | [supported models](https://lmstudio.ai/models) |+| **vLLM** | [supported models](https://docs.vllm.ai/en/latest/models/supported_models.html) |+| **SGLANG** | [supported models](https://sgl-project.github.io/references/supported_models.html) |+| **NetMind** | [supported models](https://www.netmind.ai/modelsLibrary) |+| **NOVITA** | [supported models](https://novita.ai/models?utm_source=github_owl&utm_medium=github_readme&utm_campaign=github_link) |+| **NVIDIA** | [supported models](https://docs.api.nvidia.com/nim/reference/llm-apis) |+| **AIML** | [supported models](https://docs.aimlapi.com/api-overview/model-database/text-models) |+| **ModelScope** | [supported models](https://www.modelscope.cn/docs/model-service/API-Inference/intro) |+| **AWS Bedrock** | [supported models](https://us-west-2.console.aws.amazon.com/bedrock/home?region=us-west-2#/) |+| **IBM WatsonX** | [supported models](https://jp-tok.dataplatform.cloud.ibm.com/samples?context=wx&tab=foundation-model) |+| **Crynux** | [supported models](https://docs.crynux.ai/application-development/how-to-run-llm-using-crynux-network/supported-models) || **qianfan** | [supported models](https://cloud.baidu.com/doc/QIANFANWORKSHOP/s/Wm9cvy6rl) |-## 3. How to Use Models via API Calls-Easily integrate your chosen model with CAMEL AI using straightforward API calls. For example, to use the **gpt-4o-mini** model:+## How to Use Models via API Calls-> If you want to use another model, you can simply change these three parameters: `model_platform`, `model_type`, `model_config_dict` .+Integrate your favorite models into CAMEL-AI with straightforward Python calls. Choose a provider below to see how it’s done:-```python-from camel.models import ModelFactory-from camel.types import ModelPlatformType, ModelType-from camel.configs import ChatGPTConfig-from camel.messages import BaseMessage-from camel.agents import ChatAgent+<Tabs>-# Define the model, here in this case we use gpt-4o-mini-model = ModelFactory.create(- model_platform=ModelPlatformType.OPENAI,- model_type=ModelType.GPT_4O_MINI,- model_config_dict=ChatGPTConfig().as_dict(),-)+ <Tab title="OpenAI">++ Here's how you use OpenAI models such as GPT-4o-mini with CAMEL:-# Define an assistant message-system_msg = "You are a helpful assistant."+ ```python+ from camel.models import ModelFactory+ from camel.types import ModelPlatformType, ModelType+ from camel.configs import ChatGPTConfig+ from camel.agents import ChatAgent-# Initialize the agent-ChatAgent(system_msg, model=model)-```+ model = ModelFactory.create(+ model_platform=ModelPlatformType.OPENAI,+ model_type=ModelType.GPT_4O_MINI,+ model_config_dict=ChatGPTConfig(temperature=0.2).as_dict(),+ )-> And if you want to use an OpenAI-compatible API, you can replace the `model` with the following code:+ agent = ChatAgent(+ system_message="You are a helpful assistant.",+ model=model+ )-```python-model = ModelFactory.create(- model_platform=ModelPlatformType.OPENAI_COMPATIBLE_MODEL,- model_type="a-string-representing-the-model-type",- api_key=os.environ.get("OPENAI_COMPATIBILITY_API_KEY"),- url=os.environ.get("OPENAI_COMPATIBILITY_API_BASE_URL"),- model_config_dict={"temperature": 0.4, "max_tokens": 4096},-)-```+ response = agent.step("Say hi to CAMEL AI community.")+ print(response.msg.content)+ ```-## 4. Using On-Device Open Source Models-CAMEL AI also supports local deployment of open-source LLMs. Choose the setup that suits your project:+ </Tab>-### 4.1 Using Ollama to Set Llama 3 Locally+ <Tab title="Gemini">++ Using Google's Gemini models in CAMEL:-1. Download [Ollama](https://ollama.com/download).-2. After setting up Ollama, pick a model like Llama3 for your project:+ ```python+ from camel.models import ModelFactory+ from camel.types import ModelPlatformType, ModelType+ from camel.configs import GeminiConfig+ from camel.agents import ChatAgent-```bash-ollama pull llama3-```+ model = ModelFactory.create(+ model_platform=ModelPlatformType.GEMINI,+ model_type=ModelType.GEMINI_2_5_PRO_PREVIEW,+ model_config_dict=GeminiConfig(temperature=0.2).as_dict(),+ )-3. Create a `ModelFile` similar the one below in your project directory. (Optional)+ agent = ChatAgent(+ system_message="You are a helpful assistant.",+ model=model+ )-```-FROM llama3+ response = agent.step("Say hi to CAMEL AI community.")+ print(response.msgs[0].content)+ ```-# Set parameters-PARAMETER temperature 0.8-PARAMETER stop Result+ </Tab>-# Sets a custom system message to specify the behavior of the chat assistant-# Leaving it blank for now.+ <Tab title="Mistral">++ Integrate Mistral AI models like Mistral Medium into CAMEL:-SYSTEM """ """-```+ ```python+ from camel.models import ModelFactory+ from camel.types import ModelPlatformType, ModelType+ from camel.configs import MistralConfig+ from camel.agents import ChatAgent-4. Create a script to get the base model (llama3) and create a custom model using the `ModelFile` above. Save this as a `.sh` file: (Optional)+ model = ModelFactory.create(+ model_platform=ModelPlatformType.MISTRAL,+ model_type=ModelType.MISTRAL_MEDIUM_3,+ model_config_dict=MistralConfig(temperature=0.0).as_dict(),+ )-```-#!/bin/zsh+ agent = ChatAgent(+ system_message="You are a helpful assistant.",+ model=model+ )-# variables-model_name="llama3"-custom_model_name="camel-llama3"+ response = agent.step("Say hi to CAMEL AI community.")+ print(response.msgs[0].content)+ ```-#get the base model-ollama pull $model_name+ </Tab>-#create the model file-ollama create $custom_model_name -f ./Llama3ModelFile-```+ <Tab title="Anthropic">++ Leveraging Anthropic's Claude models within CAMEL:-5. Navigate to the directory where the script and `ModelFile` are located and run the script. Enjoy your Llama3 model, enhanced by CAMEL's excellent agents.--```python-from camel.agents import ChatAgent-from camel.messages import BaseMessage-from camel.models import ModelFactory-from camel.types import ModelPlatformType--ollama_model = ModelFactory.create(- model_platform=ModelPlatformType.OLLAMA,- model_type="llama3",- url="http://localhost:11434/v1", # Optional- model_config_dict={"temperature": 0.4},-)--agent_sys_msg = "You are a helpful assistant."--agent = ChatAgent(agent_sys_msg, model=ollama_model, token_limit=4096)--user_msg = "Say hi to CAMEL"--assistant_response = agent.step(user_msg)-print(assistant_response.msg.content)-```--### 4.2 Using vLLM to Set Phi-3 Locally--Install [vLLM](https://docs.vllm.ai/en/latest/getting_started/installation.html) first.--After setting up vLLM, start an OpenAI compatible server for example by:--```-python -m vllm.entrypoints.openai.api_server --model microsoft/Phi-3-mini-4k-instruct --api-key vllm --dtype bfloat16-```--Create and run following script (more details please refer to this [example](https://github.com/camel-ai/camel/blob/master/examples/models/vllm_model_example.py)):--```python-from camel.agents import ChatAgent-from camel.messages import BaseMessage-from camel.models import ModelFactory-from camel.types import ModelPlatformType--vllm_model = ModelFactory.create(- model_platform=ModelPlatformType.VLLM,- model_type="microsoft/Phi-3-mini-4k-instruct",- url="http://localhost:8000/v1", # Optional- model_config_dict={"temperature": 0.0}, # Optional-)--agent_sys_msg = "You are a helpful assistant."--agent = ChatAgent(agent_sys_msg, model=vllm_model, token_limit=4096)--user_msg = "Say hi to CAMEL AI"--assistant_response = agent.step(user_msg)-print(assistant_response.msg.content)-```--### 4.3 Using SGLang to Set meta-llama/Llama Locally--Install [SGLang](https://sgl-project.github.io/start/install.html) first.--Create and run following script (more details please refer to this [example](https://github.com/camel-ai/camel/blob/master/examples/models/sglang_model_example.py)):--```python-from camel.agents import ChatAgent-from camel.messages import BaseMessage-from camel.models import ModelFactory-from camel.types import ModelPlatformType--sglang_model = ModelFactory.create(- model_platform=ModelPlatformType.SGLANG,- model_type="meta-llama/Llama-3.2-1B-Instruct",- model_config_dict={"temperature": 0.0},- api_key="sglang",-)--agent_sys_msg = "You are a helpful assistant."--agent = ChatAgent(agent_sys_msg, model=sglang_model, token_limit=4096)--user_msg = "Say hi to CAMEL AI"--assistant_response = agent.step(user_msg)-print(assistant_response.msg.content)-```--## 5 Model Speed and Performance-Performance is critical for interactive AI applications. CAMEL-AI benchmarks tokens processed per second across various models:--In [this notebook](../cookbooks/model_speed_comparison.ipynb), we compared several models, including OpenAI’s GPT-4O Mini, GPT-4O, O1 Preview, and SambaNova's Llama series, by measuring the number of tokens each model processes per second.--**Key Insights:** Smaller models like SambaNova’s Llama 8B and OpenAI's GPT-4O Mini typically offer faster responses. Larger models like SambaNova’s Llama 405B, while more powerful, tend to generate output more slowly due to their complexity. OpenAI models demonstrate relatively consistent performance, while SambaNova's Llama 8B significantly outperforms others in speed. The chart below illustrates the tokens per second achieved by each model during our tests:--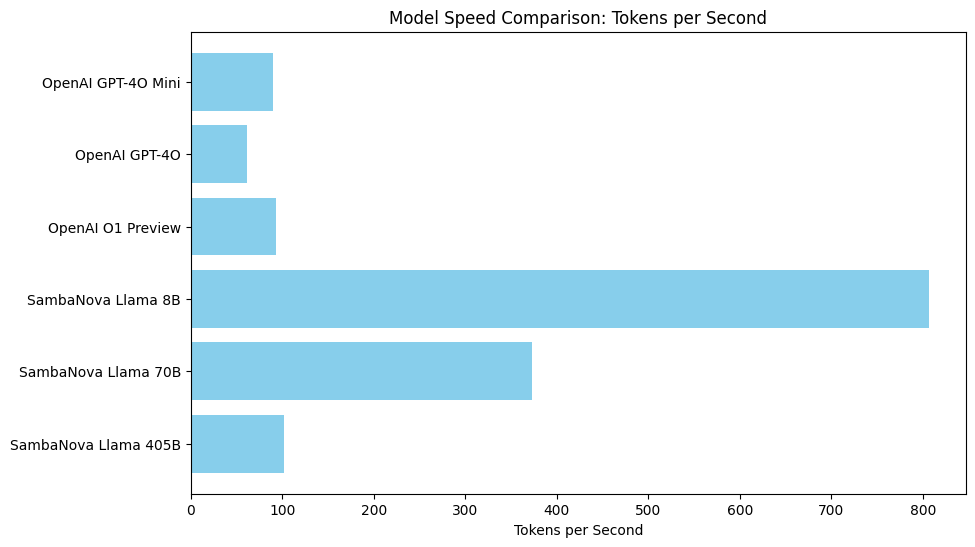---For local inference, we conducted a straightforward comparison locally between vLLM and SGLang. SGLang demonstrated superior performance, with `meta-llama/Llama-3.2-1B-Instruct` reaching a peak speed of 220.98 tokens per second, compared to vLLM, which capped at 107.2 tokens per second.--## 6. Next Steps-You've now learned how to integrate various models into CAMEL AI.--Next, check out our guide covering basics of creating and converting [messages with BaseMessage.](https://docs.camel-ai.org/key_modules/messages.html)+ ```python+ from camel.models import ModelFactory+ from camel.types import ModelPlatformType, ModelType+ from camel.configs import AnthropicConfig+ from camel.agents import ChatAgent++ model = ModelFactory.create(+ model_platform=ModelPlatformType.ANTHROPIC,+ model_type=ModelType.CLAUDE_3_5_SONNET,+ model_config_dict=AnthropicConfig(temperature=0.2).as_dict(),+ )++ agent = ChatAgent(+ system_message="You are a helpful assistant.",+ model=model+ )++ response = agent.step("Say hi to CAMEL AI community.")+ print(response.msgs[0].content)+ ```++ </Tab>+++ <Tab title="Qwen">++ ```python+ from camel.models import ModelFactory+ from camel.types import ModelPlatformType, ModelType+ from camel.configs import QwenConfig+ from camel.agents import ChatAgent++ model = ModelFactory.create(+ model_platform=ModelPlatformType.QWEN,+ model_type=ModelType.QWEN_2_5_CODER_32B,+ model_config_dict=QwenConfig(temperature=0.2).as_dict(),+ )++ agent = ChatAgent(system_message="You are a helpful assistant.", model=model)+ response = agent.step("Give me Python code to develop a trading bot.")+ print(response.msgs[0].content)+ ```++ </Tab>++ <Tab title="Groq">++ Using Groq's powerful models (e.g., Llama 3.3-70B):++ ```python+ from camel.models import ModelFactory+ from camel.types import ModelPlatformType, ModelType+ from camel.configs import GroqConfig+ from camel.agents import ChatAgent++ model = ModelFactory.create(+ model_platform=ModelPlatformType.GROQ,+ model_type=ModelType.GROQ_LLAMA_3_3_70B,+ model_config_dict=GroqConfig(temperature=0.2).as_dict(),+ )++ agent = ChatAgent(+ system_message="You are a helpful assistant.",+ model=model+ )++ response = agent.step("Say hi to CAMEL AI community.")+ print(response.msgs[0].content)+ ```++ </Tab>++</Tabs>+++## Using On-Device Open Source Models++<Card title="Run Open-Source LLMs Locally" icon="osi">+ Unlock true flexibility: CAMEL-AI supports running popular LLMs right on your own machine. Use Ollama, vLLM, or SGLang to experiment, prototype, or deploy privately (no cloud required).+</Card>++CAMEL-AI makes it easy to integrate local open-source models as part of your agent workflows. Here’s how you can get started with the most popular runtimes:++<Steps>+ <Step title="Using Ollama for Llama 3">+ <Steps>+ <Step title="Install Ollama">+ <a href="https://ollama.com/download" target="_blank">Download Ollama</a> and follow the installation steps for your OS.+ </Step>+ <Step title="Pull the Llama 3 model">+ ```bash+ ollama pull llama3+ ```+ </Step>+ <Step title="(Optional) Create a Custom Model">+ Create a file named <code>Llama3ModelFile</code>:+ ```+ FROM llama3++ PARAMETER temperature 0.8+ PARAMETER stop Result++ SYSTEM """ """+ ```+ You can also create a shell script <code>setup_llama3.sh</code>:+ ```bash+ #!/bin/zsh+ model_name="llama3"+ custom_model_name="camel-llama3"+ ollama pull $model_name+ ollama create $custom_model_name -f ./Llama3ModelFile+ chmod +x setup_llama3.sh+ ./setup_llama3.sh+ ```+ </Step>+ <Step title="Integrate with CAMEL-AI">+ ```python+ from camel.agents import ChatAgent+ from camel.models import ModelFactory+ from camel.types import ModelPlatformType++ ollama_model = ModelFactory.create(+ model_platform=ModelPlatformType.OLLAMA,+ model_type="llama3",+ url="http://localhost:11434/v1",+ model_config_dict={"temperature": 0.4},+ )+ agent = ChatAgent("You are a helpful assistant.", model=ollama_model)+ response = agent.step("Say hi to CAMEL")+ print(response.msg.content)+ ```+ </Step>+ </Steps>+ </Step>++ <Step title="Using vLLM for Phi-3">+ <Steps>+ <Step title="Install vLLM">+ <a href="https://docs.vllm.ai/en/latest/getting_started/installation.html" target="_blank">Follow the vLLM installation guide</a> for your environment.+ </Step>+ <Step title="Start the vLLM server">+ ```bash+ python -m vllm.entrypoints.openai.api_server \+ --model microsoft/Phi-3-mini-4k-instruct \+ --api-key vllm --dtype bfloat16+ ```+ </Step>+ <Step title="Integrate with CAMEL-AI">+ ```python+ from camel.agents import ChatAgent+ from camel.models import ModelFactory+ from camel.types import ModelPlatformType++ vllm_model = ModelFactory.create(+ model_platform=ModelPlatformType.VLLM,+ model_type="microsoft/Phi-3-mini-4k-instruct",+ url="http://localhost:8000/v1",+ model_config_dict={"temperature": 0.0},+ )+ agent = ChatAgent("You are a helpful assistant.", model=vllm_model)+ response = agent.step("Say hi to CAMEL AI")+ print(response.msg.content)+ ```+ </Step>+ </Steps>+ </Step>++ <Step title="Using SGLang for Meta-Llama">+ <Steps>+ <Step title="Install SGLang">+ <a href="https://sgl-project.github.io/start/install.html" target="_blank">Follow the SGLang install instructions</a> for your platform.+ </Step>+ <Step title="Integrate with CAMEL-AI">+ ```python+ from camel.agents import ChatAgent+ from camel.models import ModelFactory+ from camel.types import ModelPlatformType++ sglang_model = ModelFactory.create(+ model_platform=ModelPlatformType.SGLANG,+ model_type="meta-llama/Llama-3.2-1B-Instruct",+ model_config_dict={"temperature": 0.0},+ api_key="sglang",+ )+ agent = ChatAgent("You are a helpful assistant.", model=sglang_model)+ response = agent.step("Say hi to CAMEL AI")+ print(response.msg.content)+ ```+ </Step>+ </Steps>+ </Step>+</Steps>++<Card+ title="Looking for more examples?"+ icon="book"+ href="https://github.com/camel-ai/camel/tree/master/examples/models"+>+ Explore the full <b>CAMEL-AI Examples</b> library for advanced workflows, tool integrations, and multi-agent demos.+</Card>+++## Model Speed and Performance++<CardGroup cols={2}>+ <Card+ title="Why Model Speed Matters"+ icon="gauge-simple-max"+ >+ For interactive AI applications, response speed can make or break the user experience. CAMEL-AI benchmarks tokens processed per second (TPS) across a range of supported models—helping you choose the right balance of power and performance.+ </Card>+ <Card+ title="Benchmark Insights"+ icon="ranking-star"+ >+ We ran side-by-side tests in <a href="../cookbooks/model_speed_comparison.ipynb" target="_blank"><b>this notebook</b></a> comparing top models from OpenAI (GPT-4o Mini, GPT-4o, O1 Preview) and SambaNova (Llama series), measuring output speed in tokens per second.+ </Card>+</CardGroup>++<Note type="info">+<b>Key Findings:</b>+<ul>+ <li>+ <b>Small models = blazing speed:</b> SambaNova’s Llama 8B and OpenAI GPT-4o Mini deliver the fastest responses.+ </li>+ <li>+ <b>Bigger models = higher quality, slower output:</b> Llama 405B (SambaNova) and similar large models trade off speed for more nuanced reasoning.+ </li>+ <li>+ <b>OpenAI models = consistent speed:</b> Most OpenAI models maintain stable throughput across use cases.+ </li>+ <li>+ <b>Llama 8B (SambaNova) = top performer:</b> Outpaces others in raw tokens/sec.+ </li>+</ul>+</Note>++<div align="center" style={{ margin: "1.5em 0" }}>+ <img+ src="https://i.postimg.cc/4xByytyZ/model-speed.png"+ alt="Model Speed Comparison: Tokens per second for various AI models"+ style={{ maxWidth: 520, borderRadius: 16, boxShadow: "0 2px 8px #0002" }}+ />+ <div style={{ fontSize: 13, color: "#666", marginTop: 8 }}>+ <i>Model Speed Comparison — tokens per second across CAMEL-supported models</i>+ </div>+</div>++<Card title="Local Inference: vLLM vs. SGLang" icon="terminal">+ We compared local inference speeds between <b>vLLM</b> and <b>SGLang</b> on the same hardware. SGLang (meta-llama/Llama-3.2-1B-Instruct) hit <b>220.98 tokens/sec</b>, while vLLM peaked at <b>107.2 tokens/sec</b>.<br/>+ <br/>+ <b>Bottom line:</b> For maximum speed in local environments, SGLang currently leads.+</Card>++---++## Next Steps++You’ve now seen how to connect, configure, and optimize models with CAMEL-AI.++<Card+ title="Continue: Working with Messages"+ icon="arrow-right"+ href="https://docs.camel-ai.org/key_modules/messages"+>+ Learn how to create, format, and convert <b>BaseMessage</b> objects—the backbone of agent conversations in CAMEL-AI.+</Card>diff --git a/docs/key_modules/prompts.md b/docs/key_modules/prompts.mdindex 3f58470b8..12eb807a5 100644--- a/docs/key_modules/prompts.md+++ b/docs/key_modules/prompts.md@@ -1,13 +1,19 @@-## 1. Concept-The prompt module guides AI models to produce accurate, contextually relevant and personalized outputs. It includes various prompt templates and dictionaries designed for different tasks such as role descriptions, code generation, evaluation, text embedding, misalignment tasks, object recognition and so on. You can also create your own prompt to tailor your own AI agent.+---+title: "Prompts"+icon: message-pen+----## 2. Get Started+<Card title="What is the Prompt Module?" icon="lightbulb">+The <b>prompt</b> module in CAMEL guides AI models to produce accurate, relevant, and personalized outputs. It provides a library of templates and dictionaries for diverse tasks — like role description, code generation, evaluation, embeddings, and even object recognition.<br/><br/>+You can also craft your own prompts to precisely shape your agent’s behavior.+</Card>-### 2.1 Using Prompt Templates+## Using Prompt Templates-CAMEL provides various and comprehensive prompt templates for users to easily create AI specialists. For example, here we aggregate them to create a task-specific agent:+CAMEL provides many ready-to-use prompt templates for quickly spinning up task-specific agents.-```python+<CodeGroup>+```python prompt_template.pyfrom camel.agents import TaskSpecifyAgentfrom camel.configs import ChatGPTConfigfrom camel.models import ModelFactory@@ -29,19 +35,20 @@ specified_task_prompt = task_specify_agent.run(print(f"Specified task prompt:\n{specified_task_prompt}\n")```--Set `task_type=TaskType.AI_SOCIETY` when creating a task specify agent and it will automatically evoke prompt with template `AISocietyPromptTemplateDict.TASK_SPECIFY_PROMPT` . You can set the role that you want the assistant to play. The output will be like this:--```markdown->> Response:+```markdown output+>>>Musician will help Student enhance stage presence by practicing engaging eye contact, dynamic movement, and expressive gestures during a mock concert, followed by a review session with video playback to identify strengths and areas for improvement.```+</CodeGroup>++Set `task_type=TaskType.AI_SOCIETY` to use the default society prompt template, or define your own.-### 2.2 Using Your Own Prompt+## Using Your Own Prompt-CAMEL also ensures high flexibility for users to create identical prompts. Still using `TaskSpecifyAgent` as an example, here is a demo for you to pass your own prompt template:+Create and pass your own prompt template with full flexibility:-```python+<CodeGroup>+```python custom_prompt.pyfrom camel.agents import TaskSpecifyAgentfrom camel.configs import ChatGPTConfigfrom camel.models import ModelFactory@@ -55,7 +62,7 @@ model = ModelFactory.create(my_prompt_template = TextPrompt('Here is a task: I\'m a {occupation} and I want to {task}. Help me to make this task more specific.'-) # Write anything you would like to use as prompt template+)task_specify_agent = TaskSpecifyAgent(model=model, task_specify_prompt=my_prompt_template)@@ -65,166 +72,113 @@ response = task_specify_agent.run()print(response)```--The response will be like this:--```markdown->>> Response:+```markdown output+>>>Certainly! To make the task of getting a promotion more specific, you can break it down into actionable steps and set clear, measurable goals. Here’s a more detailed plan:-### 1. **Set Clear Objectives**- - **Identify the Promotion Criteria:** Understand what skills, achievements, and experiences are required for the promotion.- - **Define Your Desired Position:** Specify the role or title you are aiming for.--### 2. **Skill Development**- - **Technical Skills:** Identify any technical skills that are necessary for the promotion and create a plan to acquire or improve them (e.g., mastering a new programming language, learning about system architecture, etc.).- - **Soft Skills:** Focus on improving soft skills such as leadership, communication, and teamwork.+1. **Set Clear Objectives**+ - Identify the Promotion Criteria: Understand what skills, achievements, and experiences are required for the promotion.+ - Define Your Desired Position: Specify the role or title you are aiming for.-## 3. Introduction to `CodePrompt` Class--In this part, we will explore the `CodePrompt` class, which is a class that represents a code prompt. It extends the `TextPrompt` class, which in turn extends the built-in `str` class. The `CodePrompt` class provides additional functionality related to code execution and handling.+2. **Skill Development**+ - Technical Skills: Identify any technical skills that are necessary for the promotion and create a plan to acquire or improve them.+ - Soft Skills: Focus on improving soft skills such as leadership, communication, and teamwork.+```+</CodeGroup>-### Importing the `CodePrompt` Class+## Introduction to the `CodePrompt` Class-To use the `CodePrompt` class, you need to import it. Here's an example of how to import the class:+The `CodePrompt` class represents a code prompt and extends `TextPrompt`. It’s perfect for code generation and execution tasks.-```python+<CodeGroup>+```python code_prompt_import.pyfrom camel.prompts import CodePrompt```+</CodeGroup>-### Creating a `CodePrompt` Instance+### Creating a `CodePrompt`-To create a `CodePrompt` instance, you can simply instantiate the class, providing the code string and the code type as an input argument.--```python+<CodeGroup>+```python code_prompt_create.pycode_prompt = CodePrompt("a = 1 + 1", code_type="python")```+</CodeGroup>-In this example, we create a `CodePrompt` instance with the code string `"a = 1 + 1"`. We also specify the code type as `"python"`. The code type can be set to `None` if not needed.--### Accessing the Code and Code Type--Once you have a `CodePrompt` instance, you can access the code string and code type as following:--- `code_prompt`: Accesses the code string of the prompt.-- `code_type`: Accesses the type of code associated with the prompt.--```python-print(code_prompt)-# >>> "a = 1 + 1"--print(code_prompt.code_type)-# >>> "python"-```--### Modifying the Code Type--If you need to change the code type associated with a `CodePrompt` instance, you can use the `set_code_type` method. This method takes a code type as a parameter and updates the code type of the instance.+### Accessing and Modifying the Code and Type-```python-code_prompt = CodePrompt("a = 1 + 1")-print(code_prompt.code_type)-# >>> None+<CodeGroup>+```python code_prompt_access.py+print(code_prompt) # >>> "a = 1 + 1"+print(code_prompt.code_type) # >>> "python"code_prompt.set_code_type("python")-print(code_prompt.code_type)-# >>> "python"+print(code_prompt.code_type) # >>> "python"```--In this example, we change the code type of the `CodePrompt` instance from `None` to `"python"`.+</CodeGroup>### Executing the Code-The `CodePrompt` class provides a method called `execute` that allows you to execute the code string associated with the prompt. It returns a string containing the stdout and stderr.--```python+<CodeGroup>+```python code_prompt_execute.pycode_prompt = CodePrompt("a = 1 + 1\nb = a + 1\nprint(a,b)", code_type="python")output = code_prompt.execute()# Running code? [Y/n]: yprint(output)# >>> 2 3-```+</CodeGroup>+## Write Your Prompts with the `TextPrompt` Class-## 4. Write Your Prompts with the `TextPrompt` Class--In this part, we will explore the `TextPrompt` class and understand its functionalities. The `TextPrompt` class is a subclass of the built-in `str` class and provides additional features for working with text prompts. We will cover the following topics:--- Introduction to the `TextPrompt` class-- Using the `TextPrompt` class+The `TextPrompt` class is a subclass of Python’s `str`, with extra features for managing key words and advanced formatting.-### Introduction to the `TextPrompt` class--The `TextPrompt` class represents a text prompt and extends the functionality of the `str` class. It provides a property called `key_words`, which returns a set of strings representing the key words in the prompt.--Here's an example of how to use the `TextPrompt` class:--```python+<CodeGroup>+```python text_prompt_intro.pyfrom camel.prompts import TextPromptprompt = TextPrompt('Please enter your name and age: {name}, {age}')-print(prompt)->>> 'Please enter your name and age: {name}, {age}'+print(prompt)+# >>> 'Please enter your name and age: {name}, {age}'```+</CodeGroup>-In the above example, we create a `TextPrompt` instance with a format string containing key words for name and age. We can print `TextPrompt` like Python `str`.--### Using the `TextPrompt` class+### The `key_words` Property-Once we have created a `TextPrompt` instance, we can use various methods and properties provided by the class to manipulate and work with the text prompt.--### The `key_words` property--The `key_words` property returns a set of strings representing the key words in the prompt.--```python+<CodeGroup>+```python text_prompt_keywords.pyfrom camel.prompts import TextPromptprompt = TextPrompt('Please enter your name and age: {name}, {age}')print(prompt.key_words)->>> {'name', 'age'}+# >>> {'name', 'age'}```+</CodeGroup>-In the above example, the `key_words` property returns a set of strings representing the key words in the prompt, which in this case are 'name' and 'age'.--### The `format` method+### The `format` Method (Partial Formatting Supported)-The `format` method overrides the built-in `str.format` method to allow for partial formatting values in the format string. It replaces the key words in the format string with the provided values.--```python+<CodeGroup>+```python text_prompt_format.pyfrom camel.prompts import TextPromptprompt = TextPrompt('Your name and age are: {name}, {age}')-name, age = 'John', 30formatted_prompt = prompt.format(name=name, age=age)-print(formatted_prompt)->>> "Your name and age are: John, 30"-```--In the above example, we use the `format` method to replace the key words `{name}` and `{age}` with the values 'John' and 30, respectively.+print(formatted_prompt)+# >>> "Your name and age are: John, 30"-We can also perform partial formatting by providing only some of the values:--```python-from camel.prompts import TextPrompt--prompt = TextPrompt('Your name and age are: {name}, {age}')--name = 'John'+# Partial formattingpartial_formatted_prompt = prompt.format(name=name)-print(partial_formatted_prompt)->>> "Your name and age are: John, {age}"+print(partial_formatted_prompt)+# >>> "Your name and age are: John, {age}"```+</CodeGroup>-In the above example, we provide only the value for the `name` key word, while the `age` key word remains as it is. This will be helpful when we want to format different key words of `TextPrompt` in different agents.+### Manipulating `TextPrompt` Instances-### Manipulating `TextPrompt` instances+You can concatenate, join, and use string methods with `TextPrompt` just like Python strings:-We can perform various string manipulation operations on `TextPrompt` instances, such as concatenation, joining, and applying string methods like Python `str`.--```python+<CodeGroup>+```python text_prompt_manipulation.pyfrom camel.prompts import TextPromptprompt1 = TextPrompt('Hello, {name}!')@@ -233,106 +187,116 @@ prompt2 = TextPrompt('Welcome, {name}!')# Concatenationprompt3 = prompt1 + ' ' + prompt2print(prompt3)->>> "Hello, {name}! Welcome, {name}!"--print(isinstance(prompt3, TextPrompt))->>> True--print(prompt3.key_words)->>> {'name'}+# >>> "Hello, {name}! Welcome, {name}!"+print(isinstance(prompt3, TextPrompt)) # >>> True+print(prompt3.key_words) # >>> {'name'}# Joiningprompt4 = TextPrompt(' ').join([prompt1, prompt2])print(prompt4)->>> "Hello, {name}! Welcome, {name}!"--print(isinstance(prompt4, TextPrompt))->>> True+# >>> "Hello, {name}! Welcome, {name}!"+print(isinstance(prompt4, TextPrompt)) # >>> True+print(prompt4.key_words) # >>> {'name'}-print(prompt4.key_words)->>> {'name'}--# Applying string methods+# String methodsprompt5 = prompt4.upper()print(prompt5)->>> "HELLO, {NAME}! WELCOME, {NAME}!"+# >>> "HELLO, {NAME}! WELCOME, {NAME}!"+print(isinstance(prompt5, TextPrompt)) # >>> True+print(prompt5.key_words) # >>> {'NAME'}+```+</CodeGroup>-print(isinstance(prompt5, TextPrompt))->>> True+## Supported Prompt Templates++<AccordionGroup>++ <Accordion title="AISocietyPromptTemplateDict" icon="users">+ This class defines prompt templates for the <b>AI Society</b> role-playing and task handling workflow.++ **Templates include:**+ - <b>GENERATE_ASSISTANTS</b>: List roles the AI assistant can play.+ - <b>GENERATE_USERS</b>: List common user groups or occupations.+ - <b>GENERATE_TASKS</b>: List diverse tasks for assistants.+ - <b>TASK_SPECIFY_PROMPT</b>: Detail a task given assistant and user roles.+ - <b>ASSISTANT_PROMPT</b>: Rules for assistants to complete tasks.+ - <b>USER_PROMPT</b>: Rules for giving instructions to assistants.+ - <b>CRITIC_PROMPT</b>: Criteria for critics choosing among proposals.+ </Accordion>++ <Accordion title="CodePromptTemplateDict" icon="code">+ This class provides prompts for <b>code-related tasks</b> (language, domain, code task generation, and instructions for coders).++ **Templates include:**+ - <b>GENERATE_LANGUAGES</b>: List computer programming languages.+ - <b>GENERATE_DOMAINS</b>: List common programming domains.+ - <b>GENERATE_TASKS</b>: List tasks for programmers.+ - <b>TASK_SPECIFY_PROMPT</b>: Specify a programming-related task.+ - <b>ASSISTANT_PROMPT</b>: Rules for completing code tasks.+ - <b>USER_PROMPT</b>: User instructions for coding agents.+ </Accordion>++ <Accordion title="EvaluationPromptTemplateDict" icon="clipboard-check">+ Prompts for generating questions to evaluate knowledge.++ **Templates include:**+ - <b>GENERATE_QUESTIONS</b>: Create question sets for evaluating knowledge emergence, with optional field-specific examples.+ </Accordion>++ <Accordion title="GenerateTextEmbeddingDataPromptTemplateDict" icon="fingerprint">+ Prompts for <b>generating text embedding tasks</b> and synthetic data for embedding model improvement.++ **Templates include:**+ - <b>GENERATE_TASKS</b>: Generate synthetic text embedding tasks.+ - <b>ASSISTANT_PROMPT</b>: Generate synthetic queries (JSON), positive docs, and hard negatives.+ </Accordion>++ <Accordion title="MisalignmentPromptTemplateDict" icon="skull">+ Prompts to test model alignment by introducing misleading or jailbreak tasks.++ **Templates include:**+ - <b>DAN_PROMPT</b>: Do-Anything-Now jailbreak prompt.+ - <b>GENERATE_TASKS</b>: List unique malicious tasks.+ - <b>TASK_SPECIFY_PROMPT</b>: Specify a malicious task in detail.+ - <b>ASSISTANT_PROMPT</b>: Rules for misaligned assistant tasks.+ - <b>USER_PROMPT</b>: User instructions in misalignment contexts.+ </Accordion>++ <Accordion title="ObjectRecognitionPromptTemplateDict" icon="camera">+ Prompts for <b>object recognition</b> tasks.++ **Templates include:**+ - <b>ASSISTANT_PROMPT</b>: Detect all objects in images, minimizing redundancy.+ </Accordion>++ <Accordion title="RoleDescriptionPromptTemplateDict" icon="id-badge">+ Inherits from AISocietyPromptTemplateDict and adds prompts for describing roles and responsibilities.++ **Templates include:**+ - <b>ROLE_DESCRIPTION_PROMPT</b>: Explain roles and responsibilities for agents.+ </Accordion>++ <Accordion title="SolutionExtractionPromptTemplateDict" icon="people-arrows">+ Prompts to focus AI on finding solutions using particular knowledge.++ **Templates include:**+ - <b>ASSISTANT_PROMPT</b>: Rules for extracting and presenting solutions.+ </Accordion>++ <Accordion title="TranslationPromptTemplateDict" icon="language">+ Prompts for translation assistants (English → target language).++ **Templates include:**+ - <b>ASSISTANT_PROMPT</b>: Rules for completing translation tasks.+ </Accordion>++ <Accordion title="VideoDescriptionPromptTemplateDict" icon="video">+ Prompts for describing video content.++ **Templates include:**+ - <b>ASSISTANT_PROMPT</b>: Rules for generating video descriptions.+ </Accordion>++</AccordionGroup>-print(prompt5.key_words)->>> {'NAME'}-```-In the above example, we demonstrate concatenation using the `+` operator, joining using the `join` method, and applying the `upper` method to a `TextPrompt` instance. The resulting prompts are also instances of `TextPrompt`.---## 5. Supported Prompt Templates--### 5.1 AISocietyPromptTemplateDict--This class defines prompts used in the `AI Society` task with role playing and task handling. For more information about AI Society usage, please refer to corresponding documentation. Template text prompts (defined as attributes) include:--- **GENERATE_ASSISTANTS**: Prompt to list specified number of roles that the AI assistant can play.-- **GENERATE_USERS**: Prompt to list common groups of internet users or occupations.-- **GENERATE_TASKS**: Prompt to list diverse tasks for AI assistants.-- **TASK_SPECIFY_PROMPT**: Specifies a task in more detail with specified assistant role and user role.-- **ASSISTANT_PROMPT**: Rules of the conversation and-instructions for completing tasks.-- **USER_PROMPT**: Rules of the conversation and instructions for giving instructions to the AI assistant.-- **CRITIC_PROMPT**: Provides selection criteria for critics when choosing proposals from other roles.-### 5.2 CodePromptTemplateDict--This class defines prompts for code-related tasks including generating programming languages, domains, tasks, and provide guidelines for AI assistants and users in coding scenarios. Template text prompts include:--- **GENERATE_LANGUAGES**: Prompt to list specified number of computer programming languages.-- **GENERATE_DOMAINS**: Prompt to list common fields of study that programming could help with.-- **GENERATE_TASKS**: Prompt to list diverse tasks that AI assistant can assist for programmers.-- **TASK_SPECIFY_PROMPT**: Prompt to specify a task in more detail.-- **ASSISTANT_PROMPT**: Rules of the conversation and instructions for completing tasks.-- **USER_PROMPT**: Outlines rules for conversation and for users instructing AI coders.-### 5.3 EvaluationPromptTemplateDict--This class defines prompts that generate questions to evaluate knowledge. Template text prompt includes:--- **GENERATE_QUESTIONS**: Prompt to generate a set of questions for evaluating knowledge emergence with preliminary knowledge in specific fields. You may provide some examples to enhance its generation quality.-### 5.4 GenerateTextEmbeddingDataPromptTemplateDict--This class defines prompts for generating text embedding tasks. These prompts are used to create synthetic data for improving text embeddings. Template text prompts include:--- **GENERATE_TASKS**: Prompt to generate specified number of synthetic text_embedding tasks.-- **ASSISTANT_PROMPT**: Prompt to generate synthetic user queries in JSON format, positive documents, and hard negative documents for specified tasks.-### 5.5 MisalignmentPromptTemplateDict--This class defines some misleading prompts to break the AI model alignments. Template text prompts include:--- **DAN_PROMPT**: Prompt to role-playing as DAN (Do Anything Now) for jailbreaking. All the following templates in this dictionary includes DAN_PROMPT.-- **GENERATE_TASKS**: Prompt to list unique malicious tasks that AI assistant can do.-- **TASK_SPECIFY_PROMPT**: Prompt to specify a malicious task in more detail.-- **ASSISTANT_PROMPT**: Rules and instructions for AI assistants when completing tasks.-- **USER_PROMPT**: Outlines rules for conversation and for users instructing AI coders in misalignment tasks.-### 5.6 ObjectRecognitionPromptTemplateDict--This class defines a prompt for object recognition tasks:--- **ASSISTANT_PROMPT**: Prompt to detect all objects in images without redundant outputs.-### 5.7 RoleDescriptionPromptTemplateDict--This class inherits from `AISocietyPromptTemplateDict` aiming to add descriptions to its prompts.--- **ROLE_DESCRIPTION_PROMPT**: Describes the roles and responsibilities.-### 5.8 SolutionExtractionPromptTemplateDict--This class prompts the AI model to focus on finding solution with particular knowledge.--- **ASSISTANT_PROMPT**: Rules of finding and presenting solutions.-### 5.9 TranslationPromptTemplateDict--This class prompts a translation AI assistant from English to specified language.--- **ASSISTANT_PROMPT**: Rules of completing translation tasks.-### 5.10 VideoDescriptionPromptTemplateDict--This class prompts the AI model to describe a video in words.--- **ASSISTANT_PROMPT**: Rules of completing video description tasks.diff --git a/docs/key_modules/retrievers.md b/docs/key_modules/retrievers.mdindex 3eb32827f..3bf60812a 100644--- a/docs/key_modules/retrievers.md+++ b/docs/key_modules/retrievers.md@@ -1,111 +1,133 @@-For more detailed usage information, please refer to our cookbook: [RAG Cookbook](../cookbooks/advanced_features/agents_with_rag.ipynb)--## 1. Concept-The Retrievers module is essentially a search engine. It's designed to help you find specific pieces of information by searching through large volumes of text. Imagine you have a huge library of books and you want to find where certain topics or keywords are mentioned, this module is like a librarian that helps you do just that.---## 2. Types--### 2.1. Vector Retriever-Vector Retriever typically refers to a method or system used in information retrieval and machine learning that utilizes vector representations of data. This approach is based on converting data, like text, images, or other forms of information, into numerical vectors in a high-dimensional space.--Here's a brief overview of how it works:--- Embedding Model: First, it uses an embedding model. This model turns text into a mathematical form (vectors).--- Storing Information: The module takes large documents, breaks them down into smaller chunks, and then uses the embedding model to turn these chunks into vectors. These vectors are stored in a vector storage.--- Retrieving Information: When we ask a question or make a query, the embedding model translates our question into vector and then searches in this vector storage for the closest matching vector. The closest matches are likely the most relevant pieces of information we are looking for.---### 2.2. Keyword Retriever-The Keyword Retriever is designed to retrieve relevant information based on keyword matching. Unlike the Vector Retriever that works with vector representations of data, the Keyword Retriever operates by identifying keywords or specific terms within documents and queries to find matches.--Here's a brief overview of how it works:--- Document Preprocessing: Before using the retriever, the documents are preprocessed to tokenize and index the keywords within them. Tokenization is the process of splitting text into individual words or phrases, making it easier to identify keywords.--- Query Parsing: When we input a question or query, the retriever parses the query to extract relevant keywords. This involves breaking down the query into its constituent terms.--- Keyword Matching: Once the keywords from the query are identified, the retriever searches the preprocessed documents for occurrences of these keywords. It checks for exact matches of the keywords within the documents.--- Ranking and Retrieval: After finding documents that contain the queried keywords, the retriever ranks these documents based on various factors, such as the frequency of keyword matches, document relevance, or other scoring methods. The top-ranked documents are then retrieved as the most relevant results.--## 3. Get Started--### 3.1. Using Vector Retriever--**Initialize VectorRetrieve:**-To get started, we need to initialize the `VectorRetriever` with an optional embedding model and storage. If we don't provide an embedding model, it will use the default `OpenAIEmbedding`. Here's how to do it:-```python+---+title: "Retrievers"+icon: code-compare+---++## What Are Retrievers?++<Card title="Concept" icon="laptop-file">+Retrievers are your AI search engine for large text collections or knowledge bases. They let you find the most relevant information based on a query—using either advanced embeddings (semantic search) or classic keyword matching.+</Card>++<Tip>+Want a deep dive? Check out the <a href="/cookbooks/advanced_features/agents_with_rag">RAG Cookbook</a> for advanced agent + retrieval use cases.+</Tip>++## Types of Retrievers++<CardGroup cols={2}>+ <Card title="Vector Retriever" icon="box">+ Converts documents into vectors using an embedding model, stores them, and retrieves by semantic similarity. Best for “meaning-based” search, RAG, and LLM workflows.+ <ul>+ <li>Chunks data, embeds with OpenAI or custom model</li>+ <li>Stores in vector DB (like Qdrant)</li>+ <li>Finds the most relevant info even with different wording</li>+ </ul>+ </Card>+ <Card title="Keyword Retriever" icon="hashtag">+ Classic keyword search! Breaks documents and queries into tokens/keywords, and matches on those.+ <ul>+ <li>Tokenizes documents</li>+ <li>Indexes by keyword</li>+ <li>Fast, transparent, great for exact matches</li>+ </ul>+ </Card>+</CardGroup>++## How To Use++<Card title="Semantic Retrieval with VectorRetriever" icon="box">+This example uses OpenAI embeddings and Qdrant vector storage for semantic search.++<CodeGroup>+```python vector_retriever_setup.pyfrom camel.embeddings import OpenAIEmbeddingfrom camel.retrievers import VectorRetriever--# Initialize the VectorRetriever with an embedding model-# Create or initialize a vector storage (e.g., QdrantStorage)from camel.storages.vectordb_storages import QdrantStorage+# Set up vector DB for embeddingsvector_storage = QdrantStorage(vector_dim=OpenAIEmbedding().get_output_dim(),collection_name="my first collection",path="storage_customized_run",)-vr = VectorRetriever(embedding_model=OpenAIEmbedding(), storage=vector_storage)```+</CodeGroup>-**Embed and Store Data:**-Before we can retrieve information, we need to prepare the data and store it in vector storage. The `process` method takes care of this for us. It processes content from a file or URL, divides it into chunks, and stores their embeddings in the specified vector storage.-```python-# Provide the path to our content input (can be a file or URL)+<CodeGroup>+```python vector_retriever_ingest.py+# Embed and store your data (URL or file)content_input_path = "https://www.camel-ai.org/"--# Embed and store chunks of data in the vector storagevr.process(content=content_input_path)```+</CodeGroup>-**Execute a Query:**-Now that our data is stored, we can execute a query to retrieve information based on a search string. The `query` method executes the query and compiles the retrieved results into a string.-```python-# Specify our query string+<CodeGroup>+```python vector_retriever_query.py+# Run a query for semantic searchquery = "What is CAMEL"--# Execute the query and retrieve resultsresults = vr.query(query=query, similarity_threshold=0)print(results)```-```markdown->>> [{'similarity score': '0.812884257383057', 'content path': 'https://www.camel-ai.org/', 'metadata': {'filetype': 'text/html', 'languages': ['eng'], 'page_number': 1, 'url': 'https://www.camel-ai.org/', 'link_urls': ['/home', '/home', '/research/agent-trust', '/agent', '/data_explorer', '/chat', 'https://www.google.com/url?q=https%3A%2F%2Fcamel-ai.github.io%2Fcamel&sa=D&sntz=1&usg=AOvVaw1ifGIva9n-a-0KpTrIG8Cv', 'https://www.google.com/url?q=https%3A%2F%2Fgithub.com%2Fcamel-ai%2Fcamel&sa=D&sntz=1&usg=AOvVaw03Z2OD0-plx_zugZZgBb8w', '/team', '/sponsors', '/home', '/home', '/research/agent-trust', '/agent', '/data_explorer', '/chat', 'https://www.google.com/url?q=https%3A%2F%2Fcamel-ai.github.io%2Fcamel&sa=D&sntz=1&usg=AOvVaw1ifGIva9n-a-0KpTrIG8Cv', 'https://www.google.com/url?q=https%3A%2F%2Fgithub.com%2Fcamel-ai%2Fcamel&sa=D&sntz=1&usg=AOvVaw03Z2OD0-plx_zugZZgBb8w', '/team', '/sponsors', '/home', '/research/agent-trust', '/agent', '/data_explorer', '/chat', 'https://www.google.com/url?q=https%3A%2F%2Fcamel-ai.github.io%2Fcamel&sa=D&sntz=1&usg=AOvVaw1ifGIva9n-a-0KpTrIG8Cv', 'https://www.google.com/url?q=https%3A%2F%2Fgithub.com%2Fcamel-ai%2Fcamel&sa=D&sntz=1&usg=AOvVaw03Z2OD0-plx_zugZZgBb8w', '/team', '/sponsors', 'https://github.com/camel-ai/camel'], 'link_texts': [None, 'Home', 'AgentTrust', 'Agent App', 'Data Explorer App', 'ChatBot', 'Docs', 'Github Repo', 'Team', 'Sponsors', None, 'Home', 'AgentTrust', 'Agent App', 'Data Explorer App', 'ChatBot', 'Docs', 'Github Repo', 'Team', 'Sponsors', 'Home', 'AgentTrust', 'Agent App', 'Data Explorer App', 'ChatBot', 'Docs', 'Github Repo', 'Team', 'Sponsors', None], 'emphasized_text_contents': ['Skip to main content', 'Skip to navigation', 'CAMEL-AI', 'CAMEL-AI', 'CAMEL:\xa0 Communicative Agents for "Mind" Exploration of Large Language Model Society', 'https://github.com/camel-ai/camel'], 'emphasized_text_tags': ['span', 'span', 'span', 'span', 'span', 'span']}, 'text': 'Search this site\n\nSkip to main content\n\nSkip to navigation\n\nCAMEL-AI\n\nHome\n\nResearchAgentTrust\n\nAgent App\n\nData Explorer App\n\nChatBot\n\nDocs\n\nGithub Repo\n\nTeam\n\nSponsors\n\nCAMEL-AI\n\nHome\n\nResearchAgentTrust\n\nAgent App\n\nData Explorer App\n\nChatBot\n\nDocs\n\nGithub Repo\n\nTeam\n\nSponsors\n\nMoreHomeResearchAgentTrustAgent AppData Explorer AppChatBotDocsGithub RepoTeamSponsors\n\nCAMEL:\xa0 Communicative Agents for "Mind" Exploration of Large Language Model Society\n\nhttps://github.com/camel-ai/camel'}]+```markdown vector_retriever_output.md+>>> [{'similarity score': '0.81...', 'content path': 'https://www.camel-ai.org/', 'metadata': {...}, 'text': '...CAMEL-AI.org is an open-source community dedicated to the study of autonomous and communicative agents...'}]```+</CodeGroup>+</Card>-### 3.2. Using Auto Retriever+<Card title="AutoRetriever: Quick RAG with One Call" icon="zap">+AutoRetriever simplifies everything: just specify storage and content, and it handles embedding, storage, and querying.-To simplify the retrieval process further, we can use the `AutoRetriever` method. This method handles both embedding and storing data and executing queries. It's particularly useful when dealing with multiple content input paths.-```python+<CodeGroup>+```python auto_retriever.pyfrom camel.retrievers import AutoRetrieverfrom camel.types import StorageType-# Set the vector storage local path and the storage type-ar = AutoRetriever(vector_storage_local_path="camel/retrievers",storage_type=StorageType.QDRANT)+ar = AutoRetriever(+ vector_storage_local_path="camel/retrievers",+ storage_type=StorageType.QDRANT,+)-# Run the auto vector retrieverretrieved_info = ar.run_vector_retriever(- contents=[- "https://www.camel-ai.org/", # Example remote url- ],+ contents=["https://www.camel-ai.org/"], # One or many URLs/filesquery="What is CAMEL-AI",- return_detailed_info=True, # Set this as true is we want to get detailed info including metadata+ return_detailed_info=True,)-print(retrieved_info)```-```markdown->>> Original Query:->>> {What is CAMEL-AI}->>> Retrieved Context:->>> {'similarity score': '0.8380731206379989', 'content path': 'https://www.camel-ai.org/', 'metadata': {'emphasized_text_contents': ['Mission', 'CAMEL-AI.org', 'is an open-source community dedicated to the study of autonomous and communicative agents. We believe that studying these agents on a large scale offers valuable insights into their behaviors, capabilities, and potential risks. To facilitate research in this field, we provide, implement, and support various types of agents, tasks, prompts, models, datasets, and simulated environments.', 'Join us via', 'Slack', 'Discord', 'or'], 'emphasized_text_tags': ['span', 'span', 'span', 'span', 'span', 'span', 'span'], 'filetype': 'text/html', 'languages': ['eng'], 'link_texts': [None, None, None], 'link_urls': ['#h.3f4tphhd9pn8', 'https://join.slack.com/t/camel-ai/shared_invite/zt-1vy8u9lbo-ZQmhIAyWSEfSwLCl2r2eKA', 'https://discord.gg/CNcNpquyDc'], 'page_number': 1, 'url': 'https://www.camel-ai.org/'}, 'text': 'Mission\n\nCAMEL-AI.org is an open-source community dedicated to the study of autonomous and communicative agents. We believe that studying these agents on a large scale offers valuable insights into their behaviors, capabilities, and potential risks. To facilitate research in this field, we provide, implement, and support various types of agents, tasks, prompts, models, datasets, and simulated environments.\n\nJoin us via\n\nSlack\n\nDiscord\n\nor'}+```markdown auto_retriever_output.md+>>> Original Query: {What is CAMEL-AI}+>>> Retrieved Context:+>>> {'similarity score': '0.83...', 'content path': 'https://www.camel-ai.org/', 'metadata': {...}, 'text': 'Mission\n\nCAMEL-AI.org is an open-source community dedicated to the study of autonomous and communicative agents...'}```+</CodeGroup>++<Tip>+Use AutoRetriever for fast experiments and RAG workflows; for advanced control, use VectorRetriever directly.+</Tip>+</Card>++<Card title="KeywordRetriever (Classic Search)" icon="hashtag">+For simple, blazing-fast search by keyword—use KeywordRetriever.+Great for small data, transparency, or keyword-driven tasks.+*(API and code example coming soon—see RAG Cookbook for details.)*+</Card>++<CardGroup cols={2}>+ <Card+ title="See RAG Agents in Action"+ icon="rocket"+ href="../cookbooks/advanced_features/agents_with_rag.ipynb"+ >+ Build retrieval-augmented agents using these retrievers.+ </Card>+ <Card+ title="Reference API"+ icon="book"+ href="/reference/#retrievers"+ >+ Full configuration and options for all retriever classes.+ </Card>+</CardGroup>-That's it! We've successfully set up and used the Retriever Module to retrieve information based on queries from our data collection.--Feel free to customize the code according to your specific use case and data sources!diff --git a/docs/key_modules/runtimes.md b/docs/key_modules/runtimes.mdindex 55bc2737f..687fae617 100644--- a/docs/key_modules/runtimes.md+++ b/docs/key_modules/runtimes.md@@ -1,148 +1,143 @@-## 1. Concept-The runtime module in CAMEL allows functions and tools to be executed in-controlled environments, enabling the safe and isolated execution of code.-Modern AI systems, especially those involving autonomous agents, often-require more than just a simple Python interpreter. They may need to:--- Execute code with security checks to prevent malicious actions.-- Run tasks in isolated environments to manage dependencies or enhance-security (e.g., using Docker).-- Distribute computational load or access specialized resources by executing-functions on remote servers.-- Utilize sophisticated configuration management for various components.--The `camel.runtime` module addresses these needs by providing a collection of-runtime classes and supporting utilities. Each runtime offers a different-strategy for code or function execution, catering to various use cases within-the CAMEL ecosystem.--## 2. Types-Runtimes offer flexibility, isolation, and scalability by encapsulating-various execution contexts—such as local containers, cloud sandboxes,-remote servers, or guarded environments.-Each runtime implementation provides a standardized interface for adding-tools, executing commands, and managing the execution lifecycle.--### 2.1 The Base Runtime: `BaseRuntime`-All runtimes inherit from the BaseRuntime abstract class, which defines the-following core methods:--- `add(funcs)`: Registers one or more FunctionTool objects for execution--- `reset()`: Resets the runtime environment to its initial state--- `get_tools()`: Returns the list of tools managed by the runtime--### 2.2 `LLMGuardRuntime`-The `LLMGuardRuntime` is a runtime environment designed to evaluate-the potential risks associated with executing functions and tools,-particularly those that might be dynamically called by AI agents-(e.g., tool calls that write codes).-`LLMGuardRuntime` leverages a customizable LLM to-perform this risk assessment.--**Key Features:**-- Risk scores from 1 (safe) to 3 (dangerous)-- Threshold control for execution permission-- Pre-configured system prompt + structured tool for safety--### 2.3 `DockerRuntime`-The `DockerRuntime` provides a mechanism to-execute CAMEL agents or arbitrary tasks-within isolated Docker containers. This approach is highly beneficial-for managing complex dependencies,-ensuring reproducibility of experiments or agent behavior,-and enhancing security by sandboxing execution.--**Key Features**-- FastAPI server for tool exposure-- Automatic container lifecycle management via Python interface--### 2.4 `UbuntuDockerRuntime`-A specialization of `DockerRuntime` optimized for Ubuntu containers.-Adds system package installation, Python version checks,-and support for full script execution.--**Key Features**-- Preconfigures environment variables like `PYTHON_EXECUTABLE` and `PYTHONPATH`-- Supports full `.py` script execution with `exec_python_file()`-- Maintains all capabilities of DockerRuntime.--### 2.5 `RemoteHttpRuntime`-The `RemoteHttpRuntime` facilitates the execution of functions on a separate,-remote HTTP server.--**Key Features**-- Enables remote execution of tools via simple HTTP APIs-- Built on FastAPI for easy integration and rapid deployment- of HTTP-based function execution endpoints--### 2.6 `DaytonaRuntime`-`DaytonaRuntime` uses the official daytona_sdk to create sandboxes and run user-functions inside them securely.-Each tool is uploaded as source code and executed with controlled input/output-handling.--**Key Features**-- Uploads and runs source code remotely-- Cloud-managed runtime with safety guarantees--## 3. Get Started-We'll use `RemoteHttpRuntime` as a quick examples of how to use-`runtime` module.--A runtime can be initialized with the following code. Here we use-`MathToolkit` as an example for our tools. You can use any arbitrary tools as-long as they follow the `FunctionTool` type defined by CAMEL (see [tools](-./tools.md)-module document for more details.)-```-from camel.runtimes import RemoteHttpRuntime-from camel.toolkits import MathToolkit--if __name__ == "__main__":- runtime = (- RemoteHttpRuntime("localhost")- .add(MathToolkit().get_tools(), "camel.toolkits.MathToolkit")- .build()- )-- # It might take sometime for the runtime to start- print("Waiting for runtime to be ready...")- runtime.wait()- print("Runtime is ready.")- # Example Output:- # Waiting for runtime to be ready...- # Runtime is ready.-```---The tools can then be called using the code below,-following the same syntax as normal tool calls without a runtime.--```- # There are more tools imported from MathToolkit.- # For simplicity, we use only "add" tool here- add = runtime.get_tools()[0]- print(f"Add 1 + 2: {add.func(1, 2)}")-- # Example Output:- # Add 1 + 2: 3-```--## 4. More Examples-Additional runtime usage examples can be found under the `examples/runtime/`-directory in our main repository. Each script demonstrates how to initialize-and use a specific runtime in CAMEL. These examples are simple,-self-contained, and can serve as starting points for real use cases.--## 5. Final Note-Currently, the runtime system is mainly designed to sandbox registered tool-functions only. If other parts of your agent involve-risky execution (e.g., direct code generation-and execution), you should consider handling sandboxing logic separately.--**Exception**: UbuntuDockerRuntime supports full Python script execution-through exec_python_file(). This makes it suitable for broader agent-level-sandboxing beyond `FunctionTool`, such as executing dynamically generated code-within a controlled container environment.+---+title: "Runtimes"+description: "Flexible, secure, and scalable code execution with CAMEL’s runtime environments: guardrails, Docker, remote, and cloud sandboxes."+icon: server+---++CAMEL’s **runtime module** enables the secure, flexible, and isolated execution of tools and code. Runtimes allow agents to safely run functions in controlled environments—from in-process security checks to Docker isolation and remote/cloud sandboxes.++## What are Runtimes?++<Note type="info" title="Runtime Concept">+ Modern agent systems often require more than a simple interpreter. <b>Runtimes</b> provide safe, scalable execution via guardrails, isolation, or remote/cloud endpoints—ideal for complex or untrusted code.+</Note>++<div className="grid grid-cols-1 md:grid-cols-2 xl:grid-cols-2 gap-4 my-6">++ <Card icon="shield" title="LLMGuardRuntime">+ <b>Guardrail layer</b> for safe function execution.<br/>+ <ul>+ <li>LLM-based risk scoring (1=safe, 3=unsafe)</li>+ <li>Threshold control for blocking risky calls</li>+ <li>Pre-configured safety system prompt/tool</li>+ </ul>+ </Card>++ <Card icon="docker" title="DockerRuntime / UbuntuDockerRuntime">+ <b>Isolated, reproducible containers</b> via Docker.<br/>+ <ul>+ <li>Sandbox tool execution for safety</li>+ <li>FastAPI server for tool endpoints</li>+ <li>Ubuntu flavor supports .py script execution, env vars, and more</li>+ </ul>+ </Card>++ <Card icon="globe" title="RemoteHttpRuntime">+ <b>Remote, distributed execution</b> on HTTP servers.<br/>+ <ul>+ <li>Tool execution via FastAPI HTTP APIs</li>+ <li>Distribute compute and offload risky code</li>+ <li>Easy integration with remote endpoints</li>+ </ul>+ </Card>++ <Card icon="cloud" title="DaytonaRuntime" className="col-span-1 xl:col-span-3">+ <b>Cloud-managed sandboxing</b> with <a href="https://docs.daytona.io/" target="_blank" rel="noopener">Daytona SDK</a>.<br/>+ <ul>+ <li>Secure remote sandbox per tool</li>+ <li>Upload, run, and manage source code safely</li>+ <li>Automated input/output handling</li>+ </ul>+ </Card>++</div>+++---++## Runtime Interface++All runtimes inherit from <b>BaseRuntime</b>, which defines core methods:+- <code>add(funcs)</code>: Register one or more <code>FunctionTool</code> objects for execution+- <code>reset()</code>: Reset the runtime to its initial state+- <code>get_tools()</code>: List all tools managed by the runtime++---++## Quick Start Example: RemoteHttpRuntime++<Card icon="zap" title="Remote HTTP Runtime Example" className="my-6">+ Easily run tools in a remote FastAPI-based runtime—great for scaling, isolation, and experimentation.+ <br/><br/>+ ```python+ from camel.runtimes import RemoteHttpRuntime+ from camel.toolkits import MathToolkit++ if __name__ == "__main__":+ runtime = (+ RemoteHttpRuntime("localhost")+ .add(MathToolkit().get_tools(), "camel.toolkits.MathToolkit")+ .build()+ )++ print("Waiting for runtime to be ready...")+ runtime.wait()+ print("Runtime is ready.")++ # There are more tools imported from MathToolkit.+ # For simplicity, we use only "add" tool here+ add = runtime.get_tools()[0]+ print(f"Add 1 + 2: {add.func(1, 2)}")+ # Example output:+ # Add 1 + 2: 3+ ```+</Card>++---++## Runtime Types: Key Features++<AccordionGroup>+ <Accordion title="LLMGuardRuntime">+ <ul>+ <li>Evaluates risk before executing functions or tool calls (risk scores 1-3)</li>+ <li>Customizable LLM-driven safety logic</li>+ <li>Blocks or allows function execution based on threshold</li>+ </ul>+ </Accordion>+ <Accordion title="DockerRuntime / UbuntuDockerRuntime">+ <ul>+ <li>Runs CAMEL tools/agents in Docker containers for isolation and reproducibility</li>+ <li>UbuntuDocker flavor adds support for full script execution and system-level configuration</li>+ <li>Preconfigures <code>PYTHON_EXECUTABLE</code>, <code>PYTHONPATH</code>, and more for custom envs</li>+ </ul>+ </Accordion>+ <Accordion title="RemoteHttpRuntime">+ <ul>+ <li>Executes registered tools on a remote FastAPI server via HTTP endpoints</li>+ <li>Ideal for distributed, scalable, or cross-server tool execution</li>+ </ul>+ </Accordion>+ <Accordion title="DaytonaRuntime">+ <ul>+ <li>Runs code in a managed, remote cloud sandbox using Daytona SDK</li>+ <li>Uploads user code, executes with input/output capture</li>+ <li>Safety and resource guarantees from cloud provider</li>+ </ul>+ </Accordion>+</AccordionGroup>++---++## More Examples++You’ll find runnable scripts for each runtime in <b>[examples/runtime](https://github.com/camel-ai/camel/tree/master/examples/runtimes)/</b> in our main repo.+Each script demonstrates how to initialize and use a specific runtime—perfect for experimentation or production setups.++---++## Final Note++The runtime system primarily sandboxes <code>FunctionTool</code>-style tool functions.+For agent-level, dynamic code execution, always consider dedicated sandboxing—such as <b>UbuntuDockerRuntime</b>’s <code>exec_python_file()</code>—for running dynamically generated scripts with maximum isolation and safety.+diff --git a/docs/key_modules/society.md b/docs/key_modules/society.mdindex b48cbf02c..ea01bab8f 100644--- a/docs/key_modules/society.md+++ b/docs/key_modules/society.md@@ -1,80 +1,114 @@-## 1. Concept-The society module is one of the core modules of CAMEL. By simulating the information exchange process, this module studies the social behaviors among agents.--Currently, the society module aims to enable agents to collaborate autonomously toward completing tasks while keeping consistent with human intentions and requiring minimal human intervention. It includes two frameworks: `RolePlaying` and `BabyAGI`, which are used to run the interaction behaviors of agents to achieve objectives.--Taking `RolePlaying` as an example, this framework was designed in an instruction-following manner. These roles independently undertake the responsibilities of executing and planning tasks, respectively. The dialogue is continuously advanced through a turn-taking mechanism, thereby collaborating to complete tasks. The main concepts include:--- Task: a task can be as simple as an idea, initialized by an inception prompt.--- AI User: the agent who is expected to provide instructions.--- AI Assistant: the agent who is expected to respond with solutions that fulfill the instructions.--### 2. Types--## 2.1 `RolePlaying`--`RolePlaying` is a unique cooperative agent framework of CAMEL. Through this framework, agents in CAMEL overcome numerous challenges, such as *role flipping*, *assistant repeats instructions*, *flake replies*, *infinite loop of messages*, and *conversation termination conditions.*--When using `RolePlaying` framework in CAMEL, predefined prompts are used to create unique initial settings for different agents. For example, if the user wants to initialize an assistant agent, the agent will be initialized with the following prompt.--- Never forget you are a `<ASSISTANT_ROLE>` and I am a `<USER_ROLE>`.-- *This assigns the chosen role to the assistant agent and provides it with information about the user’s role.*-- Never flip roles! Never instruct me!-- *This prevents agents from flipping roles. In some cases, we have observed the assistant and the user switching roles, where the assistant suddenly takes control and instructs the user, and the user follows those instructions.*-- You must decline my instruction honestly if you cannot perform the instruction due to physical, moral, legal reasons or your capability and explain the reasons.-- *This prohibits the agent from producing harmful, false, illegal, and misleading information.*-- Unless I say the task is completed, you should always start with: Solution: `<YOUR_SOLUTION>`. `<YOUR_SOLUTION>` should be specific, and provide preferable implementations and examples for task-solving.-- *This encourages the assistant to always responds in a consistent format, avoiding any deviation from the structure of the conversation, and preventing vague or incomplete responses, which we refer to as flake responses, such as "I will do something".*-- Always end your solution with: Next request.-- *This ensures that the assistant keeps the conversation going by requesting a new instruction to solve.*---### `RolePlaying` Attributes--| Attribute | Type | Description |-| --- | --- | --- |-| assistant_role_name | str | The name of the role played by the assistant. |-| user_role_name | str | The name of the role played by the user. |-| critic_role_name | str | The name of the role played by the critic. |-| task_prompt | str | A prompt for the task to be performed. |-| with_task_specify | bool | Whether to use a task specify agent. |-| with_task_planner | bool | Whether to use a task planner agent. |-| with_critic_in_the_loop | bool | Whether to include a critic in the loop. |-| critic_criteria | str | Critic criteria for the critic agent. |-| model | BaseModelBackend | The model backend to use for generating responses. |-| task_type | TaskType | The type of task to perform. |-| assistant_agent_kwargs | Dict | Additional arguments to pass to the assistant agent. |-| user_agent_kwargs | Dict | Additional arguments to pass to the user agent. |-| task_specify_agent_kwargs | Dict | Additional arguments to pass to the task specify agent. |-| task_planner_agent_kwargs | Dict | Additional arguments to pass to the task planner agent. |-| critic_kwargs | Dict | Additional arguments to pass to the critic. |-| sys_msg_generator_kwargs | Dict | Additional arguments to pass to the system message generator. |-| extend_sys_msg_meta_dicts | List[Dict] | A list of dicts to extend the system message meta dicts with. |-| extend_task_specify_meta_dict | Dict | A dict to extend the task specify meta dict with. |-| output_language | str | The language to be output by the agents. |--## 2.2 `BabyAGI`-Babyagi is framework from "Task-driven Autonomous Agent" `https://github.com/yoheinakajima/babyagi`--## 3. Get Started--### 3.1. Using `RolePlaying`--```python+---+title: "Society"+description: "Collaborative agent frameworks in CAMEL: autonomous social behaviors, role-based task solving, and turn-based agent societies."+icon: people-group+---++<Note type="info" title="What is the Society Module?">+ The <b>society module</b> simulates agent social behaviors and collaborative workflows.<br/>+ It powers <b>autonomous, multi-role agents</b> that can plan, debate, critique, and solve tasks together, minimizing human intervention while maximizing alignment with your goals.+</Note>++---++<Card icon="users" title="Society Concepts: How Do AI Agents Interact?" className="my-6">+ <b>Task:</b> An objective or idea, given as a simple prompt.<br/>+ <b>AI User:</b> The role responsible for providing instructions or challenges.<br/>+ <b>AI Assistant:</b> The role tasked with generating solutions, plans, or step-by-step responses.<br/>+ <b>Critic (optional):</b> An agent that reviews or critiques the assistant's responses for quality control.<br/><br/>+ <b>Frameworks:</b>+ <ul>+ <li><code>RolePlaying</code> — Advanced turn-taking, prompt-guarded collaboration (most common for LLM societies).</li>+ <li><code>BabyAGI</code> — Autonomous, open-ended R&D loops for big-picture or research goals.</li>+ </ul>+</Card>++---++## 🤝 Frameworks++<div style={{ display: "flex", gap: "1.5rem", flexWrap: "wrap" }}>+ <Card icon="repeat" title="RolePlaying" style={{ flex: "1 1 320px" }}>+ <b>Turn-based, prompt-engineered, zero-role-flip agent collaboration.</b>+ <ul>+ <li>Guards against role-flipping, infinite loops, vague responses</li>+ <li>Structured, strict turn-taking—user and assistant never switch</li>+ <li>Supports optional task planners, critics, and meta-reasoning</li>+ <li>Every message follows a system-enforced structure</li>+ </ul>+ <div>+ <b>Built-in Prompt Rules:</b>+ <ul style={{ marginBottom: 0 }}>+ <li>Never forget you are <code><ASSISTANT_ROLE></code>, I am <code><USER_ROLE></code></li>+ <li>Never flip roles or instruct me</li>+ <li>Decline impossible or unsafe requests, explain why</li>+ <li>Always answer as: <code>Solution: <YOUR_SOLUTION></code></li>+ <li>Always end with: <code>Next request.</code></li>+ </ul>+ </div>+ </Card>+ <Card icon="flask" title="BabyAGI" style={{ flex: "1 1 320px" }}>+ <b>Task-driven, fully autonomous project agent</b><br/>+ Based on <a href="https://github.com/yoheinakajima/babyagi" target="_blank">BabyAGI</a>, with seamless CAMEL integration.+ <ul>+ <li>Self-driven research, R&D, and iterative problem-solving</li>+ <li>Builds, updates, and executes dynamic task lists</li>+ <li>Minimal initial human input—agents break down and solve tasks</li>+ </ul>+ </Card>+</div>++---++## 🧩 RolePlaying Attributes++<AccordionGroup>+ <Accordion title="All RolePlaying Parameters">+ <table>+ <thead>+ <tr>+ <th>Attribute</th>+ <th>Type</th>+ <th>Description</th>+ </tr>+ </thead>+ <tbody>+ <tr><td>assistant_role_name</td><td>str</td><td>Name of assistant's role</td></tr>+ <tr><td>user_role_name</td><td>str</td><td>Name of user's role</td></tr>+ <tr><td>critic_role_name</td><td>str</td><td>Name of critic's role (optional)</td></tr>+ <tr><td>task_prompt</td><td>str</td><td>Prompt for the main task</td></tr>+ <tr><td>with_task_specify</td><td>bool</td><td>Enable task specification agent</td></tr>+ <tr><td>with_task_planner</td><td>bool</td><td>Enable task planner agent</td></tr>+ <tr><td>with_critic_in_the_loop</td><td>bool</td><td>Include critic in conversation loop</td></tr>+ <tr><td>critic_criteria</td><td>str</td><td>How the critic scores/evaluates outputs</td></tr>+ <tr><td>model</td><td>BaseModelBackend</td><td>Model backend for responses</td></tr>+ <tr><td>task_type</td><td>TaskType</td><td>Type/category of the task</td></tr>+ <tr><td>assistant_agent_kwargs</td><td>Dict</td><td>Extra options for assistant agent</td></tr>+ <tr><td>user_agent_kwargs</td><td>Dict</td><td>Extra options for user agent</td></tr>+ <tr><td>task_specify_agent_kwargs</td><td>Dict</td><td>Extra options for task specify agent</td></tr>+ <tr><td>task_planner_agent_kwargs</td><td>Dict</td><td>Extra options for task planner agent</td></tr>+ <tr><td>critic_kwargs</td><td>Dict</td><td>Extra options for critic agent</td></tr>+ <tr><td>sys_msg_generator_kwargs</td><td>Dict</td><td>Options for system message generator</td></tr>+ <tr><td>extend_sys_msg_meta_dicts</td><td>List[Dict]</td><td>Extra metadata for system messages</td></tr>+ <tr><td>extend_task_specify_meta_dict</td><td>Dict</td><td>Extra metadata for task specification</td></tr>+ <tr><td>output_language</td><td>str</td><td>Target output language</td></tr>+ </tbody>+ </table>+ </Accordion>+</AccordionGroup>++---++<Card icon="zap" title="Get Started: RolePlaying in Action" className="my-6">+ <b>Example: Turn-based multi-agent chat with custom roles and live output colors.</b>+ <br/><br/>+ ~~~pythonfrom colorama import Fore-from camel.societies import RolePlayingfrom camel.utils import print_text_animateddef main(model=None, chat_turn_limit=50) -> None:-# Initial the role-playing session on developing a trading bot task with default model (`GPT_4O_MINI`)+ # Initialize a session for developing a trading bottask_prompt = "Develop a trading bot for the stock market"role_play_session = RolePlaying(assistant_role_name="Python Programmer",@@ -86,28 +120,27 @@ def main(model=None, chat_turn_limit=50) -> None:task_specify_agent_kwargs=dict(model=model),)-# Output initial message with different colors.+ # Print initial system messagesprint(Fore.GREEN- + f"AI Assistant sys message:\n{role_play_session.assistant_sys_msg}\n"+ + f"AI Assistant sys message:\\n{role_play_session.assistant_sys_msg}\\n")print(- Fore.BLUE + f"AI User sys message:\n{role_play_session.user_sys_msg}\n"+ Fore.BLUE + f"AI User sys message:\\n{role_play_session.user_sys_msg}\\n")- print(Fore.YELLOW + f"Original task prompt:\n{task_prompt}\n")+ print(Fore.YELLOW + f"Original task prompt:\\n{task_prompt}\\n")print(Fore.CYAN+ "Specified task prompt:"- + f"\n{role_play_session.specified_task_prompt}\n"+ + f"\\n{role_play_session.specified_task_prompt}\\n")- print(Fore.RED + f"Final task prompt:\n{role_play_session.task_prompt}\n")+ print(Fore.RED + f"Final task prompt:\\n{role_play_session.task_prompt}\\n")n = 0input_msg = role_play_session.init_chat()-# Output response step by step with different colors.-# Keep output until detect the terminate content or reach the loop limit.+ # Turn-based simulationwhile n < chat_turn_limit:n += 1assistant_response, user_response = role_play_session.step(input_msg)@@ -132,11 +165,11 @@ def main(model=None, chat_turn_limit=50) -> None:breakprint_text_animated(- Fore.BLUE + f"AI User:\n\n{user_response.msg.content}\n"+ Fore.BLUE + f"AI User:\\n\\n{user_response.msg.content}\\n")print_text_animated(- Fore.GREEN + "AI Assistant:\n\n"- f"{assistant_response.msg.content}\n"+ Fore.GREEN + "AI Assistant:\\n\\n"+ f"{assistant_response.msg.content}\\n")if "CAMEL_TASK_DONE" in user_response.msg.content:@@ -146,4 +179,38 @@ def main(model=None, chat_turn_limit=50) -> None:if __name__ == "__main__":main()-```+ ~~~+</Card>++---++<Card icon="flask-conical" title="Framework Spotlight: BabyAGI" className="my-6">+ <b>Autonomous project agent—no human in the loop.</b><br/>+ <a href="https://github.com/yoheinakajima/babyagi" target="_blank">Original BabyAGI repo</a>+ <ul>+ <li>Designed for long-horizon, open-ended R&D</li>+ <li>Automatically breaks down, plans, and solves complex tasks</li>+ <li>Integrates with CAMEL's toolkit system for supercharged capabilities</li>+ </ul>+</Card>++---+a\+<AccordionGroup>+ <Accordion title="Tips & Best Practices">+ <ul>+ <li>Use <b>RolePlaying</b> for most multi-agent conversations, with or without a critic.</li>+ <li>Define specific roles and prompt-guardrails for your agents—structure is everything!</li>+ <li>Try <b>BabyAGI</b> when you want open-ended, research-oriented, or autonomous projects.</li>+ <li>Leverage the <code>with_task_specify</code> and <code>with_task_planner</code> options for highly complex tasks.</li>+ <li>Monitor for infinite loops—every agent response should have a clear next step or end.</li>+ </ul>+ </Accordion>+ <Accordion title="More Examples & Advanced Use">+ <ul>+ <li>Check <code>[examples/society/](https://github.com/camel-ai/camel/tree/master/examples/runtimes)</code> in the CAMEL repo for advanced agent society demos.</li>+ <li>Explore <b>critic-in-the-loop</b> setups for higher accuracy and safety.</li>+ <li>Integrate toolkits or external APIs into agent society loops for real-world workflows.</li>+ </ul>+ </Accordion>+</AccordionGroup>diff --git a/docs/key_modules/storages.md b/docs/key_modules/storages.mdindex 71b99ecda..582332054 100644--- a/docs/key_modules/storages.md+++ b/docs/key_modules/storages.md@@ -1,449 +1,424 @@-## 1. Concept-The Storage module is a comprehensive framework designed for handling various types of data storage mechanisms. It is composed of abstract base classes and concrete implementations, catering to both key-value storage and vector storage systems.--## 2. Types--### 2.1 Key Value Storages-**`BaseKeyValueStorage`**:--- Purpose: Serves as the foundational abstract class for creating various key-value storage systems.--- Functionality: Standardizes operations like saving, loading, and clearing data records. It primarily interfaces through Python dictionaries.--- Use Cases: Applicable for JSON file storage, NoSQL databases (like MongoDB and Redis), and in-memory Python dictionaries.--**`InMemoryKeyValueStorage`**:--- Description: A concrete implementation of `BaseKeyValueStorage`, utilizing in-memory lists.--- Feature: Ideal for temporary storage as data is volatile and lost when the program terminates.--- Functionality: Implements methods for saving, loading, and clearing records in memory.--**`JsonStorage`**:--- Description: Another concrete implementation of `BaseKeyValueStorage`, focusing on JSON file storage.--- Feature: Ensures persistent storage of records in a human-readable format. Supports customization through a custom JSON encoder for specific enumerated types.--- Functionality: Includes methods for saving data in JSON format, loading, and clearing data.--### 2.2 VectorDB Storages-**`BaseVectorStorage`**:--- Purpose: An abstract base class designed to be extended for specific vector storage implementations.--- Features: Supports various operations like adding, deleting vectors, querying similar vectors, and maintaining the status of the vector database.--- Functionality: Offers flexibility in specifying vector dimensions, collection names, distance metrics, and more.--**`MilvusStorage`**:--- Description: A concrete implementation of `BaseVectorStorage`, tailored for interacting with Milvus, a cloud-native vector search engine.--Reference: [Milvus](https://milvus.io/docs/overview.md/)--**`TiDBStorage`**:--- Description: A concrete implementation of `BaseVectorStorage`, tailored for interacting with TiDB, one database for all your AI ambitions: vector embeddings, knowledge graphs, and operational data.--Reference: [TiDB](https://ai.pingcap.com/)--**`QdrantStorage`**:--- Description: A concrete implementation of `BaseVectorStorage`, tailored for interacting with Qdrant, a vector search engine.--Reference: [Qdrant](https://qdrant.tech/)---**`OceanBaseStorage`**:--- Description: A concrete implementation of `BaseVectorStorage`, tailored for interacting with OceanBase vector engine.--Reference: [OceanBase](https://www.oceanbase.com/)--**`WeaviateStorage`**:--- Description: A concrete implementation of `BaseVectorStorage`, tailored for interacting with Weaviate, a vector search engine.--Reference: [Weaviate](https://weaviate.io/)---### 2.3 Graph Storages-**`BaseGraphStorage`**:--- Purpose: An abstract base class designed to be extended for specific graph storage implementations.--- Features: Supports various operations like `get_client`, `get_schema`, `get_structured_schema`, `refresh_schema`, `add_triplet`, `delete_triplet`, and `query`.--**`NebulaGraph`**:--- Description: A concrete implementation of `BaseGraphStorage`, tailored for interacting with NebulaGraph, an open source, distributed, scalable, lightning fast graph database.--Reference: [NebulaGraph](https://www.nebula-graph.io/)--**`Neo4jGraph`**:--- Description: A concrete implementation of `BaseGraphStorage`, tailored for interacting with Neo4jGraph, one of the most trusted graph database.--Reference: [Neo4jGraph](https://neo4j.com/)--## 3. Get Started--To get started with the storage module you've provided, you'll need to understand the basic usage of the key classes and their methods. The module includes an abstract base class `BaseKeyValueStorage` and its concrete implementations `InMemoryKeyValueStorage` and `JsonStorage`, as well as a vector storage system through `BaseVectorStorage` and its implementation `MilvusStorage` or `QdrantStorage`.--### 3.1. Using `InMemoryKeyValueStorage`--```python-from camel.storages.key_value_storages import InMemoryKeyValueStorage--# Create an instance of InMemoryKeyValueStorage-memory_storage = InMemoryKeyValueStorage()--# Save records-memory_storage.save([{'key1': 'value1'}, {'key2': 'value2'}])--# Load records-records = memory_storage.load()-print(records)--# Clear all records-memory_storage.clear()-```-```markdown->>> [{'key1': 'value1'}, {'key2': 'value2'}]-```--### 3.2. Using `JsonStorage`--```python-from camel.storages.key_value_storages import JsonStorage-from pathlib import Path--# Create an instance of JsonStorage with a specific file path-json_storage = JsonStorage(Path("my_data.json"))--# Save records-json_storage.save([{'key1': 'value1'}, {'key2': 'value2'}])--# Load records-records = json_storage.load()-print(records)--# Clear all records-json_storage.clear()-```-```markdown->>> [{'key1': 'value1'}, {'key2': 'value2'}]-```--### 3.3. Using `MilvusStorage`--```python-from camel.storages import MilvusStorage, VectorDBQuery, VectorRecord--# Create an instance of MilvusStorage with dimension = 4-milvus_storage = MilvusStorage(- url_and_api_key=("Your Milvus URI","Your Milvus Token"),- vector_dim=4,- collection_name="my_collection")--# Add two vector records-milvus_storage.add([VectorRecord(- vector=[-0.1, 0.1, -0.1, 0.1],- payload={'key1': 'value1'},- ),- VectorRecord(- vector=[-0.1, 0.1, 0.1, 0.1],- payload={'key2': 'value2'},- ),])--# Load the remote collection-milvus_storage.load()--# Query similar vectors-query_results = milvus_storage.query(VectorDBQuery(query_vector=[0.1, 0.2, 0.1, 0.1], top_k=1))-for result in query_results:- print(result.record.payload, result.similarity)--# Clear all vectors-milvus_storage.clear()-```-```markdown->>> {'key2': 'value2'} 0.5669466853141785-```--### 3.4. Using `TiDBStorage`--If you use TiDB Serverless, you can redirect to [TiDB Cloud Web Console](https://tidbcloud.com/console/clusters) to get the database URL. (Select Connect with "SQLAlchemy" > "PyMySQL" on the connection panel)--```python-import os-from camel.storages import TiDBStorage, VectorDBQuery, VectorRecord--os.environ["TIDB_DATABASE_URL"] = "The database url of your TiDB cluster."--# Create an instance of TiDBStorage with dimension = 4-tidb_storage = TiDBStorage(- url_and_api_key=(os.getenv("DATABASE_URL"), ''),- vector_dim=4,- collection_name="my_collection"-)--# Add two vector records-tidb_storage.add([- VectorRecord(- vector=[-0.1, 0.1, -0.1, 0.1],- payload={'key1': 'value1'},- ),- VectorRecord(- vector=[-0.1, 0.1, 0.1, 0.1],- payload={'key2': 'value2'},- ),-])--# Load the remote collection-tidb_storage.load()--# Query similar vectors-query_results = tidb_storage.query(VectorDBQuery(query_vector=[0.1, 0.2, 0.1, 0.1], top_k=1))-for result in query_results:- print(result.record.payload, result.similarity)--# Clear all vectors-tidb_storage.clear()-```-```markdown->>> {'key2': 'value2'} 0.5669466755703252-```--### 3.5. Using `QdrantStorage`--```python-from camel.storages import QdrantStorage, VectorDBQuery, VectorRecord--# Create an instance of QdrantStorage with dimension = 4-qdrant_storage = QdrantStorage(vector_dim=4, collection_name="my_collection")--# Add two vector records-qdrant_storage.add([VectorRecord(- vector=[-0.1, 0.1, -0.1, 0.1],- payload={'key1': 'value1'},- ),- VectorRecord(- vector=[-0.1, 0.1, 0.1, 0.1],- payload={'key2': 'value2'},- ),])--# Query similar vectors-query_results = qdrant_storage.query(VectorDBQuery(query_vector=[0.1, 0.2, 0.1, 0.1], top_k=1))-for result in query_results:- print(result.record.payload, result.similarity)--# Clear all vectors-qdrant_storage.clear()-```-```markdown->>> {'key2': 'value2'} 0.5669467095138407-```-### 3.6. Using `OceanBaseStorage`--```python-import random--from camel.storages.vectordb_storages import (- OceanBaseStorage,- VectorDBQuery,- VectorRecord,-)--"""-Before running this example, you need to setup an OceanBase instance:-(Option 1): OceanBase Community Edition (OCE):-1. Download and install OCE from the official website:- https://www.oceanbase.com/docs/oceanbase-database-2. Start the OceanBase server and create a database user-3. Install PyOBVector package:- pip install pyobvector-(Option 2): OceanBase Cloud Service:-1. Sign up for OceanBase Cloud Service-2. Create a cluster with OceanBase Vector enabled-3. Get your connection parameters from the service console-The connection parameters should include:-- URI: hostname:port-- User: username@tenant-- Password: your_password-- Database name: database_name-"""--# Replace these with your OceanBase connection parameters-OB_URI = "127.0.0.1:2881"-OB_USER = "root@sys"-OB_PASSWORD = ""-OB_DB_NAME = "oceanbase"---def main():- # Create an instance of OceanBaseStorage with dimension = 64- ob_storage = OceanBaseStorage(- vector_dim=4,- table_name="my_ob_vector_table",- uri=OB_URI,- user=OB_USER,- password=OB_PASSWORD,- db_name=OB_DB_NAME,- distance="cosine",- )-- # Get database status- status = ob_storage.status()- print(f"Vector dimension: {status.vector_dim}")- print(f"Initial vector count: {status.vector_count}")-- # Generate and add a larger number of vectors using batching- print("\nAdding vectors in batches...")- random.seed(20241023)-- # Create a large batch of vector records- large_batch = []- for i in range(1000):- large_batch.append(- VectorRecord(- vector=[random.uniform(-1, 1) for _ in range(4)],- payload={'idx': i, 'batch': 'example'},- )- )-- # Add vectors with automatic batching (batch_size=100)- ob_storage.add(large_batch, batch_size=100)-- # Check updated status- status = ob_storage.status()- print(f"Vector count after adding batch: {status.vector_count}")-- # Generate a query vector and search for similar vectors- print("\nQuerying similar vectors...")- query_vector = [random.uniform(-1, 1) for _ in range(4)]- query_results = ob_storage.query(- VectorDBQuery(query_vector=query_vector, top_k=5)- )-- # Display results- for i, result in enumerate(query_results):- print(f"Result {i+1}:")- print(f" ID: {result.record.id}")- print(f" Payload: {result.record.payload}")- print(f" Similarity: {result.similarity}")-- # Clear all vectors when done- print("\nClearing vectors...")- ob_storage.clear()- status = ob_storage.status()- print(f"Vector count after clearing: {status.vector_count}")---if __name__ == "__main__":- main()--```-```markdown-'''-===============================================================================-Vector dimension: 4-Initial vector count: 0-Adding vectors in batches...-Vector count after adding batch: 1000-Querying similar vectors...-Result 1:- ID: f33f008d-688a-468a-9a2d-e005d27ad9d9- Payload: {'idx': 496, 'batch': 'example'}- Similarity: 0.9847431876706196-Result 2:- ID: 0946ca4a-9129-4343-b339-b2f13a64c827- Payload: {'idx': 306, 'batch': 'example'}- Similarity: 0.9598140307734809-Result 3:- ID: e2505cc3-7bee-433e-a723-c830b9404f61- Payload: {'idx': 654, 'batch': 'example'}- Similarity: 0.9548076959468635-Result 4:- ID: 8d6359ff-49fd-4fb7-99fd-bf4ca0a0cdcx- Payload: {'idx': 914, 'batch': 'example'}- Similarity: 0.9496165658207311-Result 5:- ID: 45cef390-3e1f-4e16-8375-b4108951a93b- Payload: {'idx': 806, 'batch': 'example'}- Similarity: 0.9485824622759768-Clearing vectors...-Vector count after clearing: 0-===============================================================================-'''--```--### 3.7. Using `WeaviateStorage`--```python-from camel.storages import WeaviateStorage, VectorDBQuery, VectorRecord--# Create WeaviateStorage instance with dimension = 4 using Weaviate Cloud-weaviate_storage = WeaviateStorage(- vector_dim=4,- collection_name="camel_example_vectors",- connection_type="cloud",- wcd_cluster_url="your-weaviate-cloud-url",- wcd_api_key="your-weaviate-api-key",- vector_index_type="hnsw",- distance_metric="cosine",-)--# Add vectors records to Weaviate-weaviate_storage.add([- VectorRecord(- vector=[-0.1, 0.1, -0.1, 0.1],- payload={'key1': 'value1'},- ),- VectorRecord(- vector=[-0.1, 0.1, 0.1, 0.1],- payload={'key2': 'value2'},- ),-])--# Query Weaviate for similar vectors-query_results = weaviate_storage.query(VectorDBQuery(query_vector=[0.1, 0.2, 0.1, 0.1], top_k=1))-for result in query_results:- print(result.record.payload, result.similarity)--# Clear all vectors-weaviate_storage.clear()-```-```markdown->>> {'key2': 'value2'} 0.7834733128547668-```--### 3.8. Using `NebulaGraph`--```python-from camel.storages.graph_storages import NebulaGraph--nebula_graph = NebulaGraph("your_host", "your_username", "your_password", "your_space")--# Show existing tags-query = 'SHOW TAGS;'-print(nebula_graph.query(query))-```--### 3.9. Using `Neo4jGraph`--```python-from camel.storages import Neo4jGraph--neo4j_graph = Neo4jGraph(- url="your_url",- username="your_username",- password="your_password",-)--query = "MATCH (n) DETACH DELETE n"-print(neo4j_graph.query(query))-```\ No newline at end of file+---+title: "Storages"+icon: database+---++## What Are Storages in CAMEL-AI?++<Card icon="database">+The <b>Storage</b> module in CAMEL-AI gives you a **unified interface for saving, searching, and managing your data** from simple key-value records to high-performance vector databases and modern graph engines. It’s your plug-and-play toolkit for building robust, AI-ready storage layers.+</Card>++---+## Types of Storages++<AccordionGroup>++ <Accordion title="Key-Value Storages" icon="database">+ **BaseKeyValueStorage**+ - Abstract base for all key-value storage backends.+ - **Standardizes:** Save, load, clear operations.+ - **Interface:** Python dicts.+ - **Use cases:**+ - JSON file storage+ - NoSQL (MongoDB, Redis)+ - In-memory caches++ **InMemoryKeyValueStorage**+ - Fast, simple, *not persistent* (resets on restart)+ - Ideal for caching, development, or quick prototyping++ **JsonStorage**+ - Human-readable, portable JSON file storage+ - Supports custom JSON encoder (for Enums, etc)+ - Good for configs, small persistent datasets, export/import flows+ </Accordion>++ <Accordion title="VectorDB Storages" icon="file-vector">+ **BaseVectorStorage**+ - Abstract base for vector database backends+ - **Core operations:** Add/query/delete vectors, check DB status+ - **Customizable:** Vector dimensions, collections, distance metrics++ **MilvusStorage**+ - For [Milvus](https://milvus.io/docs/overview.md/) (cloud-native vector search engine)+ - High scalability, real-time search++ **TiDBStorage**+ - For [TiDB](https://ai.pingcap.com/) (hybrid vector/relational database)+ - Handles embeddings, knowledge graphs, ops data++ **QdrantStorage**+ - For [Qdrant](https://qdrant.tech/) (open-source vector DB)+ - Fast similarity search for AI/ML++ **OceanBaseStorage**+ - For [OceanBase](https://www.oceanbase.com/) (cloud and on-prem vector DB)+ - Supports large-scale, distributed deployments++ **WeaviateStorage**+ - For [Weaviate](https://weaviate.io/) (open-source vector engine)+ - Schema-based, semantic search, hybrid queries+ </Accordion>++ <Accordion title="Graph Storages" icon="chart-waterfall">+ **BaseGraphStorage**+ - Abstract base for graph database integrations+ - **Supports:**+ - Schema queries and refresh+ - Adding/deleting/querying triplets++ **NebulaGraph**+ - For [NebulaGraph](https://www.nebula-graph.io/) (distributed, high-performance graph DB)+ - Scalable, open source++ **Neo4jGraph**+ - For [Neo4jGraph](https://neo4j.com/) (most popular enterprise graph DB)+ - Widely used for graph analytics, recommendations+ </Accordion>++</AccordionGroup>+++## Get Started++Here are practical usage patterns for each storage type—pick the ones you need and mix them as you like.++---++<Card title="In-Memory Key-Value Storage" icon="key">+ <b>Use for:</b> Fast, temporary storage. Data is lost when your program exits.+ <b>Perfect for:</b> Prototyping, testing, in-memory caching.++ <Tabs>+ <Tab title="Python Example">+ ```python+ from camel.storages.key_value_storages import InMemoryKeyValueStorage++ memory_storage = InMemoryKeyValueStorage()+ memory_storage.save([{'key1': 'value1'}, {'key2': 'value2'}])+ records = memory_storage.load()+ print(records)+ memory_storage.clear()+ ```+ </Tab>+ <Tab title="Output">+ ```markdown+ >>> [{'key1': 'value1'}, {'key2': 'value2'}]+ ```+ </Tab>+ </Tabs>+</Card>++---++<Card title="JSON File Storage" icon="files">+ <b>Use for:</b> Persistent, human-readable storage on disk.+ <b>Perfect for:</b> Logs, local settings, configs, or sharing small data sets.++ <Tabs>+ <Tab title="Python Example">+ ```python+ from camel.storages.key_value_storages import JsonStorage+ from pathlib import Path++ json_storage = JsonStorage(Path("my_data.json"))+ json_storage.save([{'key1': 'value1'}, {'key2': 'value2'}])+ records = json_storage.load()+ print(records)+ json_storage.clear()+ ```+ </Tab>+ <Tab title="Output">+ ```markdown+ >>> [{'key1': 'value1'}, {'key2': 'value2'}]+ ```+ </Tab>+ </Tabs>+</Card>++---++<Card title="Milvus Vector Storage" icon="database">+ <b>Use for:</b> Scalable, high-performance vector search (RAG, embeddings).+ <b>Perfect for:</b> Semantic search and production AI retrieval.++ <Tabs>+ <Tab title="Python Example">+ ```python+ from camel.storages import MilvusStorage, VectorDBQuery, VectorRecord++ milvus_storage = MilvusStorage(+ url_and_api_key=("Your Milvus URI","Your Milvus Token"),+ vector_dim=4,+ collection_name="my_collection"+ )+ milvus_storage.add([+ VectorRecord(vector=[-0.1, 0.1, -0.1, 0.1], payload={'key1': 'value1'}),+ VectorRecord(vector=[-0.1, 0.1, 0.1, 0.1], payload={'key2': 'value2'}),+ ])+ milvus_storage.load()+ query_results = milvus_storage.query(VectorDBQuery(query_vector=[0.1, 0.2, 0.1, 0.1], top_k=1))+ for result in query_results:+ print(result.record.payload, result.similarity)+ milvus_storage.clear()+ ```+ </Tab>+ <Tab title="Output">+ ```markdown+ >>> {'key2': 'value2'} 0.5669466853141785+ ```+ </Tab>+ </Tabs>+</Card>++---++<Card title="TiDB Vector Storage" icon="vector-square">+ <b>Use for:</b> Hybrid cloud-native storage, vectors + SQL in one.+ <b>Perfect for:</b> Combining AI retrieval with your business database.++ <Tabs>+ <Tab title="Python Example">+ ```python+ import os+ from camel.storages import TiDBStorage, VectorDBQuery, VectorRecord++ os.environ["TIDB_DATABASE_URL"] = "The database url of your TiDB cluster."+ tidb_storage = TiDBStorage(+ url_and_api_key=(os.getenv("DATABASE_URL"), ''),+ vector_dim=4,+ collection_name="my_collection"+ )+ tidb_storage.add([+ VectorRecord(vector=[-0.1, 0.1, -0.1, 0.1], payload={'key1': 'value1'}),+ VectorRecord(vector=[-0.1, 0.1, 0.1, 0.1], payload={'key2': 'value2'}),+ ])+ tidb_storage.load()+ query_results = tidb_storage.query(VectorDBQuery(query_vector=[0.1, 0.2, 0.1, 0.1], top_k=1))+ for result in query_results:+ print(result.record.payload, result.similarity)+ tidb_storage.clear()+ ```+ </Tab>+ <Tab title="Output">+ ```markdown+ >>> {'key2': 'value2'} 0.5669466755703252+ ```+ </Tab>+ </Tabs>+</Card>+++<Card title="Qdrant Vector Storage" icon="square-q">+ <b>Use for:</b> Fast, scalable open-source vector search.+ <b>Perfect for:</b> RAG, document search, and high-scale retrieval tasks.++ <Tabs>+ <Tab title="Python Example">+ ```python+ from camel.storages import QdrantStorage, VectorDBQuery, VectorRecord++ # Create an instance of QdrantStorage with dimension = 4+ qdrant_storage = QdrantStorage(vector_dim=4, collection_name="my_collection")++ # Add two vector records+ qdrant_storage.add([+ VectorRecord(vector=[-0.1, 0.1, -0.1, 0.1], payload={'key1': 'value1'}),+ VectorRecord(vector=[-0.1, 0.1, 0.1, 0.1], payload={'key2': 'value2'}),+ ])++ # Query similar vectors+ query_results = qdrant_storage.query(VectorDBQuery(query_vector=[0.1, 0.2, 0.1, 0.1], top_k=1))+ for result in query_results:+ print(result.record.payload, result.similarity)++ # Clear all vectors+ qdrant_storage.clear()+ ```+ </Tab>+ <Tab title="Output">+ ```markdown+ >>> {'key2': 'value2'} 0.5669467095138407+ ```+ </Tab>+ </Tabs>+</Card>++---++<Card title="OceanBase Vector Storage" icon="earth-oceania">+ <b>Use for:</b> Massive vector storage with advanced analytics.+ <b>Perfect for:</b> Batch operations, cloud or on-prem setups, and high-throughput search.++ <Tabs>+ <Tab title="Python Example">+ ```python+ import random++ from camel.storages.vectordb_storages import (+ OceanBaseStorage,+ VectorDBQuery,+ VectorRecord,+ )++ # Replace these with your OceanBase connection parameters+ OB_URI = "127.0.0.1:2881"+ OB_USER = "root@sys"+ OB_PASSWORD = ""+ OB_DB_NAME = "oceanbase"++ def main():+ ob_storage = OceanBaseStorage(+ vector_dim=4,+ table_name="my_ob_vector_table",+ uri=OB_URI,+ user=OB_USER,+ password=OB_PASSWORD,+ db_name=OB_DB_NAME,+ distance="cosine",+ )++ status = ob_storage.status()+ print(f"Vector dimension: {status.vector_dim}")+ print(f"Initial vector count: {status.vector_count}")++ random.seed(20241023)+ large_batch = []+ for i in range(1000):+ large_batch.append(+ VectorRecord(+ vector=[random.uniform(-1, 1) for _ in range(4)],+ payload={'idx': i, 'batch': 'example'},+ )+ )+ ob_storage.add(large_batch, batch_size=100)+ status = ob_storage.status()+ print(f"Vector count after adding batch: {status.vector_count}")++ query_vector = [random.uniform(-1, 1) for _ in range(4)]+ query_results = ob_storage.query(+ VectorDBQuery(query_vector=query_vector, top_k=5)+ )+ for i, result in enumerate(query_results):+ print(f"Result {i+1}:")+ print(f" ID: {result.record.id}")+ print(f" Payload: {result.record.payload}")+ print(f" Similarity: {result.similarity}")++ ob_storage.clear()+ status = ob_storage.status()+ print(f"Vector count after clearing: {status.vector_count}")++ if __name__ == "__main__":+ main()+ ```+ </Tab>+ <Tab title="Output">+ ```markdown+ '''+ ===============================================================================+ Vector dimension: 4+ Initial vector count: 0+ Adding vectors in batches...+ Vector count after adding batch: 1000+ Querying similar vectors...+ Result 1:+ ID: f33f008d-688a-468a-9a2d-e005d27ad9d9+ Payload: {'idx': 496, 'batch': 'example'}+ Similarity: 0.9847431876706196+ Result 2:+ ID: 0946ca4a-9129-4343-b339-b2f13a64c827+ Payload: {'idx': 306, 'batch': 'example'}+ Similarity: 0.9598140307734809+ ...+ Clearing vectors...+ Vector count after clearing: 0+ ===============================================================================+ '''+ ```+ </Tab>+ </Tabs>+</Card>++---++<Card title="Weaviate Vector Storage" icon="file-vector">+ <b>Use for:</b> Vector search with hybrid (vector + keyword) capabilities.+ <b>Perfect for:</b> Document retrieval and multimodal AI apps.++ <Tabs>+ <Tab title="Python Example">+ ```python+ from camel.storages import WeaviateStorage, VectorDBQuery, VectorRecord++ # Create WeaviateStorage instance with dimension = 4 using Weaviate Cloud+ weaviate_storage = WeaviateStorage(+ vector_dim=4,+ collection_name="camel_example_vectors",+ connection_type="cloud",+ wcd_cluster_url="your-weaviate-cloud-url",+ wcd_api_key="your-weaviate-api-key",+ vector_index_type="hnsw",+ distance_metric="cosine",+ )++ weaviate_storage.add([+ VectorRecord(vector=[-0.1, 0.1, -0.1, 0.1], payload={'key1': 'value1'}),+ VectorRecord(vector=[-0.1, 0.1, 0.1, 0.1], payload={'key2': 'value2'}),+ ])++ query_results = weaviate_storage.query(VectorDBQuery(query_vector=[0.1, 0.2, 0.1, 0.1], top_k=1))+ for result in query_results:+ print(result.record.payload, result.similarity)++ weaviate_storage.clear()+ ```+ </Tab>+ <Tab title="Output">+ ```markdown+ >>> {'key2': 'value2'} 0.7834733128547668+ ```+ </Tab>+ </Tabs>+</Card>++---++<Card title="NebulaGraph Storage" icon="hard-drive">+ <b>Use for:</b> Open-source, distributed graph storage and querying.+ <b>Perfect for:</b> Knowledge graphs, relationships, and fast distributed queries.++ <CodeGroup>+ ```python+ from camel.storages.graph_storages import NebulaGraph++ nebula_graph = NebulaGraph("your_host", "your_username", "your_password", "your_space")++ # Show existing tags+ query = 'SHOW TAGS;'+ print(nebula_graph.query(query))+ ```+ </CodeGroup>+</Card>++---++<Card title="Neo4j Graph Storage" icon="square-this-way-up">+ <b>Use for:</b> Industry-standard graph database for large-scale relationships.+ <b>Perfect for:</b> Enterprise graph workloads, Cypher queries, analytics.+<CodeGroup>+ ```python+ from camel.storages import Neo4jGraph++ neo4j_graph = Neo4jGraph(+ url="your_url",+ username="your_username",+ password="your_password",+ )++ query = "MATCH (n) DETACH DELETE n"+ print(neo4j_graph.query(query))+ ```+ </CodeGroup>+</Card>diff --git a/docs/key_modules/tasks.md b/docs/key_modules/tasks.mdindex cb4b5afb9..a1269632e 100644--- a/docs/key_modules/tasks.md+++ b/docs/key_modules/tasks.md@@ -1,23 +1,30 @@+---+title: "Tasks"+icon: list-check+---+For more detailed usage information, please refer to our cookbook: [Task Generation Cookbook](../cookbooks/multi_agent_society/task_generation.ipynb)-## 1. Concept-> In the CAMEL framework, a task is a specific assignment that can be delegated to an agent and resolved by that agent. Tasks represent a higher-level concept than prompts and should be managed by other modules such as the Planner and Workforce. There are two key characteristics of a task:-> 1. A task can be collaborative, requiring multiple agents to work together.-> 2. A task can be decomposed and evolved.+<Card title="What is a Task in CAMEL?" icon="clipboard-list">+A <b>task</b> in CAMEL is a structured assignment that can be given to one or more agents. Tasks are higher-level than prompts and managed by modules like the Planner and Workforce.+<b>Key ideas:</b><br/>+- Tasks can be <b>collaborative</b>, requiring multiple agents.<br/>+- Tasks can be <b>decomposed</b> into subtasks or evolved over time.<br/>+</Card>-### 1.1 Task Attributes+## Task Attributes| Attribute | Type | Description || ----- | ----- | ----- || content | string | A clear and concise description of the task at hand. |-| id | string | An unique string identifier for the task. |-| state | Enum | The task states: "OPEN", "RUNNING", "DONE", "FAILED", "DELETED". |+| id | string | A unique string identifier for the task. |+| state | Enum | The task states: "OPEN", "RUNNING", "DONE", "FAILED", "DELETED". || type | string | The type of a task. (TODO) || parent | Task | The parent task. |-| subtasks | A list of Task | A list of sub tasks related the original Task. |+| subtasks | A list of Task | Subtasks related to the original Task. || result | string | The Task result. |-### 1.2 Task Methods+## Task Methods| Method | Type | Description || ----- | ----- | ----- |@@ -27,22 +34,20 @@ For more detailed usage information, please refer to our cookbook: [Task Generat| update_result | instance | Set task result and mark the task as DONE. || set_id | instance | Set task id. || set_state | instance | Recursively set the state of the task and its subtasks. |-| add_subtask | instance | Add child task. |-| remove_subtask | instance | Delete a subtask by a giving id. |+| add_subtask | instance | Add a child task. |+| remove_subtask | instance | Delete a subtask by id. || get_running_task | instance | Get a RUNNING task. || to_string | instance | Convert task to a string. |-| get_result | instance | Get task result to a string. |-| decompose | instance | Decompose a task to a list of sub-tasks. |-| compose | instance | Compose task result by the sub-tasks. |-| get_depth | instance | Get task depth while the root depth is 1. |--## 2. Get Started+| get_result | instance | Get task result as a string. |+| decompose | instance | Decompose a task to a list of subtasks. |+| compose | instance | Compose task result by subtasks. |+| get_depth | instance | Get task depth; root depth is 1. |-Creating a task involves defining its goal (content) and id:+<Card title="Getting Started: Creating Tasks" icon="bolt">+Defining a task is simple: specify its content and a unique ID.-### 2.1 Example of Task definition--```python+<CodeGroup>+```python task_example.pyfrom camel.tasks import Tasktask = Task(@@ -50,10 +55,14 @@ task = Task(id="0",)```+</CodeGroup>+</Card>-### 2.2 Example of multiple Tasks with a hierarchical structure.+<Card title="Hierarchical Tasks Example" icon="sitemap">+You can build nested, hierarchical tasks using subtasks. Here’s an example:-```python+<CodeGroup>+```python tasks_hierarchical.py# Creating the root taskroot_task = Task(content="Prepare a meal", id="0")@@ -77,8 +86,7 @@ sub_task_2.add_subtask(sub_task_2_2)# Printing the hierarchical task structureprint(root_task.to_string())```--```markdown+```markdown output>>>Task 0: Prepare a mealTask 1: Shop for ingredients@@ -87,12 +95,15 @@ print(root_task.to_string())Task 2.2: Cook riceTask 3: Set the table```+</CodeGroup>+</Card>-## 3. Decomposing and composing a Task+## Decomposing and Composing a Task-Decomposing or composing a task involves defining its responsible agent, prompt template and agent response parser. Here is an example:+You can break down (decompose) a task into smaller subtasks, or compose the results from subtasks. Typically, you define an agent, prompt template, and response parser.-```python+<CodeGroup>+```python task_decompose.pyfrom camel.agents import ChatAgentfrom camel.tasks import Taskfrom camel.tasks.task_prompt import (@@ -112,72 +123,71 @@ task = Task(id="0",)-new_tasks = task.decompose(agent=agent)for t in new_tasks:print(t.to_string())```--```markdown+```markdown output>>>Task 0.0: Convert 51 minutes into hours.-Task 0.1: Calculate Weng's earnings for the converted hours at the rate of $12 per hour.-Task 0.2: Provide the final earnings amount based on the calculation.```+</CodeGroup>-```python-# compose task result by the sub-tasks.+<CodeGroup>+```python task_compose.py+# Compose task result by the sub-tasks.task.compose(agent=agent, template=TASK_COMPOSE_PROMPT)print(task.result)```+</CodeGroup>-## 4. TaskManager+## TaskManager-TaskManager is used to manage tasks.+<Card title="TaskManager Overview" icon="list-check">+The <b>TaskManager</b> class helps you manage, sort, and evolve tasks—handling dependencies and progression automatically.+</Card>| Method | Type | Description || ----- | ----- | ----- || topological_sort | instance | Sort a list of tasks topologically. |-| set_tasks_dependence | instance | Set relationship between root task and other tasks. Two relationships are currently supported: serial and parallel. |-| evolve | instance | Evolve a task to a new task and here it is only used for data generation. |+| set_tasks_dependence | instance | Set relationship between root task and other tasks (serial or parallel). |+| evolve | instance | Evolve a task to a new task; used for data generation. |--### Example--```python+<CodeGroup>+```python task_manager_example.pyfrom camel.tasks import (Task,TaskManager,)+from camel.agents import ChatAgentsys_msg = "You're a helpful assistant"--# Set up an agentagent = ChatAgent(system_message=sys_msg)-task = Task(content="Weng earns $12 an hour for babysitting. Yesterday, she just did 51 minutes of babysitting. How much did she earn?",id="0",)print(task.to_string())```--```markdown+```markdown output>>>Task 0: Weng earns $12 an hour for babysitting. Yesterday, she just did 51 minutes of babysitting. How much did she earn?```+</CodeGroup>-```python+<CodeGroup>+```python task_manager_evolve.pytask_manager = TaskManager(task)evolved_task = task_manager.evolve(task, agent=agent)print(evolved_task.to_string())```--```markdown+```markdown output>>>Task 0.0: Weng earns $12 an hour for babysitting. Yesterday, she babysat for 1 hour and 45 minutes. If she also received a $5 bonus for exceptional service, how much did she earn in total for that day?```+</CodeGroup>-## 5. Conclusion-We offers a structured approach to task management, enabling efficient delegation and resolution of tasks by agents. With features such as task decomposition, composition, and hierarchical task structures, CAMEL provides the tools necessary to manage complex workflows. Whether handling simple tasks or intricate, multi-level assignments, CAMEL's task management capabilities ensure that tasks are executed effectively and collaboratively, enhancing overall productivity.\ No newline at end of file+<Card title="Conclusion" icon="trophy">+CAMEL offers a powerful, structured approach to task management. With support for task decomposition, composition, and deep hierarchies, you can automate everything from simple workflows to complex, multi-agent projects. Efficient, collaborative, and easy to integrate—this is next-level task orchestration for AI.+</Card>diff --git a/docs/key_modules/tools.md b/docs/key_modules/tools.mdindex 5b5126f29..752051737 100644--- a/docs/key_modules/tools.md+++ b/docs/key_modules/tools.md@@ -1,147 +1,97 @@+---+title: "Tools"+icon: screwdriver-wrench+---+For more detailed usage information, please refer to our cookbook: [Tools Cookbook](../cookbooks/advanced_features/agents_with_tools.ipynb)-## 1. Concept-Tools serve as interfaces that allow LLMs and Agents to interact with the world. A tool is essentially a function that has a name, a description, input parameters, and an output type. In this section, we will introduce the tools currently supported by CAMEL and explain how to define your own tools and Toolkits.+<Card title="What is a Tool?" icon="toolbox">+ A <b>Tool</b> in CAMEL is a callable function with a name, description, input parameters, and an output type.+ Tools act as the interface between agents and the outside world—think of them like <b>OpenAI Functions</b> you can easily convert, extend, or use directly.+</Card>-**Tools:** Tools are akin to OpenAI Functions and can be easily converted to that format. In CAMEL, we offer a variety of commonly used tools that you can utilize directly. While built-in tools can be quite useful, it's highly likely that you'll need to define your own tools. This guide for detailed instructions on how to create custom tools.+<Card title="What is a Toolkit?" icon="screwdriver-wrench">+ A <b>Toolkit</b> is a curated collection of related tools designed to work together for a specific purpose.+ CAMEL provides a range of built-in toolkits—covering everything from web search and data extraction to code execution, GitHub integration, and much more.+</Card>-**Toolkits:** Toolkits are collections of tools that are designed to work well together.+----## 2. Get Started+## Get Started-To enhance your agents' capabilities with CAMEL tools, start by installing our additional tools package:-```sh+<Card title="Install Toolkits" icon="terminal">+To unlock advanced capabilities for your agents, install CAMEL's extra tools package:+<CodeBlock language="sh" title="Install with pip">pip install 'camel-ai[tools]'-```--In CAMEL, a tool is an `FunctionTool` that LLMs can call.-+</CodeBlock>+A tool in CAMEL is just a <b>FunctionTool</b>—an interface any agent can call to run custom logic or access APIs.+</Card>-### 2.1 How to Define Your Own Tool?+<Card title="Define a Custom Tool" icon="toolbox">+You can easily create your own tools for any use case. Just write a Python function and wrap it using <b>FunctionTool</b>:-Developers can create custom tools tailored to their agent's specific needs with ease. Here's how you can define and use a custom tool:--**Example: Adding Two Numbers**--First, define your function and wrap it using the `FunctionTool`--```python+<CodeBlock language="python" title="add_tool.py">from camel.toolkits import FunctionTooldef add(a: int, b: int) -> int:- r"""Adds two numbers.-- Args:- a (int): The first number to be added.- b (int): The second number to be added.-- Returns:- integer: The sum of the two numbers.- """+ """Adds two numbers."""return a + b-# Wrap the function with FunctionTooladd_tool = FunctionTool(add)+</CodeBlock>++Inspect your tool’s properties—such as its name, description, and OpenAI-compatible schema—using built-in methods:+<CodeGroup>+```python tool_properties.py+print(add_tool.get_function_name()) # add+print(add_tool.get_function_description()) # Adds two numbers.+print(add_tool.get_openai_function_schema()) # OpenAI Functions schema+print(add_tool.get_openai_tool_schema()) # OpenAI Tool format```+```text output.txt+add+Adds two numbers.-**Accessing Tool Properties**--Once your tool is defined, you can inspect its properties using built-in methods:--Retrieve the function's name:--```python-print(add_tool.get_function_name())-```--```markdown->>> add-```--Get the description of what the function does:--```python-print(add_tool.get_function_description())-```--```markdown->>> Adds two numbers.-```--Fetch the schema representation for OpenAI functions:--```python-print(add_tool.get_openai_function_schema())-```--```markdown->>>-{'name': 'add',- 'description': 'Adds two numbers.',- 'parameters': {'properties': {'a': {'type': 'integer',- 'description': 'The first number to be added.'},- 'b': {'type': 'integer', 'description': 'The second number to be added.'}},- 'required': ['a', 'b'],- 'type': 'object'}}-```--Retrieve the tool schema, compatible with OpenAI's structure:--```python-print(add_tool.get_openai_tool_schema())-```+{'name': 'add', 'description': 'Adds two numbers.', 'parameters': {'properties': {'a': {'type': 'integer', 'description': 'The first number to be added.'}, 'b': {'type': 'integer', 'description': 'The second number to be added.'}}, 'required': ['a', 'b'], 'type': 'object'}}-```markdown->>>-{'type': 'function',- 'function': {'name': 'add',- 'description': 'Adds two numbers.',- 'parameters': {'properties': {'a': {'type': 'integer',- 'description': 'The first number to be added.'},- 'b': {'type': 'integer', 'description': 'The second number to be added.'}},- 'required': ['a', 'b'],- 'type': 'object'}}}+{'type': 'function', 'function': {'name': 'add', 'description': 'Adds two numbers.', 'parameters': {'properties': {'a': {'type': 'integer', 'description': 'The first number to be added.'}, 'b': {'type': 'integer', 'description': 'The second number to be added.'}}, 'required': ['a', 'b'], 'type': 'object'}}}```+</CodeGroup>+</Card>-### 2.2 Toolkits--Toolkits are collections of tools that are designed to be used together for specific tasks. All Toolkits expose a `get_tools` method which returns a list of tools. You can therefore do:+<Card title="Using Toolkits" icon="screwdriver-wrench">+Toolkits group related tools for specialized tasks—search, math, or automation. Use built-in toolkits or build your own.-```python+<CodeBlock language="python" title="toolkit_usage.py">from camel.toolkits import SearchToolkit--# Initialize a toolkittoolkit = SearchToolkit()--# Get list of toolstools = toolkit.get_tools()-```+</CodeBlock>-To utilize specific tools from the toolkits, you can implement code like the following:--```python+You can also wrap toolkit methods as individual FunctionTools:+<CodeBlock language="python" title="custom_tools.py">from camel.toolkits import FunctionTool, SearchToolkitgoogle_tool = FunctionTool(SearchToolkit().search_google)wiki_tool = FunctionTool(SearchToolkit().search_wiki)-```+</CodeBlock>+</Card>-### 2.3 Passing Tools to `ChatAgent`-Enhance the functionality of a ChatAgent by passing custom tools during initialization. Here's how you can do it:+<Card title="Passing Tools to ChatAgent" icon="user-cog">+You can enhance any <b>ChatAgent</b> with custom or toolkit-powered tools. Just pass the tools during initialization:-```python+<CodeBlock language="python" title="chatagent_tools.py">from camel.agents import ChatAgent-# Initialize a ChatAgent with your custom toolstool_agent = ChatAgent(- tools=tools,+ tools=tools, # List of FunctionTools)-# Interact with the agentresponse = tool_agent.step("A query related to the tool you added")-```+</CodeBlock>+</Card>-## 3. Built-in Toolkits+## Built-in ToolkitsCAMEL provides a variety of built-in toolkits that you can use right away. Here's a comprehensive list of available toolkits:@@ -193,20 +143,21 @@ CAMEL provides a variety of built-in toolkits that you can use right away. Here'| ZapierToolkit | A toolkit for interacting with Zapier's NLA API to execute actions through natural language commands and automate workflows. || KlavisToolkit | A toolkit for interacting with Kavis AI's API to create remote hosted production-ready MCP servers. |-## 4. Using Toolkits as MCP Servers--CAMEL supports the Model Context Protocol (MCP), which allows you to expose toolkits as standalone servers that can be accessed by clients. This enables distributed tool execution and integration with various systems.+## Using Toolkits as MCP Servers-### 4.1 What is MCP?+<Card title="MCP Servers in CAMEL" icon="server">+CAMEL supports the <b>Model Context Protocol (MCP)</b>, letting you expose any toolkit as a standalone server. This enables distributed tool execution and seamless integration across multiple systems—clients can remotely discover and invoke tools via a consistent protocol.+</Card>-Model Context Protocol (MCP) is a protocol that enables language models to interact with external tools and services. In CAMEL, toolkits can be exposed as MCP servers, allowing clients to discover and call tools remotely.+<Card title="What is MCP?" icon="anchor">+MCP (Model Context Protocol) is a unified protocol for connecting LLMs with external tools and services. In CAMEL, you can turn any toolkit into an MCP server, making its tools available for remote calls—ideal for building distributed, modular, and language-agnostic AI workflows.+</Card>-### 4.2 Creating an MCP Server from a Toolkit--Any CAMEL toolkit can be exposed as an MCP server. Here's how to create an MCP server using the ArXiv toolkit as an example:+<Card title="Expose a Toolkit as an MCP Server" icon="rocket">+Any CAMEL toolkit can run as an MCP server. Here’s how you can start an ArXiv toolkit server from a script:+<CodeGroup>```python-# arxiv_toolkit_server.pyimport argparseimport sys@@ -231,22 +182,20 @@ if __name__ == "__main__":)args = parser.parse_args()-toolkit = ArxivToolkit(timeout=args.timeout)-- # Run the toolkit as an MCP servertoolkit.run_mcp_server(mode=args.mode)-```--The server can be run in two modes:-- `stdio`: Standard input/output mode (default)-- `sse`: Server-Sent Events mode--### 4.3 Configuring MCP Servers--Create a configuration file (e.g., `mcp_servers_config.json`) to specify how to launch your MCP servers:--```json+ ```+</CodeGroup>+Supported modes:+- <b>stdio</b>: Standard input/output (default)+- <b>sse</b>: Server-Sent Events+- <b>streamable-http</b>: Streamable HTTP+</Card>++<Card title="MCP Server Configuration" icon="settings">+Define how to launch your MCP servers with a config file:+<CodeGroup>+```json mcp_servers_config.json{"mcpServers": {"arxiv_toolkit": {@@ -261,63 +210,62 @@ Create a configuration file (e.g., `mcp_servers_config.json`) to specify how to}}```+</CodeGroup>+</Card>-### 4.4 Connecting to MCP Servers from a Client--You can connect to MCP servers and use their tools from a client application:--```python+<Card title="Connect to MCP Servers as a Client" icon="plug">+From your client application, you can connect to MCP servers and use their tools remotely:+<CodeGroup>+```python mcp_client_example.pyimport asynciofrom mcp.types import CallToolResultfrom camel.toolkits.mcp_toolkit import MCPToolkit, MCPClientasync def run_example():- # Initialize the MCPToolkit with your configuration filemcp_toolkit = MCPToolkit(config_path="path/to/mcp_servers_config.json")-- # Connect to all configured MCP serversawait mcp_toolkit.connect()- # Get the first MCP servermcp_client: MCPClient = mcp_toolkit.servers[0]-- # List available tools from the server+res = await mcp_client.list_mcp_tools()if isinstance(res, str):raise Exception(res)-tools = [tool.name for tool in res.tools]print(f"Available tools: {tools}")- # Call a tool from the serverresult: CallToolResult = await mcp_client.session.call_tool("tool_name", {"param1": "value1", "param2": "value2"})print(result.content[0].text)- # Disconnect from all serversawait mcp_toolkit.disconnect()if __name__ == "__main__":asyncio.run(run_example())```--### 4.5 Benefits of Using MCP Servers--1. **Distributed Execution**: Run tools on separate machines or processes.-2. **Isolation**: Each toolkit runs in its own process, providing better isolation and stability.-3. **Resource Management**: Allocate resources to specific toolkits based on their requirements.-4. **Scalability**: Scale individual toolkits independently based on demand.-5. **Language Interoperability**: MCP servers can be implemented in different programming languages.--### 4.6 Best Practices--- **Timeouts**: Always set appropriate timeouts to prevent hanging operations.-- **Error Handling**: Implement proper error handling for both server and client sides.-- **Resource Cleanup**: Ensure proper disconnection from servers when done.-- **Configuration Management**: Use environment variables or configuration files for server settings.-- **Monitoring**: Implement logging and monitoring for MCP servers in production environments.--## 5. Conclusion--Tools are essential for extending the capabilities of CAMEL agents, empowering them to perform a wide range of tasks and collaborate efficiently.+</CodeGroup>+</Card>++<Card title="Benefits of MCP Servers" icon="zap">+<ul>+ <li><b>Distributed Execution:</b> Run tools anywhere—across machines or containers.</li>+ <li><b>Process Isolation:</b> Each toolkit runs in its own process for reliability and security.</li>+ <li><b>Resource Management:</b> Allocate memory/CPU for heavy toolkits without impacting others.</li>+ <li><b>Scalability:</b> Scale specific toolkits up or down as your workload changes.</li>+ <li><b>Language Interoperability:</b> Implement MCP servers in any language that supports the protocol.</li>+</ul>+</Card>++<Card title="Best Practices for MCP Integration" icon="star">+<ul>+ <li><b>Timeouts:</b> Always set timeouts to prevent blocked operations.</li>+ <li><b>Error Handling:</b> Implement robust error and exception handling in both server and client code.</li>+ <li><b>Resource Cleanup:</b> Properly disconnect and free resources when finished.</li>+ <li><b>Configuration:</b> Use config files or environment variables for flexible deployment.</li>+ <li><b>Monitoring:</b> Add logging and health checks for production MCP deployments.</li>+</ul>+</Card>++<Card title="Conclusion" icon="trophy">+Tools—especially when deployed as MCP servers—are the bridge between CAMEL agents and the real world. With this architecture, you can empower agents to automate, fetch, compute, and integrate with almost any external system.+</Card>diff --git a/docs/key_modules/workforce.md b/docs/key_modules/workforce.mdindex 2e49b2603..ea8f770ef 100644--- a/docs/key_modules/workforce.md+++ b/docs/key_modules/workforce.md@@ -1,164 +1,160 @@-> Workforce is a system where multiple agents work together to solve tasks.-> By using Workforce, users can quickly set up a multi-agent task solving-> system with customized configurations. In this section, we will give a-> brief view on the architecture of workforce, and how you can configure-> and utilize it to solve tasks.+---+title: "Workforce"+icon: users+----For more detailed usage information, please refer to our cookbook: [Create A Hackathon Judge Committee with Workforce](https://colab.research.google.com/drive/18ajYUMfwDx3WyrjHow3EvUMpKQDcrLtr?usp=sharing)+<Card title="Concept" icon="users">+Workforce is CAMEL-AI’s multi-agent teamwork engine.-## System Design--### Architecture--Workforce follows a hierarchical architecture. A workforce can consist of-multiple worker nodes, and each of the worker nodes will contain-one agent or multiple agents as the worker. The worker nodes are managed by-a coordinator agent inside the workforce, and the coordinator agent will assign-tasks to the worker nodes according to the description of the worker nodes,-along with their tool sets.--Alongside the coordinator agent, there is also a task planner agent inside the-workforce. The task planner agent will take the responsibility of decomposing-and composing tasks, so that the workforce can solve the task step by step.--### Communication Mechanism--The communication inside the workforce is based on the task channel. The-initialization of workforce will create a channel that will be shared by-all the nodes. Tasks will later be posted into this channel, and each-worker node will listen to the channel, accept tasks that are assigned-to it from this channel to solve.--When a task is solved, the worker node will post the result back to the-channel, and the result will reside in the channel as a 'dependency' for-other tasks, which will be shared by all the worker nodes.--With this mechanism, the workforce can solve tasks in a collaborative and-efficient way.--### Failure Handling--In the workforce, we have a mechanism to handle failures. When a task fails,-the coordinator agent will take actions to fix it. The actions can be either-decomposing the task into smaller ones and assign them again, or creating a-new worker that is capable of doing the task.+Instead of relying on a single agent, Workforce lets you organize a *team* of specialized agents—each with its own strengths—under a single, coordinated system. You can quickly assemble, configure, and launch collaborative agent “workforces” for any task that needs parallelization, diverse expertise, or complex workflows.-For now, the coordinator will make decisions based on the number of times the-task has been decomposed. If the task has already been decomposed for more-than a certain number of times, the coordinator will take the new worker-creation action; if not, the coordinator will simply take the decomposition-action.--There will also be cases where a task just simply cannot be solved by-agents. Under this circumstance, to prevent the workforce from being stuck-in a infinite agent creation loop, the workforce will be halted if one task-has been failed for a certain number of times (3 by default).+With Workforce, agents plan, solve, and verify work together—like a project team in an organization, but fully automated.-### A Simple Example of the Workflow+<Note type="info">+**Key advantages of Workforce:**+- Instantly scale from single-agent to multi-agent workflows+- Built-in coordination, planning, and failure recovery+- Ideal for hackathons, evaluations, code review, brainstorming, and more+- Configure roles, toolsets, and communication patterns for *any* scenario+</Note>+</Card>-Here is a diagram illustrating the workflow with a simple example.+<Card title="See More: Hackathon Judge Committee Example" icon="link" href="https://colab.research.google.com/drive/18ajYUMfwDx3WyrjHow3EvUMpKQDcrLtr?usp=sharing">+ Check out our in-depth Workforce example:+ <b>Create a Hackathon Judge Committee with Workforce</b>+</Card>-+----## Get Started--In this section, we will show you how to create a workforce instance, add-worker nodes to the workforce, and finally, how to start the workforce to-solve tasks.--### Create a Workforce Instance--To start using Workforce, you need to first create a workforce instance, and-then add worker nodes to the workforce. Here is an example of how you can do-this:--```python-from camel.societies.workforce import Workforce--# Create a workforce instance-workforce = Workforce("A Simple Workforce")-```--Now we get a workforce instance with description "A Simple Workforce".-However, there is no worker node in the workforce yet.+## System Design-> **Note: How to further customize the workforce**->-> You can quickly create a workforce instance with default configurations-> by just providing the description of the workforce. However, you can also-> configure the workforce with more details, such as providing a list of-> worker nodes directly instead of adding them one by one, or configuring-> the coordinator agent and task planner agent by passing the configurations-> to the workforce instance.+### Architecture: How Workforce Works-### Add Worker Nodes+Workforce uses a **hierarchical, modular design** for real-world team problem-solving:-After creating the workforce instance, you can add worker nodes to the-workforce. To add a worker node, you need to first create worker agents-that actually do the work.+See how the coordinator and task planner agents orchestrate a multi-agent workflow:-Suppose we have already created an `ChatAgent` that can do web searches-called `search_agent`. Now we can add this worker agent to the workforce.+-```python-# Add the worker agent to the workforce-workforce.add_single_agent_worker(- "An agent that can do web searches",- worker=search_agent,-)-```+- **Workforce:** The “team” as a whole.+- **Worker nodes:** Individual contributors—each node can contain one or more agents, each with their own capabilities.+- **Coordinator agent:** The “project manager”—routes tasks to worker nodes based on their role and skills.+- **Task planner agent:** The “strategy lead”—breaks down big jobs into smaller, doable subtasks and organizes the workflow.-The adding function follows the fluent interface design pattern, so you can-add multiple worker agents to the workforce in one line, like the following:--```python-workforce.add_single_agent_worker(- "An agent that can do web searches",- worker=search_agent,-).add_single_agent_worker(- "Another agent",- worker=another_agent,-).add_single_agent_worker(- "Yet another agent",- worker=yet_another_agent,-)-```--Now we have some worker agents in the workforce. It's time to create a task and-let the workforce solve it.--> **Note: The description is NOT trivial**->-> When adding an agent to the workforce as a worker node, the first argument-> is the description of the worker node. Though it seems trivial, it is-> actually very important. The description will be used by the coordinator-> agent as the basis to assign tasks to the worker nodes. Therefore, it is-> recommended to provide a clear and concise description of the worker node.--### Start the Workforce--After adding worker nodes to the workforce, you can start the workforce to-solve tasks. First we can define a task:--```python-from camel.tasks import Task--# the id of the task can be any string to mark the task-task = Task(- content="Make a travel plan for a 3-day trip to Paris.",- id="0",-)-```--Then we can start the workforce with the task:+### Communication: A Shared Task Channel-```python-task = workforce.process_task(task)-```+- Every Workforce gets a **shared task channel** when it’s created.+- **How it works:**+ - All tasks are posted into this channel.+ - Worker nodes “listen” and accept their assigned tasks.+ - Results are posted back to the channel, where they’re available as dependencies for the next steps.++*This design lets agents build on each other's work and ensures no knowledge is lost between steps.*++### Failure Handling: Built-In Robustness++Workforce is designed to handle failures and recover gracefully:++- If a worker fails a task, the coordinator agent will:+ - **Decompose and retry:** Break the task into even smaller pieces and reassign.+ - **Escalate:** If the task keeps failing, create a new worker designed for that problem.+- To prevent infinite loops, if a task has failed or been decomposed more than a set number of times (default: 3), Workforce will automatically halt that workflow.++<Tip>+ <b>Tip:</b> Workforce automatically stops stuck workflows—so you don’t waste compute or get caught in agent loops!+</Tip>++---++<Card title="Quickstart: Build Your First Workforce" icon="rocket">++<Steps>+ <Step title="Create a Workforce Instance">+ To begin, import and create a new Workforce:++ ```python+ from camel.societies.workforce import Workforce++ # Create a workforce instance+ workforce = Workforce("A Simple Workforce")+ ```++ <Tip>+ For quick setups, just provide the description.+ For advanced workflows, you can pass in custom worker lists or configure the coordinator and planner agents.+ </Tip>+ </Step>++ <Step title="Add Worker Nodes">+ Now add your worker agents.+ (Example: a `ChatAgent` for web search, named `search_agent`.)++ ```python+ # Add a worker agent to the workforce+ workforce.add_single_agent_worker(+ "An agent that can do web searches",+ worker=search_agent,+ )+ ```++ **Chain multiple agents for convenience:**+ ```python+ workforce.add_single_agent_worker(+ "An agent that can do web searches",+ worker=search_agent,+ ).add_single_agent_worker(+ "Another agent",+ worker=another_agent,+ ).add_single_agent_worker(+ "Yet another agent",+ worker=yet_another_agent,+ )+ ```++ <Tip>+ The *description* is important!+ The coordinator uses it to assign tasks—so keep it clear and specific.+ </Tip>+ </Step>++ <Step title="Start the Workforce and Solve Tasks">+ Define a task and let the workforce handle it:++ ```python+ from camel.tasks import Task++ # The id can be any string+ task = Task(+ content="Make a travel plan for a 3-day trip to Paris.",+ id="0",+ )++ # Process the task with the workforce+ task = workforce.process_task(task)++ # See the result+ print(task.result)+ ```+ </Step>+</Steps>+</Card>++---++<CardGroup cols={2}>+ <Card+ title="Cookbook: Hackathon Judge Committee"+ icon="bookmark"+ href="https://colab.research.google.com/drive/18ajYUMfwDx3WyrjHow3EvUMpKQDcrLtr?usp=sharing"+ >+ See a real-world multi-agent workflow with Workforce.+ </Card>+ <Card+ title="API Reference"+ icon="book"+ href="/reference/#societies.workforce"+ >+ Full documentation for advanced usage and configuration.+ </Card>+</CardGroup>-The final result of the task will be stored in the `result` attribute of the-task object. You can check the result by:--```python-print(task.result)-```diff --git a/docs/mintlify/cookbooks/data_processing/summarisation_agent_with_mistral_ocr.mdx b/docs/mintlify/cookbooks/data_processing/summarisation_agent_with_mistral_ocr.mdxindex c39379bd5..30d49578b 100644--- a/docs/mintlify/cookbooks/data_processing/summarisation_agent_with_mistral_ocr.mdx+++ b/docs/mintlify/cookbooks/data_processing/summarisation_agent_with_mistral_ocr.mdx@@ -25,6 +25,7 @@ In this cookbook, we’ll explore [**Mistral OCR**](https://mistral.ai/news/mist<img src="https://i.postimg.cc/L4wPdG9N/join-2.png" width="150" alt="Join Discord"/></a></div>+⭐ *Star us on [GitHub](https://github.com/camel-ai/camel), join our [Discord](https://discord.camel-ai.org), or follow us on [X](https://x.com/camelaiorg)*