
Crawlee—A web scraping and browser automation library for Node.js to build reliable crawlers. In JavaScript and TypeScript. Extract data for AI, LLMs, RAG, or GPTs. Download HTML, PDF, JPG, PNG, and other files from websites. Works with Puppeteer, Playwright, Cheerio, JSDOM, and raw HTTP. Both headful and headless mode. With proxy rotation.
TypeScript apifyautomationcrawlercrawlingheadlessheadless-chromejavascriptnodejsnpmplaywrightpuppeteerscraperscrapingtypescriptweb-crawlerweb-crawlingweb-scraping
Build readme
Ondra Urban809b6664b296
diff --git a/README.md b/README.mdindex 4d035383e..b4433fafb 100644--- a/README.md+++ b/README.md@@ -116,204 +116,120 @@ The Apify SDK is available as the <a href="https://www.npmjs.com/package/apify"></li></ul>-## Getting Started-Without the right tools, crawling and scraping the web can be a difficult thing. At the very least, you need an HTTP client to make the necessary requests, but that only gets you raw HTML and sometimes not even that. Then you have to read this HTML and extract the data you're interested in. Once extracted, it must be stored in a machine readable format and easily accessible for further processing, because it is the processed data that hold value.+## Getting Started Quick+The Apify SDK requires <a href="https://nodejs.org/en/" target="_blank">Node.js</a> 8 or later.-Apify SDK covers the process end-to-end. From crawling the web for links and scraping the raw data to storing it in various machine readable formats, ready for processing. With this guide in hand, you should have your own data extraction solutions up and running in a few hours.+### Local stand-alone usage-### Intro-The goal of this getting started guide is to provide a step-by-step introduction to all the features of the Apify SDK. It will walk you through creating the simplest of crawlers that only print text to console, all the way up to complex systems that crawl pages, interact with them as if a real user were sitting in front of a real browser and output structured data.--Since Apify SDK is usable both locally on any computer and on the-<a href="https://my.apify.com" target="_blank">Apify Platform</a>,-you will be able to use the source code in both environments interchangeably. Nevertheless, some initial setup is still required, so choose your preferred starting environment and let's get into it.--### Setting up locally-To run Apify SDK on your own computer, you need to meet the following pre-requisites first:--1. Have Node.js version 8.14 or higher installed.- * Visit <a href="https://nodejs.org/en/download/" target="_blank">Node.js website</a> to download or use <a href="https://github.com/creationix/nvm" target="_blank">nvm</a>-2. Have NPM installed.- * NPM comes bundled with Node.js so you should already have it. If not, reinstall Node.js.--If you're not certain, confirm the pre-requisites by running:+Add Apify SDK to any Node.js project by running:```bash-node -v+npm install apify --save```-```bash-npm -v-```--#### Adding Apify SDK to an existing project-Apify SDK can be added as a dependency into any Node.js project, so if you already have a project that you'd like to add web crawling, scraping and automation capabilities to, just run the following command in the project's folder and you're good to go.+Run the following example to perform a recursive crawl of a website using Puppeteer.+For more examples showcasing various features of the Apify SDK,+[see the Examples section of the documentation](https://sdk.apify.com/docs/examples/basiccrawler).-```bash-npm install apify-```+```javascript+const Apify = require('apify');-#### Creating a new project-The fastest and best way to create new projects with the Apify SDK is to use our own-<a href="https://www.npmjs.com/package/apify-cli" target="_blank">Apify CLI</a>.-This command line tool allows you to create, run and manage Apify projects with ease, including their deployment to the <a href="https://my.apify.com" target="_blank">Apify Platform</a> if you wish to run them in the cloud after developing them locally.+Apify.main(async () => {+ const requestQueue = await Apify.openRequestQueue();+ await requestQueue.addRequest({ url: 'https://www.iana.org/' });+ const pseudoUrls = [new Apify.PseudoUrl('https://www.iana.org/[.*]')];-Let's install the Apify CLI with the following command:+ const crawler = new Apify.PuppeteerCrawler({+ requestQueue,+ handlePageFunction: async ({ request, page }) => {+ const title = await page.title();+ console.log(`Title of ${request.url}: ${title}`);+ await Apify.utils.puppeteer.enqueueLinks(page, 'a', pseudoUrls, requestQueue);+ },+ maxRequestsPerCrawl: 100,+ maxConcurrency: 10,+ });-```bash-npm install -g apify-cli+ await crawler.run();+});```-Once the installation finishes, all you need to do to set up an Apify SDK project is to run:-```bash-apify create my-new-project-```-A prompt will be shown, asking to choose a template. Disregard the different options for now and choose the template labeled `Hello world`. The command will now create a new directory in your current working directory, called `my-new-project`, create a `package.json` in this folder and install all the necessary dependencies. It will also add example source code that you can immediately run.+When you run the example, you should see Apify SDK automating a Chrome browser.-Let's try that!+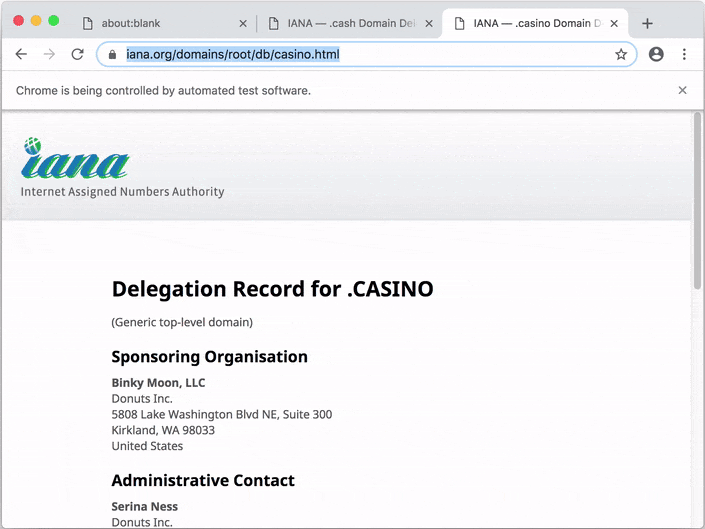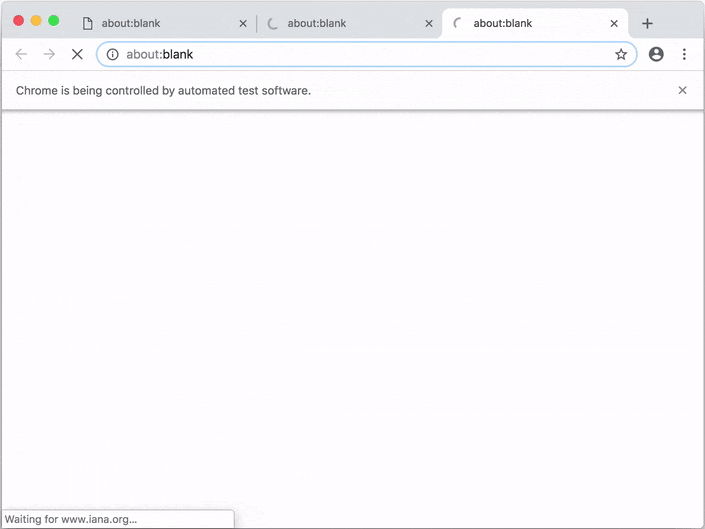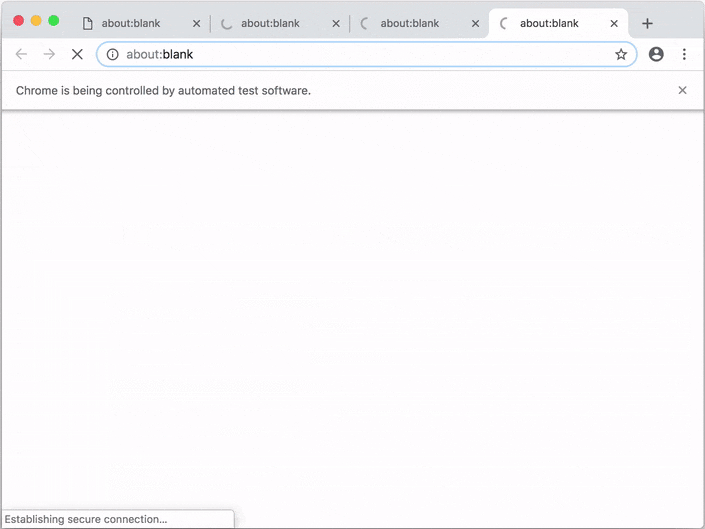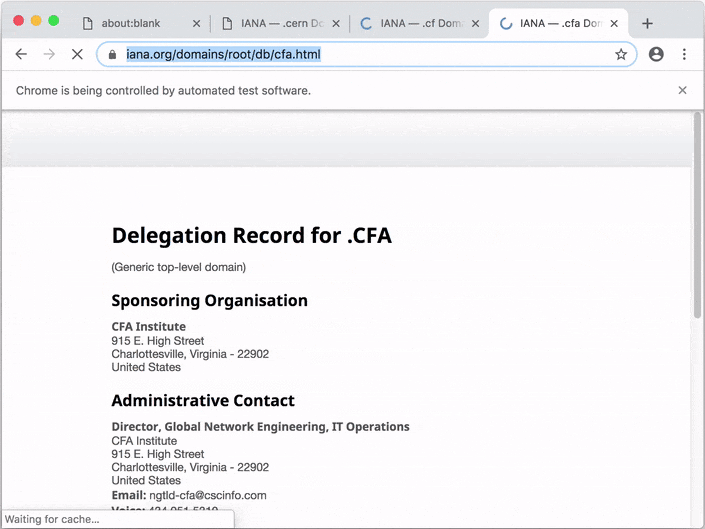-```bash-cd my-new-project-```-```bash-apify run-```+By default, Apify SDK stores data to+`./apify_storage` in the current working directory.+You can override this behavior by setting either the+`APIFY_LOCAL_STORAGE_DIR` or `APIFY_TOKEN` environment variable.+For details, see [Environment variables](https://sdk.apify.com/docs/guides/environmentvariables)+and [Data storage](https://sdk.apify.com/docs/guides/datastorage).-You should start seeing log messages in the terminal as the system boots up and after a second, a Chromium browser window should pop up. In the window, you'll see quickly changing pages and back in the terminal, you should see the titles (contents of the <title> HTML tags) of the pages printed.+### Local usage with Apify command-line interface (CLI)-You can always terminate the crawl with a keypress in the terminal:+To avoid the need to set the environment variables manually,+to create a boilerplate of your project,+and to enable pushing and running your code on the+<a href="https://www.apify.com" target="_blank">Apify Cloud</a>,+you can use the+<a href="https://github.com/apifytech/apify-cli" target="_blank">Apify command-line interface</a>+(CLI) tool.++Install the CLI by running:```bash-CTRL+C+npm -g install apify-cli```-Did you see all that? If you did, congratulations! You're ready to go!--### Setting up on the Apify Platform-Maybe you don't have Node.js installed and don't want the hassle. Or you can't install anything on your computer because you're using a company provided one. Or perhaps you'd just prefer to start working in the cloud right away. Well, no worries, we've got you covered.--The <a href="https://my.apify.com" target="_blank">Apify Platform</a> is the foundational product of <a href="https://www.apify.com" target="_blank">Apify</a>. It's a serverless cloud computing platform, specifically designed for any web automation jobs, that may include crawling and scraping, but really works amazing for any batch jobs and long running tasks.--It comes with a free account, so let's go to our-<a href="https://my.apify.com/sign-up" target="_blank">sign-up page</a>-and create one, if you haven't already. Don't forget to verify your email. Without it, you won't be able to run any projects.--Once you're in, you might by prompted by our in-app help to walk through a step-by-step guide into some of our new features. Feel free to finish that, if you'd like, but once you're done, click on the **Actors** tab in the left menu. You might be tempted to go directly to Crawlers, because what the heck are **Actors**, right? Bear with me, **Actors** are the tool that you really want! To read more about them, see: [What is an Actor](https://sdk.apify.com/docs/guides/whatisanactor).--#### Creating a new project-In the page that shows after clicking on Actors in the left menu, choose **Create new**. Give it a name in the form that opens, let's say, `my-new-actor`. Disregard all the available options for now and save your changes.--Now click on the **Sources** tab at the top. Disregard the version and environment variables inputs for now and proceed directly to **Source code**. This is where you develop the actor, if you choose not to do it locally. Just press **Run** below the **Source code** panel. It will automatically build and run the example source code. You should start seeing log messages that represent the build and after the build is complete, log messages of the running actor. Feel free to check out the other **Run** tabs, such as **Info**, where you can find useful information about the run, or **Key-value-store**, where the actor's **INPUT** and **OUTPUT** are stored.--Good job. You're now ready to run your own source code on the Apify Platform. For more information visit the-<a href="https://www.apify.com/docs/actor" target="_blank">Actor documentation page</a>,-where you'll find everything about the platform's various options.--### First crawler-Whether you've chosen to develop locally or in the cloud, it's time to start writing some actual source code. But before we do, let me just briefly introduce all the Apify SDK classes necessary to make it happen.--#### The general idea-There are 3 crawler classes available for use in the Apify SDK. [`BasicCrawler`](../api/basiccrawler), [`CheerioCrawler`](../api/cheeriocrawler) and [`PuppeteerCrawler`](https://sdk.apify.com/docs/api/puppeteercrawler). We'll talk about their differences later. Now, let's talk about what they have in common.-All the crawlers' general idea is to go to a web page, open it, do some stuff there, save some results and continue to the next page, until it's done its job. So each time the crawler needs to find answers to two questions: **Where should I go?** and **What should I do there?**. Answering those two questions is the only setup mandatory to run the crawlers.+You might need to run the above command with `sudo`, depending on how crazy your configuration is.-#### The Where - `Request`, `RequestList` and `RequestQueue`-All crawlers use instances of the [`Request`](https://sdk.apify.com/docs/api/request) class to determine where they need to go. Each request may hold a lot of information, but at the very least, it must hold a URL - a web page to open. But having only one URL would not make sense for crawling. We need to either have a pre-existing list of our own URLs that we wish to visit, perhaps a thousand, or a million, or we need to build this list dynamically as we crawl, adding more and more URLs to the list as we progress.+Now create a boilerplate of your new web crawling project by running:-A representation of the pre-existing list is an instance of the [`RequestList`](../api/requestlist) class. It is a static, immutable list of URLs and other metadata (see the [`Request`](https://sdk.apify.com/docs/api/request)%20object) that the crawler will visit, one by one, retrying whenever an error occurs, until there are no more `Requests` to process.--[`RequestQueue`](https://sdk.apify.com/docs/api/requestqueue)%20on%20the%20other%20hand,%20represents%20a%20dynamic%20queue%20of%20%60Requests%60.%20One%20that%20can%20be%20updated%20at%20runtime%20by%20adding%20more%20pages%20-%20%60Requests%60%20to%20process.%20This%20allows%20the%20crawler%20to%20open%20one%20page,%20extract%20interesting%20URLs,%20such%20as%20links%20to%20other%20pages%20on%20the%20same%20domain,%20add%20them%20to%20the%20queue%20(called%20*enqueuing*) and repeat this process to build a queue of tens of thousands or more URLs while knowing only a single one at the beginning.--`RequestList` and `RequestQueue` are essential for the crawler's operation. There is no other way to supply `Requests` = "pages to crawl" to the crawlers. At least one of them always needs to be provided while setting up. You can also use both at the same time, if you wish.--#### The What - `handlePageFunction`-The `handlePageFunction` is the brain of the crawler. It tells it what to do at each and every page it visits. Generally it handles extraction of data from the page, processing the data, saving it, calling APIs, doing calculations and whatever else you need it to do, really.--The `handlePageFunction` is provided by you, the user, and invoked automatically by the crawler for each `Request` from either the `RequestList` or `RequestQueue`. It always receives a single argument and that is a plain `Object`. Its properties change depending on the used crawler class, but it always includes at least the `request` property, which represents the currently crawled `Request` instance (i.e. the URL the crawler is visiting and related metadata) and the `autoscaledPool` property, which is an instance of the [`AutoscaledPool`](https://sdk.apify.com/docs/api/autoscaledpool) class and we'll talk about it in detail later.--```js-// The object received as a single argument by the handlePageFunction-{- request: Request,- autoscaledPool: AutoscaledPool-}+```bash+apify create my-hello-world```-#### Putting it all together-Enough theory! Let's put some of those hard learned facts into practice. We learned above that we need `Requests` and a `handlePageFunction` to setup a crawler. We will also use the [`Apify.main()`](https://sdk.apify.com/docs/api/apify#module_Apify.main) function. It's not mandatory, but it makes our life easier. We'll learn about it in detail later on.--Let's start super easy. Visit one page, get its title and close. First of all we need to require Apify, to make all of its features available to us:+The CLI will prompt you to select a project boilerplate template - just pick "Hello world".+The tool will create a directory called `my-hello-world` with a Node.js project files.+You can run the project as follows:-```js-const Apify = require('apify');+```bash+cd my-hello-world+apify run```-Easy right? It doesn't get much more difficult, trust me. For the purposes of this tutorial, we'll be scraping our own webpage <a href="https://www.apify.com" target="_blank">https://www.apify.com</a>. Now, to get there, we need a `Request` with the page's URL in one of our sources, `RequestList` or `RequestQueue`. Let's go with `RequestQueue` for now.+By default, the crawling data will be stored in a local directory at `./apify_storage`.+For example, the input JSON file for the actor is expected to be in the default key-value store+in `./apify_storage/key_value_stores/default/INPUT.json`.-```js-const Apify = require('apify');+Now you can easily deploy your code to the Apify Cloud by running:-// This is how you use the Apify.main() function.-Apify.main(async () => {- // First we create the request queue instance.- const requestQueue = await Apify.openRequestQueue();- // And then we add a request to it.- await requestQueue.addRequest({ url: 'https://www.apify.com' });-});-```-> If you're not familiar with the `async` and `await` keywords used in the example, trust that it is a native syntax in modern JavaScript and you can [learn more about it here](https://nikgrozev.com/2017/10/01/async-await/).--The [`requestQueue.addRequest()`](https://sdk.apify.com/docs/api/requestqueue#RequestQueue+addRequest) function automatically converts the plain object we passed to it to a `Request` instance, so now we have a `requestQueue` that holds one `request` which points to `https://www.apify.com`. Now we need the `handlePageFunction`.--```js-// We'll define the function separately so it's more obvious.-const handlePageFunction = async ({ request, $ }) => {- // This should look familiar if you ever worked with jQuery.- // We're just getting the text content of the <title> HTML element.- const title = $('title').text();-- console.log(`The title of "${request.url}" is: ${title}.`);-}+```bash+apify login```--Wait, where did the `$` come from? Remember what we learned about the `handlePageFunction` earlier. It expects a plain `Object` as an argument that will always have a `request` property, but it will also have other properties, depending on the chosen crawler class. Well, `$` is a property provided by the `CheerioCrawler` class which we'll set up right now.--```js-const Apify = require('apify');--Apify.main(async () => {- const requestQueue = await Apify.openRequestQueue();- await requestQueue.addRequest({ url: 'https://www.apify.com' });-- const handlePageFunction = async ({ request, $ }) => {- const title = $('title').text();-- console.log(`The title of "${request.url}" is: ${title}.`);- }-- // Set up the crawler, passing a single options object as an argument.- const crawler = new Apify.CheerioCrawler({- requestQueue,- handlePageFunction- });-- await crawler.run();-});+```bash+apify push```-And we're done! You just created your first crawler from scratch. It will download the HTML of `https://www.apify.com`, find the `<title>` element, get its text content and print it to console. Good job!--To run the code locally, copy and paste the code, if you haven't already typed it in yourself, to the `main.js` file in the `my-new-project` we created earlier and run `apify run` from that project's directory.--To run the code on Apify Platform, just replace the original example with your new code and hit Run.--Whichever environment you choose, you should see the message `The title of "https://www.apify.com" is: Web Scraping, Data Extraction and Automation - Apify.` printed to the screen. If you do, congratulations and let's move onto some bigger challenges! And if you feel like you don't really know what just happened there, no worries, it will all become clear when you learn more about the `CheerioCrawler`.---### CheerioCrawler aka jQuery crawler-This is the crawler that we used in our earlier example. Our simplest and also the fastest crawling solution. If you're familiar with `jQuery`, you'll understand `CheerioCrawler` in minutes. <a href="https://www.npmjs.com/package/cheerio" target="_blank">Cheerio</a> is essentially `jQuery` for Node.js. It offers the same API, including the familiar `$` object. You can use it, as you would `jQuery`, for manipulating the DOM of a HTML page. In crawling, you'll mostly use it to select the right elements and extract their text values - the data you're interested in. But `jQuery` runs in a browser and attaches directly to the browser's DOM. Where does `cheerio` get its HTML? This is where the `Crawler` part of `CheerioCrawler` comes in.---> TO BE CONTINUED ...+Your script will be uploaded to the Apify Cloud and built there so that it can be run.+For more information, view the+<a href="https://www.apify.com/docs/cli" target="_blank">Apify CLI</a>+and+<a href="https://www.apify.com/docs/actor" target="_blank">Apify Actor</a>+documentation.++### Usage on the Apify Cloud++You can also develop your web scraping project+in an online code editor directly on the+<a href="https://www.apify.com" target="_blank">Apify Cloud</a>.+You'll need to have an Apify Account.+Go to <a href="https://my.apify.com/actors" target="_blank">Actors</a>,+page in the app, click <i>Create new</i> and then go to the+<i>Source</i> tab and start writing your code or paste one of the examples from the Examples section.++For more information, view the+<a href="https://www.apify.com/docs/actor#quick-start" target="_blank">Apify actors quick start guide</a>.## Support