
Kepler.gl is a powerful open source geospatial analysis tool for large-scale data sets.
feat: add Shapefile, Excel, and FlatGeobuf support (#3741)
Igor Dykhta98cbeccf91f7
diff --git a/docs/user-guides/b-kepler-gl-workflow/a-add-data-to-the-map.md b/docs/user-guides/b-kepler-gl-workflow/a-add-data-to-the-map.mdindex ba83a27c5..4748eee06 100644--- a/docs/user-guides/b-kepler-gl-workflow/a-add-data-to-the-map.md+++ b/docs/user-guides/b-kepler-gl-workflow/a-add-data-to-the-map.md@@ -11,8 +11,8 @@| | ||---|---|-| **Local files** | <span style="font-weight:normal">Upload CSV, GeoJSON, GeoJSONL, KML, GPX, TCX, Arrow, or Parquet files. Files are parsed in your browser, so available memory limits how large a file you can load. For data that does not fit in memory, use a tileset instead.<span> |-| **From URL** | Directly load data or map json by pasting a remote URL. Supported extensions include `csv`, `geojson`, `json`, `geojsonl`, `kml`, `gpx`, `tcx`, `arrow`, and `parquet`. Make sure the url contains the file extension. CORS policy must be defined on your custom url domain. |+| **Local files** | <span style="font-weight:normal">Upload CSV, GeoJSON, GeoJSONL, KML, GPX, TCX, Shapefile, Excel, FlatGeobuf, Arrow, or Parquet files. Files are parsed in your browser, so available memory limits how large a file you can load. For data that does not fit in memory, use a tileset instead.<span> |+| **From URL** | Directly load data or map json by pasting a remote URL. Supported extensions include `csv`, `geojson`, `json`, `geojsonl`, `kml`, `gpx`, `tcx`, `shp`, `xlsx`, `fgb`, `arrow`, and `parquet`. Make sure the url contains the file extension. CORS policy must be defined on your custom url domain. || **Sample data** | Load one of kepler.gl’s sample datasets. The sample map data and config are directly loaded from [kepler.gl-data github][kepler.gl-data-github] repo |@@ -28,6 +28,9 @@ Geometry coordinates should be presented with a geographic coordinate reference- [KML](#kml)- [GPX](#gpx)- [TCX](#tcx)+ - [Shapefile](#shapefile)+ - [Excel](#excel)+ - [FlatGeobuf](#flatgeobuf)- [GeoArrow](#geoarrow)- [kepler.gl Json](#keplergl-json)@@ -220,6 +223,18 @@ kepler.gl accepts `.gpx` files. Waypoints, tracks, and routes are converted to Gkepler.gl accepts Garmin `.tcx` activity files. Track points are converted to GeoJSON features.+### Shapefile++kepler.gl accepts ESRI Shapefiles. Drop a `.shp` together with its sidecars (`.dbf`, `.shx`, and optionally `.prj` / `.cpg`), or a `.zip` that contains those files at the top level. Features are converted to GeoJSON and visualized with a **Polygon** layer. If a `.prj` file is present, geometries are reprojected to WGS84. Nested folders inside the zip are ignored.++### Excel++kepler.gl accepts `.xlsx` and `.xls` workbooks. The first sheet is loaded as a table, the same way as CSV. Additional sheets are not imported.++### FlatGeobuf++kepler.gl accepts `.fgb` files. Features are converted to GeoJSON and visualized with a **Polygon** layer.+### GeoArrow[GeoArrow](https://geoarrow.org/) file, a binary data format which can be visualized with the [PolygonLayer](https://docs.kepler.gl/docs/user-guides/c-types-of-layers/e-polygon).@@ -230,7 +245,7 @@ JSON file exported from kepler.gl. See "[Export Map as JSON](https://docs.kepler### Load Map Using URL-You load data or map through custom URL. It currently supports URLs with file extension of `csv`, `json`, `geojson`, `geojsonl`, `kml`, `gpx`, `tcx`, `arrow`, `parquet`, and `kepler.gl.json`.+You load data or map through custom URL. It currently supports URLs with file extension of `csv`, `json`, `geojson`, `geojsonl`, `kml`, `gpx`, `tcx`, `shp`, `xlsx`, `fgb`, `arrow`, `parquet`, and `kepler.gl.json`.A remote URL still loads the full file into memory. For datasets that do not fit in memory, use a tileset (vector tiles, COG, or PMTiles).diff --git a/docs/user-guides/c-types-of-layers/e-polygon.md b/docs/user-guides/c-types-of-layers/e-polygon.mdindex ab71995d0..e7a2e10ea 100644--- a/docs/user-guides/c-types-of-layers/e-polygon.md+++ b/docs/user-guides/c-types-of-layers/e-polygon.md@@ -2,7 +2,7 @@Polygon layer can display all geometry types defined by [RFC 7946 (GeoJSON)](https://tools.ietf.org/html/rfc7946): `Point`, `LineString`, `Polygon`, `MultiPoint`, `MultiLineString`, `MultiPolygon`.-You can load a GeoJSON file (with a single [`Feature`](https://tools.ietf.org/html/rfc7946#section-3.2) or a [`FeatureCollection`](https://tools.ietf.org/html/rfc7946#section-3.3)), newline-delimited GeoJSON (`.geojsonl`), KML, GPX, TCX, or a GeoArrow file. KML, GPX, TCX, and GeoJSONL are converted to GeoJSON features.+You can load a GeoJSON file (with a single [`Feature`](https://tools.ietf.org/html/rfc7946#section-3.2) or a [`FeatureCollection`](https://tools.ietf.org/html/rfc7946#section-3.3)), newline-delimited GeoJSON (`.geojsonl`), KML, GPX, TCX, Shapefile, FlatGeobuf, or a GeoArrow file. KML, GPX, TCX, GeoJSONL, Shapefile, and FlatGeobuf are converted to GeoJSON features.diff --git a/docs/user-guides/j-get-started.md b/docs/user-guides/j-get-started.mdindex 94d99202f..f1334db87 100644--- a/docs/user-guides/j-get-started.md+++ b/docs/user-guides/j-get-started.md@@ -7,7 +7,7 @@ Kepler.gl is a tool designed for geospatial data analysis. This guide will help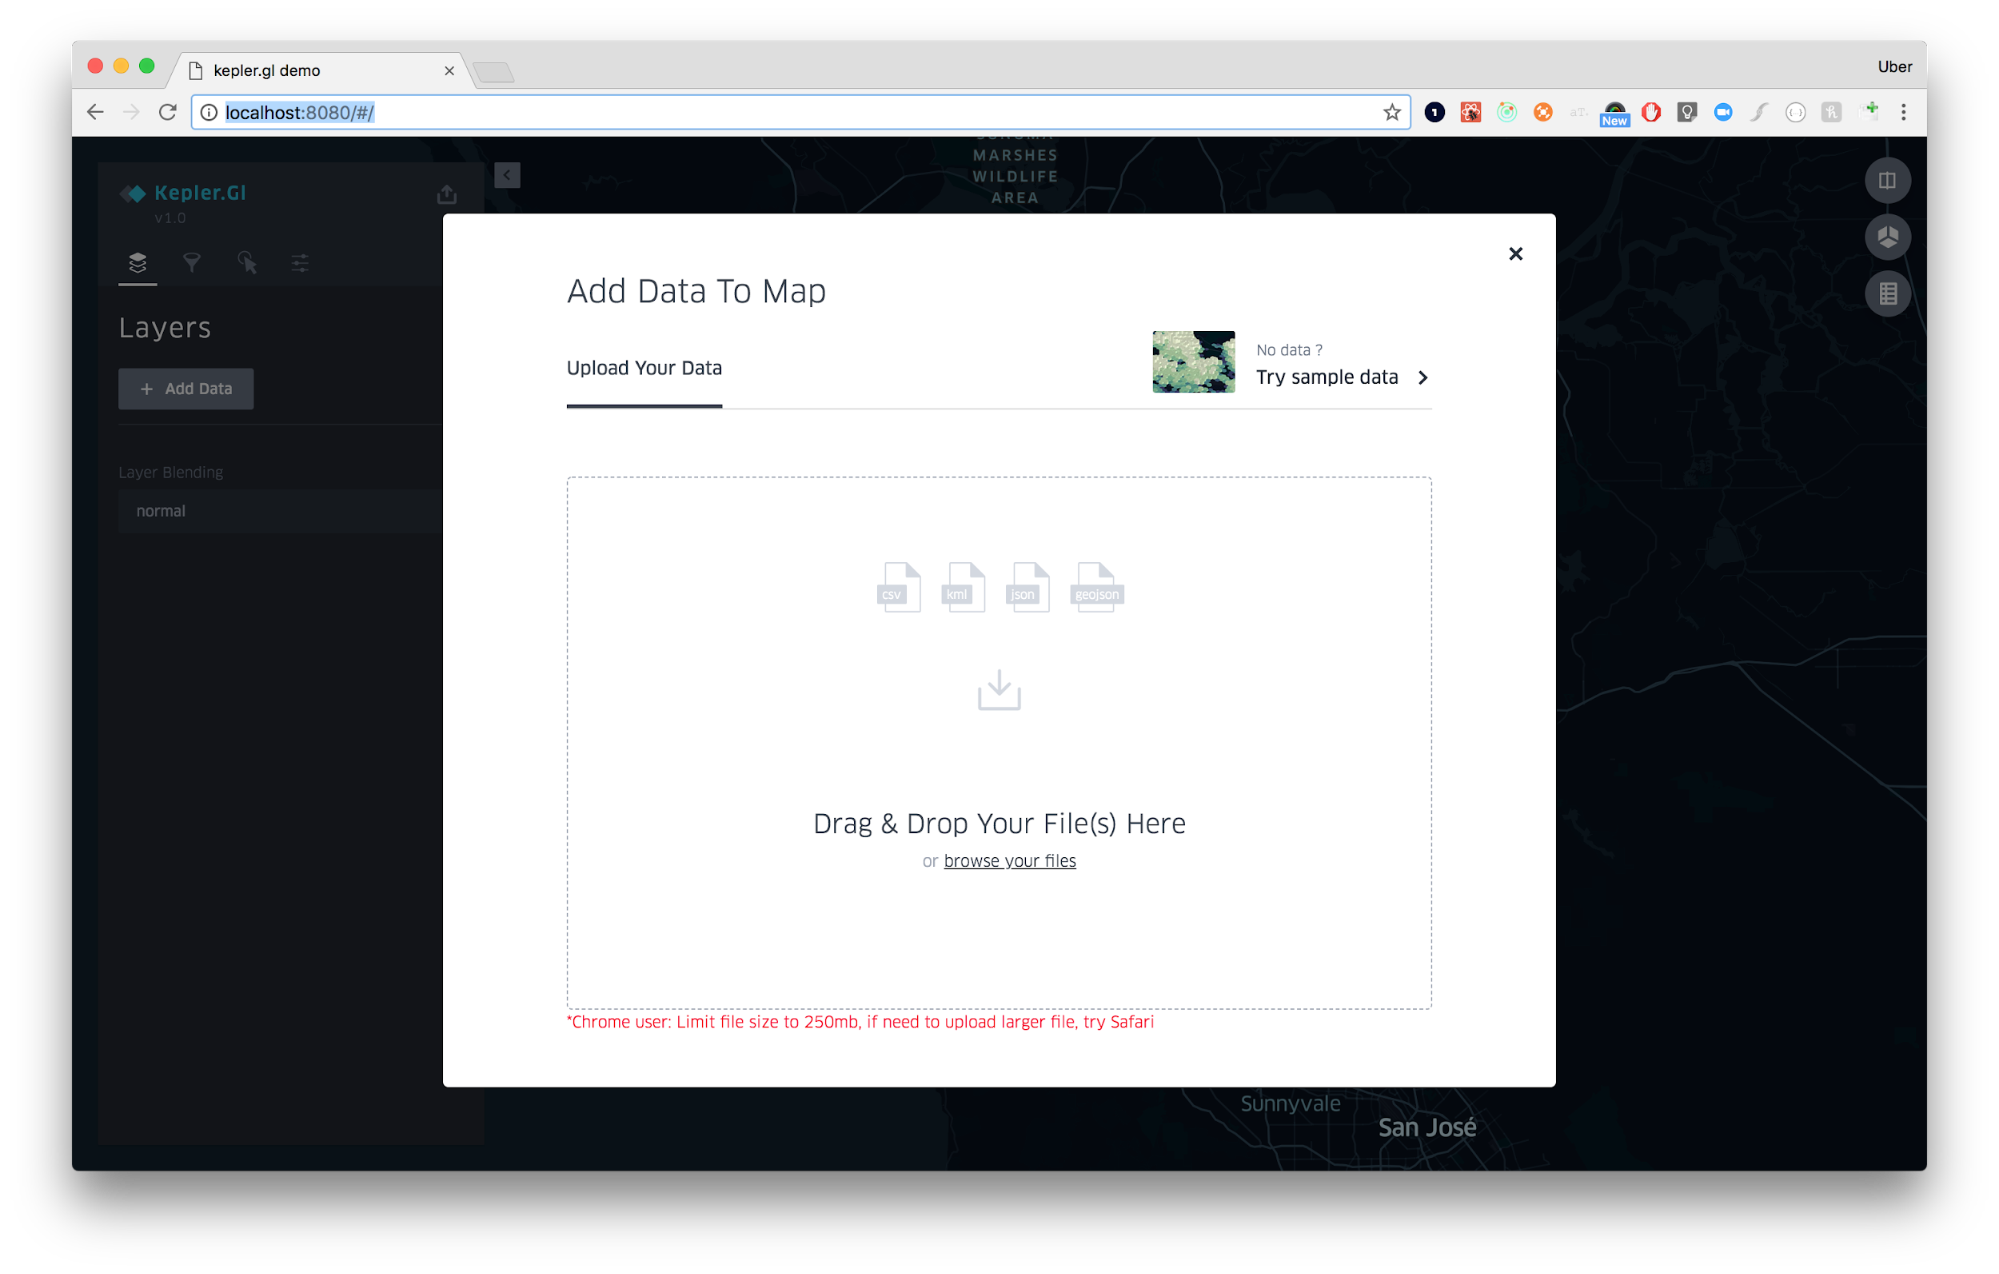-Kepler.gl will prompt you to add data to your map as soon as you open the web page. Upload your own CSV, GeoJSON, KML, or other [supported file](./b-kepler-gl-workflow/a-add-data-to-the-map.md#supported-file-formats), or add kepler.gl sample data.+Kepler.gl will prompt you to add data to your map as soon as you open the web page. Upload your own CSV, GeoJSON, KML, Shapefile, Excel, FlatGeobuf, or other [supported file](./b-kepler-gl-workflow/a-add-data-to-the-map.md#supported-file-formats), or add kepler.gl sample data.Sample data is a great way to explore and get familiar with kepler.gl’s features.Read more about adding [Add data to the map](./b-kepler-gl-workflow/a-add-data-to-the-map.md).diff --git a/package.json b/package.jsonindex 395909a1c..4e86ba75c 100644--- a/package.json+++ b/package.json@@ -269,8 +269,11 @@"@loaders.gl/draco": "4.4.1","@loaders.gl/gltf": "4.4.1","@loaders.gl/json": "4.4.1",+ "@loaders.gl/excel": "4.4.1",+ "@loaders.gl/flatgeobuf": "4.4.1","@loaders.gl/kml": "4.4.1","@loaders.gl/loader-utils": "4.4.1",+ "@loaders.gl/shapefile": "4.4.1","@loaders.gl/polyfills": "4.4.1","@loaders.gl/arrow": "4.4.1","@loaders.gl/parquet": "4.4.1",diff --git a/src/constants/src/dataset.ts b/src/constants/src/dataset.tsindex dbe90dda2..2e123d613 100644--- a/src/constants/src/dataset.ts+++ b/src/constants/src/dataset.ts@@ -22,7 +22,10 @@ export const REMOTE_FILE_FORMATS = ['ndjson','kml','gpx',- 'tcx'+ 'tcx',+ 'shp',+ 'xlsx',+ 'fgb'] as const;export type RemoteFileFormat = (typeof REMOTE_FILE_FORMATS)[number];@@ -36,7 +39,10 @@ export const REMOTE_FILE_MIME_TYPES: Record<Exclude<RemoteFileFormat, 'auto'>, sndjson: 'application/x-ndjson',kml: 'application/vnd.google-earth.kml+xml',gpx: 'application/gpx+xml',- tcx: 'application/vnd.garmin.tcx+xml'+ tcx: 'application/vnd.garmin.tcx+xml',+ shp: 'application/x-esri-shapefile',+ xlsx: 'application/vnd.openxmlformats-officedocument.spreadsheetml.sheet',+ fgb: 'application/x-flatgeobuf'};export const REMOTE_FILE_EXTENSIONS: Record<Exclude<RemoteFileFormat, 'auto'>, string> = {@@ -49,7 +55,10 @@ export const REMOTE_FILE_EXTENSIONS: Record<Exclude<RemoteFileFormat, 'auto'>, sndjson: 'ndjson',kml: 'kml',gpx: 'gpx',- tcx: 'tcx'+ tcx: 'tcx',+ shp: 'shp',+ xlsx: 'xlsx',+ fgb: 'fgb'};export const MIME_TO_REMOTE_FILE_EXTENSION: Record<string, string> = {@@ -70,7 +79,12 @@ export const MIME_TO_REMOTE_FILE_EXTENSION: Record<string, string> = {'application/json-seq': 'ndjson','application/vnd.google-earth.kml+xml': 'kml','application/gpx+xml': 'gpx',- 'application/vnd.garmin.tcx+xml': 'tcx'+ 'application/vnd.garmin.tcx+xml': 'tcx',+ 'application/x-esri-shapefile': 'shp',+ 'application/shp': 'shp',+ 'application/vnd.openxmlformats-officedocument.spreadsheetml.sheet': 'xlsx',+ 'application/x-flatgeobuf': 'fgb',+ 'application/flatgeobuf': 'fgb'};export const DATASET_REFRESH_INTERVAL_OPTIONS: {value: number; labelId: string}[] = [diff --git a/src/duckdb/src/table/duckdb-table.ts b/src/duckdb/src/table/duckdb-table.tsindex 975cce310..c2f06e386 100644--- a/src/duckdb/src/table/duckdb-table.ts+++ b/src/duckdb/src/table/duckdb-table.ts@@ -325,6 +325,14 @@ export class KeplerGlDuckDbTable extends KeplerTable {// csv file goes hereformat = DATASET_FORMATS.row;processor = processCsvRowObject; // directly import json object into duckdb-wasm+ } else if (+ data &&+ typeof data === 'object' &&+ (data.shape === 'object-row-table' || data.shape === 'row-table') &&+ Array.isArray(data.data)+ ) {+ format = DATASET_FORMATS.row;+ processor = () => processCsvRowObject(data.data);}return {processor, format};};diff --git a/src/processors/package.json b/src/processors/package.jsonindex 2daf2aaf3..d013915bf 100644--- a/src/processors/package.json+++ b/src/processors/package.json@@ -38,13 +38,17 @@"@loaders.gl/arrow": "^4.4.1","@loaders.gl/core": "^4.4.1","@loaders.gl/csv": "^4.4.1",+ "@loaders.gl/excel": "^4.4.1",+ "@loaders.gl/flatgeobuf": "^4.4.1","@loaders.gl/gis": "^4.4.1","@loaders.gl/json": "^4.4.1","@loaders.gl/kml": "^4.4.1","@loaders.gl/loader-utils": "^4.4.1","@loaders.gl/parquet": "^4.4.1","@loaders.gl/schema": "^4.4.1",+ "@loaders.gl/shapefile": "^4.4.1","@loaders.gl/wkt": "^4.4.1",+ "@loaders.gl/zip": "^4.4.1","@mapbox/geojson-normalize": "0.0.1","@turf/helpers": "^7.2.0","apache-arrow": ">=15.0.0",diff --git a/src/processors/src/file-handler.ts b/src/processors/src/file-handler.tsindex cffaac54f..c80f59dc4 100644--- a/src/processors/src/file-handler.ts+++ b/src/processors/src/file-handler.ts@@ -24,7 +24,13 @@ import {} from './data-processor';import {FileCacheItem, ValidKeplerGlMap} from './types';-import {getKeplerLoaders} from './loader-registry';+import {getKeplerLoaders, isKeplerFileFormatAccepted} from './loader-registry';+import {+ createCompanionFetch,+ getDroppedFileExtension,+ isZipFileName,+ unzipShapefileArchive+} from './shapefile-files';const BATCH_TYPE = {METADATA: 'metadata',@@ -60,6 +66,14 @@ const KML_LOADER_OPTIONS = {shape: 'geojson-table'};+const GIS_TABLE_LOADER_OPTIONS = {+ shape: 'geojson-table'+};++const EXCEL_LOADER_OPTIONS = {+ shape: 'object-row-table'+};+export type ProcessFileDataContent = {data: unknown;fileName: string;@@ -130,10 +144,16 @@ export function getGeoJsonFromLoaderResult(data: unknown): Feature | FeatureCollif (data.shape === 'geojson-table' && Array.isArray(data.features)) {return {type: 'FeatureCollection', features: data.features as Feature[]};}- if (- (data.shape === 'object-row-table' || data.shape === 'row-table') &&- isGeoJsonFeatureArray(data.data)- ) {+ if (data.shape === 'object-row-table' || data.shape === 'row-table') {+ if (isGeoJsonFeatureArray(data.data)) {+ return {type: 'FeatureCollection', features: data.data};+ }+ // Empty spreadsheet tables stay rows, not empty GeoJSON.+ return null;+ }+ // ShapefileLoader parseInBatches (v3 shape) yields `{data: Feature[]}`,+ // including empty files as `{data: []}`.+ if (Array.isArray(data.data) && (data.data.length === 0 || isGeoJsonFeatureArray(data.data))) {return {type: 'FeatureCollection', features: data.data};}return null;@@ -155,6 +175,53 @@ function getBatchRows(batch: {return Array.isArray(batchData) ? batchData : null;}+/**+ * Reconstruct the loader table/GIS identity from the current batch. Empty+ * shapefile (`{data: []}`) and spreadsheet (`object-row-table`) batches must+ * not be flattened to a bare `[]`, which processFileData cannot classify.+ *+ * JSON streaming first yields an empty `object-row-table` `partial-result`+ * (with `jsonpath` / `container`). That is a placeholder, not the dataset.+ */+function getAggregatedLoaderResult(+ batch: {+ shape?: string;+ type?: string;+ header?: unknown;+ data?: unknown;+ batchType?: string;+ jsonpath?: unknown;+ container?: unknown;+ },+ rows: unknown[],+ current: unknown+): unknown {+ if (+ batch.batchType === BATCH_TYPE.METADATA ||+ batch.batchType === BATCH_TYPE.PARTIAL_RESULT ||+ batch.batchType === BATCH_TYPE.FINAL_RESULT ||+ batch.jsonpath ||+ batch.container+ ) {+ return current;+ }+ if (batch.shape === 'geojson-table') {+ return {type: 'FeatureCollection', features: [...rows]};+ }+ // Non-empty CSV/Excel stay a flat row array (existing readBatch contract).+ if (rows.length > 0) {+ return current;+ }+ if (batch.shape === 'object-row-table' || batch.shape === 'row-table') {+ return {shape: batch.shape, data: []};+ }+ // ShapefileLoader parseInBatches always yields v3 `{header, data: Feature[]}`.+ if (batch.header != null && Array.isArray(batch.data)) {+ return {data: []};+ }+ return current;+}+export function isRowObject(json: any): boolean {return Array.isArray(json) && isPlainObject(json[0]);}@@ -212,7 +279,13 @@ function getPersistedRemoteFormat(keplerFormat?: string, fileName?: string): strconst extensionAliases: Record<string, string> = {jsonl: 'ndjson',ndgeojson: 'geojsonl',- ldgeojson: 'geojsonl'+ ldgeojson: 'geojsonl',+ xls: 'xlsx',+ xlsm: 'xlsx',+ xlsb: 'xlsx',+ shapefile: 'shp',+ excel: 'xlsx',+ flatgeobuf: 'fgb'};return extensionAliases[ext];}@@ -254,9 +327,7 @@ export async function* readBatch(batches.push(batchRows[i]);}}- if (batch.shape === 'geojson-table') {- result = {type: 'FeatureCollection', features: [...batches]};- }+ result = getAggregatedLoaderResult(batch, batches, result);}yield {@@ -285,16 +356,41 @@ export async function* readBatch(export async function readFileInBatches({file,loaders = [],- loadOptions = {}+ loadOptions = {},+ companionFiles,+ fileName}: {file: File;- fileCache: FileCacheItem[];- loaders: Loader[];- loadOptions: any;+ fileCache?: FileCacheItem[];+ loaders?: Loader[];+ loadOptions?: any;+ companionFiles?: File[];+ /** Display/progress name. Kept across zip → shapefile recursion. */+ fileName?: string;}): Promise<AsyncGenerator> {+ const displayFileName = fileName || file.name;+ if (isZipFileName(file.name) && isKeplerFileFormatAccepted('shp')) {+ const unzipped = await unzipShapefileArchive(file);+ const shapefile = unzipped.find(entry => getDroppedFileExtension(entry.name) === 'shp');+ if (!shapefile) {+ throw new Error('Zip archive does not contain a shapefile (.shp)');+ }+ return readFileInBatches({+ file: shapefile,+ loaders,+ loadOptions,+ companionFiles: [...unzipped, ...(companionFiles || [])],+ fileName: displayFileName+ });+ }+loaders = await getKeplerLoaders(file, loaders);const hasExtension = /\.[a-z0-9]+$/i.test(file.name);const mimeType = !hasExtension && file.type ? file.type : undefined;+ // Shapefile sidecars are resolved via a custom fetch that cannot be cloned+ // into a worker. Other formats keep loaders.gl worker parsing.+ const isShapefile = getDroppedFileExtension(file.name) === 'shp';+ const companionFetch = isShapefile ? createCompanionFetch(companionFiles) : undefined;loadOptions = {csv: CSV_LOADER_OPTIONS,arrow: ARROW_LOADER_OPTIONS,@@ -303,8 +399,15 @@ export async function readFileInBatches({kml: KML_LOADER_OPTIONS,gpx: KML_LOADER_OPTIONS,tcx: KML_LOADER_OPTIONS,+ shapefile: GIS_TABLE_LOADER_OPTIONS,+ shp: {_maxDimensions: 2},+ excel: EXCEL_LOADER_OPTIONS,+ flatgeobuf: GIS_TABLE_LOADER_OPTIONS,+ gis: {reproject: true, _targetCrs: 'WGS84'},metadata: true,+ ...(isShapefile ? {worker: false} : {}),...(mimeType ? {mimeType} : {}),+ ...(companionFetch ? {fetch: companionFetch} : {}),...loadOptions};@@ -319,7 +422,7 @@ export async function readFileInBatches({return readBatch(progressIterator,- file.name,+ displayFileName,sourceUrl,keplerFormat,refreshIntervalMs,@@ -366,6 +469,15 @@ export async function processFileData({// csv file goes hereformat = DATASET_FORMATS.row;processor = processRowObject;+ } else if (isPlainObject(data)) {+ const tableRows = data.data;+ if (+ (data.shape === 'object-row-table' || data.shape === 'row-table') &&+ Array.isArray(tableRows)+ ) {+ format = DATASET_FORMATS.row;+ processor = () => processRowObject(tableRows);+ }}}if (format && processor) {diff --git a/src/processors/src/index.ts b/src/processors/src/index.tsindex b91a6808c..2b24f7f64 100644--- a/src/processors/src/index.ts+++ b/src/processors/src/index.ts@@ -7,3 +7,4 @@ export * from './remote-file';export * from './types';export * from './kepler-csv-loader';export * from './loader-registry';+export * from './shapefile-files';diff --git a/src/processors/src/loader-registry.ts b/src/processors/src/loader-registry.tsindex 990bc81bd..56bc8a0cf 100644--- a/src/processors/src/loader-registry.ts+++ b/src/processors/src/loader-registry.ts@@ -33,6 +33,7 @@ const NDJSON_MIME_TYPES = ['application/geo+x-ldjson','application/geo+json-seq'];+const FLATGEOBUF_MIME_TYPES = ['application/x-flatgeobuf', 'application/flatgeobuf'];const DEFAULT_LOADER_ENTRIES: KeplerLoaderEntry[] = [{@@ -89,6 +90,40 @@ const DEFAULT_LOADER_ENTRIES: KeplerLoaderEntry[] = [extensions: ['parquet'],mimeTypes: ['application/vnd.apache.parquet'],load: async () => (await import('@loaders.gl/parquet')).ParquetArrowLoader+ },+ {+ id: 'shapefile',+ extensions: ['shp'],+ mimeTypes: ['application/x-esri-shapefile', 'application/shp'],+ load: async () => {+ const {ShapefileLoader} = await import('@loaders.gl/shapefile');+ // loaders.gl SHP magic also matches .shx sidecar files+ const loader = {...ShapefileLoader};+ delete (loader as {tests?: unknown}).tests;+ return loader;+ }+ },+ {+ id: 'excel',+ extensions: ['xlsx', 'xls', 'xlsm', 'xlsb'],+ mimeTypes: [+ 'application/vnd.openxmlformats-officedocument.spreadsheetml.sheet',+ 'application/vnd.ms-excel',+ 'application/vnd.ms-excel.sheet.macroenabled.12',+ 'application/vnd.ms-excel.sheet.binary.macroenabled.12'+ ],+ load: async () => (await import('@loaders.gl/excel')).ExcelLoader+ },+ {+ id: 'flatgeobuf',+ extensions: ['fgb'],+ mimeTypes: FLATGEOBUF_MIME_TYPES,+ load: async () => {+ const {FlatGeobufLoader} = await import('@loaders.gl/flatgeobuf');+ // loaders.gl 4.4.1 advertises application/octet-stream, which selectLoader+ // matches before magic bytes.+ return {...FlatGeobufLoader, mimeTypes: FLATGEOBUF_MIME_TYPES};+ }}];@@ -111,7 +146,21 @@ const TOKEN_TO_LOADER_ID: Record<string, string> = {tcx: 'tcx',arrow: 'arrow',feather: 'arrow',- parquet: 'parquet'+ parquet: 'parquet',+ shp: 'shapefile',+ shapefile: 'shapefile',+ zip: 'shapefile',+ dbf: 'shapefile',+ shx: 'shapefile',+ prj: 'shapefile',+ cpg: 'shapefile',+ xlsx: 'excel',+ xls: 'excel',+ xlsm: 'excel',+ xlsb: 'excel',+ excel: 'excel',+ fgb: 'flatgeobuf',+ flatgeobuf: 'flatgeobuf'};const REMOTE_FORMAT_TO_LOADER_ID: Record<Exclude<RemoteFileFormat, 'auto'>, string> = {@@ -124,7 +173,10 @@ const REMOTE_FORMAT_TO_LOADER_ID: Record<Exclude<RemoteFileFormat, 'auto'>, strindjson: 'ndjson',kml: 'kml',gpx: 'gpx',- tcx: 'tcx'+ tcx: 'tcx',+ shp: 'shapefile',+ xlsx: 'excel',+ fgb: 'flatgeobuf'};function getAcceptedLoaderIdSet(): Set<string> | null {@@ -178,6 +230,18 @@ function matchesFile(entry: KeplerLoaderEntry, file: FileMetadata): boolean {);}+/**+ * loaders.gl selectLoader matches MIME before magic bytes. Drop catch-all types+ * such as application/octet-stream so extensionless Arrow/Parquet still+ * use content detection.+ */+function withKeplerMimeTypes(loader: Loader, mimeTypes: string[]): Loader {+ if (!(loader.mimeTypes || []).includes('application/octet-stream')) {+ return loader;+ }+ return {...loader, mimeTypes};+}+/*** Resolve the loaders needed for a file. Loader modules are imported only for* matching extensions/MIME types; extensionless or unknown files retain core's@@ -190,7 +254,9 @@ export async function getKeplerLoaders(const availableEntries = getAcceptedKeplerLoaderEntries();const matchingEntries = availableEntries.filter(entry => matchesFile(entry, file));const entries = matchingEntries.length ? matchingEntries : availableEntries;- const defaultLoaders = await Promise.all(entries.map(entry => entry.load()));+ const defaultLoaders = await Promise.all(+ entries.map(async entry => withKeplerMimeTypes(await entry.load(), entry.mimeTypes))+ );const customLoaderIds = new Set(customLoaders.map(loader => loader.id));return [...customLoaders, ...defaultLoaders.filter(loader => !customLoaderIds.has(loader.id))];diff --git a/src/processors/src/shapefile-files.ts b/src/processors/src/shapefile-files.tsnew file mode 100644index 000000000..fd4c48bcf--- /dev/null+++ b/src/processors/src/shapefile-files.ts@@ -0,0 +1,90 @@+// SPDX-License-Identifier: MIT+// Copyright contributors to the kepler.gl project++import {_BrowserFileSystem, parse} from '@loaders.gl/core';++export const SHAPEFILE_SIDECAR_EXTENSIONS = ['dbf', 'shx', 'prj', 'cpg'] as const;+export const SHAPEFILE_SOURCE_EXTENSIONS = ['shp', 'zip'] as const;++type NamedFile = {name: string};++export function getDroppedFileExtension(fileName = ''): string {+ const match = fileName.match(/\.([a-z0-9]+)$/i);+ return match ? match[1].toLowerCase() : '';+}++export function isShapefileSidecarFileName(fileName: string): boolean {+ return (SHAPEFILE_SIDECAR_EXTENSIONS as readonly string[]).includes(+ getDroppedFileExtension(fileName)+ );+}++export function isZipFileName(fileName: string): boolean {+ return getDroppedFileExtension(fileName) === 'zip';+}++export function isShapefileSourceFileName(fileName: string): boolean {+ return (SHAPEFILE_SOURCE_EXTENSIONS as readonly string[]).includes(+ getDroppedFileExtension(fileName)+ );+}++/**+ * Sidecar files (.dbf, .shx, .prj, .cpg) are not datasets. Skip them when a+ * .shp or shapefile .zip is also present so they can be used as companions.+ */+export function getFilesToParse<T extends NamedFile>(files: T[]): T[] {+ const list = Array.from(files);+ const hasShapefileSource = list.some(file => isShapefileSourceFileName(file.name));+ if (!hasShapefileSource) {+ return list;+ }+ return list.filter(file => !isShapefileSidecarFileName(file.name));+}++export function createCompanionFetch(+ files?: File[]+): ((url: string) => Promise<Response>) | undefined {+ if (+ !files?.length ||+ typeof File === 'undefined' ||+ files.every(file => !(file instanceof File))+ ) {+ return undefined;+ }+ const fileSystem = new _BrowserFileSystem(files);+ return fileSystem.fetch.bind(fileSystem);+}++function fileNameFromArchivePath(path: string): string {+ const parts = path.split(/[/\\]/);+ return parts[parts.length - 1] || path;+}++/**+ * Unpack a zip that contains a shapefile. Only top-level .shp plus sidecars+ * are returned; nested folders are ignored.+ */+export async function unzipShapefileArchive(zipFile: File): Promise<File[]> {+ const {ZipLoader} = await import('@loaders.gl/zip');+ const zipData = await zipFile.arrayBuffer();+ const archive = (await parse(zipData, ZipLoader, {worker: false})) as Record<string, ArrayBuffer>;+ const files: File[] = [];++ for (const [path, buffer] of Object.entries(archive || {})) {+ if (path.includes('/')) {+ continue;+ }+ const name = fileNameFromArchivePath(path);+ const ext = getDroppedFileExtension(name);+ if (ext === 'shp' || (SHAPEFILE_SIDECAR_EXTENSIONS as readonly string[]).includes(ext)) {+ files.push(new File([buffer], name));+ }+ }++ if (!files.some(file => getDroppedFileExtension(file.name) === 'shp')) {+ throw new Error('Zip archive does not contain a shapefile (.shp)');+ }++ return files;+}diff --git a/src/reducers/src/vis-state-selectors.ts b/src/reducers/src/vis-state-selectors.tsindex 1cbab21b6..ae3d5b72f 100644--- a/src/reducers/src/vis-state-selectors.ts+++ b/src/reducers/src/vis-state-selectors.ts@@ -5,7 +5,7 @@ import {createSelector} from 'reselect';import {isKeplerFileFormatAccepted} from '@kepler.gl/processors';import {getApplicationConfig} from '@kepler.gl/utils';-// NOTE: default formats must match file-handler-test.js+// NOTE: default formats must match loader-registry-test.jsconst DEFAULT_FILE_EXTENSIONS = ['csv','tsv',@@ -21,10 +21,22 @@ const DEFAULT_FILE_EXTENSIONS = ['ldgeojson','kml','gpx',- 'tcx'+ 'tcx',+ 'shp',+ 'zip',+ 'dbf',+ 'shx',+ 'prj',+ 'cpg',+ 'xlsx',+ 'xls',+ 'xlsm',+ 'xlsb',+ 'fgb'];-// One chip per format family. Aliases (tsv, jsonl, ndgeojson, …) stay accepted-// via DEFAULT_FILE_EXTENSIONS but are not shown as separate icons/labels.+// One chip per format family. Aliases (tsv, jsonl, ndgeojson, zip, shapefile,+// excel, flatgeobuf, sidecars, …) stay accepted via DEFAULT_FILE_EXTENSIONS+// and listed in DISPLAY_FILE_FORMATS, but are not shown as extra icons.const DISPLAY_FILE_EXTENSIONS = ['csv','json',@@ -45,7 +57,10 @@ const DISPLAY_FILE_FORMATS = ['GeoJSONL','KML','GPX',- 'TCX'+ 'TCX',+ 'Shapefile',+ 'Excel',+ 'FlatGeobuf'];interface LoaderInfo {diff --git a/src/reducers/src/vis-state-updaters.ts b/src/reducers/src/vis-state-updaters.tsindex c8512b72f..3ae9b368f 100644--- a/src/reducers/src/vis-state-updaters.ts+++ b/src/reducers/src/vis-state-updaters.ts@@ -152,7 +152,7 @@ import {} from './vis-state-merger';import KeplerGLSchema, {Merger, PostMergerPayload, VisState} from '@kepler.gl/schemas';-import {loadExternallyHostedDataset, processGeojson} from '@kepler.gl/processors';+import {getFilesToParse, loadExternallyHostedDataset, processGeojson} from '@kepler.gl/processors';import {Filter,@@ -4142,14 +4142,21 @@ export const loadFilesUpdater = (return state;}- const fileLoadingProgress = Array.from(files).reduce(+ const companionFiles = Array.from(files);+ const filesToLoad = getFilesToParse(companionFiles);+ if (!filesToLoad.length) {+ return state;+ }++ const fileLoadingProgress = filesToLoad.reduce((accu, f, i) => merge_(initialFileLoadingProgress(f, i))(accu),{});const fileLoading = {fileCache: [],- filesToLoad: files,+ filesToLoad,+ companionFiles,onFinish};@@ -4215,13 +4222,20 @@ export function loadNextFileUpdater(state: VisState): VisState {file,nextState.fileLoading && nextState.fileLoading.fileCache,loaders,- loadOptions+ loadOptions,+ nextState.fileLoading ? nextState.fileLoading.companionFiles : undefined));}-export function makeLoadFileTask(file, fileCache, loaders: Loader[] = [], loadOptions = {}) {- return LOAD_FILE_TASK({file, fileCache, loaders, loadOptions}).bimap(+export function makeLoadFileTask(+ file,+ fileCache,+ loaders: Loader[] = [],+ loadOptions = {},+ companionFiles?: File[]+) {+ return LOAD_FILE_TASK({file, fileCache, loaders, loadOptions, companionFiles}).bimap(// prettier ignore// successgen =>diff --git a/src/tasks/src/index.ts b/src/tasks/src/index.tsindex a64e2d5bb..7774eda9c 100644--- a/src/tasks/src/index.ts+++ b/src/tasks/src/index.ts@@ -25,8 +25,8 @@ export {export type {TaskDescriptor} from '@kepler.gl/tasks-core';export const LOAD_FILE_TASK = Task.fromPromise(- ({file, fileCache, loaders, loadOptions}) =>- readFileInBatches({file, fileCache, loaders, loadOptions}),+ ({file, fileCache, loaders, loadOptions, companionFiles}) =>+ readFileInBatches({file, fileCache, loaders, loadOptions, companionFiles}),'LOAD_FILE_TASK');diff --git a/src/types/reducers.d.ts b/src/types/reducers.d.tsindex b4a44ba1d..1a7f45099 100644--- a/src/types/reducers.d.ts+++ b/src/types/reducers.d.ts@@ -416,7 +416,8 @@ export type MapInfo = {description: string;};export type FileLoading = {- filesToLoad: FileList;+ filesToLoad: FileList | File[];+ companionFiles?: File[];onFinish: (payload: any) => any;fileCache: any[];};diff --git a/src/utils/src/application-config.ts b/src/utils/src/application-config.tsindex 59c82824d..e68bbc3f7 100644--- a/src/utils/src/application-config.ts+++ b/src/utils/src/application-config.ts@@ -93,7 +93,21 @@ export type KeplerAcceptedFileFormat =| 'tcx'| 'arrow'| 'feather'- | 'parquet';+ | 'parquet'+ | 'shp'+ | 'shapefile'+ | 'zip'+ | 'dbf'+ | 'shx'+ | 'prj'+ | 'cpg'+ | 'xlsx'+ | 'xls'+ | 'xlsm'+ | 'xlsb'+ | 'excel'+ | 'fgb'+ | 'flatgeobuf';export type KeplerApplicationConfig = {/** Default name of export HTML file, can be overridden by user */@@ -214,7 +228,7 @@ export type KeplerApplicationConfig = {/*** File formats Kepler may load from drag-and-drop, the file picker, and remote URLs.- * Values are format ids or extensions (`csv`, `geojson`, `kml`, `geojsonl`, …).+ * Values are format ids or extensions (`csv`, `geojson`, `kml`, `shp`, `xlsx`, `fgb`, …).* When omitted or `null`, every built-in format is accepted.** @examplediff --git a/test/node/processors/file-handler-test.js b/test/node/processors/file-handler-test.jsindex e357d5a28..8e6ff7ef0 100644--- a/test/node/processors/file-handler-test.js+++ b/test/node/processors/file-handler-test.js@@ -8,7 +8,8 @@ import {filesToDataPayload,processFileData,processArrowBatches,- getGeoJsonFromLoaderResult+ getGeoJsonFromLoaderResult,+ readBatch} from '@kepler.gl/processors';import {getDatasetRefreshIntervalMs} from '@kepler.gl/constants';import * as arrow from 'apache-arrow';@@ -422,6 +423,140 @@ test('#file-handler -> processFileData Feature array is geojson', async t => {t.end();});+test('#file-handler -> shapefile-shaped loader output becomes GeoJSON', async t => {+ const data = {+ data: [+ {+ type: 'Feature',+ properties: {name: 'alpha'},+ geometry: {type: 'Point', coordinates: [-122.4, 37.8]}+ }+ ]+ };+ t.equal(+ getGeoJsonFromLoaderResult(data).features.length,+ 1,+ 'should unwrap shapefile Feature arrays'+ );++ const processed = await processFileData({+ content: {fileName: 'places.shp', data},+ fileCache: []+ });+ t.equal(processed[0].info.format, 'geojson', 'shapefile output should process as geojson');+ t.equal(processed[0].data.rows.length, 1, 'should keep the shapefile feature');+ t.end();+});++async function readLastAggregatedBatch(iterator, fileName) {+ const generator = readBatch(iterator, fileName);+ let last;+ for await (const batch of generator) {+ last = batch;+ }+ return last;+}++test('#file-handler -> empty GIS loader output becomes an empty GeoJSON dataset', async t => {+ const emptyShapefile = await processFileData({+ content: {fileName: 'empty.shp', data: {data: []}},+ fileCache: []+ });+ t.equal(emptyShapefile[0].info.format, 'geojson', 'empty shapefile output should be geojson');+ t.equal(emptyShapefile[0].data.rows.length, 0, 'should keep zero features');++ const emptyTable = await processFileData({+ content: {+ fileName: 'empty.fgb',+ data: {shape: 'geojson-table', type: 'FeatureCollection', features: []}+ },+ fileCache: []+ });+ t.equal(emptyTable[0].info.format, 'geojson', 'empty geojson-table should be geojson');+ t.equal(emptyTable[0].data.rows.length, 0, 'should keep zero geojson-table features');++ const emptyExcel = await processFileData({+ content: {fileName: 'empty.xlsx', data: {shape: 'object-row-table', data: []}},+ fileCache: []+ });+ t.equal(emptyExcel[0].info.format, 'row', 'empty spreadsheet tables should stay rows');+ t.end();+});++test('#file-handler -> readBatch does not wrap JSON streaming placeholders', async t => {+ async function* geojsonStream() {+ yield {batchType: 'metadata', shape: 'metadata', data: []};+ yield {+ shape: 'object-row-table',+ batchType: 'partial-result',+ container: {type: 'FeatureCollection', features: []},+ data: [],+ jsonpath: '$.features'+ };+ yield {+ data: [+ {+ type: 'Feature',+ properties: {name: 'alpha'},+ geometry: {type: 'Point', coordinates: [0, 1]}+ }+ ],+ jsonpath: '$.features',+ length: 1+ };+ }++ const generator = readBatch(geojsonStream(), 'places.geojson');+ await generator.next();+ const partial = await generator.next();+ t.equal(partial.value.batchType, 'partial-result', 'should yield the JSON partial-result');+ t.equal(partial.value.data.length, 0, 'partial-result should keep an empty array');+ const dataBatch = await generator.next();+ t.equal(dataBatch.value.data.length, 1, 'data batch should stay a feature array');+ t.end();+});++test('#file-handler -> readBatch preserves empty loader identity', async t => {+ async function* emptyShapefileBatches() {+ yield {header: {length: 50}, data: []};+ }+ const shapefileBatch = await readLastAggregatedBatch(emptyShapefileBatches(), 'empty.shp');+ const emptyShapefile = await processFileData({content: shapefileBatch, fileCache: []});+ t.equal(emptyShapefile[0].info.format, 'geojson', 'empty shapefile batches should stay geojson');+ t.equal(emptyShapefile[0].data.rows.length, 0, 'should keep zero shapefile features');++ async function* emptyExcelBatches() {+ yield {shape: 'object-row-table', data: []};+ }+ const excelBatch = await readLastAggregatedBatch(emptyExcelBatches(), 'empty.xlsx');+ const emptyExcel = await processFileData({content: excelBatch, fileCache: []});+ t.equal(emptyExcel[0].info.format, 'row', 'empty spreadsheet batches should stay rows');+ t.equal(emptyExcel[0].data.rows.length, 0, 'should keep zero spreadsheet rows');++ async function* emptyFlatGeobufBatches() {+ yield {batchType: 'metadata'};+ yield {shape: 'geojson-table', type: 'FeatureCollection', features: []};+ }+ const fgbBatch = await readLastAggregatedBatch(emptyFlatGeobufBatches(), 'empty.fgb');+ const emptyFgb = await processFileData({content: fgbBatch, fileCache: []});+ t.equal(emptyFgb[0].info.format, 'geojson', 'empty FlatGeobuf batches should stay geojson');+ t.equal(emptyFgb[0].data.rows.length, 0, 'should keep zero FlatGeobuf features');+ t.end();+});++test('#file-handler -> object-row-table becomes a row dataset', async t => {+ const processed = await processFileData({+ content: {+ fileName: 'table.xlsx',+ data: {shape: 'object-row-table', data: [{name: 'alpha', value: 1}]}+ },+ fileCache: []+ });+ t.equal(processed[0].info.format, 'row', 'Excel-shaped tables should process as rows');+ t.equal(processed[0].data.rows.length, 1, 'should keep the spreadsheet row');+ t.end();+});+test('#file-handler -> rows with type Feature but no geometry stay tables', async t => {const rows = [{type: 'Feature', name: 'alpha', lat: 37.8, lng: -122.4},diff --git a/test/node/processors/index.js b/test/node/processors/index.jsindex 71823c083..4650f1bdc 100644--- a/test/node/processors/index.js+++ b/test/node/processors/index.js@@ -4,3 +4,4 @@import './file-handler-test';import './remote-file-test';import './loader-registry-test';+import './shapefile-files-test';diff --git a/test/node/processors/loader-registry-test.js b/test/node/processors/loader-registry-test.jsindex 72c446fd1..096acd8ae 100644--- a/test/node/processors/loader-registry-test.js+++ b/test/node/processors/loader-registry-test.js@@ -17,6 +17,7 @@ import {getFileFormatNames} from '@kepler.gl/reducers';import {initApplicationConfig} from '@kepler.gl/utils';+import {tableFromJSON, tableToIPC} from 'apache-arrow';test('#loader-registry -> resolves matching loaders lazily', async t => {const loaders = await getKeplerLoaders({name: 'data.csv', type: ''});@@ -51,6 +52,56 @@ test('#loader-registry -> resolves NDJSON and GIS loaders by extension', async tconst tcx = await getKeplerLoaders({name: 'activity.tcx', type: ''});t.equal(tcx[0].id, 'tcx', 'tcx should resolve to the TCX loader');++ const shp = await getKeplerLoaders({name: 'places.shp', type: ''});+ t.equal(shp[0].id, 'shapefile', 'shp should resolve to the shapefile loader');+ t.notOk(shp[0].tests, 'shapefile magic tests should be stripped so .shx is not parsed as data');++ const xlsx = await getKeplerLoaders({name: 'table.xlsx', type: ''});+ t.equal(xlsx[0].id, 'excel', 'xlsx should resolve to the Excel loader');++ const fgb = await getKeplerLoaders({name: 'places.fgb', type: ''});+ t.equal(fgb[0].id, 'flatgeobuf', 'fgb should resolve to the FlatGeobuf loader');+ t.end();+});++test('#loader-registry -> generic octet-stream does not lock in shapefile', async t => {+ const extensionless = await getKeplerLoaders({+ name: 'abc123',+ type: 'application/octet-stream'+ });+ t.ok(+ extensionless.length > 1,+ 'extensionless octet-stream should keep content-based loader selection'+ );+ t.ok(+ extensionless.some(loader => loader.id === 'arrow'),+ 'Arrow should stay a candidate for generic binary MIME'+ );+ t.ok(+ extensionless.some(loader => loader.id === 'flatgeobuf'),+ 'FlatGeobuf should stay a candidate for generic binary MIME'+ );+ t.ok(+ extensionless.every(loader => !(loader.mimeTypes || []).includes('application/octet-stream')),+ 'no candidate should claim application/octet-stream (selectLoader matches MIME before magic)'+ );++ const fgb = await getKeplerLoaders({+ name: 'places.fgb',+ type: 'application/octet-stream'+ });+ t.equal(fgb[0].id, 'flatgeobuf', '.fgb should still win from the extension, not shapefile MIME');+ t.notOk(+ (fgb[0].mimeTypes || []).includes('application/octet-stream'),+ 'FlatGeobuf should not advertise the generic octet-stream MIME'+ );++ const shpMime = await getKeplerLoaders({+ name: 'dataset',+ type: 'application/x-esri-shapefile'+ });+ t.equal(shpMime[0].id, 'shapefile', 'specific shapefile MIME should still resolve shapefile');t.end();});@@ -80,6 +131,20 @@ async function readLastBatch(file) {return last;}+test('#loader-registry -> extensionless octet-stream Arrow is not parsed as FlatGeobuf', async t => {+ const bytes = tableToIPC(tableFromJSON([{name: 'alpha', value: 1}]), 'file');+ const file = new File([bytes], 'abc123', {type: 'application/octet-stream'});+ const batch = await readLastBatch(file);+ const processed = await processFileData({content: batch, fileCache: []});++ t.equal(processed[0].info.format, 'arrow', 'extensionless octet-stream Arrow should stay Arrow');+ t.ok(+ processed[0].data.fields.some(field => field.name === 'name'),+ 'should keep Arrow columns, not GIS features'+ );+ t.end();+});+test('#loader-registry -> file loading uses the async loader path', async t => {const file = new File(['name,value\nalpha,1\n'], 'data.csv', {type: 'text/csv'});const generator = await readFileInBatches({file, fileCache: [], loaders: [], loadOptions: {}});@@ -187,6 +252,43 @@ test('#loader-registry -> tcx files become GeoJSON datasets', async t => {t.end();});+test('#loader-registry -> excel files become row datasets', async t => {+ // eslint-disable-next-line @typescript-eslint/no-var-requires+ const XLSX = require('xlsx');+ const workbook = XLSX.utils.book_new();+ const sheet = XLSX.utils.json_to_sheet([{name: 'alpha', value: 1}]);+ XLSX.utils.book_append_sheet(workbook, sheet, 'Sheet1');+ const buffer = XLSX.write(workbook, {type: 'array', bookType: 'xlsx'});+ const file = new File([buffer], 'table.xlsx', {type: ''});+ const batch = await readLastBatch(file);+ const processed = await processFileData({content: batch, fileCache: []});++ t.equal(processed[0].info.format, 'row', 'Excel should process as rows');+ t.equal(processed[0].data.rows.length, 1, 'should keep the spreadsheet row');+ t.end();+});++test('#loader-registry -> flatgeobuf files become GeoJSON datasets', async t => {+ const {serialize} = await import('flatgeobuf/lib/mjs/geojson.js');+ const bytes = serialize({+ type: 'FeatureCollection',+ features: [+ {+ type: 'Feature',+ properties: {name: 'alpha'},+ geometry: {type: 'Point', coordinates: [-122.4, 37.8]}+ }+ ]+ });+ const file = new File([bytes], 'places.fgb', {type: ''});+ const batch = await readLastBatch(file);+ const processed = await processFileData({content: batch, fileCache: []});++ t.equal(processed[0].info.format, 'geojson', 'FlatGeobuf should process as geojson');+ t.equal(processed[0].data.rows.length, 1, 'should keep the FlatGeobuf feature');+ t.end();+});+test('#loader-registry -> acceptedFileFormats defaults to all formats', t => {t.ok(isKeplerFileFormatAccepted('kml'), 'kml is accepted by default');t.ok(isKeplerFileFormatAccepted('geojsonl'), 'geojsonl is accepted by default');@@ -203,14 +305,37 @@ test('#loader-registry -> acceptedFileFormats defaults to all formats', t => {getFileExtensions({loaders: []}).includes('geojsonl'),'aliases stay accepted even when not shown as icons');+ t.ok(isKeplerFileFormatAccepted('shp'), 'shp is accepted by default');+ t.ok(isKeplerFileFormatAccepted('xlsx'), 'xlsx is accepted by default');+ t.ok(isKeplerFileFormatAccepted('fgb'), 'fgb is accepted by default');+ t.ok(getFileExtensions({loaders: []}).includes('shp'), 'file picker includes shp');+ t.ok(getFileExtensions({loaders: []}).includes('zip'), 'file picker includes shapefile zip');+ t.ok(getFileExtensions({loaders: []}).includes('xlsx'), 'file picker includes xlsx');+ t.ok(getFileExtensions({loaders: []}).includes('fgb'), 'file picker includes fgb');+ t.ok(getAcceptedRemoteFileFormats().includes('shp'), 'remote format list includes shp');+ t.ok(getAcceptedRemoteFileFormats().includes('xlsx'), 'remote format list includes xlsx');+ t.ok(getAcceptedRemoteFileFormats().includes('fgb'), 'remote format list includes fgb');t.deepEqual(getDisplayedFileExtensions({loaders: []}),['csv', 'json', 'geojson', 'arrow', 'parquet', 'geojsonl', 'kml', 'gpx', 'tcx'],- 'Add Data icons show one chip per format family'+ 'Add Data icons omit Shapefile, Excel, and FlatGeobuf');t.deepEqual(getFileFormatNames({loaders: []}),- ['CSV', 'Json', 'GeoJSON', 'Arrow', 'Parquet', 'GeoJSONL', 'KML', 'GPX', 'TCX'],+ [+ 'CSV',+ 'Json',+ 'GeoJSON',+ 'Arrow',+ 'Parquet',+ 'GeoJSONL',+ 'KML',+ 'GPX',+ 'TCX',+ 'Shapefile',+ 'Excel',+ 'FlatGeobuf'+ ],'upload copy lists format families, not every alias');t.end();@@ -224,6 +349,8 @@ test('#loader-registry -> acceptedFileFormats restricts loaders and UI lists', at.ok(isKeplerFileFormatAccepted('GeoJSON'), 'geojson remains accepted');t.notOk(isKeplerFileFormatAccepted('kml'), 'kml is rejected');t.notOk(isKeplerFileFormatAccepted('parquet'), 'parquet is rejected');+ t.notOk(isKeplerFileFormatAccepted('shp'), 'shp is rejected');+ t.notOk(isKeplerFileFormatAccepted('xlsx'), 'xlsx is rejected');const ids = getAcceptedKeplerLoaderEntries().map(entry => entry.id);t.deepEqual(ids.sort(), ['csv', 'json'], 'only matching built-in loaders remain');diff --git a/test/node/processors/remote-file-test.js b/test/node/processors/remote-file-test.jsindex 4ac41b70f..06bd7b0ea 100644--- a/test/node/processors/remote-file-test.js+++ b/test/node/processors/remote-file-test.js@@ -34,6 +34,12 @@ test('#remote-file -> getMimeTypeForFormat', t => {t.equal(getMimeTypeForFormat('arrow'), 'application/vnd.apache.arrow.file');t.equal(getMimeTypeForFormat('kml'), 'application/vnd.google-earth.kml+xml');t.equal(getMimeTypeForFormat('geojsonl'), 'application/geo+x-ndjson');+ t.equal(getMimeTypeForFormat('shp'), 'application/x-esri-shapefile');+ t.equal(+ getMimeTypeForFormat('xlsx'),+ 'application/vnd.openxmlformats-officedocument.spreadsheetml.sheet'+ );+ t.equal(getMimeTypeForFormat('fgb'), 'application/x-flatgeobuf');t.end();});diff --git a/test/node/processors/shapefile-files-test.js b/test/node/processors/shapefile-files-test.jsnew file mode 100644index 000000000..1930af135--- /dev/null+++ b/test/node/processors/shapefile-files-test.js@@ -0,0 +1,217 @@+// SPDX-License-Identifier: MIT+// Copyright contributors to the kepler.gl project++import test from 'tape';+import {crc32} from 'zlib';+import {+ getFilesToParse,+ getDroppedFileExtension,+ isShapefileSidecarFileName,+ processFileData,+ readFileInBatches,+ unzipShapefileArchive+} from '@kepler.gl/processors';++function createPointShapefileBuffers({x = -122.4, y = 37.8, name = 'alpha'} = {}) {+ const shp = new ArrayBuffer(128);+ const shpView = new DataView(shp);+ shpView.setInt32(0, 9994, false);+ shpView.setInt32(24, 64, false);+ shpView.setInt32(28, 1000, true);+ shpView.setInt32(32, 1, true);+ shpView.setFloat64(36, x, true);+ shpView.setFloat64(44, y, true);+ shpView.setFloat64(52, x, true);+ shpView.setFloat64(60, y, true);+ shpView.setInt32(100, 1, false);+ shpView.setInt32(104, 10, false);+ shpView.setInt32(108, 1, true);+ shpView.setFloat64(112, x, true);+ shpView.setFloat64(120, y, true);++ const shx = new ArrayBuffer(108);+ const shxView = new DataView(shx);+ shxView.setInt32(0, 9994, false);+ shxView.setInt32(24, 54, false);+ shxView.setInt32(28, 1000, true);+ shxView.setInt32(32, 1, true);+ shxView.setFloat64(36, x, true);+ shxView.setFloat64(44, y, true);+ shxView.setFloat64(52, x, true);+ shxView.setFloat64(60, y, true);+ shxView.setInt32(100, 50, false);+ shxView.setInt32(104, 10, false);++ const fieldLen = 10;+ const headerLen = 65;+ const recordLen = 1 + fieldLen;+ const dbf = new ArrayBuffer(headerLen + recordLen);+ const dbfBytes = new Uint8Array(dbf);+ const dbfView = new DataView(dbf);+ dbfBytes[0] = 0x03;+ dbfBytes[1] = 124;+ dbfBytes[2] = 1;+ dbfBytes[3] = 1;+ dbfView.setUint32(4, 1, true);+ dbfView.setUint16(8, headerLen, true);+ dbfView.setUint16(10, recordLen, true);+ const fieldName = 'NAME';+ for (let i = 0; i < fieldName.length; i++) {+ dbfBytes[32 + i] = fieldName.charCodeAt(i);+ }+ dbfBytes[32 + 11] = 0x43;+ dbfBytes[32 + 16] = fieldLen;+ dbfBytes[64] = 0x0d;+ dbfBytes[65] = 0x20;+ const nameBytes = new TextEncoder().encode(name);+ for (let i = 0; i < fieldLen; i++) {+ dbfBytes[66 + i] = i < nameBytes.length ? nameBytes[i] : 0x20;+ }++ return {shp, shx, dbf};+}++function createStoredZip(files) {+ const locals = [];+ const centrals = [];+ let offset = 0;++ for (const file of files) {+ const nameBuf = Buffer.from(file.name);+ const data = Buffer.from(file.data);+ const crc = crc32(data);+ const local = Buffer.alloc(30 + nameBuf.length);+ local.writeUInt32LE(0x04034b50, 0);+ local.writeUInt16LE(20, 4);+ local.writeUInt32LE(crc >>> 0, 14);+ local.writeUInt32LE(data.length, 18);+ local.writeUInt32LE(data.length, 22);+ local.writeUInt16LE(nameBuf.length, 26);+ nameBuf.copy(local, 30);+ locals.push(local, data);++ const central = Buffer.alloc(46 + nameBuf.length);+ central.writeUInt32LE(0x02014b50, 0);+ central.writeUInt16LE(20, 4);+ central.writeUInt16LE(20, 6);+ central.writeUInt32LE(crc >>> 0, 16);+ central.writeUInt32LE(data.length, 20);+ central.writeUInt32LE(data.length, 24);+ central.writeUInt16LE(nameBuf.length, 28);+ central.writeUInt32LE(offset, 42);+ nameBuf.copy(central, 46);+ centrals.push(central);+ offset += local.length + data.length;+ }++ const centralBuf = Buffer.concat(centrals);+ const end = Buffer.alloc(22);+ end.writeUInt32LE(0x06054b50, 0);+ end.writeUInt16LE(files.length, 8);+ end.writeUInt16LE(files.length, 10);+ end.writeUInt32LE(centralBuf.length, 12);+ end.writeUInt32LE(offset, 16);+ return Buffer.concat([...locals, centralBuf, end]);+}++async function readLastBatch(file, companionFiles) {+ const generator = await readFileInBatches({+ file,+ fileCache: [],+ loaders: [],+ loadOptions: {},+ companionFiles+ });+ let last;+ for await (const batch of generator) {+ last = batch;+ }+ return last;+}++test('#shapefile-files -> sidecar helpers', t => {+ t.equal(getDroppedFileExtension('places.SHP'), 'shp');+ t.ok(isShapefileSidecarFileName('places.dbf'));+ t.ok(isShapefileSidecarFileName('places.prj'));+ t.notOk(isShapefileSidecarFileName('places.shp'));+ t.notOk(isShapefileSidecarFileName('places.csv'));+ t.end();+});++test('#shapefile-files -> getFilesToParse skips sidecars when a shapefile is present', t => {+ const files = [+ {name: 'places.shp'},+ {name: 'places.dbf'},+ {name: 'places.shx'},+ {name: 'extra.csv'}+ ];+ t.deepEqual(+ getFilesToParse(files).map(file => file.name),+ ['places.shp', 'extra.csv'],+ 'should parse the shapefile and other datasets, not sidecars'+ );+ t.deepEqual(+ getFilesToParse([{name: 'places.dbf'}, {name: 'places.csv'}]).map(file => file.name),+ ['places.dbf', 'places.csv'],+ 'sidecars stay in the queue when no shapefile source is present'+ );+ t.deepEqual(+ getFilesToParse([{name: 'places.zip'}, {name: 'places.prj'}]).map(file => file.name),+ ['places.zip'],+ 'a shapefile zip is a source file and its sidecars are skipped'+ );+ t.end();+});++test('#shapefile-files -> unzipShapefileArchive reads top-level shapefile files', async t => {+ const {shp, shx, dbf} = createPointShapefileBuffers();+ const zip = createStoredZip([+ {name: 'places.shp', data: Buffer.from(shp)},+ {name: 'places.shx', data: Buffer.from(shx)},+ {name: 'places.dbf', data: Buffer.from(dbf)},+ {name: 'nested/ignore.shp', data: Buffer.from(shp)}+ ]);+ const files = await unzipShapefileArchive(new File([zip], 'places.zip'));+ t.deepEqual(+ files.map(file => file.name).sort(),+ ['places.dbf', 'places.shp', 'places.shx'],+ 'should keep top-level shapefile members and ignore nested folders'+ );+ t.end();+});++test('#shapefile-files -> shapefile with sidecars becomes a GeoJSON dataset', async t => {+ const {shp, shx, dbf} = createPointShapefileBuffers();+ const shapefile = new File([shp], 'places.shp');+ const companions = [shapefile, new File([shx], 'places.shx'), new File([dbf], 'places.dbf')];+ const batch = await readLastBatch(shapefile, companions);+ const processed = await processFileData({content: batch, fileCache: []});++ t.equal(processed[0].info.format, 'geojson', 'shapefile should process as geojson');+ t.equal(processed[0].data.rows.length, 1, 'should keep the shapefile feature');+ const nameField = processed[0].data.fields.findIndex(field => field.name === 'NAME');+ t.ok(nameField >= 0, 'should include the DBF NAME field');+ t.equal(+ String(processed[0].data.rows[0][nameField]).trim(),+ 'alpha',+ 'should read DBF attributes'+ );+ t.end();+});++test('#shapefile-files -> shapefile zip unpacks before parse', async t => {+ const {shp, shx, dbf} = createPointShapefileBuffers();+ const zip = createStoredZip([+ {name: 'places.shp', data: Buffer.from(shp)},+ {name: 'places.shx', data: Buffer.from(shx)},+ {name: 'places.dbf', data: Buffer.from(dbf)}+ ]);+ const batch = await readLastBatch(new File([zip], 'places.zip'));+ const processed = await processFileData({content: batch, fileCache: []});++ t.equal(batch.fileName, 'places.zip', 'batches should keep the original zip name for progress');+ t.equal(processed[0].info.format, 'geojson', 'shapefile zip should process as geojson');+ t.equal(processed[0].info.label, 'places.zip', 'the dataset label should stay the zip name');+ t.equal(processed[0].data.rows.length, 1, 'should keep the unzipped shapefile feature');+ t.end();+});diff --git a/test/node/reducers/vis-state-test.js b/test/node/reducers/vis-state-test.jsindex 69e52c6af..eeffe4b4a 100644--- a/test/node/reducers/vis-state-test.js+++ b/test/node/reducers/vis-state-test.js@@ -6684,7 +6684,8 @@ test('#visStateReducer -> LOAD_FILES', async t => {file: {type: 'text/csv', name: 'test-file.csv'},fileCache: [],loaders: [],- loadOptions: {}+ loadOptions: {},+ companionFiles: mockFiles}};@@ -6695,6 +6696,7 @@ test('#visStateReducer -> LOAD_FILES', async t => {const expectedFileLoading = {fileCache: [],filesToLoad: [{type: 'text/csv', name: 'test-file-2.csv'}],+ companionFiles: mockFiles,onFinish: VisStateActions.loadFilesSuccess};const expectedFileLoadingProgress = {@@ -6761,7 +6763,8 @@ test('#visStateReducer -> LOAD_FILES', async t => {file: {type: 'text/csv', name: 'test-file-2.csv'},fileCache: [],loaders: [],- loadOptions: {}+ loadOptions: {},+ companionFiles: mockFiles},'should return an LOAD_FILE_TASK with 2nd file to load');@@ -6779,6 +6782,7 @@ test('#visStateReducer -> LOAD_FILES', async t => {{fileCache: [],filesToLoad: [],+ companionFiles: mockFiles,onFinish: VisStateActions.loadFilesSuccess},'fileLoading should not add result to fileCache when error'@@ -6863,6 +6867,7 @@ test('#visStateReducer -> LOAD_FILES', async t => {{fileCache: fileProcessResult,filesToLoad: [{type: 'text/csv', name: 'test-file-2.csv'}],+ companionFiles: mockFiles,onFinish: VisStateActions.loadFilesSuccess},'fileLoading should update to add result to fileCache 1'@@ -6882,7 +6887,8 @@ test('#visStateReducer -> LOAD_FILES', async t => {file: {type: 'text/csv', name: 'test-file-2.csv'},fileCache: fileProcessResult,loaders: [],- loadOptions: {}+ loadOptions: {},+ companionFiles: mockFiles},'should return an LOAD_FILE_TASK with 2nd file to load 2');@@ -6900,6 +6906,7 @@ test('#visStateReducer -> LOAD_FILES', async t => {{fileCache: fileProcessResult,filesToLoad: [],+ companionFiles: mockFiles,onFinish: VisStateActions.loadFilesSuccess},'fileLoading should update to add result to fileCache 3'@@ -6942,6 +6949,7 @@ test('#visStateReducer -> LOAD_FILES', async t => {{fileCache: file2ProcessResult,filesToLoad: [],+ companionFiles: mockFiles,onFinish: VisStateActions.loadFilesSuccess},'fileLoading should update to add 2nd file result to fileCache'diff --git a/yarn.lock b/yarn.lockindex 594af2b65..74dfdae34 100644--- a/yarn.lock+++ b/yarn.lock@@ -4314,13 +4314,17 @@ __metadata:"@loaders.gl/arrow": "npm:^4.4.1""@loaders.gl/core": "npm:^4.4.1""@loaders.gl/csv": "npm:^4.4.1"+ "@loaders.gl/excel": "npm:^4.4.1"+ "@loaders.gl/flatgeobuf": "npm:^4.4.1""@loaders.gl/gis": "npm:^4.4.1""@loaders.gl/json": "npm:^4.4.1""@loaders.gl/kml": "npm:^4.4.1""@loaders.gl/loader-utils": "npm:^4.4.1""@loaders.gl/parquet": "npm:^4.4.1""@loaders.gl/schema": "npm:^4.4.1"+ "@loaders.gl/shapefile": "npm:^4.4.1""@loaders.gl/wkt": "npm:^4.4.1"+ "@loaders.gl/zip": "npm:^4.4.1""@mapbox/geojson-normalize": "npm:0.0.1""@turf/helpers": "npm:^7.2.0"apache-arrow: "npm:>=15.0.0"@@ -5481,6 +5485,34 @@ __metadata:languageName: nodelinkType: hard+"@loaders.gl/excel@npm:4.4.1":+ version: 4.4.1+ resolution: "@loaders.gl/excel@npm:4.4.1"+ dependencies:+ "@loaders.gl/loader-utils": "npm:4.4.1"+ "@loaders.gl/schema": "npm:4.4.1"+ xlsx: "npm:^0.18.5"+ peerDependencies:+ "@loaders.gl/core": ~4.4.0+ checksum: 10c0/21a7b7b3dd064fbf6564d09b583445c47986ce4d35d8149241d553a924d3749f6d3dee808b6ad961d5985c6a089c93b34ed249ba2220e6e10552fa4d0ed450fc+ languageName: node+ linkType: hard++"@loaders.gl/flatgeobuf@npm:4.4.1":+ version: 4.4.1+ resolution: "@loaders.gl/flatgeobuf@npm:4.4.1"+ dependencies:+ "@loaders.gl/gis": "npm:4.4.1"+ "@loaders.gl/loader-utils": "npm:4.4.1"+ "@loaders.gl/schema": "npm:4.4.1"+ "@math.gl/proj4": "npm:^4.1.0"+ flatgeobuf: "npm:3.27.2"+ peerDependencies:+ "@loaders.gl/core": ~4.4.0+ checksum: 10c0/89f9c6a063d1981071ea12012643d9083f8f714a3f70f42bce27402e779fad1ca27d0a15ff60a68d2247c0b8730d0d36ac22607c7807dc8451682b7f953c9a4c+ languageName: node+ linkType: hard+"@loaders.gl/geoarrow@npm:4.4.1":version: 4.4.1resolution: "@loaders.gl/geoarrow@npm:4.4.1"@@ -5721,6 +5753,20 @@ __metadata:languageName: nodelinkType: hard+"@loaders.gl/shapefile@npm:4.4.1":+ version: 4.4.1+ resolution: "@loaders.gl/shapefile@npm:4.4.1"+ dependencies:+ "@loaders.gl/gis": "npm:4.4.1"+ "@loaders.gl/loader-utils": "npm:4.4.1"+ "@loaders.gl/schema": "npm:4.4.1"+ "@math.gl/proj4": "npm:^4.1.0"+ peerDependencies:+ "@loaders.gl/core": ~4.4.0+ checksum: 10c0/389d16b3084416e72a10d573db5f327c8cfc14131d8d86c9b849ee11b96b754c10d87f1354eb8b0108bb5def2b6b5d0cf536a87d477a0483b0455c118fd92405+ languageName: node+ linkType: hard+"@loaders.gl/terrain@npm:^4.4.1":version: 4.4.1resolution: "@loaders.gl/terrain@npm:4.4.1"@@ -6244,6 +6290,17 @@ __metadata:languageName: nodelinkType: hard+"@math.gl/proj4@npm:^4.1.0":+ version: 4.1.0+ resolution: "@math.gl/proj4@npm:4.1.0"+ dependencies:+ "@math.gl/core": "npm:4.1.0"+ "@types/proj4": "npm:^2.5.0"+ proj4: "npm:2.6.2"+ checksum: 10c0/bac437b7963a1139df7bcc18cb847cf339055b64ce066fa8e79e57d8ae805713f5c706816da8de1afcf00441d4820cf52fde318dc117ba3f86fe47a8dc5671cd+ languageName: node+ linkType: hard+"@math.gl/sun@npm:^4.1.0":version: 4.1.0resolution: "@math.gl/sun@npm:4.1.0"@@ -8461,6 +8518,13 @@ __metadata:languageName: nodelinkType: hard+"@repeaterjs/repeater@npm:3.0.5":+ version: 3.0.5+ resolution: "@repeaterjs/repeater@npm:3.0.5"+ checksum: 10c0/e6e1aca2bbfe0b8e974bc5185a6839f9e78ec8acb96b6d6911a9dfc958443689f9bc38bcc6d554e6c8598f597f0151841aafbd1ee3ef16262ee93d18b2c1d4b5+ languageName: node+ linkType: hard+"@sigstore/bundle@npm:^2.3.2":version: 2.3.2resolution: "@sigstore/bundle@npm:2.3.2"@@ -10464,6 +10528,13 @@ __metadata:languageName: nodelinkType: hard+"@types/proj4@npm:^2.5.0":+ version: 2.5.6+ resolution: "@types/proj4@npm:2.5.6"+ checksum: 10c0/7590dd982cb0e4a0de57f6089ea932b2821ec13198b1255980b950a27208838965f8f3346d3130a9e9668e345f22d77ada3971b493179281d1b168aba2d6d252+ languageName: node+ linkType: hard+"@types/prop-types@npm:*":version: 15.7.12resolution: "@types/prop-types@npm:15.7.12"@@ -11502,6 +11573,13 @@ __metadata:languageName: nodelinkType: hard+"adler-32@npm:~1.3.0":+ version: 1.3.1+ resolution: "adler-32@npm:1.3.1"+ checksum: 10c0/c1b7185526ee1bbe0eac8ed414d5226af4cd02a0540449a72ec1a75f198c5e93352ba4d7b9327231eea31fd83c2d080d13baf16d8ed5710fb183677beb85f612+ languageName: node+ linkType: hard+"agent-base@npm:6":version: 6.0.2resolution: "agent-base@npm:6.0.2"@@ -13524,6 +13602,16 @@ __metadata:languageName: nodelinkType: hard+"cfb@npm:~1.2.1":+ version: 1.2.2+ resolution: "cfb@npm:1.2.2"+ dependencies:+ adler-32: "npm:~1.3.0"+ crc-32: "npm:~1.2.0"+ checksum: 10c0/87f6d9c3878268896ed6ca29dfe32a2aa078b12d0f21d8405c95911b74ab6296823d7312bbf5e18326d00b16cc697f587e07a17018c5edf7a1ba31dd5bc6da36+ languageName: node+ linkType: hard+"chalk-template@npm:^0.4.0":version: 0.4.0resolution: "chalk-template@npm:0.4.0"@@ -14034,6 +14122,13 @@ __metadata:languageName: nodelinkType: hard+"codepage@npm:~1.15.0":+ version: 1.15.0+ resolution: "codepage@npm:1.15.0"+ checksum: 10c0/2455b482302cb784b46dea60a8ee83f0c23e794bdd979556bdb107abe681bba722af62a37f5c955ff4efd68fdb9688c3986e719b4fd536c0e06bb25bc82abea3+ languageName: node+ linkType: hard+"collapse-white-space@npm:^1.0.0, collapse-white-space@npm:^1.0.2":version: 1.0.6resolution: "collapse-white-space@npm:1.0.6"@@ -14609,6 +14704,15 @@ __metadata:languageName: nodelinkType: hard+"crc-32@npm:~1.2.0, crc-32@npm:~1.2.1":+ version: 1.2.2+ resolution: "crc-32@npm:1.2.2"+ bin:+ crc32: bin/crc32.njs+ checksum: 10c0/11dcf4a2e77ee793835d49f2c028838eae58b44f50d1ff08394a610bfd817523f105d6ae4d9b5bef0aad45510f633eb23c903e9902e4409bed1ce70cb82b9bf0+ languageName: node+ linkType: hard+"create-ecdh@npm:^4.0.0, create-ecdh@npm:^4.0.4":version: 4.0.4resolution: "create-ecdh@npm:4.0.4"@@ -18050,6 +18154,13 @@ __metadata:languageName: nodelinkType: hard+"flatbuffers@npm:23.5.26":+ version: 23.5.26+ resolution: "flatbuffers@npm:23.5.26"+ checksum: 10c0/69e0903caa3aa8d2bdbf1557995835fd097806d413abc9b4b7440301a8ae2bd427220be1d613af80609c38d38cdbdeb459706903080433b509ceb64faf91b711+ languageName: node+ linkType: hard+"flatbuffers@npm:^24.3.25":version: 24.3.25resolution: "flatbuffers@npm:24.3.25"@@ -18057,6 +18168,19 @@ __metadata:languageName: nodelinkType: hard+"flatgeobuf@npm:3.27.2":+ version: 3.27.2+ resolution: "flatgeobuf@npm:3.27.2"+ dependencies:+ "@repeaterjs/repeater": "npm:3.0.5"+ flatbuffers: "npm:23.5.26"+ slice-source: "npm:0.4.1"+ peerDependencies:+ ol: ^7 || ^8+ checksum: 10c0/db268b762f5342528296160f719f1b77c29a7ae161715f2d287c102247232ac86877b07ab0766f3596ac490aa4f6bf5d8fc671d6f88d2ec938f065813c77dfd4+ languageName: node+ linkType: hard+"flatted@npm:^3.2.9":version: 3.4.3resolution: "flatted@npm:3.4.3"@@ -18203,6 +18327,13 @@ __metadata:languageName: nodelinkType: hard+"frac@npm:~1.1.2":+ version: 1.1.2+ resolution: "frac@npm:1.1.2"+ checksum: 10c0/640740eb58b590eb38c78c676955bee91cd22d854f5876241a15c49d4495fa53a84898779dcf7eca30aabfe1c1a4a705752b5f224934257c5dda55c545413ba7+ languageName: node+ linkType: hard+"fragment-cache@npm:^0.2.1":version: 0.2.1resolution: "fragment-cache@npm:0.2.1"@@ -26972,6 +27103,16 @@ __metadata:languageName: nodelinkType: hard+"proj4@npm:2.6.2":+ version: 2.6.2+ resolution: "proj4@npm:2.6.2"+ dependencies:+ mgrs: "npm:1.0.0"+ wkt-parser: "npm:^1.2.4"+ checksum: 10c0/b184519aac86a8b4c28299cd71ddd109f85d76ec3cb9a67e6990718996033ea12ae862827ad5beb6ed96050a2ffaaceccf4bd553e880efc74b82718b4fc10668+ languageName: node+ linkType: hard+"proj4@npm:^2.9.2":version: 2.12.1resolution: "proj4@npm:2.12.1"@@ -29723,6 +29864,13 @@ __metadata:languageName: nodelinkType: hard+"slice-source@npm:0.4.1":+ version: 0.4.1+ resolution: "slice-source@npm:0.4.1"+ checksum: 10c0/a36569e6d202c2cade2b943011807426104e90b0573d773ad80421013fd3ffab4da0f49fb0602b5adf06745313d79316349c60e1afc179da8a752d2c2b6de2f0+ languageName: node+ linkType: hard+"smart-buffer@npm:^4.2.0":version: 4.2.0resolution: "smart-buffer@npm:4.2.0"@@ -30111,6 +30259,15 @@ __metadata:languageName: nodelinkType: hard+"ssf@npm:~0.11.2":+ version: 0.11.2+ resolution: "ssf@npm:0.11.2"+ dependencies:+ frac: "npm:~1.1.2"+ checksum: 10c0/c3fd24a90dc37a9dc5c4154cb4121e27507c33ebfeee3532aaf03625756b2c006cf79c0a23db0ba16c4a6e88e1349455327867e03453fc9d54b32c546bc18ca6+ languageName: node+ linkType: hard+"sshpk@npm:^1.7.0":version: 1.18.0resolution: "sshpk@npm:1.18.0"@@ -33556,6 +33713,13 @@ __metadata:languageName: nodelinkType: hard+"wkt-parser@npm:^1.2.4":+ version: 1.5.6+ resolution: "wkt-parser@npm:1.5.6"+ checksum: 10c0/67f938ffb6a1721dbc733823677327ff858a0a1f2f0d224e2ecbdf9e879f27764434dd6e44c89a2e94e3d37cc6e5f9874f878e4a1b1e2fd29a1279be38c322ca+ languageName: node+ linkType: hard+"wkt-parser@npm:^1.3.3":version: 1.3.3resolution: "wkt-parser@npm:1.3.3"@@ -33563,6 +33727,13 @@ __metadata:languageName: nodelinkType: hard+"wmf@npm:~1.0.1":+ version: 1.0.2+ resolution: "wmf@npm:1.0.2"+ checksum: 10c0/3fa5806f382632cadfe65d4ef24f7a583b0c0720171edb00e645af5248ad0bb6784e8fcee1ccd9f475a1a12a7523e2512e9c063731fbbdae14dc469e1c033d93+ languageName: node+ linkType: hard+"word-wrap@npm:^1.2.5":version: 1.2.5resolution: "word-wrap@npm:1.2.5"@@ -33570,6 +33741,13 @@ __metadata:languageName: nodelinkType: hard+"word@npm:~0.3.0":+ version: 0.3.0+ resolution: "word@npm:0.3.0"+ checksum: 10c0/c6da2a9f7a0d81a32fa6768a638d21b153da2be04f94f3964889c7cc1365d74b6ecb43b42256c3f926cd59512d8258206991c78c21000c3da96d42ff1238b840+ languageName: node+ linkType: hard+"wordwrap@npm:^1.0.0":version: 1.0.0resolution: "wordwrap@npm:1.0.0"@@ -33768,6 +33946,23 @@ __metadata:languageName: nodelinkType: hard+"xlsx@npm:^0.18.5":+ version: 0.18.5+ resolution: "xlsx@npm:0.18.5"+ dependencies:+ adler-32: "npm:~1.3.0"+ cfb: "npm:~1.2.1"+ codepage: "npm:~1.15.0"+ crc-32: "npm:~1.2.1"+ ssf: "npm:~0.11.2"+ wmf: "npm:~1.0.1"+ word: "npm:~0.3.0"+ bin:+ xlsx: bin/xlsx.njs+ checksum: 10c0/787cfa77034a3e86fdcde21572f1011c8976f87823a5e0ee5057f13b2f6e48f17a1710732a91b8ae15d7794945c7cba8a3ca904ea7150e028260b0ab8e1158c8+ languageName: node+ linkType: hard+"xml-name-validator@npm:^4.0.0":version: 4.0.0resolution: "xml-name-validator@npm:4.0.0"