
Build AI methods with your coding agent, then run them anywhere: as an MCP for chatbots, as a webapp for people, or via API for your software.
Release v0.20.3: rewrite README with updated CV Batch Screening example
Louis Choquel459e0d08b0dd
diff --git a/.github/assets/Claude-Code-Pipelex-MTHDS-Cursor.png b/.github/assets/Claude-Code-Pipelex-MTHDS-Cursor.pngnew file mode 100644index 000000000..0ece70934Binary files /dev/null and b/.github/assets/Claude-Code-Pipelex-MTHDS-Cursor.png differdiff --git a/CHANGELOG.md b/CHANGELOG.mdindex 5eeba7281..b64f0df90 100644--- a/CHANGELOG.md+++ b/CHANGELOG.md@@ -1,5 +1,11 @@# Changelog+## [v0.20.3] - 2026-03-04++### Fixed++- Rewrote README with updated CV Batch Screening example, corrected CLI command, inputs schema, Python snippet, and pipe descriptions.+## [v0.20.2] - 2026-03-04### Fixeddiff --git a/README.md b/README.mdindex 39274fc21..bace37b3c 100644--- a/README.md+++ b/README.md@@ -4,14 +4,18 @@<br/><br/><br/>- <h2 align="center">The Reference Runtime for Executing Methods</h2>- <p align="center">Pipelex is the reference Python runtime for executing methods, based on the <a href="https://mthds.ai">MTHDS</a> open standard.<br/>-Write business logic, not API calls.</p>+ <h2 align="center">Executable AI Methods</h2>+ <p align="center">Pipelex is the reference Python runtime and Claude Code plugin for the <a href="https://mthds.ai">MTHDS</a> open standard.<br/>+Readable by humans, executable by agents. No boilerplate, no lock-in.</p>+ <br/>+ <p align="center"><b>An AI method</b> is a multi-step workflow that chains LLMs, OCR, image generation, and more — each step typed and validated.<br/>+<b>Executable</b> means each method becomes a new tool — agents and skills can call it, and it also runs standalone via CLI, Python, or REST API.</p><div><a href="https://go.pipelex.com/demo"><strong>Demo</strong></a> -<a href="https://docs.pipelex.com/"><strong>Documentation</strong></a> -+ <a href="https://mthds.sh"><strong>Hub</strong></a> -<a href="https://github.com/Pipelex/pipelex/issues"><strong>Report Bug</strong></a> -<a href="https://github.com/Pipelex/pipelex/discussions"><strong>Feature Request</strong></a></div>@@ -33,166 +37,208 @@ Write business logic, not API calls.</p><br/></div>-+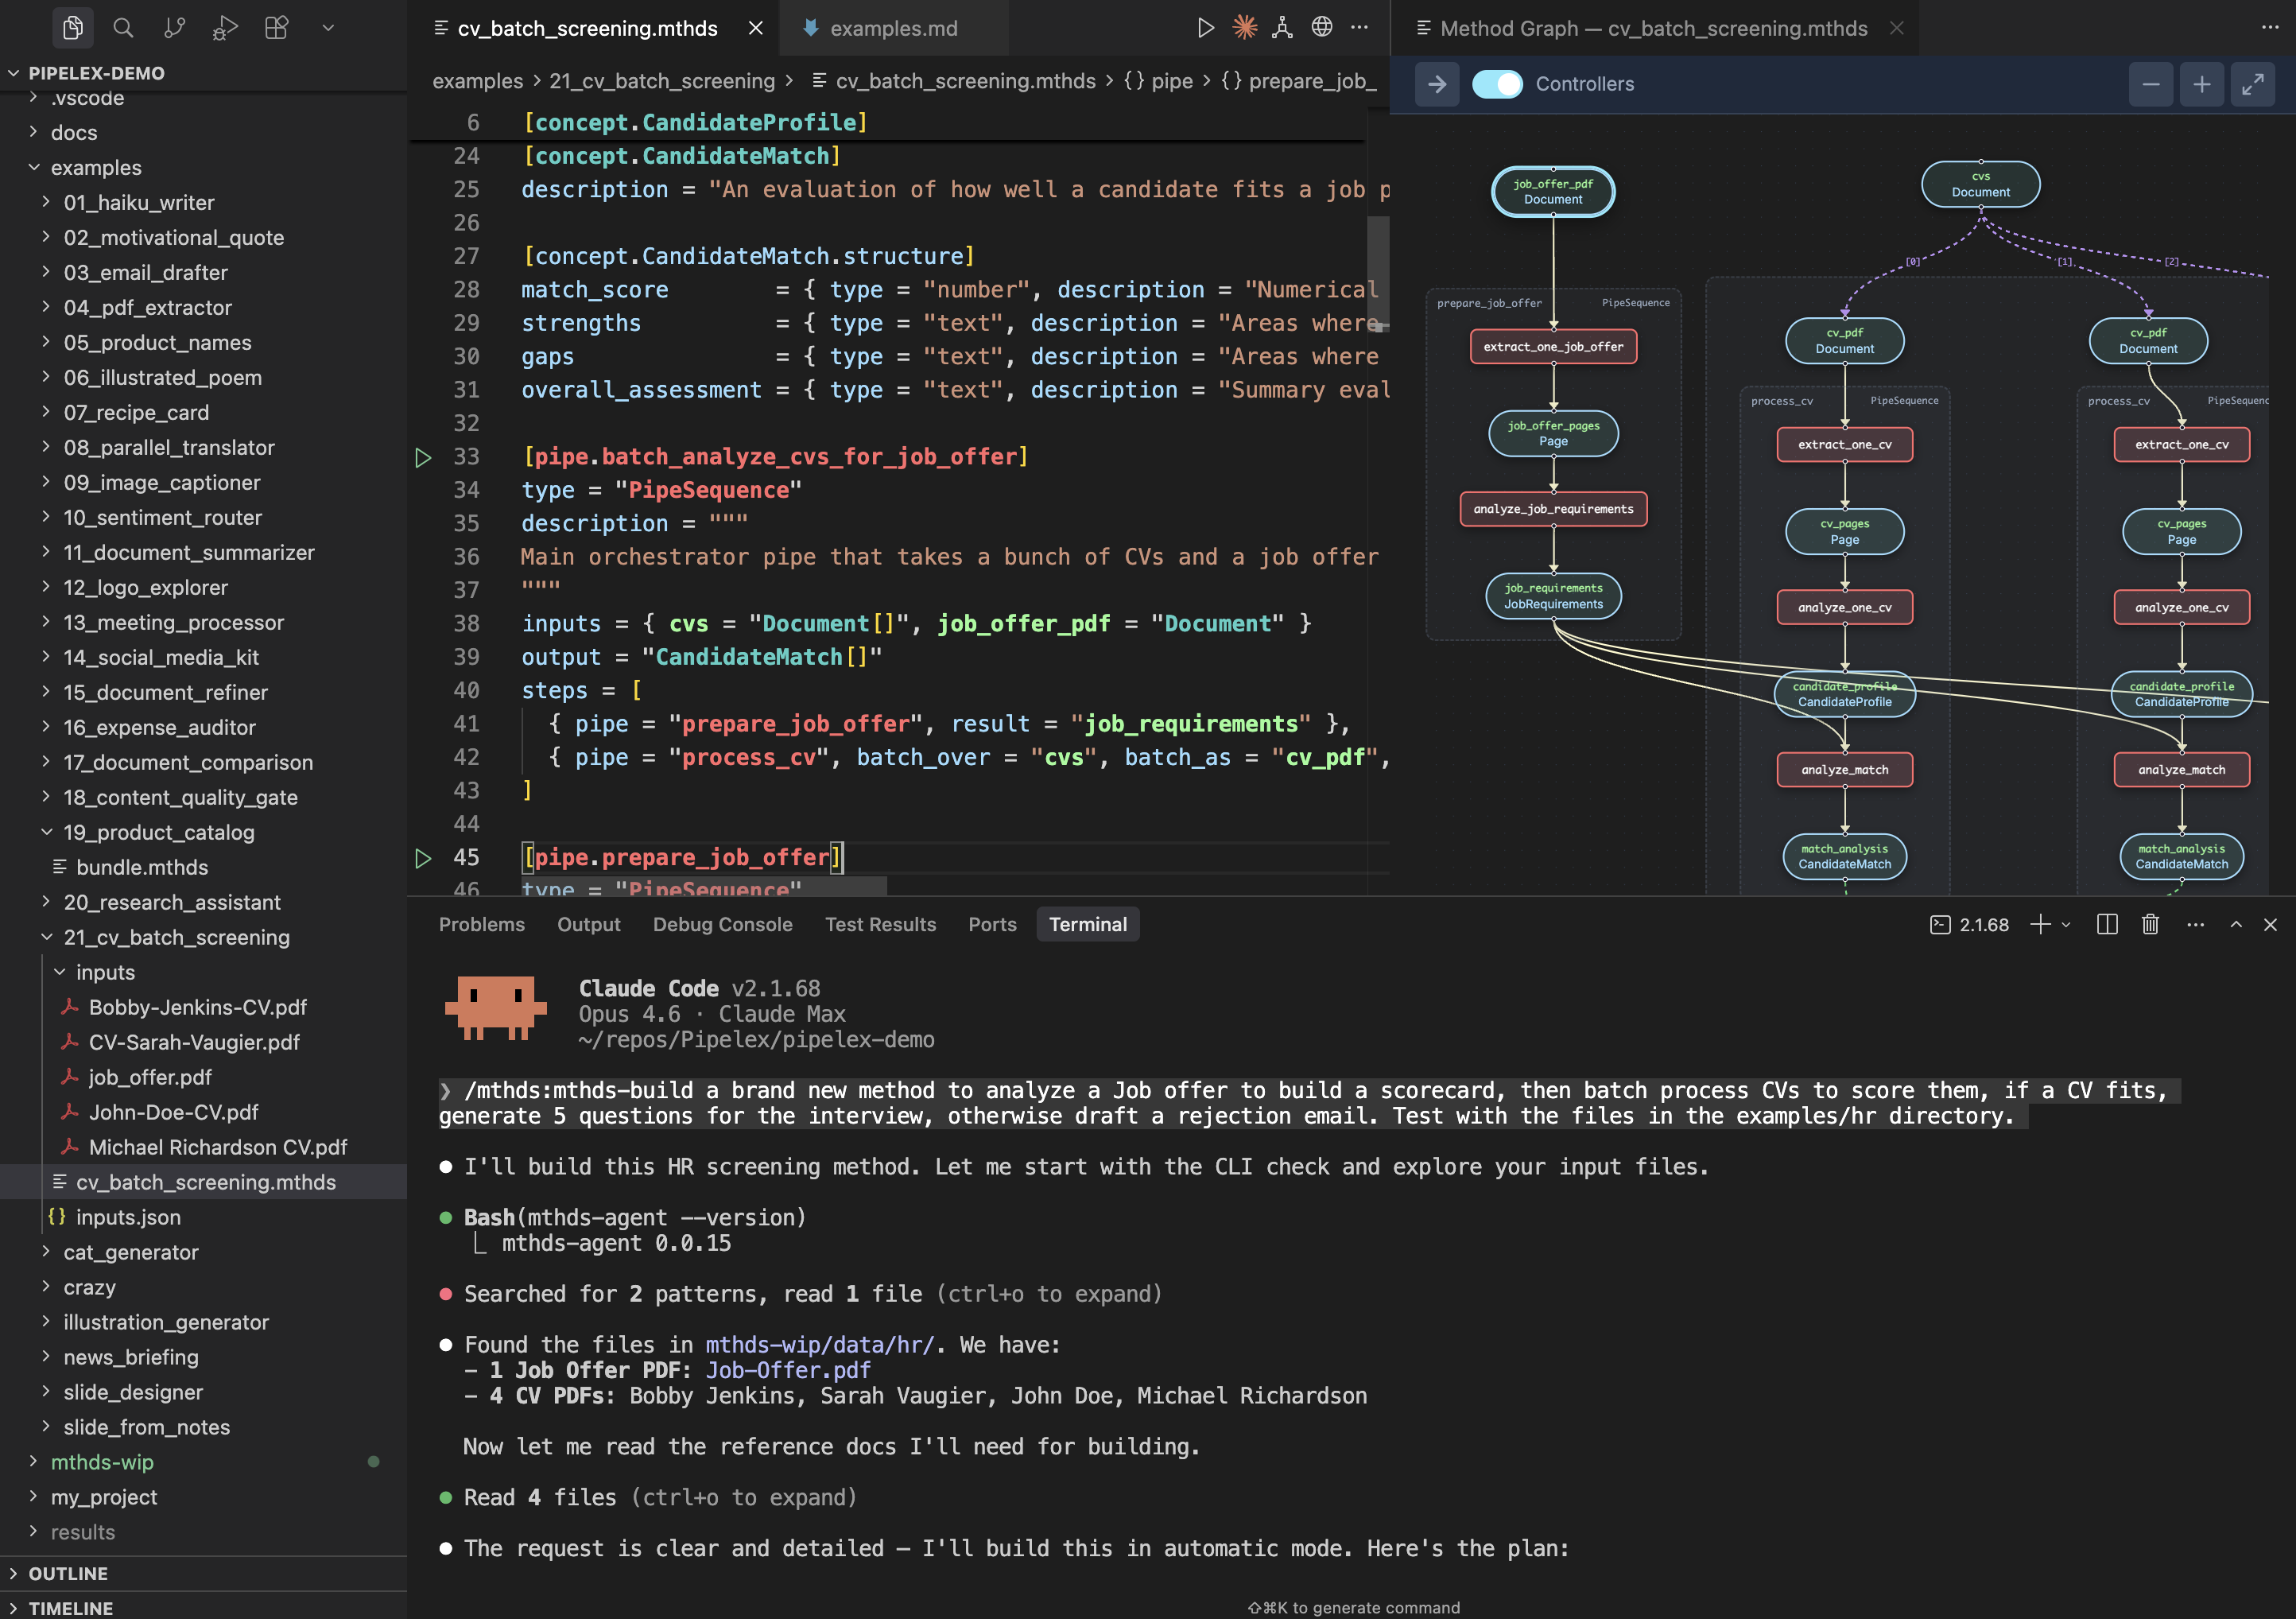+++# Quick Start++## Path A: With Claude Code (Recommended)++Install the MTHDS skills plugin:++```bash+/plugin marketplace add mthds-ai/skills+/plugin install mthds@mthds-ai-skills+```++Build your first method:++```+/mthds-build A method to analyze a Job offer to build a scorecard, then batch process CVs to score them, if a CV fits, generate 5 questions for the interview, otherwise draft a rejection email+```+Run it:-# 🚀 Quick start+```+/mthds-run+```-## 1. Install Pipelex+## Path B: Without Claude Code```bashpip install pipelexpipelex init```-## 2. Configure AI Access+Then:++1. Install the [VS Code extension](https://go.pipelex.com/vscode) for `.mthds` syntax highlighting+2. Browse methods on the [MTHDS Hub](https://mthds.sh) for inspiration+3. Author your own `.mthds` methods based on these examples+4. Validate with `pipelex validate`+5. Run them with `pipelex run`+6. View the flowchart in VS Code thanks to the extension+7. Use the [`mthds` npm package](https://github.com/mthds-ai/mthds-js) to package and publish methods on the hub-To run pipelines with AI models, choose one of these options:+## Configure AI Access++To run methods with AI models, choose one of these options:### Option A: Pipelex Gateway (Recommended)-Get **free credits** with a single API key for LLMs, document extraction, and image generation across all major providers (OpenAI, Anthropic, Google, Azure, and more). New models added constantly.+Get **free credits** with a single API key for LLMs, document extraction, and image generation across all major providers (OpenAI, Anthropic, Google, Azure, and more).1. Get your API key at [app.pipelex.com](https://app.pipelex.com/)2. Add it to your `.env` file: `PIPELEX_GATEWAY_API_KEY=your-key-here`3. Run `pipelex init` and accept the Gateway terms of service-> **Migrating from pipelex_inference?** The old `pipelex_inference` backend is deprecated. Get your new Gateway key at [app.pipelex.com](https://app.pipelex.com/).-### Option B: Bring Your Own Keys-Use your existing API keys from OpenAI, Anthropic, Google, Mistral, etc. See [Configure AI Providers](https://docs.pipelex.com/home/5-setup/configure-ai-providers/) for setup.+Use your existing API keys from OpenAI, Anthropic, Google, Mistral, etc. See [Configure AI Providers](https://docs.pipelex.com/home/5-setup/configure-ai-providers/).### Option C: Local AI-Run models locally with Ollama, vLLM, LM Studio, or llama.cpp - no API keys required. See [Configure AI Providers](https://docs.pipelex.com/home/5-setup/configure-ai-providers/) for details.--## 3. Generate Your First Method+Run models locally with Ollama, vLLM, LM Studio, or llama.cpp — no API keys required. See [Configure AI Providers](https://docs.pipelex.com/home/5-setup/configure-ai-providers/).-Create a complete AI method with a single command:--```bash-pipelex build pipe "Take a CV and Job offer in PDF, analyze if they match and generate 5 questions for the interview" --output results/cv_match.mthds-```-This command generates a production-ready `.mthds` file with domain definitions, concepts, and multiple processing steps that analyzes CV-job fit and prepares interview questions.+# Example: CV Batch Screening-**cv_match.mthds**+**cv_batch_screening.mthds**```toml-domain = "cv_match"-description = "Matching CVs with job offers and generating interview questions"-main_pipe = "analyze_cv_job_match_and_generate_questions"--[concept.MatchAnalysis]-description = """-Analysis of alignment between a candidate and a position, including strengths, gaps, and areas requiring further exploration.-"""--[concept.MatchAnalysis.structure]-strengths = { type = "text", description = "Areas where the candidate's profile aligns well with the requirements", required = true }-gaps = { type = "text", description = "Areas where the candidate's profile does not meet the requirements or lacks evidence", required = true }-areas_to_probe = { type = "text", description = "Topics or competencies that need clarification or deeper assessment during the interview", required = true }--[concept.Question]-description = "A single interview question designed to assess a candidate."-refines = "Text"--[pipe.analyze_cv_job_match_and_generate_questions]+[concept.CandidateProfile]+description = "A structured summary of a job candidate's professional background extracted from their CV."++[concept.CandidateProfile.structure]+skills = { type = "text", description = "Technical and soft skills possessed by the candidate", required = true }+experience = { type = "text", description = "Work history and professional experience", required = true }+education = { type = "text", description = "Educational background and qualifications", required = true }+achievements = { type = "text", description = "Notable accomplishments and certifications" }++[concept.JobRequirements]+description = "A structured summary of what a job position requires from candidates."++[concept.JobRequirements.structure]+required_skills = { type = "text", description = "Skills that are mandatory for the position", required = true }+responsibilities = { type = "text", description = "Main duties and tasks of the role", required = true }+qualifications = { type = "text", description = "Required education, certifications, or experience levels", required = true }+nice_to_haves = { type = "text", description = "Preferred but not mandatory qualifications" }++[concept.CandidateMatch]+description = "An evaluation of how well a candidate fits a job position."++[concept.CandidateMatch.structure]+match_score = { type = "number", description = "Numerical score representing overall fit percentage between 0 and 100", required = true }+strengths = { type = "text", description = "Areas where the candidate meets or exceeds requirements", required = true }+gaps = { type = "text", description = "Areas where the candidate falls short of requirements", required = true }+overall_assessment = { type = "text", description = "Summary evaluation of the candidate's suitability", required = true }++[pipe.batch_analyze_cvs_for_job_offer]type = "PipeSequence"description = """-Main pipeline that orchestrates the complete CV-job matching and interview question generation method. Takes a candidate's CV and a job offer as PDF documents, extracts their content, performs a comprehensive match analysis identifying strengths, gaps, and areas to probe, and generates exactly 5 targeted interview questions based on the analysis results.+Main orchestrator pipe that takes a bunch of CVs and a job offer in PDF format, and analyzes how they match."""-inputs = { cv_pdf = "PDF", job_offer_pdf = "PDF" }-output = "Question[5]"+inputs = { cvs = "Document[]", job_offer_pdf = "Document" }+output = "CandidateMatch[]"steps = [- { pipe = "extract_documents_parallel", result = "extracted_documents" },- { pipe = "analyze_match", result = "match_analysis" },- { pipe = "generate_interview_questions", result = "interview_questions" },+ { pipe = "prepare_job_offer", result = "job_requirements" },+ { pipe = "process_cv", batch_over = "cvs", batch_as = "cv_pdf", result = "match_analyses" },]```<details>-<summary><b>📄 Click to view the supporting pipes implementation</b></summary>+<summary><b>Click to view the supporting pipes implementation</b></summary>```toml-[pipe.extract_documents_parallel]-type = "PipeParallel"+[pipe.prepare_job_offer]+type = "PipeSequence"description = """-Executes parallel extraction of text content from both the CV PDF and job offer PDF simultaneously to optimize processing time.+Extracts and analyzes the job offer PDF to produce structured job requirements."""-inputs = { cv_pdf = "PDF", job_offer_pdf = "PDF" }-output = "Dynamic"-branches = [- { pipe = "extract_cv_text", result = "cv_pages" },- { pipe = "extract_job_offer_text", result = "job_offer_pages" },+inputs = { job_offer_pdf = "Document" }+output = "JobRequirements"+steps = [+ { pipe = "extract_one_job_offer", result = "job_offer_pages" },+ { pipe = "analyze_job_requirements", result = "job_requirements" },]-add_each_output = true-[pipe.extract_cv_text]-type = "PipeExtract"+[pipe.extract_one_job_offer]+type = "PipeExtract"+description = "Extracts text content from the job offer PDF document"+inputs = { job_offer_pdf = "Document" }+output = "Page[]"+model = "@default-text-from-pdf"++[pipe.analyze_job_requirements]+type = "PipeLLM"description = """-Extracts text content from the candidate's CV PDF document using OCR technology, converting all pages into machine-readable text format for subsequent analysis.+Parses and summarizes the job requirements from the extracted job offer content, identifying required skills, responsibilities, qualifications, and nice-to-haves"""-inputs = { cv_pdf = "PDF" }-output = "Page[]"-model = "@default-text-from-pdf"+inputs = { job_offer_pages = "Page" }+output = "JobRequirements"+model = "$writing-factual"+system_prompt = """+You are an expert HR analyst specializing in parsing job descriptions. Your task is to extract and summarize job requirements into a structured format.+"""+prompt = """+Analyze the following job offer content and extract the key requirements for the position.-[pipe.extract_job_offer_text]-type = "PipeExtract"-description = """-Extracts text content from the job offer PDF document using OCR technology, converting all pages into machine-readable text format for subsequent analysis.+@job_offer_pages"""-inputs = { job_offer_pdf = "PDF" }-output = "Page[]"-model = "@default-text-from-pdf"-[pipe.analyze_match]+[pipe.process_cv]+type = "PipeSequence"+description = "Processes one application"+inputs = { cv_pdf = "Document", job_requirements = "JobRequirements" }+output = "CandidateMatch"+steps = [+ { pipe = "extract_one_cv", result = "cv_pages" },+ { pipe = "analyze_one_cv", result = "candidate_profile" },+ { pipe = "analyze_match", result = "match_analysis" },+]++[pipe.extract_one_cv]+type = "PipeExtract"+description = "Extracts text content from the CV PDF document"+inputs = { cv_pdf = "Document" }+output = "Page[]"+model = "@default-text-from-pdf"++[pipe.analyze_one_cv]type = "PipeLLM"description = """-Performs comprehensive analysis comparing the candidate's CV against the job offer requirements. Identifies and structures: (1) strengths where the candidate's profile aligns well with requirements, (2) gaps where the profile lacks evidence or doesn't meet requirements, and (3) specific areas requiring deeper exploration or clarification during the interview process.+Parses and summarizes the candidate's professional profile from the extracted CV content, identifying skills, experience, education, and achievements"""-inputs = { cv_pages = "Page[]", job_offer_pages = "Page[]" }-output = "MatchAnalysis"+inputs = { cv_pages = "Page" }+output = "CandidateProfile"model = "$writing-factual"system_prompt = """-You are an expert HR analyst and recruiter specializing in candidate-job fit assessment. Your task is to generate a structured MatchAnalysis comparing a candidate's CV against job requirements.+You are an expert HR analyst specializing in parsing and summarizing candidate CVs. Your task is to extract and structure the candidate's professional profile into a structured format."""prompt = """-Analyze the match between the candidate's CV and the job offer requirements.+Analyze the following CV content and extract the candidate's professional profile.-Candidate CV:@cv_pages--Job Offer:-@job_offer_pages--Perform a comprehensive comparison and provide a structured analysis."""-[pipe.generate_interview_questions]+[pipe.analyze_match]type = "PipeLLM"description = """-Generates exactly 5 targeted, relevant interview questions based on the match analysis results. Questions are designed to probe identified gaps, clarify areas of uncertainty, validate strengths, and assess competencies that require deeper evaluation to determine candidate-position fit.+Evaluates how well the candidate matches the job requirements, calculating a match score and identifying strengths and gaps"""-inputs = { match_analysis = "MatchAnalysis" }-output = "Question[5]"-model = "$testing-structured"+inputs = { candidate_profile = "CandidateProfile", job_requirements = "JobRequirements" }+output = "CandidateMatch"+model = "$writing-factual"system_prompt = """-You are an expert HR interviewer and talent assessment specialist. Your task is to generate structured interview questions based on candidate-position match analysis.+You are an expert HR analyst specializing in candidate-job fit evaluation. Your task is to produce a structured match analysis comparing a candidate's profile against job requirements."""prompt = """-Based on the following match analysis between a candidate and a position, generate exactly 5 targeted interview questions.+Analyze how well the candidate matches the job requirements. Evaluate their fit by comparing their skills, experience, and qualifications against what the position demands.-@match_analysis+@candidate_profile-The questions should:-- Probe the identified gaps to assess if they are deal-breakers or can be mitigated-- Clarify areas that require deeper exploration-- Validate the candidate's strengths with concrete examples-- Be open-ended and behavioral when appropriate-- Help determine overall candidate-position fit+@job_requirements-Generate exactly 5 interview questions.+Provide a comprehensive match analysis including a numerical score, identified strengths, gaps, and an overall assessment."""```</details>@@ -201,66 +247,117 @@ Generate exactly 5 interview questions.**View the pipeline flowchart:**```mermaid-flowchart TD- subgraph PAR["extract_documents_parallel (PipeParallel)"]- direction LR- EXTRACT_CV["extract_cv_text (PipeExtract)"]- EXTRACT_JOB["extract_job_offer_text (PipeExtract)"]- end- subgraph MAIN["analyze_cv_job_match_and_generate_questions (PipeSequence)"]- direction TB- PAR- CV_PAGES[["cv_pages: Page"]]- JOB_PAGES[["job_offer_pages: Page"]]- ANALYZE["analyze_match (PipeLLM)"]- MATCH[["MatchAnalysis"]]- GENERATE["generate_interview_questions (PipeLLM)"]- OUT[["Question"]]- end- CV_IN[["cv_pdf: PDF"]] --> EXTRACT_CV- JOB_IN[["job_offer_pdf: PDF"]] --> EXTRACT_JOB- EXTRACT_CV --> CV_PAGES- EXTRACT_JOB --> JOB_PAGES- CV_PAGES --> ANALYZE- JOB_PAGES --> ANALYZE- ANALYZE --> MATCH- MATCH --> GENERATE- GENERATE --> OUT- classDef default stroke:#1976D2,stroke-width:2px,fill:#E3F2FD,color:#0D47A1- style EXTRACT_CV stroke:#1565C0,fill:#BBDEFB,color:#0D47A1- style EXTRACT_JOB stroke:#1565C0,fill:#BBDEFB,color:#0D47A1- style PAR fill:#FFF9C4,stroke:#F57C00,stroke-width:2px- style CV_PAGES stroke:#2E7D32,fill:#C8E6C9,color:#1B5E20- style JOB_PAGES stroke:#2E7D32,fill:#C8E6C9,color:#1B5E20- style ANALYZE stroke:#1565C0,fill:#BBDEFB,color:#0D47A1- style MATCH stroke:#2E7D32,fill:#C8E6C9,color:#1B5E20- style GENERATE stroke:#1565C0,fill:#BBDEFB,color:#0D47A1- style OUT stroke:#2E7D32,fill:#C8E6C9,color:#1B5E20- style CV_IN stroke:#2E7D32,fill:#C8E6C9,color:#1B5E20- style JOB_IN stroke:#2E7D32,fill:#C8E6C9,color:#1B5E20- style MAIN fill:#F3E5F5,stroke:#7B1FA2,stroke-width:2px+flowchart LR+ %% Pipe and stuff nodes within controller subgraphs+ subgraph sg_n_8b2136e3fe["batch_analyze_cvs_for_job_offer"]+ subgraph sg_n_91d5d6dc7c["prepare_job_offer"]+ n_fde22777cb["analyze_job_requirements"]+ s_f9f703fbb4(["job_requirements<br/>JobRequirements"]):::stuff+ n_b8469c838f["extract_one_job_offer"]+ s_d998350046(["job_offer_pages<br/>Page"]):::stuff+ end+ subgraph sg_n_f8d5afb7cd["process_cv_batch"]+ subgraph sg_n_6e53e16369["process_cv"]+ n_c18aded200["analyze_match"]+ s_5c911f7e54(["match_analysis<br/>CandidateMatch"]):::stuff+ n_a7ed00ac24["analyze_one_cv"]+ s_c5ae714e89(["candidate_profile<br/>CandidateProfile"]):::stuff+ n_d24f39aa60["extract_one_cv"]+ s_427beb5195(["cv_pdf<br/>Document"]):::stuff+ s_f1f80289df(["cv_pages<br/>Page"]):::stuff+ end+ subgraph sg_n_2cfb7a32c8["process_cv"]+ n_f6a25d1769["analyze_match"]+ s_ea99eee6ed(["match_analysis<br/>CandidateMatch"]):::stuff+ n_f48b73fbee["analyze_one_cv"]+ s_e1ffee913e(["candidate_profile<br/>CandidateProfile"]):::stuff+ n_d16f2fe381["extract_one_cv"]+ s_041bb18fb4(["cv_pdf<br/>Document"]):::stuff+ s_5fbba7194a(["cv_pages<br/>Page"]):::stuff+ end+ subgraph sg_n_08a7186be9["process_cv"]+ n_937e750ea4["analyze_match"]+ s_bb41a103f0(["match_analysis<br/>CandidateMatch"]):::stuff+ n_786a2969d5["analyze_one_cv"]+ s_c47fe821d7(["candidate_profile<br/>CandidateProfile"]):::stuff+ n_38f0cfd11c["extract_one_cv"]+ s_2634ece93d(["cv_pdf<br/>Document"]):::stuff+ s_44e253b325(["cv_pages<br/>Page"]):::stuff+ end+ end+ end++ %% Pipeline input stuff nodes (no producer)+ s_9b7e74ac51(["job_offer_pdf<br/>Document"]):::stuff++ %% Data flow edges: producer -> stuff -> consumer+ n_a7ed00ac24 --> s_c5ae714e89+ n_b8469c838f --> s_d998350046+ n_f48b73fbee --> s_e1ffee913e+ n_d16f2fe381 --> s_5fbba7194a+ n_fde22777cb --> s_f9f703fbb4+ n_d24f39aa60 --> s_f1f80289df+ n_38f0cfd11c --> s_44e253b325+ n_786a2969d5 --> s_c47fe821d7+ n_c18aded200 --> s_5c911f7e54+ n_f6a25d1769 --> s_ea99eee6ed+ n_937e750ea4 --> s_bb41a103f0+ s_c5ae714e89 --> n_c18aded200+ s_9b7e74ac51 --> n_b8469c838f+ s_d998350046 --> n_fde22777cb+ s_e1ffee913e --> n_f6a25d1769+ s_427beb5195 --> n_d24f39aa60+ s_041bb18fb4 --> n_d16f2fe381+ s_2634ece93d --> n_38f0cfd11c+ s_5fbba7194a --> n_f48b73fbee+ s_f9f703fbb4 --> n_c18aded200+ s_f9f703fbb4 --> n_f6a25d1769+ s_f9f703fbb4 --> n_937e750ea4+ s_f1f80289df --> n_a7ed00ac24+ s_44e253b325 --> n_786a2969d5+ s_c47fe821d7 --> n_937e750ea4++ %% Batch edges: list-item relationships+ s_52d84618d0(["match_analyses<br/>CandidateMatch"]):::stuff+ s_5c911f7e54 -."[0]".-> s_52d84618d0+ s_ea99eee6ed -."[1]".-> s_52d84618d0+ s_bb41a103f0 -."[2]".-> s_52d84618d0++ %% Style definitions+ classDef failed fill:#ffcccc,stroke:#cc0000+ classDef stuff fill:#fff3e6,stroke:#cc6600,stroke-width:2px+ classDef controller fill:#e6f3ff,stroke:#0066cc++ %% Subgraph depth-based coloring+ style sg_n_08a7186be9 fill:#fffde6+ style sg_n_2cfb7a32c8 fill:#fffde6+ style sg_n_6e53e16369 fill:#fffde6+ style sg_n_8b2136e3fe fill:#e6f3ff+ style sg_n_91d5d6dc7c fill:#e6ffe6+ style sg_n_f8d5afb7cd fill:#e6ffe6```-## 4. Run Your Pipeline++## Run Your Method**Via CLI:**```bash-# Run with input file-pipelex run results/cv_match.mthds --inputs inputs.json+pipelex run bundle cv_batch_screening.mthds --inputs inputs.json```Create an `inputs.json` file with your PDF URLs:```json{- "cv_pdf": {- "concept": "PDF",- "content": {- "url": "https://pipelex-web.s3.amazonaws.com/demo/John-Doe-CV.pdf"- }+ "cvs": {+ "concept": "native.Document",+ "content": [+ { "url": "https://pipelex-web.s3.amazonaws.com/demo/John-Doe-CV.pdf" },+ { "path": "inputs/Jane-Smith-CV.pdf" }+ ]},"job_offer_pdf": {- "concept": "PDF",+ "concept": "native.Document","content": {"url": "https://pipelex-web.s3.amazonaws.com/demo/Job-Offer.pdf"}@@ -272,62 +369,105 @@ Create an `inputs.json` file with your PDF URLs:```pythonimport asyncio-import jsonfrom pipelex.pipeline.runner import PipelexRunnerfrom pipelex.pipelex import Pipelex+from pipelex.content import DocumentContent+# Generated by: pipelex generate structures cv_batch_screening.mthds+from structures.cv_batch_screening__candidate_match import CandidateMatch-async def run_pipeline():- with open("inputs.json", encoding="utf-8") as f:- inputs = json.load(f)-+async def run_pipeline() -> list[CandidateMatch]:runner = PipelexRunner()response = await runner.execute_pipeline(- pipe_code="cv_match",- inputs=inputs+ pipe_code="batch_analyze_cvs_for_job_offer",+ inputs={+ "cvs": {+ "concept": "native.Document",+ "content": [+ DocumentContent(url="https://pipelex-web.s3.amazonaws.com/demo/John-Doe-CV.pdf"),+ DocumentContent(path="inputs/Jane-Smith-CV.pdf"),+ ],+ },+ "job_offer_pdf": {+ "concept": "native.Document",+ "content": DocumentContent(url="https://pipelex-web.s3.amazonaws.com/demo/Job-Offer.pdf"),+ },+ },)pipe_output = response.pipe_output- print(pipe_output.main_stuff_as_str)+ print(pipe_output)+ return pipe_output.main_stuff_as_items(item_type=CandidateMatch)Pipelex.make()asyncio.run(run_pipeline())```+# What is Pipelex?++Pipelex is the reference Python runtime for executing AI methods defined in the [MTHDS](https://mthds.ai) open standard. It separates **what** a method does from **how** it runs — you declare intent, the runtime handles execution.++MTHDS is a typed, declarative language built on two primitives:++- **Concepts** — semantically typed data, named after real domain things (`ContractClause`, `CandidateProfile`, `Invoice`)+- **Pipes** — typed transformations with explicit inputs and outputs (LLM calls, extraction, image generation, branching, batching)++Methods are readable by domain experts, executable by agents, versionable in Git, and portable across runtimes. The `.mthds` format is TOML-based — no framework lock-in, no boilerplate.++**The sweet spot between code and agent skills:**++| | Code | MTHDS | Agent Skills |+|---|---|---|---|+| **Control** | Total control, total effort | Structured freedom, open standard | Total freedom, no guarantees |+| **Time to production** | Days, 80% boilerplate | Minutes, zero boilerplate | Minutes, different result every run |+| **Validation** | Deterministic, testable | Typed schemas, validated before runtime | No validation, no audit trail |+| **Audience** | Developers only | Engineers and domain experts | Anyone |++**Agent-first by design:** The Claude Code plugin lets agents write, edit, run, and compose methods. A domain expert who can describe what they need in plain language can have Claude author the method, which then runs consistently, is testable, and lives in version control.+++# The MTHDS Ecosystem++| | Description | Link |+|---|---|---|+| **MTHDS Standard** | The open standard specification — language, package system, and typed concepts | [mthds.ai](https://mthds.ai) |+| **MTHDS Hub** | Discover and share methods — browse packages, search by signature | [mthds.sh](https://mthds.sh) |+| **Skills Plugin** | Claude Code plugin — 11 commands to build, run, edit, check, fix, and publish methods | [github.com/mthds-ai/skills](https://github.com/mthds-ai/skills) |+| **Package System** | Versioned dependencies, lock files with SHA-256 integrity, cross-package references via `->` | [Packages docs](https://mthds.ai/packages/structure/) |+| **Know-How Graph** | Typed discovery — "I have X, I need Y" — find methods or chains by typed signature | [Know-How Graph](https://mthds.ai/know-how-graph/) |++### Skills Plugin Commands++| Command | Description |+|---------|-------------|+| `/mthds-build` | Build new AI method bundles from scratch |+| `/mthds-run` | Execute methods and interpret their JSON output |+| `/mthds-edit` | Modify existing methods — change pipes, update prompts, add steps |+| `/mthds-check` | Validate bundles for issues (read-only) |+| `/mthds-fix` | Auto-fix validation errors |+| `/mthds-explain` | Walk through execution flow in plain language |+| `/mthds-inputs` | Prepare inputs: templates, synthetic data, user files |+| `/mthds-install` | Install method packages from GitHub or local dirs |+| `/mthds-pkg` | Package management — init, deps, lock, install, update |+| `/mthds-publish` | Publish methods to the hub |+| `/mthds-share` | Share methods on social media |++<div>- <h2 align="center">🚀 See Pipelex in Action</h2>-+ <h2 align="center">See Pipelex in Action</h2>+<table align="center"><tr><td align="center" width="50%">- <h3>From Whiteboard to AI Method in less than 5 minutes with no hands (2025-07)</h3>+ <h3>Claude Code builds your AI Method</h3><a href="https://go.pipelex.com/demo"><img src="https://go.pipelex.com/demo-thumbnail" alt="Pipelex Demo" width="100%" style="max-width: 500px; height: auto;"></a></td>- <td align="center" width="50%">- <h3>The AI method that writes an AI method in 64 seconds (2025-09)</h3>- <a href="https://go.pipelex.com/Demo-Live">- <img src="https://d2cinlfp2qnig1.cloudfront.net/banners/pipelex_play_video_demo_live.jpg" alt="Pipelex Live Demo" width="100%" style="max-width: 500px; height: auto;">- </a>- </td></tr></table>--</div>--## 💡 What is Pipelex?--Pipelex is the reference Python runtime for executing **repeatable AI methods**, based on the [MTHDS](https://mthds.ai) open standard. Instead of cramming everything into one complex prompt, you break tasks into focused steps, each pipe handling one clear transformation.--Each pipe processes information using **Concepts** (typing with meaning) to ensure your pipelines make sense. The mthds language (`.mthds` files) is simple and human-readable, even for non-technical users. Each step can be structured and validated, giving you the reliability of software with the intelligence of AI.--## 📖 Next Steps-**Learn More:**-- [Design and Run Methods](https://docs.pipelex.com/home/6-build-reliable-ai-workflows/pipes/) - Complete guide with examples-- [Kick off a Method Project](https://docs.pipelex.com/home/6-build-reliable-ai-workflows/kick-off-a-methods-project/) - Deep dive into Pipelex-- [Configure AI Providers](https://docs.pipelex.com/home/5-setup/configure-ai-providers/) - Set up AI providers and models+</div>-## 🔧 IDE Extension+## IDE ExtensionWe **highly** recommend installing our extension for `.mthds` syntax highlighting in your IDE:@@ -336,15 +476,27 @@ We **highly** recommend installing our extension for `.mthds` syntax highlightinRunning `pipelex init` will also offer to install the extension automatically if it detects your IDE.-## 📚 Examples & Cookbook+## Examples & CookbookExplore real-world examples in our **Cookbook** repository:[](https://github.com/Pipelex/pipelex-cookbook/tree/main)-Clone it, fork it, and experiment with production-ready pipelines for various use cases.+Clone it, fork it, and experiment with production-ready methods for various use cases.++## Run Anywhere++The same `.mthds` file runs from multiple execution targets:++| Target | How |+|--------|-----|+| **CLI** | `pipelex run bundle method.mthds --inputs inputs.json` |+| **Python** | `PipelexRunner().execute_pipeline(...)` |+| **REST API** | Self-hosted API server |+| **MCP** | Model Context Protocol — agents call methods as tools |+| **n8n** | Pipelex node for workflow automation |-## 🎯 Optional Features+## Optional FeaturesThe package supports the following additional features:@@ -353,12 +505,13 @@ The package supports the following additional features:- `mistralai`: Mistral AI support for text generation and OCR- `bedrock`: Amazon Bedrock support for text generation- `fal`: Image generation with Black Forest Labs "FAL" service+- `linkup`: Web search with Linkup+- `docling`: OCR with DoclingInstall all extras:-Using `pip`:```bash-pip install "pipelex[anthropic,google,google-genai,mistralai,bedrock,fal]"+pip install "pipelex[anthropic,google,google-genai,mistralai,bedrock,fal,linkup,docling]"```## Privacy & Telemetry@@ -368,31 +521,31 @@ Pipelex supports two independent telemetry streams:- **Gateway Telemetry**: When using Pipelex Gateway, telemetry must be enabled (tied to your hashed API key) to monitor service quality and enforce fair usage. [Learn more](https://docs.pipelex.com/home/5-setup/telemetry/#gateway-telemetry-pipelex-controlled)- **Custom Telemetry**: User-controlled via `.pipelex/telemetry.toml` for your own observability systems (Langfuse, PostHog, OTLP). [Learn more](https://docs.pipelex.com/home/5-setup/telemetry/#custom-telemetry-user-controlled)-**We only collect technical data** (model names, token counts, latency, error rates) - never your prompts, completions, or business data. Set `DO_NOT_TRACK=1` to disable all telemetry (note: Gateway requires telemetry to function).+**We only collect technical data** (model names, token counts, latency, error rates) — never your prompts, completions, or business data. Set `DO_NOT_TRACK=1` to disable all telemetry (note: Gateway requires telemetry to function).For more details, see the [Telemetry Documentation](https://docs.pipelex.com/home/5-setup/telemetry/) or read our [Privacy Policy](https://go.pipelex.com/privacy-policy).-## 🤝 Contributing+## ContributingWe welcome contributions! Please see our [Contributing Guidelines](CONTRIBUTING.md) for details on how to get started, including development setup and testing information.-## 👥 Join the Community+## Join the CommunityJoin our vibrant Discord community to connect with other developers, share your experiences, and get help with your Pipelex projects](https://go.pipelex.com/discord)-## 💬 Support+## Support- **GitHub Issues**: For bug reports and feature requests- **Discussions**: For questions and community discussions- [**Documentation**](https://docs.pipelex.com/)-## ⭐ Star Us!+## Star Us!If you find Pipelex helpful, please consider giving us a star! It helps us reach more developers and continue improving the tool.-## 📝 License+## LicenseThis project is licensed under the [MIT license](LICENSE). Runtime dependencies are distributed under their own licenses via PyPI.@@ -400,4 +553,4 @@ This project is licensed under the [MIT license](LICENSE). Runtime dependencies"Pipelex" is a trademark of Evotis S.A.S.-© 2025 Evotis S.A.S.+© 2026 Evotis S.A.S.diff --git a/pyproject.toml b/pyproject.tomlindex 4760db302..bb26bb5b1 100644--- a/pyproject.toml+++ b/pyproject.toml@@ -1,6 +1,6 @@[project]name = "pipelex"-version = "0.20.2"+version = "0.20.3"description = "Execute composable AI methods declared in the MTHDS open standard"authors = [{ name = "Evotis S.A.S.", email = "[email protected]" }]maintainers = [{ name = "Pipelex staff", email = "[email protected]" }]diff --git a/uv.lock b/uv.lockindex ee4a2b961..68c92a3fe 100644--- a/uv.lock+++ b/uv.lock@@ -3313,7 +3313,7 @@ wheels = [[[package]]name = "pipelex"-version = "0.20.2"+version = "0.20.3"source = { editable = "." }dependencies = [{ name = "aiofiles" },