
Build AI methods with your coding agent, then run them anywhere: as an MCP for chatbots, as a webapp for people, or via API for your software.
Redesign README: lead with value, collapse details (#758)
Louis Choquel63dd86946d34
diff --git a/.gitignore b/.gitignoreindex b29451577..30d6c1835 100644--- a/.gitignore+++ b/.gitignore@@ -73,4 +73,5 @@ mthds-wipderived/# Claude plans-.claude/plans/\ No newline at end of file+.claude/plans/+.gstack/diff --git a/README.md b/README.mdindex 0a7923b76..b90f8c180 100644--- a/README.md+++ b/README.md@@ -4,12 +4,9 @@<br/><br/><br/>- <h2 align="center">Executable AI Methods</h2>- <p align="center">Pipelex is the reference Python runtime and Claude Code plugin for the <a href="https://mthds.ai">MTHDS</a> open standard.<br/>-Readable by humans, executable by agents. No boilerplate, no lock-in.</p>- <br/>- <p align="center"><b>An AI method</b> is a multi-step workflow that chains LLMs, OCR, image generation, and more — each step typed and validated.<br/>-<b>Executable</b> means each method becomes a new tool — agents and skills can call it, and it also runs standalone via CLI, Python, or REST API.</p>+ <h2 align="center">Build & Run AI Methods</h2>+ <p align="center">A method is a reusable, typed AI procedure — declared in a <code>.mthds</code> file and executed by Pipelex.<br/>+Each step is explicit, each output is structured, and every run is repeatable.</p><div>@@ -40,6 +37,25 @@ Readable by humans, executable by agents. No boilerplate, no lock-in.</p>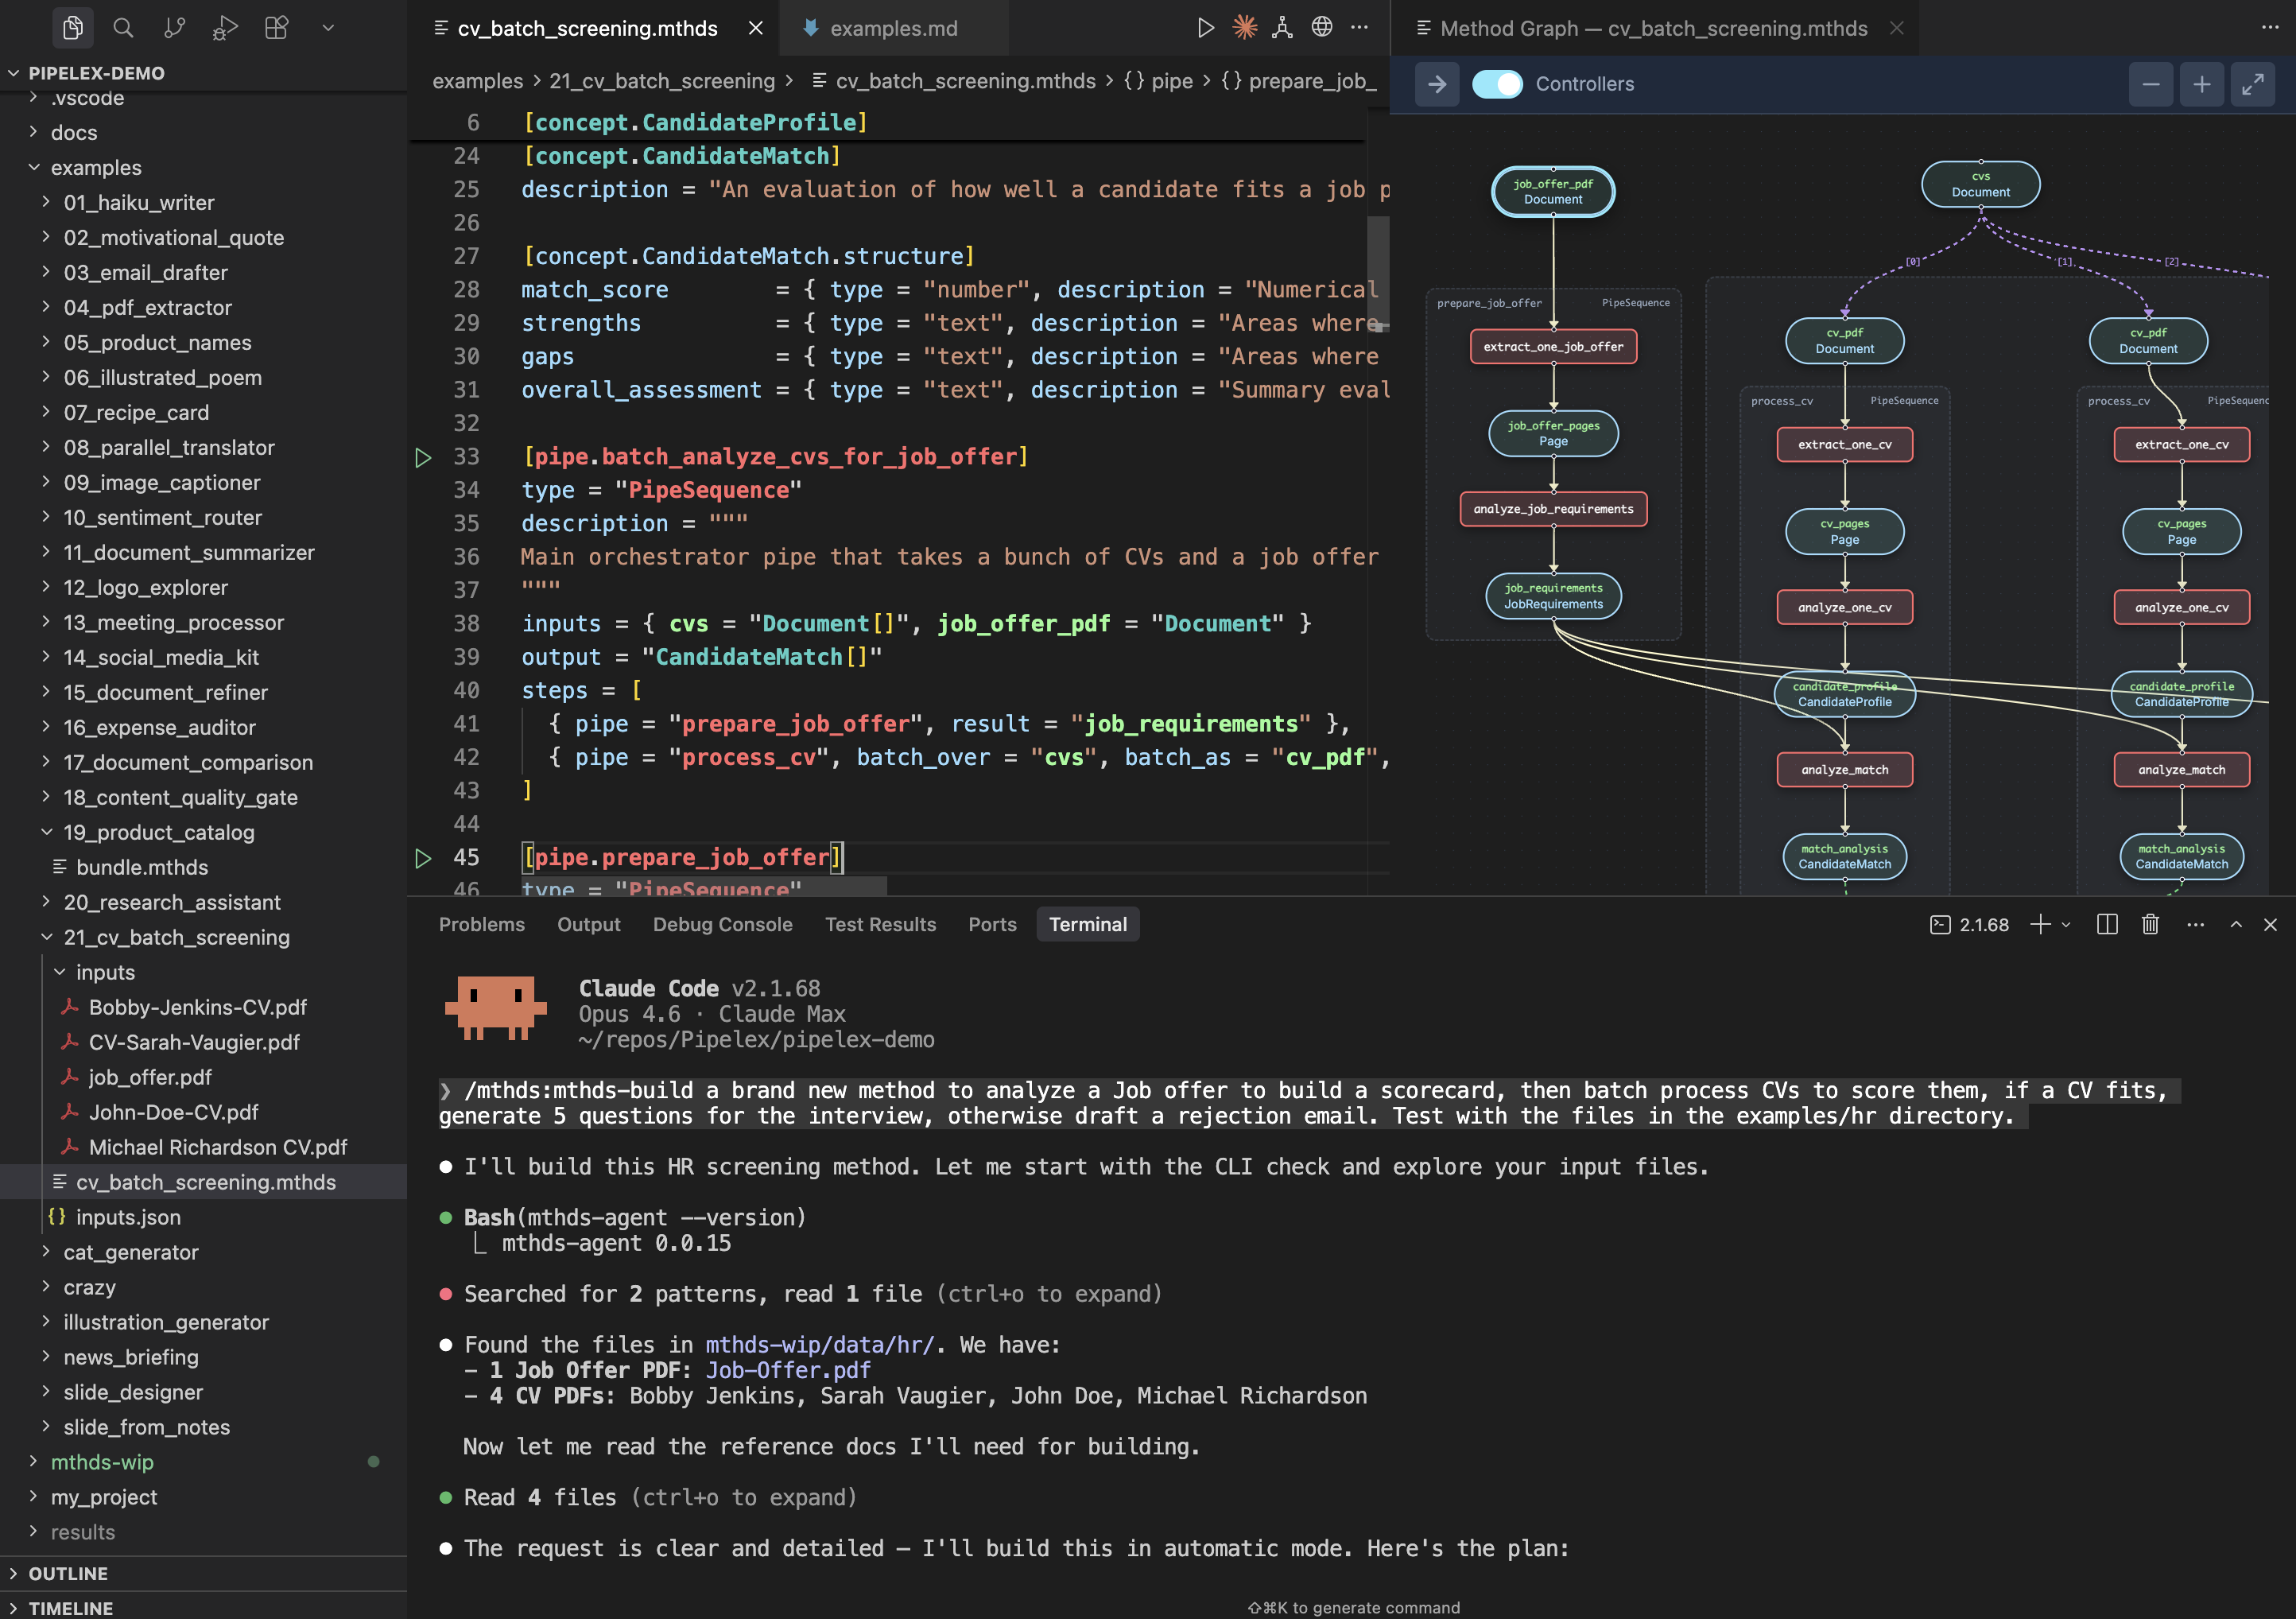+## What a Method Looks Like++```toml+[pipe.summarize_article]+type = "PipeLLM"+inputs = { article = "Text", audience = "Text" }+output = "Text"+prompt = "Summarize $article in three bullet points for $audience."+```++From here, Pipelex handles model routing across 60+ models, structured output parsing, and pipeline orchestration.++## Why Methods?++| | |+|---|---|+| **Declarative** — Human-readable `.mthds` files that work across models | **Typed** — Semantic types: AI understands what you mean, every input/output connects with purpose |+| **Repeatable** — Deterministic orchestration with controlled room for AI creativity | **Composable** — Chain pipes into sequences, nest methods inside methods, share with the community |+# Quick Start```bash@@ -47,7 +63,7 @@ pip install pipelexpipelex init```-## Path A: With Claude Code (Recommended)+## With Claude Code (Recommended)Install the `mthds` npm package:@@ -56,29 +72,33 @@ npm install -g mthds```Start Claude Code:+```bashclaude```Tell Claude to install the MTHDS skills marketplace:-```bash++```/plugin marketplace add mthds-ai/skills```then install the MTHDS skills plugin:-```bash++```/plugin install mthds@mthds-ai-skills```then you must exit Claude Code and reopen it.-```bash++```/exit```Build your first method:```-/mthds-build A method to analyze a Job offer to build a scorecard, then batch process CVs to score them, if a CV fits, generate 5 questions for the interview, otherwise draft a rejection email+/mthds-build A method to summarize articles with key takeaways for different audiences```Run it:@@ -87,7 +107,7 @@ Run it:/mthds-run```-## Path B: Without Claude Code+## Without Claude Code1. Install the [VS Code extension](https://go.pipelex.com/vscode) for `.mthds` syntax highlighting2. Browse methods on the [MTHDS Hub](https://mthds.sh) for inspiration@@ -95,32 +115,39 @@ Run it:4. Validate with `pipelex validate bundle your_method.mthds`5. Run them with `pipelex run bundle your_method.mthds`6. View the flowchart in VS Code thanks to the extension-7. Use the [`mthds` npm package](https://github.com/mthds-ai/mthds-js) to package and publish methods on the hub## Configure AI Access-To run methods with AI models, choose one of these options:+- **Pipelex Gateway (Recommended)** — Free credits, single API key for LLMs, OCR / document extraction, and image generation across all major providers. [Get your key](https://app.pipelex.com/), add `PIPELEX_GATEWAY_API_KEY=your-key-here` to `~/.pipelex/.env`, run `pipelex init`.+- **Bring Your Own Keys** — Use existing API keys from OpenAI, Anthropic, Google, Mistral, etc. See [Configure AI Providers](https://docs.pipelex.com/latest/setup/configure-ai-providers/).+- **Local AI** — Ollama, vLLM, LM Studio, or llama.cpp — no API keys required. See [Configure AI Providers](https://docs.pipelex.com/latest/setup/configure-ai-providers/).-### Option A: Pipelex Gateway (Recommended)-Get **free credits** with a single API key for LLMs, document extraction, and image generation across all major providers (OpenAI, Anthropic, Google, Azure, and more).+# Real-World Example: CV Batch Screening-1. Get your API key at [app.pipelex.com](https://app.pipelex.com/)-2. Add it to your `.env` file: `PIPELEX_GATEWAY_API_KEY=your-key-here`-3. Run `pipelex init` and accept the Gateway terms of service+A production method that takes a stack of CVs and a job offer PDF, extracts and analyzes each, then scores how well each candidate matches the role.-### Option B: Bring Your Own Keys--Use your existing API keys from OpenAI, Anthropic, Google, Mistral, etc. See [Configure AI Providers](https://docs.pipelex.com/latest/setup/configure-ai-providers/).--### Option C: Local AI+**cv_batch_screening.mthds**-Run models locally with Ollama, vLLM, LM Studio, or llama.cpp — no API keys required. See [Configure AI Providers](https://docs.pipelex.com/latest/setup/configure-ai-providers/).+```toml+[pipe.batch_analyze_cvs_for_job_offer]+type = "PipeSequence"+description = """+Main orchestrator pipe that takes a bunch of CVs and a job offer in PDF format, and analyzes how they match.+"""+inputs = { cvs = "Document[]", job_offer_pdf = "Document" }+output = "CandidateMatch[]"+steps = [+ { pipe = "prepare_job_offer", result = "job_requirements" },+ { pipe = "process_cv", batch_over = "cvs", batch_as = "cv_pdf", result = "match_analyses" },+]+```+<details>+<summary><b>View concepts, supporting pipes, flowchart, and run commands</b></summary>-# Example: CV Batch Screening+**Concepts:**-**cv_batch_screening.mthds**```toml[concept.CandidateProfile]description = "A structured summary of a job candidate's professional background extracted from their CV."@@ -148,18 +175,6 @@ match_score = { type = "number", description = "Numerical score representstrengths = { type = "text", description = "Areas where the candidate meets or exceeds requirements", required = true }gaps = { type = "text", description = "Areas where the candidate falls short of requirements", required = true }overall_assessment = { type = "text", description = "Summary evaluation of the candidate's suitability", required = true }--[pipe.batch_analyze_cvs_for_job_offer]-type = "PipeSequence"-description = """-Main orchestrator pipe that takes a bunch of CVs and a job offer in PDF format, and analyzes how they match.-"""-inputs = { cvs = "Document[]", job_offer_pdf = "Document" }-output = "CandidateMatch[]"-steps = [- { pipe = "prepare_job_offer", result = "job_requirements" },- { pipe = "process_cv", batch_over = "cvs", batch_as = "cv_pdf", result = "match_analyses" },-]```<details>@@ -258,10 +273,11 @@ Analyze how well the candidate matches the job requirements. Evaluate their fitProvide a comprehensive match analysis including a numerical score, identified strengths, gaps, and an overall assessment."""```-</details>+</details>-**View the pipeline flowchart:**+<details>+<summary><b>View the pipeline flowchart</b></summary>```mermaidflowchart LR@@ -354,7 +370,9 @@ flowchart LRstyle sg_n_f8d5afb7cd fill:#e6ffe6```-## Run Your Method+</details>++### Run Your Method**Via CLI:**@@ -418,27 +436,37 @@ Pipelex.make()asyncio.run(run_pipeline())```-# What is Pipelex?+</details>-Pipelex is the reference Python runtime for executing AI methods defined in the [MTHDS](https://mthds.ai) open standard. It separates **what** a method does from **how** it runs — you declare intent, the runtime handles execution.-MTHDS is a typed, declarative language built on two primitives:+## See Pipelex in Action-- **Concepts** — semantically typed data, named after real domain things (`ContractClause`, `CandidateProfile`, `Invoice`)-- **Pipes** — typed transformations with explicit inputs and outputs (LLM calls, extraction, image generation, branching, batching)+**Claude Code builds your AI Method**-Methods are readable by domain experts, executable by agents, versionable in Git, and portable across runtimes. The `.mthds` format is TOML-based — no framework lock-in, no boilerplate.+<a href="https://go.pipelex.com/demo">+ <img src="https://go.pipelex.com/demo-thumbnail" alt="Pipelex Demo" width="500" style="max-width: 100%; height: auto;">+</a>-**The sweet spot between code and agent skills:**+## IDE Extension-| | Code | MTHDS | Agent Skills |-|---|---|---|---|-| **Control** | Total control, total effort | Structured freedom, open standard | Total freedom, no guarantees |-| **Time to production** | Days, 80% boilerplate | Minutes, zero boilerplate | Minutes, different result every run |-| **Validation** | Deterministic, testable | Typed schemas, validated before runtime | No validation, no audit trail |-| **Audience** | Developers only | Engineers and domain experts | Anyone |+We **highly** recommend installing our extension for `.mthds` syntax highlighting in your IDE:++- **VS Code**: Install from the [VS Code Marketplace](https://marketplace.visualstudio.com/items?itemName=pipelex.pipelex)+- **Cursor, Windsurf, and other VS Code forks**: Install from the [Open VSX Registry](https://open-vsx.org/extension/Pipelex/pipelex), or search for "Pipelex" directly in your extensions tab-**Agent-first by design:** The Claude Code plugin lets agents write, edit, run, and compose methods. A domain expert who can describe what they need in plain language can have Claude author the method, which then runs consistently, is testable, and lives in version control.+Running `pipelex init` will also offer to install the extension automatically if it detects your IDE.++## Run Anywhere++The same `.mthds` file runs from multiple execution targets:++| Target | How |+|--------|-----|+| **CLI** | `pipelex run bundle method.mthds --inputs inputs.json` |+| **Python** | `PipelexRunner().execute_pipeline(...)` |+| **REST API** | Self-hosted API server |+| **MCP** | Model Context Protocol — agents call methods as tools |+| **n8n** | Pipelex node for workflow automation |# The MTHDS Ecosystem@@ -448,10 +476,11 @@ Methods are readable by domain experts, executable by agents, versionable in Git| **MTHDS Standard** | The open standard specification — language, package system, and typed concepts | [mthds.ai](https://mthds.ai) || **MTHDS Hub** | Discover and share methods — browse packages, search by signature | [mthds.sh](https://mthds.sh) || **Skills Plugin** | Claude Code plugin — 11 commands to build, run, edit, check, fix, and publish methods | [github.com/mthds-ai/skills](https://github.com/mthds-ai/skills) |-| **Package System** | Versioned dependencies, lock files with SHA-256 integrity, cross-package references via `->` | [Packages docs](https://mthds.ai/packages/structure/) |-| **Know-How Graph** | Typed discovery — "I have X, I need Y" — find methods or chains by typed signature | [Know-How Graph](https://mthds.ai/know-how-graph/) |+| **Package System** | Versioned dependencies, lock files with SHA-256 integrity, cross-package references via `->` | [Packages docs](https://mthds.ai/latest/packages/structure/) |+| **Know-How Graph** | Typed discovery — "I have X, I need Y" — find methods or chains by typed signature | [Know-How Graph](https://mthds.ai/latest/know-how-graph/) |-### Skills Plugin Commands+<details>+<summary><b>View all 11 Skills Plugin commands</b></summary>| Command | Description ||---------|-------------|@@ -467,31 +496,8 @@ Methods are readable by domain experts, executable by agents, versionable in Git| `/mthds-publish` | Publish methods to the hub || `/mthds-share` | Share methods on social media |+</details>-<div>- <h2 align="center">See Pipelex in Action</h2>-- <table align="center">- <tr>- <td align="center" width="50%">- <h3>Claude Code builds your AI Method</h3>- <a href="https://go.pipelex.com/demo">- <img src="https://go.pipelex.com/demo-thumbnail" alt="Pipelex Demo" width="100%" style="max-width: 500px; height: auto;">- </a>- </td>- </tr>- </table>--</div>--## IDE Extension--We **highly** recommend installing our extension for `.mthds` syntax highlighting in your IDE:--- **VS Code**: Install from the [VS Code Marketplace](https://marketplace.visualstudio.com/items?itemName=pipelex.pipelex)-- **Cursor, Windsurf, and other VS Code forks**: Install from the [Open VSX Registry](https://open-vsx.org/extension/Pipelex/pipelex), or search for "Pipelex" directly in your extensions tab--Running `pipelex init` will also offer to install the extension automatically if it detects your IDE.## Examples & Cookbook@@ -501,18 +507,6 @@ Explore real-world examples in our **Cookbook** repository:Clone it, fork it, and experiment with production-ready methods for various use cases.-## Run Anywhere--The same `.mthds` file runs from multiple execution targets:--| Target | How |-|--------|-----|-| **CLI** | `pipelex run bundle method.mthds --inputs inputs.json` |-| **Python** | `PipelexRunner().execute_pipeline(...)` |-| **REST API** | Self-hosted API server |-| **MCP** | Model Context Protocol — agents call methods as tools |-| **n8n** | Pipelex node for workflow automation |-## Optional FeaturesThe package supports the following additional features:@@ -531,36 +525,13 @@ Install all extras:pip install "pipelex[anthropic,google,google-genai,mistralai,bedrock,fal,linkup,docling]"```-## Privacy & Telemetry--Pipelex supports two independent telemetry streams:--- **Gateway Telemetry**: When using Pipelex Gateway, telemetry must be enabled (tied to your hashed API key) to monitor service quality and enforce fair usage. [Learn more](https://docs.pipelex.com/latest/setup/telemetry/#gateway-telemetry-pipelex-controlled)-- **Custom Telemetry**: User-controlled via `.pipelex/telemetry.toml` for your own observability systems (Langfuse, PostHog, OTLP). [Learn more](https://docs.pipelex.com/latest/setup/telemetry/#custom-telemetry-user-controlled)--**We only collect technical data** (model names, token counts, latency, error rates) — never your prompts, completions, or business data. Set `DO_NOT_TRACK=1` to disable all telemetry (note: Gateway requires telemetry to function).--For more details, see the [Telemetry Documentation](https://docs.pipelex.com/latest/setup/telemetry/) or read our [Privacy Policy](https://go.pipelex.com/privacy-policy).--## Contributing--We welcome contributions! Please see our [Contributing Guidelines](CONTRIBUTING.md) for details on how to get started, including development setup and testing information.--## Join the Community--Join our vibrant Discord community to connect with other developers, share your experiences, and get help with your Pipelex projects!--[](https://go.pipelex.com/discord)--## Support+----- **GitHub Issues**: For bug reports and feature requests-- **Discussions**: For questions and community discussions-- [**Documentation**](https://docs.pipelex.com/)+**Privacy & Telemetry** — Pipelex Gateway collects only technical data (model names, token counts, latency) — never prompts or business data. If you want to avoid Gateway telemetry, disable `pipelex_gateway` and use your own provider keys or local AI instead. [Learn more](https://docs.pipelex.com/latest/setup/telemetry/)-## Star Us!+**Contributing** — We welcome contributions! See our [Contributing Guidelines](CONTRIBUTING.md).-If you find Pipelex helpful, please consider giving us a star! It helps us reach more developers and continue improving the tool.+**Community** — [](https://go.pipelex.com/discord) [GitHub Issues](https://github.com/Pipelex/pipelex/issues) · [Discussions](https://github.com/Pipelex/pipelex/discussions) · [Documentation](https://docs.pipelex.com/)## License@@ -570,4 +541,4 @@ This project is licensed under the [MIT license](LICENSE). Runtime dependencies"Pipelex" is a trademark of Evotis S.A.S.-© 2026 Evotis S.A.S.+© 2025-2026 Evotis S.A.S.diff --git a/docs/CLAUDE.md b/docs/CLAUDE.mdindex b23ce0e8f..b6d05112b 100644--- a/docs/CLAUDE.md+++ b/docs/CLAUDE.md@@ -54,6 +54,14 @@ The `docs-deploy-root` Makefile target deploys root assets (`404.html`, `robots.- `meta-manager` — applies `docs/.meta.yml` defaults to all pages- `glightbox` — image lightbox+## Sidebar Width++Material for MkDocs hard-codes `.md-sidebar { width: 12.1rem }`. The root font-size is **20px** (not 16), so `rem` values are larger than you'd expect (12.1rem = 242px). Custom overrides live in `docs/stylesheets/general.css`.++To widen the sidebar you must override **two** things:+1. `.md-sidebar { width: ... }` — the container itself+2. `.md-sidebar .md-sidebar__inner { padding-right: 4px }` — the theme dynamically inflates `padding-right` on `.md-sidebar__inner` to absorb extra container width, keeping the nav at its original size. Pin this padding to prevent that.+## Common Mistakes to Avoid- Do NOT create `docs/404.md` — it poisons the sitemap with an indexable `/latest/404/` URLdiff --git a/docs/building-methods/concepts/inline-structures.md b/docs/building-methods/concepts/inline-structures.mdindex 0b3337a3f..5d6c4c2f7 100644--- a/docs/building-methods/concepts/inline-structures.md+++ b/docs/building-methods/concepts/inline-structures.md@@ -310,5 +310,5 @@ See [Python StructuredContent Classes](python-classes.md) for advanced features.- [Define Your Concepts](define_your_concepts.md) - Learn about concept semantics and naming- [Python StructuredContent Classes](python-classes.md) - Advanced features with Python-- [Writing Methods Tutorial](../../get-started/write-methods-manually.md) - Get started with structured outputs+- [MTHDS Language Tutorial](../../get-started/mthds-language-tutorial.md) - Get started with structured outputsdiff --git a/docs/building-methods/concepts/native-concepts.md b/docs/building-methods/concepts/native-concepts.mdindex e444b273f..331adb396 100644--- a/docs/building-methods/concepts/native-concepts.md+++ b/docs/building-methods/concepts/native-concepts.md@@ -355,5 +355,5 @@ prompt = "What is $topic?"- [Define Your Concepts](define_your_concepts.md) - Learn about concept semantics- [Inline Structures](inline-structures.md) - Add structure to refined concepts- [Python StructuredContent Classes](python-classes.md) - Advanced customization-- [Writing Methods Tutorial](../../get-started/write-methods-manually.md) - Use native concepts in pipelines+- [MTHDS Language Tutorial](../../get-started/mthds-language-tutorial.md) - Use native concepts in pipelinesdiff --git a/docs/building-methods/concepts/python-classes.md b/docs/building-methods/concepts/python-classes.mdindex e55843a21..23e83fa01 100644--- a/docs/building-methods/concepts/python-classes.md+++ b/docs/building-methods/concepts/python-classes.md@@ -259,6 +259,5 @@ Product = "A product in the catalog"- [Inline Structures](inline-structures.md) - Fast prototyping with TOML- [Define Your Concepts](define_your_concepts.md) - Learn about concept semantics and naming-<!-- path verified: resolves to docs/get-started/write-methods-manually.md -->-- [Writing Methods Tutorial](../../get-started/write-methods-manually.md) - Get started with structured outputs+- [MTHDS Language Tutorial](../../get-started/mthds-language-tutorial.md) - Get started with structured outputsdiff --git a/docs/building-methods/pipes/pipe-controllers/PipeSequence.md b/docs/building-methods/pipes/pipe-controllers/PipeSequence.mdindex 664063fed..7d97ea029 100644--- a/docs/building-methods/pipes/pipe-controllers/PipeSequence.md+++ b/docs/building-methods/pipes/pipe-controllers/PipeSequence.md@@ -78,7 +78,7 @@ steps = [## Related Documentation-- [Invoice Extractor Example](../../../cookbook/invoice-extractor.md) - Complete invoice processing pipeline using PipeSequence+- [Invoice Extraction Example](../../../cookbook/extract-invoice.md) - Complete invoice processing pipeline using PipeSequence- [Write Tweet Example](../../../cookbook/write-tweet.md) - Multi-step tweet generation workflow- [Table Extraction Example](../../../cookbook/extract-table.md) - Extract and correct tables from images- [Gantt Extraction Example](../../../cookbook/extract-gantt.md) - Extract Gantt chart data from documents\ No newline at end of filediff --git a/docs/building-methods/pipes/pipe-operators/PipeExtract.md b/docs/building-methods/pipes/pipe-operators/PipeExtract.mdindex c62ae6142..d56309d51 100644--- a/docs/building-methods/pipes/pipe-operators/PipeExtract.md+++ b/docs/building-methods/pipes/pipe-operators/PipeExtract.md@@ -82,7 +82,6 @@ To use this pipe, first load a PDF into the `ScannedDocument` concept. After the## Related Documentation-- [Simple OCR Example](../../../cookbook/simple-ocr.md) - Basic OCR pipeline using PipeExtract-- [Generic Extraction Example](../../../cookbook/extract-generic.md) - Multi-modal document extraction-- [Invoice Extractor Example](../../../cookbook/invoice-extractor.md) - Complete invoice processing pipeline+- [Generic Document Extraction Example](../../../cookbook/extract-generic.md) - Extract markdown from complex PDFs using vision+- [Invoice Extraction Example](../../../cookbook/extract-invoice.md) - Complete invoice processing pipeline- [Document Extraction Feature](../../../features/document-extraction.md) - Overview of document extraction capabilitiesdiff --git a/docs/building-methods/pipes/pipe-operators/PipeLLM.md b/docs/building-methods/pipes/pipe-operators/PipeLLM.mdindex 0e423e4d9..e59db0619 100644--- a/docs/building-methods/pipes/pipe-operators/PipeLLM.md+++ b/docs/building-methods/pipes/pipe-operators/PipeLLM.md@@ -380,7 +380,7 @@ Analyze the following topic in depth, considering multiple perspectives:## Related Documentation- [Hello World Example](../../../cookbook/hello-world.md) - Simple introductory example using PipeLLM-- [Invoice Extractor Example](../../../cookbook/invoice-extractor.md) - Complete invoice processing pipeline+- [Invoice Extraction Example](../../../cookbook/extract-invoice.md) - Complete invoice processing pipeline- [Write Tweet Example](../../../cookbook/write-tweet.md) - Multi-step tweet generation workflow- [Table Extraction Example](../../../cookbook/extract-table.md) - Extract and correct tables from images- [Gantt Extraction Example](../../../cookbook/extract-gantt.md) - Extract Gantt chart data from documents\ No newline at end of filediff --git a/docs/configuration/config-technical/inference-backend-config.md b/docs/configuration/config-technical/inference-backend-config.mdindex 6c4882de8..5afd37d4f 100644--- a/docs/configuration/config-technical/inference-backend-config.md+++ b/docs/configuration/config-technical/inference-backend-config.md@@ -658,4 +658,4 @@ Common error types:- [LLM Integration](../../features/llm-integration.md) - Overview of LLM provider support and capabilities- [PipeLLM Operator](../../building-methods/pipes/pipe-operators/PipeLLM.md) - The pipe operator that uses inference backends-- [Configure AI Providers](../../setup/configure-ai-providers.md) - Setup guide for connecting AI providers+- [Configure AI Providers](../../get-started/configure-ai-providers.md) - Setup guide for connecting AI providersdiff --git a/docs/cookbook/advisory-board.md b/docs/cookbook/advisory-board.mdnew file mode 100644index 000000000..6f51c09fb--- /dev/null+++ b/docs/cookbook/advisory-board.md@@ -0,0 +1,65 @@+---+title: "Advisory Board Example"+description: "Solve complex business problems through multi-board consultation — a Pipelex pipeline that consults specialized advisory boards and synthesizes strategic recommendations."+---++# Example: Advisory Board++!!! warning "Work in Progress"+ This example is under active development and may change.++This example solves complex business problems by consulting multiple specialized advisory boards (Executive, Product, Engineering, Marketing, etc.), analyzing consensus and conflicts across their responses, and producing a comprehensive strategic report.++## Get the code++[](https://github.com/Pipelex/pipelex-cookbook/blob/main/examples/wip/advisory_board/bundle.mthds)++## What it demonstrates++- Complex concept hierarchy (BusinessProblem, AdvisoryBoard, BoardResponse, ConsensusItem, ConflictItem, StrategicReport, etc.)+- Multi-board consultation pattern with batching+- Consensus and conflict analysis across expert opinions+- Multi-file method bundle (main `bundle.mthds` + `presentation.mthds`)+- 16 specialized advisory boards to choose from++## The Method: `bundle.mthds`++### Pipeline overview++```toml+[pipe.master_advisory_orchestrator]+type = "PipeSequence"+inputs = { user_input = "Text" }+output = "presentation.MarkdownReport"+steps = [+ { pipe = "classify_business_problem", result = "business_problem" },+ { pipe = "select_advisory_boards", result = "selected_advisory_boards" },+ { pipe = "consult_board", batch_over = "selected_advisory_boards",+ batch_as = "advisory_board", result = "board_consultations" },+ { pipe = "analyze_board_responses", result = "response_analysis" },+ { pipe = "generate_strategic_report", result = "strategic_report" },+ { pipe = "present_as_markdown", result = "strategic_report_markdown" },+]+```++The pipeline:++1. **Classifies** the business problem into a structured `BusinessProblem` (category, urgency, stakeholders)+2. **Selects** 5-10 relevant advisory boards from 16 available+3. **Consults** each board in parallel (batched) for domain-specific recommendations+4. **Analyzes** all responses to find consensus, conflicts, and unique insights+5. **Generates** a comprehensive strategic report with implementation roadmap and risk assessment+6. **Presents** the report as formatted markdown++## How to run++```bash+pipelex run bundle examples/wip/advisory_board/bundle.mthds \+ -i examples/wip/advisory_board/inputs.json+```++## Related Documentation++- [PipeSequence Controller](../building-methods/pipes/pipe-controllers/PipeSequence.md) - Chain pipes into sequential workflows+- [PipeLLM Operator](../building-methods/pipes/pipe-operators/PipeLLM.md) - The core operator for LLM interactions+- [Understanding Multiplicity](../building-methods/pipes/understanding-multiplicity.md) - How batching worksdiff --git a/docs/cookbook/blog-article-generator.md b/docs/cookbook/blog-article-generator.mdnew file mode 100644index 000000000..15d1b3d7c--- /dev/null+++ b/docs/cookbook/blog-article-generator.md@@ -0,0 +1,66 @@+---+title: "Blog Article Generator Example"+description: "Generate SEO-optimized blog articles from a structured request using a two-step Pipelex pipeline."+---++# Example: Blog Article Generator++!!! warning "Work in Progress"+ This example is under active development and may change.++This example generates complete SEO-optimized blog articles from a structured request. It uses a two-step pipeline: create an outline, then write the full article.++## Get the code++[](https://github.com/Pipelex/pipelex-cookbook/blob/main/examples/wip/blog_article_generator/bundle.mthds)++## What it demonstrates++- Structured input concept (`BlogArticleRequest` with topic, audience, tone, length)+- Two-step content generation: outline then write+- Constrained choices for tone and length fields++## The Method: `bundle.mthds`++### Input concept++```toml+[concept.BlogArticleRequest]+description = "Structured request describing the blog article to generate"++[concept.BlogArticleRequest.structure]+text = { type = "text", description = "Free-form instruction for the article", required = true }+topic = { type = "text", description = "The main topic of the blog article", required = true }+audience = { type = "text", description = "Target audience for the article", required = true }+tone = { type = "text", description = "Writing tone", choices = [+ "Casual", "Professional", "Humorous", "Academic",+], required = true }+length = { type = "text", description = "Desired article length", choices = [+ "Short", "Medium", "Long",+], required = true }+```++### Pipeline++```toml+[pipe.generate_blog_article]+type = "PipeSequence"+inputs = { user_prompt = "BlogArticleRequest" }+output = "BlogArticle"+steps = [+ { pipe = "create_outline", result = "outline" },+ { pipe = "write_article", result = "article" },+]+```++## How to run++```bash+pipelex run bundle examples/wip/blog_article_generator/bundle.mthds \+ -i examples/wip/blog_article_generator/inputs.json+```++## Related Documentation++- [PipeLLM Operator](../building-methods/pipes/pipe-operators/PipeLLM.md) - The core operator for LLM interactions+- [PipeSequence Controller](../building-methods/pipes/pipe-controllers/PipeSequence.md) - Chain pipes into sequential workflowsdiff --git a/docs/cookbook/design-slides.md b/docs/cookbook/design-slides.mdnew file mode 100644index 000000000..995d0f74c--- /dev/null+++ b/docs/cookbook/design-slides.md@@ -0,0 +1,83 @@+---+title: "Design Slides Example"+description: "Generate multiple slide design proposals from a brief — including themes, visual mockups, and an HTML report — using Pipelex."+---++# Example: Design Slides++This example takes a slide design brief and generates multiple themed design proposals, complete with visual mockups and an HTML report comparing them.++## Get the code++[](https://github.com/Pipelex/pipelex-cookbook/blob/main/examples/b_basics/generate_visuals/design_slides/bundle.mthds)++## What it demonstrates++- Rich concept hierarchy (nested structures: `Theme` contains `ColorPalette`, `Typography`, `LayoutSettings`, `StyleSettings`)+- `nb_output` parameter to generate multiple results from a single pipe+- `PipeImgGen` for generating visual mockup images+- `PipeCompose` with an HTML template for report rendering+- Multi-step creative pipeline: polish brief, generate themes, render visuals, compose report++## The Method: `bundle.mthds`++### Key concepts++The method defines a deep hierarchy of design concepts:++```toml+[concept.SlideDesignBrief]+description = "Client brief for slide deck design"++[concept.SlideDesignBrief.structure]+topic = { type = "text", description = "The main topic or subject of the presentation", required = true }+brand_guidelines = { type = "text", description = "The client's brand guidelines", required = false }+tone = { type = "text", description = "The tone of the presentation", choices = [+ "formal", "playful", "innovative", "trustworthy", "artsy",+], required = false }+# ... goal, audience fields+```++```toml+[concept.Theme]+description = "Complete presentation theme with colors, typography, layout, and style"++[concept.Theme.structure]+name = { type = "text", description = "Theme name identifier", required = true }+colors = { type = "concept", concept_ref = "ColorPalette", description = "Color palette for the theme", required = true }+typography = { type = "concept", concept_ref = "Typography", description = "Typography settings", required = true }+layout = { type = "concept", concept_ref = "LayoutSettings", description = "Layout configuration", required = true }+style = { type = "concept", concept_ref = "StyleSettings", description = "Visual style settings", required = true }+```++### Pipeline++```toml+[pipe.generate_design_proposals_from_rough_brief]+type = "PipeSequence"+description = "Transform a design brief into multiple themes with visual mockups and HTML report"+inputs = { brief = "SlideDesignBrief" }+output = "Html"+steps = [+ { pipe = "polish_brief", result = "polished_brief" },+ { pipe = "generate_multiple_themes", nb_output = 3, result = "themes" },+ { pipe = "render_visual_proposal", batch_over = "themes", batch_as = "theme", result = "design_proposals" },+ { pipe = "compose_proposals_report", result = "proposals_report" },+]+```++The `nb_output = 3` parameter tells `generate_multiple_themes` to produce 3 different theme proposals. Each theme is then rendered as a visual mockup using `PipeImgGen`, and everything is assembled into an HTML report.++## How to run++```bash+pipelex run bundle examples/b_basics/generate_visuals/design_slides/bundle.mthds \+ -i examples/b_basics/generate_visuals/design_slides/inputs.json+```++## Related Documentation++- [PipeLLM Operator](../building-methods/pipes/pipe-operators/PipeLLM.md) - The core operator for LLM interactions+- [PipeImgGen Operator](../building-methods/pipes/pipe-operators/PipeImgGen.md) - Generate images from prompts+- [PipeCompose Operator](../building-methods/pipes/pipe-operators/PipeCompose.md) - Template-based data composition+- [PipeSequence Controller](../building-methods/pipes/pipe-controllers/PipeSequence.md) - Chain pipes into sequential workflowsdiff --git a/docs/cookbook/discord-newsletter.md b/docs/cookbook/discord-newsletter.mdnew file mode 100644index 000000000..2053d9f46--- /dev/null+++ b/docs/cookbook/discord-newsletter.md@@ -0,0 +1,71 @@+---+title: "Discord Newsletter Example"+description: "Generate HTML newsletters from Discord channel data — summarize messages, organize by category, and format as a weekly digest."+---++# Example: Discord Newsletter++!!! warning "Work in Progress"+ This example is under active development and may change.++This example generates HTML newsletters from Discord channel data. It summarizes messages from each channel, organizes them by category (Share, Introduce Yourself, Geographic Hubs), and formats everything as a weekly newsletter.++## Get the code++[](https://github.com/Pipelex/pipelex-cookbook/blob/main/examples/wip/discord_newsletter/bundle.mthds)++## What it demonstrates++- `PipeCondition` for conditional routing based on channel name+- Structured Discord data concepts (messages, attachments, embeds, channels)+- Channel-specific summarization strategies (new members vs. general)+- `PipeCompose` with complex Jinja2 HTML template (filtering, sorting, conditional sections)+- Custom Python runner for loading external JSON data++## The Method: `bundle.mthds`++### Pipeline++```toml+[pipe.write_discord_newsletter]+type = "PipeSequence"+inputs = { discord_channel_updates = "DiscordChannelUpdate[]" }+output = "HtmlNewsletter"+steps = [+ { pipe = "summarize_discord_channel_update",+ batch_over = "discord_channel_updates", batch_as = "discord_channel_update",+ result = "channel_summaries" },+ { pipe = "write_weekly_summary", result = "weekly_summary" },+ { pipe = "format_html_newsletter", result = "html_newsletter" },+]+```++### Conditional routing++The `summarize_discord_channel_update` pipe uses `PipeCondition` to route different channels to different summarization strategies:++```toml+[pipe.summarize_discord_channel_update]+type = "PipeCondition"+description = "Select the appropriate summary pipe based on the channel name"+inputs = { discord_channel_update = "DiscordChannelUpdate" }+output = "ChannelSummary"+expression = "discord_channel_update.name"+outcomes = { "Introduce-Yourself" = "summarize_discord_channel_update_for_new_members" }+default_outcome = "summarize_discord_channel_update_general"+```++## How to run++This example requires a custom Python runner to load Discord channel data from JSON:++```bash+cd examples/wip/discord_newsletter+python run_discord_newsletter.py+```++## Related Documentation++- [PipeCondition Controller](../building-methods/pipes/pipe-controllers/PipeCondition.md) - Conditional pipe routing+- [PipeCompose Operator](../building-methods/pipes/pipe-operators/PipeCompose.md) - Template-based data composition+- [PipeSequence Controller](../building-methods/pipes/pipe-controllers/PipeSequence.md) - Chain pipes into sequential workflowsdiff --git a/docs/cookbook/extract-dpe.md b/docs/cookbook/extract-dpe.mdindex 5f96ef099..32b2d9b6a 100644--- a/docs/cookbook/extract-dpe.md+++ b/docs/cookbook/extract-dpe.md@@ -1,93 +1,71 @@----description: "Extract structured data from French energy performance diagnostics (DPE) using Pipelex declarative AI workflows and typed schemas."+title: "DPE Extraction Example"+description: "Extract structured data from French energy performance diagnostics (DPE) using vision-based Pipelex pipelines and typed schemas."---# Example: DPE Extraction-This example demonstrates how to extract information from a French "Diagnostic de Performance Énergétique" (DPE) document. This is a specialized document, and the pipeline is tailored to its specific structure.+This example extracts information from French "Diagnostic de Performance Energetique" (DPE) documents. It uses a three-step pipeline: extract pages, convert each to markdown using vision, then conclude the DPE details from the combined markdown.## Get the code-[**➡️ View on GitHub: examples/b_basics/document_extract/extract_dpe/extract_dpe.py**](https://github.com/Pipelex/pipelex-cookbook/blob/examples/b_basics/document_extract/extract_dpe/extract_dpe.py)+[](https://github.com/Pipelex/pipelex-cookbook/blob/main/examples/b_basics/document_extract/extract_dpe/bundle.mthds)-## The Pipeline Explained+## What it demonstrates-The pipeline `power_extractor_dpe` is designed to recognize and extract the key information from a DPE document. The result is a structured `Dpe` object.+- Custom structured concept with constrained choices (energy efficiency classes A-G)+- Three-step extraction: pages, markdown per page, then conclude+- Vision-based extraction focused on specific document elements (energy classes, graphs, tables)+- Using shared method packages for page extraction-```python-async def extract_dpe(pdf_url: str) -> Dpe:- pipe_output = await execute_pipeline(- pipe_code="power_extractor_dpe",- inputs={- "document": DocumentContent(url=pdf_url),- },- )- working_memory = pipe_output.working_memory- dpe: Dpe = working_memory.get_list_stuff_first_item_as(name="dpe", item_type=Dpe)- return dpe-```--This example shows how Pipelex can be used for very specific document extraction tasks by creating custom pipelines and data models.--## The Data Structure: `Dpe` Model+## The Method: `bundle.mthds`-The pipeline extracts a `Dpe` object, which is structured to hold the specific information found in a French "Diagnostic de Performance Énergétique". It even uses a custom `IndexScale` enum for the energy efficiency classes.+### DPE concept-```python-class IndexScale(StrEnum):- A = "A"- B = "B"- C = "C"- D = "D"- E = "E"- F = "F"- G = "G"+```toml+[concept.Dpe]+description = "A diagnostic of the energy performance of a building"++[concept.Dpe.structure]+address = { type = "text", description = "The address of the building" }+date_of_issue = { type = "date", description = "The date the DPE was issued" }+date_of_expiration = { type = "date", description = "The expiration date of the DPE" }+energy_efficiency_class = { type = "text", description = "The energy efficiency class",+ choices = ["A", "B", "C", "D", "E", "F", "G"] }+per_year_per_m2_consumption = { type = "number", description = "Energy consumption per year per m2" }+co2_emission_class = { type = "text", description = "The CO2 emission class",+ choices = ["A", "B", "C", "D", "E", "F", "G"] }+per_year_per_m2_co2_emissions = { type = "number", description = "CO2 emissions per year per m2" }+yearly_energy_costs = { type = "number", description = "Yearly energy costs" }+```+### Pipeline-class Dpe(StructuredContent):- address: Optional[str] = None- date_of_issue: Optional[datetime] = None- date_of_expiration: Optional[datetime] = None- energy_efficiency_class: Optional[IndexScale] = None- per_year_per_m2_consumption: Optional[float] = None- co2_emission_class: Optional[IndexScale] = None- per_year_per_m2_co2_emissions: Optional[float] = None- yearly_energy_costs: Optional[float] = None+```toml+[pipe.power_extractor_dpe]+type = "PipeSequence"+inputs = { document = "Document" }+output = "Dpe"+steps = [+ { pipe = "github.com/Pipelex/methods/documents->documents.extract_page_contents_and_views",+ result = "page_contents" },+ { pipe = "write_markdown_from_page_content_dpe",+ batch_over = "page_contents", batch_as = "page_content",+ result = "dpe_pages" },+ { pipe = "conclude_dpe", result = "dpe" },+]```-## The Pipeline Definition: `extract_dpe.mthds`+The final `conclude_dpe` step takes all the markdown pages and produces a single structured `Dpe` object.-The pipeline uses a `PipeLLM` with a very specific prompt to extract the information from the document. The combination of the image and the OCR text allows the LLM to accurately capture all the details.+## How to run-```toml-[pipe.write_markdown_from_page_content_dpe]-type = "PipeLLM"-description = "Write markdown from page content of a 'Diagnostic de Performance Energetique'"-inputs = { "page_content.page_view" = "Image", page_content = "Page" }-output = "Dpe"-model = "$vision"-structuring_method = "preliminary_text"-system_prompt = """You are a multimodal LLM, expert at converting images into perfect markdown."""-prompt = """-You are given an image of a French 'Diagnostic de Performance Energetique': $page_content.page_view-Your role is to convert the image into perfect markdown.--To help you do so, you are given the text extracted from the page by an OCR model.-@page_content.text_and_images.text.text--- It is very important that you collect every element, especially if they are related to the energy performance of the building.-- Pay attention to all the pieces of information that may be included in images, graphs, charts, or tables.-- We value letters like "A, B, C, D, E, F, G" as they are energy performance classes.-- Pay attention to the text alignment, it might have been misaligned by the OCR.-- The OCR extraction may be highly incomplete. It is your job to complete the text and add the missing information using the image.-- Output only the markdown, nothing else. No need for "```markdown" or "```".-- You can use HTML if it helps you.-- You can use tables if it is relevant.-"""+```bash+pipelex run bundle examples/b_basics/document_extract/extract_dpe/bundle.mthds \+ -i examples/b_basics/document_extract/extract_dpe/inputs.json```-This is a great example of how to create a highly specialized extraction pipeline by combining a custom data model with a detailed, guiding prompt.## Related Documentation- [PipeLLM Operator](../building-methods/pipes/pipe-operators/PipeLLM.md) - The core operator for LLM interactions-- [Document Extraction](../features/document-extraction.md) - Overview of document extraction capabilities\ No newline at end of file+- [Document Extraction](../features/document-extraction.md) - Overview of document extraction capabilitiesdiff --git a/docs/cookbook/extract-gantt.md b/docs/cookbook/extract-gantt.mdindex dccb5905f..8195bbd34 100644--- a/docs/cookbook/extract-gantt.md+++ b/docs/cookbook/extract-gantt.md@@ -1,62 +1,27 @@----description: "Extract tasks, dates, and dependencies from Gantt chart images using executable AI methods — a step-by-step Pipelex cookbook example."+title: "Gantt Chart Extraction Example"+description: "Extract tasks, dates, and dependencies from Gantt chart images using a step-by-step divide-and-conquer Pipelex pipeline."---# Example: Gantt Chart Extraction-This example showcases the ability of Pipelex to extract structured information from images. In this case, it processes an image of a Gantt chart and extracts the tasks, dates, and dependencies.+This example extracts structured information from Gantt chart images: timescale, task names, task details (dates, dependencies), and milestones. It uses a "divide and conquer" approach where each aspect is extracted separately.## Get the code-[**➡️ View on GitHub: examples/b_basics/document_extract/extract_gantt/extract_gantt.py**](https://github.com/Pipelex/pipelex-cookbook/blob/main/examples/b_basics/document_extract/extract_gantt/extract_gantt.py)+[](https://github.com/Pipelex/pipelex-cookbook/blob/main/examples/b_basics/document_extract/extract_gantt/bundle.mthds)-## The Pipeline Explained+## What it demonstrates-The pipeline takes an image as input, creates a working memory, and then executes the `extract_gantt_by_steps` pipeline to produce a structured `GanttChart` object.+- Divide-and-conquer extraction: timescale, task names, task details, then assemble+- Batching over task names to extract details for each independently+- Vision-based extraction using `$vision-diagram` model+- Rich structured output (`GanttChart` with `GanttTaskDetails` and `Milestone` lists)+- Two alternative approaches: step-by-step vs. direct one-shot extraction-```python-async def extract_gantt(image_url: str) -> GanttChart:- # Run the pipe- pipe_output = await execute_pipeline(- pipe_code="extract_gantt_by_steps",- inputs={- "gantt_chart_image": {- "concept": "gantt.GanttChartImage",- "content": ImageContent(url=image_url),- }- },- )- # Output the result- return pipe_output.main_stuff_as(content_type=GanttChart)-```--This is a powerful demonstration of multi-modal capabilities, combining vision and language understanding.--## The Data Structure: `GanttChart` Model--The final output is a `GanttChart` object, which contains lists of tasks and milestones. These are themselves structured objects, ensuring the data is clean and easy to work with.--```python-class GanttTaskDetails(StructuredContent):- """Do not include timezone in the dates."""- name: str- start_date: Optional[datetime] = None- end_date: Optional[datetime] = None- # ...--class Milestone(StructuredContent):- name: str- date: Optional[datetime]- # ...--class GanttChart(StructuredContent):- tasks: Optional[List[GanttTaskDetails]]- milestones: Optional[List[Milestone]]-```+## The Method: `bundle.mthds`-## The Pipeline Definition: `gantt.mthds`--The `extract_gantt_by_steps` pipeline is a sequence of smaller, focused pipes. This is a great example of building a complex method from simple, reusable components.+### Pipeline```toml[pipe.extract_gantt_by_steps]@@ -65,156 +30,26 @@ description = "Extract all details from a gantt chart"inputs = { gantt_chart_image = "GanttChartImage" }output = "GanttChart"steps = [- # First, figure out the timescale of the chart{ pipe = "extract_gantt_timescale", result = "gantt_timescale" },- # Then, get the names of all the tasks{ pipe = "extract_gantt_task_names", result = "gantt_task_names" },- # Then, for each task, extract the details- { pipe = "extract_details_of_task", batch_as = "gantt_task_name", result = "details_of_all_tasks" },- # Finally, assemble everything into a single GanttChart object+ { pipe = "extract_details_of_task", batch_as = "gantt_task_name",+ result = "details_of_all_tasks" },{ pipe = "gather_in_a_gantt_chart", result = "gantt_chart" },]--[pipe.extract_details_of_task]-type = "PipeLLM"-description = "Extract the precise dates of the task, start_date and end_date"-inputs = { gantt_chart_image = "GanttChartImage", gantt_timescale = "GanttTimescaleDescription", gantt_task_name = "GanttTaskName" }-output = "GanttTaskDetails"-structuring_method = "preliminary_text"-model = "$vision-diagram"-prompt = """-I am sharing an image of a Gantt chart: $gantt_chart_image.-Please analyse the image and for a given task name (and only this task), extract the information of the task, if relevant.--Be careful, the time unit is this:-@gantt_timescale--If the task is a milestone, then only output the start_date.--Here is the name of the task you have to extract the dates for:-@gantt_task_name-"""```-This demonstrates the "divide and conquer" approach that Pipelex encourages. By breaking down a complex problem into smaller steps, each step can be handled by a specialized pipe, making the overall method more robust and easier to debug.--## Flowchart-```mermaid-----config:- layout: dagre- theme: base-----flowchart LR- subgraph "extract_gantt_by_steps"- direction LR- ZJNLe["gantt_chart_image:<br>**Gantt image**"]- Bh9Ab["gantt_timescale:<br>**Gantt timescale description**"]- R2oLH["gantt_task_names:<br>**List of [Gantt task name]**"]- end- subgraph "extract_details_of_task"- direction LR- R2oLH-branch-0["**Gantt task name** #1"]- QFEdmVvYVHdL6DsCRtwqHq-branch-0["**Gantt task details** #1"]- R2oLH-branch-1["**Gantt task name** #2"]- QFEdmVvYVHdL6DsCRtwqHq-branch-1["**Gantt task details** #2"]- R2oLH-branch-2["**Gantt task name** #3"]- QFEdmVvYVHdL6DsCRtwqHq-branch-2["**Gantt task details** #3"]- R2oLH-branch-3["**Gantt task name** #4"]- QFEdmVvYVHdL6DsCRtwqHq-branch-3["**Gantt task details** #4"]- R2oLH-branch-4["**Gantt task name** #5"]- QFEdmVvYVHdL6DsCRtwqHq-branch-4["**Gantt task details** #5"]- R2oLH-branch-5["**Gantt task name** #6"]- QFEdmVvYVHdL6DsCRtwqHq-branch-5["**Gantt task details** #6"]- R2oLH-branch-6["**Gantt task name** #7"]- QFEdmVvYVHdL6DsCRtwqHq-branch-6["**Gantt task details** #7"]- R2oLH-branch-7["**Gantt task name** #8"]- QFEdmVvYVHdL6DsCRtwqHq-branch-7["**Gantt task details** #8"]- R2oLH-branch-8["**Gantt task name** #9"]- QFEdmVvYVHdL6DsCRtwqHq-branch-8["**Gantt task details** #9"]- R2oLH-branch-9["**Gantt task name** #10"]- QFEdmVvYVHdL6DsCRtwqHq-branch-9["**Gantt task details** #10"]- R2oLH-branch-10["**Gantt task name** #11"]- QFEdmVvYVHdL6DsCRtwqHq-branch-10["**Gantt task details** #11"]- R2oLH-branch-11["**Gantt task name** #12"]- QFEdmVvYVHdL6DsCRtwqHq-branch-11["**Gantt task details** #12"]- nCmpx["details_of_all_tasks:<br>**List of [Gantt task details]**"]- NuMVc["gantt_chart:<br>**Gantt chart**"]- end-class extract_gantt_by_steps sub_a;-class extract_details_of_task sub_b;+Each task's details are extracted individually using the chart image, the timescale context, and the specific task name — making each extraction focused and accurate.- classDef sub_a fill:#e6f5ff,color:#333,stroke:#333;+The bundle also includes a `transcript_gantt_direct` pipe for one-shot extraction to markdown, useful for simpler charts.- classDef sub_b fill:#fff5f7,color:#333,stroke:#333;+## How to run- classDef sub_c fill:#f0fff0,color:#333,stroke:#333;- ZJNLe -- "Extract gantt timescale" ----> Bh9Ab- ZJNLe -- "Extract gantt task names" ----> R2oLH- ZJNLe -- "Extract details of task" ----> QFEdmVvYVHdL6DsCRtwqHq-branch-0- ZJNLe -- "Extract details of task" ----> QFEdmVvYVHdL6DsCRtwqHq-branch-1- ZJNLe -- "Extract details of task" ----> QFEdmVvYVHdL6DsCRtwqHq-branch-2- ZJNLe -- "Extract details of task" ----> QFEdmVvYVHdL6DsCRtwqHq-branch-3- ZJNLe -- "Extract details of task" ----> QFEdmVvYVHdL6DsCRtwqHq-branch-4- ZJNLe -- "Extract details of task" ----> QFEdmVvYVHdL6DsCRtwqHq-branch-5- ZJNLe -- "Extract details of task" ----> QFEdmVvYVHdL6DsCRtwqHq-branch-6- ZJNLe -- "Extract details of task" ----> QFEdmVvYVHdL6DsCRtwqHq-branch-7- ZJNLe -- "Extract details of task" ----> QFEdmVvYVHdL6DsCRtwqHq-branch-8- ZJNLe -- "Extract details of task" ----> QFEdmVvYVHdL6DsCRtwqHq-branch-9- ZJNLe -- "Extract details of task" ----> QFEdmVvYVHdL6DsCRtwqHq-branch-10- ZJNLe -- "Extract details of task" ----> QFEdmVvYVHdL6DsCRtwqHq-branch-11- Bh9Ab -- "Extract details of task" ----> QFEdmVvYVHdL6DsCRtwqHq-branch-0- Bh9Ab -- "Extract details of task" ----> QFEdmVvYVHdL6DsCRtwqHq-branch-1- Bh9Ab -- "Extract details of task" ----> QFEdmVvYVHdL6DsCRtwqHq-branch-2- Bh9Ab -- "Extract details of task" ----> QFEdmVvYVHdL6DsCRtwqHq-branch-3- Bh9Ab -- "Extract details of task" ----> QFEdmVvYVHdL6DsCRtwqHq-branch-4- Bh9Ab -- "Extract details of task" ----> QFEdmVvYVHdL6DsCRtwqHq-branch-5- Bh9Ab -- "Extract details of task" ----> QFEdmVvYVHdL6DsCRtwqHq-branch-6- Bh9Ab -- "Extract details of task" ----> QFEdmVvYVHdL6DsCRtwqHq-branch-7- Bh9Ab -- "Extract details of task" ----> QFEdmVvYVHdL6DsCRtwqHq-branch-8- Bh9Ab -- "Extract details of task" ----> QFEdmVvYVHdL6DsCRtwqHq-branch-9- Bh9Ab -- "Extract details of task" ----> QFEdmVvYVHdL6DsCRtwqHq-branch-10- Bh9Ab -- "Extract details of task" ----> QFEdmVvYVHdL6DsCRtwqHq-branch-11- R2oLH -...- R2oLH-branch-0- R2oLH -...- R2oLH-branch-1- R2oLH -...- R2oLH-branch-2- R2oLH -...- R2oLH-branch-3- R2oLH -...- R2oLH-branch-4- R2oLH -...- R2oLH-branch-5- R2oLH -...- R2oLH-branch-6- R2oLH -...- R2oLH-branch-7- R2oLH -...- R2oLH-branch-8- R2oLH -...- R2oLH-branch-9- R2oLH -...- R2oLH-branch-10- R2oLH -...- R2oLH-branch-11- R2oLH-branch-0 -- "Extract details of task" ----> QFEdmVvYVHdL6DsCRtwqHq-branch-0- QFEdmVvYVHdL6DsCRtwqHq-branch-0 -...- nCmpx- R2oLH-branch-1 -- "Extract details of task" ----> QFEdmVvYVHdL6DsCRtwqHq-branch-1- QFEdmVvYVHdL6DsCRtwqHq-branch-1 -...- nCmpx- R2oLH-branch-2 -- "Extract details of task" ----> QFEdmVvYVHdL6DsCRtwqHq-branch-2- QFEdmVvYVHdL6DsCRtwqHq-branch-2 -...- nCmpx- R2oLH-branch-3 -- "Extract details of task" ----> QFEdmVvYVHdL6DsCRtwqHq-branch-3- QFEdmVvYVHdL6DsCRtwqHq-branch-3 -...- nCmpx- R2oLH-branch-4 -- "Extract details of task" ----> QFEdmVvYVHdL6DsCRtwqHq-branch-4- QFEdmVvYVHdL6DsCRtwqHq-branch-4 -...- nCmpx- R2oLH-branch-5 -- "Extract details of task" ----> QFEdmVvYVHdL6DsCRtwqHq-branch-5- QFEdmVvYVHdL6DsCRtwqHq-branch-5 -...- nCmpx- R2oLH-branch-6 -- "Extract details of task" ----> QFEdmVvYVHdL6DsCRtwqHq-branch-6- QFEdmVvYVHdL6DsCRtwqHq-branch-6 -...- nCmpx- R2oLH-branch-7 -- "Extract details of task" ----> QFEdmVvYVHdL6DsCRtwqHq-branch-7- QFEdmVvYVHdL6DsCRtwqHq-branch-7 -...- nCmpx- R2oLH-branch-8 -- "Extract details of task" ----> QFEdmVvYVHdL6DsCRtwqHq-branch-8- QFEdmVvYVHdL6DsCRtwqHq-branch-8 -...- nCmpx- R2oLH-branch-9 -- "Extract details of task" ----> QFEdmVvYVHdL6DsCRtwqHq-branch-9- QFEdmVvYVHdL6DsCRtwqHq-branch-9 -...- nCmpx- R2oLH-branch-10 -- "Extract details of task" ----> QFEdmVvYVHdL6DsCRtwqHq-branch-10- QFEdmVvYVHdL6DsCRtwqHq-branch-10 -...- nCmpx- R2oLH-branch-11 -- "Extract details of task" ----> QFEdmVvYVHdL6DsCRtwqHq-branch-11- QFEdmVvYVHdL6DsCRtwqHq-branch-11 -...- nCmpx- nCmpx -- "Gather in a gantt chart" ----> NuMVc+```bash+pipelex run bundle examples/b_basics/document_extract/extract_gantt/bundle.mthds \+ -i examples/b_basics/document_extract/extract_gantt/inputs.json```## Related Documentation- [PipeLLM Operator](../building-methods/pipes/pipe-operators/PipeLLM.md) - The core operator for LLM interactions-- [PipeSequence Controller](../building-methods/pipes/pipe-controllers/PipeSequence.md) - Chain pipes into sequential workflows\ No newline at end of file+- [PipeSequence Controller](../building-methods/pipes/pipe-controllers/PipeSequence.md) - Chain pipes into sequential workflowsdiff --git a/docs/cookbook/extract-generic.md b/docs/cookbook/extract-generic.mdindex 260e4de1d..7408b0a50 100644--- a/docs/cookbook/extract-generic.md+++ b/docs/cookbook/extract-generic.md@@ -1,63 +1,71 @@---title: "Generic Document Extraction Example"-description: "Extract content from complex PDF documents containing text and images. This Pipelex pipeline merges extracted content into a single coherent output."+description: "Extract content from complex PDF documents containing text and images. This Pipelex pipeline converts each page to markdown using vision."---# Example: Generic Document Extraction-This example demonstrates a powerful and generic pipeline for extracting content from complex PDF documents. It can handle documents that contain both text and images, and it merges the extracted content into a single, coherent output.+This example demonstrates a generic pipeline for extracting content from complex PDF documents. It extracts pages with views, then converts each page to markdown using a vision-capable LLM that combines OCR text with the page image.## Get the code-[**➡️ View on GitHub: examples/b_basics/document_extract/extract_generic/extract_generic.py**](https://github.com/Pipelex/pipelex-cookbook/blob/main/examples/b_basics/document_extract/extract_generic/extract_generic.py)--## The Pipeline Explained--The `power_extractor` pipeline is at the heart of this example. After its execution, a custom function `merge_markdown_and_images` is used to combine the text (converted to Markdown) and the images from all pages.--```python-async def extract_generic(pdf_url: str) -> TextAndImagesContent:- pipe_output = await execute_pipeline(- pipe_code="power_extractor",- inputs={- "document": DocumentContent(url=pdf_url),- },- )- working_memory = pipe_output.working_memory- markdown_and_images: TextAndImagesContent = merge_markdown_and_images(working_memory)- return markdown_and_images+[](https://github.com/Pipelex/pipelex-cookbook/blob/main/examples/b_basics/document_extract/extract_generic/bundle.mthds)++## What it demonstrates++- Vision-based page-to-markdown conversion using `PipeLLM` with `$vision` model+- Using shared method packages for page extraction+- Batching over pages to process each one independently+- Combining OCR text with page images for accurate extraction++## The Method: `bundle.mthds`++```toml+domain = "extract_generic"+main_pipe = "power_extractor"++[pipe.power_extractor]+type = "PipeSequence"+description = "Update page content with markdown"+inputs = { document = "Document" }+output = "Text[]"+steps = [+ { pipe = "github.com/Pipelex/methods/documents->documents.extract_page_contents_and_views",+ result = "page_contents" },+ { pipe = "write_markdown_from_page_content",+ batch_over = "page_contents", batch_as = "page_content",+ result = "markdowns" },+]++[pipe.write_markdown_from_page_content]+type = "PipeLLM"+description = "Write markdown from page content"+inputs = { "page_content.page_view" = "Image", page_content = "Page" }+output = "Text"+model = "$vision"+system_prompt = "You are a multimodal LLM, expert at converting images into perfect markdown."+prompt = """+You are given an image which is a view of a document page: $page_content.page_view+You are also given the text extracted from the page by an OCR model.+Your task is to output the perfect markdown of the page.++Here is the text extracted from the page:+{{ page_content.text_and_images.text.text|tag("ocr_text") }}++- Ensure you do not miss any information from the page.+- Output only the markdown, nothing else.+"""```-The `merge_markdown_and_images` function is a great example of how you can add your own Python code to a Pipelex method to perform custom processing.--```python-def merge_markdown_and_images(working_memory: WorkingMemory) -> TextAndImagesContent:- # Pages extracted from the PDF by PipeOCR- page_contents_list = working_memory.get_stuff_as_list(name="page_contents", item_type=PageContent)- # Markdown text extracted from the Pages by PipeLLM- page_markdown_list = working_memory.get_stuff_as_list(name="markdowns", item_type=TextContent)+## How to run- # ... (check for length equality)-- # Concatenate the markdown text- concatenated_markdown_text: str = "\n".join([page_markdown.text for page_markdown in page_markdown_list.items])-- # Aggregate the images from the page contents- image_contents: List[ImageContent] = []- for page_content in page_contents_list.items:- if page_content.text_and_images.images:- image_contents.extend(page_content.text_and_images.images)-- return TextAndImagesContent(- text=TextContent(text=concatenated_markdown_text),- images=image_contents,- )+```bash+pipelex run bundle examples/b_basics/document_extract/extract_generic/bundle.mthds \+ -i examples/b_basics/document_extract/extract_generic/inputs.json```-This example shows the flexibility of Pipelex in handling complex, multi-modal documents and allowing for custom logic.-## Related Documentation- [PipeExtract Operator](../building-methods/pipes/pipe-operators/PipeExtract.md) - Extract text and images from documents- [PipeLLM Operator](../building-methods/pipes/pipe-operators/PipeLLM.md) - The core operator for LLM interactions-- [Document Extraction](../features/document-extraction.md) - Overview of document extraction capabilities\ No newline at end of file+- [Document Extraction](../features/document-extraction.md) - Overview of document extraction capabilitiesdiff --git a/docs/cookbook/extract-invoice.md b/docs/cookbook/extract-invoice.mdnew file mode 100644index 000000000..85a57e391--- /dev/null+++ b/docs/cookbook/extract-invoice.md@@ -0,0 +1,78 @@+---+title: "Invoice Extraction Example"+description: "Extract structured invoice data from PDF documents using a multi-step Pipelex pipeline with vision-based LLM analysis."+---++# Example: Invoice Extraction++This example processes PDF invoices through a multi-step pipeline: extract pages with views, classify the invoice type, then extract structured data using vision.++## Get the code++[](https://github.com/Pipelex/pipelex-cookbook/blob/main/examples/b_basics/document_extract/extract_invoice/bundle.mthds)++## What it demonstrates++- Rich structured concept (`Invoice` with 14+ fields including nested `InvoiceDetails`)+- Nested `PipeSequence` (main pipeline batches over pages, sub-pipeline does analyze then extract)+- Vision-based extraction using page views and OCR text+- Using shared method packages for page extraction++## The Method: `bundle.mthds`++### Invoice concept++```toml+[concept.Invoice]+description = "Invoice information extracted from text, supporting both formal bills and receipts"++[concept.Invoice.structure]+invoice_id = { type = "text", description = "Unique identifier for the invoice" }+invoice_number = { type = "text", description = "Invoice number as shown on the document" }+date = { type = "date", description = "Date when the invoice was issued" }+amount_incl_tax = { type = "number", description = "Total amount including taxes" }+amount_excl_tax = { type = "number", description = "Net amount excluding taxes" }+vendor = { type = "text", description = "Name of the vendor/seller" }+category = { type = "concept", concept_ref = "invoice_extraction.InvoiceDetails", description = "Category or type of expense" }+# ... and more fields+```++### Pipeline++```toml+[pipe.process_invoice]+type = "PipeSequence"+inputs = { document = "Document" }+output = "Invoice[]"+steps = [+ { pipe = "github.com/Pipelex/methods/documents->documents.extract_page_contents_and_views", result = "invoice_pages" },+ { pipe = "extract_invoice", batch_over = "invoice_pages", batch_as = "invoice_page", result = "invoice" },+]+```++Each page goes through a sub-pipeline that first classifies the invoice type (bill vs. receipt), then extracts the full structured data using both the page view and OCR text:++```toml+[pipe.extract_invoice]+type = "PipeSequence"+inputs = { invoice_page = "Page" }+output = "Invoice"+steps = [+ { pipe = "analyze_invoice", result = "invoice_details" },+ { pipe = "extract_invoice_data", result = "invoice" },+]+```++## How to run++```bash+pipelex run bundle examples/b_basics/document_extract/extract_invoice/bundle.mthds \+ -i examples/b_basics/document_extract/extract_invoice/inputs.json+```++## Related Documentation++- [PipeExtract Operator](../building-methods/pipes/pipe-operators/PipeExtract.md) - Extract text and images from documents+- [PipeLLM Operator](../building-methods/pipes/pipe-operators/PipeLLM.md) - The core operator for LLM interactions+- [PipeSequence Controller](../building-methods/pipes/pipe-controllers/PipeSequence.md) - Chain pipes into sequential workflows+- [Document Extraction](../features/document-extraction.md) - Overview of document extraction capabilitiesdiff --git a/docs/cookbook/extract-markdown.md b/docs/cookbook/extract-markdown.mdnew file mode 100644index 000000000..6b62f05e1--- /dev/null+++ b/docs/cookbook/extract-markdown.md@@ -0,0 +1,61 @@+---+title: "Extract Markdown from Document"+description: "Extract clean markdown text from any PDF document using Pipelex document extraction and page composition."+---++# Example: Extract Markdown from Document++This example extracts text from a PDF document and composes the pages into a single clean markdown output. It leverages the shared `documents` method package for page extraction.++## Get the code++[](https://github.com/Pipelex/pipelex-cookbook/blob/main/examples/b_basics/document_extract/extract_markdown/bundle.mthds)++## What it demonstrates++- Using shared method packages (`github.com/Pipelex/methods/documents`)+- `PipeCompose` with Jinja2 templates to concatenate page text+- Simple two-step document-to-markdown pipeline++## The Method: `bundle.mthds`++The pipeline uses a shared extraction pipe and then composes all pages into a single text:++```toml+domain = "extract_markdown"+main_pipe = "extract_markdown_from_document"++[pipe.extract_markdown_from_document]+type = "PipeSequence"+description = "Extract markdown from a document"+inputs = { document = "Document" }+output = "Text"+steps = [+ { pipe = "github.com/Pipelex/methods/documents->documents.extract_markdown_pages", result = "pages" },+ { pipe = "write_markdown_from_pages", result = "markdown" },+]++[pipe.write_markdown_from_pages]+type = "PipeCompose"+description = "Write markdown from pages"+inputs = { pages = "Page[]" }+output = "Text"+template = """+{% for page in pages %}+{{ page.text_and_images.text }}+{% endfor %}+"""+```++## How to run++```bash+pipelex run bundle examples/b_basics/document_extract/extract_markdown/bundle.mthds \+ -i examples/b_basics/document_extract/extract_markdown/inputs.json+```++## Related Documentation++- [PipeExtract Operator](../building-methods/pipes/pipe-operators/PipeExtract.md) - Extract text and images from documents+- [PipeCompose Operator](../building-methods/pipes/pipe-operators/PipeCompose.md) - Template-based data composition+- [Packages](../building-methods/packages.md) - Using shared method packagesdiff --git a/docs/cookbook/extract-proof-of-purchase.md b/docs/cookbook/extract-proof-of-purchase.mdindex b0690538f..69472aa68 100644--- a/docs/cookbook/extract-proof-of-purchase.md+++ b/docs/cookbook/extract-proof-of-purchase.md@@ -1,85 +1,71 @@----description: "Build a pipeline that extracts structured data from receipts and invoices using declarative AI workflows and .mthds files."+title: "Proof of Purchase Extraction"+description: "Extract structured data from receipts and invoices using vision-based AI — including products, amounts, and payment details."---# Example: Proof of Purchase Extraction-This example demonstrates a pipeline designed to extract structured data from a proof of purchase, such as a receipt or an invoice.+This example extracts structured data from receipts and invoices. It defines nested data concepts (`Product` inside `ProofOfPurchase`) and uses vision-based extraction to capture all details from the document.## Get the code-[**➡️ View on GitHub: examples/b_basics/document_extract/extract_proof_of_purchase/extract_proof_of_purchase.py**](https://github.com/Pipelex/pipelex-cookbook/blob/main/examples/b_basics/document_extract/extract_proof_of_purchase/extract_proof_of_purchase.py)+[](https://github.com/Pipelex/pipelex-cookbook/blob/main/examples/b_basics/document_extract/extract_proof_of_purchase/bundle.mthds)-## The Pipeline Explained+## What it demonstrates-The pipeline `power_extractor_proof_of_purchase` is specifically designed to handle receipts and invoices. It extracts key information and returns a structured `ProofOfPurchase` object.+- Nested structured concepts (`Product` referenced inside `ProofOfPurchase`)+- Vision-based extraction with `$vision` model and `structuring_method = "preliminary_text"`+- Using shared method packages for page extraction+- Batching over pages to process each independently-```python-async def extract_proof_of_purchase(pdf_url: str) -> ProofOfPurchase:- pipe_output = await execute_pipeline(- pipe_code="power_extractor_proof_of_purchase",- inputs={- "document": DocumentContent(url=pdf_url),- },- )- working_memory = pipe_output.working_memory- proof_of_purchase: ProofOfPurchase = working_memory.get_list_stuff_first_item_as(name="proof_of_purchase", item_type=ProofOfPurchase)- return proof_of_purchase-```--This is a great starting point for building more complex expense processing or accounting automation pipelines.+## The Method: `bundle.mthds`-## The Data Structure: `ProofOfPurchase` Model+### Concepts-The pipeline is designed to extract a `ProofOfPurchase` object, which is a structured model that includes a list of `Products`.--```python-class Products(StructuredContent):- name: Optional[str] = None- quantity: Optional[int] = None- unit_price: Optional[float] = None- total_price: Optional[float] = None+```toml+[concept.Product]+description = "A product in a proof of purchase"++[concept.Product.structure]+name = { type = "text", description = "Name of the product" }+quantity = { type = "integer", description = "Quantity purchased" }+unit_price = { type = "number", description = "Unit price of the product" }+total_price = { type = "number", description = "Total price for this product" }++[concept.ProofOfPurchase]+description = "Elements from a proof of purchase"++[concept.ProofOfPurchase.structure]+date_of_purchase = { type = "date", description = "Date of the purchase" }+amount_paid = { type = "number", description = "Total amount paid" }+currency = { type = "text", description = "Currency used for the purchase" }+payment_method = { type = "text", description = "Method of payment used" }+purchase_number = { type = "text", description = "Purchase or receipt number" }+products = { type = "list", item_type = "concept", item_concept_ref = "extract_proof_of_purchase.Product", description = "List of products purchased" }+```+### Pipeline-class ProofOfPurchase(StructuredContent):- date_of_purchase: Optional[datetime] = None- amount_paid: Optional[float] = None- currency: Optional[str] = None- payment_method: Optional[str] = None- purchase_number: Optional[str] = None- products: Optional[List[Products]] = None+```toml+[pipe.power_extractor_proof_of_purchase]+type = "PipeSequence"+inputs = { document = "Document" }+output = "ProofOfPurchase[]"+steps = [+ { pipe = "github.com/Pipelex/methods/documents->documents.extract_page_contents_and_views",+ result = "page_contents" },+ { pipe = "write_markdown_from_page_content_proof_of_purchase",+ batch_over = "page_contents", batch_as = "page_content",+ result = "proof_of_purchase" },+]```-This demonstrates how you can create nested data structures to accurately model your data.-## The Pipeline Definition: `extract_proof_of_purchase.mthds`+## How to run-The pipeline uses a powerful `PipeLLM` to extract the structured data from the document. The prompt is carefully engineered to guide the LLM.--```toml-[pipe.write_markdown_from_page_content_proof_of_purchase]-type = "PipeLLM"-description = "Write markdown from page content"-inputs = { "page_content.page_view" = "Image", page_content = "Page" }-output = "ProofOfPurchase"-model = "$vision"-structuring_method = "preliminary_text"-system_prompt = """You are a multimodal LLM, expert at converting images into perfect markdown."""-prompt = """-You are given an image of a proof of purchase: $page_content.page_view-Your role is to convert the image into perfect markdown.--To help you do so, you are given the text extracted from the page by an OCR model.-@page_content.text_and_images.text.text--- Ensure you collect every title, number, and currency from the proof of purchase.-- Pay attention to the text alignment, it might have been misaligned by the OCR.-- The OCR extraction may be highly incomplete. It is your job to complete the text and add the missing information using the image.-- Output only the markdown, nothing else. No need for "```markdown" or "```".-- You can use HTML if it helps you.-- You can use tables if it is relevant.-"""+```bash+pipelex run bundle examples/b_basics/document_extract/extract_proof_of_purchase/bundle.mthds \+ -i examples/b_basics/document_extract/extract_proof_of_purchase/inputs.json```-The combination of a detailed prompt, the OCR text, and the document image allows the LLM to accurately extract the required information and structure it as a `ProofOfPurchase` object.## Related Documentationdiff --git a/docs/cookbook/extract-slides.md b/docs/cookbook/extract-slides.mdnew file mode 100644index 000000000..05c23daa8--- /dev/null+++ b/docs/cookbook/extract-slides.md@@ -0,0 +1,63 @@+---+title: "Extract Slides from Presentation"+description: "Extract slide content and descriptions from presentation documents using vision-based LLM analysis with Pipelex."+---++# Example: Extract Slides from Presentation++This example extracts structured slide information from a presentation document — including titles, content as markdown, and visual descriptions of each slide layout.++## Get the code++[](https://github.com/Pipelex/pipelex-cookbook/blob/main/examples/b_basics/document_extract/extract_slides/bundle.mthds)++## What it demonstrates++- Custom `Slide` concept with inline structure (title, text, description)+- Vision-based slide analysis using `PipeLLM` with page views+- Batching over extracted pages to process each slide individually+- `PipeCompose` for assembling structured output into formatted text++## The Method: `bundle.mthds`++### Slide concept++```toml+[concept.Slide]+description = "A slide from a presentation"++[concept.Slide.structure]+title = { type = "text", description = "The title of the slide" }+text_markdown = { type = "text", description = "The content of the slide as markdown" }+description = { type = "text", description = "A description of the slide: layout of the text, description of the graphics" }+```++### Pipeline++The pipeline extracts pages with views, describes each slide using a vision model, then concatenates the descriptions:++```toml+[pipe.extract_slides]+type = "PipeSequence"+description = "Extract markdown from a document"+inputs = { document = "Document" }+output = "Text"+steps = [+ { pipe = "extract_markdown_and_views_from_document", result = "pages" },+ { pipe = "describe_slide", batch_over = "pages", batch_as = "page", result = "slides" },+ { pipe = "concatenate_slide_descriptions", result = "slides_description" },+]+```++## How to run++```bash+pipelex run bundle examples/b_basics/document_extract/extract_slides/bundle.mthds \+ -i examples/b_basics/document_extract/extract_slides/inputs.json+```++## Related Documentation++- [PipeLLM Operator](../building-methods/pipes/pipe-operators/PipeLLM.md) - The core operator for LLM interactions+- [PipeExtract Operator](../building-methods/pipes/pipe-operators/PipeExtract.md) - Extract text and images from documents+- [PipeCompose Operator](../building-methods/pipes/pipe-operators/PipeCompose.md) - Template-based data compositiondiff --git a/docs/cookbook/extract-table.md b/docs/cookbook/extract-table.mdindex 7eb8a0ddc..7015b76c1 100644--- a/docs/cookbook/extract-table.md+++ b/docs/cookbook/extract-table.md@@ -1,67 +1,26 @@----description: "Turn table images into structured HTML with Pipelex executable AI methods — ideal for processing scanned documents and reports."+title: "Table Extraction from Image"+description: "Turn table images into structured HTML with Pipelex — using an extract-and-review self-correction pattern."---# Example: Table Extraction from Image-This example shows how to extract a table from an image and convert it into a structured HTML format. This is a common requirement when dealing with scanned documents or reports where data is presented in tabular form.+This example extracts a table from an image and converts it into structured HTML. It uses a two-step "extract and review" pattern where the first pipe does the initial extraction and the second pipe reviews the result against the original image to correct errors.## Get the code-[**➡️ View on GitHub: examples/b_basics/document_extract/extract_table/extract_table.py**](https://github.com/Pipelex/pipelex-cookbook/blob/main/examples/b_basics/document_extract/extract_table/extract_table.py)--## The Pipeline Explained--The pipeline `extract_html_table_and_review` takes an image of a table, processes it, and returns an `HtmlTable` object.--```python-async def extract_table(table_screenshot: str) -> HtmlTable:- pipe_output = await execute_pipeline(- pipe_code="extract_html_table_and_review",- inputs={- "table_screenshot": {- "concept": "tables.TableScreenshot",- "content": ImageContent(url=table_screenshot),- }- },- )- html_table = pipe_output.main_stuff_as(content_type=HtmlTable)- return html_table-```+[](https://github.com/Pipelex/pipelex-cookbook/blob/main/examples/b_basics/document_extract/extract_table/bundle.mthds)-This is another example of Pipelex's multi-modal capabilities, turning visual information into structured data.--## The Data Structure: `HtmlTable` Model--The pipeline outputs an `HtmlTable` object. This is a great example of a "smart" data model. It uses a `pydantic.model_validator` to parse the generated HTML with BeautifulSoup and validate its structure, ensuring the LLM has produced valid and well-formed HTML.--```python-class HtmlTable(StructuredContent):- title: str- inner_html_table: str- allowed_tags: ClassVar[set[str]] = { "br", "table", "thead", "tbody", "tr", "th", "td" }-- @model_validator(mode="after")- def validate_html_table(self) -> Self:- soup = BeautifulSoup(self.inner_html_table, "html.parser")- # Check if there's exactly one table element- tables = soup.find_all("table")- if len(tables) != 1:- raise ValueError(f"HTML must contain exactly one table element...")-- # Validate that only allowed table-related tags are present- all_tags = {tag.name for tag in soup.find_all()}- invalid_tags = all_tags - self.allowed_tags- if invalid_tags:- raise ValueError(f"Invalid HTML tags found: {invalid_tags}")-- # ... more validation- return self-```+## What it demonstrates-## The Pipeline Definition: `table.mthds`+- Self-correction pattern: extract then review against the original image+- Custom structured concept (`HtmlTable` with title and HTML content)+- Vision-based extraction using `$vision-table` model+- Multi-modal inputs (image + structured data) in a single pipe-The pipeline uses a two-step "extract and review" pattern. The first pipe does the initial extraction, and the second pipe reviews the generated HTML against the original image to correct any errors. This is a powerful pattern for increasing the reliability of LLM outputs.+## The Method: `bundle.mthds`++### Pipeline```toml[pipe.extract_html_table_and_review]@@ -70,9 +29,7 @@ description = "Get an HTML table and review it"inputs = { table_screenshot = "TableScreenshot" }output = "HtmlTable"steps = [- # First, do an initial extraction of the table from the image{ pipe = "extract_html_table_from_image", result = "html_table" },- # Then, ask an LLM to review the extracted table against the image and correct it{ pipe = "review_html_table", result = "reviewed_html_table" },]@@ -91,9 +48,17 @@ Rewrite the entire html table with your potential corrections.Make sure you do not forget any text."""```-This self-correction pattern is a key technique for building robust and reliable AI methods with Pipelex.++This self-correction pattern is a key technique for building robust AI methods — the first step provides a draft, and the second step verifies and corrects it against the source.++## How to run++```bash+pipelex run bundle examples/b_basics/document_extract/extract_table/bundle.mthds \+ -i examples/b_basics/document_extract/extract_table/inputs.json+```## Related Documentation- [PipeLLM Operator](../building-methods/pipes/pipe-operators/PipeLLM.md) - The core operator for LLM interactions-- [PipeSequence Controller](../building-methods/pipes/pipe-controllers/PipeSequence.md) - Chain pipes into sequential workflows\ No newline at end of file+- [PipeSequence Controller](../building-methods/pipes/pipe-controllers/PipeSequence.md) - Chain pipes into sequential workflowsdiff --git a/docs/cookbook/gen-expense-data.md b/docs/cookbook/gen-expense-data.mdnew file mode 100644index 000000000..ae402bc4d--- /dev/null+++ b/docs/cookbook/gen-expense-data.md@@ -0,0 +1,79 @@+---+title: "Expense Data Generation Example"+description: "Generate realistic synthetic expense reports with receipts, including fraud scenarios, using a complex multi-level Pipelex pipeline."+---++# Example: Expense Data with Receipts++This advanced example generates complete synthetic expense datasets for multiple employees, including realistic receipt images and HTML reports. It features fraud scenario generation for testing expense validation systems.++## Get the code++[](https://github.com/Pipelex/pipelex-cookbook/blob/main/examples/c_advanced/gen_expense_data/bundle.mthds)++## What it demonstrates++- Deep concept hierarchy (Employee, ExpenseScenario, CompanyProfile, ReceiptContent, Expense, etc.)+- Nested `PipeSequence` pipelines (main pipeline batches over employees, sub-pipeline batches over categories)+- `PipeImgGen` for generating realistic receipt images+- `PipeCompose` with `construct` for assembling structured objects from parts+- `PipeCompose` with HTML templates for report rendering+- Fraud scenario modeling (weekend expenses, inflated amounts, receipt mismatches, vague purposes)+- Custom Python runner for post-processing (PDF generation, file export)++## The Method: `bundle.mthds`++### Concept hierarchy (simplified)++```+NbOfEmployees (input, refines Number)+ -> Employee[]+ -> CompanyCategory[] (with ExpenseScenario)+ -> CompanyProfile+ -> ReceiptContent (from ReceiptHeader + ReceiptItemsAndTotals + ExpenseMetadata)+ -> Receipt (image via PipeImgGen)+ -> Expense + Receipt = ExpenseWithReceipt+ -> EmployeeExpenseReport (employee + expenses + HTML report)+```++### Main pipeline++```toml+[pipe.generate_expense_dataset]+type = "PipeSequence"+inputs = { nb_employees = "NbOfEmployees" }+output = "EmployeeExpenseReport[]"+steps = [+ { pipe = "generate_employees", result = "employees" },+ { pipe = "generate_employee_report", batch_over = "employees", batch_as = "employee", result = "reports" },+]+```++For each employee, the `generate_employee_report` sub-pipeline assigns expense categories (with fraud scenarios), then for each category generates a company profile, receipt content, receipt image, and expense record.++### Receipt generation++Receipt content is built in multiple steps: header (transaction number, date), items and totals (from the company's product catalog), and business purpose metadata. These are composed into formatted thermal-paper-style text, then rendered as a photo using `PipeImgGen`.++## How to run++**Using the CLI:**++```bash+pipelex run bundle examples/c_advanced/gen_expense_data/bundle.mthds \+ -i examples/c_advanced/gen_expense_data/inputs.json+```++**Using the Python runner** (for PDF export and file organization):++```bash+cd examples/c_advanced/gen_expense_data+python run_generate_expense_dataset.py+```++## Related Documentation++- [PipeSequence Controller](../building-methods/pipes/pipe-controllers/PipeSequence.md) - Chain pipes into sequential workflows+- [PipeImgGen Operator](../building-methods/pipes/pipe-operators/PipeImgGen.md) - Generate images from prompts+- [PipeCompose Operator](../building-methods/pipes/pipe-operators/PipeCompose.md) - Template-based data composition+- [Understanding Multiplicity](../building-methods/pipes/understanding-multiplicity.md) - How batching worksdiff --git a/docs/cookbook/gen-synthetic-data.md b/docs/cookbook/gen-synthetic-data.mdnew file mode 100644index 000000000..de9caa52e--- /dev/null+++ b/docs/cookbook/gen-synthetic-data.md@@ -0,0 +1,70 @@+---+title: "Synthetic Data Generation Example"+description: "Generate diverse synthetic data samples from a description using a two-step pipeline that identifies cases then creates profiles for each."+---++# Example: Synthetic Data Generation++This example generates diverse synthetic data samples from a text description. It first identifies a comprehensive set of sample cases, then creates detailed profiles for each one.++## Get the code++[](https://github.com/Pipelex/pipelex-cookbook/blob/main/examples/c_advanced/gen_synthetic_data/bundle.mthds)++## What it demonstrates++- Concept refinement (`DataDescription` refines `Text`, `NbOfSamples` refines `Number`)+- Rich structured concept with constrained choices (`Sample` with `current_performance`, `learns_best_with`, etc.)+- Two-step generation: identify diverse cases, then create a profile for each+- Batching over identified cases to generate samples in parallel++## The Method: `bundle.mthds`++### Sample concept++The `Sample` concept represents a student profile with constrained fields:++```toml+[concept.Sample]+description = "A complete synthetic data record representing a student profile."++[concept.Sample.structure]+student_name = { type = "text", description = "The name of the student", required = true }+current_performance = { type = "text", description = "The student's current performance level", choices = [+ "Struggling", "Average", "Advanced",+], required = true }+learns_best_with = { type = "text", description = "The learning modality that works best", choices = [+ "Visual examples", "Step-by-step text", "Hands-on practice", "Videos",+], required = true }+# ... pace, complexity, strengths, needs_help_with, etc.+```++### Pipeline++```toml+[pipe.generate_synthetic_data_samples]+type = "PipeSequence"+inputs = { data_description = "DataDescription", nb_samples = "NbOfSamples" }+output = "Sample[]"+steps = [+ { pipe = "identify_sample_cases", result = "cases" },+ { pipe = "create_profile_for_case", result = "samples",+ batch_over = "cases", batch_as = "case_characterization" },+]+```++The first step identifies diverse real-world scenarios to ensure comprehensive coverage (edge cases, common scenarios, important variations). The second step creates a full profile for each case.++## How to run++```bash+pipelex run bundle examples/c_advanced/gen_synthetic_data/bundle.mthds \+ -i examples/c_advanced/gen_synthetic_data/inputs.json+```++## Related Documentation++- [PipeLLM Operator](../building-methods/pipes/pipe-operators/PipeLLM.md) - The core operator for LLM interactions+- [PipeSequence Controller](../building-methods/pipes/pipe-controllers/PipeSequence.md) - Chain pipes into sequential workflows+- [Understanding Multiplicity](../building-methods/pipes/understanding-multiplicity.md) - How batching works+- [Refining Concepts](../building-methods/concepts/refining-concepts.md) - How concept refinement worksdiff --git a/docs/cookbook/generate-image.md b/docs/cookbook/generate-image.mdnew file mode 100644index 000000000..8c4de0051--- /dev/null+++ b/docs/cookbook/generate-image.md@@ -0,0 +1,70 @@+---+title: "Generate Image Example"+description: "Generate creative, absurd images using a multi-step pipeline that imagines a scene, crafts a prompt, and renders the image."+---++# Example: Generate Image++This example generates creative, absurd images through a three-step pipeline: imagine a surreal scene concept, refine it into an optimized image prompt, then render the image.++## Get the code++[](https://github.com/Pipelex/pipelex-cookbook/blob/main/examples/b_basics/generate_visuals/gen_image/bundle.mthds)++## What it demonstrates++- Concept refinement (`SceneConcept` and `ImagePrompt` both refine `Text`)+- `PipeImgGen` for image generation+- Multi-step creative pipeline where each step builds on the previous one+- No external inputs required — the pipeline generates everything from scratch++## The Method: `bundle.mthds`++```toml+domain = "crazy_image_generation"+main_pipe = "generate_crazy_image"++[concept.SceneConcept]+description = "A creative, abstract description of an absurd and surreal scene."+refines = "Text"++[concept.ImagePrompt]+description = "A detailed textual description optimized for image generation models."+refines = "Text"++[pipe.generate_crazy_image]+type = "PipeSequence"+description = "Main pipeline that imagines a scene, refines it into a prompt, and renders the image"+output = "Image"+steps = [+ { pipe = "imagine_scene", result = "scene_concept" },+ { pipe = "generate_img_prompt", result = "image_prompt" },+ { pipe = "render_image", result = "crazy_image" },+]+```++The `render_image` pipe uses `PipeImgGen` to generate the final image:++```toml+[pipe.render_image]+type = "PipeImgGen"+description = "Generates the absurd image based on the creative scene description"+inputs = { image_prompt = "ImagePrompt" }+output = "Image"+prompt = "$image_prompt"+model = "@default-small"+```++## How to run++```bash+pipelex run bundle examples/b_basics/generate_visuals/gen_image/bundle.mthds+```++No inputs needed — the pipeline imagines everything from scratch.++## Related Documentation++- [PipeImgGen Operator](../building-methods/pipes/pipe-operators/PipeImgGen.md) - Generate images from prompts+- [PipeLLM Operator](../building-methods/pipes/pipe-operators/PipeLLM.md) - The core operator for LLM interactions+- [Refining Concepts](../building-methods/concepts/refining-concepts.md) - How concept refinement worksdiff --git a/docs/cookbook/hello-world.md b/docs/cookbook/hello-world.mdindex 8f8d98eeb..25d2d1023 100644--- a/docs/cookbook/hello-world.md+++ b/docs/cookbook/hello-world.md@@ -11,59 +11,27 @@ It's the perfect starting point to verify your installation and get a first tast## Get the code-You can find the complete code for this example in the Pipelex Cookbook repository.+[](https://github.com/Pipelex/pipelex-cookbook/blob/main/examples/a_quick_start/hello_world.mthds)-[**➡️ View on GitHub: examples/a_quick_start/hello_world.py**](https://github.com/Pipelex/pipelex-cookbook/blob/main/examples/a_quick_start/hello_world.py)+## What it demonstrates-## The Pipeline Explained+- Minimal Pipelex setup with a single `PipeLLM` pipe+- The `main_pipe` field to designate the entry point+- Running a method bundle from the CLI-The `hello_world` function demonstrates the simplest possible Pipelex pipeline. It runs a single pipe that generates a haiku about "Hello World".+## The Method: `hello_world.mthds`-```python-import asyncio--from pipelex import pretty_print-from pipelex.pipelex import Pipelex-from pipelex.pipeline.runner import PipelexRunner---async def hello_world():- """- This function demonstrates the use of a super simple Pipelex pipeline to generate text.- """- # Run the pipe- runner = PipelexRunner()- response = await runner.execute_pipeline(- pipe_code="hello_world",- )- pipe_output = response.pipe_output-- # Print the output- pretty_print(pipe_output, title="Your first Pipelex output")---# start Pipelex-Pipelex.make()-# run sample using asyncio-asyncio.run(hello_world())-```--This example shows the minimal setup needed to run a Pipelex pipeline: initialize Pipelex, execute a pipeline by its code name, and pretty-print the results.--## The Pipeline Definition: `hello_world.mthds`--The pipeline definition is extremely simple - it's a single LLM call that generates a haiku:+The method definition is extremely simple — a single LLM call that generates a haiku:```toml-domain = "quick_start"-description = "Discovering Pipelex"+domain = "quick_start"+main_pipe = "hello_world"[pipe][pipe.hello_world]type = "PipeLLM"description = "Write text about Hello World."output = "Text"-model = { model = "gpt-4o-mini", temperature = 0.9, max_tokens = "auto" }prompt = """Write a haiku about Hello World."""@@ -71,19 +39,20 @@ Write a haiku about Hello World.## How to run-1. Clone the cookbook repository:+1. Clone the cookbook repository and install dependencies:+```bashgit clone https://github.com/Pipelex/pipelex-cookbook.gitcd pipelex-cookbook- ```-2. Install dependencies:- ```bashpip install .```-3. Set up your environment variables by copying `.env.example` to `.env` and adding your API keys.-4. Run the example:++2. Set up your environment variables by copying `.env.example` to `.env` and adding your API keys.++3. Run the example:+```bash- python examples/a_quick_start/hello_world.py+ pipelex run bundle examples/a_quick_start/hello_world.mthds```Expected output: A haiku about "Hello World" displayed with pretty formatting.diff --git a/docs/cookbook/index.md b/docs/cookbook/index.mdindex 6ba1b5f26..4747c9dbb 100644--- a/docs/cookbook/index.md+++ b/docs/cookbook/index.md@@ -1,53 +1,55 @@---title: "Cookbook Examples"-description: "Practical Pipelex examples and ready-to-use recipes: Hello World, OCR, document extraction, invoice processing, image generation, and more."+description: "Practical Pipelex examples and ready-to-use recipes: Hello World, document extraction, visual generation, synthetic data, and more."---# Pipelex Cookbook ExamplesWelcome to the Pipelex Cookbook!-[](https://github.com/Pipelex/pipelex-cookbook/tree/main)+[](https://github.com/Pipelex/pipelex-cookbook/tree/main)This is your go-to resource for practical examples and ready-to-use recipes to build powerful and reliable AI methods with Pipelex. Whether you're a beginner looking to get started or an experienced user searching for advanced patterns, you'll find something useful here.-## Philosophy+We strongly encourage you to clone the [Pipelex Cookbook repository](https://github.com/Pipelex/pipelex-cookbook/tree/main), play with the examples, and tailor them to your specific needs.-Our examples are designed to be:+## Quick Start-- **Practical**: Solving real-world problems.-- **Readable**: Easy to understand and adapt.-- **A Starting Point**: A foundation for your own custom pipelines.+- [**Hello World**](./hello-world.md) — The simplest Pipelex pipeline: a single LLM call that generates a haiku.+- [**Summarize**](./summarize.md) — Multi-step text summarization with topic extraction and batching.-We strongly encourage you to clone our [Pipelex Cookbook repository](https://github.com/Pipelex/pipelex-cookbook/tree/main), play with the examples, and tailor them to your specific needs.+## Document Extraction-## Contribute to the Community!+- [**Generic Document**](./extract-generic.md) — Extract markdown from complex PDFs using vision.+- [**Invoice**](./extract-invoice.md) — Extract structured invoice data with classification and vision analysis.+- [**Proof of Purchase**](./extract-proof-of-purchase.md) — Extract receipt data including product lists.+- [**DPE (Energy Diagnostic)**](./extract-dpe.md) — Specialized extraction for French energy performance certificates.+- [**Table from Image**](./extract-table.md) — Convert table images to HTML with self-correction review.+- [**Gantt Chart**](./extract-gantt.md) — Extract tasks and dates from Gantt chart images using divide-and-conquer.+- [**Markdown from Document**](./extract-markdown.md) — Simple document-to-markdown using shared method packages.+- [**Slides from Presentation**](./extract-slides.md) — Extract slide content and descriptions with vision analysis.-Have you built a cool pipeline with Pipelex? Share it with the community! We welcome contributions. Check out our [contribution guidelines](../contributing.md) and help us grow this collection of examples.--## Available Examples--Here are some of the examples you can find in the cookbook, organized by category:+## Visual Generation-### Getting Started+- [**Design Slides**](./design-slides.md) — Generate themed slide design proposals with visual mockups.+- [**Generate Image**](./generate-image.md) — Creative image generation through a three-step pipeline.-* [**Hello World**](./hello-world.md): A simple start to your Pipelex journey.+## Advanced-### Document Processing+- [**Synthetic Data**](./gen-synthetic-data.md) — Generate diverse synthetic data samples from a description.+- [**Expense Data with Receipts**](./gen-expense-data.md) — Generate complete expense datasets with receipt images and fraud scenarios.+- [**Using Inference Plugins**](./using-inference-plugins.md) — Route model calls through custom provider configurations.-* [**Simple OCR**](./simple-ocr.md): A basic OCR pipeline to extract text from a PDF.-* [**Generic Document Extraction**](./extract-generic.md): A powerful pipeline to extract text and images from complex documents.-* [**Invoice Extractor**](./invoice-extractor.md): A complete method for processing invoices, including reporting.-* [**Proof of Purchase Extraction**](./extract-proof-of-purchase.md): A targeted pipeline for extracting data from receipts.+## Work in Progress-### Graphical Extraction+These examples are under active development and may change:-* [**Gantt Chart Extraction**](./extract-gantt.md): Extract tasks, dates, and dependencies from a Gantt chart image.-* [**Table Extraction from Image**](./extract-table.md): Convert a table from an image into structured HTML.-* [**DPE Extraction**](./extract-dpe.md): A specialized pipeline for extracting information from French energy performance certificates.+- [**Tweet Optimizer**](./write-tweet.md) — Analyze and optimize tech tweets with style transfer.+- [**Blog Article Generator**](./blog-article-generator.md) — Generate SEO-optimized articles from structured requests.+- [**Advisory Board**](./advisory-board.md) — Multi-board business consultation with consensus analysis.+- [**Discord Newsletter**](./discord-newsletter.md) — Generate HTML newsletters from Discord channel data.+- [**Expense Validation**](./validate-expense-data.md) — Validate expense reports against company policies.-### Text Generation+## Contribute-* [**Tweet Optimizer (wip)**](./write-tweet.md): A style-transfer pipeline that optimizes a draft tweet based on a given writing style.--Dive in and happy piping! 🚀+Have you built a cool pipeline with Pipelex? Share it with the community! We welcome contributions. Check out our [contribution guidelines](../contributing.md) and help us grow this collection of examples.diff --git a/docs/cookbook/invoice-extractor.md b/docs/cookbook/invoice-extractor.mddeleted file mode 100644index 104fe9380..000000000--- a/docs/cookbook/invoice-extractor.md+++ /dev/null@@ -1,134 +0,0 @@-----title: "Invoice Extractor Example"-description: "Process PDF invoices with Pipelex: extract key information into structured Invoice objects, generate reports, and track pipeline execution."------# Example: Invoice Extractor--This example provides a comprehensive pipeline for processing invoices. It takes a PDF invoice, extracts key information, and returns a structured `Invoice` object. It also demonstrates how to generate reports and track pipeline execution.--## Get the code--[**➡️ View on GitHub: examples/b_basics/document_extract/extract_invoice/extract_invoice.py**](https://github.com/Pipelex/pipelex-cookbook/blob/main/examples/b_basics/document_extract/extract_invoice/extract_invoice.py)--## The Pipeline Explained--The `process_invoice` pipeline is a complete method for invoice processing.--```python-async def process_invoice(pdf_url: str) -> ListContent[Invoice]:- pipe_output = await execute_pipeline(- pipe_code="process_invoice",- inputs={- "document": DocumentContent(url=pdf_url),- },- )-- return pipe_output.main_stuff_as_list(item_type=Invoice)-```--This example also showcases some of the powerful observer features of Pipelex. After the pipeline runs, it generates a cost report.--```python-# Print the cost reporting-get_report_delegate().generate_report()-```--This is invaluable for understanding the cost of your pipelines.--## The Data Structure: `Invoice` Model--The pipeline's output is a structured `Invoice` object. This is defined using Pydantic's `BaseModel`, which allows for clear, typed, and validated data.--```python-class Invoice(StructuredContent):- """Invoice information extracted from text, supporting both formal bills and receipts"""-- invoice_id: Optional[str] = Field(None, description="Unique identifier for the invoice")- invoice_number: Optional[str] = Field(None, description="Invoice number as shown on the document")- date: Optional[datetime] = Field(None, description="Date when the invoice was issued")-- amount_incl_tax: Optional[float] = Field(None, description="Total amount including taxes")-- vendor: Optional[str] = Field(None, description="Name of the vendor/seller")-- # ... other fields-```--## The Pipeline Definition: `invoice.mthds`--The entire method is defined in a MTHDS file. This declarative approach makes the pipeline easy to understand and modify. Here's a snippet from `invoice.mthds`:--```toml-[pipe.process_invoice]-type = "PipeSequence"-description = "Process relevant information from an invoice"-inputs = { document = "Document" }-output = "Invoice"-steps = [- { pipe = "extract_text_from_image", result = "invoice_pages" },- { pipe = "extract_invoice", batch_over = "invoice_pages", batch_as = "invoice_page", result = "invoice" },-]--[pipe.extract_text_from_image]-type = "PipeExtract"-description = "Extract page contents from an image"-inputs = { document = "Document" }-output = "Page"-page_views = true-model = "base_extract_mistral"--[pipe.extract_invoice_data]-type = "PipeLLM"-description = "Extract invoice information from an invoice text transcript"-inputs = { "invoice_page.page_view" = "Image", invoice_details = "InvoiceDetails", invoice_page = "Page" }-output = "Invoice"-model = "$engineering-structured"-prompt = """-Extract invoice information from this invoice: $invoice_page.page_view--The category of this invoice is: $invoice_details.category.--@invoice_page.text_and_images.text.text-"""-```--This shows how a complex method, including text extraction with `PipeExtract` and LLM calls, can be defined in a simple, readable format. The `model = "$engineering-structured"` line is particularly powerful, as it tells the LLM to structure its output according to the `Invoice` model.--## The Pipeline Flowchart--```mermaid-----config:- layout: dagre- theme: base-----flowchart LR- subgraph "extract_invoice"- direction LR- ZynbH-branch-0["invoice_page:<br>**Page**"]- RRYZF["invoice_details:<br>**Invoice details**"]- RzjEzwGpkk5dXnrK3HXQJx-branch-0["invoice:<br>**Invoice**"]- ZynbH["invoice_pages:<br>**List of [Page]**"]- 5SXqJ["invoice:<br>**List of [Invoice]**"]- end-class extract_invoice sub_a;-- classDef sub_a fill:#e6f5ff,color:#333,stroke:#333;-- classDef sub_b fill:#fff5f7,color:#333,stroke:#333;-- classDef sub_c fill:#f0fff0,color:#333,stroke:#333;- ZynbH-branch-0 -- "Analyze invoice" ----> RRYZF- ZynbH-branch-0 -- "Extract invoice data" ----> RzjEzwGpkk5dXnrK3HXQJx-branch-0- RRYZF -- "Extract invoice data" ----> RzjEzwGpkk5dXnrK3HXQJx-branch-0- RzjEzwGpkk5dXnrK3HXQJx-branch-0 -...- 5SXqJ- ZynbH -...- ZynbH-branch-0-```--## Related Documentation--- [PipeExtract Operator](../building-methods/pipes/pipe-operators/PipeExtract.md) - Extract text and images from documents-- [PipeLLM Operator](../building-methods/pipes/pipe-operators/PipeLLM.md) - The core operator for LLM interactions-- [PipeSequence Controller](../building-methods/pipes/pipe-controllers/PipeSequence.md) - Chain pipes into sequential workflows-- [Cost Tracking](../features/cost-tracking.md) - Track and monitor AI usage costs\ No newline at end of filediff --git a/docs/cookbook/simple-ocr.md b/docs/cookbook/simple-ocr.mddeleted file mode 100644index c8d6c35dd..000000000--- a/docs/cookbook/simple-ocr.md+++ /dev/null@@ -1,37 +0,0 @@-----title: "Simple OCR Example"-description: "Build a basic OCR pipeline with Pipelex. Extract text from PDF pages and save the content — a fundamental building block for document processing methods."------# Example: Simple OCR--This example demonstrates a basic OCR (Optical Character Recognition) pipeline. It takes a PDF file as input, extracts the text from each page, and saves the content.--This is a fundamental building block for many document processing methods.--## Get the code--[**➡️ View on GitHub: examples/a_quick_start/simple_ocr.py**](https://github.com/Pipelex/pipelex-cookbook/blob/main/examples/a_quick_start/simple_ocr.py)--## The Pipeline Explained--The core of this example is a simple function that executes a pre-defined pipeline called `extract_page_contents_from_pdf`.--```python-async def simple_ocr(pdf_url: str) -> ListContent[PageContent]:- pipe_output = await execute_pipeline(- pipe_code="extract_page_contents_from_pdf",- inputs={- "document": DocumentContent(url=pdf_url),- },- )- page_content_list: ListContent[PageContent] = pipe_output.main_stuff_as_list(item_type=PageContent)- return page_content_list-```--This showcases how easy it is to kick off a complex process with just a few lines of code. The `inputs` dictionary simply maps the input name to the PDF content, and the pipeline handles the rest.--## Related Documentation--- [PipeExtract Operator](../building-methods/pipes/pipe-operators/PipeExtract.md) - Extract text and images from documents-- [Document Extraction](../features/document-extraction.md) - Overview of document extraction capabilities\ No newline at end of filediff --git a/docs/cookbook/summarize.md b/docs/cookbook/summarize.mdnew file mode 100644index 000000000..b9853f6b0--- /dev/null+++ b/docs/cookbook/summarize.md@@ -0,0 +1,86 @@+---+title: "Summarize Example"+description: "Summarize text using a multi-step pipeline that extracts topics, summarizes each, and combines them into a final summary."+---++# Example: Summarize++This example demonstrates two approaches to summarizing text: a direct structured summary and a multi-step topic-based summarization pipeline.++## Get the code++[](https://github.com/Pipelex/pipelex-cookbook/blob/main/examples/a_quick_start/summarize.mthds)++## What it demonstrates++- Defining custom concepts with inline structures (`StructuredSummary`)+- Multi-step `PipeSequence` with intermediate results+- Batching over a list of topics (`batch_over` / `batch_as`)+- Two pipes producing different outputs from the same input++## The Method: `summarize.mthds`++### Concepts++The method defines a `StructuredSummary` concept with fields for the summary, an abstract, and a list of main concepts:++```toml+domain = "summarize"+description = "Example of summarizing text by topics."+system_prompt = "You are an expert at summarizing text."++[concept]+Topic = "A topic a text deals with."+Summary = "A concise rewriting of a dense text."++[concept.StructuredSummary]+description = "A summary with a structured output."++[concept.StructuredSummary.structure]+summary = { type = "text", description = "Summary of the text, super clear and factual", required = true }+abstract = { type = "text", description = "Abstract of the summary 1 short sentences", required = true }+main_concepts = { type = "list", item_type = "text", description = "Array of main concepts tackled in the text" }+```++### Multi-step pipeline++The `summarize_by_steps` pipeline breaks summarization into three stages: extract topics, summarize each topic individually (batched), then combine all summaries:++```toml+[pipe.summarize_by_steps]+type = "PipeSequence"+description = "Summarize text by steps: extract topics, summarize for each topic, summarize from summaries."+inputs = { text = "Text" }+output = "Summary"+steps = [+ { pipe = "extract_topics", result = "topics" },+ { pipe = "summarize_topic", batch_over = "topics", batch_as = "topic", result = "summarized_topics" },+ { pipe = "summarize_from_summaries", result = "summary" },+]+```++Each topic is summarized independently using `batch_over`, and the final step merges everything into a single cohesive summary.++## How to run++**Direct structured summary:**++```bash+pipelex run bundle examples/a_quick_start/summarize.mthds \+ --pipe summarize_with_structure \+ -i examples/a_quick_start/inputs.json+```++**Multi-step topic-based summary:**++```bash+pipelex run bundle examples/a_quick_start/summarize.mthds \+ --pipe summarize_by_steps \+ -i examples/a_quick_start/inputs.json+```++## Related Documentation++- [PipeSequence Controller](../building-methods/pipes/pipe-controllers/PipeSequence.md) - Chain pipes into sequential workflows+- [PipeLLM Operator](../building-methods/pipes/pipe-operators/PipeLLM.md) - The core operator for LLM interactions+- [Understanding Multiplicity](../building-methods/pipes/understanding-multiplicity.md) - How batching worksdiff --git a/docs/cookbook/using-inference-plugins.md b/docs/cookbook/using-inference-plugins.mdnew file mode 100644index 000000000..0f3093130--- /dev/null+++ b/docs/cookbook/using-inference-plugins.md@@ -0,0 +1,53 @@+---+title: "Using Inference Plugins Example"+description: "Use custom LLM inference plugins in Pipelex to route model calls through your own provider configuration."+---++# Example: Using Inference Plugins++This example shows how to use an LLM inference plugin to route model calls through a custom provider configuration instead of the default Pipelex gateway.++## Get the code++[](https://github.com/Pipelex/pipelex-cookbook/blob/main/examples/c_advanced/using_inference_plugins/hello_plugin.mthds)++## What it demonstrates++- Referencing an LLM plugin by name in the `model` field+- How plugins allow you to use your own API keys and provider configuration+- Minimal change from a standard `PipeLLM` pipe++## The Method: `hello_plugin.mthds`++```toml+domain = "hello_plugin"+main_pipe = "hello_plugin"++[pipe]+[pipe.hello_plugin]+type = "PipeLLM"+description = "Write text about Hello World."+output = "Text"+model = { model = "llm_plugin_example_using_openai", temperature = 0.5 }+prompt = """+Write a haiku about Hello World.+"""+```++The key difference from the standard [Hello World](./hello-world.md) example is the `model` field: instead of using a default gateway model, it references `llm_plugin_example_using_openai` — a plugin defined in your project's configuration.++## How to run++1. Configure the LLM plugin in your project's `.pipelex/pipelex.toml` (see the [Configuration](../features/configuration.md) docs for details).++2. Run the example:++ ```bash+ pipelex run bundle examples/c_advanced/using_inference_plugins/hello_plugin.mthds+ ```++## Related Documentation++- [LLM Integration](../features/llm-integration.md) - Overview of LLM integration and plugins+- [Configuration System](../features/configuration.md) - How to configure providers and plugins+- [Pipelex Gateway & Model Access](../features/gateway.md) - Default model access through the gatewaydiff --git a/docs/cookbook/validate-expense-data.md b/docs/cookbook/validate-expense-data.mdnew file mode 100644index 000000000..33f233626--- /dev/null+++ b/docs/cookbook/validate-expense-data.md@@ -0,0 +1,85 @@+---+title: "Expense Validation Example"+description: "Validate expense reports against company policies using a comprehensive Pipelex pipeline combining LLM checks, Python functions, and vision analysis."+---++# Example: Expense Validation++!!! warning "Work in Progress"+ This example is under active development and may change.++This example validates expense reports against company policies. It extracts data from PDF reports, then runs each expense through multiple validation checks — including receipt matching with vision, spending limits, weekend policy, purpose quality assessment, and amount reasonableness.++## Get the code++[](https://github.com/Pipelex/pipelex-cookbook/blob/main/examples/wip/validate_expense_data/validation.mthds)++## What it demonstrates++- `PipeFunc` for Python-based validation logic (spending limits, weekend checks, timeliness)+- `PipeLLM` with vision for receipt matching+- `PipeLLM` for subjective assessments (purpose quality, amount reasonableness)+- `PipeExtract` for PDF parsing+- Complex validation pipeline combining 6 different checks per expense+- Rich result concepts with detailed approval status and statistics++## The Method: `validation.mthds`++### Validation pipeline++```toml+[pipe.validate_expense_report]+type = "PipeSequence"+inputs = { expense_pdf = "ExpenseReportPDF", receipts = "ReceiptImage[]" }+output = "ValidationReport"+steps = [+ { pipe = "extract_pdf_content", result = "pages" },+ { pipe = "parse_expense_report", result = "report" },+ { pipe = "extract_expenses_list", result = "expenses" },+ { pipe = "validate_single_expense", batch_over = "expenses", batch_as = "expense",+ result = "expense_validations" },+ { pipe = "compose_validation_report", result = "validation_report" },+]+```++### Per-expense validation++Each expense goes through 6 checks, then results are composed:++```toml+[pipe.validate_single_expense]+type = "PipeSequence"+inputs = { report = "ExpenseReport", expense = "Expense", receipts = "ReceiptImage[]" }+output = "ExpenseValidationResult"+steps = [+ { pipe = "check_receipt_match", result = "receipt_check" },+ { pipe = "check_spending_limit", result = "limit_check" },+ { pipe = "check_weekend", result = "weekend_check" },+ { pipe = "check_timeliness", result = "timeliness_check" },+ { pipe = "check_purpose_quality", result = "purpose_check" },+ { pipe = "check_reasonable_amount", result = "reasonable_check" },+ { pipe = "compose_expense_result", result = "validation_result" },+]+```++The checks use a mix of:++- **`PipeFunc`**: Deterministic checks (spending limits, weekend detection, timeliness)+- **`PipeLLM`**: Subjective assessments (purpose quality, amount reasonableness)+- **`PipeLLM` with vision**: Receipt-to-expense matching++## How to run++This example requires a custom Python runner:++```bash+cd examples/wip/validate_expense_data+python run_validate_expenses.py+```++## Related Documentation++- [PipeFunc Operator](../building-methods/pipes/pipe-operators/PipeFunc.md) - Call Python functions from pipes+- [PipeLLM Operator](../building-methods/pipes/pipe-operators/PipeLLM.md) - The core operator for LLM interactions+- [PipeExtract Operator](../building-methods/pipes/pipe-operators/PipeExtract.md) - Extract text and images from documents+- [PipeSequence Controller](../building-methods/pipes/pipe-controllers/PipeSequence.md) - Chain pipes into sequential workflowsdiff --git a/docs/cookbook/write-tweet.md b/docs/cookbook/write-tweet.mdindex eb56ee71a..98d1638ac 100644--- a/docs/cookbook/write-tweet.md+++ b/docs/cookbook/write-tweet.md@@ -1,55 +1,42 @@----description: "Generate optimized tweets with style transfer using Pipelex — define your writing workflow once in .mthds files, then run it reliably."+title: "Tweet Optimizer Example"+description: "Optimize tech tweets with style transfer using Pipelex — analyze for pitfalls then rewrite based on a reference writing style."---# Example: Tweet Optimizer-This example demonstrates how to create a pipeline that takes a draft of a tweet and a desired writing style, and then generates an optimized tweet. This is a practical example of "style transfer" for text.+!!! warning "Work in Progress"+ This example is under active development and may change.++This example takes a draft tweet and a reference writing style, then optimizes the tweet through a two-step "analyze and optimize" pipeline. The analysis step checks for common pitfalls (fluffiness, cringiness, humblebragginess, vagueness), and the optimization step rewrites the tweet based on that analysis.## Get the code-[**➡️ View on GitHub: examples/wip/write_tweet/write_tweet.py**](https://github.com/Pipelex/pipelex-cookbook/blob/main/examples/wip/write_tweet/write_tweet.py)--## The Pipeline Explained--The `optimize_tweet` function is the core of this example. It takes two strings, `draft_tweet` and `writing_style`, and executes the `optimize_tweet_sequence` pipeline, passing both inputs through the `inputs` dictionary with their respective concept specifications.--```python-async def optimize_tweet(draft_tweet: str, writing_style: str) -> str:- pipe_output = await execute_pipeline(- pipe_code="optimize_tweet_sequence",- inputs={- "draft_tweet": {- "concept": "tech_tweet.DraftTweet",- "content": draft_tweet,- },- "writing_style": {- "concept": "tech_tweet.WritingStyle",- "content": writing_style,- },- },- )-- # Get the optimized tweet- optimized_tweet = pipe_output.main_stuff_as_str- return optimized_tweet-```+[](https://github.com/Pipelex/pipelex-cookbook/blob/main/examples/wip/write_tweet/tech_tweet.mthds)-This example shows how to use multiple inputs to guide the generation process and produce text that adheres to a specific style.+## What it demonstrates-## The Data Structure: `OptimizedTweet` Model+- Two-step "analyze then refine" pattern+- Multiple inputs (`DraftTweet`, `WritingStyle`) flowing into a `PipeSequence`+- Specialized model references (`$writing-factual`, `$writing-creative`)+- Simple concept definitions without structures (text-only concepts)-The data model for this pipeline is very simple, as the final output is just a piece of text. However, the pipeline uses several concepts internally to manage the workflow, such as `DraftTweet`, `TweetAnalysis`, and `WritingStyle`.+## The Method: `tech_tweet.mthds`-```python-class OptimizedTweet(TextContent):- """A tweet optimized for Twitter/X engagement following best practices."""- pass-```+### Concepts-## The Pipeline Definition: `tech_tweet.mthds`+```toml+domain = "tech_tweet"+main_pipe = "optimize_tweet_sequence"++[concept]+DraftTweet = "A draft version of a tech tweet that needs optimization"+OptimizedTweet = "A tweet optimized for Twitter/X engagement following best practices"+TweetAnalysis = "Analysis of the tweet's structure and potential improvements"+WritingStyle = "A style of writing"+```-This pipeline uses a two-step "analyze and optimize" sequence. The first pipe analyzes the draft tweet for common pitfalls, and the second pipe rewrites the tweet based on the analysis and a provided writing style. This is a powerful pattern for refining generated content.+### Pipeline```toml[pipe.optimize_tweet_sequence]@@ -58,62 +45,18 @@ description = "Analyze and optimize a tech tweet in sequence"inputs = { draft_tweet = "DraftTweet", writing_style = "WritingStyle" }output = "OptimizedTweet"steps = [- # First, analyze the draft tweet for issues like "fluffiness" and "vagueness".- { pipe = "analyze_tweet", result = "tweet_analysis" },- # Then, optimize the tweet based on the analysis and the desired writing style.- { pipe = "optimize_tweet", result = "optimized_tweet" },+ { pipe = "analyze_tweet", result = "tweet_analysis" },+ { pipe = "optimize_tweet", result = "optimized_tweet" },]--# This is the pipe that analyzes the draft tweet.-[pipe.analyze_tweet]-type = "PipeLLM"-description = "Analyze the draft tweet and identify areas for improvement"-inputs = { draft_tweet = "DraftTweet" }-output = "TweetAnalysis"-system_prompt = """-You are an expert in social media optimization, particularly for tech content on Twitter/X.-Your role is to analyze tech tweets and check if they display typical startup communication pitfalls.-"""-prompt = """-Evaluate the tweet for these key issues:--**Fluffiness** - Overuse of buzzwords without concrete meaning...-**Cringiness** - Content that induces secondhand embarrassment...-**Humblebragginess** - Disguising boasts as casual updates...-**Vagueness** - Failing to clearly communicate what the product/service actually does...--@draft_tweet-"""```-This "analyze and refine" pattern is a great way to build more reliable and sophisticated text generation workflows. The first step provides a structured critique, and the second step uses that critique to improve the final output.-Here is the flowchart generated during this run:+The analysis pipe evaluates the tweet for fluffiness, cringiness, humblebragginess, and vagueness — scoring each 1-5. The optimization pipe then rewrites based on this analysis and the reference writing style.-```mermaid-----config:- layout: dagre- theme: base-----flowchart LR- subgraph "optimize_tweet_sequence"- direction LR- FGunn["draft_tweet:<br>**Draft tweet**"]- EWhtJ["tweet_analysis:<br>**Tweet analysis**"]- 65Eb2["optimized_tweet:<br>**Optimized tweet**"]- i34D5["writing_style:<br>**Writing style**"]- end-class optimize_tweet_sequence sub_a;-- classDef sub_a fill:#e6f5ff,color:#333,stroke:#333;-- classDef sub_b fill:#fff5f7,color:#333,stroke:#333;-- classDef sub_c fill:#f0fff0,color:#333,stroke:#333;- FGunn -- "Analyze tweet" ----> EWhtJ- FGunn -- "Optimize tweet" ----> 65Eb2- EWhtJ -- "Optimize tweet" ----> 65Eb2- i34D5 -- "Optimize tweet" ----> 65Eb2+## How to run++```bash+pipelex run bundle examples/wip/write_tweet/tech_tweet.mthds \+ -i examples/wip/write_tweet/inputs.json```## Related Documentationdiff --git a/docs/features/claude-code-skills-plugin.md b/docs/features/claude-code-skills-plugin.mdindex 9292d1389..806b68523 100644--- a/docs/features/claude-code-skills-plugin.md+++ b/docs/features/claude-code-skills-plugin.md@@ -30,9 +30,13 @@ Install from [mthds-ai/skills](https://github.com/mthds-ai/skills).## Getting Started-```text-# Run these inside Claude Code:+```/plugin marketplace add mthds-ai/skills+```++then:++```/plugin install mthds@mthds-ai-skills```diff --git a/docs/features/document-extraction.md b/docs/features/document-extraction.mdindex eaca00546..dfc1d6285 100644--- a/docs/features/document-extraction.md+++ b/docs/features/document-extraction.md@@ -39,5 +39,4 @@ Include PDFs directly in your prompts using `@variable` syntax. PipeLLM automati## Related Documentation- [PipeExtract](../building-methods/pipes/pipe-operators/PipeExtract.md) - Operator reference and MTHDS fields-- [Simple OCR Example](../cookbook/simple-ocr.md) - Small end-to-end extraction example-- [Generic Document Extraction](../cookbook/extract-generic.md) - Multi-step document method example+- [Generic Document Extraction Example](../cookbook/extract-generic.md) - Extract markdown from complex PDFs using visiondiff --git a/docs/features/gateway.md b/docs/features/gateway.mdindex ce506f4b8..8cd65315a 100644--- a/docs/features/gateway.md+++ b/docs/features/gateway.md@@ -50,4 +50,4 @@ Run open-source models through dedicated providers:Routing profiles control which backend handles each model. Define pattern-based routes, defaults, and fallback orders in `routing_profiles.toml`. Switch a pipeline from one provider to another — or from Pipelex Gateway to your own keys — without changing the method definition.-See [Configure AI Providers](../setup/configure-ai-providers.md) for setup details.+See [Configure AI Providers](../get-started/configure-ai-providers.md) for setup details.diff --git a/docs/get-started/build-with-claude-code.md b/docs/get-started/build-with-claude-code.mdnew file mode 100644index 000000000..fc13c149c--- /dev/null+++ b/docs/get-started/build-with-claude-code.md@@ -0,0 +1,46 @@+---+title: "Build with Claude Code"+description: "Build and run Pipelex methods using Claude Code and the MTHDS skills plugin."+---++# Build with Claude Code++Install the `mthds` CLI:++```bash+npm install -g mthds+```++Launch Claude Code and tell it to install the MTHDS plugin:++```+/plugin marketplace add mthds-ai/skills+```++```+/plugin install mthds@mthds-ai-skills+```++then exit Claude Code and reopen it:++```+/exit+```++Reopen Claude Code, and build your first method:++```+/mthds-build A method to analyze a Job offer to build a scorecard, then batch process CVs to score them+```++Run it:++```+/mthds-run+```++That's it — Claude writes the `.mthds` file, creates inputs, and runs the method for you. See the [Claude Code Skills Plugin](../features/claude-code-skills-plugin.md) documentation for the full list of commands (`/mthds-edit`, `/mthds-check`, `/mthds-fix`, `/mthds-explain`, and more).++See [Configure AI Providers](./configure-ai-providers.md) for other options: bring your own keys, local AI, etc.++diff --git a/docs/setup/configure-ai-providers.md b/docs/get-started/configure-ai-providers.mdsimilarity index 90%rename from docs/setup/configure-ai-providers.mdrename to docs/get-started/configure-ai-providers.mdindex 8598db9d2..6a84b88fd 100644--- a/docs/setup/configure-ai-providers.md+++ b/docs/get-started/configure-ai-providers.md@@ -32,12 +32,12 @@ Get **free credits** for testing and development with a single API key for LLMs,3. Run `pipelex init` and accept the Gateway terms of service when prompted.-That's it! Your pipelines can now access any supported LLM. See [Gateway Available Models](./gateway-models.md) for the full list.+That's it! Your pipelines can now access any supported LLM. See [Gateway Available Models](../setup/gateway-models.md) for the full list.!!! info "Terms of Service & Telemetry"When using Pipelex Gateway, you'll be prompted to accept our terms of service. By using the Gateway, identified telemetry is automatically enabled (tied to your hashed API key) to help us monitor service quality and enforce fair usage.-- **We collect only technical data** (model names, token counts, latency, error rates). We do **NOT** collect your prompts, completions, or business data. See [Telemetry](./telemetry.md) for details and trade-offs, and our [Privacy Policy](https://go.pipelex.com/privacy-policy) for more.++ **We collect only technical data** (model names, token counts, latency, error rates). We do **NOT** collect your prompts, completions, or business data. See [Telemetry](../setup/telemetry.md) for details and trade-offs, and our [Privacy Policy](https://go.pipelex.com/privacy-policy) for more.### Option 2: Bring Your Own API Keys@@ -167,10 +167,9 @@ Learn more in our [Inference Backend Configuration](../configuration/config-techNow that you have your backend configured:-1. **Organize your project**: [Project Organization](./project-organization.md)-2. **Learn the concepts**: [Writing Methods Tutorial](../get-started/write-methods-manually.md)-3. **Explore examples**: [Cookbook Repository](https://github.com/Pipelex/pipelex-cookbook/tree/main)-4. **Deep dive**: [Build Reliable AI Methods](../building-methods/kick-off-a-methods-project.md)+1. **Learn the concepts**: [MTHDS Language Tutorial](./mthds-language-tutorial.md)+2. **Explore examples**: [Cookbook Repository](https://github.com/Pipelex/pipelex-cookbook/tree/main)+3. **Deep dive**: [Build Reliable AI Methods](../building-methods/kick-off-a-methods-project.md)!!! tip "Advanced Configuration"For detailed backend configuration options, see [Inference Backend Configuration](../configuration/config-technical/inference-backend-config.md).diff --git a/docs/get-started/images/character_sheet.png b/docs/get-started/images/character_sheet.pngdeleted file mode 100644index 359cd760b..000000000Binary files a/docs/get-started/images/character_sheet.png and /dev/null differdiff --git a/docs/get-started/images/extracted_character_metadata.png b/docs/get-started/images/extracted_character_metadata.pngdeleted file mode 100644index bd4c235a9..000000000Binary files a/docs/get-started/images/extracted_character_metadata.png and /dev/null differdiff --git a/docs/get-started/images/structured_character_sheet.png b/docs/get-started/images/structured_character_sheet.pngdeleted file mode 100644index 0b659c76d..000000000Binary files a/docs/get-started/images/structured_character_sheet.png and /dev/null differdiff --git a/docs/get-started/images/structured_character_sheet_json.png b/docs/get-started/images/structured_character_sheet_json.pngdeleted file mode 100644index 8ec628cf5..000000000Binary files a/docs/get-started/images/structured_character_sheet_json.png and /dev/null differdiff --git a/docs/get-started/mthds-language-tutorial.md b/docs/get-started/mthds-language-tutorial.mdnew file mode 100644index 000000000..6bfe0d276--- /dev/null+++ b/docs/get-started/mthds-language-tutorial.md@@ -0,0 +1,228 @@+---+title: "The MTHDS Language Tutorial"+description: "Learn the declarative MTHDS language step by step — pipes, sequences, inputs, and structured outputs."+---++# The MTHDS Language Tutorial++This tutorial walks you through writing `.mthds` files manually, step by step.++Set up your project and get free AI access:++```bash+pip install pipelex+pipelex init+pipelex login+```++`pipelex init` creates your project configuration. `pipelex login` opens your browser to authenticate with Pipelex Gateway (free). See [Configure AI Providers](./configure-ai-providers.md) for other options: bring your own keys, local AI, etc.++!!! tip "VS Code Extension"+ We **highly** recommend installing the Pipelex extension for `.mthds` syntax highlighting and flowchart visualization:++ - **VS Code**: Install from the [VS Code Marketplace](https://marketplace.visualstudio.com/items?itemName=pipelex.pipelex)+ - **Cursor, Windsurf, and other VS Code forks**: Install from the [Open VSX Registry](https://open-vsx.org/extension/Pipelex/pipelex)++ Running `pipelex init` will also offer to install the extension automatically if it detects your IDE.++## Step 1: Hello World++Create a file called `hello_world.mthds`:++```toml+domain = "tutorial_hello_world"+description = "Your first Pipelex pipeline"+main_pipe = "tutorial_hello_world"++[pipe]++[pipe.tutorial_hello_world]+type = "PipeLLM"+description = "Generate a creative story idea"+output = "Text"+prompt = """+Generate a one-paragraph creative story idea about a robot learning to paint.+"""+```++Run it:++```bash+pipelex run bundle hello_world.mthds+```++Here's what each part means:++- **`domain`** — a namespace for this bundle (like a Python package name)+- **`main_pipe`** — the entry point pipe that runs when you execute the bundle+- **`PipeLLM`** — a pipe type that makes an LLM call+- **`output = "Text"`** — the pipe returns plain text (a native concept)+- **`prompt`** — the prompt sent to the LLM++## Step 2: Chaining LLM Calls++Most real methods need multiple steps. `PipeSequence` chains pipes together, passing data between them.++Create `chaining_llm_calls.mthds`:++```toml+domain = "chaining_llm_calls"+description = "Chain multiple LLM calls together"+main_pipe = "generate_and_expand"++[pipe]++# First pipe: Generate a story idea+[pipe.chain_generate_idea]+type = "PipeLLM"+description = "Generate a creative story idea"+output = "Text"+prompt = """+Generate a one-paragraph creative story idea about a robot learning to paint.+"""++# Second pipe: Expand the story idea (uses result from first pipe)+[pipe.chain_expand_idea]+type = "PipeLLM"+description = "Expand a story idea into a detailed outline"+inputs = { story_idea = "Text" }+output = "Text"+prompt = """+Take this story idea and expand it into a 3-act outline:++@story_idea++Provide a brief description for each act.+"""++# PipeSequence: Chain the two pipes together+[pipe.generate_and_expand]+type = "PipeSequence"+description = "Generate a story idea then expand it"+output = "Text"+steps = [+ { pipe = "chain_generate_idea", result = "story_idea" },+ { pipe = "chain_expand_idea", result = "story_outline" },+]+```++Run it:++```bash+pipelex run bundle chaining_llm_calls.mthds+```++Key concepts:++- **`PipeSequence`** — runs pipes in order, passing results between them+- **`steps`** — each step names a pipe and stores its output in a `result` variable+- **`@story_idea`** — references data from a previous step's result in the prompt++## Step 3: Using Inputs++Instead of hardcoding everything in the prompt, you can pass data in at runtime.++Create `using_inputs.mthds`:++```toml+domain = "using_inputs"+description = "Learn how to pass inputs to your pipeline"+main_pipe = "write_about_topic"++[pipe]++# A pipe that takes an input and uses it+[pipe.write_about_topic]+type = "PipeLLM"+description = "Write a short paragraph about a given topic"+inputs = { topic = "Text" }+output = "Text"+prompt = """+Write a short, engaging paragraph about the following topic:++$topic++Keep it under 100 words.+"""+```++Create an `inputs.json` file:++```json+{+ "topic": "Photosynthesis"+}+```++Run it with the `-i` flag:++```bash+pipelex run bundle using_inputs.mthds -i inputs.json+```++Key concepts:++- **`inputs = { topic = "Text" }`** — declares what the pipe expects as input+- **`$topic`** — references an input variable in the prompt (as opposed to `@variable` which references data from working memory)+- **`-i inputs.json`** — provides input data at runtime++## Step 4: Structured Outputs++LLMs can return structured data instead of plain text. Define a **concept** with a **structure**, and the LLM output will be validated against it.++Create `structured_output.mthds`:++```toml+domain = "structured_output"+description = "Get structured data from LLMs"+main_pipe = "struct_generate_book_idea"++[concept]++# Define the structure of a book idea+[concept.BookIdea]+description = "A book idea with title, genre, and synopsis"++[concept.BookIdea.structure]+title = { type = "text", description = "The book title", required = true }+genre = { type = "text", description = "The genre of the book", required = true }+synopsis = { type = "text", description = "A brief synopsis of the book" }+target_audience = { type = "text", description = "Who this book is for" }++[pipe]++# Generate a structured book idea+[pipe.struct_generate_book_idea]+type = "PipeLLM"+description = "Generate a structured book idea"+output = "BookIdea"+prompt = """+Generate a creative book idea. Provide a compelling title, genre, synopsis, and target audience.+"""+```++Run it:++```bash+pipelex run bundle structured_output.mthds+```++Key concepts:++- **`[concept.BookIdea]`** — declares a typed concept with a description+- **`[concept.BookIdea.structure]`** — defines the fields and their types+- **`output = "BookIdea"`** — the pipe returns a structured `BookIdea` object instead of plain text++Learn more about concepts in [Define Your Concepts](../building-methods/concepts/define_your_concepts.md).++---++## Next Steps++You now understand the building blocks: pipes, sequences, inputs, and structured outputs.++- **Tutorial** — more lessons in the [Cookbook](../cookbook/index.md) (document extraction, batch processing, and more)+- **Build Reliable AI Methods** — deep dive into [method project design](../building-methods/kick-off-a-methods-project.md)+- **Pipe Operators & Controllers** — reference for [pipe operators](../building-methods/pipes/pipe-operators/index.md) (PipeLLM, PipeExtract, PipeCompose, ...) and [pipe controllers](../building-methods/pipes/pipe-controllers/index.md) (PipeSequence, PipeParallel, PipeBatch, PipeCondition)+- **Cookbook Examples** — real-world [examples and patterns](../cookbook/index.md)+- **CLI Reference** — full [command-line reference](../tools/cli/index.md)diff --git a/docs/get-started/write-methods-manually.md b/docs/get-started/write-methods-manually.mddeleted file mode 100644index a46737b9d..000000000--- a/docs/get-started/write-methods-manually.md+++ /dev/null@@ -1,356 +0,0 @@-----title: "Getting Started — Writing Methods"-description: "Learn how to write Pipelex AI methods manually. Create methods, define concepts, and understand the `.mthds` language step by step."------# Writing Methods--Ready to dive deeper? This section shows you how to manually create methods and understand the `.mthds` language.--## Write Your First Method--Let's build a **character generator** to understand the basics.-Create a `.mthds` file anywhere in your project (we recommend a `pipelines` directory):--`character.mthds`-```toml-domain = "characters" # domain of existance of your pipe--[pipe]-[pipe.create_character] # Declare the pipe and give it a code name-type = "PipeLLM" # Specify the type: Here, PipeLLM can provide LLM/vLLM calls.-description = "Creates a character." # Give it a description in natural language-output = "Text" # Specify the output of the pipe: Here its will be plain text.-prompt = """ # write your prompt-You are a book writer. Your task is to create a character.-Think of it and then output the character description.-"""-```--This pipeline is a simple LLM call without any input, with the provided prompt and will output a `TextContent` object. See more about native concepts [here](../building-methods/concepts/define_your_concepts.md)--### Run Your First Pipelex Script--**CLI:**--```bash-pipelex run pipe create_character-```--**Python:**--Create a Python file to execute the pipeline:--`character.py`-```python-from pipelex.pipeline.runner import PipelexRunner-from pipelex.pipelex import Pipelex--# Initialize pipelex to load your pipeline libraries-Pipelex.make()--runner = PipelexRunner()-response = await runner.execute_pipeline(- pipe_code="create_character",-)-pipe_output = response.pipe_output--print(pipe_output.main_stuff_as_str) # `main_stuff_as_str` is allowed here because the output is a `TextContent`-```--Then run the python file.--```bash-python character.py-```--### Get Your First Pipelex Result----As you might notice, this is plain text, and nothing is structured. Now we are going to see how to output a structured object instead of plain text.--## Generate Structured Outputs--Let's create a rigorously structured `Character` object instead of plain text. We need to create the concept `Character`. The concept names MUST be in PascalCase. [Learn more about defining concepts](../building-methods/concepts/define_your_concepts.md)--### Option 1: Define the Structure in your `.mthds` file--Define structures directly in your `.mthds` file:--```toml-[concept.Character] # Declare the concept by giving it a name.-description = "A character in a fiction story" # Give it a description in natural language.--[concept.Character.structure] # Define the structure-name = "The character's name" # First attribute: name, with the description in natural language "The character's name"-age = { type = "integer", description = "The character's age", required = true } # Second attribute: age, that is mandatory.-gender = "The character's gender" # Third attribute: "gender"-description = "A description of the character" # Fourth attribute: "description"-```--### Now use your structured concept in your pipe--Specify that the output of your Pipellm is a `Character` object:--`characters.mthds`-```toml-domain = "characters"--[concept.Character]-description = "A character in a fiction story"--[concept.Character.structure]-name = "The character's name"-age = { type = "integer", description = "The character's age", required = true }-gender = "The character's gender"-description = "A description of the character"--[pipe]-[pipe.create_character]-type = "PipeLLM"-description = "Create a character. Get a structured result."-output = "Character" # <- This is the output concept for your pipe-prompt = """-You are a book writer. Your task is to create a character.-Think of it and then output the character description.-"""-```--!!! tip "Concept Naming"- The concept name matches the class name (`Character`), so Pipelex automatically links them.--!!! tip "Semantic Clarity"- Defining concepts removes ambiguity—"character" could mean a letter or symbol, but here it clearly means a fictional person.---### Option 2: Define the Structure using Pydantic BaseModel--Using [Pydantic BaseModel](https://docs.pydantic.dev/latest/) syntax:--`characters.py`-```python-from pipelex.core.stuffs.structured_content import StructuredContent--# Define the structure of your output here-# This class MUST be a subclass of StructuredContent-class Character(StructuredContent):- name: str- age: int- gender: str- description: str-```--!!! tip "Keep Structure Files Clean"- Keep your `StructuredContent` classes in dedicated files with minimal module-level code. Pipelex imports these modules during auto-discovery, so any module-level code will be executed.--Learn more in [Inline Structures](../building-methods/concepts/inline-structures.md) or [Python StructuredContent Classes](../building-methods/concepts/python-classes.md).--### Use your Structured Concept in Your Pipe--Specify that the output of your Pipellm is a `Character` object:--`characters.mthds`-```toml-domain = "characters"--[concept]-Character = "A character in a fiction story" # <- Declare your concept by giving it the same name as the python class--[pipe]-[pipe.create_character]-type = "PipeLLM"-description = "Create a character. Get a structured result."-output = "Character" # <- This is the output concept for your pipe-prompt = """-You are a book writer. Your task is to create a character.-Think of it and then output the character description.-"""-```--!!! tip "Concept Naming"- The concept name matches the class name (`Character`), so Pipelex automatically links them.--!!! tip "Semantic Clarity"- Defining concepts removes ambiguity—"character" could mean a letter or symbol, but here it clearly means a fictional person.--#### Run Your Pipeline--The output is now a structured `Character` instance:----### Add variables in your prompt--Let's process existing characters and extract metadata from their descriptions. Let's imagine, that I have already an instance of the class `Character`. I would like to use it in a prompt in order to process that information, and extract some of the information.--For example, I would like to create and instance of `CharacterMetadata`, that contains the `name`, `age`, and height if it was provided in the description of the character.---```toml-domain = "characters"--[concept.Character]-description = "A character in a fiction story"--[concept.Character.structure]-name = "The character's name"-age = { type = "integer", description = "The character's age", required = true }-gender = "The character's gender"-description = "A description of the character"--[concept.CharacterMetadata] # <- Declare the new concept-description = "Metadata of a character"--[concept.CharacterMetadata.structure] # <- Declare its structure-name = "The character's name"-age = { type = "integer", description = "The character's age", required = true }-height = { type = "number", description = "The characters' height" }--[pipe]-[pipe.extract_character_advanced]-type = "PipeLLM"-description = "Get character information from a description."-inputs = { character = "Character" } # <- These inputs are usable in the prompt-output = "CharacterMetadata"-prompt = """-You are given a text description of a character.-Your task is to extract specific data from the following description.--@character-"""-```--!!! tip "Template Syntax"- Our template syntax is based on [Jinja2](https://jinja.palletsprojects.com/en/stable/). Use `@` prefix for tagging a variable in the prompt. Learn more about prompting with Pipelex in the [PipeLLM documentation](../building-methods/pipes/pipe-operators/PipeLLM.md).--!!! tip "Template Variables"- `@character.description` grabs the `character` stuff from the instance and uses its `description` attribute.--Learn more about Jinja in the [PipeLLM documentation](../building-methods/pipes/pipe-operators/PipeLLM.md).--#### Execute from Python--`run_pipe.py`-```python-from pipelex.pipeline.runner import PipelexRunner-from pipelex.pipelex import Pipelex--from character_model import CharacterMetadata--Pipelex.make()--inputs = {- "character": {- "concept": "character.Character",- "content": {- "name": "Elias",- "age": 38,- "gender": "man",- "occupation": "explorer",- "description": "Elias Varrin is a 38-year-old man, standing at approximately 1.85 meters tall, with a lean, weathered frame shaped by decades of travel through remote and often unforgiving landscapes. His name, though not widely known, carries weight among historians, explorers, and those who trade in whispered legends. Elias has piercing storm-gray eyes that scan every environment with sharp precision, and his ash-blond hair—flecked with early streaks of grey—is usually tucked beneath a wide-brimmed, timeworn hat."- }- }-}--# Run the pipe with loaded inputs-runner = PipelexRunner()-response = await runner.execute_pipeline(- pipe_code="extract_character_advances",- inputs=inputs,-)-pipe_output = response.pipe_output--# Get the result as a properly typed instance-print(pipe_output)-```--### How to type the output ?--You can get an instance of the python class `CharacterMetadata` if you have created the concept with python:--`character_model.py`-```python-from pipelex.core.stuffs.structured_content import StructuredContent--# input class-class Character(StructuredContent):- name: str- age: int- gender: str- occupation: str- description: str--# output class-class CharacterMetadata(StructuredContent):- name: str- age: int- height: float-```--`run_pipe.py`-```python-from pipelex.pipeline.runner import PipelexRunner-from pipelex.pipelex import Pipelex--from character_model import CharacterMetadata--Pipelex.make()--inputs = {- "character": {- "concept": "character.Character",- "content": {- "name": "Elias",- "age": 38,- "gender": "man",- "occupation": "explorer",- "description": "Elias Varrin is a 38-year-old man, standing at approximately 1.85 meters tall, with a lean, weathered frame shaped by decades of travel through remote and often unforgiving landscapes. His name, though not widely known, carries weight among historians, explorers, and those who trade in whispered legends. Elias has piercing storm-gray eyes that scan every environment with sharp precision, and his ash-blond hair—flecked with early streaks of grey—is usually tucked beneath a wide-brimmed, timeworn hat."- }- }-}--# Run the pipe with loaded inputs-runner = PipelexRunner()-response = await runner.execute_pipeline(- pipe_code="extract_character_advances",- inputs=inputs,-)-pipe_output = response.pipe_output--# Get the result as a properly typed instance-extracted_metadata = pipe_output.main_stuff_as(content_type=CharacterMetadata)-print(extracted_metadata)-```--#### Get Result----# Next Steps--Now that you understand the basics, explore more:--**Learn More about the PipeLLM:**--- [LLM Configuration: play with the models](../building-methods/configure-ai-llm-to-optimize-methods.md) - Optimize cost and quality-- [Full configuration of the PipeLLM](../building-methods/pipes/pipe-operators/PipeLLM.md)--**Learn more about Pipelex (domains, project structure, best practices...)**--- [Build Reliable AI Methods](../building-methods/kick-off-a-methods-project.md) - Deep dive into pipeline design-- [Cookbook Examples](../cookbook/index.md) - Real-world examples and patterns--**Learn More about the other pipes**--- [Pipe Operators](../building-methods/pipes/pipe-operators/index.md) - PipeLLM, PipeExtract, PipeCompose, and more-- [Pipe Controllers](../building-methods/pipes/pipe-controllers/index.md) - PipeSequence, PipeParallel, PipeBatch, PipeCondition--**Explore Tools:**--- [Claude Code Skills Plugin](../features/claude-code-skills-plugin.md) - Generate pipelines from natural language-- [CLI Commands](../tools/cli/index.md) - Command-line interface reference--**Configure:**--- [Inference Backend](../configuration/config-technical/inference-backend-config.md) - Configure model providersdiff --git a/docs/index.md b/docs/index.mdindex 89dd717b0..b5b61b826 100644--- a/docs/index.md+++ b/docs/index.md@@ -1,65 +1,118 @@----title: "What is Pipelex?"-description: "Pipelex is the open-source reference runtime for executable AI methods written in MTHDS. Build repeatable AI methods with typed concepts, focused pipes, and broad model support."+title: "Build & Run AI Methods"+description: "Methods are reusable, typed AI procedures written in MTHDS and executed by Pipelex. Build repeatable AI know-how with structured concepts, focused pipes, and 60+ models."----# What is Pipelex?+# Build & Run AI Methods-Pipelex is the open-source reference runtime for **executable AI methods** written in MTHDS. Instead of cramming everything into one complex prompt, you break tasks into focused steps, each pipe handling one clear transformation.+A method is a reusable, typed AI procedure — declared in a `.mthds` file and executed by Pipelex. Each step is explicit, each output is structured, and every run is repeatable.-Each pipe processes information using **Concepts** (typing with meaning) to keep method inputs and outputs explicit. MTHDS (`.mthds` files) is a human-readable format for defining those methods, and Pipelex validates and runs them.--Each step can be structured and validated, so you get the reliability of software and the flexibility of AI.+[:material-robot-outline: Claude Code](./get-started/build-with-claude-code.md){ .md-button .md-button--primary }+[:material-school: MTHDS Tutorial](./get-started/mthds-language-tutorial.md){ .md-button }+[:material-book-open-variant: Cookbook](./cookbook/index.md){ .md-button }----## Key Features+## Why Methods?++<div class="grid cards" markdown>++- :material-file-document-check: **Declarative**++ Express business logic at a high level of abstraction, in human-readable `.mthds` files that work across models.++- :material-shape-outline: **Typed**-### 🔄 Repeatable AI Methods-Build methods that produce consistent, reliable results every time they run.+ Concepts are semantic types: AI understands what you mean, and every input and output connects with purpose.-### 🧩 Concept-Driven Design-Use semantic typing (Concepts) to ensure each step of your pipeline makes sense and connects logically.+- :material-refresh: **Repeatable**-### 📝 Human-Readable Language-Write methods in `.mthds` files that are easy to read, edit, and maintain—even for non-developers.+ Deterministic orchestration that leaves exactly the room you want for AI to express its intelligence and creativity.-### 🤖 AI-Assisted Development-Generate and iterate on methods using natural language with your favorite AI coding assistant.+- :material-puzzle: **Composable**-### 🔧 Production-Ready-Validate, test, and deploy AI methods with the same confidence as traditional software.+ Chain pipes into sequences, nest methods inside methods, and share them with the community.++</div>----## Why Pipelex?+## What a Method Looks Like++A single pipe in MTHDS — five lines that call an LLM with typed inputs and output:++```toml+[pipe.summarize_article]+type = "PipeLLM"+inputs = { article = "Text", audience = "Text" }+output = "Text"+prompt = "Summarize $article in three bullet points for $audience."+```++From here, Pipelex handles model routing across 60+ models, structured output parsing, and pipeline orchestration.++---++## Capabilities++<div class="grid cards" markdown>++- :material-shape-outline: **[Typed Concepts](./features/concepts.md)**++ Semantic types that give meaning to every input and output — native, inline, or backed by Python classes.++- :material-pipe: **[Pipe Operators](./features/pipe-operators.md)**++ Six operators that do the work: LLM calls, document extraction, image generation, web search, composition, and custom functions.-Traditional AI applications often struggle with:+- :material-sitemap: **[Pipeline Orchestration](./features/pipeline-orchestration.md)**-- **Complexity**: One massive prompt trying to do everything-- **Unpredictability**: Different results each time-- **Maintenance**: Hard to debug and improve-- **Collaboration**: Difficult for teams to work together+ Sequence, parallel, batch, and conditional controllers that wire pipes into full methods with shared working memory.-Pipelex solves these problems by:+- :material-cloud-check: **[60+ AI Models](./features/llm-integration.md)**-- **Breaking down complexity** into focused, manageable steps-- **Ensuring consistency** through structured validation-- **Enabling iteration** with clear, editable methods-- **Facilitating collaboration** with human-readable syntax+ One gateway key or bring-your-own: OpenAI, Anthropic, Mistral, Google, Deepseek, Hugging Face, and more.++- :material-check-decagram: **[Validation and Dry Run](./features/validation-dry-run.md)**++ Validate pipelines before execution and dry-run with mocked responses — catch errors without spending tokens.++- :material-console: **[CLI and Tooling](./features/cli.md)**++ Full CLI for init, build, validate, run, and graph visualization. Plus `plxt` for formatting and linting `.mthds` files.++</div>++---++## The MTHDS Ecosystem++MTHDS is the open standard behind Pipelex methods. It defines the language, the file format, and the ecosystem for sharing methods.++!!! info "Explore the ecosystem"++ - **[mthds.ai](https://mthds.ai)** — The MTHDS language specification+ - **[mthds.sh](https://mthds.sh)** — The Methods Hub for discovering and sharing methods----## Next Steps+## Get Started++<div class="grid cards" markdown>++- :material-robot-outline: **[Build with Claude Code](./get-started/build-with-claude-code.md)**++ Describe what you want in natural language — Claude writes, runs, and iterates on your method for you.++- :material-school: **[MTHDS Language Tutorial](./get-started/mthds-language-tutorial.md)**++ Learn the declarative language step by step: concepts, pipes, sequences, inputs, and structured outputs.-Ready to get started?+- :material-book-open-variant: **[Cookbook Examples](./cookbook/index.md)**-- [:material-rocket-launch: Get Started](./get-started/write-methods-manually.md){ .md-button .md-button--primary }-- [:material-shape-outline: Learn MTHDS](./features/mthds-language.md){ .md-button }-- [:material-book-open: Read the Know-How Graph](./viewpoint/viewpoint.md){ .md-button }+ Production-ready recipes — from Hello World to document extraction, synthetic data, and image generation.-**Explore Examples:**+</div>-[](https://github.com/Pipelex/pipelex-cookbook/tree/main)diff --git a/docs/setup/index.md b/docs/setup/index.mddeleted file mode 100644index f8d7f04c0..000000000--- a/docs/setup/index.md+++ /dev/null@@ -1,24 +0,0 @@-----title: "Setup"-description: "Set up Pipelex for your first MTHDS methods project. Configure AI providers, organize `.mthds` files, and choose your project layout."------# Setup (first run)--This section is for **first-time onboarding**: the key choices you need to make to get a project running quickly and safely.--If you already have a project running and want to tune behavior, jump to [Configuration (TOML reference)](../configuration/index.md).--## What belongs where?--- **Setup**: pick providers, create initial files, understand privacy/telemetry trade-offs, and follow recommended project layout.-- **Configuration**: the detailed reference for each TOML section and its options.--## Quick guide--- **Need to run methods with LLMs?** Start with [Configure AI Providers](./configure-ai-providers.md).-- **Need a recommended repo layout for `.mthds` and Python code?** See [Project Organization](./project-organization.md).-- **Need to understand telemetry and privacy trade-offs?** See [Telemetry](./telemetry.md).-- **Ready to tune the knobs?** Go to [Configuration Overview](../configuration/index.md).--diff --git a/docs/setup/project-organization.md b/docs/setup/project-organization.mddeleted file mode 100644index e30754050..000000000--- a/docs/setup/project-organization.md+++ /dev/null@@ -1,64 +0,0 @@-----description: "Learn how to structure your Pipelex project so that .mthds files, Python code, and executable AI methods stay organized and easy to maintain."------# Project Organization--## Overview--Pipelex automatically discovers `.mthds` pipeline files anywhere in your project (excluding `.venv`, `.git`, `node_modules`, etc.).--## Recommended: Keep pipelines with related code--```bash-your_project/-├── METHODS.toml # Package manifest (optional)-├── my_project/ # Your Python package-│ ├── finance/-│ │ ├── services.py-│ │ ├── invoices.mthds # Pipeline with finance code-│ │ └── invoices_struct.py # Structure classes-│ └── legal/-│ ├── services.py-│ ├── contracts.mthds # Pipeline with legal code-│ └── contracts_struct.py-├── .pipelex/ # Config at repo root-│ └── pipelex.toml-├── .env # API keys (git-ignored)-└── requirements.txt-```--- **Package manifest**: `METHODS.toml` at your project root declares package identity and pipe visibility. See [Packages](../building-methods/packages.md) for details.--## Alternative: Centralize pipelines--```bash-your_project/-├── pipelines/-│ ├── invoices.mthds-│ ├── contracts.mthds-│ └── structures.py-└── .pipelex/- └── pipelex.toml-```--Learn more in our [Project Structure documentation](../building-methods/kick-off-a-methods-project.md).-------## Prerequisites--- **Python**: Version 3.10 or above-- **API Access**: One of the three options from [Configure AI Providers](./configure-ai-providers.md) (Pipelex Inference, your own keys, or local AI)-------## Next Steps--Now that you understand project organization:--1. **Start building**: [Get Started](../get-started/write-methods-manually.md)-2. **Learn the concepts**: [Writing Methods Tutorial](../get-started/write-methods-manually.md)-3. **Explore examples**: [Cookbook Repository](https://github.com/Pipelex/pipelex-cookbook/tree/main)-4. **Deep dive**: [Build Reliable AI Methods](../building-methods/kick-off-a-methods-project.md)-diff --git a/docs/stylesheets/general.css b/docs/stylesheets/general.cssindex 7446c0fa8..d27cdb046 100644--- a/docs/stylesheets/general.css+++ b/docs/stylesheets/general.css@@ -12,8 +12,18 @@.equal-width { width: 100%; max-width: 300px; display: inline-block; }pre code { white-space: pre-wrap !important; word-wrap: break-word; overflow-wrap: break-word; }+/* --- Sidebar width — widen to fit longer nav labels without wrapping --- */+.md-sidebar { width: 13rem; }+.md-sidebar .md-sidebar__inner { padding-right: 4px; }+/* --- Sidebar nav --- */+/* Hide the tab-name label that repeats the active tab above the sidebar tree+ (e.g. "Get Started", "Guide") — these are top-level section labels in --lifted mode */+.md-nav--primary.md-nav--lifted > .md-nav__list > .md-nav__item--section > label.md-nav__link {+ display: none !important;+}+/* Ensure all link and label elements have no shadow */.md-nav__link,label.md-nav__link {@@ -73,3 +83,19 @@ label.md-nav__link {font-weight: 700 !important;background-color: rgba(69, 191, 159, 0.12) !important;}++/* --- Top nav tabs: consistent sizing so active tab doesn't shift --- */+.md-tabs__link {+ padding: 4px 12px !important;+ border-radius: 6px;+}++/* --- Top nav tabs: active tab stands out --- */+.md-tabs__item--active .md-tabs__link {+ font-weight: 700 !important;+ opacity: 1 !important;+ background-color: rgba(255, 255, 255, 0.15);+}+[data-md-color-scheme="default"] .md-tabs__item--active .md-tabs__link {+ background-color: rgba(255, 255, 255, 0.25);+}diff --git a/docs/tools/cli/index.md b/docs/tools/cli/index.mdindex 6b2c9b579..9990416e1 100644--- a/docs/tools/cli/index.md+++ b/docs/tools/cli/index.md@@ -52,7 +52,7 @@ Package manifest management currently lives in the `mthds` CLI:## Related Documentation-- [Configure AI Providers](../../setup/configure-ai-providers.md) - Set up LLM backends+- [Configure AI Providers](../../get-started/configure-ai-providers.md) - Set up LLM backends- [Design and Run Pipelines](../../building-methods/pipes/index.md) - Pipeline development guide- [Packages](../../building-methods/packages.md) - `METHODS.toml` manifests and exportsdiff --git a/docs/tools/cli/init.md b/docs/tools/cli/init.mdindex e2e2a4888..b74d08882 100644--- a/docs/tools/cli/init.md+++ b/docs/tools/cli/init.md@@ -121,7 +121,7 @@ pipelex-agent init -g --config '{"backends": ["pipelex_gateway"], "accept_gatewa## Related Configuration-- [Configure AI Providers](../../setup/configure-ai-providers.md)+- [Configure AI Providers](../../get-started/configure-ai-providers.md)- [Inference Backend Configuration](../../configuration/config-technical/inference-backend-config.md)- [Telemetry Configuration](../../configuration/config-practical/telemetry-config.md)diff --git a/mkdocs.yml b/mkdocs.ymlindex 74b4701bc..b7a184ea2 100644--- a/mkdocs.yml+++ b/mkdocs.yml@@ -81,7 +81,8 @@ plugins:'home/10-advanced-customizations/reporting-delegate-injection.md': 'advanced/reporting-delegate-injection.md''home/10-advanced-customizations/secrets-provider-injection.md': 'advanced/secrets-provider-injection.md''home/10-advanced-customizations/storage-provider-injection.md': 'advanced/storage-provider-injection.md'- 'home/2-get-started/write-methods-manually.md': 'get-started/write-methods-manually.md'+ 'get-started/write-methods-manually.md': 'get-started/mthds-language-tutorial.md'+ 'home/2-get-started/write-methods-manually.md': 'get-started/mthds-language-tutorial.md''home/3-understand-pipelex/viewpoint.md': 'viewpoint/viewpoint.md''home/4-cookbook-examples/extract-dpe.md': 'cookbook/extract-dpe.md''home/4-cookbook-examples/extract-gantt.md': 'cookbook/extract-gantt.md'@@ -90,14 +91,19 @@ plugins:'home/4-cookbook-examples/extract-table.md': 'cookbook/extract-table.md''home/4-cookbook-examples/hello-world.md': 'cookbook/hello-world.md''home/4-cookbook-examples/index.md': 'cookbook/index.md'- 'home/4-cookbook-examples/invoice-extractor.md': 'cookbook/invoice-extractor.md'- 'home/4-cookbook-examples/simple-ocr.md': 'cookbook/simple-ocr.md'+ 'home/4-cookbook-examples/invoice-extractor.md': 'cookbook/extract-invoice.md'+ 'home/4-cookbook-examples/simple-ocr.md': 'cookbook/index.md'+ 'cookbook/simple-ocr.md': 'cookbook/index.md'+ 'cookbook/invoice-extractor.md': 'cookbook/extract-invoice.md''home/4-cookbook-examples/write-tweet.md': 'cookbook/write-tweet.md'- 'home/5-setup/configure-ai-providers.md': 'setup/configure-ai-providers.md'+ 'home/5-setup/configure-ai-providers.md': 'get-started/configure-ai-providers.md''home/5-setup/gateway-models.md': 'setup/gateway-models.md'- 'home/5-setup/index.md': 'setup/index.md'- 'home/5-setup/project-organization.md': 'setup/project-organization.md'+ 'home/5-setup/index.md': 'get-started/build-with-claude-code.md'+ 'home/5-setup/project-organization.md': 'get-started/build-with-claude-code.md''home/5-setup/telemetry.md': 'setup/telemetry.md'+ 'setup/index.md': 'get-started/build-with-claude-code.md'+ 'setup/project-organization.md': 'get-started/build-with-claude-code.md'+ 'setup/configure-ai-providers.md': 'get-started/configure-ai-providers.md''home/6-build-reliable-ai-workflows/adapt-to-llm-prompting-style-openai-anthropic-mistral.md': 'building-methods/adapt-to-llm-prompting-style-openai-anthropic-mistral.md''home/6-build-reliable-ai-workflows/concepts/define_your_concepts.md': 'building-methods/concepts/define_your_concepts.md''home/6-build-reliable-ai-workflows/concepts/inline-structures.md': 'building-methods/concepts/inline-structures.md'@@ -194,9 +200,41 @@ extra_css:- stylesheets/general.cssnav:- - Home:- - What is Pipelex?: index.md- - Getting Started: get-started/write-methods-manually.md+ - Get Started:+ - Build & Run AI Methods: index.md+ - Build with Claude Code: get-started/build-with-claude-code.md+ - The MTHDS Language Tutorial: get-started/mthds-language-tutorial.md+ - Configure AI Providers: get-started/configure-ai-providers.md+ - Cookbook Examples:+ - Overview: cookbook/index.md+ - Quick Start:+ - Hello World: cookbook/hello-world.md+ - Summarize: cookbook/summarize.md+ - Document Extraction:+ - Generic Document: cookbook/extract-generic.md+ - Invoice: cookbook/extract-invoice.md+ - Proof of Purchase: cookbook/extract-proof-of-purchase.md+ - DPE (Energy Diagnostic): cookbook/extract-dpe.md+ - Table from Image: cookbook/extract-table.md+ - Gantt Chart: cookbook/extract-gantt.md+ - Markdown from Document: cookbook/extract-markdown.md+ - Slides from Presentation: cookbook/extract-slides.md+ - Visual Generation:+ - Design Slides: cookbook/design-slides.md+ - Generate Image: cookbook/generate-image.md+ - Advanced:+ - Synthetic Data: cookbook/gen-synthetic-data.md+ - Expense Data with Receipts: cookbook/gen-expense-data.md+ - Using Inference Plugins: cookbook/using-inference-plugins.md+ - Work in Progress:+ - Tweet Optimizer: cookbook/write-tweet.md+ - Blog Article Generator: cookbook/blog-article-generator.md+ - Advisory Board: cookbook/advisory-board.md+ - Discord Newsletter: cookbook/discord-newsletter.md+ - Expense Validation: cookbook/validate-expense-data.md+ - Viewpoint:+ - The Know-How Graph: viewpoint/viewpoint.md+ - Guide:- Features:- Overview: features/index.md- Declarative AI Methods:@@ -223,26 +261,6 @@ nav:- Configuration & Extensibility:- Configuration System: features/configuration.md- Advanced Customizations: features/advanced-customizations.md- - Cookbook Examples:- - Overview: cookbook/index.md- - Hello World: cookbook/hello-world.md- - Document Processing:- - Simple OCR: cookbook/simple-ocr.md- - Generic Document Extraction: cookbook/extract-generic.md- - Invoice Extractor: cookbook/invoice-extractor.md- - Proof of Purchase Extraction: cookbook/extract-proof-of-purchase.md- - Graphical Extraction:- - Gantt Chart Extraction: cookbook/extract-gantt.md- - Table Extraction from Image: cookbook/extract-table.md- - DPE Extraction: cookbook/extract-dpe.md- - Text Generation:- - Tweet Optimizer (wip): cookbook/write-tweet.md- - Setup (first run):- - Overview: setup/index.md- - Configure AI Providers: setup/configure-ai-providers.md- - Gateway Available Models: setup/gateway-models.md- - Project Organization: setup/project-organization.md- - Telemetry: setup/telemetry.md- Build Reliable AI Methods:- Kick off a Method Project: building-methods/kick-off-a-methods-project.md- Pipelex Bundle Specification: building-methods/pipelex-bundle-specification.md@@ -279,6 +297,21 @@ nav:- Optimize Cost & Quality: building-methods/configure-ai-llm-to-optimize-methods.md- LLM Structured Generation: building-methods/llm-structured-generation-config.md- LLM Prompting Style: building-methods/adapt-to-llm-prompting-style-openai-anthropic-mistral.md+ - Reference:+ - CLI Reference:+ - Overview: tools/cli/index.md+ - Init: tools/cli/init.md+ - Validate: tools/cli/validate.md+ - Run: tools/cli/run.md+ - Show: tools/cli/show.md+ - Pkg: tools/cli/pkg.md+ - Build:+ - Overview: tools/cli/build/index.md+ - Runner: tools/cli/build/runner.md+ - Structures: tools/cli/build/structures.md+ - Inputs: tools/cli/build/inputs.md+ - Output: tools/cli/build/output.md+ - Agent CLI: tools/cli/agent-cli.md- Configuration (TOML reference):- Overview: configuration/index.md- Pipeline Validation Configuration:@@ -294,25 +327,14 @@ nav:- LLM Providers & Models: configuration/config-technical/inference-backend-config.md- Library: configuration/config-technical/library-config.md- Feature: configuration/config-advanced/feature-config.md- - Analytics:- - Observer Data Extraction: analytics/data-extraction.md- Tools:- - CLI:- - Overview: tools/cli/index.md- - Init: tools/cli/init.md- - Validate: tools/cli/validate.md- - Run: tools/cli/run.md- - Show: tools/cli/show.md- - Pkg: tools/cli/pkg.md- - Build:- - Overview: tools/cli/build/index.md- - Runner: tools/cli/build/runner.md- - Structures: tools/cli/build/structures.md- - Inputs: tools/cli/build/inputs.md- - Output: tools/cli/build/output.md- - Agent CLI: tools/cli/agent-cli.md- plxt (Formatter & Linter): tools/plxt.md- Logging: tools/logging.md+ - Analytics:+ - Observer Data Extraction: analytics/data-extraction.md+ - Telemetry: setup/telemetry.md+ - Gateway Available Models: setup/gateway-models.md+ - Advanced:- Advanced Customizations:- Overview: advanced/index.md- Secrets Provider: advanced/secrets-provider-injection.md@@ -321,24 +343,20 @@ nav:- Observer: advanced/observer-provider-injection.md- Content Generator: advanced/content-generator-injection.md- Pipe Router: advanced/pipe-router-injection.md- - Viewpoint:- - The Know-How Graph: viewpoint/viewpoint.md- - Under the Hood:- - Overview: under-the-hood/index.md- - Architecture Overview: under-the-hood/architecture-overview.md- - Dry Run Mock Generation: under-the-hood/dry-run-mock-generation.md- - Execution Graph Tracing: under-the-hood/execution-graph-tracing.md- - Image Handling in LLM Prompts: under-the-hood/image-handling-in-llm-prompts.md- - Reasoning Controls: under-the-hood/reasoning-controls.md- - StuffArtefact & Image Rendering: under-the-hood/stuffartefact-and-image-rendering.md- - Test Profile Configuration: under-the-hood/test-profile-configuration.md- - Init CLI Flows: under-the-hood/init-cli-flows.md- - API: https://pipelex.github.io/pipelex-api/- - MCP: https://pipelex.github.io/pipelex-mcp/- - n8n: https://pipelex.github.io/n8n-nodes-pipelex/- - Contribute:+ - Under the Hood:+ - Overview: under-the-hood/index.md+ - Architecture Overview: under-the-hood/architecture-overview.md+ - Dry Run Mock Generation: under-the-hood/dry-run-mock-generation.md+ - Execution Graph Tracing: under-the-hood/execution-graph-tracing.md+ - Image Handling in LLM Prompts: under-the-hood/image-handling-in-llm-prompts.md+ - Reasoning Controls: under-the-hood/reasoning-controls.md+ - StuffArtefact & Image Rendering: under-the-hood/stuffartefact-and-image-rendering.md+ - Test Profile Configuration: under-the-hood/test-profile-configuration.md+ - Init CLI Flows: under-the-hood/init-cli-flows.md+ - Project:- Contributing: contributing.md- Configuration Internals: contribute/configuration-defaults-and-overrides.md- Code of Conduct: CODE_OF_CONDUCT.md- License: license.md- - Changelog: changelog.md+ - Changelog: changelog.md+ - API: https://pipelex.github.io/pipelex-api/diff --git a/pyproject.toml b/pyproject.tomlindex 27e11ae14..86f408ce9 100644--- a/pyproject.toml+++ b/pyproject.toml@@ -59,7 +59,7 @@ Homepage = "https://pipelex.com"Repository = "https://github.com/Pipelex/pipelex"Documentation = "https://docs.pipelex.com/"Changelog = "https://docs.pipelex.com/changelog/"-"MTHDS Standard" = "https://mthds.ai"+"MTHDS Standard" = "https://mthds.ai/latest/"[project.optional-dependencies]anthropic = ["anthropic>=0.78.0"]