
RAGFlow is an agent-native database: a Retrieval-Augmented Generation (RAG) engine that grew into context infrastructure.
Go agent-harnessagent-native-databaseagentic-aiagentic-retrievalagentic-searchaiai-agentscontext-enginecontext-engineeringcontext-managementharness-engineeringknowledge-compilationragretrieval-augmented-generationretrieval-harnesssearch-harness
Update docs (#21876)
Yingfeng05bebd9495c1
diff --git a/docs/basics/agent_context_engine.md b/docs/basics/agent_context_engine.mdindex 87db270a7f..e74348031d 100644--- a/docs/basics/agent_context_engine.md+++ b/docs/basics/agent_context_engine.md@@ -1,10 +1,9 @@----sidebar_position: 2+sidebar_position: 3title: "What Is Agent Context Engine?"sidebar_label: "What Is Agent Context Engine?"slug: /what-is-agent-context-engine----# What Is Agent Context Engine?From 2025, a silent revolution began beneath the dazzling surface of AI Agents. While the world marveled at agents that could write code, analyze data, and automate workflows, a fundamental bottleneck emerged: why do even the most advanced agents still stumble on simple questions, forget previous conversations, or misuse available tools?@@ -14,6 +13,7 @@ The answer lies not in the intelligence of the Large Language Model (LLM) itselfThis is where the Agent Context Engine comes in. It is not merely an incremental improvement but a foundational shift, representing the evolution of RAG from a singular technique into the core data and intelligence substrate for the entire Agent ecosystem.## Beyond the Hype: The Reality of Today's "Intelligent" Agents+Today, the “intelligence” behind most AI Agents hides a mountain of human labor. Developers must:- Hand-craft elaborate prompt templates@@ -32,9 +32,7 @@ So, what exactly is an Agent Context Engine? It is a unified, intelligent, and aAt its core, an Agent Context Engine is built on a triumvirate of next-generation retrieval capabilities, seamlessly integrated into a single service layer:1. The Knowledge Core (Advanced RAG): This is the evolution of traditional RAG. It moves beyond simple chunk-and-embed to intelligently process static, private enterprise knowledge. Techniques like TreeRAG (building LLM-generated document outlines for "locate-then-expand" retrieval) and GraphRAG (extracting entity networks to find semantically distant connections) work to close the "semantic gap." The engine’s Ingestion Pipeline acts as the ETL for unstructured data, parsing multi-format documents and using LLMs to enrich content with summaries, metadata, and structure before indexing.-2. The Memory Layer: An Agent’s intelligence is defined by its ability to learn from interaction. The Memory Layer is a specialized retrieval system for dynamic, episodic data: conversation history, user preferences, and the agent’s own internal state (e.g., "waiting for human input"). It manages the lifecycle of this data—storing raw dialogue, triggering summarization into semantic memory, and retrieving relevant past interactions to provide continuity and personalization. Technologically, it is a close sibling to RAG, but focused on a temporal stream of data.-3. The Tool Orchestrator: As MCP (Model Context Protocol) enables the connection of hundreds of internal services as tools, a new problem arises: tool selection. The Context Engine solves this with Tool Retrieval. Instead of dumping all tool descriptions into the prompt, it maintains an index of tools and—critically—an index of Skills (best practices on when and how to use tools). For a given task, it retrieves only the most relevant tools and instructions, transforming the LLM’s job from "searching a haystack" to "following a recipe."## Why Do We Need a Dedicated Engine? The Case for a Unified Substrate@@ -48,12 +46,11 @@ The necessity of an Agent Context Engine becomes clear when we examine the alterThe shift from Context Engineering to a Context Platform/Engine marks the maturation of enterprise AI, as summarized in the table below:| Dimension | Context engineering (present) | Context engineering/Platform (future) |-|---------------------|----------------------------------------------------------------------------|---------------------------------------------------------------------------------------|+| ------------------- | -------------------------------------------------------------------------- | ------------------------------------------------------------------------------------- || Context creation | Manual, artisanal work by developers and prompt engineers. | Automated, driven by intelligent ingestion pipelines and configurable rules. || Context delivery | Hard-coded prompts and static retrieval logic embedded in agent workflows. | Dynamic, real-time retrieval and assembly based on the agent's live state and intent. || Context maintenance | A development and operational burden, logic locked in code. | A manageable platform function, with visibility and control returned to the business. |-## RAGFlow: A Resolute March Toward the Context Engine of AgentsThis is the future RAGFlow is forging.diff --git a/docs/basics/agent_native_database.md b/docs/basics/agent_native_database.mdnew file mode 100644index 0000000000..e2fb1f975f--- /dev/null+++ b/docs/basics/agent_native_database.md@@ -0,0 +1,104 @@+---+sidebar_position: 1+title: "What Is Agent Native Database?"+sidebar_label: "What Is Agent Native Database?"+slug: /what-is-agent-native-database+---++# What is an Agent Native Database?++An agent native database is a **context supply layer** that an agent harness can query directly. It stores, compiles, and governs context—claims with verbatim evidence, navigation structures, entity relations, timelines, ontologies, wikis, and memory—and hands the agent the smallest sufficient set of verified facts instead of a ranked list of passages.++It is not a RAG engine, not a vector database, and not a relational database. It is the layer that produces and delivers context, while the harness decides what enters the model window.++---++## Why it matters++Retrieval-augmented generation is becoming agentic. A search harness writes queries, reads what it finds, reformulates, and decides when to stop. This shift has largely solved the accuracy problem: a harness with only BM25, grep, and MiniMax M3 answers 85% of BrowseComp-Plus and reaches 91% on the multi-hop FRAMES benchmark in our runs, without any compiled index and without any vector index.++What the shift exposes is a context problem. An undisciplined loop repeats the same queries, rereads the same documents, and fills the window with passages that are never used. The process consumes tokens but does not become an answer.++The missing layer is **knowledge compilation**: a configurable ingestion pipeline that enriches source documents with context no chunk contains on its own. Compilation is not a better retriever. It is a supply layer.++The economics are asymmetric. A navigation tree whose leaves are claim–evidence pairs cuts total query tokens by 91% when the evidence suffices and adds 1.9% when it does not—a 38% average reduction. That asymmetry implies a 2% break-even sufficiency rate, while the measured rate on FRAMES is near 43%. Compilation is not a bet on hits; it is a trade that pays on most corpora.++---++## How it works++### Three layers, one division of labor++**Model layer.** The large language model that reasons and answers. It is tightly coupled with the harness and evolves with it.++**Harness layer.** The agent loop that orchestrates: it decides what to search, what to read, and when to stop. It can be RAGFlow's reference harness, an external framework such as LangGraph, or a custom loop.++**Context layer.** The agent native database. It supplies compiled, governed context through a query interface, and it never decides what the model should conclude.++The division is one sentence: **the harness orchestrates, the database supplies.**++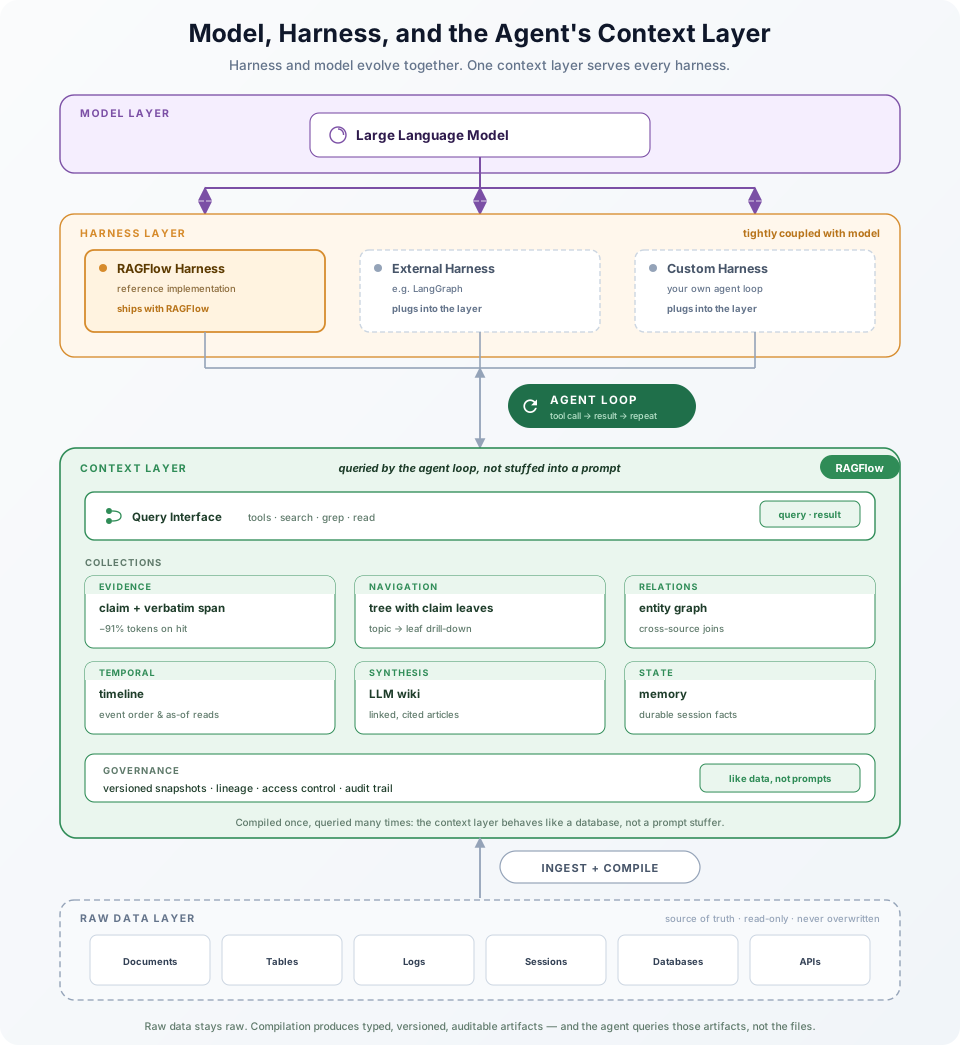++### Inside the context layer++The context layer behaves like a database, not a prompt stuffer:++- **Query interface.** Tools such as search, grep, read, navigation, graph, and memory. It returns candidates and evidence, never conclusions.+- **Collections.** Evidence (claim + verbatim span), navigation trees, entity graphs, timelines, LLM wikis, and memory—each typed, versioned, and queryable.+- **Governance.** Versioned snapshots, lineage, access control, and audit trails. Every delivered claim resolves to a live source span.++### From raw data to context++Raw data—documents, tables, logs, sessions, databases, APIs—stays raw. It is never overwritten. An **ingest and compile** pipeline parses, chunks, enriches, validates, assembles, and registers typed artifacts. Those artifacts are the data the agent queries.++Two rules keep the layer trustworthy:++- **Raw and derived channels are separate.** Derived artifacts are read-only and never written back into the source. A model reading a claim can always fall back to the original text.+- **Compilation is query-independent.** Understanding moves from query time to index time. Compile once, reuse across queries, artifacts, and sessions.++---++## Key concepts++**Knowledge compilation.** A query-independent transformation that turns a corpus into typed, versioned artifacts with lineage to the exact source spans.++**Claim–evidence pair.** The unit of compilation: a normalized claim, a verbatim evidence span, source offsets, and validity metadata. A claim without a locatable span is not stored.++**Navigation tree with claim leaves.** The tree organizes; the leaves carry evidence. Structure alone adds no accuracy—under a competent harness, summary trees, PageIndex outlines, wikis, and graphs produced no detectable accuracy gain on FRAMES, and a PageIndex outline degraded at scale.++**Two version lines.** Pipeline versions govern execution (“which graph this document runs on”); compilation versions govern provenance (“which template produced this knowledge”). Both are mechanisms, not conventions.++**Evidence gate.** A decision model that answers one question before generation: is this block of evidence sufficient to send? Its value is in deciding what not to send, not in ranking what to send.++---++## How it differs from RAG and vector databases++| | RAG engine | Vector database | Agent native database |+| ---------------- | --------------- | ------------------ | ---------------------------------- |+| Primary consumer | Human user | Retrieval pipeline | Agent harness |+| Delivers | Ranked passages | Similarity hits | Smallest sufficient context |+| Unit of value | Recall@k | Embedding quality | Token cost, provenance, governance |+| Structure | Chunks + index | Vectors | Typed, versioned artifacts |+| Query form | Search box | Similarity query | Tool calls |++A RAG engine answers “what passages are relevant?” A vector database answers “what is nearest?” An agent native database answers “what is the smallest sufficient set of verified facts for this step, and where did each fact come from?”++---++## What it deliberately does not do++- **It does not replace search or grep.** Search finds candidates; compilation helps the harness use less context after it finds them.+- **It does not claim structure improves accuracy.** Our measurements say otherwise. Structure organizes; evidence supplies.+- **It does not default to a vector index.** Inside a harness, a dense leg added no signal the loop lacked, and in our runs it lowered accuracy.+- **It does not lock in a single harness.** RAGFlow's harness is a reference implementation. The database serves any harness that can call its tools.+- **It is not a relational database.** There is no query language and no schema enforcement. The harness, not the store, decides what a given question reads.++---++## Getting started++RAGFlow 1.0 is the first open-source implementation of an agent native database. It is written in Go, ships with a configurable ingestion pipeline and a stateful retrieval harness, and is API-compatible with 0.27.x for a smooth upgrade.++- GitHub: https://github.com/infiniflow/ragflow+- Paper: *Context as Infrastructure: Knowledge Compilation for Retrieval in Agentic Systems with Harnesses* https://arxiv.org/abs/2610.41172diff --git a/docs/basics/rag.md b/docs/basics/rag.mdindex 45b3280fb4..9ea6a09b8d 100644--- a/docs/basics/rag.md+++ b/docs/basics/rag.md@@ -1,8 +1,7 @@----sidebar_position: 1+sidebar_position: 2slug: /what-is-rag----# What Is Retrieval-Augmented Generation (RAG)?Since large language models (LLMs) became the focus of technology, their ability to handle general knowledge has been astonishing. However, when questions shift to internal corporate documents, proprietary knowledge bases, or real-time data, the limitations of LLMs become glaringly apparent: they cannot access private information outside their training data. Retrieval-Augmented Generation (RAG) was born precisely to address this core need. Before an LLM generates an answer, it first retrieves the most relevant context from an external knowledge base and inputs it as "reference material" to the LLM, thereby guiding it to produce accurate answers. In short, RAG elevates LLMs from "relying on memory" to "having evidence to rely on," significantly improving their accuracy and trustworthiness in specialized fields and real-time information queries.@@ -59,6 +58,7 @@ Advanced Practice: Leading solutions, such as RAGFlow, tend to use Visual Langua### The Complexity of Chunking: The Trade-Off Between Precision and ContextA simple "chunk-embed-retrieve" pipeline has an inherent contradiction:+- Semantic Matching requires small text chunks to ensure clear semantic focus.- Context Understanding requires large text chunks to ensure complete and coherent information.@@ -69,6 +69,7 @@ Advanced Practice: Leading solutions, such as RAGFlow, employ semantic enhanceme### Why Is a Vector Database Insufficient for Serving RAG?Vector databases excel at semantic similarity search, but RAG requires precise and reliable answers, demanding more capabilities from the retrieval system:+- Hybrid Search: Relying solely on vector retrieval may miss exact keyword matches (e.g., product codes, regulation numbers). Hybrid search, combining vector retrieval with keyword retrieval (BM25), ensures both semantic breadth and keyword precision.- Tensor or Multi-Vector Representation: To support cross-modal data, employing tensor or multi-vector representation has become an important trend.- Metadata Filtering: Filtering based on attributes like date, department, and type is a rigid requirement in business scenarios.@@ -78,9 +79,10 @@ Therefore, the retrieval layer of RAG is a composite system based on vector sear## RAG and Memory: Retrieval from the Same Source but Different StreamsWithin the agent framework, the essence of the memory mechanism is the same as RAG: both retrieve relevant information from storage based on current needs. The key difference lies in the data source:+- RAG: Targets pre-existing static or dynamic private data provided by the user in advance (e.g., documents, databases).- Memory: Targets dynamic data generated or perceived by the agent in real-time during interaction (e.g., conversation history, environmental state, tool execution results).-They are highly consistent at the technical base (e.g., vector retrieval, keyword matching) and can be seen as the same retrieval capability applied in different scenarios ("existing knowledge" vs. "interaction memory"). A complete agent system often includes both an RAG module for inherent knowledge and a Memory module for interaction history.+ They are highly consistent at the technical base (e.g., vector retrieval, keyword matching) and can be seen as the same retrieval capability applied in different scenarios ("existing knowledge" vs. "interaction memory"). A complete agent system often includes both an RAG module for inherent knowledge and a Memory module for interaction history.## RAG Applications