
RAGFlow is an agent-native database: a Retrieval-Augmented Generation (RAG) engine that grew into context infrastructure.
Go agent-harnessagent-native-databaseagentic-aiagentic-retrievalagentic-searchaiai-agentscontext-enginecontext-engineeringcontext-managementharness-engineeringknowledge-compilationragretrieval-augmented-generationretrieval-harnesssearch-harness
docs: delete redundant docs (#19078)
YanZhang092b2744023e
diff --git a/docs/guides/agent/agent_quickstarts/sandbox_quickstart.md b/docs/guides/agent/agent_quickstarts/sandbox_quickstart.mddeleted file mode 100644index 6258989ed0..0000000000--- a/docs/guides/agent/agent_quickstarts/sandbox_quickstart.md+++ /dev/null@@ -1,262 +0,0 @@-----sidebar_position: 20-title: Sandbox Quickstart-sidebar_label: Sandbox Quickstart-slug: /sandbox_quickstart-sidebar_custom_props: {- categoryIcon: LucideCodesandbox-}-----# Sandbox Quickstart--RAGFlow's `CodeExec` agent component needs a sandbox provider to run Python and JavaScript code.--The simplest setup flow is:--1. Start the required sandbox services.-2. Open the RAGFlow admin page.-3. Go to **Admin > Sandbox Settings**.-4. Choose a provider and save the configuration.-5. Test the connection in the same page.--## Admin Page--Configure sandbox providers from the admin page:--- `self_managed`: Uses the executor manager service.-- `local`: Runs code on the current machine.-- `ssh`: Runs code on a remote machine over SSH.-- `aliyun_codeinterpreter`, `e2b`, `tenki`, and `ucloud_agent_sandbox`: Cloud providers.---## Provider Options---RAGFlow supports multiple sandbox providers. Configure the active provider in-Admin > Sandbox Settings after the services are up.--- `self_managed`: Runs code inside Docker-managed sandbox containers. This is the default provider.-- `local`: Runs code as local Python or Node.js subprocesses. Use this only in trusted development environments.-- `ssh`: Runs code on a remote machine over SSH.-- `aliyun_codeinterpreter` and `e2b`: Cloud-hosted providers that remain available in the admin provider list.-- `tenki`: Cloud-hosted provider that runs each execution in a disposable [Tenki](https://tenki.cloud) microVM. See [Tenki](#tenki) below.-- `ucloud_agent_sandbox`: Cloud-hosted provider that runs each execution in a disposable [UCloud Agent Sandbox](https://astraflow.ucloud.cn/docs/agent-sandbox). See [UCloud Agent Sandbox](#ucloud-agent-sandbox) below.--### Tenki--`tenki` runs each code execution in a fresh Tenki microVM and destroys it afterwards. It is cloud-hosted, so it needs no local sandbox services, gVisor, or Docker base images — only outbound network access and an API key.--The `tenki` SDK is an optional dependency (it requires `protobuf>=6.31`, which differs from RAGFlow's default gRPC stack), so it is not installed by default. Install it into the RAGFlow runtime before selecting this provider:--```bash-pip install tenki-```--Configure it in **Admin > Sandbox Settings**:--- `api_key` (required): Tenki API key. Create one at [app.tenki.cloud](https://app.tenki.cloud) under **API Keys**.-- `base_url` (optional): override the Tenki API endpoint.-- `image` (optional): sandbox base image. Leave empty to use the Tenki default image, which includes `python3` and `node`.-- `allow_outbound` (optional, security-relevant): whether the sandbox may make outbound network connections. Defaults to `false` so sandboxed code has no network access; set it to `true` when code needs the network (for example, to install packages).-- `timeout`, `max_lifetime`, `cpu_cores`, `memory_mb`, `disk_size_gb`, and the output/artifact limits have sensible defaults and can be tuned in the same page.--Notes:--- Supported languages are Python and JavaScript.-- Files written to the `artifacts/` directory of the working directory are returned as run artifacts.-- The provider uses only Tenki's create/exec/destroy operations; it does not use volumes or snapshots.--### UCloud Agent Sandbox--`ucloud_agent_sandbox` uses UCloud's native Sandbox SDK to create one disposable sandbox for each CodeExec run. No local sandbox service or Docker runtime is required.--Configure it in **Admin > Sandbox Settings**:--- `api_key` (required): obtain one from [UCloud ModelVerse API Keys](https://astraflow.ucloud.cn/modelverse/api-keys).-- `region`: defaults to `cn-wlcb`; `us-ca` is also supported.-- `domain` and `api_url`: optional endpoint overrides for private or custom deployments.-- `template`: defaults to `base`, which includes Python and Node.js runtimes.-- `allow_internet_access`: defaults to `false`; enable it only when sandboxed code needs outbound network access.-- `timeout`, `sandbox_timeout`, and the output/artifact limits can be tuned for the workload.--Notes:--- Supported languages are Python and JavaScript.-- RAGFlow uses HTTPS with TLS certificate verification. The `insecure_http` option is intended only for trusted test deployments.-- Files written to the execution workspace's `artifacts/` directory are returned as run artifacts.-- The Python runtime dependency is installed with RAGFlow. The Go runtime uses UCloud's native Go SDK.--See [UCloud Agent Sandbox prerequisites](https://astraflow.ucloud.cn/docs/agent-sandbox/product/prerequisites) and [regions](https://astraflow.ucloud.cn/docs/agent-sandbox/product/region).--## Prerequisites--- Linux distribution compatible with gVisor.-- gVisor installed and configured.-- Docker version 25.0 or higher (API 1.44+). Ensure your executor manager image ships with Docker CLI `29.1.0` or higher to stay compatible with the latest Docker daemons.-- Docker Compose version 2.26.1 or higher (similar to RAGFlow requirements).-- uv package and project manager installed.-- (Optional) GNU Make for simplified command-line management.--:::tip NOTE-The error message `client version 1.43 is too old. Minimum supported API version is 1.44` indicates that your executor manager image's built-in Docker CLI version is lower than `29.1.0` required by the Docker daemon in use.-:::--## Build Docker Base Images--The sandbox uses isolated base images for secure containerized execution environments.--### Option 1: Build from Source--Build the runtime base images:--```bash-docker build -t sandbox-base-python:latest ./sandbox_base_image/python-docker build -t sandbox-base-nodejs:latest ./sandbox_base_image/nodejs-```--Alternatively, build all base images at once using the Makefile:--```bash-make build-```--Build the executor manager image:--```bash-docker build -t sandbox-executor-manager:latest ./executor_manager-```--### Option 2: Pull Base Images from Docker Hub--If you do not need to customize runtime dependencies, pull the published base images and tag them with the names used by standalone Docker Compose:--```bash-docker pull infiniflow/sandbox-base-python:latest-docker pull infiniflow/sandbox-base-nodejs:latest--docker tag infiniflow/sandbox-base-python:latest sandbox-base-python:latest-docker tag infiniflow/sandbox-base-nodejs:latest sandbox-base-nodejs:latest-```--Then restart the standalone sandbox services:--```bash-docker compose -f docker-compose.yml down-docker compose -f docker-compose.yml up -d-```--## Running with RAGFlow--1. Verify that gVisor is properly installed and operational.--2. Configure the .env file located at docker/.env:--- Set `SANDBOX_ENABLED=1`.-- Include `sandbox` in `COMPOSE_PROFILES` if you want the default- `self_managed` executor-manager service.-- Keep the self-managed deployment defaults in `.env` if you need to change the- sandbox-executor-manager image, pool size, base images, seccomp, memory, or- timeout.--3. Add the following entry to your /etc/hosts file to resolve the executor manager service:-- ```bash- 127.0.0.1 es01 infinity mysql minio redis sandbox-executor-manager- ```--4. Start the RAGFlow service as usual.-5. Open **Admin > Sandbox Settings**.-6. Select a provider.-7. Fill in the required fields.-8. Click **Save**.-9. Click **Test Connection** if needed.--## Environment Variables--The variables in `docker/.env` are grouped by scope.--### System-Level Variables--These variables apply to sandbox support in general:--- `SANDBOX_ENABLED`: Enables sandbox support in RAGFlow.-- `COMPOSE_PROFILES`: Include `sandbox` to start the default self-managed executor-manager service.-- `SANDBOX_ARTIFACT_BUCKET`: MinIO bucket used for files generated by sandbox code.-- `SANDBOX_ARTIFACT_EXPIRE_DAYS`: Number of days before sandbox artifacts expire.--### Self-Managed Deployment Defaults--These variables are shown in Admin as deployment defaults for `self_managed`.-Changing them requires restarting `sandbox-executor-manager`.--- `SANDBOX_EXECUTOR_MANAGER_IMAGE`: Docker image for the executor manager service.-- `SANDBOX_EXECUTOR_MANAGER_POOL_SIZE`: Number of Python and Node.js sandbox containers kept in the pool.-- `SANDBOX_BASE_PYTHON_IMAGE`: Python runtime image used by executor-managed containers.-- `SANDBOX_BASE_NODEJS_IMAGE`: Node.js runtime image used by executor-managed containers.-- `SANDBOX_EXECUTOR_MANAGER_PORT`: Host port exposed by the executor manager.-- `SANDBOX_ENABLE_SECCOMP`: Enables the optional seccomp profile for sandbox containers.-- `SANDBOX_MAX_MEMORY`: Memory limit for each sandbox runtime container.-- `SANDBOX_TIMEOUT`: Default execution timeout.--### Admin-Managed Runtime Settings--Provider selection and runtime settings are configured in **Admin > Sandbox Settings**.--Examples:--- Choose the active provider-- Configure `self_managed` runtime settings-- Configure all `local` settings-- Configure all `ssh` settings--For `self_managed`:--- Runtime settings are editable in Admin-- Deployment defaults come from `.env` and are shown as read-only values--## Running Standalone--### Manual Setup--1. Initialize the environment variables:-- ```bash- cp .env.example .env- ```--2. Launch the sandbox services with Docker Compose:-- ```bash- docker compose -f docker-compose.yml up- ```--3. Test the sandbox setup:-- ```bash- source .venv/bin/activate- export PYTHONPATH=$(pwd)- uv pip install -r executor_manager/requirements.txt- uv run tests/sandbox_security_tests_full.py- ```--### Using Makefile--Run all setup, build, launch, and tests with a single command:--```bash-make-```--### Monitoring--To follow logs of the executor manager container:--```bash-docker logs -f sandbox-executor-manager-```--Or use the Makefile shortcut:--```bash-make logs-```diff --git a/docs/guides/dataset/advanced/_category_.json b/docs/guides/dataset/advanced/_category_.jsondeleted file mode 100644index a71322d2ba..0000000000--- a/docs/guides/dataset/advanced/_category_.json+++ /dev/null@@ -1,11 +0,0 @@-{- "label": "Advanced Enrichment",- "position": 8,- "link": {- "type": "generated-index",- "description": "Advanced enrichment."- },- "customProps": {- "categoryIcon": "LucideFlower"- }-}diff --git a/docs/guides/dataset/advanced/auto_metadata.md b/docs/guides/dataset/advanced/auto_metadata.mddeleted file mode 100644index ea8f03781e..0000000000--- a/docs/guides/dataset/advanced/auto_metadata.md+++ /dev/null@@ -1,52 +0,0 @@-----sidebar_position: 4-title: Auto-Extract Metadata-sidebar_label: Auto-Extract Metadata-slug: /auto_metadata-sidebar_custom_props: {- categoryIcon: LucideFileCodeCorner-}-----# Auto-Extract Metadata--Automatically extract metadata from uploaded files.-------RAGFlow v0.23.0 introduces the Auto-metadata feature, which uses large language models to automatically extract and generate metadata for files—eliminating the need for manual entry. In a typical RAG pipeline, metadata serves two key purposes:--- During the retrieval stage: Filters out irrelevant documents, narrowing the search scope to improve retrieval accuracy.-- During the generation stage: If a text chunk is retrieved, its associated metadata is also passed to the LLM, providing richer contextual information about the source document to aid answer generation.---:::danger WARNING-Enabling TOC extraction requires significant memory, computational resources, and tokens.-:::----## Procedure--1. On your dataset's **Configuration** page, select an indexing model, which will be used to generate the knowledge graph, RAPTOR, auto-metadata, auto-keyword, and auto-question features for this dataset.--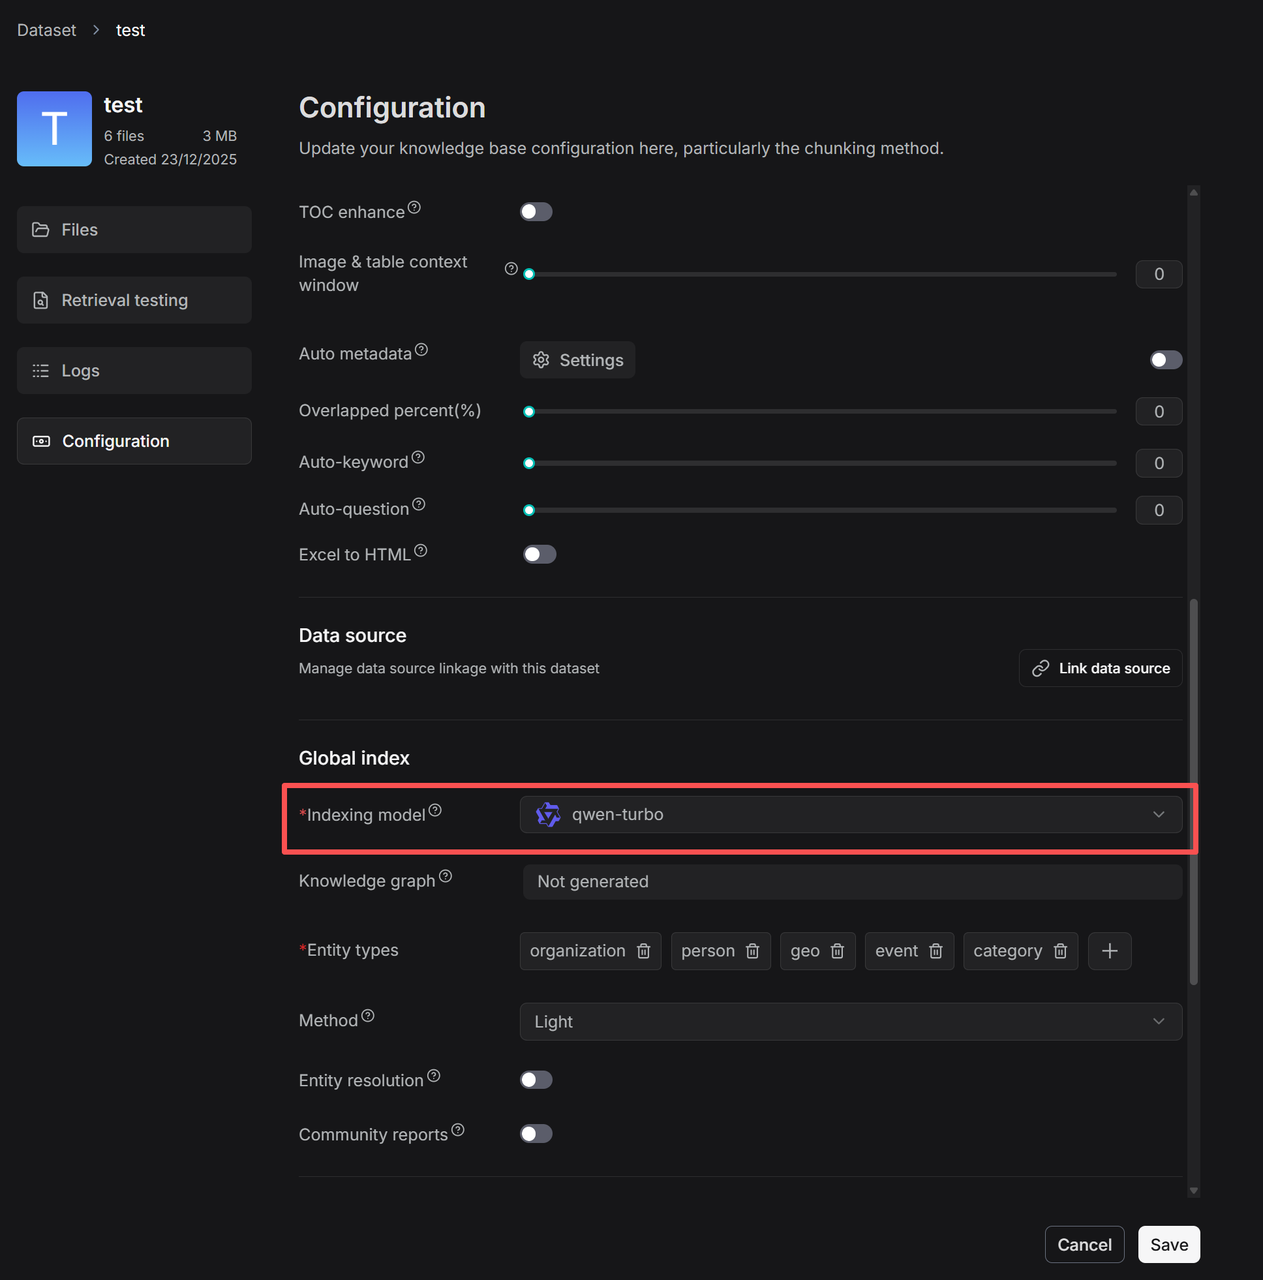---2. Click **Auto metadata** **>** **Settings** to go to the configuration page for automatic metadata generation rules.-- _The configuration page for rules on automatically generating metadata appears._--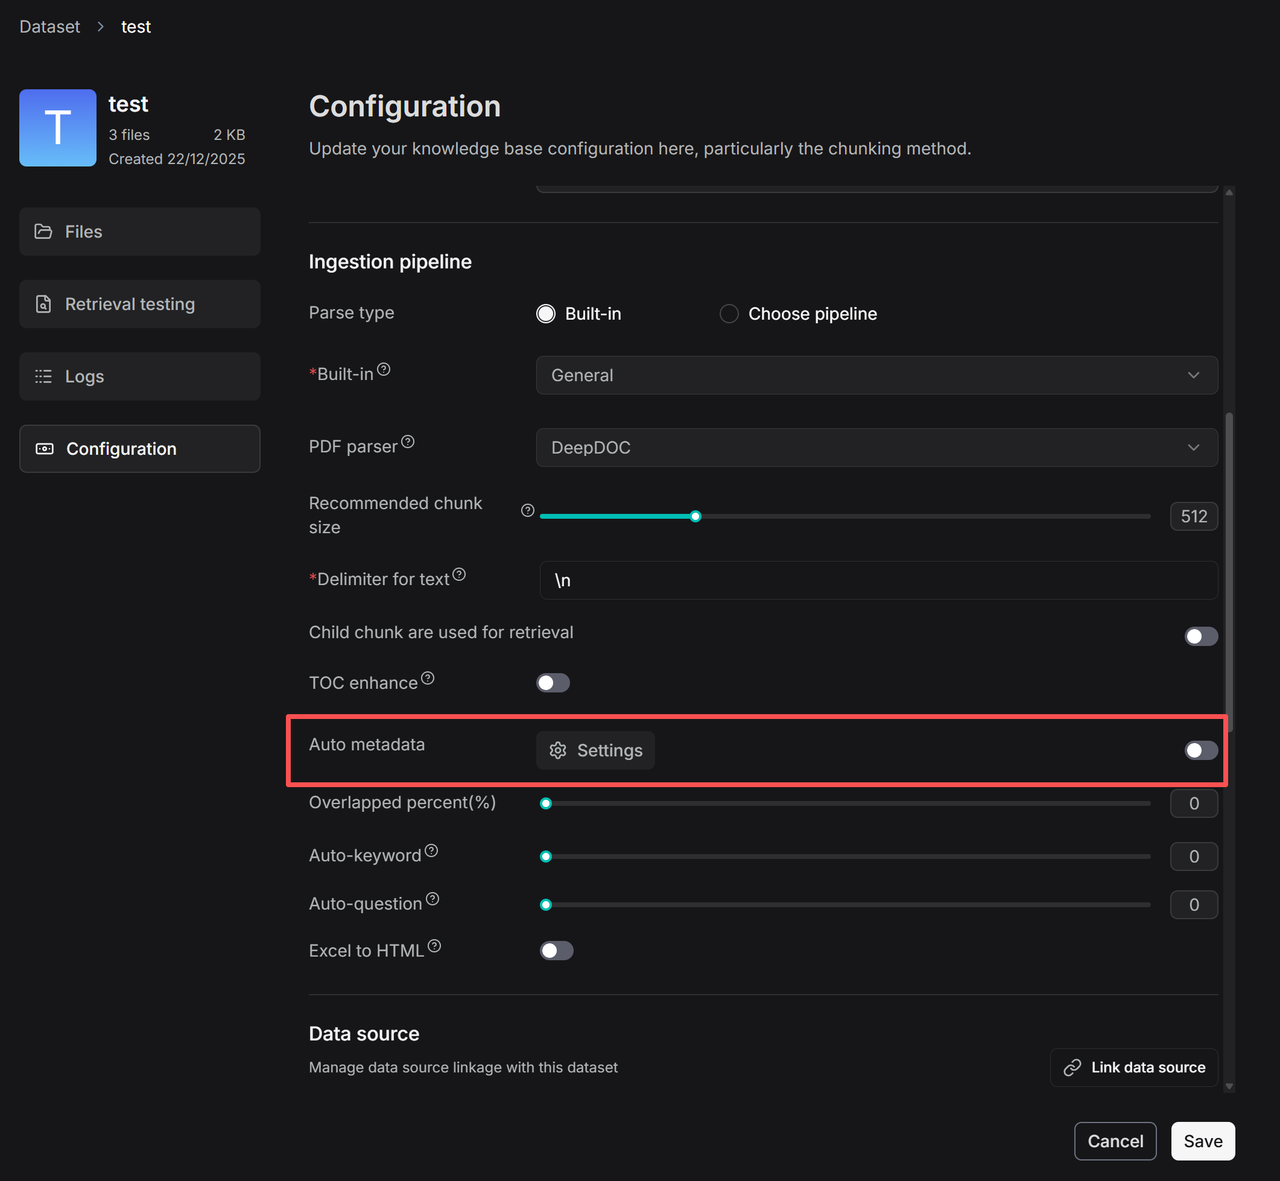--3. Click **+** to add new fields and enter the configuration page.--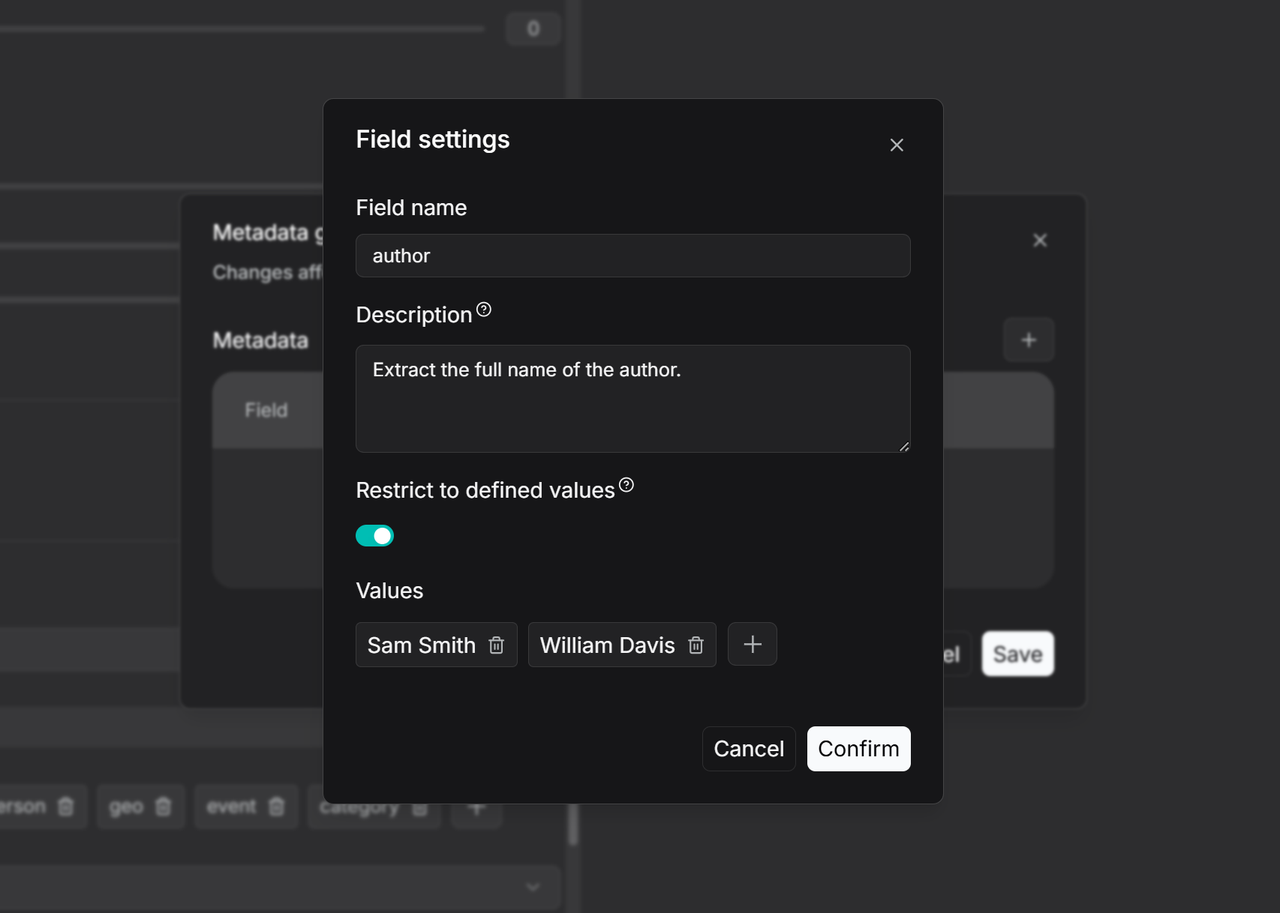--4. Enter a field name, such as Author, and add a description and examples in the Description section. This provides context to the large language model (LLM) for more accurate value extraction. If left blank, the LLM will extract values based only on the field name.--5. To restrict the LLM to generating metadata from a predefined list, enable the Restrict to defined values mode and manually add the allowed values. The LLM will then only generate results from this preset range.--6. Once configured, turn on the Auto-metadata switch on the Configuration page. All newly uploaded files will have these rules applied during parsing. For files that have already been processed, you must re-parse them to trigger metadata generation. You can then use the filter function to check the metadata generation status of your files.--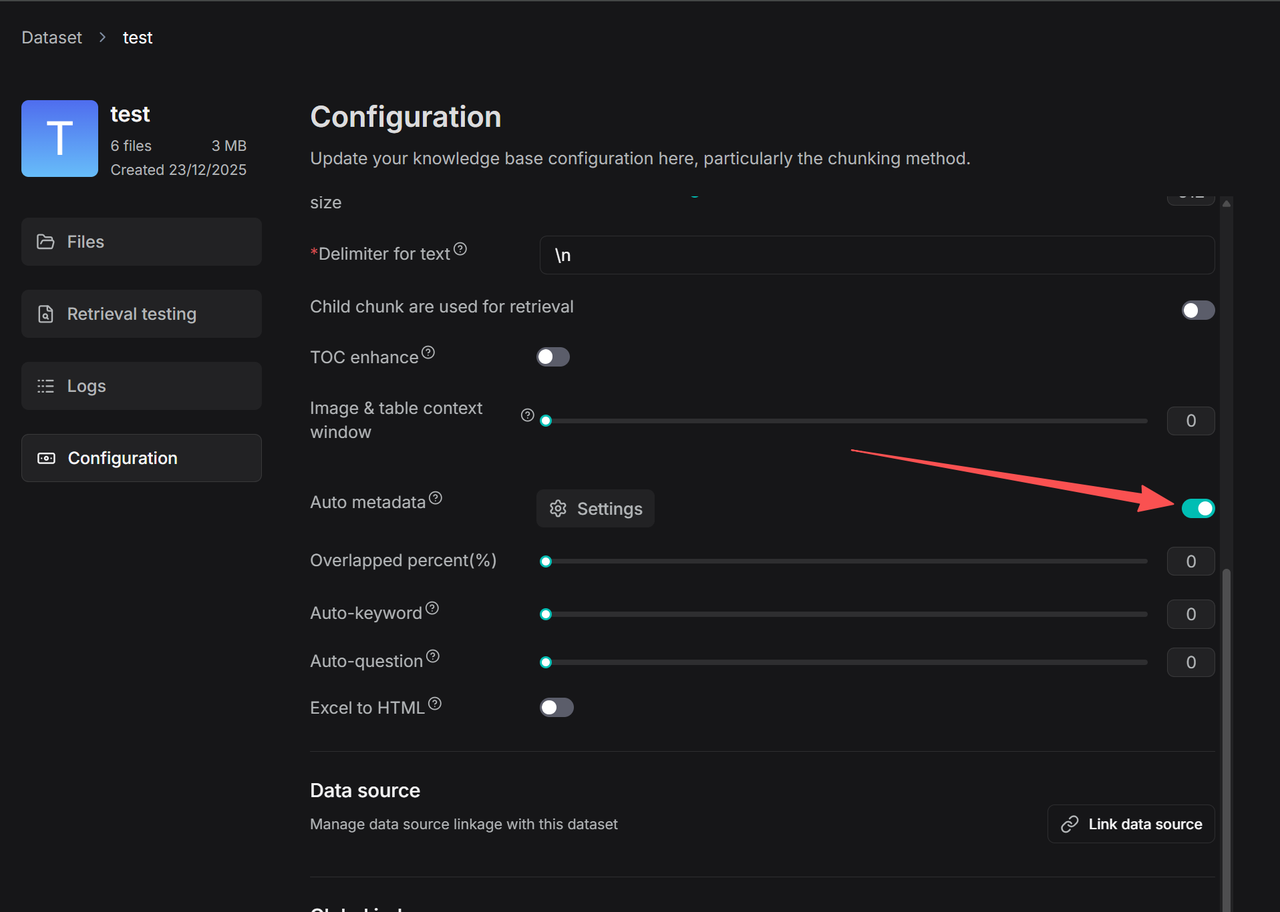-diff --git a/docs/guides/dataset/advanced/autokeyword_autoquestion.mdx b/docs/guides/dataset/advanced/autokeyword_autoquestion.mdxdeleted file mode 100644index 907ed87298..0000000000--- a/docs/guides/dataset/advanced/autokeyword_autoquestion.mdx+++ /dev/null@@ -1,76 +0,0 @@-----sidebar_position: 0-title: Auto-Keyword Auto-Question-sidebar_label: Auto-Keyword Auto-Question-slug: /autokeyword_autoquestion-sidebar_custom_props: {- categoryIcon: LucideSlidersHorizontal-}-----# Auto-Keyword Auto-Question-import APITable from '@site/src/components/APITable';--Use a chat model to generate keywords or questions from each chunk in the dataset.-------When selecting a chunking method, you can also enable auto-keyword or auto-question generation to increase retrieval rates. This feature uses a chat model to produce a specified number of keywords and questions from each created chunk, generating an "additional layer of information" from the original content.--:::caution WARNING-Enabling this feature increases document indexing time and uses extra tokens, as all created chunks will be sent to the chat model for keyword or question generation.-:::--## What Is Auto-Keyword?--Auto-keyword refers to the auto-keyword generation feature of RAGFlow. It uses a chat model to generate a set of keywords or synonyms from each chunk to correct errors and enhance retrieval accuracy. This feature is implemented as a slider under **Page rank** on the **Configuration** page of your dataset.--**Values**:--- 0: (Default) Disabled.-- Between 3 and 5 (inclusive): Recommended if you have chunks of approximately 1,000 characters.-- 30 (maximum)--:::tip NOTE-- If your chunk size increases, you can increase the value accordingly. Please note, as the value increases, the marginal benefit decreases.-- An Auto-keyword value must be an integer. If you set it to a non-integer, say 1.7, it will be rounded down to the nearest integer, which in this case is 1.-:::--## What Is Auto-Question?--Auto-question is a feature of RAGFlow that automatically generates questions from chunks of data using a chat model. These questions (e.g. who, what, and why) also help correct errors and improve the matching of user queries. The feature usually works with FAQ retrieval scenarios involving product manuals or policy documents. And you can find this feature as a slider under **Page rank** on the **Configuration** page of your dataset.--**Values**:--- 0: (Default) Disabled.-- 1 or 2: Recommended if you have chunks of approximately 1,000 characters.-- 10 (maximum)--:::tip NOTE-- If your chunk size increases, you can increase the value accordingly. Please note, as the value increases, the marginal benefit decreases.-- An Auto-question value must be an integer. If you set it to a non-integer, say 1.7, it will be rounded down to the nearest integer, which in this case is 1.-:::--## Tips from the Community--The Auto-keyword or Auto-question values relate closely to the chunking size in your dataset. However, if you are new to this feature and unsure which value(s) to start with, the following are some value settings we gathered from our community. While they may not be accurate, they provide a starting point at the very least.--```mdx-code-block-<APITable>-```--| Use cases or typical scenarios | Document volume/length | Auto_keyword (0–30) | Auto_question (0–10) |-|---------------------------------------------------------------------|---------------------------------|----------------------------|----------------------------|-| Internal process guidance for employee handbook | Small, under 10 pages | 0 | 0 |-| Customer service FAQs | Medium, 10–100 pages | 3–7 | 1–3 |-| Technical white papers: Development standards, protocol details | Large, over 100 pages | 2–4 | 1–2 |-| Contracts / Regulations / Legal clause retrieval | Large, over 50 pages | 2–5 | 0–1 |-| Multi-repository layered new documents + old archive | Many | Adjust as appropriate |Adjust as appropriate |-| Social media comment pool: multilingual & mixed spelling | Very large volume of short text | 8–12 | 0 |-| Operational logs for troubleshooting | Very large volume of short text | 3–6 | 0 |-| Marketing asset library: multilingual product descriptions | Medium | 6–10 | 1–2 |-| Training courses / eBooks | Large | 2–5 | 1–2 |-| Maintenance manual: equipment diagrams + steps | Medium | 3–7 | 1–2 |--```mdx-code-block-</APITable>-```diff --git a/docs/guides/dataset/advanced/construct_knowledge_graph.md b/docs/guides/dataset/advanced/construct_knowledge_graph.mddeleted file mode 100644index 4769bb74ac..0000000000--- a/docs/guides/dataset/advanced/construct_knowledge_graph.md+++ /dev/null@@ -1,105 +0,0 @@-----sidebar_position: 1-title: Construct Knowledge Graph-sidebar_label: Construct Knowledge Graph-slug: /construct_knowledge_graph-sidebar_custom_props: {- categoryIcon: LucideWandSparkles-}-----# Construct Knowledge Graph--Generate a knowledge graph for your dataset.-------To enhance multi-hop question-answering, RAGFlow adds a knowledge graph construction step between data extraction and indexing. This step creates additional chunks from existing ones generated by your specified chunking method.---From v0.16.0 onward, RAGFlow supports constructing a knowledge graph on a dataset, allowing you to construct a *unified* graph across multiple files within your dataset. When a newly uploaded file starts parsing, the generated graph will automatically update.--:::danger WARNING-Constructing a knowledge graph requires significant memory, computational resources, and tokens.-:::--## Scenarios--Knowledge graphs are especially useful for multi-hop question-answering involving *nested* logic. They outperform traditional extraction approaches when you are performing question answering on books or works with complex entities and relationships.--:::tip NOTE-RAPTOR (Recursive Abstractive Processing for Tree Organized Retrieval) can also be used for multi-hop question-answering tasks. See [Enable RAPTOR](./enable_raptor.md) for details. You may use either approach or both, but ensure you understand the memory, computational, and token costs involved.-:::--## Prerequisites--The system's default chat model is used to generate knowledge graph. Before proceeding, ensure that you have a chat model properly configured:--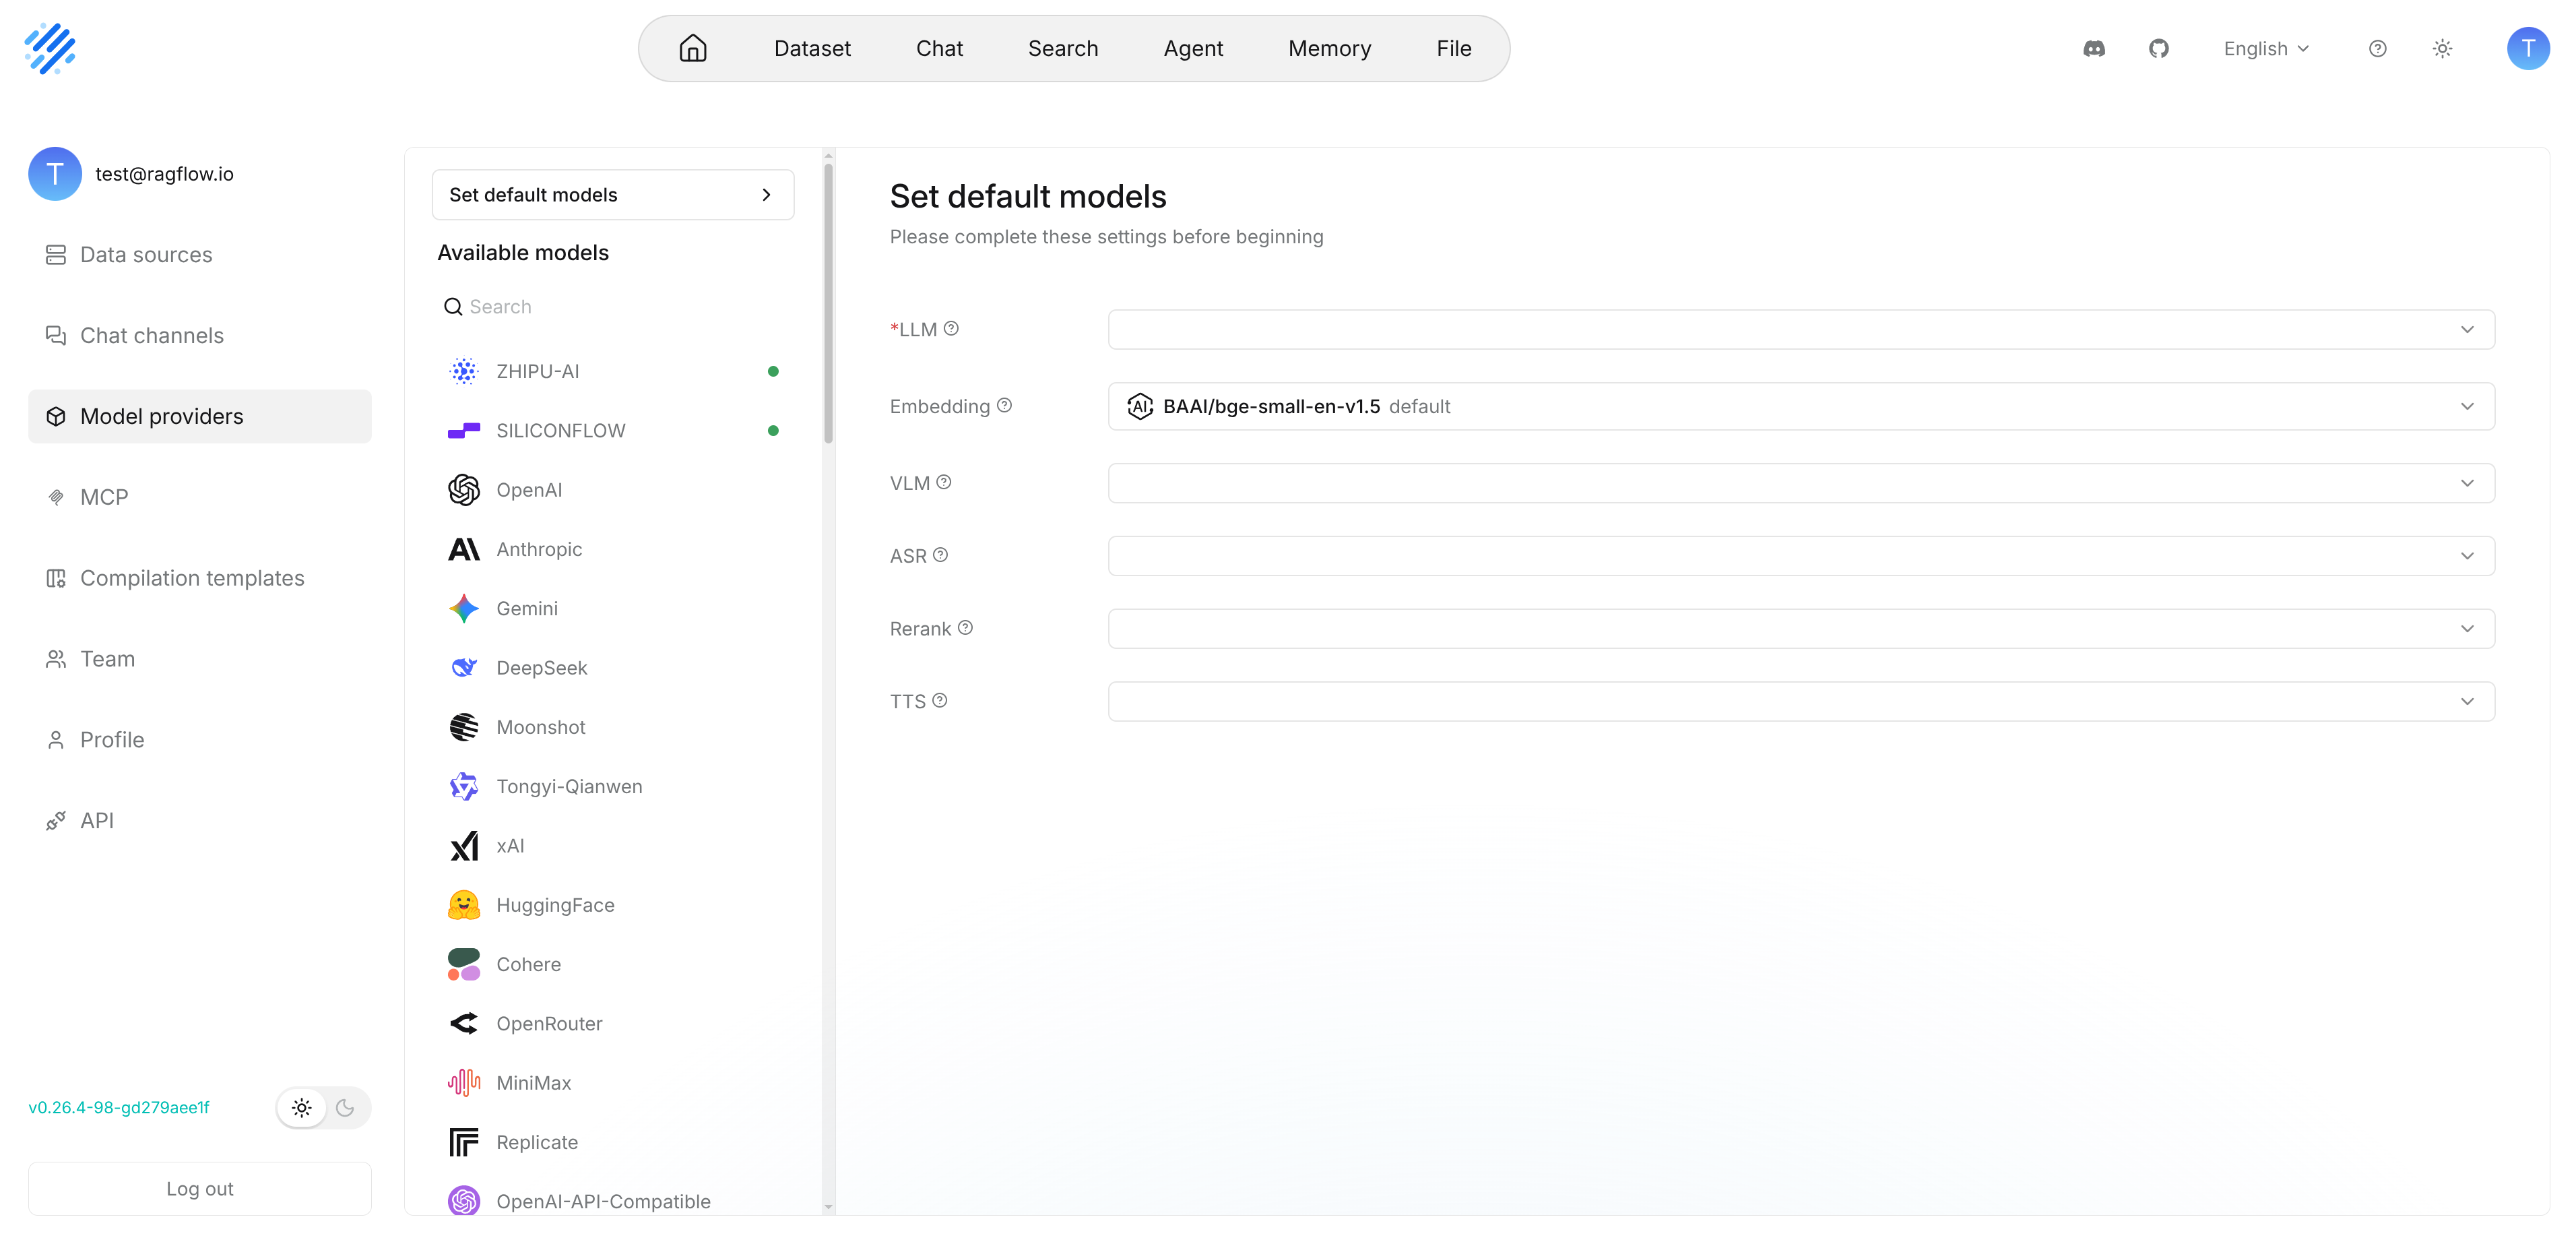--## Configurations--### Entity Types (*Required*)--The types of the entities to extract from your dataset. The default types are: **organization**, **person**, **event**, and **category**. Add or remove types to suit your specific dataset.--### Method--The method to use to construct knowledge graph:--- **General**: Use prompts provided by [GraphRAG](https://github.com/microsoft/graphrag) to extract entities and relationships.-- **Light**: (Default) Use prompts provided by [LightRAG](https://github.com/HKUDS/LightRAG) to extract entities and relationships. This option consumes fewer tokens, less memory, and fewer computational resources.--### Entity Resolution--Whether to enable entity resolution. You can think of this as an entity deduplication switch. When enabled, the LLM will combine similar entities - e.g., '2025' and 'the year of 2025', or 'IT' and 'Information Technology' - to construct a more effective graph.--- (Default) Disable entity resolution.-- Enable entity resolution. This option consumes more tokens.--### Community Reports--In a knowledge graph, a community is a cluster of entities linked by relationships. You can have the LLM generate an abstract for each community, known as a community report. See [here](https://www.microsoft.com/en-us/research/blog/graphrag-improving-global-search-via-dynamic-community-selection/) for more information. This indicates whether to generate community reports:--- Generate community reports. This option consumes more tokens.-- (Default) Do not generate community reports.--## Quickstart--1. Navigate to the **Configuration** page of your dataset and update:-- - Entity types: *Required* - Specifies the entity types in the knowledge graph to generate. You don't have to stick with the default, but you need to customize them for your documents.- - Method: *Optional*- - Entity resolution: *Optional*- - Community reports: *Optional*- *The default knowledge graph configurations for your dataset are now set.*--2. Navigate to the **Files** page of your dataset, click the **Generate** button on the top right corner of the page, then select **Knowledge graph** from the dropdown to initiate the knowledge graph generation process.-- *You can click the pause button in the dropdown to halt the build process when necessary.*--3. Go back to the **Configuration** page:-- *Once a knowledge graph is generated, the **Knowledge graph** field changes from `Not generated` to `Generated at a specific timestamp`. You can delete it by clicking the recycle bin button to the right of the field.*--4. To use the created knowledge graph, do either of the following:-- - In the **Chat setting** panel of your chat app, switch on the **Use knowledge graph** toggle.- - If you are using an agent, click the **Retrieval** agent component to specify the dataset(s) and switch on the **Use knowledge graph** toggle.--## Frequently Asked Questions--### Does the Knowledge Graph Automatically Update When I Remove a Related File?--Nope. The knowledge graph does *not* update *until* you regenerate a knowledge graph for your dataset.--### How to Remove a Generated Knowledge Graph?--On the **Configuration** page of your dataset, find the **Knowledge graph** field and click the recycle bin button to the right of the field.--### Where Is the Created Knowledge Graph Stored?--All chunks of the created knowledge graph are stored in RAGFlow's document engine: either Elasticsearch or [Infinity](https://github.com/infiniflow/infinity).--### How to Export a Created Knowledge Graph?--Nope. Exporting a created knowledge graph is not supported. If you still consider this feature essential, please [raise an issue](https://github.com/infiniflow/ragflow/issues) explaining your use case and its importance.diff --git a/docs/guides/dataset/advanced/enable_raptor.md b/docs/guides/dataset/advanced/enable_raptor.mddeleted file mode 100644index 916632f5be..0000000000--- a/docs/guides/dataset/advanced/enable_raptor.md+++ /dev/null@@ -1,97 +0,0 @@-----sidebar_position: 2-title: Enable Raptor-sidebar_label: Enable Raptor-slug: /enable_raptor-sidebar_custom_props: {- categoryIcon: LucideNetwork-}-----# Enable Raptor--A recursive abstractive method used in long-context knowledge retrieval and summarization, balancing broad semantic understanding with fine details.-------RAPTOR (Recursive Abstractive Processing for Tree Organized Retrieval) is an enhanced document preprocessing technique introduced in a [2024 paper](https://arxiv.org/html/2401.18059v1). Designed to tackle multi-hop question-answering issues, RAPTOR performs recursive clustering and summarization of document chunks to build a hierarchical tree structure. This enables more context-aware retrieval across lengthy documents. RAGFlow v0.6.0 integrates RAPTOR for document clustering as part of its data preprocessing pipeline between data extraction and indexing, as illustrated below.--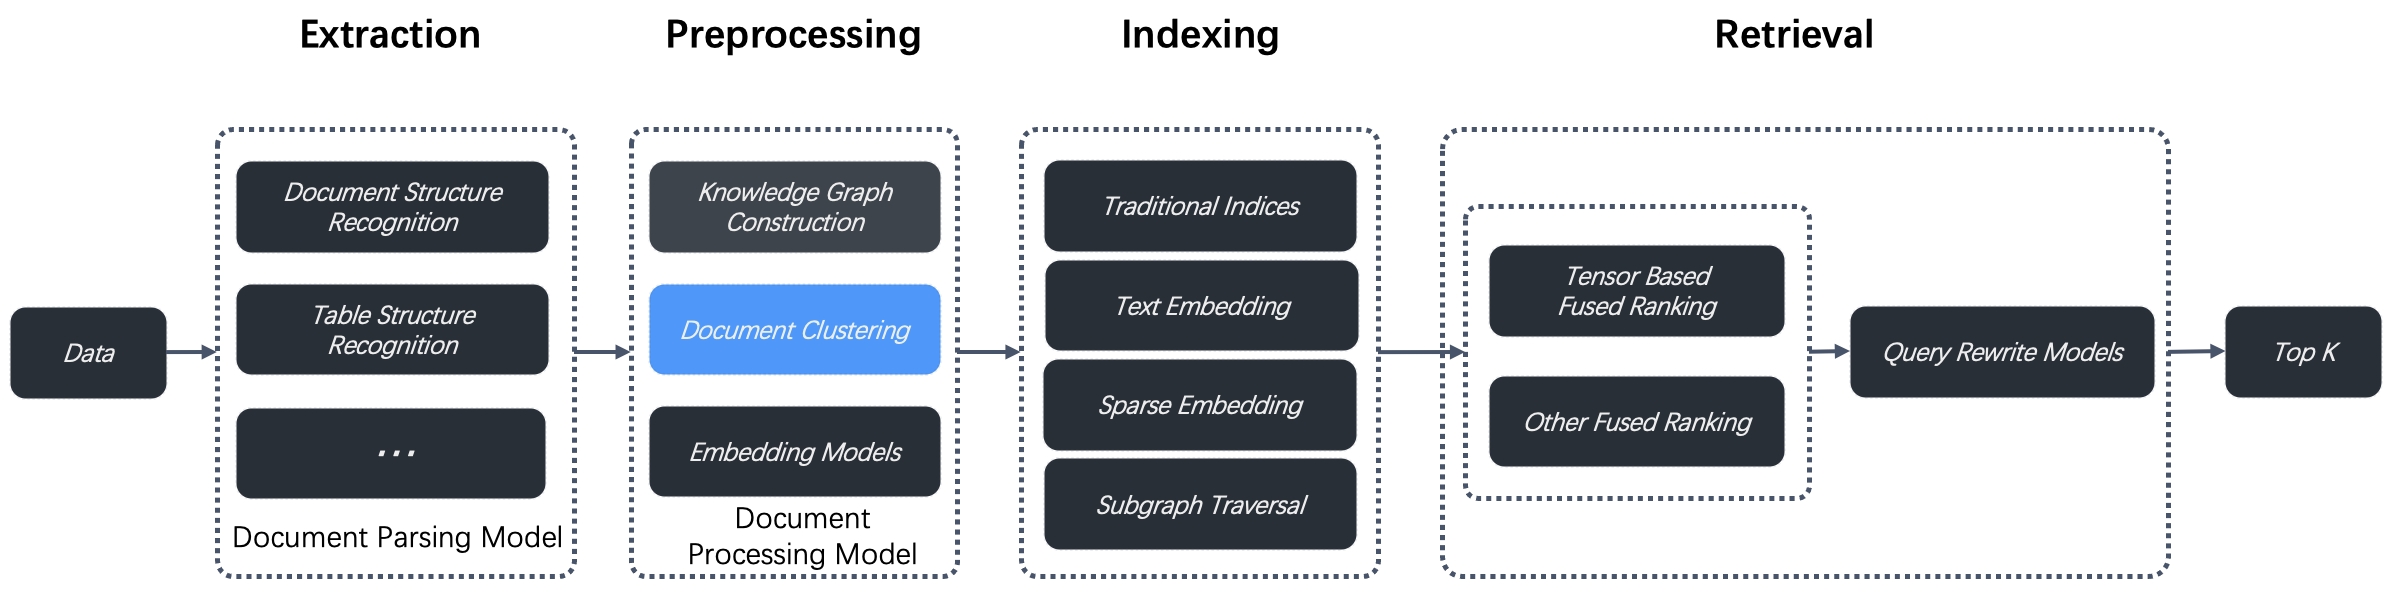--Our tests with this new approach demonstrate state-of-the-art (SOTA) results on question-answering tasks requiring complex, multistep reasoning. By combining RAPTOR retrieval with our built-in chunking methods and/or other retrieval-augmented generation (RAG) approaches, you can further improve your question-answering accuracy.--:::danger WARNING-Enabling RAPTOR requires significant memory, computational resources, and tokens.-:::--## Basic Principles--After the original documents are divided into chunks, the chunks are clustered by semantic similarity rather than by their original order in the text. Clusters are then summarized into higher-level chunks by your system's default chat model. This process is applied recursively, forming a tree structure with various levels of summarization from the bottom up. As illustrated in the figure below, the initial chunks form the leaf nodes (shown in blue) and are recursively summarized into a root node (shown in orange).--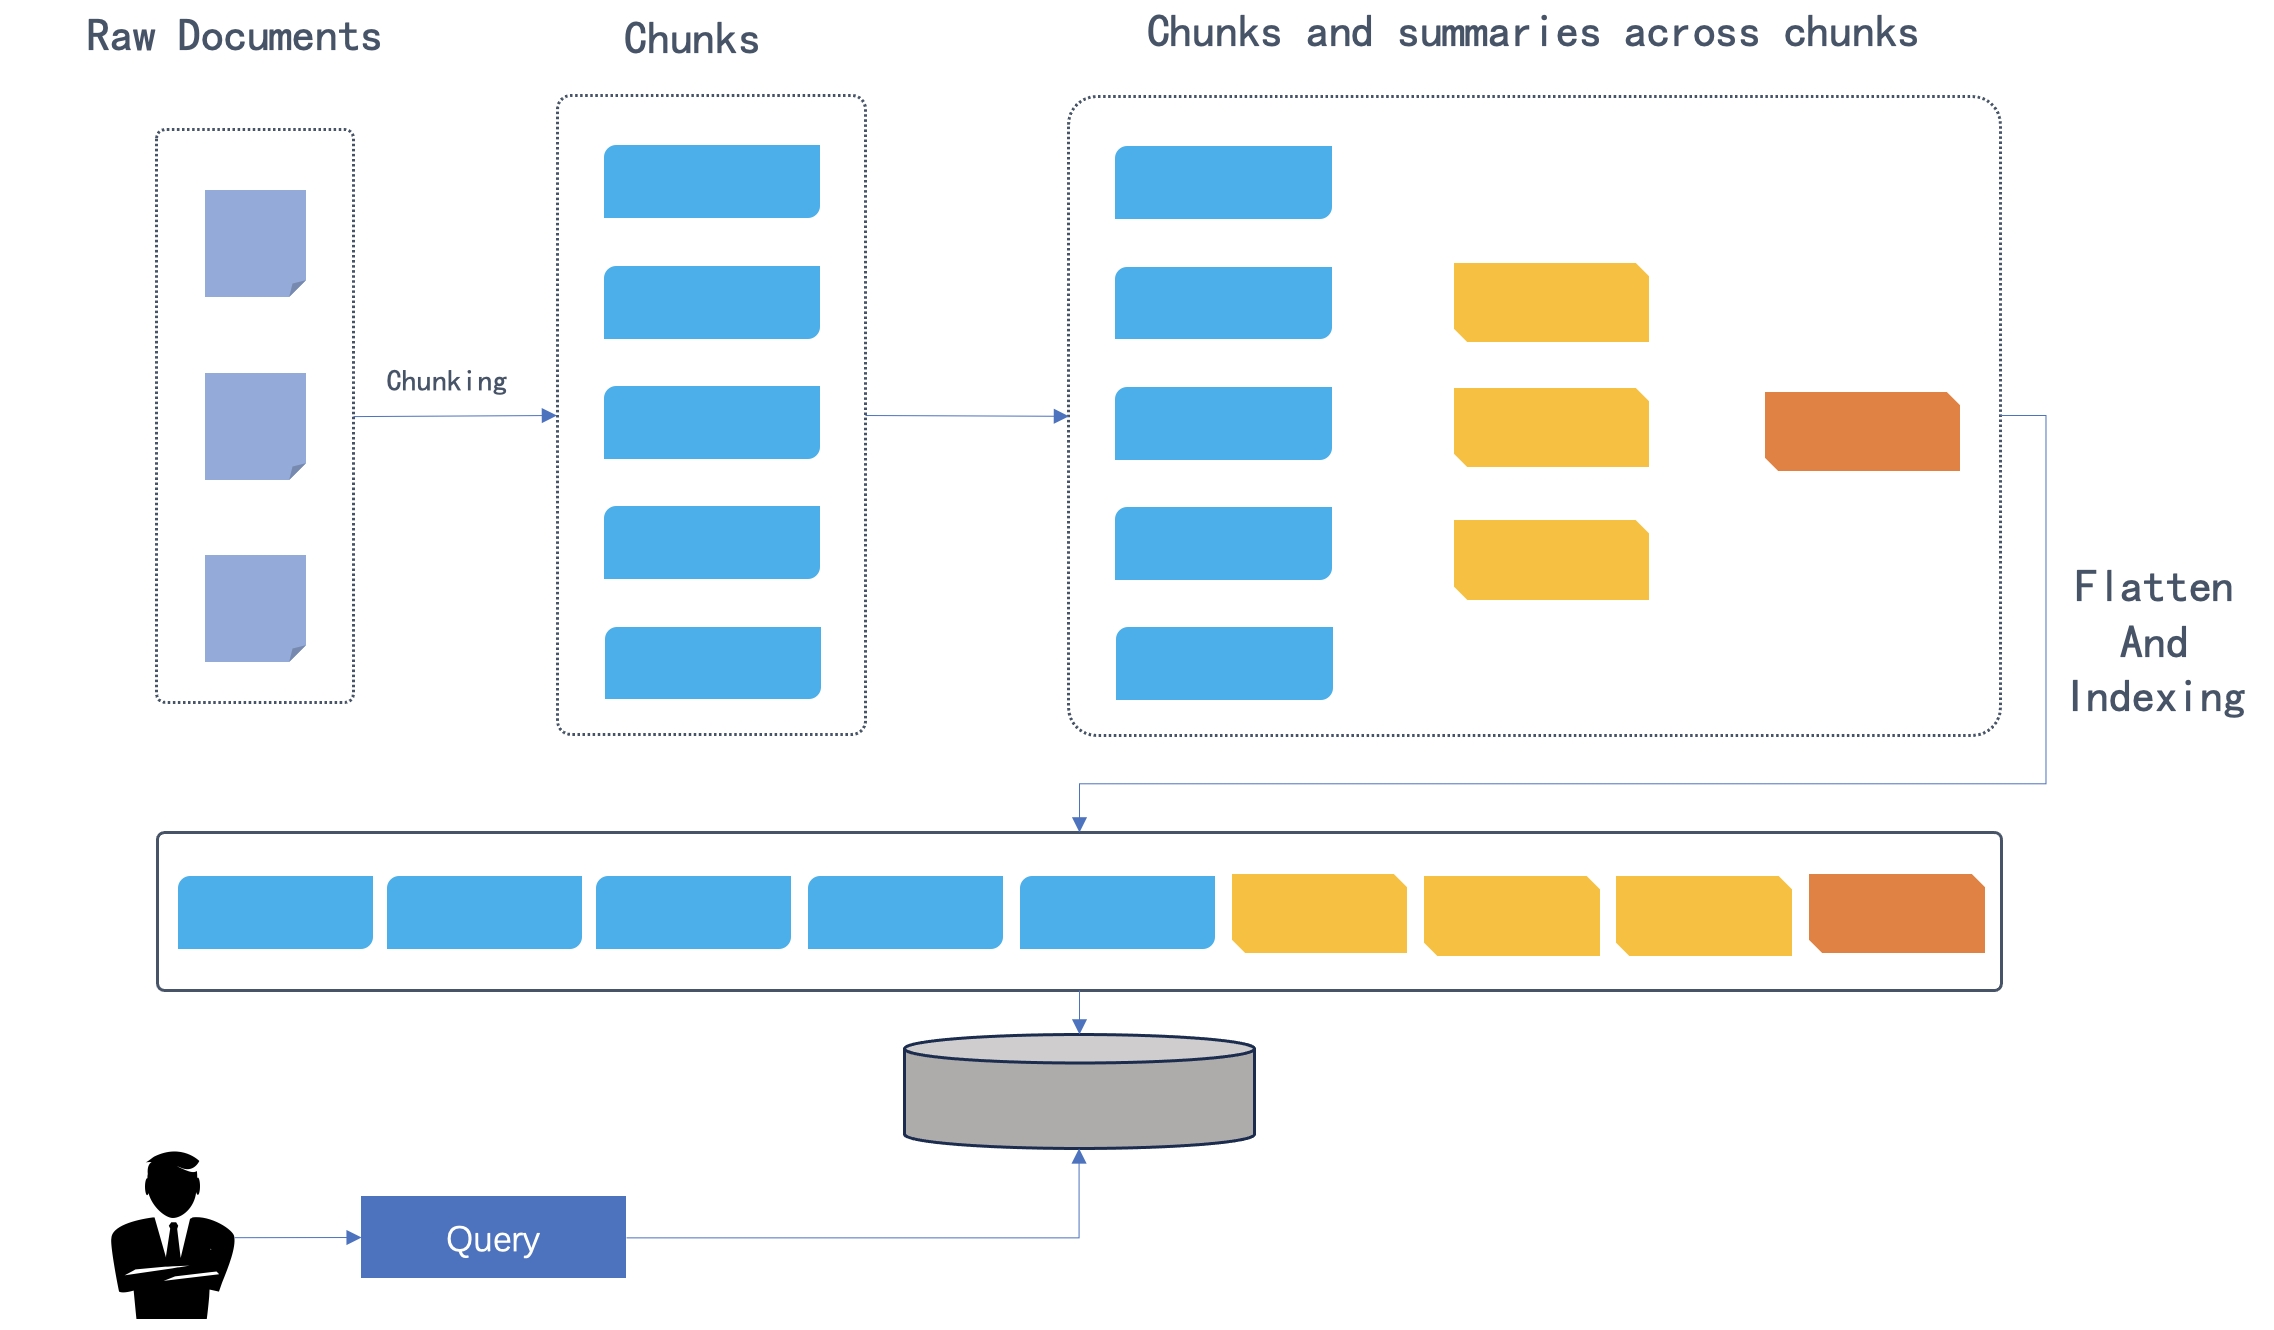--The recursive clustering and summarization capture a broad understanding (by the root node) as well as fine details (by the leaf nodes) necessary for multi-hop question-answering.--## Scenarios--For multi-hop question-answering tasks involving complex, multistep reasoning, a semantic gap often exists between the question and its answer. As a result, searching with the question often fails to retrieve the relevant chunks that contribute to the correct answer. RAPTOR addresses this challenge by providing the chat model with richer and more context-aware and relevant chunks to summarize, enabling a holistic understanding without losing granular details.--:::tip NOTE-Knowledge graphs can also be used for multi-hop question-answering tasks. See [Construct knowledge graph](../advanced/construct_knowledge_graph.md) for details. You may use either approach or both, but ensure you understand the memory, computational, and token costs involved.-:::--## Prerequisites--The system's default chat model is used to summarize clustered content. Before proceeding, ensure that you have a chat model properly configured:----## Configurations--The RAPTOR feature is disabled by default. To enable it, manually switch on the **Use RAPTOR to enhance retrieval** toggle on your dataset's **Configuration** page.--### Prompt--The following prompt will be applied *recursively* for cluster summarization, with `{cluster_content}` serving as an internal parameter. We recommend that you keep it as-is for now. The design will be updated in due course.--```-Please summarize the following paragraphs... Paragraphs as following:- {cluster_content}-The above is the content you need to summarize.-```--### Max Token--The maximum number of tokens per generated summary chunk. Defaults to 256, with a maximum limit of 2048.--### Threshold--In RAPTOR, chunks are clustered by their semantic similarity. The **Threshold** parameter sets the minimum similarity required for chunks to be grouped together.--It defaults to 0.1, with a maximum limit of 1. A higher **Threshold** means fewer chunks in each cluster, while a lower one means more.--### Max Cluster--The maximum number of clusters to create. Defaults to 64, with a maximum limit of 1024.--### Random Seed--A random seed. Click **+** to change the seed value.--## Quickstart--1. Navigate to the **Configuration** page of your dataset and update:-- - Prompt: *Optional* - We recommend that you keep it as-is until you understand the mechanism behind.- - Max token: *Optional*- - Threshold: *Optional*- - Max cluster: *Optional*--2. Navigate to the **Files** page of your dataset, click the **Generate** button on the top right corner of the page, then select **RAPTOR** from the dropdown to initiate the RAPTOR build process.-- *You can click the pause button in the dropdown to halt the build process when necessary.*--3. Go back to the **Configuration** page:-- *The **RAPTOR** field changes from `Not generated` to `Generated at a specific timestamp` when a RAPTOR hierarchical tree structure is generated. You can delete it by clicking the recycle bin button to the right of the field.*--4. Once a RAPTOR hierarchical tree structure is generated, your chat assistant and **Retrieval** agent component will use it for retrieval as a default.diff --git a/docs/guides/dataset/advanced/extract_table_of_contents.md b/docs/guides/dataset/advanced/extract_table_of_contents.mddeleted file mode 100644index dfe48ddfb2..0000000000--- a/docs/guides/dataset/advanced/extract_table_of_contents.md+++ /dev/null@@ -1,43 +0,0 @@-----sidebar_position: 3-title: Extract Table of Contents-sidebar_label: Extract Table of Contents-slug: /enable_table_of_contents-sidebar_custom_props: {- categoryIcon: LucideTableOfContents-}-----# Extract Table of Contents--Extract PageIndex, namely table of contents, from documents to provide long context RAG and improve retrieval.-------During indexing, this technique uses LLM to extract and generate chapter information, which is added to each chunk to provide sufficient global context. At the retrieval stage, it first uses the chunks matched by search, then supplements missing chunks based on the PageIndex (table of contents) structure. This addresses issues caused by chunk fragmentation and insufficient context, improving answer quality.--:::danger WARNING-Enabling PageIndex extraction requires significant memory, computational resources, and tokens.-:::--## Prerequisites--The system's default chat model is used to summarize clustered content. Before proceeding, ensure that you have a chat model properly configured:----## Quickstart--1. Navigate to the **Configuration** page.--2. Enable **PageIndex**.--3. To use this technique during retrieval, do either of the following:-- - In the **Chat setting** panel of your chat app, switch on the **PageIndex** toggle.- - If you are using an Agent, click the **Retrieval** agent component to specify the dataset(s) and switch on the **PageIndex** toggle.--## Frequently Asked Questions--### Will Previously Parsed Files Be Searched Using the Directory Enhancement Feature Once I Enable `PageIndex`?--No. Only files parsed after you enable **PageIndex** will be searched using the directory enhancement feature. To apply this feature to files parsed before enabling **PageIndex**, you must reparse them.