
RAGFlow is an agent-native database: a Retrieval-Augmented Generation (RAG) engine that grew into context infrastructure.
Go agent-harnessagent-native-databaseagentic-aiagentic-retrievalagentic-searchaiai-agentscontext-enginecontext-engineeringcontext-managementharness-engineeringknowledge-compilationragretrieval-augmented-generationretrieval-harnesssearch-harness
docs: update knowledge compilation docs (#19734)
YanZhang0b7dd3720a72
diff --git a/docs/guides/knowledge_compilation/built_in_templates_and_dedicated_configuration.md b/docs/guides/knowledge_compilation/built_in_templates_and_dedicated_configuration.mdindex c8baba2d10..1e010278dd 100644--- a/docs/guides/knowledge_compilation/built_in_templates_and_dedicated_configuration.md+++ b/docs/guides/knowledge_compilation/built_in_templates_and_dedicated_configuration.md@@ -115,10 +115,19 @@ Configuration recommendations:Example: Summarize the main topics, key events, and important information in the document. Keep the content accurate and do not add information that does not appear in the document.-### Summary Prompt+### Summarization PromptSets the generation rules for node summaries and controls the information and output format the system focuses on when summarizing each node. Users can adjust the summary direction based on actual requirements, such as emphasizing key content, core conclusions, or important information.+#### Claim Extraction Prompt++Defines the system prompt used to extract atomic claims from leaf chunks before clustering.++The extracted claims include supporting evidence from the source chunks and are used to represent the semantic information of the chunks during clustering. This helps reduce the influence of layout or other irrelevant text when grouping related content.++Leave this field empty to use the built-in claim extraction rules. Customize it only when you need domain-specific claim extraction requirements.++### Maximum TokensSets the maximum length for node summary generation. A larger value can preserve more summary information and is suitable for more complex documents. A smaller value can generate more concise summaries and is suitable for quickly viewing a document overview.@@ -131,6 +140,16 @@ Adjusts the matching degree during document content clustering and affects how rAdjusts the content clustering ratio in the Tree structure and affects the number of final hierarchy levels and the structure detail. Increasing this parameter usually generates a richer hierarchy. Decreasing this parameter can reduce the number of nodes and make the overall structure more concise.+#### Re-chunk by Tree Leaves++Determines whether the source chunks belonging to each leaf cluster are merged into a new retrieval chunk.++When enabled, RAGFlow merges the source chunks of each leaf cluster into a single replacement chunk. The original chunks are retained but marked as unavailable for retrieval.++This allows the final retrieval chunks to follow the semantic boundaries identified by the generated Tree instead of the original chunk boundaries.++Only one Tree template in the same template group can enable this option.+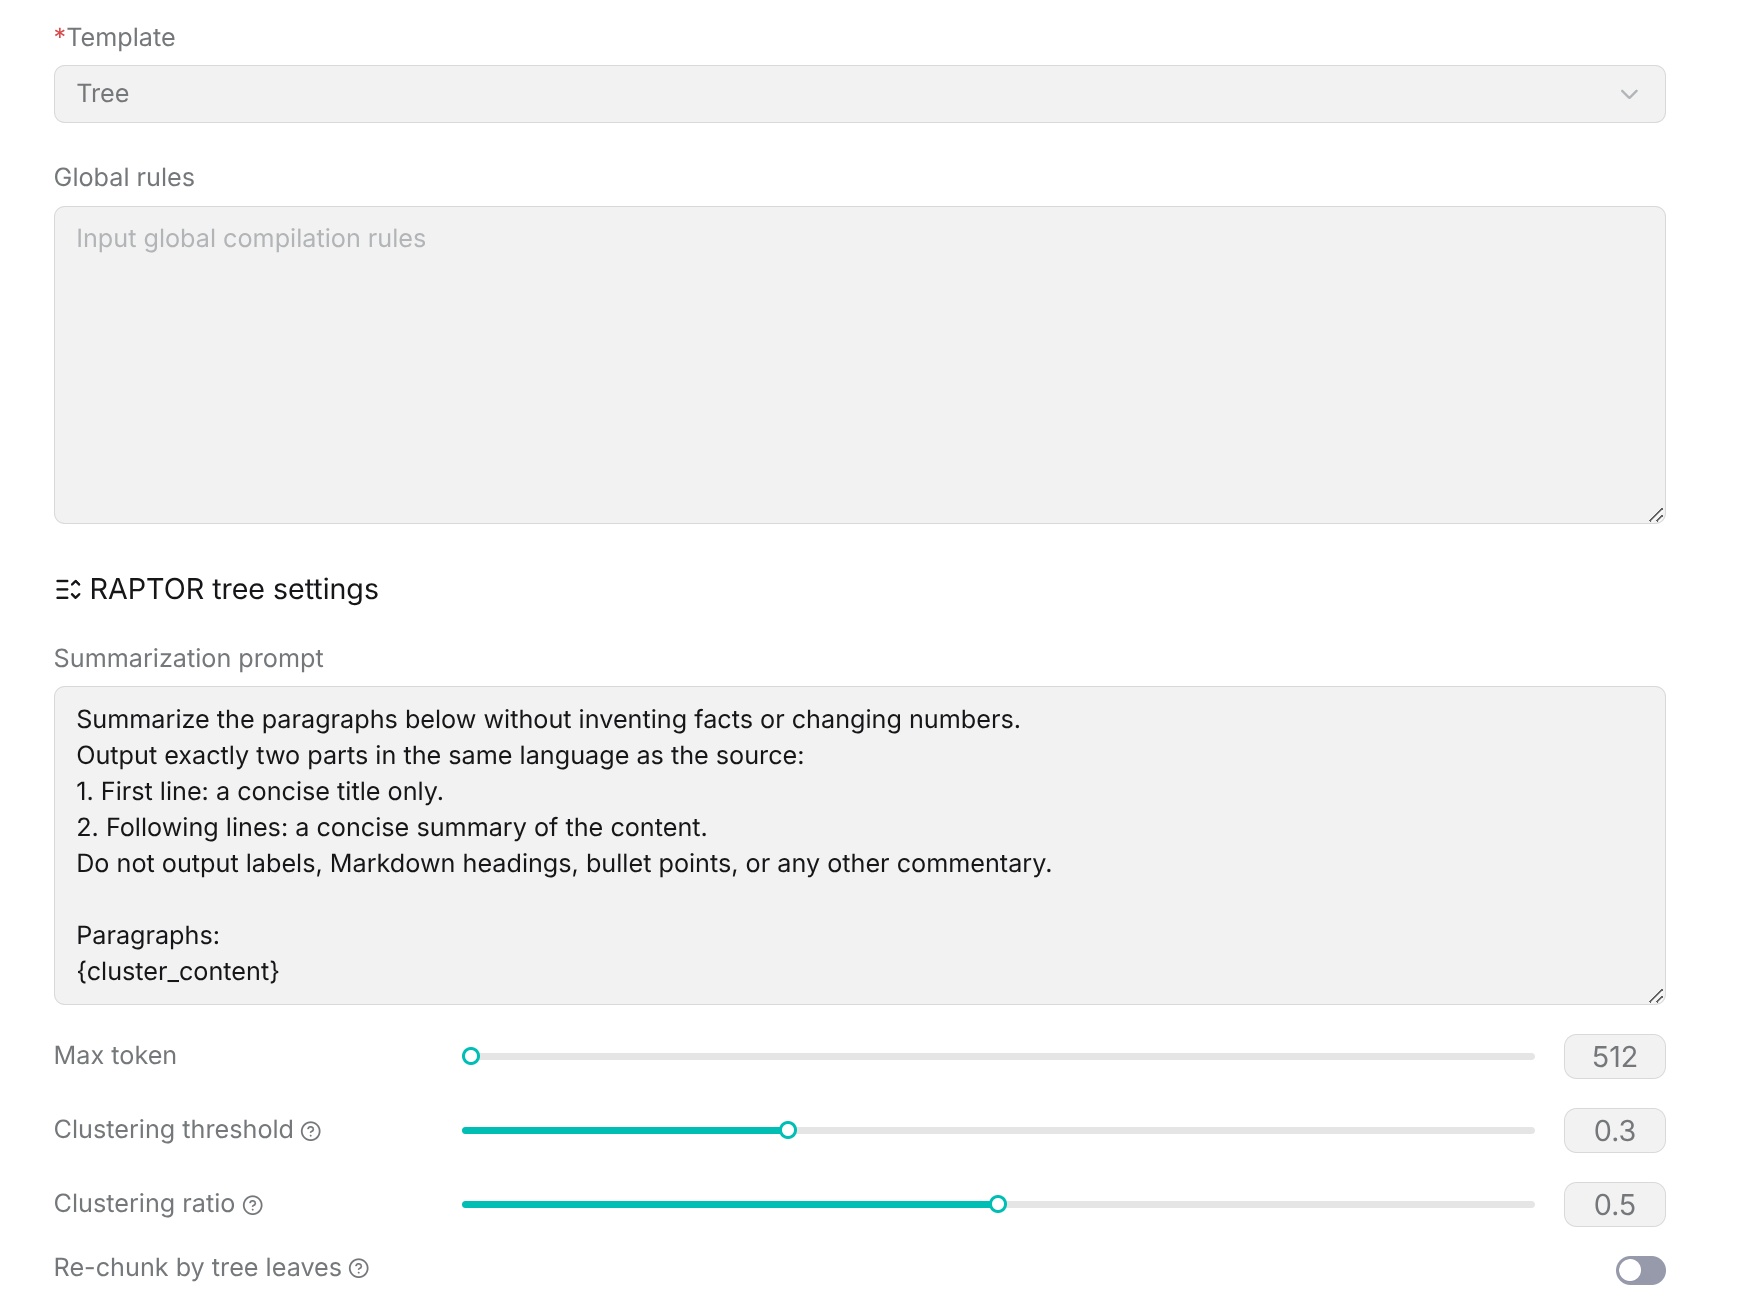## PageIndex@@ -150,6 +169,16 @@ Configuration recommendations:- Extract only key information related to each chapter topic and avoid generating irrelevant content.- For content without clear titles, it is not recommended to force-generate chapter nodes.+### Re-chunk parser output++When **Re-chunk parser output** is enabled, RAGFlow reorganizes the chunks generated by the parser before running PageIndex knowledge compilation according to the configured **Rechunking rules**.++The rechunking process attempts to preserve the original content order, heading hierarchy, and section boundaries while keeping structures such as tables, lists, and code blocks intact. This helps produce input that is better suited for building the hierarchical structure used by PageIndex.++**Rechunking rules** define how parser-generated chunks are reorganized, such as whether adjacent chunks can be merged, how headings should remain associated with their content, and how section boundaries should be preserved.++When this option is disabled, PageIndex uses the original chunks generated by the parser directly for knowledge compilation.+### EntitySpecificationEntitySpecification defines the content fields that PageIndex needs to extract. Different fields record different types of information in chapters. Users can adjust the default fields provided by the system based on requirements, or add new fields.@@ -386,18 +415,13 @@ System default rules include:Users can adjust rules based on business requirements, such as limiting the entity scope to focus on, supplementing domain knowledge, or adjusting page generation requirements.-### Plan--Plan is used to plan and organize document content before generating Wiki content. After Plan is enabled, the system first generates a content plan for the Wiki based on the document content, and then generates the corresponding Wiki content according to the plan, making the generated result more clearly structured.--When creating or editing a Wiki compilation template, you can choose whether to enable Plan.+### Wiki mode-- **Plan enabled**: The system first generates a content plan, and then generates Wiki content according to the plan. This is suitable for documents with substantial content and complex structures that require overall organization of Wiki content.-- **Plan disabled**: The system does not generate a content plan and directly generates Wiki content based on the document content.+Specifies how Wiki pages are organized.-After the configuration is completed and the template is saved, the system follows the current Plan configuration when using this template for knowledge compilation.+- **Entity mode**: Generates Wiki pages by entity or concept. Each identified entity or concept is organized into a separate Wiki page. This mode is suitable for exploring information about individual entities or concepts.-Note: Whether Plan is enabled affects the Wiki content generation flow. For longer documents or documents with complex content structures, it is recommended to enable Plan.+- **Topic mode**: Organizes Wiki pages by topic. The LLM groups related entities or concepts into the same Wiki page based on their relationships and context. This mode is suitable for organizing and exploring knowledge at the topic level.### EntitySpecification