
RAGFlow is an agent-native database: a Retrieval-Augmented Generation (RAG) engine that grew into context infrastructure.
Go agent-harnessagent-native-databaseagentic-aiagentic-retrievalagentic-searchaiai-agentscontext-enginecontext-engineeringcontext-managementharness-engineeringknowledge-compilationragretrieval-augmented-generationretrieval-harnesssearch-harness
docs: Align user guides with current UI and configuration options (#21631)
YanZhang0bf20ebd222d
diff --git a/docs/guides/agent/import_and_export_agents.md b/docs/guides/agent/import_and_export_agents.mdindex eb674e8589..a2163ae23d 100644--- a/docs/guides/agent/import_and_export_agents.md+++ b/docs/guides/agent/import_and_export_agents.md@@ -16,6 +16,8 @@ sidebar_custom_props: {2. Enter **Name** and upload one Agent JSON file under **DSL**.3. Click **Save**, then open the imported Agent to check its configuration.+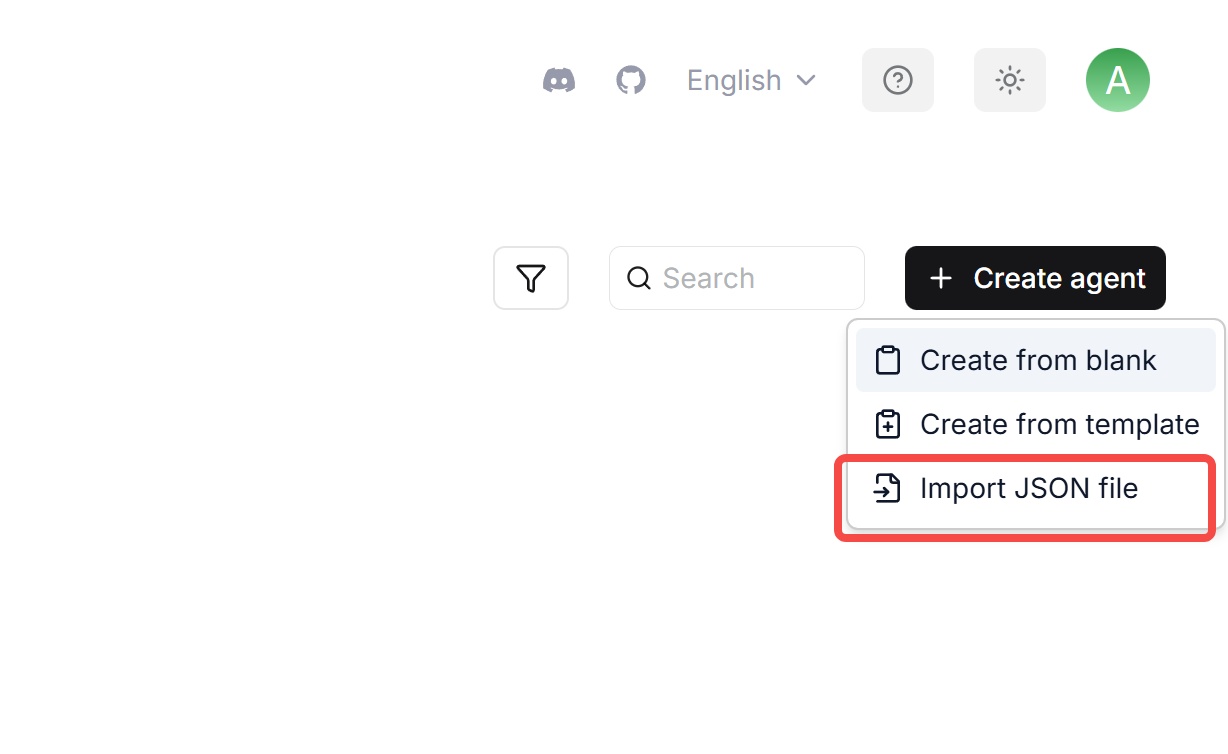+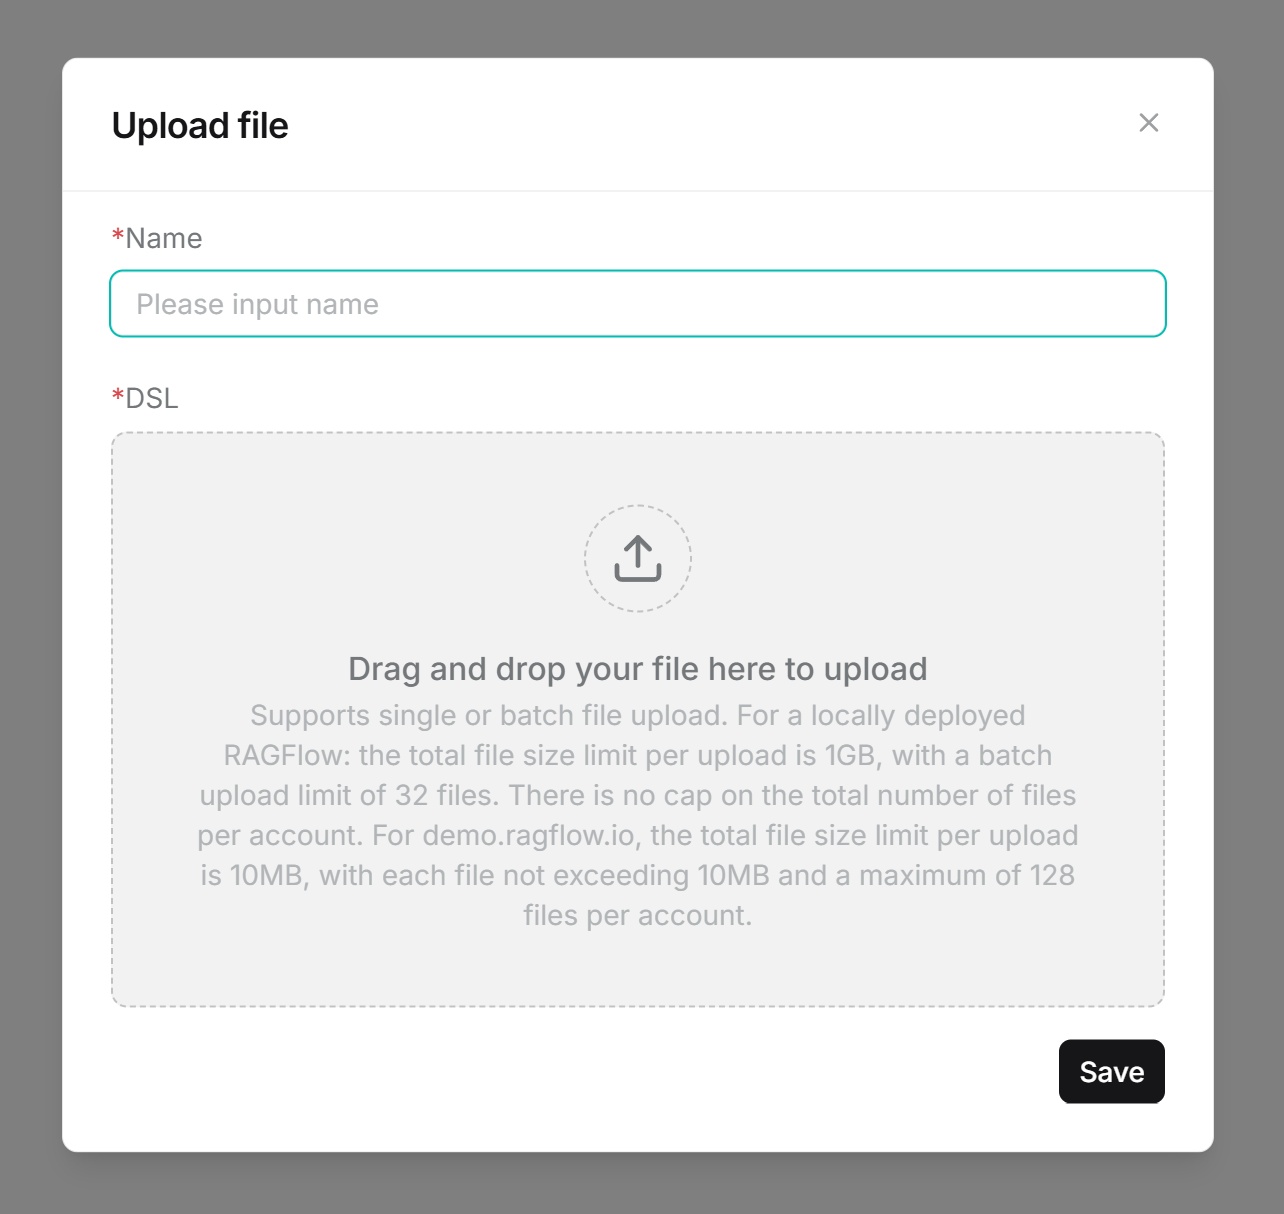## Export Agentdiff --git a/docs/guides/agent/ingestion_pipeline/connect_the_pipeline_to_a_knowledge_base.md b/docs/guides/agent/ingestion_pipeline/connect_the_pipeline_to_a_knowledge_base.mdindex 8372ab7c70..dbc5d99f14 100644--- a/docs/guides/agent/ingestion_pipeline/connect_the_pipeline_to_a_knowledge_base.md+++ b/docs/guides/agent/ingestion_pipeline/connect_the_pipeline_to_a_knowledge_base.md@@ -11,9 +11,13 @@ sidebar_custom_props: {# Connect the Pipeline to a Knowledge Base1. When creating or editing a knowledge base, find the parsing method section.-2. Click **Select pipeline** and choose the pipeline you saved.-3. Any file uploaded to this knowledge base will be processed by your custom Pipeline.+2. Open **Parse mode** and select your pipeline.-+ 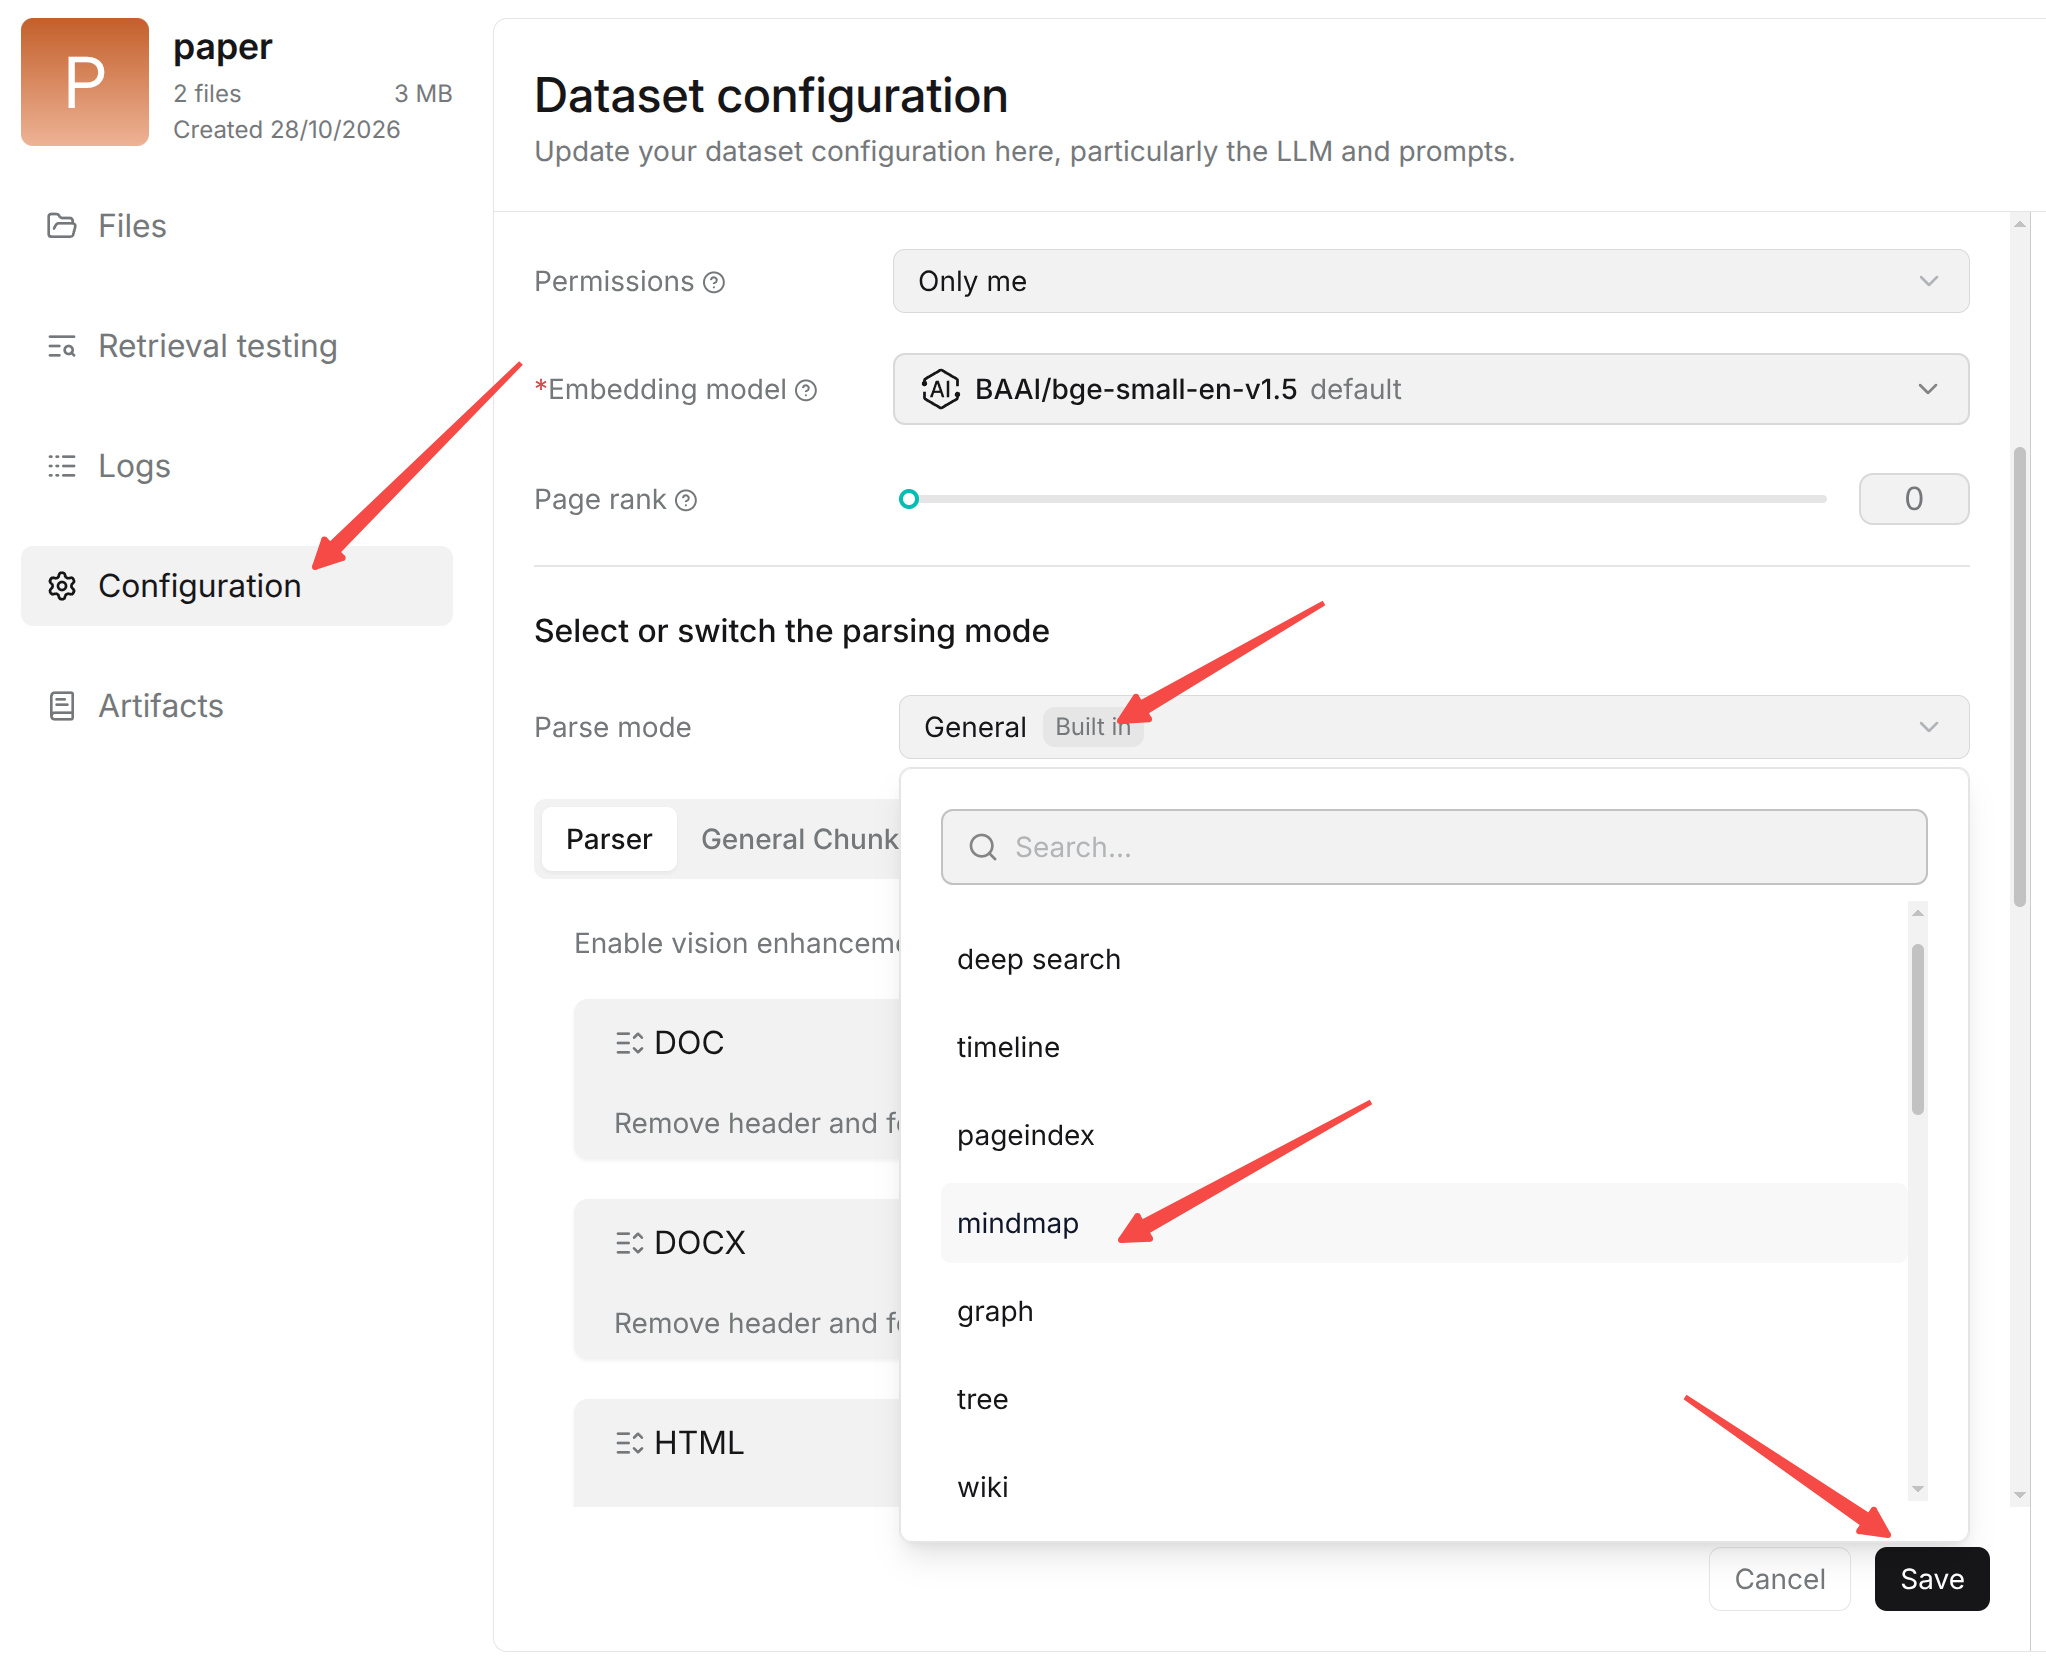-\ No newline at end of file+ The screenshot shows pipeline selection in **Parse mode**. The **Version** selector appears after choosing a pipeline.++3. In the dataset configuration, select a pipeline **Version**, then click **Save**.+4. Files uploaded to this knowledge base use the selected pipeline version.++The dataset keeps its selected pipeline version. To use a different version, select the target version in **Configuration** and save.diff --git a/docs/guides/chat/Mutimodel_comparison_and_FAQ.md b/docs/guides/chat/Mutimodel_comparison_and_FAQ.mdindex 282a43b72a..7e1ab12bfa 100644--- a/docs/guides/chat/Mutimodel_comparison_and_FAQ.md+++ b/docs/guides/chat/Mutimodel_comparison_and_FAQ.md@@ -26,6 +26,6 @@ Use representative questions from actual business scenarios instead of selectingYes, we support enhancing user queries based on existing context of an ongoing conversation:-1. On the **Chat** page, hover over the desired assistant and select **Edit**.-2. In the **Chat Configuration** popup, click the **Prompt engine** tab.-3. Switch on **Multi-turn optimization** to enable this feature.+1. Open the desired Chat and click the settings icon in the upper-right corner.+2. Expand **Advanced settings** in **Chat setting**.+3. Enable **Multi-turn optimization** and click **Save**.diff --git a/docs/guides/chat/chat_configuration.md b/docs/guides/chat/chat_configuration.mdindex 211151d009..9b7599b528 100644--- a/docs/guides/chat/chat_configuration.md+++ b/docs/guides/chat/chat_configuration.md@@ -11,9 +11,9 @@ sidebar_custom_props:## Dataset Configuration-dataset determine the data scope that Chat can retrieve and cite. Only dataset that contain successfully parsed, available chunks can serve as valid knowledge sources.+Datasets determine the data scope that Chat can retrieve and cite. Only datasets that contain successfully parsed, available chunks can serve as valid knowledge sources.-- **Select dataset**: Associate one or more dataset in the **dataset** field. New or empty dataset generally do not appear in the selection list.+- **Select dataset**: Associate one or more datasets in the **dataset** field. New or empty datasets generally do not appear in the selection list.- **Unavailable dataset**: If a dataset has been deleted or contains no available chunks, Chat indicates that the selected dataset is unavailable. Select another dataset.:::tip NOTE@@ -58,11 +58,12 @@ Clearer prompts produce more stable behavior. Refine the prompt continuously bas## Retrieval Configuration-Retrieval configuration controls how Chat recalls, filters, and ranks chunks from dataset. Tune these settings to balance retrieval scope, relevance, and response efficiency.+Retrieval configuration controls how Chat recalls, filters, and ranks chunks from datasets. Tune these settings to balance retrieval scope, relevance, and response efficiency.- **Similarity threshold**: The minimum similarity score for retrieved content. A higher threshold is stricter and usually returns more relevant content, but may miss useful information. A lower threshold broadens recall but may introduce less relevant content.-- **Vector similarity weight**: Controls the relative weight of vector semantic similarity and full-text matching in hybrid search. A higher vector weight favors semantic similarity; a higher full-text weight favors keyword and text matching. Tune it according to the dataset content and question style.-- **Top N**: The number of candidate chunks returned by each retrieval. A larger value provides more context but increases context length, response time, and cost. Tune it according to document scale and retrieval results.+- **Keyword similarity weight**: Sets the full-text weight in hybrid retrieval; the vector weight is `1` minus this value. Increase it for exact keyword matching and decrease it for semantic matching.+- **Rerank candidates**: The candidate pool used for ranking or reranking, with a default of `64` and a range of `64–256`. This controls the pool from which the final results are selected.+- **Top N**: The maximum number of retrieved chunks used to generate the answer. A larger value provides more context but increases context length, response time, and cost. Tune it according to document scale and retrieval results.- **Rerank model**: Reranks retrieval results, calculates the relevance between candidate chunks and the question, and moves more relevant content forward for answer generation. Configure an available rerank model before using this option.- **Metadata**: Uses document or chunk metadata to limit the retrieval scope, such as by document type, date, or source.@@ -118,5 +119,4 @@ Retrieval augmentation options further optimize queries or expand information reAnswer and display settings control how generated content is presented and output. They generally do not change the dataset retrieval scope, but affect how citations, metadata, and voice content are presented to users.- **Show citations**: When enabled, Chat displays the dataset content cited in the answer and its source, allowing users to inspect the evidence and trace it to the original document. When disabled, citation information is not shown.-- **Show chunk metadata**: When enabled, citations display metadata for the corresponding chunk, such as the source, author, and date fields configured for the document. This supplements citation context and helps users understand the source and attributes of the cited content.- **Text-to-speech**: Select the model used to convert text answers to speech. Once configured, Chat can output generated text as speech. Leave it disabled if voice output is not needed. Before using this feature, configure an available text-to-speech (TTS) model.diff --git a/docs/guides/chat/feature_overview_and_creation.md b/docs/guides/chat/feature_overview_and_creation.mdindex 05f6e08c47..588da08b58 100644--- a/docs/guides/chat/feature_overview_and_creation.md+++ b/docs/guides/chat/feature_overview_and_creation.md@@ -17,7 +17,7 @@ After creating a Chat, configure its datasets, model, system prompt, and retriev## Create a Chat-1. Select **Chat** in the left navigation bar.+1. Select **Chat** in the top navigation bar.2. Click **Create chat**.3. Enter a name for the Chat.4. Confirm the creation.@@ -26,9 +26,9 @@ After creating a Chat, configure its datasets, model, system prompt, and retriev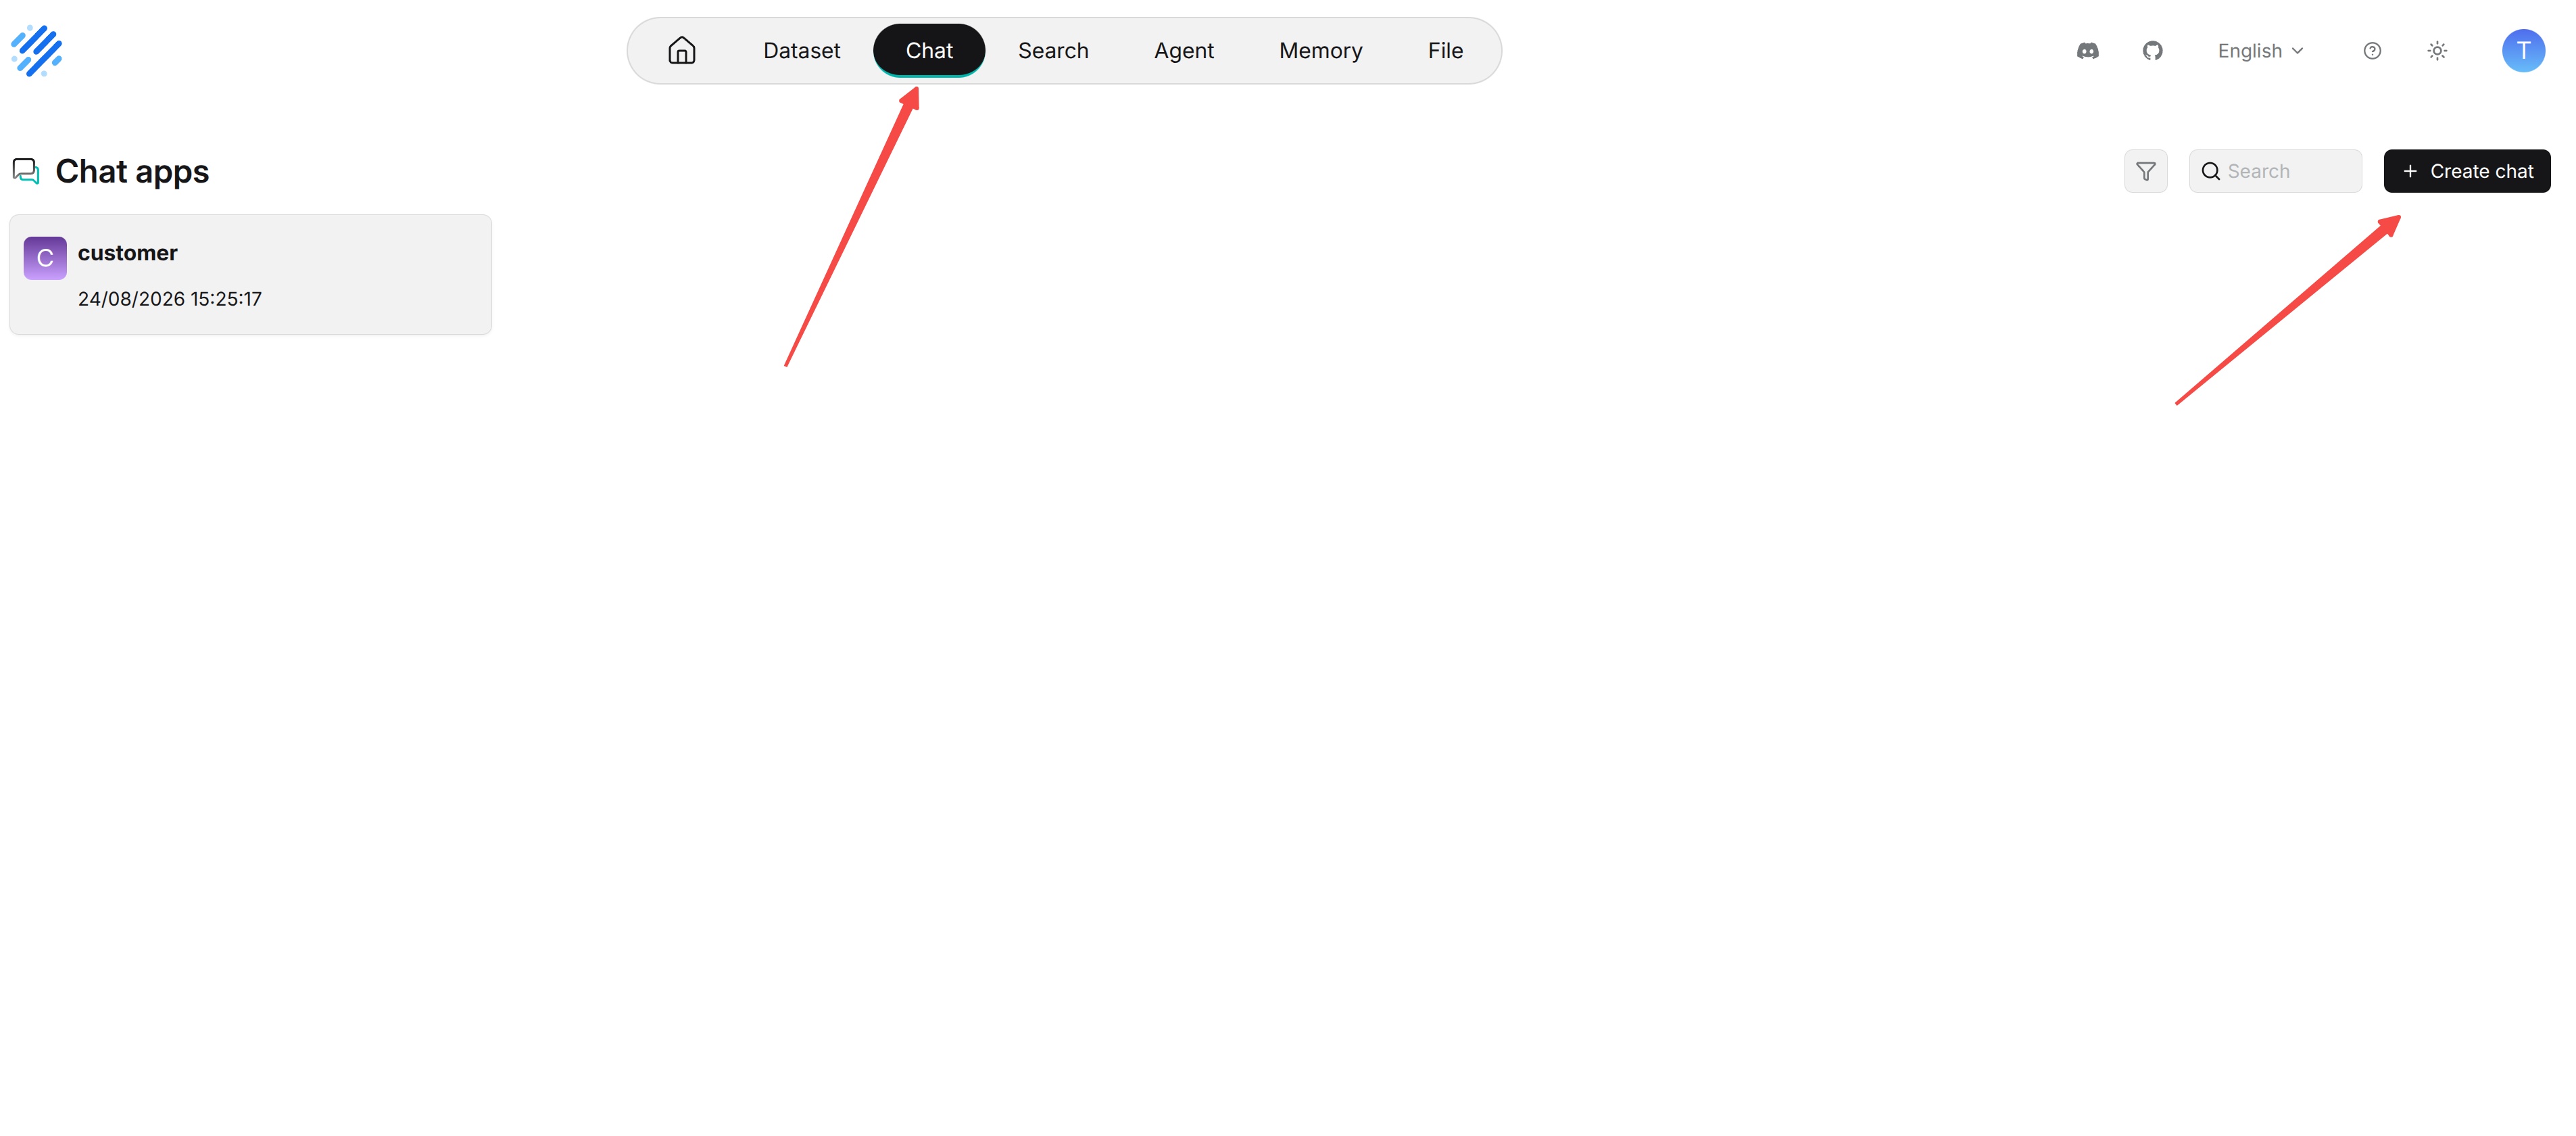-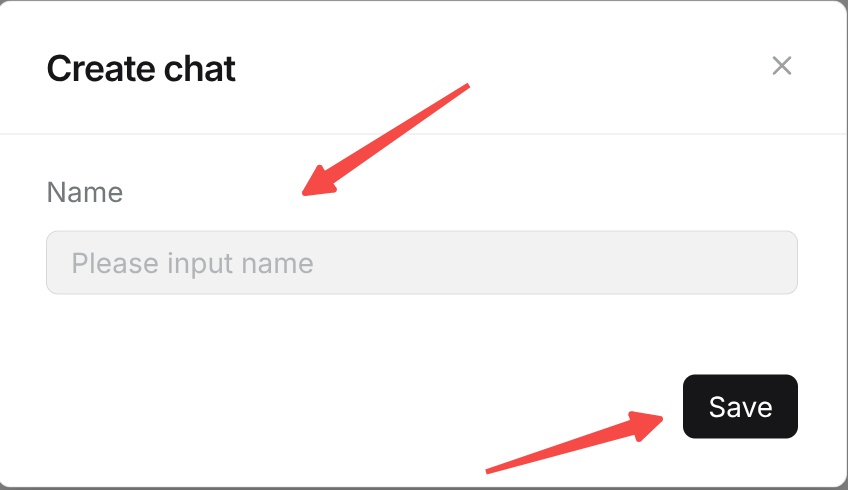+-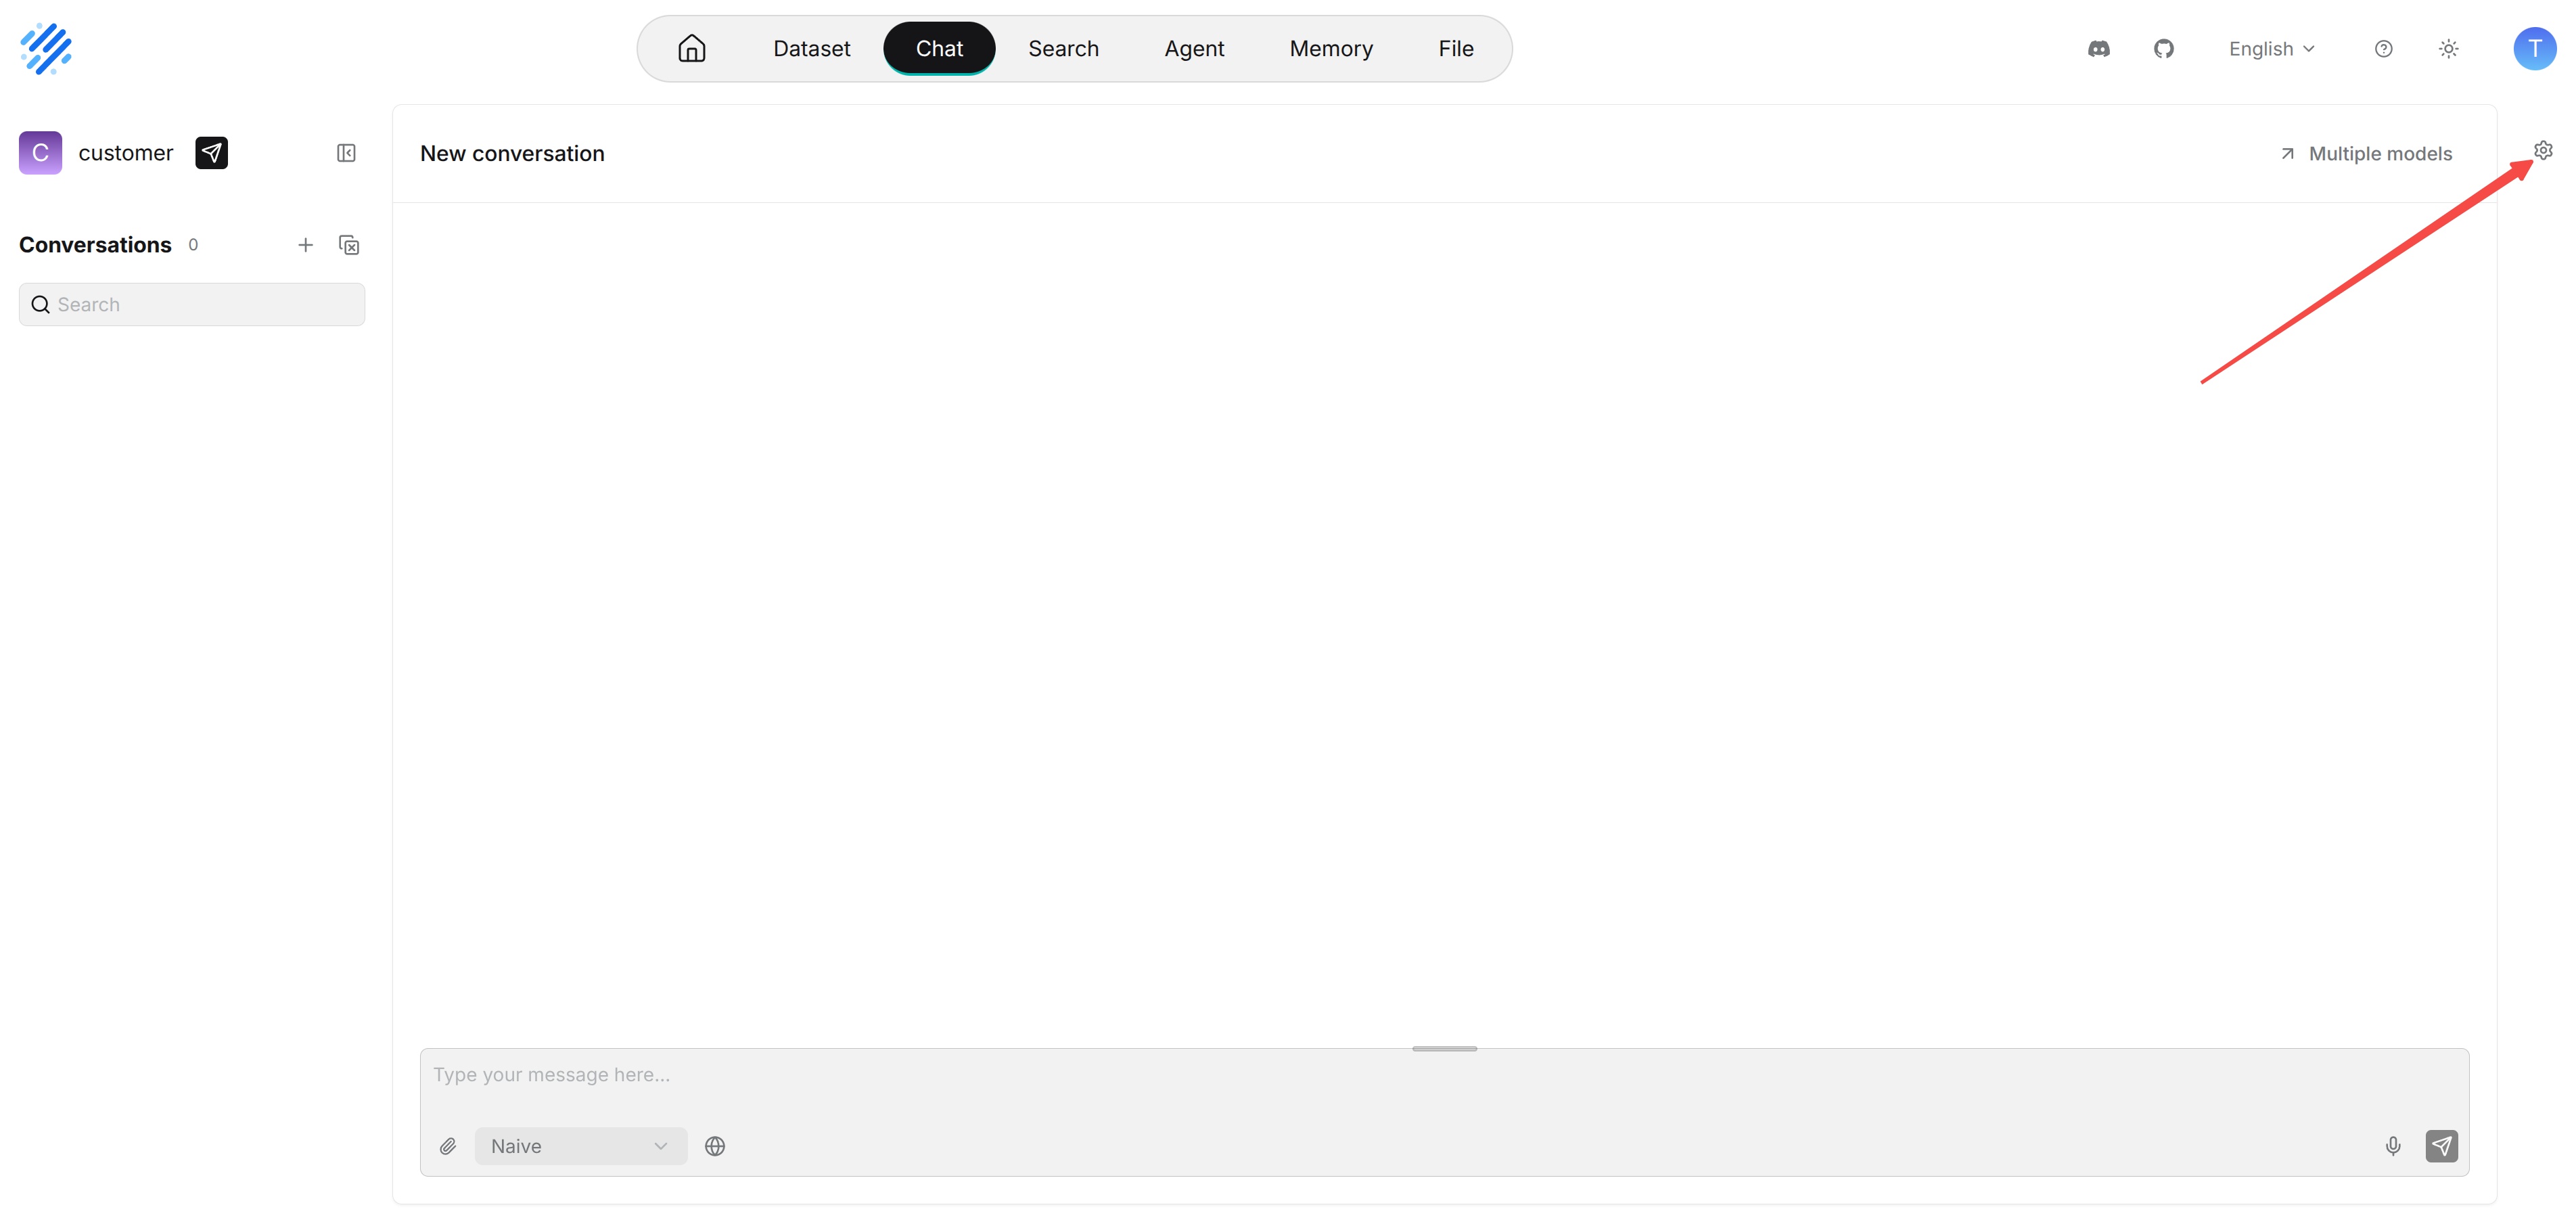+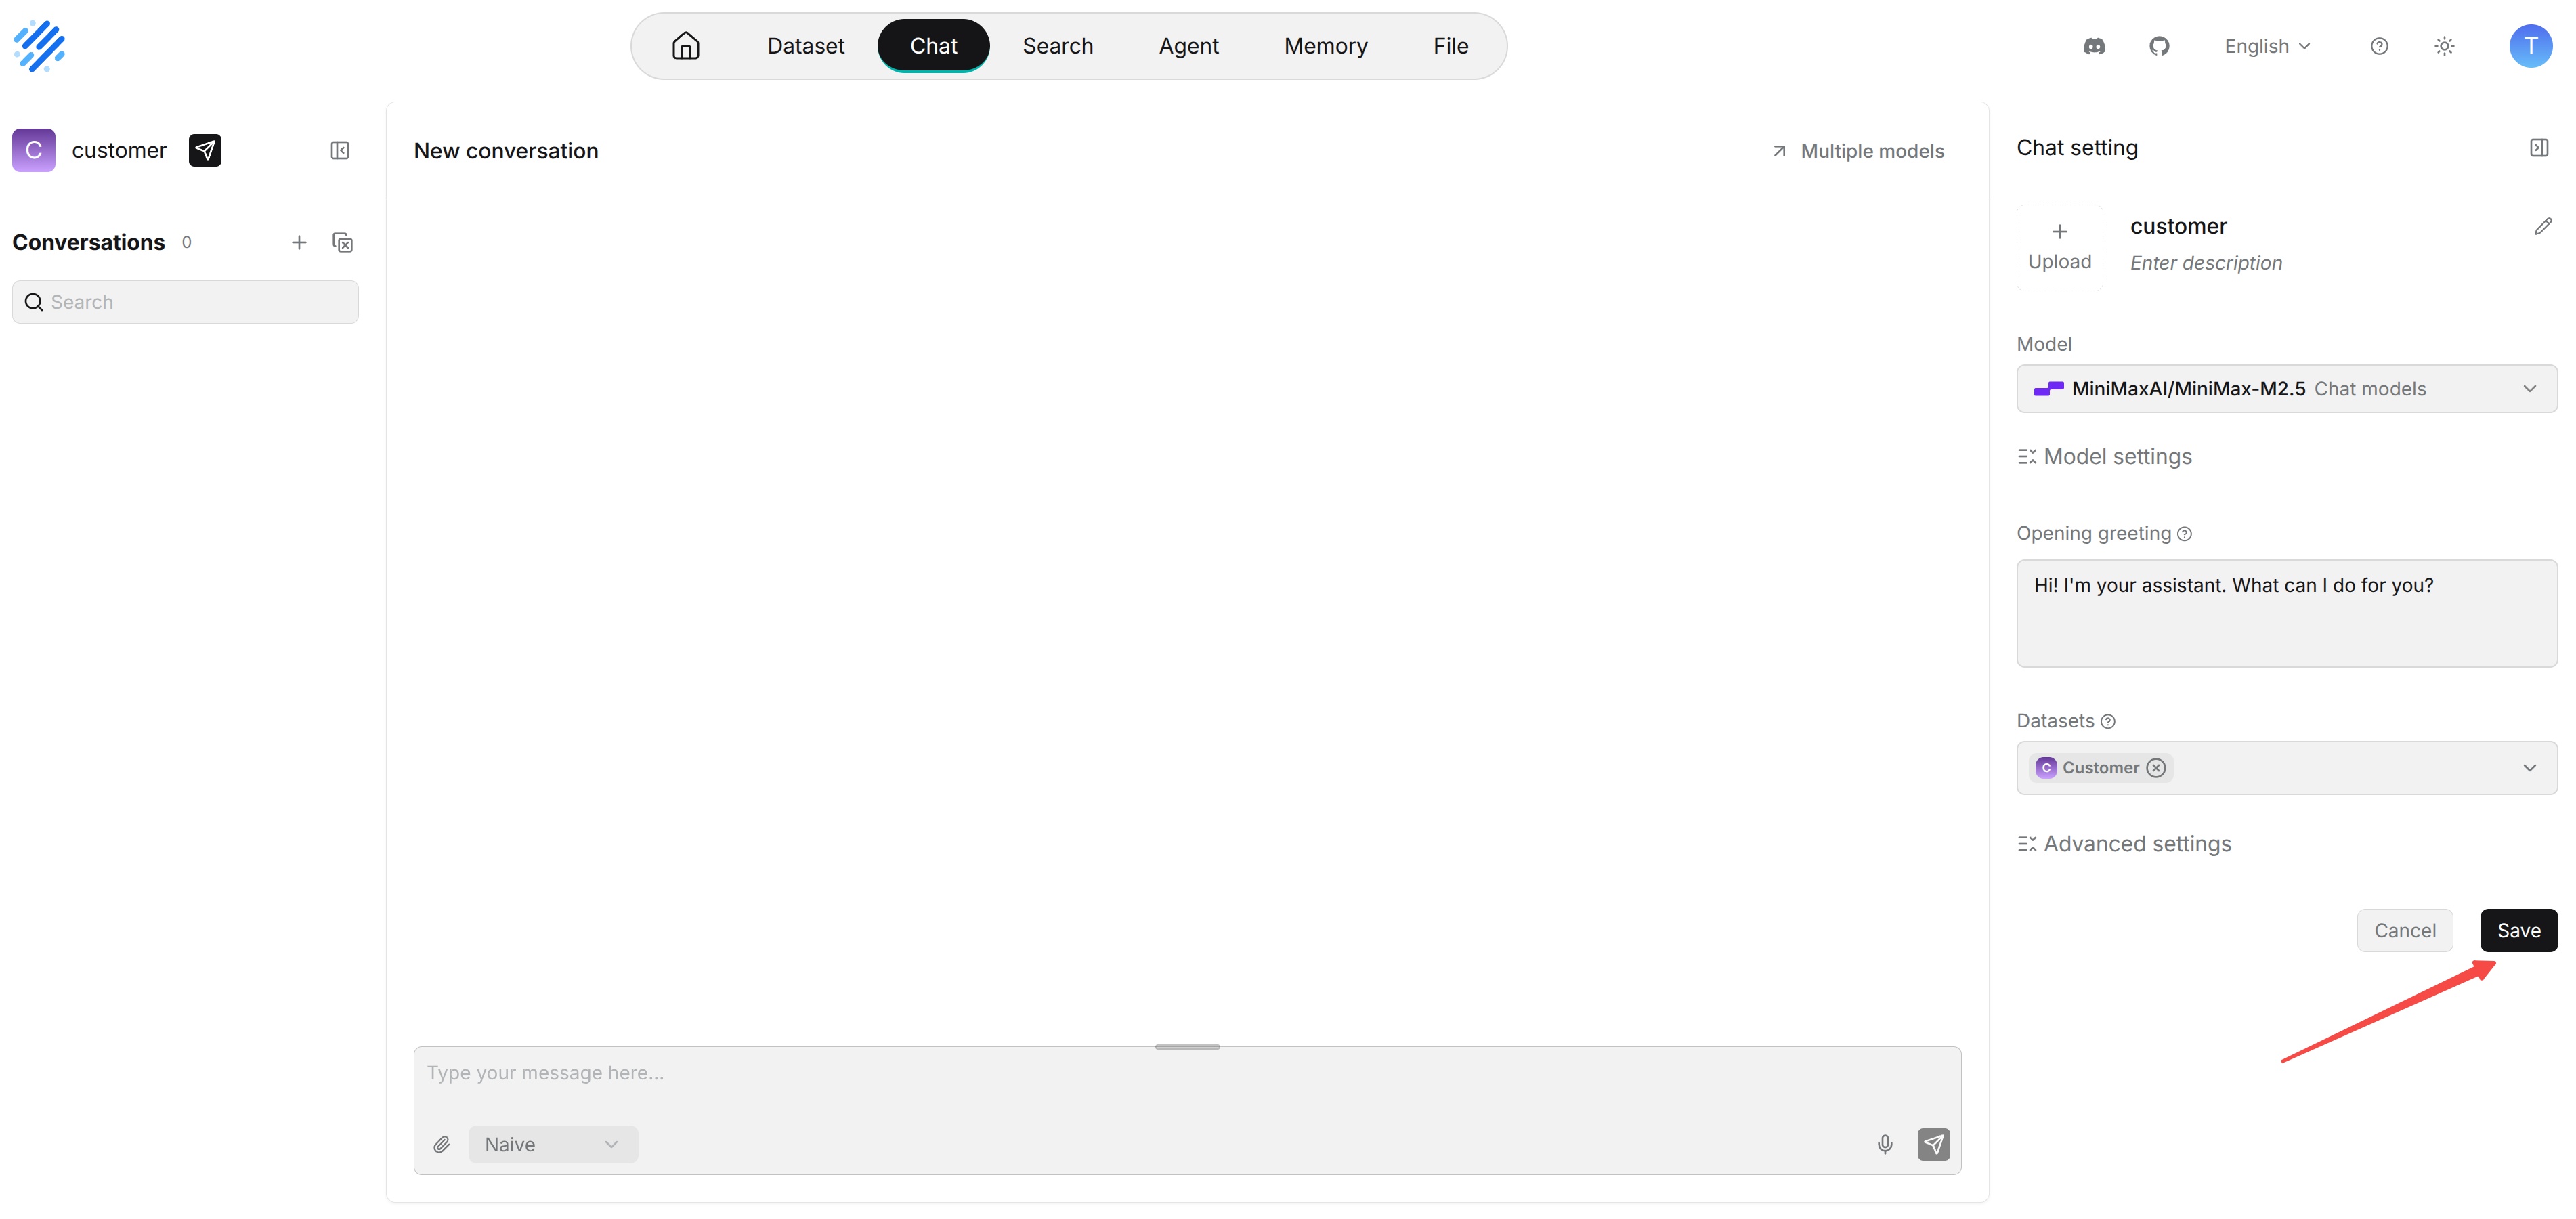diff --git a/docs/guides/chat/using_chat_sessions.md b/docs/guides/chat/using_chat_sessions.mdindex 055573e55d..64aab5fca4 100644--- a/docs/guides/chat/using_chat_sessions.md+++ b/docs/guides/chat/using_chat_sessions.md@@ -67,9 +67,9 @@ RAGFlow provides an HTTP API for integration:You can also embed the created Chat assistant in a third-party webpage with an iframe:1. [Acquire an API key](../../develop/acquire_ragflow_api_key.md) before continuing. Otherwise, an error occurs.-2. Hover over the target Chat assistant and click **Edit** to open the iframe window.+2. Click the paper-airplane icon next to the Chat name to open **Embed into website**.3. Copy the iframe code and embed it in your webpage.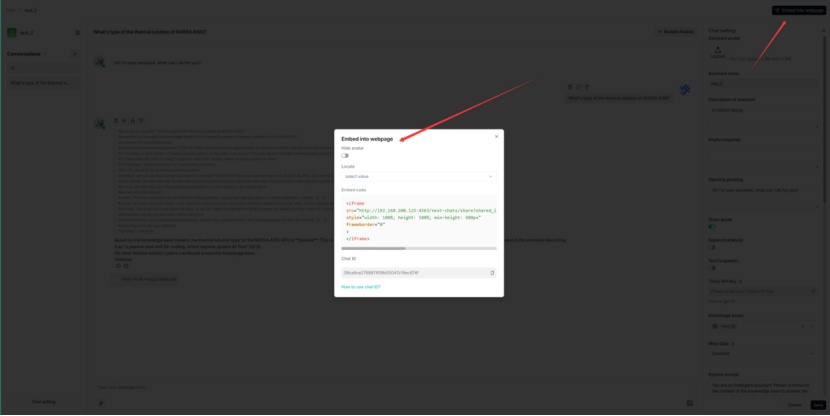-+diff --git a/docs/guides/data_source/data_source_configuration.md b/docs/guides/data_source/data_source_configuration.mdindex b518ccca71..8c5318e0c1 100644--- a/docs/guides/data_source/data_source_configuration.md+++ b/docs/guides/data_source/data_source_configuration.md@@ -161,7 +161,7 @@ The SeaFile data source is used to synchronize account, library, or directory co- **Batch size**: Set the number of items processed in each batch.- **Sync deleted files**: After this is enabled, content deleted from the external system is removed from the knowledge base index.-+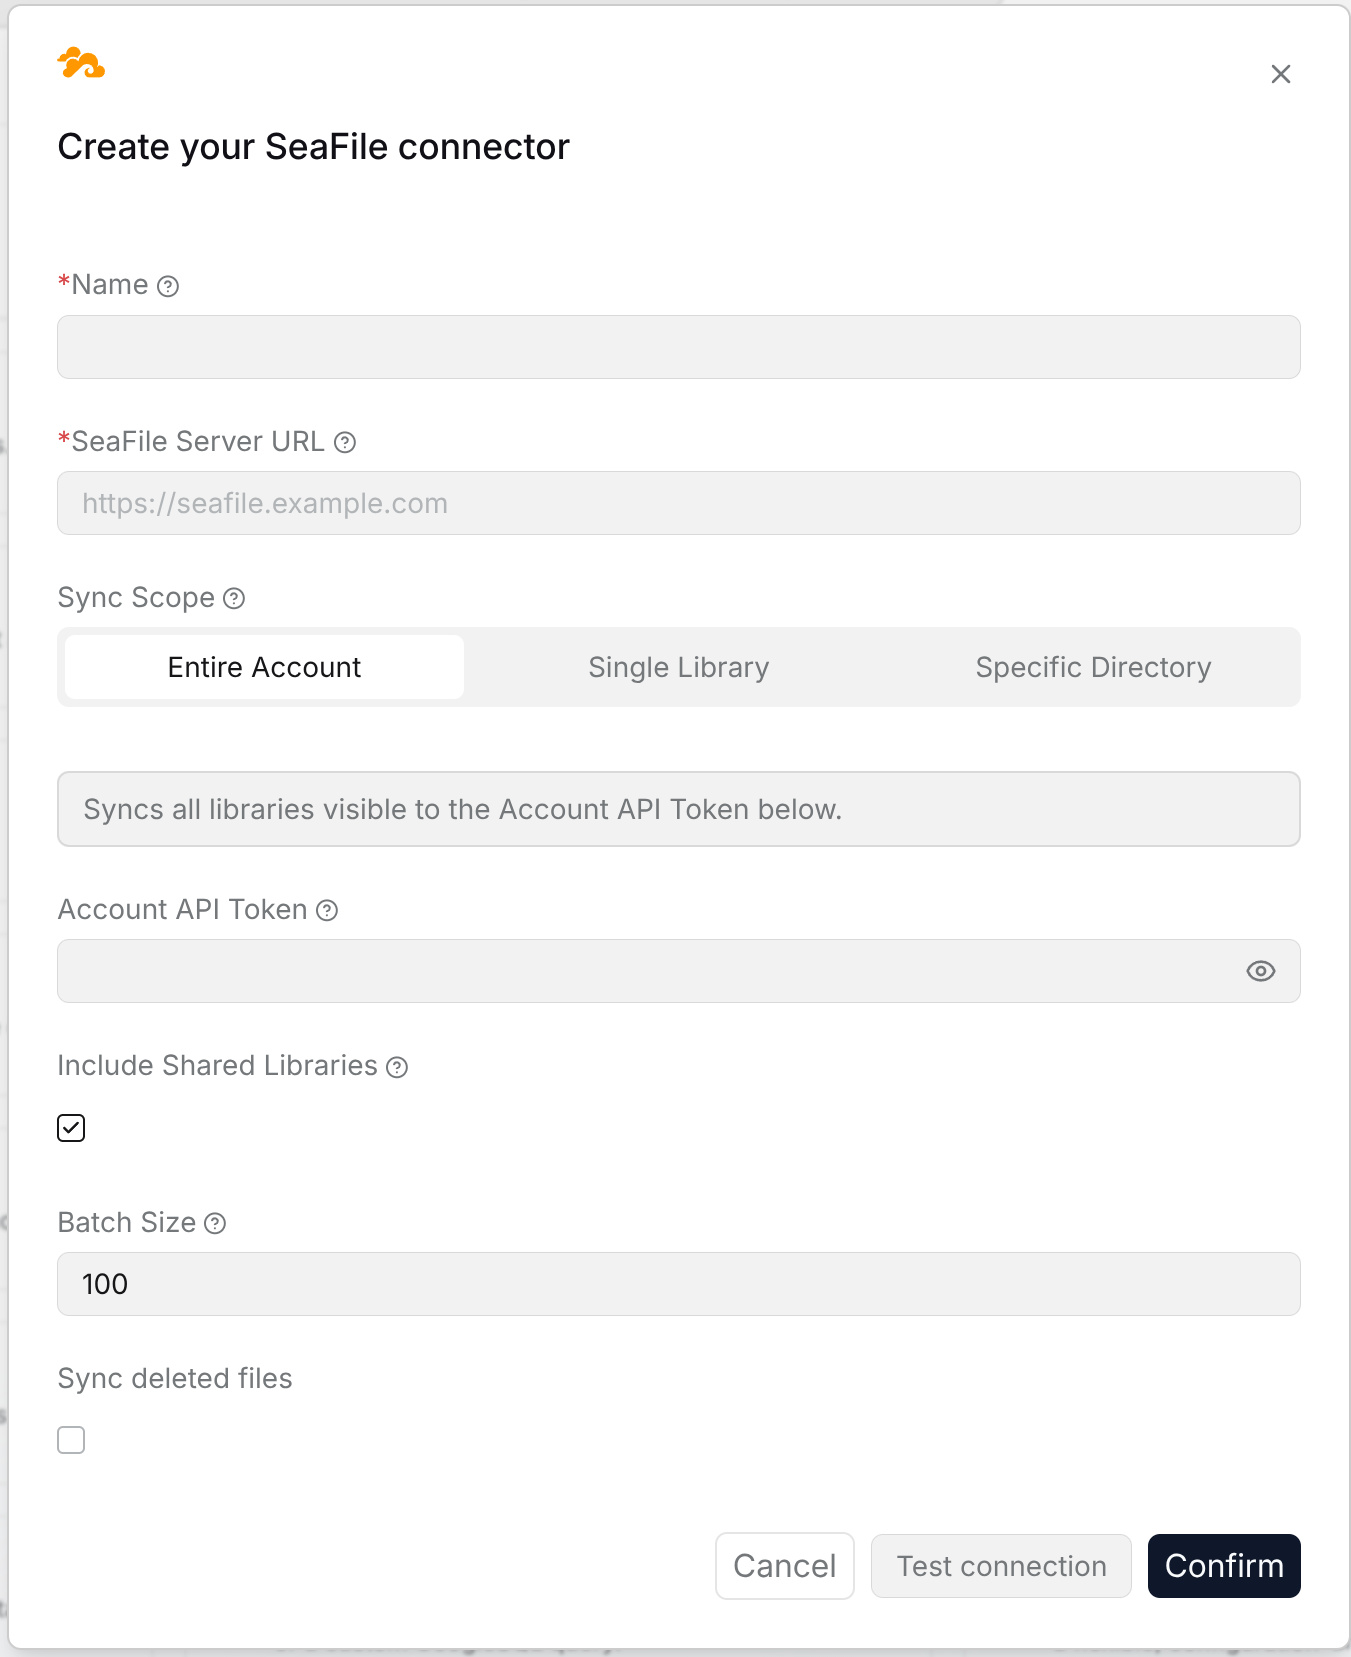## S3@@ -277,20 +277,25 @@ The MySQL data source is used to synchronize table records or query results in M**Configuration parameters**:-- **Name**: Customize the name in RAGFlow to identify this MySQL connection.-- **Host**: Fill in the database host address.-- **Port**: Fill in the database port.-- **Database**: Fill in the database name that needs to be synchronized.-- **Username**: Fill in the database username.-- **Password**: Fill in the database password.-- **SQL query**: Fill in the SQL statement used to read data.-- **Content column**: Select the field to be written as document content.-- **Metadata column**: Select the field to be written as metadata.-- **ID column**: Select the unique ID field.-- **Timestamp column**: Select the field used to determine incremental updates.-- **Sync deleted files**: After this is enabled, deleted records can be removed from the knowledge base index according to the field mapping or cleanup task.+- **Name**: Enter a connection name for display in RAGFlow.+- **Host**: Enter the database hostname or IP address reachable from the RAGFlow server.+- **Port**: Enter the MySQL service port, usually `3306`.+- **Database**: Enter the database name to read.+- **Username / Password**: Enter the database account and password. Use an account with read access to the required tables.+- **SQL Query**: Enter a `SELECT` query to limit the imported rows or columns. Leave it empty to load all tables in the database.+- **Content Columns**: Enter the column names to use as document text, separated by commas, such as `title,description,content`.+- **Metadata Columns**: Enter comma-separated column names to store as metadata, such as `category,status`.+- **ID Column**: Enter a stable, unique record identifier, such as `id`, so records can be identified across synchronizations.+- **Timestamp Column**: Enter the last-update column, such as `updated_at`, for incremental synchronization.+- **File Extension**: Enter the extension for generated documents, such as `.txt`, `.md`, or `.html`. Match it to the content format.+- **Batch Size**: Enter a positive number of records to process per batch.+- **Sync deleted files**: Enable this to remove synchronized documents when their source records are deleted.-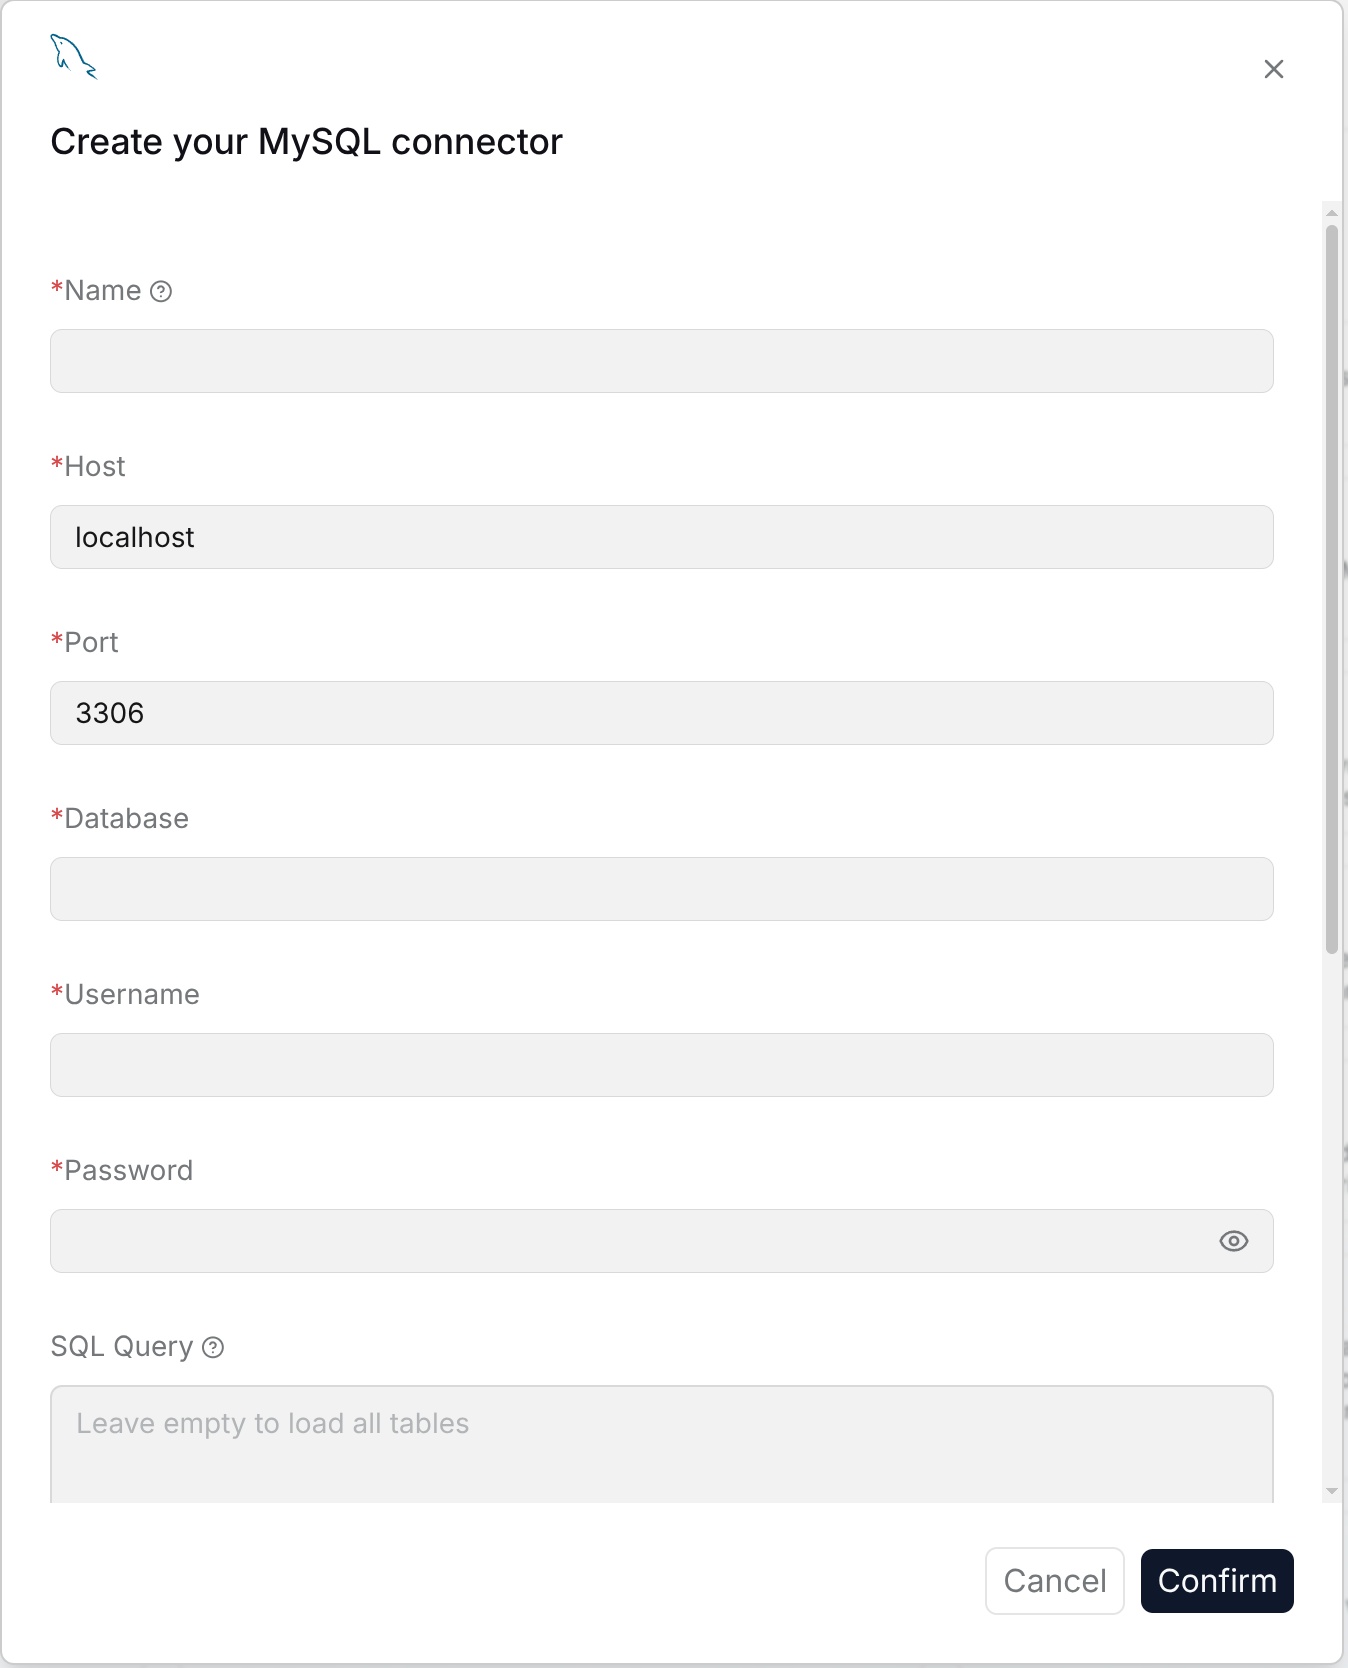+When using a custom query, use the column names or aliases returned by that query for the column settings. Click **Test connection** to check the configuration, then **Confirm** to create the connection.++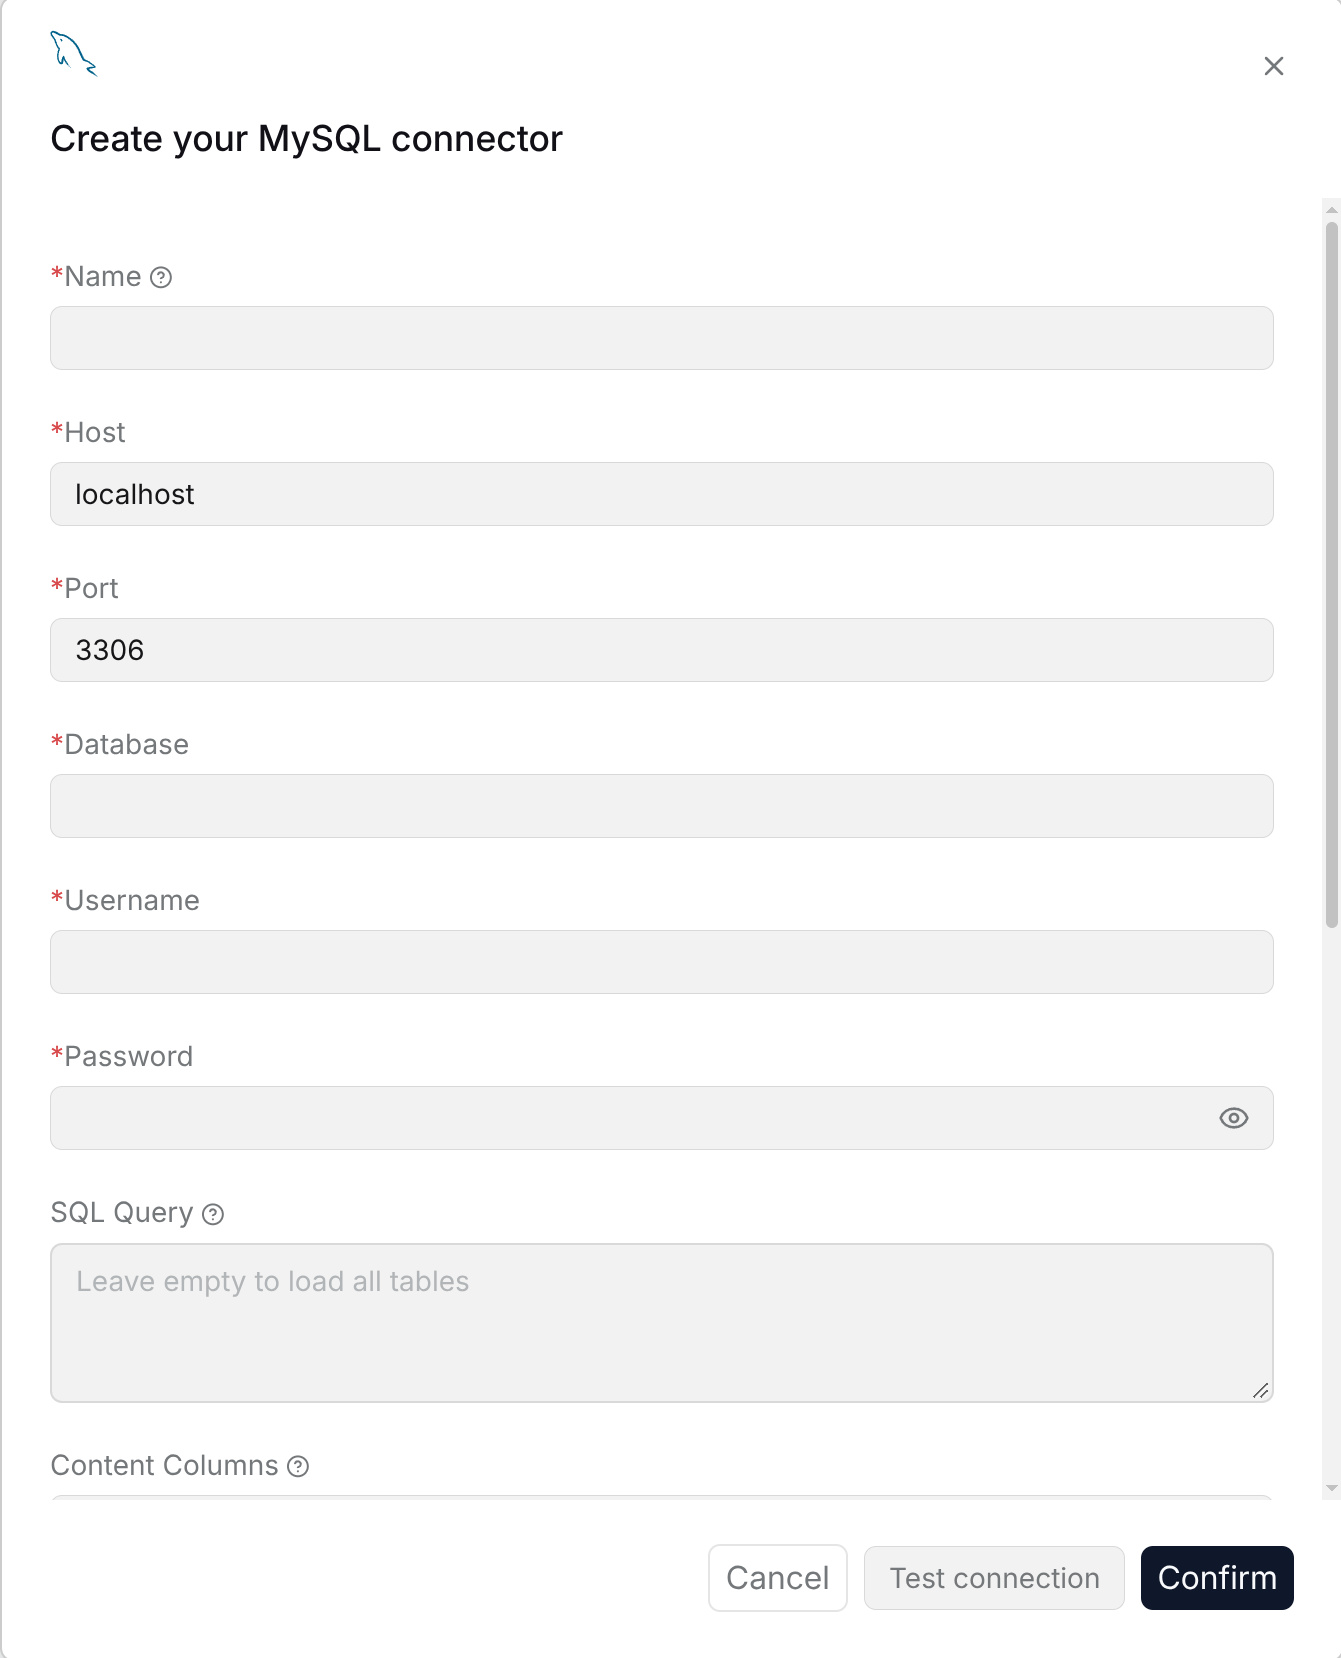++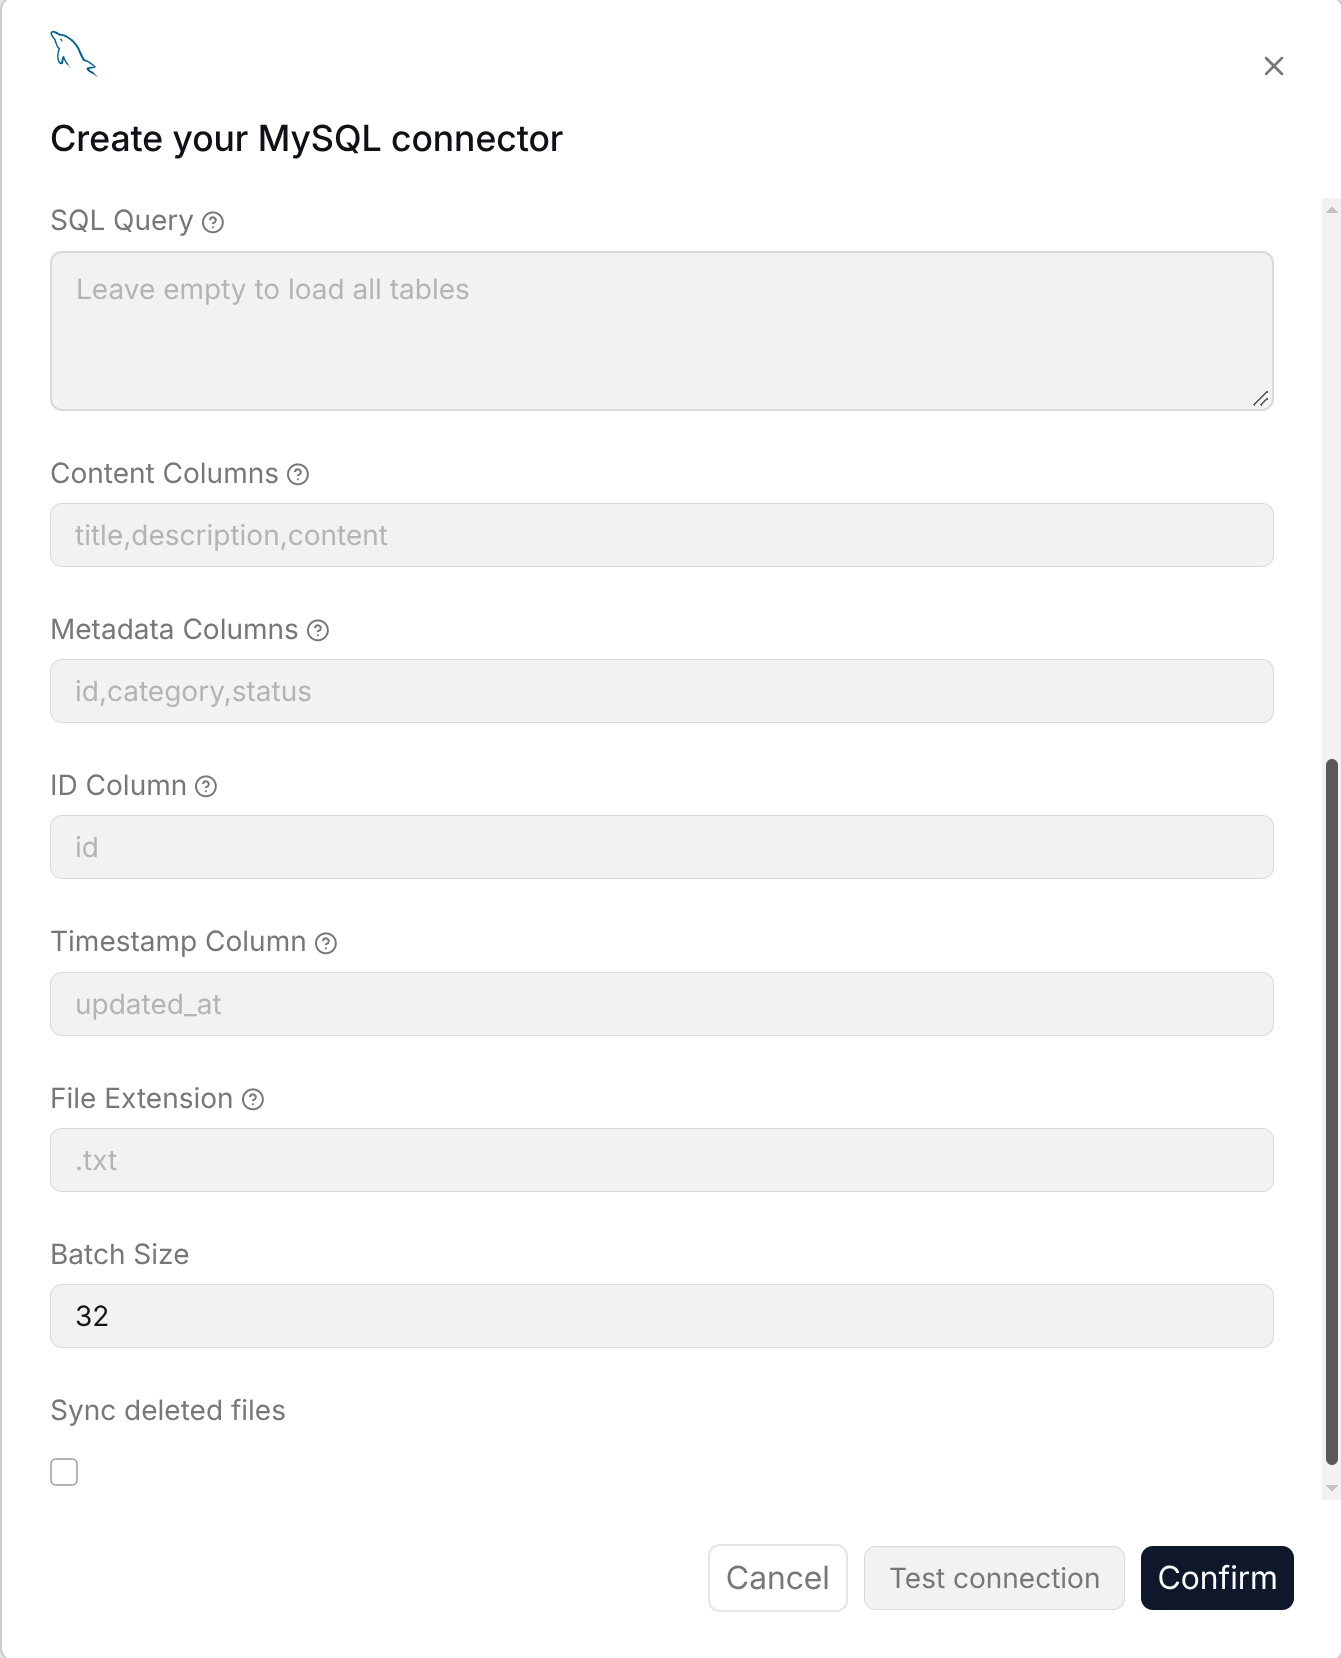## PostgreSQL@@ -300,9 +305,15 @@ The PostgreSQL data source is used to synchronize table records or query results**Account version requirements**: Both personal self-built databases and enterprise databases can be used. It is recommended to use a read-only account to connect to the target database tables.-**Configuration parameters**: The configuration fields are the same as those for MySQL, including name, host, port, database, username, password, SQL query, content column, metadata column, ID column, timestamp column, and sync deleted files.+**Configuration parameters**:++The fields and column settings are the same as those for **MySQL** above: **Name**, **Host**, **Port**, **Database**, **Username**, **Password**, **SQL Query**, **Content Columns**, **Metadata Columns**, **ID Column**, **Timestamp Column**, **File Extension**, **Batch Size**, and **Sync deleted files**.-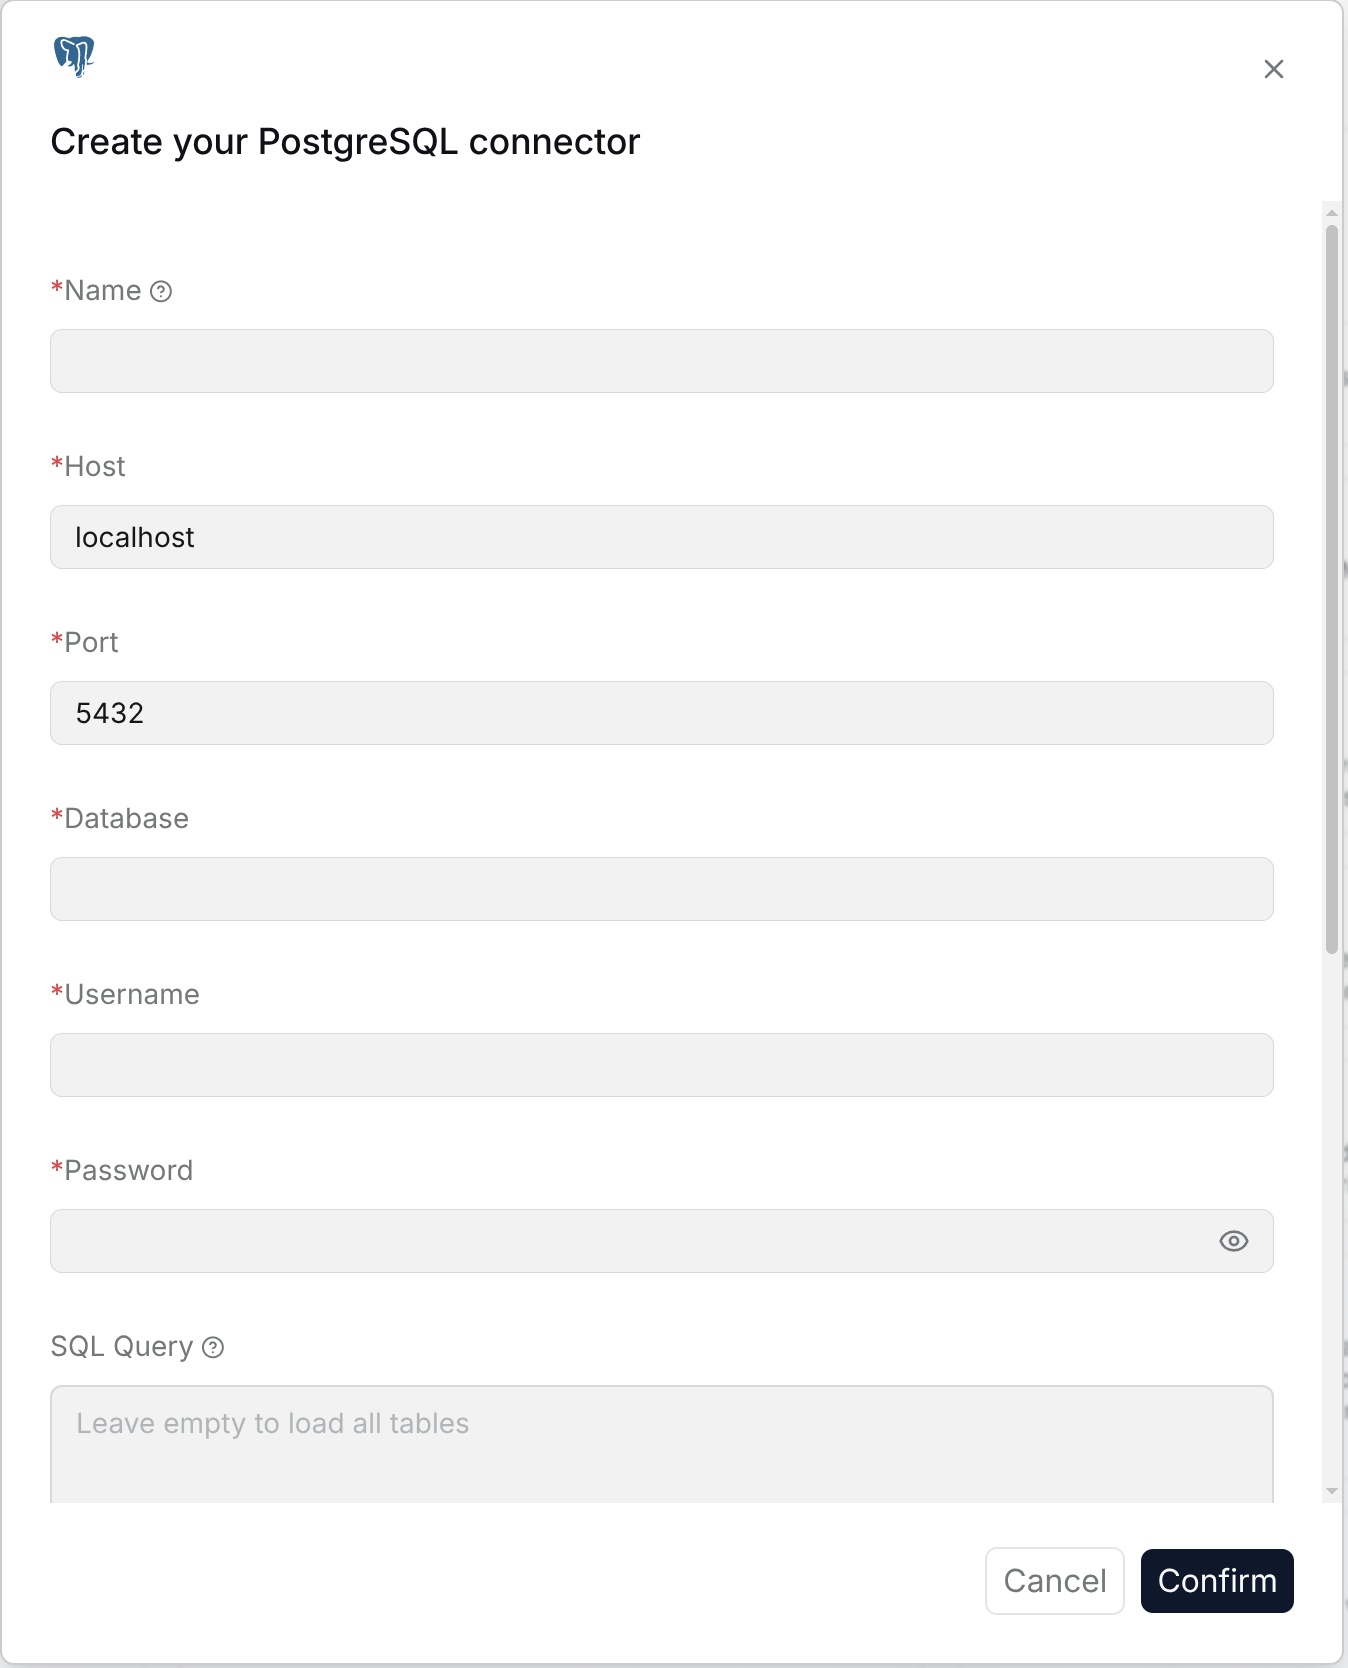+Use the PostgreSQL service port, usually `5432`, and PostgreSQL syntax for a custom `SELECT` query. Leave **SQL Query** empty to load all tables. Click **Test connection**, then **Confirm**.++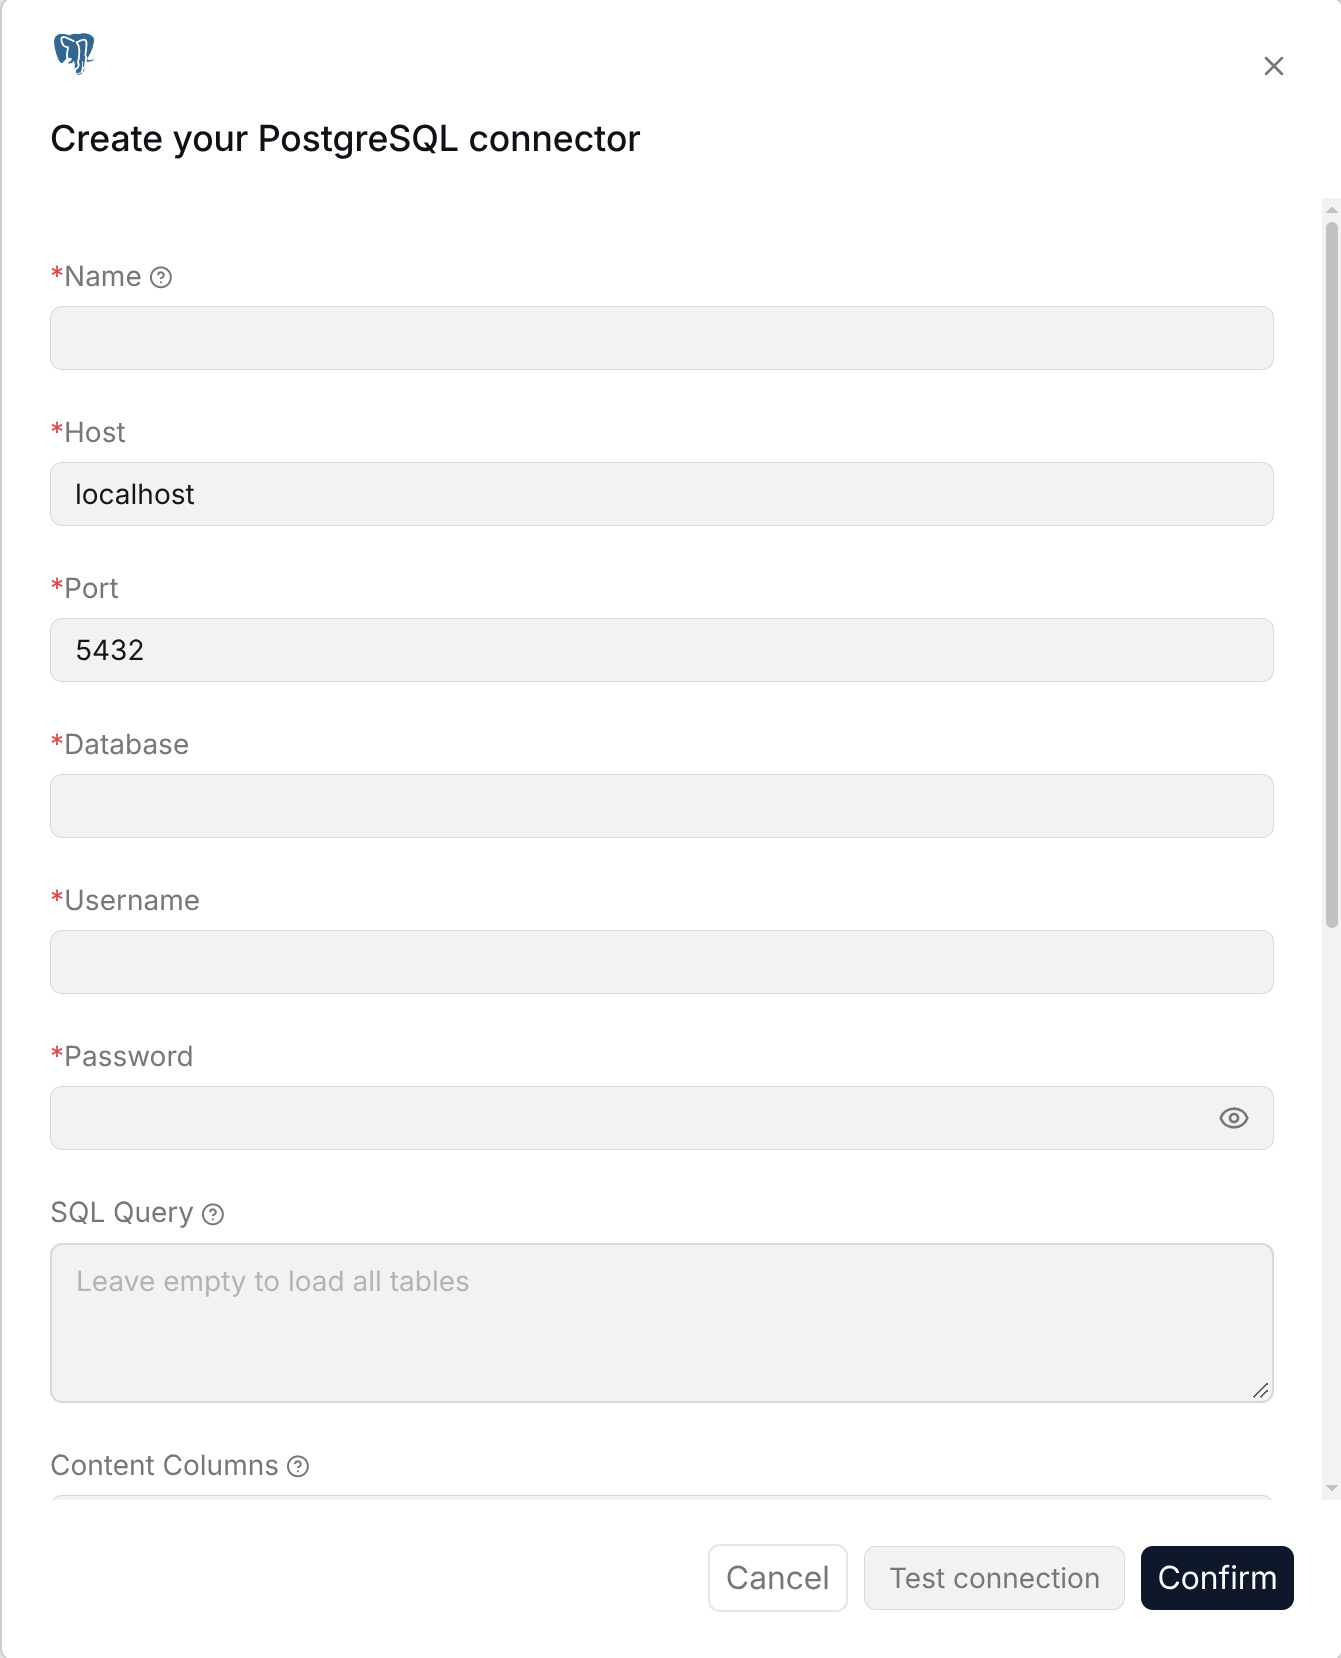++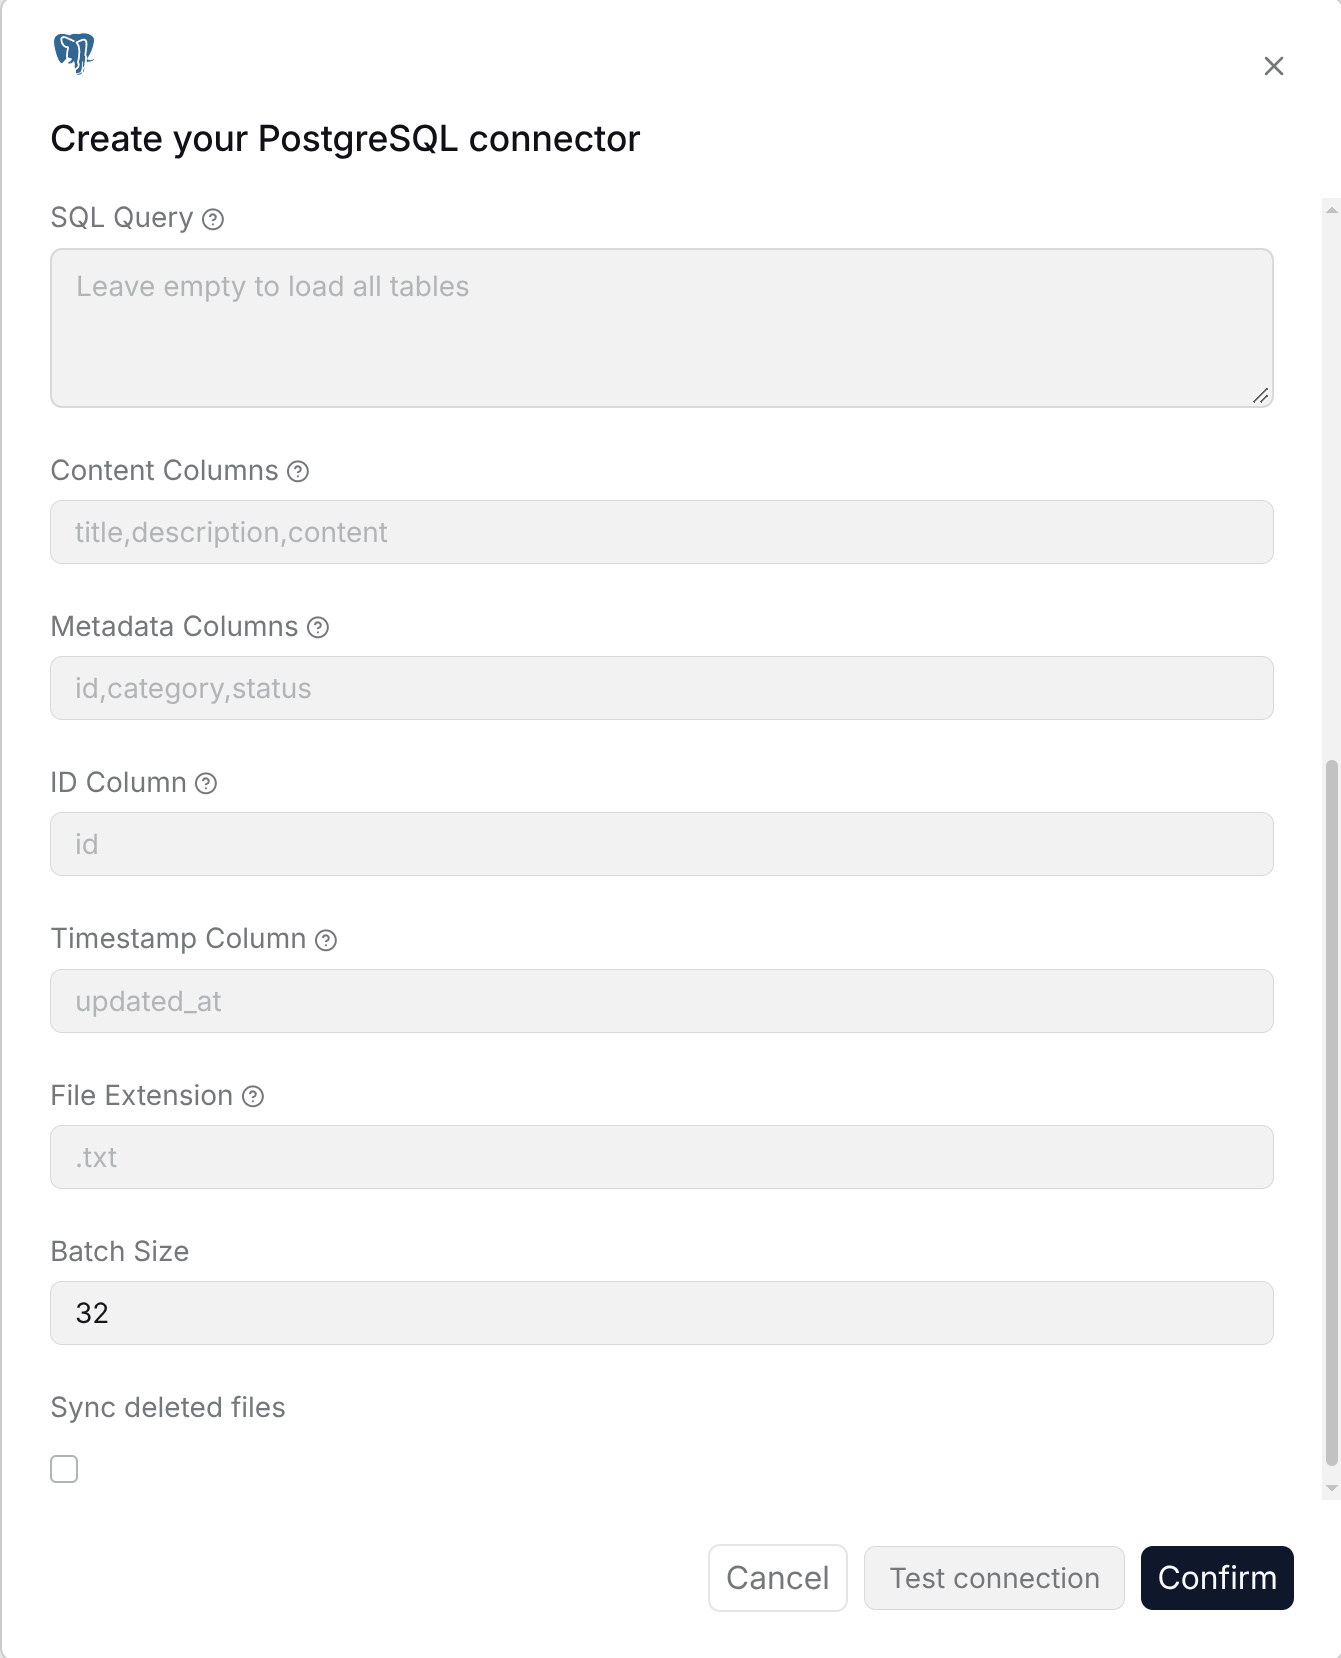## BigQuery@@ -314,19 +325,28 @@ The BigQuery data source is used to synchronize table records or query results i**Configuration parameters**:-- **Name**: Customize the name in RAGFlow to identify this BigQuery connection.-- **Service account JSON**: Fill in or upload the service account JSON used to access BigQuery.-- **Project ID**: Fill in the Google Cloud project ID.-- **Dataset**: Fill in the dataset name.-- **Table**: Fill in the table name.-- **SQL query**: Fill in the SQL statement used to read data.-- **Content column**: Select the field to be written as document content.-- **Metadata column**: Select the field to be written as metadata.-- **ID column**: Select the unique ID field.-- **Timestamp column**: Select the field used to determine incremental updates.-- **Sync deleted files**: After this is enabled, deleted records can be removed from the knowledge base index according to the field mapping or cleanup task.+- **Name**: Enter a connection name for display in RAGFlow.+- **Project ID**: Enter the Google Cloud project ID, such as `my-gcp-project`.+- **Location**: Enter the BigQuery dataset location, such as `US` or `EU`.+- **Service Account JSON**: Paste the complete JSON key for a service account with access to the data and permission to run BigQuery jobs.+- **Dataset ID / Table ID**: Enter the source dataset and table IDs, such as `analytics` and `customers`.+- **SQL Query**: Enter a GoogleSQL query to select the source data. Leave it empty to use **Dataset ID** and **Table ID**.+- **Content Columns**: Enter comma-separated result column names to use as document text, such as `name,description,notes`. This field is required.+- **Metadata Columns**: Enter comma-separated result column names to store as metadata, such as `status,region`.+- **ID Column**: Enter a stable, unique record identifier, such as `customer_id`.+- **Timestamp Column**: Enter the last-update column, such as `updated_at`, for incremental synchronization.+- **Max Bytes Billed**: Enter the maximum bytes a query is allowed to bill. For example, `1073741824` is 1 GiB.+- **Job Timeout (ms)**: Enter the query job timeout in milliseconds; `300000` is 5 minutes.+- **Page Size**: Enter the number of query-result rows to fetch per page.+- **Batch Size**: Enter the number of records to process per synchronization batch.+- **Use Query Cache**: Enable this to allow BigQuery to reuse eligible cached query results.+- **Sync deleted files**: Enable this to remove synchronized documents when their source records are deleted.++Use source column names, or result aliases when using a custom query. Click **Test connection**, then **Confirm**.++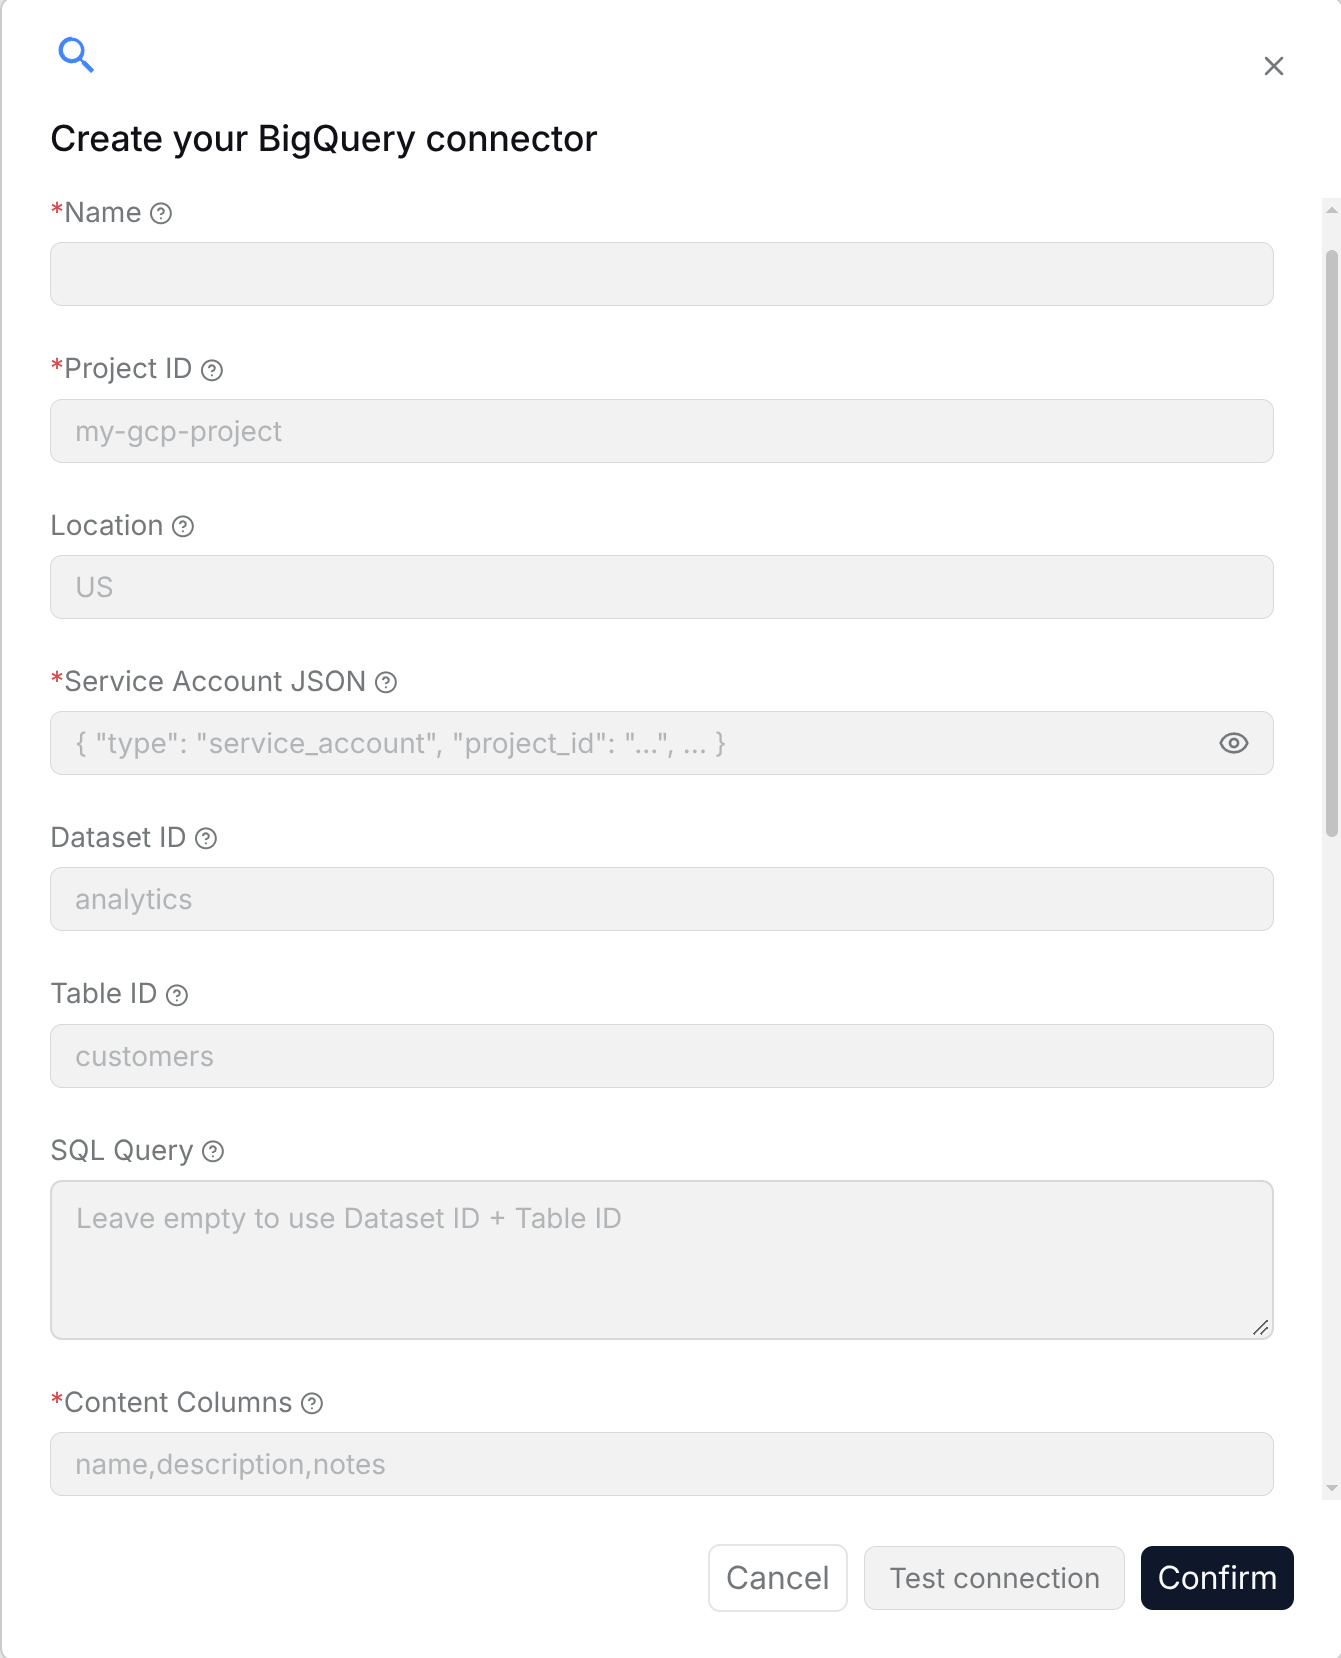-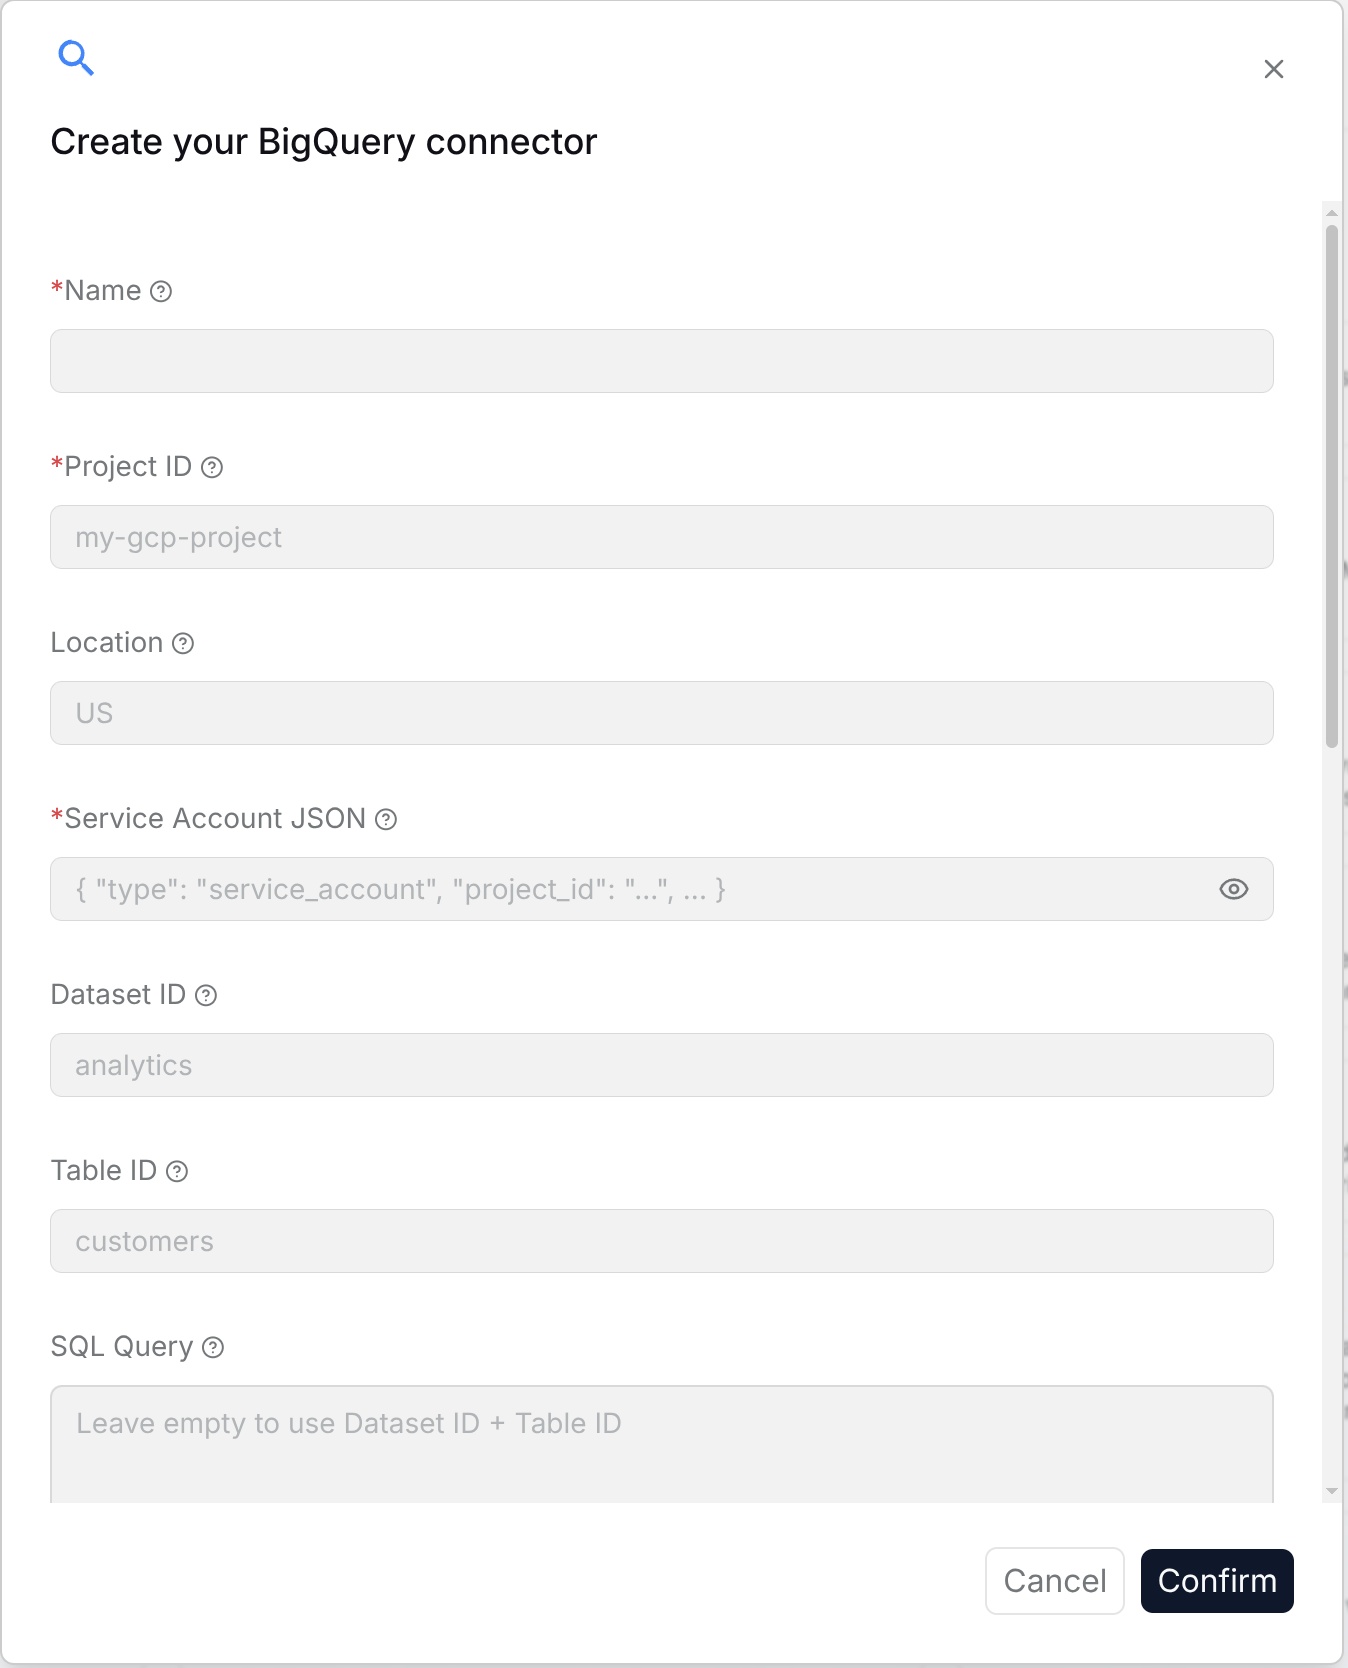+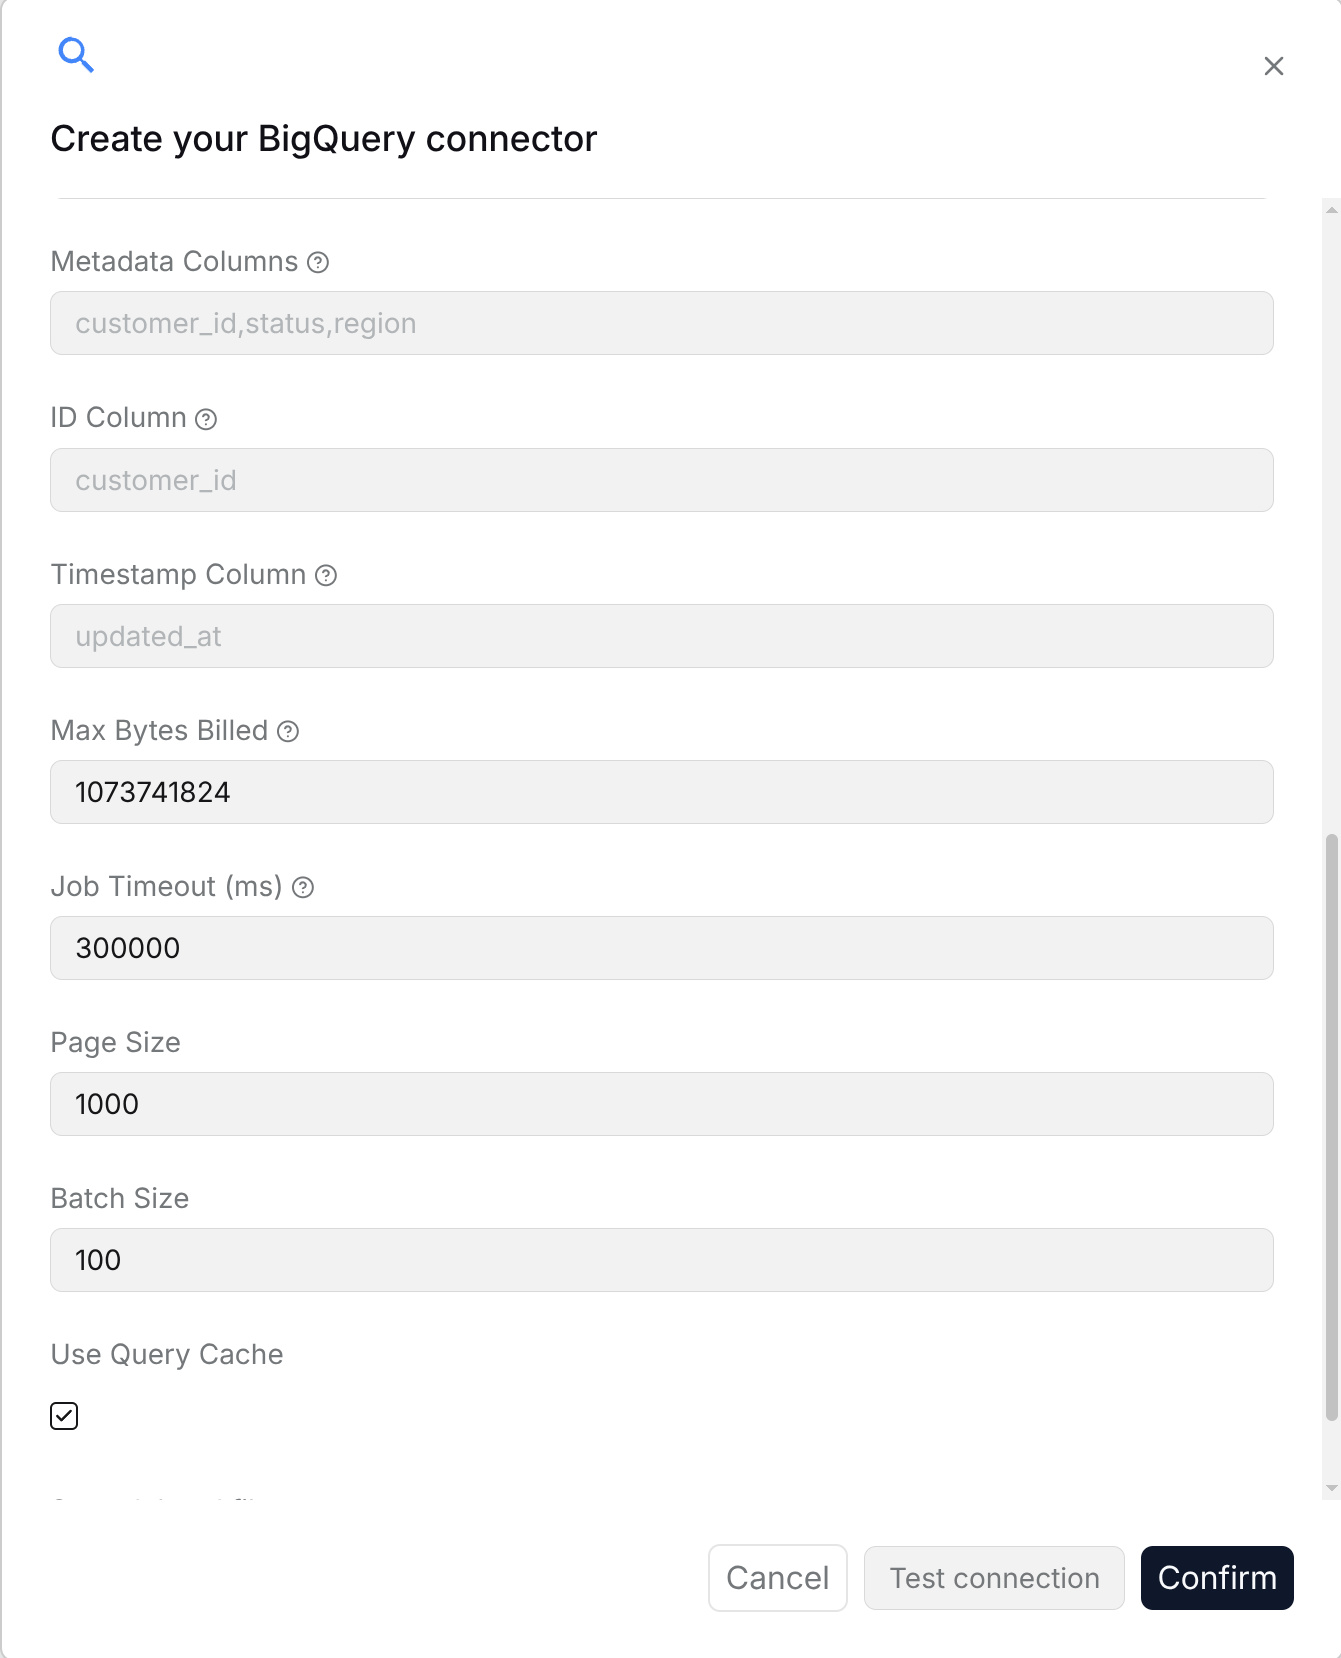## GitHub@@ -358,16 +378,19 @@ The GitLab data source is used to synchronize GitLab repositories, issues, merge**Configuration parameters**:-- **Name**: Customize the name in RAGFlow to identify this GitLab connection.-- **GitLab instance URL**: Fill in the GitLab service address.-- **Project ID or path**: Fill in the GitLab project ID or project path.-- **Access token**: Fill in the GitLab access token.-- **Include merge requests**: Select whether to synchronize merge requests.-- **Include issues**: Select whether to synchronize issues.-- **Include repository files**: Select whether to synchronize repository files.-- **Sync deleted files**: After this is enabled, content deleted from the external system is removed from the knowledge base index.+- **Name**: Enter a connection name for display in RAGFlow.+- **Project Owner**: Enter the user or group namespace that owns the project. Include subgroups when applicable, such as `my-group/my-subgroup`.+- **Project Name**: Enter the project path name. For `my-group/my-project`, use `my-group` as **Project Owner** and `my-project` as **Project Name**.+- **GitLab Personal Access Token**: Enter a token with read access to the selected project content.+- **GitLab URL**: Enter the GitLab instance base URL, such as `https://gitlab.com` or your self-hosted address.+- **Include Merge Requests**: Enable this to synchronize merge requests.+- **Include Issues**: Enable this to synchronize issues.+- **Include Code Files**: Enable this to synchronize repository source files.+- **Sync deleted files**: Enable this to remove synchronized content deleted from GitLab.-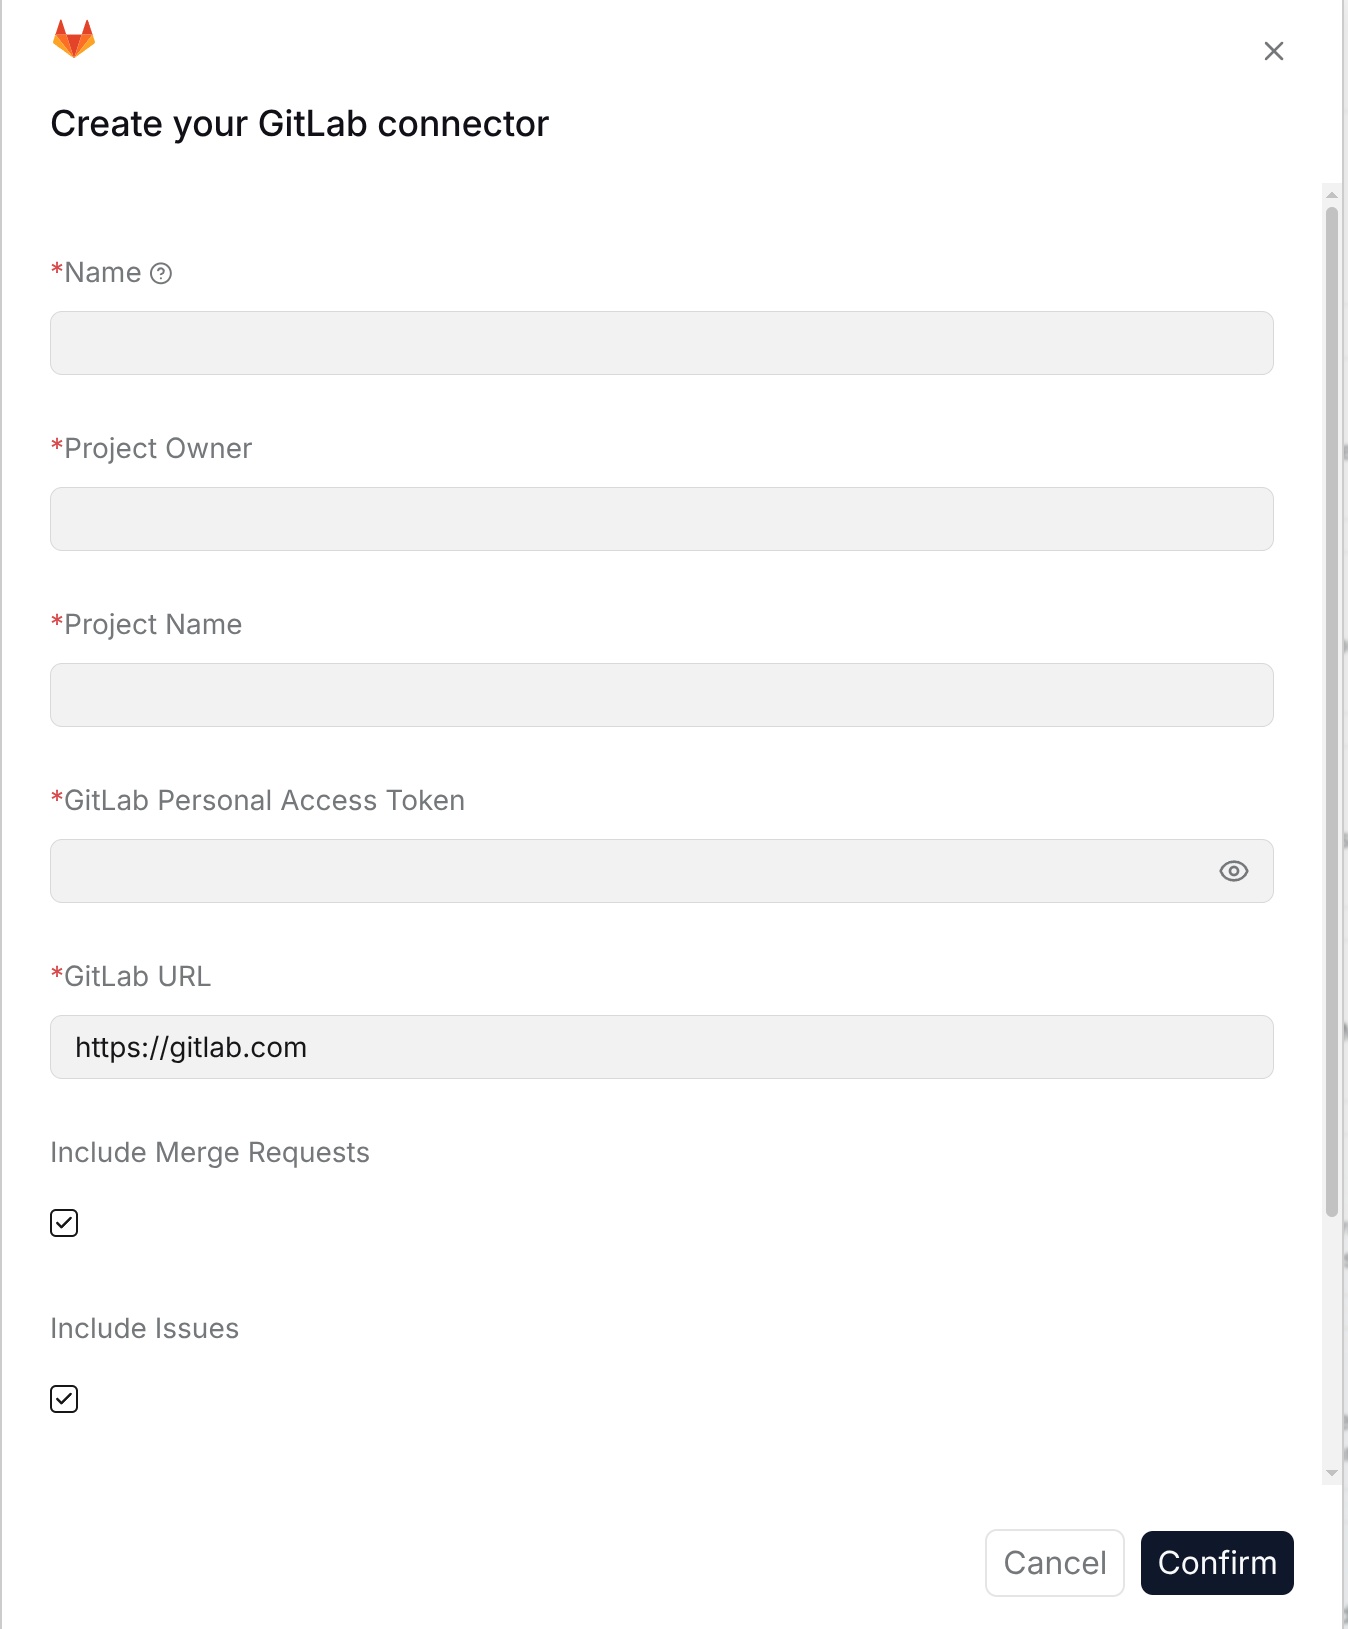+Select the content types you need, click **Test connection**, then **Confirm**.++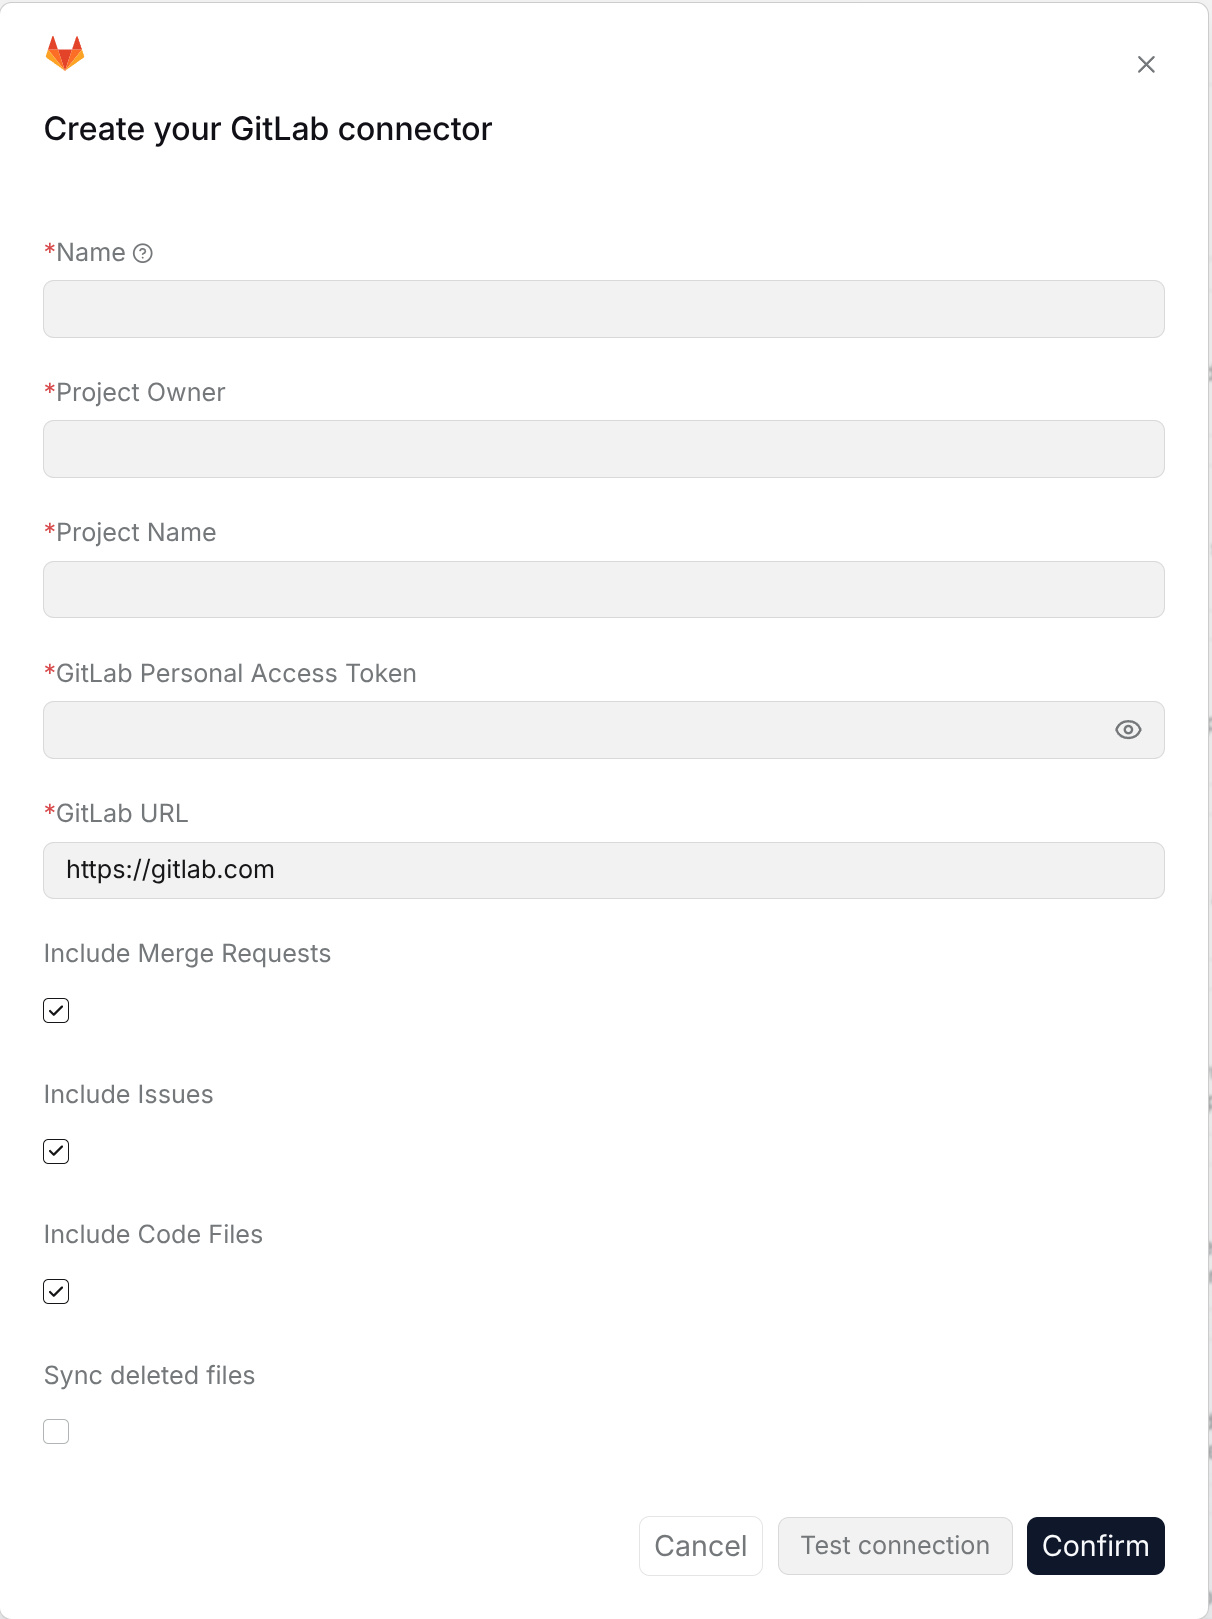## Bitbucket@@ -423,17 +446,27 @@ The Jira data source is used to synchronize issues, comments, and project record**Configuration parameters**:-- **Name**: Customize the name in RAGFlow to identify this Jira connection.-- **Jira base URL**: Fill in the Jira site address.-- **Email or username**: Fill in the Jira account.-- **API token or password**: Fill in the Jira API token or password.-- **Project key**: Fill in the Jira project key that needs to be synchronized.-- **JQL**: Fill in the JQL condition used to limit the synchronization scope.-- **Sync comments**: Select whether to synchronize issue comments.-- **Sync attachments**: Select whether to synchronize attachments.-- **Sync deleted files**: After this is enabled, content deleted from the external system is removed from the knowledge base index.+- **Name**: Enter a connection name for display in RAGFlow.+- **Mode**: Select **Cloud** for Jira Cloud or **Server** for Jira Server / Data Center.+- **Jira User Email / Jira Username**: In Cloud mode, enter the account email. In Server mode, enter the Jira username.+- **Jira Base URL**: Enter the Jira site address, such as `https://your-domain.atlassian.net`, without an issue-specific path.+- **Jira API Token / Jira Password**: In Cloud mode, enter the account's API token. In Server mode, enter its password.+- **Use Scoped Token**: In Cloud mode, enable this only when the API token was created with explicit scopes.+- **Project Key**: Enter the project key, such as `RAG`, to restrict synchronization to that project.+- **Custom JQL**: Enter a complete filter, such as `project = RAG AND updated >= -7d`. When provided, this replaces the **Project Key** filter; include the project condition here if needed.+- **Batch Size**: Enter a positive number of issues to fetch per batch.+- **Attachment Size Limit (bytes)**: Enter the maximum attachment size to download; `10485760` is 10 MiB.+- **Labels to Skip**: Use **+** to add labels. Issues carrying a listed label are excluded.+- **Comment Email Blacklist**: Use **+** to add author email addresses whose comments should be excluded.+- **Include Comments**: Enable this to include issue comments.+- **Include Attachments**: Enable this to download issue attachments within the configured size limit.+- **Sync deleted files**: Enable this to remove synchronized content deleted from Jira.++Click **Test connection** to check the account and site settings, then **Confirm**.++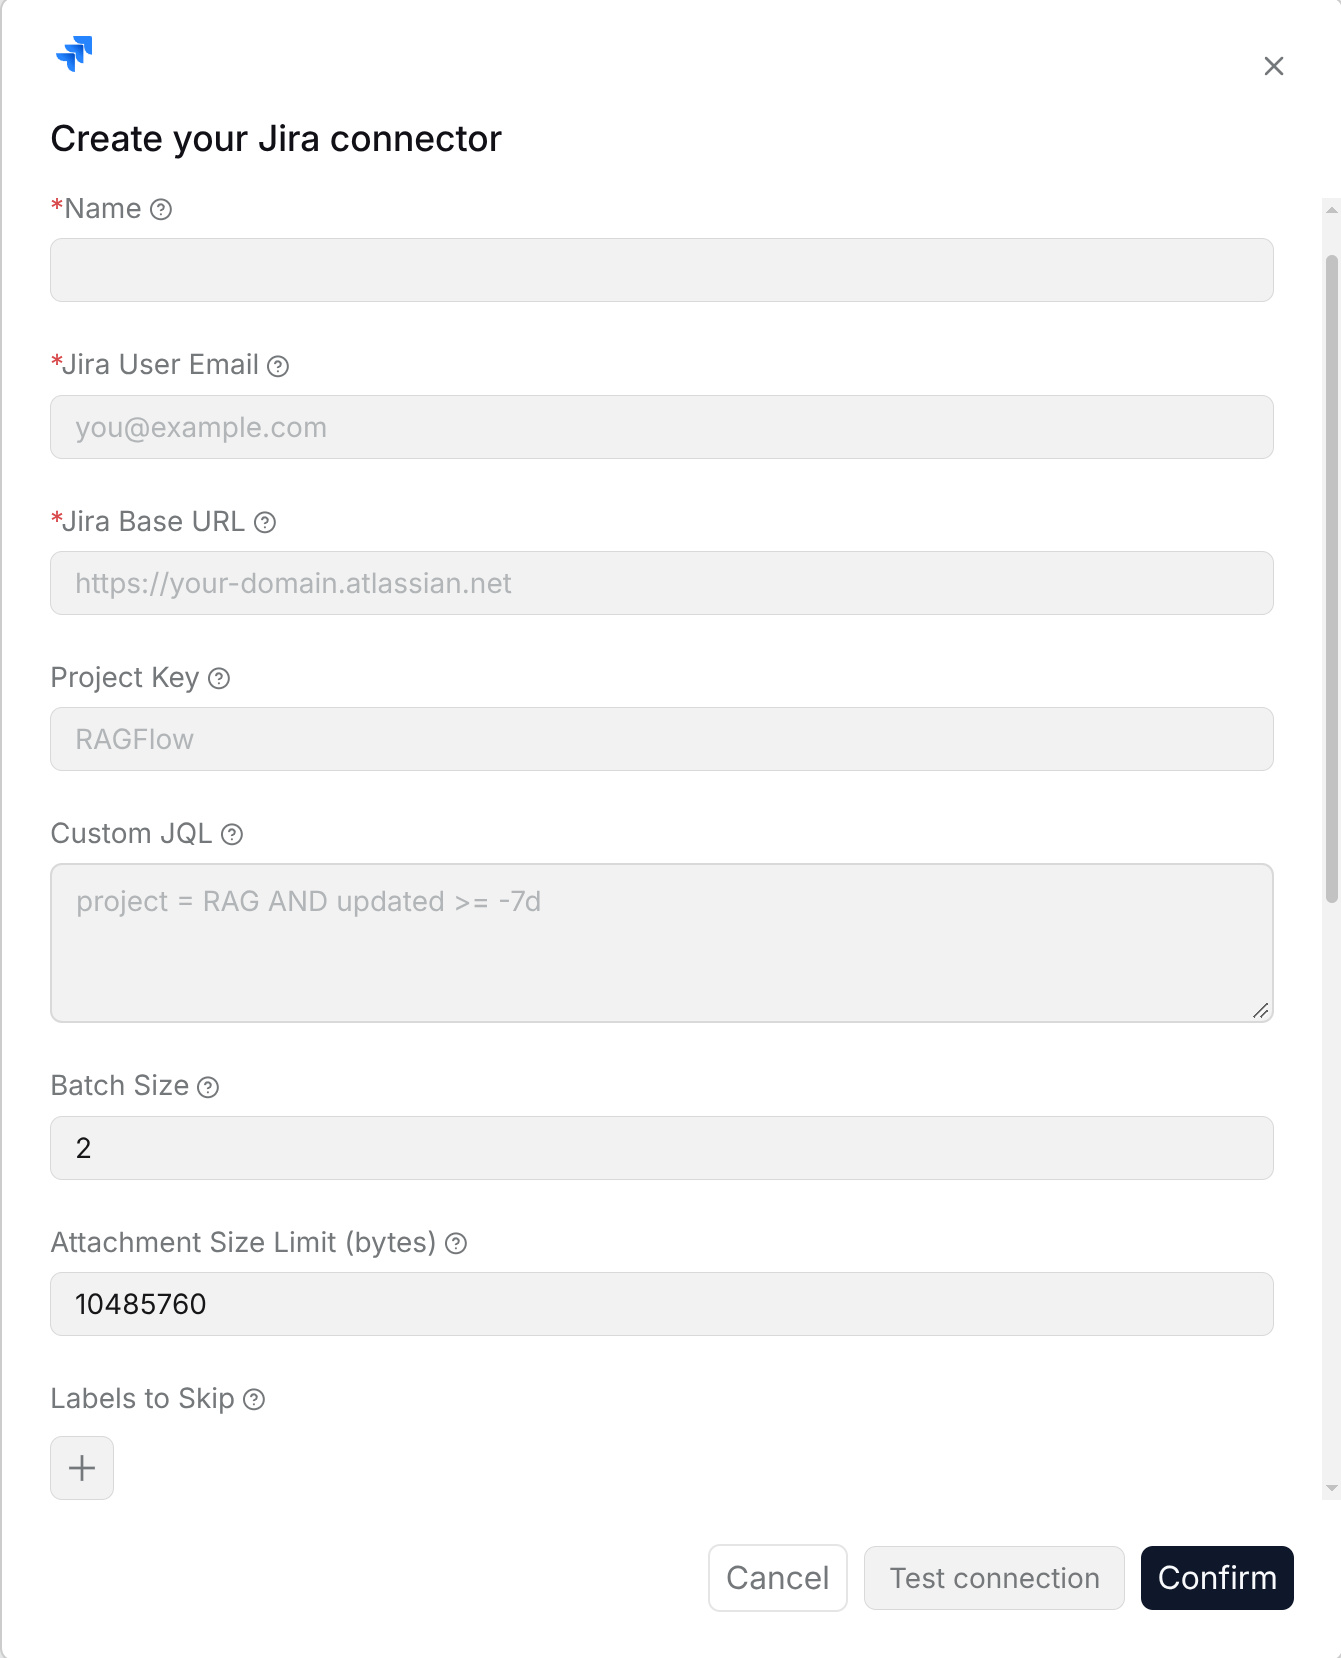-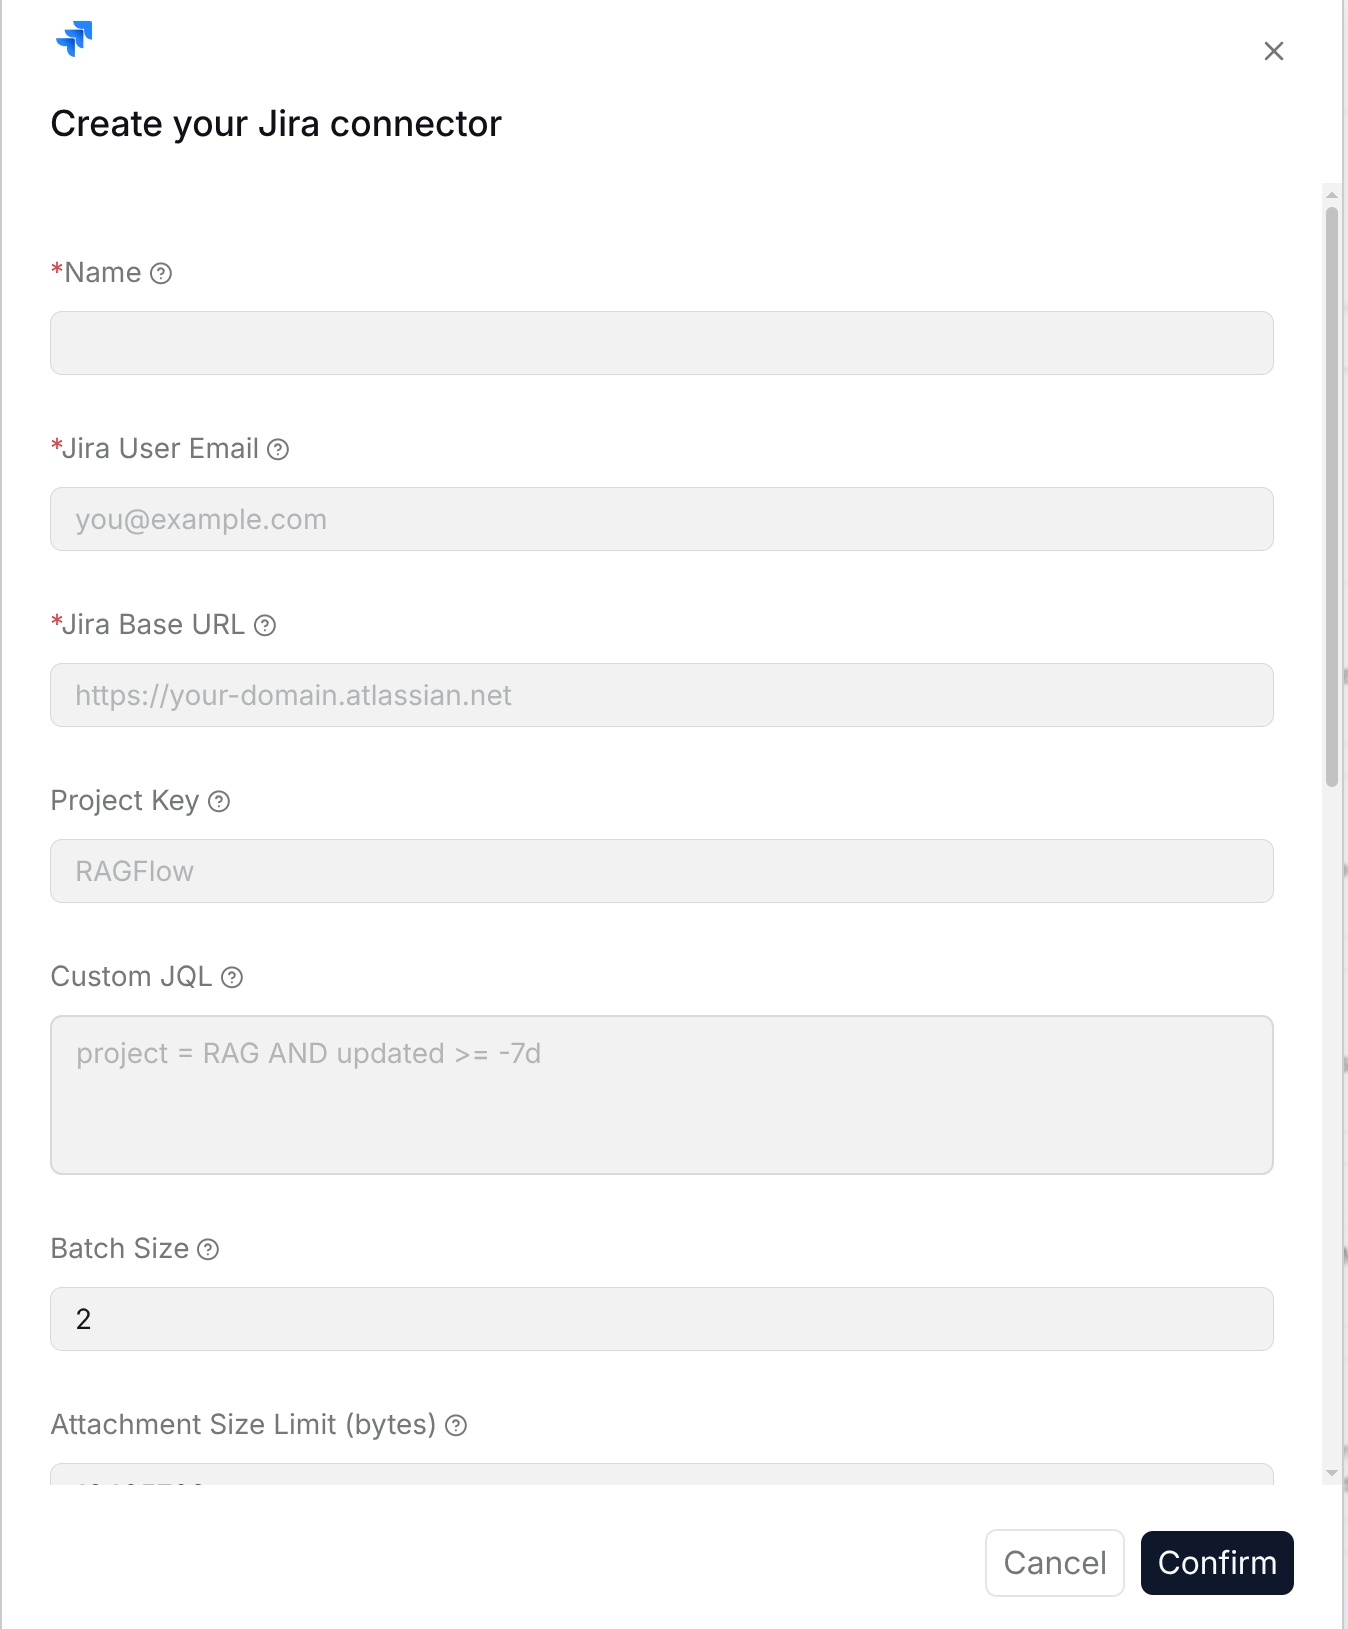+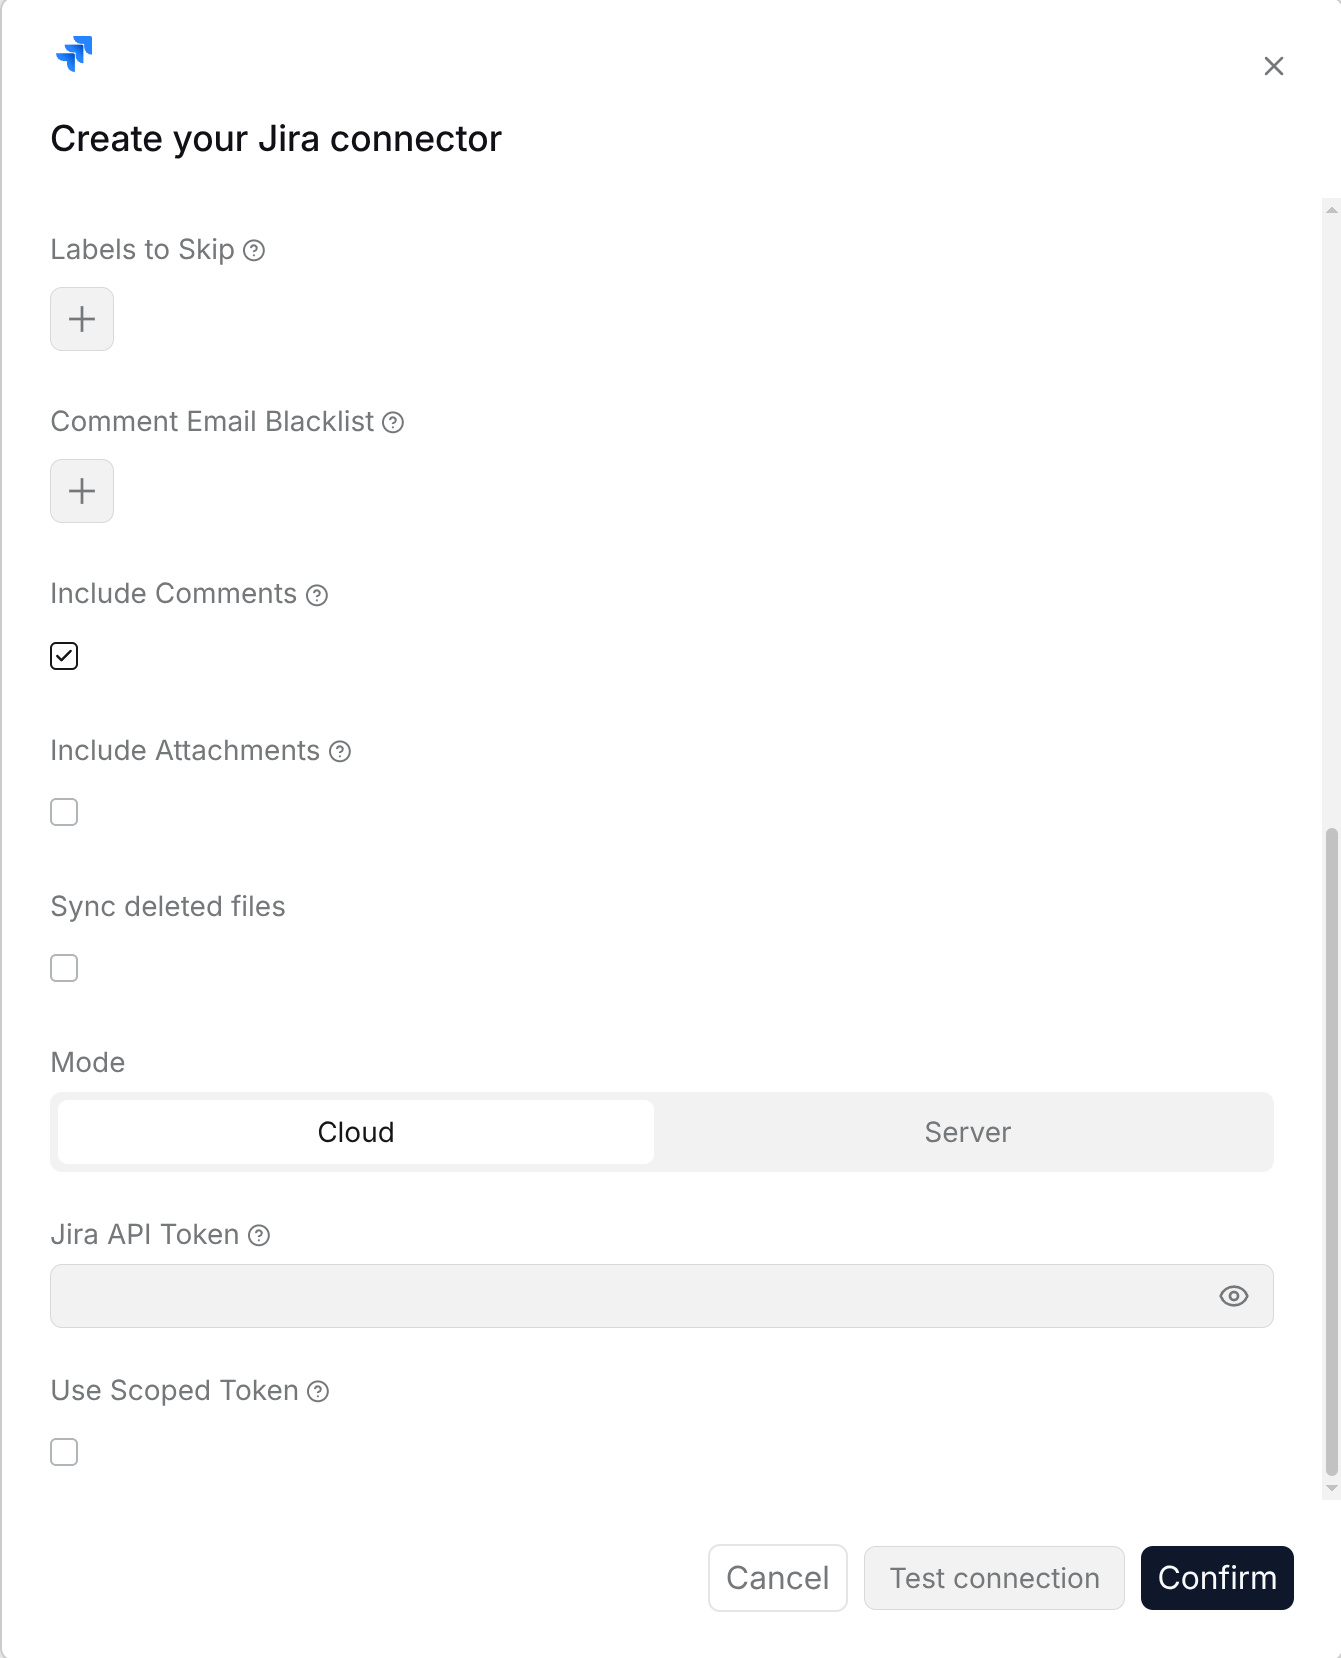## Asanadiff --git a/docs/guides/data_source/overview_and_page_management.md b/docs/guides/data_source/overview_and_page_management.mdindex 1210db119a..93ac456b05 100644--- a/docs/guides/data_source/overview_and_page_management.md+++ b/docs/guides/data_source/overview_and_page_management.md@@ -28,8 +28,8 @@ Select the system you need to connect from the available data sources. The syste1. Fill in the connection name, which is used to identify the connection on the data source page and in the knowledge base.2. Fill in connection information such as the account, token, address, path, or storage scope.-3. Set synchronization parameters as needed, such as sync deletion, refresh interval, cleanup interval, and timeout.-4. Click **Save** to create the data source connection.+3. Set the synchronization options available in the window, then click **Test connection**.+4. Click **Confirm** to create the connection.Different data source creation windows display different fields. Users only need to fill in the fields in the current window. Credentials, addresses, spaces, buckets, database tables, and other information should be based on the actual configuration in the corresponding external system.@@ -51,7 +51,7 @@ Click the settings button on the right side of a connected data source to enterCommon fields on the settings page include:-- **Name**: The name displayed for the current data source connection in RAGFlow.+- **Name**: The connection name, displayed as read-only after creation.- **Authentication information**: The account, token, key, or authorization file used to access the external system.- **Synchronization scope**: The pages, folders, buckets, database tables, channels, or project scope that need to be read.- **Sync deleted files**: After this is enabled, content deleted from the external system is removed from the knowledge base index during subsequent synchronization or cleanup tasks.@@ -60,7 +60,7 @@ Common fields on the settings page include:- **Timeout**: The maximum time that a single connection or synchronization task is allowed to wait.- **Test connection**: Verifies whether the current configuration can successfully connect to the external data source. It is recommended to test the connection before saving the configuration or starting a sync task.-After completing the modification, click **Save**. The new configuration is used for subsequent synchronization tasks. Content that has already been synchronized to the knowledge base is gradually updated according to the next synchronization or cleanup task.+After changing settings, click **Test connection**, then **Save**. With no unsaved changes, the primary button may show **Stop** or **Resume**, depending on the connection status. Updated settings apply to subsequent synchronization tasks.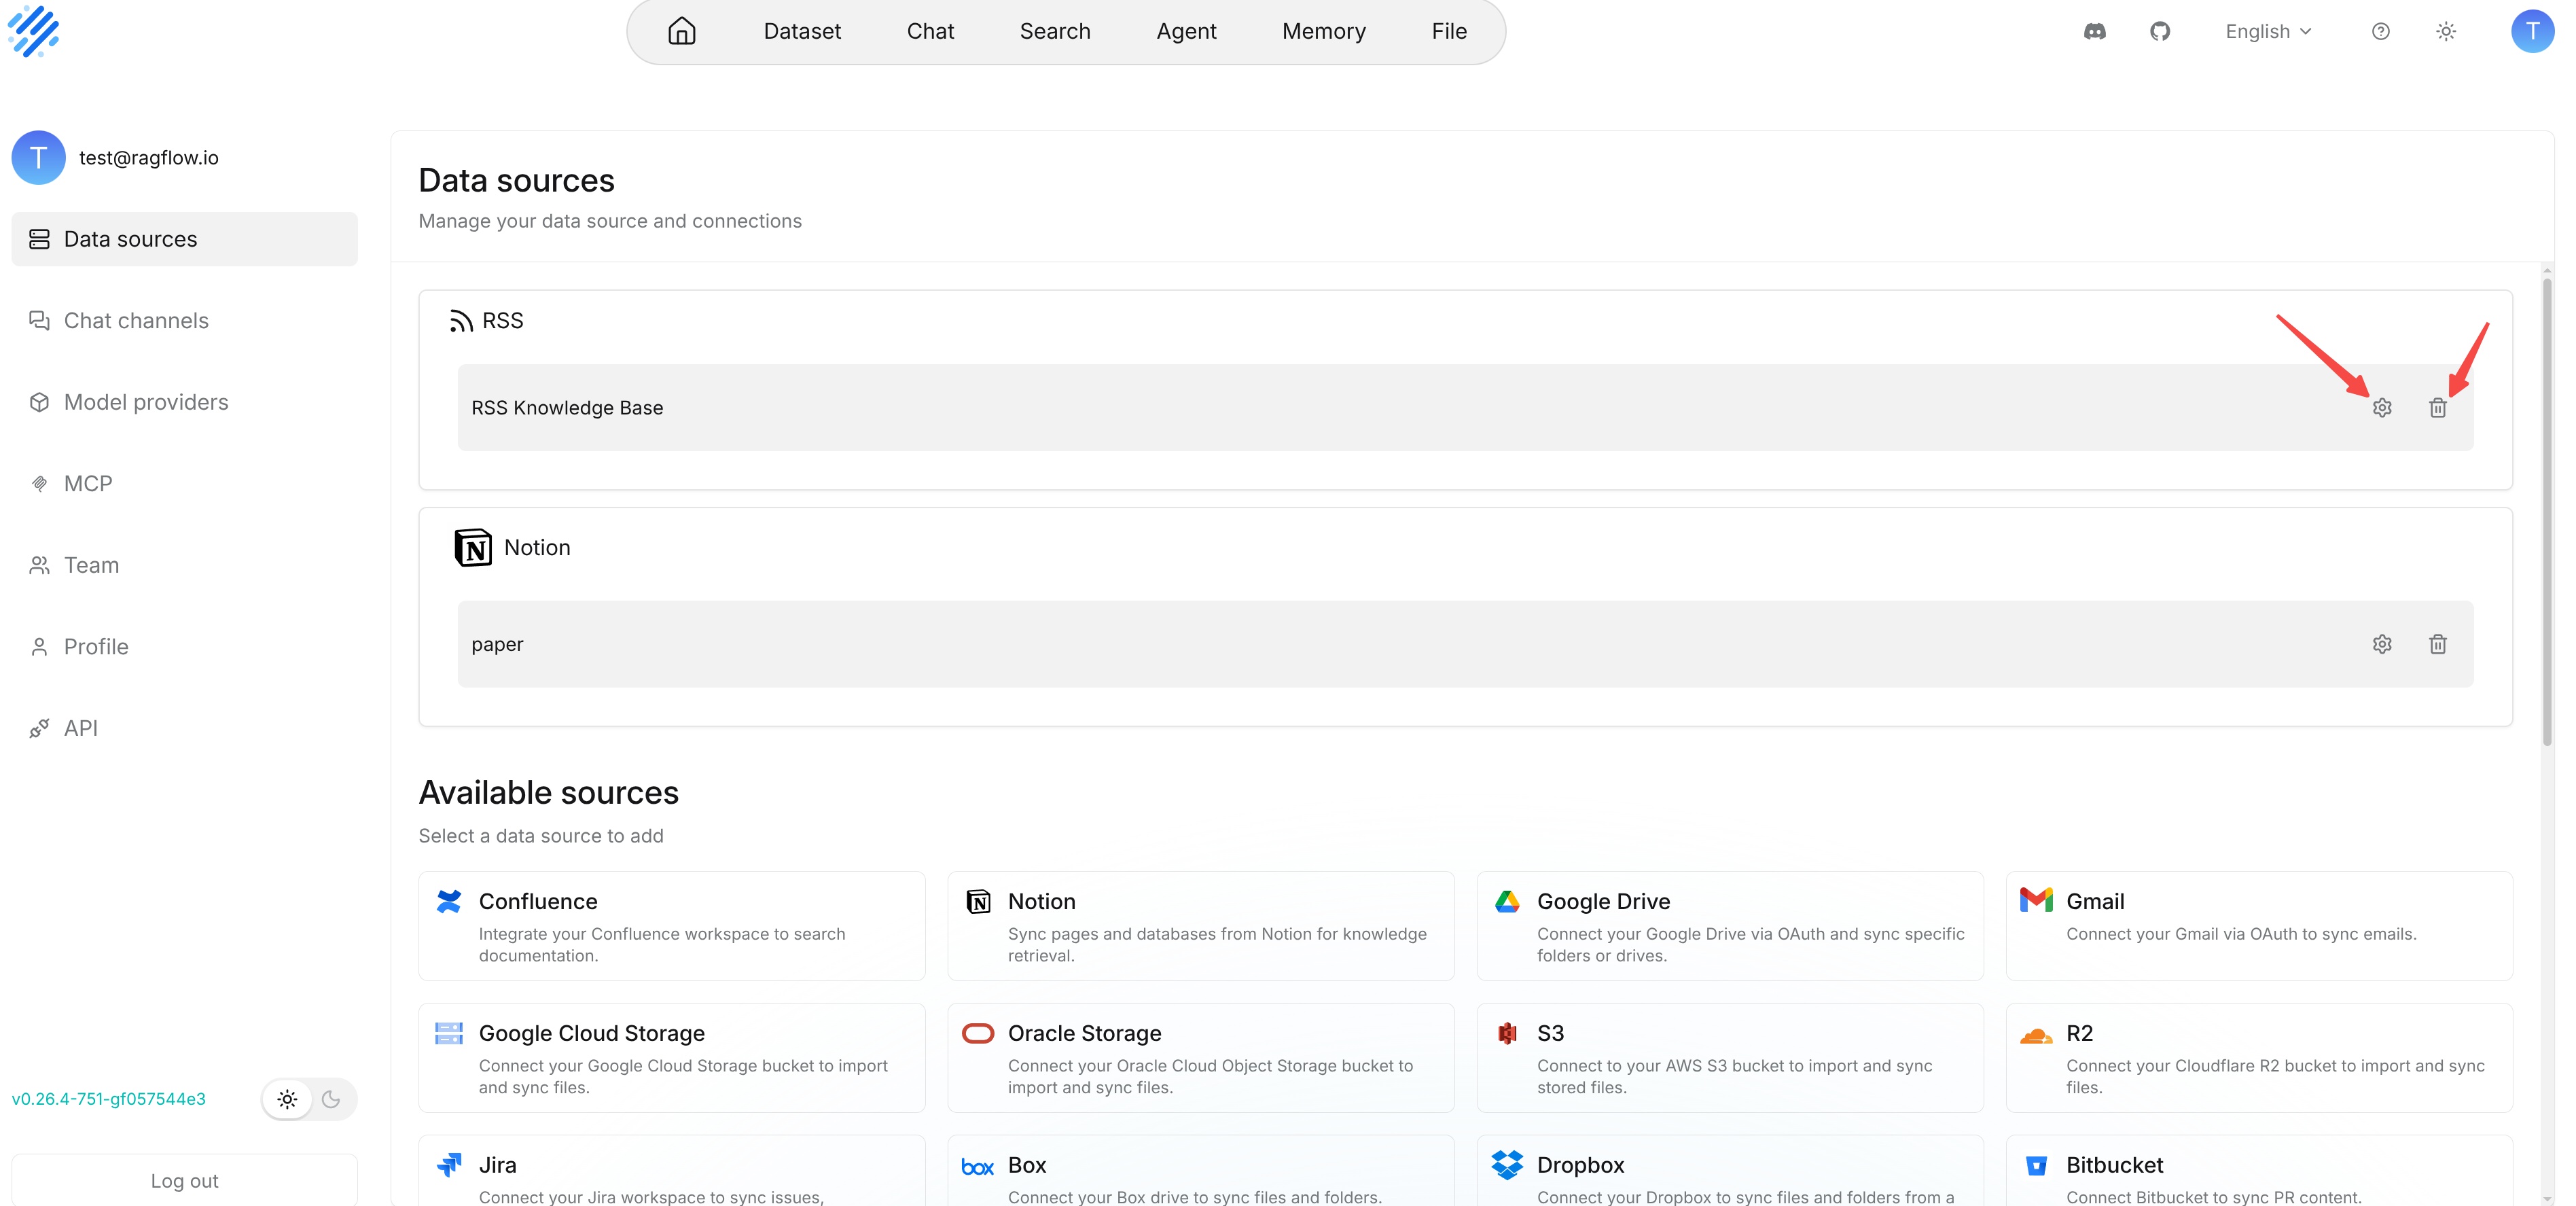@@ -73,7 +73,7 @@ Log fields are described as follows:- **Start time**: The time when the synchronization task started.- **Status**: The execution result of the synchronization task, such as successful, failed, or in progress.- **Knowledge base**: The knowledge base that the synchronization task writes to.-- **Task type**: For example, initial synchronization, incremental synchronization, or cleanup task.+- **Task type**: `sync` synchronizes source content; `prune` removes content deleted from the source.- **Summary**: The synchronization summary or error description, used to troubleshoot permissions, fields, networks, rate limits, and other issues.If the log is empty, it usually means that the data source has not been used by any knowledge base, or that no synchronization task has been triggered.diff --git a/docs/guides/dataset/chunk_parsing_results_and_knowledge_fragment_management.md b/docs/guides/dataset/chunk_parsing_results_and_knowledge_fragment_management.mdindex e7c8360d88..38fd4ae27e 100644--- a/docs/guides/dataset/chunk_parsing_results_and_knowledge_fragment_management.md+++ b/docs/guides/dataset/chunk_parsing_results_and_knowledge_fragment_management.md@@ -15,6 +15,8 @@ Chunks are the retrievable knowledge fragments generated after document parsing.After document parsing is completed, click the document name on the **Files** page to enter the document parsing result page. The parsing result page displays chunks generated from the document. You can use this page to check whether document content has been correctly parsed, split, and stored.+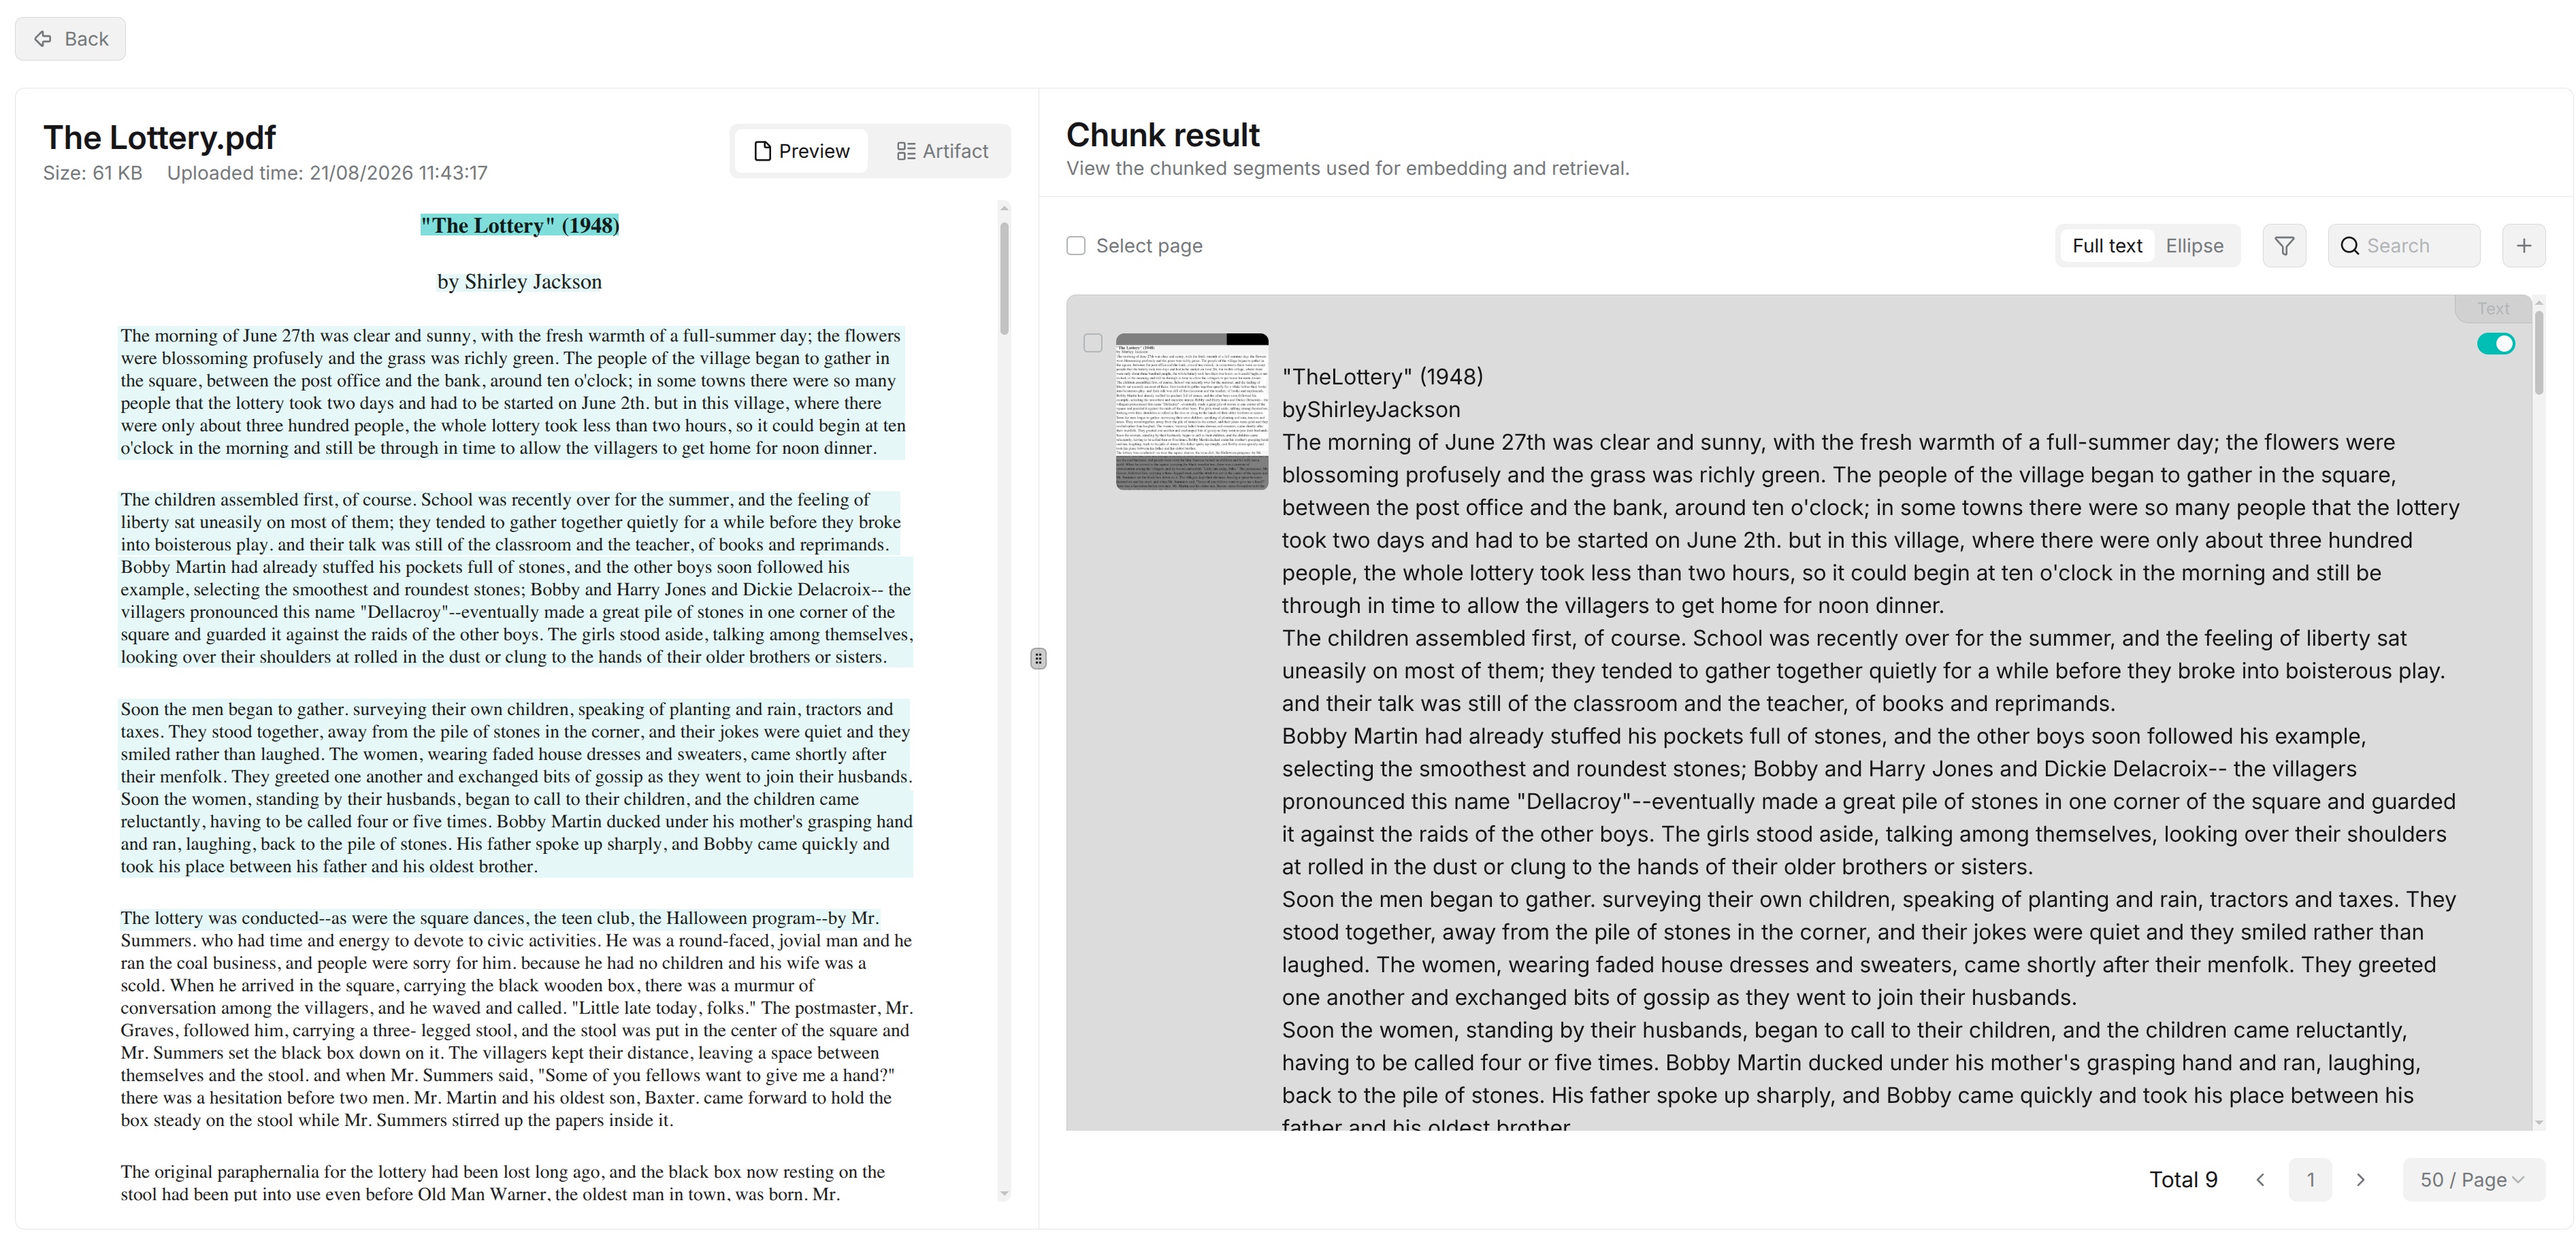+## View Chunk ListThe chunk list displays the chunks generated for the current document. Each chunk usually includes body text, keywords, questions, enabled status, and related operations. For documents that support source preview, the chunk list can be linked with source content. After clicking chunk text, the document preview area jumps to the corresponding source location, making it convenient to compare with the original document and check parsing and splitting results.@@ -25,6 +27,8 @@ For document types that cannot locate source text, parsing results are mainly viWhen a document contains many chunks, use the search and filter functions in the toolbar to quickly locate target content. You can enter keywords to search chunks or filter chunks by enabled status. For chunks with long body text, you can switch between full display and collapsed display as needed to browse parsing results.+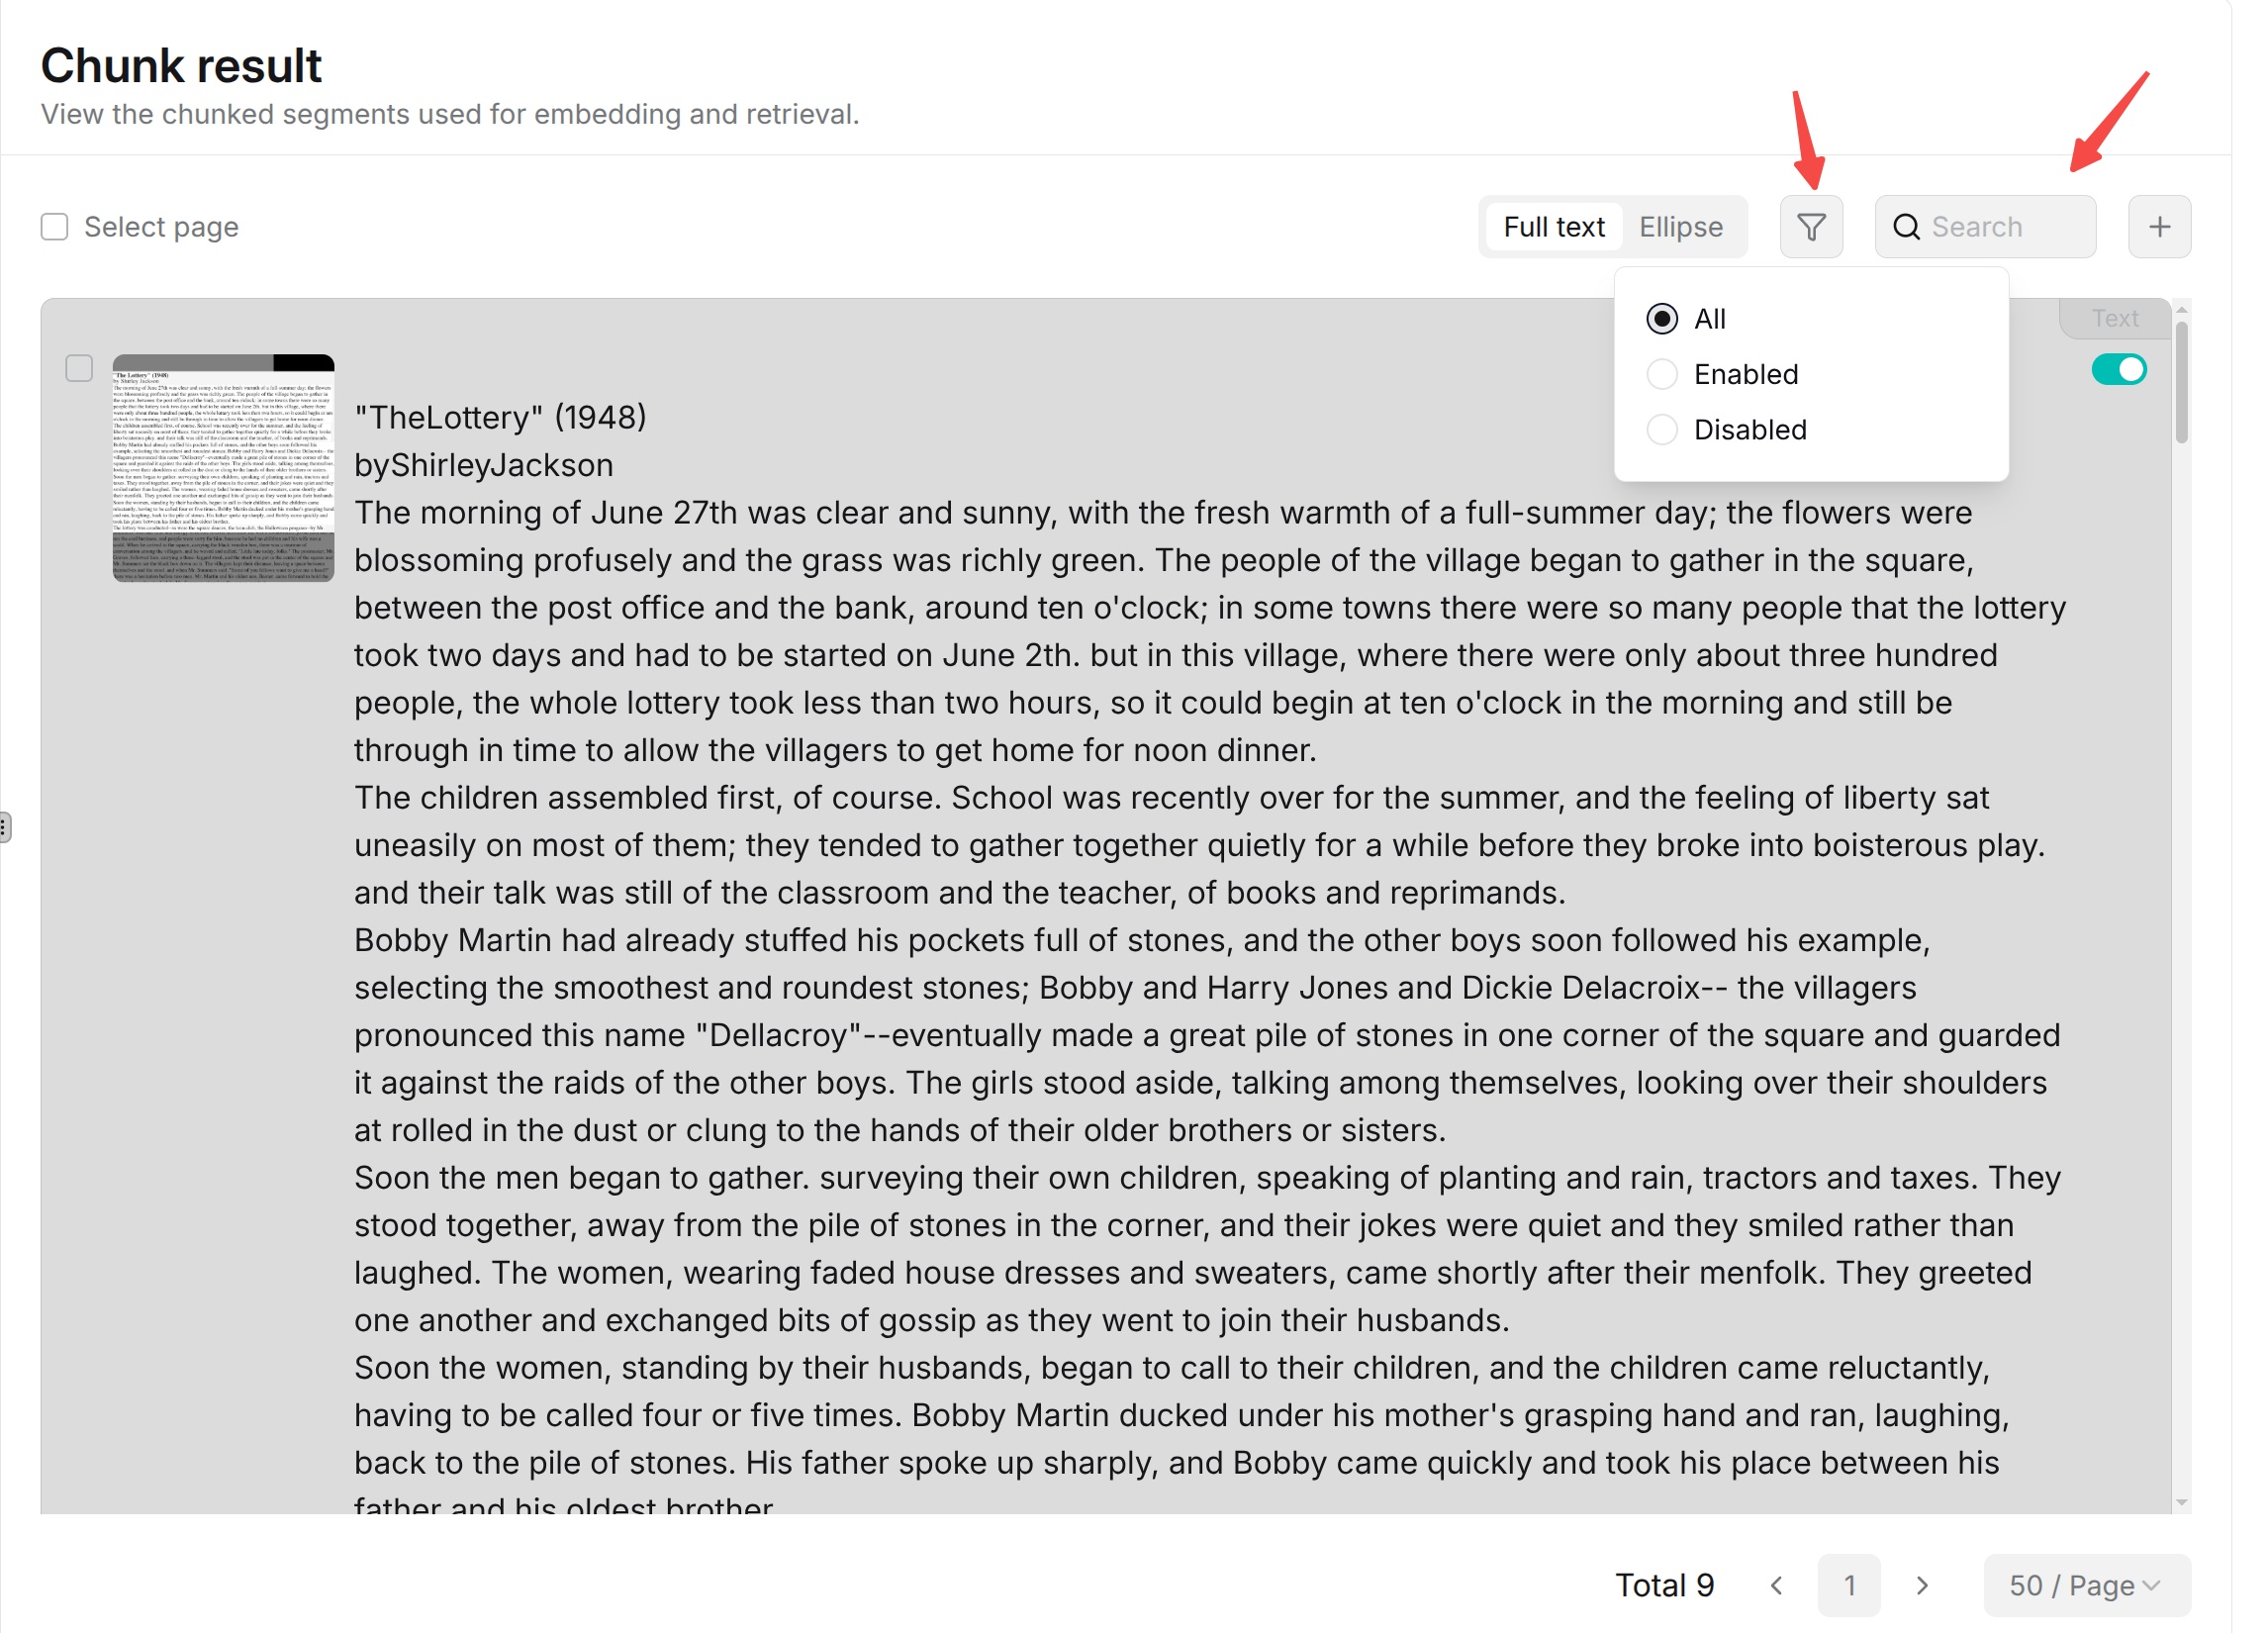+### View Chunk DetailsAfter opening chunk details, you can further view the body text and related information for the knowledge fragment, such as:@@ -47,20 +51,28 @@ If parsing results are inaccurate or content needs to be supplemented, you can eAfter saving the edit, the updated chunk content is used for later retrieval.+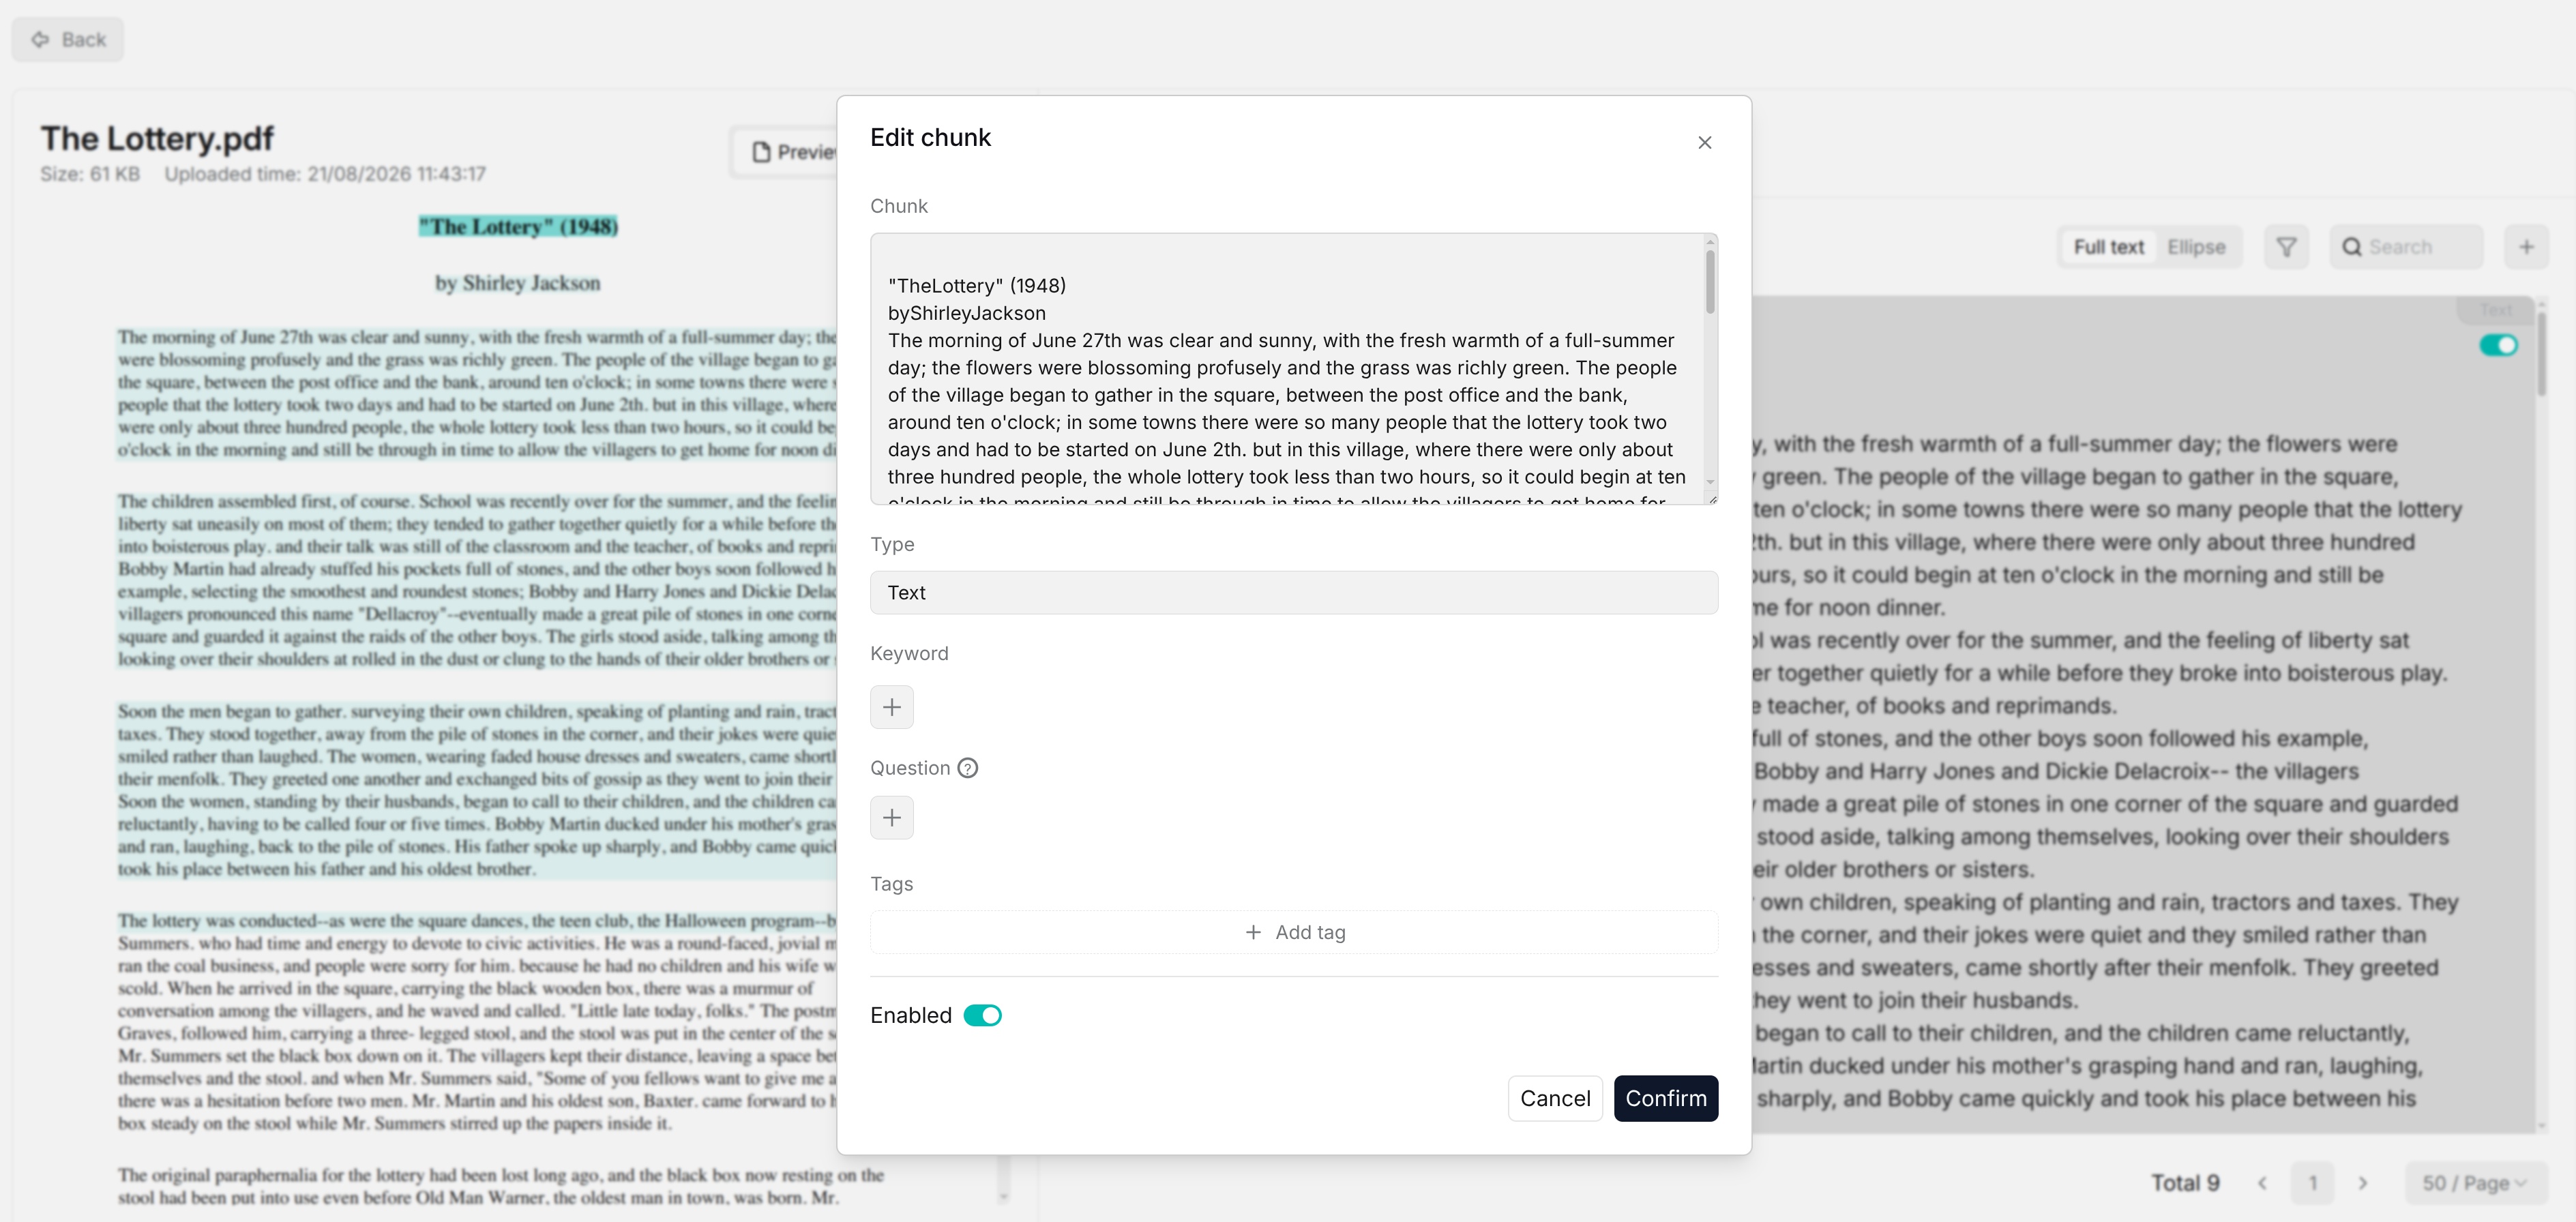+### Add ChunkIf you need to add extra knowledge fragments manually, you can add chunks on the chunk management page. Added chunks are stored under the current document and can be used as content sources for dataset retrieval and Q&A.When adding a chunk, you usually need to enter the chunk content and configure keywords, questions, tags, or enabled status as needed.+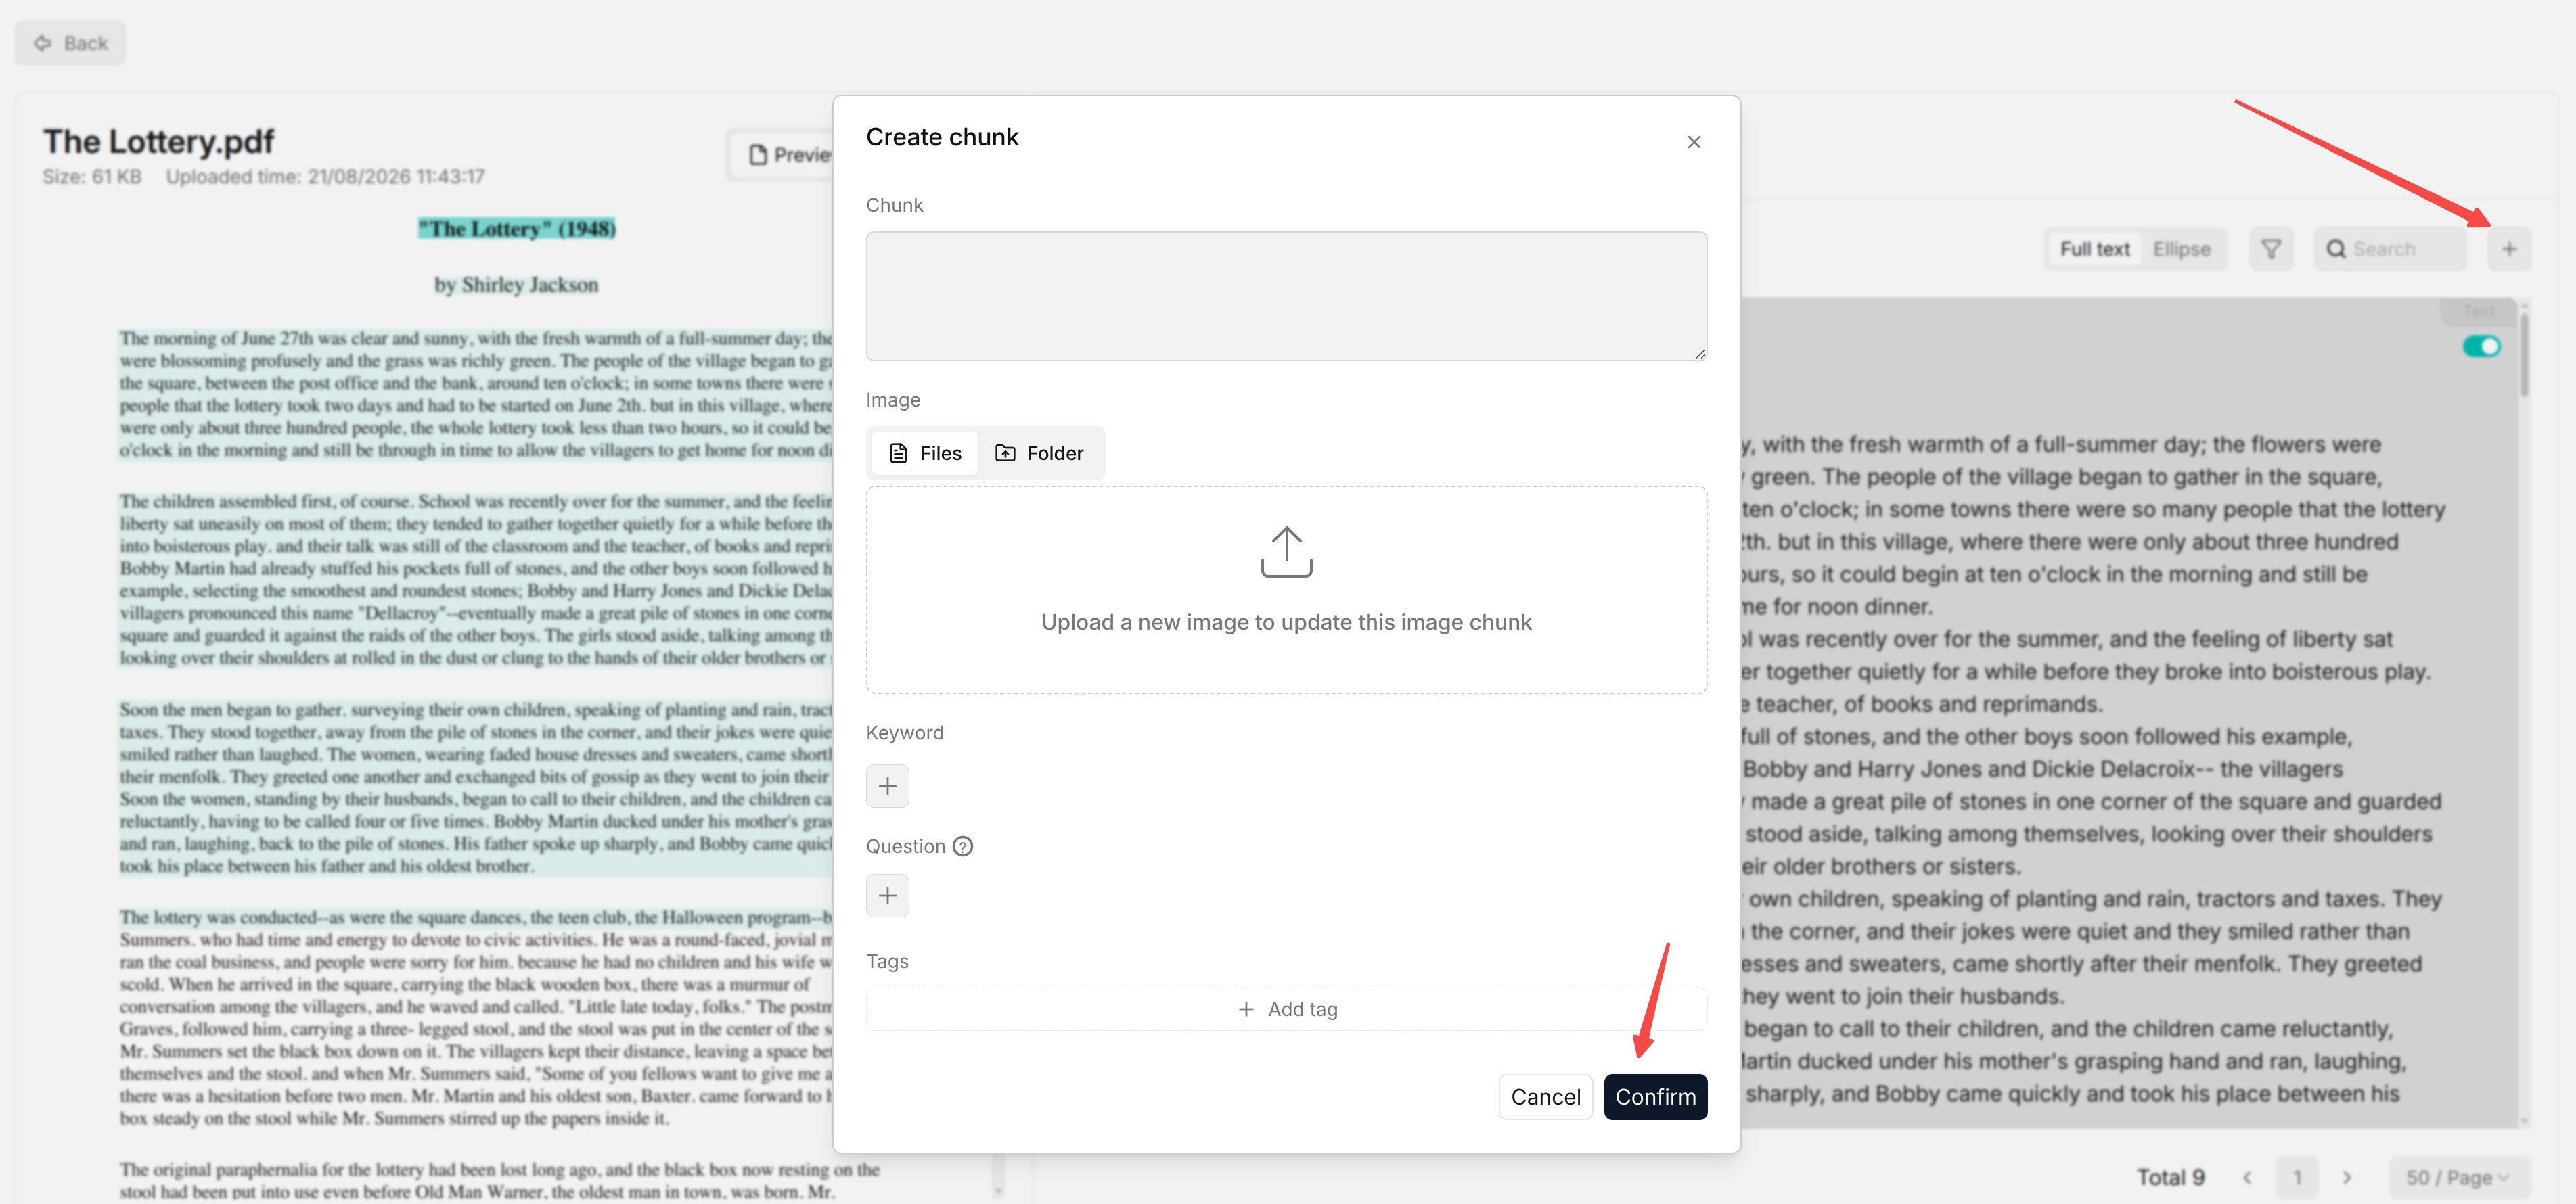+### Enable and Disable ChunkThe enabled status of a chunk determines whether it participates in dataset retrieval. A disabled chunk remains in the parsing result but is not recalled during retrieval.If a chunk contains outdated, incorrect, or temporarily unnecessary content, you can disable it. If the content needs to participate in retrieval again, enable it again.+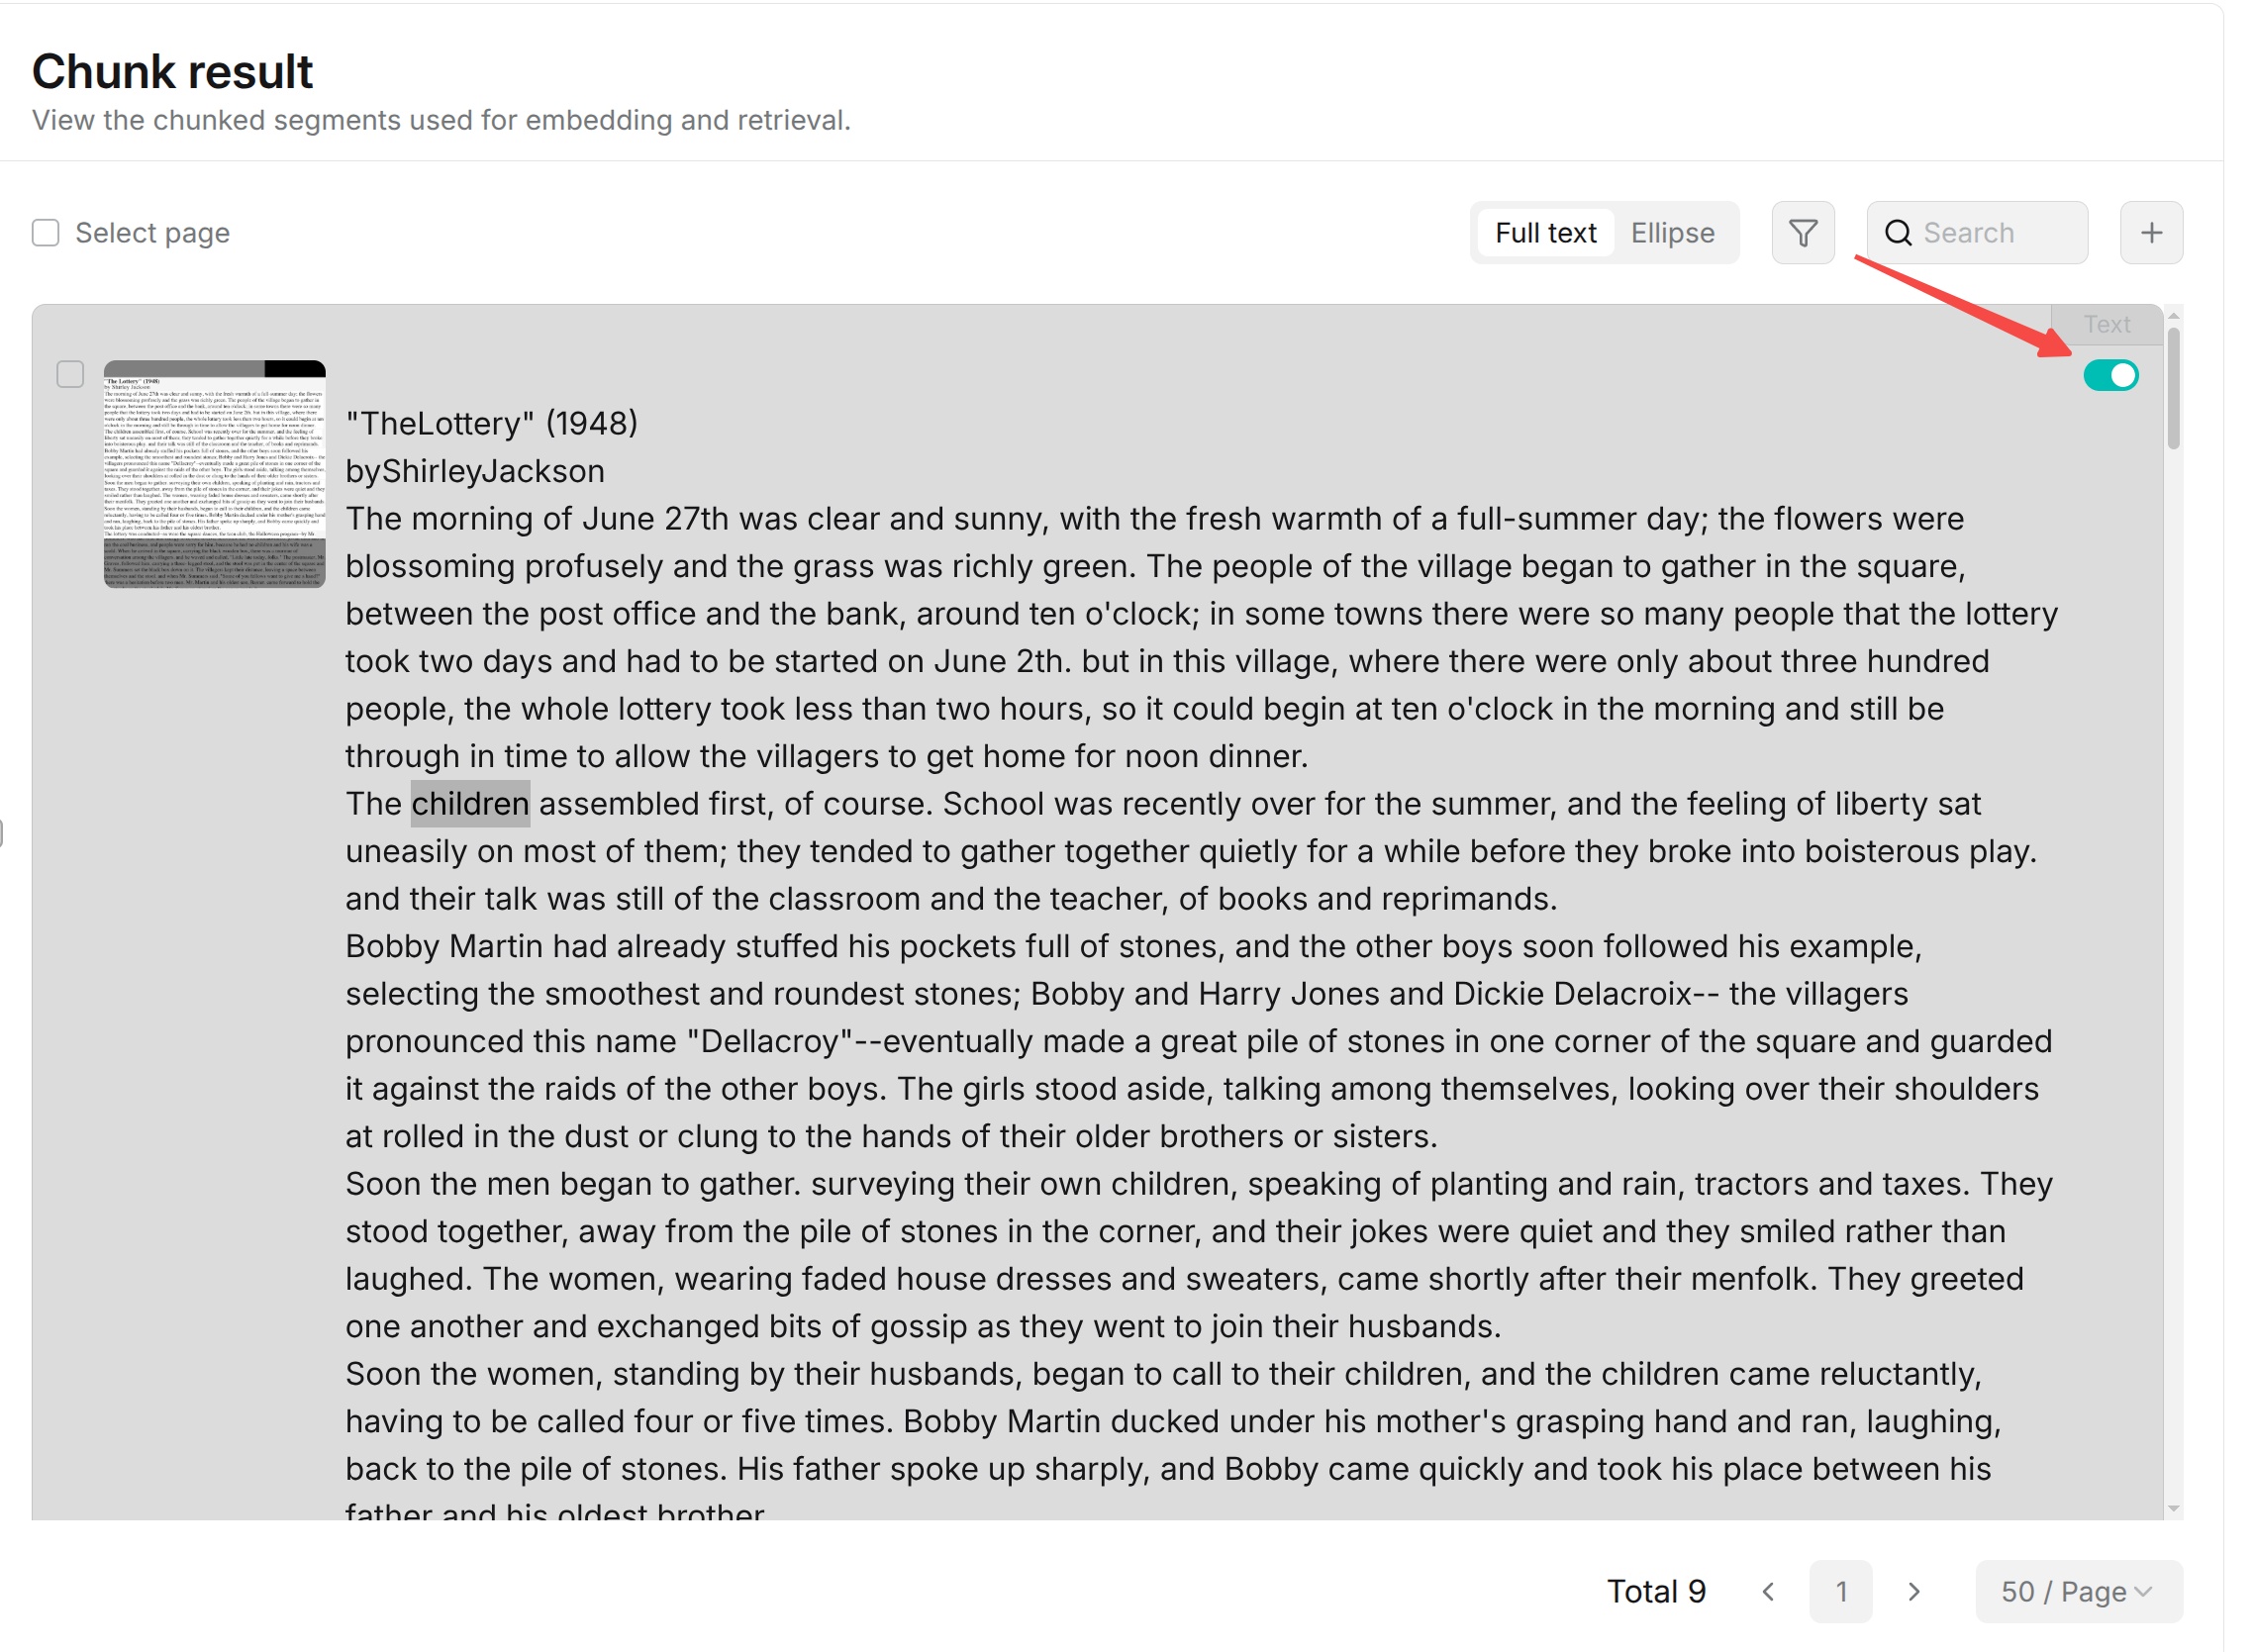+### Delete ChunkDeleting a chunk removes it from the current document's parsing results. It no longer participates in later retrieval or Q&A.Before deleting, confirm that the chunk is no longer needed. If you only want to temporarily exclude it from retrieval, use disable instead.++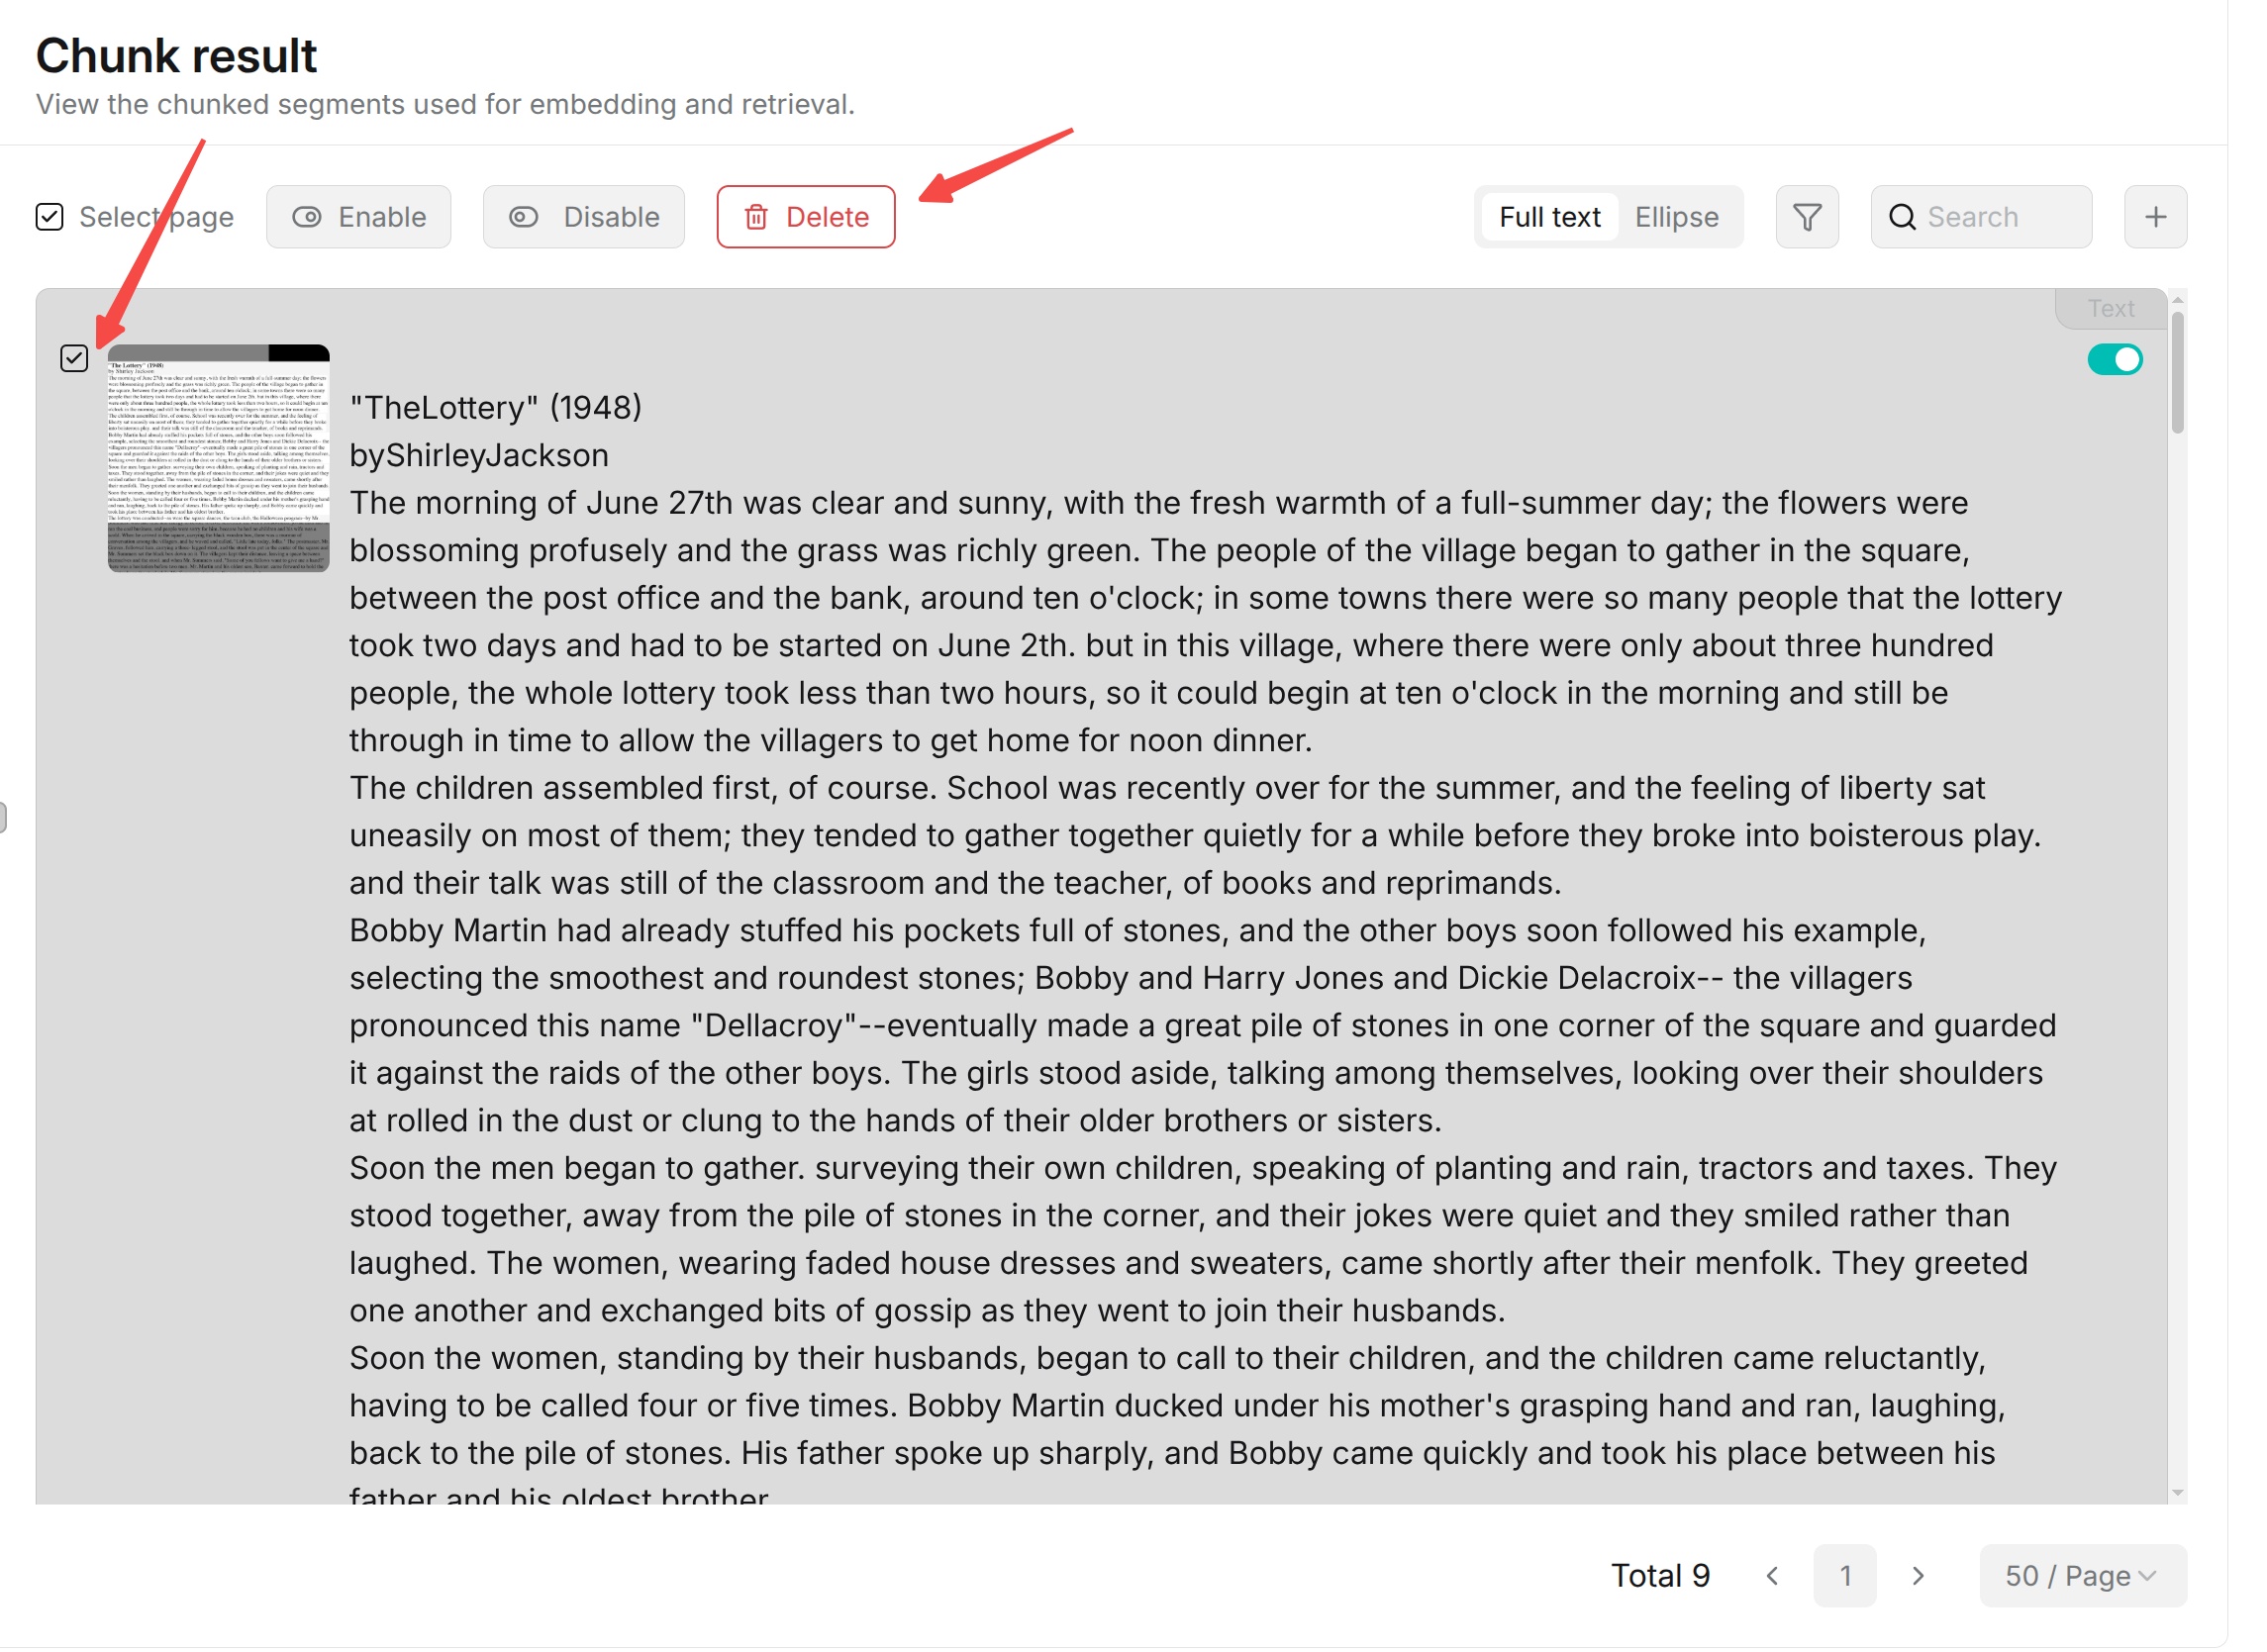diff --git a/docs/guides/dataset/configuration.md b/docs/guides/dataset/configuration.mdindex 276c1c92fe..6b8a633c3f 100644--- a/docs/guides/dataset/configuration.md+++ b/docs/guides/dataset/configuration.md@@ -12,18 +12,19 @@ sidebar_custom_props: {## Basic Information-The configuration page is used to maintain the core configuration of a dataset. Basic information includes **Name**, **Language**, **Avatar**, **Description**, **Embedding model**, **PageRank**.+The configuration page is used to maintain the core configuration of a dataset. Basic information includes **Name**, **Language**, **Avatar**, **Description**, **Permissions**, **Embedding model**, **PageRank**.- **Name**: The dataset name. It can still be modified after creation and is used in list cards and the detail page title.- **Language**: The primary language of the dataset. The language setting affects language assumptions during parsing and model processing.- **Avatar**: The dataset avatar. Image uploads are supported, and the maximum image size is 4 MB.- **Description**: The dataset description, used to describe the material scope, business purpose, or maintenance notes.+- **Permissions**: Choose **Only me** for personal access or **Team** to share the dataset with workspace members.- **Embedding model**: The model used to vectorize chunks. Before the dataset contains chunks, you can change the model directly. Once chunks exist, selecting a different model on the configuration page triggers a compatibility check against sampled existing vectors. The vector dimensions must match, and the average cosine similarity must be at least 0.9. If the check fails, the previous selection is restored. Saving a model change does not automatically re-embed existing chunks.- **PageRank**: Sets the dataset's PageRank score. During retrieval, this score is added to the hybrid similarity score of matched chunks in the dataset, increasing their ranking weight. This is suitable when content from a specific dataset needs higher priority during retrieval across multiple datasets.## Parsing Method-The parsing method determines how a dataset processes uploaded documents and how documents are converted into chunks. **Parse type** in configuration provides two entries: **Built-in** and **Pipeline**.+The parsing method determines how uploaded documents are processed into chunks. In **Parse mode**, select a built-in template or a saved ingestion pipeline from the same drop-down list.### Built-in Parsing@@ -47,7 +48,7 @@ The following built-in parsing methods are available:Selection suggestion: choose the parsing method based on the form of the material itself. Use **General** first for regular documents; use **Table** first for tabular materials; choose the corresponding method for Q&A collections, manuals, papers, images, audio, and emails to reduce later chunk adjustment costs.-### Build-in Parsing Configuration+### Built-in Parsing ConfigurationAfter selecting a built-in template parsing method, you can further configure document parsing, chunking, and content enhancement. Appropriate settings can improve the accuracy and recall of subsequent retrieval.@@ -57,6 +58,12 @@ Different built-in methods display different configuration options. Refer to theParser configuration determines how different types of content are processed. You can configure parsing parameters for each format according to the document structure, layout complexity, and extraction requirements. This helps improve content extraction and the accuracy of subsequent chunk generation.+##### Vision Enhancement++- **Enable vision enhancement**: Uses a vision model to describe image and table blocks. This shared setting applies across document formats.+- **Model**: Select an available vision model after enabling enhancement.+- **System prompt**: Set instructions for the generated descriptions. Vision enhancement adds model calls and token usage.+##### PDF ParsingConfigure how PDF documents are parsed. You can select a parsing method based on the PDF layout and set options such as page ranges and vision models.@@ -76,69 +83,42 @@ Configure how PDF documents are parsed. You can select a parsing method based onExternal models are often better suited to complex layouts, scanned documents, images, borderless tables, and mixed text and images. However, they incur additional model calls and token usage. The available models depend on the configured model providers and their capabilities.- **Page range:** Specifies which PDF pages to parse. You can set a start and end page and add multiple page ranges to avoid processing unnecessary content.-- **Disable vision model:** Controls whether a VLM is used during PDF parsing. When this option is enabled, no vision model assists with parsing. When disabled, a vision model can help interpret complex layouts or content combining text and images.-- **Model:** Selects the vision model to use when PDF parsing requires one. A more capable vision model may provide a more complete understanding of complex layouts and visual content. Parsing quality and token usage depend on the selected model.##### Table Parsing-Configure how tables in documents are parsed. The system can use a built-in parser or a vision model to recognize table structure and extract text and cell information.--- **Parsing method:** Selects a parser or model for tables. Methods differ in table structure recognition, cell content extraction, and handling of complex layouts. Built-in methods include:- - **DeepDOC:** RAGFlow's built-in document parser. It recognizes table structure and extracts cell content, making it suitable for most standard tables.- - **TCADP Parser:** An open-source parser from Tencent that can recognize and parse tables in documents.-- You can also select an external model already configured in the system. Available models are grouped by model provider in the drop-down list. For complex tables, borderless tables, merged rows or columns, or tables that require visual interpretation, choose an external model with vision or document understanding capabilities as needed. External models may incur additional model calls and token usage.-- **Disable vision model:** Controls whether a vision model is used for table parsing. Built-in parsers may be sufficient for regular tables with clear boundaries. A vision model can help with complex or borderless tables.-- **Model:** Selects the vision model used for table parsing when vision support is enabled. Models may differ in their understanding of table structure and complex layouts, as well as in token usage.--For ordinary text-based PDFs, consider starting with a built-in parser. For scanned documents, multi-column layouts, complex tables, and mixed text and images, a vision model may improve parsing quality. Because vision models incur additional calls and token usage, enable them according to the document type.+Select **DeepDOC** or **TCADP Parser** from the **Parser** list to extract table content and structure. Vision models are configured through the shared **Enable vision enhancement** setting above.##### Image Parsing-Configure how image files are parsed so that text or visual content can be converted into text for subsequent chunking and retrieval.+- **OCR**: Extracts text from images and is enabled by default.+- **OCR model**: Select **DeepDoc** for local OCR or an available **PaddleOCR** model.+- **Enable vision enhancement**: Adds visual descriptions using the shared model and prompt settings above. It can run together with OCR.-- **Parsing method:** Selects how image files are processed.- - **OCR:** Uses optical character recognition to extract text from images. It is suitable for screenshots, scans, photographs, and other images containing readable text.- - **External model:** Uses a configured model with visual understanding capabilities. Compared with traditional OCR, such a model can recognize text and interpret layouts, charts, objects, and relationships between text and images. External models are grouped by model provider in the drop-down list. The available models depend on the configured providers and model capabilities.--For images that mainly contain clear text, consider starting with OCR. For charts, complex layouts, interface screenshots, or content that requires visual understanding, select an external vision model. External models may incur additional model calls and token usage.--Parsing quality also depends on image clarity, text size, layout, and overall image quality.+Keep OCR or vision enhancement enabled so images can produce searchable text. To turn OCR off, first enable vision enhancement.##### Markdown ParsingParse Markdown documents while preserving their text and basic structure for subsequent chunking.-- **Remove original table of contents:** Removes an existing table of contents during parsing to avoid repeating title links and body content.-- **Disable vision model:** Controls whether a vision model assists with Markdown parsing. When enabled, no vision model is used. When disabled, the selected vision model can process images or other content in the Markdown document that requires visual understanding.-- **Model:** Selects the vision model when one is needed. Available models depend on the configured model providers and their capabilities. External models may incur additional model calls and token usage.-##### HTML ParsingParse HTML documents to extract useful text and structured content while filtering page elements that need not be included in knowledge base retrieval.-- **Remove original table of contents:** Removes an existing table of contents or navigation list to reduce duplicated content.- **Remove headers and footers:** Attempts to remove repeated headers and footers, reducing the effect of navigation and copyright information on chunking and retrieval.-For HTML files saved or exported from websites, decide whether to enable these options based on the page structure. Keep headers, footers, or tables of contents when they contain information you need.+For HTML files saved or exported from websites, keep headers and footers if they contain information you need.##### DOC Parsing-Parse Word documents in `.doc` format. You can choose whether to remove the table of contents, headers, and footers, and whether to use an external vision model for complex content.+Parse Word documents in `.doc` format. Use **Remove headers and footers** to exclude repeated content. Visual descriptions use the shared **Enable vision enhancement** setting above.-- **Remove original table of contents:** Removes the existing table of contents to reduce duplication between the contents list and the document body.- **Remove headers and footers:** Attempts to remove repeated headers and footers so that page numbers, document titles, and copyright information do not repeatedly appear in chunks.-- **Disable vision model:** Controls whether an external vision model assists with DOC parsing. When enabled, no vision model is called. When disabled, you can select a configured external model to further parse images, complex layouts, or other visual content.-- **Model:** Selects an external model to assist with DOC parsing. Only models already configured in the system are available. The options depend on the connected providers and model capabilities. External models may incur additional model calls and token usage.##### DOCX Parsing-Parse Word documents in `.docx` format. You can choose whether to remove the table of contents, headers, and footers, and whether to use an external vision model for complex content.+Parse Word documents in `.docx` format. Use **Remove headers and footers** to exclude repeated content. Visual descriptions use the shared **Enable vision enhancement** setting above.-- **Remove original table of contents:** Removes the existing table of contents to avoid duplicating headings and body content.- **Remove headers and footers:** Removes repeated headers and footers to reduce irrelevant information in subsequent chunks and search results.-- **Disable vision model:** Controls whether an external vision model is used for DOCX parsing. When enabled, no vision model is used. When disabled, an external model can help interpret images, complex layouts, and other visual content.-- **Model:** Selects an external model to assist with DOCX parsing. This option only lists configured external models; it does not offer built-in parsing methods such as DeepDOC, Naive, or Docling. The available models depend on the configured model providers.##### PPTX Parsing@@ -338,6 +318,8 @@ If no pipeline is currently available, you can use the entry provided in the pipAfter saving, the system generates corresponding metadata from document content during subsequent document parsing based on these field definitions.+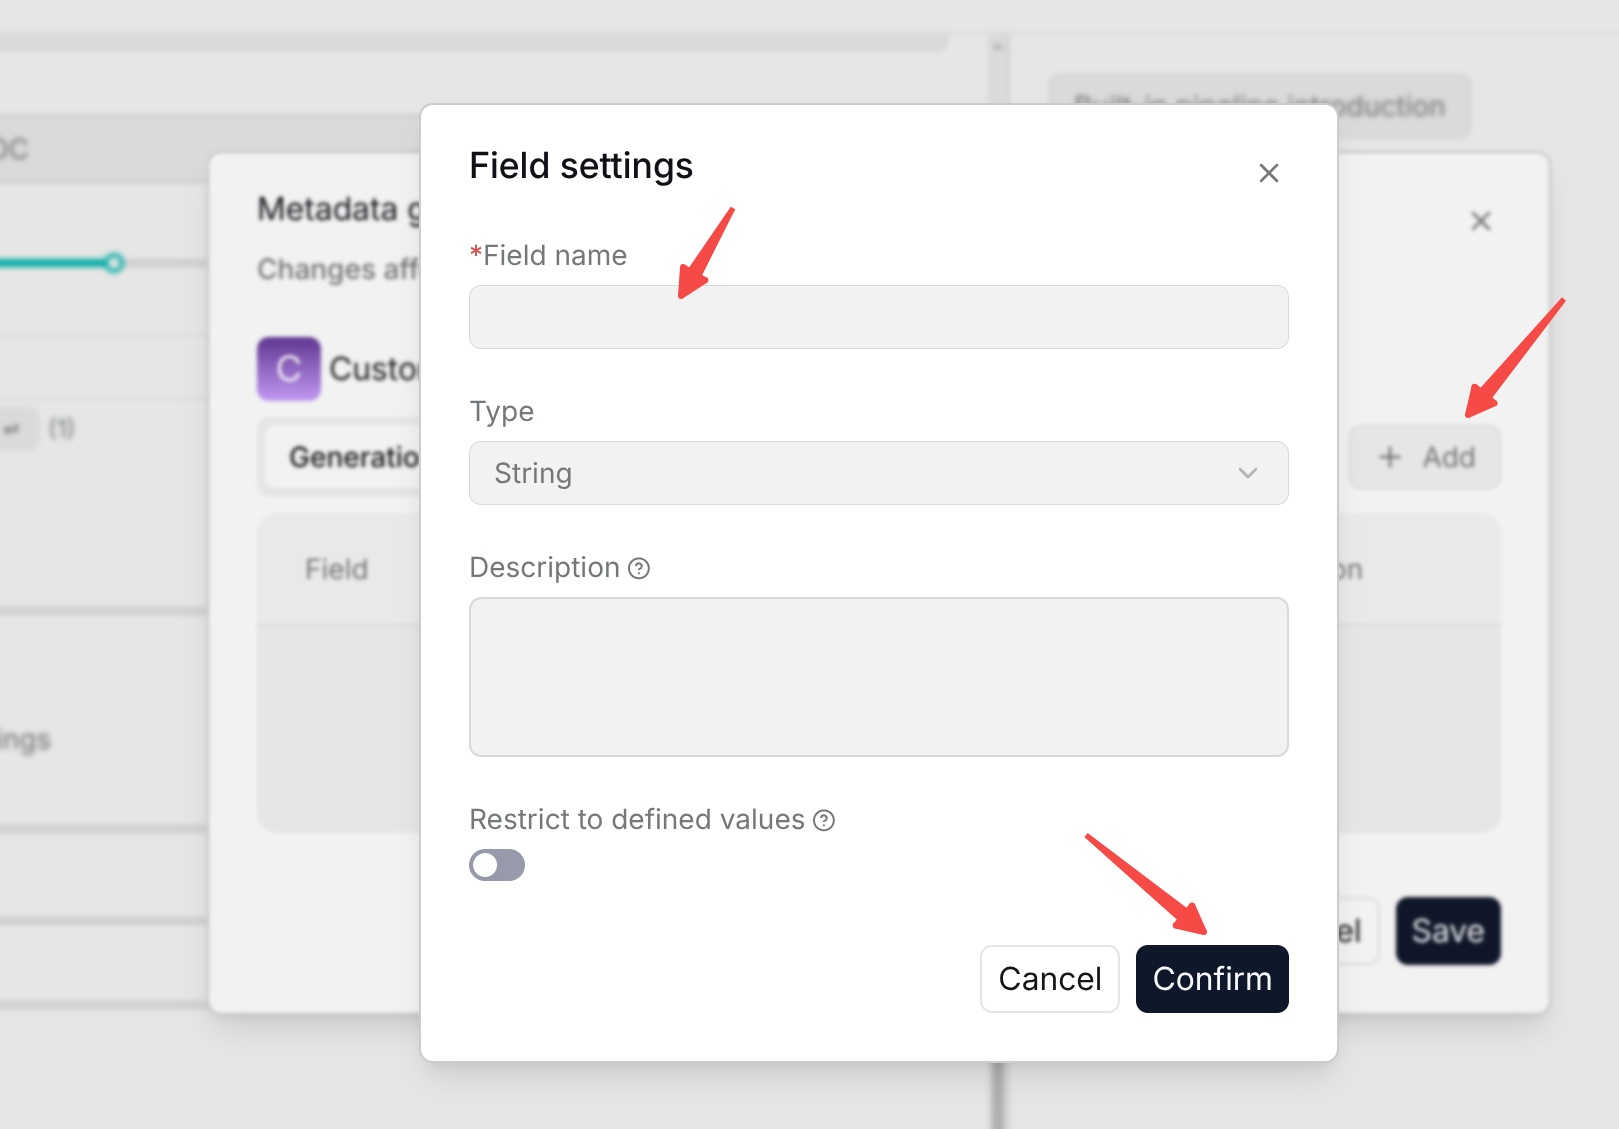+#### Built-in: Built-in Metadata**Built-in** provides system-predefined metadata fields. You do not need to manually create or configure field rules. Use the switch on the right side of each corresponding field to choose whether to generate that metadata during document parsing. The following built-in fields are currently supported:@@ -347,6 +329,8 @@ After saving, the system generates corresponding metadata from document contentSelect the fields to use, enable their switches, and then click **Save** to save the configuration. Generated metadata can be used in document management and retrieval filtering. To view or edit generated metadata, [**Metadata management**](../dataset/metadata_management.md).+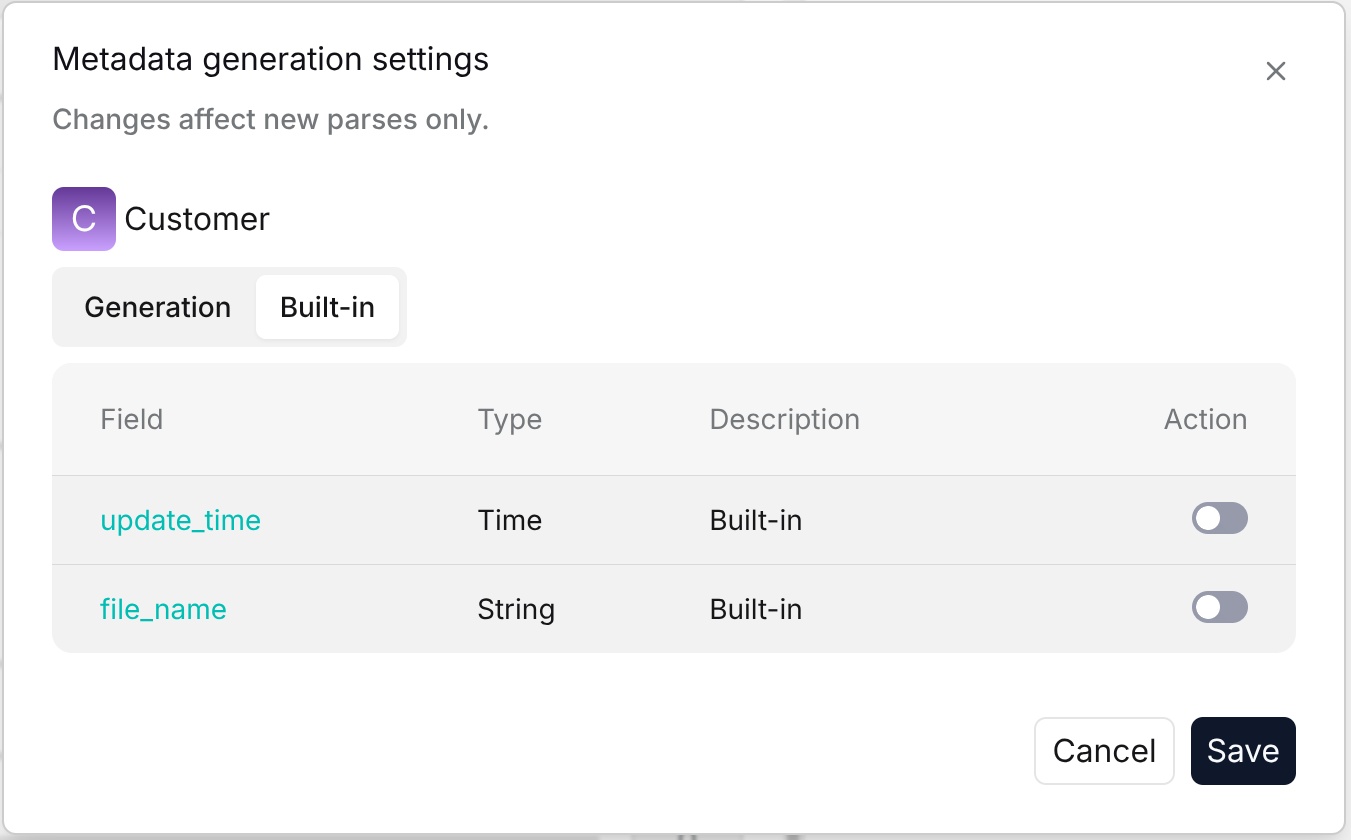+### Table Column Role ConfigurationWhen a dataset uses **Table** as the built-in parsing method, you can use **Column mode** to set the purpose of each table column during parsing and retrieval. A column can be included in chunk text for indexing, used only as metadata, or used for both.diff --git a/docs/guides/dataset/dataset_list_and_creation.md b/docs/guides/dataset/dataset_list_and_creation.mdindex f27e9b3204..652a091ff3 100644--- a/docs/guides/dataset/dataset_list_and_creation.md+++ b/docs/guides/dataset/dataset_list_and_creation.md@@ -12,20 +12,19 @@ sidebar_custom_props: {## Create Dataset-On the dataset list page, click **Create dataset** to open the creation popup. When creating a dataset, you need to set **Name**, **Embedding model**, and **Parse type**, and then, based on the selected parse type, further select a **Built-in** parsing method or an existing **Pipeline**.+Click **Create dataset** on the dataset list page, then complete the following settings:-1. Fill in **Name**. The name cannot be empty. It is recommended to use a name that reflects the business or material scope.-2. Select **Embedding model**. The drop-down list displays embedding models that have been added to the system and are currently available. Select the model used to vectorize documents in the dataset.-3. Select **Parse type**. RAGFlow provides the following two types of document parsing:- - **Built-in**: Uses RAGFlow's built-in document parsing methods. The system provides multiple preset parsing methods. You can choose a suitable method based on the document content and structure, such as general documents, Q&A, tables, papers, books, presentations, and so on. This is suitable when you want to directly use the system's preset parsing rules to process documents.- - **Pipeline**: Uses a custom pipeline to parse documents. The pipeline must be created and configured in **Agent** in advance. You can customize the document parsing and processing flow according to actual requirements. After creation, you can select the corresponding pipeline when creating a dataset.-4. When **Built-in** is selected, continue selecting the specific built-in parsing method. When **Pipeline** is selected, select the pipeline used to process documents.-5. Click **Save** to complete creation. Creating a dataset is only the first step. After creation, it is recommended to go to the dataset configuration page and further check and configure language, parsing method, auto metadata, data source associations, and other options based on the actual scenario before uploading documents in bulk.+1. Enter **Name**.+2. Select an available **Embedding model**.+3. In **Parse mode**, choose a built-in template, such as **General**, or an ingestion pipeline previously created in **Agent**. Built-in templates and saved pipelines appear in the same list.+4. Click **Save**, then review the dataset's **Configuration** before uploading documents.## View Dataset List-After entering **Datasets** from the left menu, the page displays the datasets accessible to the current user as cards, including datasets created by the user and datasets shared by other users. Each dataset card displays basic information such as the dataset avatar or initials, name, document count, and creation time, making it easy to quickly understand the dataset content and status.+After entering **Datasets** from the top navigation bar, the page displays the datasets accessible to the current user as cards, including datasets created by the user and datasets shared by other users. Each dataset card displays basic information such as the dataset avatar or initials, name, document count, and creation time, making it easy to quickly understand the dataset content and status.Click a dataset card to enter its detail page and view and manage documents, chunks, and related configuration. If there are many datasets, use the pagination feature at the bottom of the page to switch pages and adjust the number of datasets displayed per page.Click **Create dataset** to create a new dataset. During creation, configure the dataset name, embedding model, document parsing method, and other information.++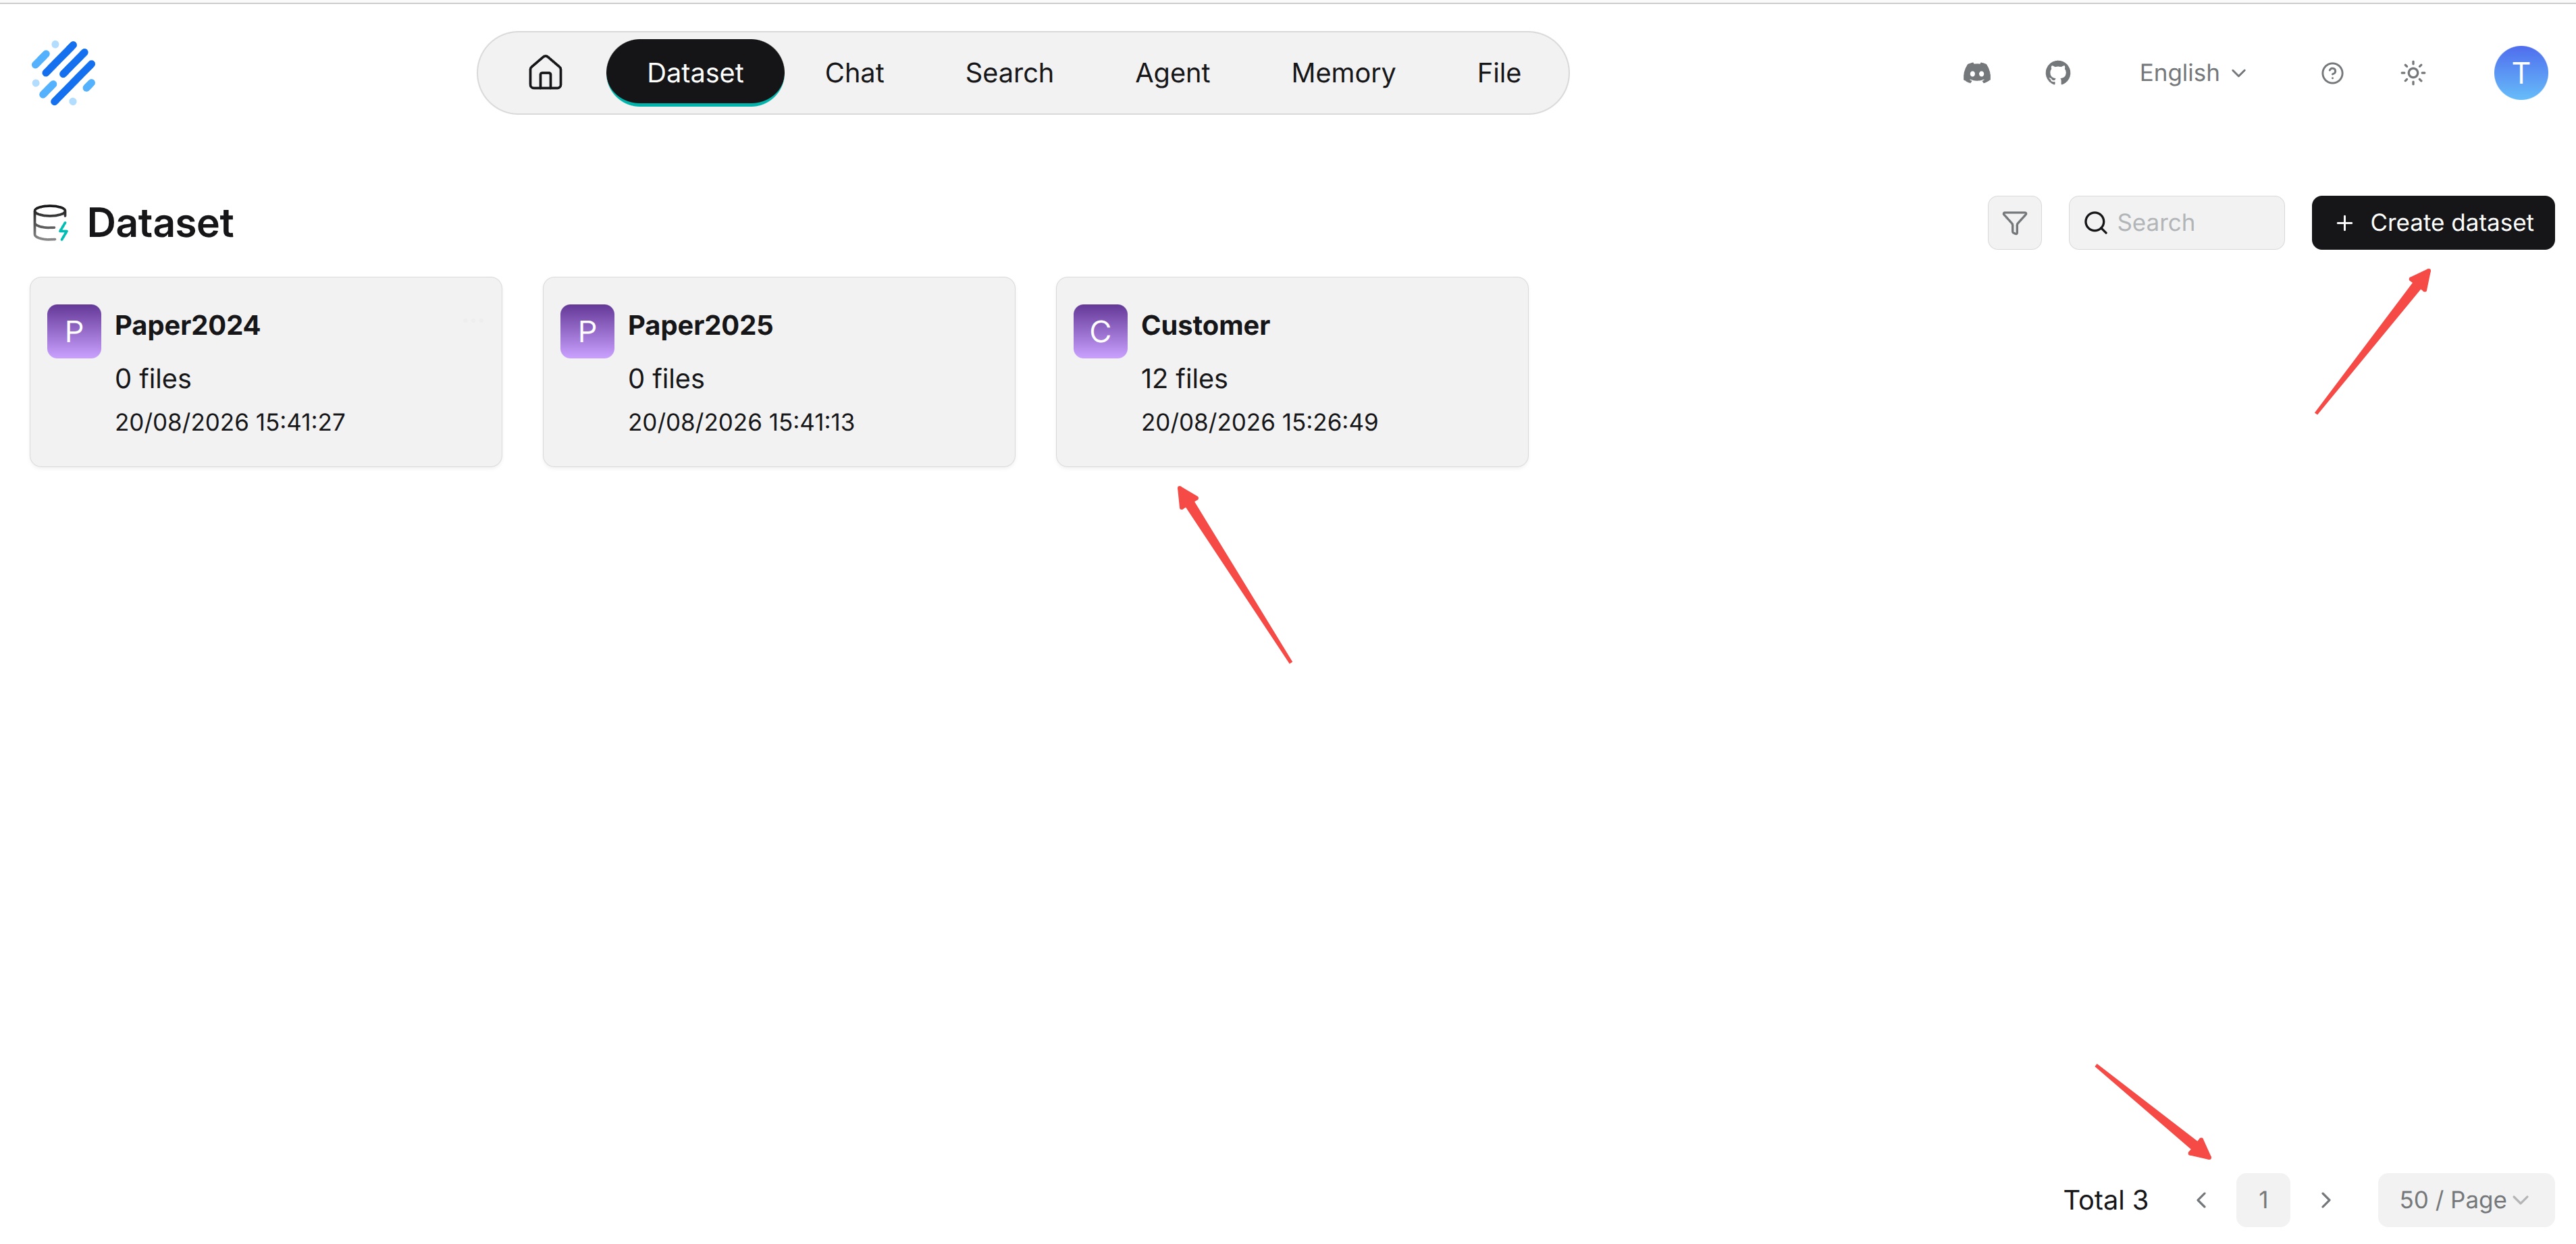diff --git a/docs/guides/dataset/dataset_overview.md b/docs/guides/dataset/dataset_overview.mdindex e9a506b4ad..3d0e76b73a 100644--- a/docs/guides/dataset/dataset_overview.md+++ b/docs/guides/dataset/dataset_overview.md@@ -25,7 +25,7 @@ The configuration page allows you to manage the core settings of a knowledge bas- **Avatar**: The avatar of the knowledge base. Image uploads are supported, with a maximum file size of 4 MB.- **Description**: A description of the knowledge base, used to explain its data scope, business purpose, or maintenance information.- **Permissions**: Controls access to the knowledge base and the scope of allowed operations.-- **Embedding model**: The model used to vectorize chunks. Changing the embedding model after content has already been parsed usually affects existing indexes and should be done with caution.+- **Embedding model**: The model used to vectorize chunks. When chunks already exist, changing the model requires a compatibility check against existing vectors. Saving the change does not automatically re-embed existing chunks.- **PageRank**: Sets the PageRank score for the knowledge base. During retrieval, this score is added to the hybrid similarity score of matching chunks from the knowledge base, increasing their ranking weight. This is useful when searching across multiple knowledge bases and you want to prioritize content from a specific knowledge base.## Dataset Page Overview@@ -35,5 +35,5 @@ The following briefly introduces the main entries on the dataset detail page and- **File list**: The default entry on the dataset detail page. It is used to manage documents, parsing status, enabled status, chunk count, metadata field count, and document-level operations in the dataset.- **Retrieval Testing**: Used to enter test questions and adjust retrieval parameters to verify the recall effect of the current dataset. Test parameter adjustments are not saved automatically and must be applied separately in **Chat Assistant** or the **Retrieval Agent** component.- **Artifacts**: Used to view entries for knowledge artifacts related to the current dataset, such as **Wiki**, **Navigation**, and **Graph**. This dataset manual only introduces the entry and viewing method. For generation and updates, see **Knowledge Compilation**.-- **Logs**: Used to view document parsing and dataset-level task records, including document logs and dataset-level logs.+- **Logs**: Used to view document parsing and dataset-level task records, including document logs, dataset-level logs, and data source synchronization logs.- **Configuration**: Used to maintain the dataset's basic information, embedding model, parsing method, data source associations, and other configurations.diff --git a/docs/guides/dataset/files_dataset_document_management.md b/docs/guides/dataset/files_dataset_document_management.mdindex cc95c84c1b..5fcad65d8f 100644--- a/docs/guides/dataset/files_dataset_document_management.md+++ b/docs/guides/dataset/files_dataset_document_management.md@@ -11,21 +11,23 @@ sidebar_custom_props:## Document Management Overview-Document management is used to upload, add, parse, search, filter, enable, disable, delete, and maintain documents in a dataset. Documents become retrievable content only after parsing generates chunks. On the document management page, you can complete the complete process from importing files to parsing, checking results, maintaining metadata, and maintaining chunks.+Document management is used to upload, parse, and manage documents in a dataset.## Document List-The document list is used to view the basic status of each document in the current dataset. The main fields in the list include **Name**, **Size**, **Source**, **Enabled**, **Chunks**, **Metadata**, **Parse**, **Status**, and **Action**.+The document list shows each document's information and parsing progress.-- **Name**: The document name.-- **Size**: The document file size.-- **Source**: The document source, such as local upload, associated data source, or file management.-- **Enabled**: Whether the document participates in dataset retrieval. After a document is disabled, it remains in the dataset but is not used as a retrieval source.-- **Chunks**: The number of chunks generated for the document. A value of `0` usually means the document has not been parsed, parsing failed, or no usable content was produced after parsing.-- **Metadata**: The number of document-level metadata fields. Click this field to view or edit document metadata.-- **Parse**: Displays the current parsing method or provides entries related to adjusting the parsing method and starting parsing.-- **Status**: Displays the document parsing task status, used to determine whether the document is waiting for parsing, being parsed, parsed successfully, or failed.-- **Action**: Provides operations such as renaming the document, viewing information, downloading, and deleting.+- **Name**: The document name. Click it to view parsing results.+- **Upload date**: When the document was uploaded.+- **Enabled**: Whether the document is included in retrieval. Disabling it keeps the document in the dataset.+- **Chunks**: The number of chunks generated from the document.+- **Metadata**: The number of document metadata fields. Click it to view or edit them.+- **Parse**: The parsing method used for the document.+- **Action**: Available document operations, such as renaming, downloading, and deleting.++Parsing status, progress indicators, and log controls appear in a separate, unlabeled column beside **Parse**.++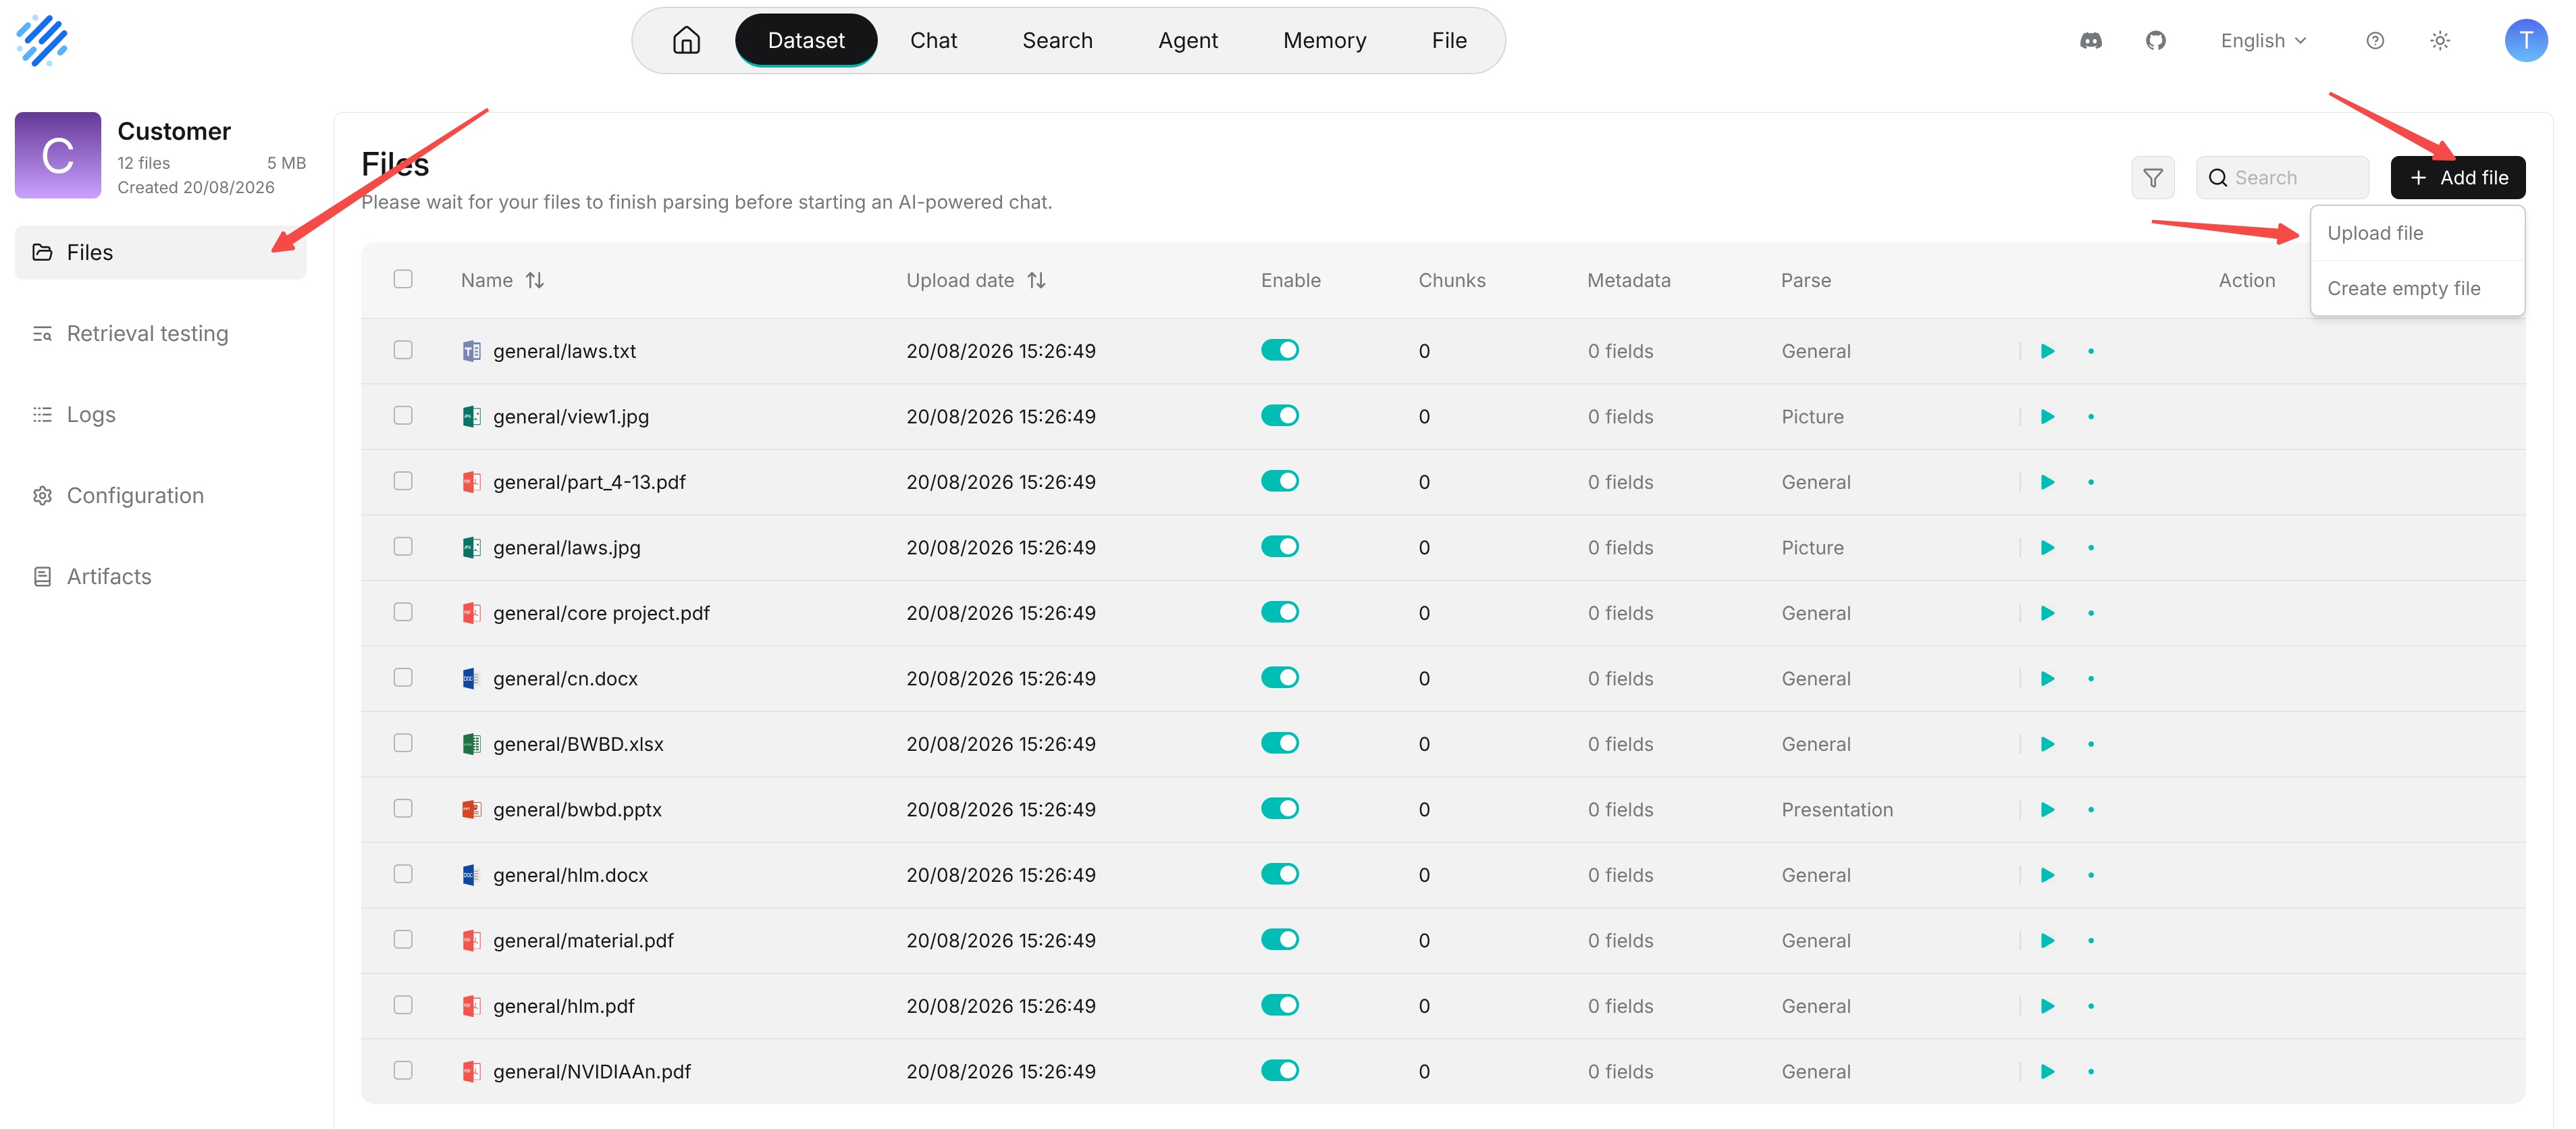## Add Documents@@ -39,6 +41,8 @@ Click **Add file** and select **Upload file** to upload documents from the local4. Choose whether to enable **Parse on creation** as needed.5. After confirming the upload, view the document status in the document list.++### Add Documents from an Associated Data SourceIf a dataset has already been associated with an external data source in configuration, documents in the data source can be added to the dataset from the document management page. After addition, the documents enter the dataset document list. They still need to complete parsing before generating chunks, metadata, and retrieval content.@@ -75,6 +79,10 @@ You can view the current parsing status of each document in the document list anIf parsing fails, view the related information in **Logs**, troubleshoot the problem, and run parsing again.++++### Parse AgainIf parsing configuration changes or parsing results need to be updated, you can parse a document again. Common scenarios that require parsing again include:@@ -94,6 +102,8 @@ The parsing method in dataset configuration is the default parsing configurationThis adjustment only applies to the current document and does not affect the default parsing configuration of the dataset.++## Search and Filter Documents**Search documents**: You can enter keywords in the document list to search by document name or related content. Search helps quickly locate target documents when there are many documents.@@ -117,8 +127,13 @@ After selecting the checkboxes on the left side of the document list, a batch op- **Metadata**: Maintain metadata for selected documents in bulk.- **Delete**: Delete selected documents.++## Single-Document Operations+++### View and Manage DocumentsClick the document name to enter the document detail page and view document information, parsing results, chunks, and metadata.diff --git a/docs/guides/dataset/logs.md b/docs/guides/dataset/logs.mdindex 3baef87e83..87726f0d4f 100644--- a/docs/guides/dataset/logs.md+++ b/docs/guides/dataset/logs.md@@ -1,17 +1,17 @@---sidebar_position: 9-title: "Logs: Logs"-sidebar_label: "Logs: Logs"+title: "Logs"+sidebar_label: "Logs"slug: /dataset_logssidebar_custom_props:categoryIcon: LucideDatabaseZap----# Logs: Logs+# Logs## Log Overview-**Logs** is used to view execution records of tasks related to the current dataset. The top of the page displays statistics such as **Total files**, **Processing**, and **Downloading**. The lower area is divided into document logs and dataset-level logs by log type. Document logs focus on the processing process of a single document. Dataset-level logs focus on tasks within the entire dataset scope. When troubleshooting, first determine whether the problem occurs in a single document or the entire dataset, then go to the corresponding logs to view details.+**Logs** shows task execution records for the current dataset. The top of the page displays file, processing, and downloading statistics. Use the **File**, **Dataset**, and **Data source** tabs to inspect document processing, dataset-level tasks, and external data source synchronization respectively.## Document Logs@@ -46,13 +46,25 @@ When a dataset-level processing task fails, does not complete for a long time, o> Tip: For tasks executed on a single document, such as document parsing, view document logs. For tasks executed on the entire dataset, such as **Knowledge Compilation**, view dataset-level logs.+## Data Source Logs++Open **Logs** and select **Data source** to check synchronization tasks for the current dataset. The table shows:++- **Time started**: The time shown for the task record.+- **Status**: The task's execution status.+- **Task Type**: `sync` synchronizes content; `prune` removes content deleted from the source.+- **Summary**: Synchronization progress, results, or error information.++Use this tab when source files are missing or synchronization fails. For parsing failures after synchronization, check **File** logs.+## Log Troubleshooting SuggestionsWhen task execution is abnormal or does not complete for a long time, first select the corresponding logs based on task type, then troubleshoot based on task status and log details.- **Document processing tasks**: View document logs. Document logs record processing tasks for specific documents. Use information such as **Filename**, **Source**, **Ingestion pipeline**, **Task**, and **Status** to confirm which document and processing flow has the exception. For documents processed with **Data Pipeline**, you can also use the entry in **Operations** to view the corresponding pipeline execution result.- **Dataset-level processing tasks**: View dataset-level logs. Dataset-level tasks such as **Knowledge Compilation** are recorded here. Use **Processing type** and **Status** to find the corresponding task, and view log details through **Operations**.+- **Data source synchronization**: Select **Data source** and check **Status**, **Task Type**, and **Summary**.- **Task execution failed**: When **Status** is **Failed**, open the corresponding task log details and view the specific error information.- **Task does not complete for a long time**: When a task stays in **Pending**, **Running**, or **Schedule** for a long time, first confirm the current task status and start time, then view log details to determine whether the task is still running normally.-> Note: Document logs and dataset-level logs record different types of processing tasks. They are not parent-child logs or summary logs. When troubleshooting, select the corresponding log based on the actual task.+> Note: File, dataset, and data source logs cover different task types. Select the tab that matches the task you are troubleshooting.diff --git a/docs/guides/dataset/metadata_management.md b/docs/guides/dataset/metadata_management.mdindex 445a9d15fa..4c36ac16ed 100644--- a/docs/guides/dataset/metadata_management.md+++ b/docs/guides/dataset/metadata_management.md@@ -19,10 +19,16 @@ Metadata may come from system built-in fields, automatic generation during parsiIn document management or document details, you can view and maintain metadata related to documents. Metadata is displayed in list form, including **Field**, **Type**, **Values**, and related operations.++++## Add MetadataYou can add metadata manually for documents. When adding metadata, you need to specify the field name, data type, and value. To improve subsequent filtering and retrieval, keep field names, data types, and value formats consistent.++## Automatically Generate MetadataAfter **Auto Metadata** is enabled in dataset configuration, the system can automatically generate metadata during document parsing according to the configured generation rules. Automatically generated metadata usually comes from document content, source information, or built-in parsing information.diff --git a/docs/guides/dataset/notes_and_faqs.md b/docs/guides/dataset/notes_and_faqs.mdindex b88e7ad36b..eb7c5a208a 100644--- a/docs/guides/dataset/notes_and_faqs.md+++ b/docs/guides/dataset/notes_and_faqs.md@@ -37,9 +37,9 @@ After resolving any storage issues, upload the missing file again and retry pars## What Should I Do If Retrieval Testing Cannot Retrieve Content?-It is recommended to troubleshoot in the order of **document status -> chunk -> metadata -> retrieval parameters**. First confirm that the document has been parsed successfully and generated usable chunks. Then check whether metadata has filter conditions that exclude related chunks. Finally, check retrieval parameters such as **Similarity threshold**, **Vector similarity weight**, and **Top K**.+It is recommended to troubleshoot in the order of **document status -> chunk -> metadata -> retrieval parameters**. First confirm that the document has been parsed successfully and generated usable chunks. Then check whether metadata has filter conditions that exclude related chunks. Finally, check retrieval parameters such as **Similarity threshold**, **Keyword similarity weight**, and **Top N**.-Common causes include documents not yet parsed, no usable chunks generated, metadata filters being too strict, **Similarity threshold** being too high, or **Top K** being too small.+Common causes include documents not yet parsed, no usable chunks generated, metadata filters being too strict, **Similarity threshold** being too high, or **Top N** being too small.## Why Can't I See Artifacts?@@ -66,9 +66,9 @@ During retrieval testing, hybrid search is used to retrieve chunks created by thThis setting is the threshold for retrieving chunks. Chunks with similarity below the threshold are filtered out. By default, the threshold is set to `0.2`. This means only chunks with a hybrid similarity score of `0.2` or higher are retrieved.-#### Vector Similarity Weight+#### Keyword Similarity Weight-This setting controls the weight of vector similarity in the comprehensive similarity score, whether it is combined with vector cosine similarity or rerank score. By default, it is set to `0.3`, so the other component's weight is `0.7` (`1 - 0.3`).+This setting controls the keyword similarity weight in hybrid retrieval. The default is `0.7`, leaving a vector similarity or rerank weight of `0.3` (`1 - 0.7`). Increase it to favor keyword matching; decrease it to favor semantic matching.#### Rerank Modeldiff --git a/docs/guides/dataset/retrieval_testing.md b/docs/guides/dataset/retrieval_testing.mdindex 0cedd2c518..98b7b187b5 100644--- a/docs/guides/dataset/retrieval_testing.md+++ b/docs/guides/dataset/retrieval_testing.md@@ -22,11 +22,12 @@ Retrieval testing can also help troubleshoot Q&A result problems. If the correctThe **Setting** area on the **Retrieval testing** page is used to adjust retrieval parameters for the current test. You can modify parameters and run tests repeatedly to compare recall results under different configurations. The main parameters include:- **Similarity threshold**: Candidate chunks below this threshold are filtered out. Raising the threshold narrows the recall range and makes results stricter; lowering the threshold expands the recall range. The default value is `0.2`.-- **Vector similarity weight**: The weight of vector similarity in the comprehensive similarity calculation. The other part of the weight is used for full-text or keyword similarity. For example, when this is set to `0.3`, the other part is `0.7`.+- **Keyword similarity weight**: Sets the full-text weight in hybrid retrieval. For example, `0.7` means full-text weight `0.7` and vector weight `0.3`. Increase it for keyword matching; decrease it for semantic matching.- **Rerank model**: The reranking model used to further calculate relevance and sort candidate results. If no rerank model is selected, retrieval results combine keyword similarity and vector cosine similarity. If selected, reranking results participate in the comprehensive score. Using a rerank model may increase retrieval latency.- **Cross-language search**: Select one or more target languages so a query can match related content in other languages in the dataset. If no language is selected, retrieval is mainly performed in the current language.- **Metadata**: Restricts the retrieval range by metadata conditions. After it is set, retrieval is performed only in content that meets the metadata conditions.-- **Top**: Sets the maximum number of candidate results returned. For example, if **Top 10** is selected, up to 10 eligible results are returned.+- **Rerank candidates**: Sets the candidate pool for ranking or reranking. The default is `64`, and the range is `64–256`. It must be at least **Top N**, which controls the final number of returned results.+- **Top N**: Sets the maximum number of final results returned. For example, if **Top N** is set to `10`, up to 10 eligible results are returned.> Note: Parameter changes in **Retrieval Testing** are only used for the current test and are not automatically synchronized to **Chat Assistant** or **Agent**. After suitable parameters are determined, configure the corresponding parameters in the application that actually uses the dataset or in the **Retrieval** component.@@ -53,14 +54,16 @@ The upper-right corner of **Results** provides a **File** filter. You can selectThe focus of retrieval testing is not to compare a single score in isolation, but to confirm whether the needed chunks can be accurately recalled and reasonably ranked under the current retrieval configuration.+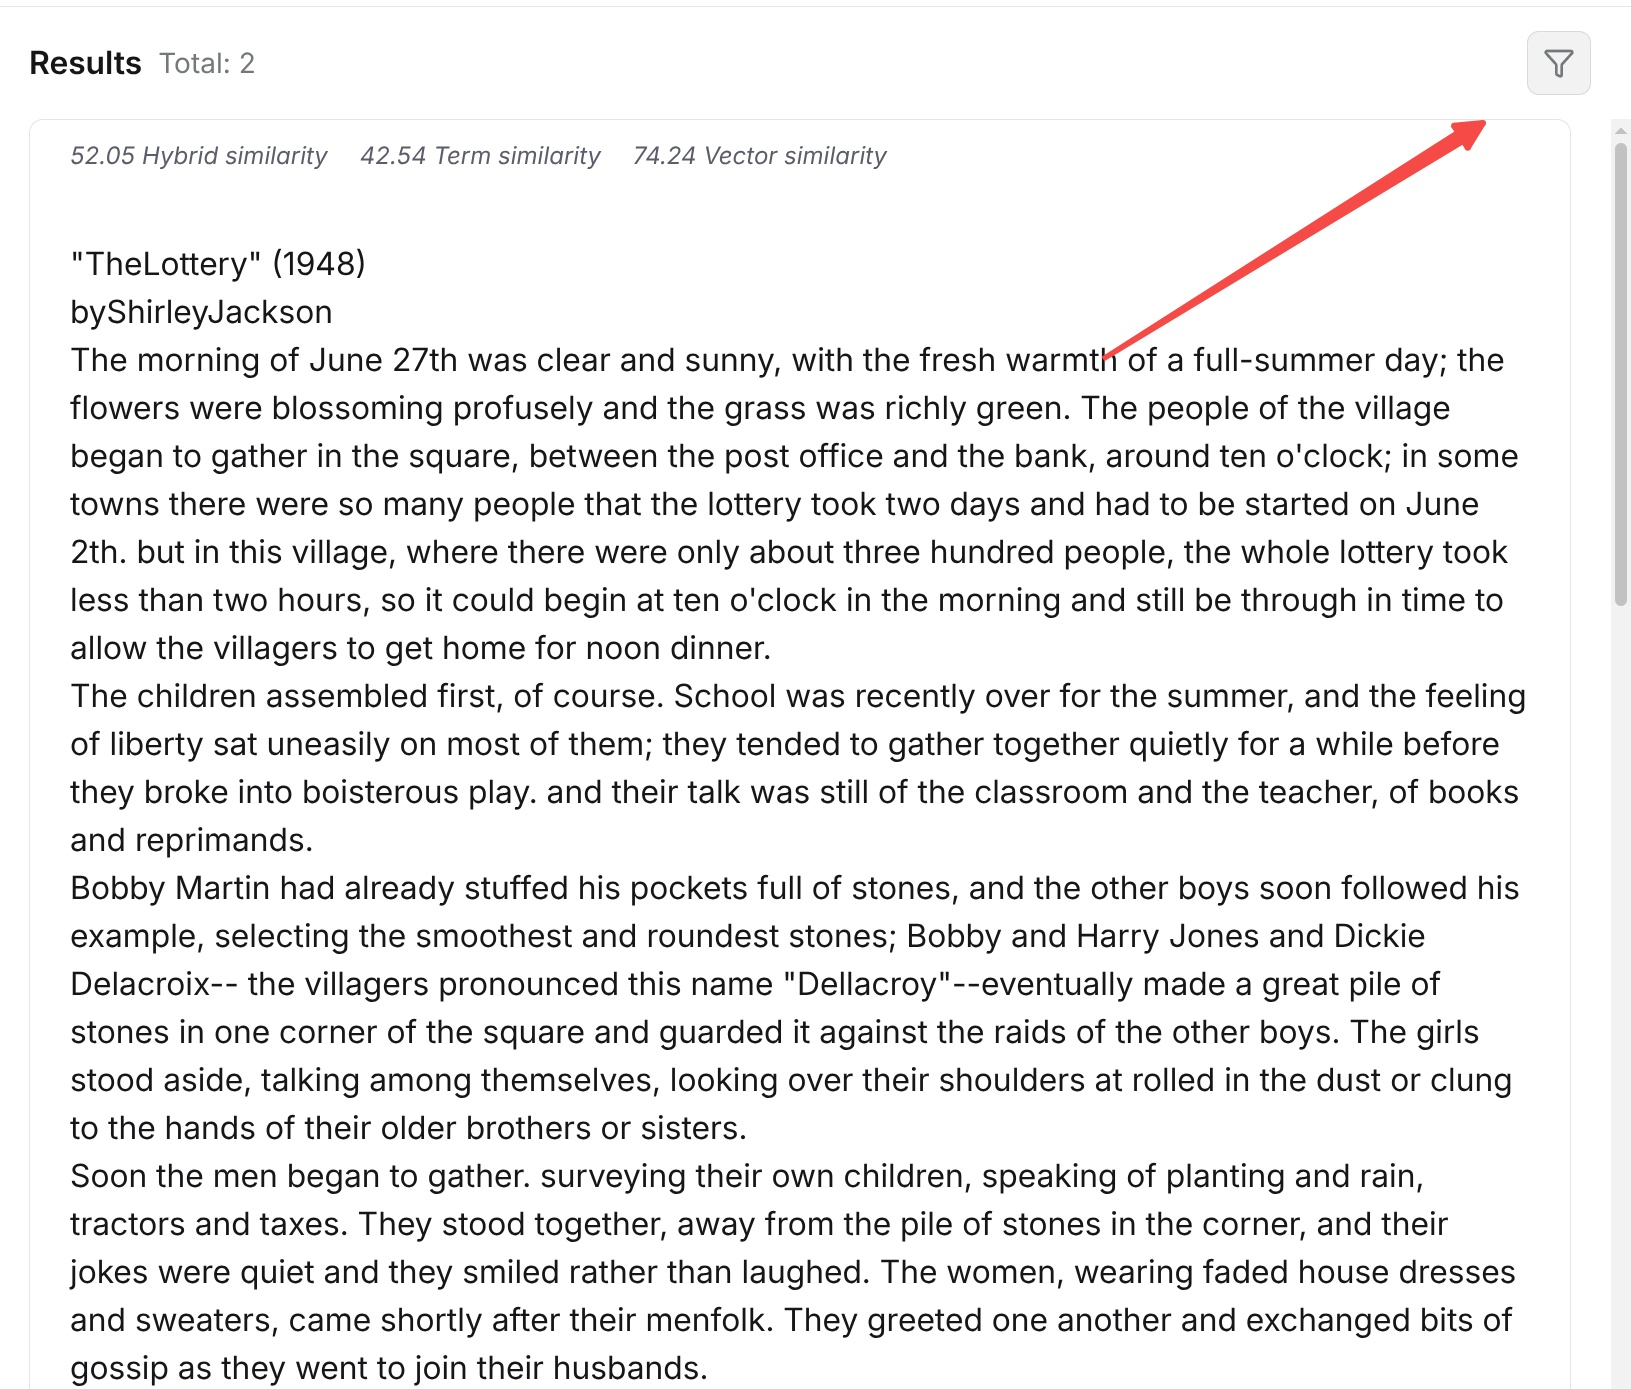+## Adjust Retrieval ResultsIf retrieval results do not meet expectations, first determine whether the problem is a content problem or a retrieval configuration problem, then adjust accordingly.If the target content does not appear in retrieval results at all, check whether the document was parsed successfully, whether the target content has generated corresponding chunks, and whether metadata conditions exclude the related content.-If the target chunk can be recalled but many irrelevant results also appear, raise **Similarity threshold** appropriately to narrow the recall range. If retrieval results rely more on semantic expression or keyword matching, adjust **Vector similarity weight** to rebalance vector retrieval and full-text retrieval. If the target chunk can already be recalled but ranking is unsatisfactory, try configuring **Rerank model** to rerank candidate results.+If the target chunk can be recalled but many irrelevant results also appear, raise **Similarity threshold** appropriately to narrow the recall range. If retrieval results rely more on semantic expression or keyword matching, adjust **Keyword similarity weight** to rebalance vector retrieval and full-text retrieval. If the target chunk can already be recalled but ranking is unsatisfactory, try configuring **Rerank model** to rerank candidate results.-If you need to see more or fewer candidate results, adjust **Top**. For cross-language datasets, also check whether **Cross-language search** includes the target languages to retrieve. It is recommended to use multiple representative queries for repeated testing and determine final parameters based on the overall recall result instead of adjusting configuration based only on a single test.+If you need to see more or fewer final results, adjust **Top N**. For cross-language datasets, also check whether **Cross-language search** includes the target languages to retrieve. It is recommended to use multiple representative queries for repeated testing and determine final parameters based on the overall recall result instead of adjusting configuration based only on a single test.Debugging suggestion: when retrieval results are unsatisfactory, troubleshoot in the order of document parsing → chunk → metadata → retrieval parameters. First confirm that the knowledge content itself has correctly entered the dataset, then adjust retrieval parameters. This helps locate the problem faster.diff --git a/docs/guides/file/batch_move_and_delete.md b/docs/guides/file/batch_move_and_delete.mdindex 5a7def73ff..27c67a60a6 100644--- a/docs/guides/file/batch_move_and_delete.md+++ b/docs/guides/file/batch_move_and_delete.md@@ -19,6 +19,8 @@ Checkboxes are available on the left side of the file list. After you select at3. Select the target folder in the directory tree.4. Click **Save** to save the move result.+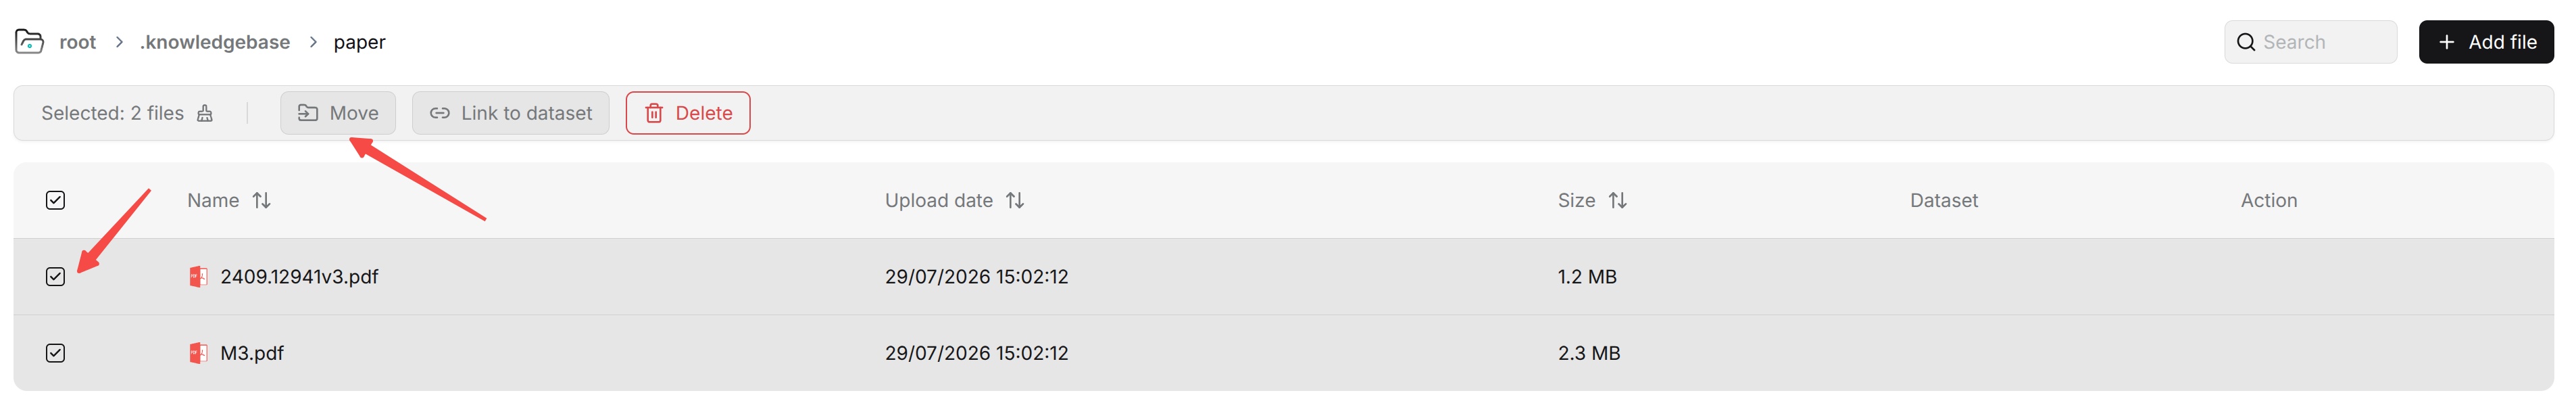+## Batch Delete1. Select one or more files.@@ -27,3 +29,5 @@ Checkboxes are available on the left side of the file list. After you select at4. After confirming that everything is correct, submit the deletion.Some system folders, external data source files, or files from special sources cannot be selected or cannot perform certain batch operations. This is normal behavior caused by permission and source controls.++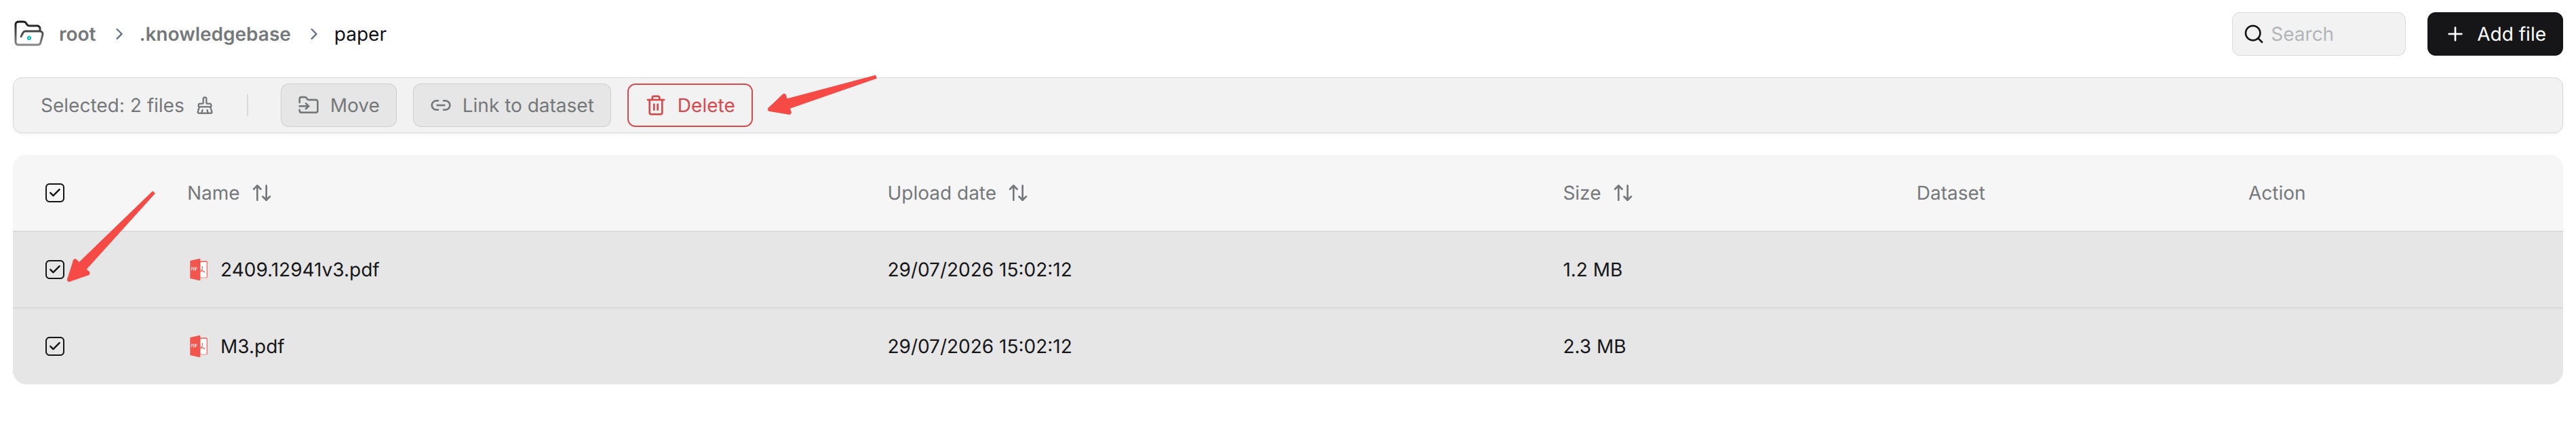diff --git a/docs/guides/file/file.md b/docs/guides/file/file.mdindex 11a70561db..b9c4bccafb 100644--- a/docs/guides/file/file.md+++ b/docs/guides/file/file.md@@ -23,6 +23,10 @@ RAGFlow file management lets you build your own file system through nested folde3. Enter the folder name in the **Name** input field. The name cannot be empty. It is recommended to use a short name that reflects the business source.4. Click **Save**.+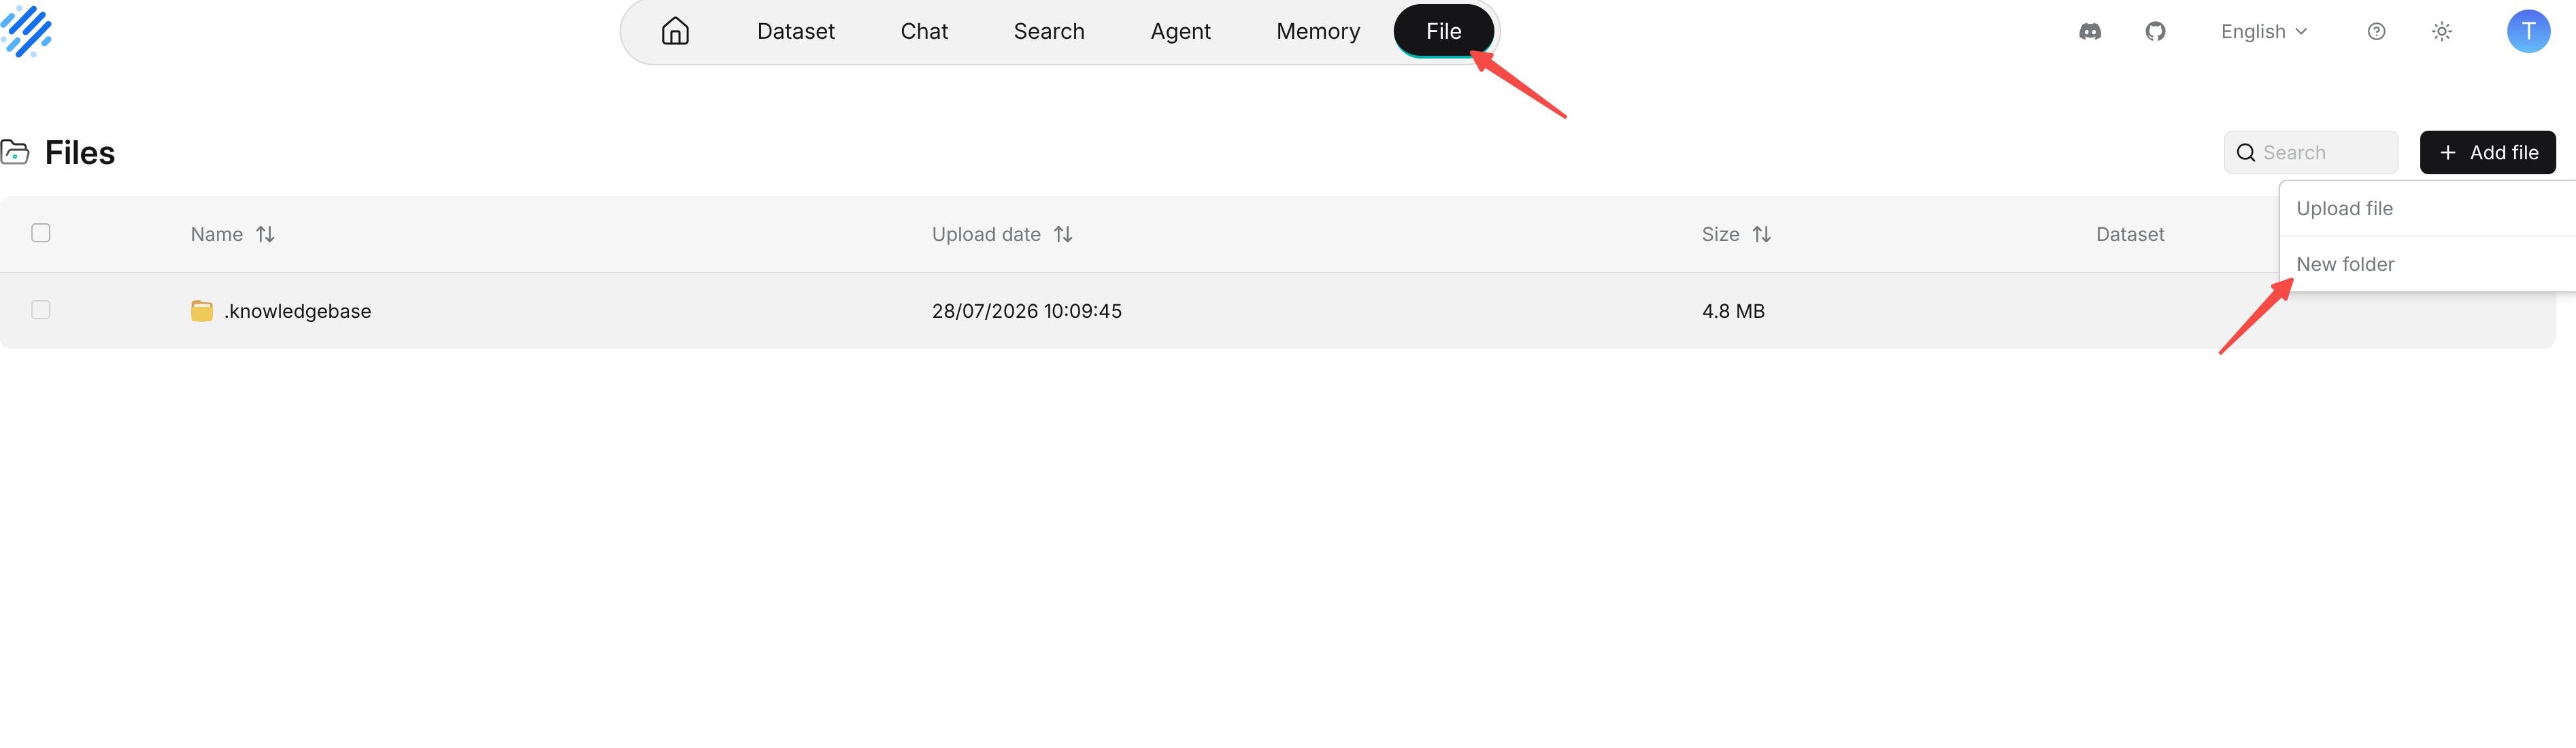++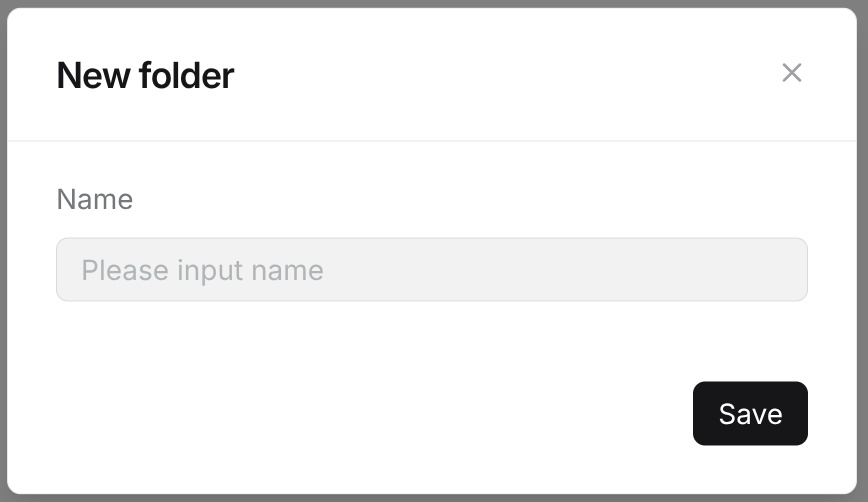+## Upload Files or FoldersAfter clicking **Add File** in the upper-right corner of the page, select **Upload File** to open the upload window. The upload control contains two tabs: **File** and **Folder**. You can select one or more files, or upload an entire folder.diff --git a/docs/guides/knowledge_compilation/apply_knowledge_compilation_template.md b/docs/guides/knowledge_compilation/apply_knowledge_compilation_template.mdindex b4d9e0facf..e8ea1a0116 100644--- a/docs/guides/knowledge_compilation/apply_knowledge_compilation_template.md+++ b/docs/guides/knowledge_compilation/apply_knowledge_compilation_template.md@@ -29,13 +29,11 @@ Note: CompilationTemplate only defines "how to compile". A KnowledgeArtifact is1. Go to the Dataset page and create a Dataset or open an existing Dataset.2. Upload the documents to process.-3. In the file list, select Configure Ingestion Pipeline.-4. Select the Ingestion Pipeline that contains CompilerOperator.+3. Open **Configuration** and find **Parse mode**.+4. Select the Ingestion Pipeline that contains CompilerOperator and click **Save**.5. Start parsing and check in the task logs whether Parser, Chunker, Compiler, and Indexer complete in sequence.---+If CompilationTemplate is modified, completed documents are not automatically recompiled. You need to reparse or rerun the Pipeline according to the operations currently provided by the product before the new configuration can be applied.diff --git a/docs/guides/memory/configure_memory.md b/docs/guides/memory/configure_memory.mdindex 389cefea29..a21e54c31e 100644--- a/docs/guides/memory/configure_memory.md+++ b/docs/guides/memory/configure_memory.md@@ -22,6 +22,8 @@ The embedding model and large language model are the basic configuration for memOnce a memory contains messages, you cannot change its embedding model, the associated embedding model instance, or its memory types. Saving a change to any of these settings is rejected. Choose these settings before writing messages; create a new memory if you need a different configuration while retaining the existing memory's messages. The large language model can still be changed, but changing it does not automatically re-extract existing messages.+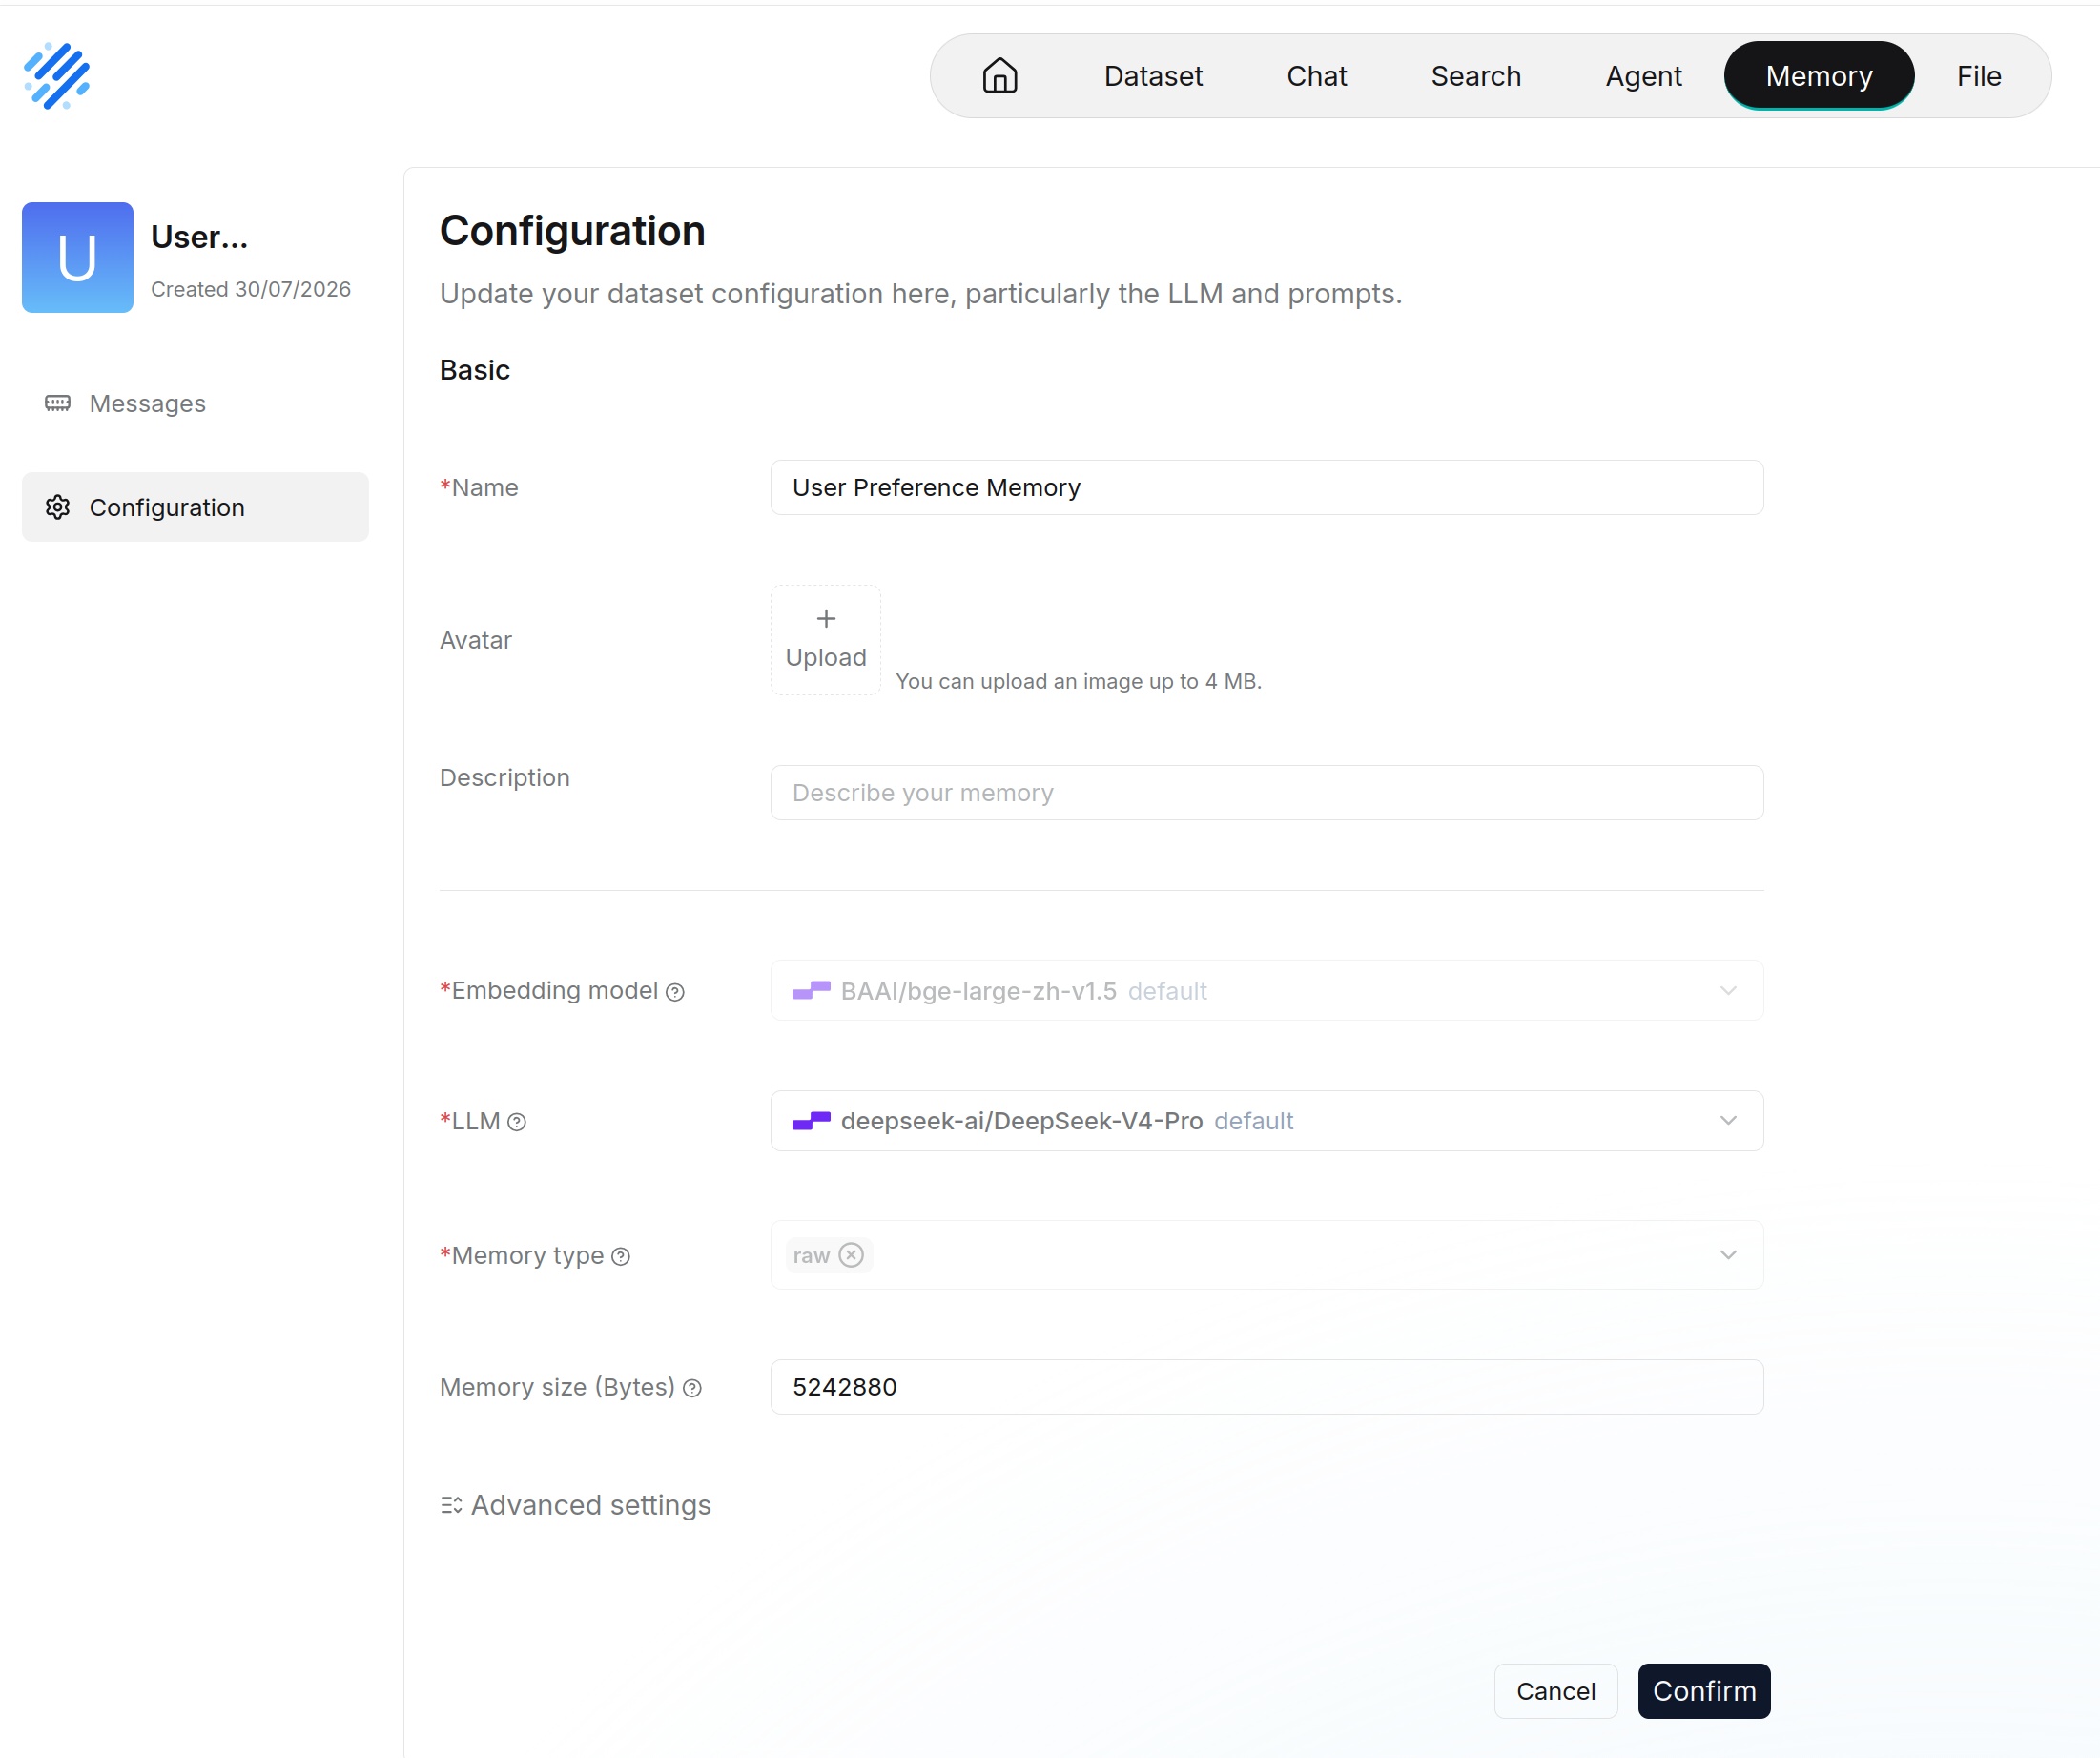+### Memory TypeMultiple memory types can be selected, but **Raw (`raw`)** is required and cannot be removed. When multiple types are selected, the system saves or extracts memories at different levels according to the selected types.diff --git a/docs/guides/memory/connect_to_an_agent.md b/docs/guides/memory/connect_to_an_agent.mdindex 5e34949a36..9c6b949529 100644--- a/docs/guides/memory/connect_to_an_agent.md+++ b/docs/guides/memory/connect_to_an_agent.md@@ -28,7 +28,7 @@ A memory must be connected to an Agent before historical messages can be written1. Select or add the **Retrieval** component on the Agent canvas.2. In **Query variable**, select the query source. `sys.query` is commonly used.3. In **Retrieval source**, select **Memory**, and select one or more target memories.-4. Adjust **Similarity threshold**, **Vector similarity weight**, and **Top N** as needed.+4. Adjust **Similarity threshold**, **Keyword similarity weight**, and **Top N** as needed.5. Connect the retrieval result to a subsequent large language model or answer component, so that the Agent can use the retrieved historical context.6. Save and run a test, and check whether the answer correctly references historical memories.diff --git a/docs/guides/models/llm_api_key_setup.md b/docs/guides/models/llm_api_key_setup.mdindex 01e9633bc9..37721c3b52 100644--- a/docs/guides/models/llm_api_key_setup.md+++ b/docs/guides/models/llm_api_key_setup.md@@ -105,7 +105,7 @@ At minimum, set the following defaults:1. Default LLM.2. Default embedding model.-If you have configured a rerank model, it is also recommended to set a default rerank model. Configure VLM, ASR, TTS, and OCR defaults as required by your business.+If you have configured a rerank model, it is also recommended to set a default rerank model. Configure VLM, ASR, and TTS defaults as required by your business.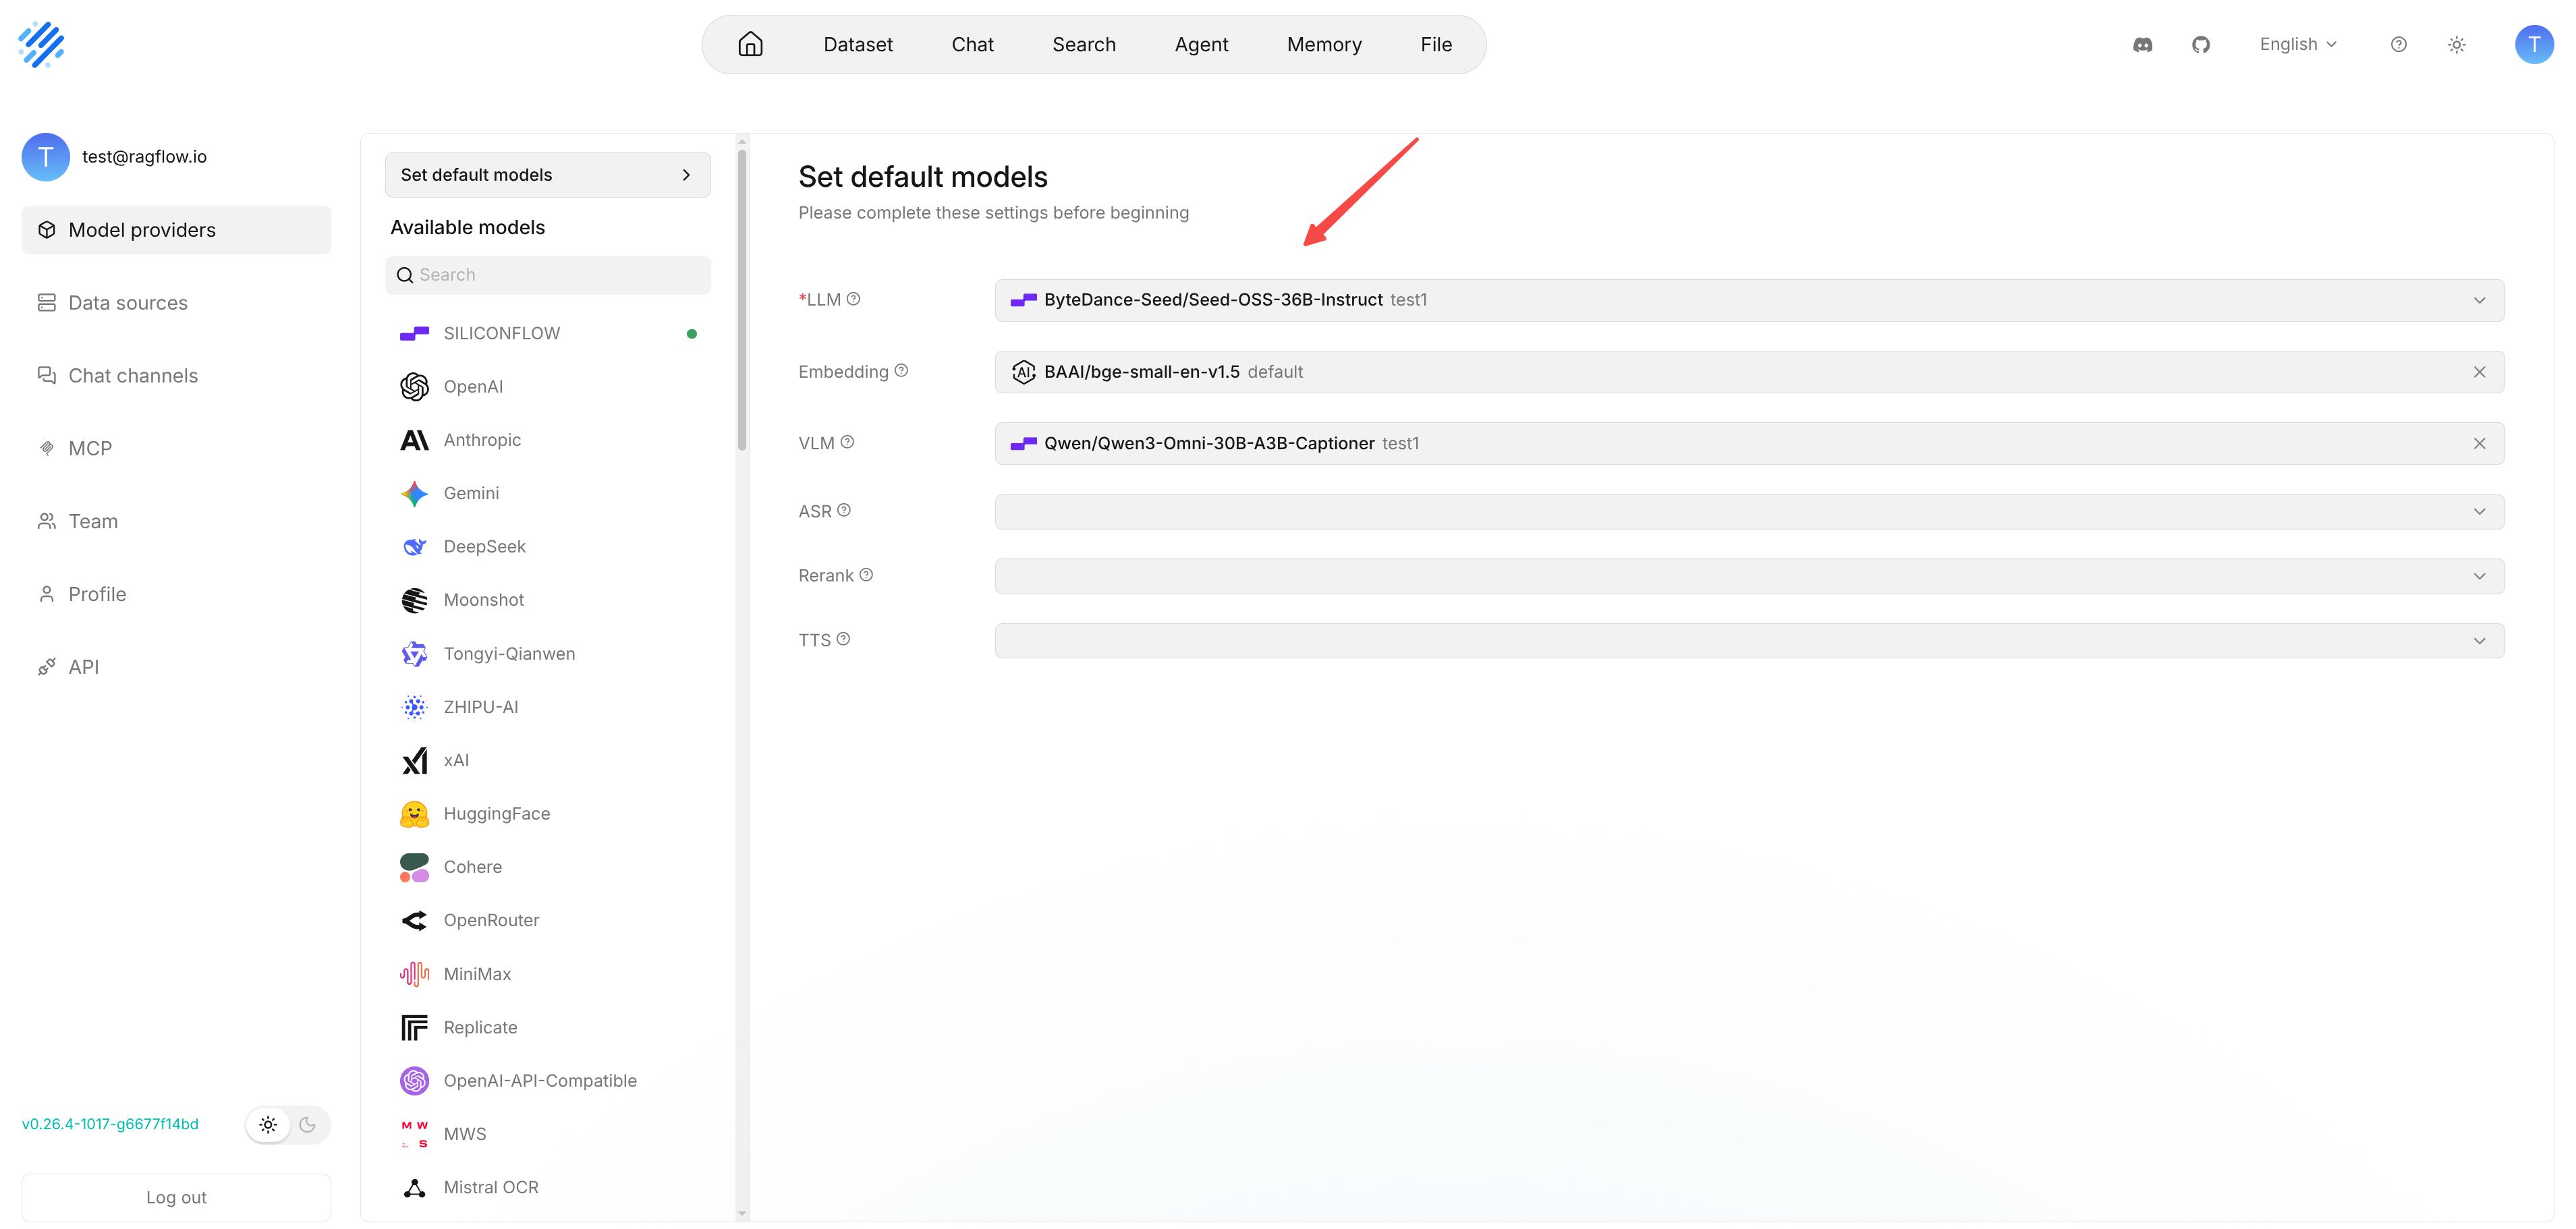diff --git a/docs/guides/search/faq.md b/docs/guides/search/faq.mdindex 4eb74c168a..60addc7345 100644--- a/docs/guides/search/faq.md+++ b/docs/guides/search/faq.md@@ -17,7 +17,7 @@ Chat is designed for knowledge-based question answering. In addition to retrievi**Why can't I find content that already exists in the knowledge base?**-The relevant chunks may not meet the **Similarity threshold**, or the query may differ significantly from the wording in the source content. Try lowering the similarity threshold, adjusting the **Vector similarity weight**, or using more specific keywords.+The relevant chunks may not meet the **Similarity threshold**, or the query may differ significantly from the wording in the source content. Try lowering the similarity threshold, adjusting the **Keyword similarity weight**, or using more specific keywords.Also make sure that the target knowledge base has been added to the current Search and that the relevant documents have been successfully parsed and indexed.@@ -25,13 +25,13 @@ Also make sure that the target knowledge base has been added to the current SearTry increasing the **Similarity threshold** to filter out less relevant results.-If your query relies mainly on keywords, proper nouns, or identifiers, you can also decrease the **Vector similarity weight** to give full-text retrieval more weight in hybrid retrieval.+If your query relies mainly on keywords, proper nouns, or identifiers, you can also increase the **Keyword similarity weight** to give full-text retrieval more weight in hybrid retrieval.-**How should I set the Vector similarity weight?**+**How should I set the Keyword similarity weight?**This parameter controls the balance between vector retrieval and full-text retrieval.-For semantic search scenarios, you can increase the Vector weight. If you mainly search for product names, identifiers, technical terms, or other content that requires exact matching, you can increase the Full-text weight. In most cases, it is recommended to start with the default value and adjust it based on actual search results.+Decrease **Keyword similarity weight** to favor semantic matching. Increase it for product names, identifiers, technical terms, and exact matches. Start with the default value and adjust it based on search results.**Why does Search become slower after I enable the Rerank model?**diff --git a/docs/guides/search/search_settings.md b/docs/guides/search/search_settings.mdindex 891c5ed95c..67abe0f7c9 100644--- a/docs/guides/search/search_settings.md+++ b/docs/guides/search/search_settings.md@@ -19,13 +19,9 @@ You can select one or more knowledge bases. When multiple knowledge bases are seSelect knowledge bases based on the intended use case of the Search. Avoid adding large numbers of knowledge bases that are unrelated to the search topic, as this may increase the number of irrelevant results.-## Show chunk metadata+## Metadata-Controls whether chunk metadata is displayed in search results.--When enabled, search results can display metadata associated with each chunk in addition to its text. This helps users identify the source of the content and further filter or evaluate the results.--If you are mainly interested in the content itself, you can leave this option disabled. Enable it if you need to inspect or verify the sources of the results.+Use **Metadata** to restrict retrieval by document metadata. Available fields depend on the selected knowledge bases. This setting filters content; it is not a switch for displaying metadata in results.## Similarity threshold@@ -38,23 +34,14 @@ Only content with a similarity score that meets or exceeds the threshold is inclIf there are too many results and their relevance is low, try increasing this value. If Search frequently fails to return the expected content, try decreasing it.-## Vector similarity weight--Sets the relative weights of vector similarity and full-text search in hybrid retrieval.--For example, a value of `0.3` means:--- Vector = `0.3`-- Full-text = `0.7`--Vector search focuses more on semantic similarity between the query and the document, while full-text search focuses more on matching keywords, terms, and other textual elements.+## Keyword similarity weight-Therefore:+Sets the full-text weight in hybrid retrieval. For example, `0.7` means full-text weight `0.7` and vector weight `0.3`.-- Increase the vector weight: Gives greater priority to semantic matching. This is suitable when a user's wording differs from that of the source text.-- Decrease the vector weight: Gives greater priority to full-text matching. This is suitable for exact matches involving proper nouns, product models, identifiers, fixed terminology, and similar content.+- Increase it to favor keywords, product names, identifiers, and exact terms.+- Decrease it to favor semantic matches when the query differs from the source wording.-You can generally start with the default value and adjust it based on actual search performance.+Start with the default value and adjust it based on search results.## Rerank candidatesdiff --git a/docs/guides/team/team_management/view_current_workspace_members.md b/docs/guides/team/team_management/view_current_workspace_members.mdindex 21506d4d3a..0dbecba4ad 100644--- a/docs/guides/team/team_management/view_current_workspace_members.md+++ b/docs/guides/team/team_management/view_current_workspace_members.md@@ -15,7 +15,7 @@ The list contains the following fields:| Name | The member's nickname. || Update date | The time when the membership record was last updated. || Email | The member's email address. |-| Role | The member's team role. `normal` is displayed as **Member**, `invite` is displayed as **Invite**, and `owner` is displayed as **Owner**. |+| Status | The member's team relationship status. `normal` is displayed as **Member**, `invite` is displayed as **Invite**, and `owner` is displayed as **Owner**. || Action | Operations available for the current member, such as removing a member when permitted. |You can search members by nickname or email address, and sort members by **Update date**.diff --git a/docs/quickstart.mdx b/docs/quickstart.mdxindex f0cb48b74e..5d34db652f 100644--- a/docs/quickstart.mdx+++ b/docs/quickstart.mdx@@ -108,7 +108,7 @@ You can upload files to a dataset in RAGFlow and parse them into chunks. A datasTo create your first dataset:1. Select **Datasets** in the navigation bar, then click **Create dataset**.-2. Enter **Name**, select **Embedding model**, and choose **Parse type**. For a first dataset, select **Built-in** and a parsing method suitable for your files. To use **Pipeline**, first create an **Ingestion Pipeline** in **Agent > Ingestion Pipeline**, then select it in the creation dialog.+2. Enter **Name**, select **Embedding model**, then choose a built-in template or a saved ingestion pipeline from **Parse mode**. For a first dataset, use **General**.3. Click **Save**, open the dataset, and review its **Configuration** before uploading files.See [Dataset List and Creation](./guides/dataset/dataset_list_and_creation.md) and [Dataset Configuration](./guides/dataset/configuration.md) for details.@@ -144,9 +144,6 @@ RAGFlow features visibility and explainability, allowing you to view the chunkin4. In Retrieval testing, ask a quick question in **Test text** to double check if your configurations work:- _As you can tell from the following, RAGFlow responds with truthful citations._-- 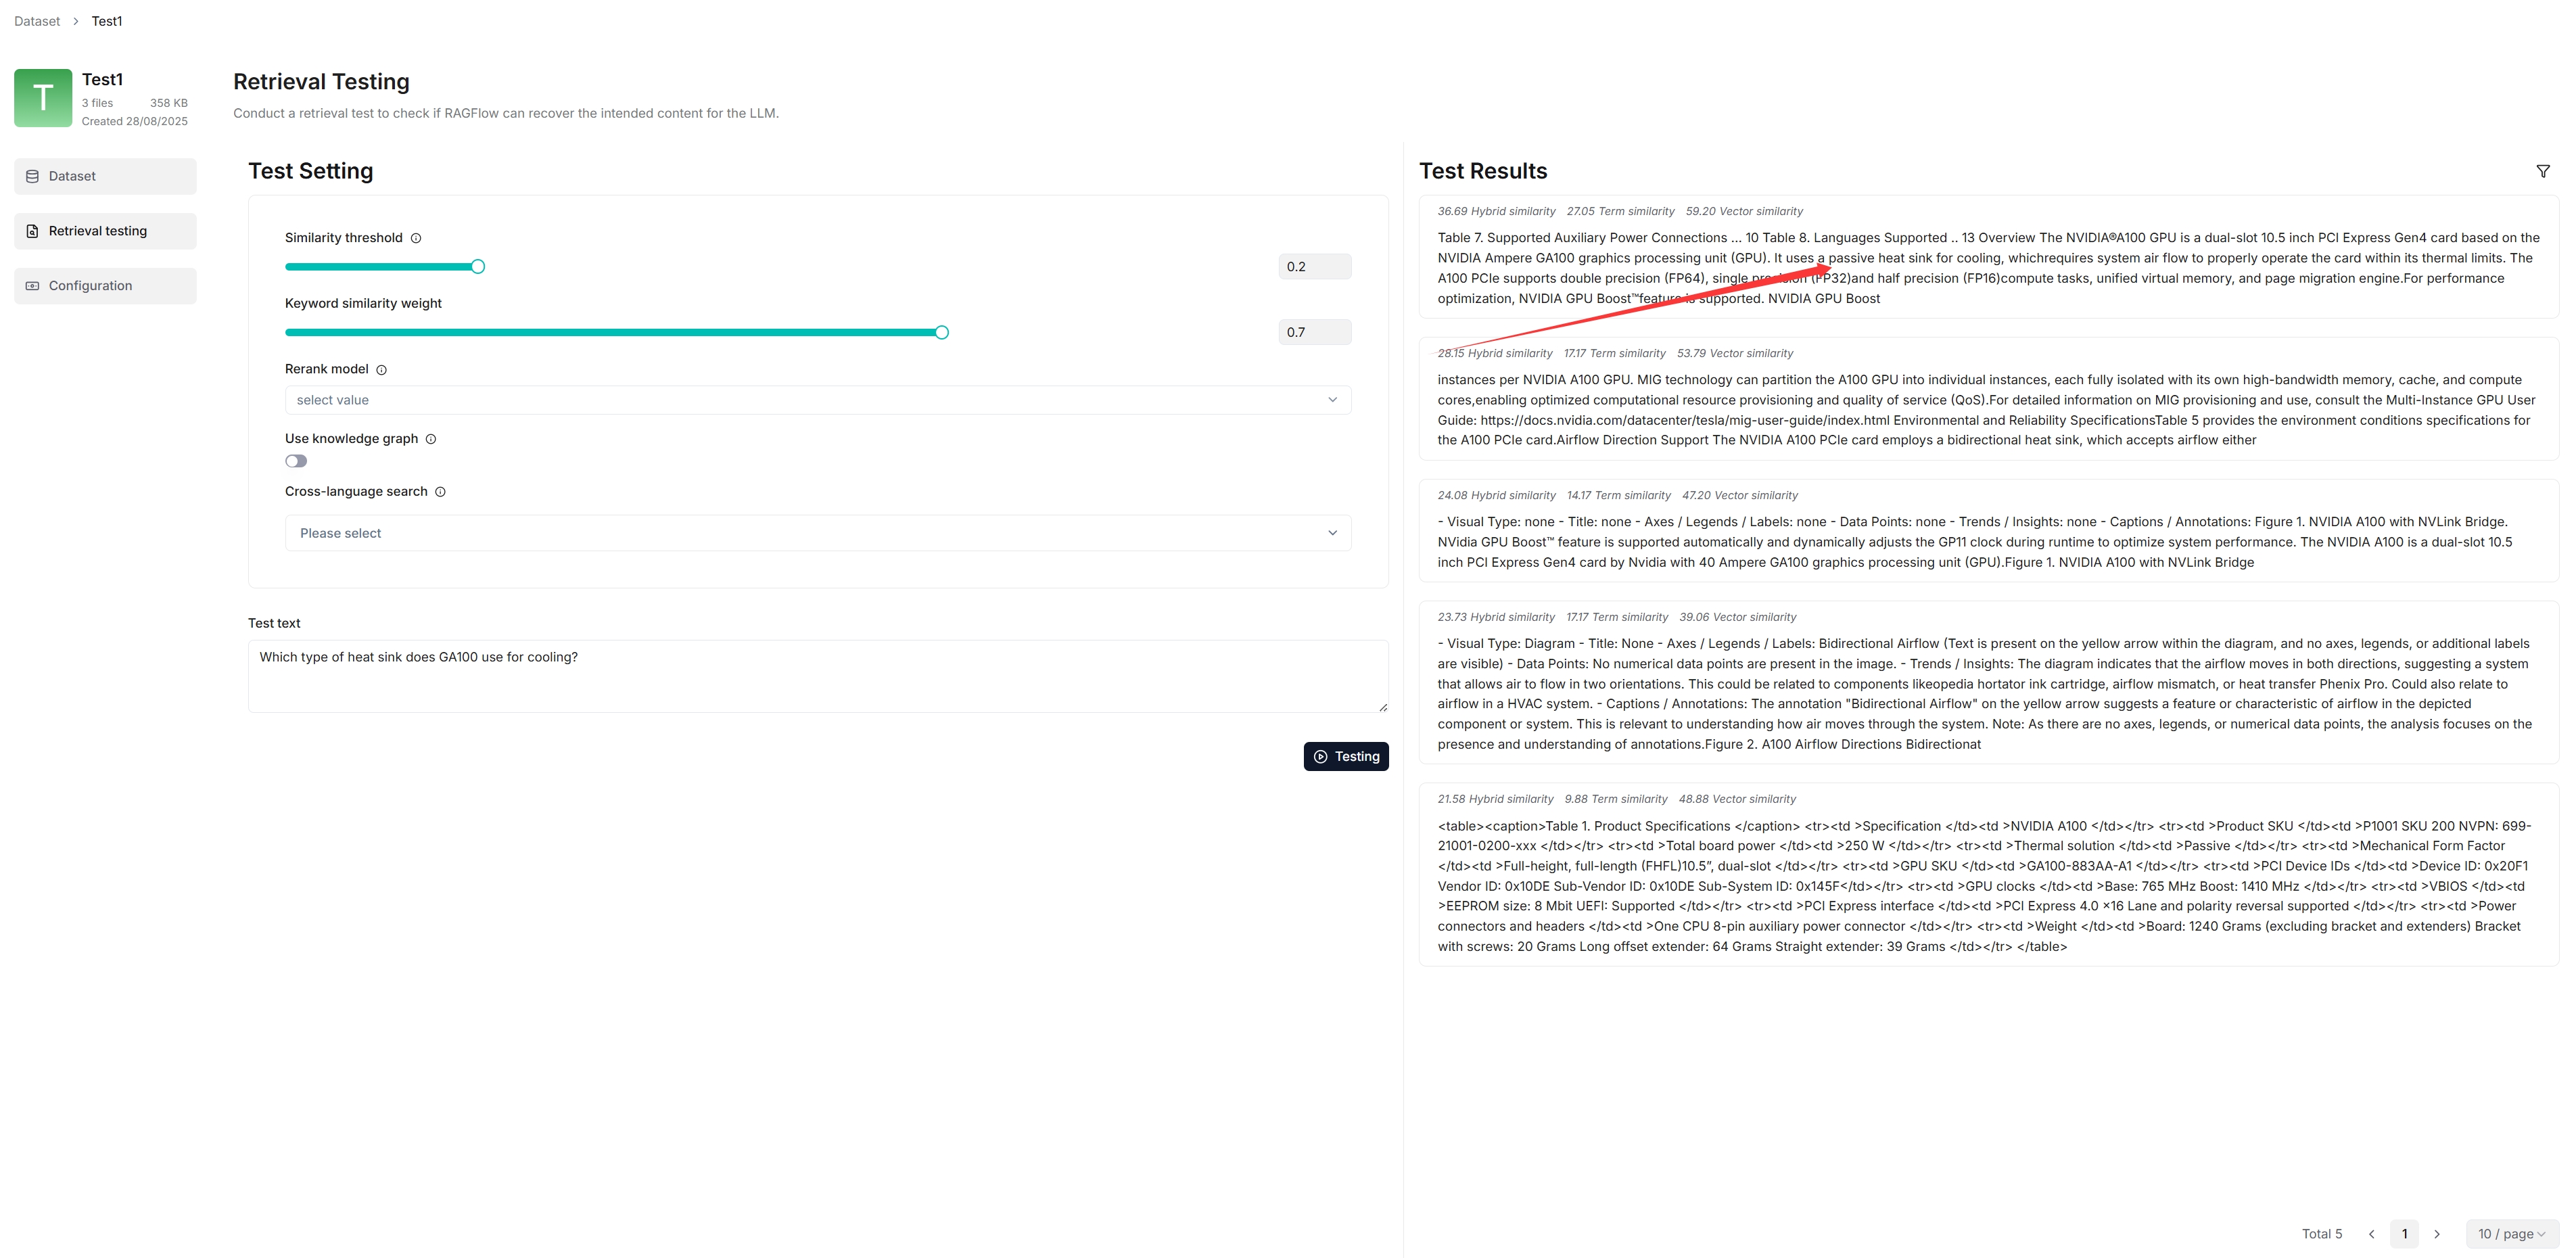## Set up an AI chat