
RAGFlow is an agent-native database: a Retrieval-Augmented Generation (RAG) engine that grew into context infrastructure.
Go agent-harnessagent-native-databaseagentic-aiagentic-retrievalagentic-searchaiai-agentscontext-enginecontext-engineeringcontext-managementharness-engineeringknowledge-compilationragretrieval-augmented-generationretrieval-harnesssearch-harness
docs: add compilation docs & fix some issues (#18268)
YanZhang1097cc9c84f5
diff --git a/docs/guides/agent/agent_workflow/basic_component_configuration.md b/docs/guides/agent/agent_workflow/basic_component.mdsimilarity index 88%rename from docs/guides/agent/agent_workflow/basic_component_configuration.mdrename to docs/guides/agent/agent_workflow/basic_component.mdindex 99e2ea0099..6f2a1171c9 100644--- a/docs/guides/agent/agent_workflow/basic_component_configuration.md+++ b/docs/guides/agent/agent_workflow/basic_component.md@@ -1,14 +1,14 @@---sidebar_position: 1-title: Basic Component Configuration-sidebar_label: Basic Component Configuration-slug: /basic_component_configuration+title: Basic Component+sidebar_label: Basic Component+slug: /basic_componentsidebar_custom_props: {categoryIcon: RagAiAgent}----# Basic Component Configuration+# Basic Component## Begin Component@@ -58,6 +58,9 @@ Variable types:| File upload | Allows users to upload files as workflow input. This can be used for document analysis, image processing, and similar scenarios. Uploaded files are not automatically saved to knowledge bases, and are used only in the current workflow. || Number | Used to enter numeric values, such as quantity, threshold, `Top K`, and maximum returned items. || Boolean | Provides a switch (`True`/`False`) or yes/no option, used to control whether a feature is enabled or whether a branch is executed. |+| JSON object | Used to enter structured JSON data, such as parameters, configurations, or other complex data containing multiple fields. |++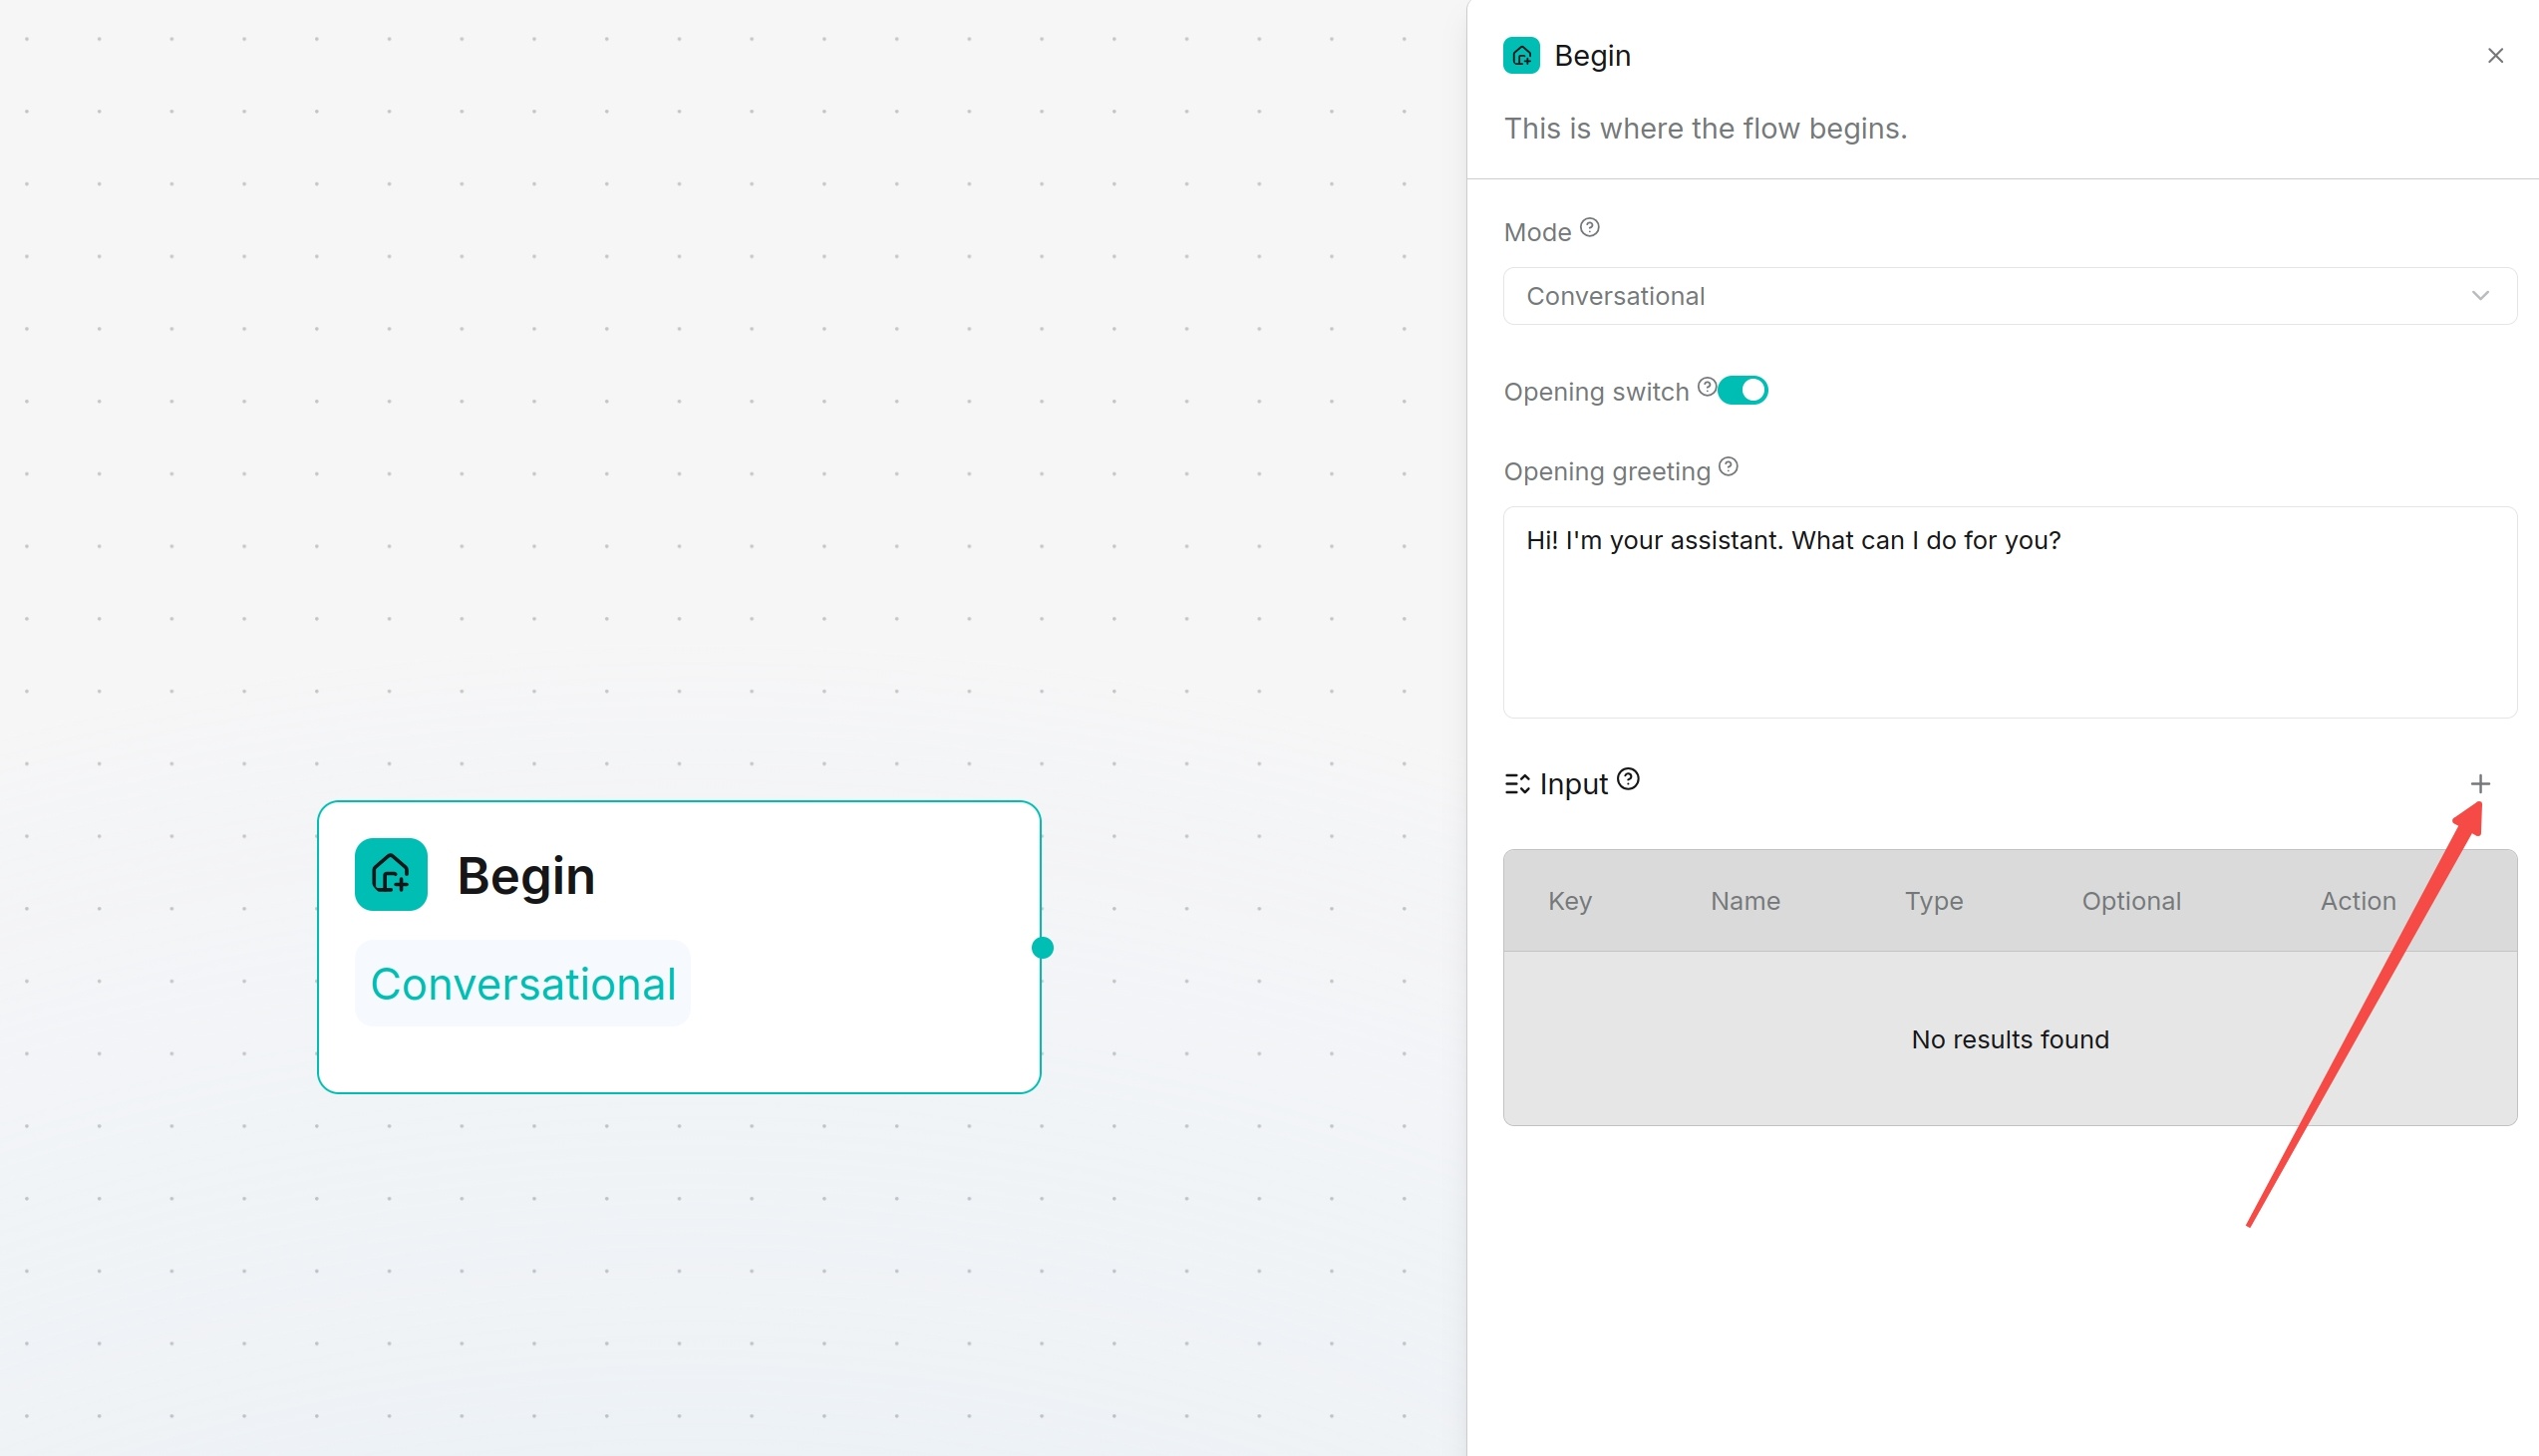:::tip NOTE@@ -65,8 +68,6 @@ Files uploaded through the `Begin` component are used only as input for the curr:::--## Agent ComponentThe Agent component is used to call large language models for reasoning, content generation, task planning, and tool calling. It can process user questions independently, or work with components such as knowledge retrieval, HTTP requests, code, databases, and sub-agents to complete multi-step tasks.@@ -145,7 +146,7 @@ For structured output, after enabling **Structured output**, click **Configurati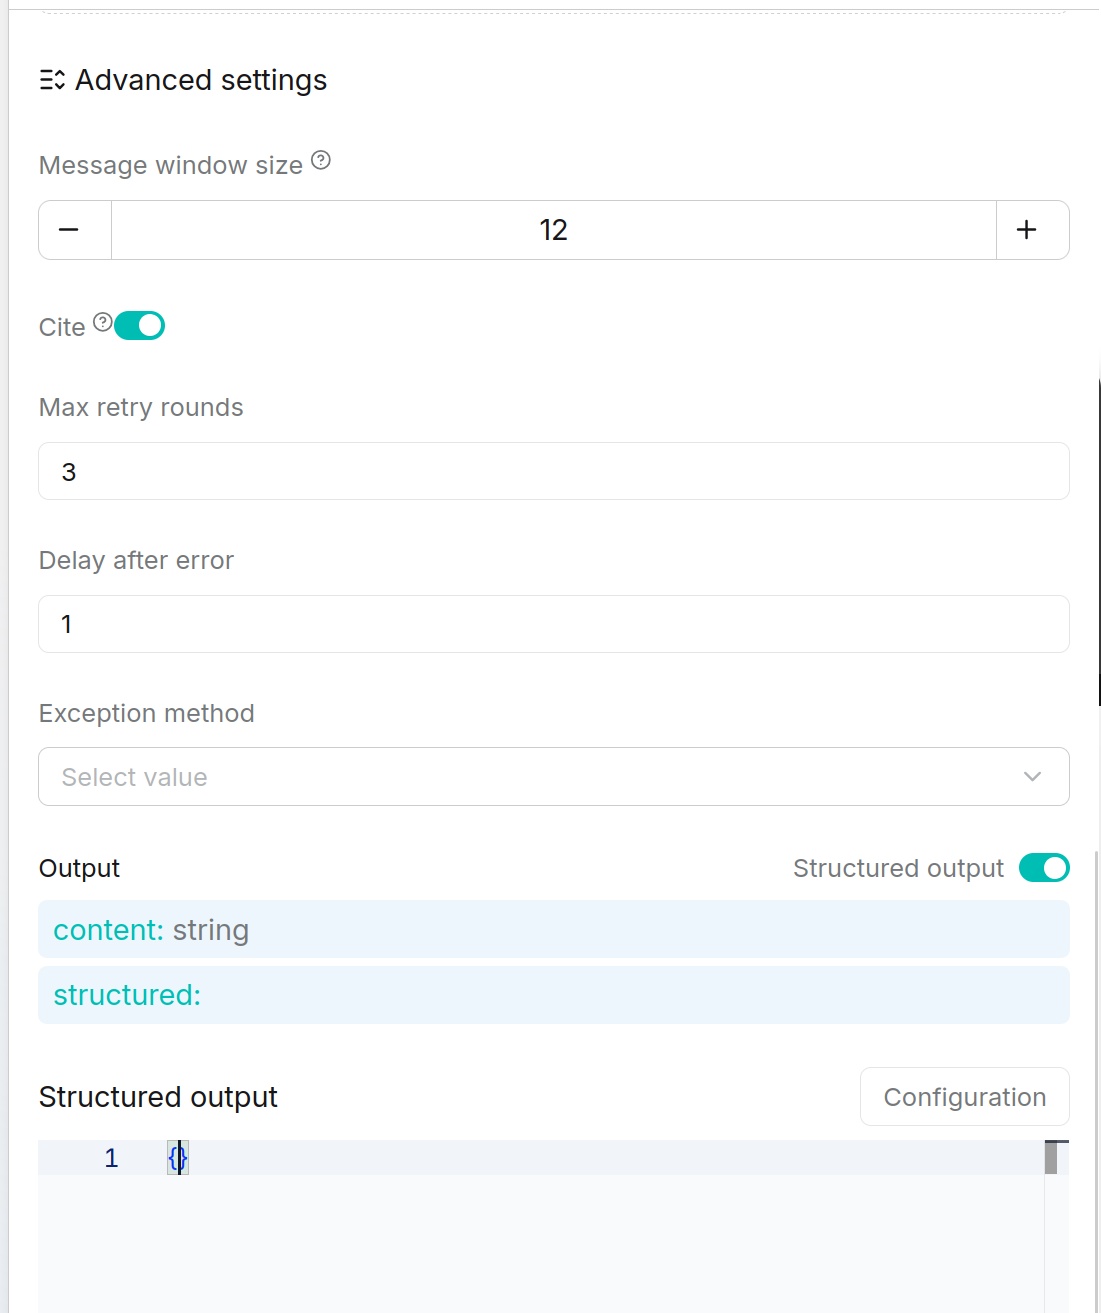-## Knowledge Retrieval Component+## Retrieval ComponentThe knowledge retrieval component is used to retrieve relevant content from specified knowledge bases or memories. It can be used as a regular workflow component, or as a tool for the Agent component.@@ -190,28 +191,3 @@ Retrieval parameters directly affect answer coverage, accuracy, and response tim| Similarity threshold | 0.5 | General Q&A | Default starting value. || Similarity threshold | 0.8 | Strict precise matching | Scenarios that require exact terminology matching. |-## Reply Message Component--The message is used to output static or dynamic messages to users, and is usually used as the final component of a workflow. It can directly write fixed text, or insert upstream variables.--### Configuration Method--Write the output content in the message. Type `/` or click the variable button to insert component outputs.--If multiple messages are added, the system randomly selects one of them to send. When the `Begin` component selects `Webhook` and the response method is `Final response`, the reply message component can set an HTTP status code in the range of 200 to 399.--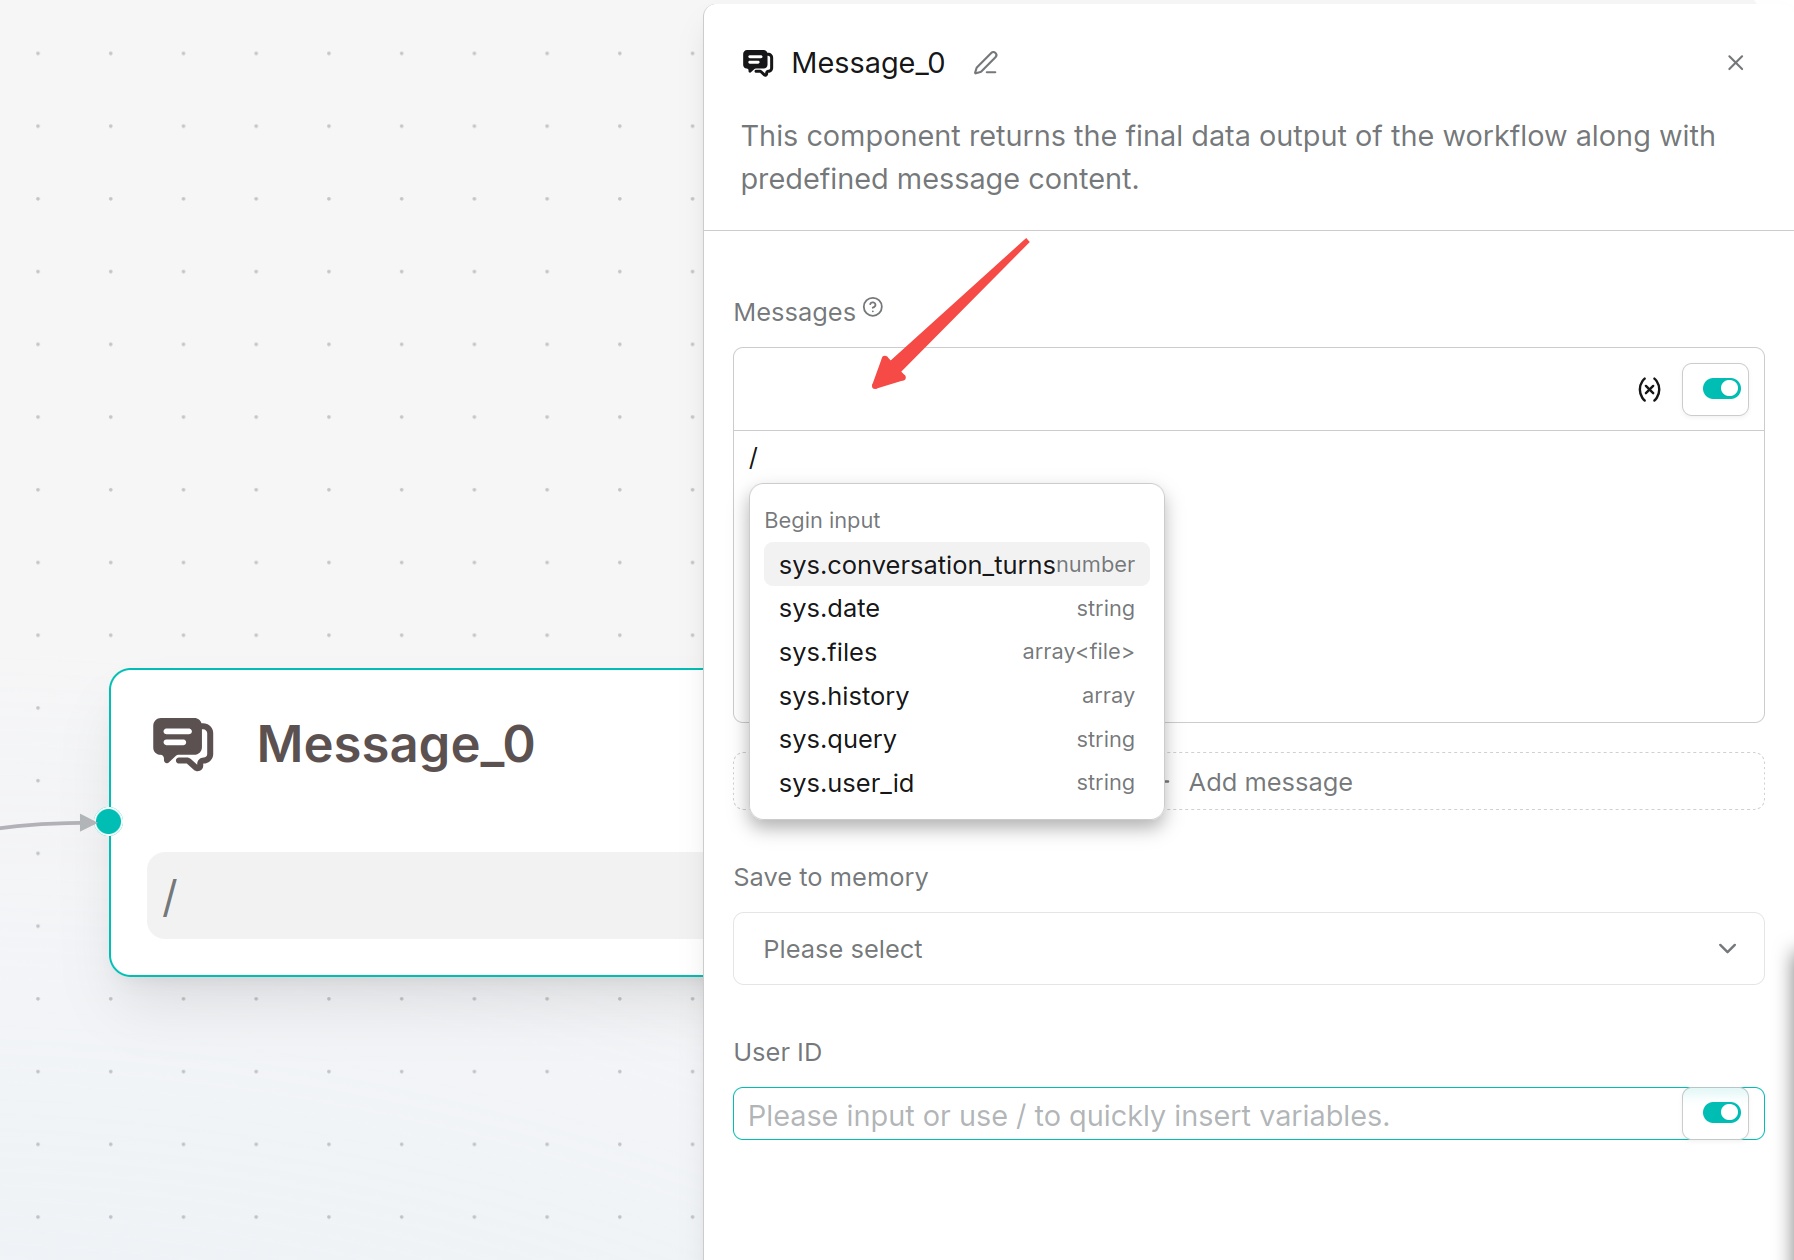--### Save to Memory--The reply message component can choose to save to memory, storing the conversation in the specified memory. After enabling **User ID**, conversations can be associated with user IDs, and subsequent knowledge retrieval can query related memories by user ID.--### Applicable Scenarios--This component is suitable for outputting final answers, branch hints, fallback replies, or displaying intermediate processing results to users.--### Output Result--The message outputs the configured text or variable content to the conversation window, webhook response, or embedded page.--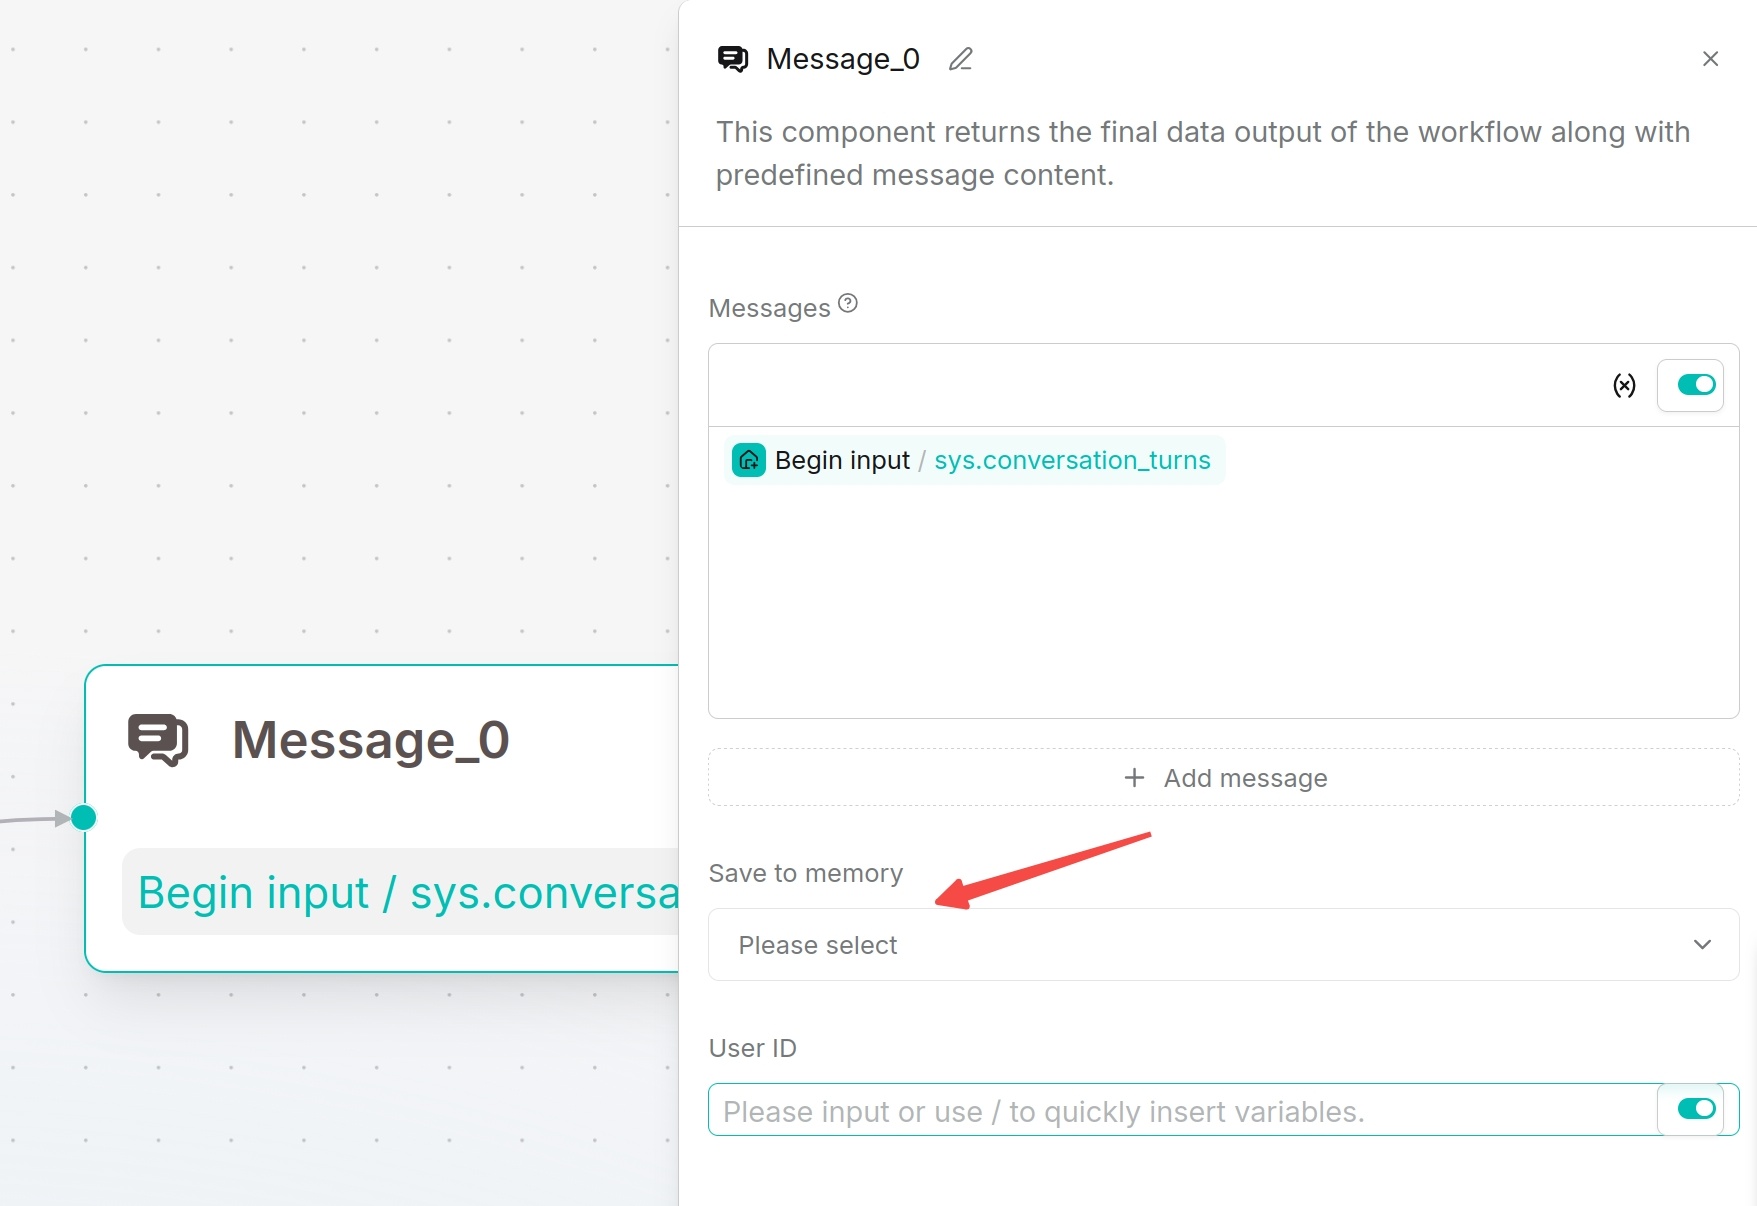diff --git a/docs/guides/agent/agent_workflow/data_manipulation_components.md b/docs/guides/agent/agent_workflow/data_manipulation_components.mdindex 011cd6ecb1..ee2ec34a6d 100644--- a/docs/guides/agent/agent_workflow/data_manipulation_components.md+++ b/docs/guides/agent/agent_workflow/data_manipulation_components.md@@ -1,5 +1,5 @@----sidebar_position: 3+sidebar_position: 4title: Data Manipulation Componentssidebar_label: Data Manipulation Componentsslug: /data_manipulation_componentsdiff --git a/docs/guides/agent/agent_workflow/dialogue_component.md b/docs/guides/agent/agent_workflow/dialogue_component.mdnew file mode 100644index 0000000000..31cbbfb807--- /dev/null+++ b/docs/guides/agent/agent_workflow/dialogue_component.md@@ -0,0 +1,51 @@+---+sidebar_position: 2+title: Dialogue Component+sidebar_label: Dialogue Component+slug: /dialogue_component+sidebar_custom_props: {+ categoryIcon: RagAiAgent+}+---++# Dialogue Component++## Reply Message Component++The message is used to output static or dynamic messages to users, and is usually used as the final component of a workflow. It can directly write fixed text, or insert upstream variables.++### Configuration Method++Write the output content in the message. Type `/` or click the variable button to insert component outputs.++If multiple messages are added, the system randomly selects one of them to send. When the `Begin` component selects `Webhook` and the response method is `Final response`, the reply message component can set an HTTP status code in the range of 200 to 399.++++### Save to Memory++The reply message component can choose to save to memory, storing the conversation in the specified memory. After enabling **User ID**, conversations can be associated with user IDs, and subsequent knowledge retrieval can query related memories by user ID.++### Applicable Scenarios++This component is suitable for outputting final answers, branch hints, fallback replies, or displaying intermediate processing results to users.++### Output Result++The message outputs the configured text or variable content to the conversation window, webhook response, or embedded page.++++## Await Response Component+Await Response pauses the workflow and waits for users to supplement information. Suitable for multi-turn dialogue, form collection, confirmation operations or file upload requirements.++### Configuration Method+Define prompt messages to guide users. Input supports the same variable types as Begin: single-line text, paragraph text, dropdown options, file upload, number and boolean.++Recommendations:+- Dropdown options: Select business categories+- Paragraph text: Collect detailed requirement descriptions+- File upload: Receive contracts, reports or screenshots+- Boolean: Confirm continue/cancel operations++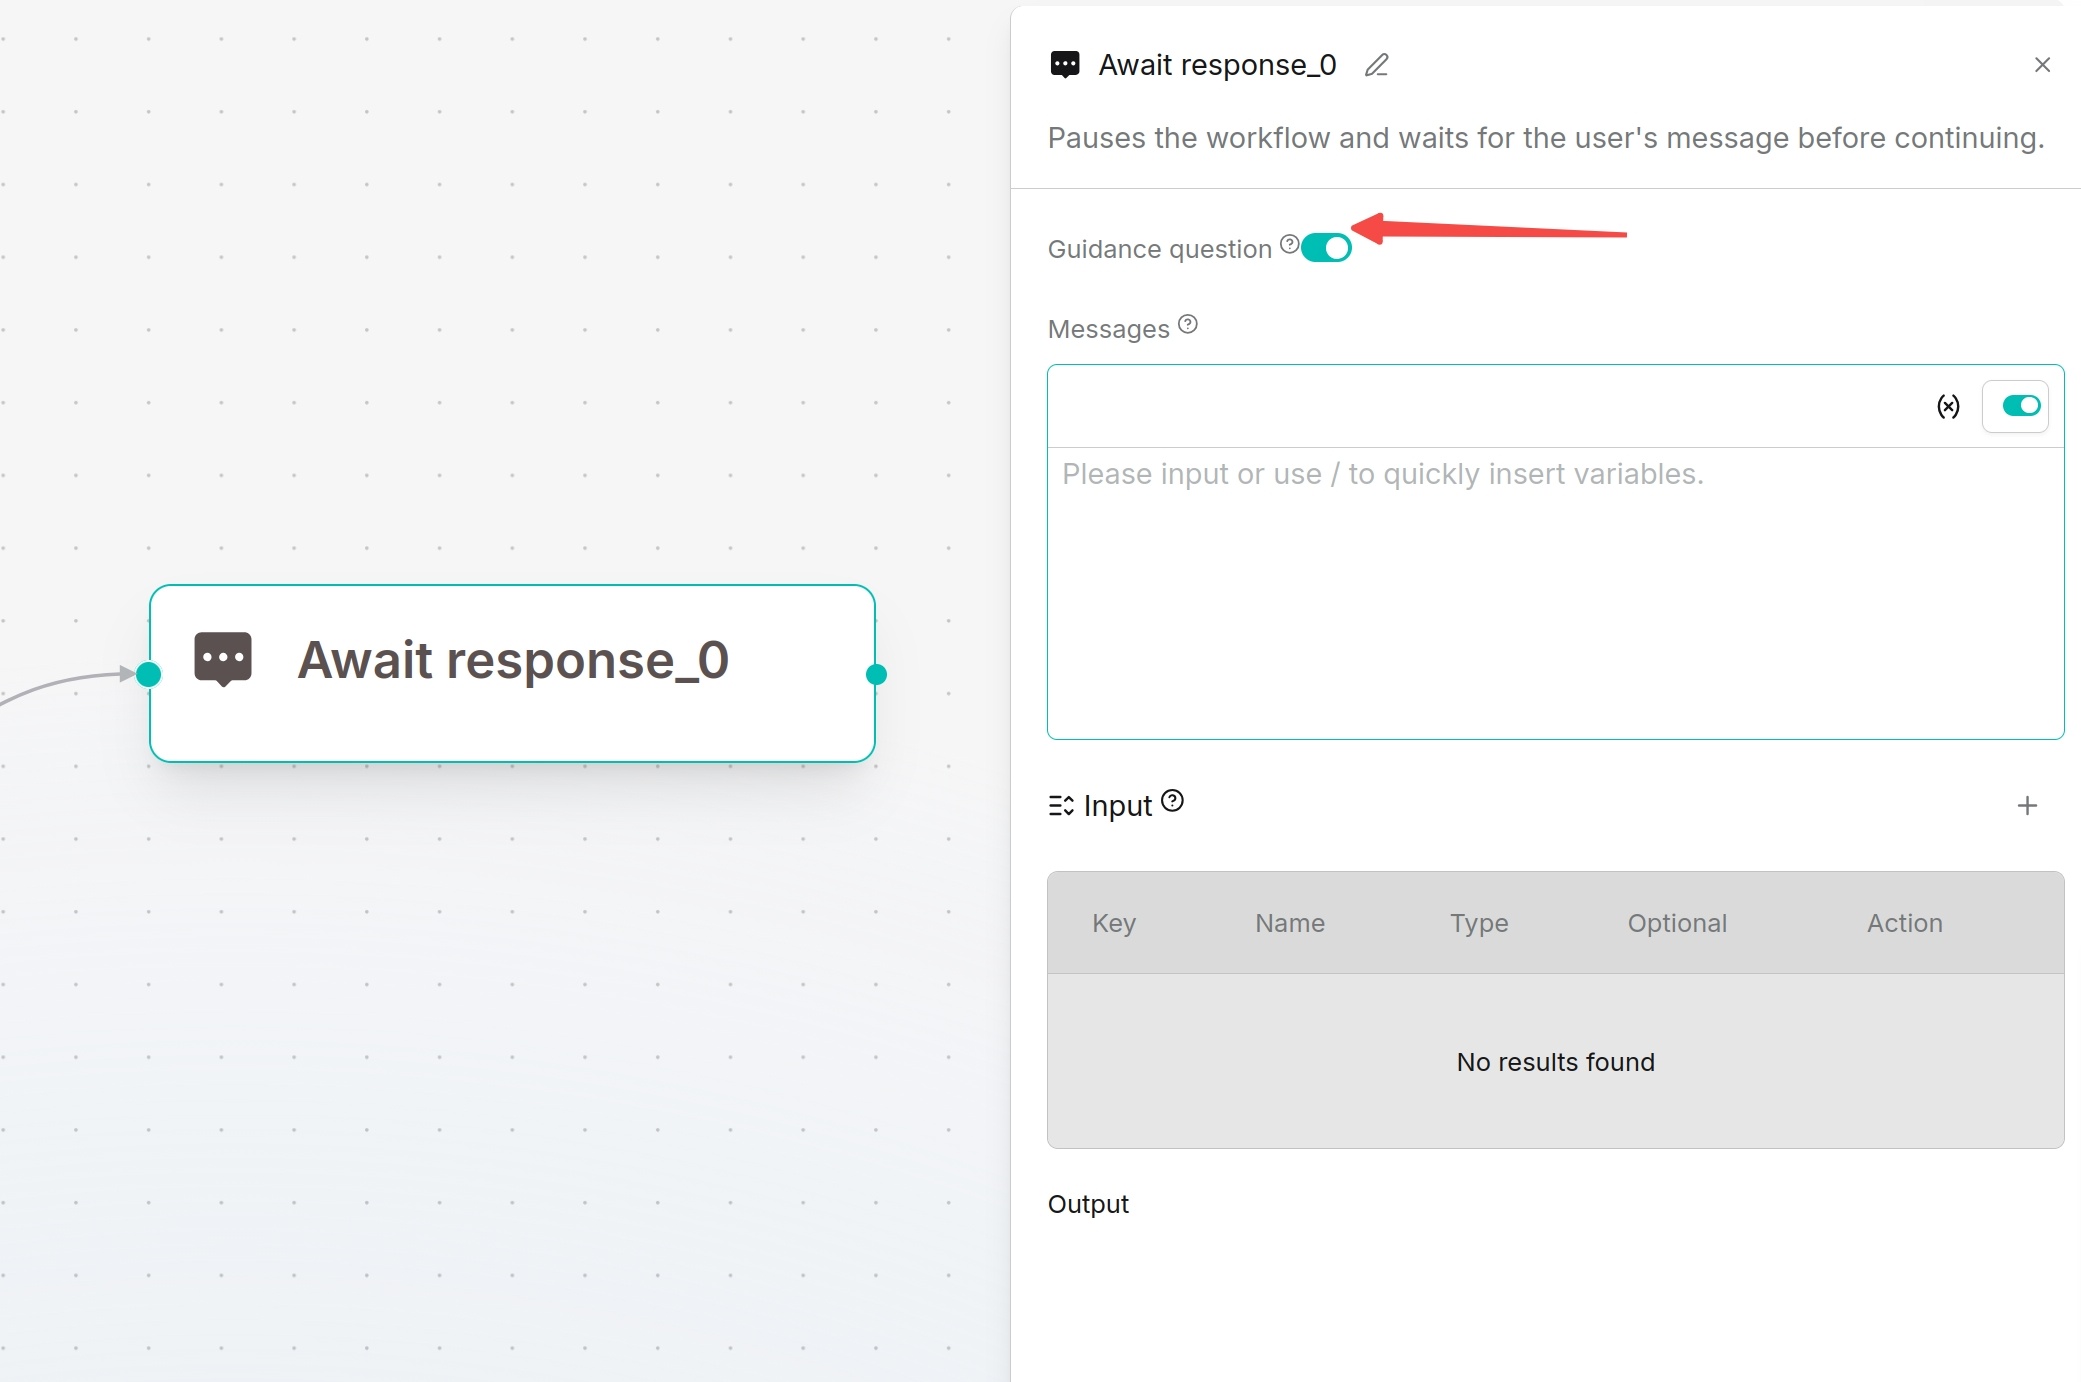diff --git a/docs/guides/agent/agent_workflow/flow_components.md b/docs/guides/agent/agent_workflow/flow_components.mdnew file mode 100644index 0000000000..22d7fa9db5--- /dev/null+++ b/docs/guides/agent/agent_workflow/flow_components.md@@ -0,0 +1,74 @@+---+sidebar_position: 3+title: Flow Components+sidebar_label: Flow Components+slug: /flow_components+sidebar_custom_props: {+ categoryIcon: RagAiAgent+}+---++# Flow Components++## Switch Component+Switch executes rule-based judgment and routes workflows to different downstream paths according to results.++### Configuration Method+At least one Case must be defined. Each Case can contain multiple conditions combined by AND / OR.+Supported operators: Equals, Not equal, Greater than, Greater equal, Less than, Less equal, Contains, Not contains, Starts with, Ends with, Is empty, Not empty.++:::tip NOTE+Switch is rule-based judgment for structured data and clear conditions. Categorize uses LLM-based classification for natural language intent recognition.+:::++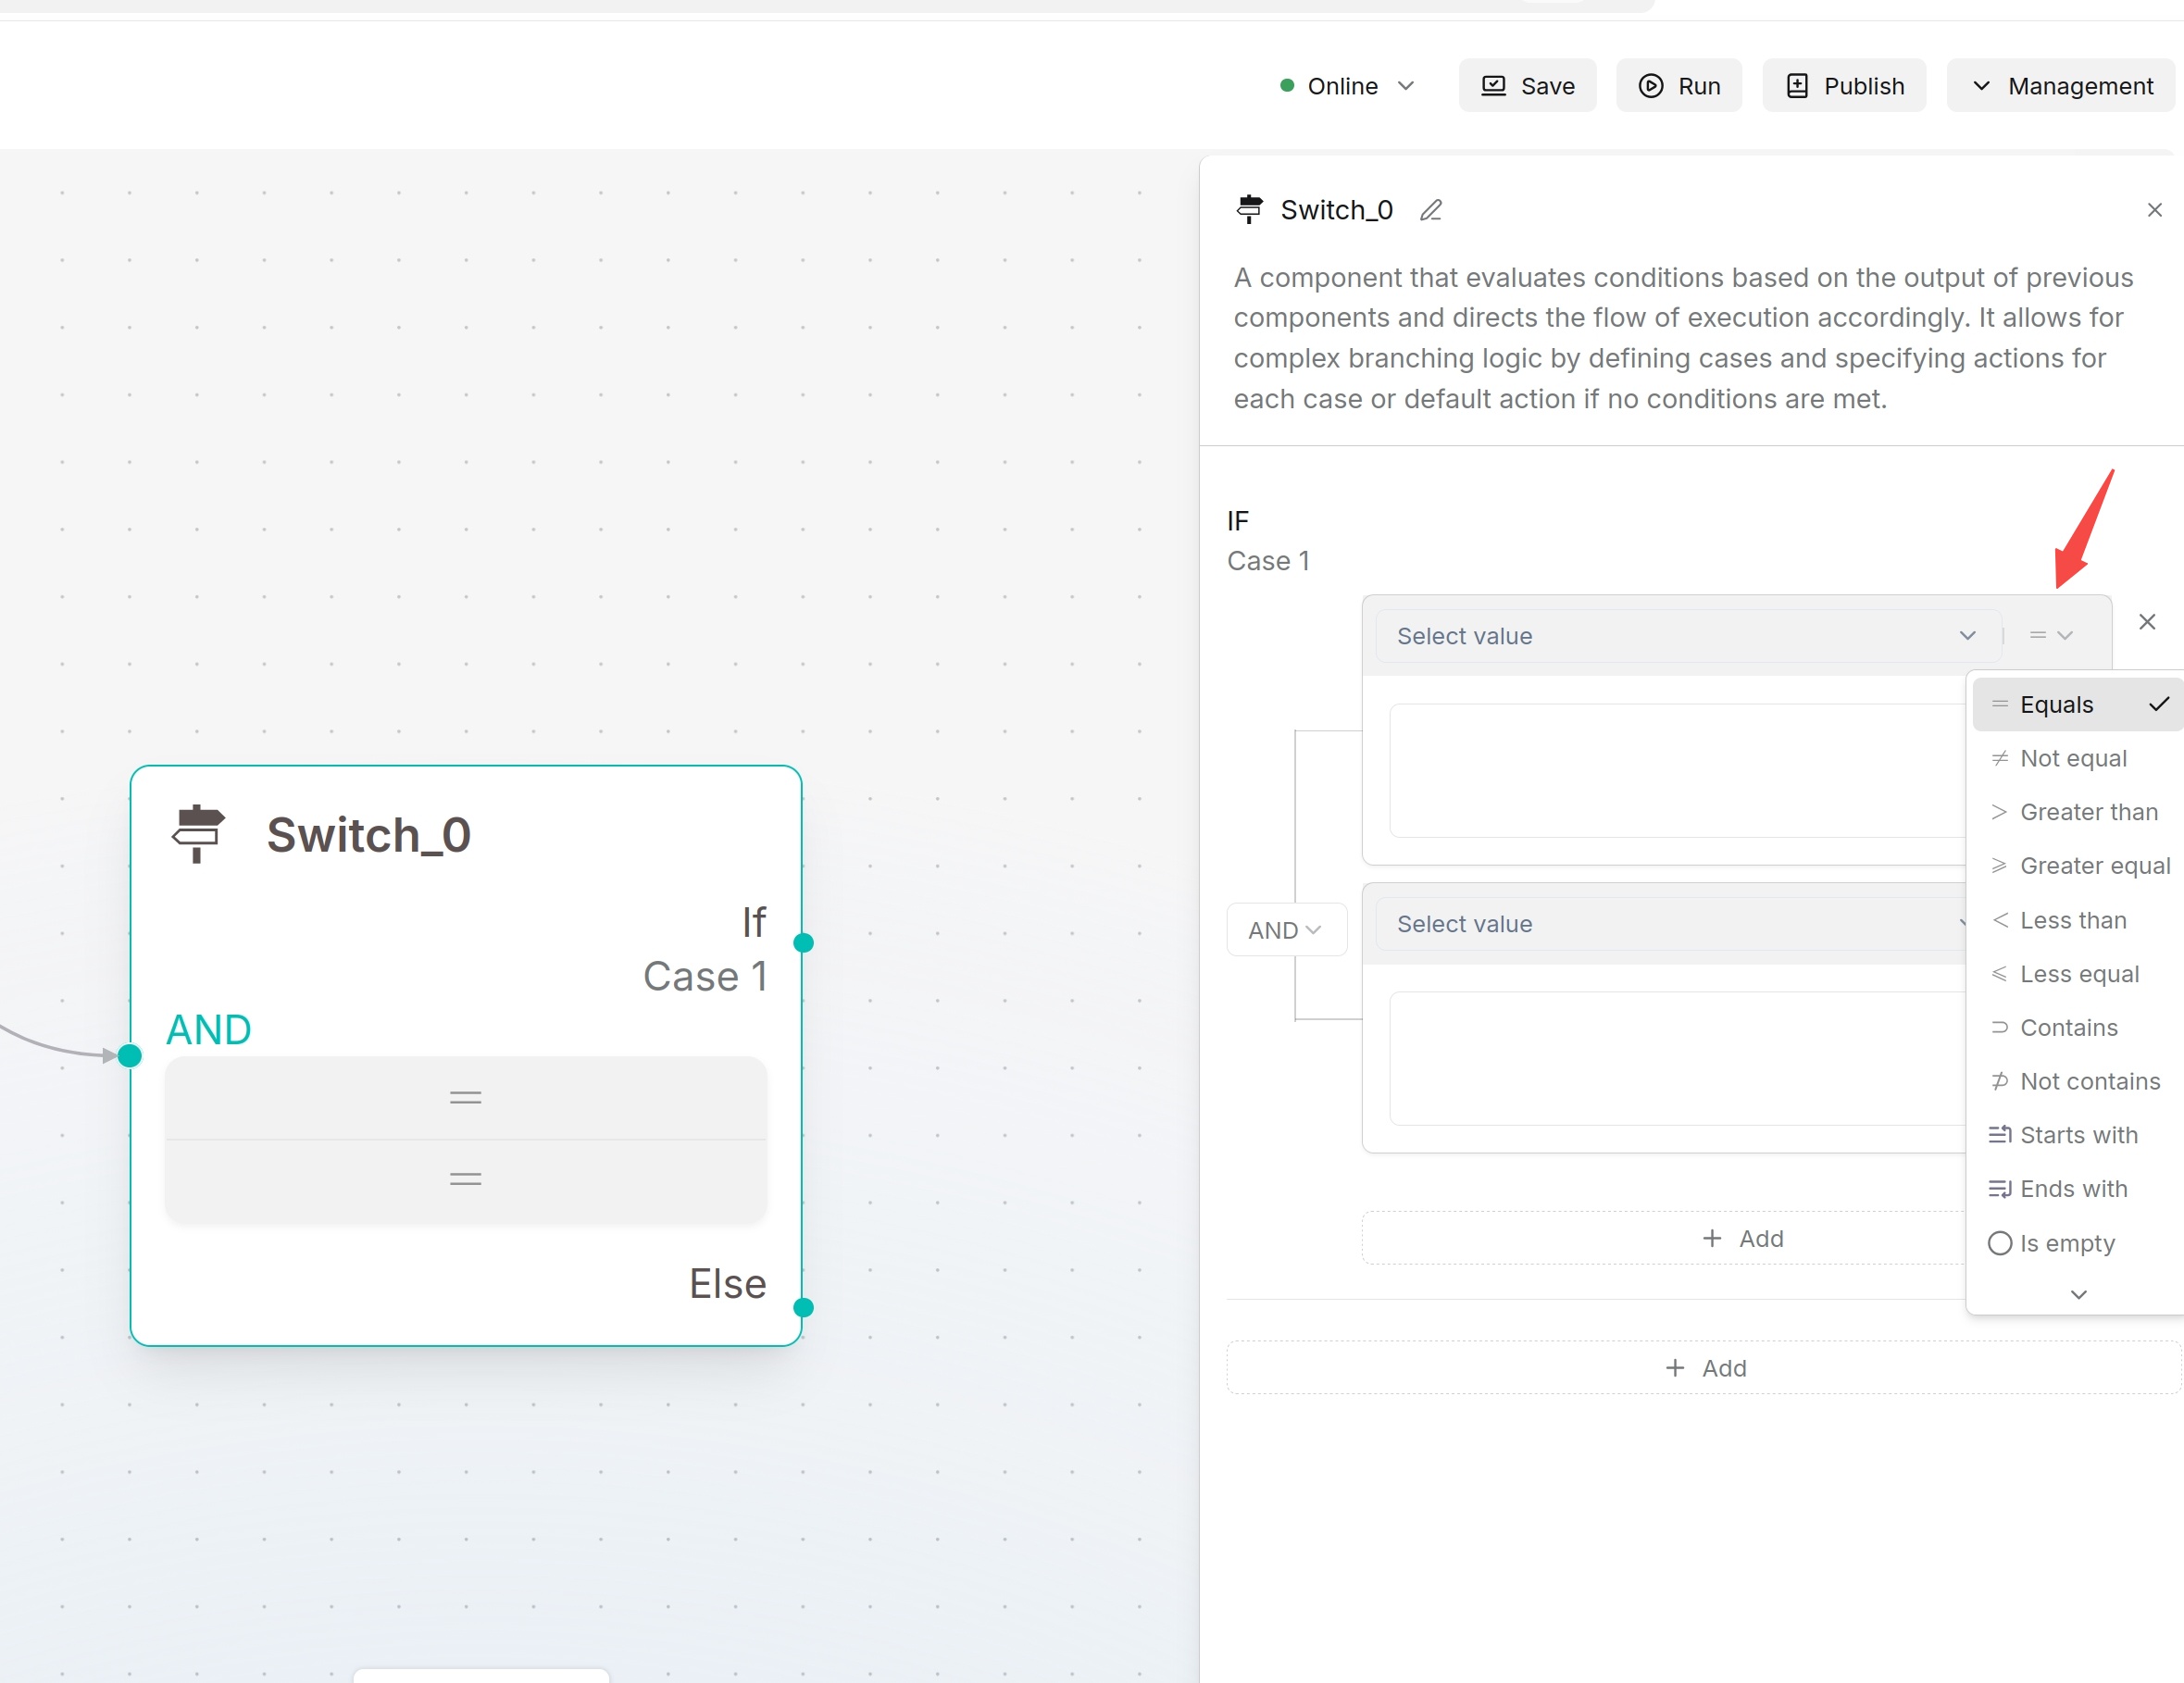++### Iteration+The Iteration component iterates over an array and repeatedly executes the same processing logic for each element. It is suitable for scenarios such as batch file processing or processing multiple data items with the same logic.++#### Configuration+When configuring the Iteration component, set **Query variables** and **Output**.+- **Query variables**: Specifies the array variable to iterate over. You can select an array output from an upstream component or a system variable, such as `sys.files` or `sys.history`. The Iteration component processes each element in the array in sequence and executes the configured internal workflow.+- **Internal workflow**: Add the components to be repeatedly executed inside the Iteration area. In each iteration, the internal workflow processes the current array element until all elements in the array have been processed.+- **Output**: Defines the results returned by each iteration. You can add one or more output fields and select variables generated by components inside the Iteration as their values. After all iterations are completed, the component aggregates the results and makes them available to downstream components.++> **Note**+>+> The Iteration component is suitable when the input is an array and each element can be processed independently. For example, by selecting `sys.files`, you can process multiple files uploaded by the user one by one.++## Loop Component+Iteration splits text into fragments and executes the same set of internal components for each fragment. Suitable for long-text translation, paragraph-wise summarization, batch generation and item-by-item list processing.++### Internal Workflow:+Iteration contains built-in `Loop Item`. Components dragged inside Iteration can only be accessed within the loop. Reference `Loop Item` to obtain current fragment data.++++### Configuration Method+###### **Configuration**+When configuring the Loop component, you need to set the loop variables, loop termination condition, and maximum loop count.+- **Loop variables**: Define the variables used during the loop. Set the variable name, type, and initial value. Other components within the loop can read or update these variables.+- **Loop termination condition**: Defines the condition for exiting the loop. When the condition is met, the Loop stops. Otherwise, it continues to the next iteration.+- **Maximum loop count**: Limits the maximum number of loop iterations to prevent an infinite loop if the termination condition is never met. The Loop automatically stops when the maximum loop count is reached.++:::tip NOTE+Configure both termination condition and maximum loop count to avoid long-running infinite loops.+:::+++## Categorize Component+Categorize uses LLM to judge user intent or input category and branch the workflow based on classification results.++### Configuration Method+1. Select content to classify in Query variable / Input.+2. Select model and Creativity.+3. Configure message window size (keep default for single-turn classification).+4. Add at least two Categories.+5. Fill clear Name, Description and Examples for each category.+6. Connect downstream components for each classification result on the canvas.++### Classification Recommendations+Use easy-to-understand category names, e.g. Product Consultation, Installation Reservation, After-sales Fault, Other Questions.+Examples improve classification stability; provide 2~3 typical samples for each category.++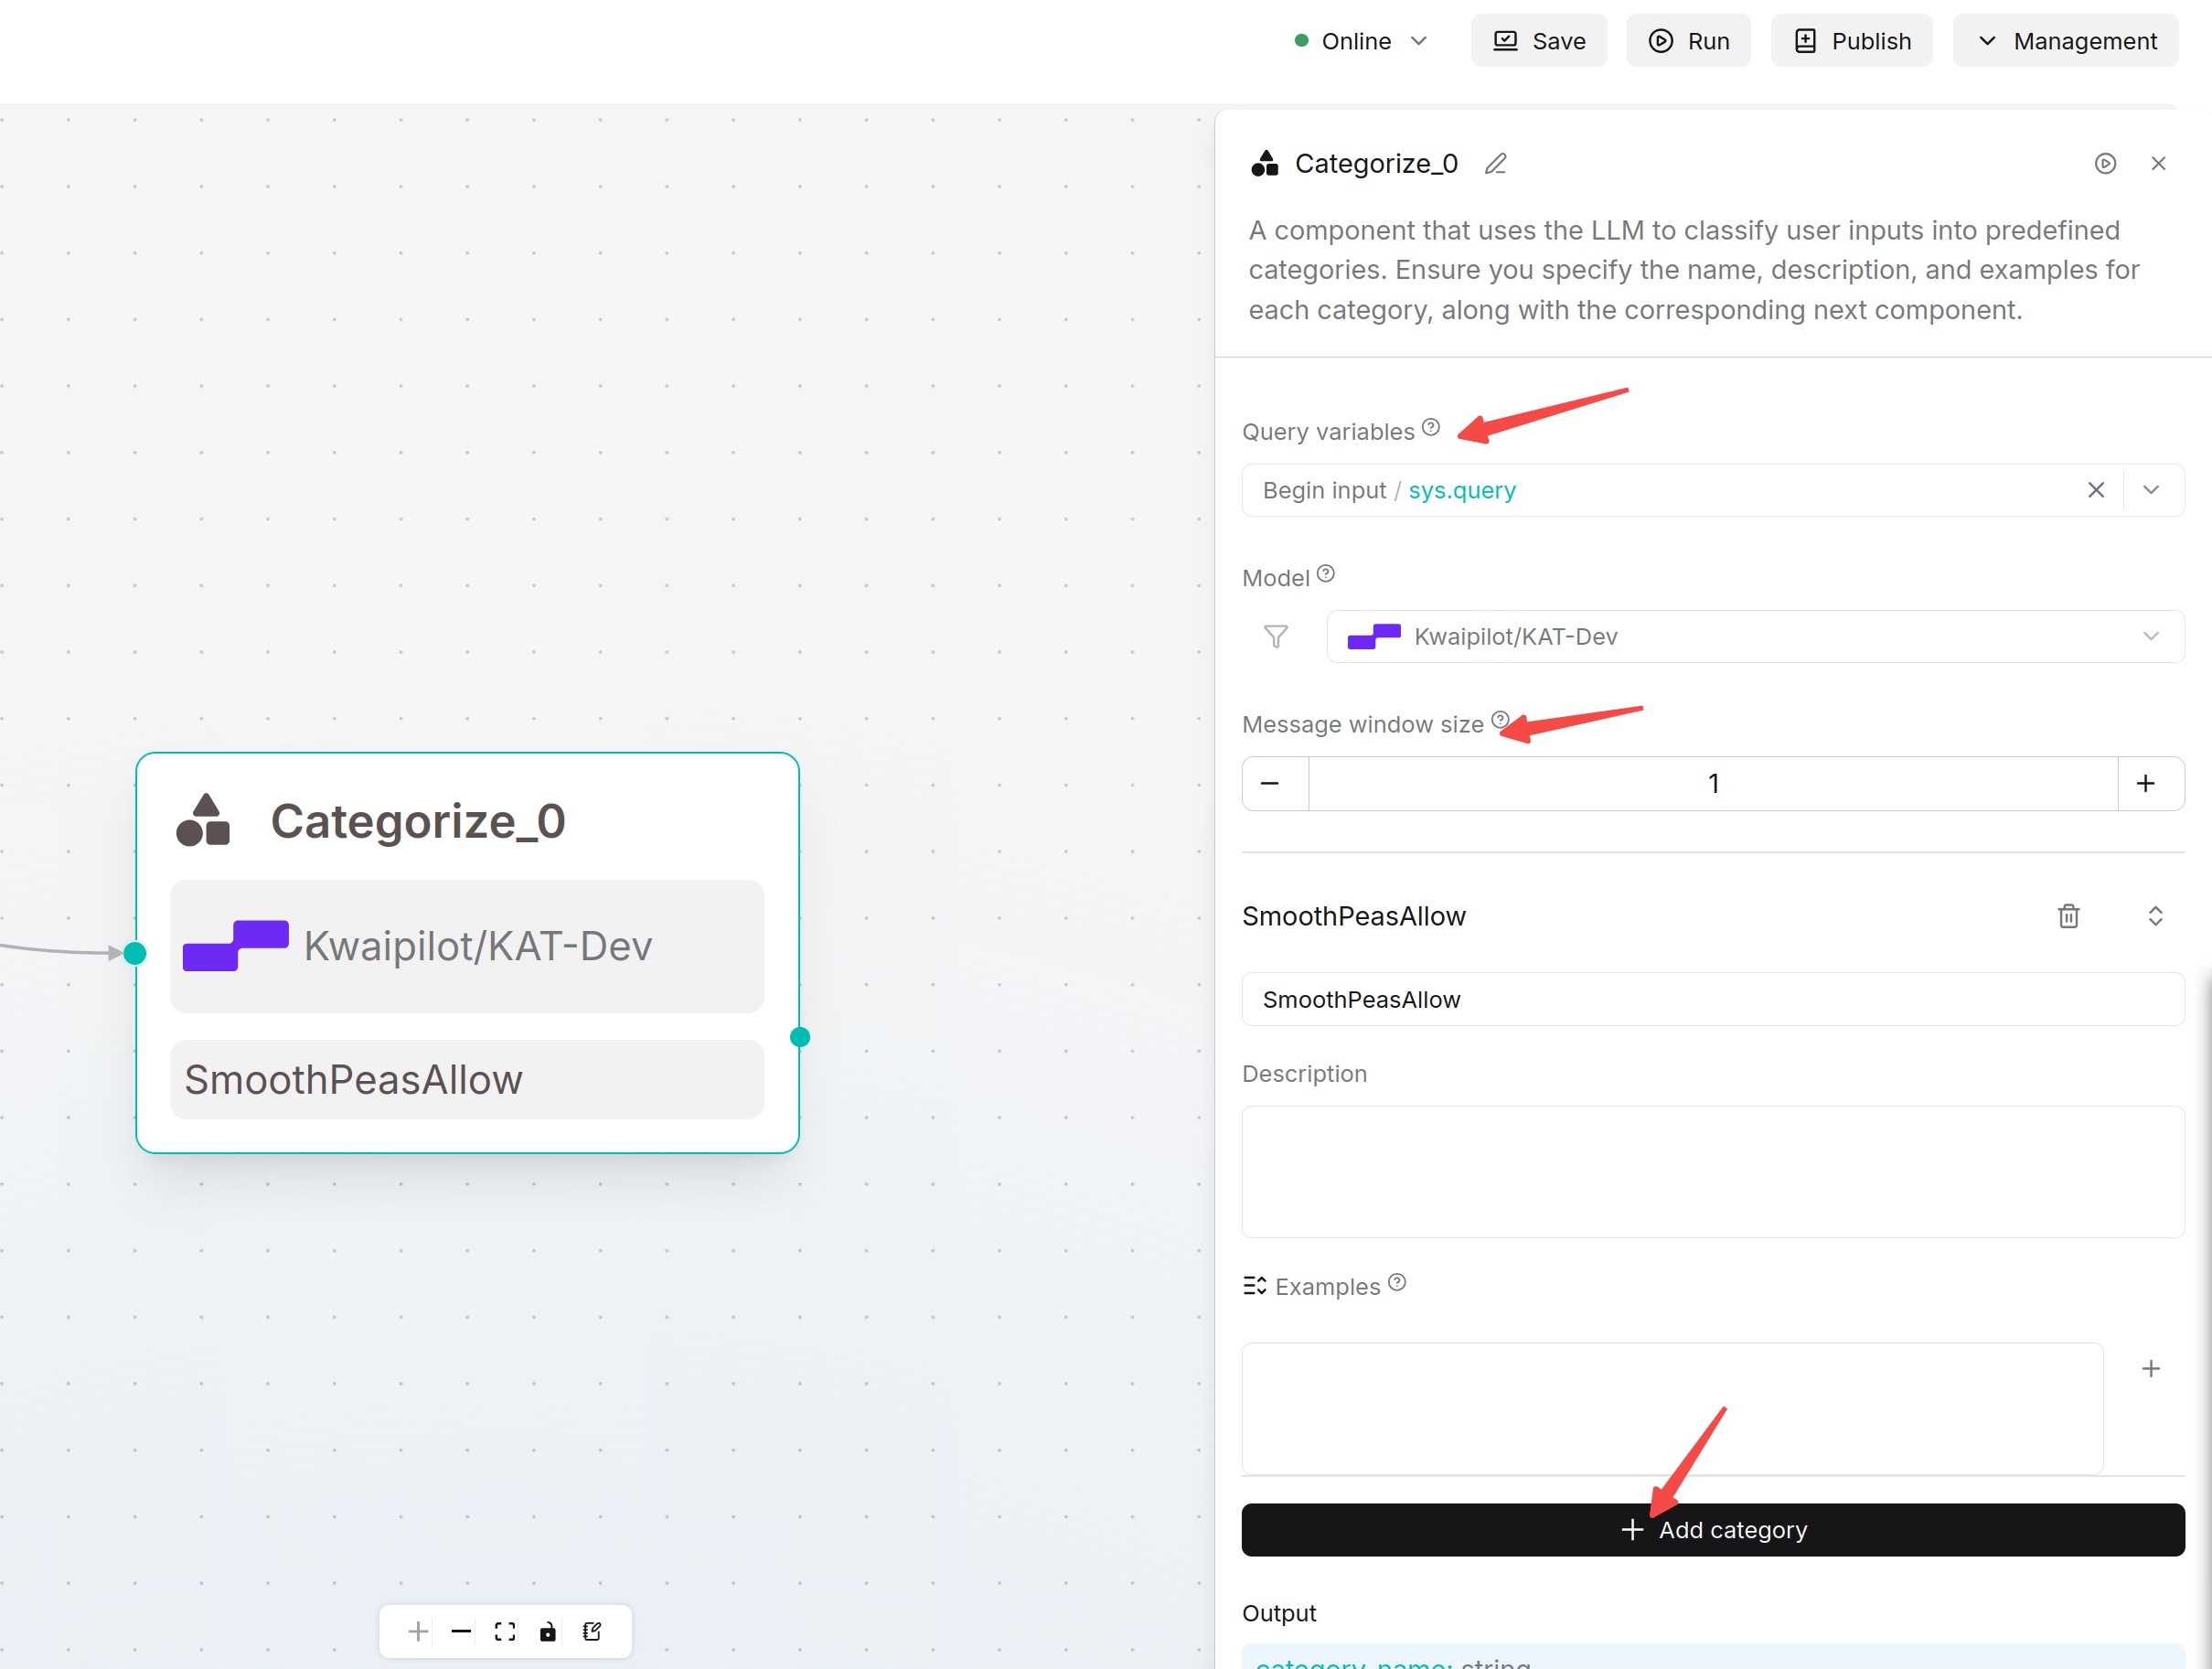diff --git a/docs/guides/agent/agent_workflow/flow_control_components.md b/docs/guides/agent/agent_workflow/flow_control_components.mddeleted file mode 100644index daad36e28b..0000000000--- a/docs/guides/agent/agent_workflow/flow_control_components.md+++ /dev/null@@ -1,72 +0,0 @@-----sidebar_position: 2-title: Flow Control Components-sidebar_label: Flow Control Components-slug: /flow_control_components-sidebar_custom_props: {- categoryIcon: RagAiAgent-}------# Flow Control Components-## Await Response Component-Await Response pauses the workflow and waits for users to supplement information. Suitable for multi-turn dialogue, form collection, confirmation operations or file upload requirements.--Configuration:-Define prompt messages to guide users. Input supports the same variable types as Begin: single-line text, paragraph text, dropdown options, file upload, number and boolean.--Recommendations:-- Dropdown options: Select business categories-- Paragraph text: Collect detailed requirement descriptions-- File upload: Receive contracts, reports or screenshots-- Boolean: Confirm continue/cancel operations-----## Switch (Conditional) Component-Switch executes rule-based judgment and routes workflows to different downstream paths according to results.--Configuration:-At least one Case must be defined. Each Case can contain multiple conditions combined by AND / OR.-Supported operators: Equals, Not equal, Greater than, Greater equal, Less than, Less equal, Contains, Not contains, Starts with, Ends with, Is empty, Not empty.--:::tip NOTE-Switch is rule-based judgment for structured data and clear conditions. Categorize uses LLM-based classification for natural language intent recognition.-:::----## Iteration Component-Iteration splits text into fragments and executes the same set of internal components for each fragment. Suitable for long-text translation, paragraph-wise summarization, batch generation and item-by-item list processing.--Internal Workflow:-Iteration contains built-in `Loop Item`. Components dragged inside Iteration can only be accessed within the loop. Reference `Loop Item` to obtain current fragment data.--Configuration Parameters:-- **Loop variables**: Variables used during iteration; support read and update inside the loop-- **Loop termination condition**: Exit condition to stop iteration-- **Maximum loop count**: Prevent infinite iteration--:::tip NOTE-Configure both termination condition and maximum loop count to avoid long-running infinite loops.-:::----## Categorize Component-Categorize uses LLM to judge user intent or input category and branch the workflow based on classification results.--Configuration Steps:-1. Select content to classify in Query variable / Input.-2. Select model and Creativity.-3. Configure message window size (keep default for single-turn classification).-4. Add at least two Categories.-5. Fill clear Name, Description and Examples for each category.-6. Connect downstream components for each classification result on the canvas.--Classification Recommendations:-Use easy-to-understand category names, e.g. Product Consultation, Installation Reservation, After-sales Fault, Other Questions.-Examples improve classification stability; provide 2~3 typical samples for each category.--diff --git a/docs/guides/agent/agent_workflow/tool_components.md b/docs/guides/agent/agent_workflow/tool_components.mdindex 0d4d95d3ff..b3f2532f16 100644--- a/docs/guides/agent/agent_workflow/tool_components.md+++ b/docs/guides/agent/agent_workflow/tool_components.md@@ -1,5 +1,5 @@----sidebar_position: 4+sidebar_position: 5title: Tool Componentssidebar_label: Tool Componentsslug: /tool_components@@ -24,7 +24,7 @@ Tool components connect external search, databases, HTTP APIs, email sending, do## Web Page and Information Retrieval-### Tavily Search (TavilySearch)+### Tavily SearchTavily is a web search service for LLMs. It is suitable for retrieving general web information, news, and content that needs to be limited to specific domains. Keep queries focused on a single topic and avoid overly long natural-language questions.@@ -70,7 +70,7 @@ The output usually contains search result summaries, titles, links, snippets, an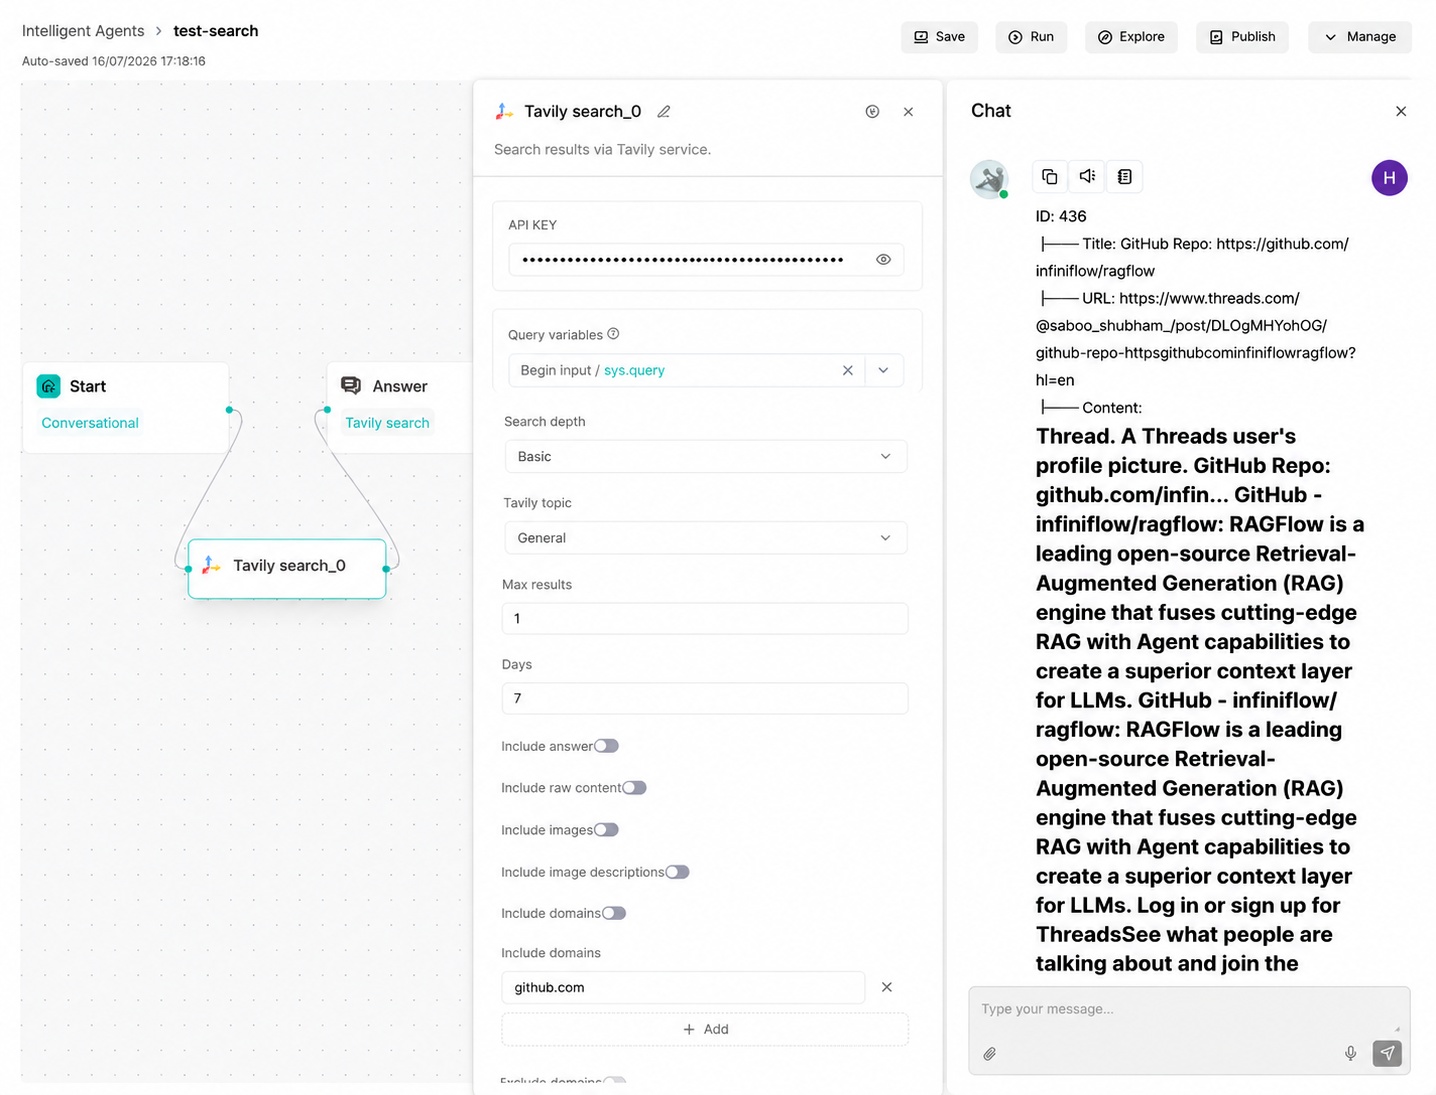-### Tavily Extract (TavilyExtract)+### Tavily ExtractTavily Extract reads the body content of one or more known URLs. A common workflow is to use Tavily Search to obtain links, then pass those links to this component to extract page content.@@ -109,7 +109,7 @@ The output contains the page body, title, URL, and extraction status. `formalize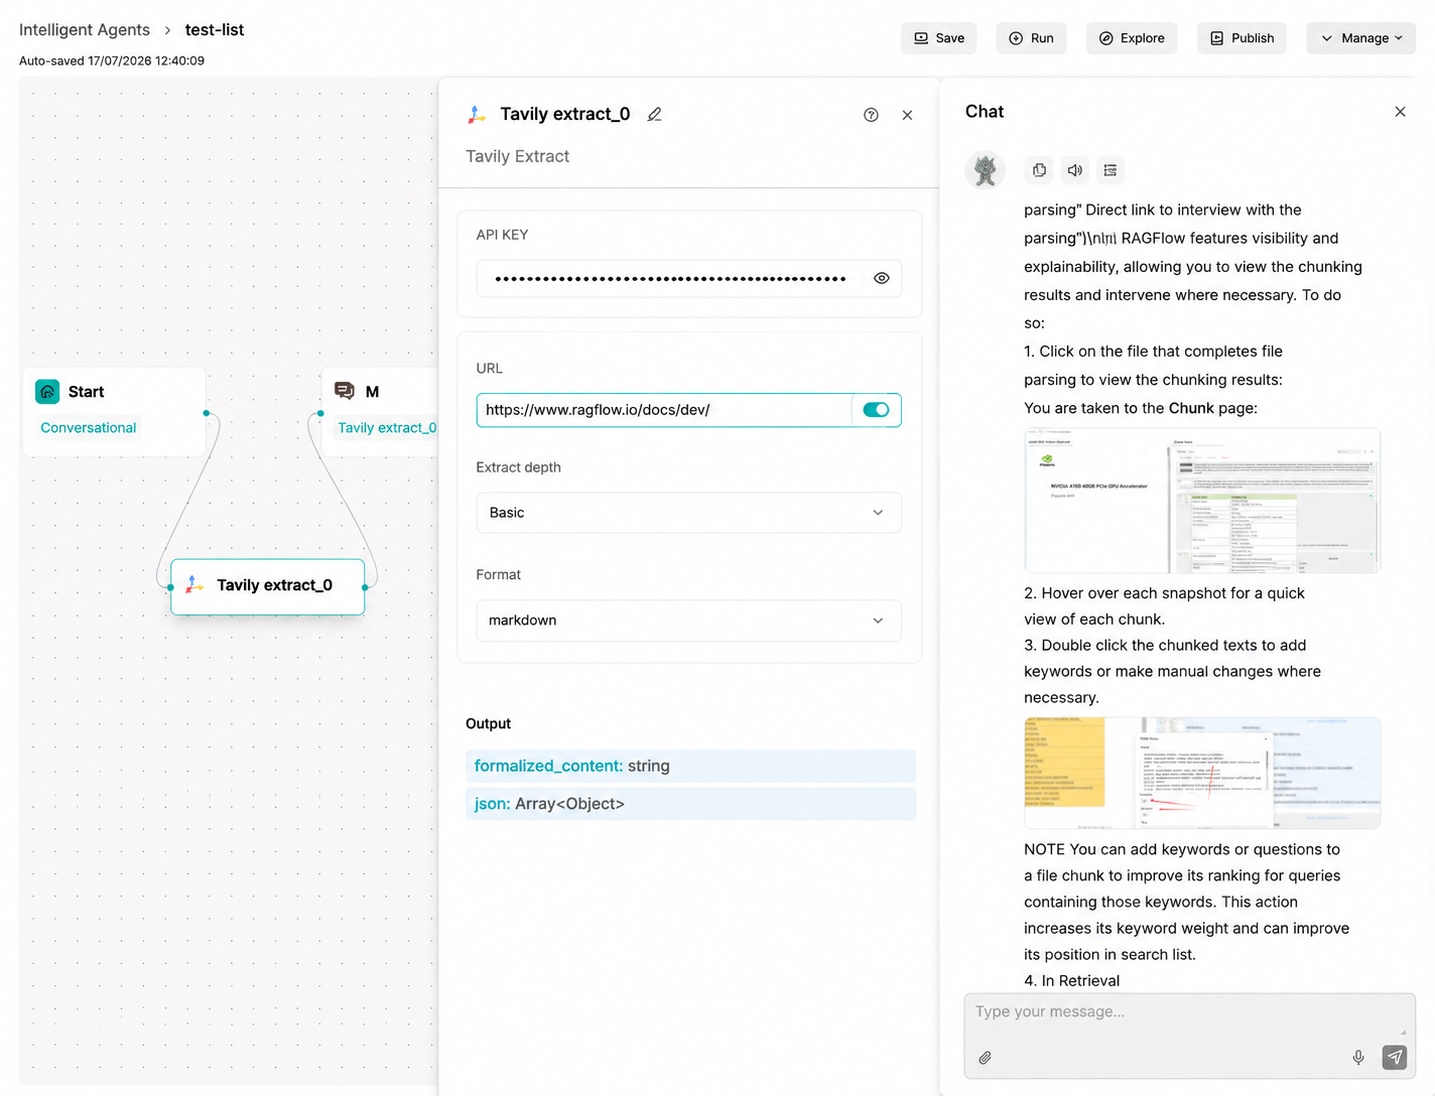-### Google Search (Google)Google Search obtains Google organic search results through SerpApi. It is suitable for web retrieval that requires country and language targeting.@@ -141,7 +141,7 @@ The output contains search result titles, links, and summaries. The organized te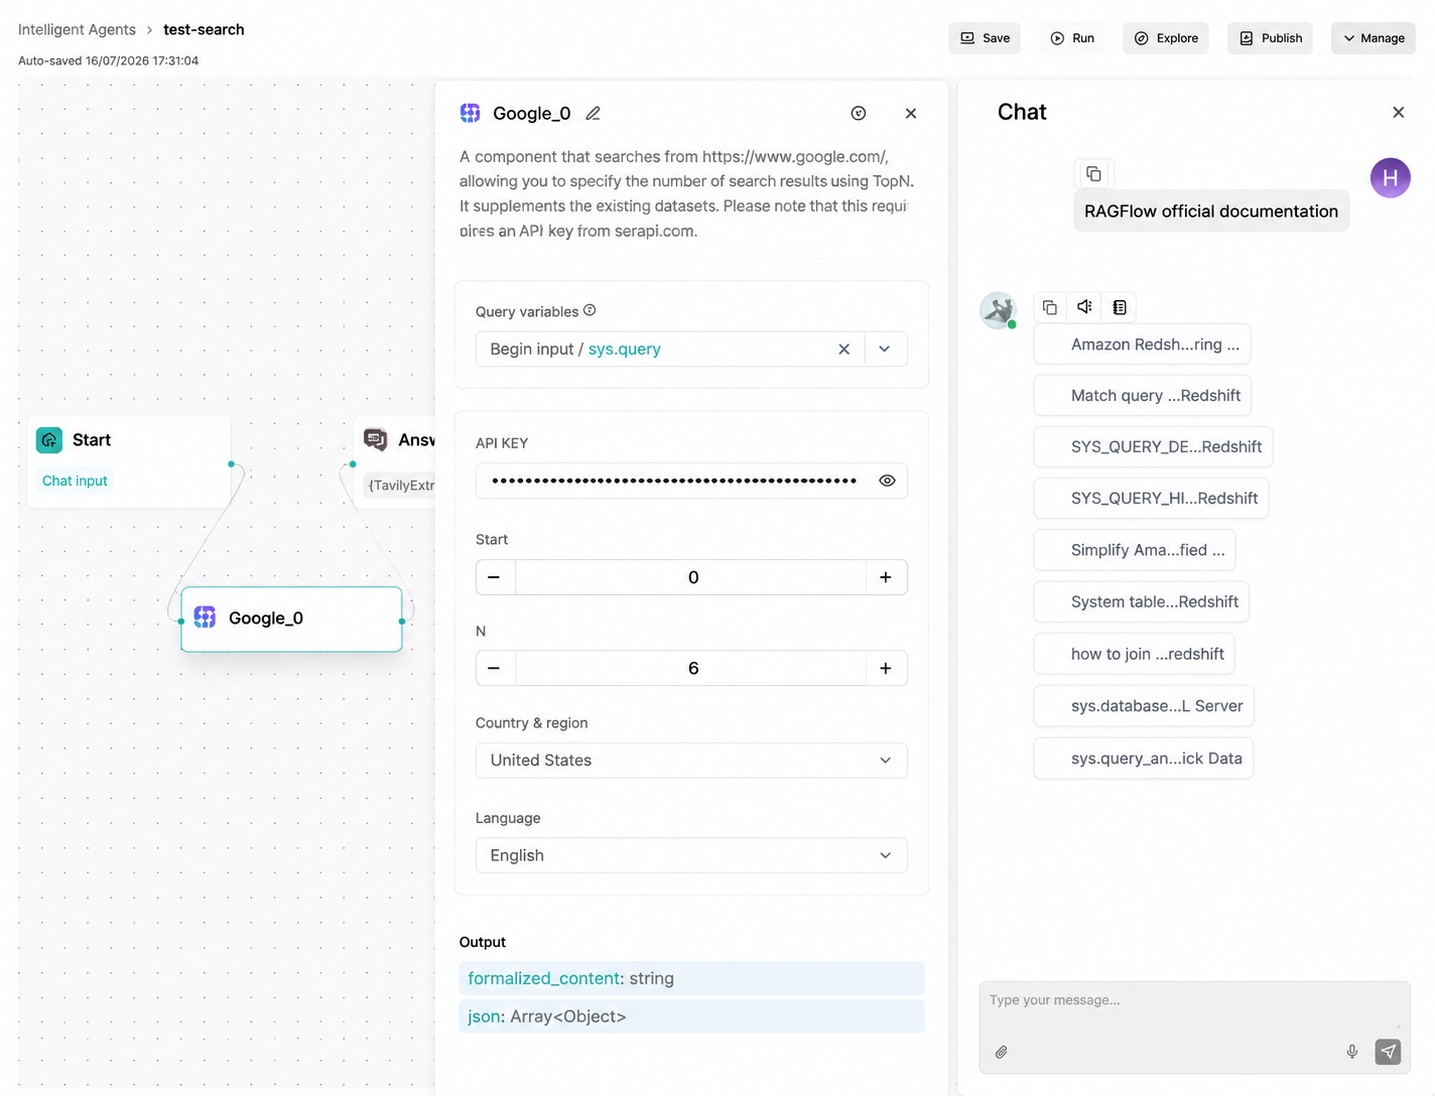-### DuckDuckGo (DuckDuckGo)+### DuckDuckGoDuckDuckGo is a privacy-focused search engine component. It does not require a separate API key and can be used for general web and news retrieval.@@ -169,7 +169,7 @@ The output contains titles, links, and summaries returned by DuckDuckGo. It can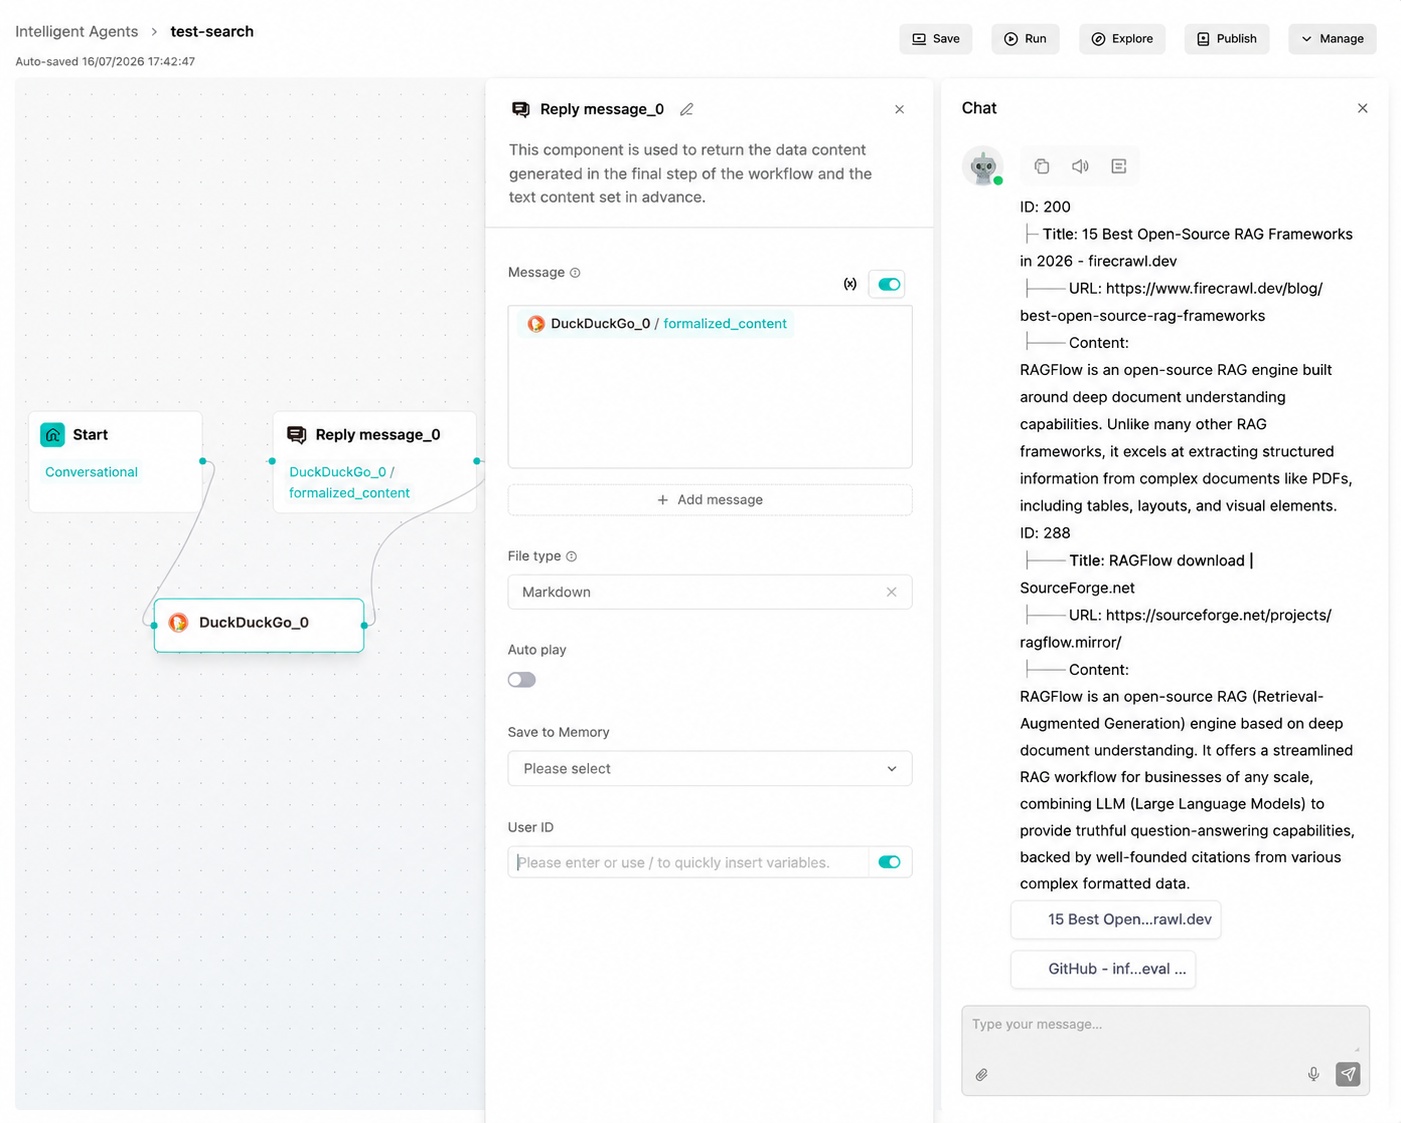-### SearXNG (SearXNG)+### SearXNGSearXNG is a self-hostable privacy-oriented meta-search engine. This component calls a user-provided SearXNG instance and is suitable for scenarios that need control over retrieval sources or internal search deployment.@@ -193,7 +193,7 @@ SearXNG is a self-hostable privacy-oriented meta-search engine. This component cThe output contains titles, links, summaries, and source information returned by SearXNG. Before use, configure a reachable SearXNG service address and pass the system security checks.-### Keenable (KeenableSearch)+### KeenableKeenable is a web search API for AI Agents. By default, it supports a public free path without a key. After configuring a key, you can increase the limit and enable low-latency realtime mode.@@ -225,8 +225,7 @@ The output contains search entries, summaries, and links returned by Keenable. I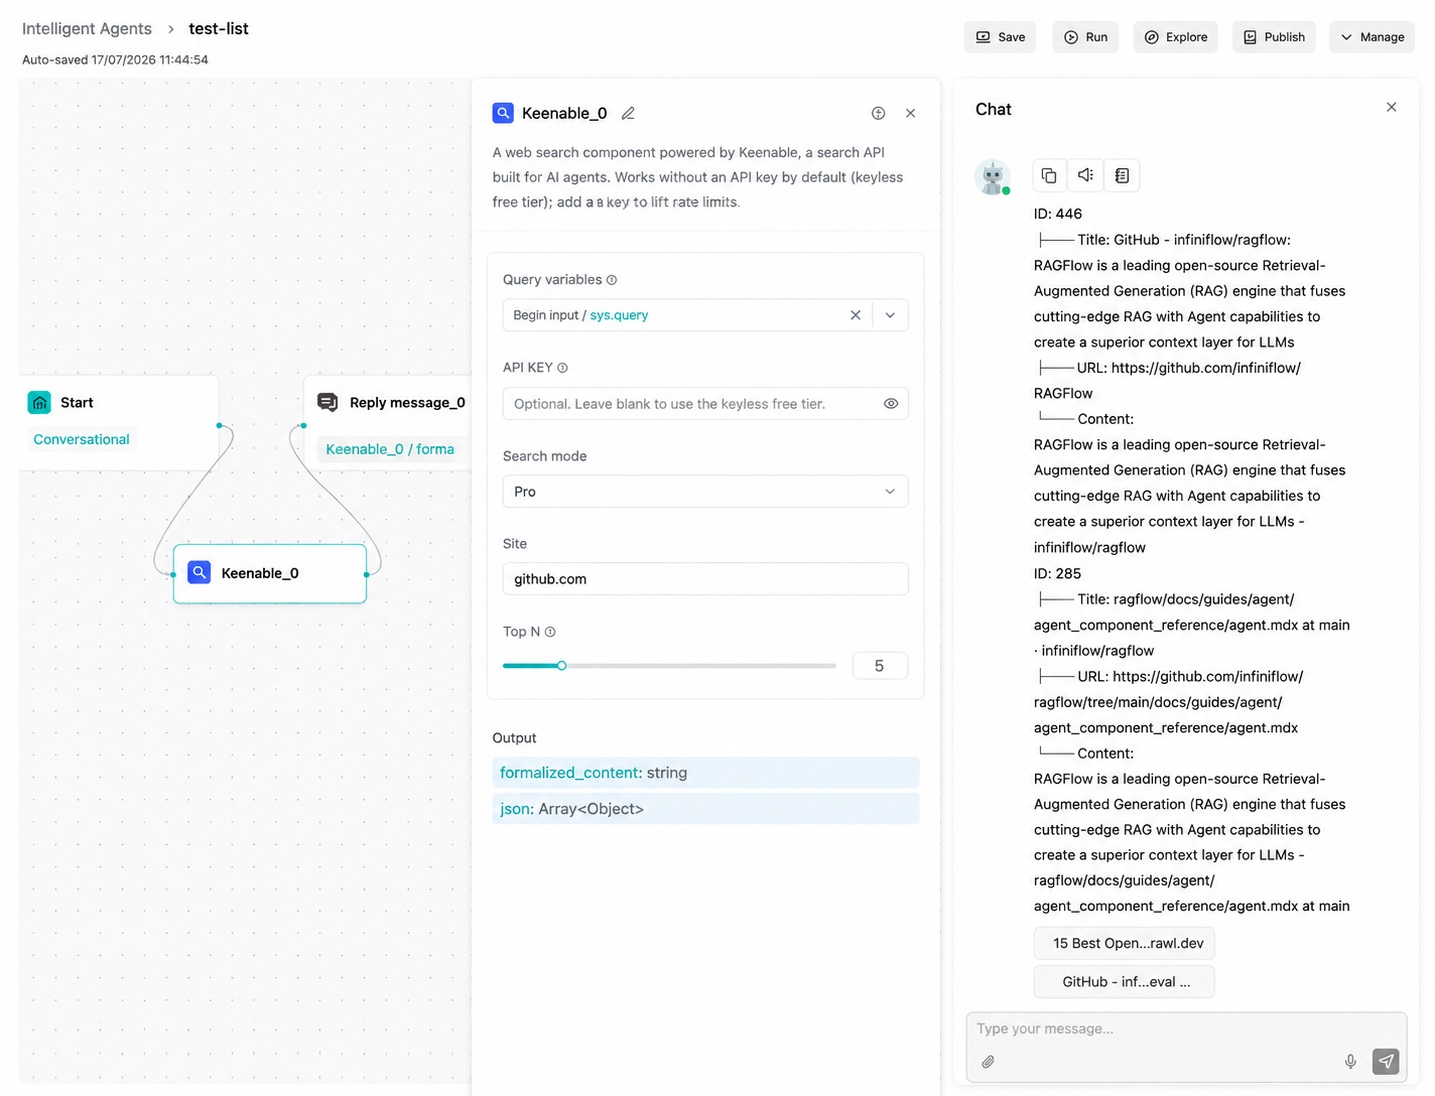-### Wikipedia (Wikipedia)-+### WikipediaThe Wikipedia component searches encyclopedia entries and extracts entry summaries. It is suitable for querying clear entities, concepts, and historical events. Query terms should be as close as possible to the entry title.#### Parameter Description@@ -251,7 +250,7 @@ The output contains the titles, summaries, and page links of matching entries. I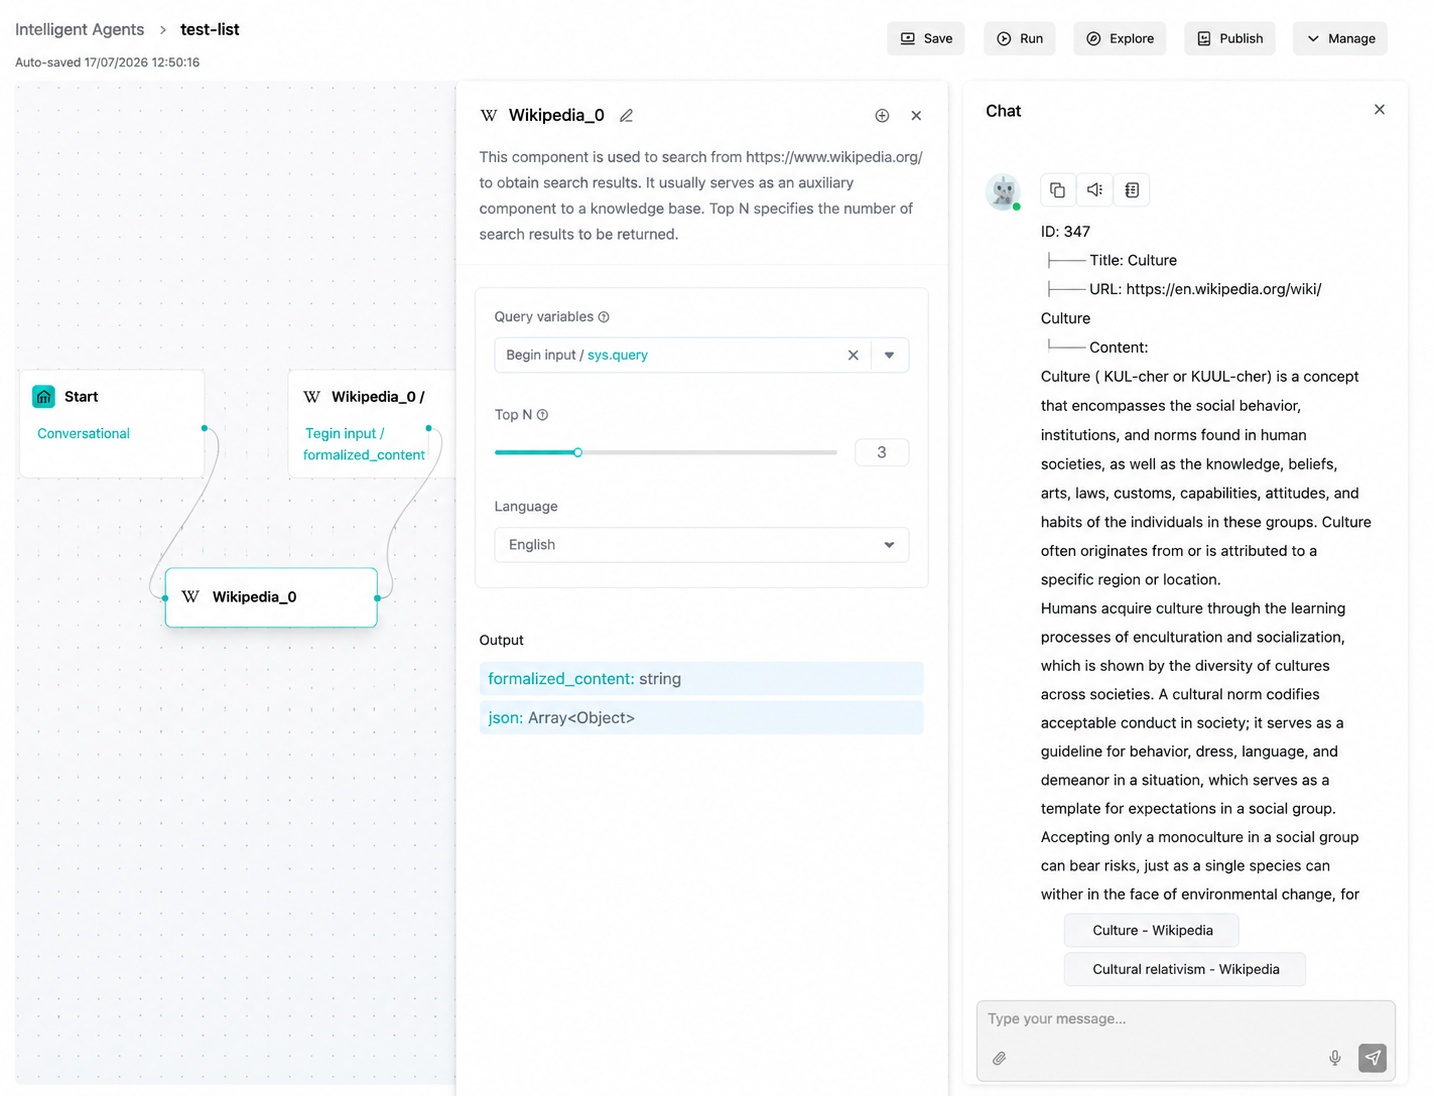-### GitHub (GitHub)+### GitHubThe GitHub component searches repositories through the GitHub Repository Search API and sorts by popularity by default. It is suitable for finding open-source projects, reference implementations, and technology ecosystems.@@ -277,7 +276,7 @@ The output contains repository, issue, code, or user search entries, usually inc## Academic Literature Retrieval-### Google Scholar (GoogleScholar)+### Google ScholarGoogle Scholar is used to retrieve papers, dissertations, books, abstracts, and other academic materials. It is suitable for preliminary literature discovery before a research review, but should not replace verification of original texts and citation information.@@ -309,7 +308,7 @@ The output contains academic retrieval entries such as paper titles, authors, ab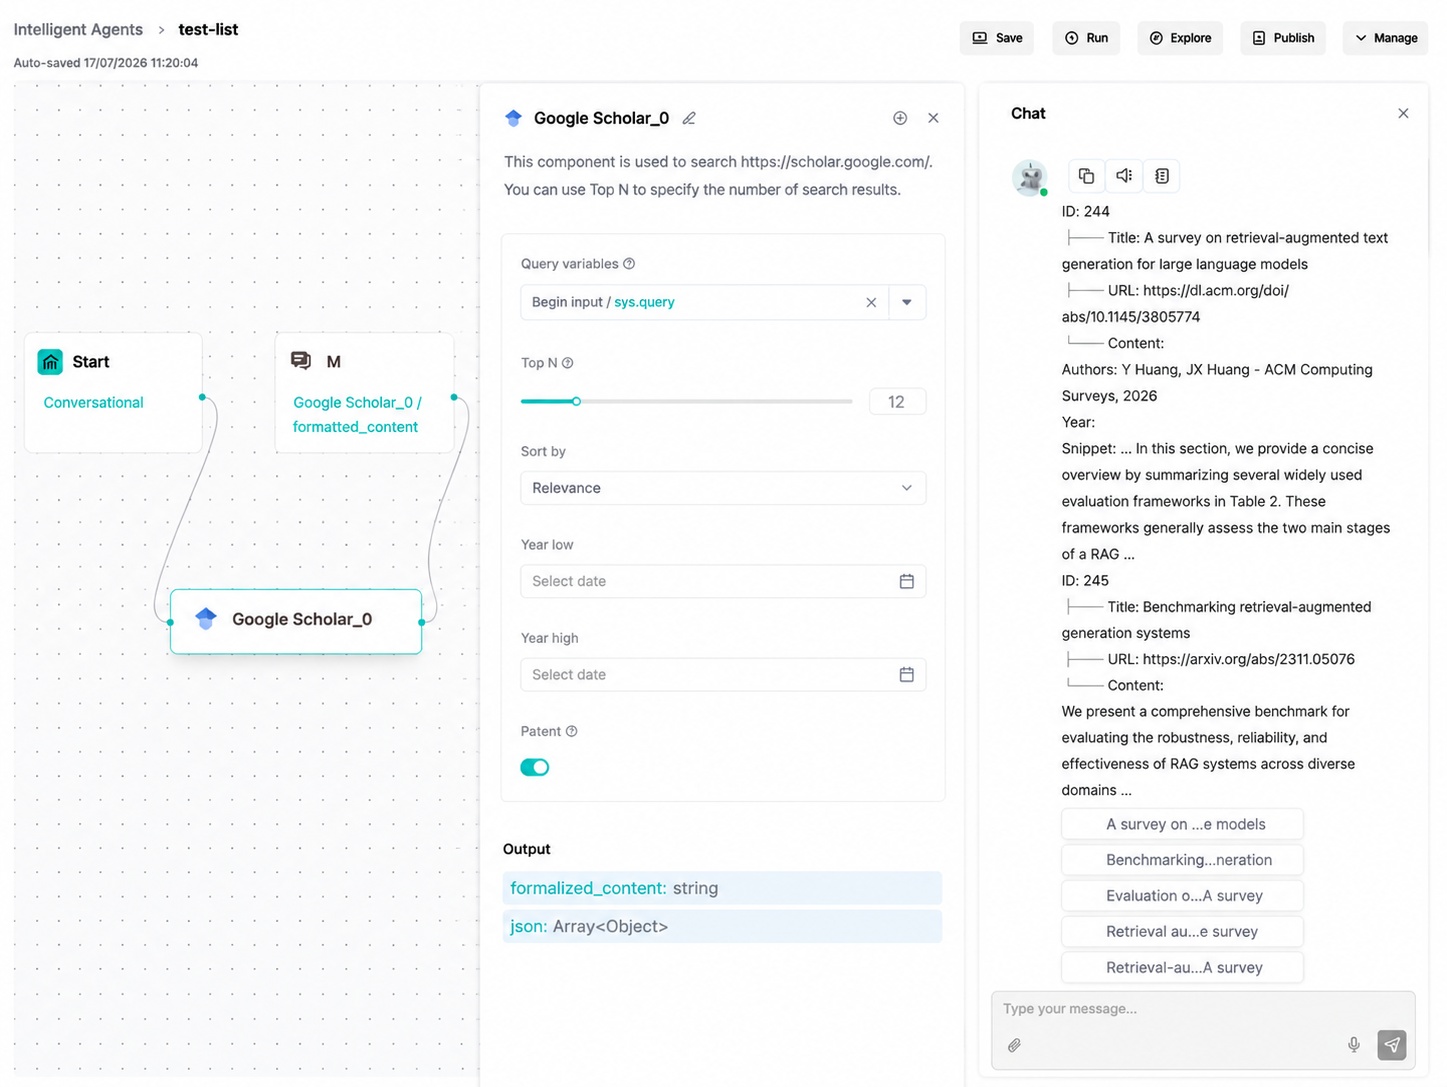-### ArXiv (ArXiv)+### ArXivArXiv is used to retrieve open preprints across fields such as computer science, mathematics, physics, and quantitative finance. ArXiv papers may not have undergone peer review, so mark their preprint nature when using the results.@@ -335,7 +334,7 @@ The output contains paper titles, authors, abstracts, publication times, categor-### PubMed (PubMed)+### PubMedPubMed is used to retrieve life science and biomedical literature. The component queries through NCBI E-utilities and returns titles, authors, journals, DOIs, abstracts, and other information.@@ -361,7 +360,7 @@ The output contains medical literature titles, authors, journals, abstracts, pub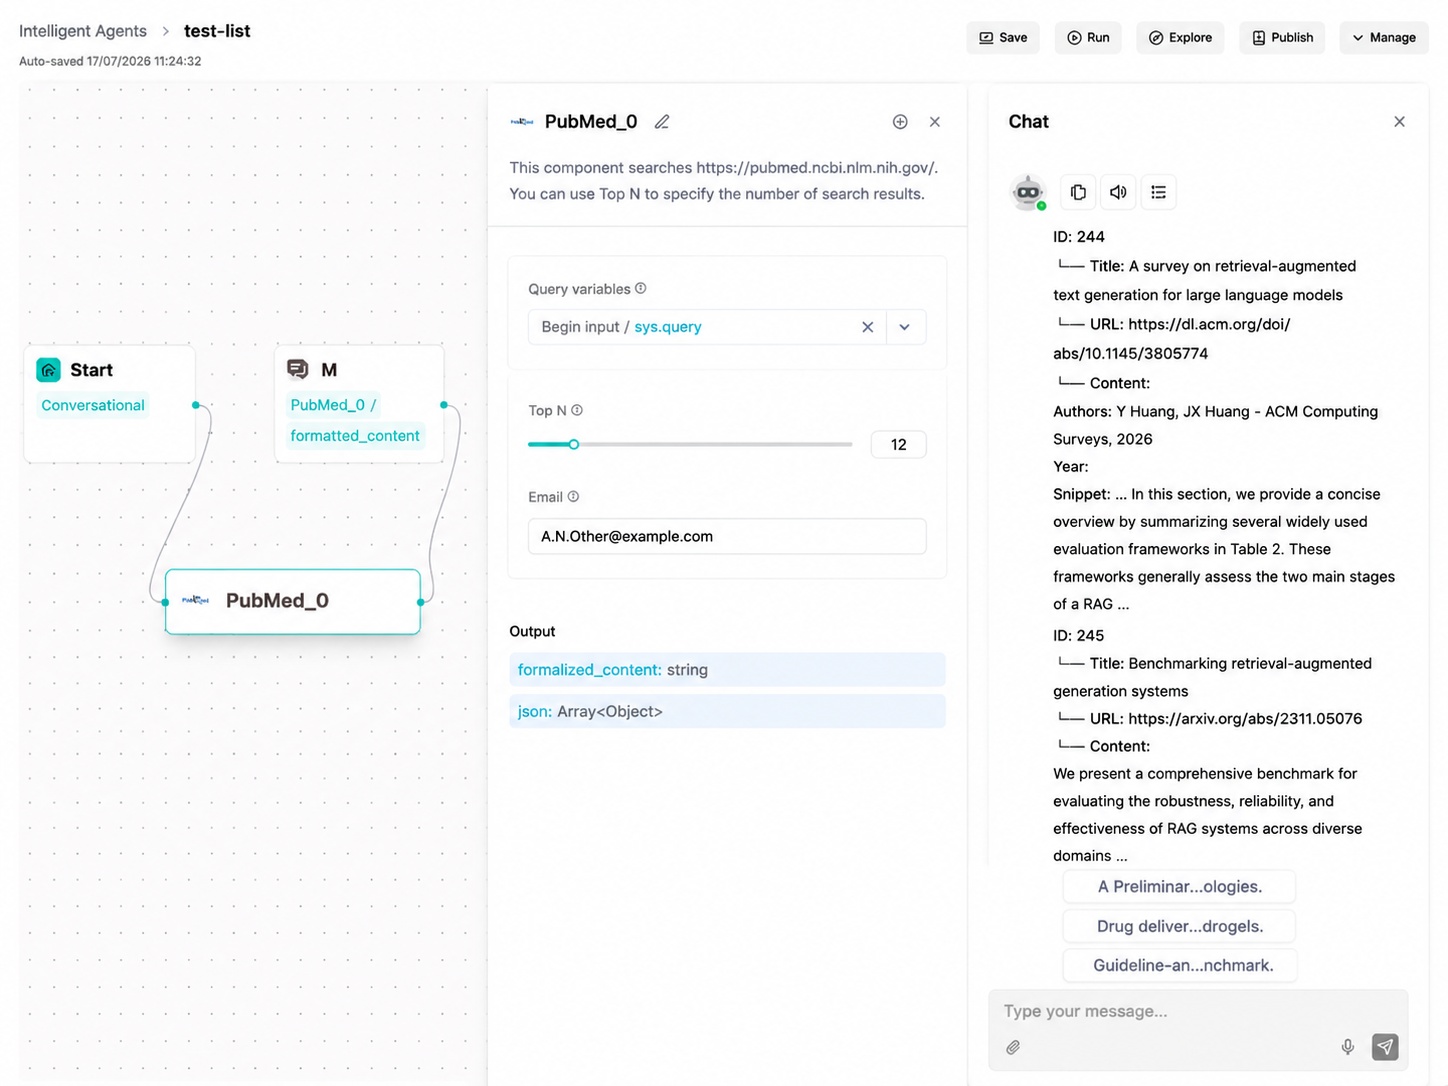-### BGPT (BGPT)+### BGPTBGPT retrieves scientific papers and returns structured evidence, including research methods, sample sizes, results, limitations, conflicts of interest, data availability, and falsifiability tips. It is suitable for evaluating scientific claims, not only for finding paper abstracts.@@ -391,7 +390,7 @@ The output contains biomedical knowledge retrieval results and summaries, which## Data and Financial Queries-### Execute SQL (ExeSQL)+### Execute SQLExecute SQL connects to an external database and executes SQL statements. The result is formatted as text or table content.@@ -441,7 +440,7 @@ The output contains SQL execution results, field names, and record content. You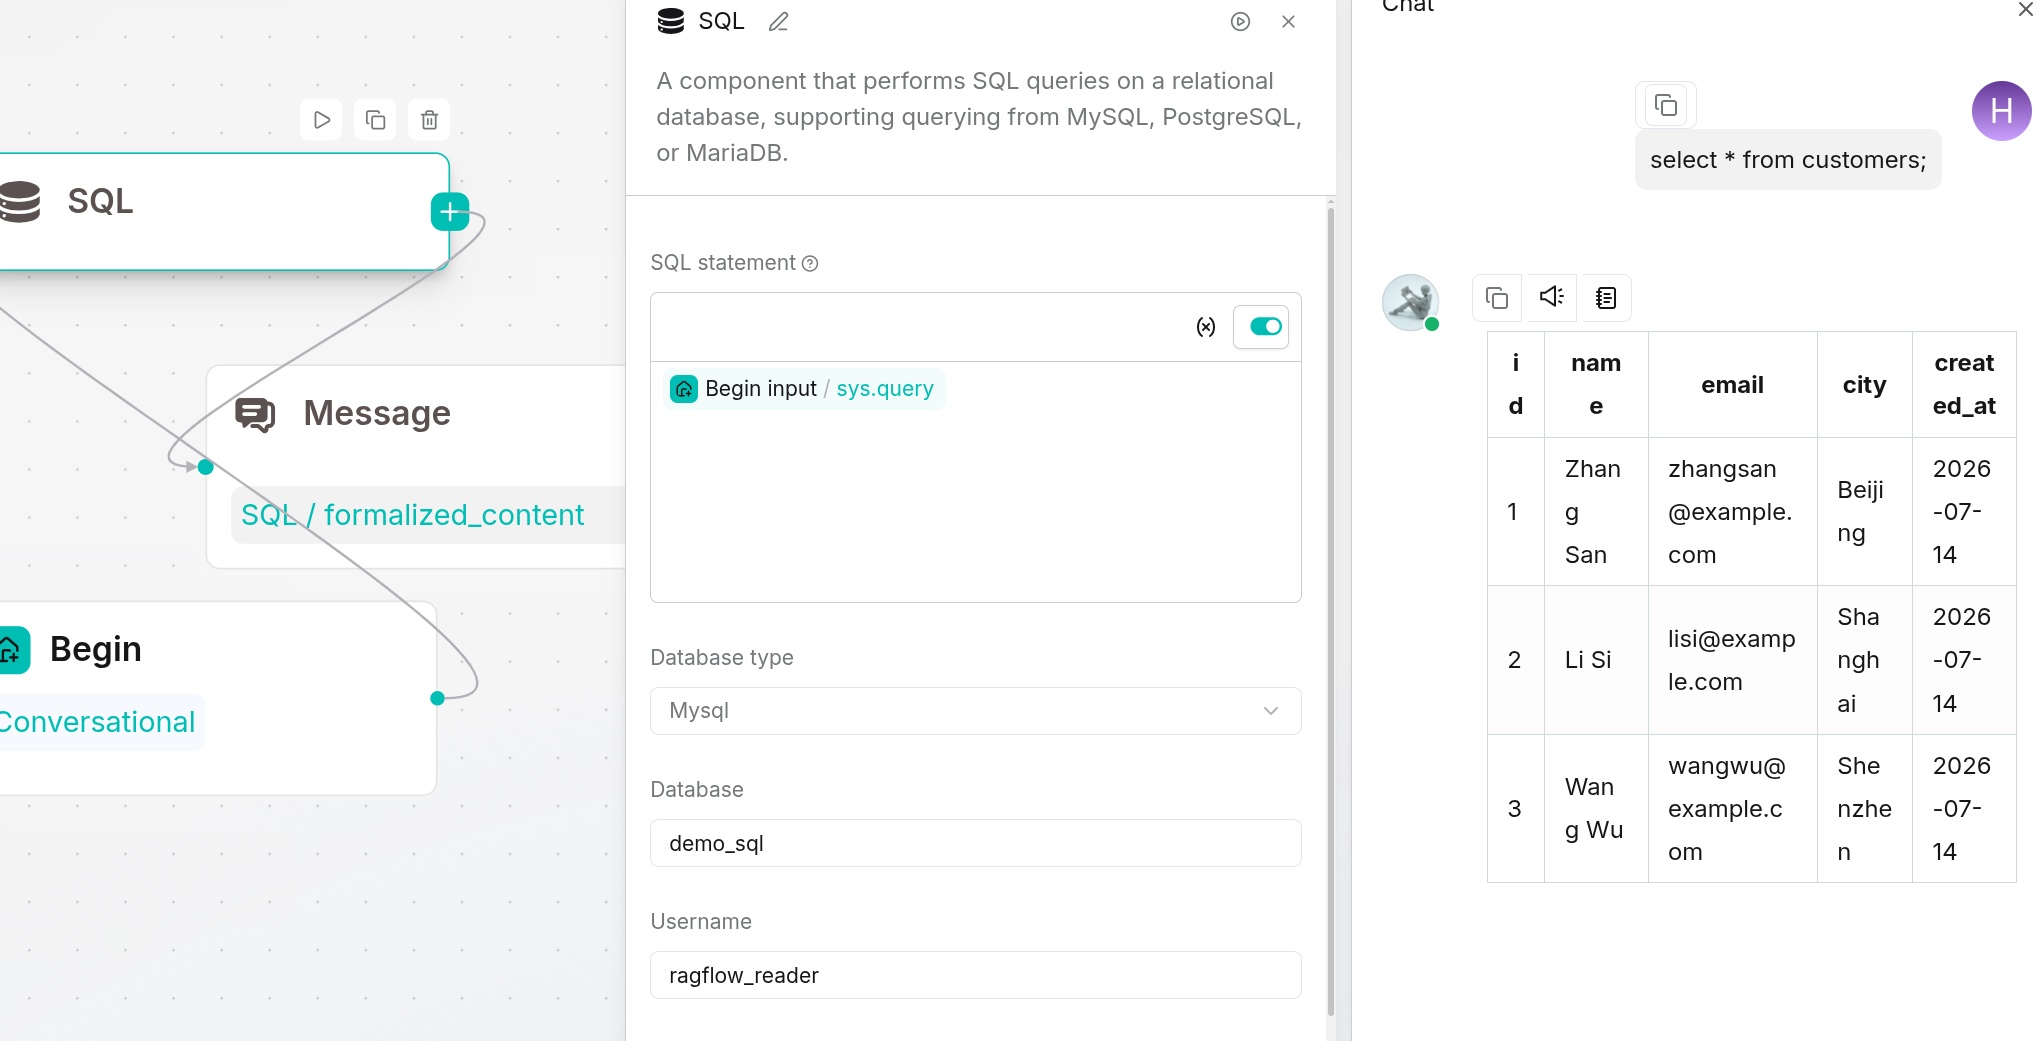-### Yahoo Finance (YahooFinance)+### Yahoo FinanceThe Yahoo Finance component queries stock quotes, company profiles, historical market data, financial statements, and news through `yfinance`, and outputs the selected content as a Markdown report.@@ -482,8 +481,7 @@ The Yahoo Finance component queries stock quotes, company profiles, historical mThe output contains a financial query report and structured market data, which can be used by subsequent Agents to generate market overviews or indicator explanations.-### WenCai (WenCai)-+### WenCaiWenCai is used to screen financial data such as stocks, indices, funds, Hong Kong stocks, U.S. stocks, futures, and other instruments based on natural-language conditions.#### Parameter Description@@ -576,7 +574,7 @@ The output contains sending status and error information. `success` being `true`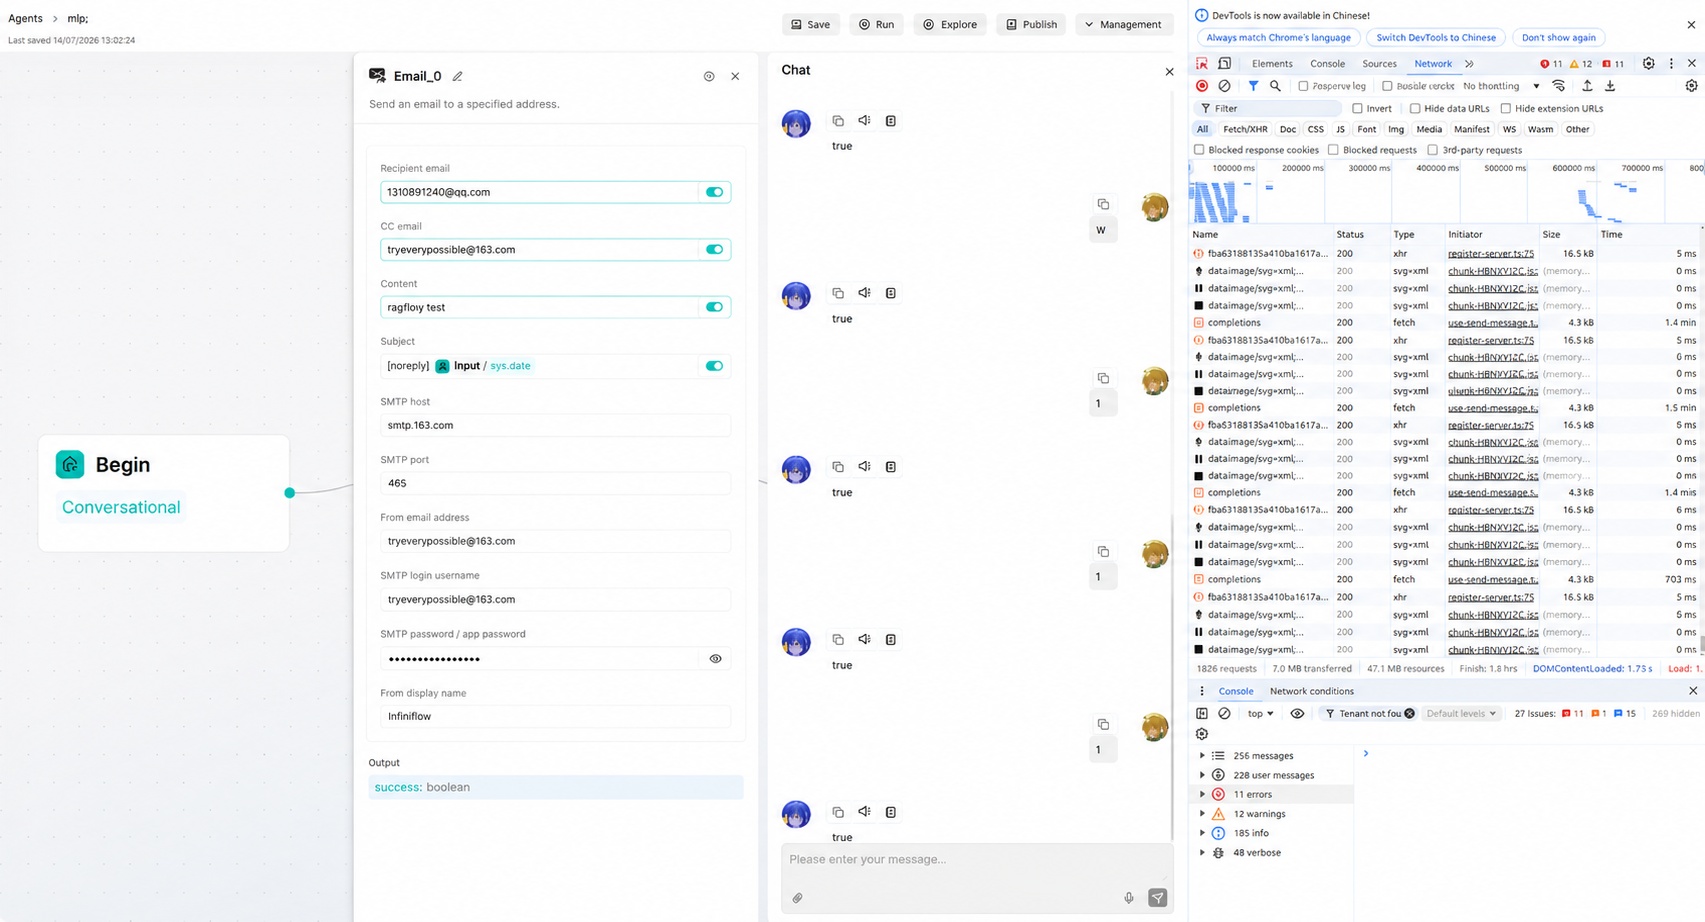-### HTTP Request (Invoke)+### HTTP RequestThe HTTP Request component calls external HTTP APIs, allowing business systems, third-party services, or self-built APIs to be connected to Agent workflows.@@ -584,16 +582,16 @@ The HTTP Request component calls external HTTP APIs, allowing business systems,| Field | Type | Required | Default Value | Description || --- | --- | --- | --- | --- |-| url | string | Yes | Empty | API address. Canvas variables can be used. The Python implementation can add `http://` to addresses with missing protocols, while the Go implementation requires `http://` or `https://` explicitly. |-| method | string | Yes | get | Python supports `get`, `post`, and `put`; the Go implementation also supports `DELETE`. |+| url | string | Yes | Empty | API address. Canvas variables can be used. |+| method | string | Yes | get | Supports `get`, `post`, and `put`. || headers | string/object | No | Empty | Request headers in JSON object format. Variables can be used in values. || variables | array[object] | No | `[]` | Request parameter list. Each item usually contains `key`, `value`, and `ref`. |-| timeout | integer | No | 60 | Request timeout in seconds. The Go default is 30 seconds. |+| timeout | integer | No | 60 | Request timeout in seconds. || proxy | string | No | Empty | Optional HTTP/HTTPS proxy address. || clean_html | boolean | No | false | Whether to clean HTML tags from the response. || datatype | string | No | json | Python request body type: `json` or `formdata`. || body | string | No | Empty | Raw request body supported by the Go runtime. |-| content_type | string | No | Empty | Go runtime `Content-Type`; POST/PUT default to `application/json`. |+| content_type | string | No | Empty | POST/PUT default to `application/json`. |#### Supported Valuesdiff --git a/docs/guides/agent/creation_and_management.md b/docs/guides/agent/creation_and_management.mdindex 3cb6b9d305..3ca019697f 100644--- a/docs/guides/agent/creation_and_management.md+++ b/docs/guides/agent/creation_and_management.md@@ -13,25 +13,28 @@ sidebar_custom_props: {## Access Agent PageAfter logging into RAGFlow, click **Agent** in the top navigation bar to enter the Agent page. Created Agents are displayed as cards. Click an existing card to continue editing; click the creation entry to create a new Agent.++## Create from TemplateRAGFlow provides Agent templates for different business scenarios. When creating from a template, the system presets common components and connections. Users only need to modify models, knowledge bases, prompts, interface addresses or output content.+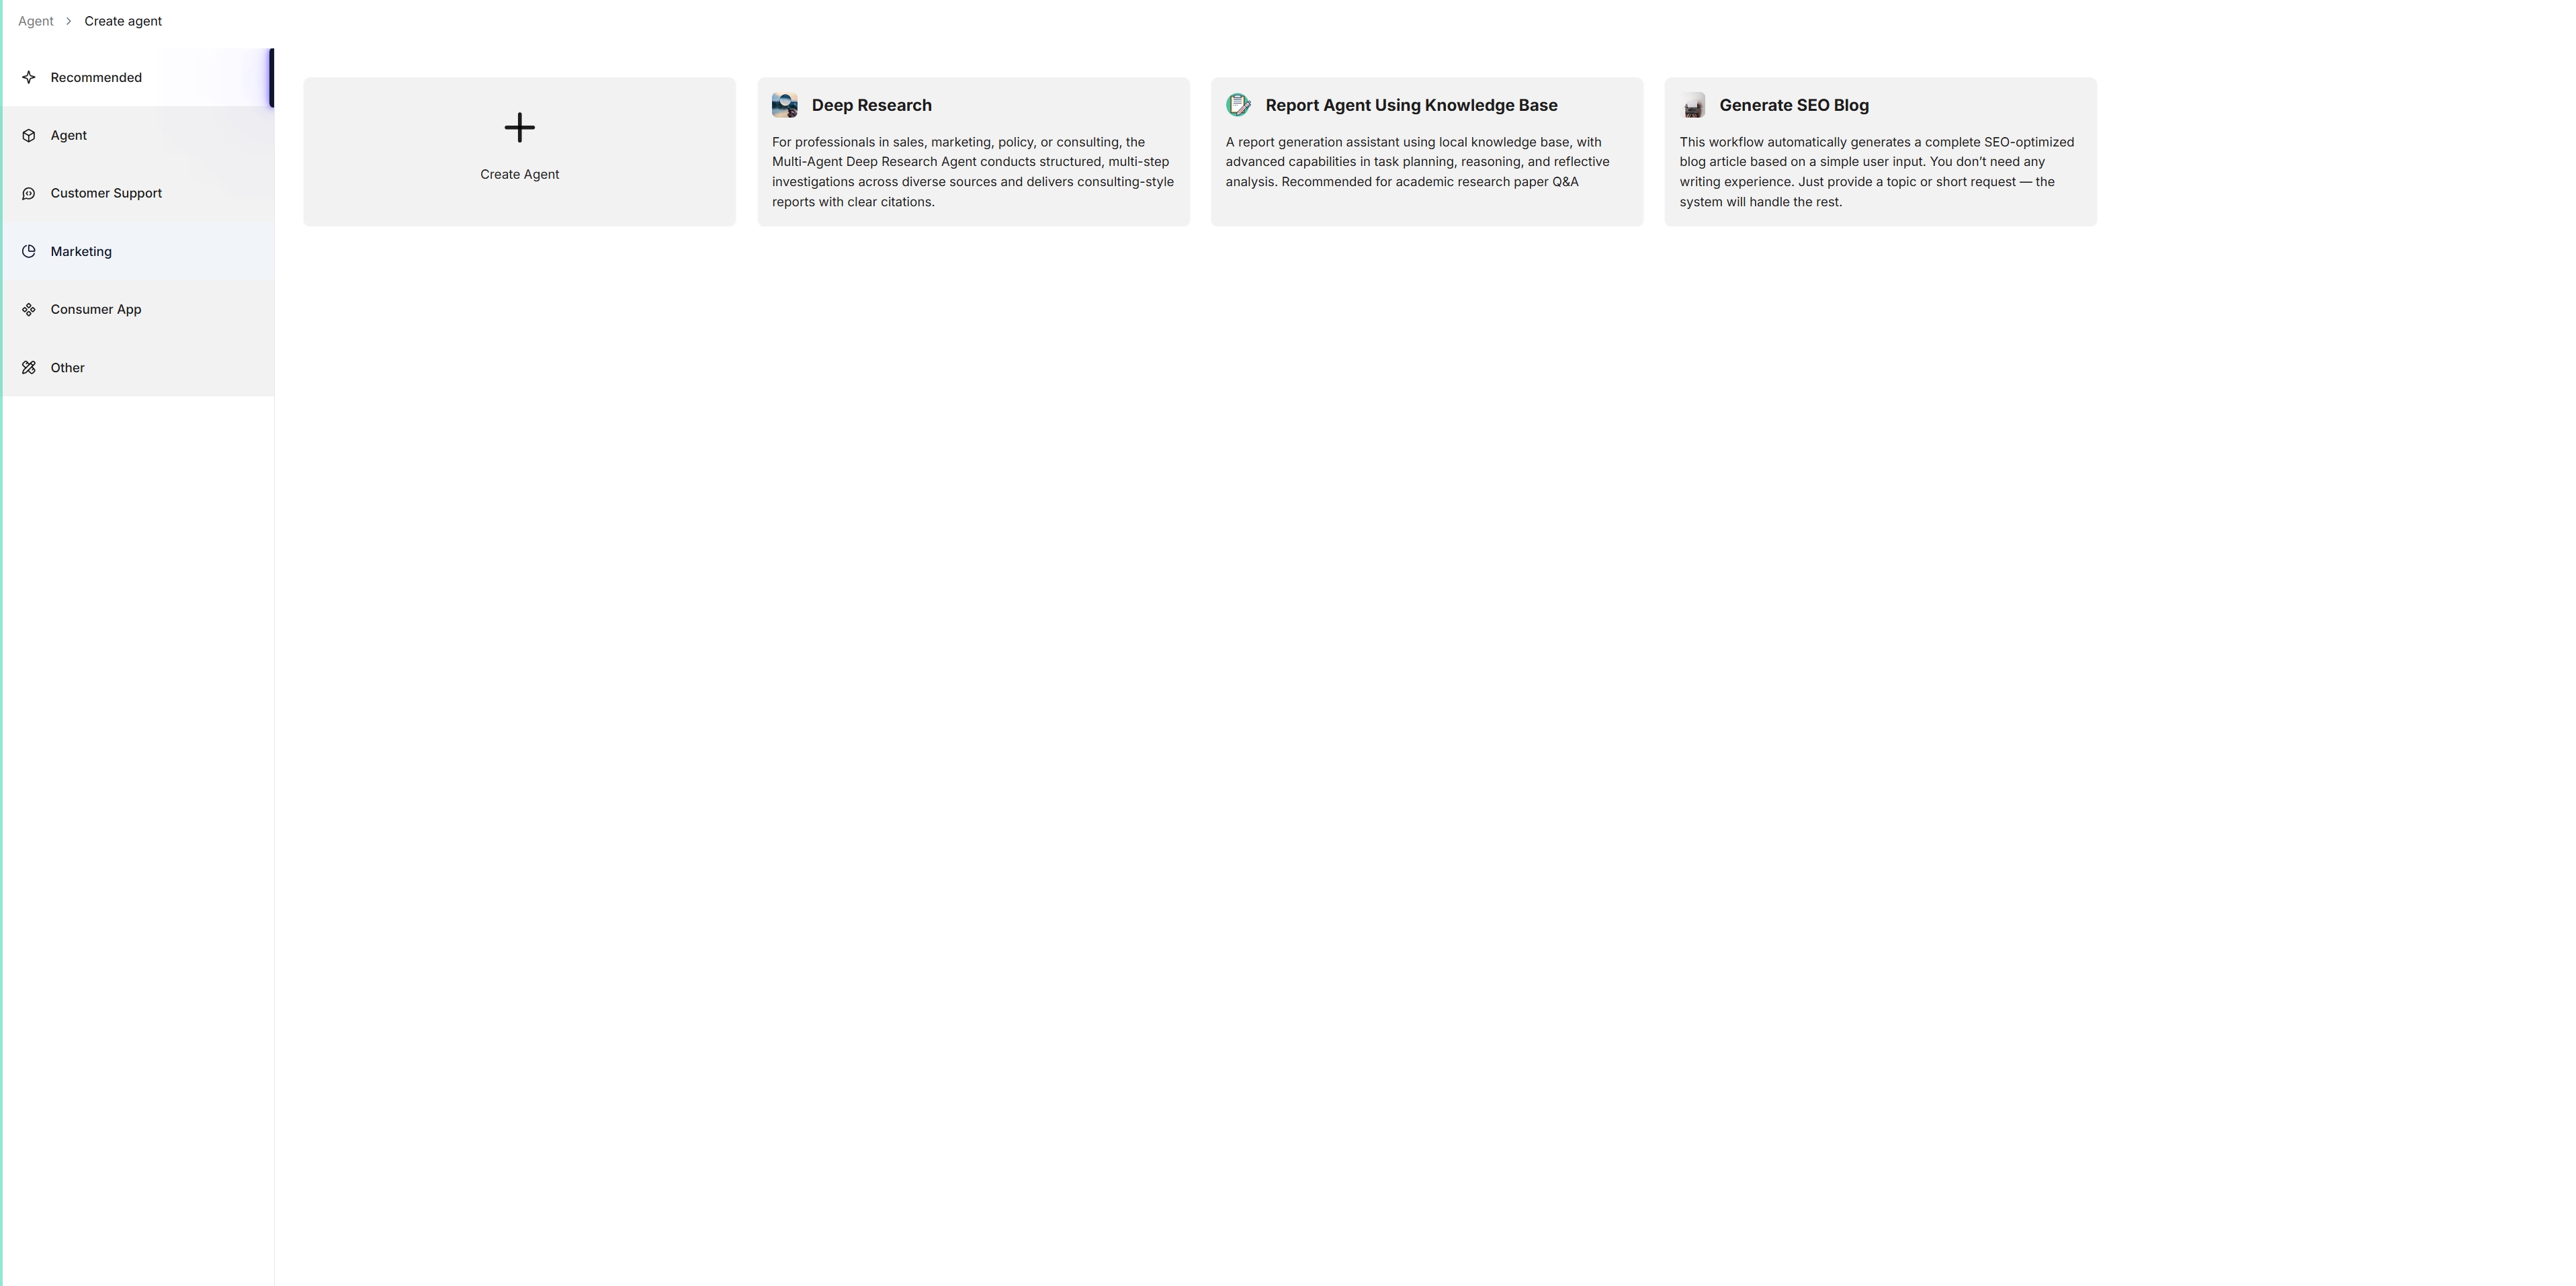+Steps:1. Enter the Agent page.2. Click **Create agent**.++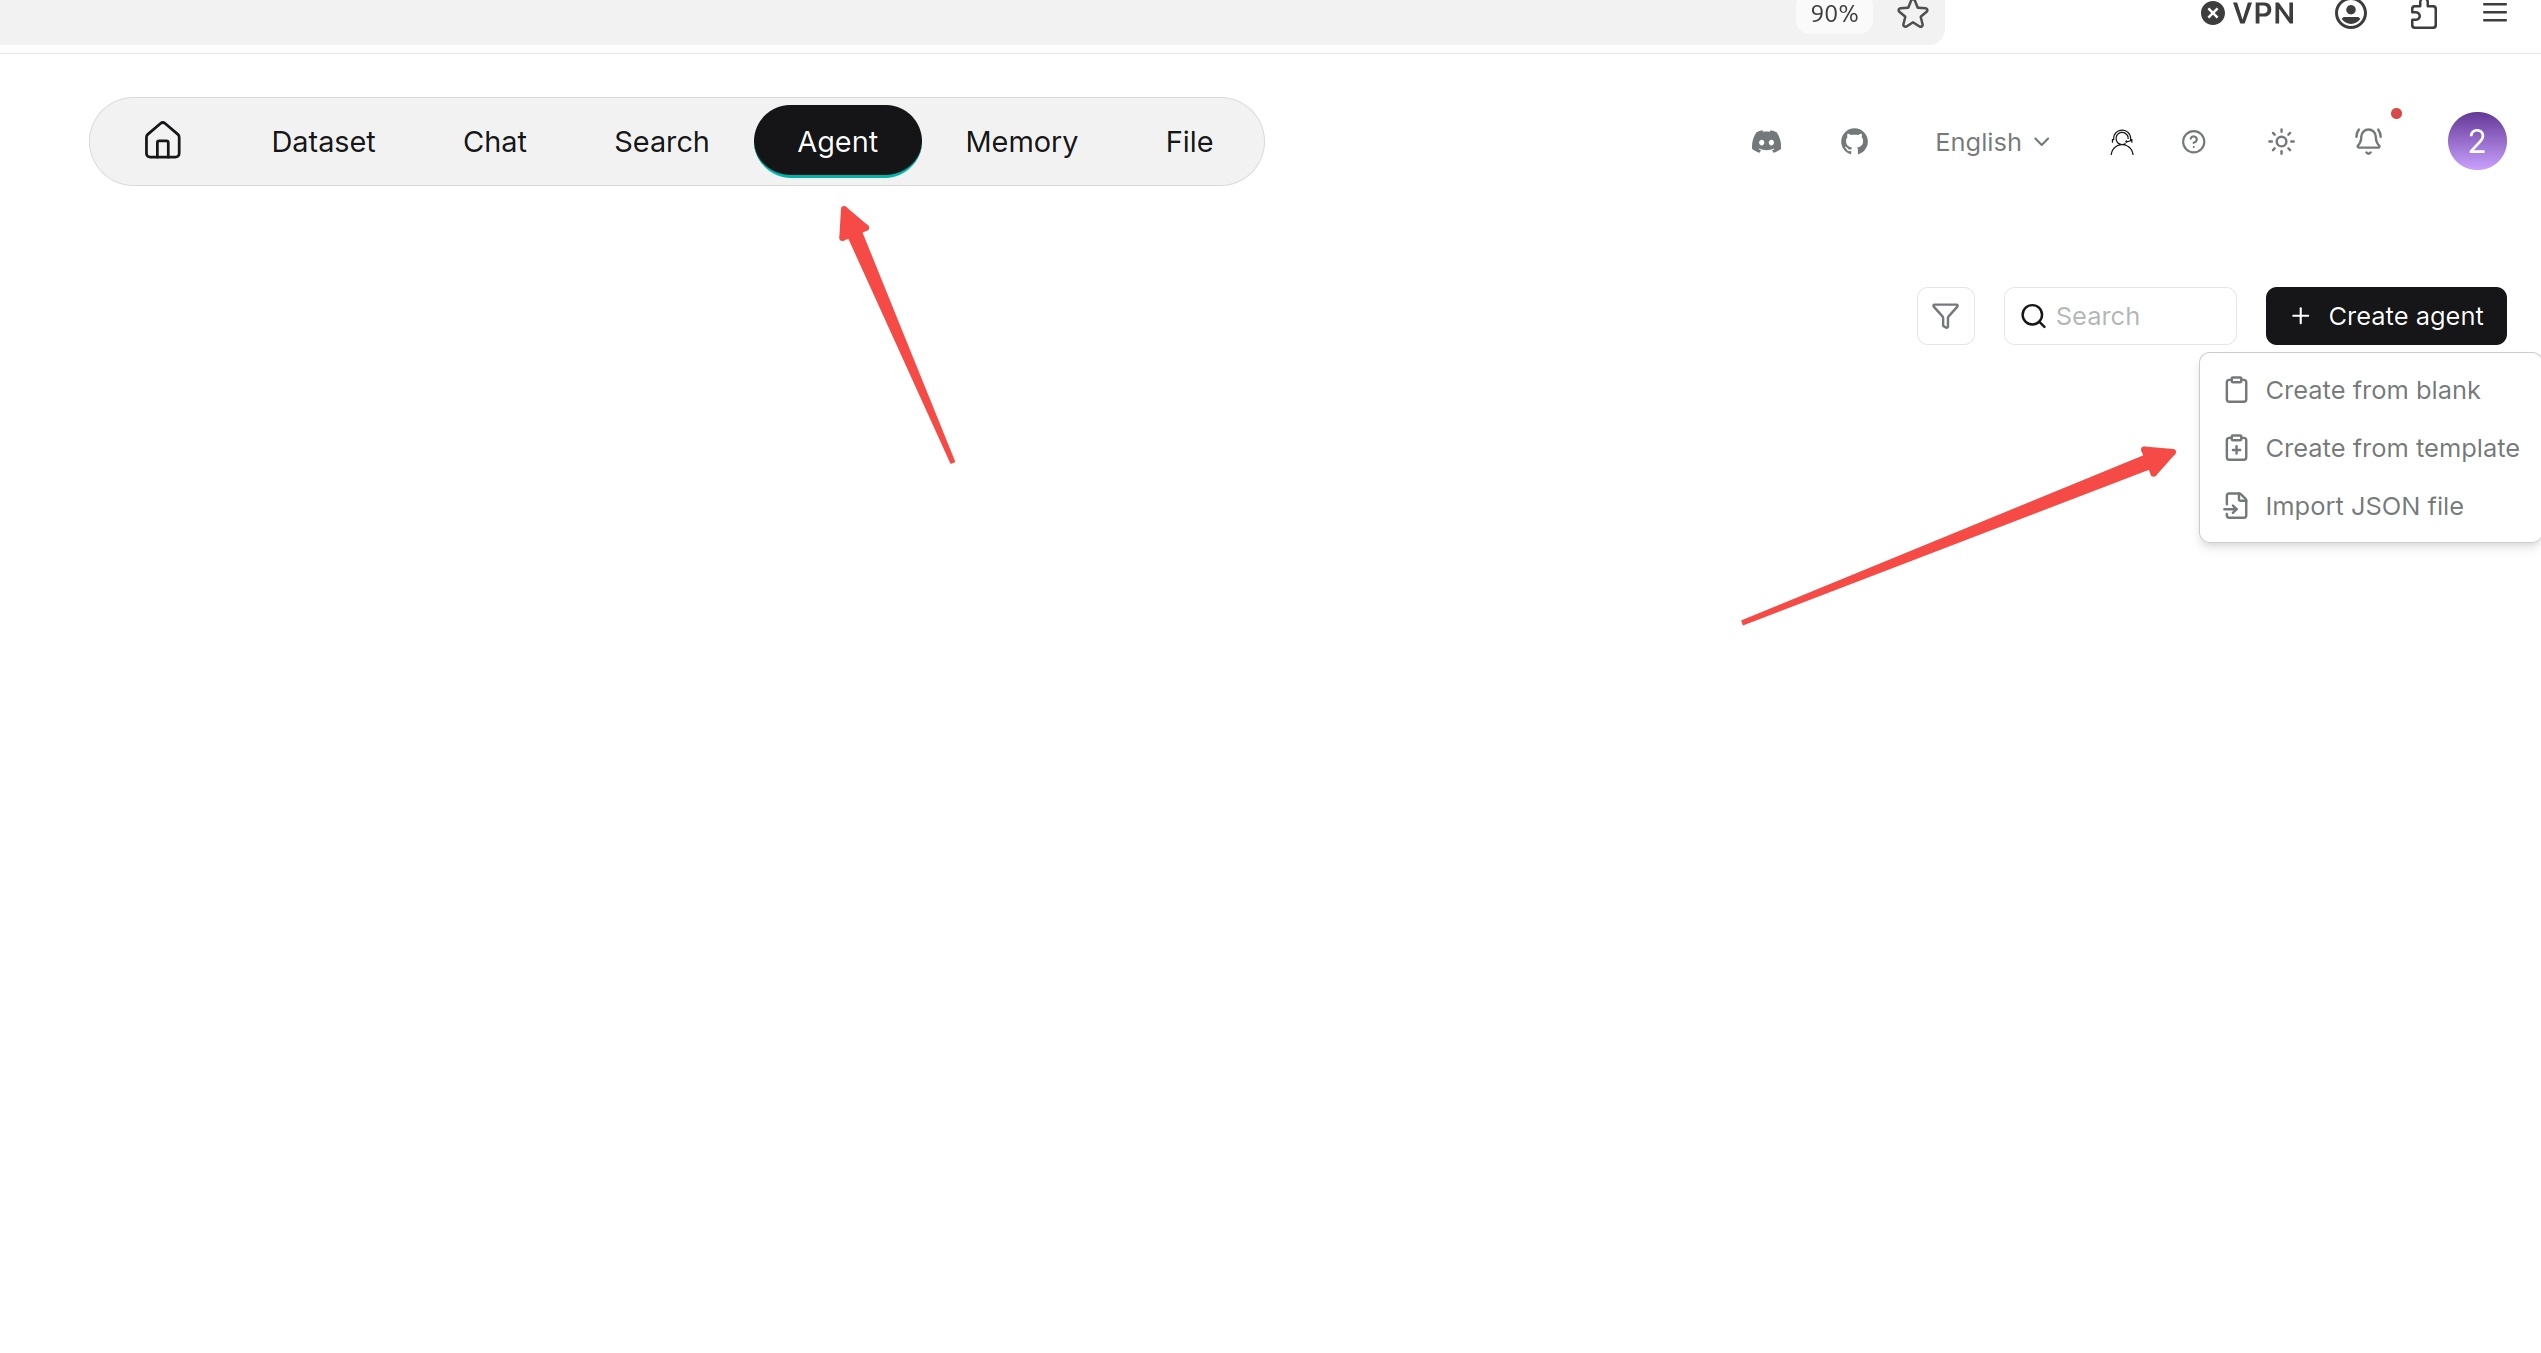3. Select an appropriate template on the template page, such as Deep Research, Knowledge Base Q&A, Data Analysis or E-commerce Customer Service template.++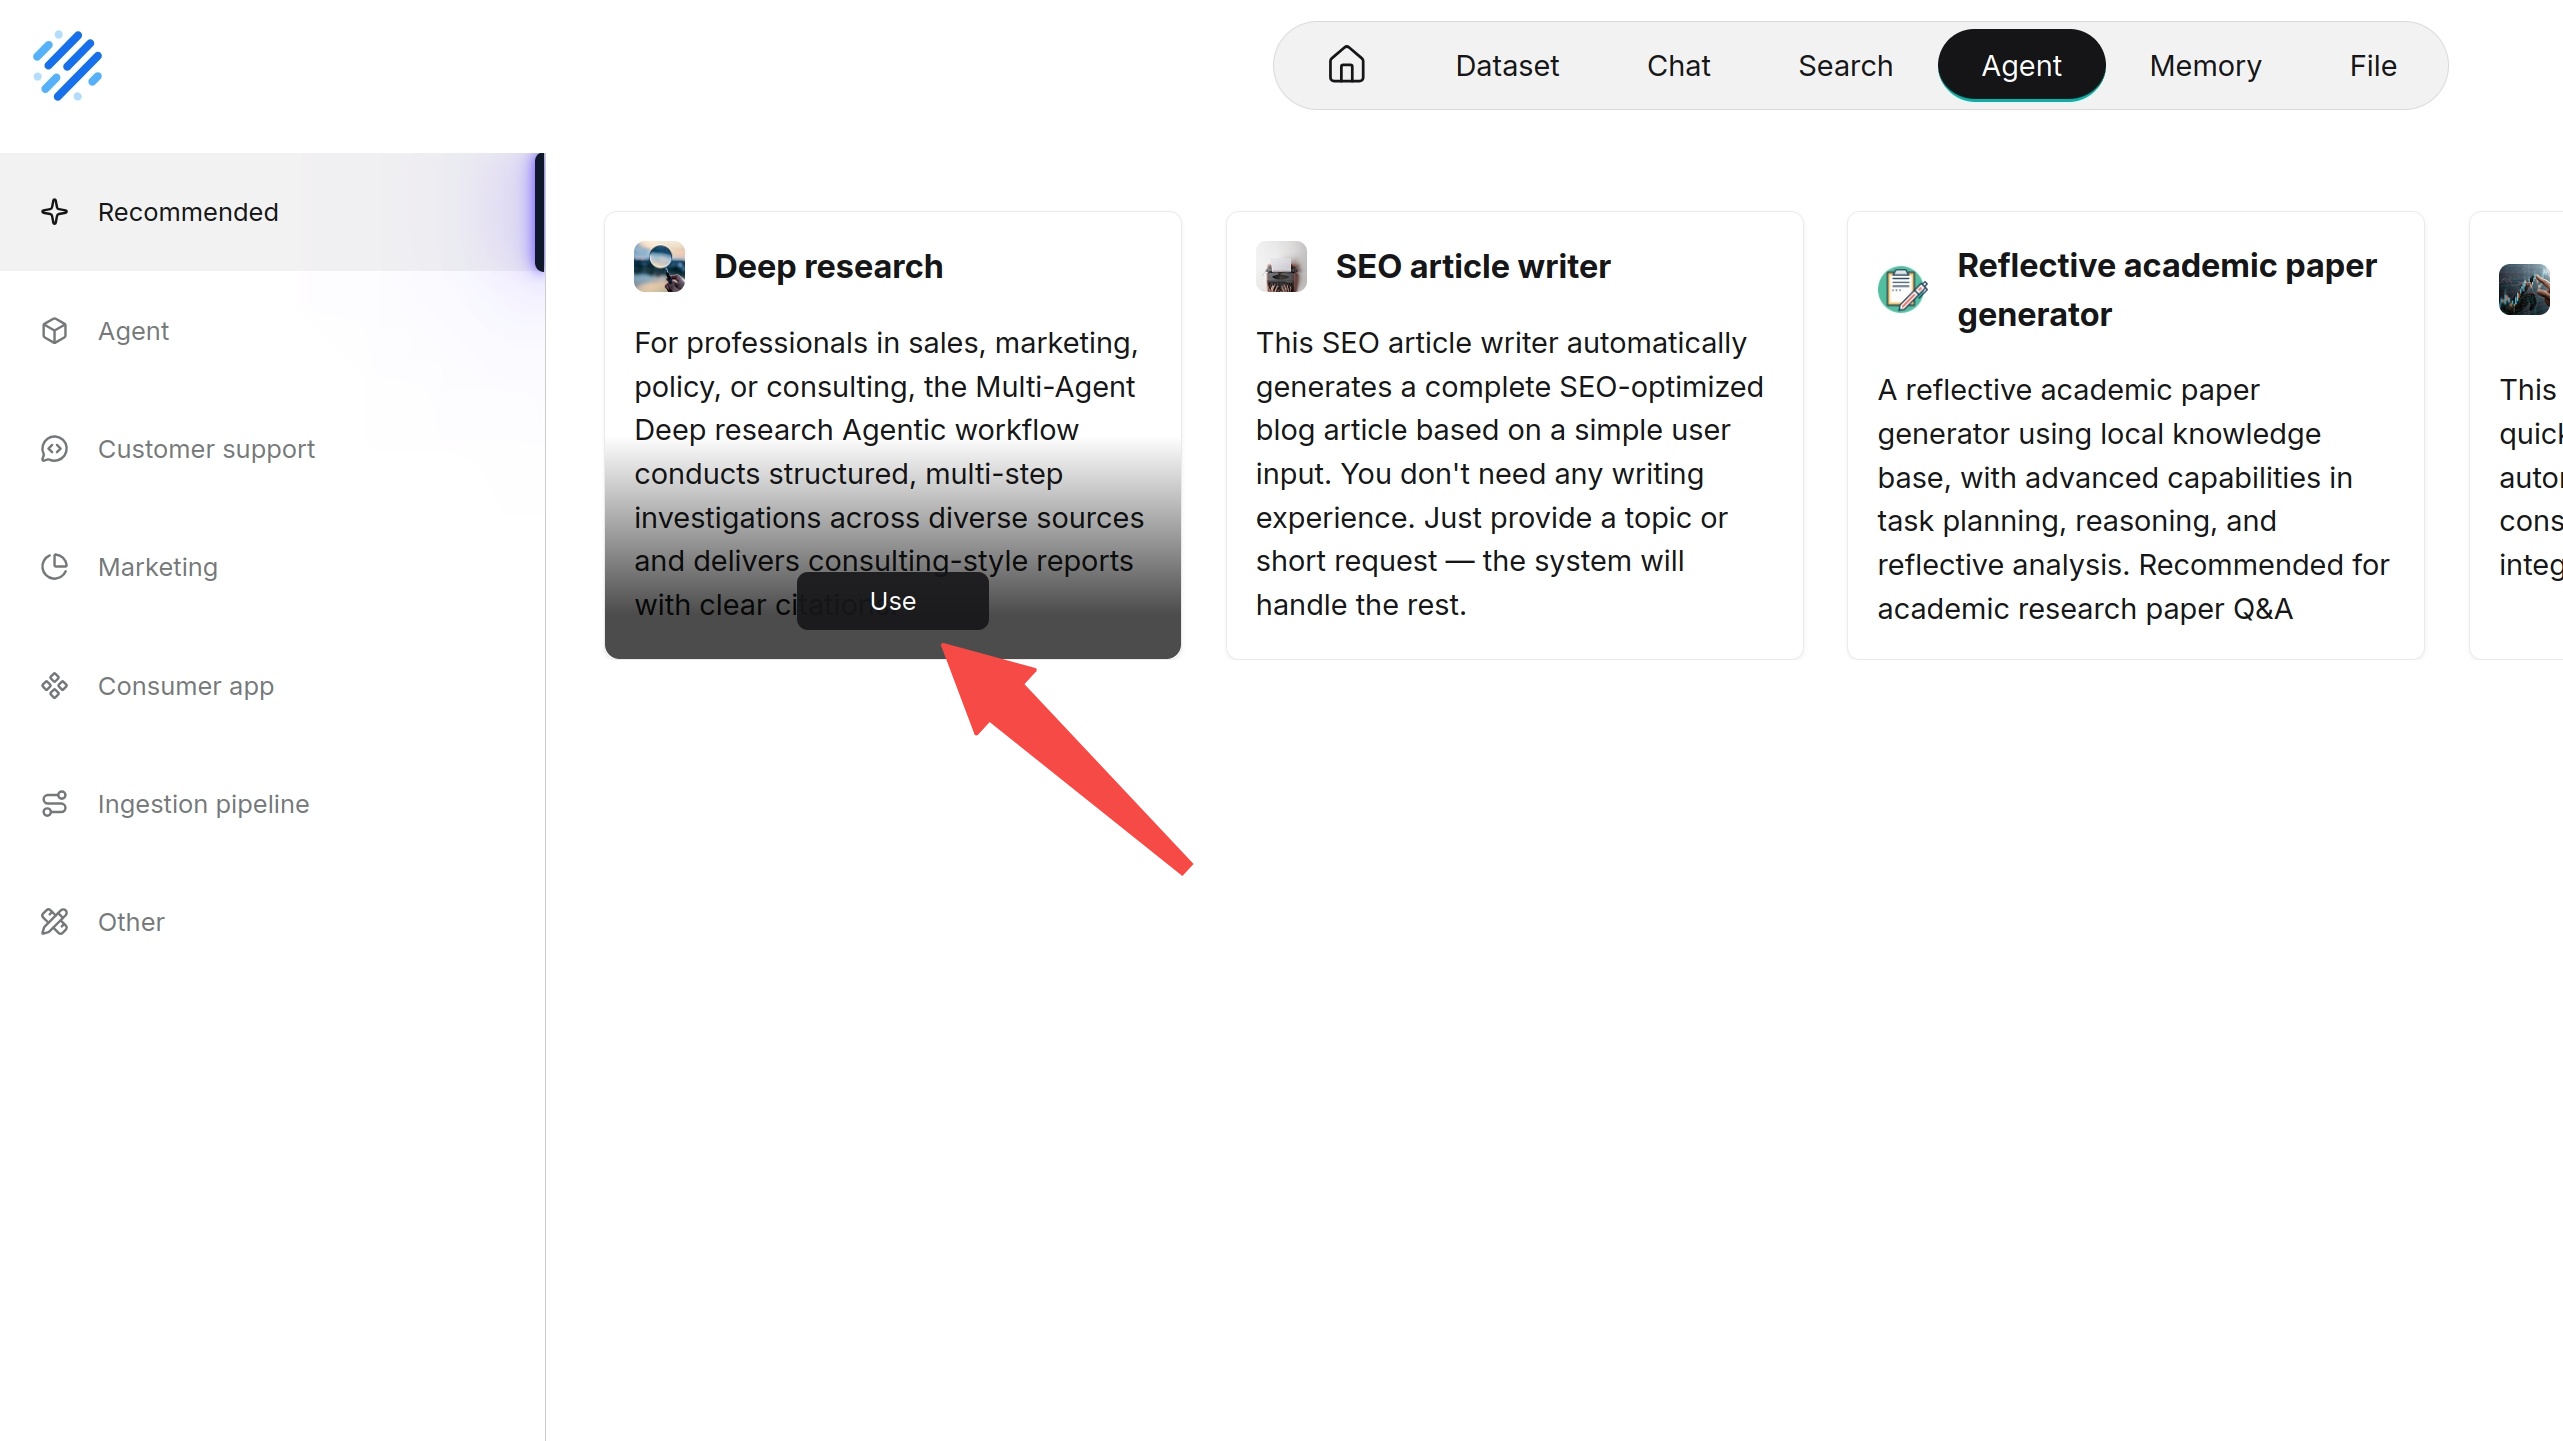4. Enter the Agent name.5. Click **OK**.-6. After entering the canvas, check the configuration of each component and save.--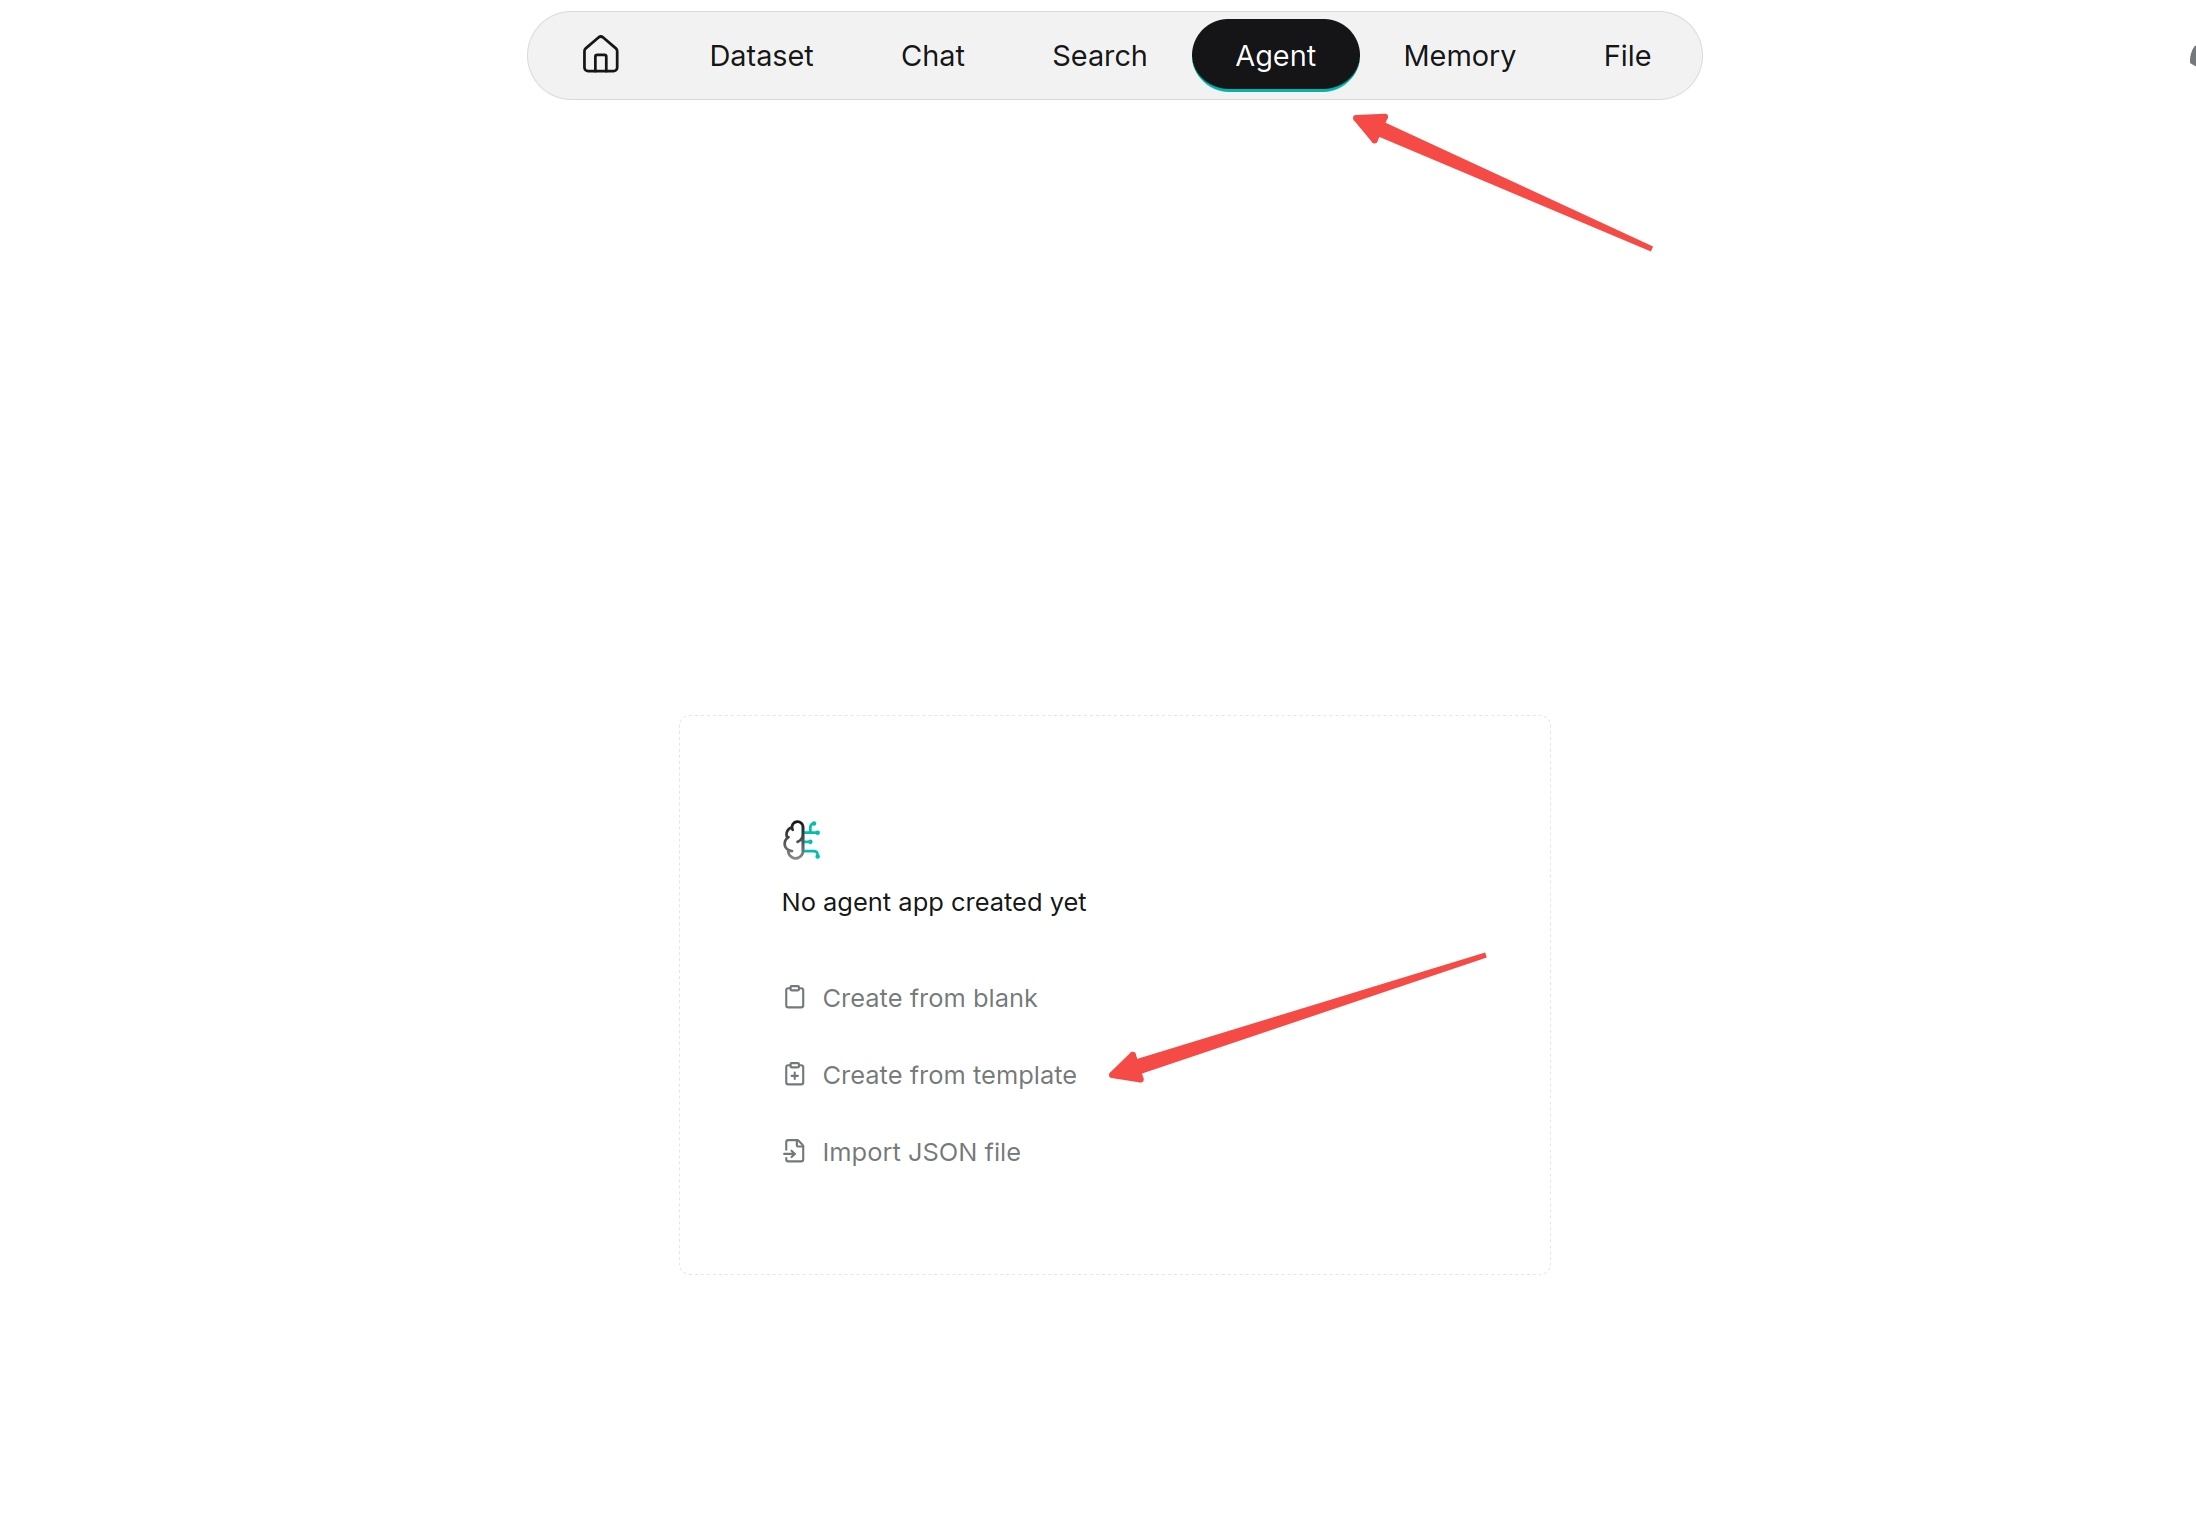-----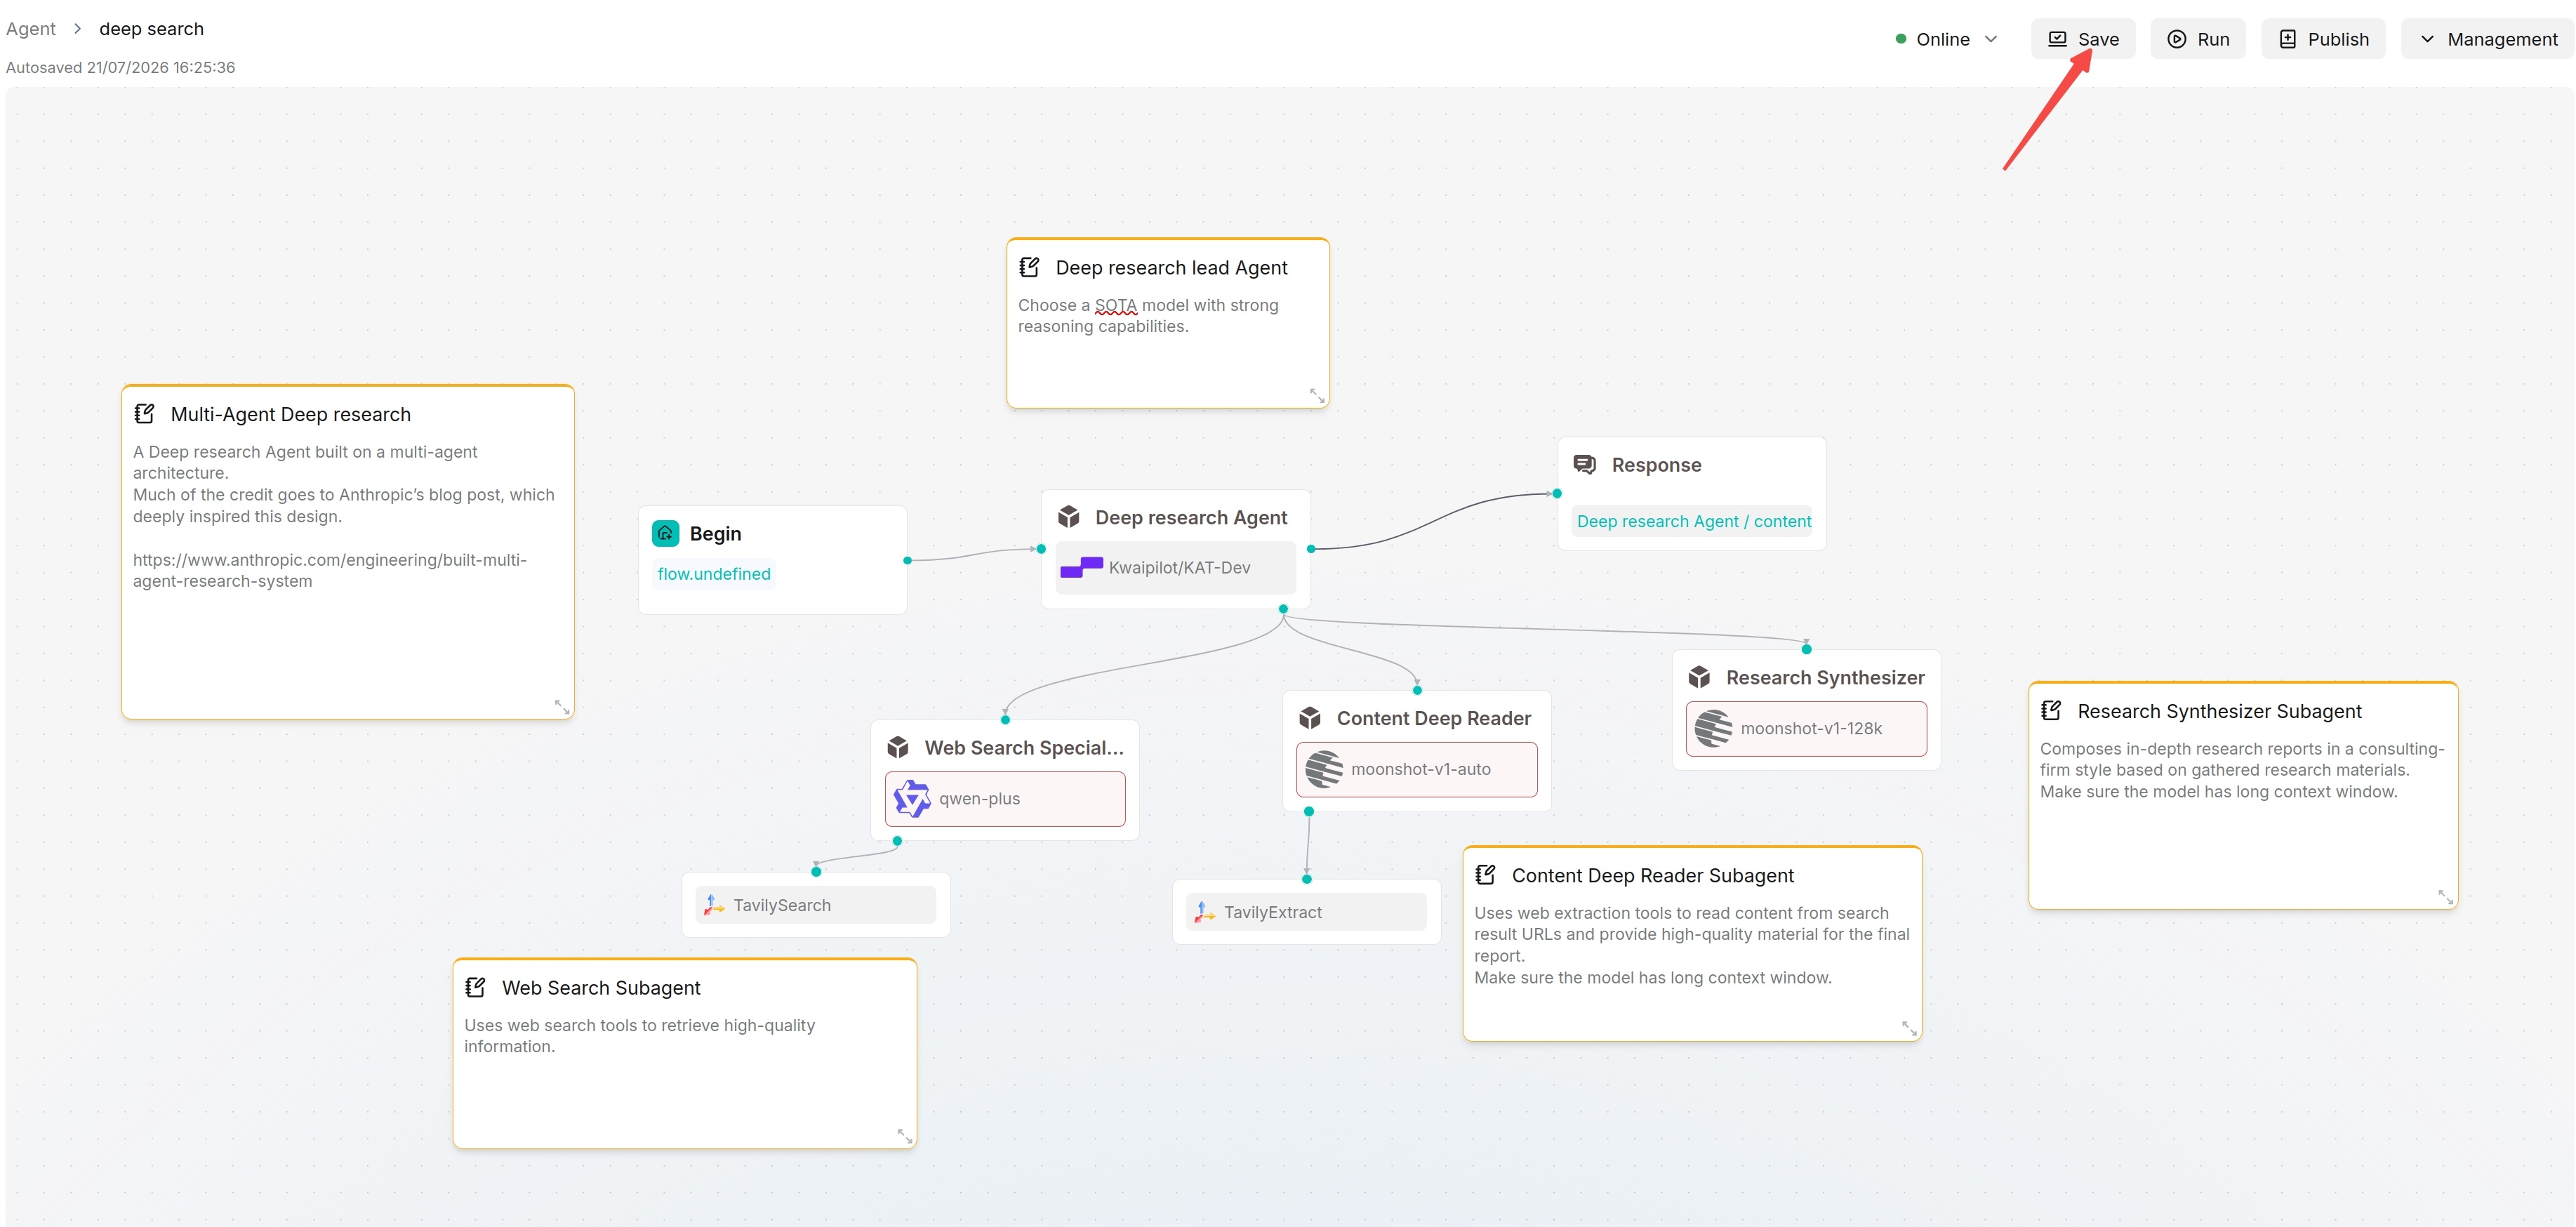++6. After entering the canvas, check the configuration of each component and save.+## Create from Blank AgentWhen creating a blank Agent, the canvas contains a default `Begin` component. Users can click the plus sign next to the Begin component or other components to add downstream components.@@ -39,22 +42,21 @@ Steps:1. Enter the Agent page.2. Click **Create agent**.3. Select blank creation.++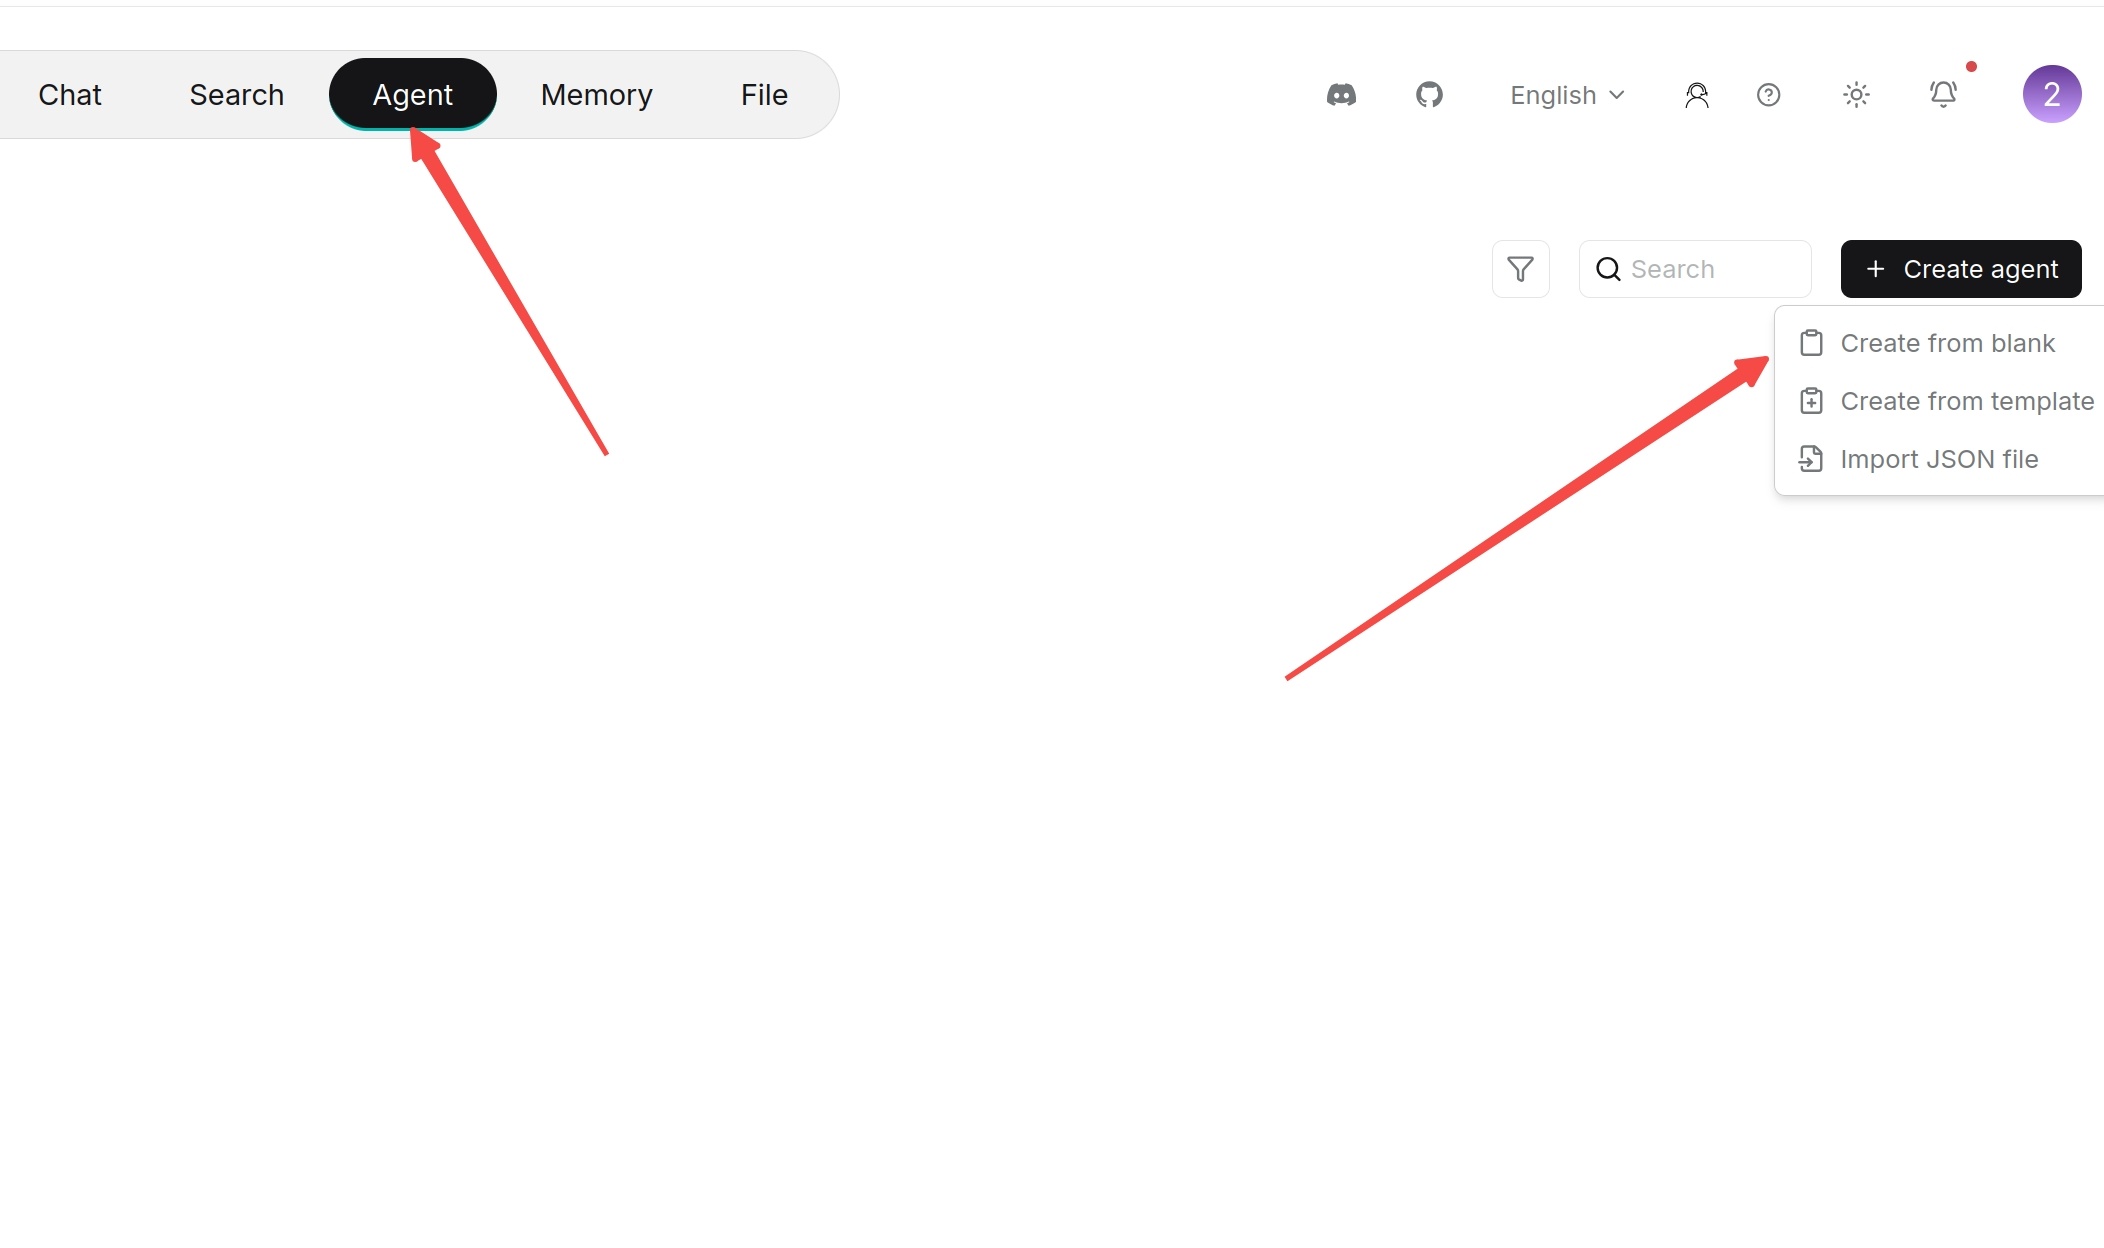4. Enter the Agent name and select the agent type.++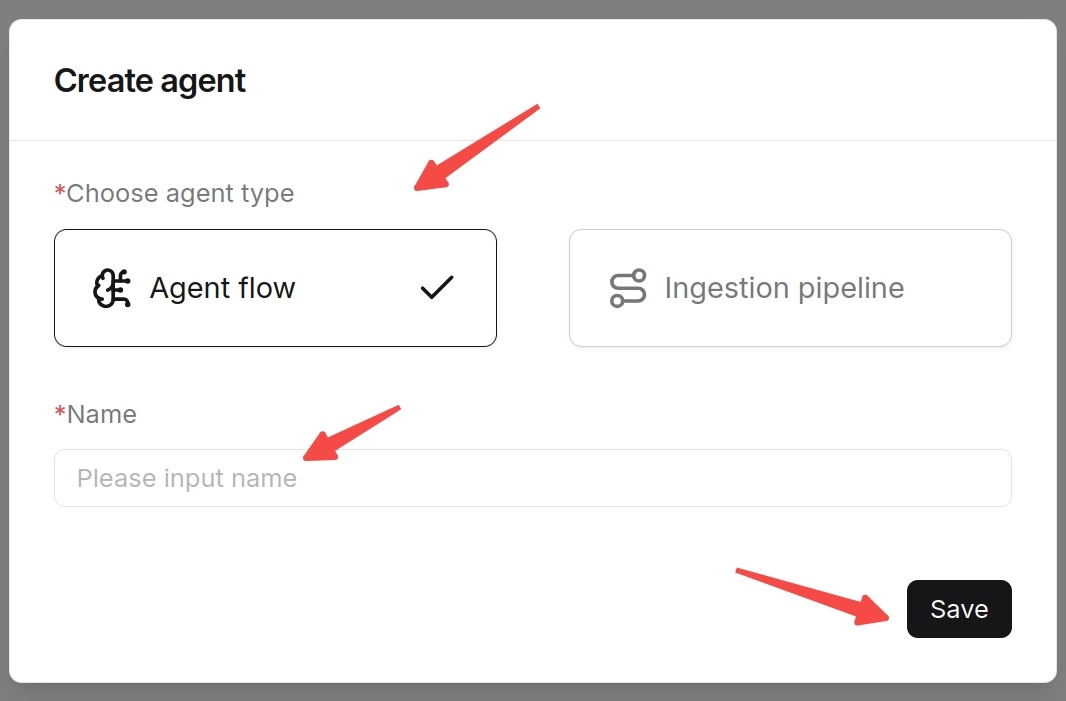5. Enter the canvas.6. Click the plus sign next to the `Begin` component, and add components according to business processes.++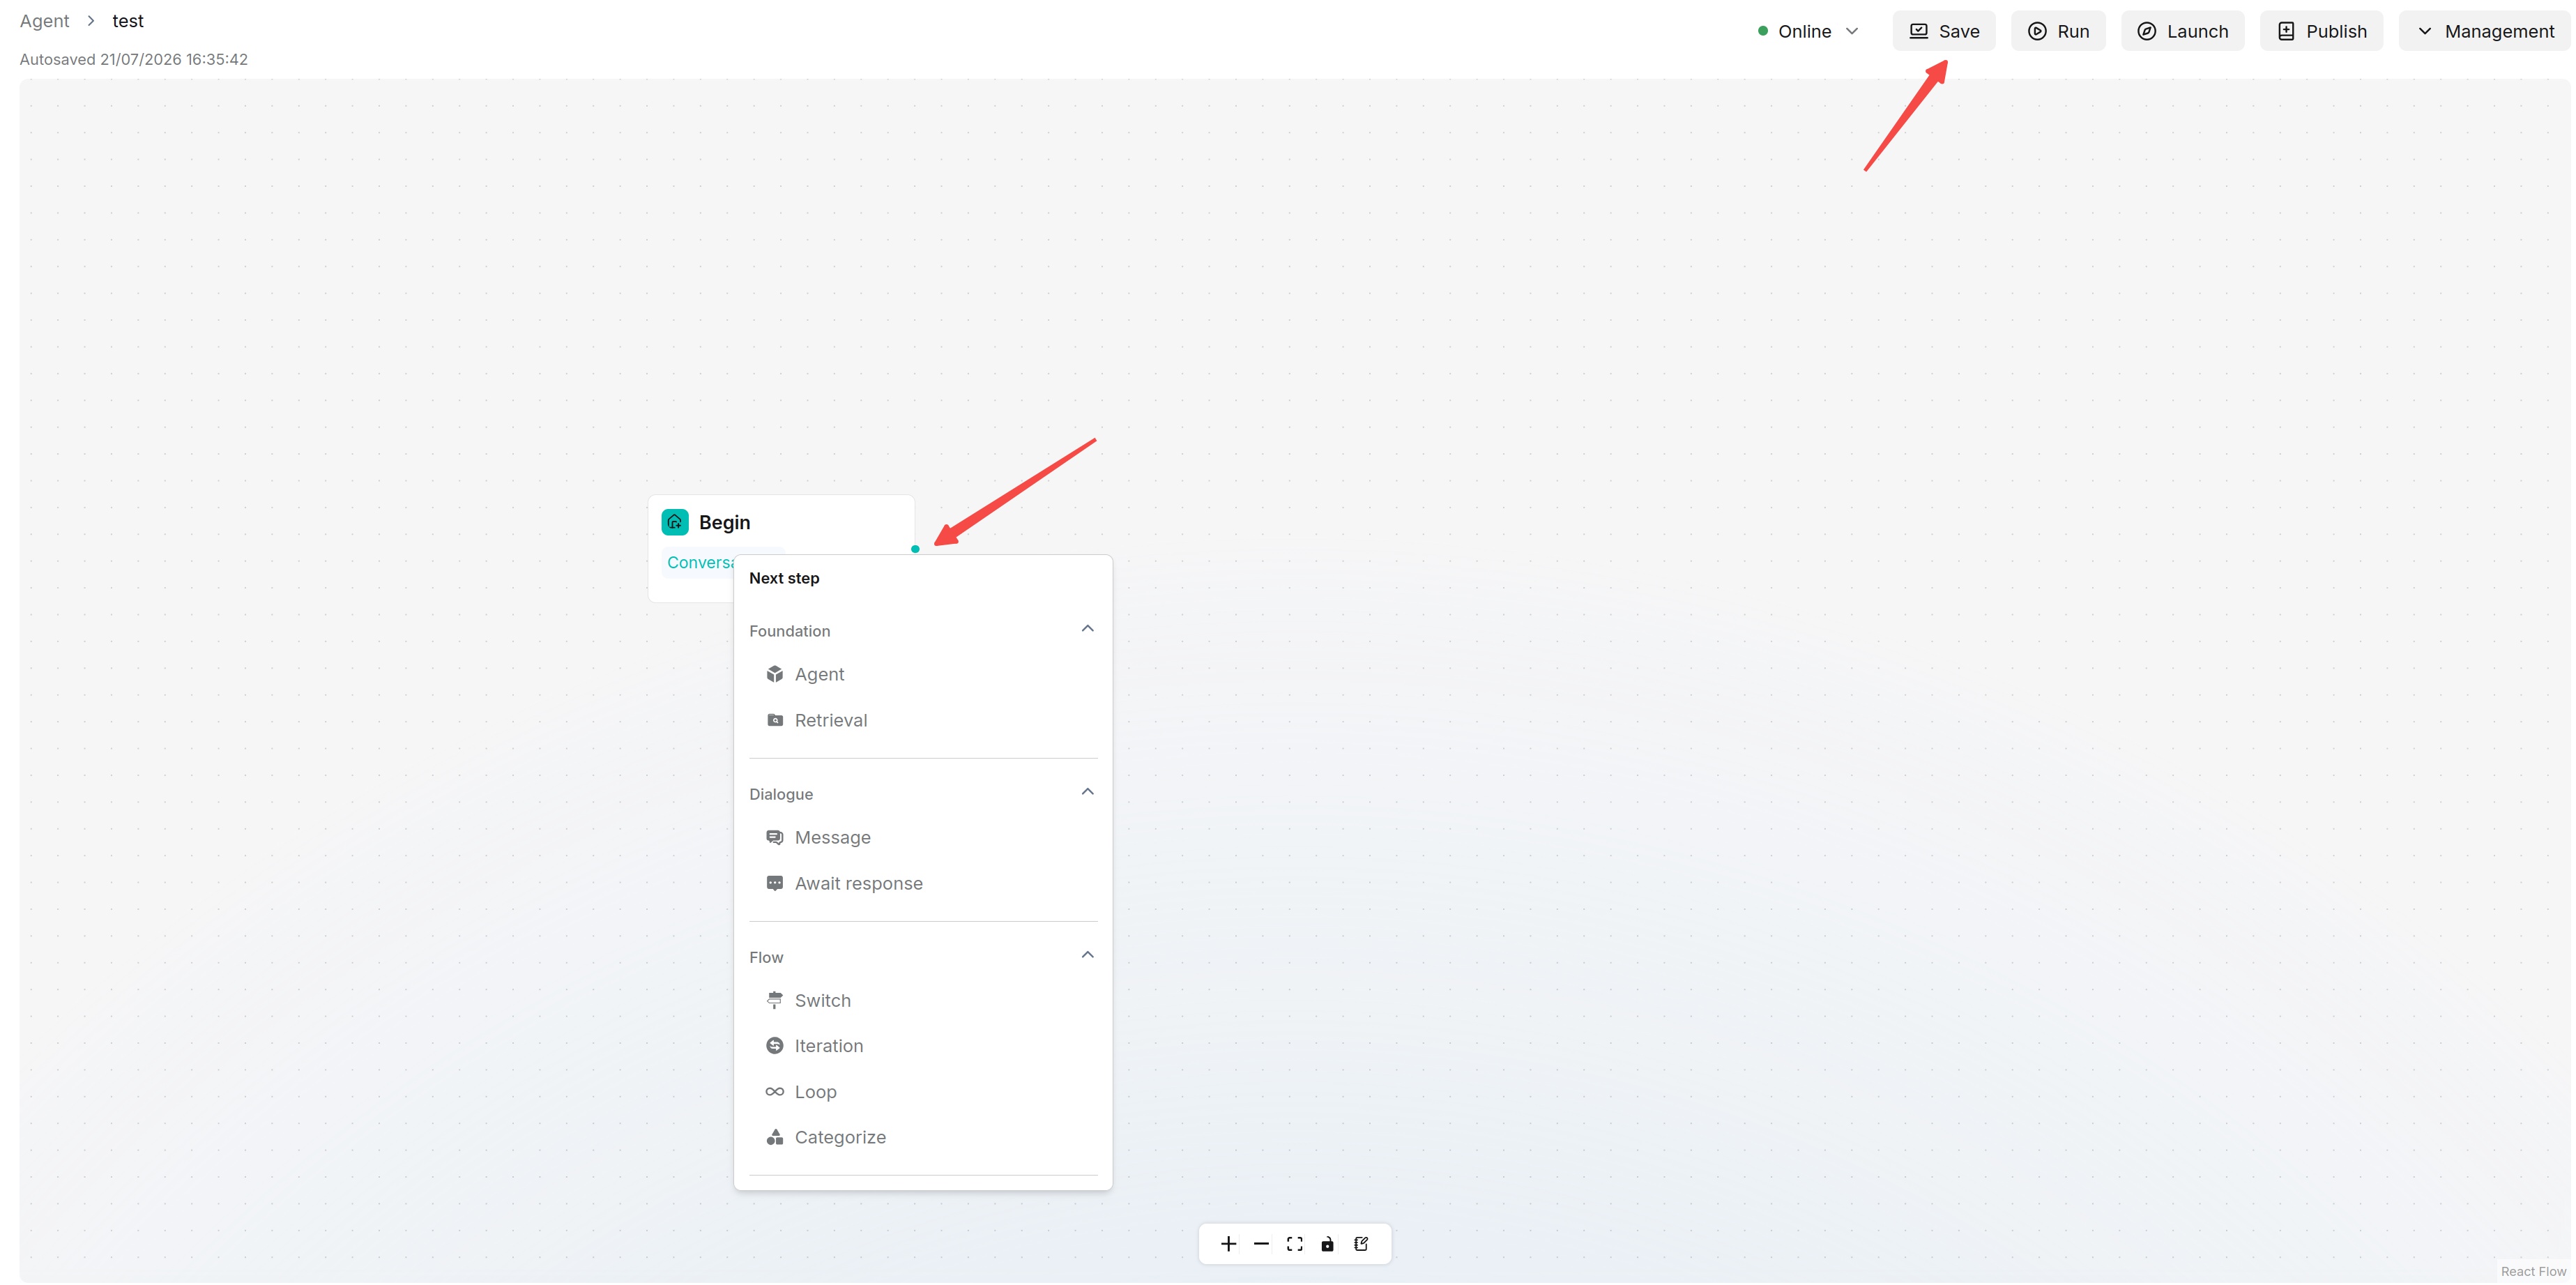7. Configure each component.8. Click **Save**.:::tip NOTEThe `Begin` component is the start of the workflow. Each Agent can only have one Begin component and it cannot be deleted. After creation, configure Begin first, then configure subsequent components.:::-------## Search, Copy and Delete AgentIn the Agent list, you can search for target Agents by name. If copy, delete or other operation entries are available on the interface, confirm the Agent name and permission scope before operation. Deletion is usually irreversible. Please confirm whether the Agent is referenced by embedded web pages, API calls or other workflows.diff --git a/docs/guides/agent/embed_into_web_pages.md b/docs/guides/agent/embed_into_web_pages.mdindex 6dce51ab60..57f97782ec 100644--- a/docs/guides/agent/embed_into_web_pages.md+++ b/docs/guides/agent/embed_into_web_pages.md@@ -18,6 +18,9 @@ Prerequisite: You must obtain an API Key.Steps:1. On the Agent page, click the target Agent to open its editing page.2. Click **Manage > Embed Webpage** in the upper right corner of the canvas to open the iframe window.++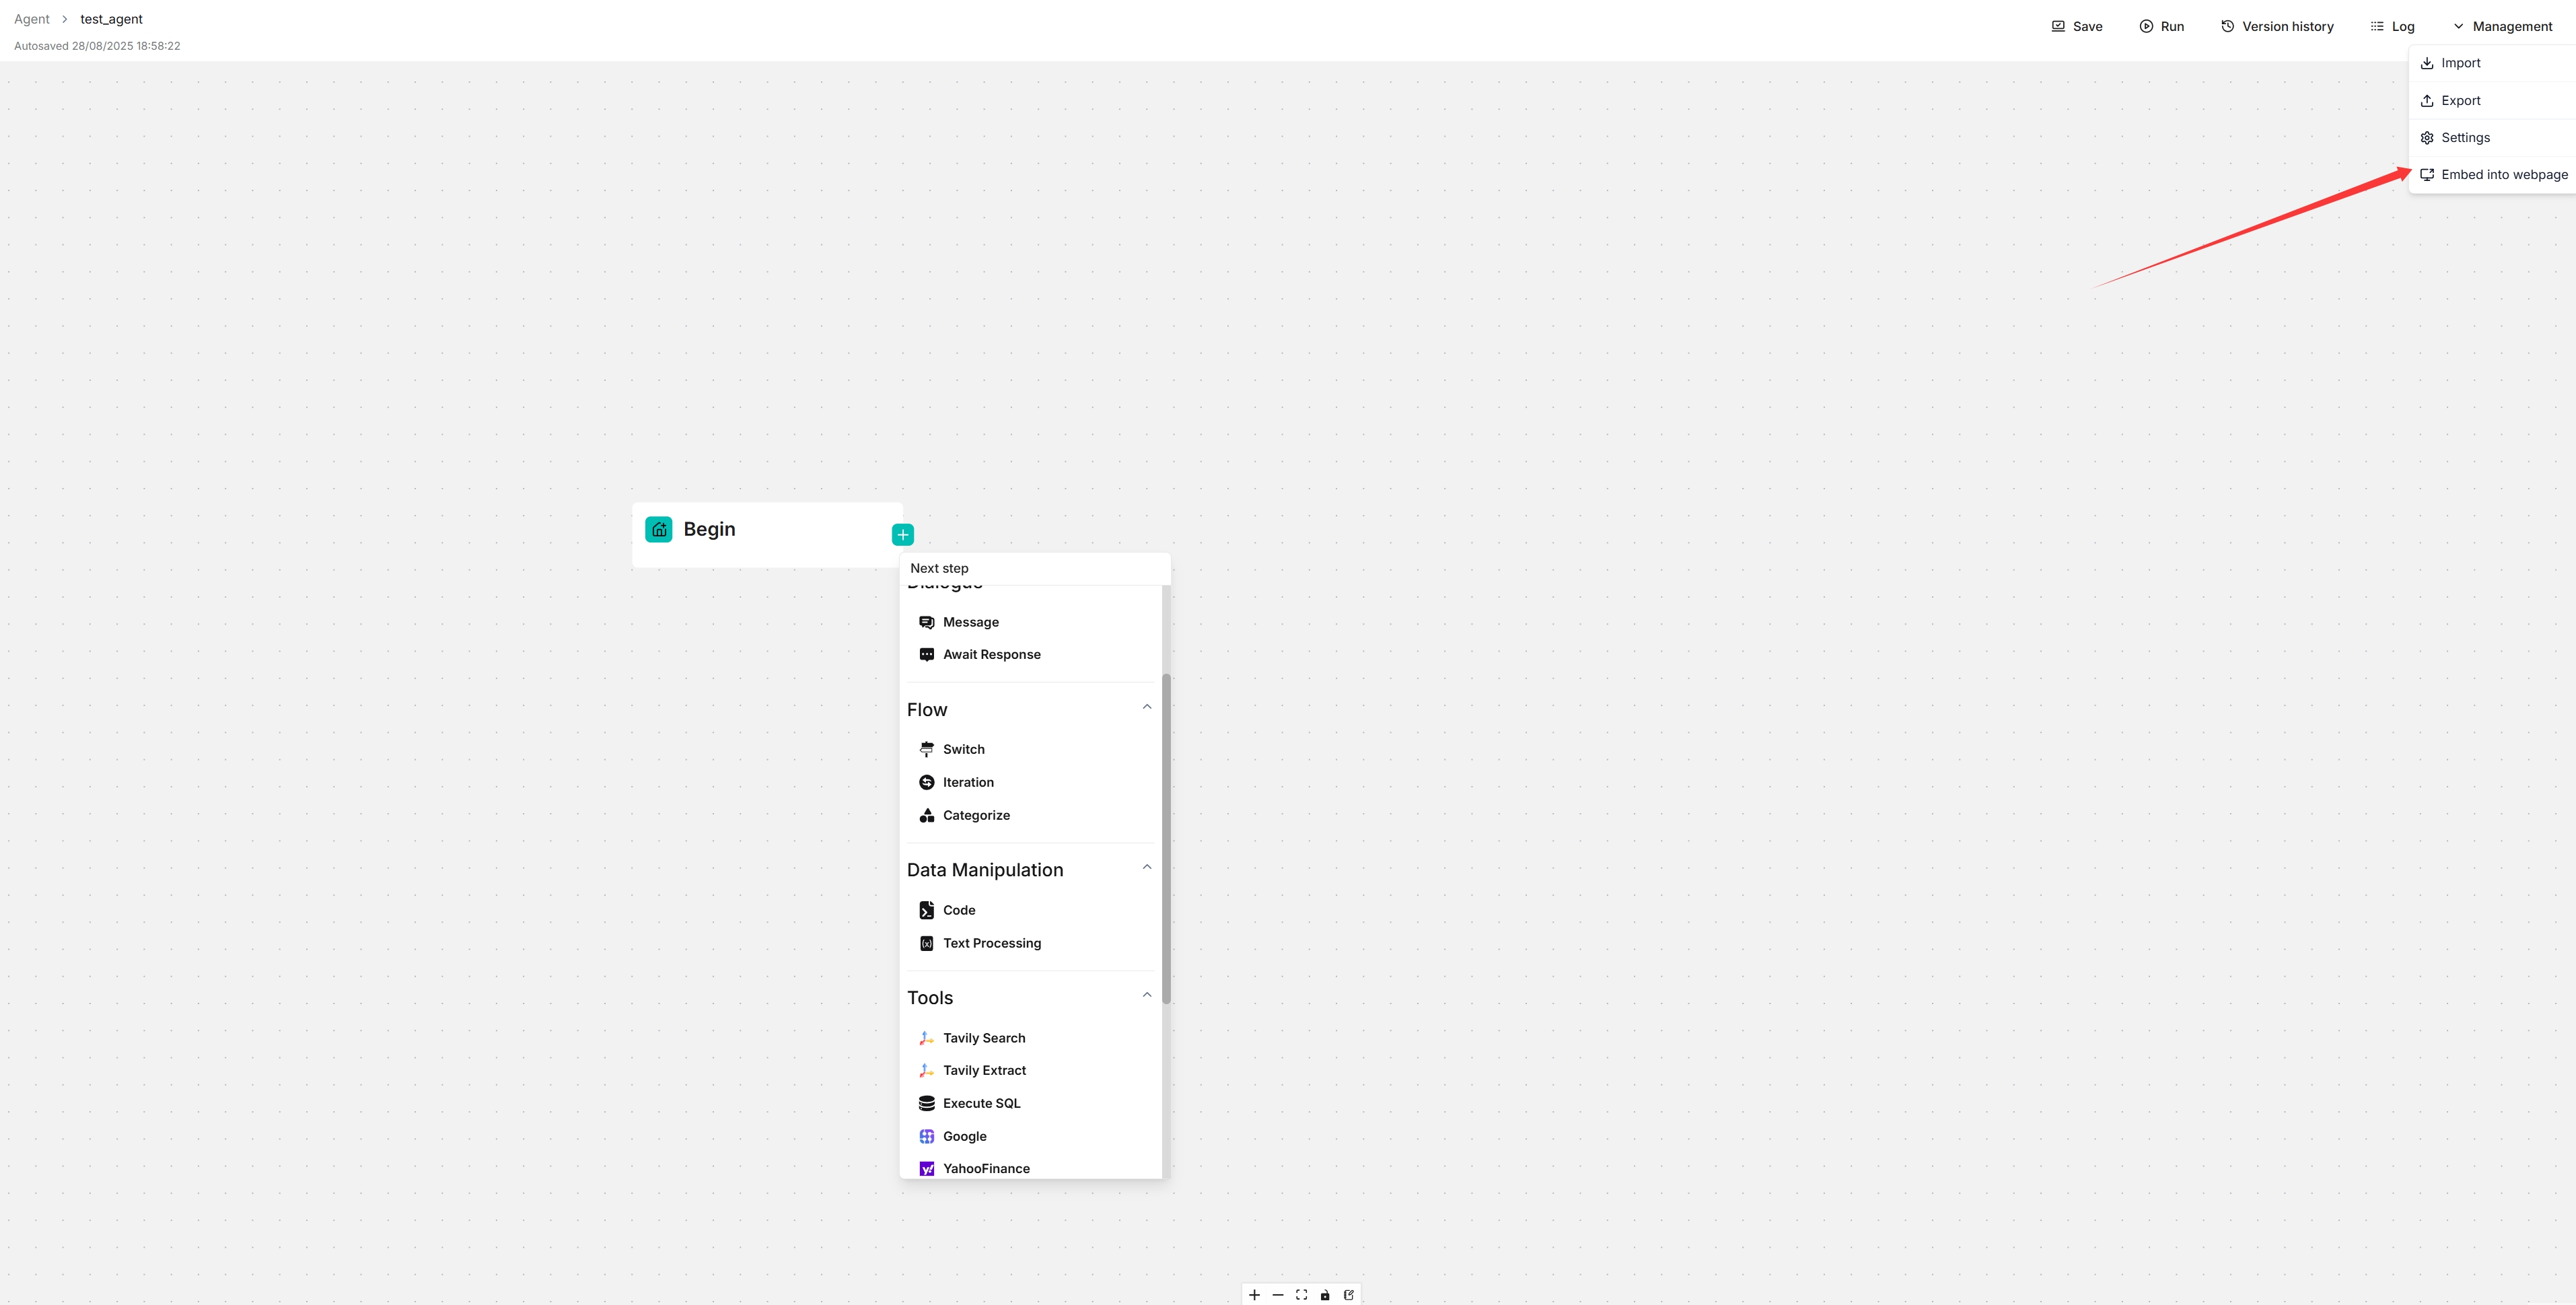3. Copy the iframe code and embed it into your webpage.-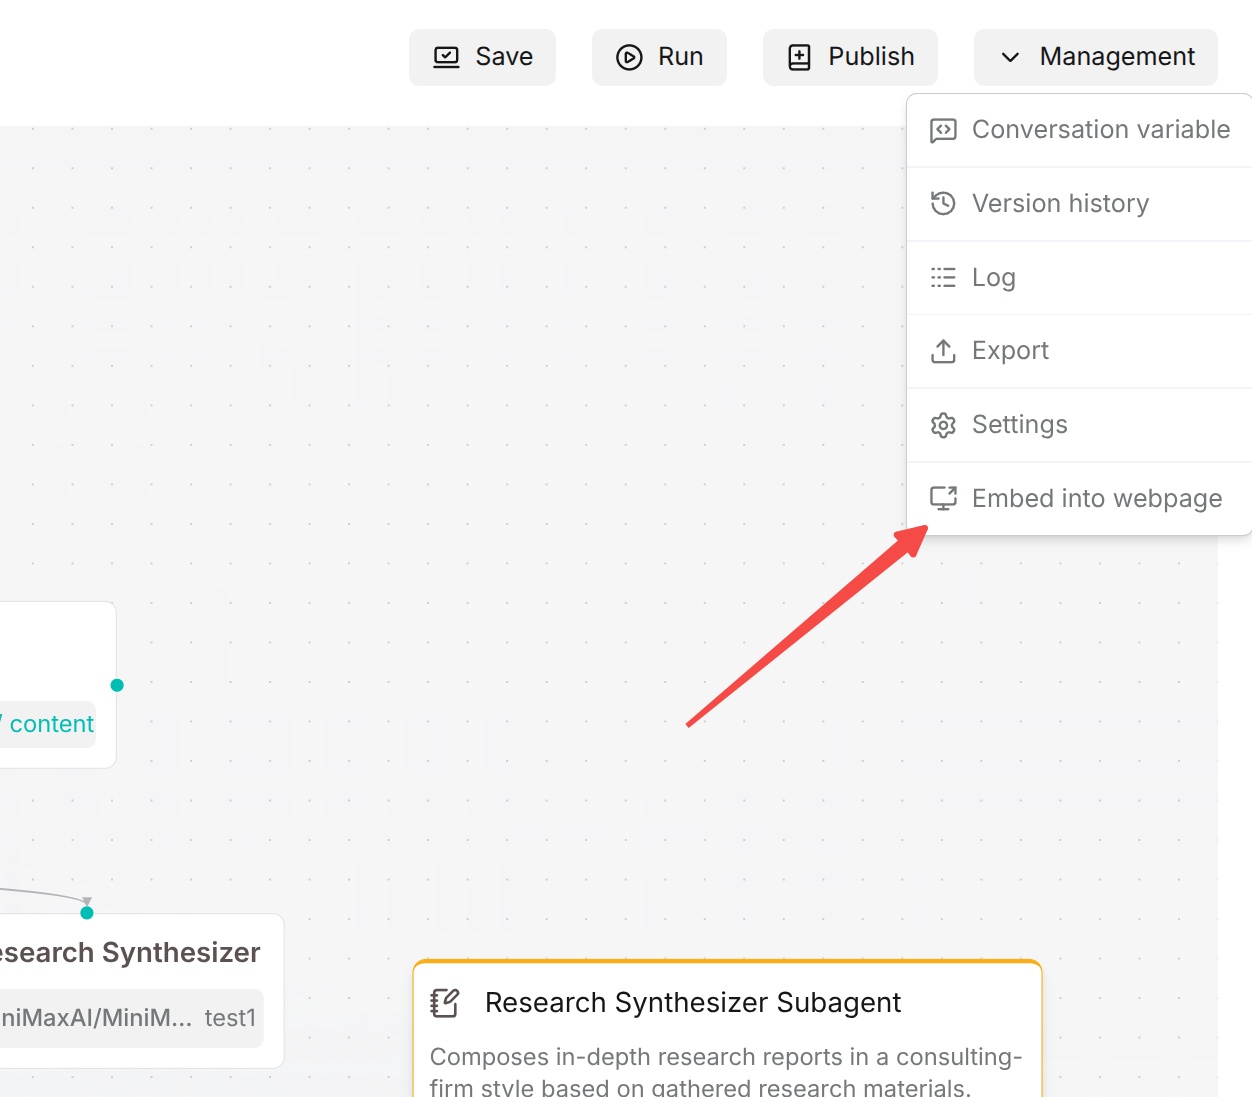++> **Note:** Currently, only **Workflow** agents can be embedded in web pages. **Ingestion pipeline** and **Compilation Operator** agents do not support web embedding.\ No newline at end of filediff --git a/docs/guides/agent/import_and_export_agents.md b/docs/guides/agent/import_and_export_agents.mdindex 46d581253c..45a088b0ef 100644--- a/docs/guides/agent/import_and_export_agents.md+++ b/docs/guides/agent/import_and_export_agents.md@@ -12,15 +12,14 @@ sidebar_custom_props: {## Import Agent- First-time import: Upload the JSON file, fill in corresponding information, drag or click to upload the file, then save.-- Non-first-time import: Upload the JSON file, fill in corresponding information, drag or click to upload the file, then save.---++- Non-first-time import: Upload the JSON file, fill in corresponding information, drag or click to upload the file, then save.-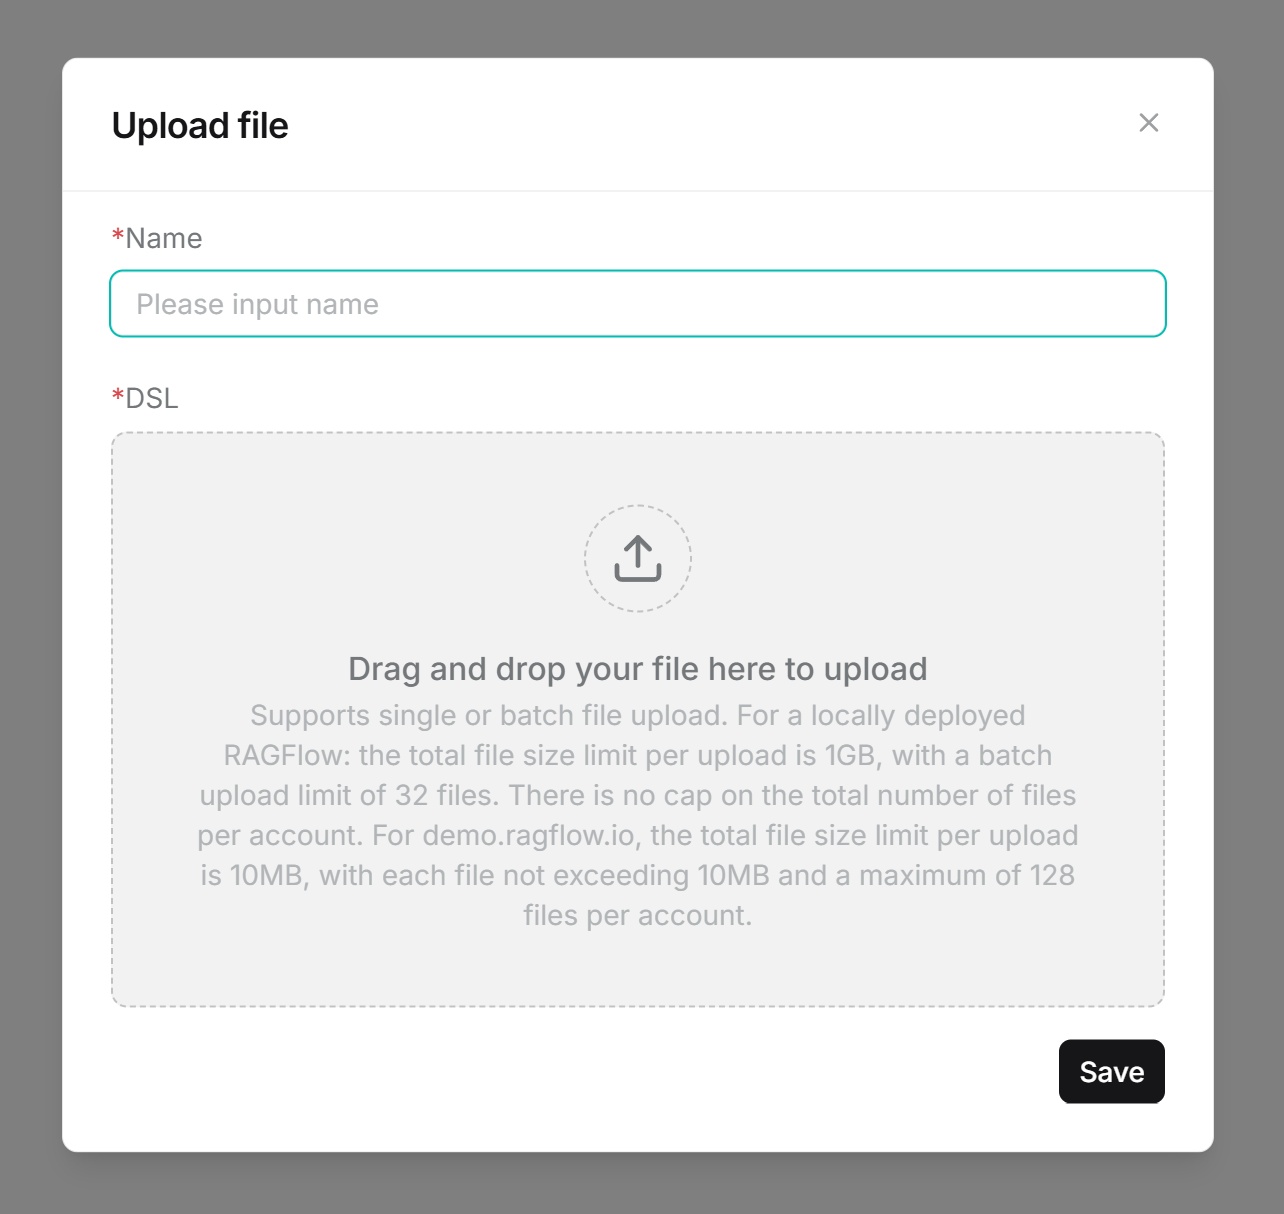++## Export AgentOpen an Agent, click **Manage** in the upper right corner, then click export.-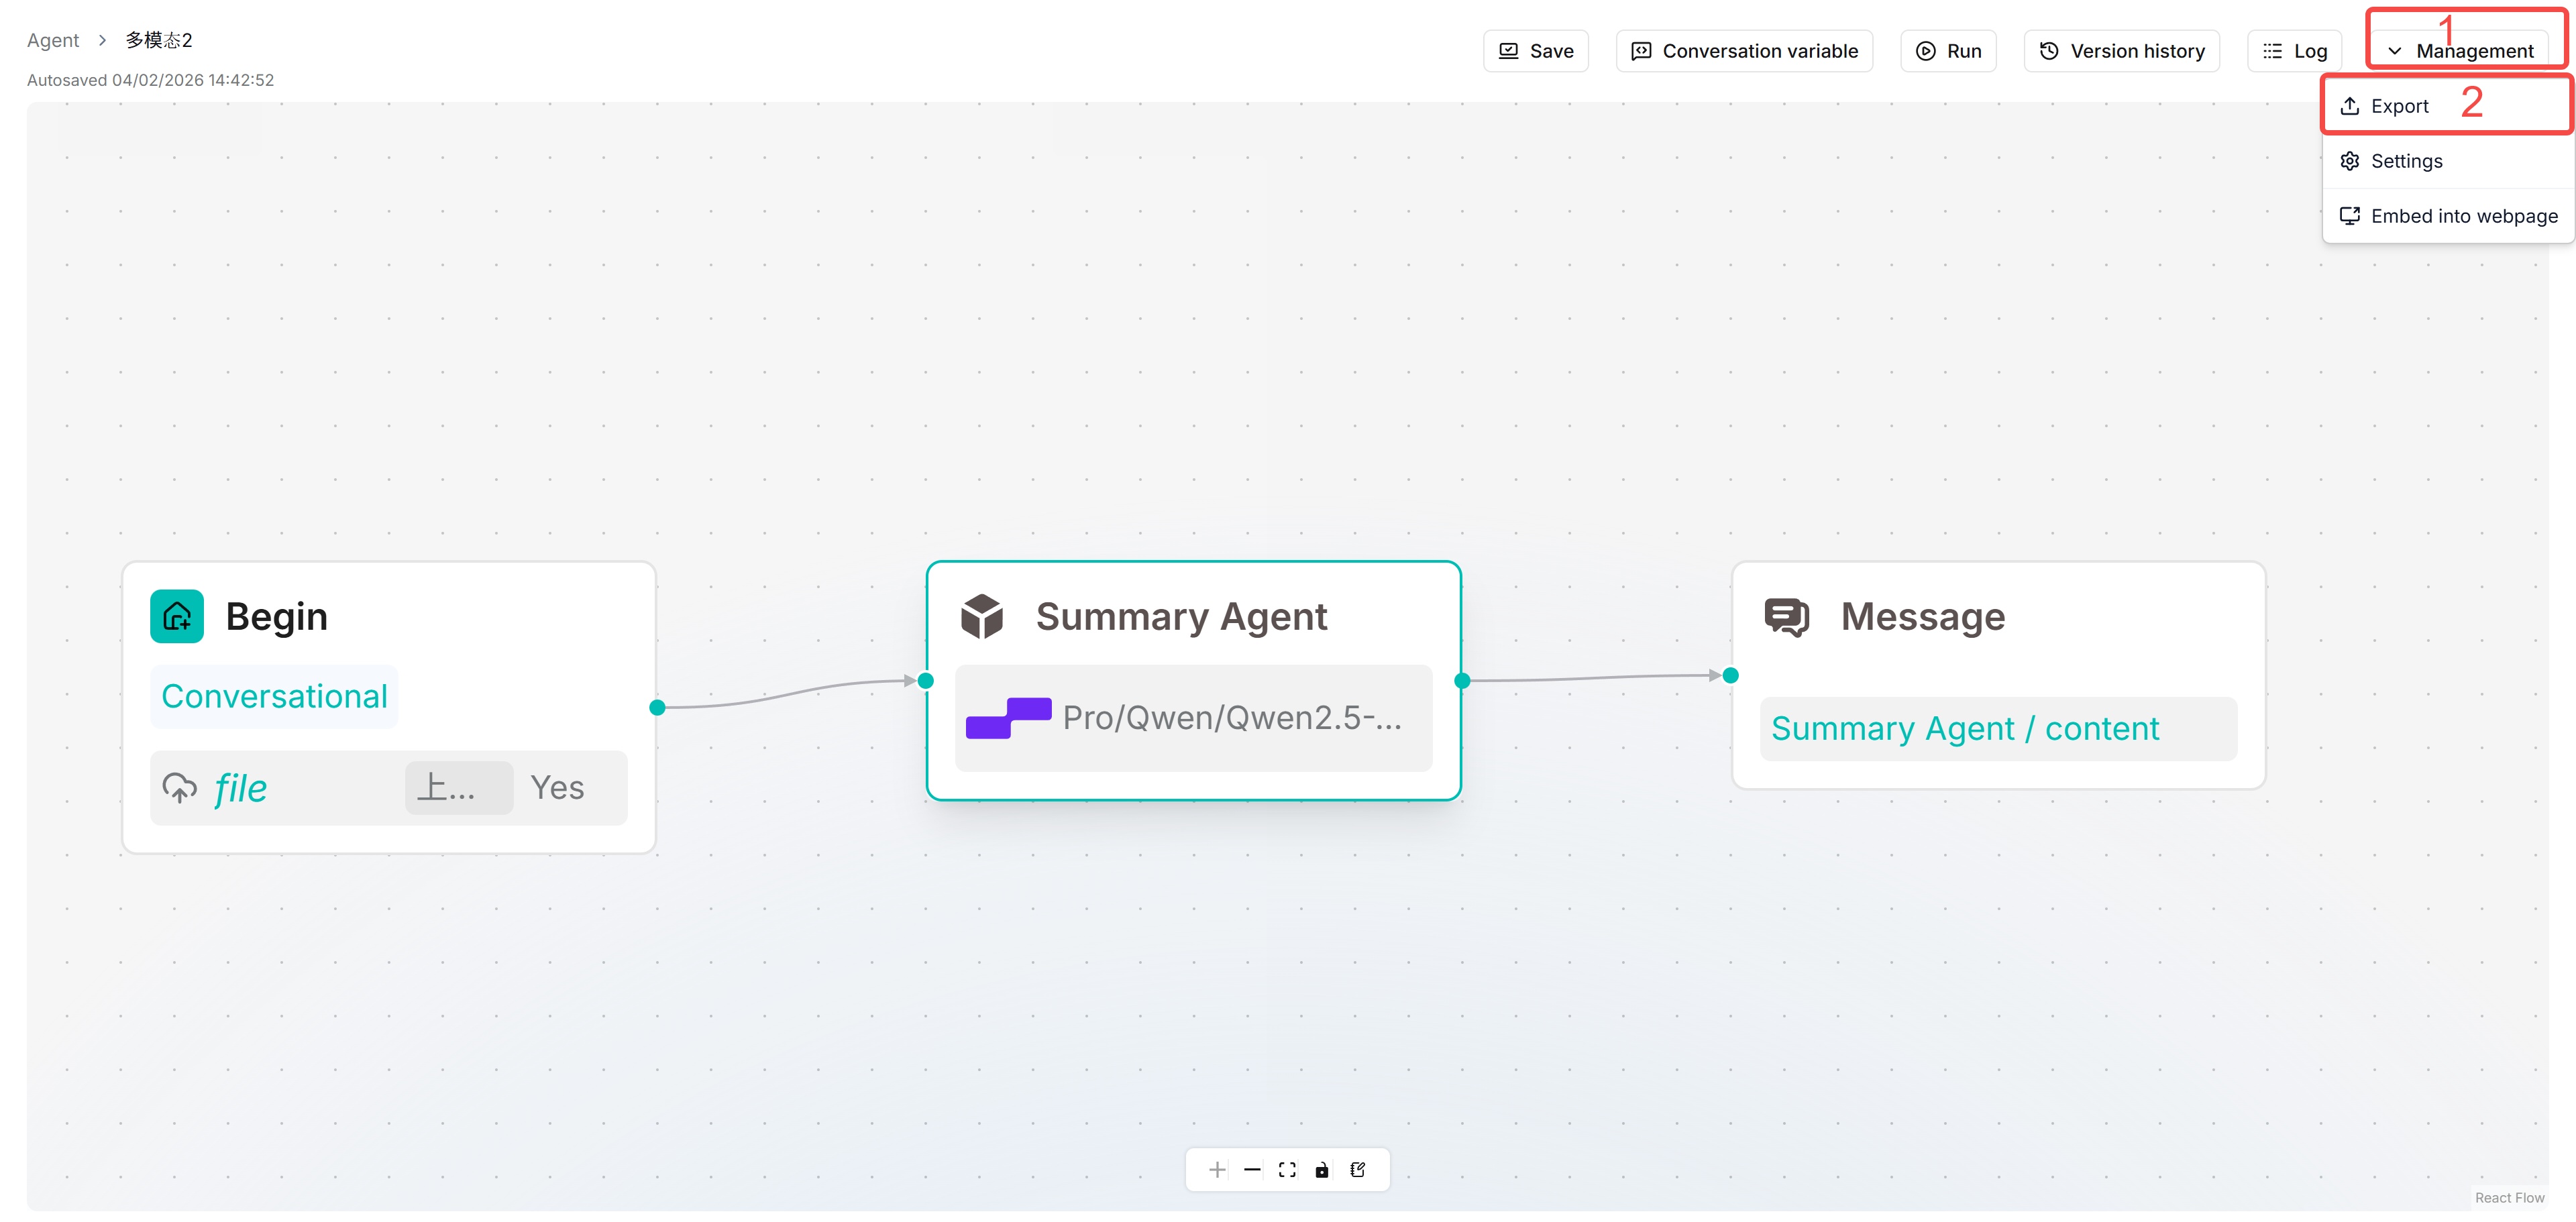+diff --git a/docs/guides/agent/ingestion_pipeline/configure_parser_component.md b/docs/guides/agent/ingestion_pipeline/configure_parser_component.mdindex 8aa89977f4..49bd9706d6 100644--- a/docs/guides/agent/ingestion_pipeline/configure_parser_component.md+++ b/docs/guides/agent/ingestion_pipeline/configure_parser_component.md@@ -14,6 +14,8 @@ The **Parser** component converts your files into structured text while preserviIt supports 8 file categories and more than 23 formats, including PDF, images, audio, video, email, spreadsheets (Excel), Word, PPT, HTML and Markdown.+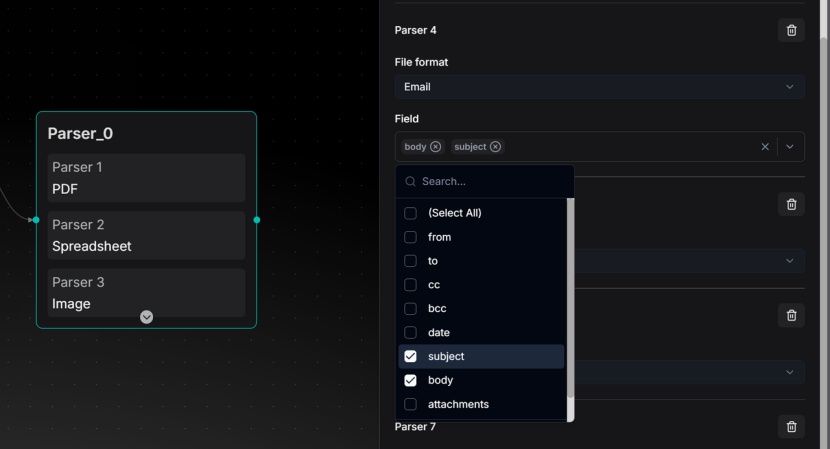+Key configurations:For PDF files, select one of the following:@@ -22,6 +24,8 @@ For PDF files, select one of the following:- **MinerU**: Industry-leading for complex elements such as mathematical formulas and complex layouts.- **Naive**: Simple text extraction. Use it for clean, text-based PDFs without complex elements.+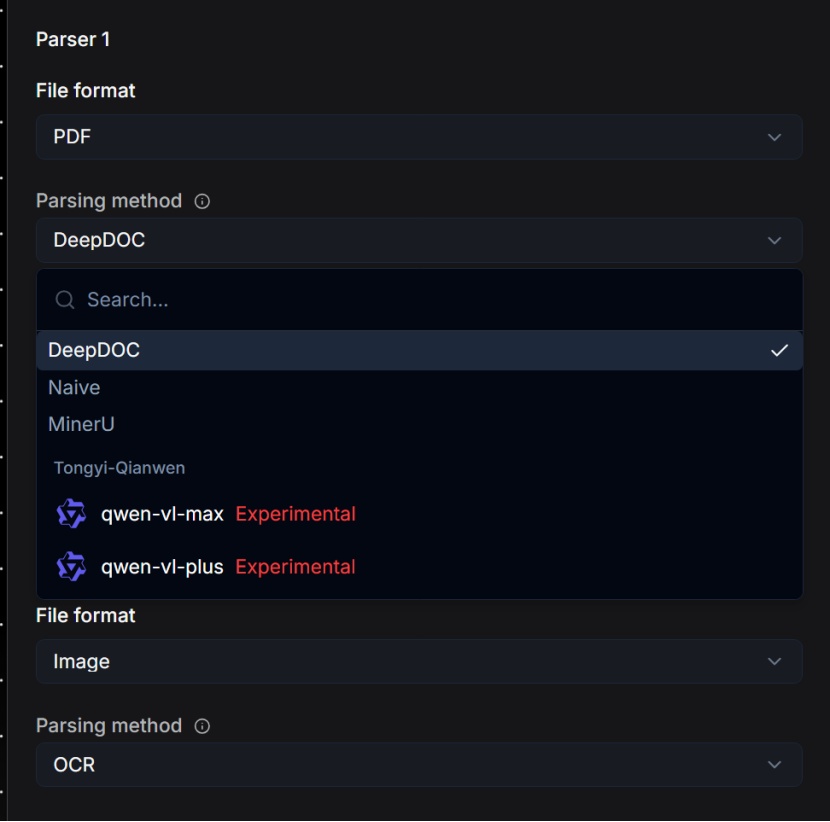+For image files:- OCR is used by default.@@ -42,7 +46,3 @@ For Word/PPT:For text and markup (HTML/MD):- Formatting tags are automatically removed and clean text is output.----diff --git a/docs/guides/agent/ingestion_pipeline/configure_transformer_component.md b/docs/guides/agent/ingestion_pipeline/configure_transformer_component.mdindex 9c3ac33118..18479d793e 100644--- a/docs/guides/agent/ingestion_pipeline/configure_transformer_component.md+++ b/docs/guides/agent/ingestion_pipeline/configure_transformer_component.md@@ -19,6 +19,8 @@ It has four generation types:- **Questions**: Generates questions that each text chunk can answer.- **Metadata**: Custom metadata extraction.+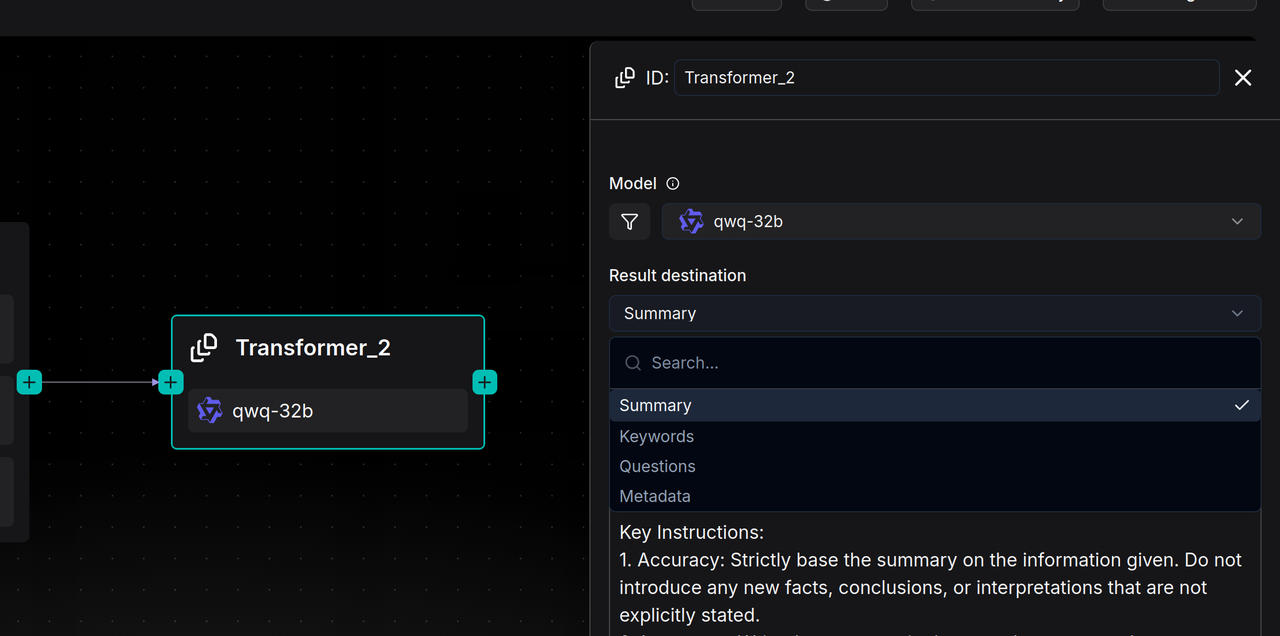+If you have multiple **Transformer** components, make sure to separate the **Transformer** component for each function, for example, one for summaries and another for keywords.Key configurations:@@ -29,6 +31,8 @@ Model mode (select one):- **Precise**: Strictly faithful to the text, suitable for summary and keyword extraction.- **Balanced**: A middle ground suitable for most scenarios.+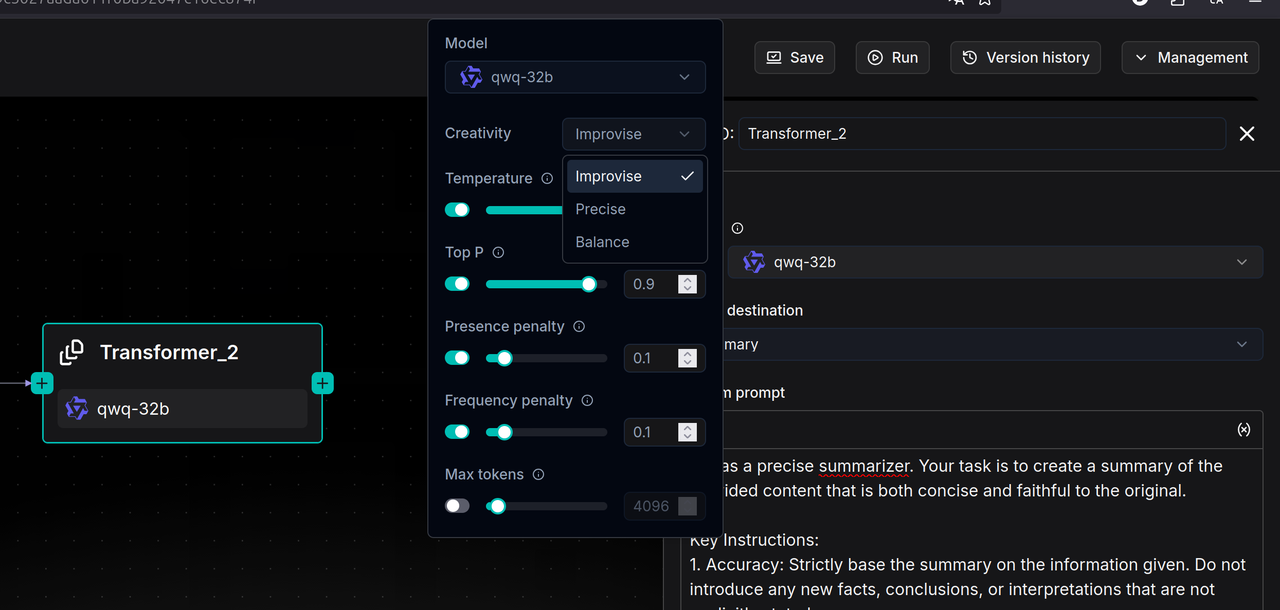+Prompt engineering:- The system prompt for each generation type is open and customizable.@@ -45,8 +49,4 @@ Chained connection:- When chaining **Transformer** components, if variables are referenced correctly, the second **Transformer** component processes the output of the first one, for example, generating keywords from a summary.-----+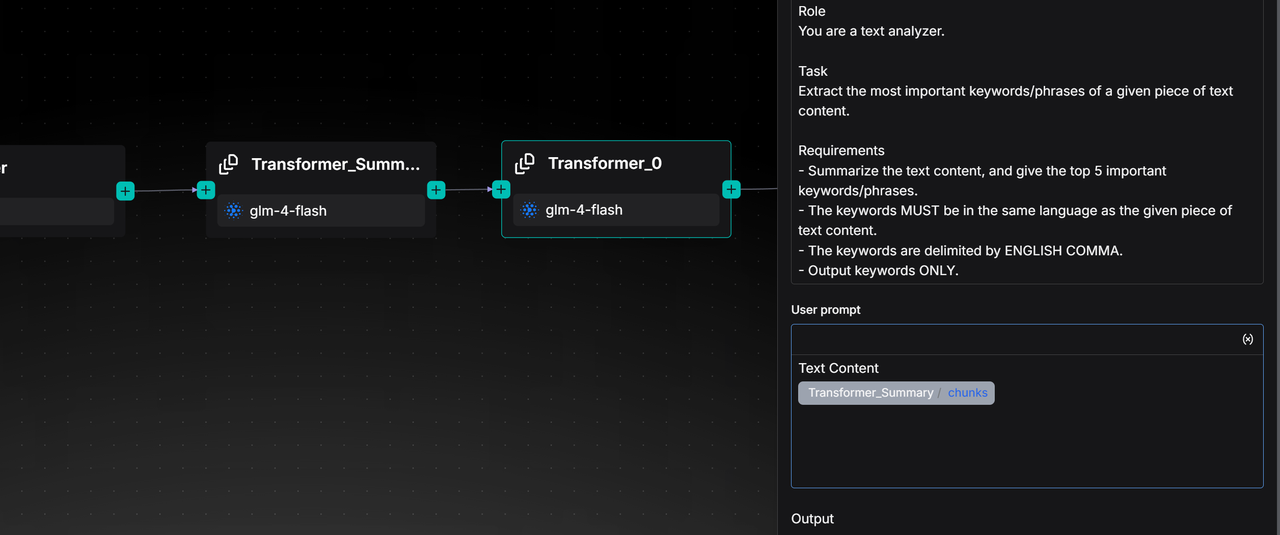diff --git a/docs/guides/agent/ingestion_pipeline/connect_the_pipeline_to_a_knowledge_base.md b/docs/guides/agent/ingestion_pipeline/connect_the_pipeline_to_a_knowledge_base.mdindex 4996d97ee4..8372ab7c70 100644--- a/docs/guides/agent/ingestion_pipeline/connect_the_pipeline_to_a_knowledge_base.md+++ b/docs/guides/agent/ingestion_pipeline/connect_the_pipeline_to_a_knowledge_base.md@@ -14,8 +14,6 @@ sidebar_custom_props: {2. Click **Select pipeline** and choose the pipeline you saved.3. Any file uploaded to this knowledge base will be processed by your custom Pipeline.-+---+\ No newline at end of filediff --git a/docs/guides/agent/ingestion_pipeline/create_ingestion_pipeline.md b/docs/guides/agent/ingestion_pipeline/create_ingestion_pipeline.mdindex 39682521e1..8389281df9 100644--- a/docs/guides/agent/ingestion_pipeline/create_ingestion_pipeline.md+++ b/docs/guides/agent/ingestion_pipeline/create_ingestion_pipeline.md@@ -12,6 +12,6 @@ sidebar_custom_props: {1. Go to the **Agent** page.2. Click **Create Agent** and start from a blank canvas or a prebuilt template. Templates are recommended for beginners.-3. On the canvas, drag, drop and connect components from the right panel to design your flow, for example: Parser -> Chunker -> Transformer -> Indexer.-++3. On the canvas, drag, drop and connect components from the right panel to design your flow, for example: Parser -> Chunker -> Transformer -> Indexer.diff --git a/docs/guides/agent/understand_the_canvas.md b/docs/guides/agent/understand_the_canvas.mdindex f7b6d7fa3a..404f8b47e9 100644--- a/docs/guides/agent/understand_the_canvas.md+++ b/docs/guides/agent/understand_the_canvas.md@@ -16,6 +16,8 @@ Click the plus sign next to any component on the canvas to select the next compoAfter adding a component, click the component itself to open the configuration panel on the right. Fields in the configuration panel define input data, processing logic, output variables, and references for subsequent steps.+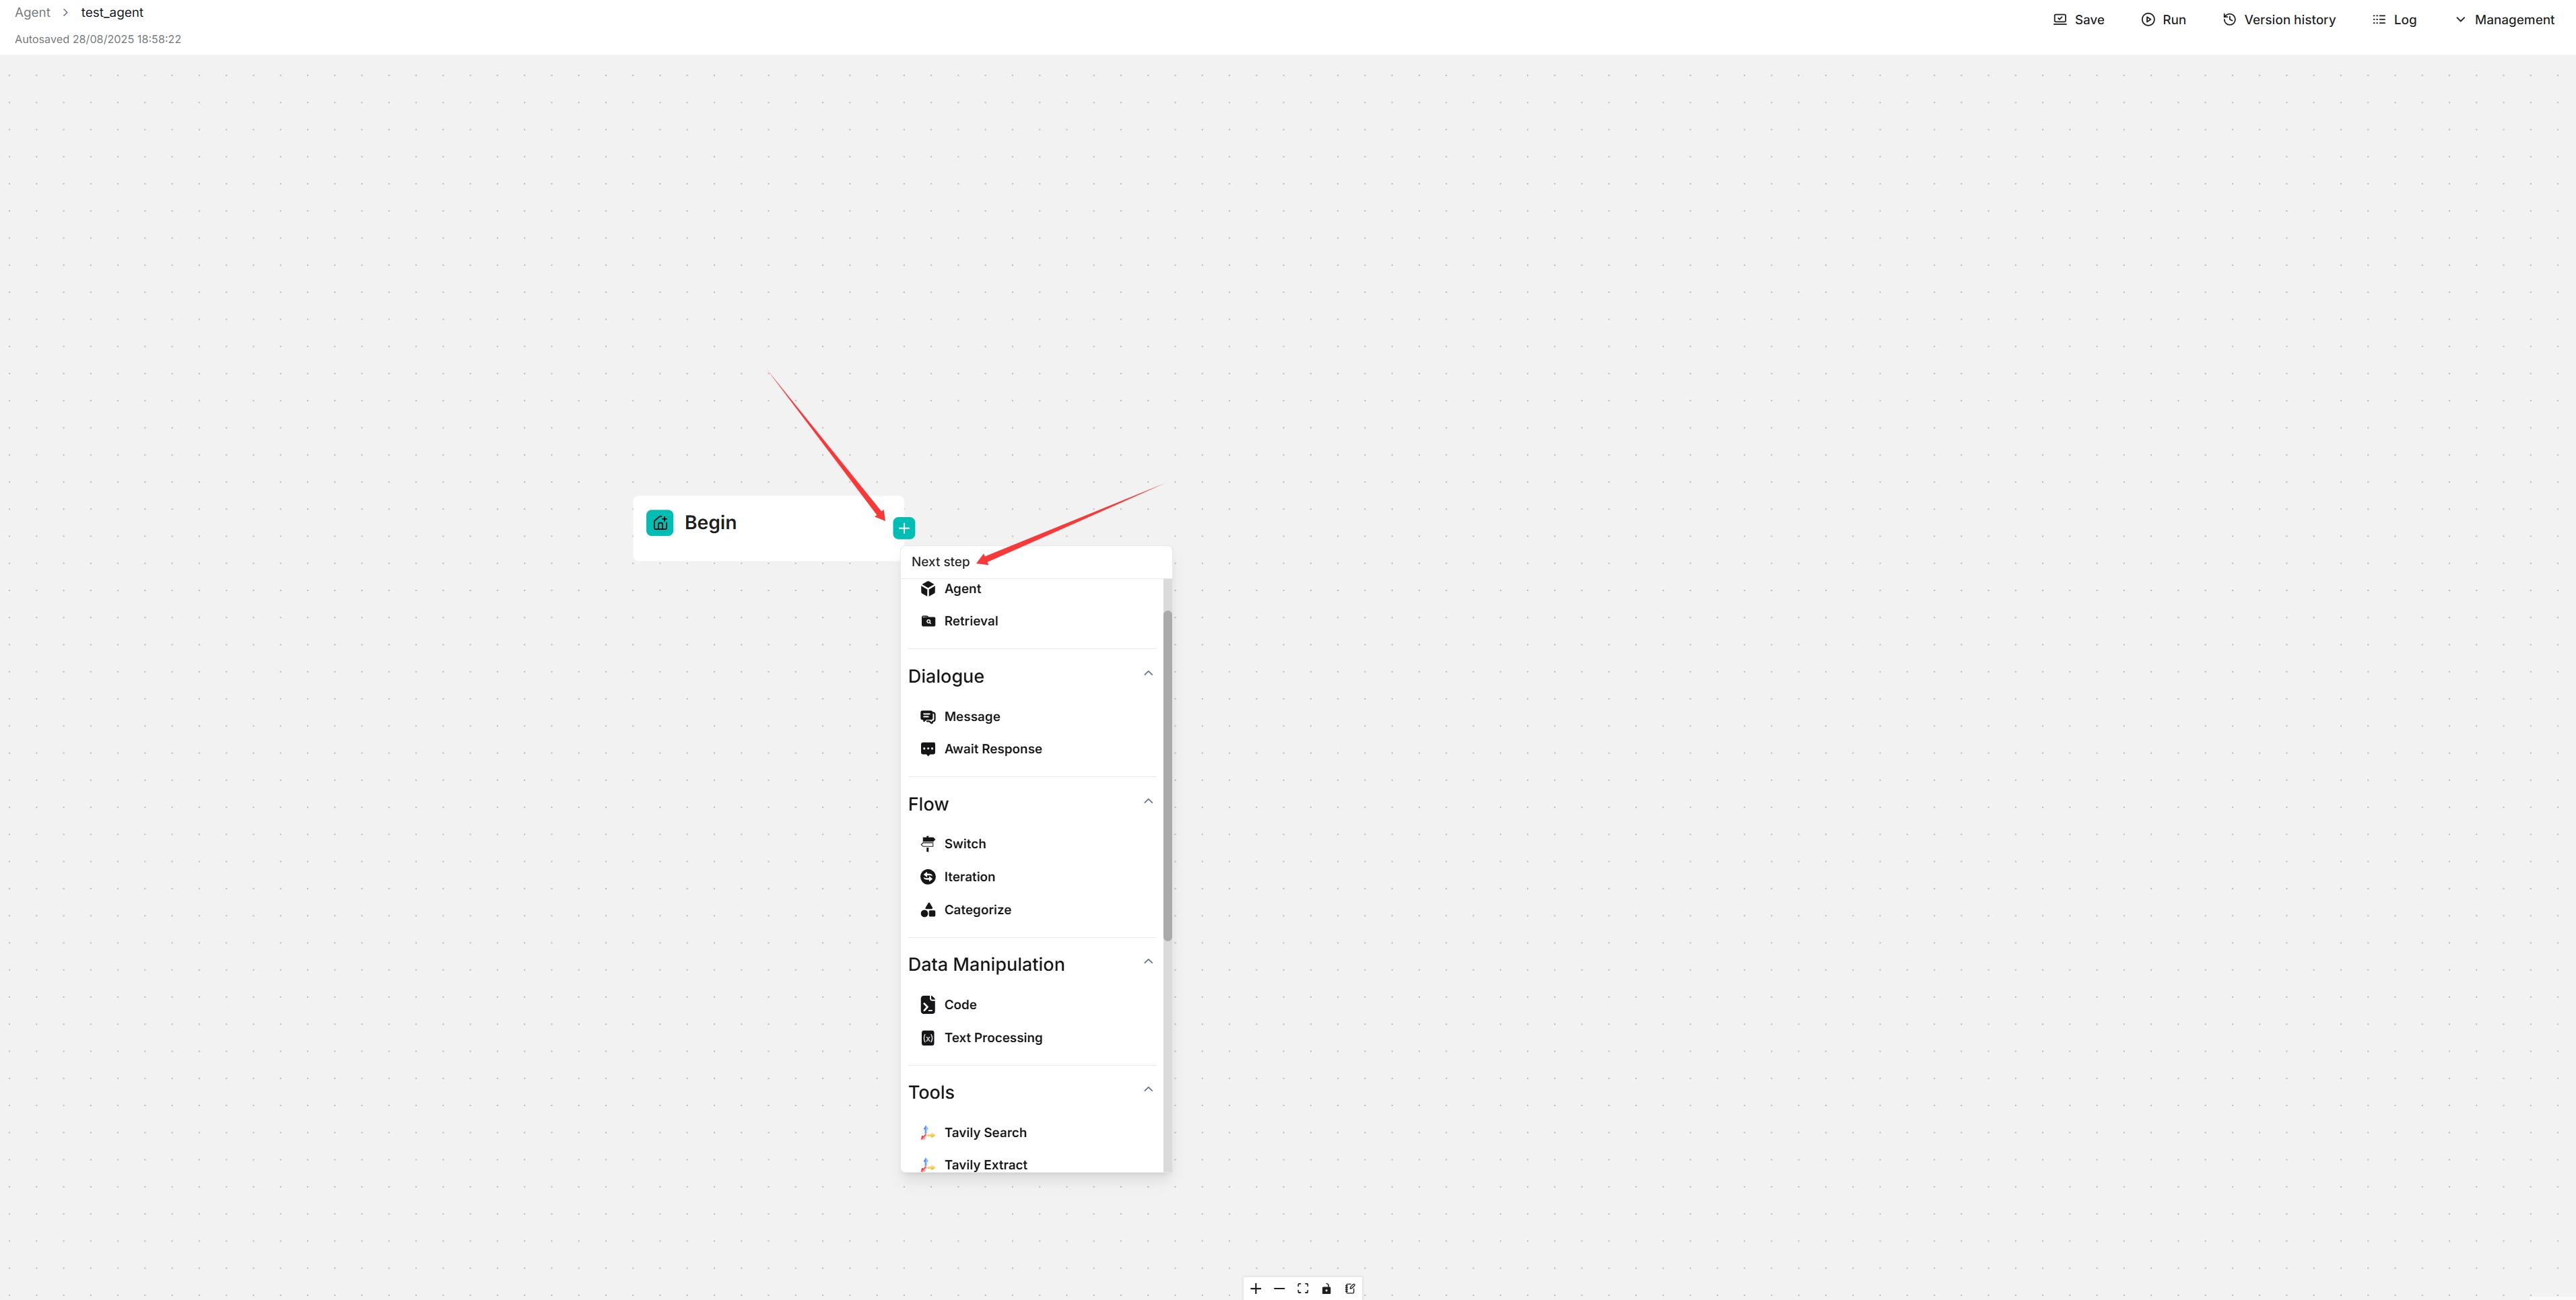+## Use VariablesComponents on the Agent canvas support variable references to implement data transmission between components. Variable sources include system variables, global variables defined in the Begin component, and outputs from upstream components.@@ -43,13 +45,11 @@ Operation Steps:6. After selection, the variable will be automatically inserted into the input box.7. Save component configuration and run the Agent to verify data transmission.-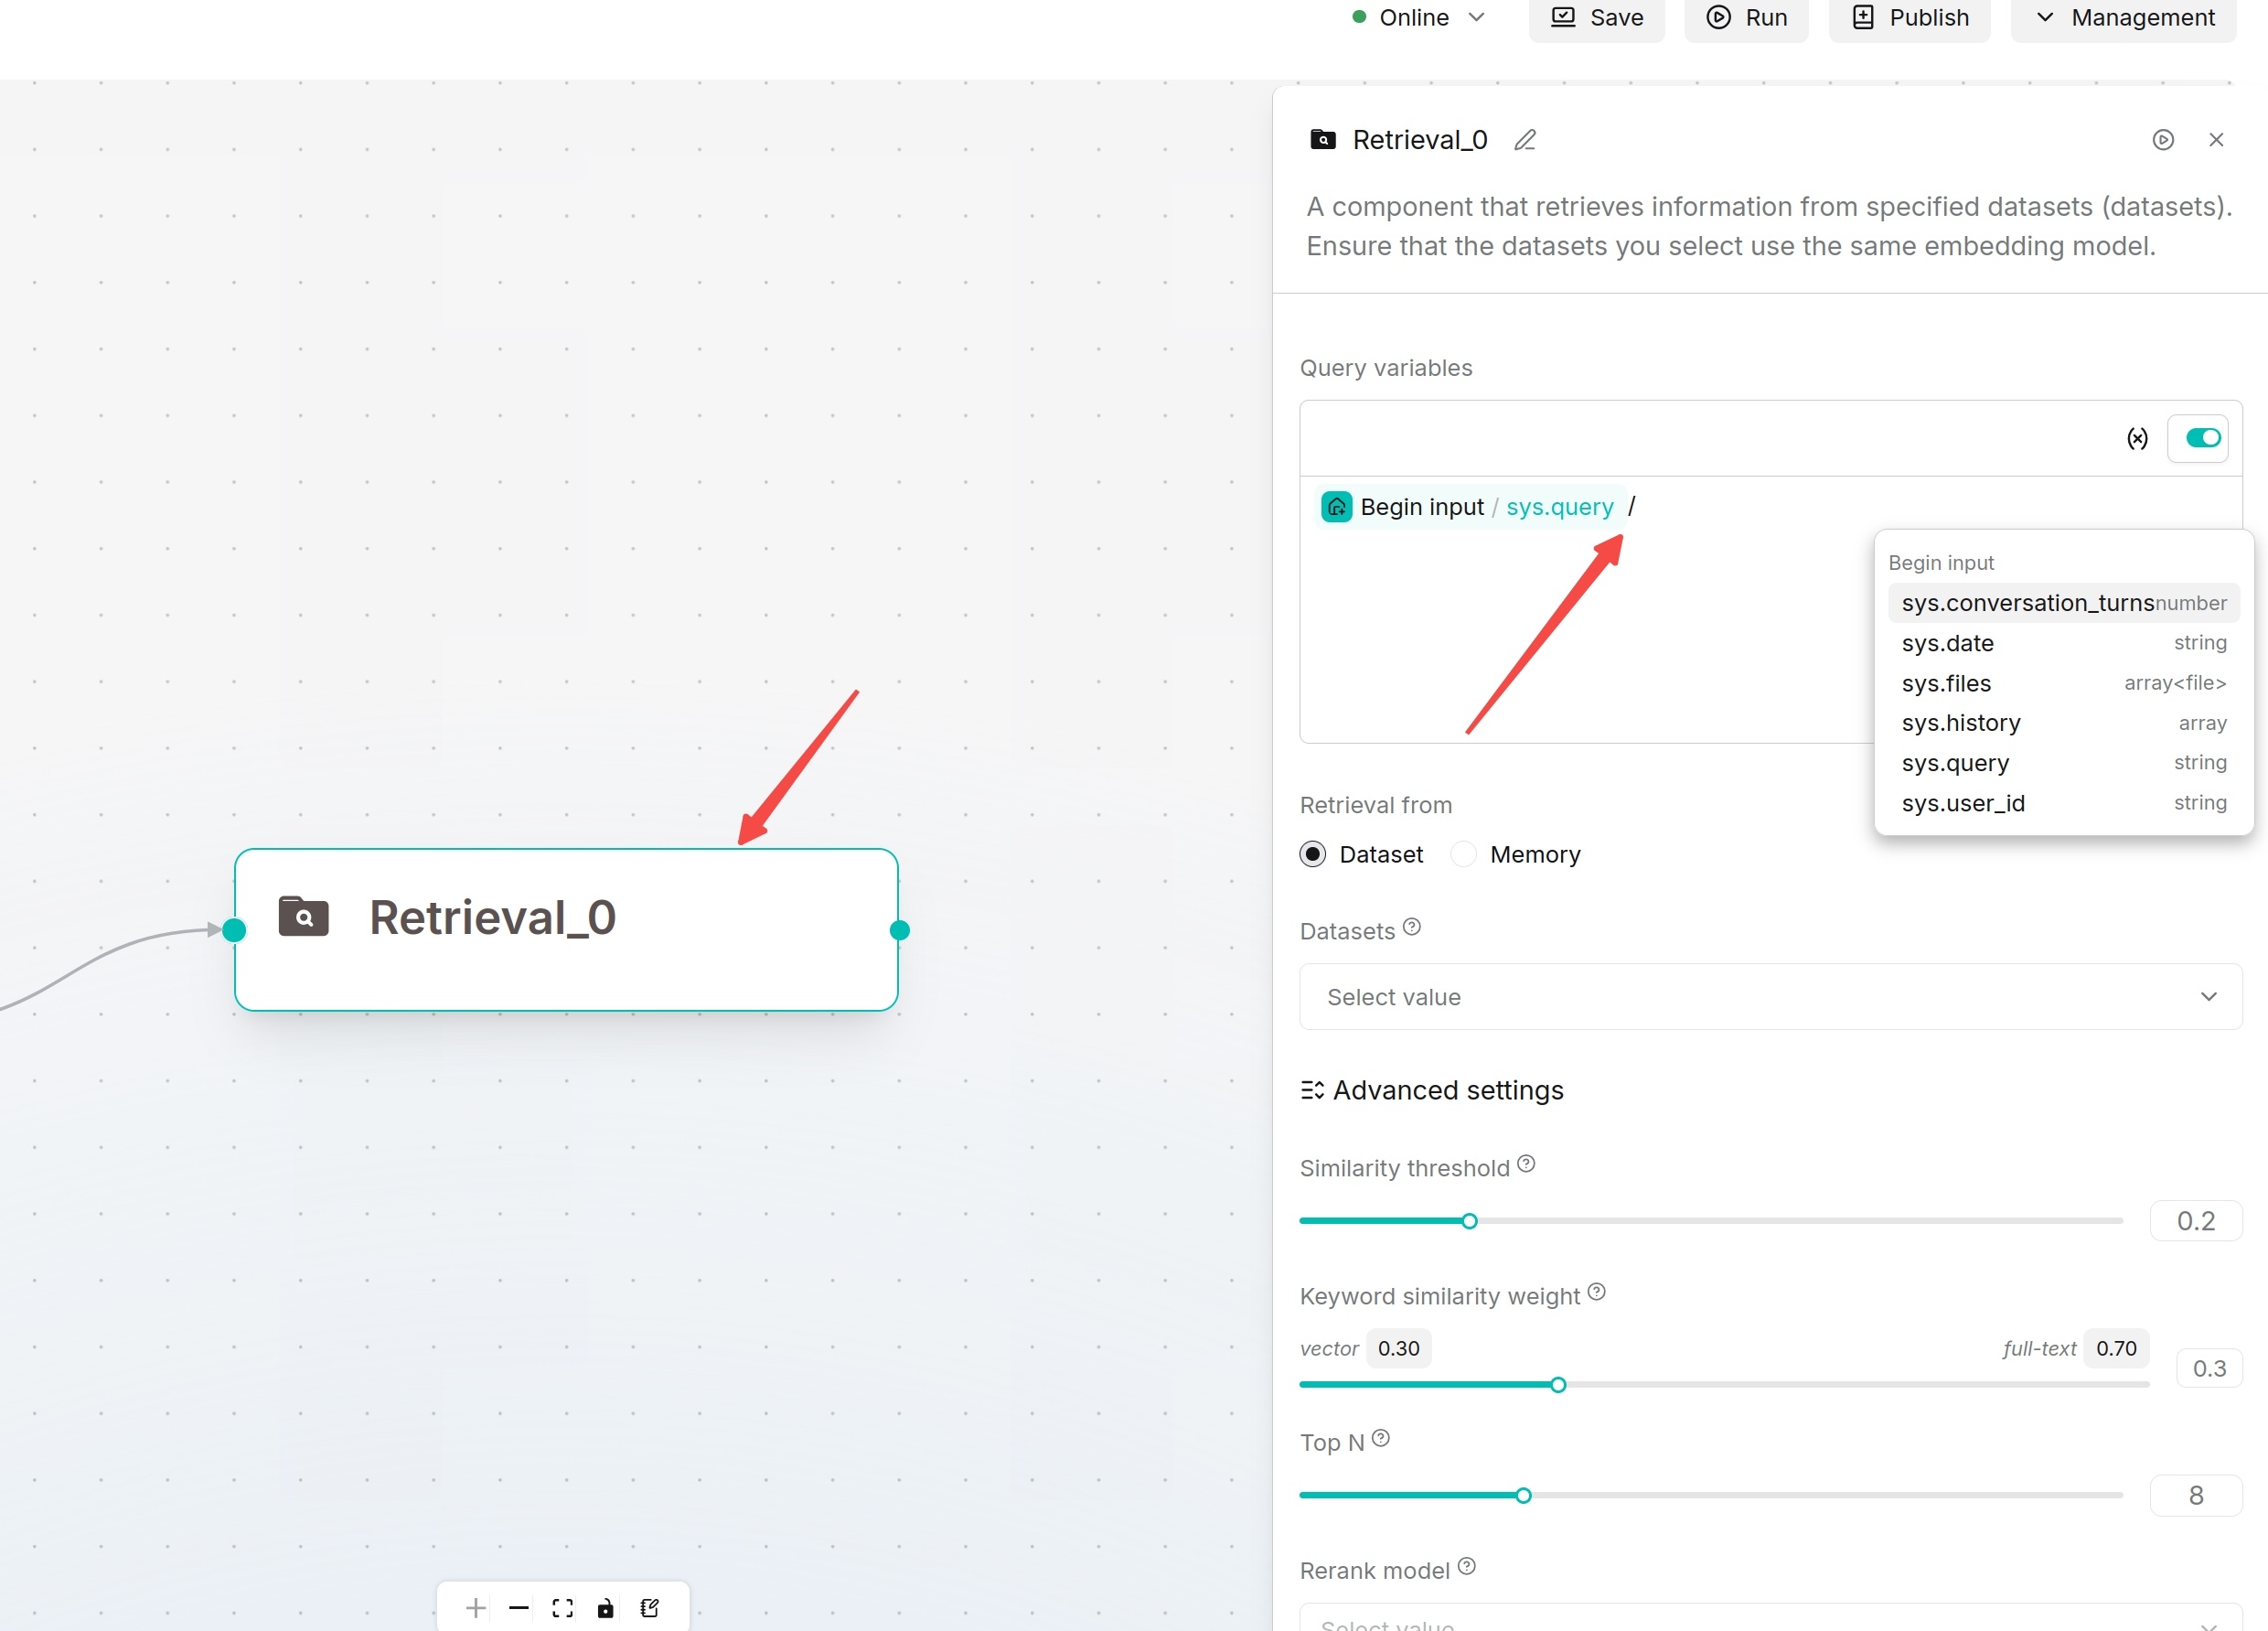-+## Save & RunAfter configuration, click **Save** to save the Agent. During debugging, click **Run** at the top of the canvas, enter test questions and observe the execution result of each component. If a component returns no output, check input variables, model configuration, knowledge base permissions, external interface addresses or tool configuration.--+## Component Connection RulesConnections define component execution order. Sequential components run along a single path. Branch components such as `Switch` and `Categorize` route workflows to different exits according to conditions. `Iteration` executes sub-processes in loops. Components not connected to the execution path will not run. Before deleting a component, check upstream/downstream connections and variable references to avoid missing inputs for subsequent nodes.diff --git a/docs/guides/chatchannel/chat_channels_overview.md b/docs/guides/chatchannel/chat_channels_overview.mdindex 52b9cb04f6..50715a6343 100644--- a/docs/guides/chatchannel/chat_channels_overview.md+++ b/docs/guides/chatchannel/chat_channels_overview.md@@ -34,6 +34,8 @@ After logging in to RAGFlow, go to **User Settings** and click **Chat channels**When using this feature for the first time, the page indicates that no chat channel has been added. You can select the platform you need from the **Available channels** area.+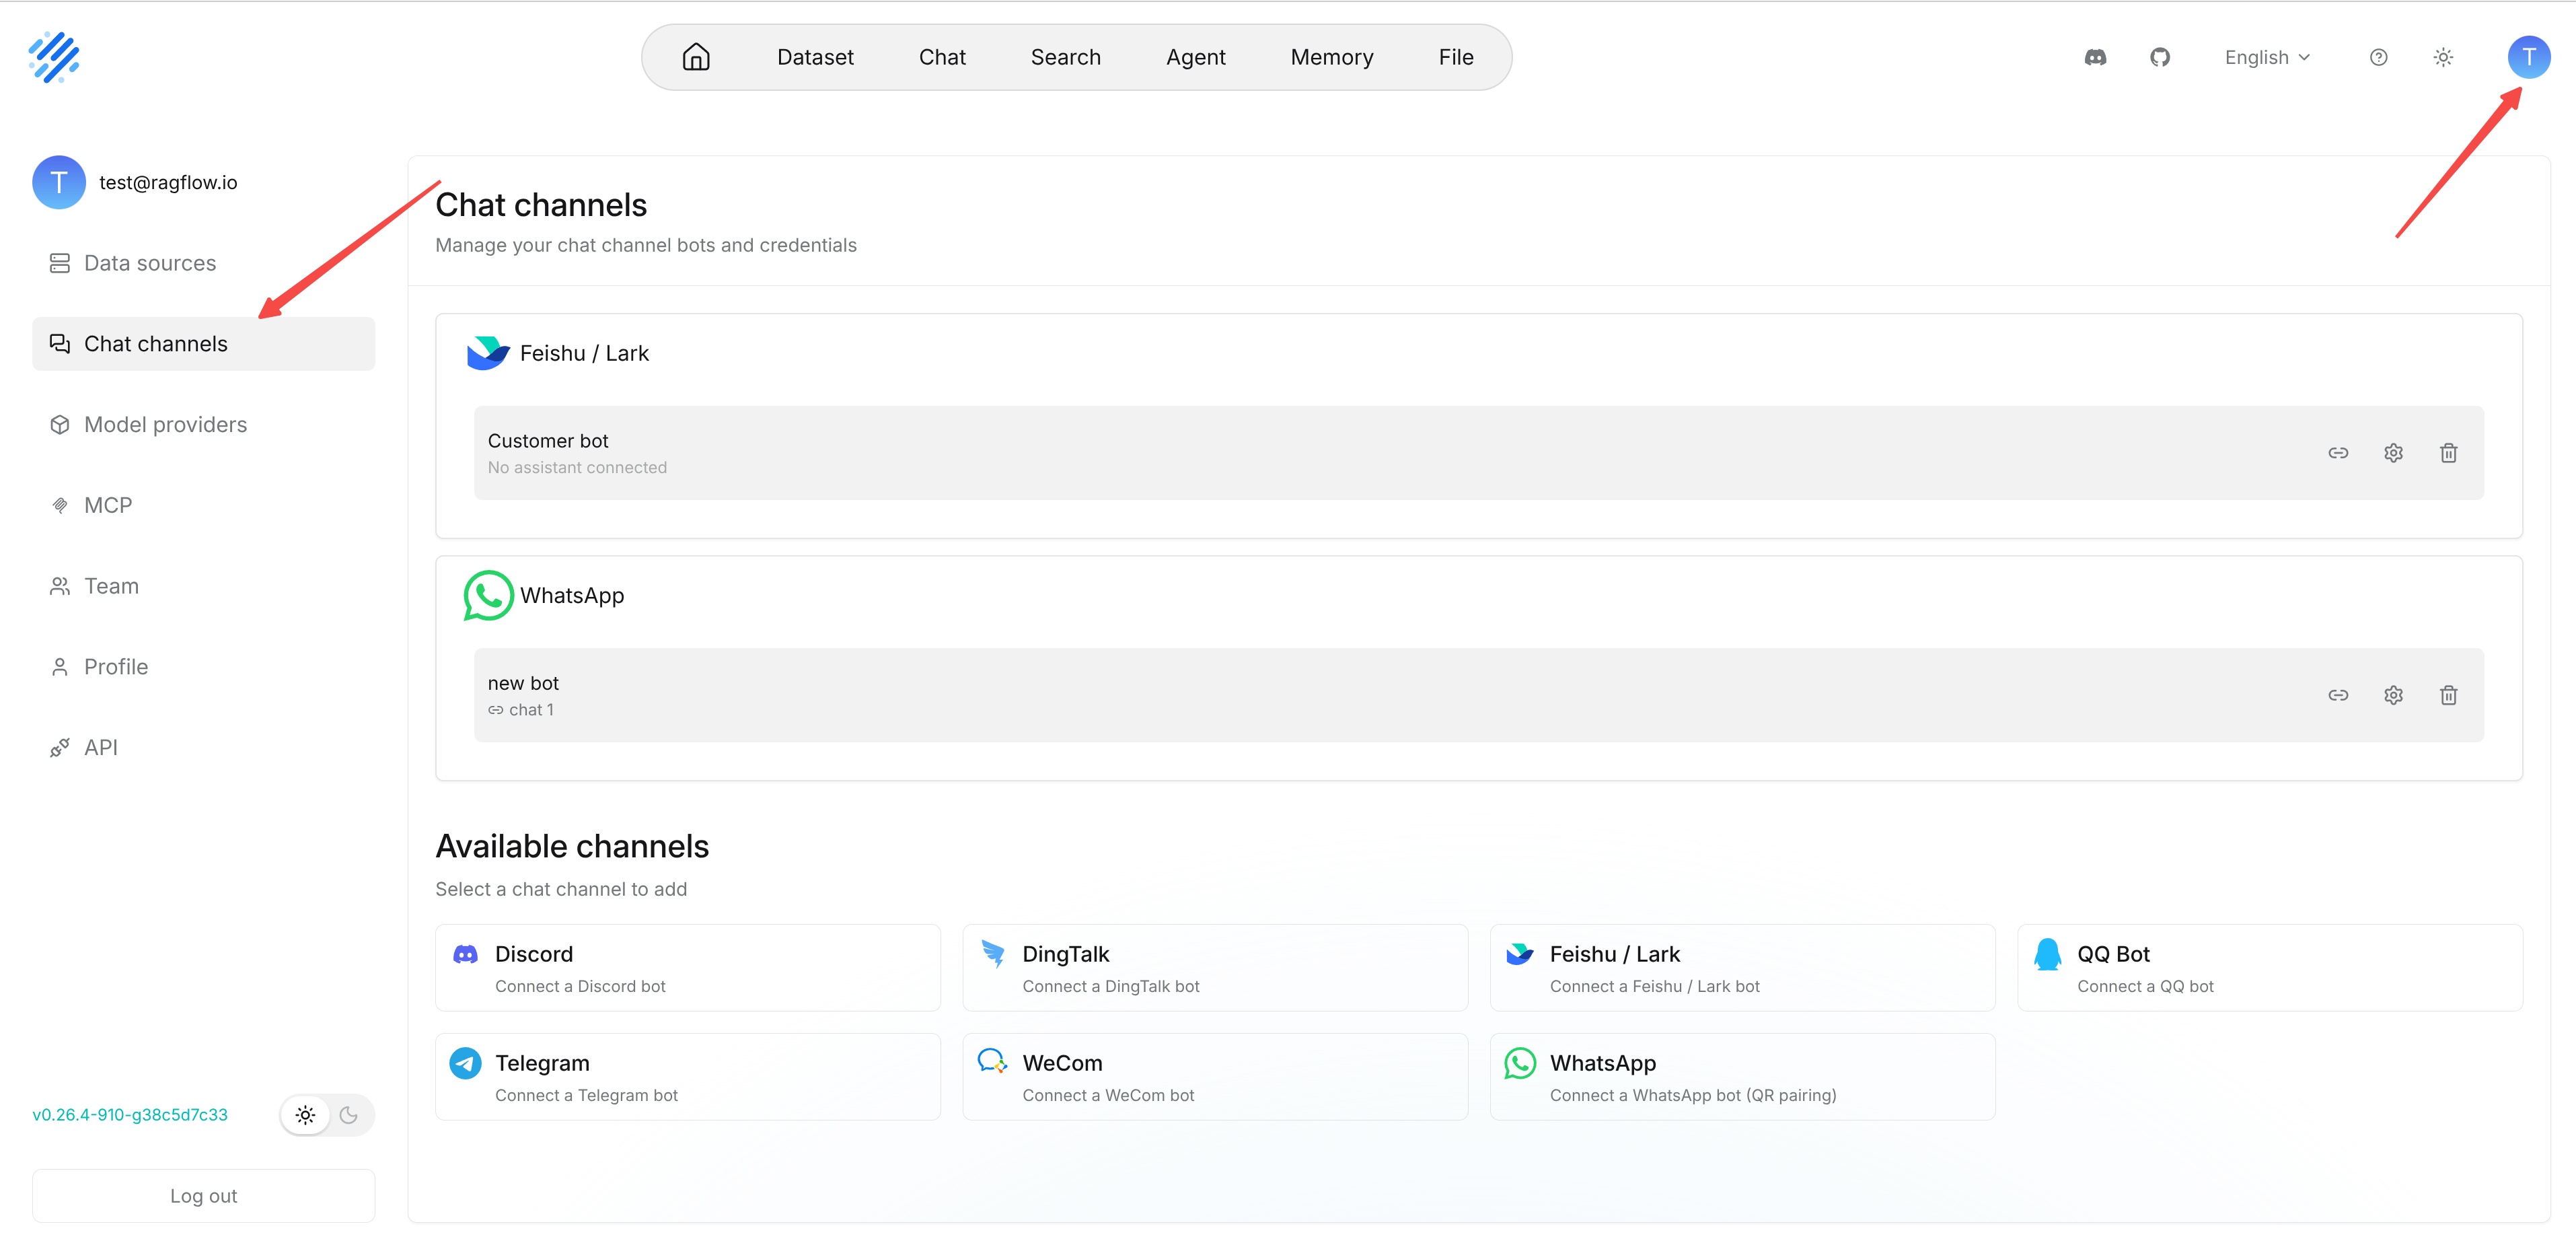+**General configuration and operation workflow**Before completing chat channel configuration, select the appropriate platform based on your actual use case, then create the channel and complete the connection configuration. After configuration, users can connect the chat channel to a Chat and interact with the bot through a third-party platform.@@ -48,6 +50,8 @@ Operation steps:6. Connect the chat channel to a Chat.7. Send a test message to the bot in the corresponding third-party platform.+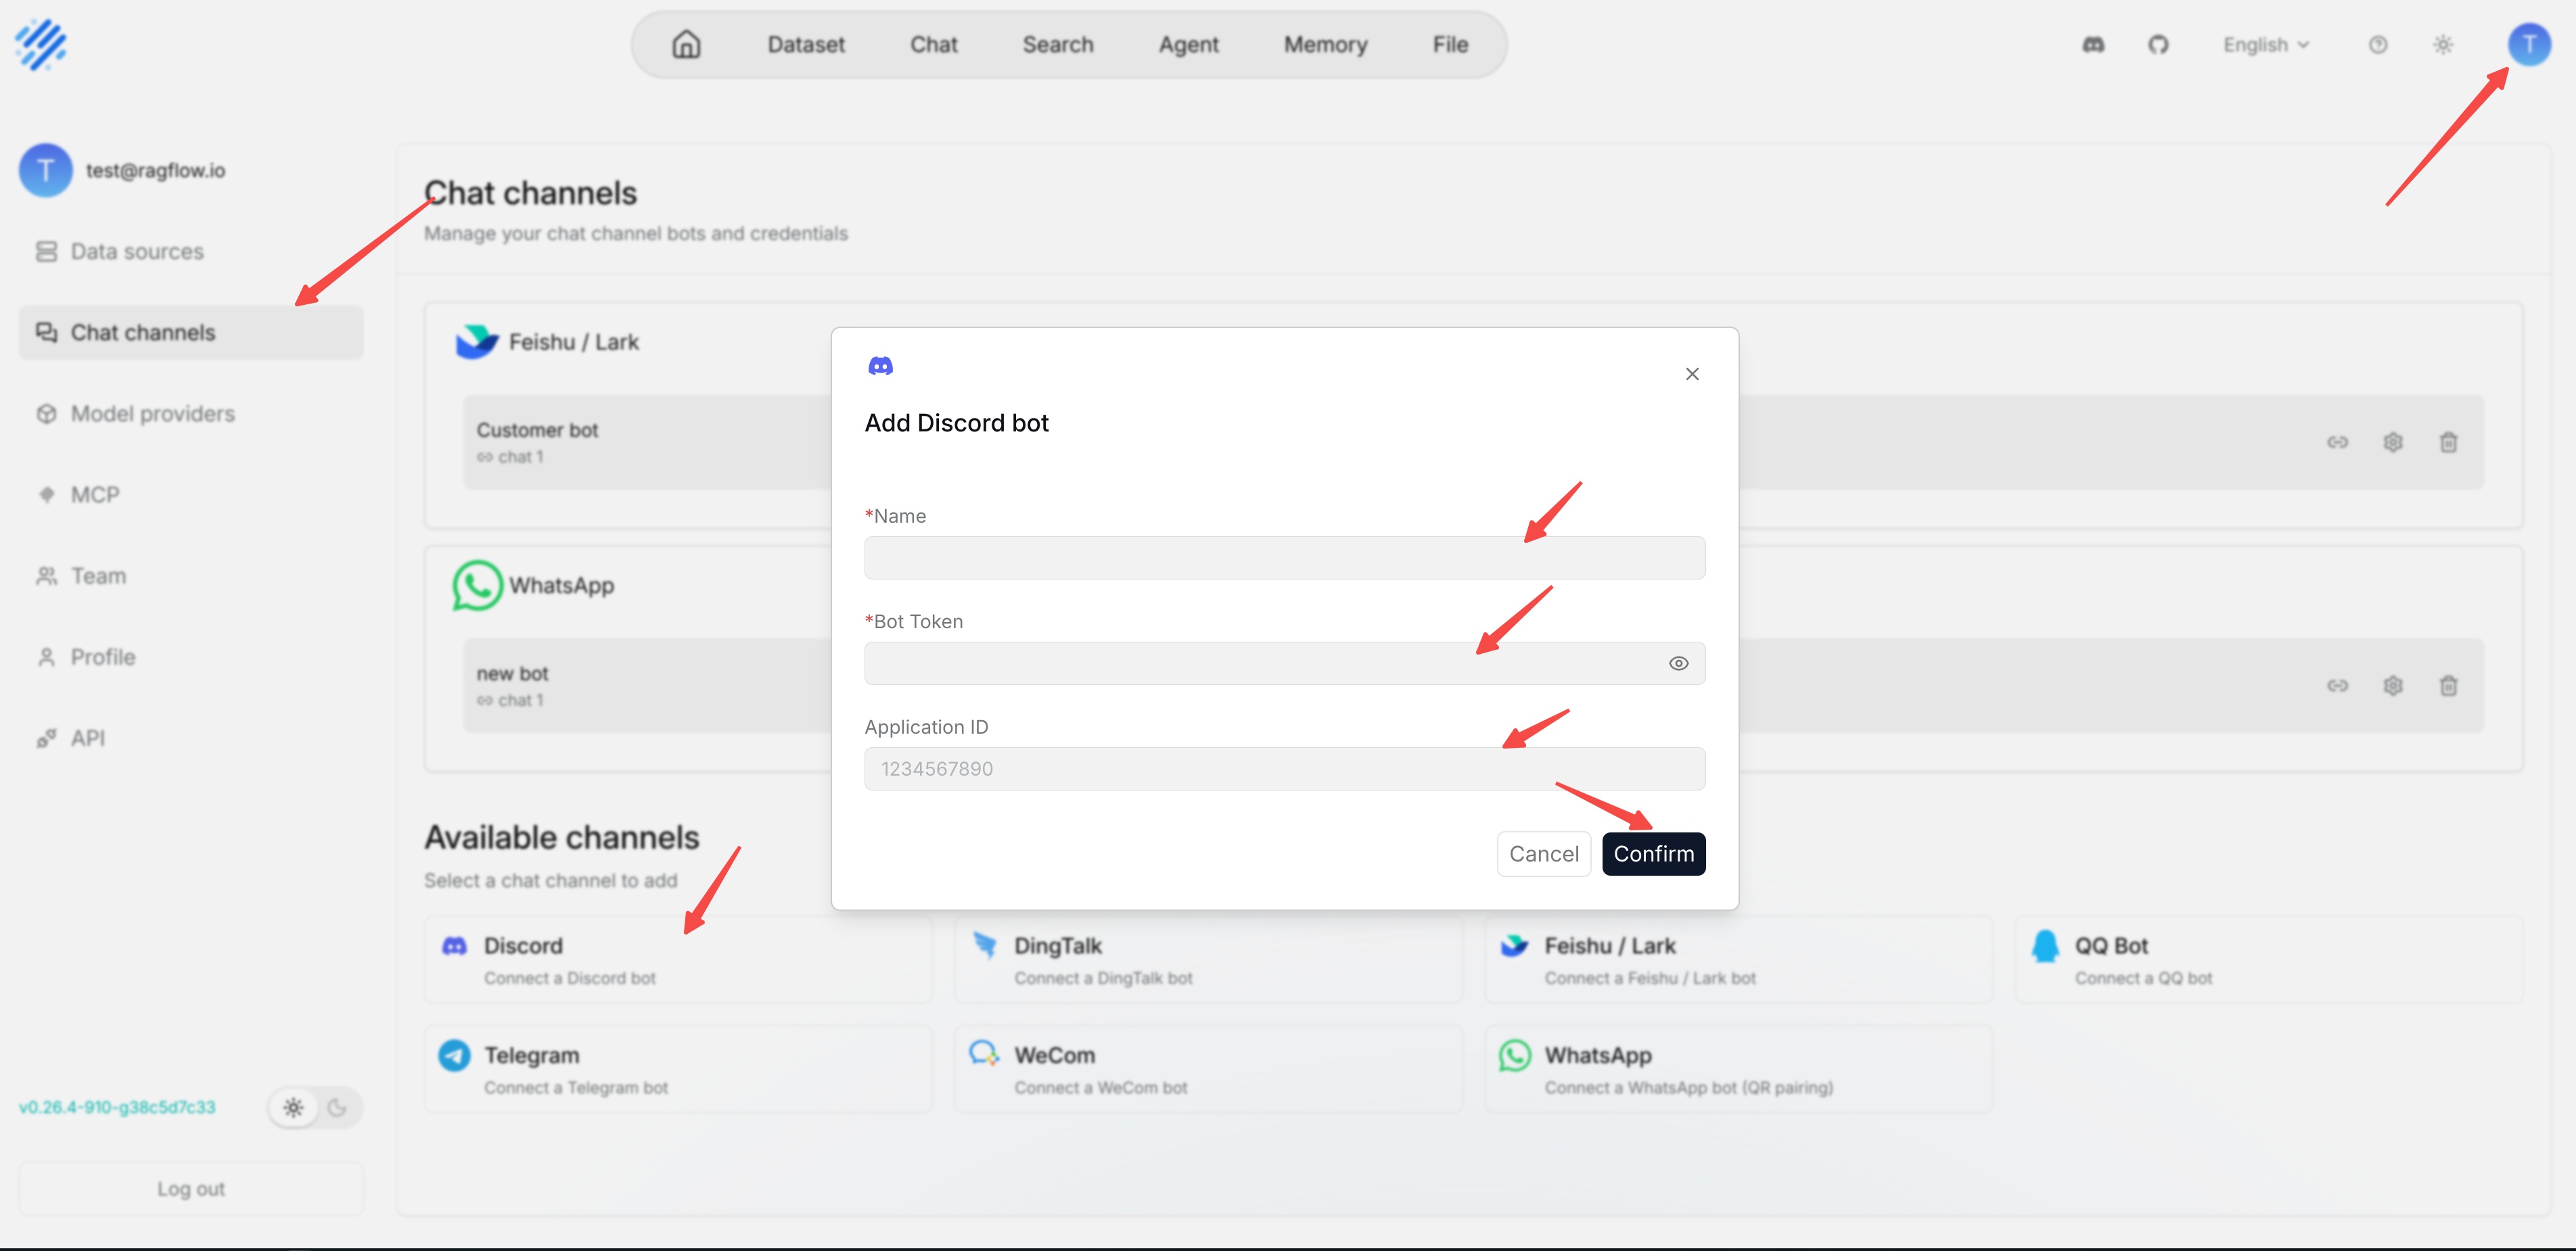+For some platforms, after saving, it may take a few seconds before the page displays the connection status, QR code, or follow-up operation prompts. Follow the page prompts and do not repeatedly create channels before the QR code or status has been generated.After adding a channel, you need to connect it to a Chat. If the channel is enabled but not connected to a Chat, RAGFlow can receive external messages but will not generate replies.diff --git a/docs/guides/chatchannel/connect_chat.md b/docs/guides/chatchannel/connect_chat.mdindex 0bbb791c7c..763e42c148 100644--- a/docs/guides/chatchannel/connect_chat.md+++ b/docs/guides/chatchannel/connect_chat.md@@ -20,4 +20,6 @@ Operation steps:4. Save the configuration.5. Return to the corresponding third-party platform and send a test message to the bot.+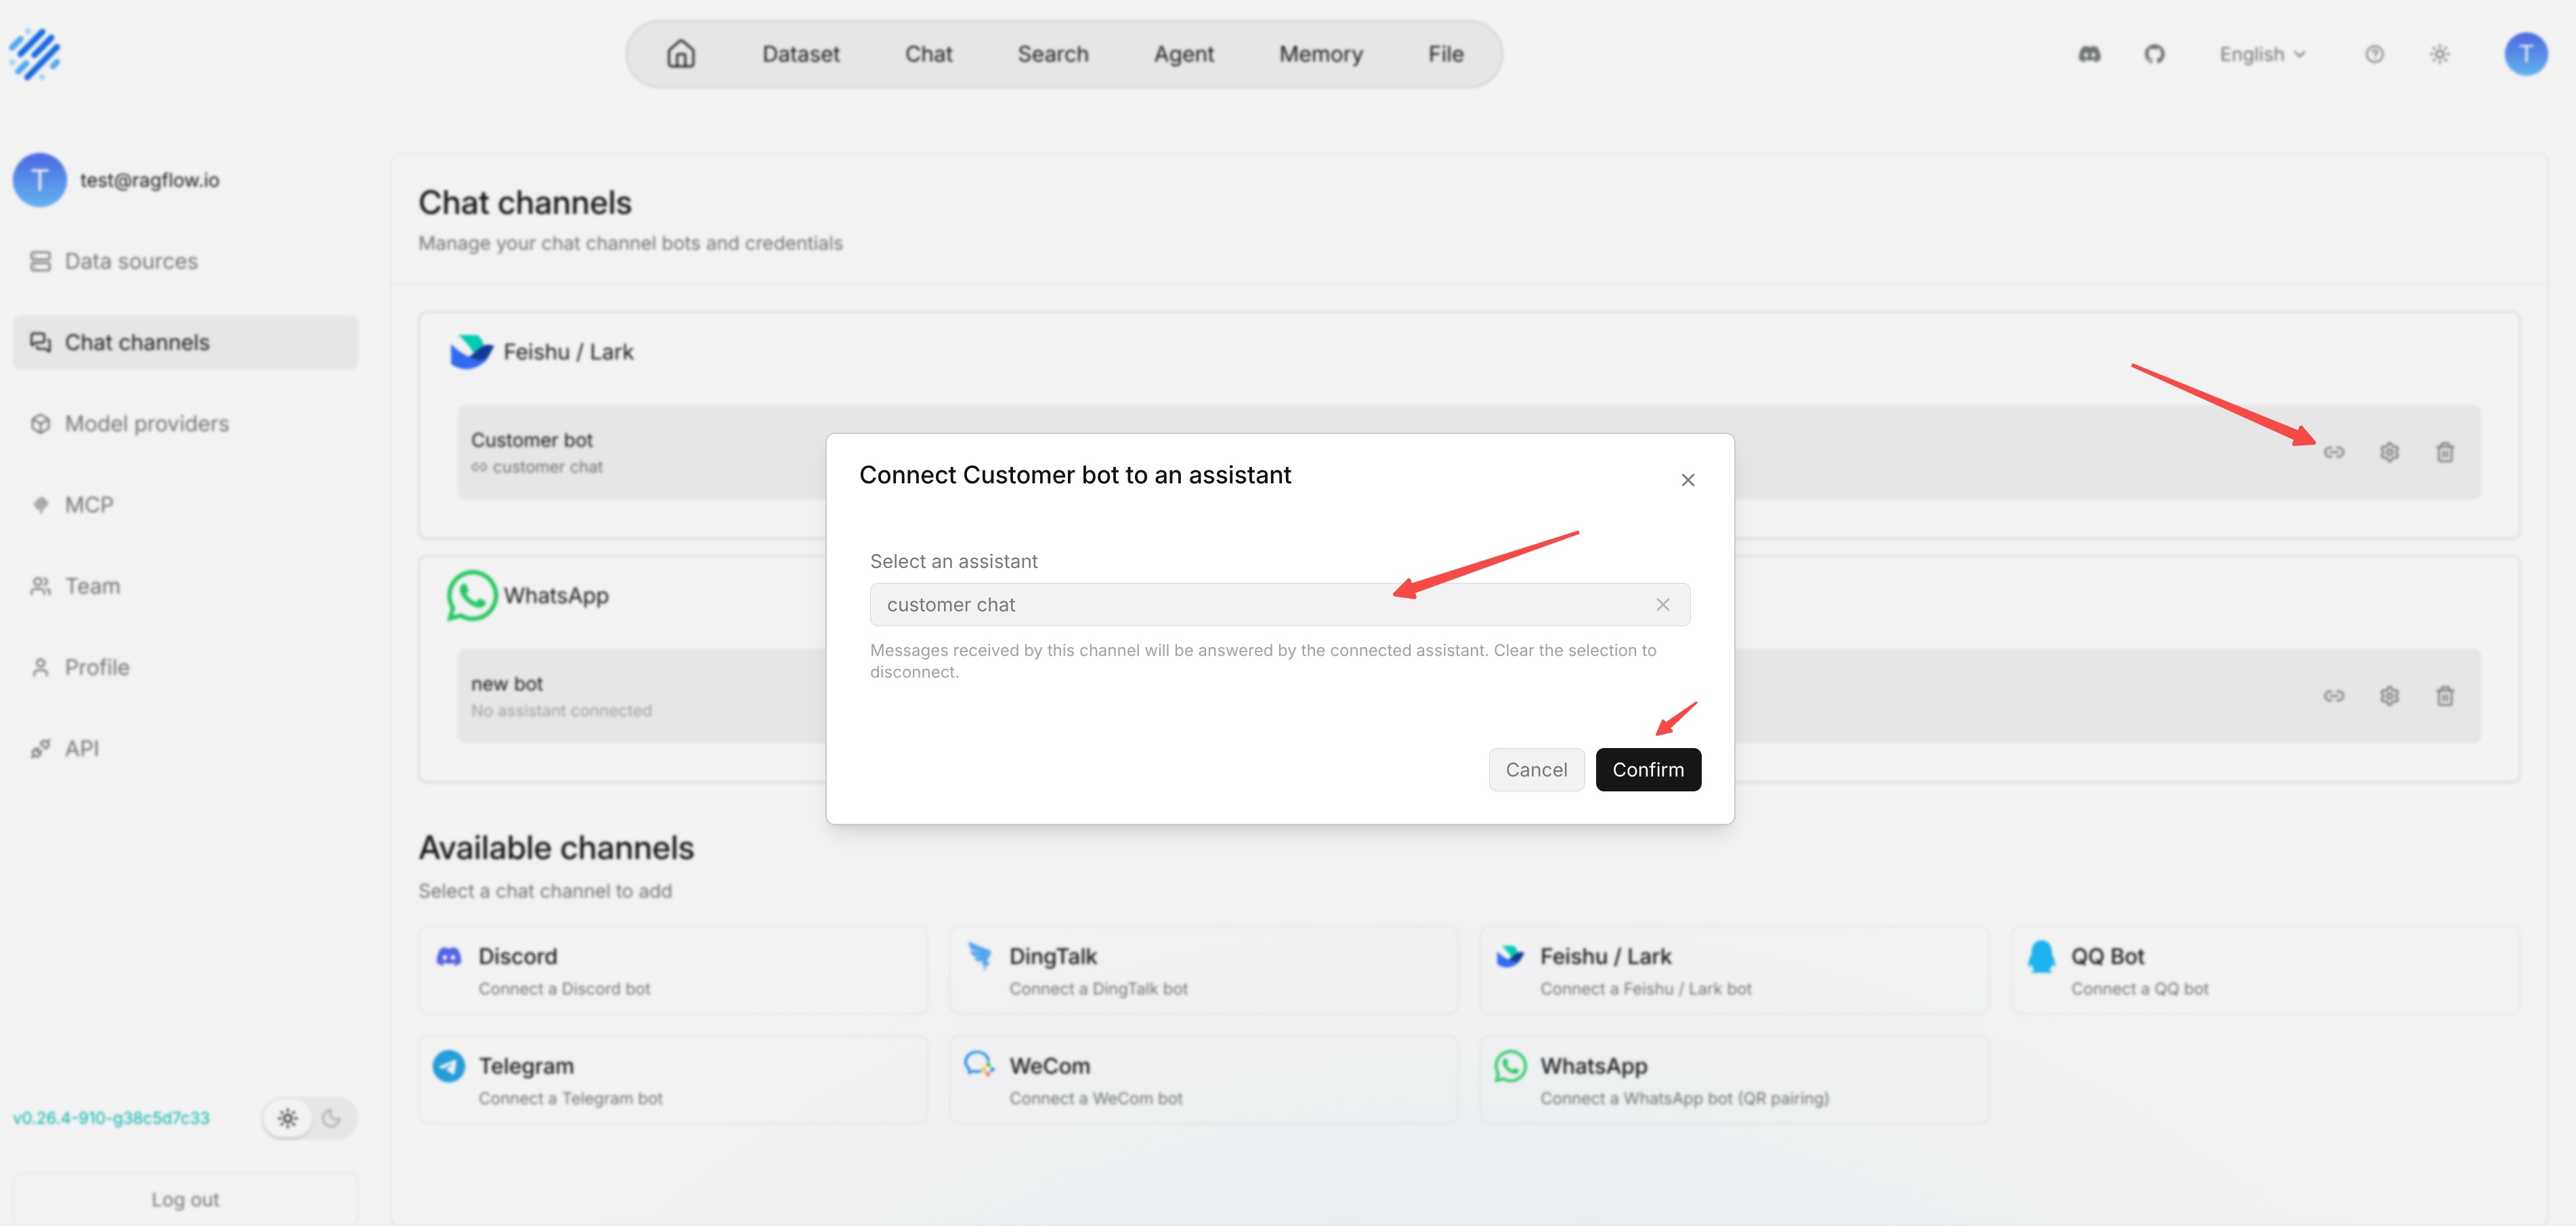+If the test message receives no reply, first check whether the channel has been connected to a Chat. Then check whether the bot is online, whether third-party platform permissions are complete, and whether the Chat itself can answer normally on the RAGFlow page.diff --git a/docs/guides/knowledge_compilation/_category_.json b/docs/guides/knowledge_compilation/_category_.jsonnew file mode 100644index 0000000000..4d6c9edca6--- /dev/null+++ b/docs/guides/knowledge_compilation/_category_.json@@ -0,0 +1,11 @@+{+ "label": "Knowledge Compilation",+ "position": 11,+ "link": {+ "type": "generated-index",+ "description": "Guides on configuring and applying knowledge compilation templates."+ },+ "customProps": {+ "categoryIcon": "LucideWandSparkles"+ }+}diff --git a/docs/guides/knowledge_compilation/apply_knowledge_compilation_template.md b/docs/guides/knowledge_compilation/apply_knowledge_compilation_template.mdnew file mode 100644index 0000000000..fe896437e4--- /dev/null+++ b/docs/guides/knowledge_compilation/apply_knowledge_compilation_template.md@@ -0,0 +1,82 @@+---+sidebar_position: 4+title: Apply a Knowledge Compilation Template+sidebar_label: Apply a Knowledge Compilation Template+slug: /knowledge_compilation/apply_knowledge_compilation_template+sidebar_custom_props: {+ categoryIcon: LucideWandSparkles+}+---++# Apply a Knowledge Compilation Template++## Configure the Ingestion Pipeline++After creating a template, you need to reference the template in an Ingestion Pipeline.++Configuration steps:++1. Create or open an Ingestion Pipeline.+2. Add and connect Parser, Chunker, Compiler, and Indexer.+3. Open CompilerOperator and select the target CompilationTemplate from the template list.+4. Check node connections and required parameters, and then save the Pipeline.++Note: CompilationTemplate only defines "how to compile". A KnowledgeArtifact is generated only after the template is referenced in CompilerOperator and the document actually executes this Pipeline.++## Apply the Pipeline in Dataset++1. Go to the Dataset page and create a Dataset or open an existing Dataset.+2. Upload the documents to process.+3. In the file list, select Configure Ingestion Pipeline.+4. Select the Ingestion Pipeline that contains CompilerOperator.+5. Start parsing and check in the task logs whether Parser, Chunker, Compiler, and Indexer complete in sequence.++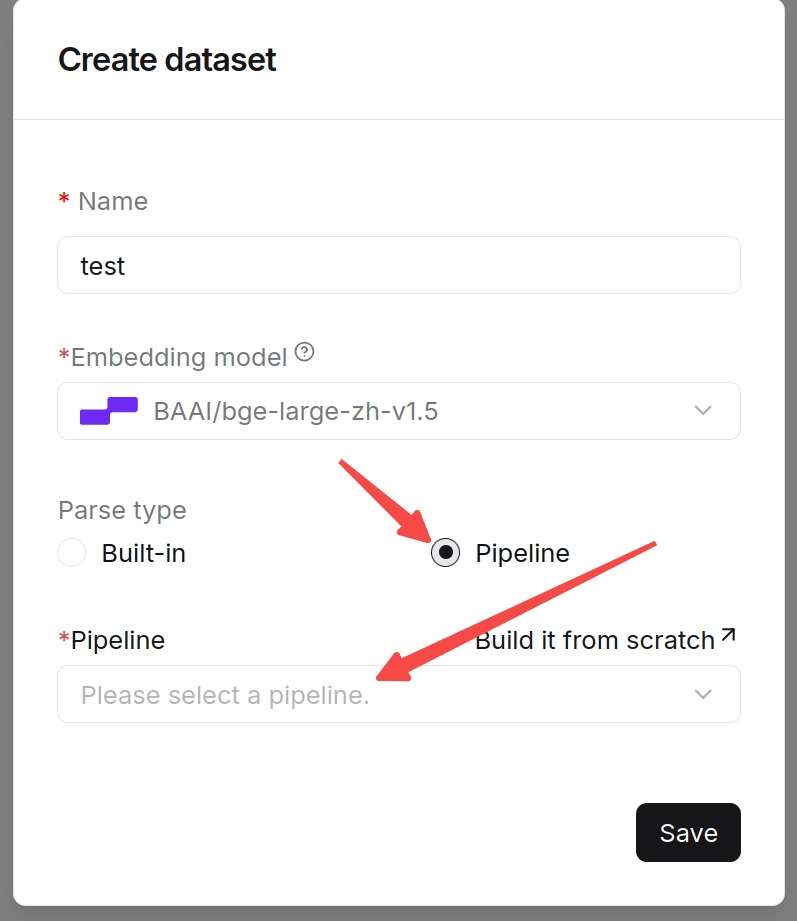++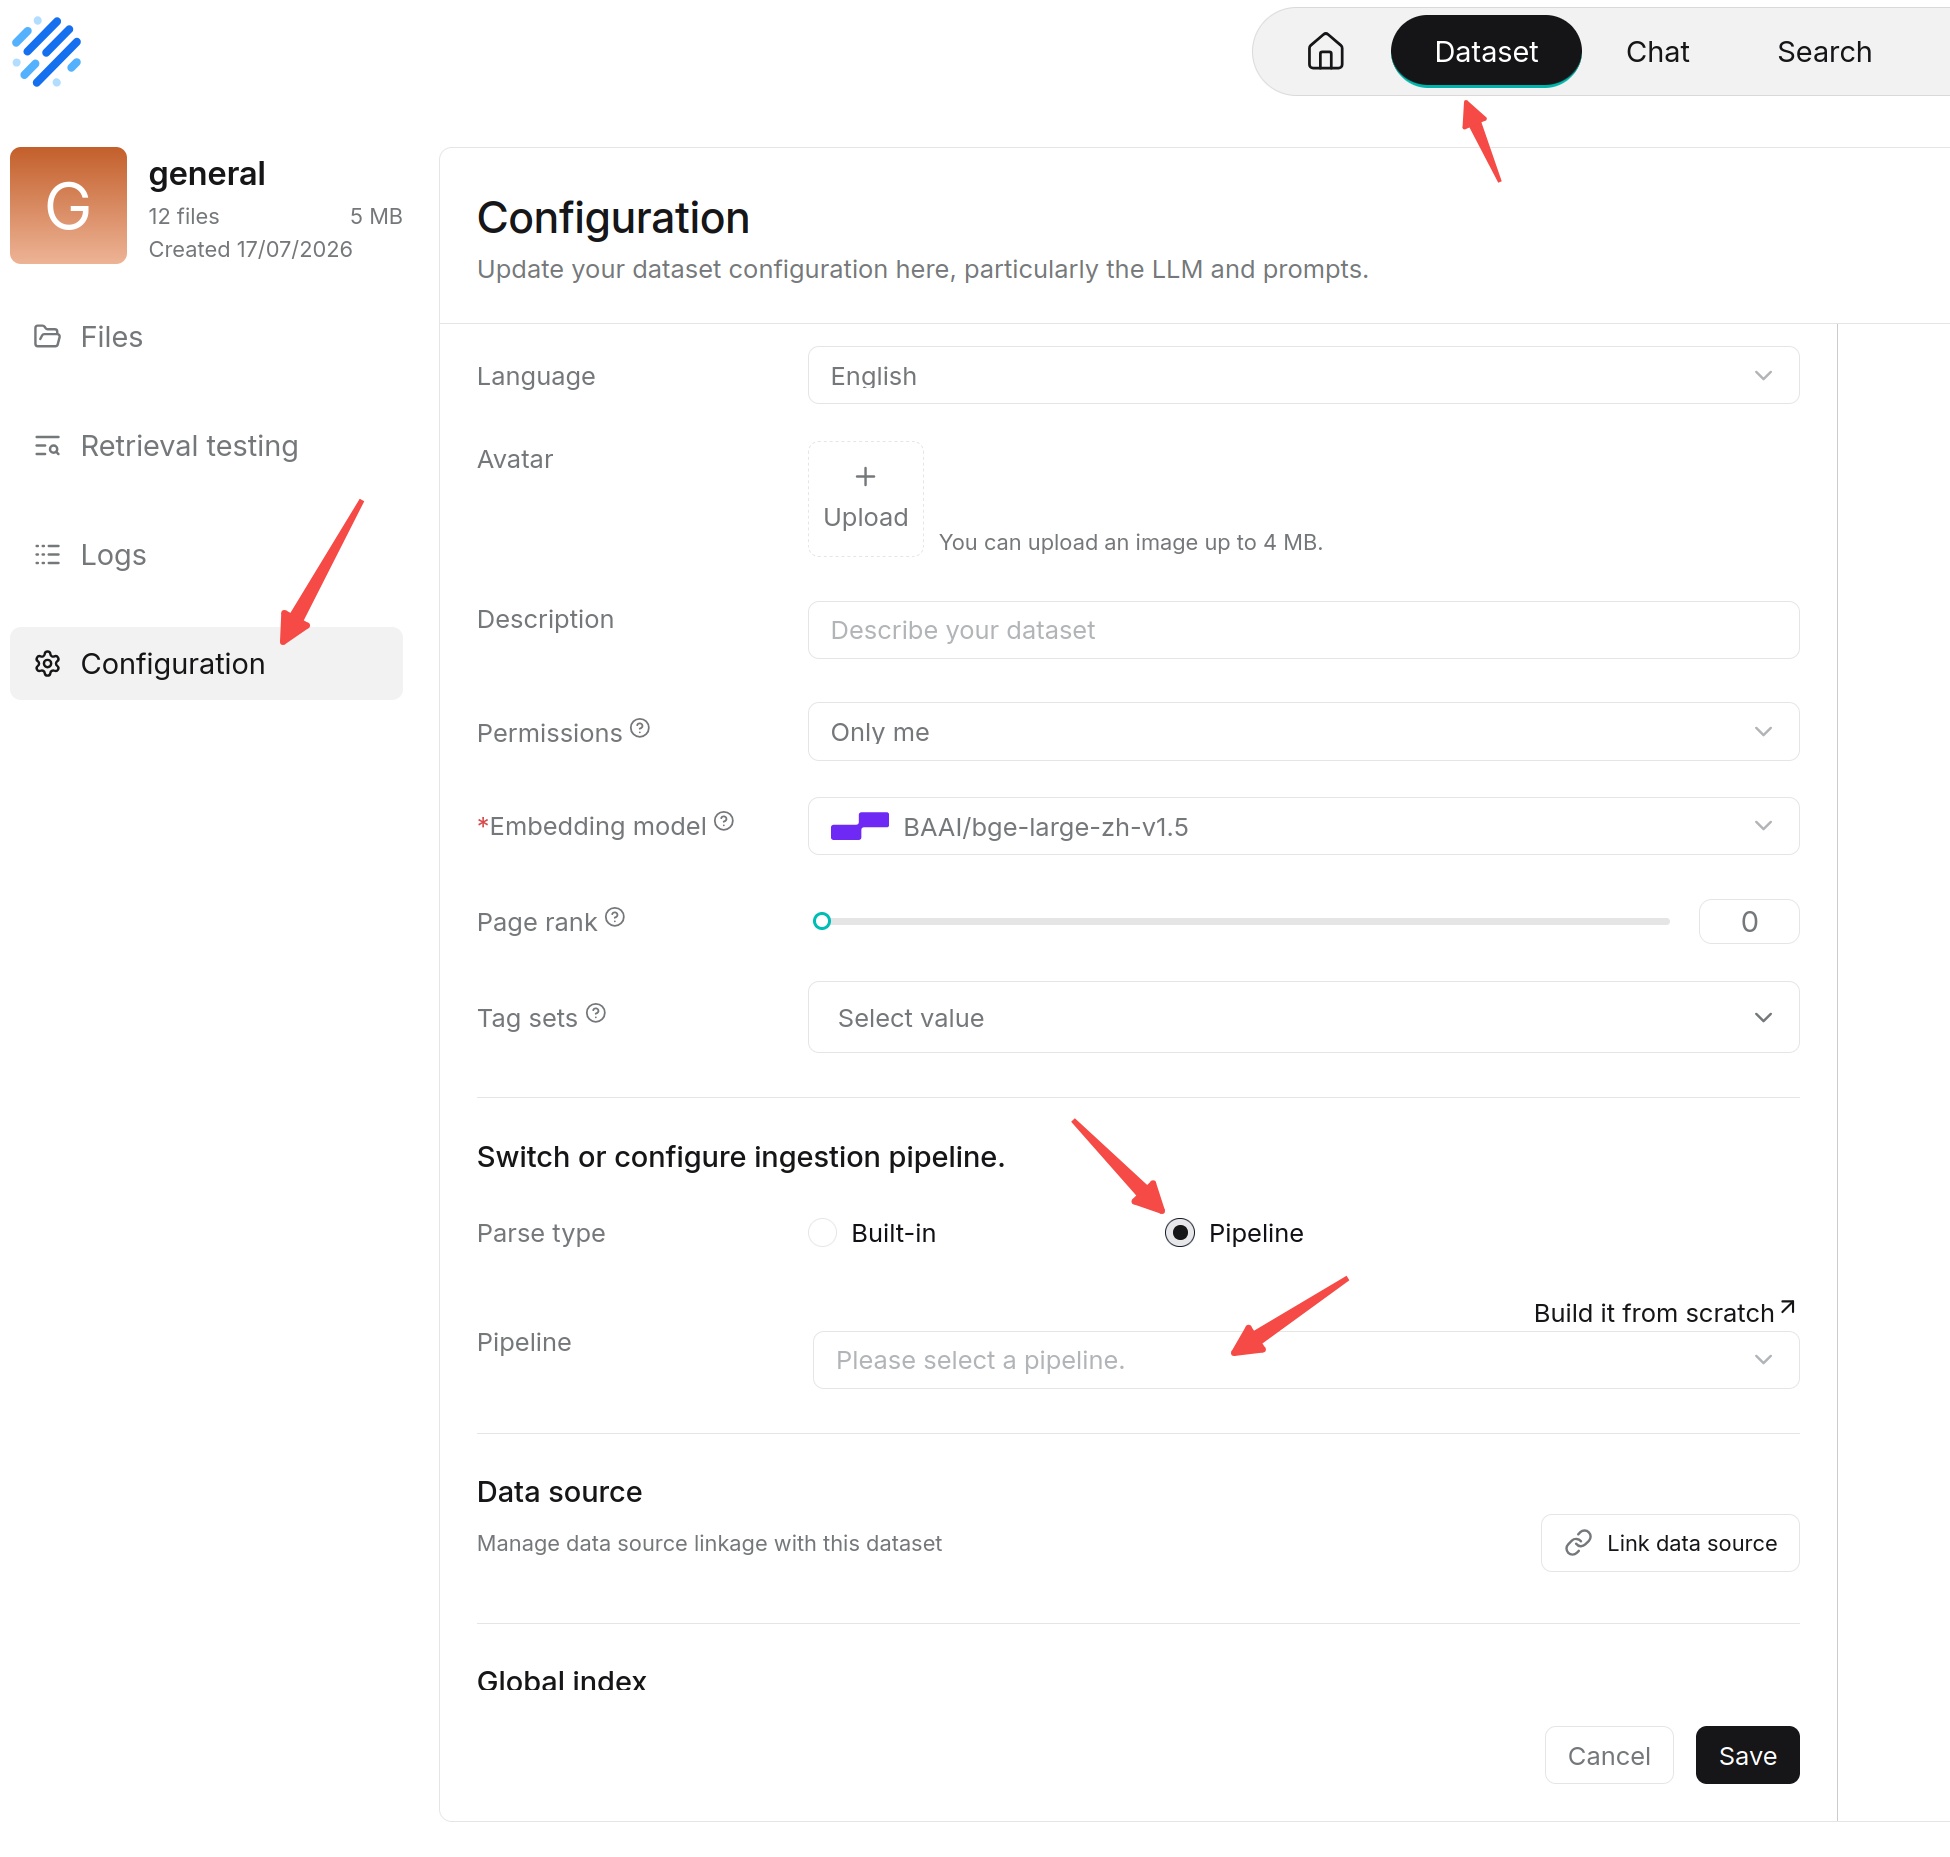++If CompilationTemplate is modified, completed documents are not automatically recompiled. You need to reparse or rerun the Pipeline according to the operations currently provided by the product before the new configuration can be applied.++## View Knowledge Artifacts++After knowledge compilation is complete, enter the corresponding knowledge base and select **Artifacts** from the left sidebar. In the upper-right corner of the Artifacts page, select the artifact type you want to view from the drop-down list, such as **Wiki**, **To Skills**, **Tree/Page index**, **Graph**, **Mind map**, or **Timeline**, to view the corresponding generated results.++Knowledge artifacts can be divided by generation scope into document-level and knowledge-base-level artifacts:++- **Document-level knowledge artifacts**: Graph, Tree, PageIndex, MindMap, and Timeline can generate corresponding document-level results during document knowledge compilation and can be viewed in Artifacts.+- **Knowledge-base-level knowledge artifacts**: Some knowledge artifacts support further generation of knowledge-base-level results based on documents in the knowledge base. After executing a knowledge-base-level generation task, you can view the generated results in Artifacts. Wiki is generated as a knowledge-base-level artifact. After knowledge compilation for related documents is complete, you need to go to the Artifacts page of the knowledge base and click generate. The system then generates Wiki based on the compilation results in the current knowledge base.++Graph can also be further generated as a knowledge-base-level knowledge artifact through knowledge-base-level generation operations after document-level knowledge compilation is complete.++When a knowledge-base-level knowledge artifact generation task is executed, the system generates corresponding knowledge-base-level logs. You can use the logs to view the task execution status and related runtime information. When a generation task fails or the result is abnormal, check it together with the log information.++## Knowledge Artifact Check++After knowledge artifacts are generated, check the generated results based on the template used and confirm whether the content and structure meet expectations.++For different knowledge artifact types, focus on the following checks:++| Type | Check Focus |+| --- | --- |+| Graph | Whether entities are duplicated; whether relationship directions are correct; whether there are unsupported nodes or edges. |+| Tree | Whether the hierarchy is clear; whether peer nodes are at similar abstraction levels; whether summaries are accurate. |+| PageIndex | Whether chapter hierarchy is preserved; whether facts and conclusions come from the corresponding chapters. |+| MindMap | Whether the central topic is clear; whether branches are duplicated or crossed; whether node names are concise. |+| Timeline | Whether time is accurate; whether event order is correct; whether relative time is misinterpreted. |+| Wiki | Whether page topics are reasonable; whether links between pages are valid; whether facts are consistent with sources. |++## Update Knowledge Artifacts++After knowledge artifacts are generated, the system continuously detects document changes in the knowledge base. When documents are added to or removed from the knowledge base, the corresponding knowledge artifacts are not automatically regenerated. Instead, an update prompt is displayed to remind users to synchronize the latest knowledge base content.++When document changes are detected, an **Update** button appears in the upper-left corner of the knowledge artifact page, and the number of documents to update is displayed next to the button.++Hover over the update prompt area to view the specific document changes:++- **New documents**: Documents uploaded to the knowledge base after the knowledge artifact was generated and not yet included in the current knowledge artifact.+- **Removed documents**: Documents deleted from the knowledge base after the knowledge artifact was generated, but whose related content has not yet been synchronized and removed from the current knowledge artifact.+- **Number indicator**: Indicates the current number of documents detected as pending update.++After confirming that synchronization is needed, click **Update**. The system updates the knowledge artifact based on the current document changes in the knowledge base, keeping it consistent with the latest documents in the knowledge base.++Note: Uploading or deleting knowledge base documents alone does not immediately update existing knowledge artifacts. After the update prompt appears, you need to manually click **Update** to complete synchronization.diff --git a/docs/guides/knowledge_compilation/basic_information_configuration.md b/docs/guides/knowledge_compilation/basic_information_configuration.mdnew file mode 100644index 0000000000..4a0e5ff407--- /dev/null+++ b/docs/guides/knowledge_compilation/basic_information_configuration.md@@ -0,0 +1,58 @@+---+sidebar_position: 2+title: Basic Information Configuration+sidebar_label: Basic Information Configuration+slug: /knowledge_compilation/basic_information_configuration+sidebar_custom_props: {+ categoryIcon: LucideWandSparkles+}+---++# Basic Information Configuration++When creating or editing a knowledge compilation template, you need to complete the basic information configuration first. Basic information determines the template name, the model used, and the basic compilation method. All knowledge compilation template types include these configuration items.++## Template Name++Sets the name of the knowledge compilation template so different templates can be identified during later configuration and use. It is recommended to name the template based on its actual purpose so that the name clearly reflects the usage scenario.++## Template Description++The template description explains the function, applicable scenarios, and main processing content of the current template, making later viewing and management easier.++## Default Extraction Model++The default extraction model specifies the model used during knowledge compilation. The system uses this model to understand and analyze document content, and completes information extraction and structured generation according to the rules defined in the template.++Select an appropriate model based on actual business requirements and model capabilities. You can refer to the related description in the "Template Selection Recommendations" section.++## Template++Selects the knowledge artifact type to generate through knowledge compilation. The following templates are currently supported:++- Graph+- Tree+- PageIndex+- MindMap+- Timeline+- Wiki++Different templates correspond to different knowledge organization methods and configuration items. After selecting a template, you can continue configuring the parameters for that template. The template is used to select the template type used by the knowledge compilation task.++## Global Rules++Sets the requirements that the current knowledge compilation template must follow uniformly during execution.++The content controlled by global rules differs between templates. For example, Graph can use global rules to constrain entity and relationship extraction, while Wiki can use global rules to control content organization and generation requirements. For specific configuration methods, refer to the corresponding template chapter.++## Re-Split Parser Output++Controls whether Compiler reorganizes and splits Parser output before executing knowledge compilation.++After this option is enabled, Compiler reorganizes Parser output based on the processing requirements of the current knowledge compilation template before executing subsequent knowledge compilation. If disabled, compilation is performed directly based on Parser output.++This setting only affects the knowledge compilation process and does not replace Chunker in the Ingestion Pipeline.++Whether this feature is enabled must be determined when configuring the knowledge compilation template. After the template is saved, the setting takes effect when the template is used for knowledge compilation.++diff --git a/docs/guides/knowledge_compilation/built_in_templates_and_dedicated_configuration.md b/docs/guides/knowledge_compilation/built_in_templates_and_dedicated_configuration.mdnew file mode 100644index 0000000000..c8baba2d10--- /dev/null+++ b/docs/guides/knowledge_compilation/built_in_templates_and_dedicated_configuration.md@@ -0,0 +1,529 @@+---+sidebar_position: 3+title: Built-In Templates and Dedicated Configuration+sidebar_label: Built-In Templates and Dedicated Configuration+slug: /knowledge_compilation/built_in_templates_and_dedicated_configuration+sidebar_custom_props: {+ categoryIcon: LucideWandSparkles+}+---++# Built-In Templates and Dedicated Configuration++## Graph++Graph extracts entities and relationships from documents, helping users build a knowledge network in the document. Users can configure the Graph template to define the entity types, relationship types, and extraction rules that need to be recognized. Based on the configuration, the system identifies and associates key information in documents to generate the corresponding knowledge graph.++Graph configuration mainly includes:++- Global rules+- EntitySpecification+- RelationSpecification+- Re-splitting Parser output++### Global Rules++Global rules set general requirements for the knowledge graph extraction process and apply to the current Graph template. Users can enter global rules to supplement the entity recognition scope, relationship extraction requirements, naming conventions, and other restrictions.++Configuration recommendations:++- Describe the entities and relationships that need focused attention based on the business scenario.+- Avoid overly broad rules to reduce invalid entity generation.+- For professional domain documents, supplement domain-specific constraints through rules.++Example: Extract only core people, organizations, products, and key events from the document. Keep entity names complete and do not generate entities that cannot be confirmed.++### EntitySpecification++EntitySpecification defines the entity types that need to be recognized in the knowledge graph. Click an entity type card to enter the entity configuration page.++Configuration items:++| Configuration Item | Description |+| --- | --- |+| Type | Entity type name, used to identify the current entity category. |+| Description | Describes the object scope corresponding to this entity type. |+| Rule | Defines entity extraction requirements, such as recognition scope, naming conventions, and restrictions. |++The system provides the following default node types:++| Entity Name | Description |+| --- | --- |+| person | Person entity, used to represent natural persons or specific individuals, such as authors, employees, customers, historical figures, and similar entities. |+| org | Organization entity, used to represent companies, institutions, departments, associations, or other organizational groups. |+| product | Product entity, used to represent specific products, services, software, solutions, or other business offerings. |+| regulation | Regulation entity, used to represent laws, policies, standards, specifications, guidance documents, or regulatory documents. |+| location | Location entity, used to represent geographic locations, including countries, cities, addresses, regions, or natural geographic entities. |+| other | Other entity, used to represent business-meaningful entity objects that do not belong to the categories above. |++### RelationSpecification++RelationSpecification defines the entity relationship types that need to be recognized in the knowledge graph. The system provides some preset relationship types to cover common entity association scenarios. Users can adjust relationship types based on business requirements.++Users can:++- Edit existing relationship types.+- Delete unnecessary relationship types.+- Add custom relationship types.++Click a relationship type card to enter the relationship configuration page.++Configuration items:++| Configuration Item | Description |+| --- | --- |+| Type | Relationship type name, used to identify the current relationship category. |+| Description | Describes the entity association method represented by this relationship. |+| Rule | Supplements relationship extraction requirements, such as relationship direction, applicable scope, and restrictions. |++The system provides the following default relationship types:++| Relationship Name | Description |+| --- | --- |+| owns | Ownership relationship, used to indicate ownership or possession between entities, such as a person owning assets or an enterprise owning products. |+| part_of | Composition relationship, used to indicate composition or inclusion between entities, such as a component belonging to a product or a department belonging to an organization. |+| caused_by | Causal relationship, used to indicate that an event, action, or state is caused by other factors. |+| regulates | Regulatory relationship, used to indicate that laws, standards, or specifications constrain, manage, or guide entities. |+| located_in | Location relationship, used to indicate location associations between entities, such as a company located in a city or a building located in a region. |+| other | Other relationship, used to represent valuable entity relationships that cannot be classified into the categories above. |++### Configuration Recommendations++To improve knowledge graph extraction results, follow these principles:++- Select entity types and relationship types that require attention based on business requirements.+- Delete default configurations that have no practical use to reduce invalid information extraction.+- Keep entity type names and descriptions clear, and avoid using multiple types to represent similar concepts.+- Relationship types should have clear meanings and avoid overly broad definitions.+- For complex business scenarios, add extra constraints through the rule field.++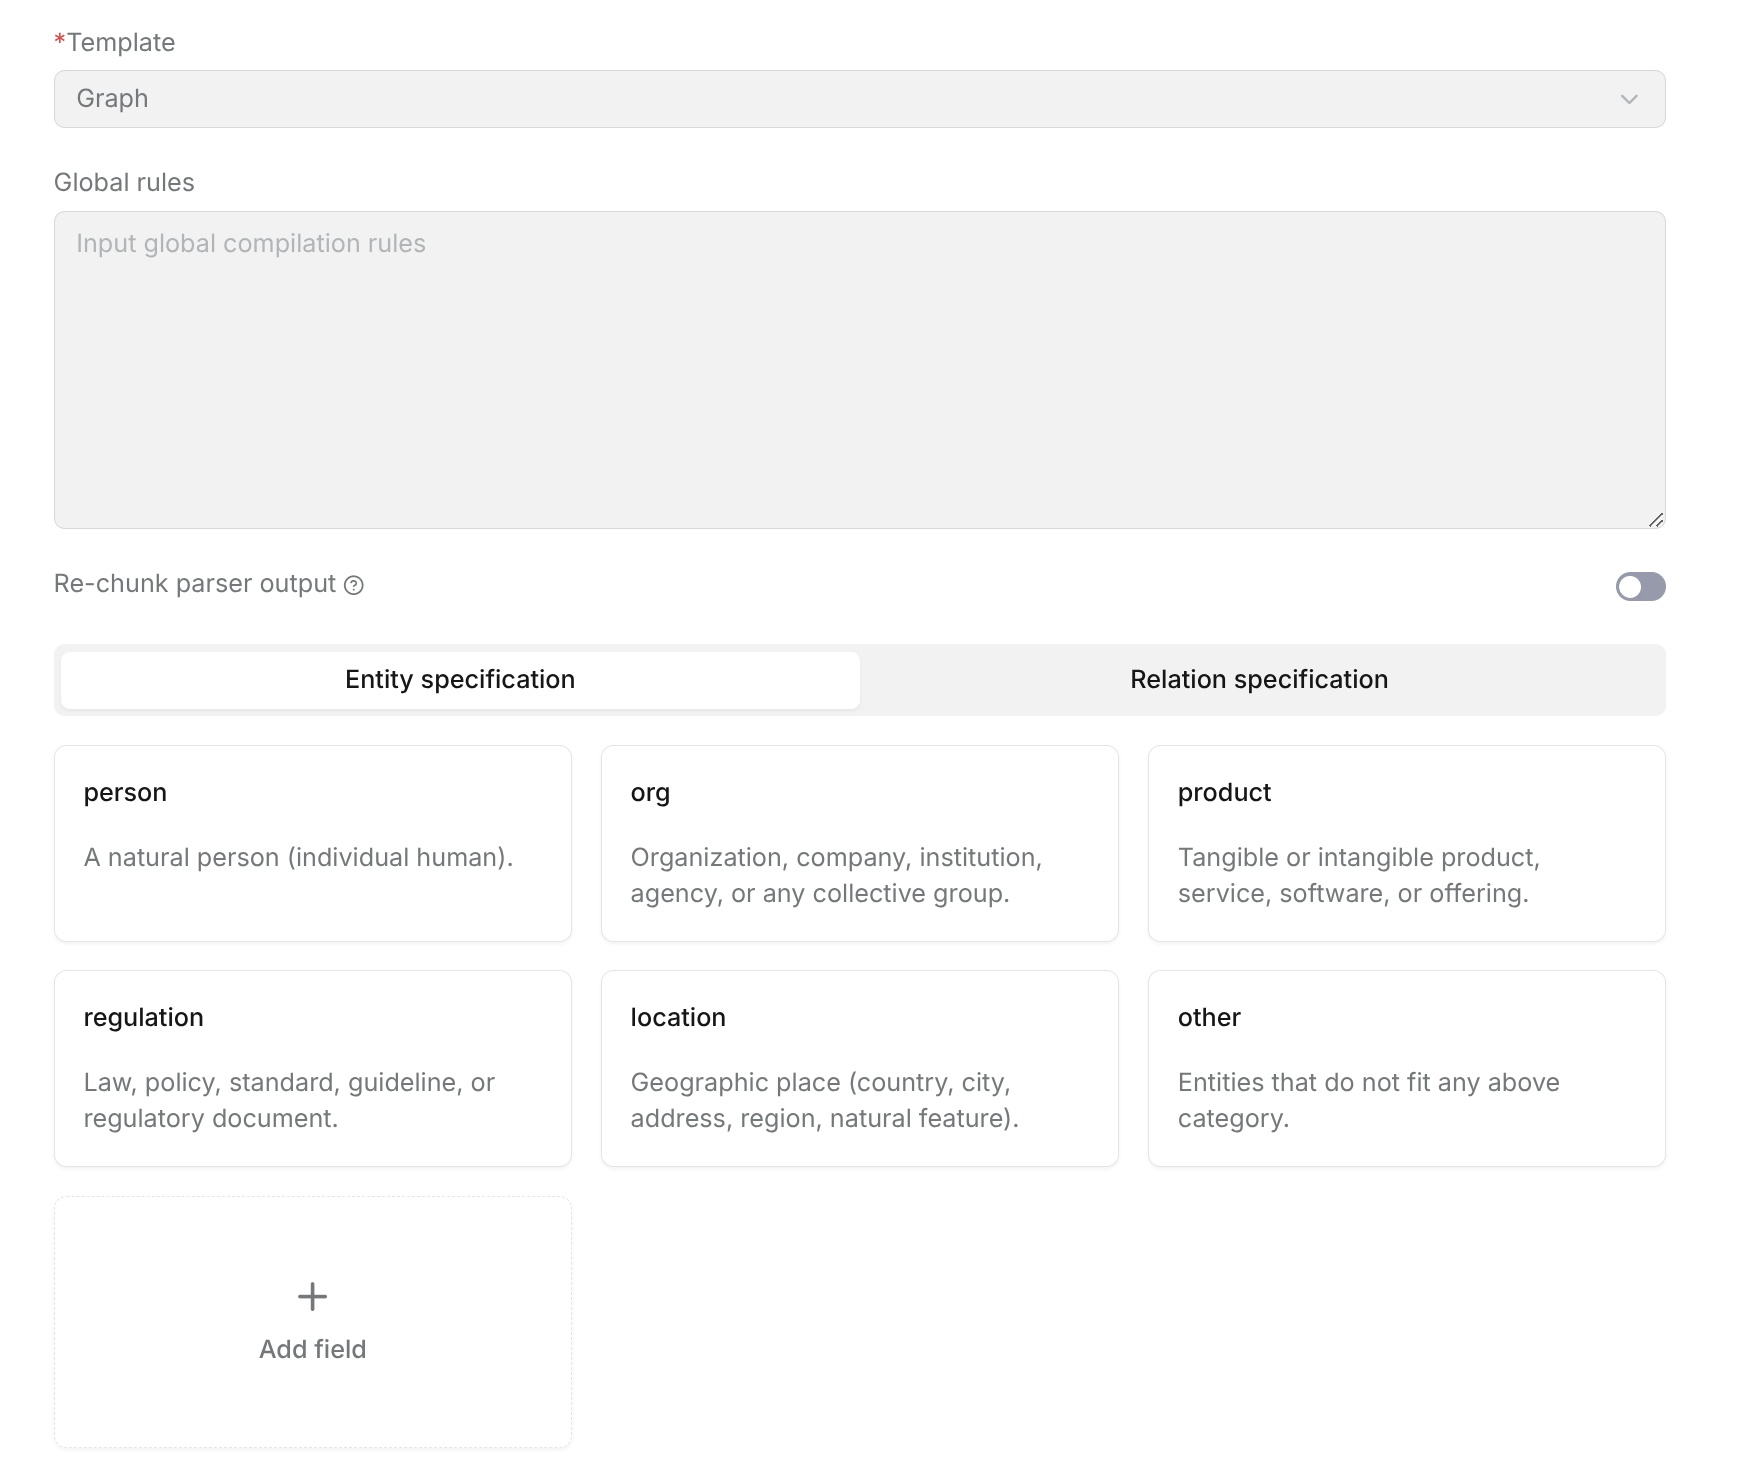++## Tree++The Tree template controls the final knowledge tree generation result mainly through summary rules, summary length, content clustering, and tree structure parameters.++### Global Rules++Global rules set the overall requirements that the Tree template should follow when generating structures and summaries. Users can use global rules to supplement the document processing direction, such as specifying information types to focus on, summary generation methods, or content organization requirements.++Configuration recommendations:++- Set content that requires focused attention based on document characteristics.+- For specific business scenarios, supplement additional content extraction requirements.+- Avoid overly broad or complex rules to ensure the generated results meet expectations.++Example: Summarize the main topics, key events, and important information in the document. Keep the content accurate and do not add information that does not appear in the document.++### Summary Prompt++Sets the generation rules for node summaries and controls the information and output format the system focuses on when summarizing each node. Users can adjust the summary direction based on actual requirements, such as emphasizing key content, core conclusions, or important information.++### Maximum Tokens++Sets the maximum length for node summary generation. A larger value can preserve more summary information and is suitable for more complex documents. A smaller value can generate more concise summaries and is suitable for quickly viewing a document overview.++### Clustering Threshold++Adjusts the matching degree during document content clustering and affects how related content is merged into the same topic node. Increasing this parameter makes content division stricter and usually generates more detailed topic nodes. Decreasing this parameter merges more related content together, making the structure more concentrated.++### Clustering Ratio++Adjusts the content clustering ratio in the Tree structure and affects the number of final hierarchy levels and the structure detail. Increasing this parameter usually generates a richer hierarchy. Decreasing this parameter can reduce the number of nodes and make the overall structure more concise.++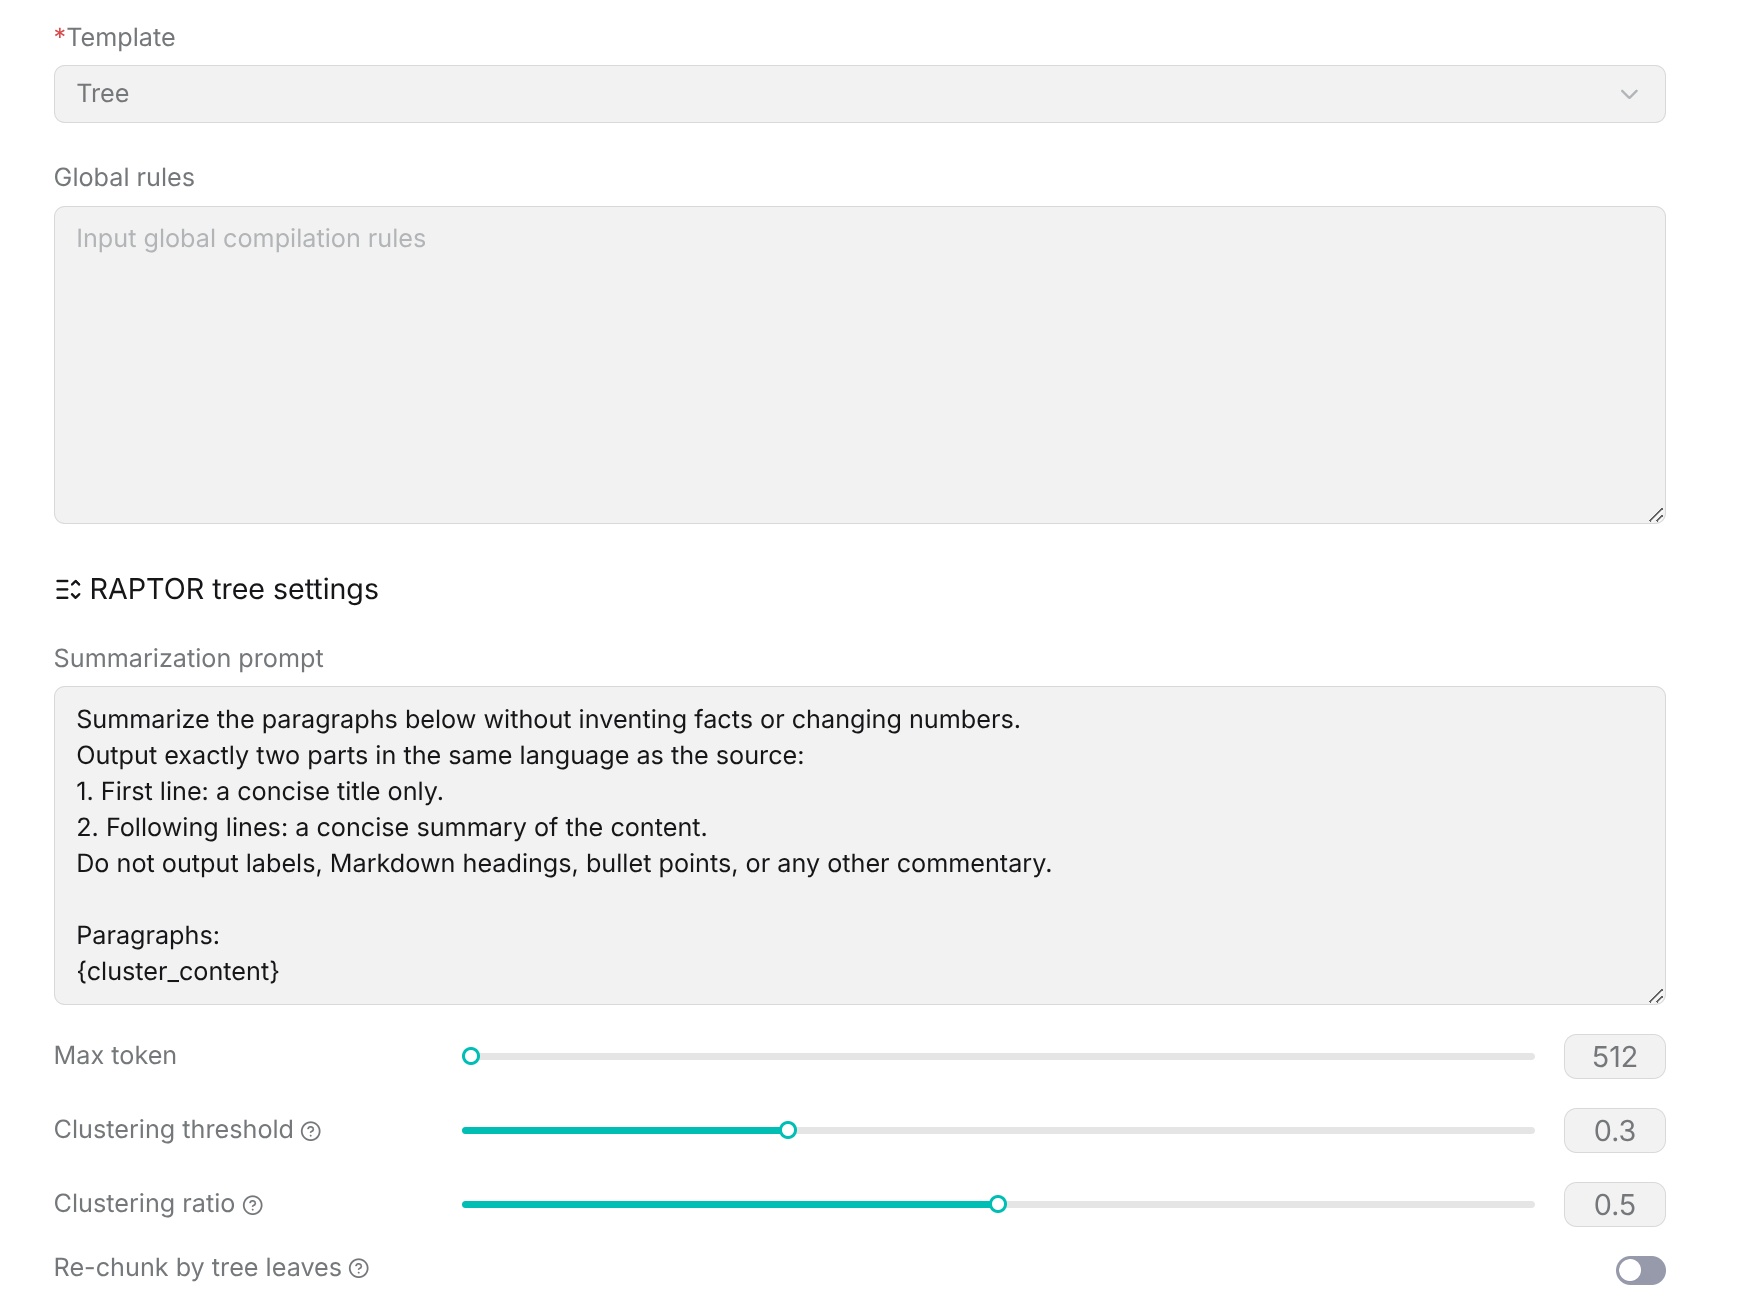++## PageIndex++PageIndex generates a hierarchical index based on the chapter structure in a document, helping users quickly locate document content. This template is suitable for documents with clear title hierarchies, such as books, reports, and specification documents.++By configuring entity fields and relationship rules, PageIndex can extract chapter titles, key facts, and summary content from documents, and establish hierarchical relationships between chapters.++### Global Rules++Global rules define general requirements that must be followed during PageIndex content extraction, such as chapter recognition scope, content extraction specifications, and index generation rules.++Configuration recommendations:++- Preserve the original chapter structure of the document and generate an index according to the title hierarchy in the document.+- Prefer the original chapter titles as index node names.+- Extract only key information related to each chapter topic and avoid generating irrelevant content.+- For content without clear titles, it is not recommended to force-generate chapter nodes.++### EntitySpecification++EntitySpecification defines the content fields that PageIndex needs to extract. Different fields record different types of information in chapters. Users can adjust the default fields provided by the system based on requirements, or add new fields.++Field configuration parameters:++| Parameter Name | Description |+| --- | --- |+| Type | Field type, used to specify the information type to extract for the current field, such as title, fact, or conclusion. |+| Description | Field description, used to explain the specific content that needs to be extracted for this field, helping the system understand the field meaning and extraction scope. |+| Rule | Field rule, used to further constrain how content is extracted, including content format, length, extraction scope, and other requirements. |++The system provides the following default fields:++| Field Name | Description |+| --- | --- |+| title | Title field, used to extract titles or chapter names from the document. The title content should preserve the original text and should not include page numbers, numbering, or other irrelevant symbols. |+| fact | Fact field, used to extract key facts, rules, definitions, or explanatory content related to the current chapter, reflecting the core information of the chapter. |+| conclusion | Conclusion field, used to extract summaries, analysis results, or important conclusions from the chapter, supplementing the chapter's core viewpoints. |++### RelationSpecification++RelationSpecification defines relationships between different chapter nodes. PageIndex uses the include relationship by default to represent inclusion between chapters, for example:++- A document contains chapters.+- A chapter contains subchapters.++Through this relationship, the system can generate a hierarchical index based on the original document structure.++Configuration parameters:++| Parameter | Description |+| --- | --- |+| Type | Relationship type, used to define the association method between entities. The current supported type is include, which indicates an inclusion relationship. |+| Description | Describes the meaning of the relationship and helps the model understand the association rules between two entities. |+| Rule | Further constrains relationship extraction logic, including relationship direction, applicable scope, and entity connection requirements. |++The system provides the following default relationship type:++| Relationship Name | Description |+| --- | --- |+| conclusion | Conclusion relationship, used to represent findings, results, or conclusion information extracted based on document content. |++Configuration recommendations:++- Keep the hierarchical relationships between chapters consistent with the original structure.+- Avoid adding associations without clear hierarchical evidence.+- For documents with simple structures, you can directly use the default relationship configuration.++### Configuration Description++The PageIndex template is already configured with basic fields and relationship rules by default. Users can adjust them based on actual business requirements.++Supported operations:++- Edit field descriptions to optimize the content extraction scope.+- Add new entity fields to extend index information.+- Delete unnecessary fields to reduce invalid content generation.+- Modify relationship rules to adjust associations between chapters.++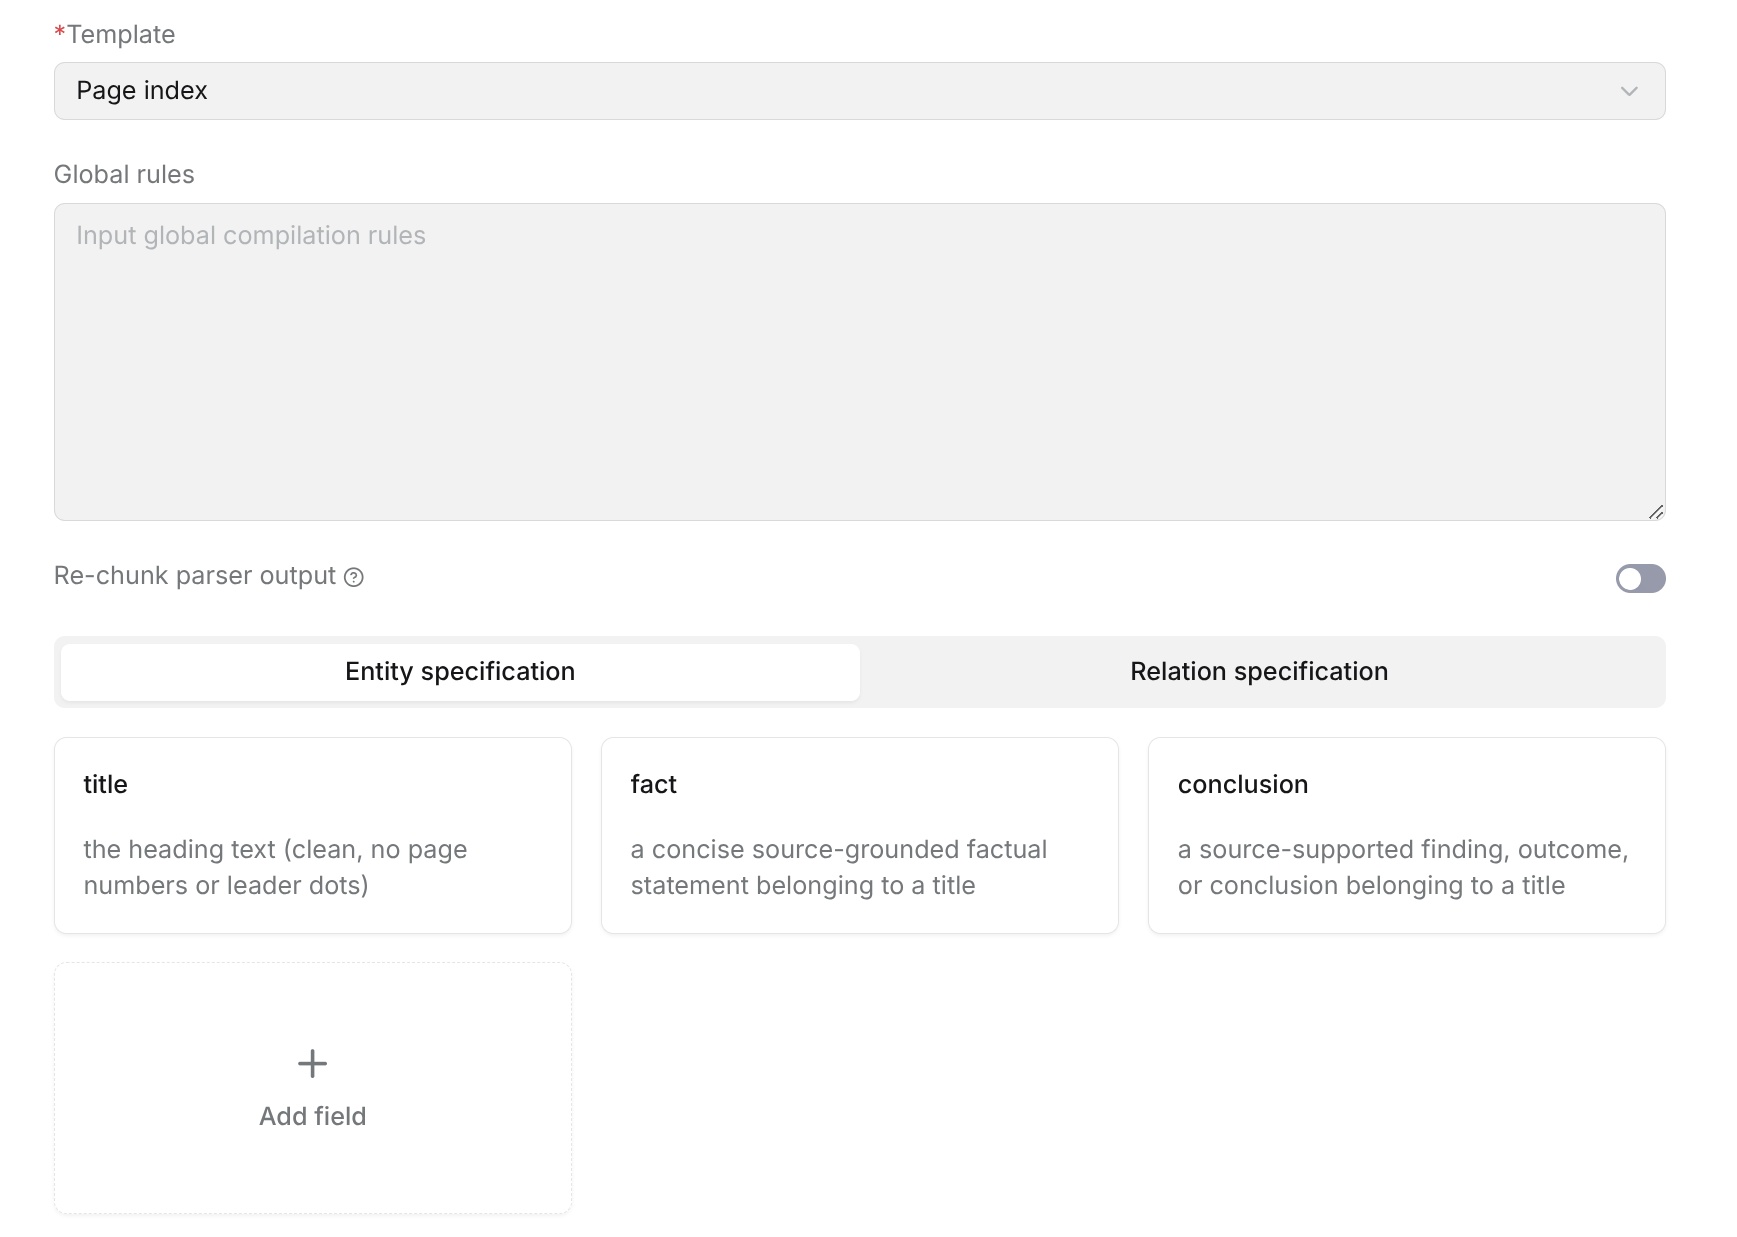++## MindMap++MindMap generates a hierarchical structure around the core topic of a document, displaying content relationships through a central topic, branches, and keywords. It helps users quickly understand the main content, knowledge structure, and concept relationships of a document.++### Global Rules++Global rules define the overall requirements for mind map generation, including topic extraction, hierarchical organization, and node naming conventions.++Configuration recommendations:++- Generate a mind map around the core content of the document and prioritize extracting main topics.+- Use important topics as first-level branches and expand related details as lower-level branches.+- Keep node names concise and avoid using complete sentences as nodes.+- Maintain clear hierarchical relationships and avoid duplicate or circular references.+- Keep node language consistent with the original text.++### EntitySpecification++EntitySpecification defines the node types in the mind map. Different node types correspond to information content at different levels. Users can adjust the default nodes provided by the system based on business requirements, including deleting existing nodes or adding custom nodes.++When configuring nodes, the main parameters are as follows. The system provides the following default node types:++| Node Name | Description |+| --- | --- |+| CentralTopic | Core topic node, used to represent the main topic of the document or content as the center node of the mind map. |+| Branch | First-level branch node, used to represent the main directions, categories, or knowledge domains expanded around the core topic. |+| Sub-branch | Second-level branch node, used to represent specific concepts, tasks, cases, or detailed content under Branch. |+| Keyword | Keyword node, used to supplement other nodes with key concepts or core information. |++### RelationSpecification++RelationSpecification defines the relationships between different nodes in the mind map and describes the hierarchy and content associations between nodes. The system uses relationship definitions to determine how nodes are connected, such as inclusion between the core topic and branches, or support relationships between branches and keywords.++| Parameter Name | Description |+| --- | --- |+| Type | Node type name, used to identify the role of the current node in the mind map. |+| Description | Describes the information content that this node needs to extract, helping the system understand the node definition and scope. |+| Rule | Further constrains node generation methods, including content selection, naming requirements, length limits, and other generation requirements. |++The system provides common relationship types. Users can adjust them based on business requirements, including adding, modifying, or deleting relationship types.++Relationship configuration parameters:++| Parameter Name | Description |+| --- | --- |+| Type | Relationship type name, used to identify the association method between nodes. |+| Description | Describes the connection meaning represented by this relationship, helping the system understand relationships between nodes. |+| Rule | Further restricts relationship generation conditions, such as applicable node types, connection direction, and relationship usage scenarios. |++The system provides the following default relationship types:++| Relationship Name | Description |+| --- | --- |+| has_branch | Indicates that the core topic contains major branches and is used to connect CentralTopic and Branch. |+| has_sub_branch | Indicates that a branch contains more specific sub-branches and is used to connect Branch and Sub-branch. |+| supports | Indicates that keywords, cases, or details provide supplementary explanation for an upper-level concept. |+| related_to | Indicates an association between two concepts that does not belong to a clear parent-child structure. |++Users can adjust relationship definitions based on document content characteristics:++- For content with a clear hierarchy, use inclusion relationships such as topic -> branch -> sub-branch.+- For content with associations but no parent-child relationship, use association relationships.+- Relationship names should be concise and clear, and should reflect the connection meaning between nodes.+- Avoid configuring too many meaningless relationships to prevent generating a complex or hard-to-understand mind map structure.++### Node Configuration Description++In the node configuration area, users can view the currently configured node types and adjust them as needed.++Supported operations:++- **Add node**: Add a new node type to meet specific business scenarios.+- **Delete node**: Remove a node type that does not need to participate in generation.+- **Modify node description**: Adjust the node definition, affecting how the system extracts content.++Recommendations:++- Preserve a clear hierarchy and avoid configuring too many node types, which can make the structure complex.+- Node names should be short and clear for final display.+- Adjust node definitions based on document type. For example, technical documents can add types such as "module" and "function", while business documents can add types such as "process" and "role".++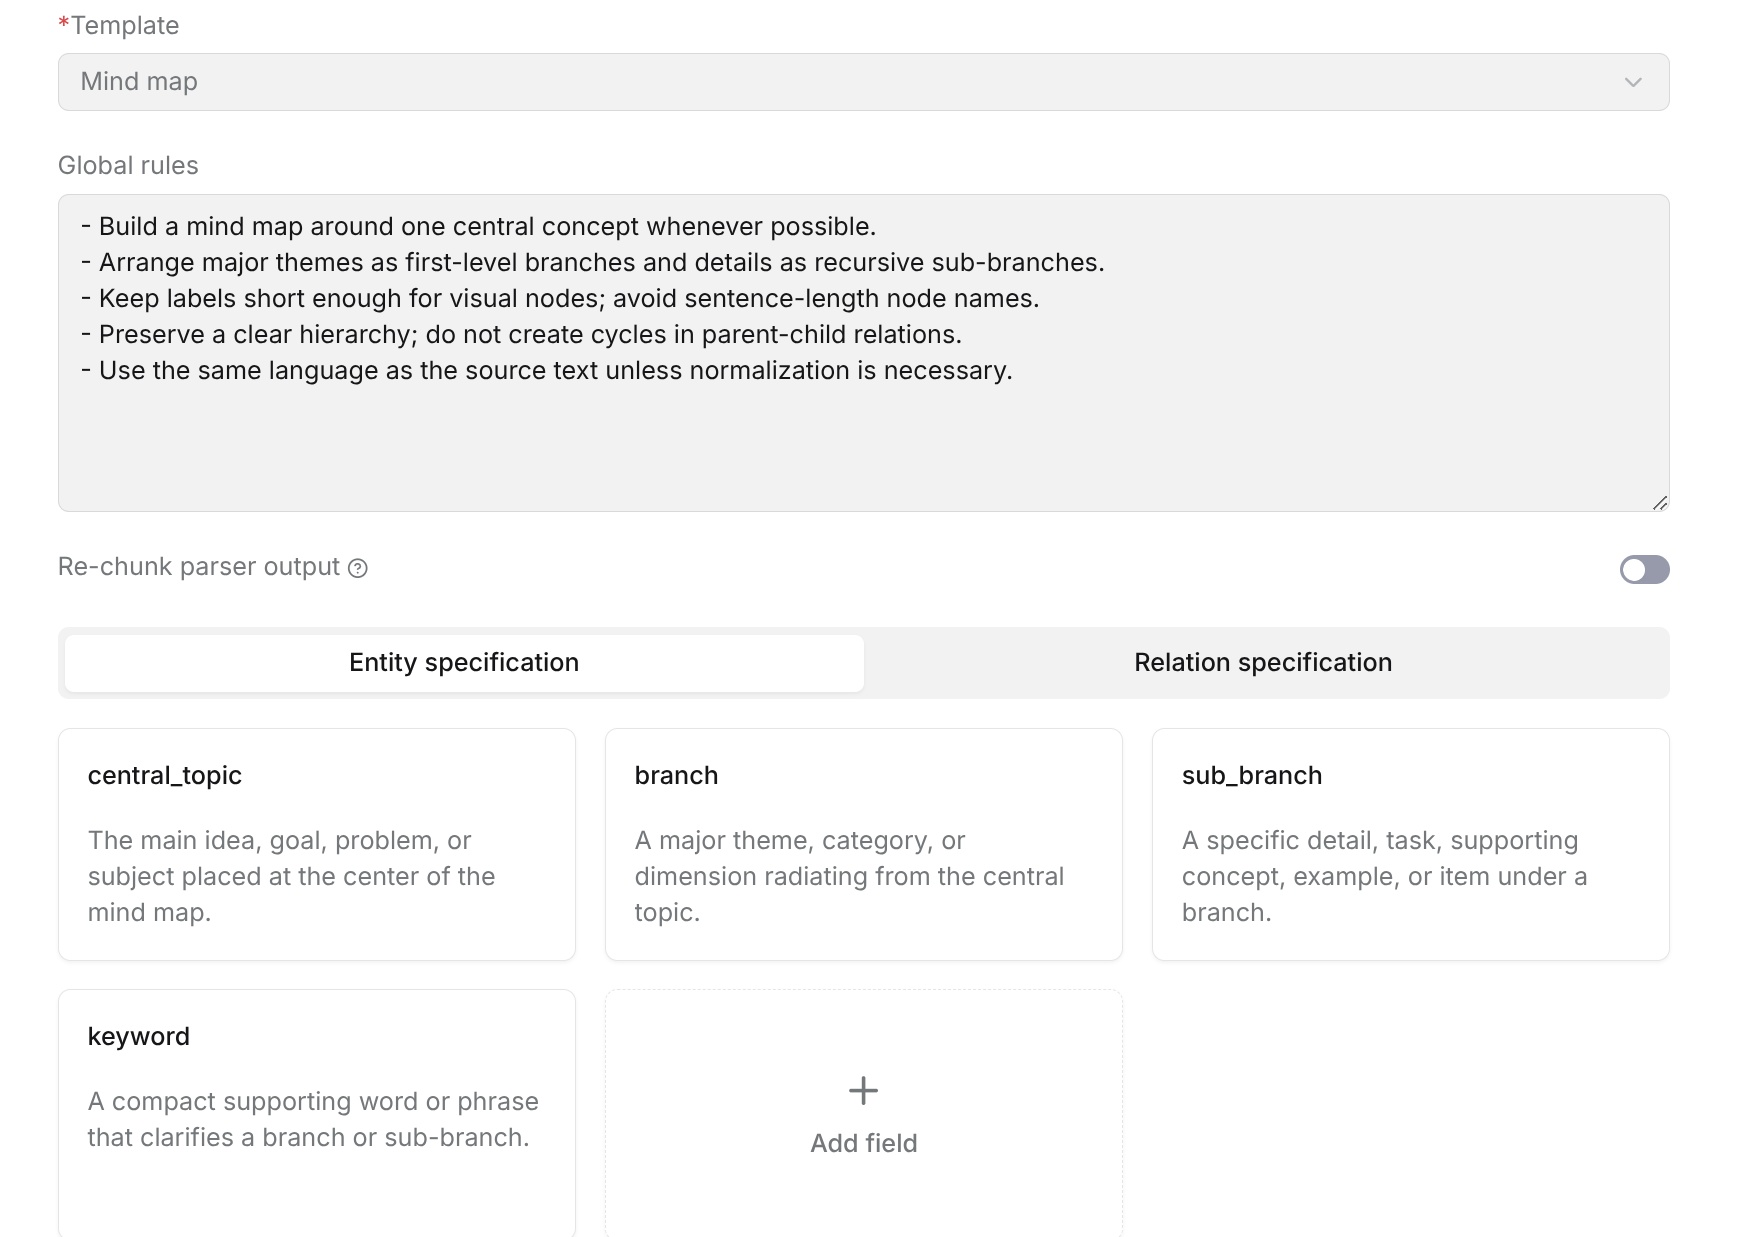++## Timeline++Timeline identifies key time information and related events in documents, then organizes event relationships in chronological order, helping users quickly understand the development process of events in the document.++This template is suitable for documents that contain timelines, event records, historical processes, project progress, personal experiences, and similar content. It extracts time points (Timestamp) and corresponding events (Event) to generate a continuous time relationship chain.++### Global Rules++Global rules define general requirements for Timeline extraction, including the scope of time information recognition, event extraction rules, and time relationship organization methods.++The system provides the following default rules:++- Extract valid time information and corresponding events from the document.+- Organize event relationships in chronological order to form a continuous time chain.+- Preserve events with clear time evidence and do not delete events because they are difficult to sort.+- When multiple events have the same time information, arrange them in the order they appear in the document.++Users can adjust rules based on actual business requirements, such as specifying event types to focus on, limiting the time range, or supplementing domain-specific requirements.++### EntitySpecification++Entity configuration defines the information types that need to be recognized and extracted in Timeline.++Each entity contains the following configuration items:++| Configuration Item | Description |+| --- | --- |+| Type | Entity type name, used to identify the information category to extract. |+| Description | Describes the content scope that the entity needs to extract, helping the model accurately recognize target information. |+| Rule | Further constrains entity extraction methods, such as format requirements, content restrictions, and special processing logic. |++The system provides the following default entity types:++| Entity Name | Description |+| --- | --- |+| timestamp | Indicates the time information when an event occurs. It can be a specific date, time point, or valid time range. |+| event | Indicates the event content corresponding to the time information and describes the main occurrence. |++Users can add entity types based on actual requirements to supplement time-related information that needs attention.++### RelationSpecification++Relationship configuration defines associations between entities and describes chronological order or other relationships between events.++Each relationship contains the following configuration items:++| Configuration Item | Description |+| --- | --- |+| Type | Relationship type name, used to define the connection method between entities. |+| Description | Describes the meaning and applicable scenarios of the relationship. |+| Rule | Restricts relationship generation methods, such as sorting rules and connection conditions. |++The system provides the following default relationship type:++| Relationship Name | Description | Rule Description |+| --- | --- | --- |+| ordered | Indicates that events are arranged in chronological order and is used to build a continuous time chain. | Sort events by occurrence time to form relationships from earliest to latest. When multiple events have the same time, arrange them in the order they appear in the document. |++Users can add relationship types based on actual requirements to describe more complex event relationships.++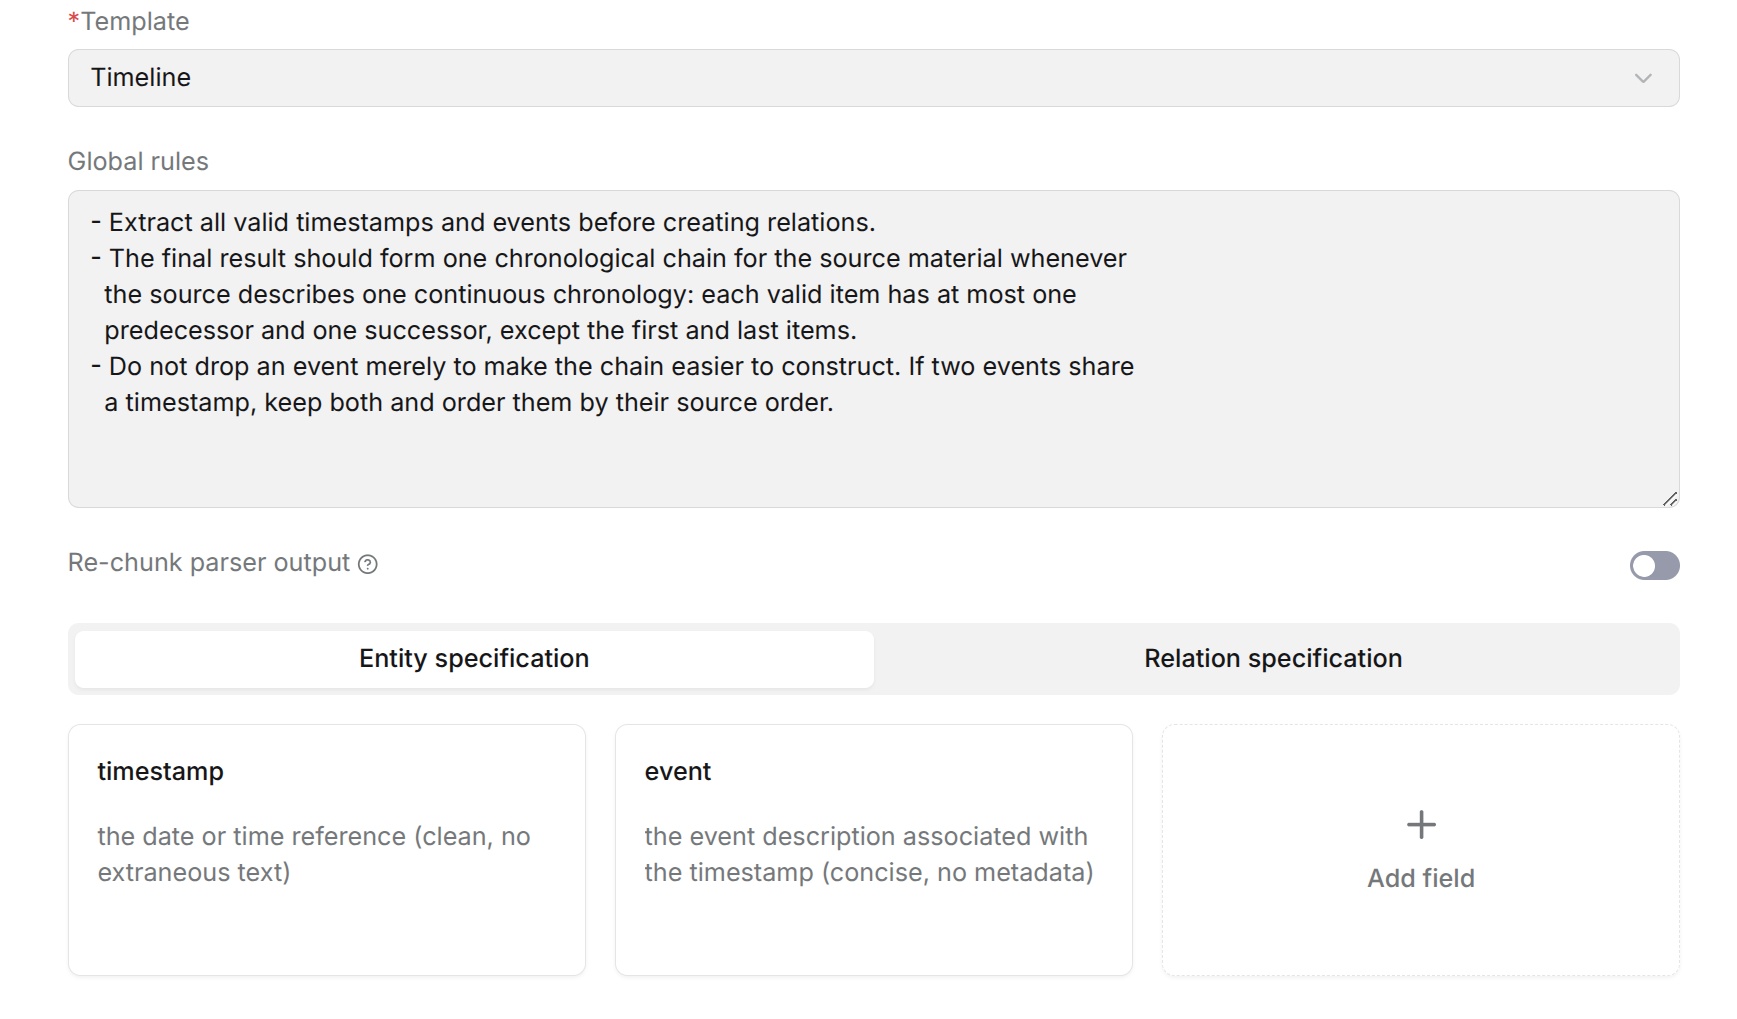++### Configuration Recommendations++Entity descriptions should clearly specify the scope of information to extract and avoid overly broad descriptions.++Rule configuration is used to supplement special extraction requirements, such as time format, sorting method, or content restrictions.++For timeline documents, it is recommended to keep the default timestamp, event, and ordered configurations to ensure the basic time relationship generation effect.++When adding entities or relationships, make sure they can form clear associations with the document content and avoid producing invalid information.++## Wiki++Wiki compiles document content into structured and associated knowledge pages. The system identifies entities, relationships, facts, and concepts in documents, then generates content similar to encyclopedia knowledge pages according to page organization rules.++Wiki is suitable for enterprise knowledge accumulation, product documentation, domain knowledge bases, and similar scenarios. It helps users convert scattered document content into clearly structured knowledge pages that are easy to browse and retrieve.++### Global Rules++Global rules define general requirements for Wiki knowledge extraction, including entity recognition, relationship establishment, and content organization.++System default rules include:++- Each relationship must connect two extracted entities and define a clear relationship type.+- Relationship direction is determined according to the actual semantics between entities.+- When multiple relationships exist, preserve them in the order they appear in the document.+- Keep relationship type names in a unified format.++Users can adjust rules based on business requirements, such as limiting the entity scope to focus on, supplementing domain knowledge, or adjusting page generation requirements.++### Plan++Plan is used to plan and organize document content before generating Wiki content. After Plan is enabled, the system first generates a content plan for the Wiki based on the document content, and then generates the corresponding Wiki content according to the plan, making the generated result more clearly structured.++When creating or editing a Wiki compilation template, you can choose whether to enable Plan.++- **Plan enabled**: The system first generates a content plan, and then generates Wiki content according to the plan. This is suitable for documents with substantial content and complex structures that require overall organization of Wiki content.+- **Plan disabled**: The system does not generate a content plan and directly generates Wiki content based on the document content.++After the configuration is completed and the template is saved, the system follows the current Plan configuration when using this template for knowledge compilation.++Note: Whether Plan is enabled affects the Wiki content generation flow. For longer documents or documents with complex content structures, it is recommended to enable Plan.++### EntitySpecification++EntitySpecification defines the entity types that need to be recognized and extracted in Wiki.++Each entity contains the following configuration items:++| Configuration Item | Description |+| --- | --- |+| Type | Entity type name, used to identify the information category to extract. |+| Description | Describes the entity definition and recognition scope. |+| Rule | Supplements entity extraction requirements, such as format restrictions and content scope. |++The system provides the following default entity types:++| Entity Name | Description |+| --- | --- |+| person | People, including individuals or natural persons. |+| org | Organizations, companies, institutions, or other collective organizations. |+| product | Products, services, software, or other offerings. |+| regulation | Laws, policies, standards, specifications, and other rule documents. |+| location | Geographic locations, including countries, cities, regions, and similar entities. |+| system | Technical systems, platforms, frameworks, or infrastructure. |+| equipment | Devices, machines, hardware, and similar entities. |+| other | Other entities that do not belong to the categories above. |++Users can add, modify, or delete entity types based on business scenarios.++### RelationSpecification++RelationSpecification defines relationship types between entities and is used to build knowledge associations in Wiki pages.++Each relationship contains the following configuration items:++| Configuration Item | Description |+| --- | --- |+| Type | Relationship type name, used to indicate the association method between entities. |+| Description | Describes the relationship meaning and applicable scope. |+| Rule | Restricts relationship extraction methods, such as relationship direction and connection conditions. |++The system provides the following default relationship types:++| Relationship Name | Description |+| --- | --- |+| owns | Indicates ownership or affiliation. |+| part_of | Indicates a composition relationship, such as a component belonging to a whole. |+| caused_by | Indicates a causal relationship. |+| regulates | Indicates a regulatory, management, or constraint relationship. |+| uses | Indicates a usage relationship. |+| located_in | Indicates a location inclusion relationship. |+| other | Indicates another valid relationship not covered above. |++Users can add relationship types based on business requirements to describe domain-specific associations.++### ClaimSpecification++ClaimSpecification defines factual descriptions that need to be extracted.++Each Claim field contains:++| Configuration Item | Description |+| --- | --- |+| Description | Defines the factual content to extract, usually as a complete factual statement. |++System default requirements:++- Claim content should be a complete factual description.+- Entities or concepts associated with a Claim should come from extracted information.+- Avoid generating speculative content that cannot be verified from the document.++### ConceptSpecification++ConceptSpecification defines professional concepts, topics, or core terms that need to be extracted.++Each Concept field contains:++| Configuration Item | Description |+| --- | --- |+| Description | Defines the concept name or topic content to extract. |++By default, the system identifies:++- Professional terms.+- Core concepts.+- Important topics in the document.++### Blueprint++Blueprint defines the structure template used when generating Wiki pages. The system provides multiple preset blueprints. Users can select an appropriate blueprint based on document content and usage scenarios, or select Custom to define page generation rules.++Configuration items:++The system provides the following blueprints:++- **Brand**: Suitable for brand-related content.+- **Engineering**: Suitable for technical, R&D, and engineering content.+- **General**: A general blueprint suitable for documents without specific content structure requirements.+- **Market**: Suitable for market, industry analysis, and related content.+- **Product**: Suitable for product introductions, product planning, and product-related documents.+- **Userinterview**: Suitable for user interviews, research records, and similar content.+- **Custom**: A custom blueprint that can configure Wiki page generation rules based on actual requirements.++| Configuration Item | Description |+| --- | --- |+| Blueprint | Specifies the template for Wiki page generation. |+| Instruction | Supplements page generation rules, such as chapter structure, content format, and display requirements. |++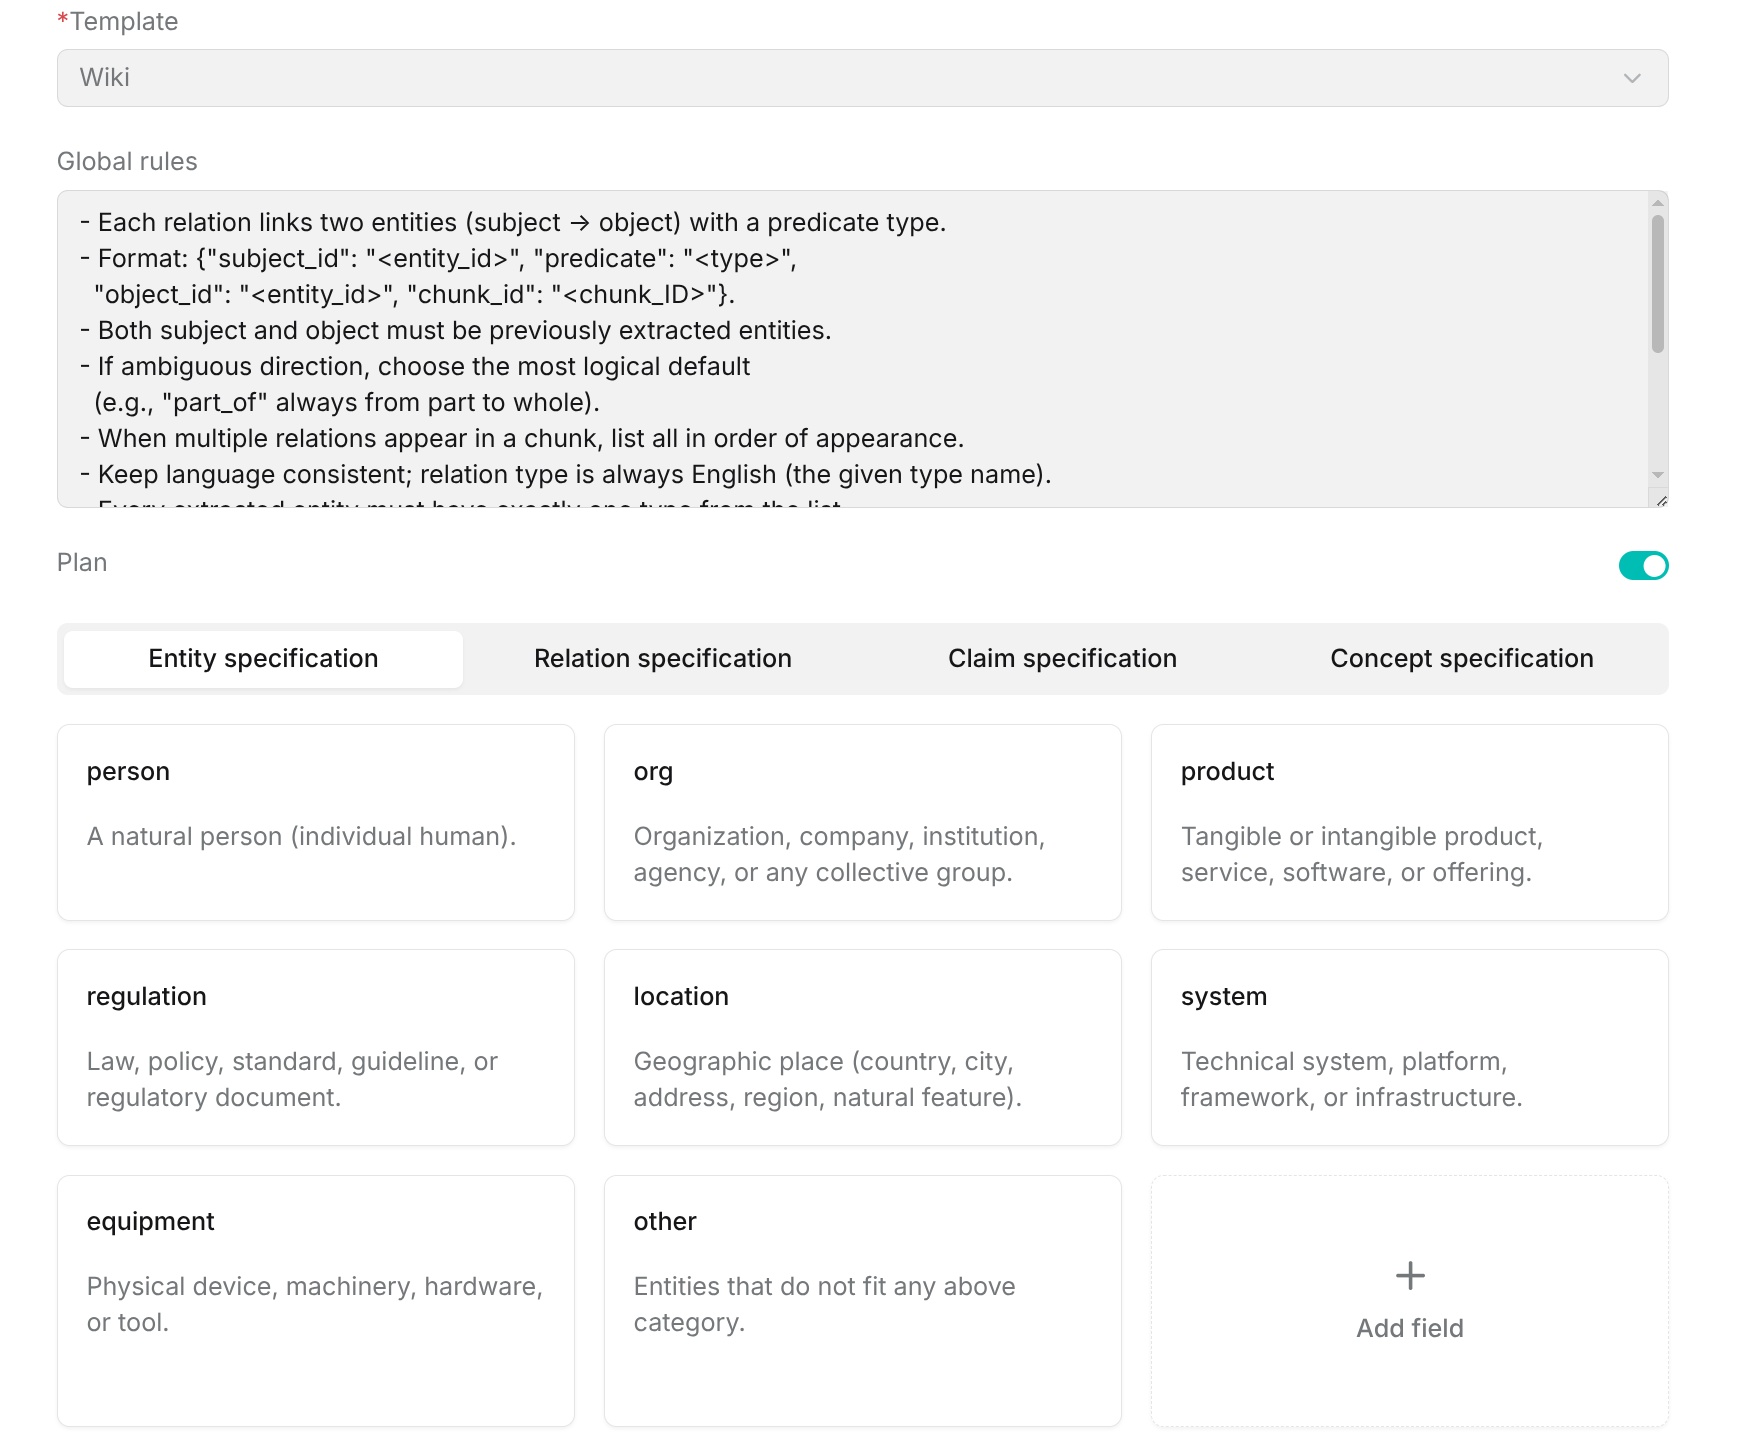+++After a blueprint is selected, the system generates Wiki content according to the preset page structure and rules of the corresponding blueprint. When Custom is selected, you can customize page generation requirements through Instruction, such as chapter structure, content format, and display method.++### Example Preview++After configuring a blueprint, you can preview the Wiki page structure corresponding to the current blueprint in the Example area below. The preview content displays the page title, chapter hierarchy, and content requirements of each chapter, helping users understand the page organization method of the selected blueprint before generating the Wiki.++### Configuration Recommendations++For structurally complex content such as enterprise knowledge bases and product documentation, it is recommended to enable Plan.++Entity types should be adjusted based on the business domain to avoid configuring too many irrelevant entities.++Relationship types should remain clear and avoid defining relationships with duplicate meanings.++Claim is used to supplement factual information and is suitable for scenarios that require knowledge verification.++Concept is suitable for professional domain knowledge organization and can help improve the association capability of Wiki pages.++Blueprint controls the final page display effect. It is recommended to adjust it based on the purpose of the knowledge base.diff --git a/docs/guides/knowledge_compilation/faq.md b/docs/guides/knowledge_compilation/faq.mdnew file mode 100644index 0000000000..2404fbd5f7--- /dev/null+++ b/docs/guides/knowledge_compilation/faq.md@@ -0,0 +1,67 @@+---+sidebar_position: 5+title: FAQ+sidebar_label: FAQ+slug: /knowledge_compilation/faq+sidebar_custom_props: {+ categoryIcon: LucideWandSparkles+}+---++# FAQ++## 1. Why can't I see Wiki in Artifacts after knowledge compilation is complete?++Wiki is generated differently from other knowledge artifacts.++Graph, Tree, PageIndex, MindMap, and Timeline are document-level knowledge artifacts. Their corresponding results can be viewed after knowledge compilation is complete.++Wiki is a knowledge-base-level knowledge artifact. After document knowledge compilation is complete, you still need to go to the Artifacts page of the knowledge base and click generate. The system then generates Wiki based on the compilation results in the current knowledge base.++## 2. Why are no corresponding knowledge artifacts generated after knowledge compilation?++Check the following items in sequence:++- Whether Compiler has been added to the Ingestion Pipeline.+- Whether Compiler has selected the correct knowledge compilation template.+- Whether the knowledge compilation task executed successfully.+- Whether the knowledge compilation template has been correctly configured and saved.+- Whether the default extraction model can be used normally.++If the task execution fails, use the task execution logs to further check the specific cause.++## 3. Why is the generated knowledge artifact incomplete or inconsistent with expectations?++The generation result of a knowledge artifact is affected by factors such as the original document content, selected template, default extraction model, and template configuration.++It is recommended to first check whether the parsing result of the original document is complete. Then adjust the global rules and the configuration parameters of the corresponding template based on the generated result, and execute knowledge compilation again.++## 4. Will already generated knowledge artifacts update automatically after I modify a knowledge compilation template?++No. After modifying template configuration, you need to use the updated template to execute knowledge compilation again before the new configuration is applied to the generated result.++## 5. Can I use different knowledge compilation templates for the same document?++Yes. You can select different knowledge compilation templates based on actual usage scenarios to generate different types of knowledge artifacts, such as Graph, Tree, PageIndex, MindMap, or Timeline.++Different templates have different knowledge organization methods and applicable scenarios. For details, refer to the template selection recommendations.++## 6. What is the difference between "Re-Split Parser Output" and Chunker?++Re-Split Parser Output controls whether Compiler reorganizes and splits Parser output based on the processing requirements of the current template before knowledge compilation.++Chunker is used for document chunk processing in the Ingestion Pipeline.++They act at different processing stages. Re-Split Parser Output does not replace Chunker.++## 7. Why do results differ when the same document uses different models?++During knowledge compilation, the model is responsible for tasks such as entity extraction, content understanding, and structure generation.++Different models may differ in understanding capability, context length, and generation capability, so the final knowledge artifacts may also differ. Select an appropriate model based on document type, content complexity, and the knowledge compilation template used.++## 8. What should I adjust first when the knowledge compilation result is unsatisfactory?++It is recommended to first confirm whether the original document parsing result is correct.++If the parsing result is normal, check and adjust the default extraction model, global rules, and specific configuration parameters of the current template in sequence. After adjustment, execute knowledge compilation again and compare whether the new knowledge artifact meets expectations.diff --git a/docs/guides/knowledge_compilation/overview.md b/docs/guides/knowledge_compilation/overview.mdnew file mode 100644index 0000000000..18ff8c0db8--- /dev/null+++ b/docs/guides/knowledge_compilation/overview.md@@ -0,0 +1,76 @@+---+sidebar_position: 1+title: Overview+sidebar_label: Overview+slug: /knowledge_compilation/overview+sidebar_custom_props: {+ categoryIcon: LucideWandSparkles+}+---++# Overview++Knowledge compilation converts unstructured documents into structured knowledge content. The system analyzes information in documents with a large language model and generates different types of knowledge artifacts based on the compilation template selected by the user.++Generated knowledge artifacts can be used for knowledge retrieval, intelligent Q&A, and Agent applications, helping users quickly understand and use key information in documents. The following knowledge artifact types are currently supported:++- **Knowledge graph**: Displays entities in documents and their relationships. It is suitable for content such as personal relationships, organizational structures, and product relationships.+- **Knowledge tree**: Organizes document content by hierarchy. It is suitable for chapter structures, topic classification, and knowledge system organization.+- **Page index**: Preserves the original document structure and enhances chapter positioning. It is suitable for manuals, specifications, reports, and similar materials.+- **Mind map**: Expands content relationships around core topics and helps users quickly understand the overall document structure.+- **Timeline**: Organizes event information in chronological order. It is suitable for historical materials, project records, event tracking, and similar content.+- **Knowledge page**: Generates interconnected knowledge pages. It is suitable for enterprise knowledge, product materials, and domain knowledge management.++Generated knowledge artifacts can be used as auxiliary information for subsequent retrieval and Q&A, improving the efficiency of knowledge queries and content understanding.++## Core Concepts++Before using knowledge compilation, you need to understand the following basic concepts:++- **Compilation template**: Defines how knowledge compilation is generated, including the information types to extract, the organization structure, and generation rules. Users can select different templates based on actual requirements to generate the corresponding knowledge artifacts.+- **Knowledge artifact**: A structured result produced by knowledge compilation, including knowledge graphs, knowledge trees, page indexes, mind maps, timelines, and knowledge pages. Different knowledge artifact types are suitable for different information organization scenarios.+- **Compilation node**: A processing node in the knowledge compilation flow that executes a specified compilation task. When using a compilation node, you need to associate it with the corresponding compilation template to determine the format and structure of the generated content.++## Template Selection Recommendations++Knowledge compilation provides multiple built-in templates. Different templates are suitable for different knowledge organization methods. When creating a knowledge compilation template, select an appropriate template based on the document content and the expected knowledge artifact.++| Template | Applicable Scenario |+| --- | --- |+| Graph | Suitable for extracting entities and relationships between entities in documents, such as people, organizations, products, and their relationships. |+| Tree | Suitable for organizing document content by topic and hierarchy, arranging knowledge into a tree structure. |+| PageIndex | Suitable for preserving the original chapter and page structure of a document and building a hierarchical index for quick content positioning and retrieval. |+| MindMap | Suitable for extracting core topics and branch content from documents and displaying the knowledge structure as a mind map. |+| Timeline | Suitable for documents that contain clear time information and events, organizing and displaying events in chronological order. |+| Wiki | Suitable for documents with substantial content and relationships between topics, organizing the content into interconnected Wiki pages. |++After selecting a template, you can also adjust global rules and template-specific configurations based on actual business requirements to control the content and generation results of knowledge compilation.++## Preparation Before Starting++Before configuration, confirm the following conditions:++- An available LLM has been configured, and the model has strong text understanding, structured output, and reasoning capabilities.+- You have created or plan to create an Ingestion Pipeline that includes Parser, Chunker, Compiler, and Indexer.+- Source documents with clear topics and reliable content are ready.+- The template type to use has been determined based on the target knowledge structure.++Recommendation: When using this feature for the first time, select a small number of representative documents for testing. After confirming the output structure and quality, process data at a larger scale.++## Standard Workflow++1. **Create a knowledge compilation template**: On the Agent page, select **Compilation Operator** when creating a new Agent. Then create a template based on the type of knowledge artifact to generate and complete the related parameter configuration.+2. **Configure the Ingestion Pipeline**: Add Compiler to the Ingestion Pipeline and select the created knowledge compilation template.+3. **Apply the Ingestion Pipeline**: In Dataset, select the documents to process and apply the configured Ingestion Pipeline.+4. **Execute knowledge compilation**: The system parses documents according to the Pipeline configuration and generates the corresponding knowledge artifacts based on the selected template.+5. **View knowledge artifacts**: After compilation is complete, view generated artifacts such as Graph, Tree, PageIndex, MindMap, Timeline, or Wiki.++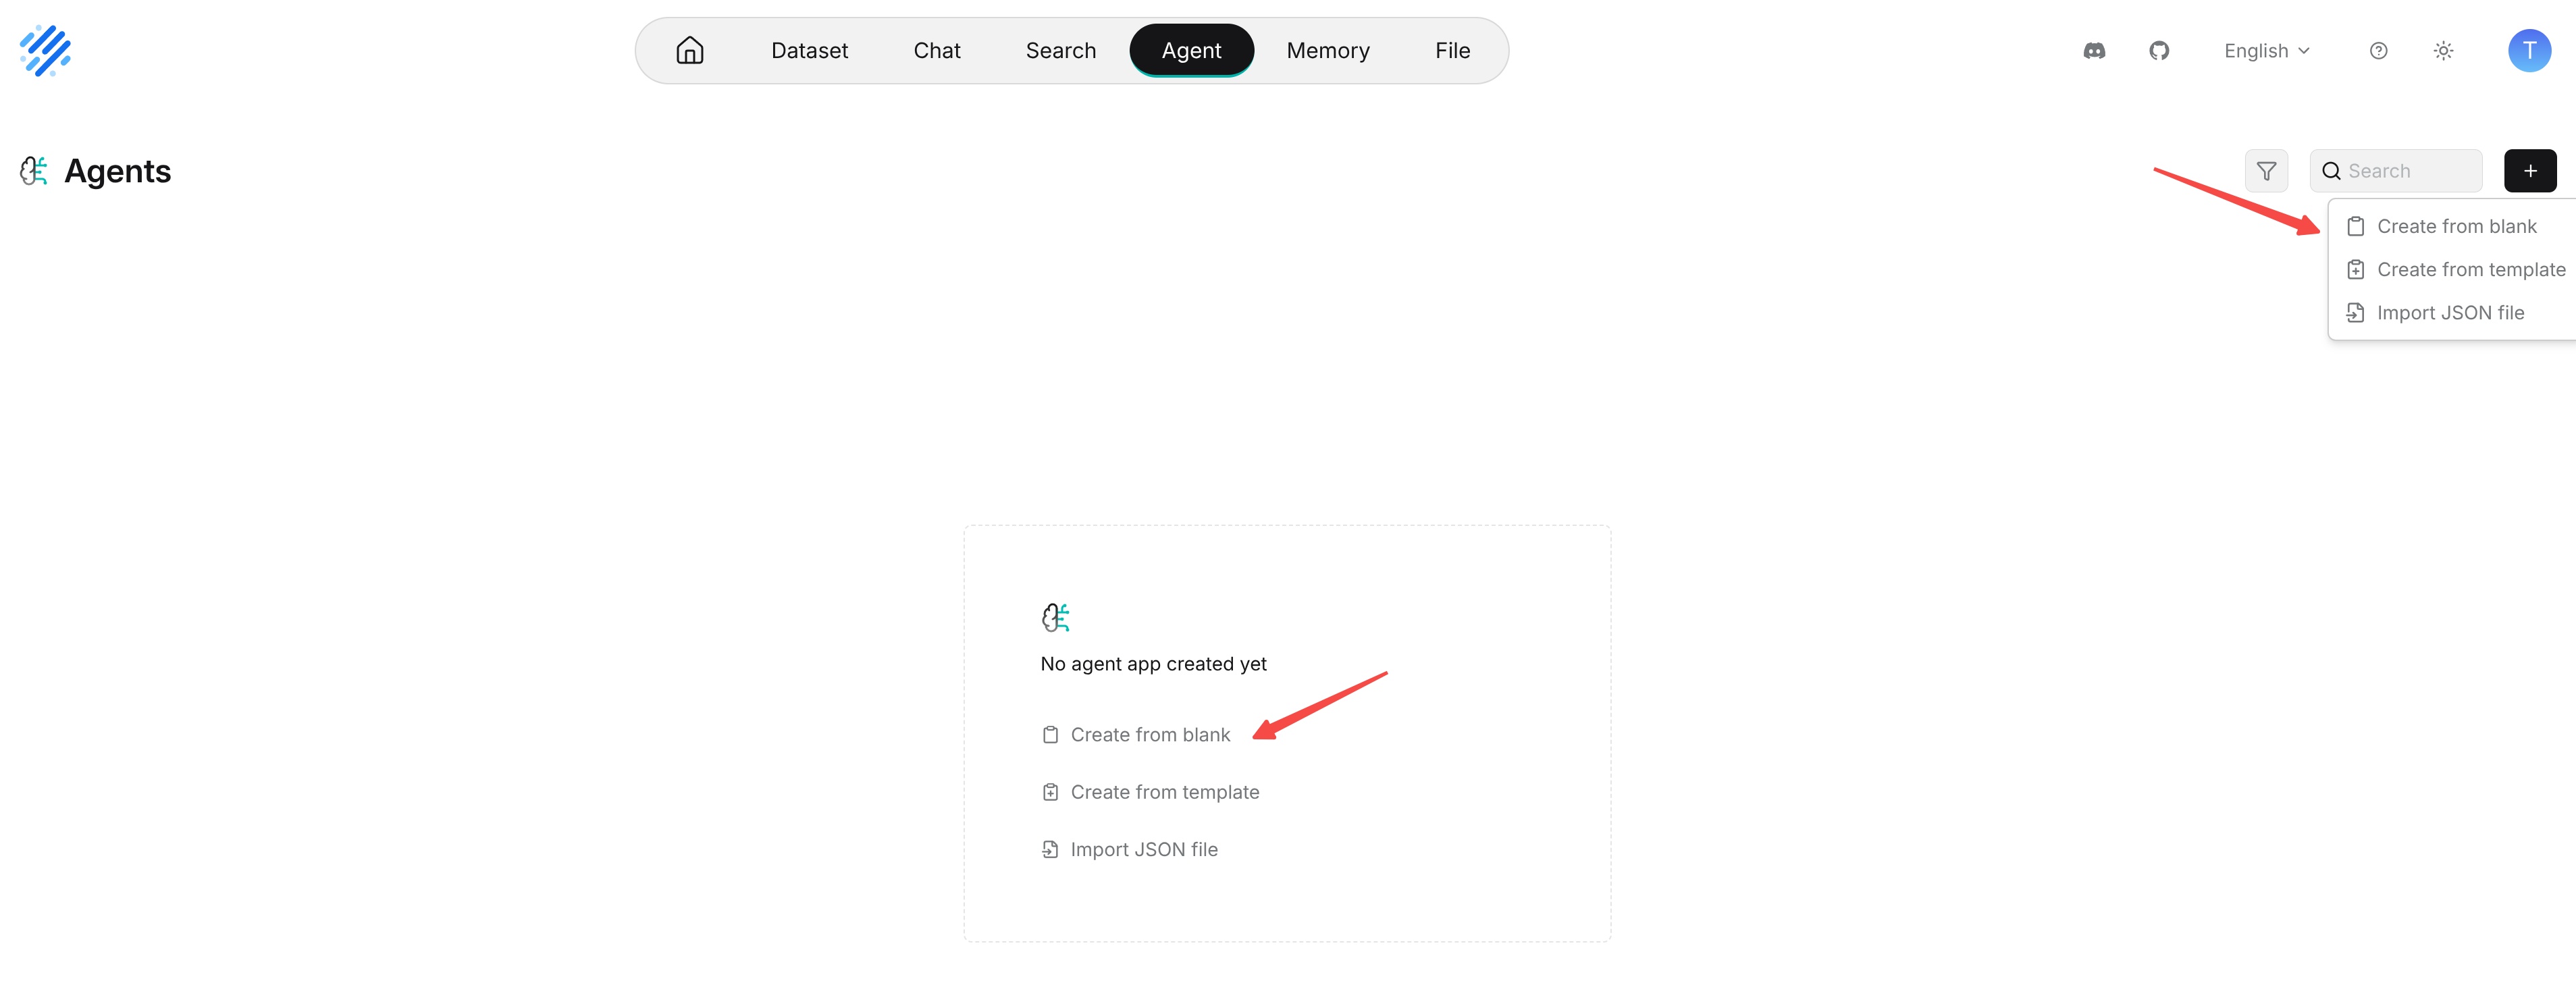++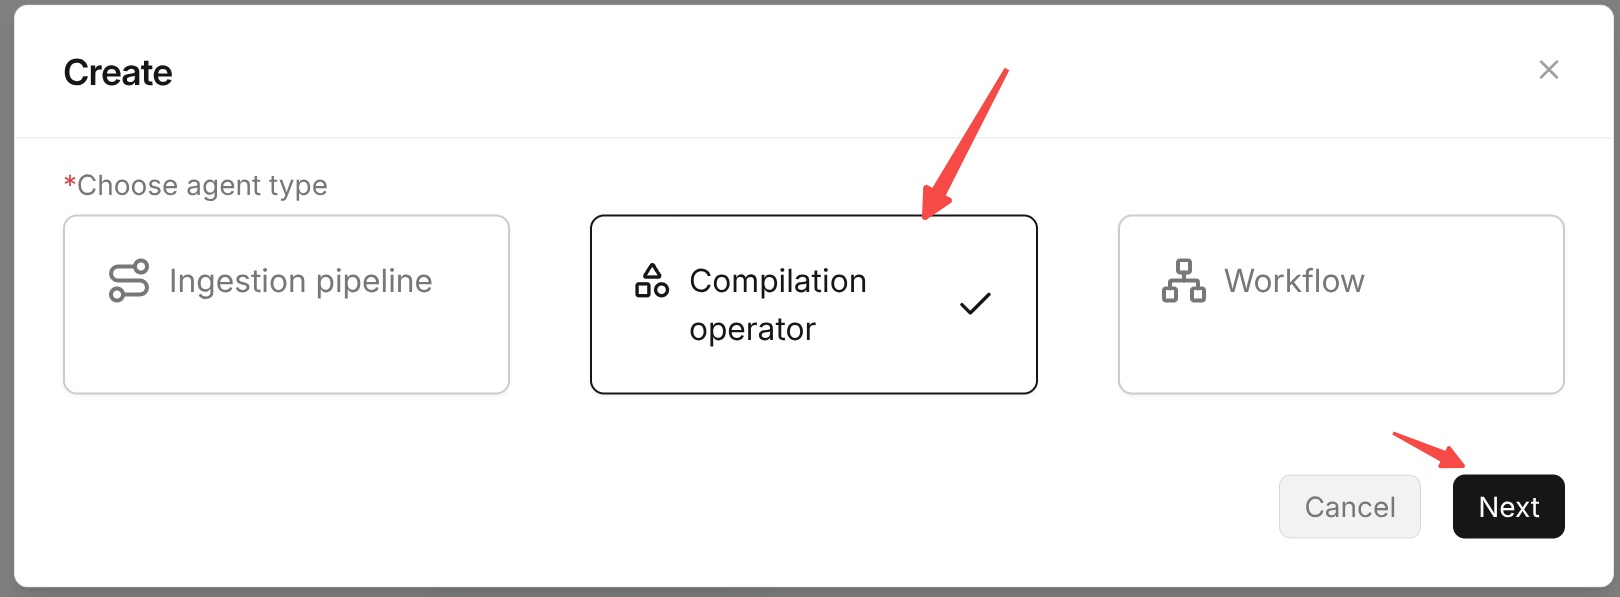++Note: This section helps users quickly understand the overall workflow of knowledge compilation and only shows the operation interface for "creating a knowledge compilation template". Ingestion Pipeline configuration, document application, knowledge artifact viewing, and other operations are described in detail in the corresponding later chapters with interface screenshots. For specific operations, refer to the relevant chapters.++Typical flow: Parser -> Chunker -> Compiler -> Indexer.++Parser is responsible for parsing, Chunker is responsible for splitting, Compiler is responsible for knowledge compilation, and Indexer is responsible for building the indexes required for subsequent retrieval.diff --git a/docs/guides/models/llm_api_key_setup.md b/docs/guides/models/llm_api_key_setup.mdindex d102c14bcc..2aa6729ba4 100644--- a/docs/guides/models/llm_api_key_setup.md+++ b/docs/guides/models/llm_api_key_setup.md@@ -25,7 +25,7 @@ If you find your online LLM is not on the list, don't feel disheartened. The lisGo to **User settings** **>** **Model providers**. In **Available models**, select a provider and complete its configuration. After the configuration succeeds, the provider is marked as **Configured**.-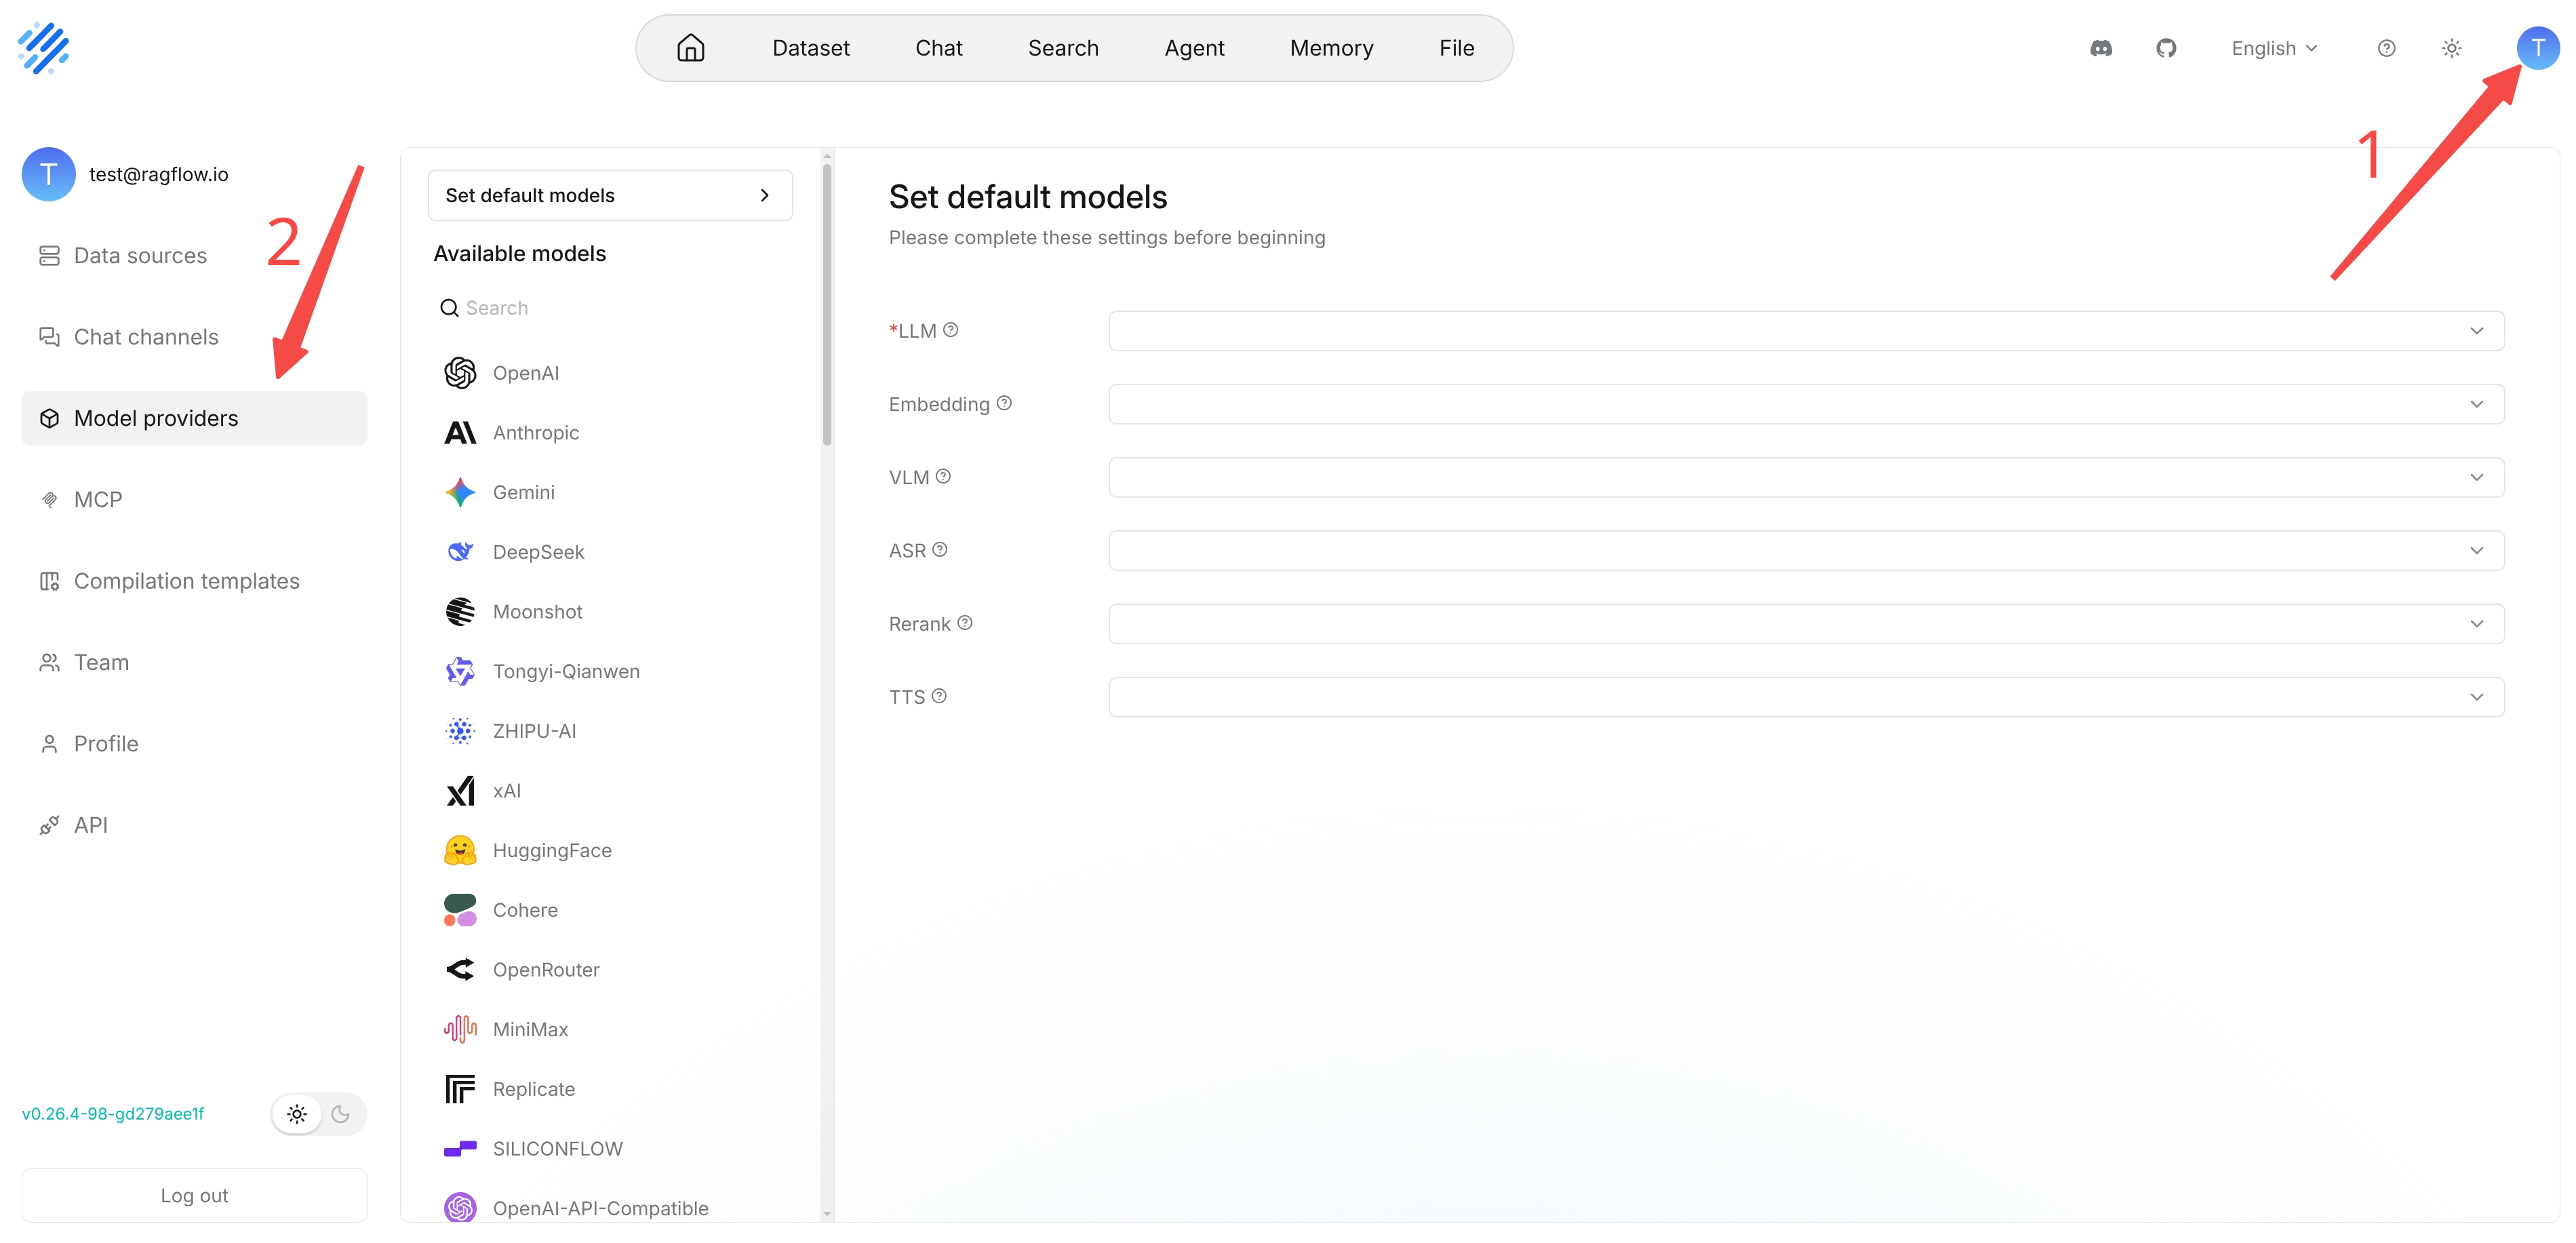+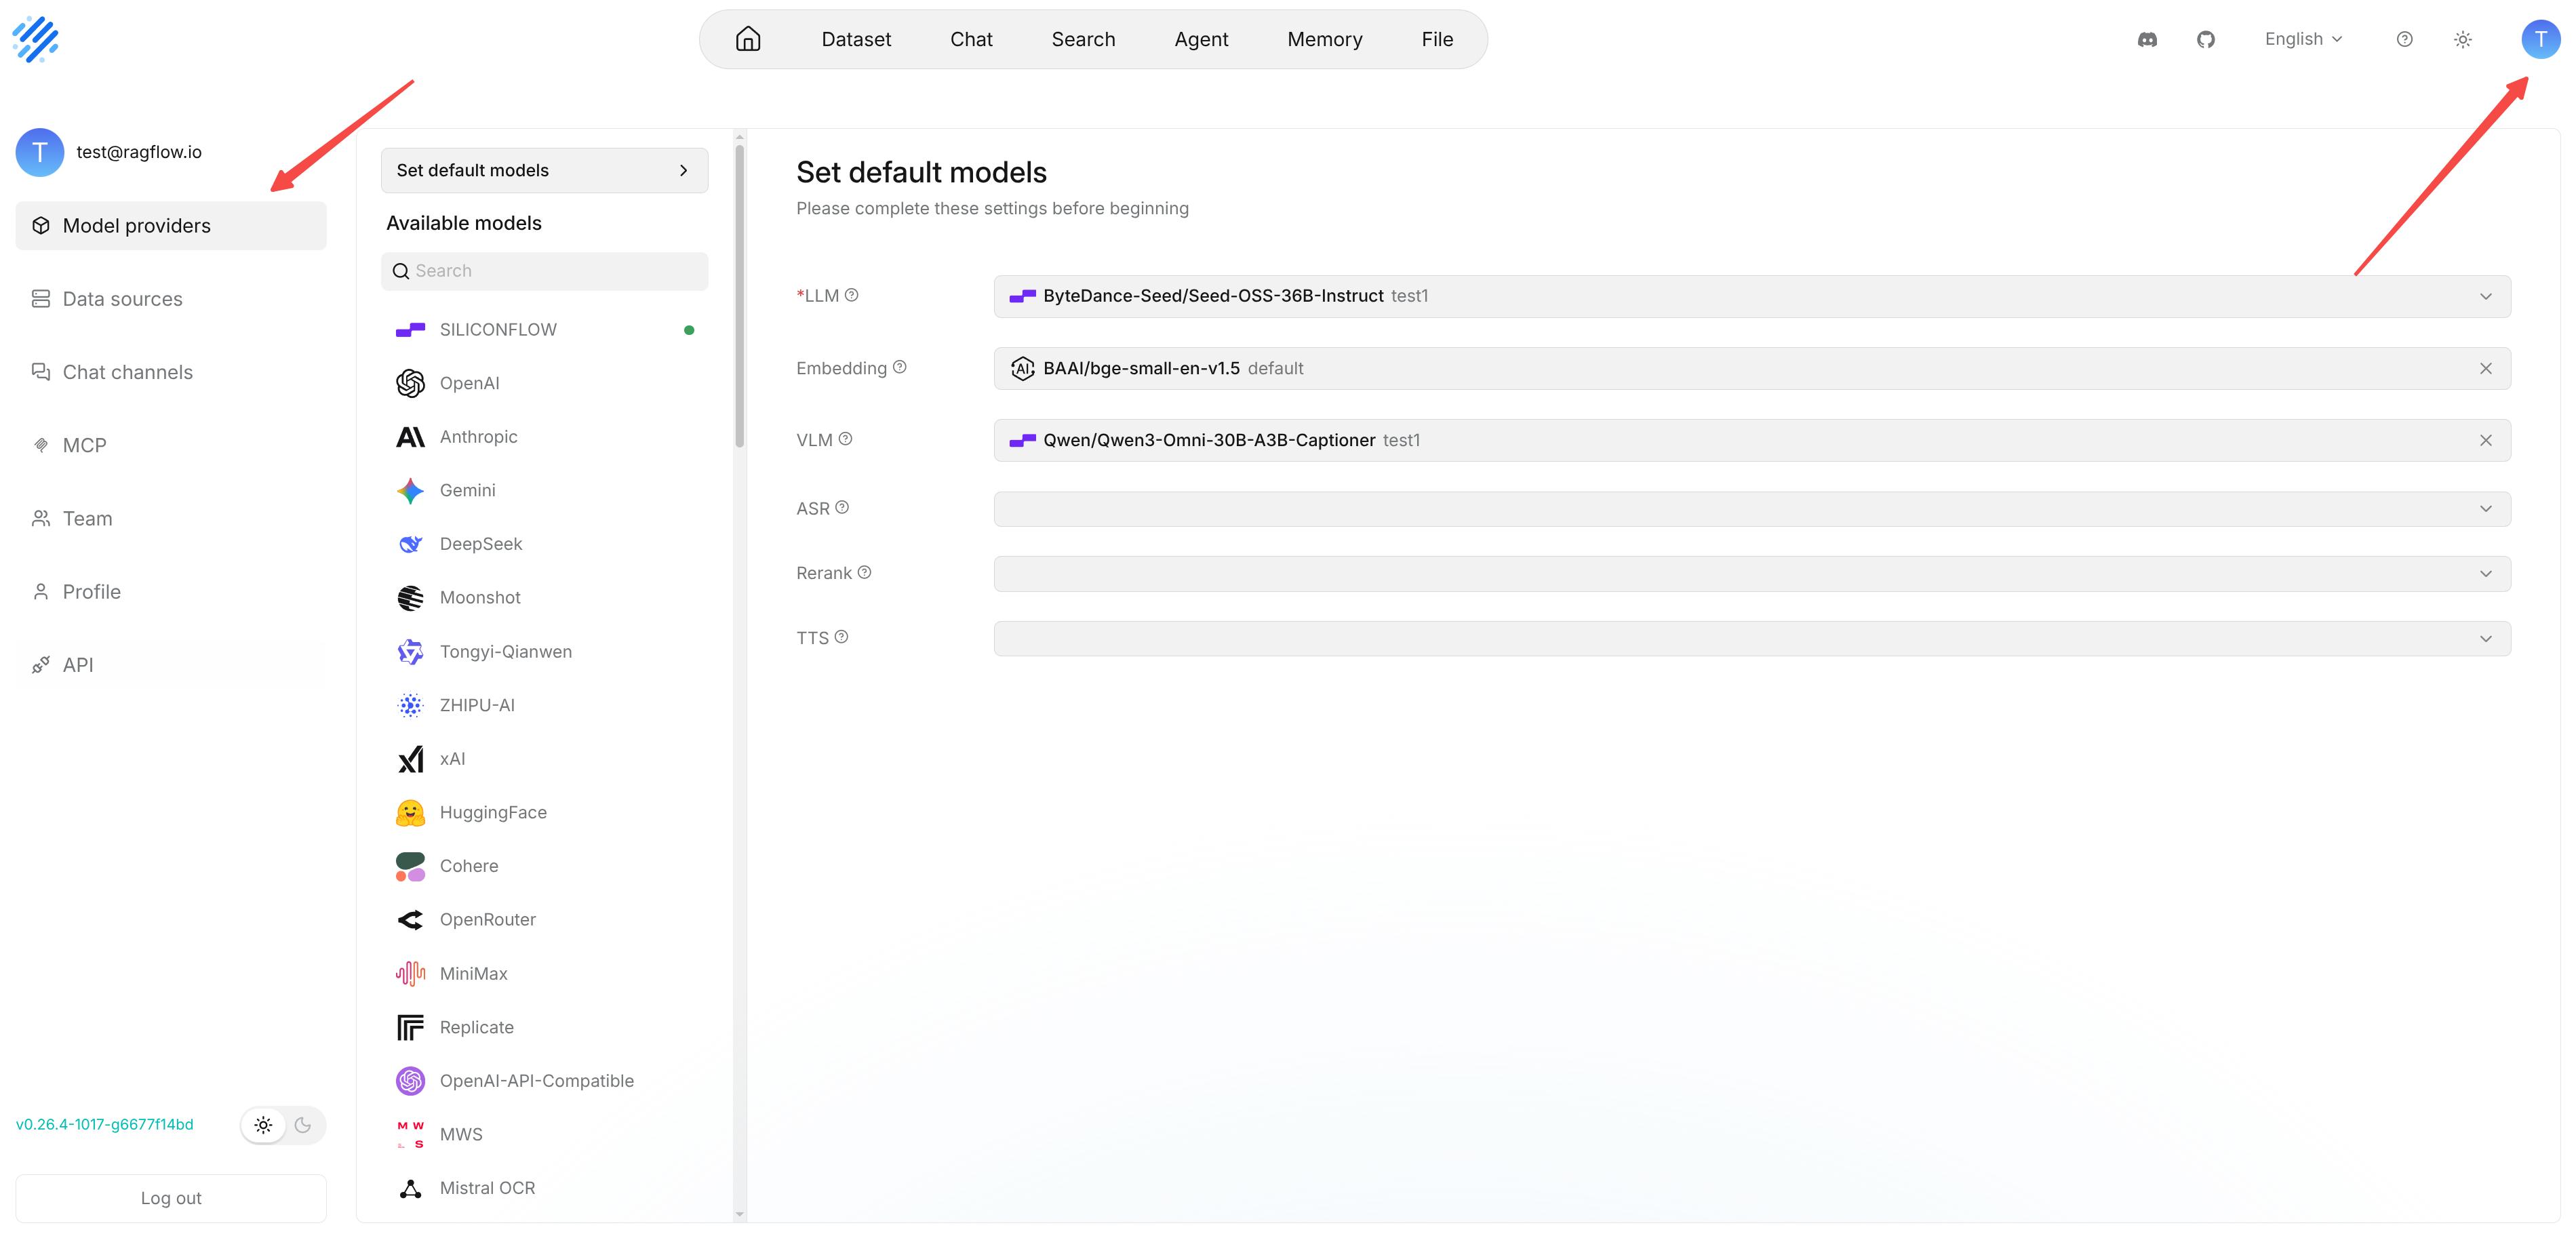### Create a Model Provider Instance and Configure Connection Information@@ -43,7 +43,7 @@ To configure a model provider:3. Enter **API Key** and **Base URL**.4. Save the instance.-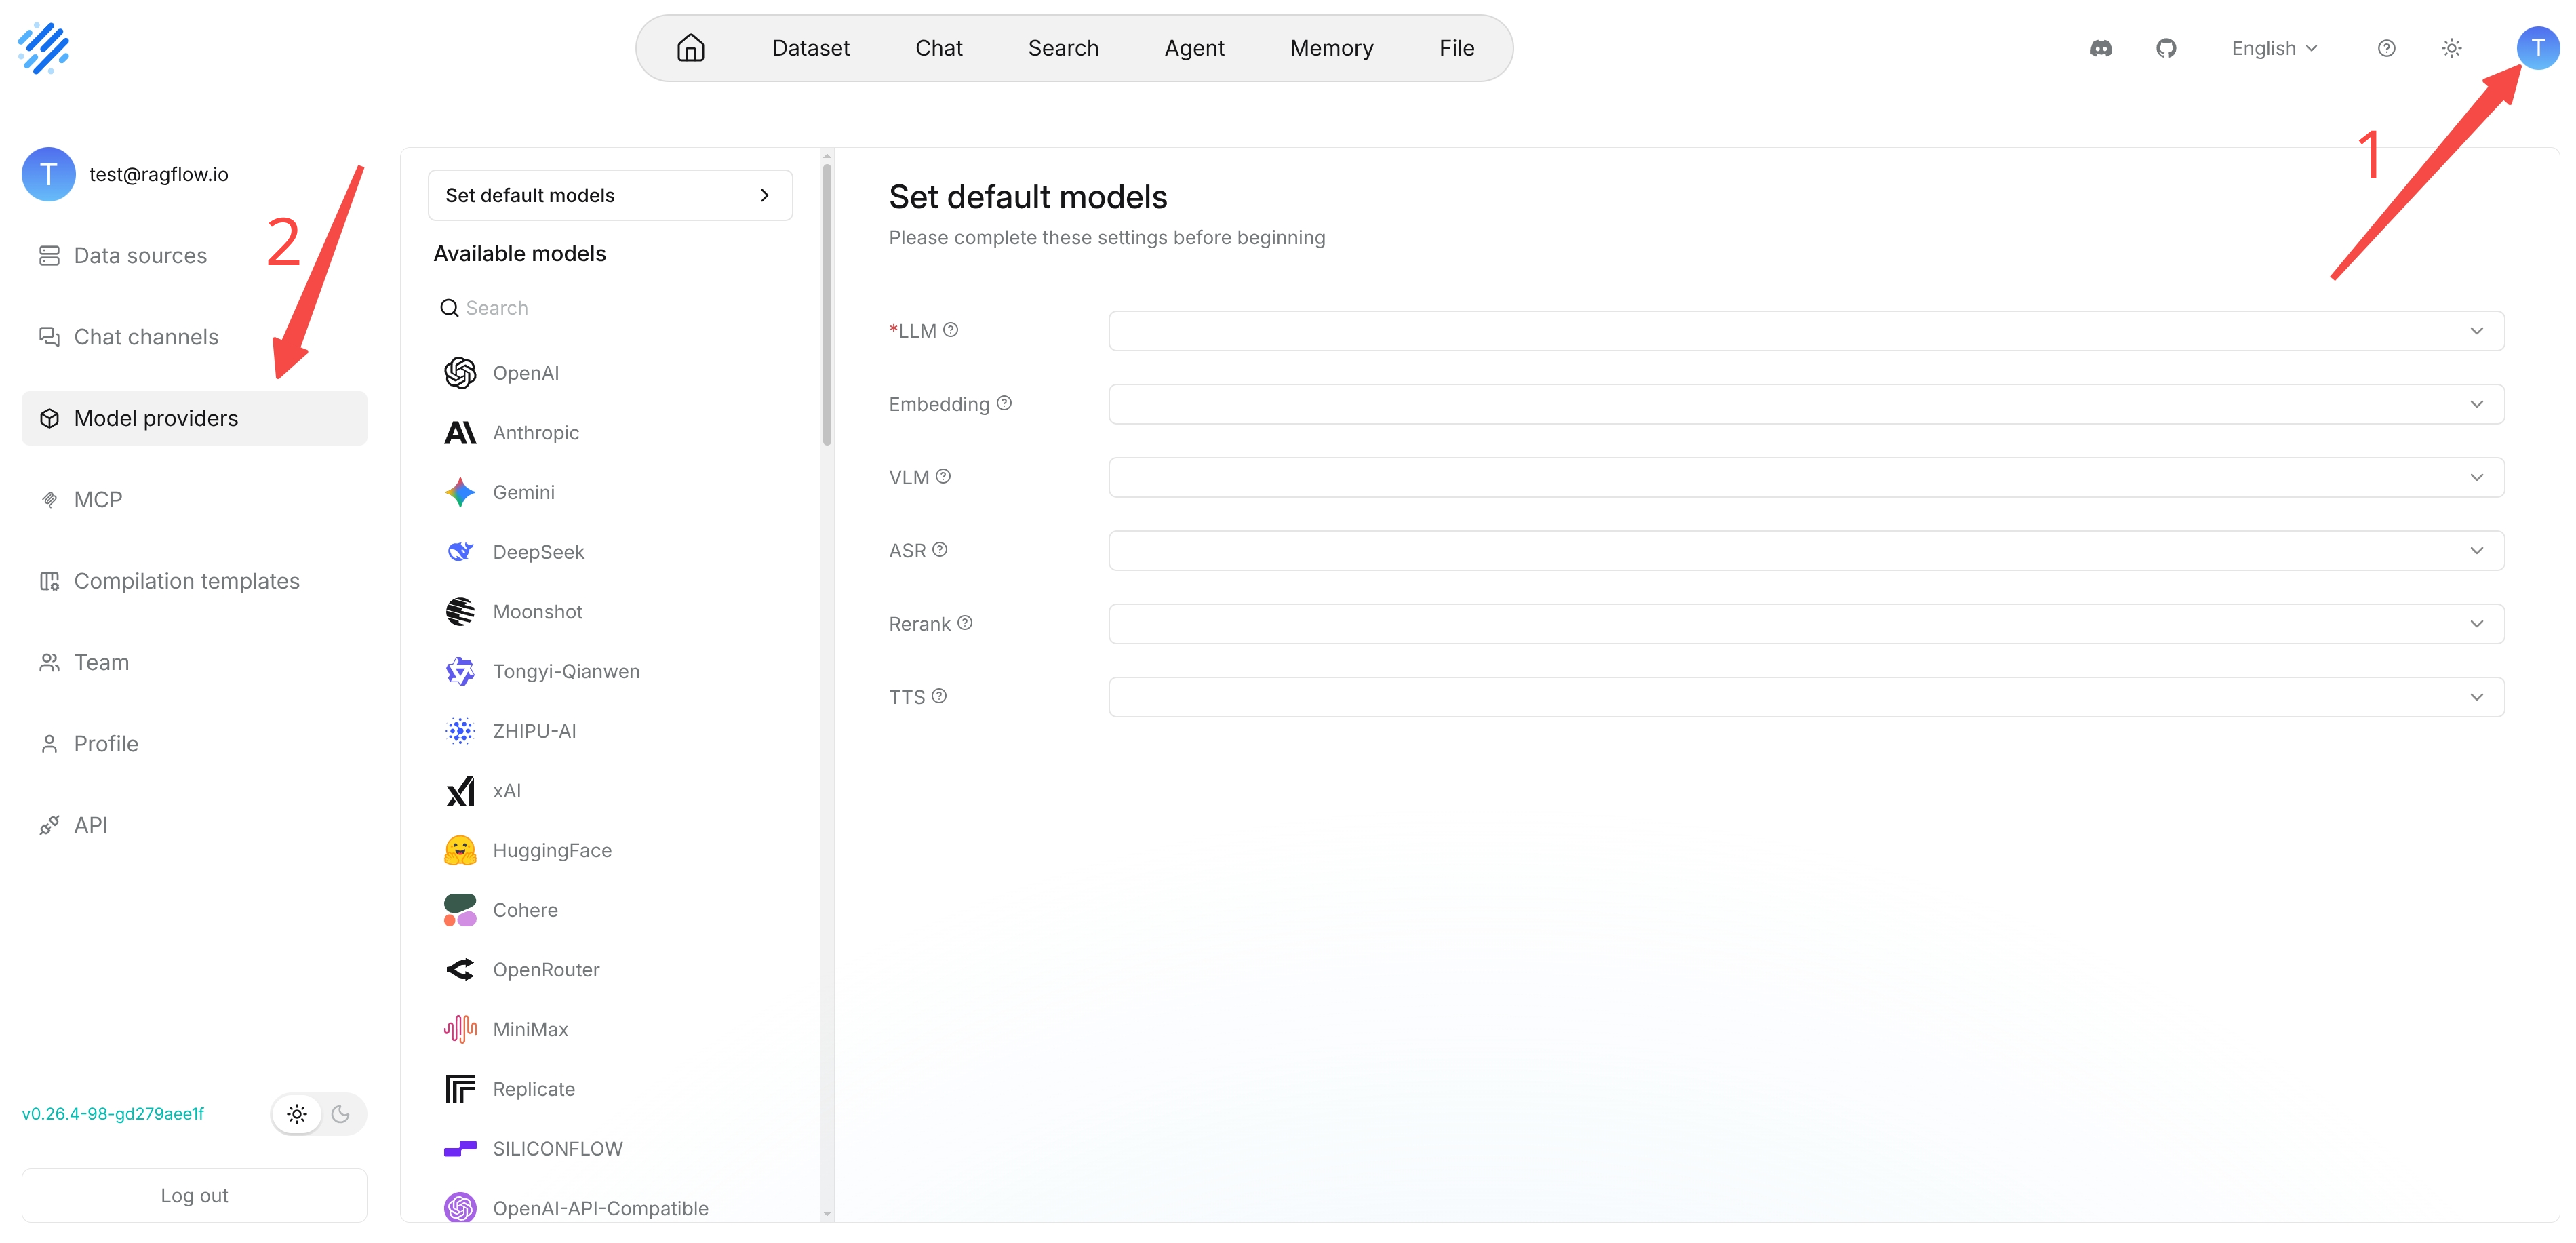+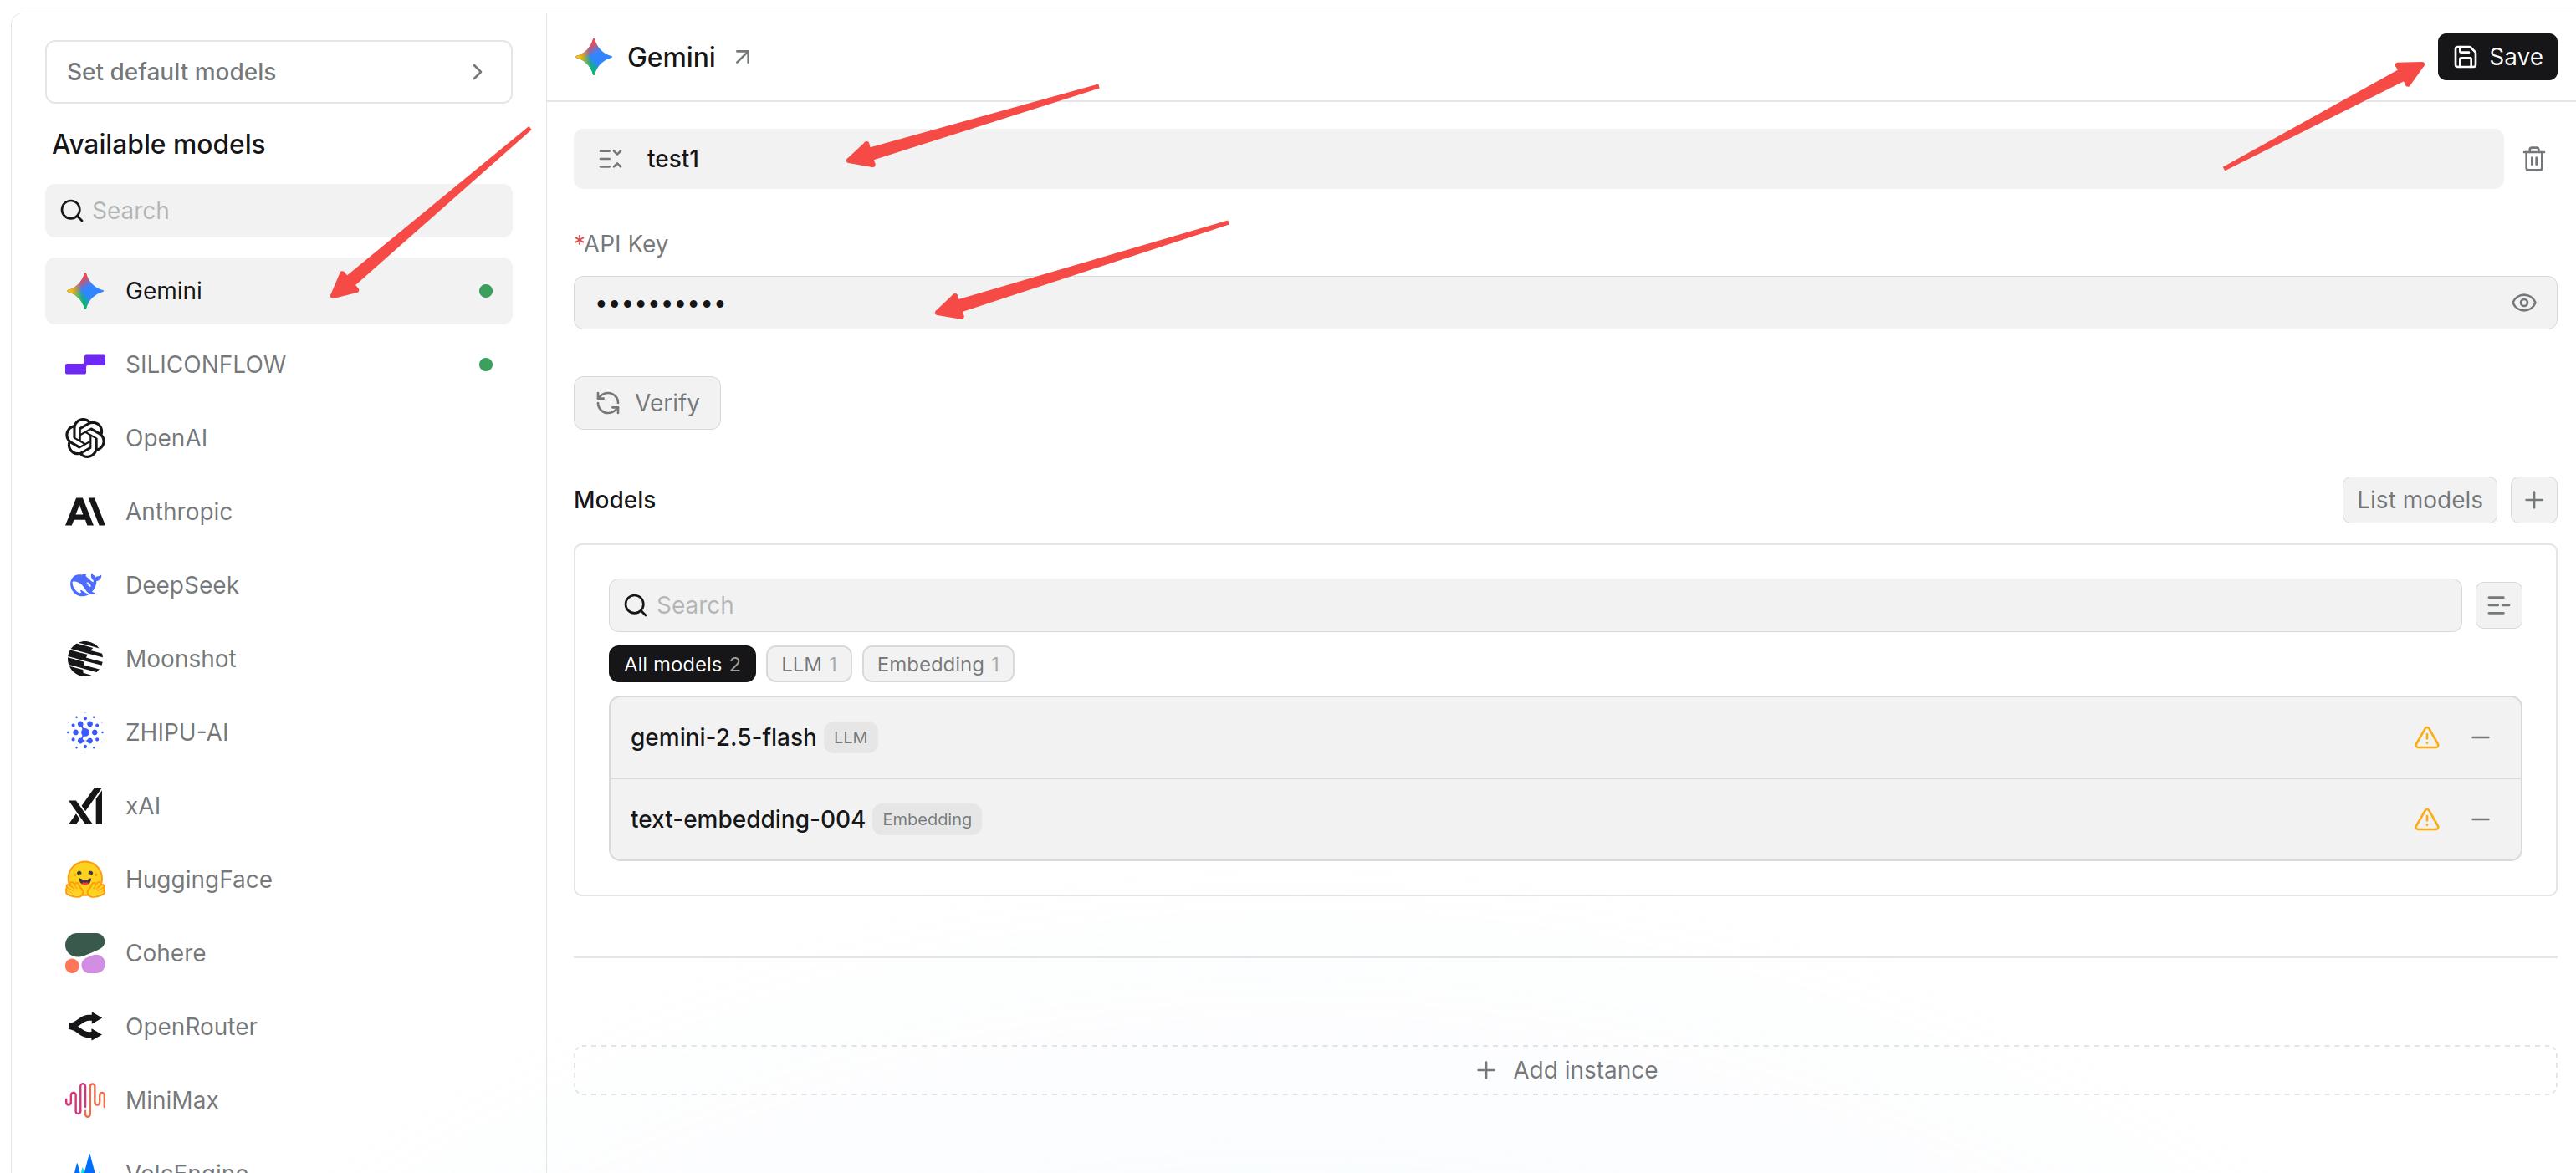:::cautionDo not expose your API Key. An incorrect Base URL causes connection verification or model calls to fail. When using a compatible API, confirm whether the path must include `/v1`.@@ -97,7 +97,7 @@ At minimum, set the following defaults:If you have configured a rerank model, it is also recommended to set a default rerank model. Configure VLM, ASR, TTS, and OCR defaults as required by your business.-+## Model Types and Usagediff --git a/docs/guides/models/supported_models.mdx b/docs/guides/models/supported_models.mdxindex de274f119b..e341c4e494 100644--- a/docs/guides/models/supported_models.mdx+++ b/docs/guides/models/supported_models.mdx@@ -17,67 +17,76 @@ A complete list of model providers supported by RAGFlow, which will continue to<APITable>```-| Provider | URL |-| --------------------- | ----------------------------------------------- |-| aimlapi.com | `https://aimlapi.com` |-| Anthropic | `https://www.anthropic.com` |-| Astraflow | `https://astraflow.ucloud-global.com/en-us` |-| Astraflow-CN | `https://astraflow.ucloud.cn/` |-| Avian | `https://www.avian.io` |-| Azure-OpenAI | `https://azure.microsoft.com/en-us/products/ai-services/openai-service` |-| BaiChuan | `https://www.baichuan-ai.com` |-| BaiduYiyan | `https://yiyan.baidu.com` |-| Bedrock | `https://aws.amazon.com/bedrock/` |-| Cohere | `https://cohere.com` |-| DeepSeek | `https://www.deepseek.com` |-| Fish Audio | `https://fish.audio` |-| FunASR | `https://github.com/modelscope/FunASR` |-| FuturMix | `https://futurmix.ai` |-| Gemini | `https://gemini.google.com` |-| Google Cloud | `https://cloud.google.com` |-| GPUStack | `https://gpustack.ai` |-| Groq | `https://groq.com` |-| GreenPT | `https://greenpt.ai` |-| HuggingFace | `https://huggingface.co` |-| Jina | `https://jina.ai` |-| LocalAI | `https://localai.io` |-| LongCat | `https://longcat.chat` |-| LM-Studio | `https://lmstudio.ai` |-| MiniMax | `https://www.minimaxi.com` |-| MinerU | `https://mineru.net/` |-| Mistral | `https://mistral.ai` |-| ModelScope | `https://www.modelscope.cn` |-| Moonshot | `https://www.moonshot.cn` |-| MWS | `https://mws.ru/docs/cloud-platform/gpt.html` |-| NovitaAI | `https://novita.ai` |-| NVIDIA | `https://www.nvidia.com` |-| Ollama | `https://ollama.com` |-| OpenAI | `https://openai.com` |+| Provider | URL |+| --- | --- |+| 302.AI | `https://302.ai` |+| aimlapi.com | `https://aimlapi.com` |+| Anthropic | `https://www.anthropic.com` |+| Astraflow | `https://astraflow.ucloud-global.com/en-us` |+| Astraflow-CN | `https://astraflow.ucloud.cn/` |+| Avian | `https://www.avian.io` |+| Azure-OpenAI | `https://azure.microsoft.com/en-us/products/ai-services/openai-service` |+| BaiChuan | `https://www.baichuan-ai.com` |+| BaiduYiyan | `https://yiyan.baidu.com` |+| Bedrock | `https://aws.amazon.com/bedrock/` |+| Cohere | `https://cohere.com` |+| CometAPI | `https://cometapi.com` |+| DeepInfra | `https://deepinfra.com` |+| DeepSeek | `https://www.deepseek.com` |+| DeerAPI | `https://deerapi.com` |+| Fish Audio | `https://fish.audio` |+| FunASR | `https://github.com/modelscope/FunASR` |+| FuturMix | `https://futurmix.ai` |+| Gemini | `https://gemini.google.com` |+| GiteeAI | — |+| Google Cloud | `https://cloud.google.com` |+| GPUStack | `https://gpustack.ai` |+| GreenPT | `https://greenpt.ai` |+| Groq | `https://groq.com` |+| HuggingFace | `https://huggingface.co` |+| Jiekou.AI | `https://jiekou.ai` |+| Jina | `https://jina.ai` |+| LM-Studio | `https://lmstudio.ai` |+| LocalAI | `https://localai.io` |+| LongCat | `https://longcat.chat` |+| MiniMax | `https://www.minimaxi.com` |+| MinerU | `https://mineru.net/` |+| Mistral | `https://mistral.ai` |+| Mistral OCR | — |+| ModelScope | `https://www.modelscope.cn` |+| Moonshot | `https://www.moonshot.cn` |+| MWS | `https://mws.ru/docs/cloud-platform/gpt.html` |+| n1n | — |+| New API | — |+| NVIDIA | `https://www.nvidia.com` |+| NovitaAI | `https://novita.ai` |+| Ollama | `https://ollama.com` |+| OpenAI | `https://openai.com` || OpenAI-API-Compatible | N/A |-| OpenRouter | `https://openrouter.ai` |-| Perplexity | `https://www.perplexity.ai` |-| Replicate | `https://replicate.com` |-| PPIO | `https://ppio.com` |-| SILICONFLOW | `https://siliconflow.cn` |-| StepFun | `https://www.stepfun.com` |-| Tencent Hunyuan | `https://hunyuan.tencent.com` |-| Tencent Cloud | `https://cloud.tencent.com` |-| TogetherAI | `https://www.together.ai` |-| TokenPony | `https://tokenpony.cn` |-| Tongyi-Qianwen | `https://tongyi.aliyun.com` |-| Upstage | `https://www.upstage.ai` |-| VLLM | `https://vllm.ai` |-| VolcEngine | `https://www.volcengine.com` |-| Voyage AI | `https://www.voyageai.com` |-| Xinference | `https://github.com/xorbitsai/inference` |-| XunFei Spark | `https://xinghuo.xfyun.cn` |-| xAI | `https://x.ai` |-| ZHIPU-AI | `https://www.zhipuai.cn` |-| DeepInfra | `https://deepinfra.com` |-| 302.AI | `https://302.ai` |-| CometAPI | `https://cometapi.com` |-| DeerAPI | `https://deerapi.com` |-| Jiekou.AI | `https://jiekou.ai` |+| OpenDataLoader | — |+| OpenRouter | `https://openrouter.ai` |+| PaddleOCR | — |+| Perplexity | `https://www.perplexity.ai` |+| PPIO | `https://ppio.com` |+| RAGcon | — |+| Replicate | `https://replicate.com` |+| SILICONFLOW | `https://siliconflow.cn` |+| SoMark | — |+| StepFun | `https://www.stepfun.com` |+| Tencent Cloud | `https://cloud.tencent.com` |+| Tencent Hunyuan | `https://hunyuan.tencent.com` |+| TogetherAI | `https://www.together.ai` |+| TokenPony | `https://tokenpony.cn` |+| Tongyi-Qianwen | `https://tongyi.aliyun.com` |+| Upstage | `https://www.upstage.ai` |+| VLLM | `https://vllm.ai` |+| VolcEngine | `https://www.volcengine.com` |+| Voyage AI | `https://www.voyageai.com` |+| xAI | `https://x.ai` |+| Xiaomi | — |+| Xinference | `https://github.com/xorbitsai/inference` |+| XunFei Spark | `https://xinghuo.xfyun.cn` |+| ZHIPU-AI | `https://www.zhipuai.cn` |```mdx-code-block</APITable>diff --git a/web/src/locales/zh.ts b/web/src/locales/zh.tsindex cd24c9e3ae..1ed9a0f5a8 100644--- a/web/src/locales/zh.ts+++ b/web/src/locales/zh.ts@@ -128,7 +128,7 @@ export default {enterSpace: '进入',spaceCreated: 'Skills 空间创建成功',spaceDeleted: 'Skills 空间删除成功',- fetchError: '获取 Skills 列表列表失败',+ fetchError: '获取 Skills 列表失败',deleteSpaceTitle: '删除 Skills 空间',deleteSpaceDescription:'确定要删除此 Skills 空间吗?此操作无法撤销,该空间中的所有 Skills 将被永久删除。',@@ -137,7 +137,7 @@ export default {uploadError: 'Skills 上传失败',deleteSuccess: 'Skills 删除成功',deleteError: 'Skills 删除失败',- skillExists: '同名 Skills 已已存在,请先删除或使用其他名称',+ skillExists: '同名 Skills 已存在,请先删除或使用其他名称',uploadSkill: '上传 Skills',searchPlaceholder: '搜索 Skills...',noSkills: '暂无 Skills,上传您的第一个 Skill',@@ -2055,7 +2055,7 @@ NER:使用 spaCy NER 和基于规则的关键词提取来抽取 Entities 和 RgraphContent: '完整 Graph 内容',docCount: '{{count}} 个文档',deleteAllTitle: '删除 PageIndex',- deleteAllDescription: '确定要删除整个 PageIndex 吗吗?此操作无法撤销。',+ deleteAllDescription: '确定要删除整个 PageIndex 吗?此操作无法撤销。',deleteNodeTitle: '删除 PageIndex',deleteNodeDescription: '确定要删除该节点及其子节点吗?',},