
RAGFlow is an agent-native database: a Retrieval-Augmented Generation (RAG) engine that grew into context infrastructure.
Go agent-harnessagent-native-databaseagentic-aiagentic-retrievalagentic-searchaiai-agentscontext-enginecontext-engineeringcontext-managementharness-engineeringknowledge-compilationragretrieval-augmented-generationretrieval-harnesssearch-harness
docs:Improve local model deployment and provider configuration docs (#21002)
YanZhang271f601ca2e5
diff --git a/docs/faq.mdx b/docs/faq.mdxindex 0eded1b533..7c263f08f8 100644--- a/docs/faq.mdx+++ b/docs/faq.mdx@@ -312,7 +312,7 @@ Use the [system health API](./references/http_api_reference.md#check-system-heal### How do I run RAGFlow with a locally deployed LLM?-You can use Ollama or Xinference to deploy a local LLM. See [Deploy a local LLM](./guides/models/deploy_local_llm.mdx) for configuration details.+You can use Ollama or vLLM to deploy local models. See [Deploy Local Models](./guides/models/deploy_local_llm.mdx) for configuration instructions.---diff --git a/docs/guides/models/deploy_local_llm.mdx b/docs/guides/models/deploy_local_llm.mdxindex 1d6401c9c3..9a8f9db1f8 100644--- a/docs/guides/models/deploy_local_llm.mdx+++ b/docs/guides/models/deploy_local_llm.mdx@@ -7,384 +7,291 @@ sidebar_custom_props: {categoryIcon: LucideMonitorCog}---+# Deploy Local Models-import Tabs from '@theme/Tabs';-import TabItem from '@theme/TabItem';-Deploy and run local models using Ollama, Xinference, vLLM ,SGLang , GPUStack or other frameworks.+Deploy and run local models using Ollama or vLLM, then connect them to RAGFlow.----RAGFlow supports deploying models locally using Ollama, Xinference, IPEX-LLM, vLLM ,SGLang , GPUStack or jina. If you have locally deployed models to leverage or wish to enable GPU or CUDA for inference acceleration, you can bind Ollama or Xinference into RAGFlow and use either of them as a local "server" for interacting with your local models.+RAGFlow supports lightweight local inference with Ollama and GPU-accelerated serving with vLLM. This guide uses [MiniCPM5-2B](https://huggingface.co/openbmb/MiniCPM5-2B), a compact Apache-2.0-licensed chat model with Chinese and English support, for both deployment methods.-RAGFlow seamlessly integrates with Ollama and Xinference, without the need for further environment configurations. You can use them to deploy two types of local models in RAGFlow: chat models and embedding models.+## Before You Begin-:::tip NOTE-This user guide does not intend to cover much of the installation or configuration details of Ollama or Xinference; its focus is on configurations inside RAGFlow. For the most current information, you may need to check out the official site of Ollama or Xinference.-:::+This guide provides simple Ollama and vLLM deployment examples for new RAGFlow users. It focuses on starting a local model and connecting it to RAGFlow rather than covering every installation or production deployment option. For complete setup, platform, and configuration instructions, see the [Ollama documentation](https://docs.ollama.com/) and the [vLLM documentation](https://docs.vllm.ai/).-## Deploy Local Models Using Ollama+| Purpose | Ollama model name | vLLM source model ID | vLLM served model name |+| --- | --- | --- | --- |+| Chat | `openbmb/minicpm5-2b` | `openbmb/MiniCPM5-2B` | `MiniCPM5-2B` |-[Ollama](https://github.com/ollama/ollama) enables you to run open-source large language models that you deployed locally. It bundles model weights, configurations, and data into a single package, defined by a Modelfile, and optimizes setup and configurations, including GPU usage.+Ollama uses its registry name. vLLM downloads the model using its Hugging Face repository ID, while RAGFlow and other API clients use the name assigned by `--served-model-name`.:::note-- For information about downloading Ollama, see [here](https://github.com/ollama/ollama?tab=readme-ov-file#ollama).-- For a complete list of supported models and variants, see the [Ollama model library](https://ollama.com/library).+MiniCPM5-2B is a chat model, not an embedding model. To create and parse a RAGFlow knowledge base, you must also configure an embedding model. The Ollama instructions below use `qwen3-embedding:0.6b` as a lightweight example.:::-### 1. Deploy Ollama Using Docker+## Deploy MiniCPM5-2B Using Ollama-Ollama can be [installed from binaries](https://ollama.com/download) or [deployed with Docker](https://hub.docker.com/r/ollama/ollama). Here are the instructions to deploy with Docker:+[Ollama](https://github.com/ollama/ollama) packages model weights and configuration for straightforward local inference. See the [Ollama download page](https://ollama.com/download) for native installation options.-```bash-$ sudo docker run --name ollama -p 11434:11434 ollama/ollama-> time=2024-12-02T02:20:21.360Z level=INFO source=routes.go:1248 msg="Listening on [::]:11434 (version 0.4.6)"-> time=2024-12-02T02:20:21.360Z level=INFO source=common.go:49 msg="Dynamic LLM libraries" runners="[cpu cpu_avx cpu_avx2 cuda_v11 cuda_v12]"-```+### 1. Start Ollama Using Docker-Ensure Ollama is listening on all IP address:-```bash-$ sudo ss -tunlp | grep 11434-> tcp LISTEN 0 4096 0.0.0.0:11434 0.0.0.0:* users:(("docker-proxy",pid=794507,fd=4))-> tcp LISTEN 0 4096 [::]:11434 [::]:* users:(("docker-proxy",pid=794513,fd=4))-```+Run Ollama in the background and expose its default port:-Pull models as you need. We recommend that you start with `llama3.2` (a 3B chat model) and `bge-m3` (a 567M embedding model):-```bash-$ sudo docker exec ollama ollama pull llama3.2-> pulling dde5aa3fc5ff... 100% ▕████████████████▏ 2.0 GB-> success-```+:::caution+Before publishing port `11434`, confirm that the host firewall does not allow public inbound access to this port. Allow access only from the host or trusted private networks.+:::```bash-$ sudo docker exec ollama ollama pull bge-m3-> pulling daec91ffb5dd... 100% ▕████████████████▏ 1.2 GB-> success+sudo docker run -d \+ --name ollama \+ --restart unless-stopped \+ -p 11434:11434 \+ -v ollama:/root/.ollama \+ ollama/ollama```-### 2. Find Ollama URL and Ensure It Is Accessible+The `ollama` volume keeps downloaded models available if the container is removed and recreated.-- If RAGFlow runs in Docker, the localhost is mapped within the RAGFlow Docker container as `host.docker.internal`. If Ollama runs on the same host machine, the right URL to use for Ollama would be `http://host.docker.internal:11434/' and you should check that Ollama is accessible from inside the RAGFlow container with:-```bash-$ sudo docker exec -it docker-ragflow-cpu-1 bash-$ curl http://host.docker.internal:11434/-> Ollama is running-```+If the container already exists, start it with:-- If RAGFlow is launched from source code and Ollama runs on the same host machine as RAGFlow, check if Ollama is accessible from RAGFlow's host machine:```bash-$ curl http://localhost:11434/-> Ollama is running+sudo docker start ollama```-- If RAGFlow and Ollama run on different machines, check if Ollama is accessible from RAGFlow's host machine:-```bash-$ curl http://${IP_OF_OLLAMA_MACHINE}:11434/-> Ollama is running-```--### 3. Add Ollama--In RAGFlow, click on your logo on the top right of the page **>** **Model providers** and add Ollama to RAGFlow:-+This reuses the container's existing storage configuration. If the container was originally created without the `ollama:/root/.ollama` volume, recreate it with the command above to enable model persistence.+:::tip+See the [Ollama Docker image documentation](https://hub.docker.com/r/ollama/ollama) to enable NVIDIA or AMD GPU acceleration.+:::-### 4. Complete Basic Ollama Settings--In the popup window, complete basic settings for Ollama:--1. Ensure that your model name and type match those been pulled at step 1 (Deploy Ollama using Docker). For example, (`llama3.2` and `chat`) or (`bge-m3` and `embedding`).-2. Put in the Ollama base URL, i.e. `http://host.docker.internal:11434`, `http://localhost:11434` or `http://${IP_OF_OLLAMA_MACHINE}:11434`.-3. OPTIONAL: Switch on the toggle under **Does it support Vision?** if your model includes an image-to-text model.+### 2. Pull MiniCPM5-2B+Pull the chat model:-:::caution WARNING-Improper base URL settings will trigger the following error:```bash-Max retries exceeded with url: /api/chat (Caused by NewConnectionError('<urllib3.connection.HTTPConnection object at 0xffff98b81ff0>: Failed to establish a new connection: [Errno 111] Connection refused'))+sudo docker exec ollama ollama pull openbmb/minicpm5-2b```-:::--### 5. Update System Model Settings-Click on your logo **>** **Model providers** **>** **System Model Settings** to update your model:--- *You should now be able to find **llama3.2** from the dropdown list under **Chat model**, and **bge-m3** from the dropdown list under **Embedding model**.*--### 6. Update Chat Configuration--Update your model(s) accordingly in **Chat Configuration**.--## Deploy a Local Model Using Xinference--Xorbits Inference ([Xinference](https://github.com/xorbitsai/inference)) enables you to unleash the full potential of cutting-edge AI models.--:::note-- For information about installing Xinference Ollama, see [here](https://inference.readthedocs.io/en/latest/getting_started/).-- For a complete list of supported models, see the [Builtin Models](https://inference.readthedocs.io/en/latest/models/builtin/).-:::--To deploy a local model, e.g., **Mistral**, using Xinference:--### 1. Check Firewall Settings--Ensure that your host machine's firewall allows inbound connections on port 9997.--### 2. Start an Xinference Instance+If you intend to create a knowledge base, also pull a lightweight embedding model:```bash-$ xinference-local --host 0.0.0.0 --port 9997+sudo docker exec ollama ollama pull qwen3-embedding:0.6b```-### 3. Launch Your Local Model--Launch your local model (**Mistral**), ensuring that you replace `${quantization}` with your chosen quantization method:+List the downloaded models:```bash-$ xinference launch -u mistral --model-name mistral-v0.1 --size-in-billions 7 --model-format pytorch --quantization ${quantization}+curl http://localhost:11434/api/tags```-### 4. Add Xinference--In RAGFlow, click on your logo on the top right of the page **>** **Model providers** and add Xinference to RAGFlow:--### 5. Complete Basic Xinference Settings+The response should list `openbmb/minicpm5-2b` and, if you pulled it, `qwen3-embedding:0.6b`.-Enter an accessible base URL, such as `http://<your-xinference-endpoint-domain>:9997/v1`.-> For rerank model, please use the `http://<your-xinference-endpoint-domain>:9997/v1/rerank` as the base URL.+### 3. Test the Ollama Chat Model-### 6. Update System Model Settings+Send a test request directly to Ollama:-Click on your logo **>** **Model providers** **>** **System Model Settings** to update your model.--*You should now be able to find **mistral** from the dropdown list under **Chat model**.*--### 7. Update Chat Configuration--Update your chat model accordingly in **Chat Configuration**:+```bash+curl http://localhost:11434/api/chat \+ -d '{+ "model": "openbmb/minicpm5-2b",+ "messages": [+ {+ "role": "user",+ "content": "Briefly explain how retrieval-augmented generation reduces hallucinations."+ }+ ],+ "stream": false+ }'+```-## Deploy a Local Model Using IPEX-LLM+A successful response contains an assistant message with generated content.-[IPEX-LLM](https://github.com/intel-analytics/ipex-llm) is a PyTorch library for running LLMs on local Intel CPUs or GPUs (including iGPU or discrete GPUs like Arc, Flex, and Max) with low latency. It supports Ollama on Linux and Windows systems.+### 4. Make Ollama Accessible to RAGFlow-To deploy a local model, e.g., **Qwen2**, using IPEX-LLM-accelerated Ollama:+Use the URL that matches your deployment:-### 1. Check Firewall Settings+| Deployment | Ollama base URL |+| --- | --- |+| RAGFlow runs in Docker and Ollama runs on the same host | `http://host.docker.internal:11434` |+| RAGFlow and Ollama run directly on the same host | `http://localhost:11434` |+| Ollama runs on another machine | `http://<OLLAMA_HOST_IP>:11434` |-Ensure that your host machine's firewall allows inbound connections on port 11434. For example:+When RAGFlow runs in Docker, first find the actual RAGFlow container name:```bash-sudo ufw allow 11434/tcp+sudo docker ps \+ --filter "label=com.docker.compose.service=ragflow-cpu" \+ --format '{{.Names}}'```-### 2. Launch Ollama Service Using IPEX-LLM+Then replace `<RAGFLOW_CONTAINER>` below with the returned name and verify connectivity from that container:-#### 2.1 Install IPEX-LLM for Ollama+```bash+sudo docker exec -it <RAGFLOW_CONTAINER> \+ curl http://host.docker.internal:11434/api/tags+```-:::tip NOTE-IPEX-LLM's supports Ollama on Linux and Windows systems.+:::caution+Do not expose port `11434` directly to the public internet. Restrict access with a firewall or private network.:::-For detailed information about installing IPEX-LLM for Ollama, see [Run llama.cpp with IPEX-LLM on Intel GPU Guide](https://github.com/intel-analytics/ipex-llm/blob/main/docs/mddocs/Quickstart/llama_cpp_quickstart.md):-- [Prerequisites](https://github.com/intel-analytics/ipex-llm/blob/main/docs/mddocs/Quickstart/llama_cpp_quickstart.md#0-prerequisites)-- [Install IPEX-LLM cpp with Ollama binaries](https://github.com/intel-analytics/ipex-llm/blob/main/docs/mddocs/Quickstart/llama_cpp_quickstart.md#1-install-ipex-llm-for-llamacpp)--*After the installation, you should have created a Conda environment, e.g., `llm-cpp`, for running Ollama commands with IPEX-LLM.*--#### 2.2 Initialize Ollama--1. Activate the `llm-cpp` Conda environment and initialize Ollama:--<Tabs- defaultValue="linux"- values={[- {label: 'Linux', value: 'linux'},- {label: 'Windows', value: 'windows'},- ]}>- <TabItem value="linux">+### 5. Add Ollama to RAGFlow- ```bash- conda activate llm-cpp- init-ollama- ```- </TabItem>- <TabItem value="windows">+1. In RAGFlow, click your avatar in the upper-right corner and select **Model providers**.+2. Find **Ollama** and add a provider instance.+3. Enter the accessible Ollama base URL from the previous step.+4. Leave **API Key** empty.+5. Add `openbmb/minicpm5-2b` as a **Chat** model.+6. If you pulled the embedding model, add `qwen3-embedding:0.6b` as an **Embedding** model.+7. Verify models individually, or click **Verify all models** to verify every model currently shown by the active search and type filters.+8. Save the provider instance.- Run these commands with *administrator privileges in Miniforge Prompt*:+The model names must exactly match the names returned by Ollama.- ```cmd- conda activate llm-cpp- init-ollama.bat- ```- </TabItem>-</Tabs>+Successful verification indicates that RAGFlow can reach Ollama and call the selected models.-2. If the installed `ipex-llm[cpp]` requires an upgrade to the Ollama binary files, remove the old binary files and reinitialize Ollama using `init-ollama` (Linux) or `init-ollama.bat` (Windows).+### 6. Use the Models in RAGFlow- *A symbolic link to Ollama appears in your current directory, and you can use this executable file following standard Ollama commands.*+- Select `openbmb/minicpm5-2b` as the chat model in **Set default models** or your chat configuration.+- Select `qwen3-embedding:0.6b` as the embedding model when creating a knowledge base.-#### 2.3 Launch Ollama Service+## Deploy MiniCPM5-2B Using vLLM-1. Set the environment variable `OLLAMA_NUM_GPU` to `999` to ensure that all layers of your model run on the Intel GPU; otherwise, some layers may default to CPU.-2. For optimal performance on Intel Arc™ A-Series Graphics with Linux OS (Kernel 6.2), set the following environment variable before launching the Ollama service:+[vLLM](https://docs.vllm.ai/) provides a high-throughput OpenAI-compatible server for GPU inference. This example serves MiniCPM5-2B as a chat model.- ```bash- export SYCL_PI_LEVEL_ZERO_USE_IMMEDIATE_COMMANDLISTS=1- ```-3. Launch the Ollama service:+### 1. Install vLLM-<Tabs- defaultValue="linux"- values={[- {label: 'Linux', value: 'linux'},- {label: 'Windows', value: 'windows'},- ]}>- <TabItem value="linux">+Create and activate a dedicated Python environment, then install vLLM:- ```bash- export OLLAMA_NUM_GPU=999- export no_proxy=localhost,127.0.0.1- export ZES_ENABLE_SYSMAN=1- source /opt/intel/oneapi/setvars.sh- export SYCL_CACHE_PERSISTENT=1-- ./ollama serve- ```-- </TabItem>- <TabItem value="windows">-- Run the following command *in Miniforge Prompt*:+```bash+python3 -m venv .venv+source .venv/bin/activate+python -m pip install --upgrade pip vllm+```- ```cmd- set OLLAMA_NUM_GPU=999- set no_proxy=localhost,127.0.0.1- set ZES_ENABLE_SYSMAN=1- set SYCL_CACHE_PERSISTENT=1+For supported GPUs and platform-specific instructions, see the [official vLLM installation guide](https://docs.vllm.ai/en/latest/getting_started/installation/).- ollama serve- ```- </TabItem>-</Tabs>+### 2. Start MiniCPM5-2B+Start the OpenAI-compatible API server:-:::tip NOTE-To enable the Ollama service to accept connections from all IP addresses, use `OLLAMA_HOST=0.0.0.0 ./ollama serve` rather than simply `./ollama serve`.+:::caution+The following command listens on all network interfaces. Before starting it, confirm that the host firewall does not allow public inbound access to port `8000`. Allow access only from trusted hosts or private networks.:::-The console displays service startup messages.---### 3. Pull and Run Ollama Model--#### 3.1 Pull Ollama Model--With the Ollama service running, open a new terminal and run `./ollama pull <model_name>` (Linux) or `ollama.exe pull <model_name>` (Windows) to pull the desired model. e.g., `qwen2:latest`:---#### 3.2 Run Ollama Model--<Tabs- defaultValue="linux"- values={[- {label: 'Linux', value: 'linux'},- {label: 'Windows', value: 'windows'},- ]}>- <TabItem value="linux">-- ```bash- ./ollama run qwen2:latest- ```- </TabItem>- <TabItem value="windows">+```bash+vllm serve openbmb/MiniCPM5-2B \+ --served-model-name MiniCPM5-2B \+ --host 0.0.0.0 \+ --port 8000 \+ --dtype auto \+ --max-model-len 8192+```- ```cmd- ollama run qwen2:latest- ```+`--served-model-name` defines the model name that clients, including RAGFlow, must use. The example limits the context length to 8192 tokens to reduce GPU memory consumption.- </TabItem>-</Tabs>+Keep this terminal running while vLLM serves the model, and open another terminal for the verification commands below.-### 4. Configure RAGFlow+The example starts vLLM without authentication. To require an API key, add `--api-key <API_KEY>` to the `vllm serve` command. For example, an authenticated request to list the available models is:-To enable IPEX-LLM accelerated Ollama in RAGFlow, you must also complete the configurations in RAGFlow. The steps are identical to those outlined in the *Deploy a local model using Ollama* section:+```bash+curl http://localhost:8000/v1/models \+ -H "Authorization: Bearer <API_KEY>"+```-1. [Add Ollama](#3-add-ollama)-2. [Complete basic Ollama settings](#4-complete-basic-ollama-settings)-3. [Update System Model Settings](#6-update-system-model-settings)-4. [Update Chat Configuration](#7-update-chat-configuration)+When authentication is enabled, add this `Authorization` header to every vLLM verification request in this guide, including the chat request and the request run inside the RAGFlow container. Enter the same value in the RAGFlow **API Key** field when you configure the VLLM provider instance.-### 5. Deploy vLLM+### 3. Verify the vLLM Server-ubuntu 22.04/24.04+Check that the model is available:```bash-pip install vllm+curl http://localhost:8000/v1/models```-### 5.1 Run vLLM with Best Practise++The response should contain a model whose ID is `MiniCPM5-2B`.++Then send a chat request:```bash-nohup vllm serve /data/Qwen3-8B --served-model-name Qwen3-8B-FP8 --dtype auto --port 1025 --gpu-memory-utilization 0.90 --tool-call-parser hermes --enable-auto-tool-choice > /var/log/vllm_startup1.log 2>&1 &-```-you can get log info-```bash-tail -f -n 100 /var/log/vllm_startup1.log-```-when see the follow ,it means vllm engine is ready for access-```bash-Starting vLLM API server 0 on http://0.0.0.0:1025-Started server process [19177]-Application startup complete.+curl http://localhost:8000/v1/chat/completions \+ -H "Content-Type: application/json" \+ -d '{+ "model": "MiniCPM5-2B",+ "messages": [+ {+ "role": "user",+ "content": "Briefly explain how retrieval-augmented generation reduces hallucinations."+ }+ ]+ }'```-### 5.2 Integrating RAGFlow with vLLM Chat/Em/Rerank LLM with WebUI-Go to **Settings** → **Model Providers** → **Search** → **vLLM** → **Add**; configure as follows:+A successful response contains generated text in the assistant message under `choices`.-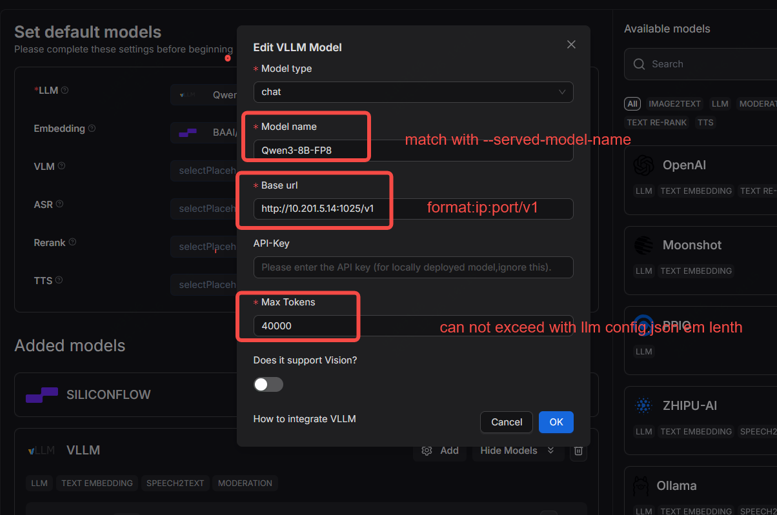+If you enabled vLLM API key authentication, use the following authenticated chat request instead:-Select the vLLM chat model as the default LLM model:+```bash+curl http://localhost:8000/v1/chat/completions \+ -H "Authorization: Bearer <API_KEY>" \+ -H "Content-Type: application/json" \+ -d '{+ "model": "MiniCPM5-2B",+ "messages": [+ {+ "role": "user",+ "content": "Briefly explain how retrieval-augmented generation reduces hallucinations."+ }+ ]+ }'+```-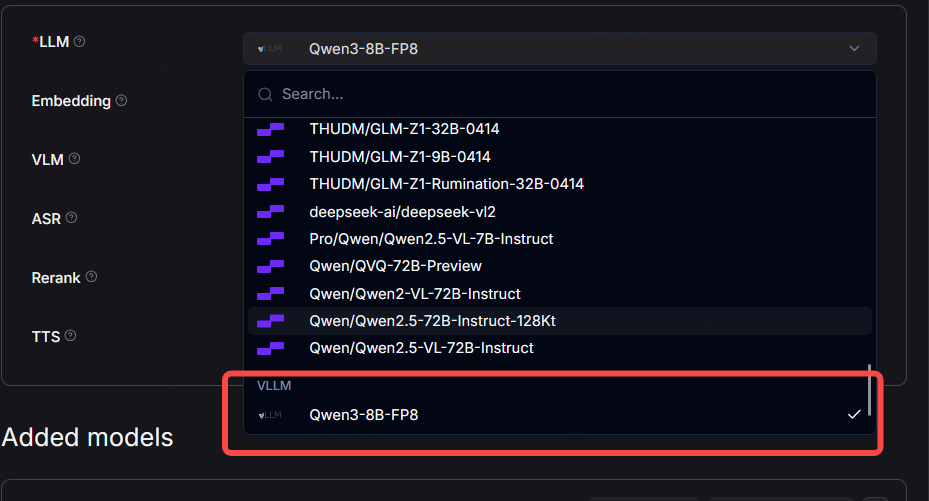+### 4. Make vLLM Accessible to RAGFlow-### 5.3 Chat with vLLM Chat Model+Use the URL that matches your deployment:-Create a chat and start a conversation as follows:+| Deployment | vLLM base URL |+| --- | --- |+| RAGFlow runs in Docker and vLLM runs on the same host | `http://host.docker.internal:8000/v1` |+| RAGFlow and vLLM run directly on the same host | `http://localhost:8000/v1` |+| vLLM runs on another machine | `http://<VLLM_HOST_IP>:8000/v1` |-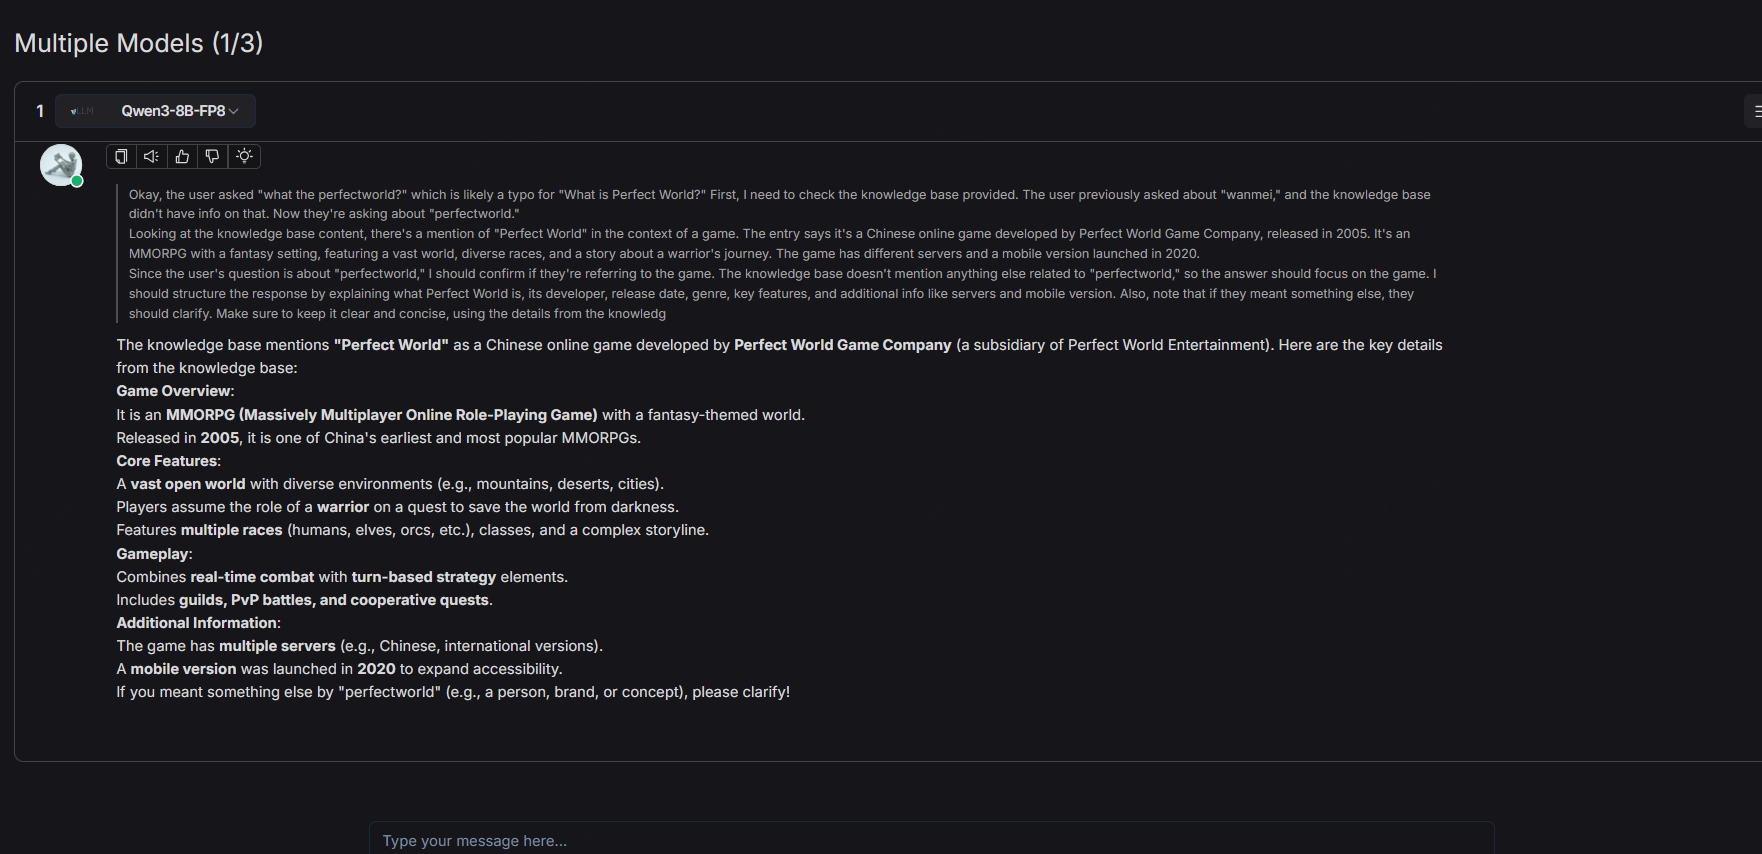+When RAGFlow runs in Docker, find the actual container name as described in the Ollama section above. Then replace `<RAGFLOW_CONTAINER>` with that name and verify connectivity from the container:-### 6. Deploy GPUStack+```bash+sudo docker exec -it <RAGFLOW_CONTAINER> \+ curl http://host.docker.internal:8000/v1/models+```-ubuntu 22.04/24.04+For a vLLM server without authentication, the response should contain a model whose ID is `MiniCPM5-2B`.-### 6.1 Run GPUStack with Best Practise+For an authenticated vLLM server, use this complete container connectivity check:```bash-sudo docker run -d --name gpustack \- --restart unless-stopped \- -p 80:80 \- -p 10161:10161 \- --volume gpustack-data:/var/lib/gpustack \- gpustack/gpustack-```-you can get docker info-```bash-docker ps-```-when see the follow ,it means vllm engine is ready for access-```bash-root@gpustack-prod:~# docker ps-CONTAINER ID IMAGE COMMAND CREATED STATUS PORTS NAMES-abf59be84b1a gpustack/gpustack "/usr/bin/entrypoint…" 6 hours ago Up 6 hours 0.0.0.0:80->80/tcp, [::]:80->80/tcp, 0.0.0.0:10161->10161/tcp, [::]:10161->10161/tcp gpustack+sudo docker exec -it <RAGFLOW_CONTAINER> \+ curl http://host.docker.internal:8000/v1/models \+ -H "Authorization: Bearer <API_KEY>"```-### 6.2 Integrating RAGFlow with GPUStack Chat/Em/Rerank LLM with WebUI--setting->model providers->search->gpustack->add ,configure as follow:-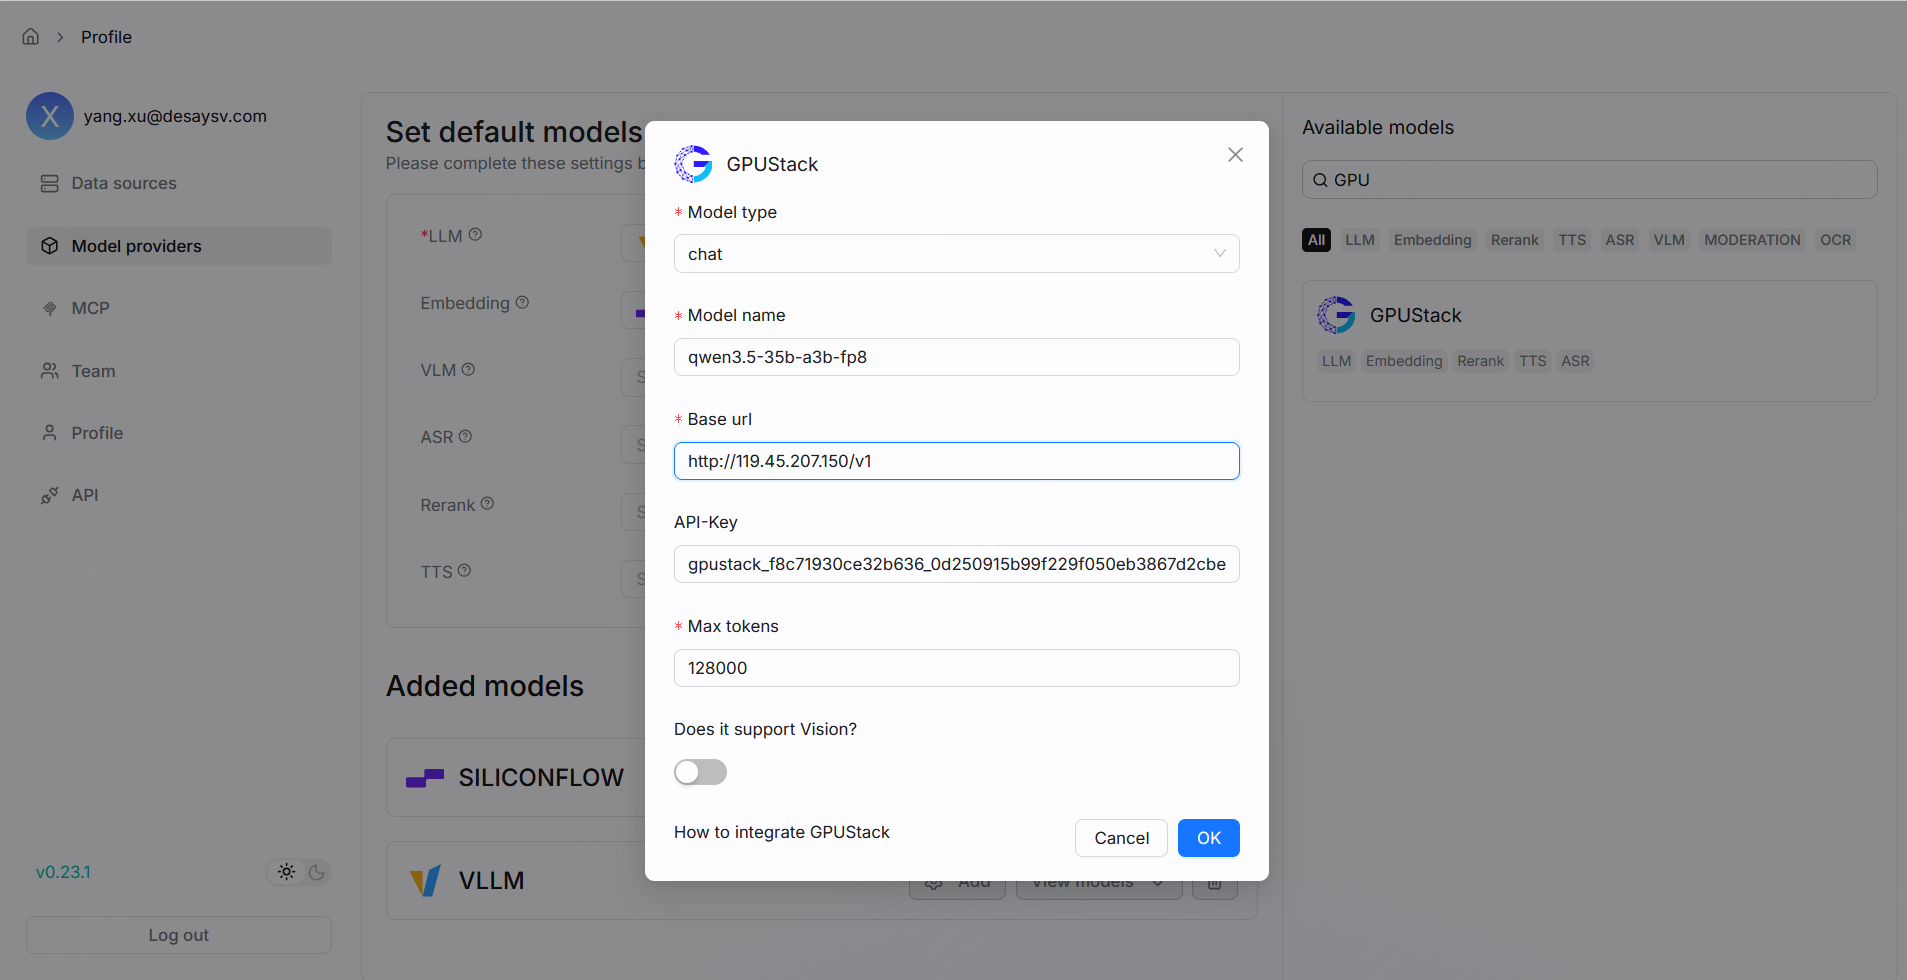+:::caution+Do not expose port `8000` directly to the public internet unless you have configured authentication and network access controls.+:::-Select the GPUStack chat model as the default LLM:+### 5. Add vLLM to RAGFlow-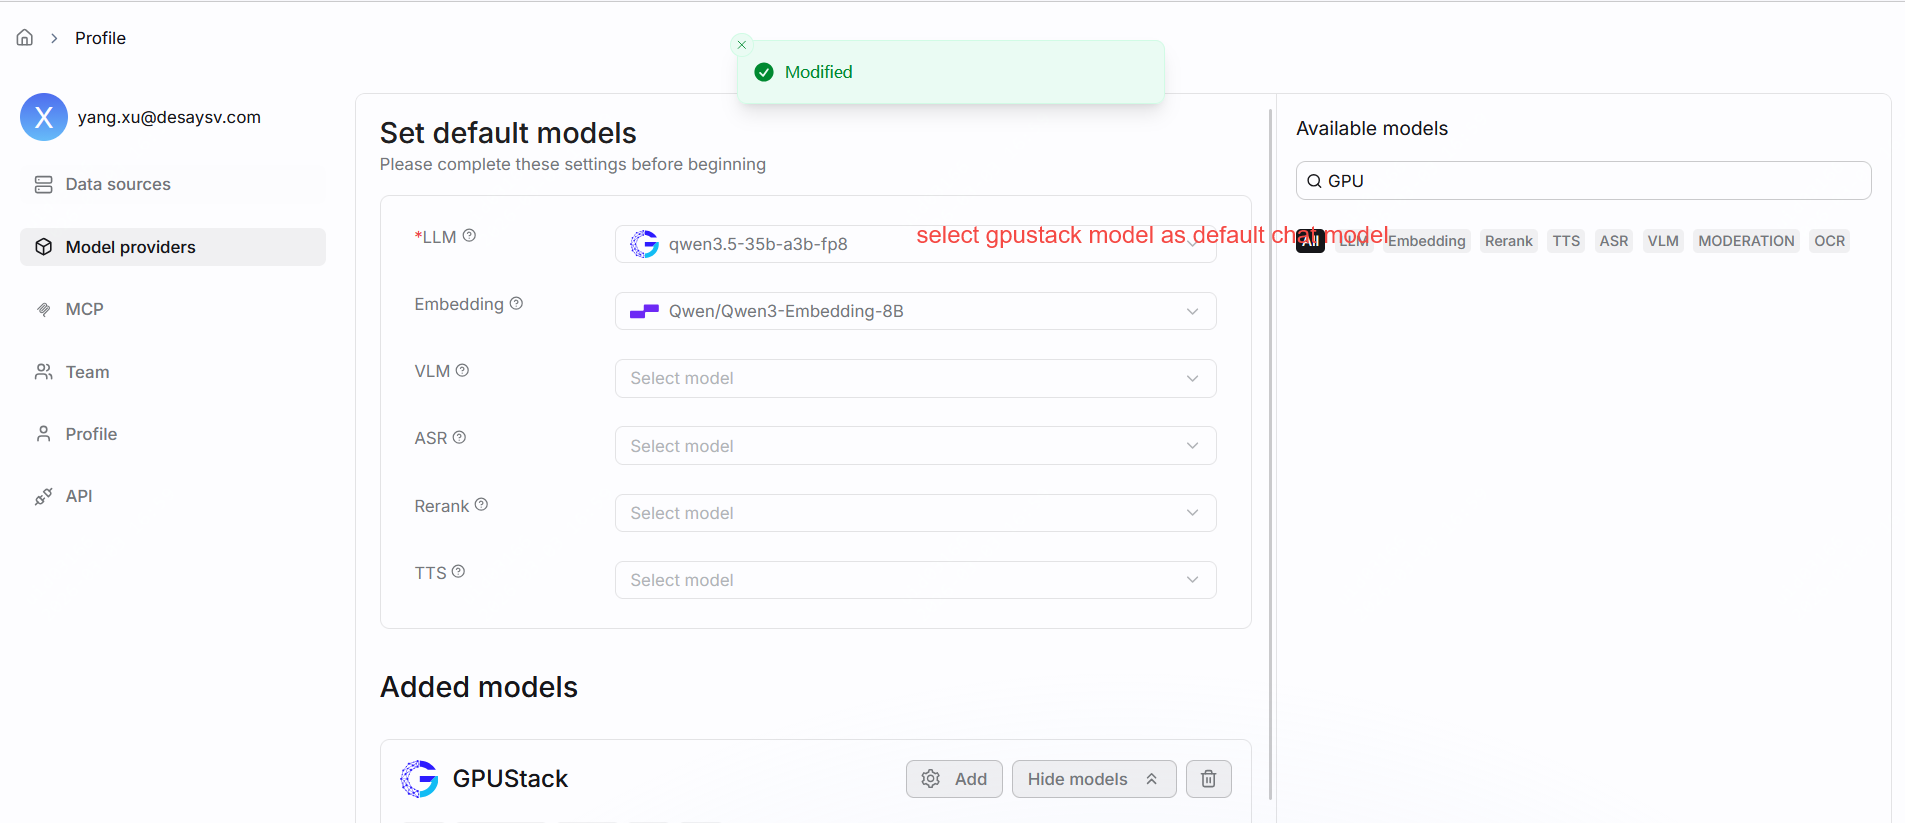+1. In RAGFlow, click your avatar in the upper-right corner and select **Model providers**.+2. Find **VLLM** and add a provider instance.+3. Enter the accessible base URL from the previous step.+4. Leave **API Key** empty unless you explicitly configured API key authentication for your vLLM server. If authentication is enabled, enter the actual API key.+5. Add `MiniCPM5-2B` as a **Chat** model. This name must match the value passed to `--served-model-name`.+6. Verify the added model.+7. Save the provider instance.+Select `MiniCPM5-2B` in **Set default models** or your chat configuration to start using it.+Successful verification indicates that RAGFlow can reach the vLLM server and call `MiniCPM5-2B`.+:::note+You can use the vLLM chat model with an embedding model from another provider. For example, use `MiniCPM5-2B` from vLLM for chat and `qwen3-embedding:0.6b` from Ollama for knowledge-base embeddings.+:::diff --git a/docs/guides/models/llm_api_key_setup.md b/docs/guides/models/llm_api_key_setup.mdindex 49cc0ab5d4..01e9633bc9 100644--- a/docs/guides/models/llm_api_key_setup.md+++ b/docs/guides/models/llm_api_key_setup.md@@ -1,37 +1,37 @@---sidebar_position: 1-title: Configure Model API Key-sidebar_label: Configure Model API Key+title: Configure Model Providers+sidebar_label: Configure Model Providersslug: /llm_api_key_setupsidebar_custom_props: {categoryIcon: LucideKey}----# Configure Model API Key+# Configure Model ProvidersRAGFlow model provider management allows you to connect online models, local models, and OpenAI-compatible models to RAGFlow for use in knowledge bases, chats, search, and agents.-## Get Model API Key+## Get a Model Provider API Key-RAGFlow supports most mainstream LLMs. You will need to apply for your model API key online.+RAGFlow supports most mainstream model providers. If an online provider uses API key authentication, obtain an API key from that provider before configuring it in RAGFlow. Local providers and providers that use other authentication methods may not require an API key.:::note-If you find your online LLM is not on the list, don't feel disheartened. The list is expanding, and you can [file a feature request](https://github.com/infiniflow/ragflow/issues/new?assignees=&labels=feature+request&projects=&template=feature_request.yml&title=%5BFeature+Request%5D%3A+) with us! Alternatively, if you have customized or locally-deployed models, you can [bind them to RAGFlow using Ollama, Xinference, or LocalAI](./deploy_local_llm.mdx).+If the model provider you need is not listed, don't feel disheartened. The list is expanding, and you can [file a feature request](https://github.com/infiniflow/ragflow/issues/new?assignees=&labels=feature+request&projects=&template=feature_request.yml&title=%5BFeature+Request%5D%3A+) with us! Alternatively, you can [connect locally deployed models to RAGFlow using Ollama or vLLM](./deploy_local_llm.mdx).:::## Add a Model Provider Instance### Select a Model Provider-Go to **User settings** **>** **Model providers**. In **Available models**, select a provider and complete its configuration. After the configuration succeeds, the provider is marked as **Configured**.+Go to **User settings** **>** **Model providers**. In **Available models**, select the provider you want to configure.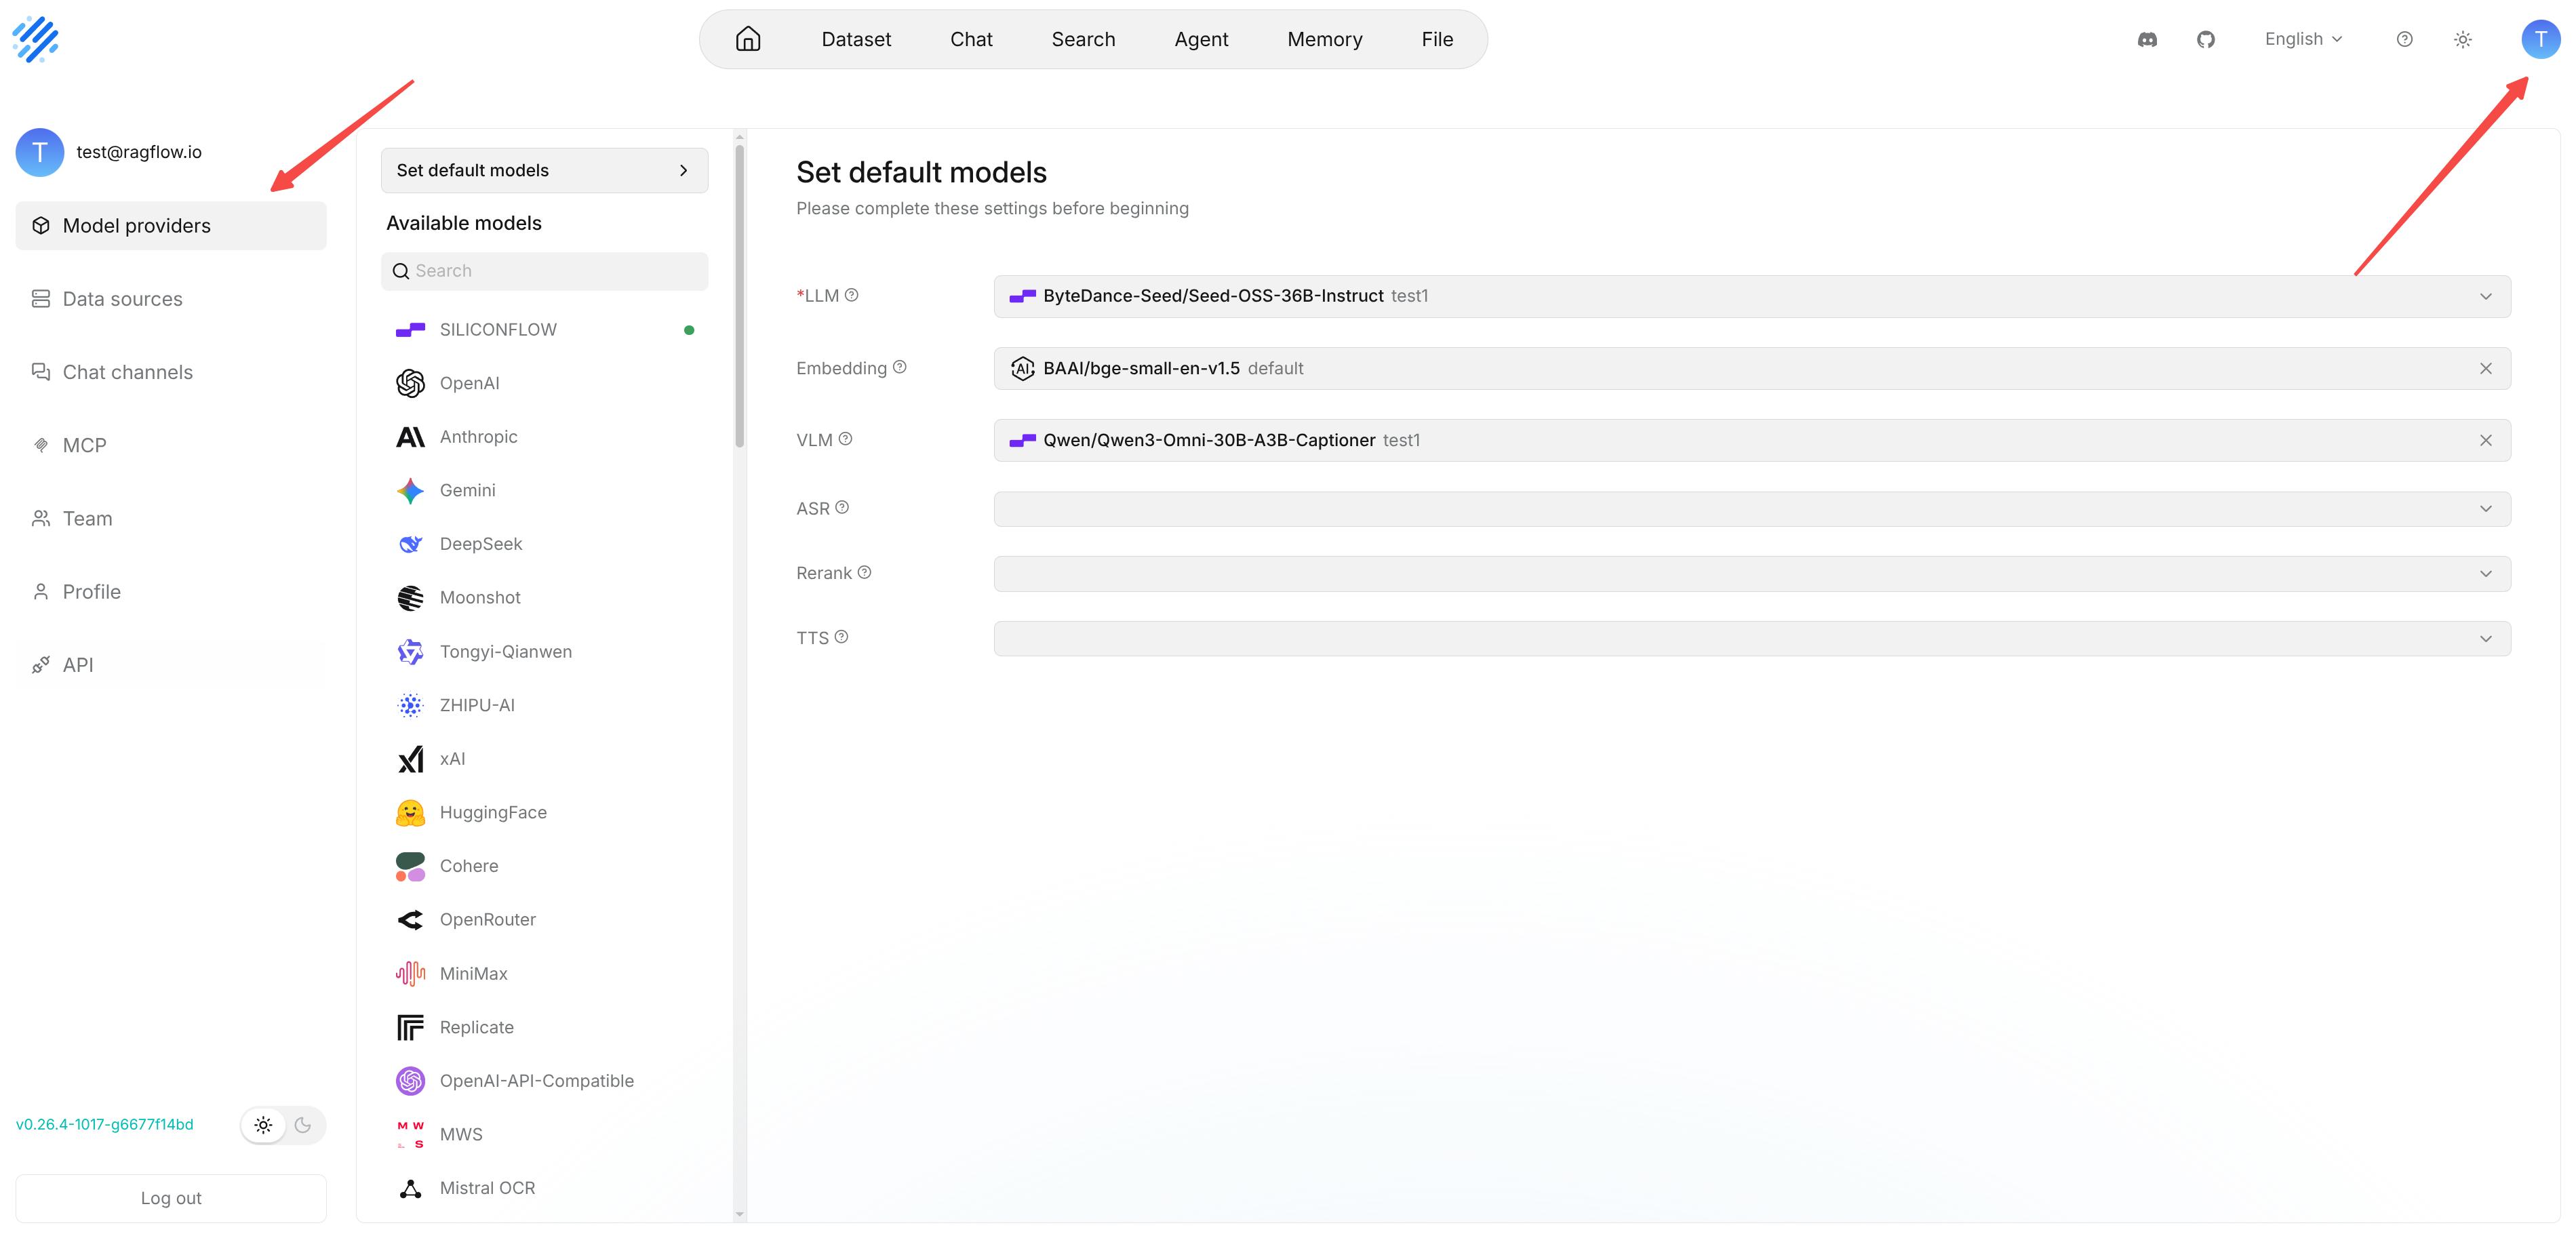### Create a Model Provider Instance and Configure Connection Information-An instance stores a set of connection settings under a provider. You can create separate instances for test environments, production environments, local models, or proxy gateways to avoid mixing configurations for different purposes. When you configure a provider for the first time, the right pane prompts you to create an instance first. After the instance is saved, you can continue to fill in **API Key** and **Base URL** and add models.+An instance stores a set of connection settings under a provider. You can create separate instances for test environments, production environments, local models, or proxy gateways to avoid mixing configurations for different purposes. Configure the instance name, connection information, and models in the instance card, verify the selected models, and then save the instance.-**API Key** is used for authentication. **Base URL** specifies the model service endpoint.+When present, **API Key** is used for authentication and **Base URL** specifies the model service endpoint. The required fields depend on the provider. For example, local providers such as Ollama and VLLM allow an empty API key, some official providers use a fixed endpoint, and Amazon Bedrock supports multiple authentication methods.For official providers, keep the default **Base URL** in most cases. For proxies, gateways, local models, or compatible APIs, enter the actual service address.@@ -39,13 +39,15 @@ To configure a model provider:1. Select the provider you want to configure.2. Enter an instance name.-3. Enter **API Key** and **Base URL**.-4. Save the instance.+3. Complete the required fields displayed for that provider.+4. Select models from the available model list or add custom models.+5. Verify models individually, or click **Verify all models** to verify every model currently shown by the active search and type filters.+6. Save the instance.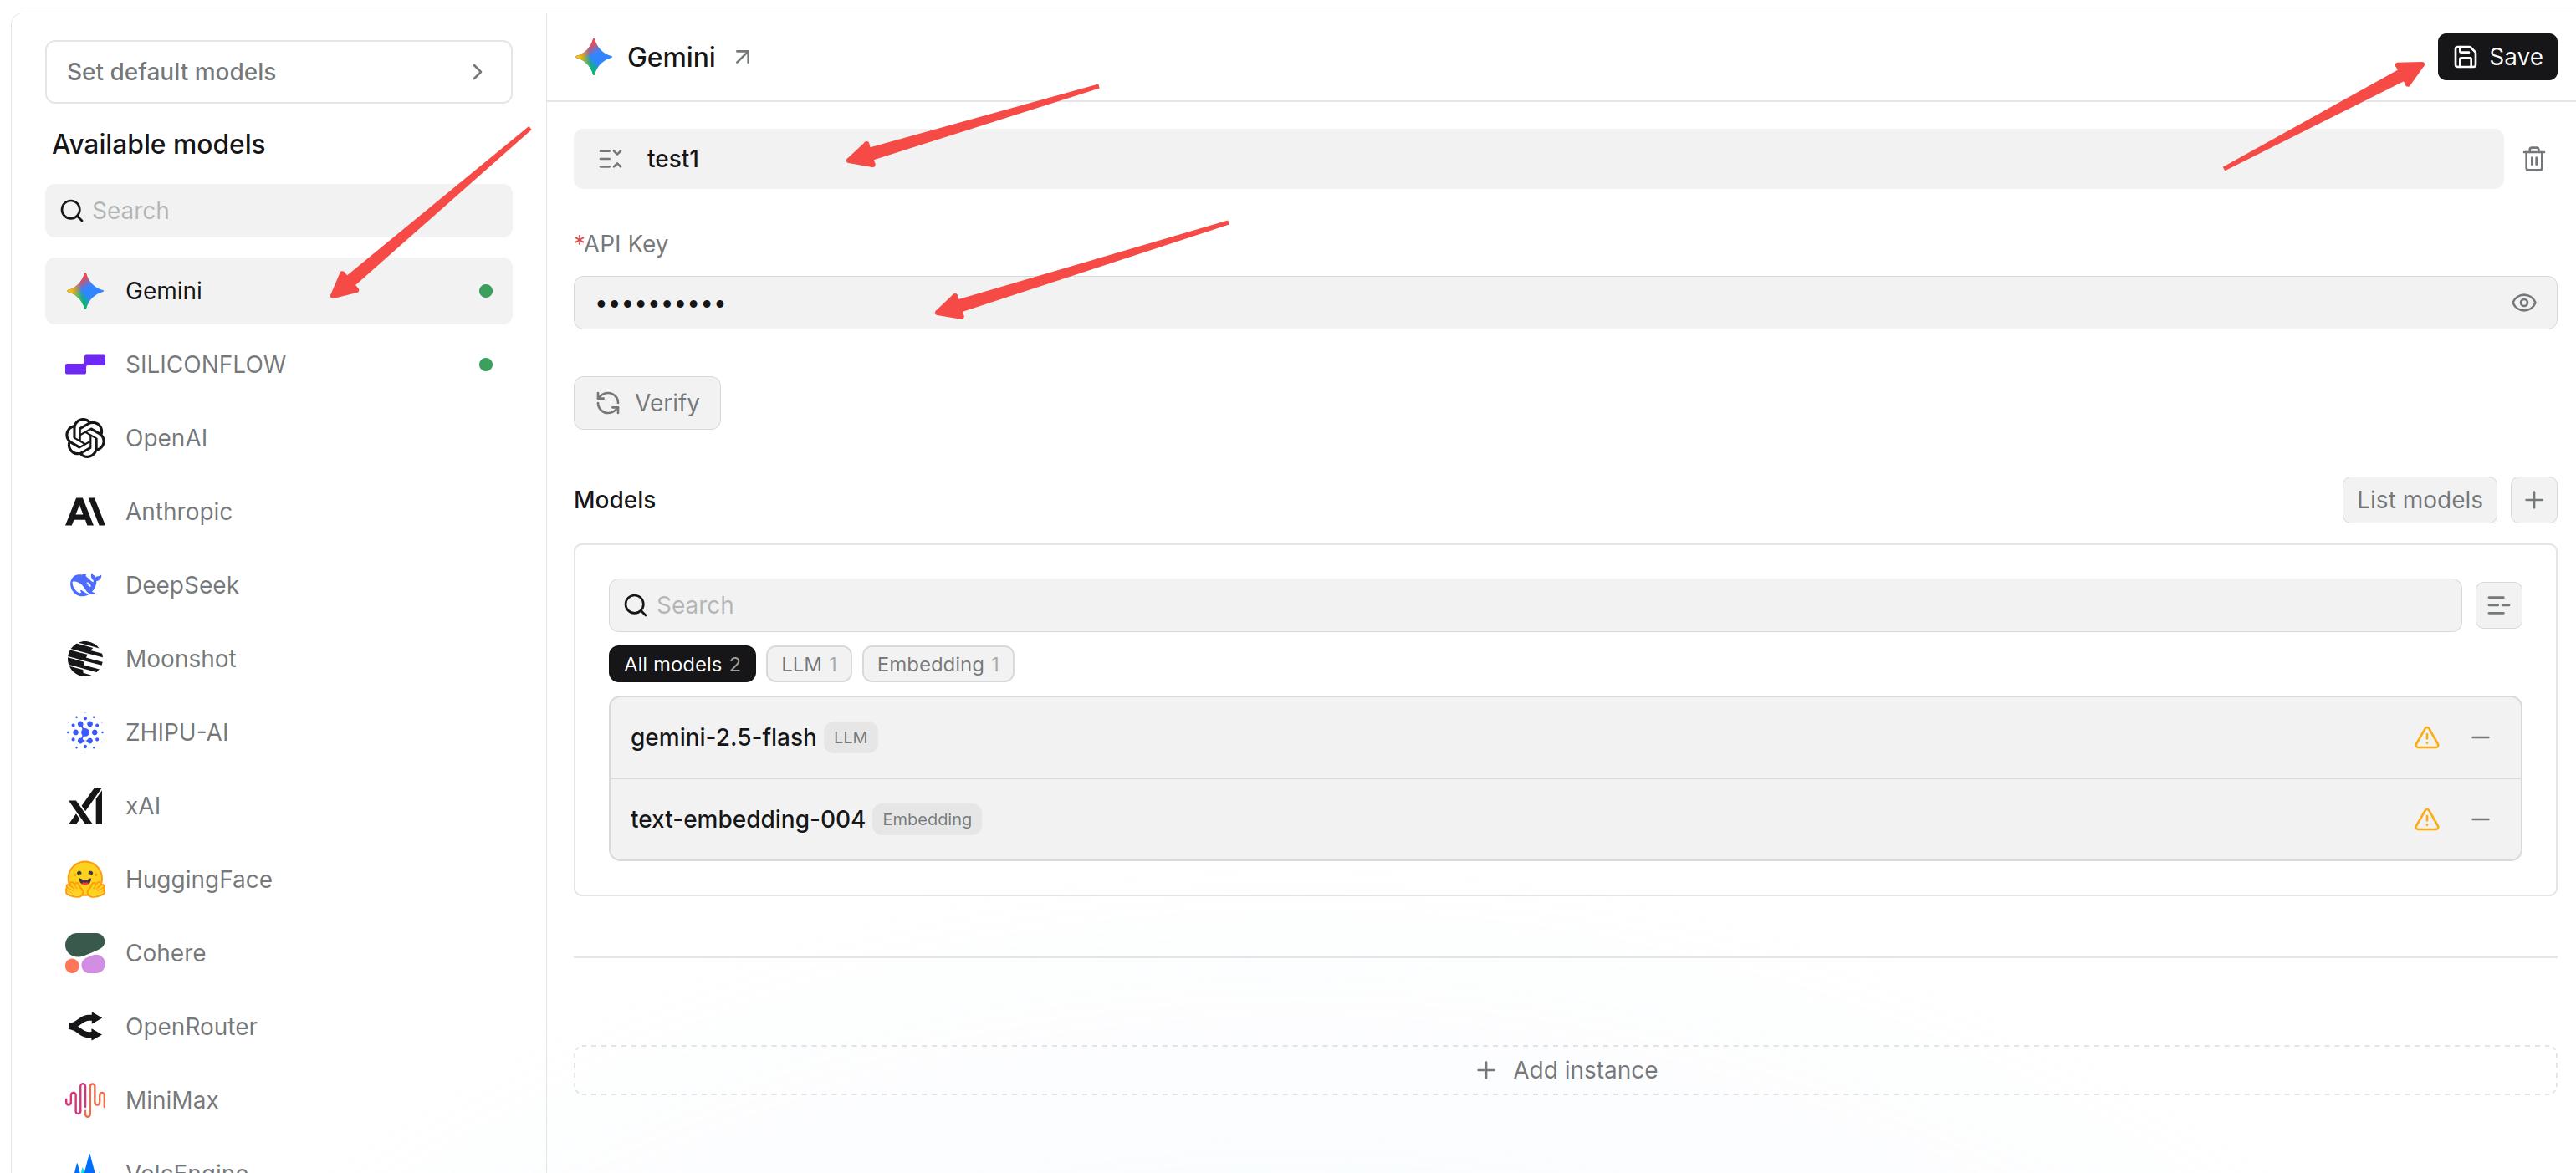:::caution-Do not expose your API Key. An incorrect Base URL causes connection verification or model calls to fail. When using a compatible API, confirm whether the path must include `/v1`.+Do not expose your API Key. An incorrect Base URL causes model verification or model calls to fail. When using a compatible API, confirm whether the path must include `/v1`.:::#### Amazon Bedrock API keys@@ -56,21 +58,15 @@ Bedrock API key authentication does not support rerank models.Use short-term Bedrock API keys for production whenever possible. Long-term keys remain valid until they expire or are deleted, so store them as secrets, restrict access to the RAGFlow instance, and rotate them regularly.-### Verify the Connection--After filling in **API Key** and **Base URL**, verify the connection first. If verification fails, check the API Key, Base URL, network connection, account quota, and model availability.--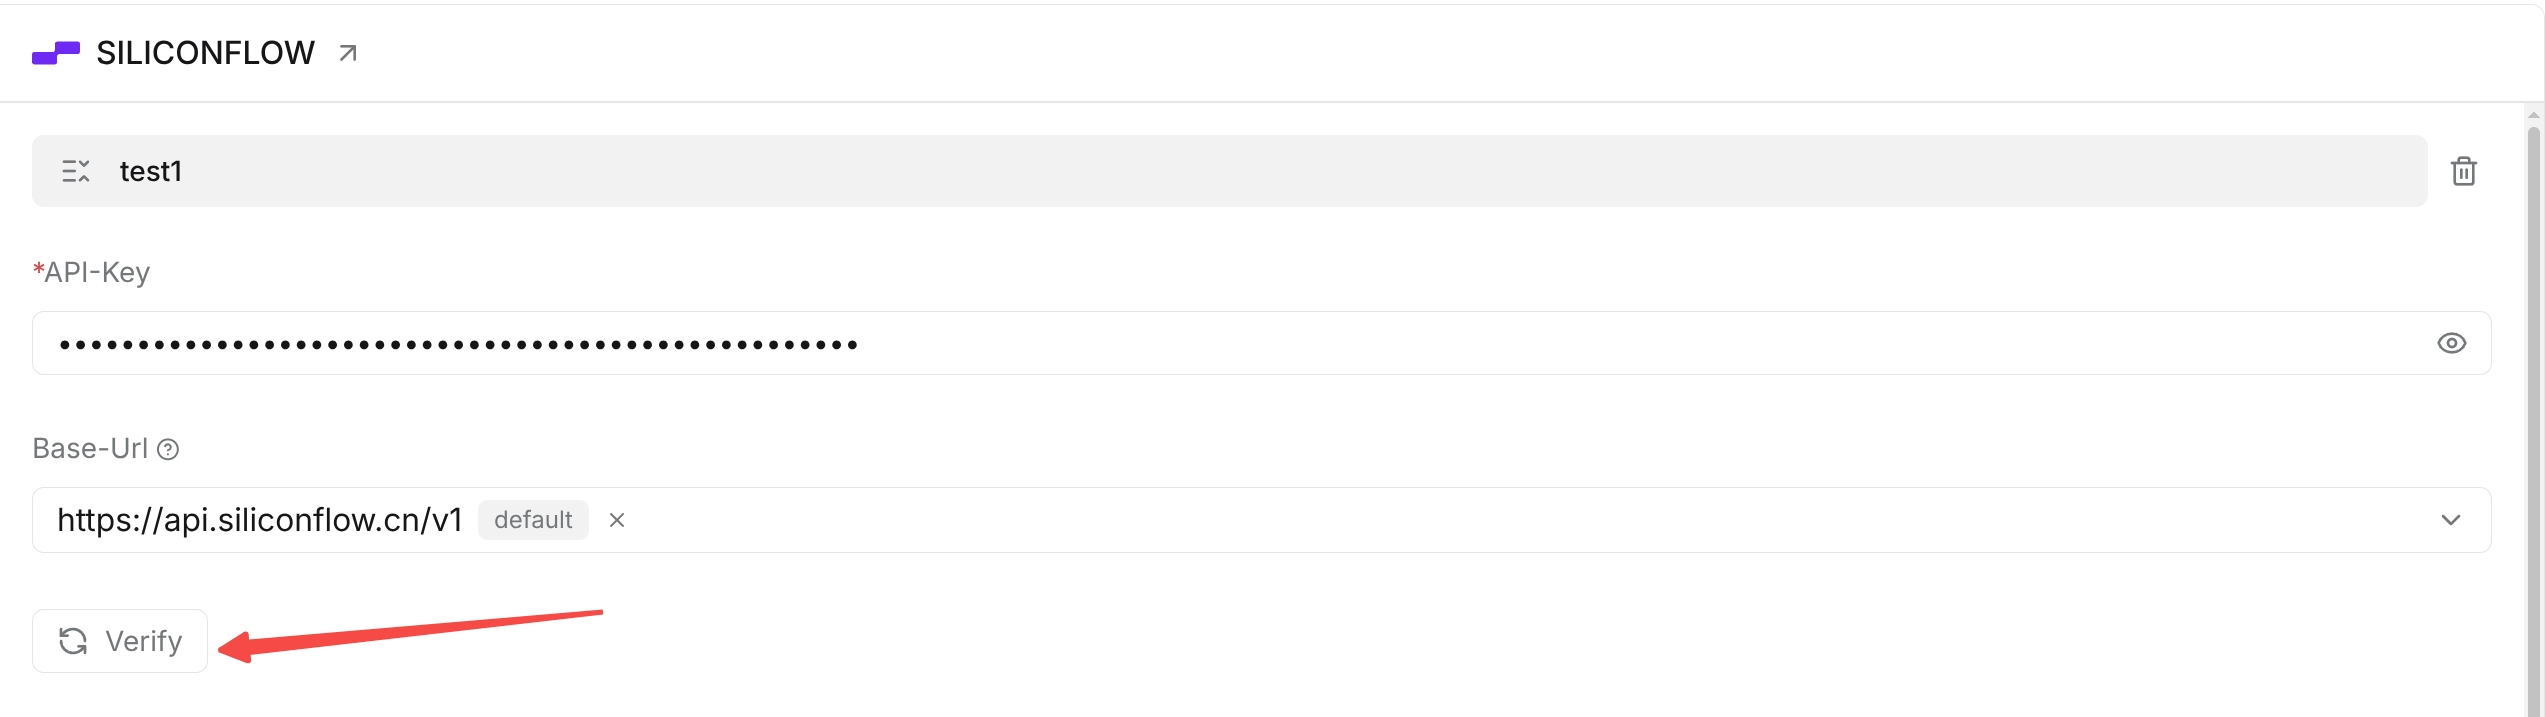-## Add Models to an Instance-After you add a model provider instance and the connection verification succeeds, you can add and configure models for this instance. Add the model types required by your business, such as large language models (LLMs), embedding models, vision-language models (VLMs), automatic speech recognition models (ASR), rerank models, and text-to-speech models (TTS).+In the provider instance card, add and configure the models required by your business, such as large language models (LLMs), embedding models, vision-language models (VLMs), automatic speech recognition models (ASR), rerank models, and text-to-speech models (TTS).After adding models, you can set them as the default models for the corresponding model types.### Add Models from the List-After the model instance connection succeeds, RAGFlow automatically displays some models supported by the model provider. You can search for the models you need and add them one by one, or add the models in the current list in batch.+RAGFlow displays models discovered from the provider together with any models defined in its built-in catalog. You can search for the models you need and add them one by one, or add the models in the current list in batch.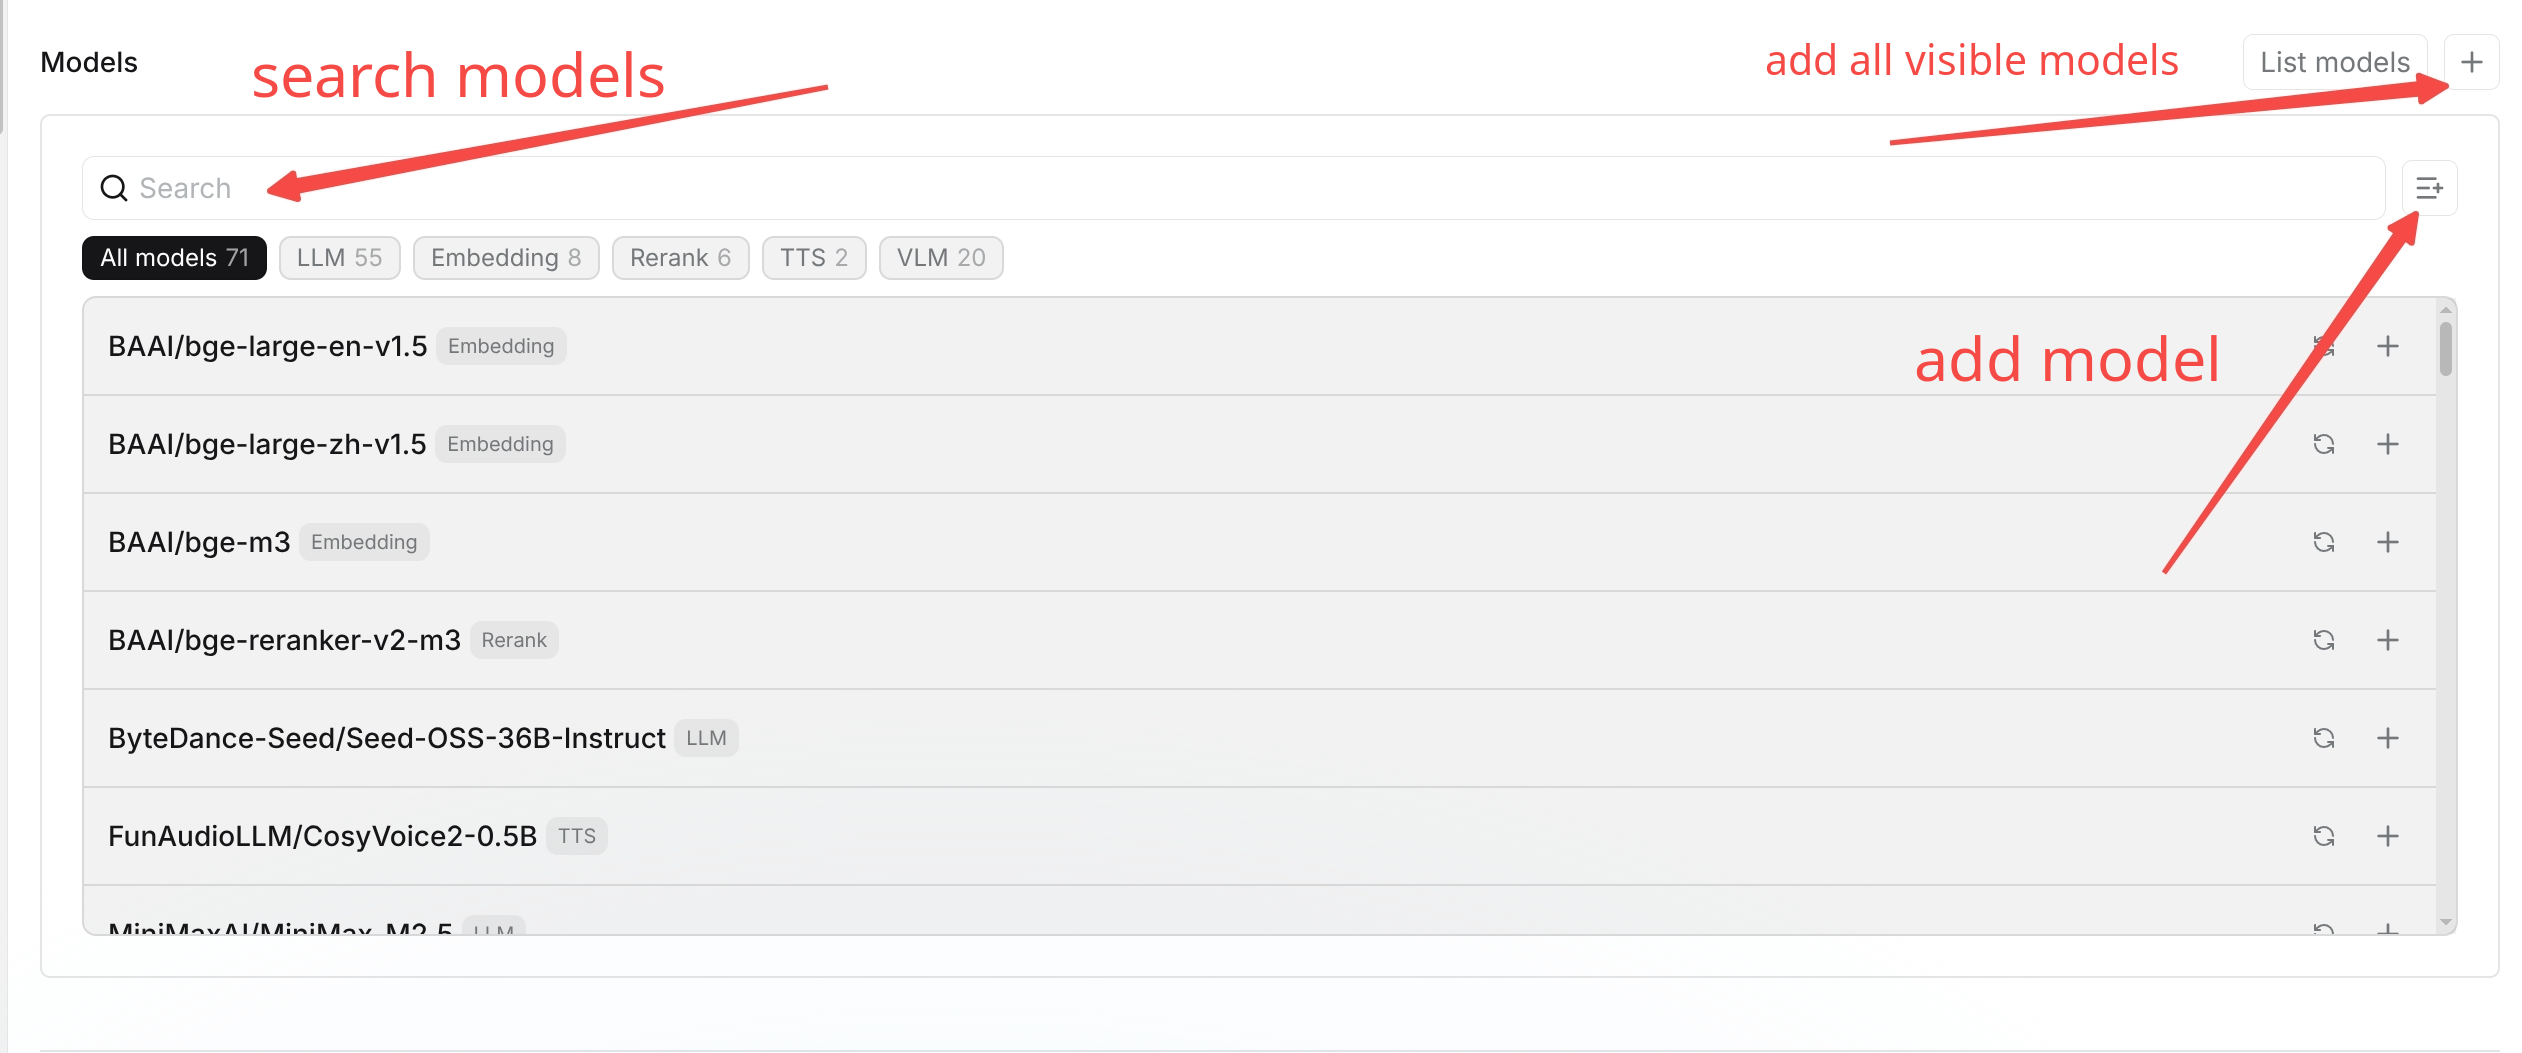@@ -85,14 +81,21 @@ To add a custom model:1. Go to the configured provider instance and click **Add custom model**.2. Enter the model name. The name must match the actual model identifier provided by the provider.3. Select the corresponding model type.-4. Fill in **Max tokens** according to the model capability. This value sets the maximum number of tokens the model can generate in one call.-5. If the model supports tool calling, enable **Tool call**. After it is enabled, the model can call external tools or functions during chats or agent runs, such as knowledge retrieval or API requests. Do not enable it for models that do not support this capability.-6. Click **Confirm** to save the model, and verify whether the model is available through an actual call.+4. Optionally fill in **Max context length** to override the detected value or provide one when the provider does not return it. This value sets the maximum number of tokens the model can process in its context, including the input and generated output. If you do not need to override it, keep the default value.+5. If the model supports tool calling, enable **Tool calling**. After it is enabled, the model can call external tools or functions during chats or agent runs, such as knowledge retrieval or API requests. Do not enable it for models that do not support this capability.+6. Click **Confirm** to add the model.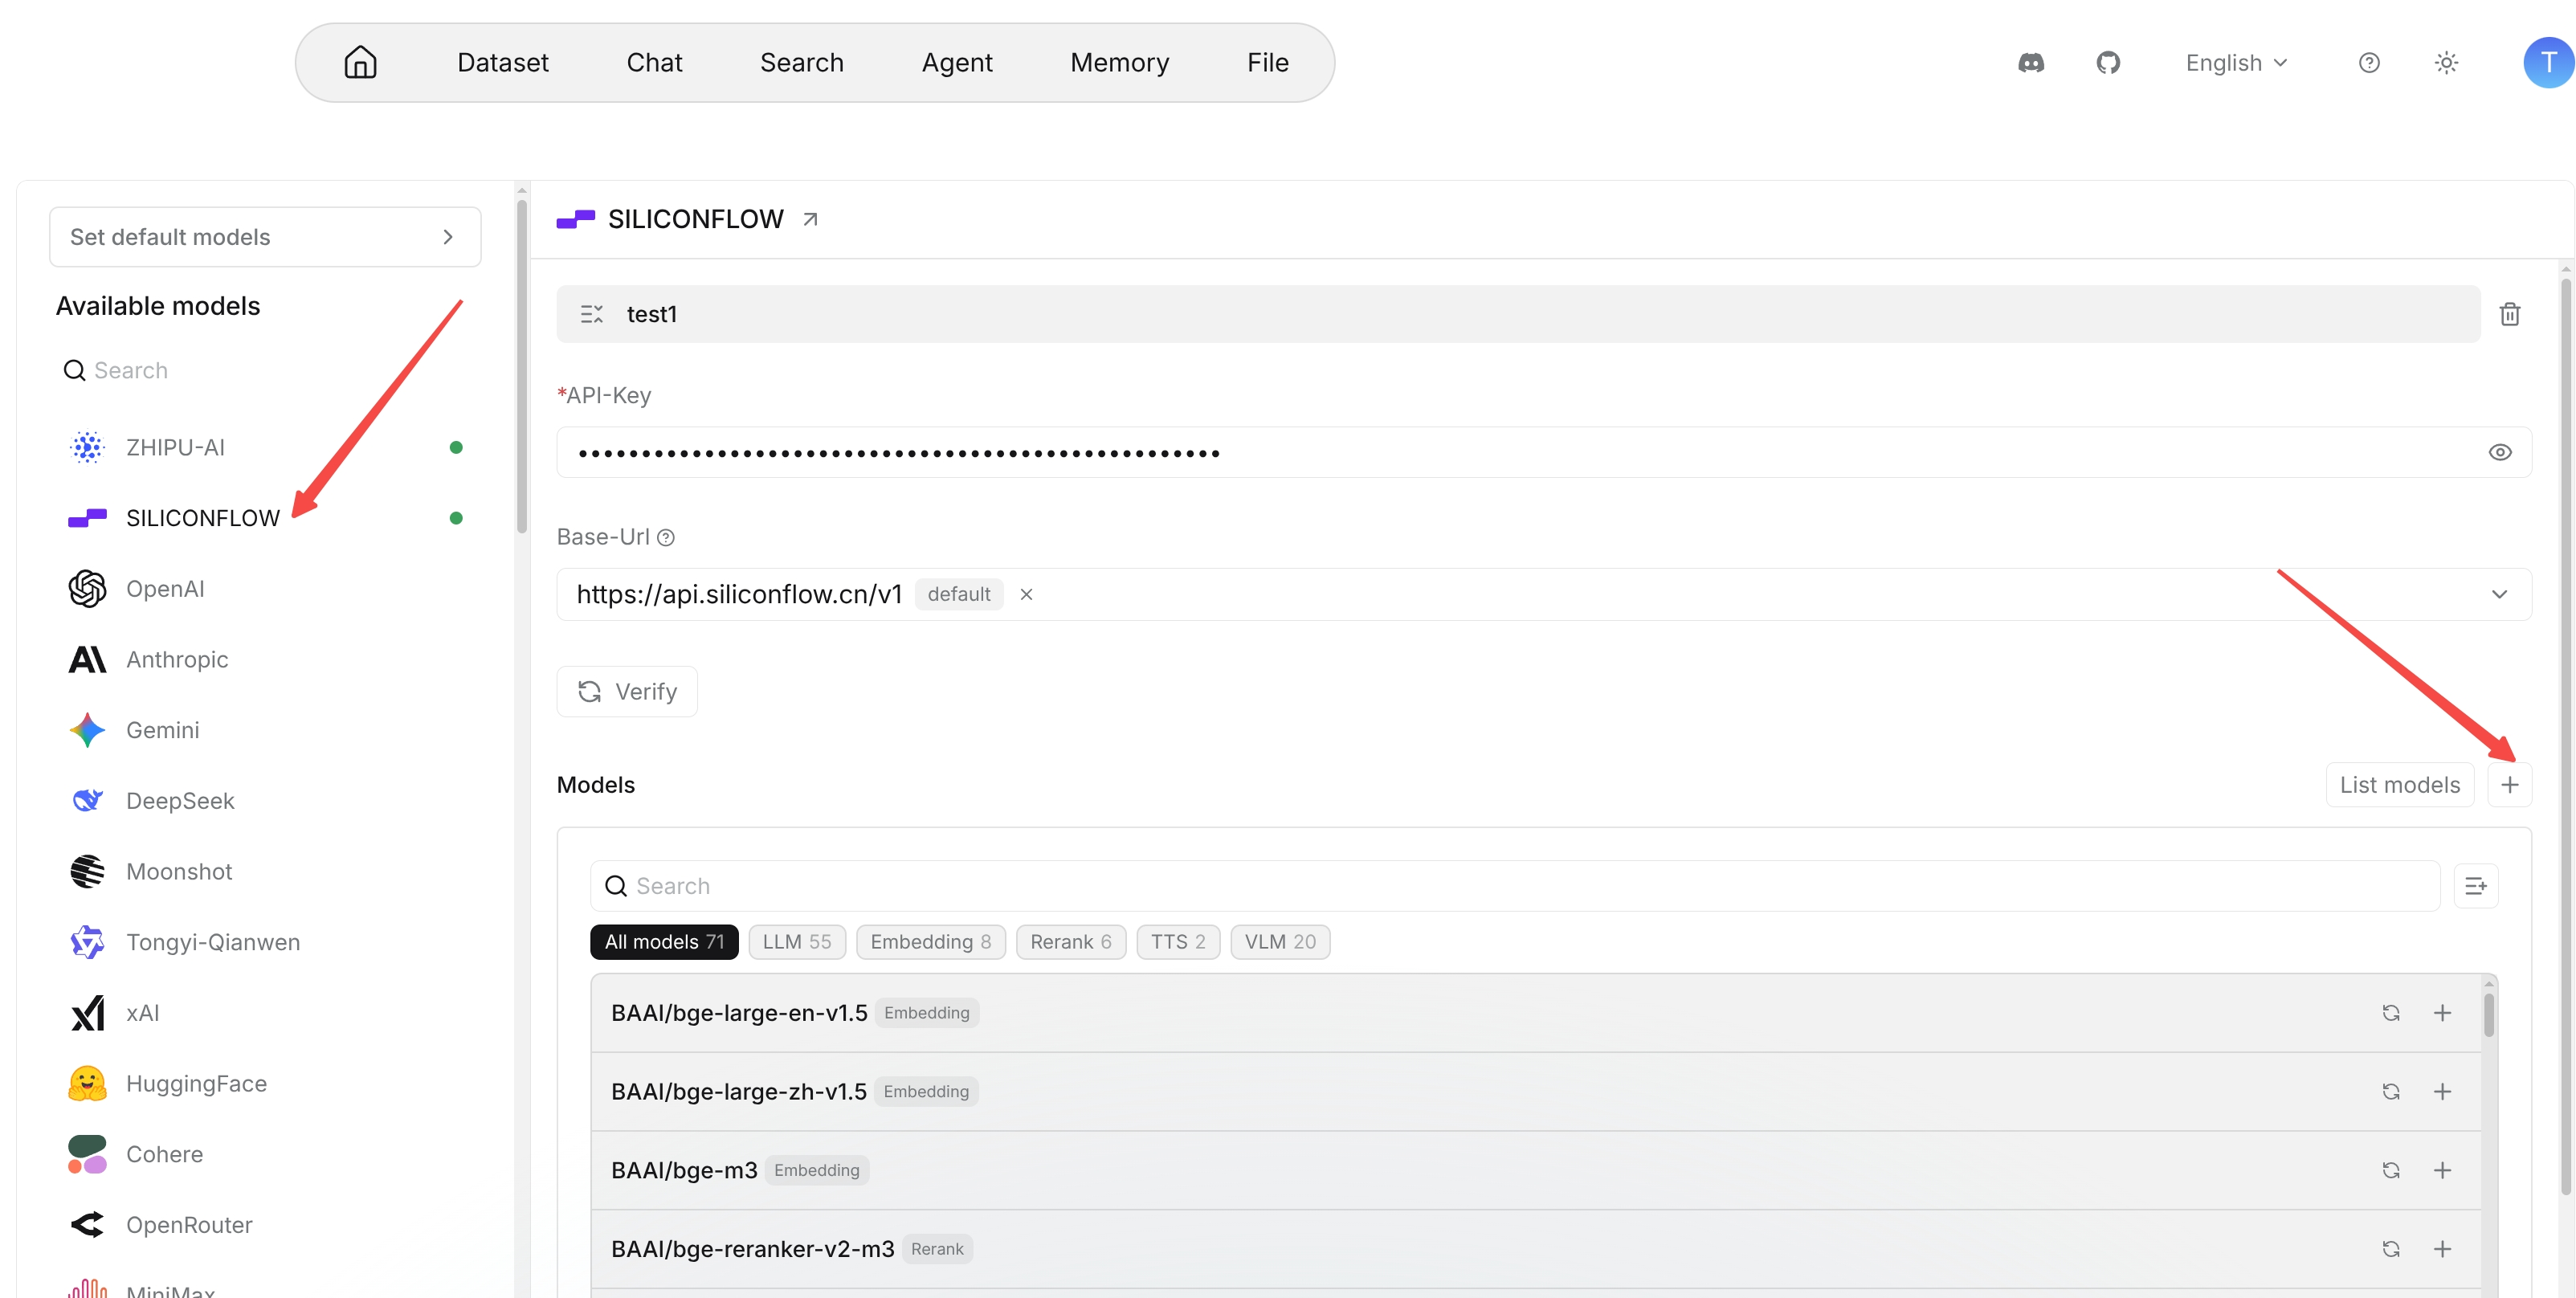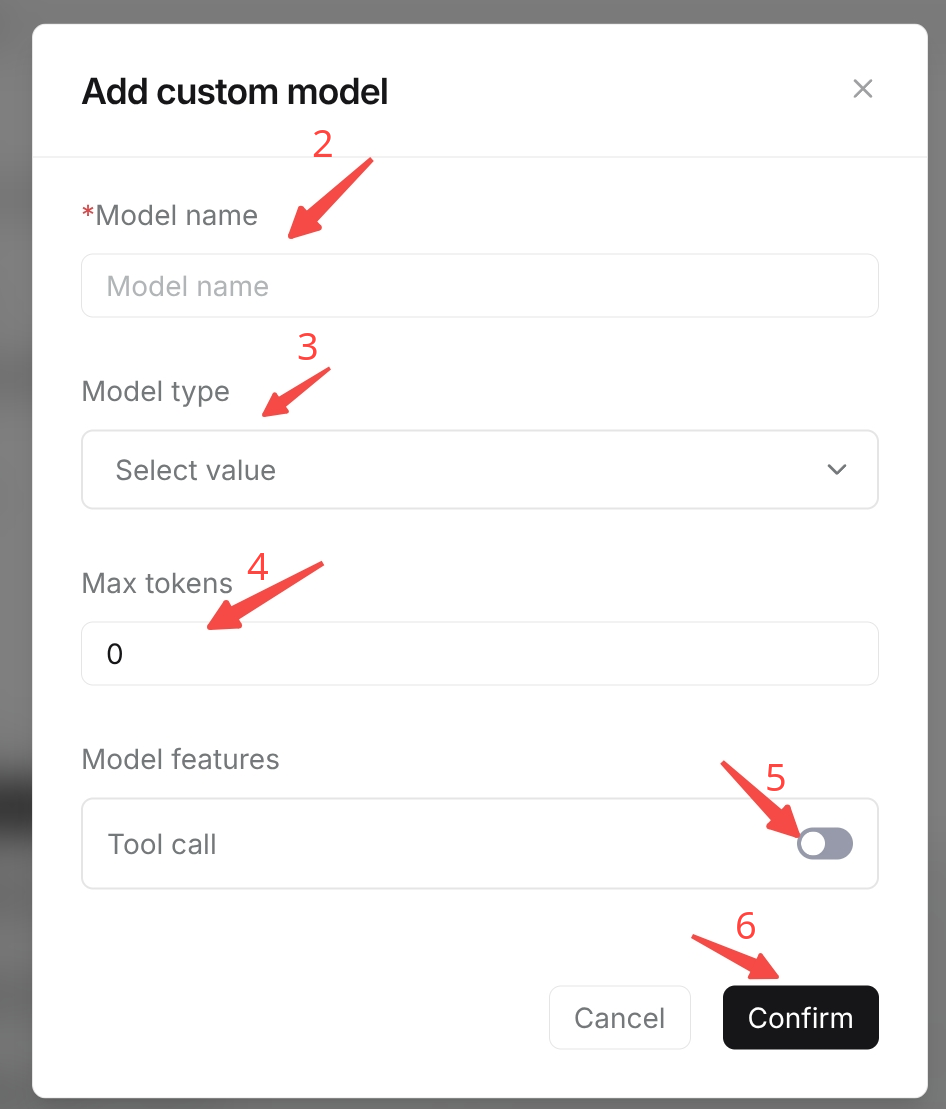++### Verify Models++After adding models, verify them individually, or click **Verify all models** to verify every model currently shown by the active search and type filters. Verification checks each model together with the current instance credentials and endpoint. If verification fails, check the authentication information, Base URL, network connection, account quota, model name, and model availability.+++## Set Default ModelsDefault models are used when RAGFlow needs to select a model automatically and no model has been specified separately. Set default models after adding and verifying models to avoid selecting unavailable models on business pages.@@ -118,10 +121,8 @@ If you have configured a rerank model, it is also recommended to set a default r| TTS | Text-to-Speech model | Converts text into speech | Text | Audio | Voice playback, audio content, and voice interaction || OCR | Optical Character Recognition model | Recognizes text in images or scanned documents | Images or scanned documents | Recognized text | Scanned document recognition and receipt recognition |-The following model types usually work together for retrieval and generation:+The following model types serve different parts of retrieval, generation, and multimodal workflows:1. **Embedding**, **Rerank**, and **LLM**: The embedding model converts queries and knowledge chunks into vectors, and the system recalls candidate chunks based on vector similarity. The rerank model scores and reorders the candidate chunks by relevance. The LLM understands the question based on the selected knowledge content and generates the answer.-2. **VLM**, **ASR**, **TTS**, and **OCR**: VLM is used to understand images and image-text information. OCR recognizes text in images or scanned documents. ASR converts speech into text. TTS converts text into speech. Different model types jointly support multimodal scenarios such as image understanding, document recognition, and voice interaction.--3. **Moderation**: The moderation model is used to identify non-compliant, harmful, or sensitive content in text or images. It can review user input and model output to reduce the risk of generating or spreading non-compliant content.+2. **VLM**, **ASR**, **TTS**, and **OCR**: Configure these capabilities individually or combine them according to the multimodal scenario. VLM understands images and image-text information, OCR recognizes text in images or scanned documents, ASR converts speech into text, and TTS converts text into speech.diff --git a/docs/quickstart.mdx b/docs/quickstart.mdxindex fbafba6483..673da7b421 100644--- a/docs/quickstart.mdx+++ b/docs/quickstart.mdx@@ -85,7 +85,7 @@ The Go container runs the API server, ingestion workers, and data synchronizatioRAGFlow is a RAG engine and needs to work with an LLM to offer grounded, hallucination-free question-answering capabilities. RAGFlow supports most mainstream LLMs.:::note-RAGFlow also supports deploying LLMs locally using Ollama, Xinference, or LocalAI, but this part is not covered in this quick start guide.+RAGFlow also supports deploying models locally using Ollama or vLLM, but this part is not covered in this quick start guide. See [Deploy Local Models](./guides/models/deploy_local_llm.mdx) for instructions.:::To add and configure an LLM: