
RAGFlow is an agent-native database: a Retrieval-Augmented Generation (RAG) engine that grew into context infrastructure.
Go agent-harnessagent-native-databaseagentic-aiagentic-retrievalagentic-searchaiai-agentscontext-enginecontext-engineeringcontext-managementharness-engineeringknowledge-compilationragretrieval-augmented-generationretrieval-harnesssearch-harness
doc: fix typos (#21947)
Jin Hai47e94cb73431
diff --git a/docs/administrator/management/admin_ui/check_system_status.md b/docs/administrator/management/admin_ui/check_system_status.mdindex a91250cab2..04215ba56a 100644--- a/docs/administrator/management/admin_ui/check_system_status.md+++ b/docs/administrator/management/admin_ui/check_system_status.md@@ -38,7 +38,7 @@ On the **Services** page, administrators can view the service `Name`, `Service t3. Read the properties in the **Service … detail** dialog. For example, the MySQL detail shows `type`, `name`, `host`, `port`, `status`, `elapsed`, and `message` as a property list.4. Click **Close** to return to the list.-The MySQL dialog displays the health-check record, not a database process list. Use your deployment's database administration tools if you need to inspect SQL sessions or processes.+The MySQL dialog displays the health check record, not a database process list. Use your deployment's database administration tools if you need to inspect SQL sessions or processes.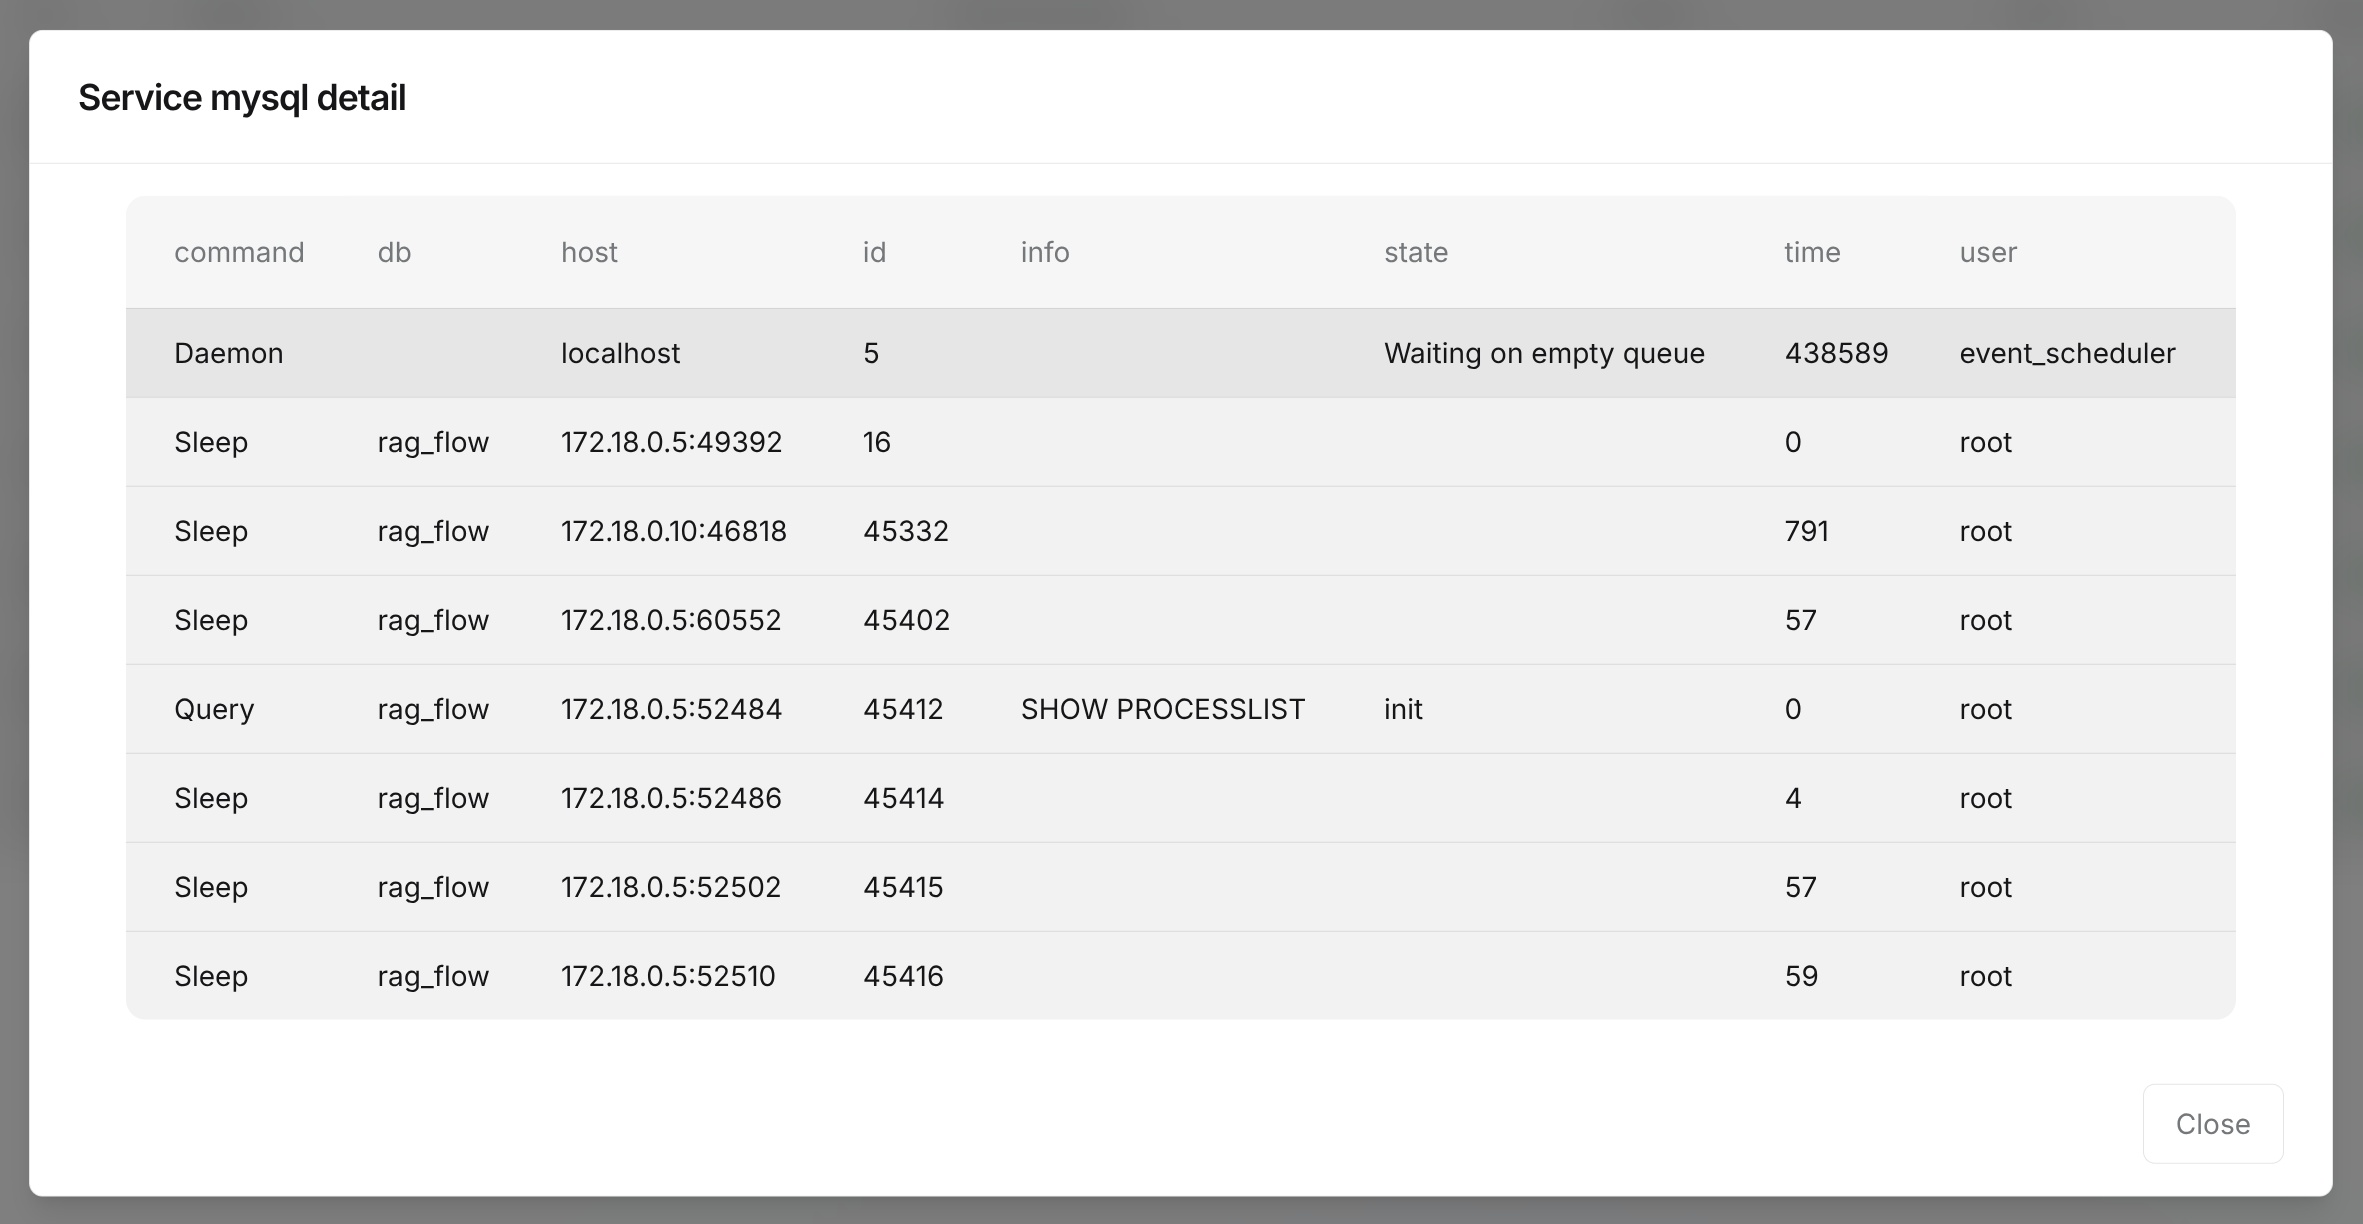diff --git a/docs/administrator/upgrade_and_migration/backup_and_restore_v0.md b/docs/administrator/upgrade_and_migration/backup_and_restore_v0.mdindex 13dcdf7520..11b769d745 100644--- a/docs/administrator/upgrade_and_migration/backup_and_restore_v0.md+++ b/docs/administrator/upgrade_and_migration/backup_and_restore_v0.md@@ -41,12 +41,12 @@ doneThe `docker` project commonly uses these volumes:-| Data | Typical volume |-|------|----------------|-| Metadata database | `docker_mysql_data` |+| Data | Typical volume |+|-----------------------------------|---------------------|+| Metadata database | `docker_mysql_data` || Uploaded objects in bundled MinIO | `docker_minio_data` |-| Redis data | `docker_redis_data` |-| Elasticsearch index | `docker_esdata01` |+| Redis data | `docker_redis_data` |+| Elasticsearch index | `docker_esdata01` |Use these four default volumes as the starting point. If the deployment uses Infinity instead of Elasticsearch, include its persistent data. Add every named volume and persistent host directory shown by the mount check.@@ -83,10 +83,10 @@ The `date` command adds the current time to the directory name so that files froChoose one backup method:-| Deployment | Backup method |-|------------|---------------|-| `v0.20.1` or later with the four default MySQL, MinIO, Redis, and Elasticsearch volumes | Use the bundled script. |-| `v0.20.0`, Infinity, or any non-default volume set | Use the manual procedure for every recorded volume. |+| Deployment | Backup method |+|-----------------------------------------------------------------------------------------|-----------------------------------------------------|+| `v0.20.1` or later with the four default MySQL, MinIO, Redis, and Elasticsearch volumes | Use the bundled script. |+| `v0.20.0`, Infinity, or any non-default volume set | Use the manual procedure for every recorded volume. |For a deployment with the four default volumes, create the archives with:diff --git a/docs/administrator/upgrade_and_migration/backup_and_restore_v1.md b/docs/administrator/upgrade_and_migration/backup_and_restore_v1.mdindex fc415574bd..98cc7224f8 100644--- a/docs/administrator/upgrade_and_migration/backup_and_restore_v1.md+++ b/docs/administrator/upgrade_and_migration/backup_and_restore_v1.md@@ -39,16 +39,16 @@ Write down every RAGFlow volume name and every persistent host directory shown iUse the following table to check the list you recorded. Include each service enabled in your deployment, together with any additional or externally managed storage used in your environment.-| Service or data | Persistent location |-|-----------------|---------------------|-| Metadata database in bundled MySQL | `docker_mysql_data` |-| Uploaded objects in bundled MinIO | `docker_minio_data` |-| Elasticsearch index | `docker_esdata01` |-| Infinity index | `docker_infinity_data` |-| Kvrocks cache and checkpoint data | `docker_kvrocks_data` |-| NATS JetStream data | `docker_nats_data` |-| Kibana data, when Kibana is enabled | `docker_kibana_data` |-| RAGFlow logs | `docker/ragflow-logs` bind mount |+| Service or data | Persistent location |+|-------------------------------------|----------------------------------|+| Metadata database in bundled MySQL | `docker_mysql_data` |+| Uploaded objects in bundled MinIO | `docker_minio_data` |+| Elasticsearch index | `docker_esdata01` |+| Infinity index | `docker_infinity_data` |+| Kvrocks cache and checkpoint data | `docker_kvrocks_data` |+| NATS JetStream data | `docker_nats_data` |+| Kibana data, when Kibana is enabled | `docker_kibana_data` |+| RAGFlow logs | `docker/ragflow-logs` bind mount |This table is a checklist. Always use the mounts reported by `docker inspect` as the final backup scope.diff --git a/docs/administrator/upgrade_and_migration/upgrade_from_v0_to_v1.md b/docs/administrator/upgrade_and_migration/upgrade_from_v0_to_v1.mdindex 8f40055a83..5576a3bafb 100644--- a/docs/administrator/upgrade_and_migration/upgrade_from_v0_to_v1.md+++ b/docs/administrator/upgrade_and_migration/upgrade_from_v0_to_v1.md@@ -196,7 +196,7 @@ docker compose -p docker -f docker/docker-compose.yml pscurl -f http://127.0.0.1/api/v1/system/healthz```-The health-check command uses the default web port `80`. If `SVR_WEB_HTTP_PORT` has been changed in `docker/.env`, use that port in the URL.+The health check command uses the default web port `80`. If `SVR_WEB_HTTP_PORT` has been changed in `docker/.env`, use that port in the URL.If the logs report a migration error, stop the v1 deployment and preserve the logs. Do not retry against the partially migrated data. Restore the complete `v0.27.2` recovery point, resolve the cause in a separate test environment, and retry the upgrade only from the restored recovery point.diff --git a/docs/basics/agent_context_engine.md b/docs/basics/agent_context_engine.mdindex e74348031d..fad8a87d81 100644--- a/docs/basics/agent_context_engine.md+++ b/docs/basics/agent_context_engine.md@@ -46,7 +46,7 @@ The necessity of an Agent Context Engine becomes clear when we examine the alterThe shift from Context Engineering to a Context Platform/Engine marks the maturation of enterprise AI, as summarized in the table below:| Dimension | Context engineering (present) | Context engineering/Platform (future) |-| ------------------- | -------------------------------------------------------------------------- | ------------------------------------------------------------------------------------- |+|---------------------|----------------------------------------------------------------------------|---------------------------------------------------------------------------------------|| Context creation | Manual, artisanal work by developers and prompt engineers. | Automated, driven by intelligent ingestion pipelines and configurable rules. || Context delivery | Hard-coded prompts and static retrieval logic embedded in agent workflows. | Dynamic, real-time retrieval and assembly based on the agent's live state and intent. || Context maintenance | A development and operational burden, logic locked in code. | A manageable platform function, with visibility and control returned to the business. |diff --git a/docs/basics/agent_native_database.md b/docs/basics/agent_native_database.mdindex e2fb1f975f..073cec649d 100644--- a/docs/basics/agent_native_database.md+++ b/docs/basics/agent_native_database.md@@ -75,7 +75,7 @@ Two rules keep the layer trustworthy:## How it differs from RAG and vector databases| | RAG engine | Vector database | Agent native database |-| ---------------- | --------------- | ------------------ | ---------------------------------- |+|------------------|-----------------|--------------------|------------------------------------|| Primary consumer | Human user | Retrieval pipeline | Agent harness || Delivers | Ranked passages | Similarity hits | Smallest sufficient context || Unit of value | Recall@k | Embedding quality | Token cost, provenance, governance |diff --git a/docs/guides/agent/agent_workflow/basic_component.md b/docs/guides/agent/agent_workflow/basic_component.mdindex e337f6e1cf..7347ddfea0 100644--- a/docs/guides/agent/agent_workflow/basic_component.md+++ b/docs/guides/agent/agent_workflow/basic_component.md@@ -59,15 +59,15 @@ Common fields are as follows:Variable types:-| Type | Description |-| --- | --- |-| Single-line text | Used to enter short text, such as names, keywords, and serial numbers. |-| Paragraph text | Used to enter longer content, such as problem descriptions, requirement descriptions, and prompts. |-| Dropdown options | Provides predefined options for users to select. You can click **Add option** to add multiple options. This is suitable for fixed-value inputs such as language, department, and model type. |-| File upload | Allows users to upload files as workflow input. This can be used for document analysis, image processing, and similar scenarios. Uploaded files are not automatically saved to knowledge bases, and are used only in the current workflow. |-| Number | Used to enter numeric values, such as quantity, threshold, `Top K`, and maximum returned items. |-| Boolean | Provides a switch (`True`/`False`) or yes/no option, used to control whether a feature is enabled or whether a branch is executed. |-| JSON object | Used to enter structured JSON data, such as parameters, configurations, or other complex data containing multiple fields. |+| Type | Description |+|------------------|--------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------|+| Single-line text | Used to enter short text, such as names, keywords, and serial numbers. |+| Paragraph text | Used to enter longer content, such as problem descriptions, requirement descriptions, and prompts. |+| Dropdown options | Provides predefined options for users to select. You can click **Add option** to add multiple options. This is suitable for fixed-value inputs such as language, department, and model type. |+| File upload | Allows users to upload files as workflow input. This can be used for document analysis, image processing, and similar scenarios. Uploaded files are not automatically saved to knowledge bases, and are used only in the current workflow. |+| Number | Used to enter numeric values, such as quantity, threshold, `Top K`, and maximum returned items. |+| Boolean | Provides a switch (`True`/`False`) or yes/no option, used to control whether a feature is enabled or whether a branch is executed. |+| JSON object | Used to enter structured JSON data, such as parameters, configurations, or other complex data containing multiple fields. |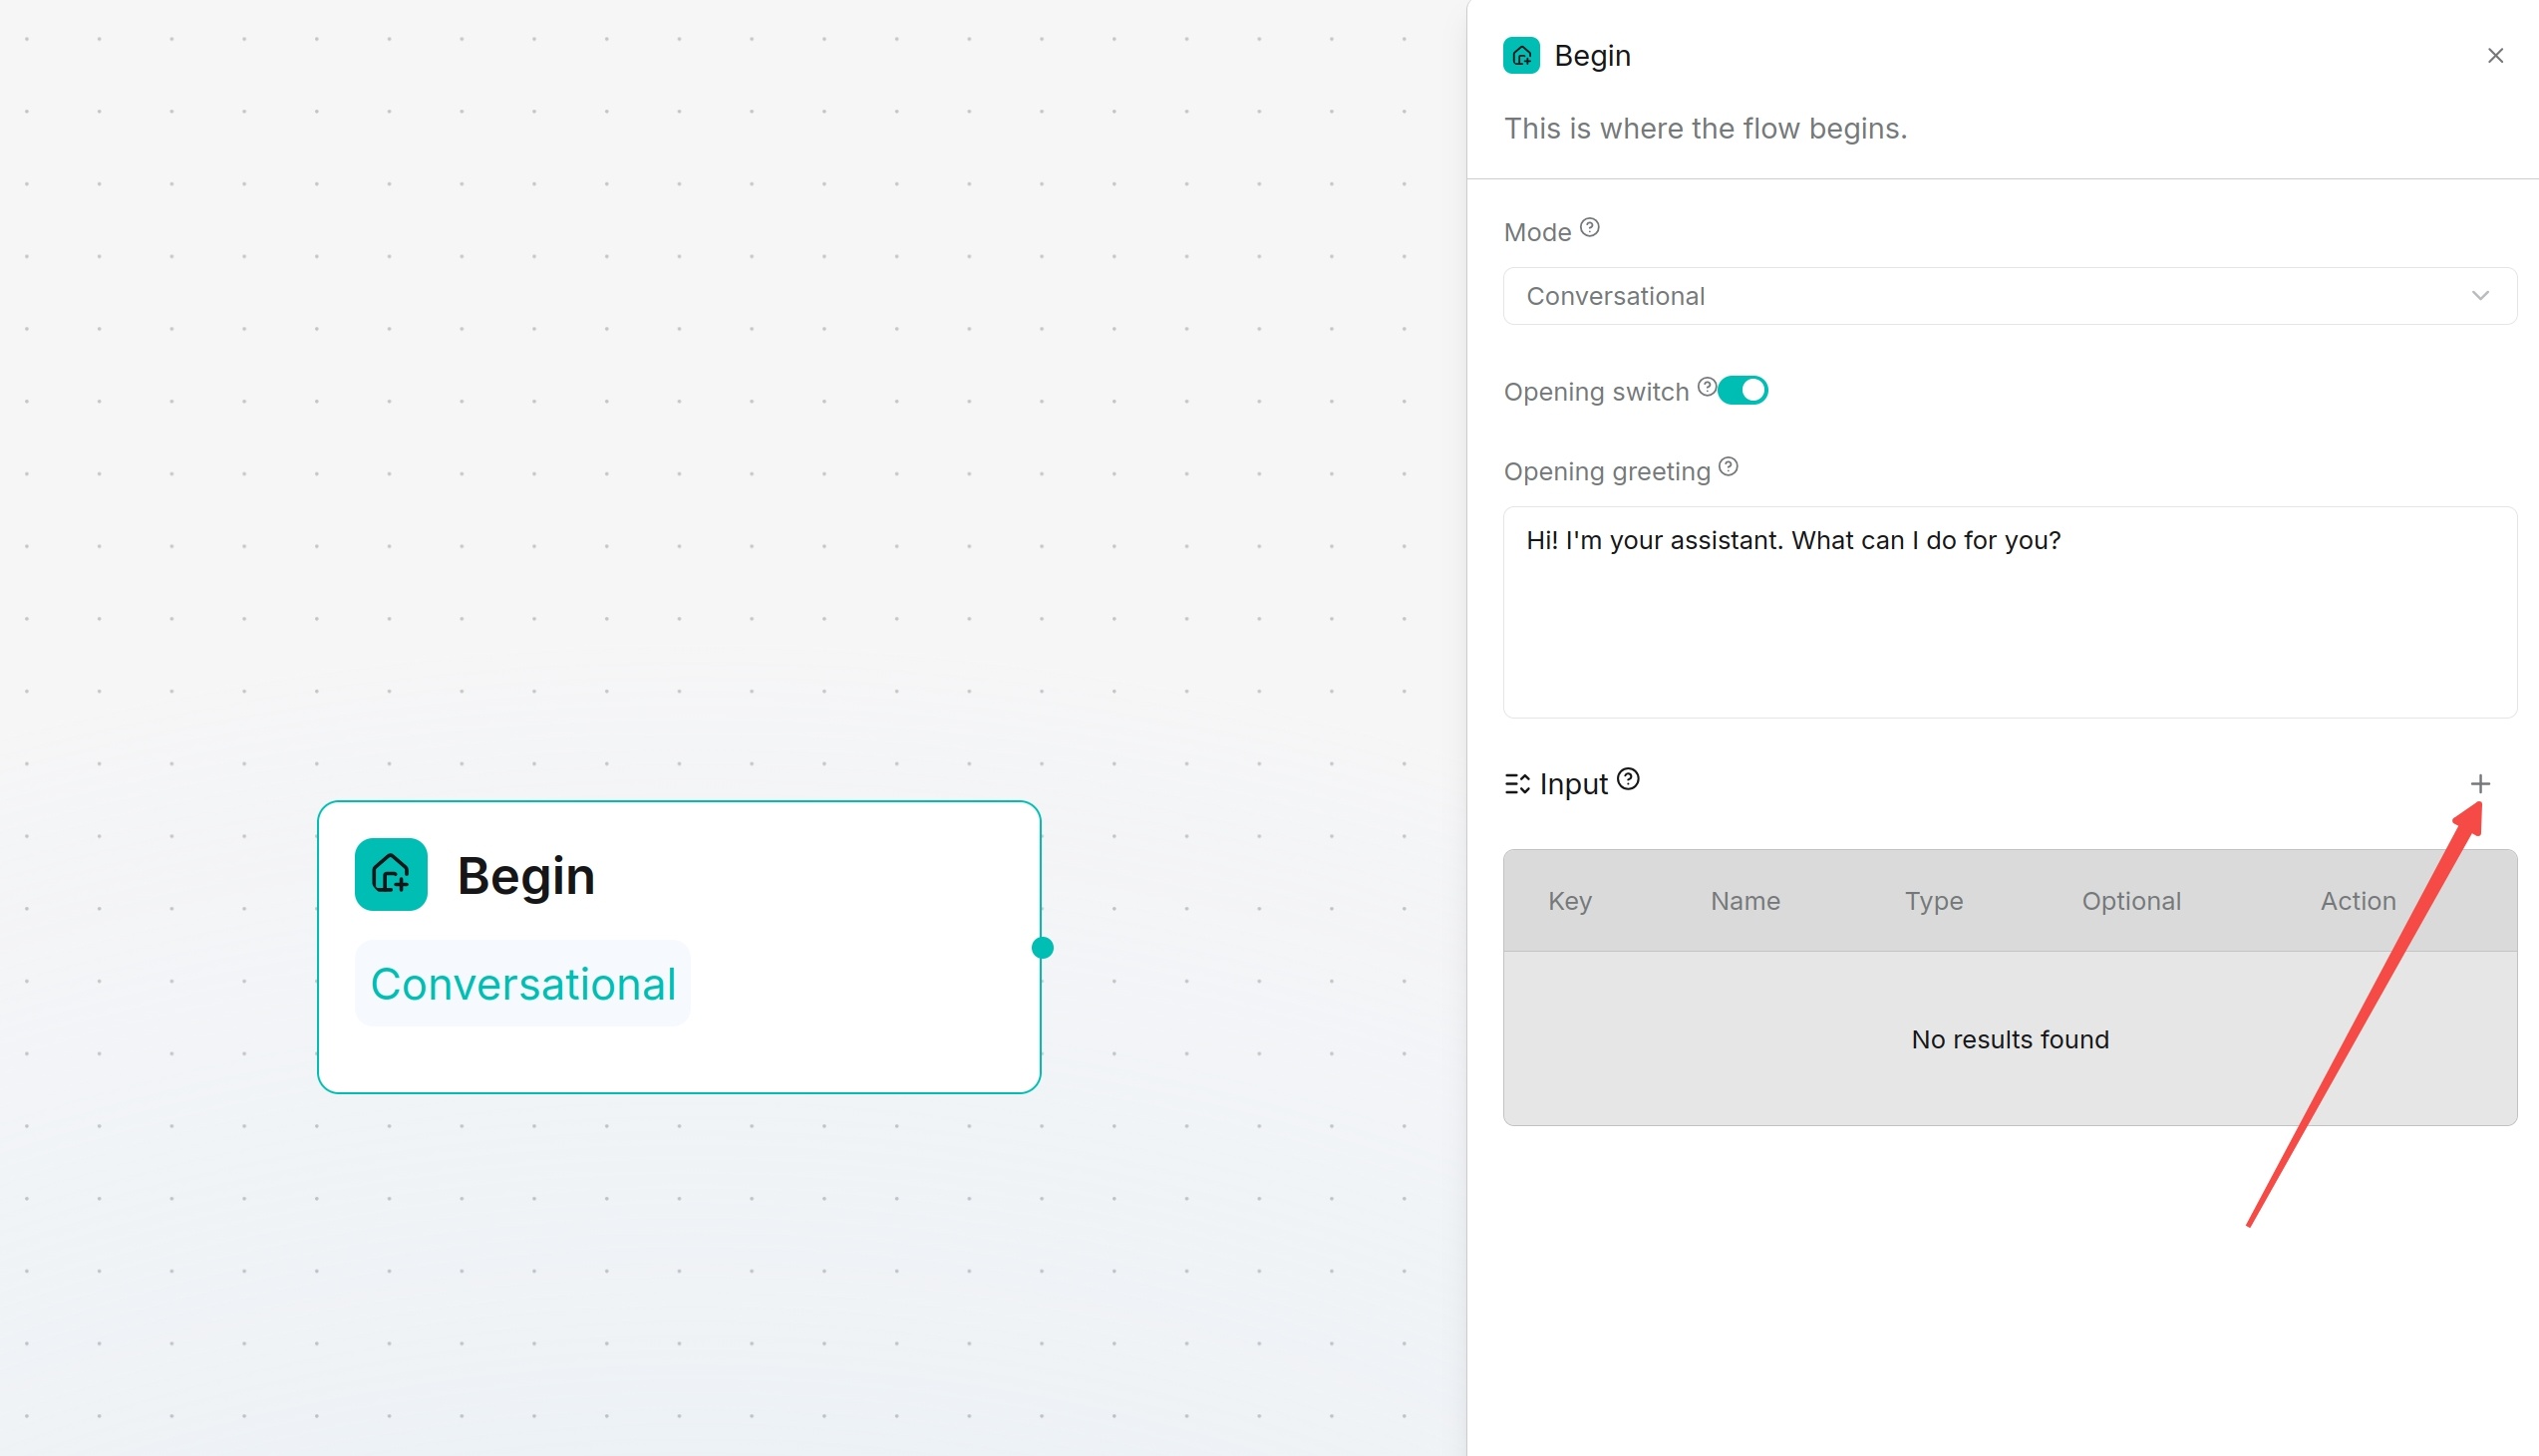@@ -85,7 +85,7 @@ Keep uploaded content within the selected model's context limit.## Agent Component-The Agent component is used to call large language models for reasoning, content generation, task planning, and tool calling. It can process user questions independently, or work with components such as knowledge retrieval, HTTP requests, code, databases, and sub-agents to complete multi-step tasks.+The Agent component is used to call large language models for reasoning, content generation, task planning, and tool calling. It can process user questions independently, or work with components such as knowledge retrieval, HTTP requests, code, databases, and sub-agents to complete multistep tasks.The Agent component can work independently and has the following capabilities:@@ -142,10 +142,10 @@ Use **Advanced settings** to adjust conversation history and citations.Parameter description:-| Parameter | Description | Suggestion |-| --- | --- | --- |-| Message window size | Sets the number of historical messages retained by the Agent during reasoning. A larger window provides more context, but increases token consumption. | Keep the default value in general. Increase it for multi-turn conversations, and decrease it for single-turn tasks. |-| Citation | Specifies whether to return citation information in answers. When the Agent uses knowledge bases or retrieval results to generate answers, source citations can be enabled to make it easier to view the basis for the answer. | Recommended for knowledge base Q&A scenarios. |+| Parameter | Description | Suggestion |+|---------------------|--------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------|---------------------------------------------------------------------------------------------------------------------|+| Message window size | Sets the number of historical messages retained by the Agent during reasoning. A larger window provides more context, but increases token consumption. | Keep the default value in general. Increase it for multi-turn conversations, and decrease it for single-turn tasks. |+| Citation | Specifies whether to return citation information in answers. When the Agent uses knowledge bases or retrieval results to generate answers, source citations can be enabled to make it easier to view the basis for the answer. | Recommended for knowledge base Q&A scenarios. |If an Agent run fails, check the error details in the run results, correct the cause, and run again.@@ -153,10 +153,10 @@ If an Agent run fails, check the error details in the run results, correct the c`Output` is used to configure the output content of the Agent node.-| Configuration item | Description |-| --- | --- |-| `content` | The natural language text returned by the Agent. This is the default output. |-| `structured` | Structured data returned by the Agent. After structured output is enabled, results can be output according to a predefined JSON Schema, making it easier for subsequent nodes to read and process. |+| Configuration item | Description |+|--------------------|----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------|+| `content` | The natural language text returned by the Agent. This is the default output. |+| `structured` | Structured data returned by the Agent. After structured output is enabled, results can be output according to a predefined JSON Schema, making it easier for subsequent nodes to read and process. |For structured output, after enabling **Structured output**, click **Configuration** to configure the output structure. Users can define the returned data format according to JSON Schema, such as specifying field names, data types, and required fields. The Agent tries to return results according to the configured structure, making it easier to pass data to nodes such as Code, HTTP Request, Execute SQL, and Switch for automated processing.@@ -200,11 +200,11 @@ Similarity threshold values below use the UI percentage scale: enter `20`, `50`,Retrieval parameters directly affect answer coverage, accuracy, and response time. You can start with the settings in the following table, and then optimize them based on real questions.-| Parameter | Suggested Value | Scenario | Description |-| --- | --- | --- | --- |-| Top N | 3-5 | FAQ and short knowledge entries | Faster responses for clear answers. |-| Top N | 5-10 | Product documentation and help centers | A suggested range to test with representative questions. |-| Top N | 10-20 | Legal contracts and long document analysis | More context with higher token consumption. |-| Similarity threshold | 20 | Loose recall | Questions with diverse expressions. |-| Similarity threshold | 50 | General Q&A | A stricter tuning example; the initial UI value is 20 (20%). |-| Similarity threshold | 80 | Strict precise matching | Scenarios that require exact terminology matching. |+| Parameter | Suggested Value | Scenario | Description |+|----------------------|-----------------|--------------------------------------------|--------------------------------------------------------------|+| Top N | 3-5 | FAQ and short knowledge entries | Faster responses for clear answers. |+| Top N | 5-10 | Product documentation and help centers | A suggested range to test with representative questions. |+| Top N | 10-20 | Legal contracts and long document analysis | More context with higher token consumption. |+| Similarity threshold | 20 | Loose recall | Questions with diverse expressions. |+| Similarity threshold | 50 | General Q&A | A stricter tuning example; the initial UI value is 20 (20%). |+| Similarity threshold | 80 | Strict precise matching | Scenarios that require exact terminology matching. |diff --git a/docs/guides/agent/best_practices/accelerate_agent_question_answering.md b/docs/guides/agent/best_practices/accelerate_agent_question_answering.mdindex 5a5d311f81..e5e0eef1b9 100644--- a/docs/guides/agent/best_practices/accelerate_agent_question_answering.md+++ b/docs/guides/agent/best_practices/accelerate_agent_question_answering.md@@ -8,13 +8,13 @@ slug: /accelerate_agent_question_answeringUse a representative question and inspect component results and execution logs to find the slow step. Change one setting at a time, then compare both response time and answer quality.-| Slow step | What to check |-| --- | --- |-| Agent generation | Keep prompts focused, request a concise answer, and reduce unnecessary history. Use a faster model for simple formatting or classification tasks. |-| Planning and tool calls | Remove tools or sub-agents that the task does not need. Keep reflection and multi-step planning for tasks that benefit from them. |-| Retrieval | Compare with and without a Rerank model. Adjust Rerank candidate count and Top N while checking that the evidence needed for the answer is still returned. |-| External tools | Inspect individual tool durations, response sizes, timeouts, and provider errors before increasing retries. |-| Iteration | For independent items, try a bounded Maximum concurrency greater than `1`. Respect model and service rate limits. |+| Slow step | What to check |+|-------------------------|------------------------------------------------------------------------------------------------------------------------------------------------------------|+| Agent generation | Keep prompts focused, request a concise answer, and reduce unnecessary history. Use a faster model for simple formatting or classification tasks. |+| Planning and tool calls | Remove tools or sub-agents that the task does not need. Keep reflection and multi-step planning for tasks that benefit from them. |+| Retrieval | Compare with and without a Rerank model. Adjust Rerank candidate count and Top N while checking that the evidence needed for the answer is still returned. |+| External tools | Inspect individual tool durations, response sizes, timeouts, and provider errors before increasing retries. |+| Iteration | For independent items, try a bounded Maximum concurrency greater than `1`. Respect model and service rate limits. |If the selected model provides reasoning settings, adjust them and compare response time and answer quality.diff --git a/docs/guides/agent/ingestion_pipeline/configure_transformer_component.md b/docs/guides/agent/ingestion_pipeline/configure_transformer_component.mdindex e21140f083..781e164d28 100644--- a/docs/guides/agent/ingestion_pipeline/configure_transformer_component.md+++ b/docs/guides/agent/ingestion_pipeline/configure_transformer_component.md@@ -23,13 +23,13 @@ The panel lists **Auto keywords**, **Auto-question**, **Tags**, **Summary**, and## Configure Extraction Functions-| Function | Settings and purpose |-| --- | --- |+| Function | Settings and purpose |+|---------------|---------------------------------------------------------------------------------------------------------------------------------------|| Auto keywords | Set **Number of keywords to extract** and review **System prompt**. The model extracts key terms from each chunk to assist retrieval. |-| Auto-question | Set **Auto-question number** and review **System prompt**. The model generates questions that the chunk can answer. |-| Tags | Set **Auto-tags** to control the number of tags and select the source under **Tag file**. The model assigns tags from that source. |-| Summary | Review or customize **System prompt** to control how the model summarizes chunk content. |-| Metadata | Enable metadata generation and click **Settings** to define custom fields or select built-in fields. See the steps below. |+| Auto-question | Set **Auto-question number** and review **System prompt**. The model generates questions that the chunk can answer. |+| Tags | Set **Auto-tags** to control the number of tags and select the source under **Tag file**. The model assigns tags from that source. |+| Summary | Review or customize **System prompt** to control how the model summarizes chunk content. |+| Metadata | Enable metadata generation and click **Settings** to define custom fields or select built-in fields. See the steps below. |Enable only the functions you need. Review the prompts for your document language, required output, and business scope before processing a large collection of files.diff --git a/docs/guides/agent/quickstarts/build_customer_support_agent.md b/docs/guides/agent/quickstarts/build_customer_support_agent.mdindex 84eb82a419..3178734543 100644--- a/docs/guides/agent/quickstarts/build_customer_support_agent.md+++ b/docs/guides/agent/quickstarts/build_customer_support_agent.md@@ -19,10 +19,10 @@ Build a workflow that answers product questions through retrieval and collects c2. After **Begin**, add **Categorize**. Use `sys.query` as the query variable and select the chat model.3. Add two categories:-| Name | Description | Example |-| --- | --- | --- |-| Product help | Product features, setup, and troubleshooting. | How do I reset Model A? |-| Appointment | Requests to arrange a service appointment. | I want to arrange an installation. |+| Name | Description | Example |+|--------------|-----------------------------------------------|------------------------------------|+| Product help | Product features, setup, and troubleshooting. | How do I reset Model A? |+| Appointment | Requests to arrange a service appointment. | I want to arrange an installation. |### Product help branch@@ -46,10 +46,10 @@ Connect **Appointment → Await Response → Message**. Follow the [form exampleSave, then click **Run** and test each path:-| Input | Expected result |-| --- | --- |-| How do I reset Model A? | Product help branch; the answer mentions holding reset for five seconds. |-| Does Model A support Bluetooth? | Product help branch; the answer says the guide does not establish this. |+| Input | Expected result |+|------------------------------------|-----------------------------------------------------------------------------------|+| How do I reset Model A? | Product help branch; the answer mentions holding reset for five seconds. |+| Does Model A support Bluetooth? | Product help branch; the answer says the guide does not establish this. || I want to arrange an installation. | Appointment branch; a form appears and the submitted name and time are displayed. |If routing is wrong, refine the category descriptions and examples. If retrieval is empty, check parsing status, knowledge-base selection, and the query. If the answer ignores retrieved text, check the Agent's variable references. Publish only after both branches work as intended.diff --git a/docs/guides/agent/workflow_overview.md b/docs/guides/agent/workflow_overview.mdindex efed1ea0be..742841be18 100644--- a/docs/guides/agent/workflow_overview.md+++ b/docs/guides/agent/workflow_overview.md@@ -22,7 +22,7 @@ Agents are commonly used in the following scenarios:## Relationship Between Agent and Knowledge Base Q&A- **Chat**: Suitable for applications mainly based on knowledge base Q&A and multi-turn dialogue.-- **Agent**: Suitable for business workflows requiring conditional branching, tool calling, data processing or multi-step orchestration.+- **Agent**: Suitable for business workflows requiring conditional branching, tool calling, data processing or multistep orchestration.The `Retrieval` component can be used inside an Agent to query knowledge bases. Retrieval can also be used as a tool under the Agent component, allowing the LLM to autonomously decide when to perform retrieval.diff --git a/docs/guides/data_source/data_source_configuration.md b/docs/guides/data_source/data_source_configuration.mdindex 8c2fa8e6a0..afa15591e6 100644--- a/docs/guides/data_source/data_source_configuration.md+++ b/docs/guides/data_source/data_source_configuration.md@@ -432,7 +432,7 @@ The Azure DevOps data source is used to synchronize Azure Repos source files and- **Repositories**: Comma separated repositories, used when indexing by repository. Use `project/repo` to disambiguate repositories that share a name across projects.- **Content types**: Choose whether to index source files, pull requests, or both.-Pull request descriptions are re-fetched individually when they reach the 400 character limit imposed by the list endpoint, so long descriptions are indexed in full. Completed and abandoned pull requests are filtered by their close date; active ones are always re-indexed because Azure DevOps exposes no dependable "last updated" timestamp for them.+Pull request descriptions are re-fetched individually when they reach the 400-character limit imposed by the list endpoint, so long descriptions are indexed in full. Completed and abandoned pull requests are filtered by their close date; active ones are always re-indexed because Azure DevOps exposes no dependable "last updated" timestamp for them.- **Sync deleted files**: After this is enabled, content deleted from the external system is removed from the knowledge base index.Build output and vendored directories such as `node_modules`, `bin`, `obj`, `dist`, and `vendor` are skipped, along with binary files and files larger than 1 MB.diff --git a/docs/guides/dataset/dataset_overview.md b/docs/guides/dataset/dataset_overview.mdindex 3d0e76b73a..f17c1c43f7 100644--- a/docs/guides/dataset/dataset_overview.md+++ b/docs/guides/dataset/dataset_overview.md@@ -26,7 +26,7 @@ The configuration page allows you to manage the core settings of a knowledge bas- **Description**: A description of the knowledge base, used to explain its data scope, business purpose, or maintenance information.- **Permissions**: Controls access to the knowledge base and the scope of allowed operations.- **Embedding model**: The model used to vectorize chunks. When chunks already exist, changing the model requires a compatibility check against existing vectors. Saving the change does not automatically re-embed existing chunks.-- **PageRank**: Sets the PageRank score for the knowledge base. During retrieval, this score is added to the hybrid similarity score of matching chunks from the knowledge base, increasing their ranking weight. This is useful when searching across multiple knowledge bases and you want to prioritize content from a specific knowledge base.+- **PageRank**: Sets the PageRank score for the knowledge base. During retrieval, this score is added to the hybrid similarity score of matching chunks from the knowledge base, increasing their ranking weight. This is useful when searching across multiple knowledge bases, and you want to prioritize content from a specific knowledge base.## Dataset Page Overviewdiff --git a/docs/guides/knowledge_compilation/apply_knowledge_compilation_template.md b/docs/guides/knowledge_compilation/apply_knowledge_compilation_template.mdindex 0d92246d2d..f7f36ef2fa 100644--- a/docs/guides/knowledge_compilation/apply_knowledge_compilation_template.md+++ b/docs/guides/knowledge_compilation/apply_knowledge_compilation_template.md@@ -55,14 +55,14 @@ After knowledge artifacts are generated, check the generated results based on thFor different knowledge artifact types, focus on the following checks:-| Type | Check Focus |-| --- | --- |-| Graph | Whether entities are duplicated; whether relationship directions are correct; whether there are unsupported nodes or edges. |-| Tree | Whether the hierarchy is clear; whether peer nodes are at similar abstraction levels; whether summaries are accurate. |-| PageIndex | Whether chapter hierarchy is preserved; whether facts and conclusions come from the corresponding chapters. |-| Mindmap | Whether the central topic is clear; whether branches are duplicated or crossed; whether node names are concise. |-| Timeline | Whether time is accurate; whether event order is correct; whether relative time is misinterpreted. |-| Wiki | Whether page topics are reasonable; whether links between pages are valid; whether facts are consistent with sources. |+| Type | Check Focus |+|-----------|-----------------------------------------------------------------------------------------------------------------------------|+| Graph | Whether entities are duplicated; whether relationship directions are correct; whether there are unsupported nodes or edges. |+| Tree | Whether the hierarchy is clear; whether peer nodes are at similar abstraction levels; whether summaries are accurate. |+| PageIndex | Whether chapter hierarchy is preserved; whether facts and conclusions come from the corresponding chapters. |+| Mindmap | Whether the central topic is clear; whether branches are duplicated or crossed; whether node names are concise. |+| Timeline | Whether time is accurate; whether event order is correct; whether relative time is misinterpreted. |+| Wiki | Whether page topics are reasonable; whether links between pages are valid; whether facts are consistent with sources. |## Update Knowledge Artifactsdiff --git a/docs/guides/knowledge_compilation/built_in_templates_and_dedicated_configuration.md b/docs/guides/knowledge_compilation/built_in_templates_and_dedicated_configuration.mdindex d7025f9521..82a96d4d8c 100644--- a/docs/guides/knowledge_compilation/built_in_templates_and_dedicated_configuration.md+++ b/docs/guides/knowledge_compilation/built_in_templates_and_dedicated_configuration.md@@ -47,22 +47,22 @@ EntitySpecification defines the entity types that need to be recognized in the kConfiguration items:-| Configuration Item | Description |-| --- | --- |-| Type | Entity type name, used to identify the current entity category. |-| Description | Describes the object scope corresponding to this entity type. |-| Rule | Defines entity extraction requirements, such as recognition scope, naming conventions, and restrictions. |+| Configuration Item | Description |+|--------------------|----------------------------------------------------------------------------------------------------------|+| Type | Entity type name, used to identify the current entity category. |+| Description | Describes the object scope corresponding to this entity type. |+| Rule | Defines entity extraction requirements, such as recognition scope, naming conventions, and restrictions. |The system provides the following default node types:-| Entity Name | Description |-| --- | --- |-| person | Person entity, used to represent natural persons or specific individuals, such as authors, employees, customers, historical figures, and similar entities. |-| org | Organization entity, used to represent companies, institutions, departments, associations, or other organizational groups. |-| product | Product entity, used to represent specific products, services, software, solutions, or other business offerings. |-| regulation | Regulation entity, used to represent laws, policies, standards, specifications, guidance documents, or regulatory documents. |-| location | Location entity, used to represent geographic locations, including countries, cities, addresses, regions, or natural geographic entities. |-| other | Other entity, used to represent business-meaningful entity objects that do not belong to the categories above. |+| Entity Name | Description |+|-------------|------------------------------------------------------------------------------------------------------------------------------------------------------------|+| person | Person entity, used to represent natural persons or specific individuals, such as authors, employees, customers, historical figures, and similar entities. |+| org | Organization entity, used to represent companies, institutions, departments, associations, or other organizational groups. |+| product | Product entity, used to represent specific products, services, software, solutions, or other business offerings. |+| regulation | Regulation entity, used to represent laws, policies, standards, specifications, guidance documents, or regulatory documents. |+| location | Location entity, used to represent geographic locations, including countries, cities, addresses, regions, or natural geographic entities. |+| other | Other entity, used to represent business-meaningful entity objects that do not belong to the categories above. |### RelationSpecification@@ -78,22 +78,22 @@ Click a relationship type card to enter the relationship configuration page.Configuration items:-| Configuration Item | Description |-| --- | --- |-| Type | Relationship type name, used to identify the current relationship category. |-| Description | Describes the entity association method represented by this relationship. |-| Rule | Supplements relationship extraction requirements, such as relationship direction, applicable scope, and restrictions. |+| Configuration Item | Description |+|--------------------|-----------------------------------------------------------------------------------------------------------------------|+| Type | Relationship type name, used to identify the current relationship category. |+| Description | Describes the entity association method represented by this relationship. |+| Rule | Supplements relationship extraction requirements, such as relationship direction, applicable scope, and restrictions. |The system provides the following default relationship types:-| Relationship Name | Description |-| --- | --- |-| owns | Ownership relationship, used to indicate ownership or possession between entities, such as a person owning assets or an enterprise owning products. |-| part_of | Composition relationship, used to indicate composition or inclusion between entities, such as a component belonging to a product or a department belonging to an organization. |-| caused_by | Causal relationship, used to indicate that an event, action, or state is caused by other factors. |-| regulates | Regulatory relationship, used to indicate that laws, standards, or specifications constrain, manage, or guide entities. |-| located_in | Location relationship, used to indicate location associations between entities, such as a company located in a city or a building located in a region. |-| other | Other relationship, used to represent valuable entity relationships that cannot be classified into the categories above. |+| Relationship Name | Description |+|-------------------|--------------------------------------------------------------------------------------------------------------------------------------------------------------------------------|+| owns | Ownership relationship, used to indicate ownership or possession between entities, such as a person owning assets or an enterprise owning products. |+| part_of | Composition relationship, used to indicate composition or inclusion between entities, such as a component belonging to a product or a department belonging to an organization. |+| caused_by | Causal relationship, used to indicate that an event, action, or state is caused by other factors. |+| regulates | Regulatory relationship, used to indicate that laws, standards, or specifications constrain, manage, or guide entities. |+| located_in | Location relationship, used to indicate location associations between entities, such as a company located in a city or a building located in a region. |+| other | Other relationship, used to represent valuable entity relationships that cannot be classified into the categories above. |### Configuration Recommendations@@ -192,19 +192,19 @@ EntitySpecification defines the content fields that PageIndex needs to extract.Field configuration parameters:-| Parameter Name | Description |-| --- | --- |-| Type | Field type, used to specify the information type to extract for the current field, such as title, fact, or conclusion. |-| Description | Field description, used to explain the specific content that needs to be extracted for this field, helping the system understand the field meaning and extraction scope. |-| Rule | Field rule, used to further constrain how content is extracted, including content format, length, extraction scope, and other requirements. |+| Parameter Name | Description |+|----------------|--------------------------------------------------------------------------------------------------------------------------------------------------------------------------|+| Type | Field type, used to specify the information type to extract for the current field, such as title, fact, or conclusion. |+| Description | Field description, used to explain the specific content that needs to be extracted for this field, helping the system understand the field meaning and extraction scope. |+| Rule | Field rule, used to further constrain how content is extracted, including content format, length, extraction scope, and other requirements. |The system provides the following default fields:-| Field Name | Description |-| --- | --- |-| title | Title field, used to extract titles or chapter names from the document. The title content should preserve the original text and should not include page numbers, numbering, or other irrelevant symbols. |-| fact | Fact field, used to extract key facts, rules, definitions, or explanatory content related to the current chapter, reflecting the core information of the chapter. |-| conclusion | Conclusion field, used to extract summaries, analysis results, or important conclusions from the chapter, supplementing the chapter's core viewpoints. |+| Field Name | Description |+|------------|----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------|+| title | Title field, used to extract titles or chapter names from the document. The title content should preserve the original text and should not include page numbers, numbering, or other irrelevant symbols. |+| fact | Fact field, used to extract key facts, rules, definitions, or explanatory content related to the current chapter, reflecting the core information of the chapter. |+| conclusion | Conclusion field, used to extract summaries, analysis results, or important conclusions from the chapter, supplementing the chapter's core viewpoints. |### RelationSpecification@@ -217,17 +217,17 @@ Through this relationship, the system can generate a hierarchical index based onConfiguration parameters:-| Parameter | Description |-| --- | --- |-| Type | Relationship type, used to define the association method between entities. The current supported type is include, which indicates an inclusion relationship. |-| Description | Describes the meaning of the relationship and helps the model understand the association rules between two entities. |-| Rule | Further constrains relationship extraction logic, including relationship direction, applicable scope, and entity connection requirements. |+| Parameter | Description |+|-------------|--------------------------------------------------------------------------------------------------------------------------------------------------------------|+| Type | Relationship type, used to define the association method between entities. The current supported type is include, which indicates an inclusion relationship. |+| Description | Describes the meaning of the relationship and helps the model understand the association rules between two entities. |+| Rule | Further constrains relationship extraction logic, including relationship direction, applicable scope, and entity connection requirements. |The system provides the following default relationship type:-| Relationship Name | Description |-| --- | --- |-| conclusion | Conclusion relationship, used to represent findings, results, or conclusion information extracted based on document content. |+| Relationship Name | Description |+|-------------------|------------------------------------------------------------------------------------------------------------------------------|+| conclusion | Conclusion relationship, used to represent findings, results, or conclusion information extracted based on document content. |Configuration recommendations:@@ -278,32 +278,32 @@ EntitySpecification defines the node types in the mind map. Different node typesWhen configuring nodes, the main parameters are as follows. The system provides the following default node types:-| Node Name | Description |-| --- | --- |-| CentralTopic | Core topic node, used to represent the main topic of the document or content as the center node of the mind map. |-| Branch | First-level branch node, used to represent the main directions, categories, or knowledge domains expanded around the core topic. |-| Sub-branch | Second-level branch node, used to represent specific concepts, tasks, cases, or detailed content under Branch. |-| Keyword | Keyword node, used to supplement other nodes with key concepts or core information. |+| Node Name | Description |+|--------------|----------------------------------------------------------------------------------------------------------------------------------|+| CentralTopic | Core topic node, used to represent the main topic of the document or content as the center node of the mind map. |+| Branch | First-level branch node, used to represent the main directions, categories, or knowledge domains expanded around the core topic. |+| Sub-branch | Second-level branch node, used to represent specific concepts, tasks, cases, or detailed content under Branch. |+| Keyword | Keyword node, used to supplement other nodes with key concepts or core information. |### RelationSpecificationRelationSpecification defines the relationships between different nodes in the mind map and describes the hierarchy and content associations between nodes. The system uses relationship definitions to determine how nodes are connected, such as inclusion between the core topic and branches, or support relationships between branches and keywords.-| Parameter Name | Description |-| --- | --- |-| Type | Node type name, used to identify the role of the current node in the mind map. |-| Description | Describes the information content that this node needs to extract, helping the system understand the node definition and scope. |-| Rule | Further constrains node generation methods, including content selection, naming requirements, length limits, and other generation requirements. |+| Parameter Name | Description |+|----------------|-------------------------------------------------------------------------------------------------------------------------------------------------|+| Type | Node type name, used to identify the role of the current node in the mind map. |+| Description | Describes the information content that this node needs to extract, helping the system understand the node definition and scope. |+| Rule | Further constrains node generation methods, including content selection, naming requirements, length limits, and other generation requirements. |The system provides common relationship types. Users can adjust them based on business requirements, including adding, modifying, or deleting relationship types.Relationship configuration parameters:-| Parameter Name | Description |-| --- | --- |-| Type | Relationship type name, used to identify the association method between nodes. |-| Description | Describes the connection meaning represented by this relationship, helping the system understand relationships between nodes. |-| Rule | Further restricts relationship generation conditions, such as applicable node types, connection direction, and relationship usage scenarios. |+| Parameter Name | Description |+|----------------|----------------------------------------------------------------------------------------------------------------------------------------------|+| Type | Relationship type name, used to identify the association method between nodes. |+| Description | Describes the connection meaning represented by this relationship, helping the system understand relationships between nodes. |+| Rule | Further restricts relationship generation conditions, such as applicable node types, connection direction, and relationship usage scenarios. |The system provides the following default relationship types:@@ -372,18 +372,18 @@ Entity configuration defines the information types that need to be recognized anEach entity contains the following configuration items:-| Configuration Item | Description |-| --- | --- |-| Type | Entity type name, used to identify the information category to extract. |-| Description | Describes the content scope that the entity needs to extract, helping the model accurately recognize target information. |-| Rule | Further constrains entity extraction methods, such as format requirements, content restrictions, and special processing logic. |+| Configuration Item | Description |+|--------------------|--------------------------------------------------------------------------------------------------------------------------------|+| Type | Entity type name, used to identify the information category to extract. |+| Description | Describes the content scope that the entity needs to extract, helping the model accurately recognize target information. |+| Rule | Further constrains entity extraction methods, such as format requirements, content restrictions, and special processing logic. |The system provides the following default entity types:-| Entity Name | Description |-| --- | --- |-| timestamp | Indicates the time information when an event occurs. It can be a specific date, time point, or valid time range. |-| event | Indicates the event content corresponding to the time information and describes the main occurrence. |+| Entity Name | Description |+|-------------|------------------------------------------------------------------------------------------------------------------|+| timestamp | Indicates the time information when an event occurs. It can be a specific date, time point, or valid time range. |+| event | Indicates the event content corresponding to the time information and describes the main occurrence. |Users can add entity types based on actual requirements to supplement time-related information that needs attention.@@ -393,11 +393,11 @@ Relationship configuration defines associations between entities and describes cEach relationship contains the following configuration items:-| Configuration Item | Description |-| --- | --- |-| Type | Relationship type name, used to define the connection method between entities. |-| Description | Describes the meaning and applicable scenarios of the relationship. |-| Rule | Restricts relationship generation methods, such as sorting rules and connection conditions. |+| Configuration Item | Description |+|--------------------|---------------------------------------------------------------------------------------------|+| Type | Relationship type name, used to define the connection method between entities. |+| Description | Describes the meaning and applicable scenarios of the relationship. |+| Rule | Restricts relationship generation methods, such as sorting rules and connection conditions. |The system provides the following default relationship type:diff --git a/docs/guides/team/team_management/join_and_leave_teams.md b/docs/guides/team/team_management/join_and_leave_teams.mdindex 935828468e..769f0b9ff3 100644--- a/docs/guides/team/team_management/join_and_leave_teams.md+++ b/docs/guides/team/team_management/join_and_leave_teams.md@@ -37,7 +37,7 @@ When someone invites you to their team, you can respond from your own account:After you accept, the invitation actions are replaced by a leave-team icon. Find resources shared with **Team** in the corresponding Dataset, Agent, or Memory list. See [Team usage guides](../resource_sharing/resource_sharing_and_permissions.md#find-the-sharing-setting). Private resources remain unavailable.-If you decline, the invitation is removed from the active list and you do not join the team. The owner can invite you again later if needed.+If you decline, the invitation is removed from the active list, and you do not join the team. The owner can invite you again later if needed.## Leave a Teamdiff --git a/docs/references/http_api_reference.md b/docs/references/http_api_reference.mdindex f8ce271503..373933b921 100644--- a/docs/references/http_api_reference.md+++ b/docs/references/http_api_reference.md@@ -6234,7 +6234,7 @@ curl --location 'http://{address}/api/v1/messages' \- `user_id`: `string`, *Optional*- The user participating in the conversation with the agent. Honoured only when the request is authenticated with an API key. For API key authentication, this field must be a non-empty string; surrounding whitespace is stripped, and a missing, blank, or non-string value causes the request to fail. Any other authentication, whether a JWT bearer token or a browser session, ignores this field and attributes the message to the authenticated user.+ The user participating in the conversation with the agent. Honored only when the request is authenticated with an API key. For API key authentication, this field must be a non-empty string; surrounding whitespace is stripped, and a missing, blank, or non-string value causes the request to fail. Any other authentication, whether a JWT bearer token or a browser session, ignores this field and attributes the message to the authenticated user.- `user_input`: `string`, *Required*@@ -7599,7 +7599,7 @@ Failure:**GET** `/api/v1/workspaces/{workspace_id}/commits`-Lists all commits for the specified folder with pagination. Also available at:+Lists all commits for the specified folder with pagination. Also, available at:- `/api/v1/datasets/{dataset_id}/commits`#### Request@@ -7665,7 +7665,7 @@ Success:**GET** `/api/v1/workspaces/{workspace_id}/commits/{commit_id}`-Retrieves the details of a specific commit, including its file changes. Also available at:+Retrieves the details of a specific commit, including its file changes. Also, available at:- `/api/v1/datasets/{dataset_id}/commits/{commit_id}`#### Request@@ -7734,7 +7734,7 @@ Failure:**GET** `/api/v1/workspaces/{workspace_id}/commits/{commit_id}/files`-Lists the file changes associated with a specific commit. Also available at:+Lists the file changes associated with a specific commit. Also, available at:- `/api/v1/datasets/{dataset_id}/commits/{commit_id}/files`#### Request@@ -7781,7 +7781,7 @@ Success:**GET** `/api/v1/workspaces/{workspace_id}/commits/diff?from={commit_id}&to={commit_id}`-Compares two commits and returns the differences. Also available at:+Compares two commits and returns the differences. Also, available at:- `/api/v1/datasets/{dataset_id}/commits/diff?from=...&to=...`#### Request@@ -7847,7 +7847,7 @@ Failure:**GET** `/api/v1/workspaces/{workspace_id}/changes`-Returns the uncommitted changes for the specified folder (similar to `git status`). Also available at:+Returns the uncommitted changes for the specified folder (similar to `git status`). Also, available at:- `/api/v1/datasets/{dataset_id}/changes`#### Request@@ -7898,7 +7898,7 @@ Success:**GET** `/api/v1/workspaces/{workspace_id}/commits/{commit_id}/tree`-Retrieves the full folder tree snapshot as it existed at a specific commit. Also available at:+Retrieves the full folder tree snapshot as it existed at a specific commit. Also, available at:- `/api/v1/datasets/{dataset_id}/commits/{commit_id}/tree`#### Request@@ -7964,7 +7964,7 @@ Success:**GET** `/api/v1/workspaces/{workspace_id}/commits/{commit_id}/files/{file_id}/content`-Retrieves the file content as it existed at a specific commit. Also available at:+Retrieves the file content as it existed at a specific commit. Also, available at:- `/api/v1/datasets/{dataset_id}/commits/{commit_id}/files/{file_id}/content`#### Request