
RAGFlow is an agent-native database: a Retrieval-Augmented Generation (RAG) engine that grew into context infrastructure.
Go agent-harnessagent-native-databaseagentic-aiagentic-retrievalagentic-searchaiai-agentscontext-enginecontext-engineeringcontext-managementharness-engineeringknowledge-compilationragretrieval-augmented-generationretrieval-harnesssearch-harness
docs: modify docs display & add images (#17575)
YanZhang611e0596f6ec
diff --git a/docs/administrator/_category_.json b/docs/administrator/_category_.jsonindex e00d9a56ab..fbcfb3b9e4 100644--- a/docs/administrator/_category_.json+++ b/docs/administrator/_category_.json@@ -1,5 +1,5 @@{- "label": "Administrator guides",+ "label": "Administrator Guides","position": 4,"link": {"type": "generated-index",diff --git a/docs/administrator/admin/_category_.json b/docs/administrator/admin/_category_.jsonindex c05f2e4800..e6b4068b3c 100644--- a/docs/administrator/admin/_category_.json+++ b/docs/administrator/admin/_category_.json@@ -1,5 +1,5 @@{- "label": "Admin service",+ "label": "Admin Service","position": 3,"link": {"type": "generated-index",diff --git a/docs/administrator/admin/admin_service.md b/docs/administrator/admin/admin_service.mdindex 35ecabae93..7ec27c390b 100644--- a/docs/administrator/admin/admin_service.md+++ b/docs/administrator/admin/admin_service.md@@ -1,5 +1,7 @@---sidebar_position: 0+title: Admin Service+sidebar_label: Admin Serviceslug: /admin_servicesidebar_custom_props: {categoryIcon: LucideActivity@@ -15,7 +17,7 @@ With its unified interface design, the Admin Service combines the convenience of## Starting the Admin Service-### Launching from source code+### Launching from Source Code1. Before start Admin Service, please make sure RAGFlow system is already started.@@ -27,7 +29,7 @@ With its unified interface design, the Admin Service combines the convenience ofThe service will start and listen for incoming connections from the CLI on the configured port.-### Using docker image+### Using Docker Image1. Before startup, please configure the `docker_compose.yml` file to enable admin server:diff --git a/docs/administrator/admin/admin_ui/before_you_begin.md b/docs/administrator/admin/admin_ui/before_you_begin.mdindex 88e871e8f2..b22ce5cacc 100644--- a/docs/administrator/admin/admin_ui/before_you_begin.md+++ b/docs/administrator/admin/admin_ui/before_you_begin.md@@ -1,6 +1,7 @@---sidebar_position: 1-sidebar_label: "Before You Begin"+sidebar_label: Before You Begin+title: Before You Begin---# Before You Begin@@ -11,7 +12,7 @@ System administrators can access the RAGFlow Admin UI in a browser. The currentAfter entering the Admin UI, administrators can perform service health checks, maintain user accounts, configure sandboxes, control registration, manage roles and permissions, configure system settings, and configure identity providers. The Admin UI should be exposed only to trusted administrators.-+Regular users do not need to enter the Admin UI when they use business features such as knowledge bases, chat, Agent, files, and model providers.diff --git a/docs/administrator/admin/admin_ui/check_system_status.md b/docs/administrator/admin/admin_ui/check_system_status.mdindex 8649c2a92f..3bfa93725d 100644--- a/docs/administrator/admin/admin_ui/check_system_status.md+++ b/docs/administrator/admin/admin_ui/check_system_status.md@@ -1,6 +1,7 @@---sidebar_position: 2-sidebar_label: "Check System Status"+sidebar_label: Check System Status+title: Check System Status---# Check System Status@@ -9,11 +10,11 @@ sidebar_label: "Check System Status"After entering the Admin UI, open the **Service status** page to view the runtime status of RAGFlow and its dependent services. The page displays each service's name, service type, host, port, and current status, so administrators can confirm whether all system components are running normally.-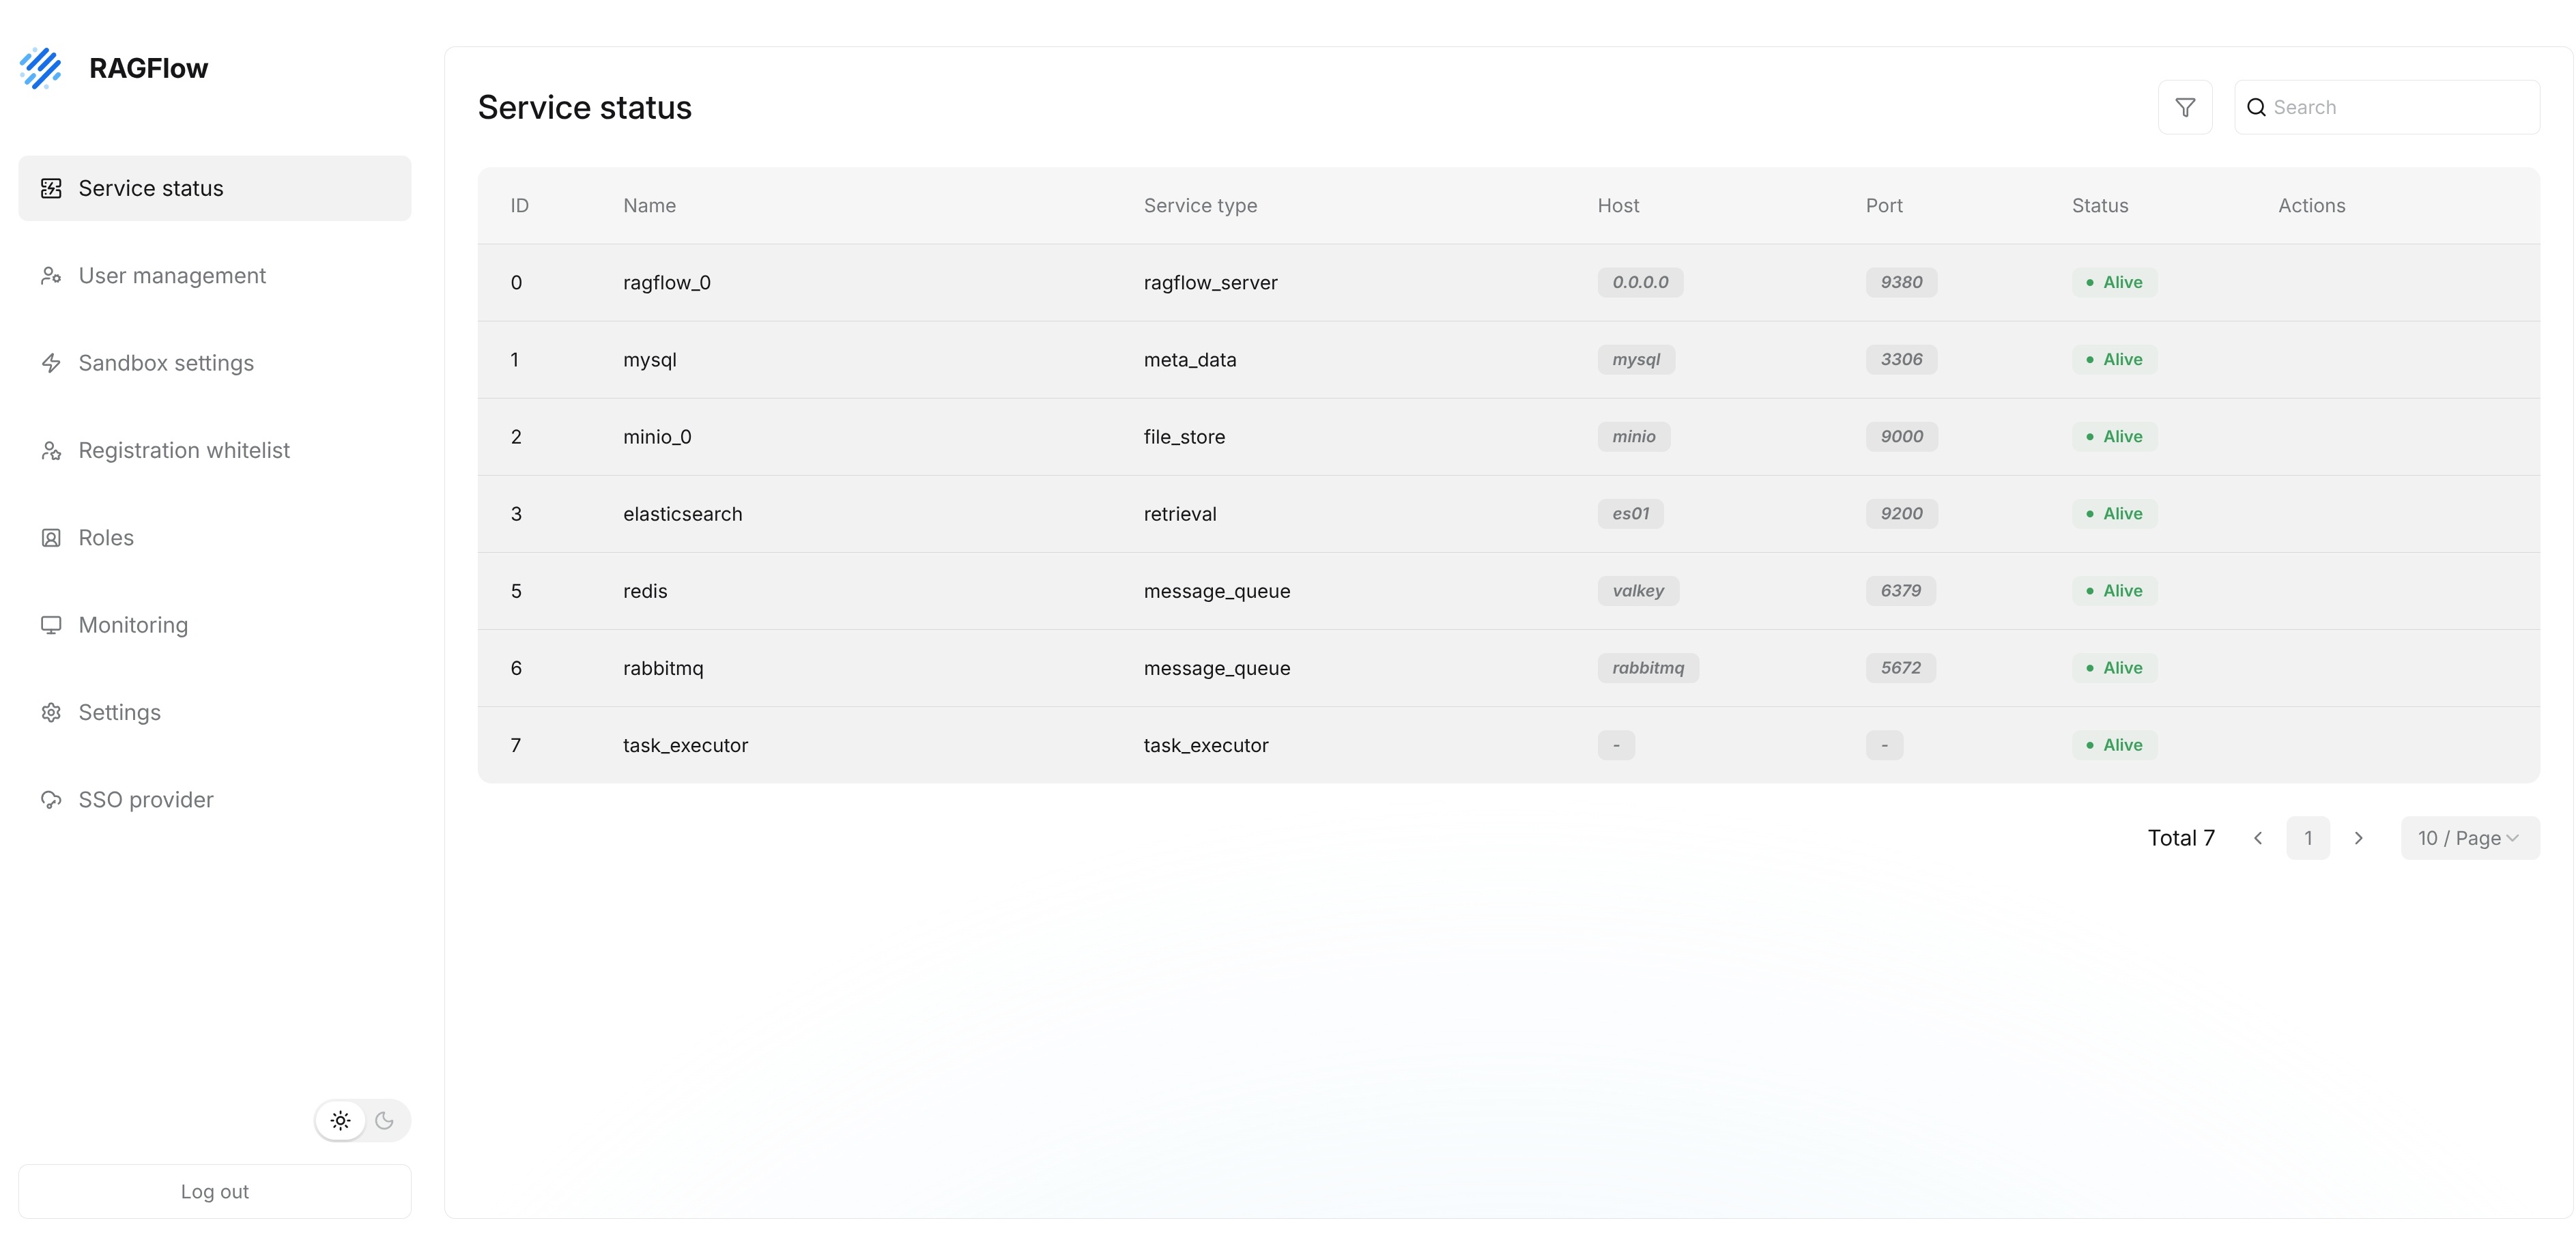+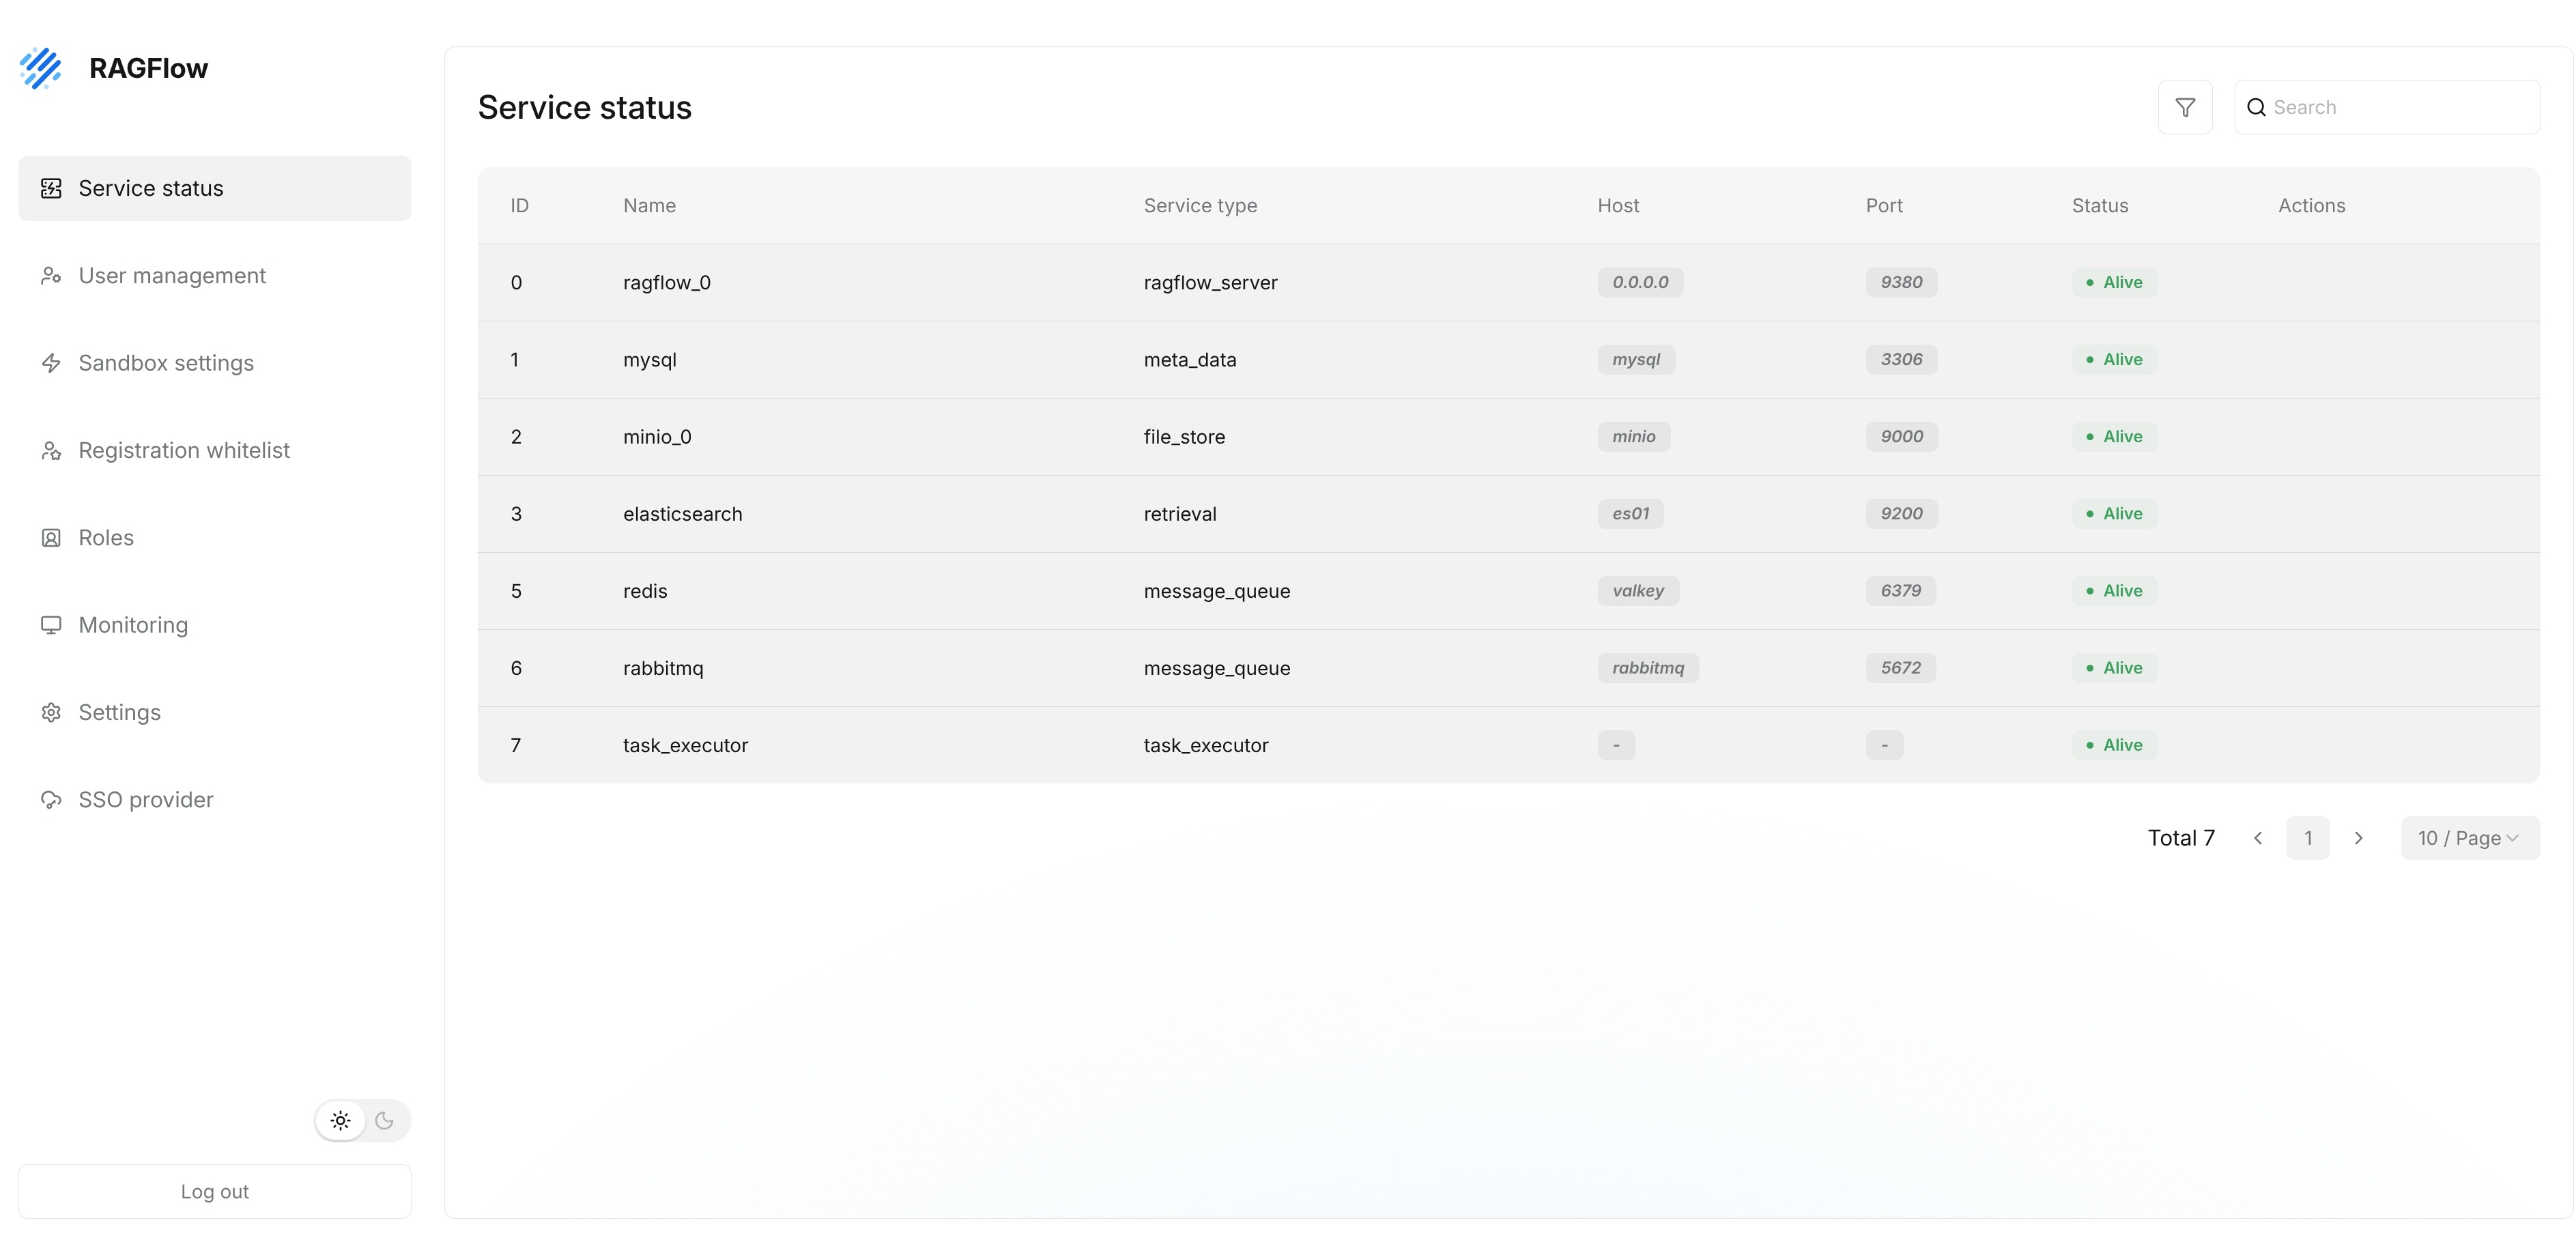When **Status** is `Alive`, the service is running normally. Any other status may affect the corresponding features.-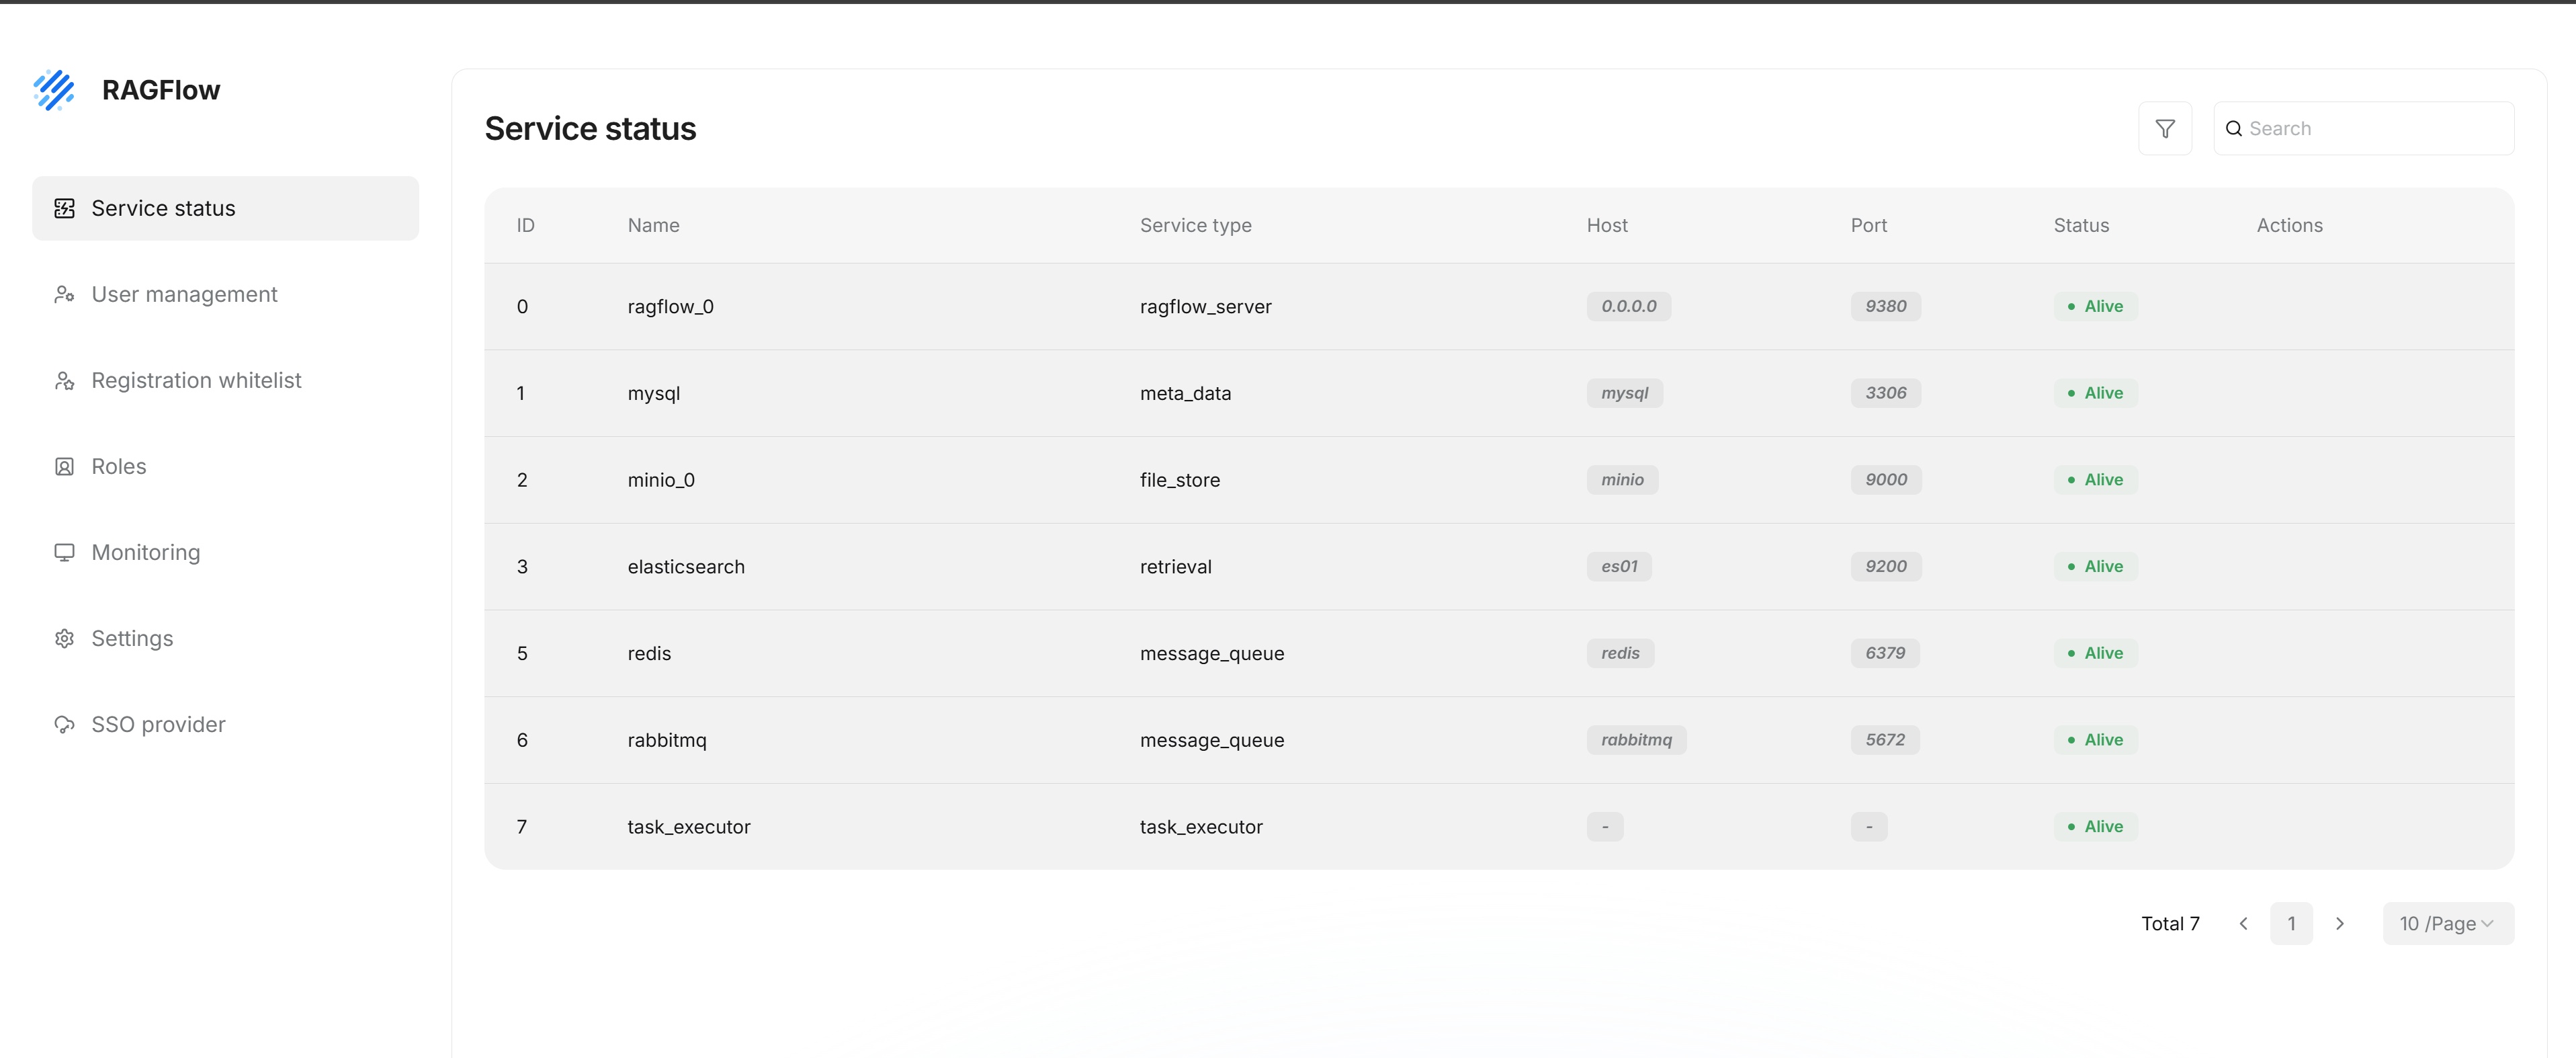+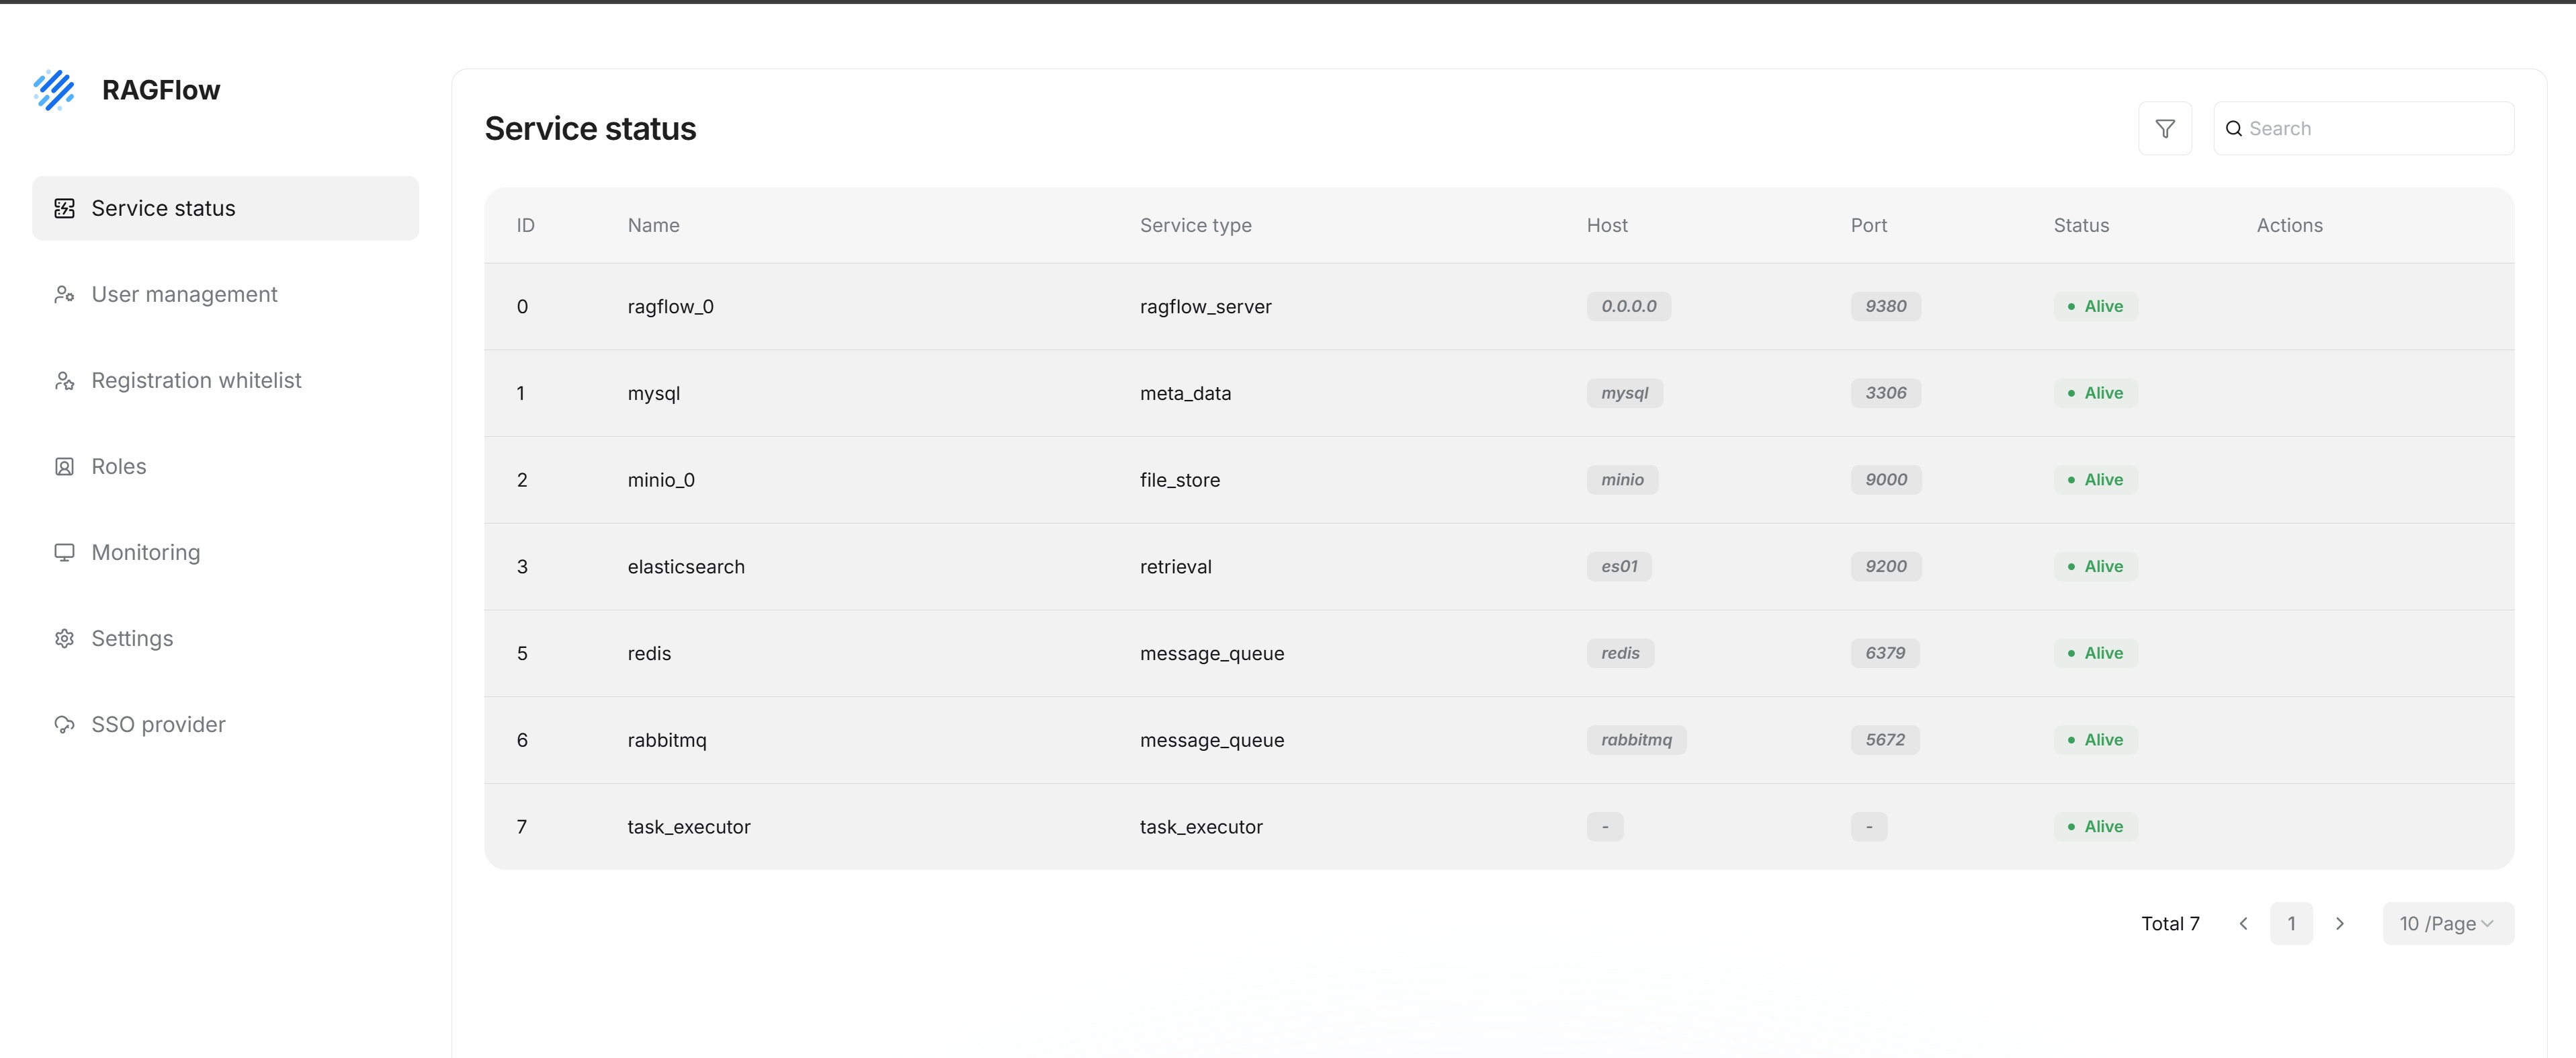| Service name | Main purpose | Possible issues when abnormal | Affected features || --- | --- | --- | --- |@@ -31,15 +32,15 @@ On the **Service status** page, administrators can view the service `ID`, `Name`Administrators can open service details from **Actions**. Different services display different details. For example, the `mysql` service details show current database connection and process information, including `command`, `db`, `host`, `id`, `info`, `state`, `time`, and `user`. Administrators can use this information to determine whether there are long-running connections, waiting states, or abnormal queries.-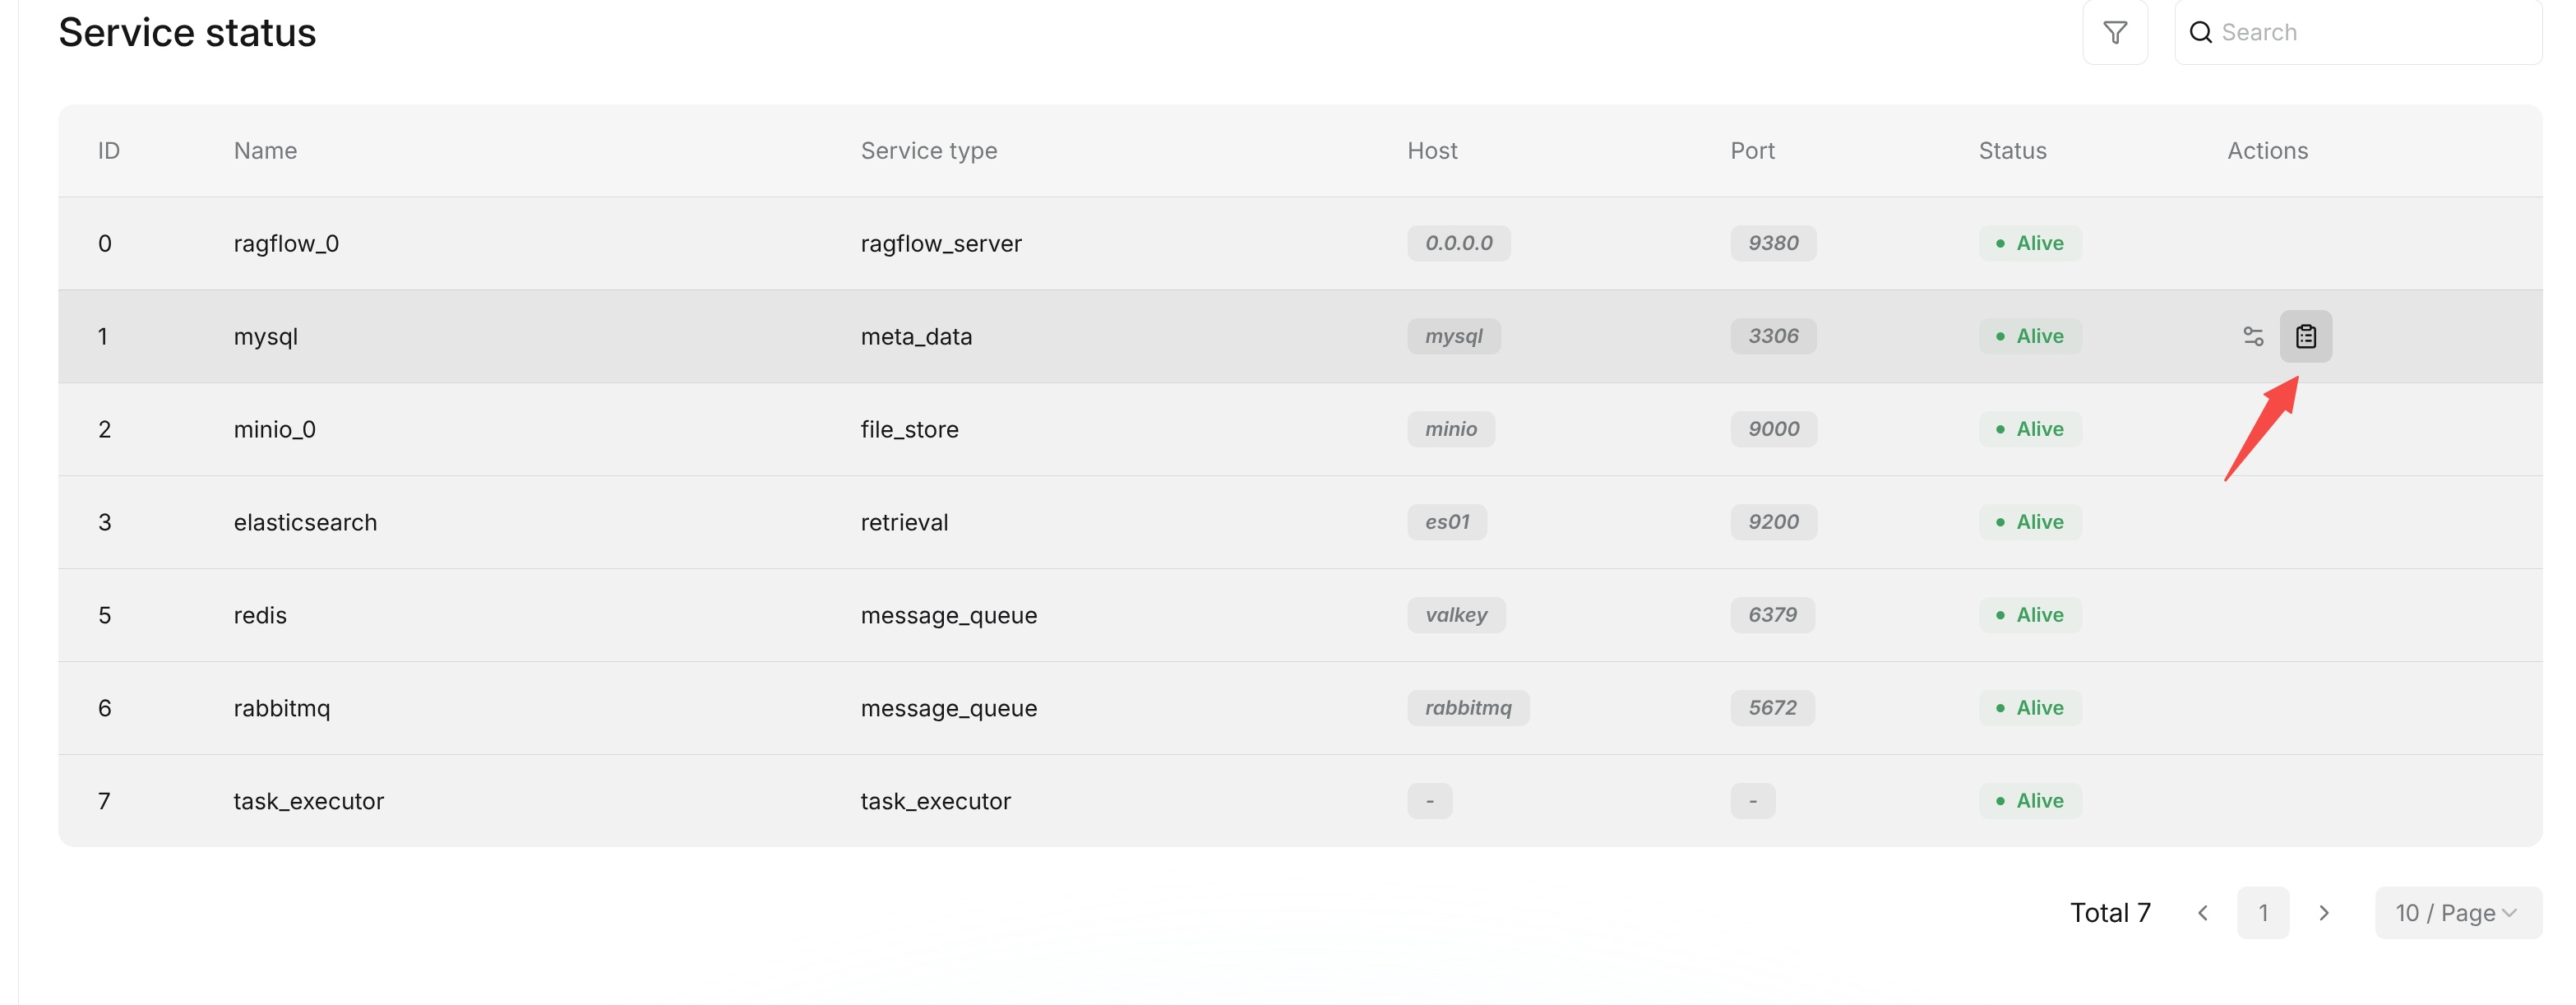+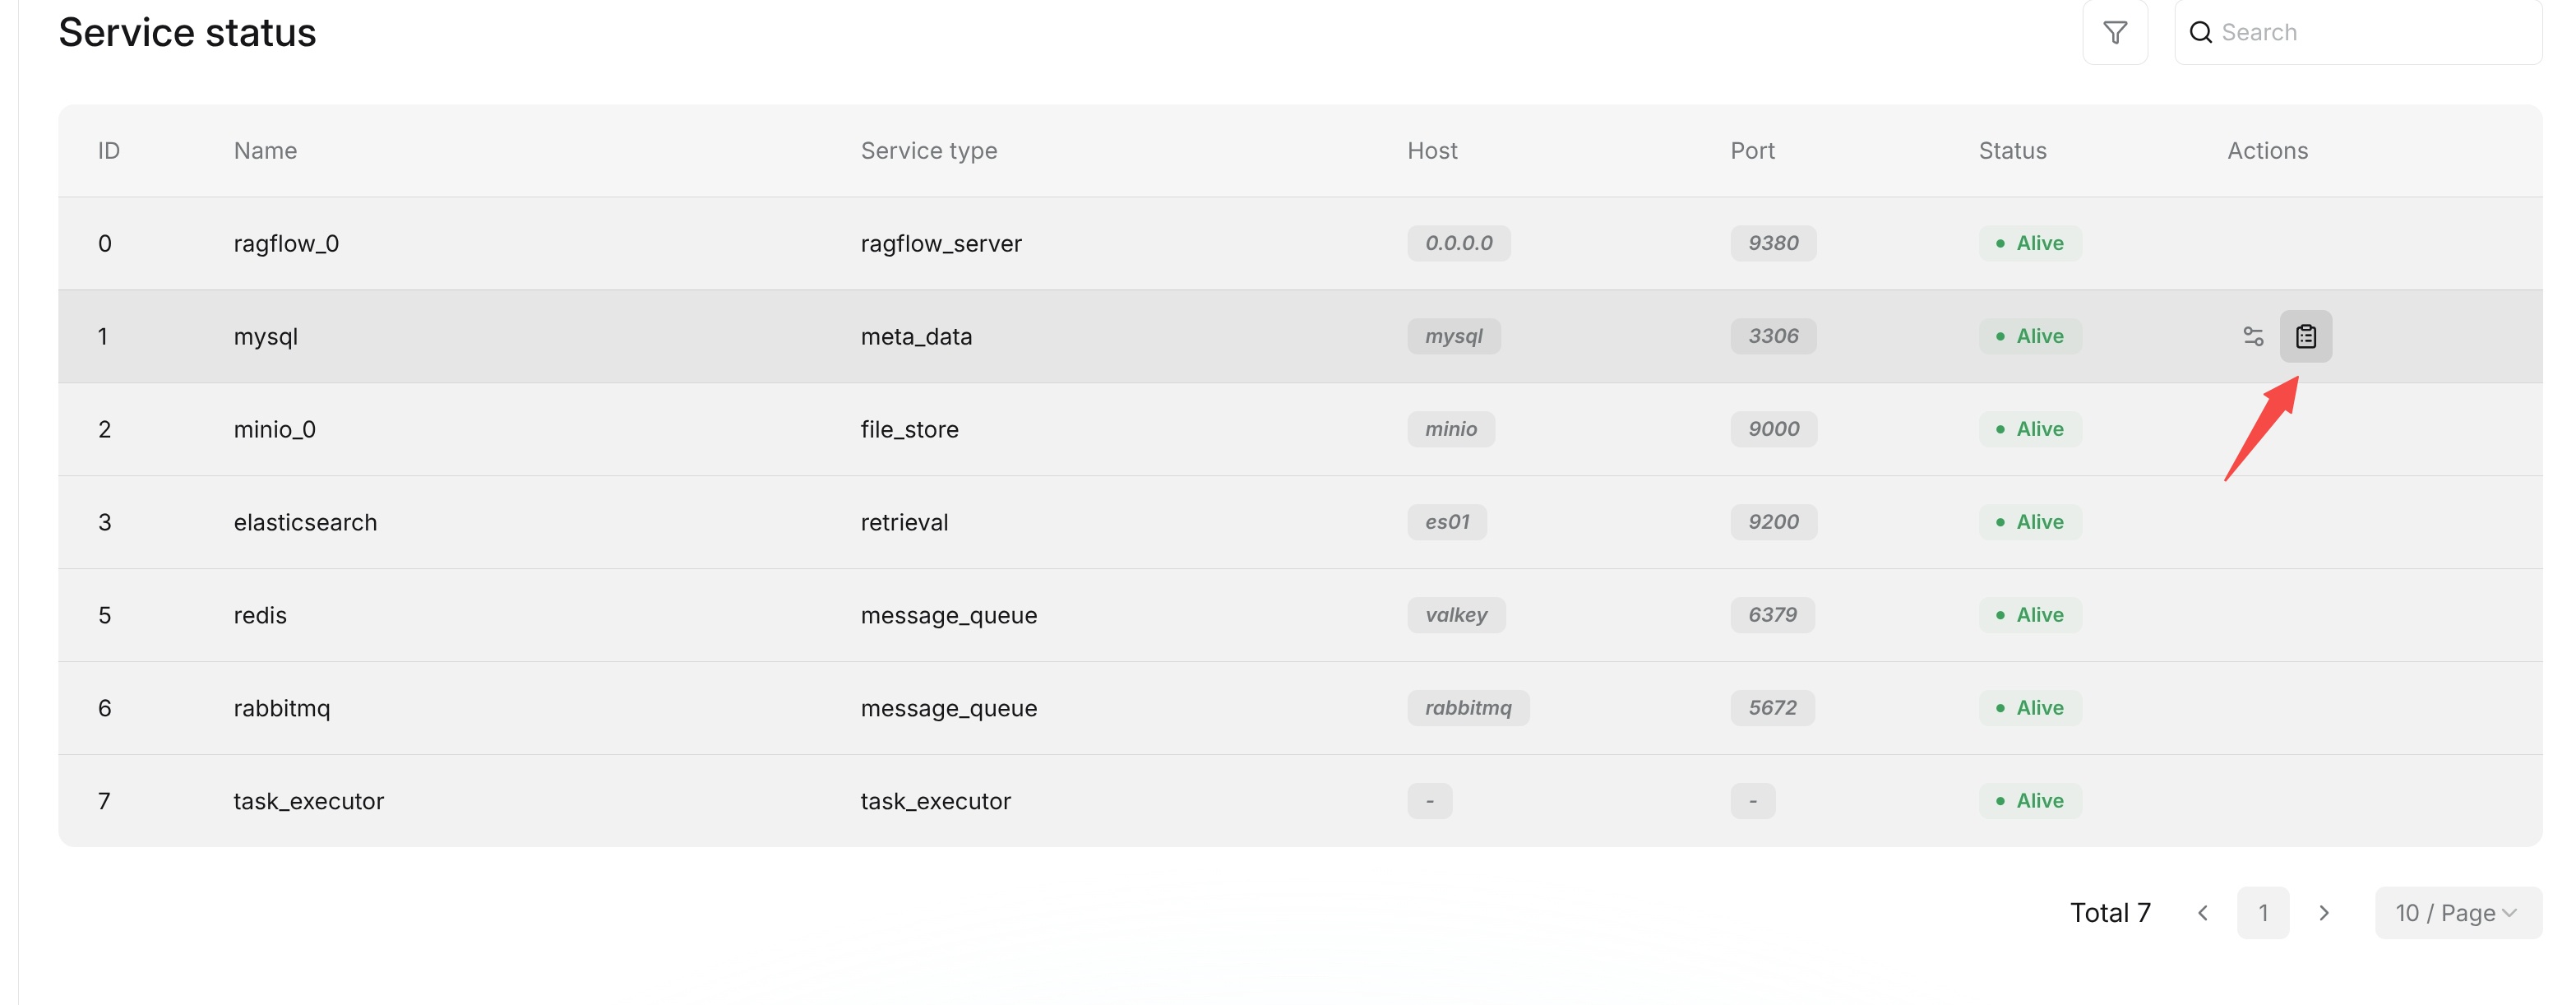-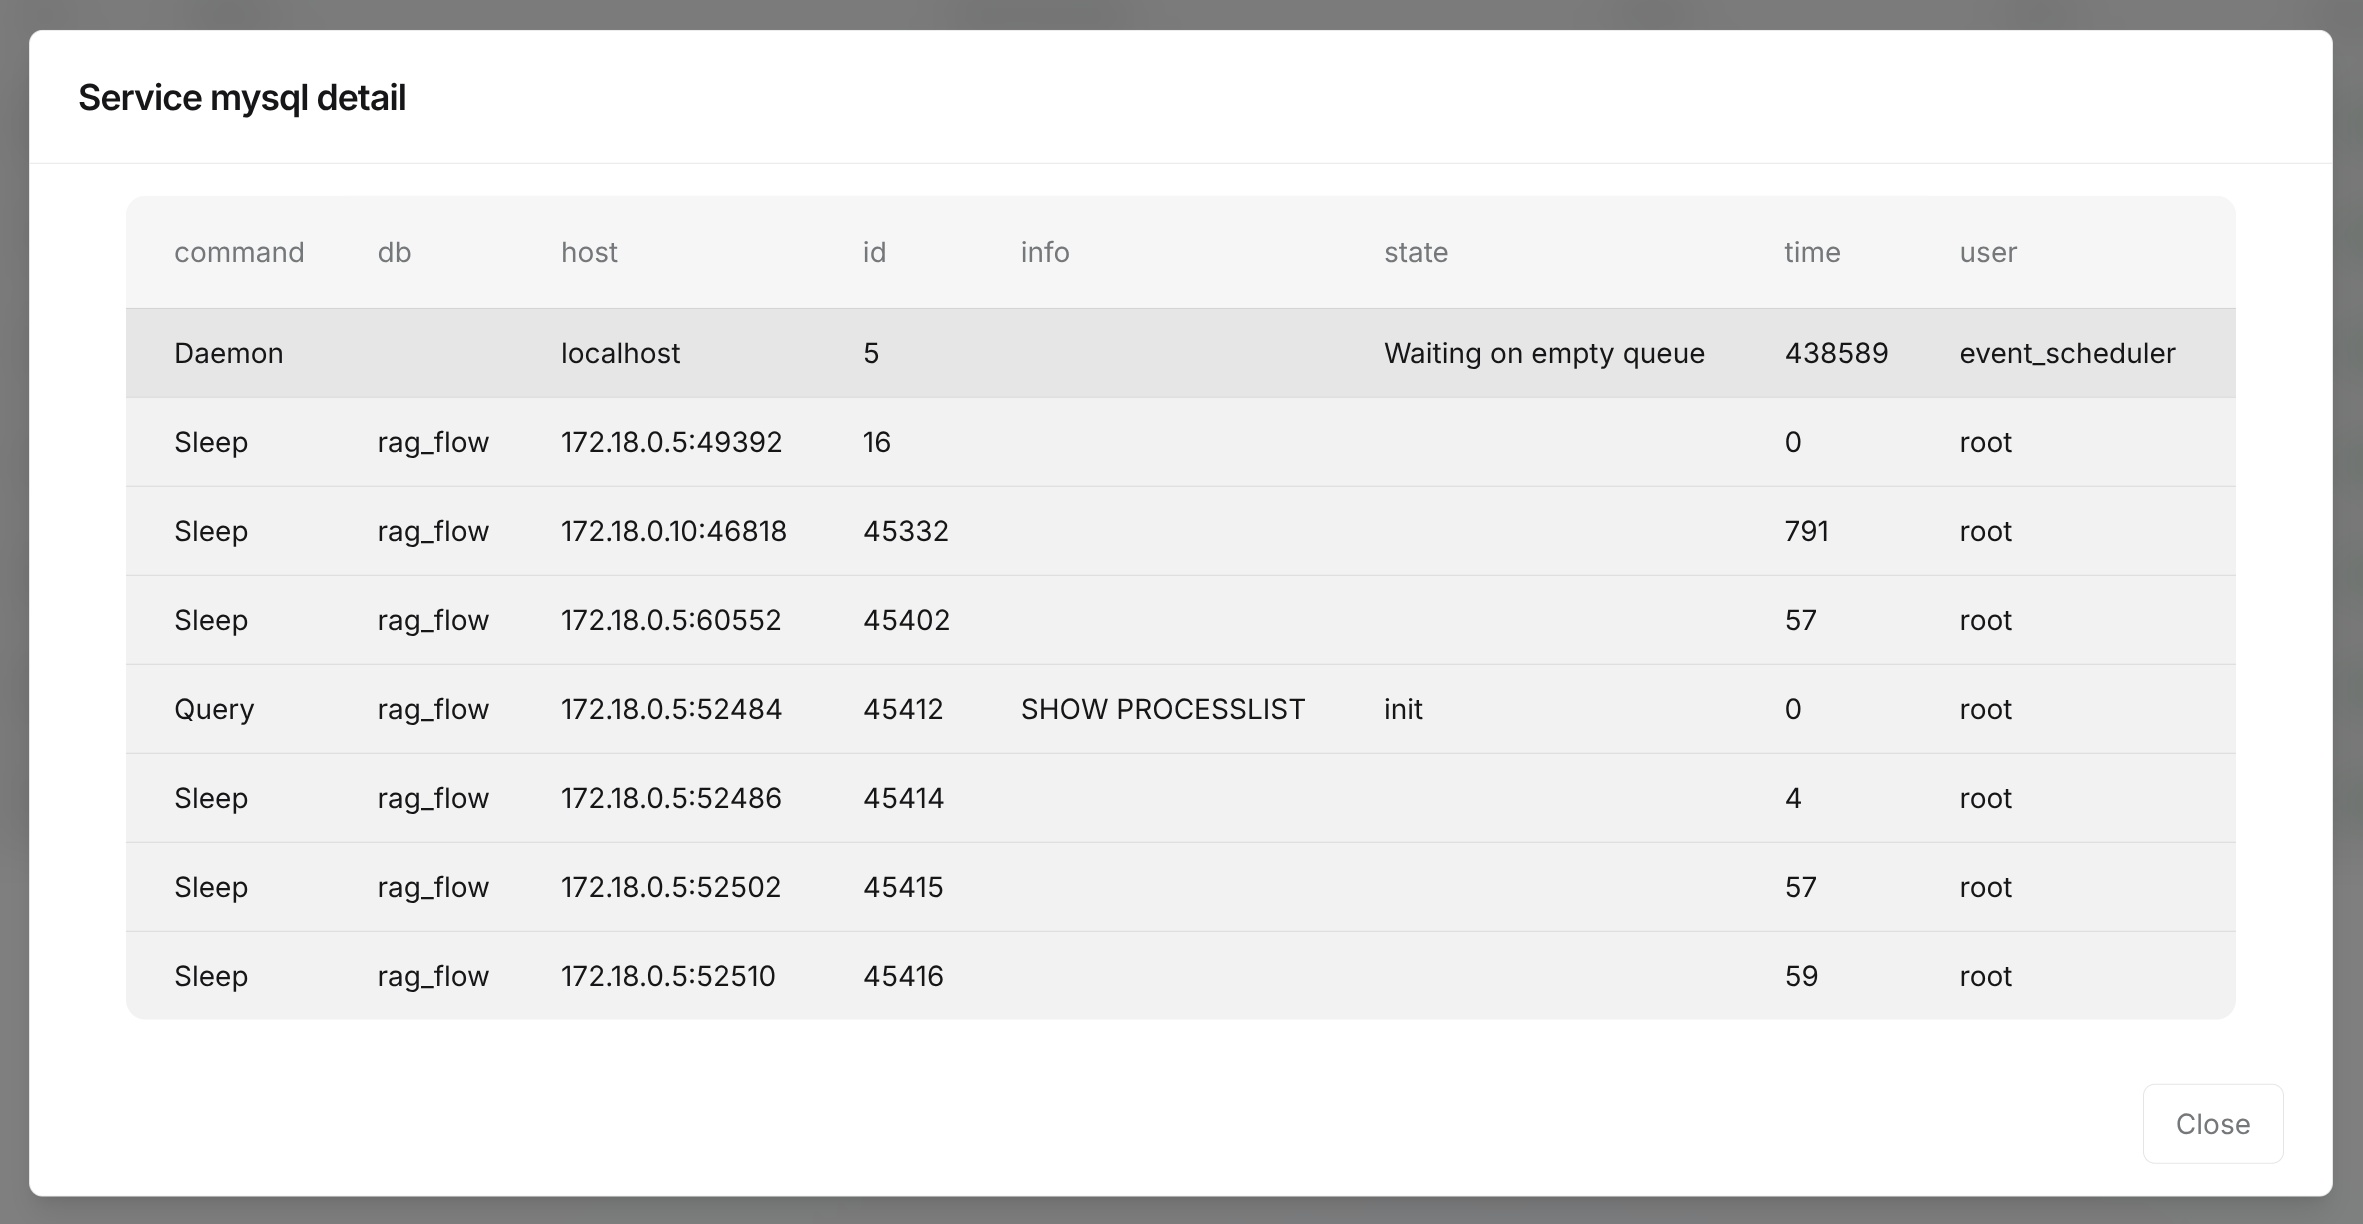+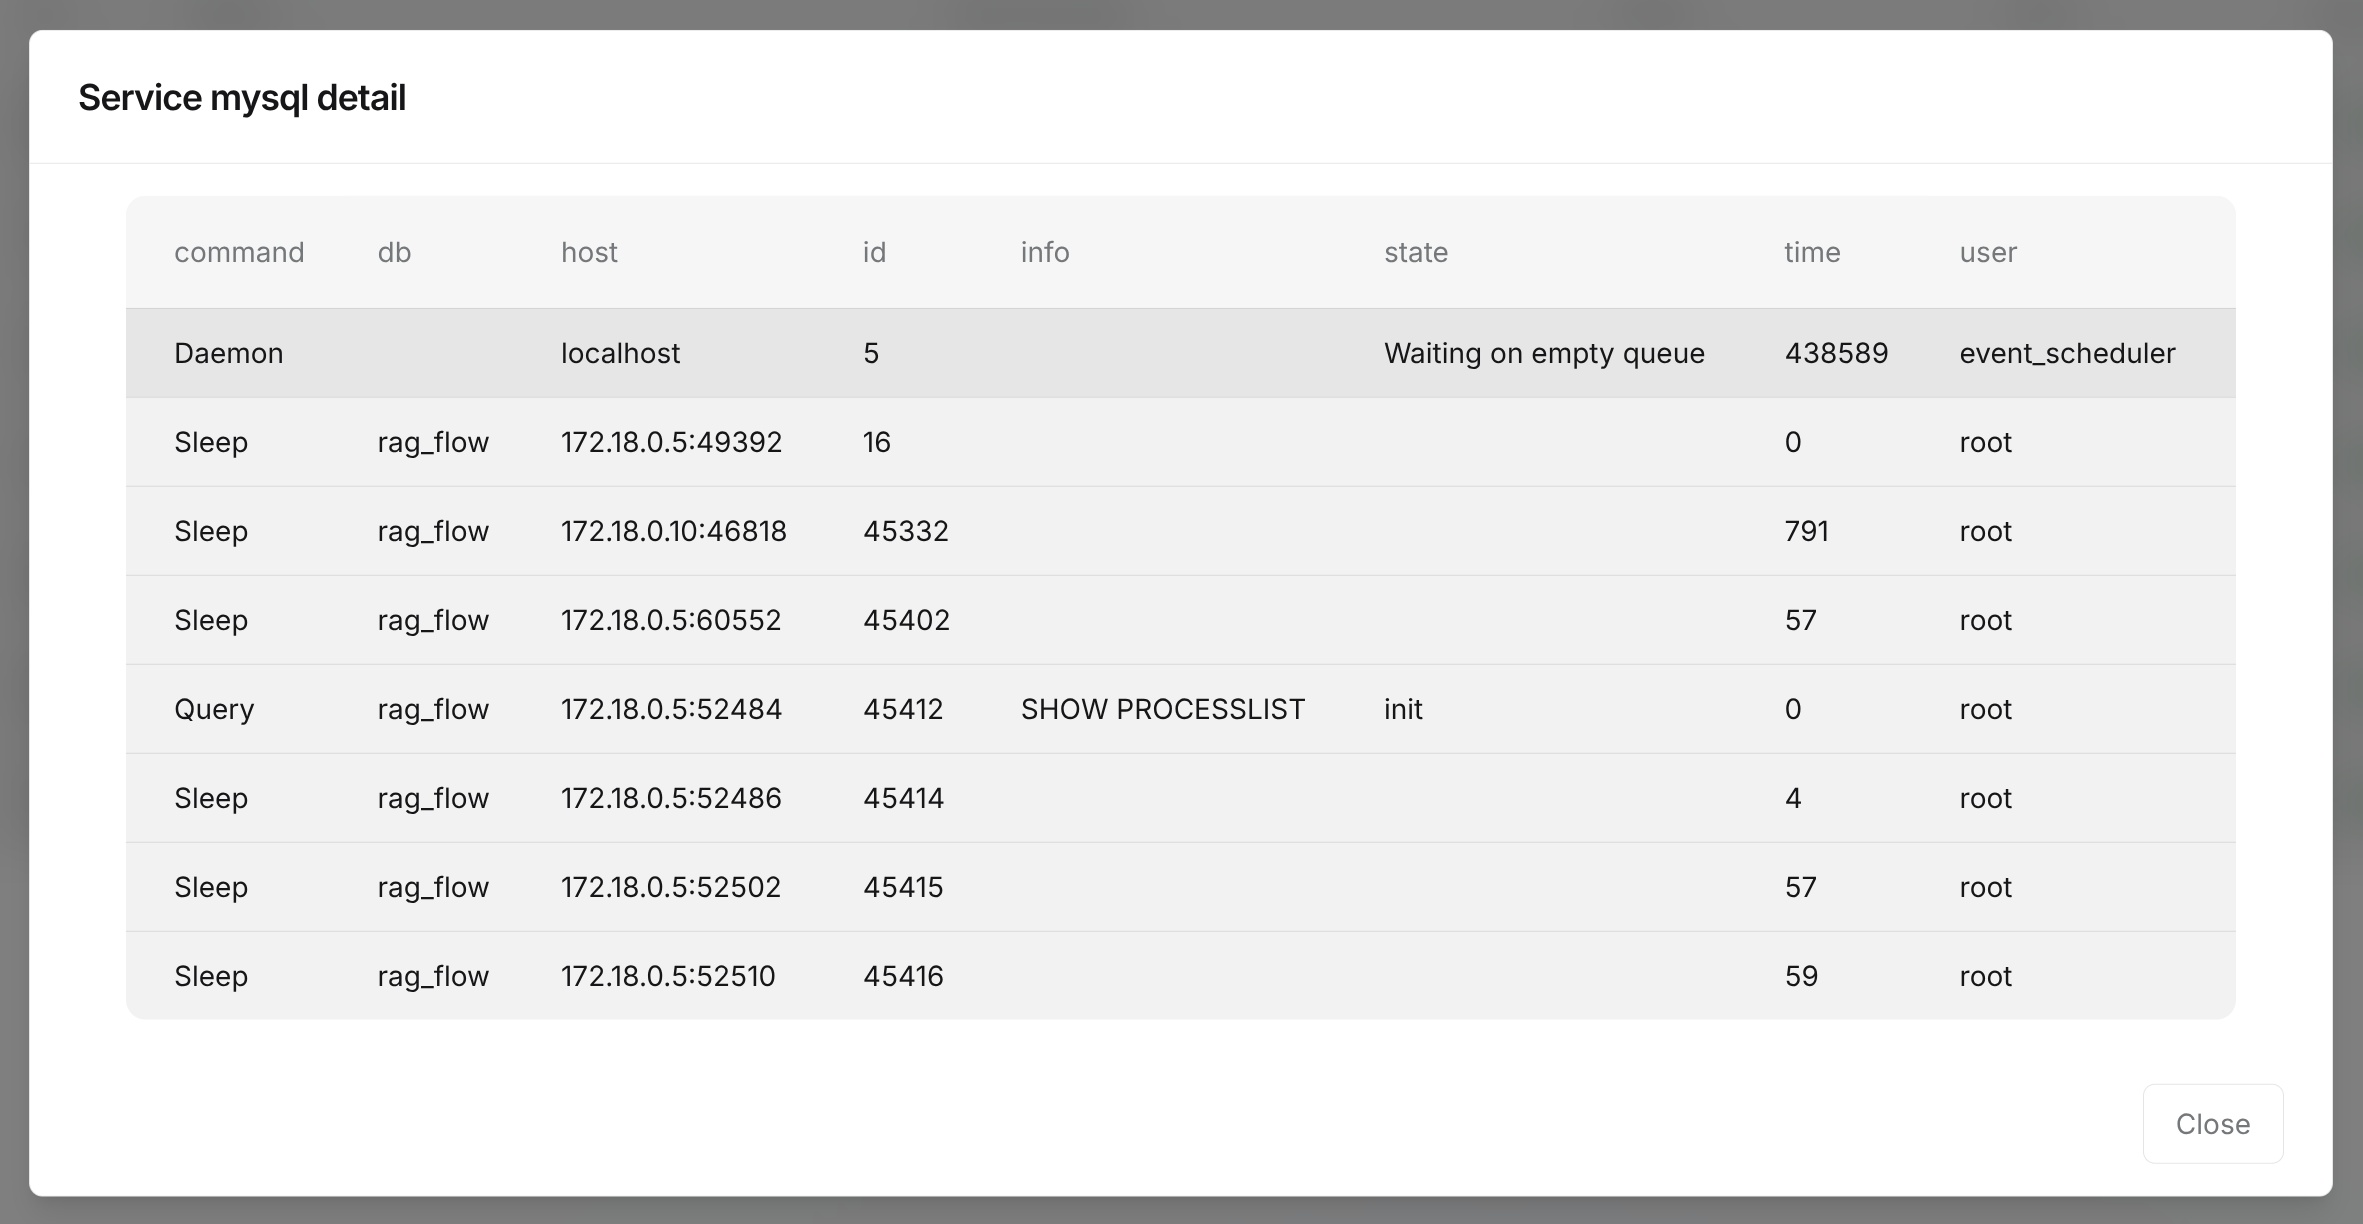Some services also provide an **Extra information** dialog that displays supplementary configuration information. For example, an object storage service may display information such as `store_type` and `user`. This information is mainly used to confirm service configuration.-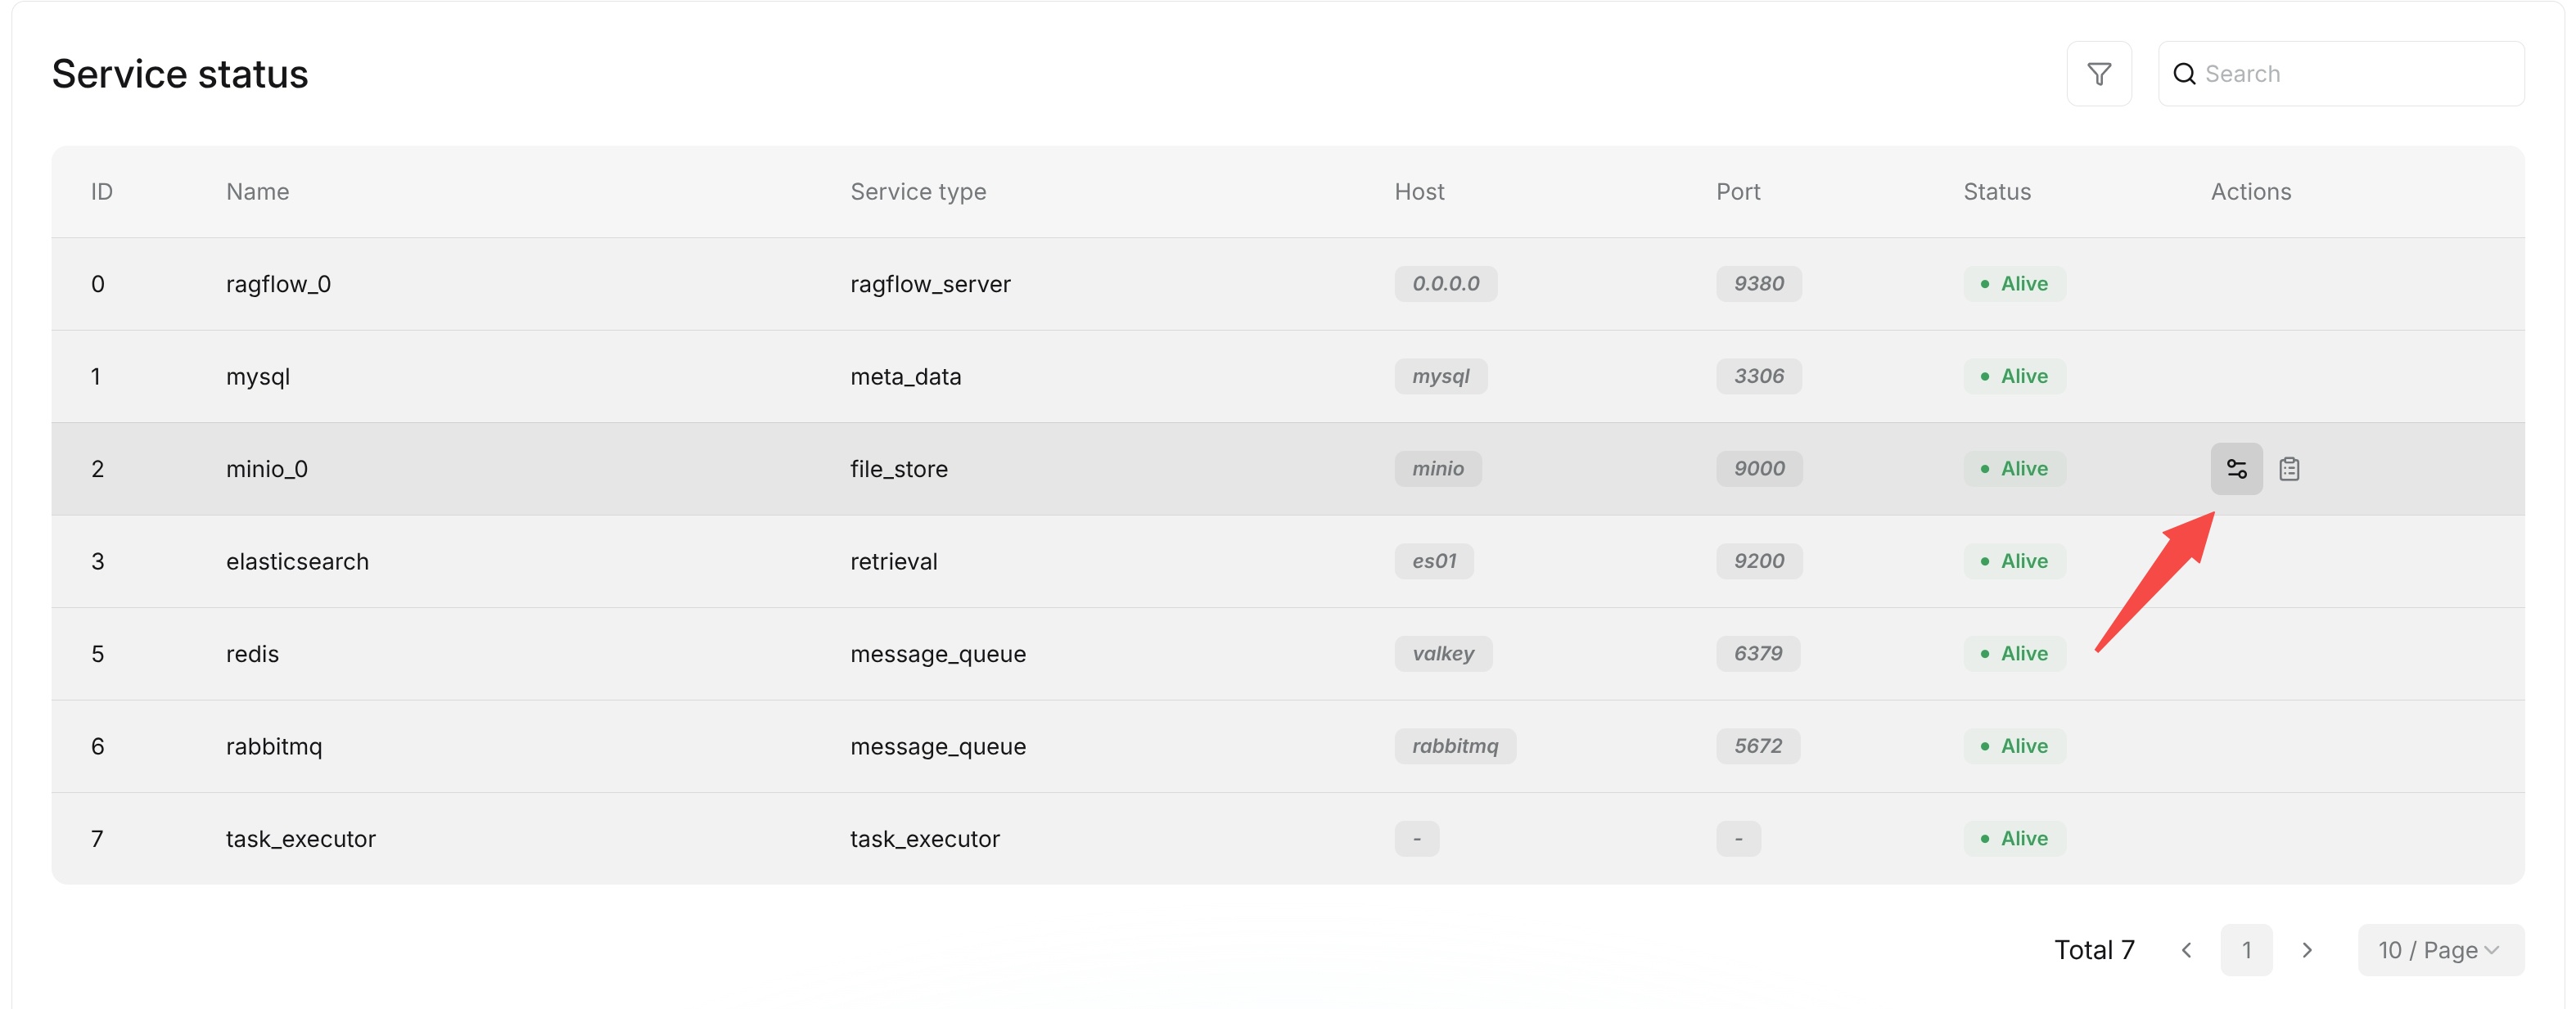+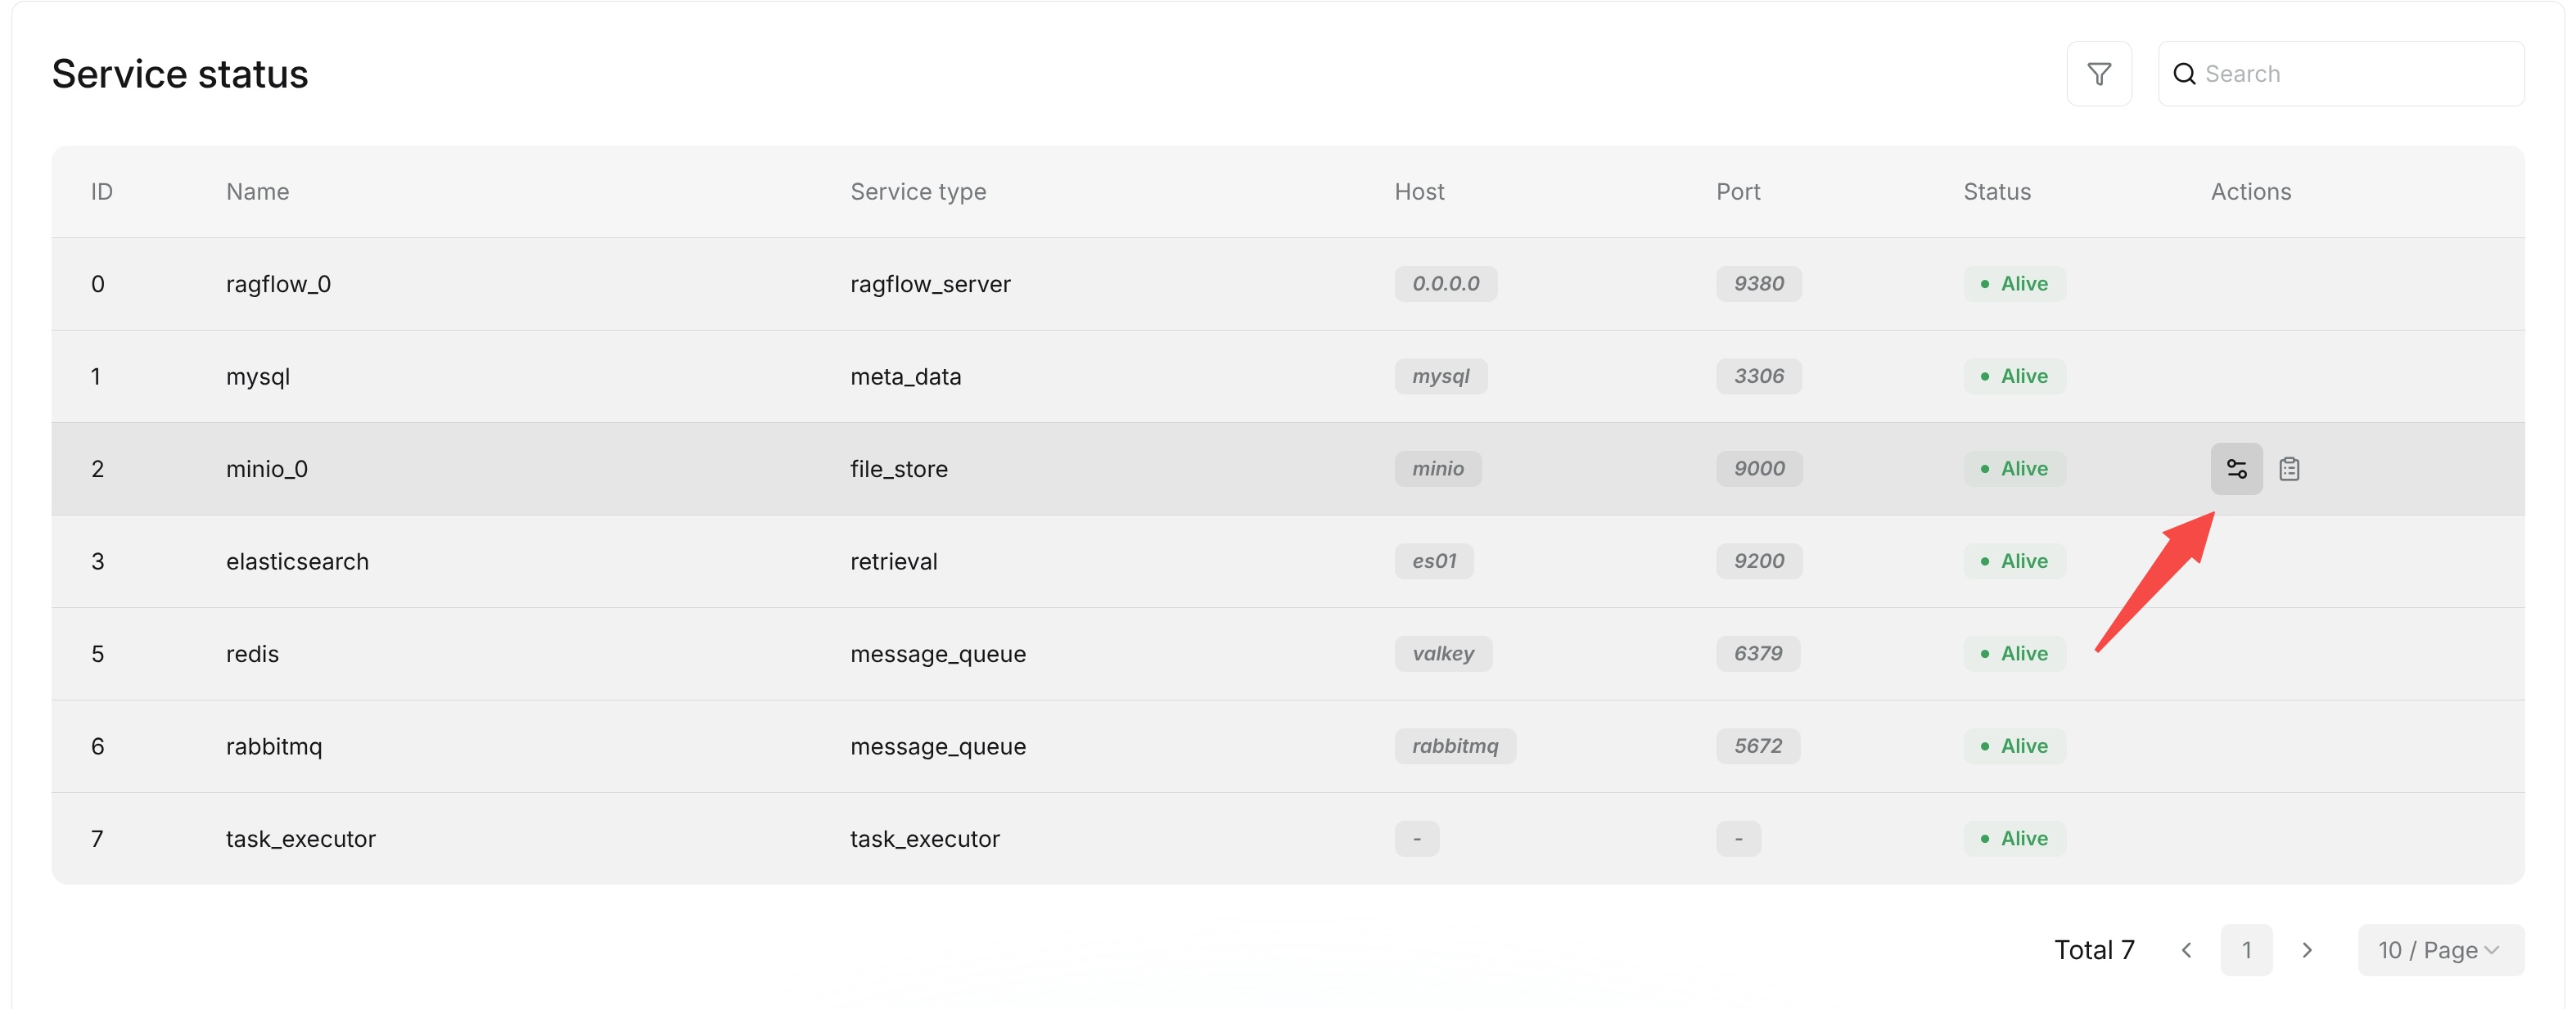-+If a service's `Status` is not `Alive`, first record its `ID`, `Name`, `Service type`, `Host`, `Port`, and any abnormal information visible in the details dialog or **Extra information**.diff --git a/docs/administrator/admin/admin_ui/configure_code_execution_sandbox.md b/docs/administrator/admin/admin_ui/configure_code_execution_sandbox.mdindex 7f4a1e4bdb..be0c3514f6 100644--- a/docs/administrator/admin/admin_ui/configure_code_execution_sandbox.md+++ b/docs/administrator/admin/admin_ui/configure_code_execution_sandbox.md@@ -1,6 +1,7 @@---sidebar_position: 4-sidebar_label: "Configure Code Execution Sandbox"+sidebar_label: Configure Code Execution Sandbox+title: Configure Code Execution Sandbox---# Configure Code Execution Sandbox@@ -21,7 +22,7 @@ The current page supports the following `Provider` options:After selecting a `Provider`, the page displays the corresponding configuration area.-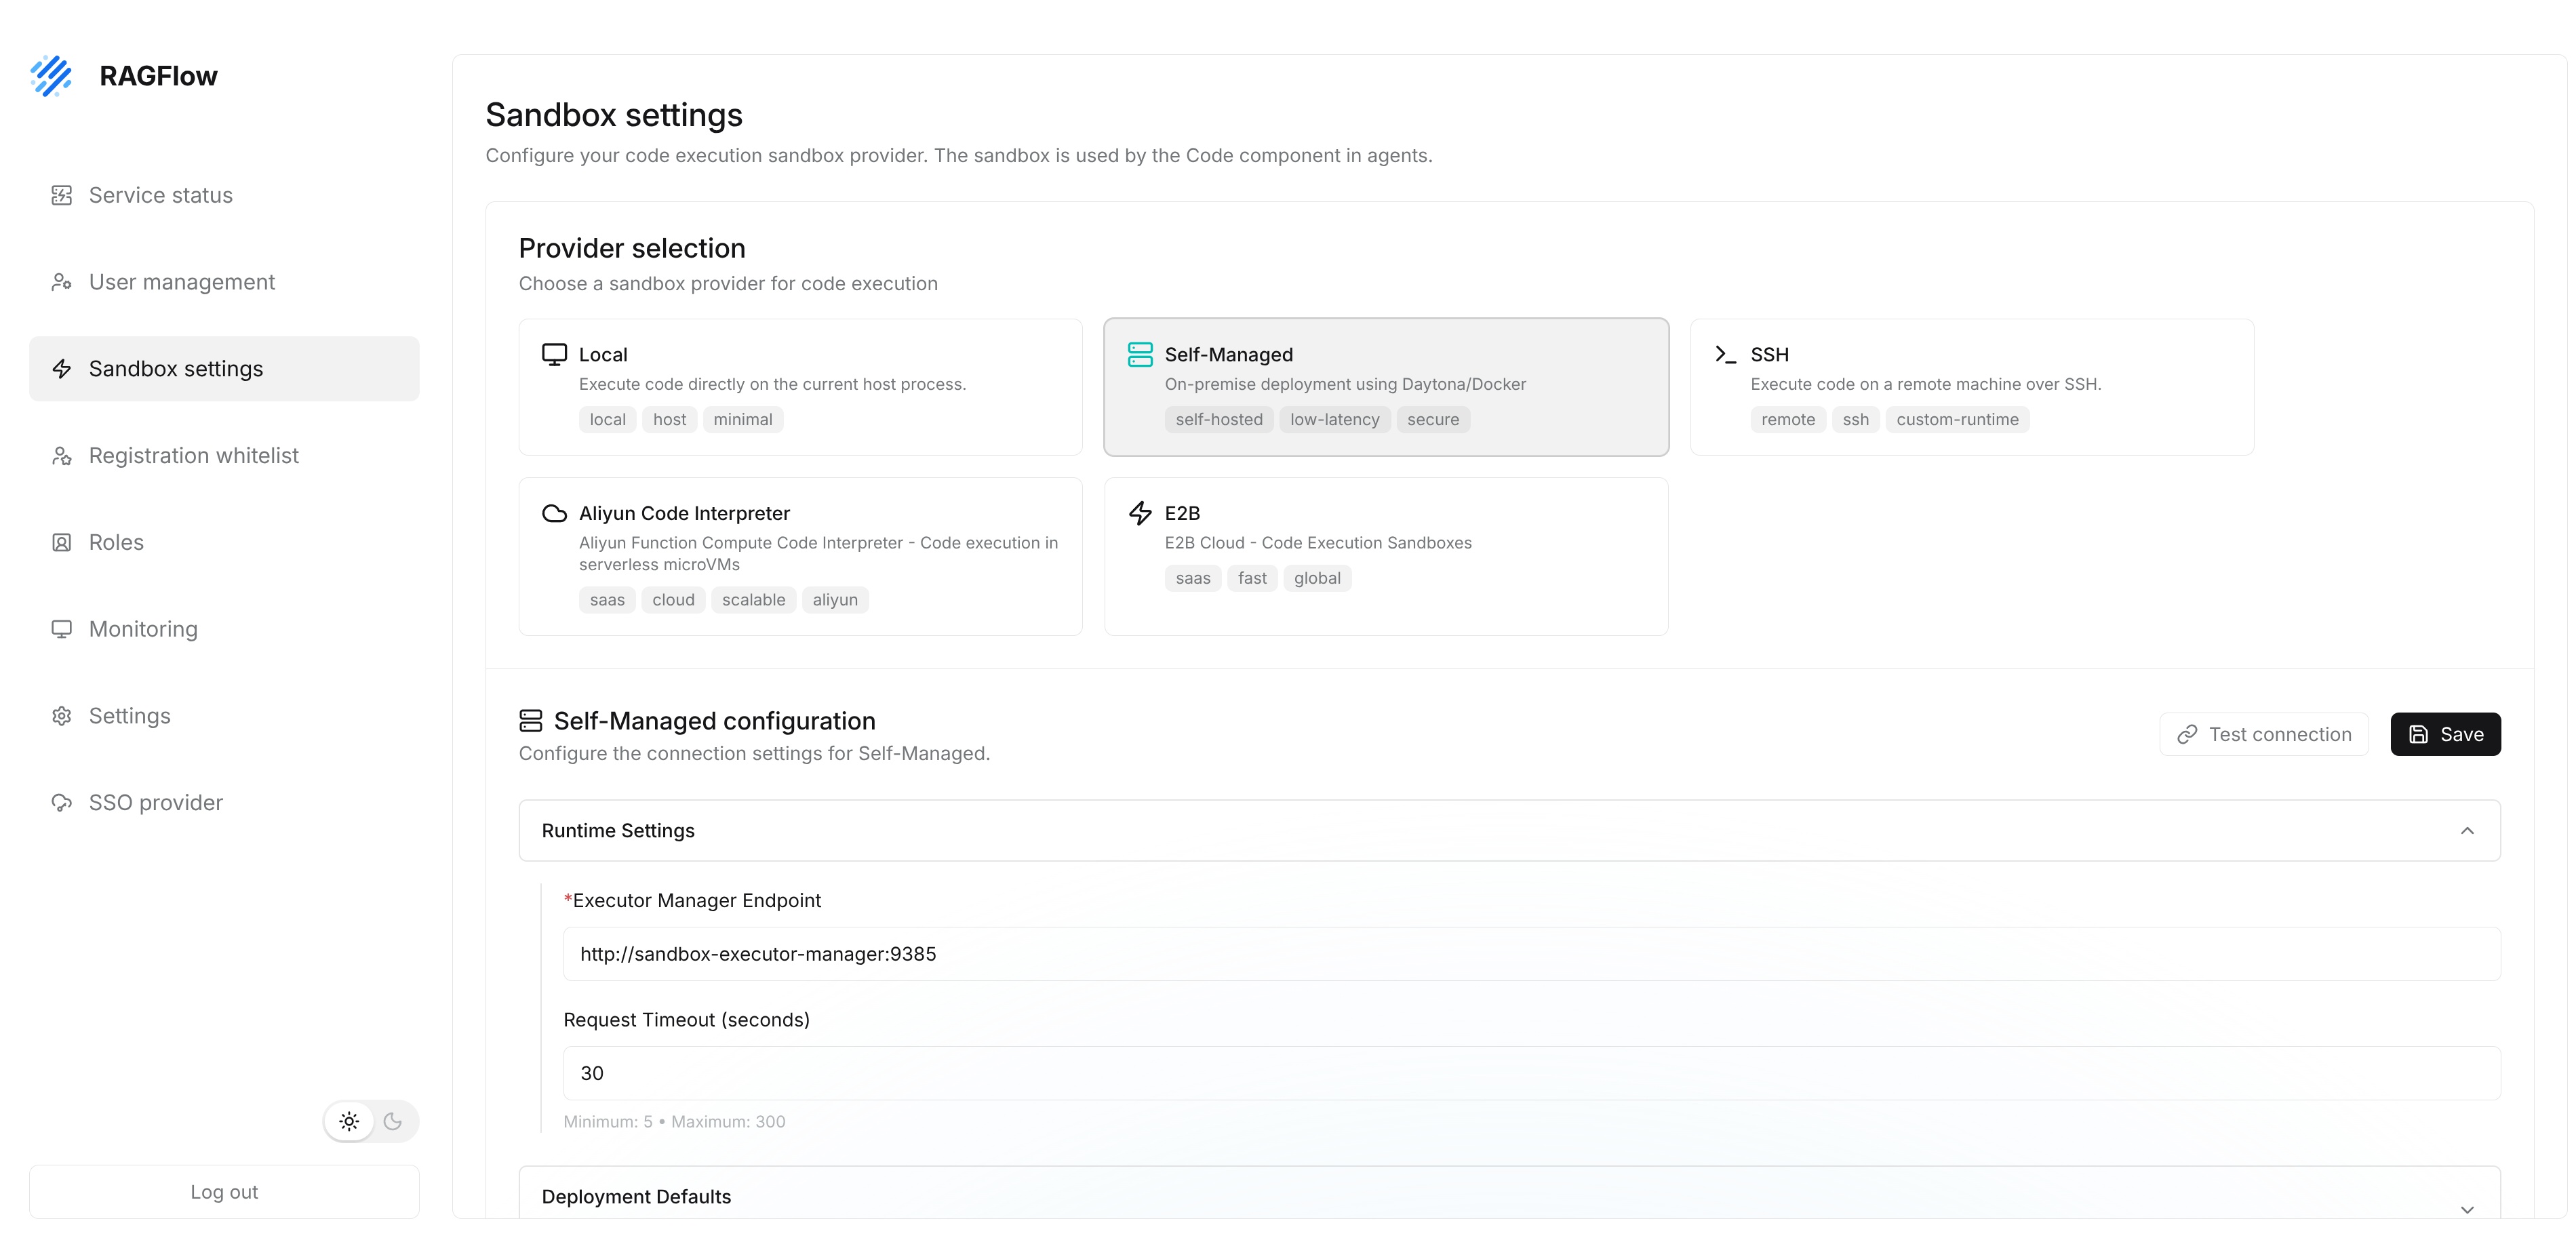+**Caution:** Sandbox configuration affects not only connection availability, but also code isolation, network access, file access, and runtime resource limits. In production environments, prefer `Self-Managed`, cloud, or independent remote execution solutions with isolation capabilities. Direct use of `Local` is not recommended.diff --git a/docs/administrator/admin/admin_ui/configure_user_roles_and_permissions_enterprise.md b/docs/administrator/admin/admin_ui/configure_user_roles_and_permissions_enterprise.mddeleted file mode 100644index 6d2c7558ce..0000000000--- a/docs/administrator/admin/admin_ui/configure_user_roles_and_permissions_enterprise.md+++ /dev/null@@ -1,30 +0,0 @@-----sidebar_position: 6-sidebar_label: "Configure User Roles and Permissions (Enterprise Edition)"------# Configure User Roles and Permissions (Enterprise Edition)--## Maintain Roles--Enterprise Edition maintains roles and permissions through the **Roles** page. Administrators can view existing roles on this page and create new roles through **New role**.--The current page displays a permission matrix under each role. Visible resources include `Dataset`, `Chat`, `Agent`, `Search`, `File`, `Team`, `Memory`, and `Model provider`. Visible actions include `Enable`, `Read`, `Write`, and `Share`.--Administrators should configure roles according to user responsibilities and should not grant ordinary users resource permissions beyond what their work requires.--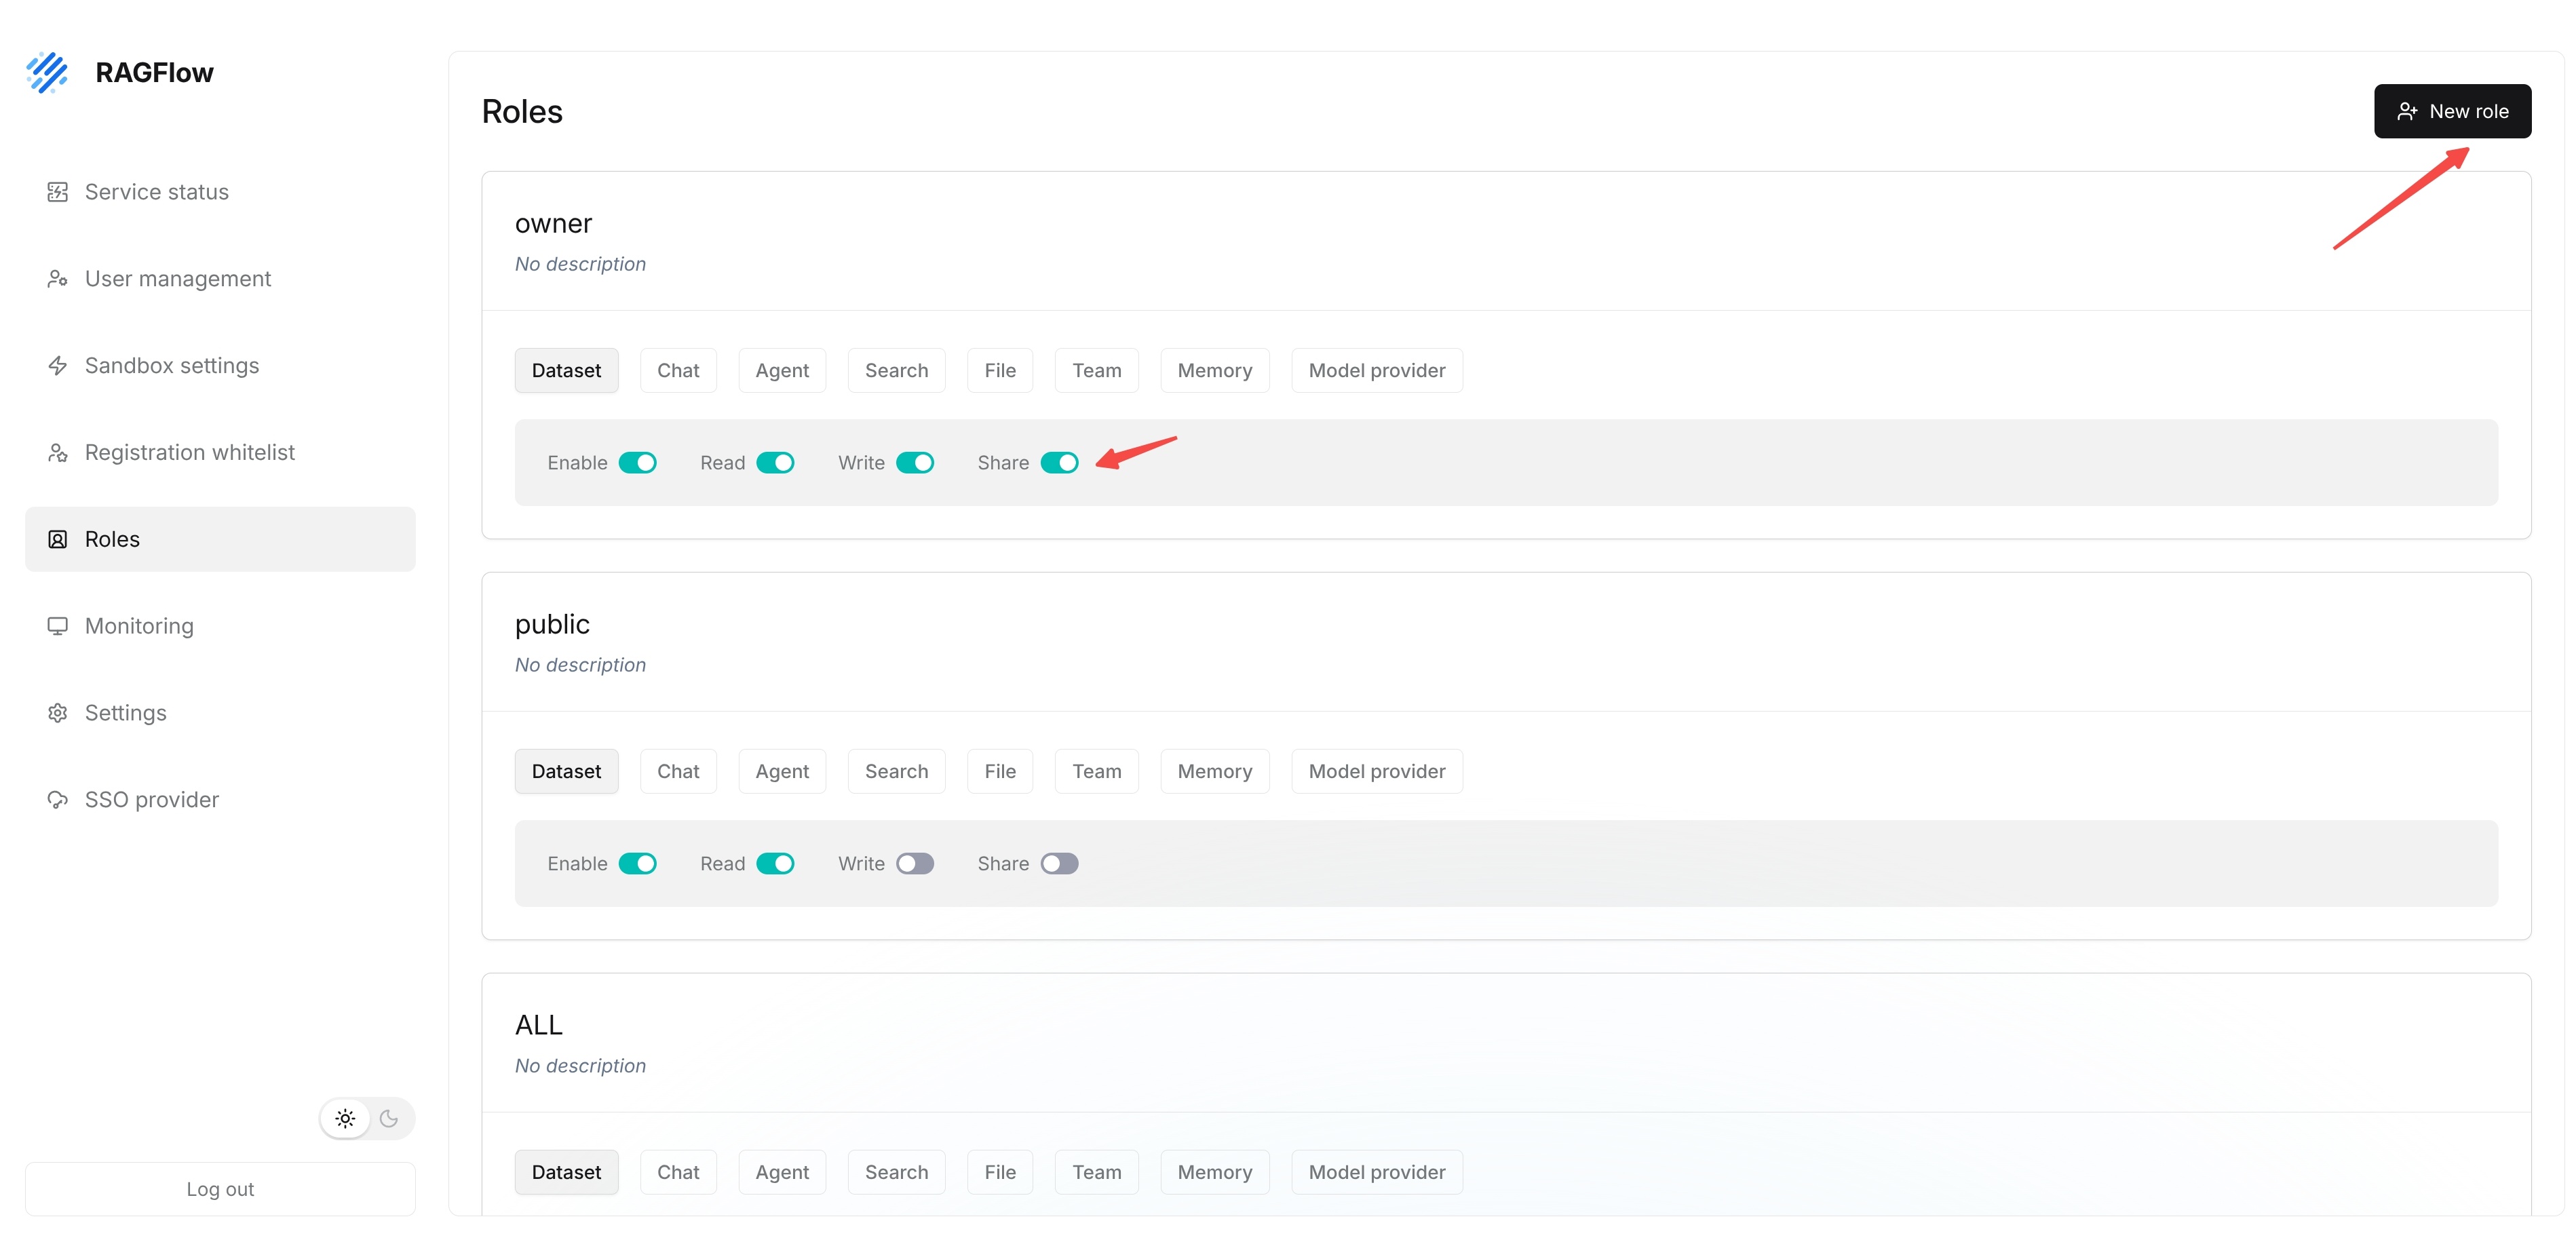--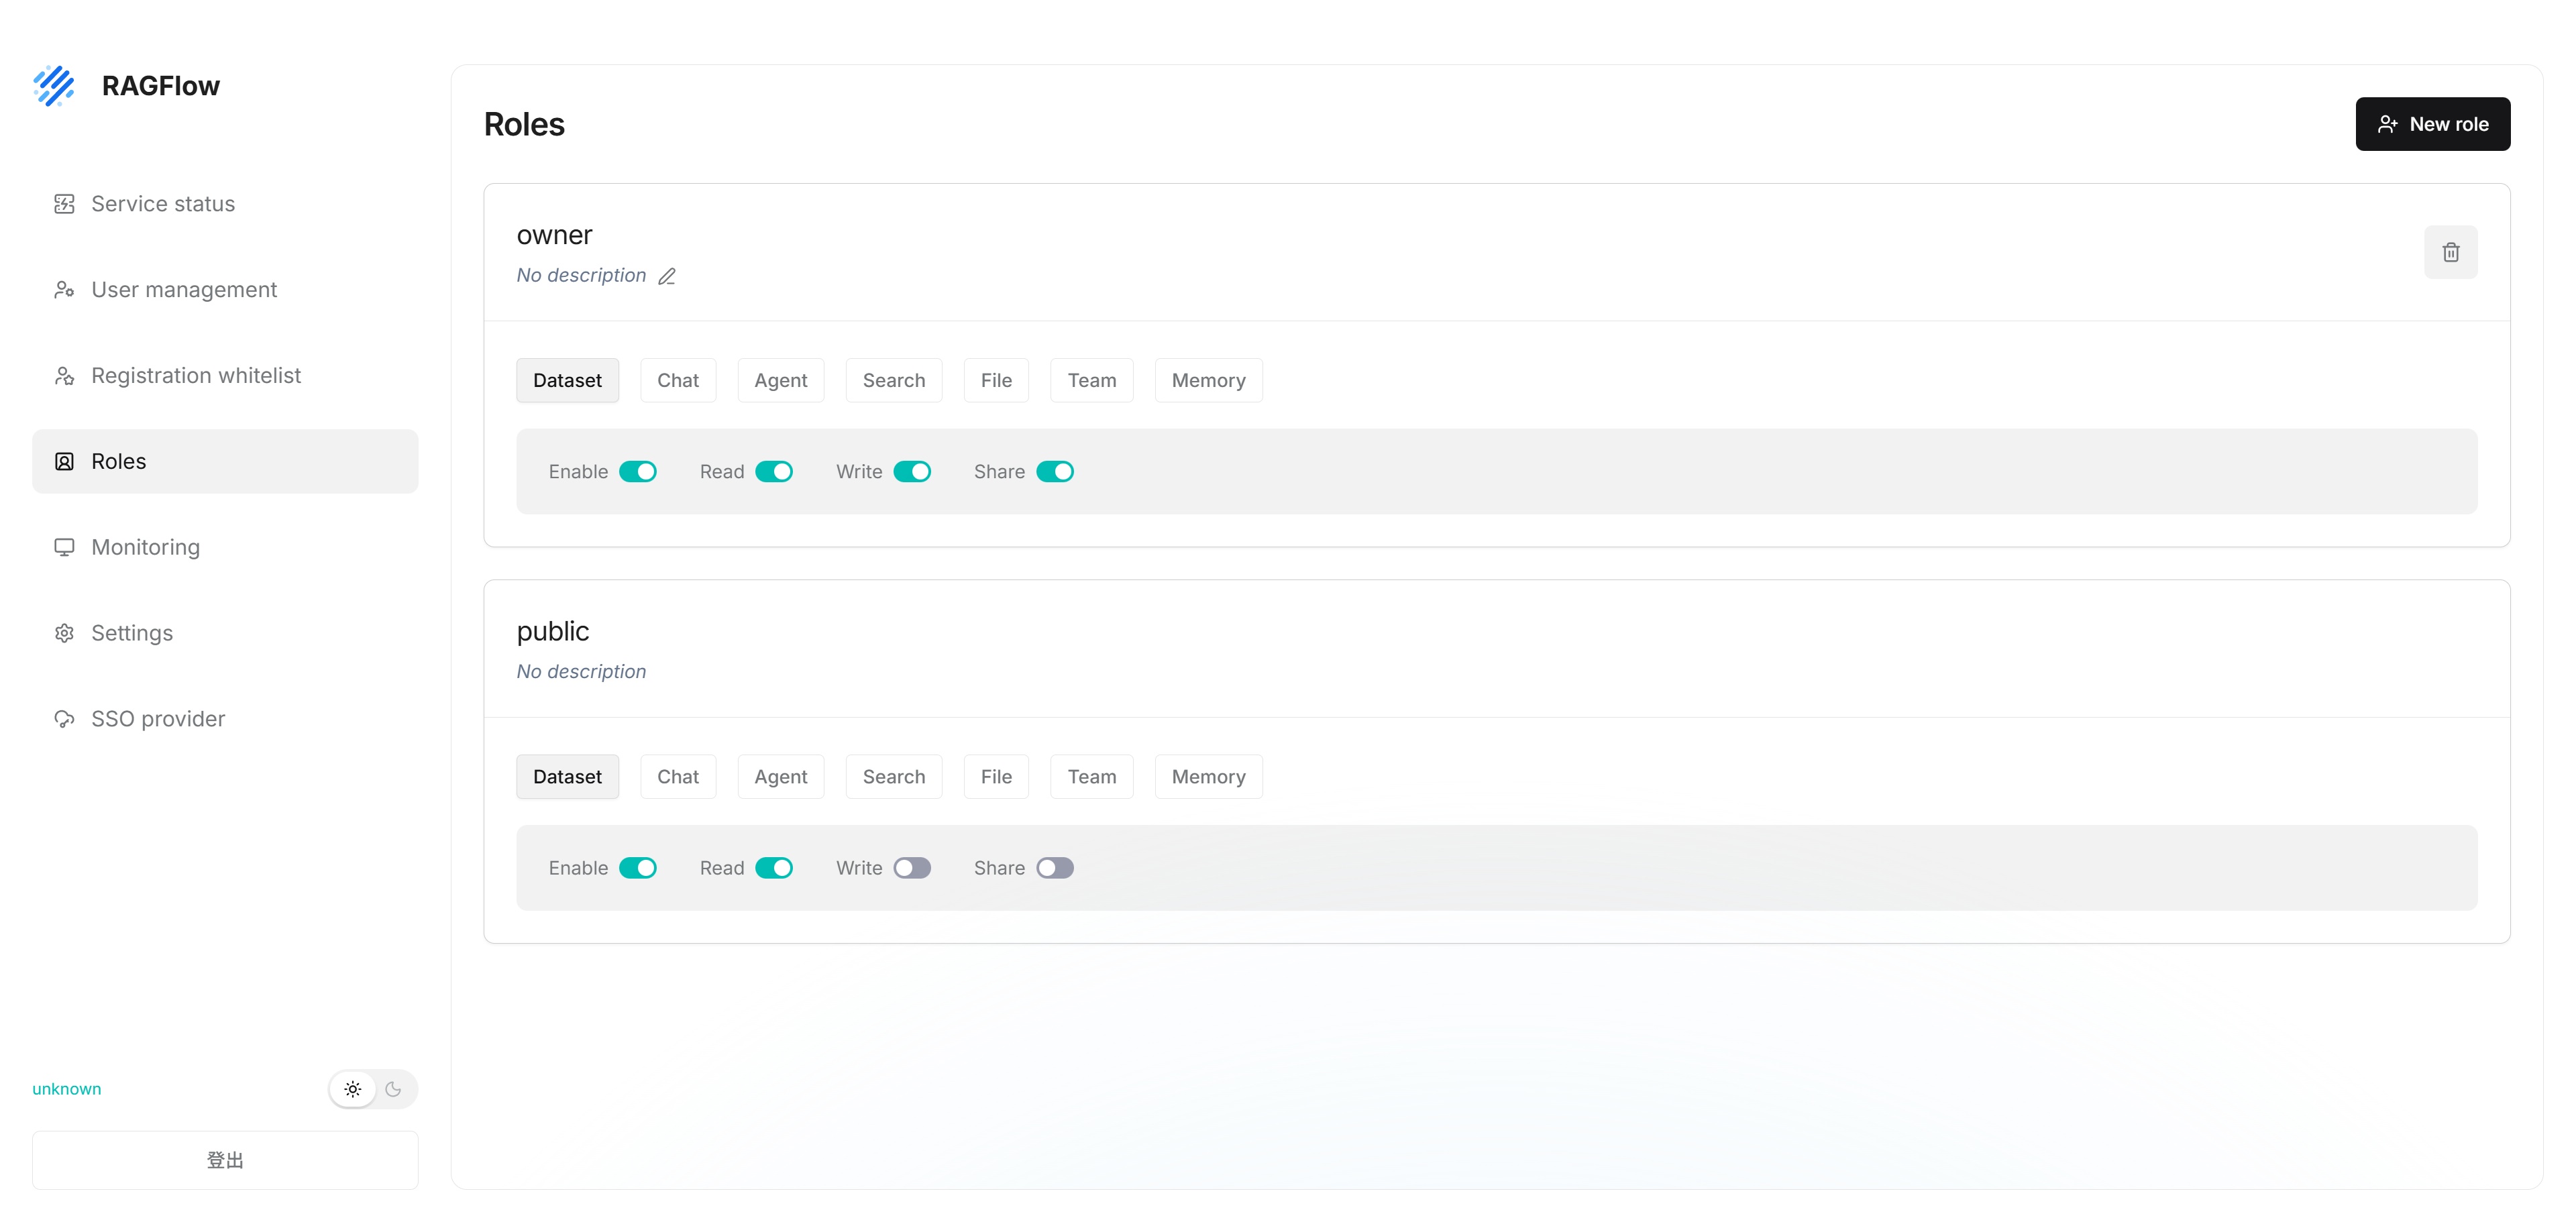--**Note:** Modifying role permissions affects users' access scope for knowledge bases, chat, Agent, search, files, teams, memory, model providers, and other resources.--## Assign Roles to Users--In Enterprise Edition, a user's `Role` can be assigned on the **User management** page. Administrators can click the target user's current `Role` and select a new role from the role list.--1. Go to the **User management** page.-2. Find the target user and open the role dropdown in the `Role` column.-3. Select the new role.--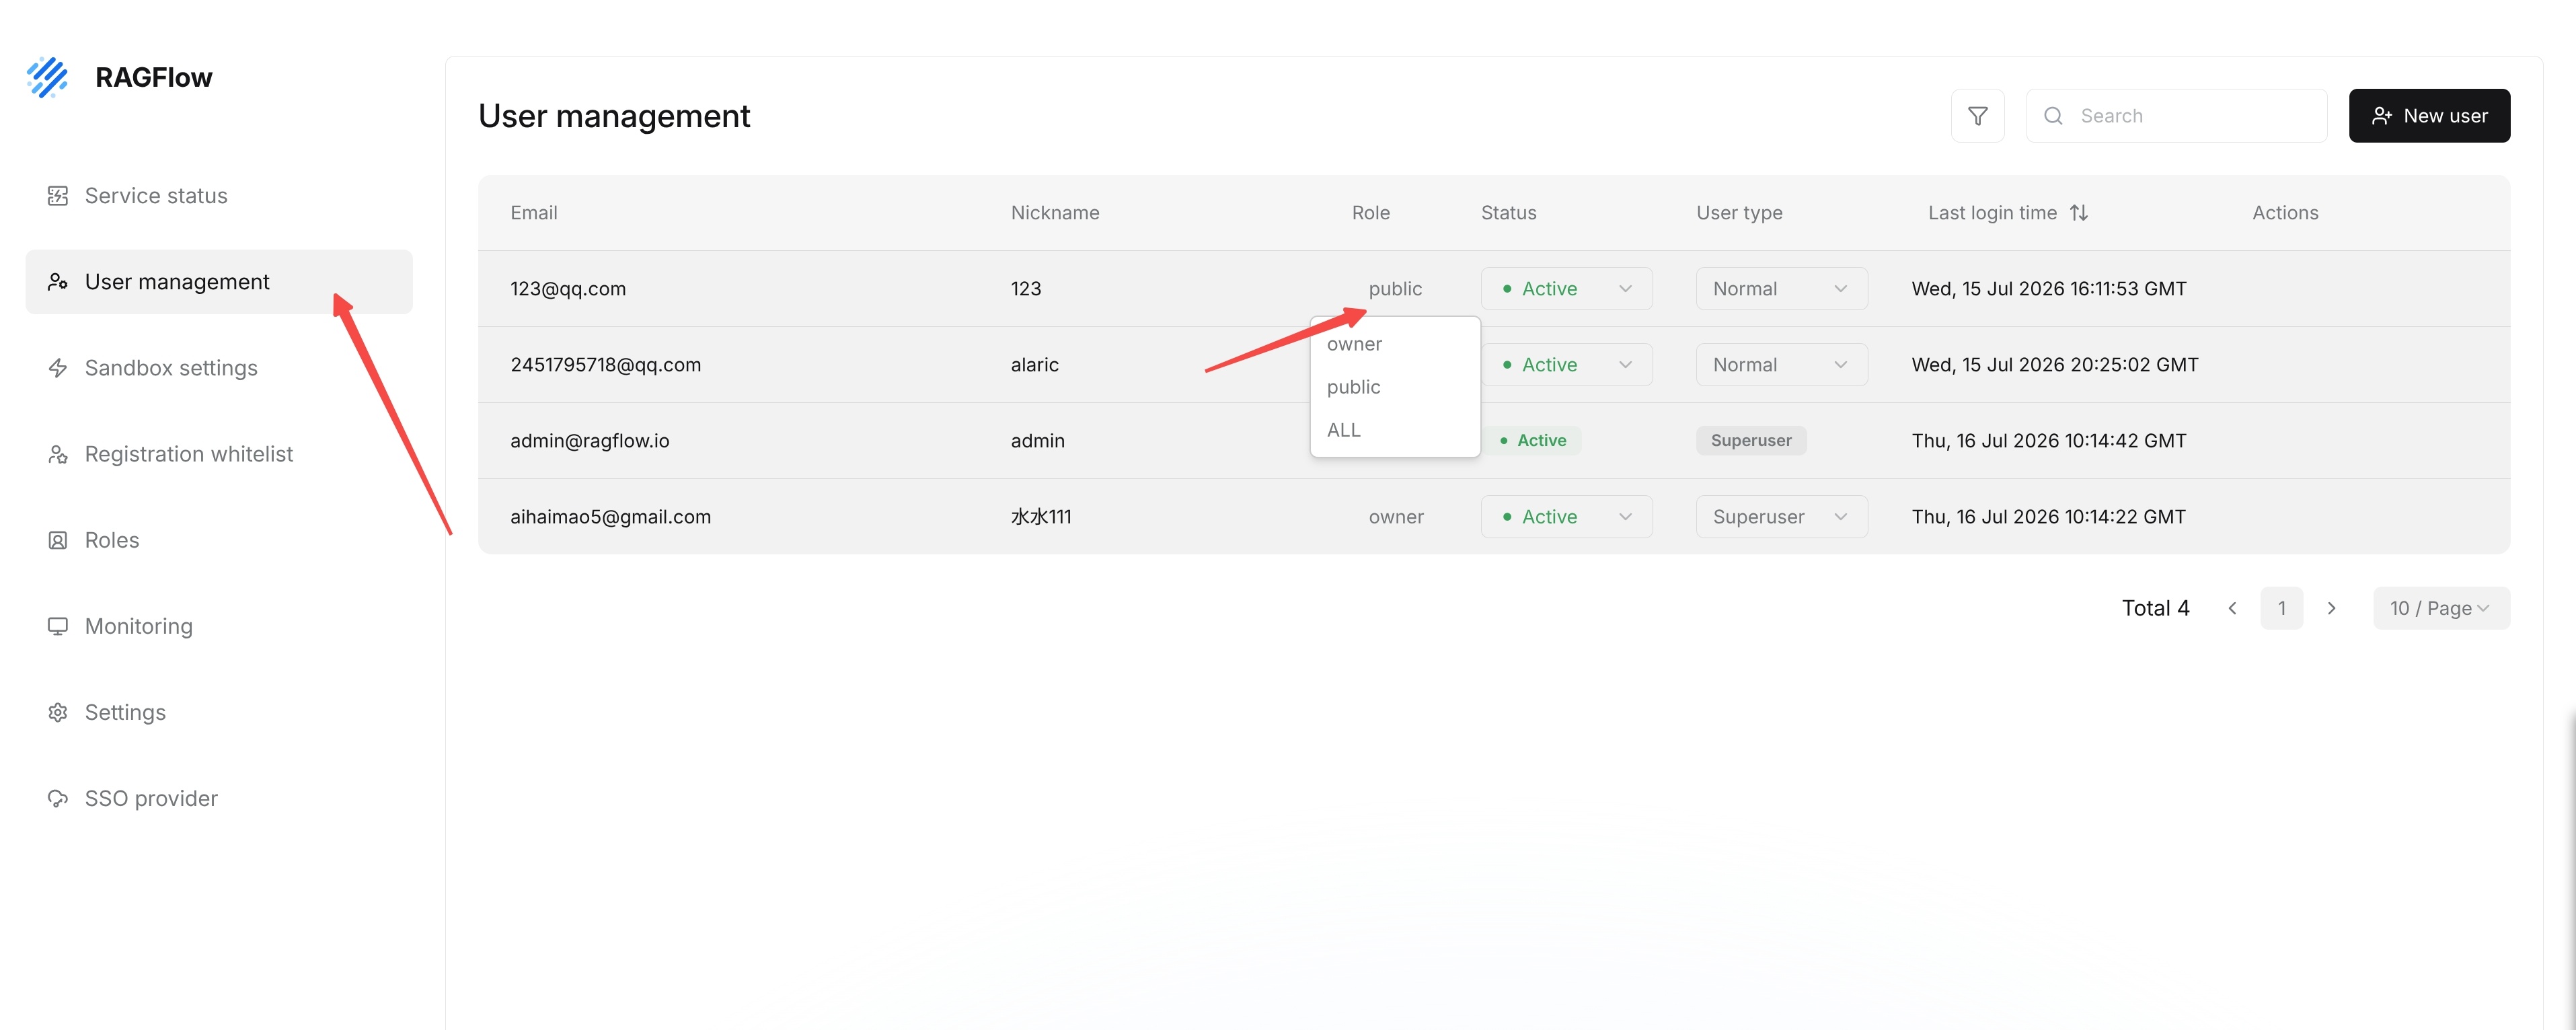diff --git a/docs/administrator/admin/admin_ui/control_registration_and_system_settings_enterprise.md b/docs/administrator/admin/admin_ui/control_registration_and_system_settings_enterprise.mddeleted file mode 100644index bef3a915e2..0000000000--- a/docs/administrator/admin/admin_ui/control_registration_and_system_settings_enterprise.md+++ /dev/null@@ -1,35 +0,0 @@-----sidebar_position: 5-sidebar_label: "Control Registration and System Settings (Enterprise Edition)"------# Control Registration and System Settings (Enterprise Edition)--## Enable the Registration Whitelist--Enterprise Edition can restrict which users are allowed to register through the registration whitelist. To use the registration whitelist, first go to **Settings** and enable **Enable module** in the **Registration whitelist** module. After enabling it, return to **Registration whitelist** to maintain allowed email addresses or rules.--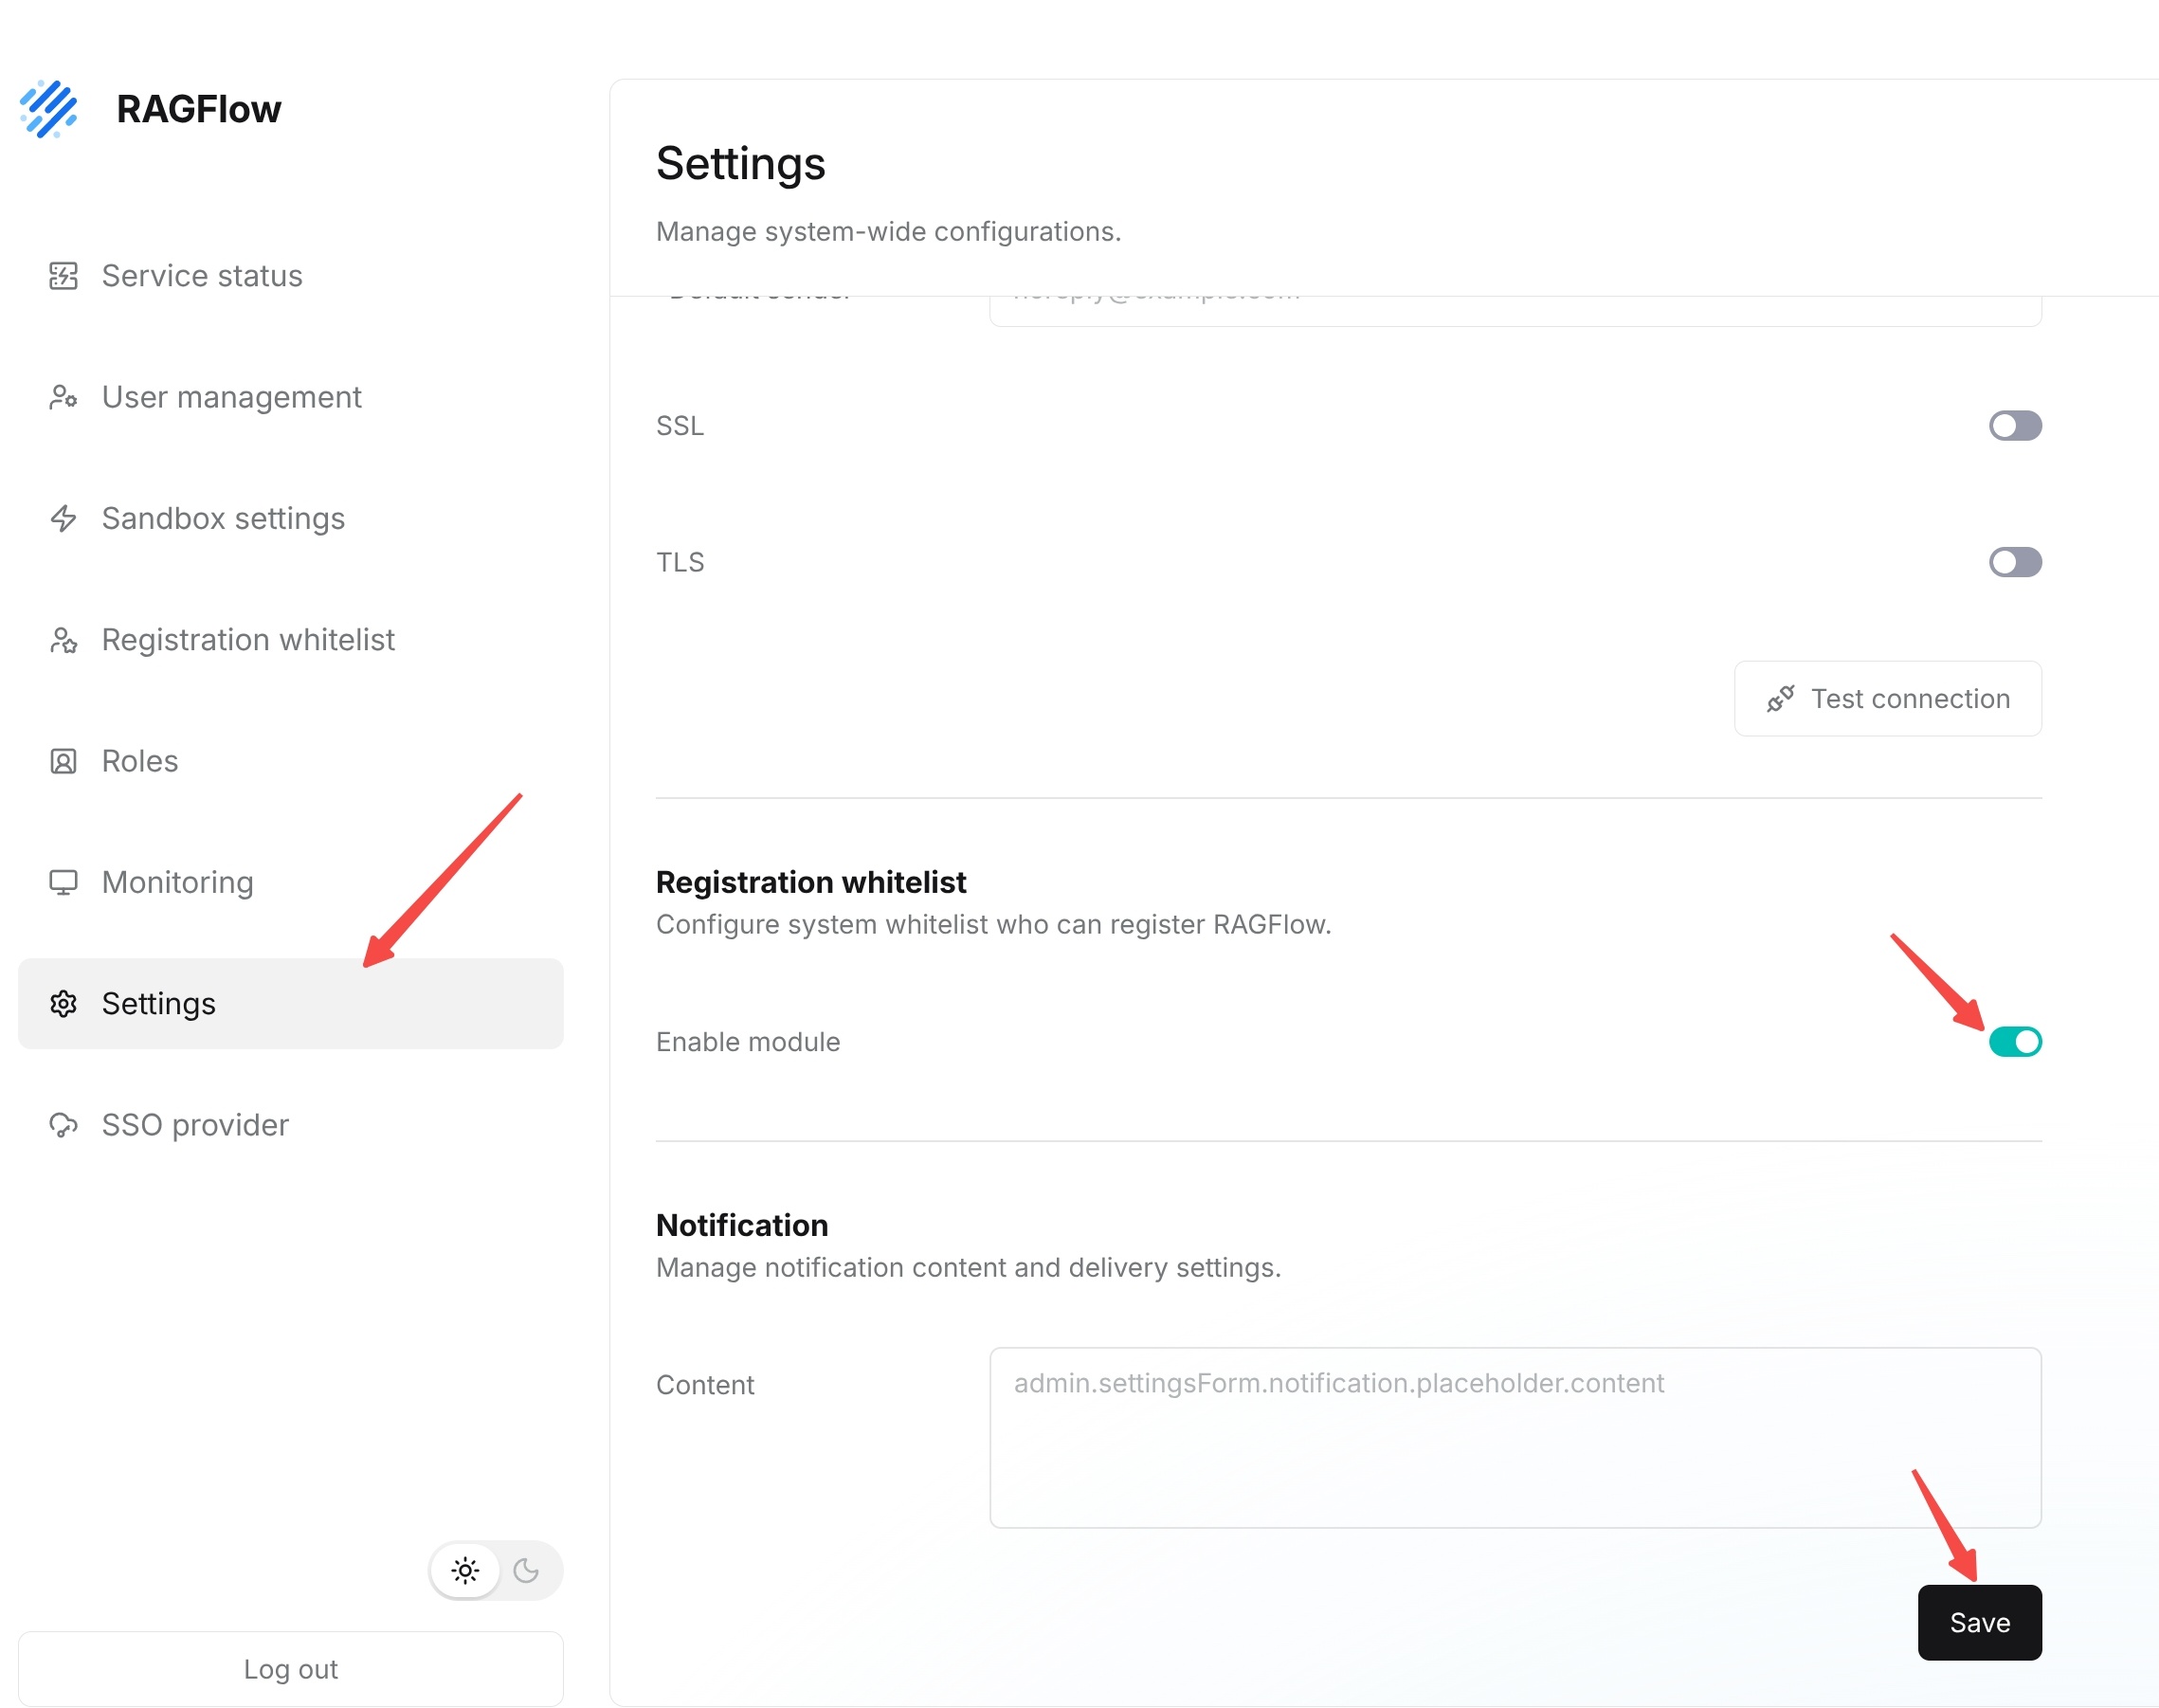--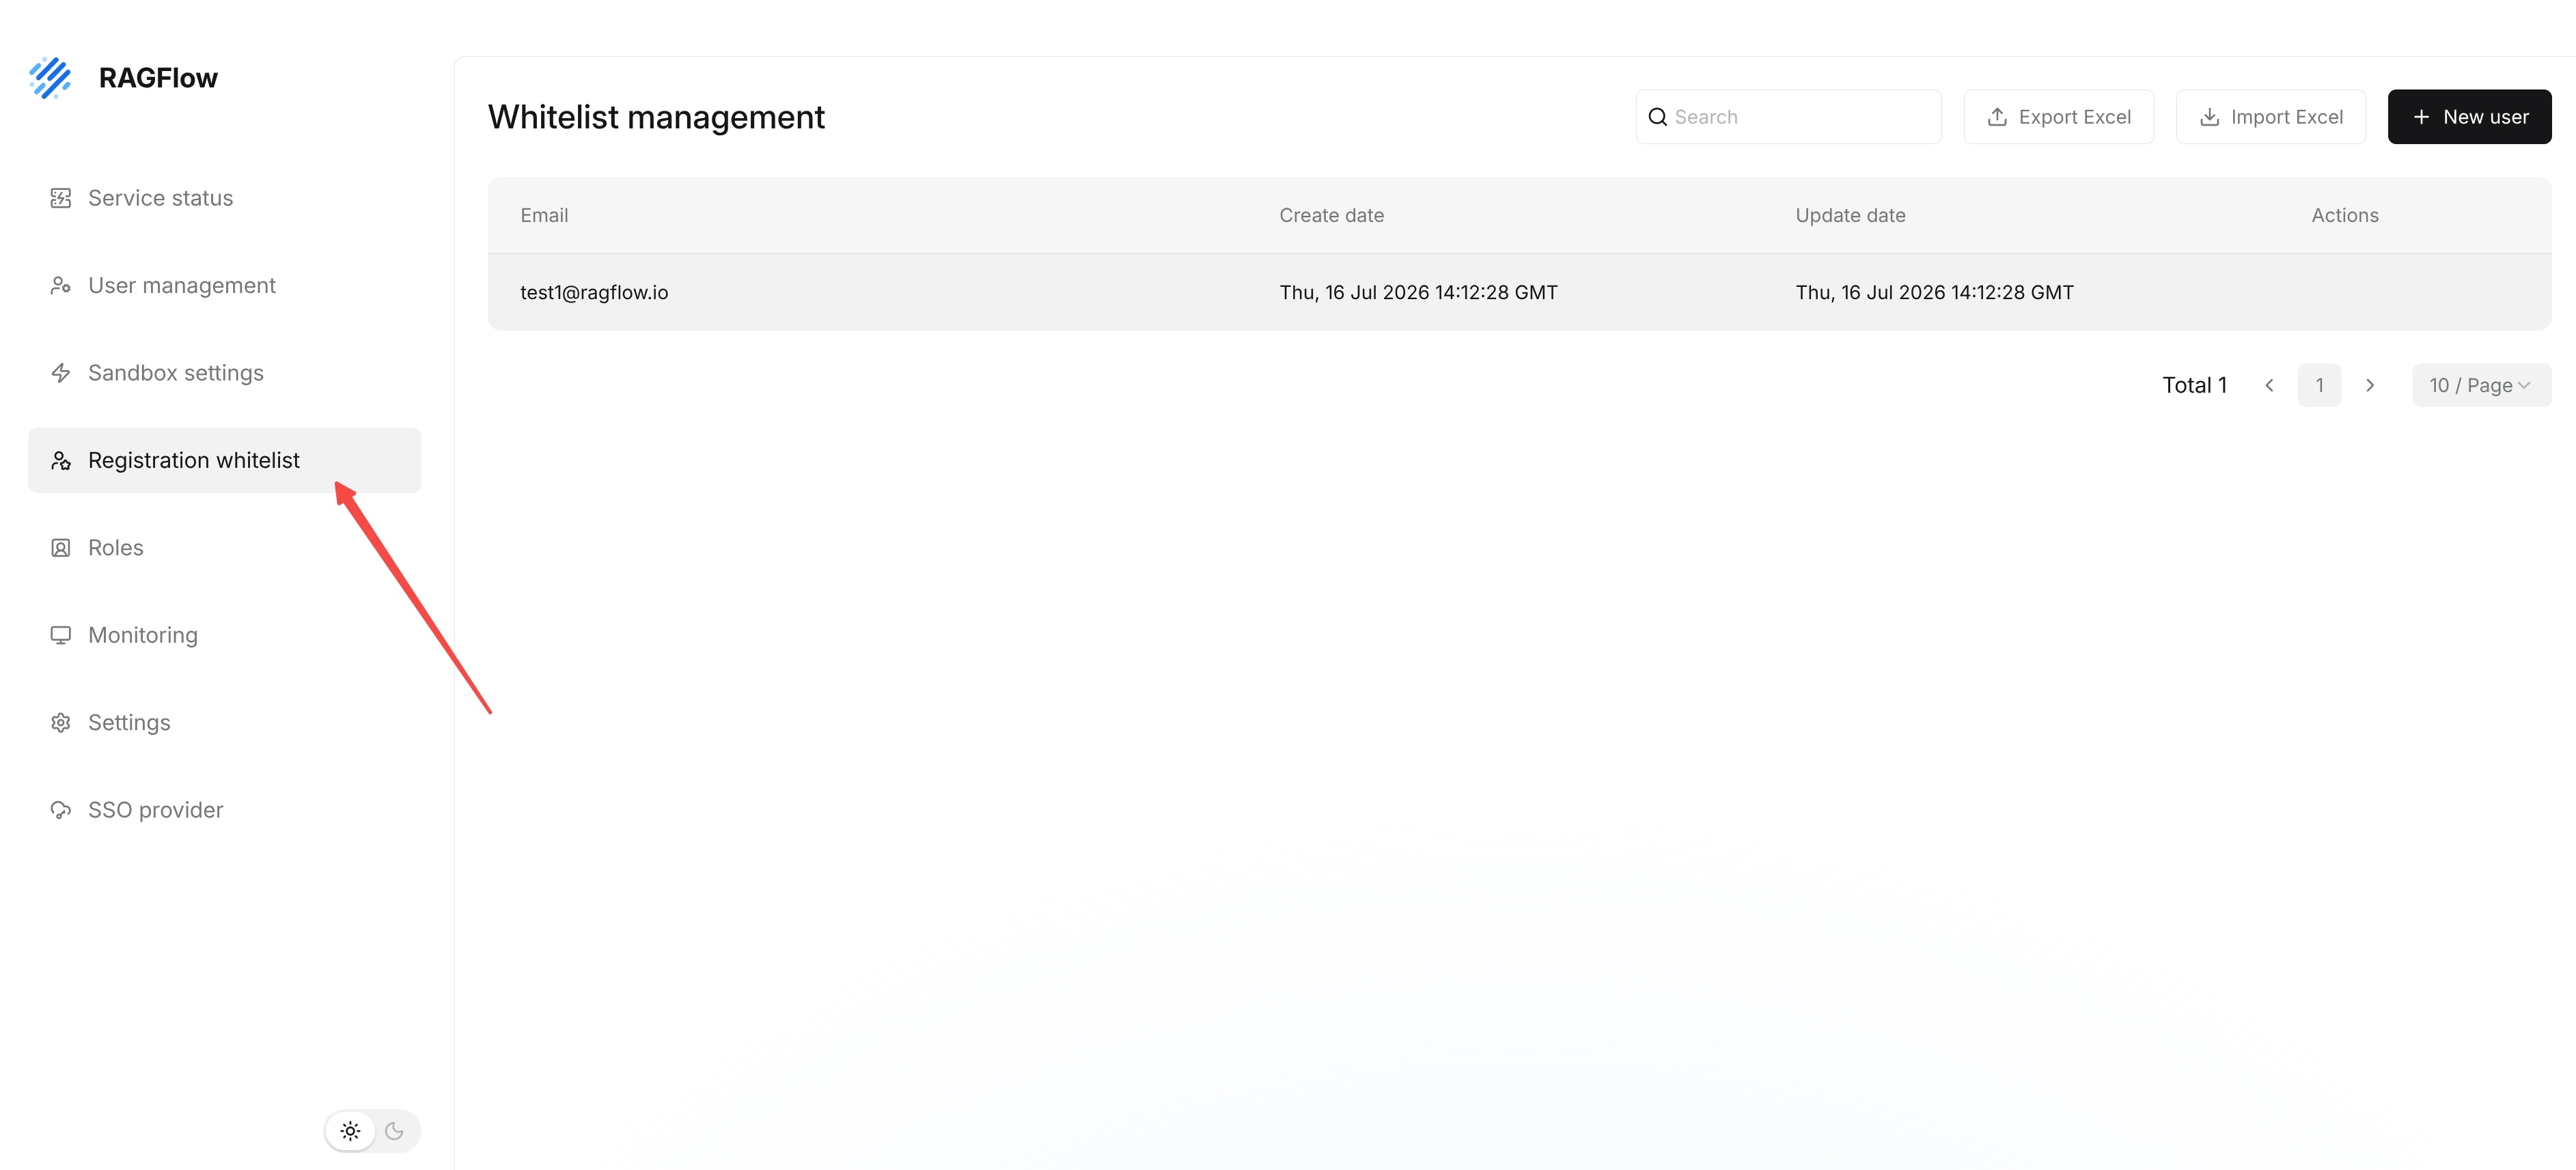--## Manage the Registration Whitelist--Enterprise Edition uses **Registration whitelist** to control which email addresses can register for RAGFlow. When the system needs to restrict the registration scope, administrators can maintain allowed email addresses in **Registration whitelist**. After the whitelist is enabled, email addresses that are not in the whitelist cannot complete registration directly.--After entering the **Registration whitelist** page, the page displays **Whitelist management**. Administrators can view email addresses that have already been added to the whitelist, along with each record's creation time and update time. The list fields include `Email`, `Create date`, `Update date`, and `Actions`.--The top of the page provides common maintenance operations:--| Operation | Description |-| --- | --- |-| `Search` | Search whitelist records by email address. |-| `New user` | Add a single email address. |-| `Import Excel` | Import whitelist records in batches. |-| `Export Excel` | Export the current whitelist data. |--The lower-right corner of the page displays the current total number of records, pagination, and page size. To add a single email address, click **New user**, fill in the email address as prompted, and save it. For batch maintenance, prepare an Excel file first and then import it through **Import Excel**. After importing, use search to spot-check whether key email addresses appear in the list.--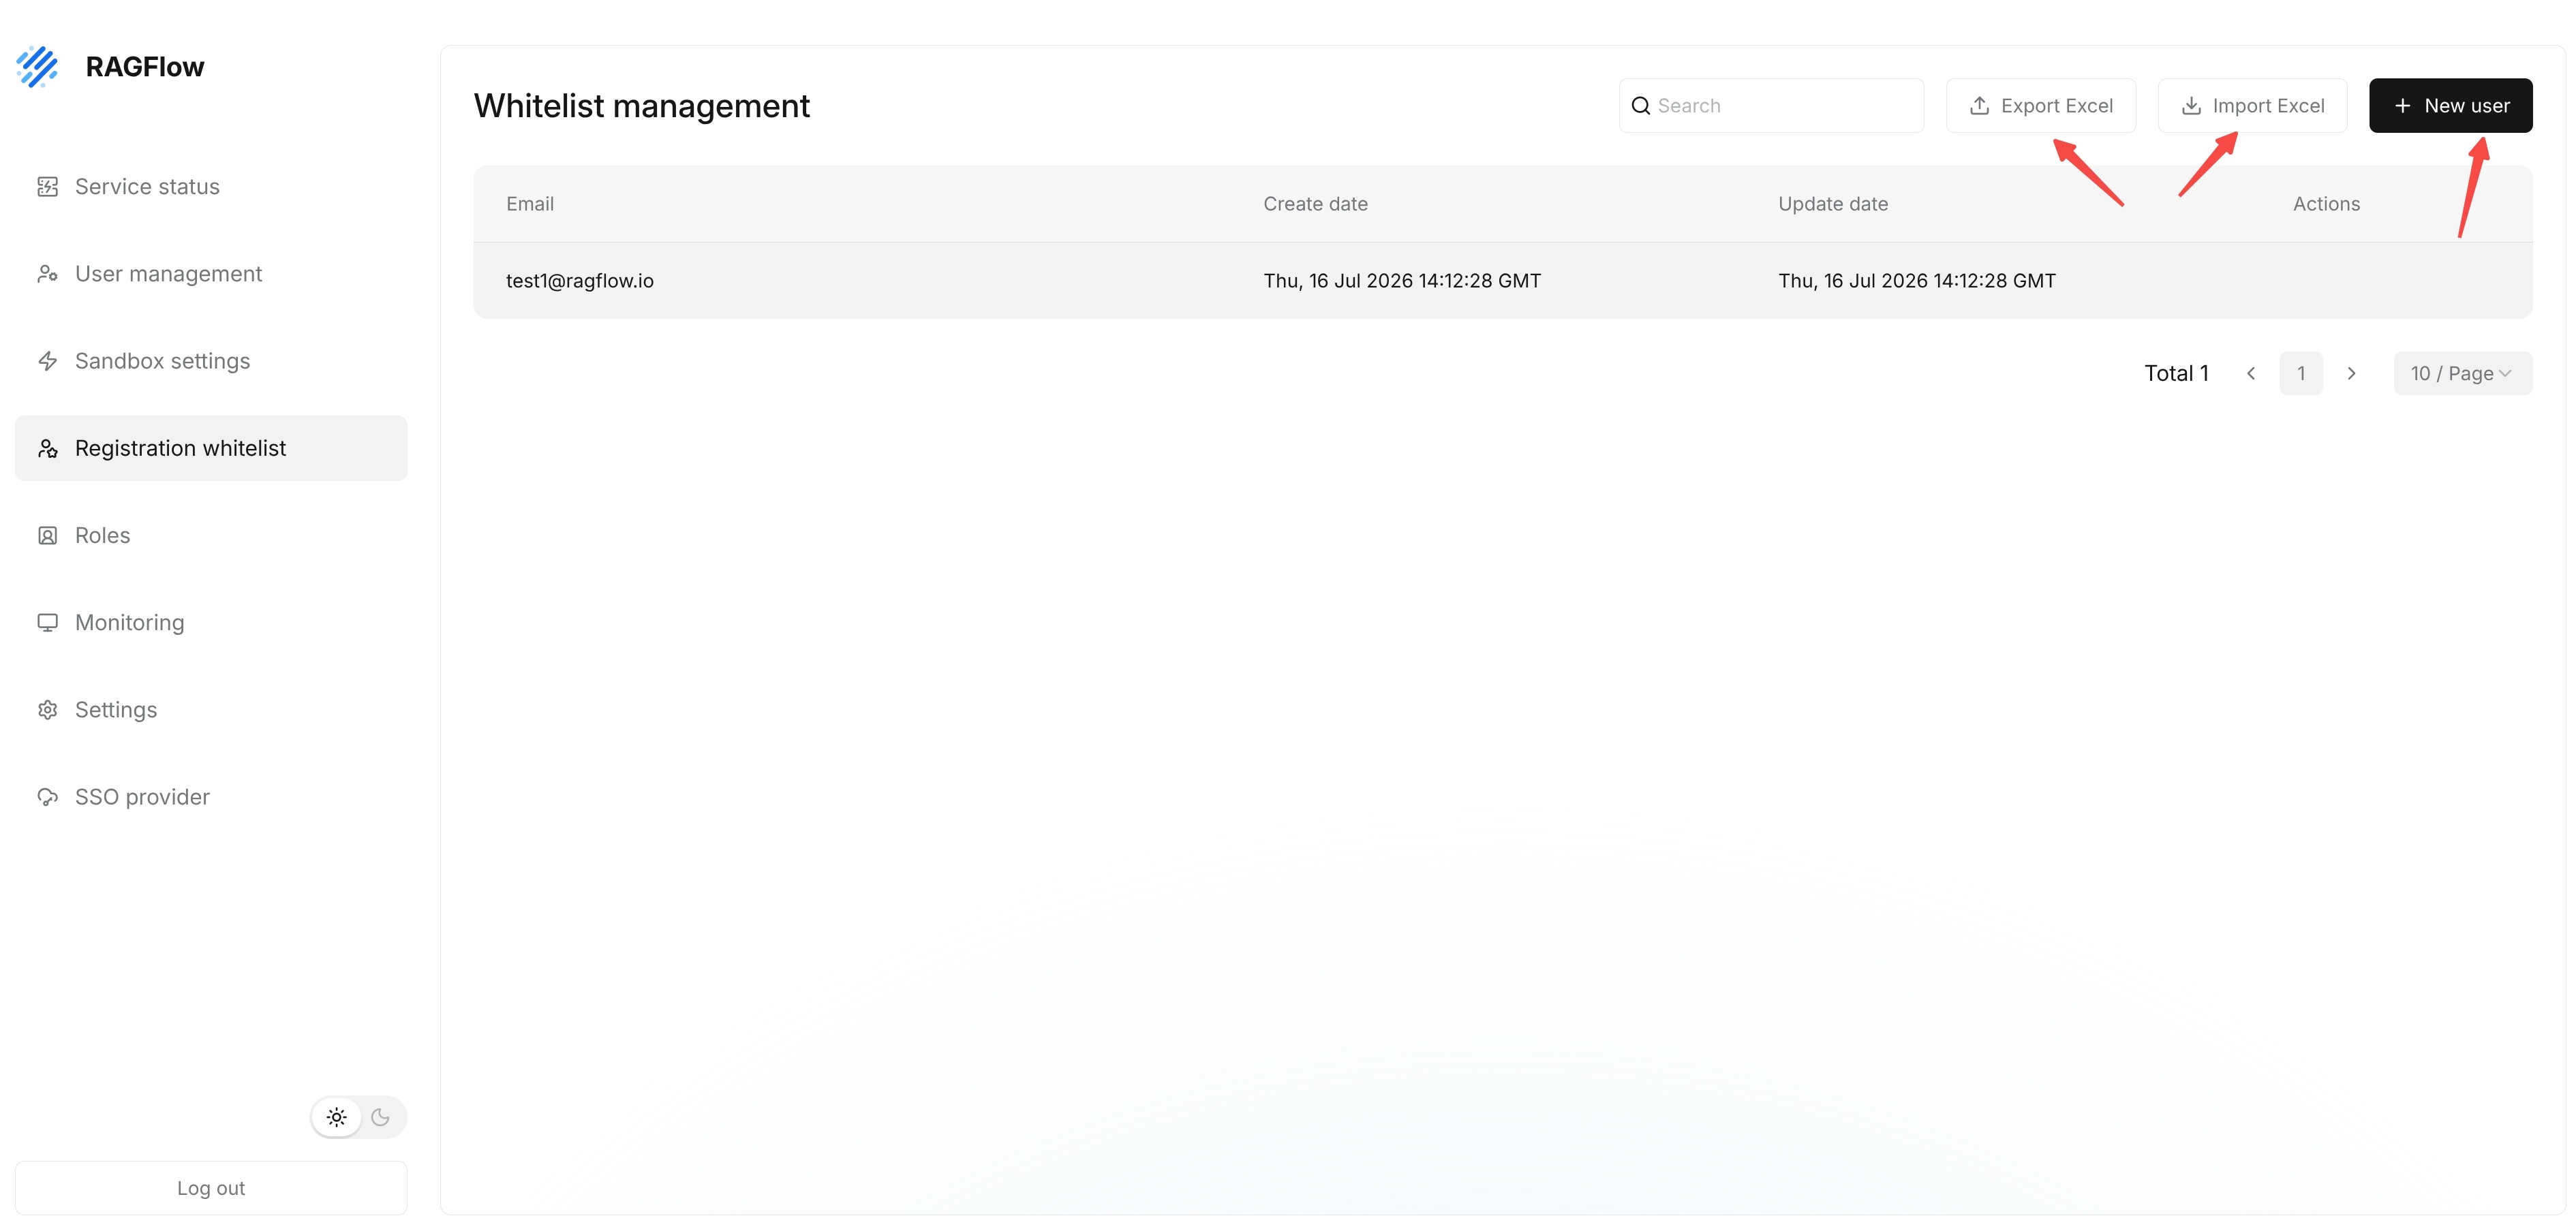--diff --git a/docs/administrator/admin/admin_ui/manage_system_settings_enterprise.md b/docs/administrator/admin/admin_ui/manage_system_settings_enterprise.mddeleted file mode 100644index 9e9c2fa316..0000000000--- a/docs/administrator/admin/admin_ui/manage_system_settings_enterprise.md+++ /dev/null@@ -1,84 +0,0 @@-----sidebar_position: 7-sidebar_label: "Manage System Settings (Enterprise Edition)"------# Manage System Settings (Enterprise Edition)--## Manage Licenses--Enterprise Edition system settings include the **License** module, which is used to manage licenses and confirm that the system remains available. The current page displays the license `ID`, `Start time`, `Expiry time`, and `Status`, and provides **Add license**.--Administrators should regularly check license status and expiration time to avoid license expiration affecting Enterprise Edition capabilities. After adding or updating a license, confirm that `Status` is normal.--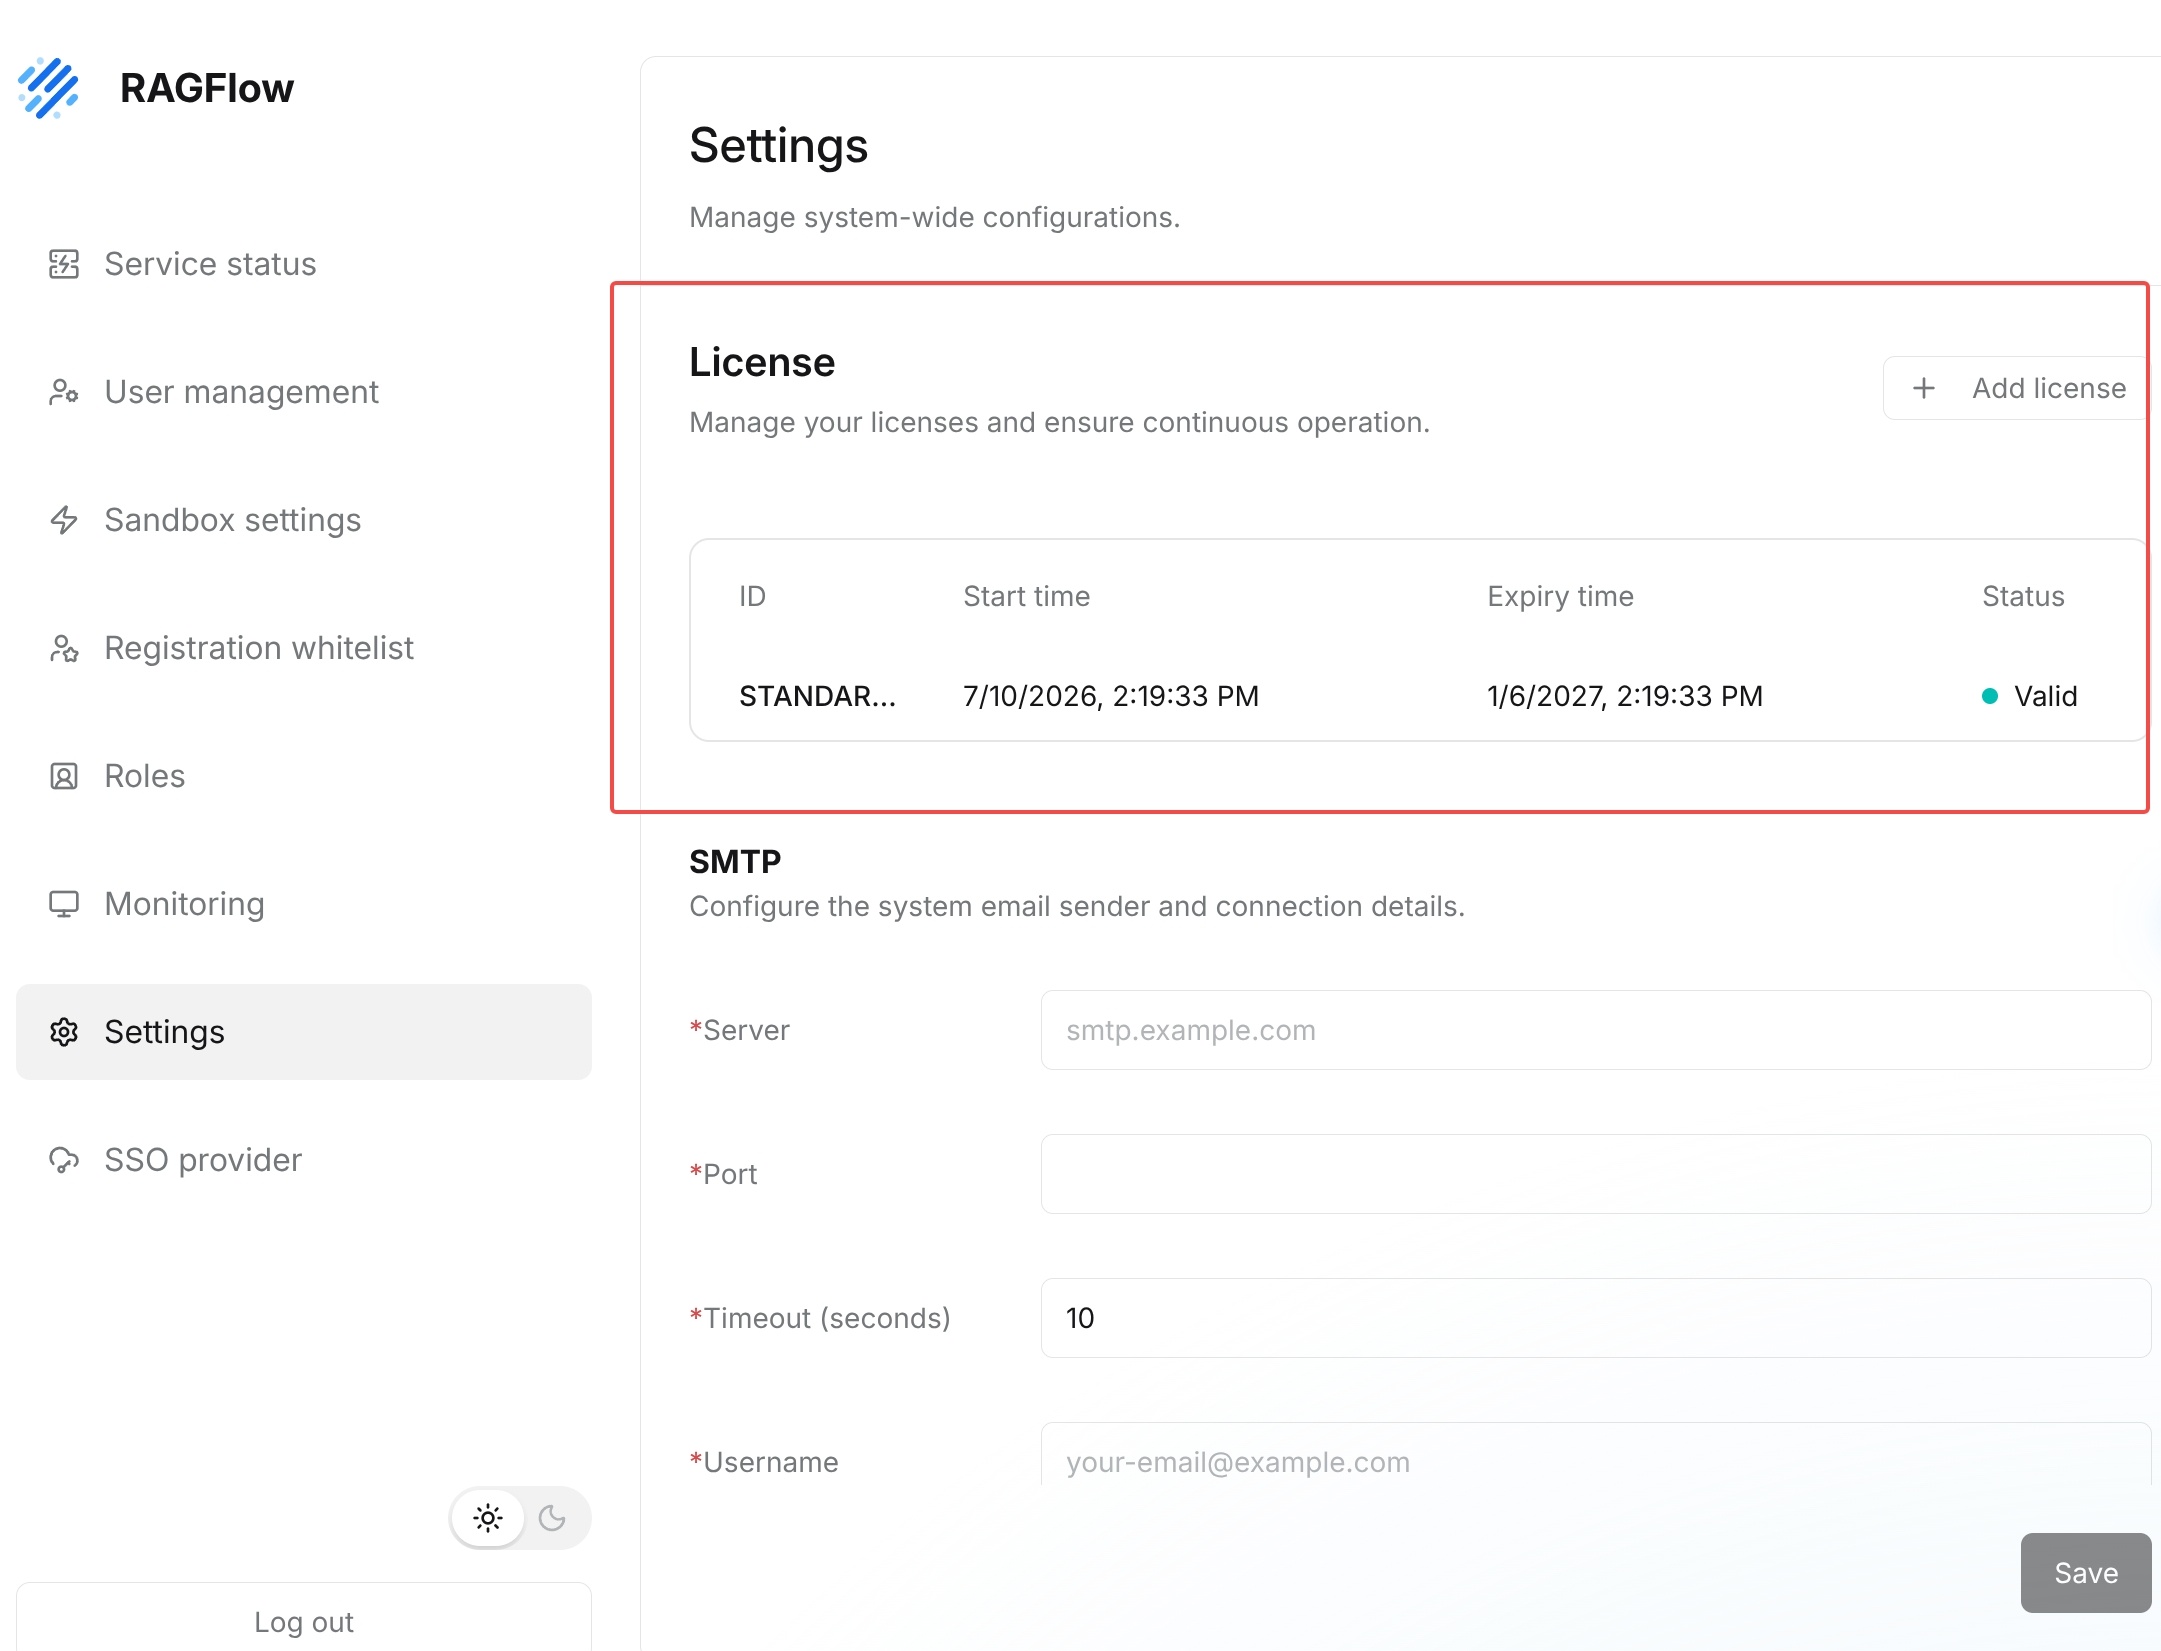--## Configure System Email--`SMTP` (Simple Mail Transfer Protocol) configures the system email sending service. After successful configuration, the system can send verification codes, password reset emails, notification emails, and other email messages.--| Configuration item | Required | Description | Example or recommendation |-| --- | --- | --- | --- |-| `Server` | Yes | SMTP mail server address. | `smtp.example.com` |-| `Port` | Yes | SMTP service port. Keep it consistent with the SSL/TLS configuration. | SSL: `465`; TLS: `587`; no encryption: `25` (generally not recommended). |-| `Timeout (seconds)` | Yes | SMTP connection timeout, in seconds. | Keep the default value `10`. |-| `Username` | Yes | Email account used for sending mail. | `[email protected]` |-| `Password` | Yes | Email login password or SMTP authorization code. Some email providers require an authorization code instead of the login password. | Fill in according to your email provider's requirements. |-| `Default sender` | Yes | Sender email address displayed when the system sends email. It is recommended to keep it consistent with `Username`. | `[email protected]` |-| `SSL` | As needed | Whether to enable SSL encrypted connection. | Usually enabled when using port `465`. |-| `TLS` | As needed | Whether to enable TLS (STARTTLS) encrypted connection. | Usually enabled when using port `587`. |-| `Test connection` | Recommended | After configuration, click **Test connection** to verify that the SMTP service can connect normally. | Save the configuration only after the test succeeds. |--Different email providers use different server addresses, ports, and authentication methods. Configure SMTP according to the parameters provided by your email provider. Usually, you only need to enable either SSL or TLS. Fill in the configuration according to the email provider's guidance.--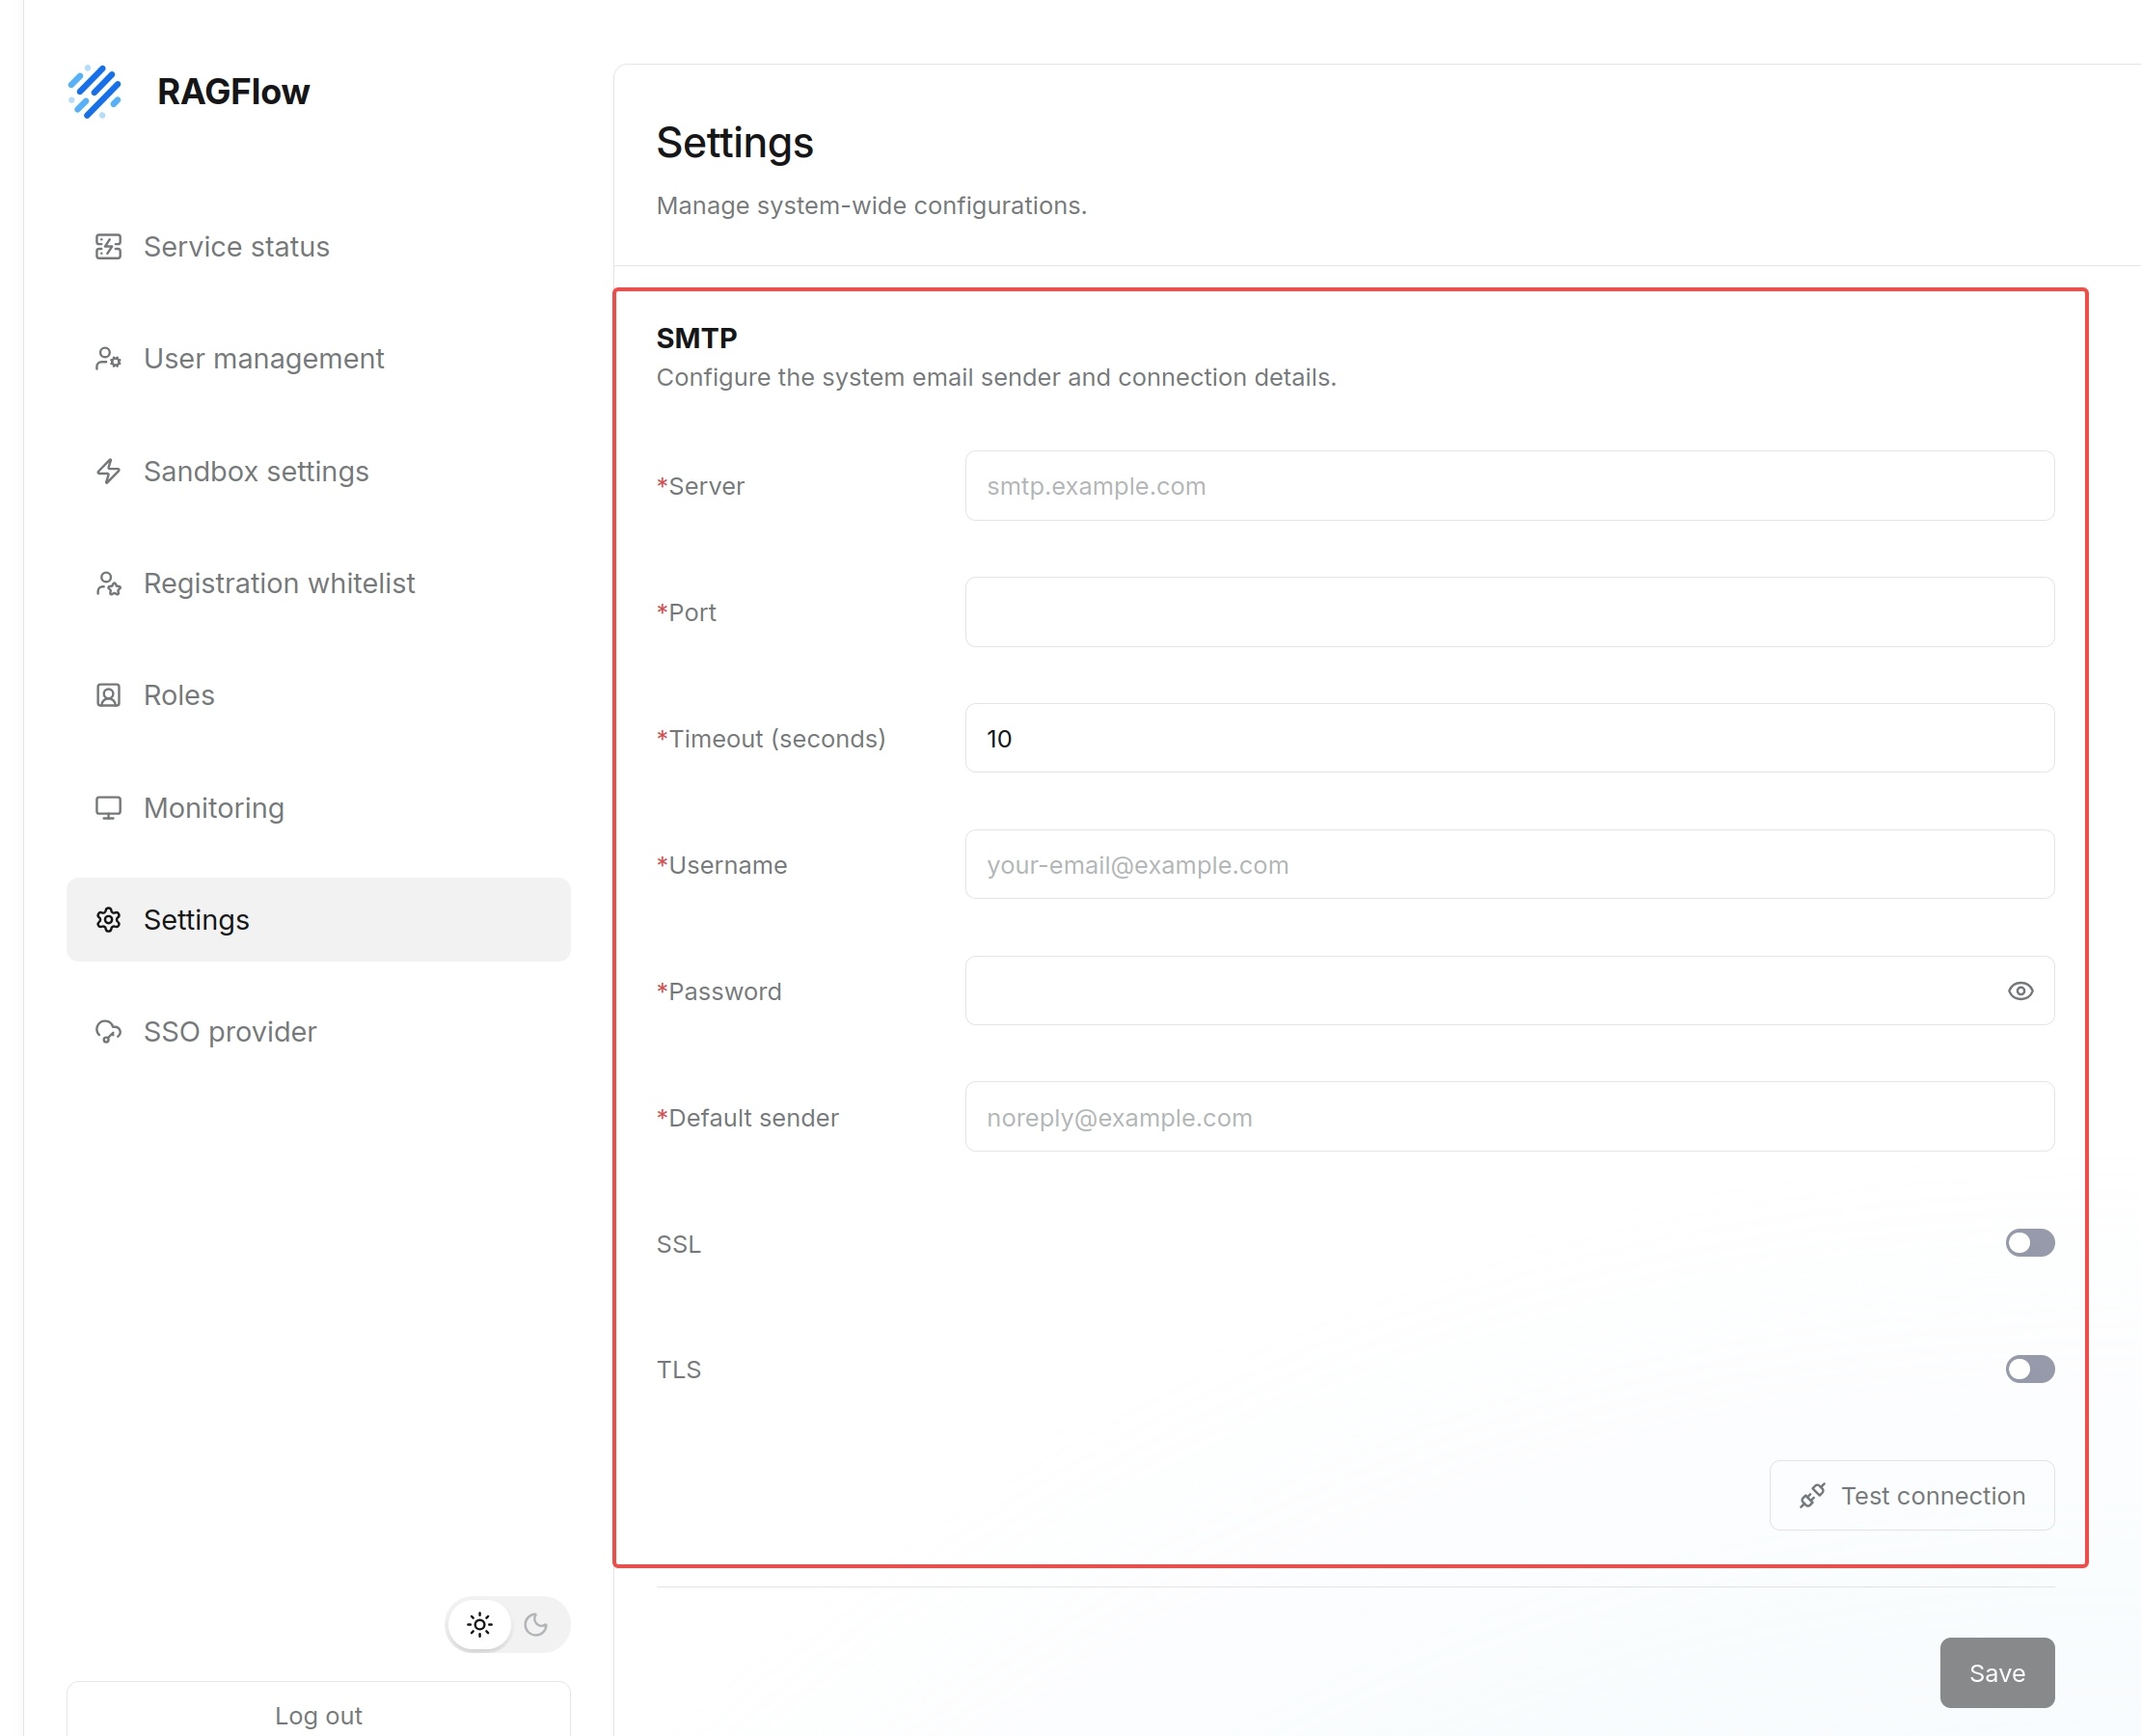--## Configure System Notifications--`Notification` manages system notification content and enablement status. Administrators can enter notification content in `Content` and use `Enable` to control whether the notification takes effect. This feature applies to system announcements, maintenance notices, downtime notices, or other information that needs to be displayed uniformly to users.--1. Go to the **Settings** page.-2. Find the **Notification** area.-3. Enter the content to display in `Content`.-4. Turn on the `Enable` switch.-5. Click **Save**.--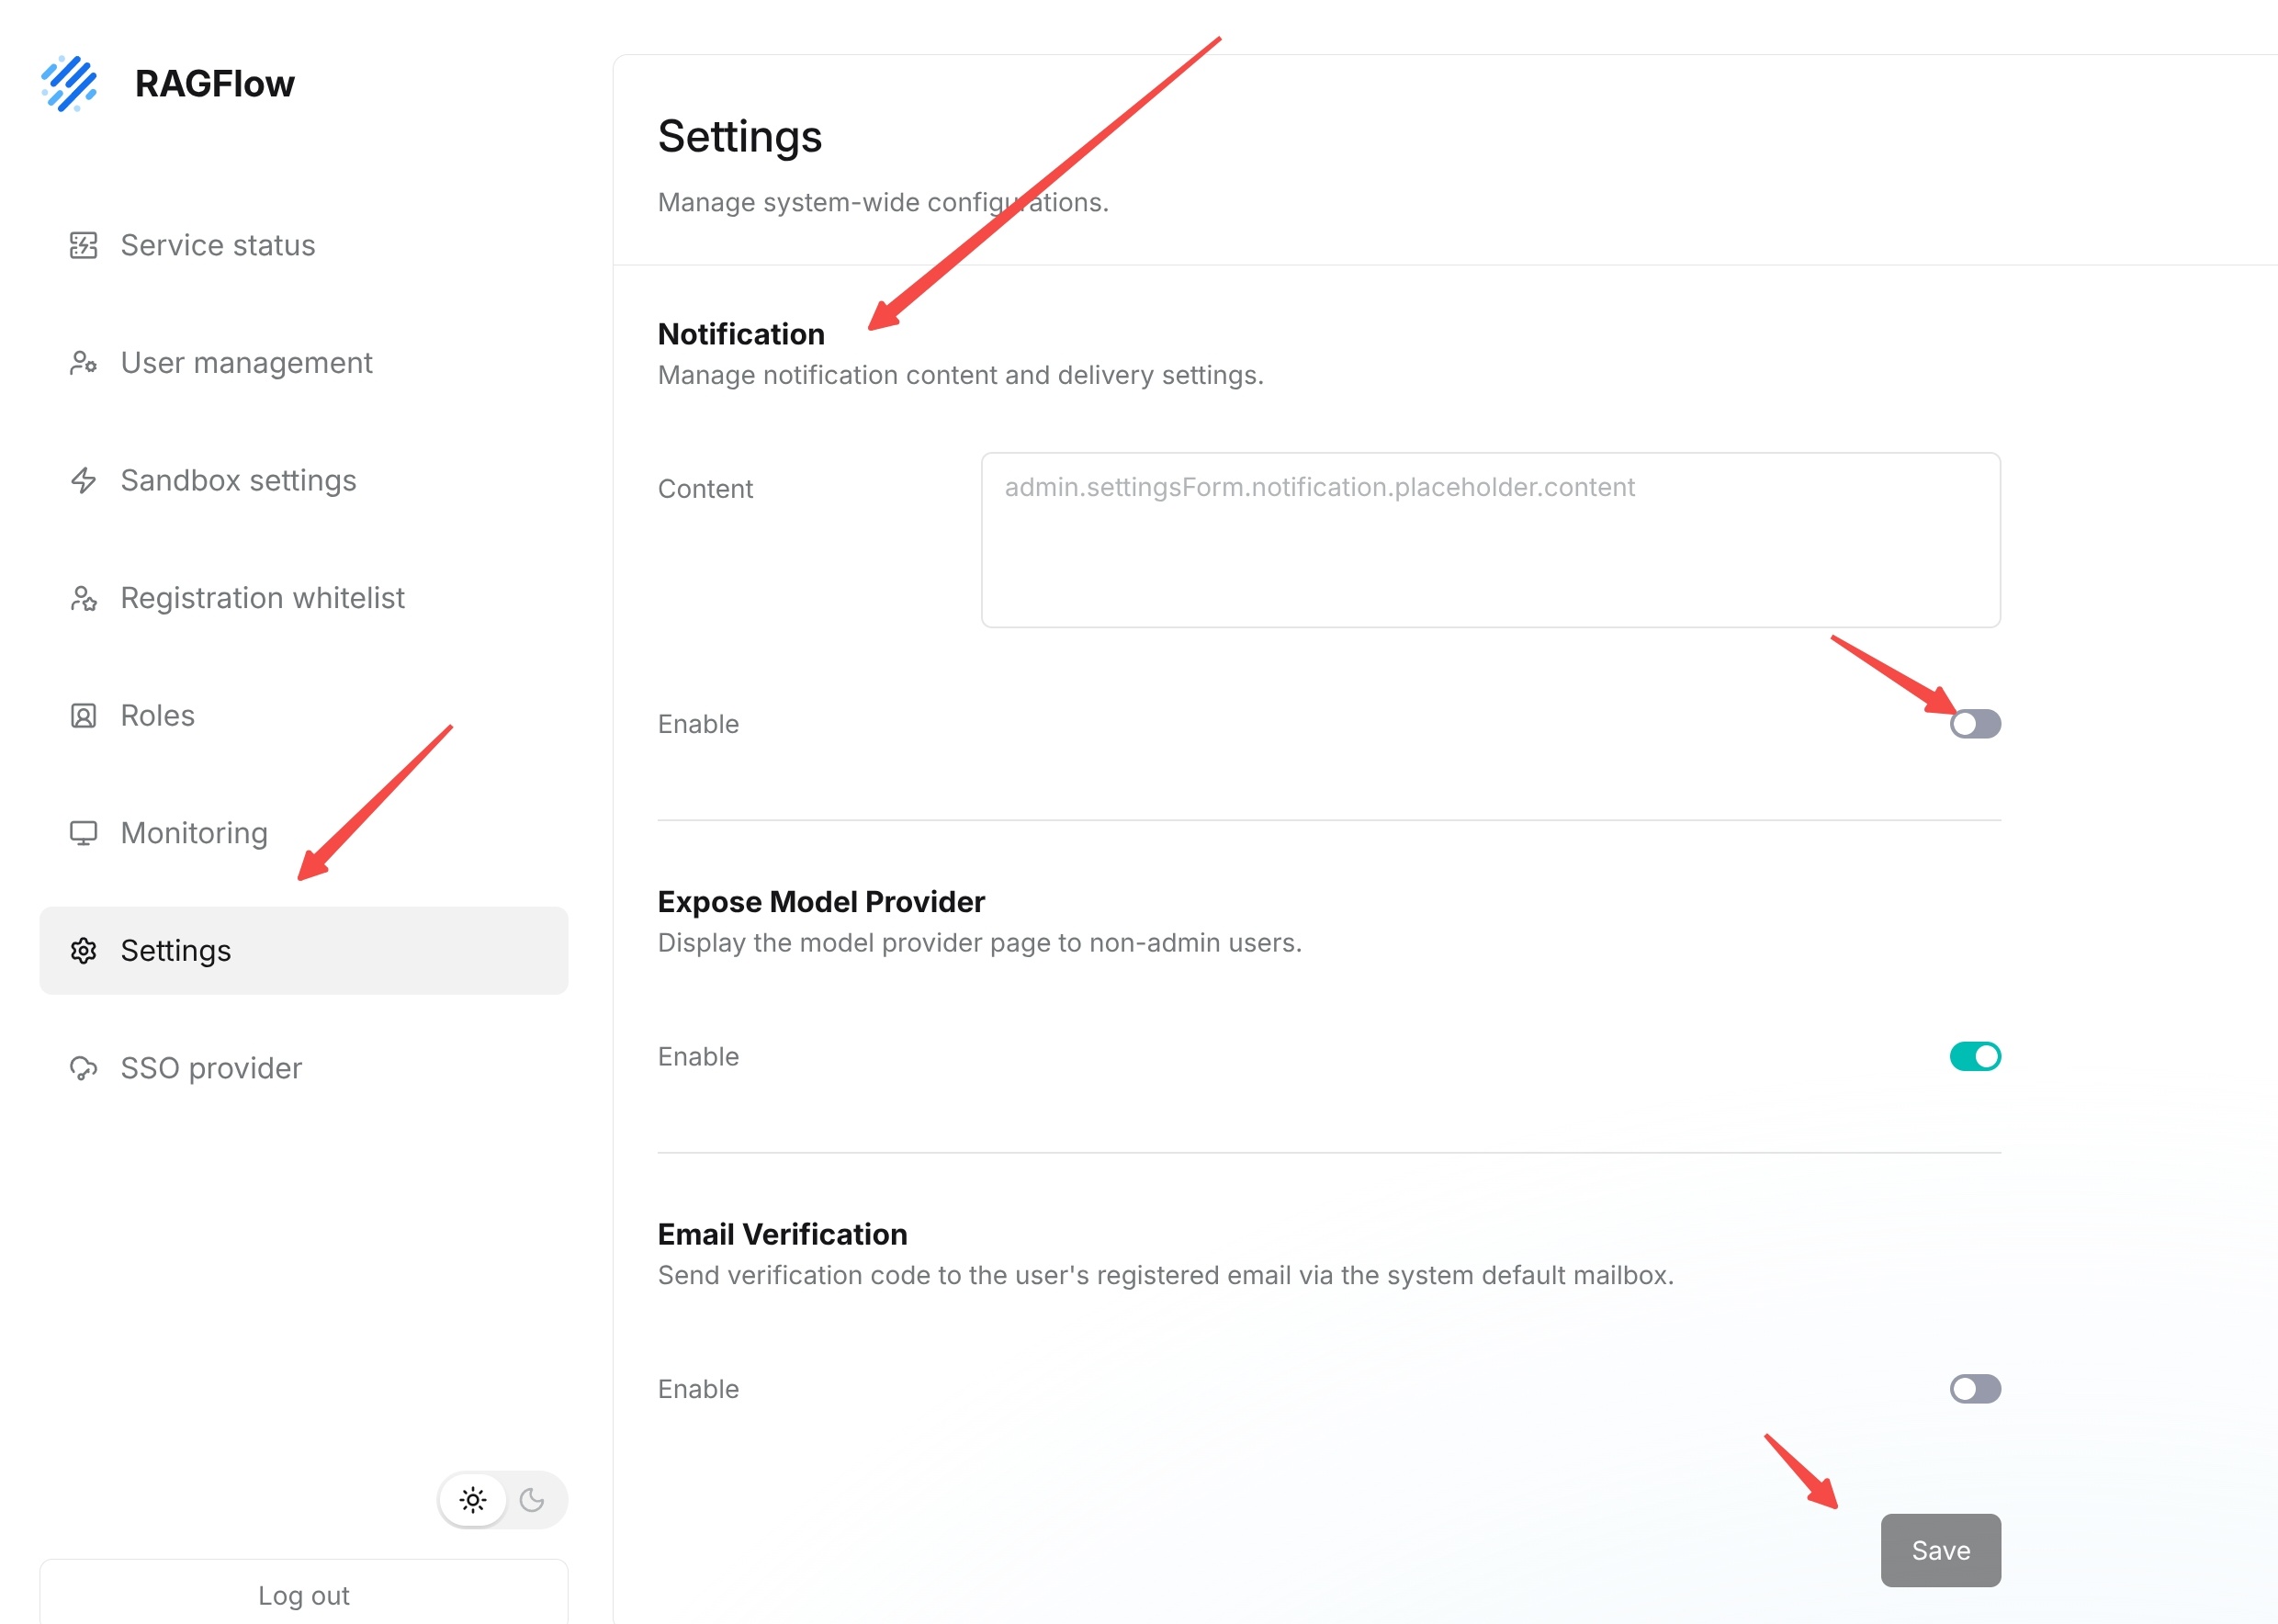--## Set Model Provider Page Visibility Scope--`ExposeModelProvider` controls whether the model provider page is displayed to non-administrator users. When enabled, non-administrator users can also see the `Model Provider` page entry. When disabled, the page is visible only to users with corresponding management permissions.--1. Go to the **Settings** page.-2. Find the **ExposeModelProvider** area.-3. Turn the `Enable` switch on or off according to the enterprise permission policy.-4. Click **Save**.--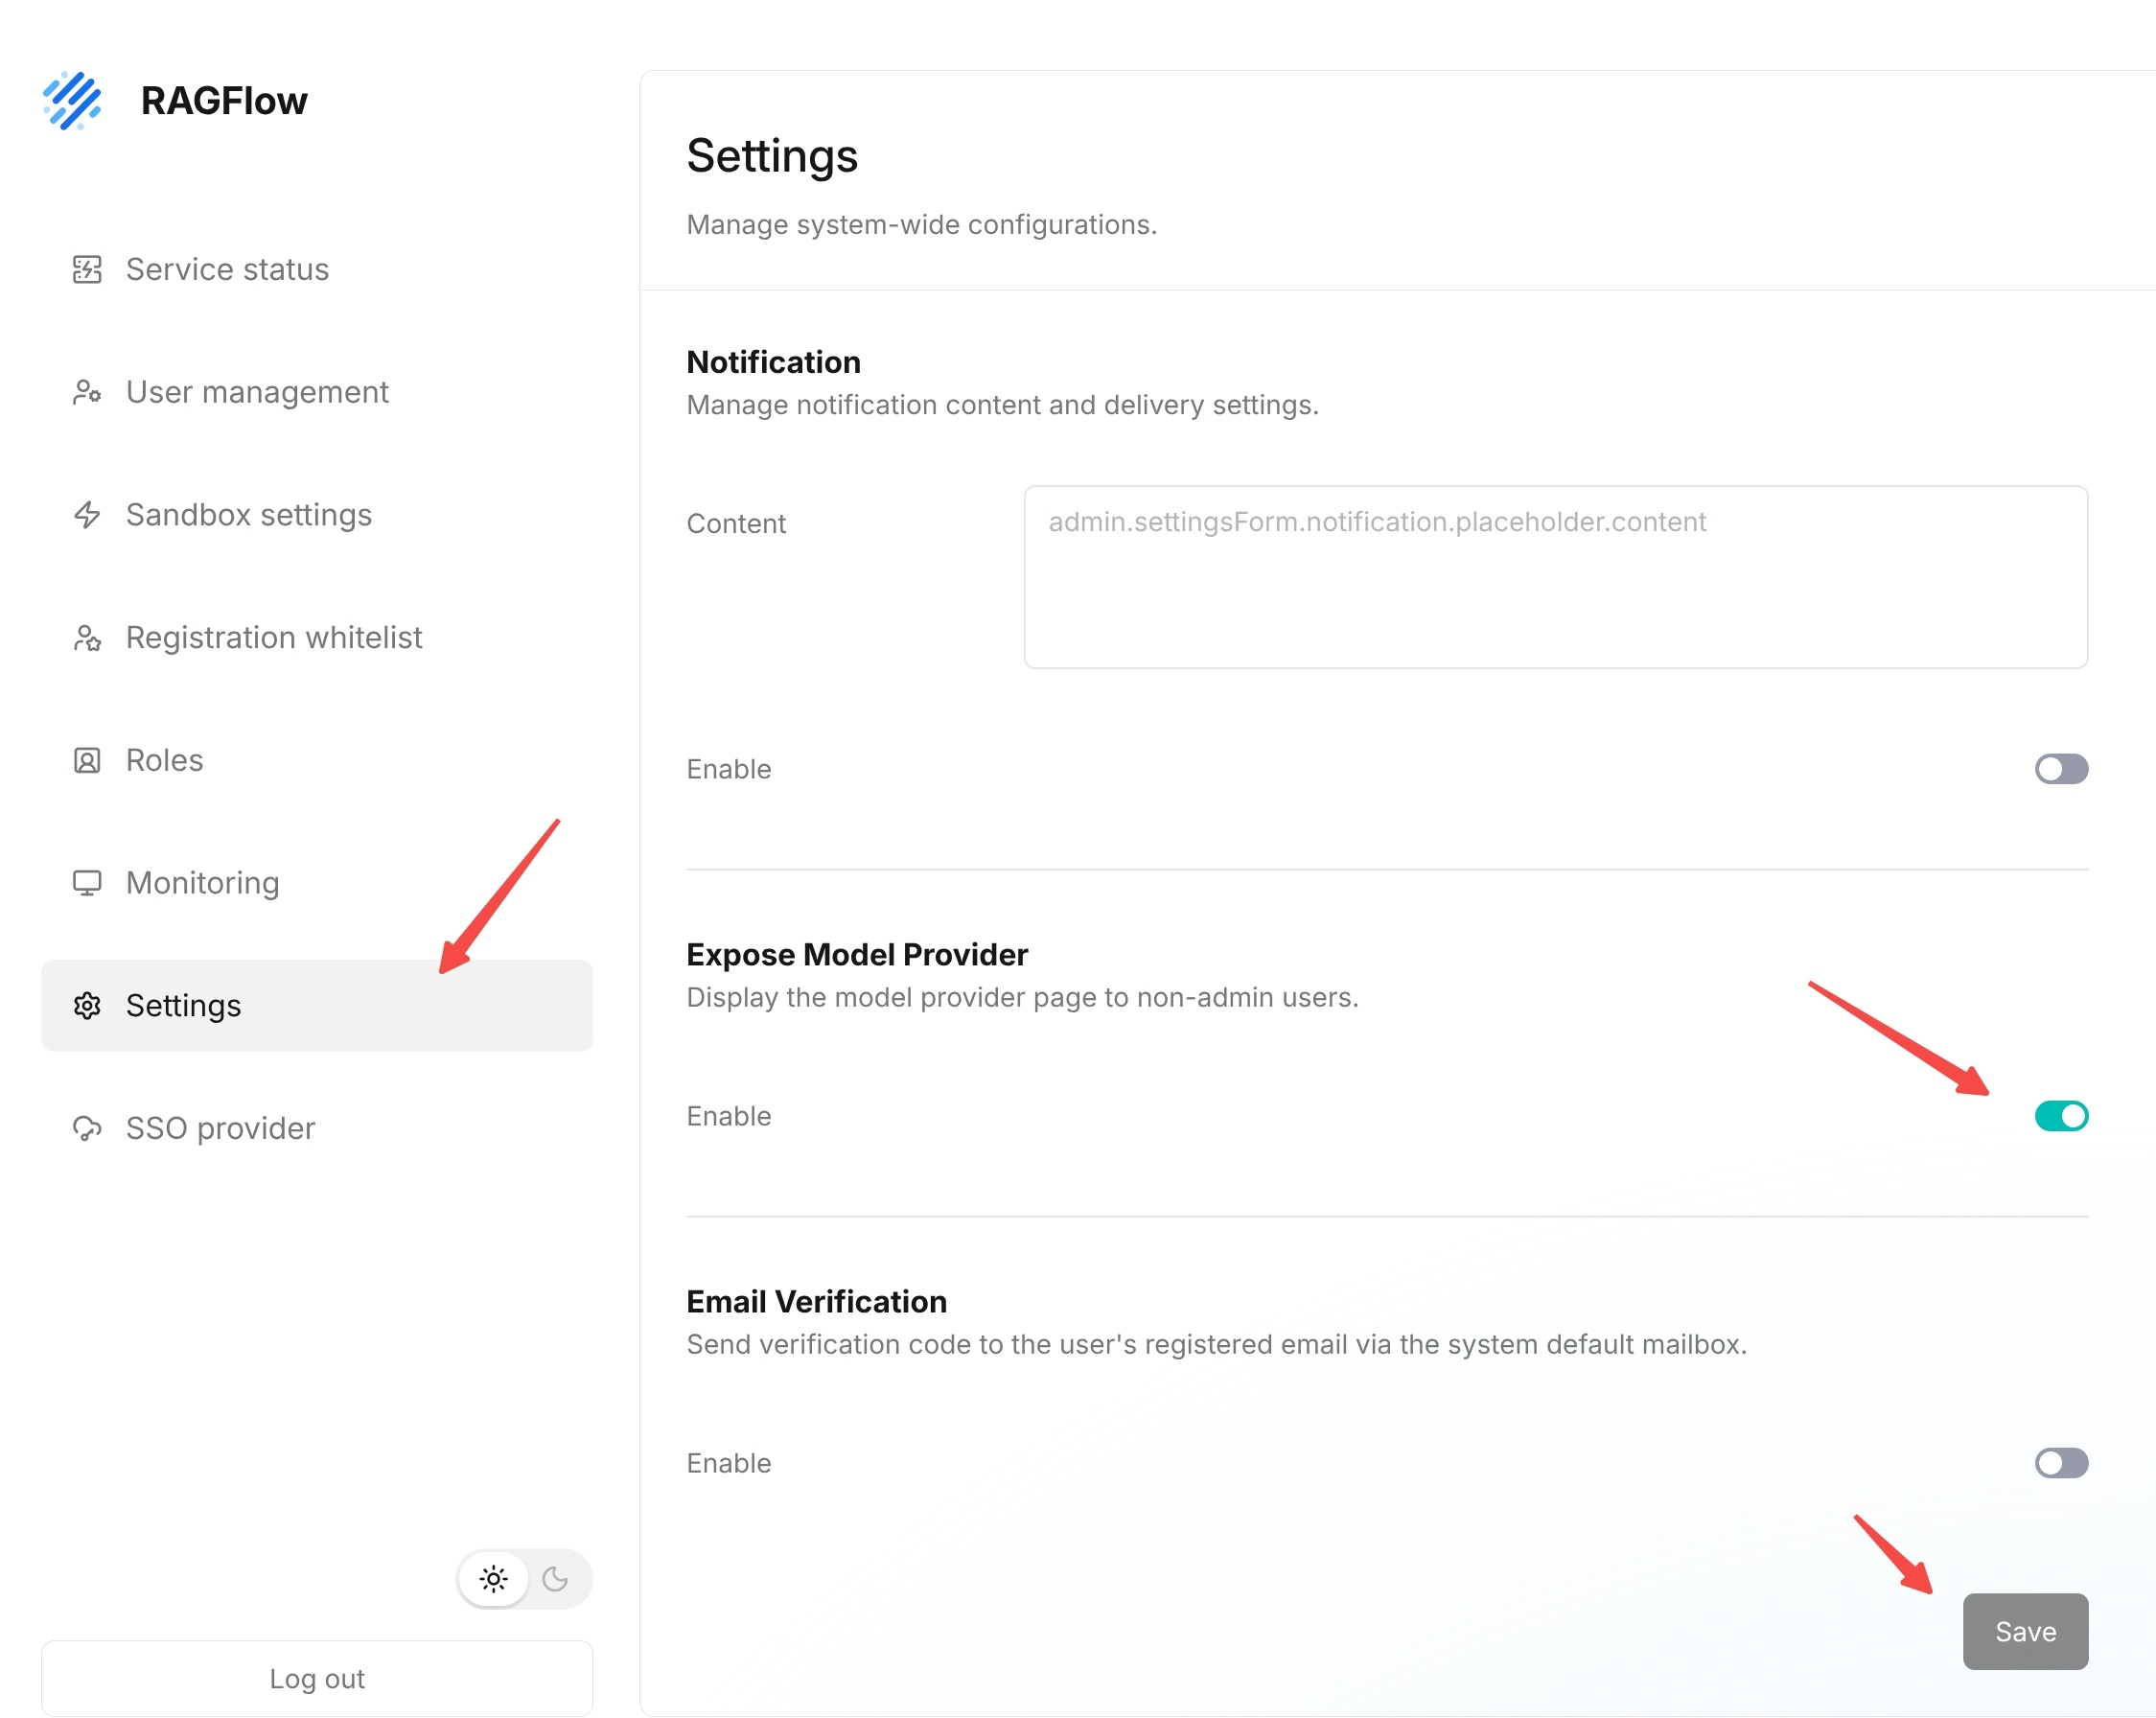--## Enable Email Verification--`EmailVerification` controls the registration email verification code feature. When enabled, the system sends a verification code from the default email account to the user's registration email address to verify that the registration email is genuine.--1. Go to the **Settings** page.-2. Confirm that SMTP has been configured correctly and that **Test connection** passed.-3. Find the **EmailVerification** area.-4. Turn on the `Enable` switch.-5. Click **Save**.--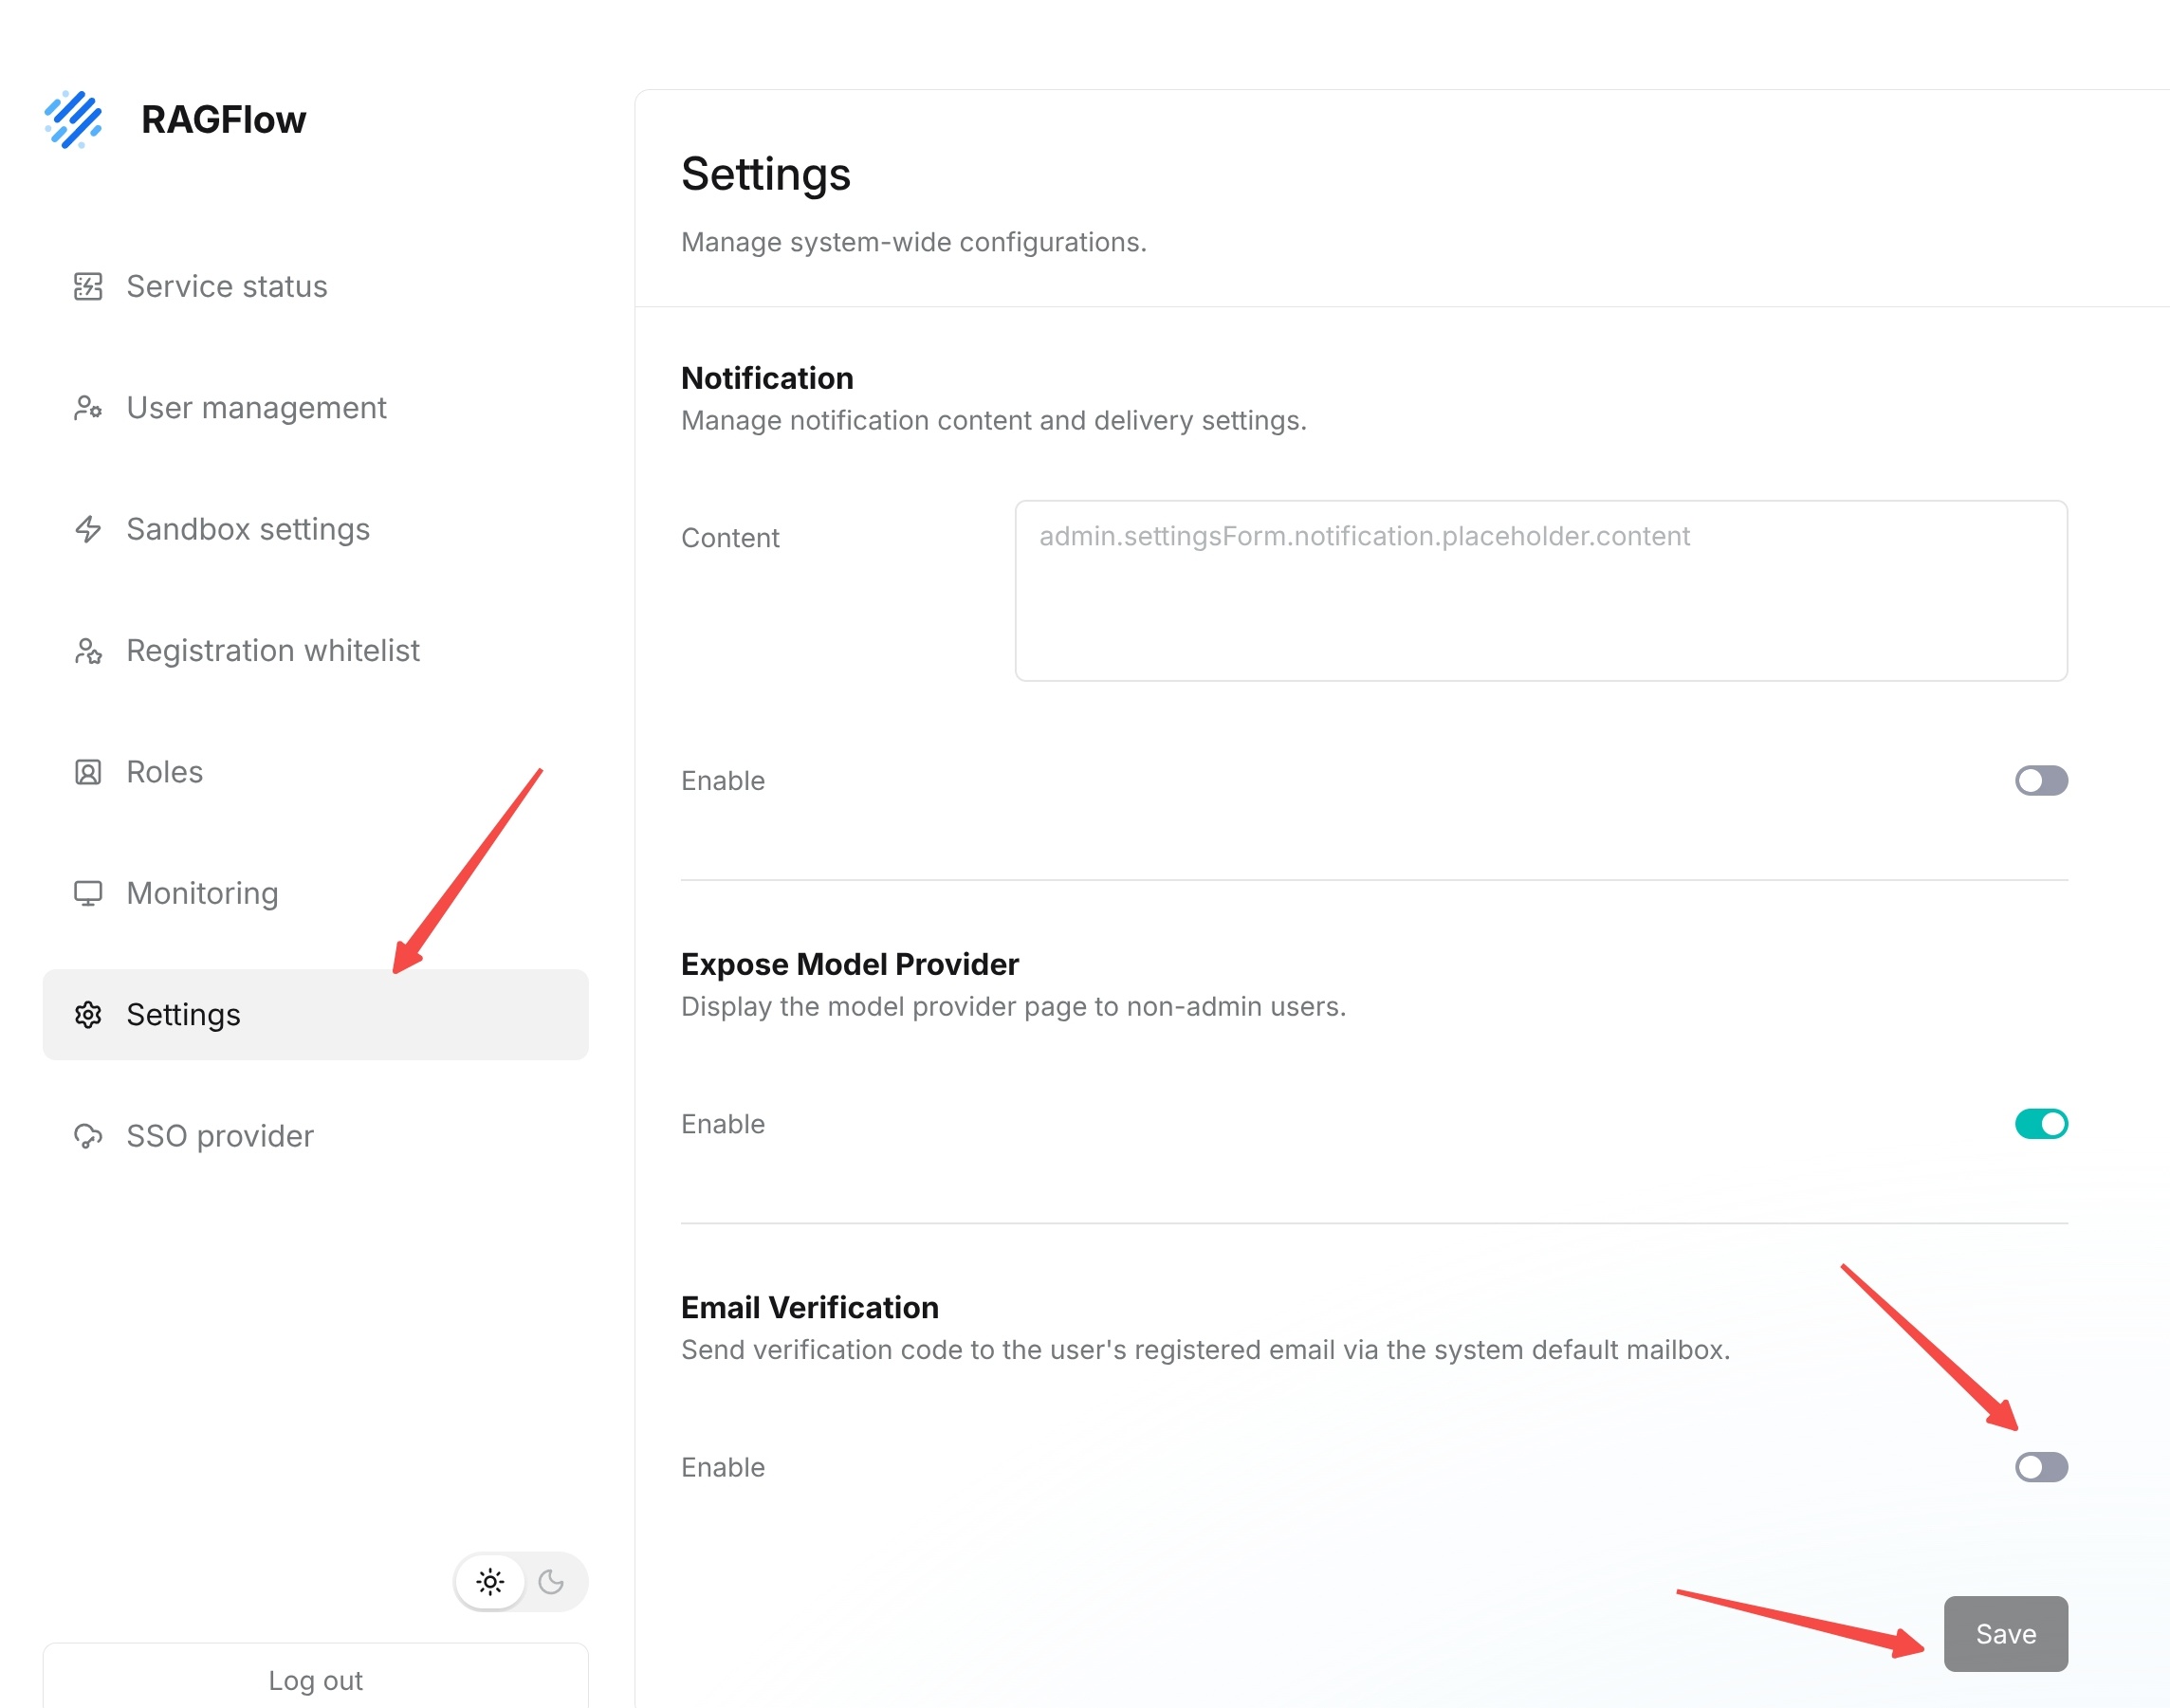--## Configure SSO Identity Providers--`SSO provider` selects a unified login identity provider for the organization. Administrators can choose one identity provider mode from `None`, `Cloud IDP`, and `LDAP`.--`Cloud IDP` configures a third-party cloud identity provider. The current page provides `Google`, `GitHub`, and `Feishu`. `LDAP` configures an enterprise directory identity provider and is suitable for organizations that use internal directory services.--1. Go to the **SSO provider** page.-2. Select `None`, `Cloud IDP`, or `LDAP` according to the organization's identity management method.-3. If you select `Cloud IDP`, enable the corresponding identity provider from `Google`, `GitHub`, and `Feishu`.-4. If you select `LDAP`, enable the default LDAP configuration or click **Add** to add a new LDAP configuration.-5. Click the settings button on the right side of the corresponding identity provider and fill in the identity provider parameters as required by the page.-6. After configuration, verify the login flow with a test account before switching to production use.--**Note:** Before switching the production identity provider, make sure at least one administrator login method remains available. Otherwise, a configuration error may prevent administrators from entering the Admin UI.diff --git a/docs/administrator/admin/admin_ui/manage_user_accounts.md b/docs/administrator/admin/admin_ui/manage_user_accounts.mdindex 10032332a2..974d40905f 100644--- a/docs/administrator/admin/admin_ui/manage_user_accounts.md+++ b/docs/administrator/admin/admin_ui/manage_user_accounts.md@@ -1,47 +1,47 @@---sidebar_position: 3-sidebar_label: "Manage User Accounts"+sidebar_label: Manage User Accounts+title: Manage User Accounts---# Manage User Accounts## View and Search Users-User accounts are managed on the **User management** page. Administrators can view the user list, including `Email`, `Nickname`, `Status`, `User type`, and `Last login time`. The current Enterprise Edition page also displays `Role`.+User accounts are managed on the **User management** page. Administrators can view the user list, including `Email`, `Nickname`, `Status`, `User type`, and `Last login time`.-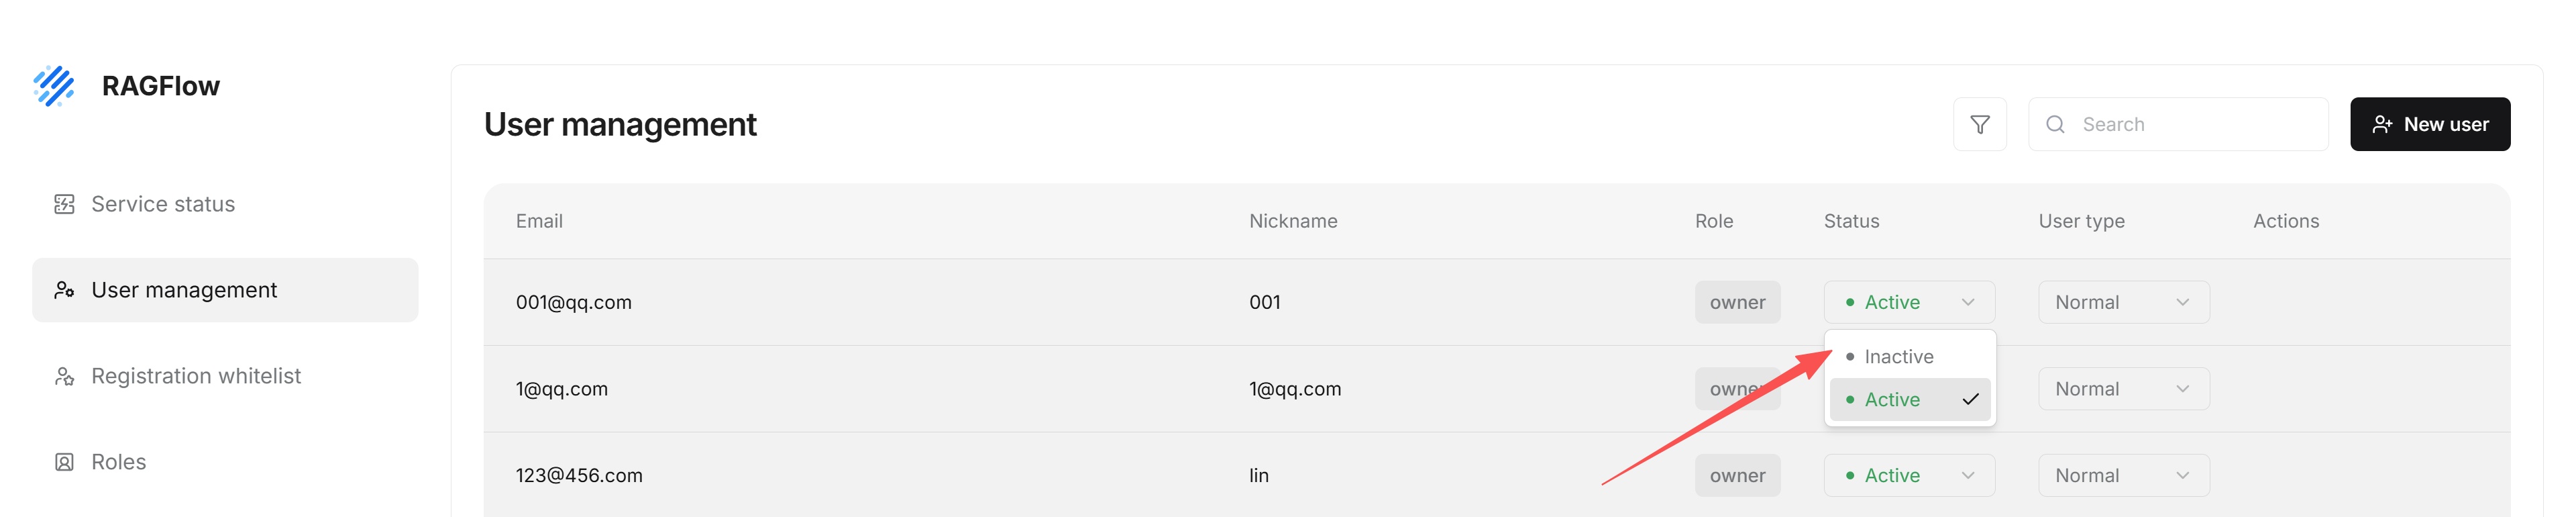+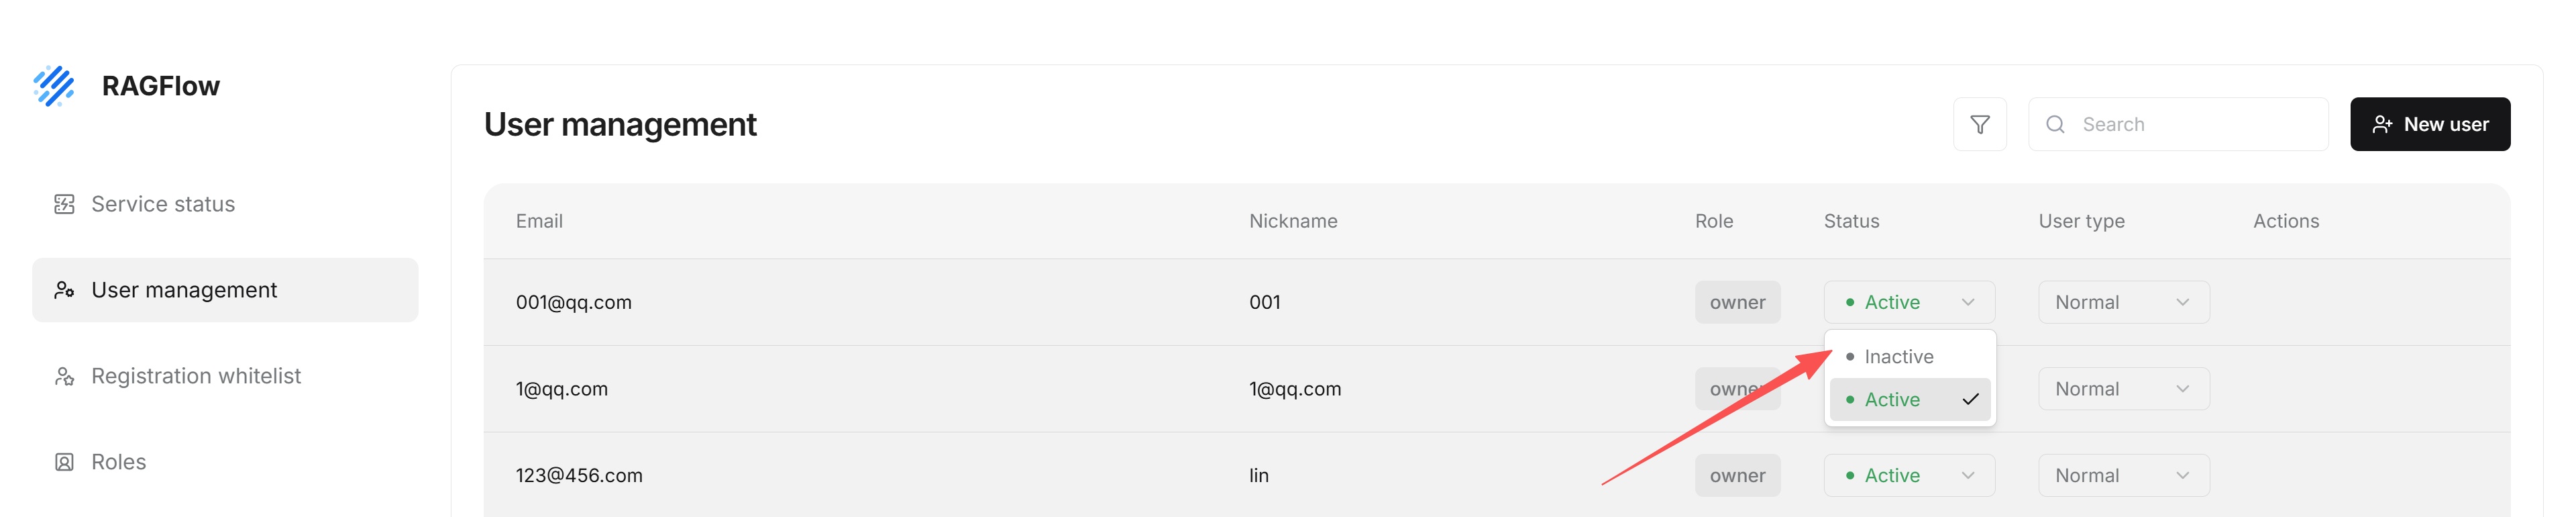-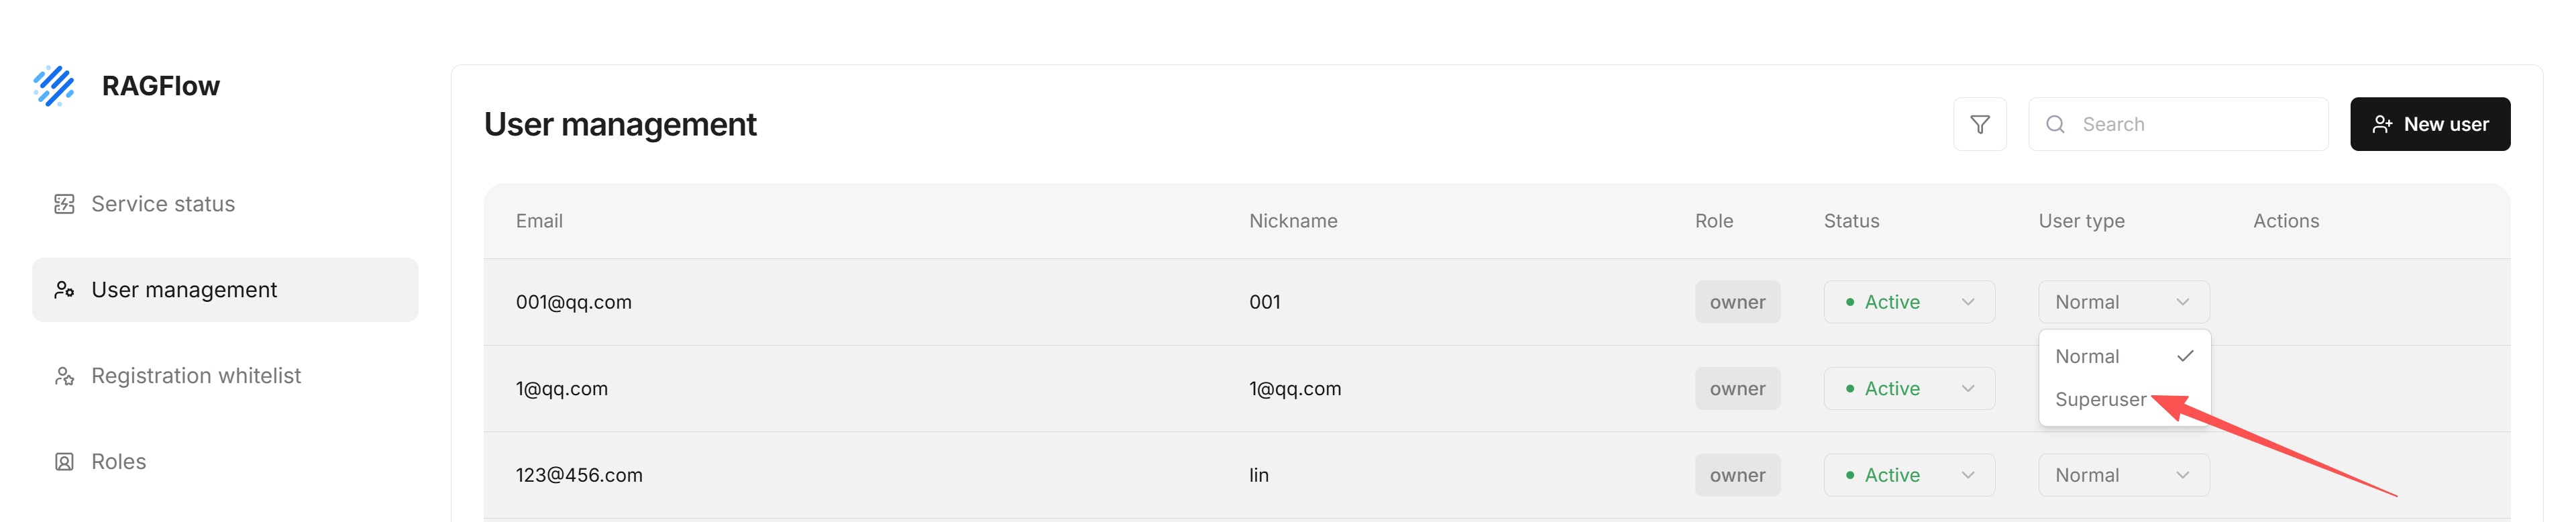+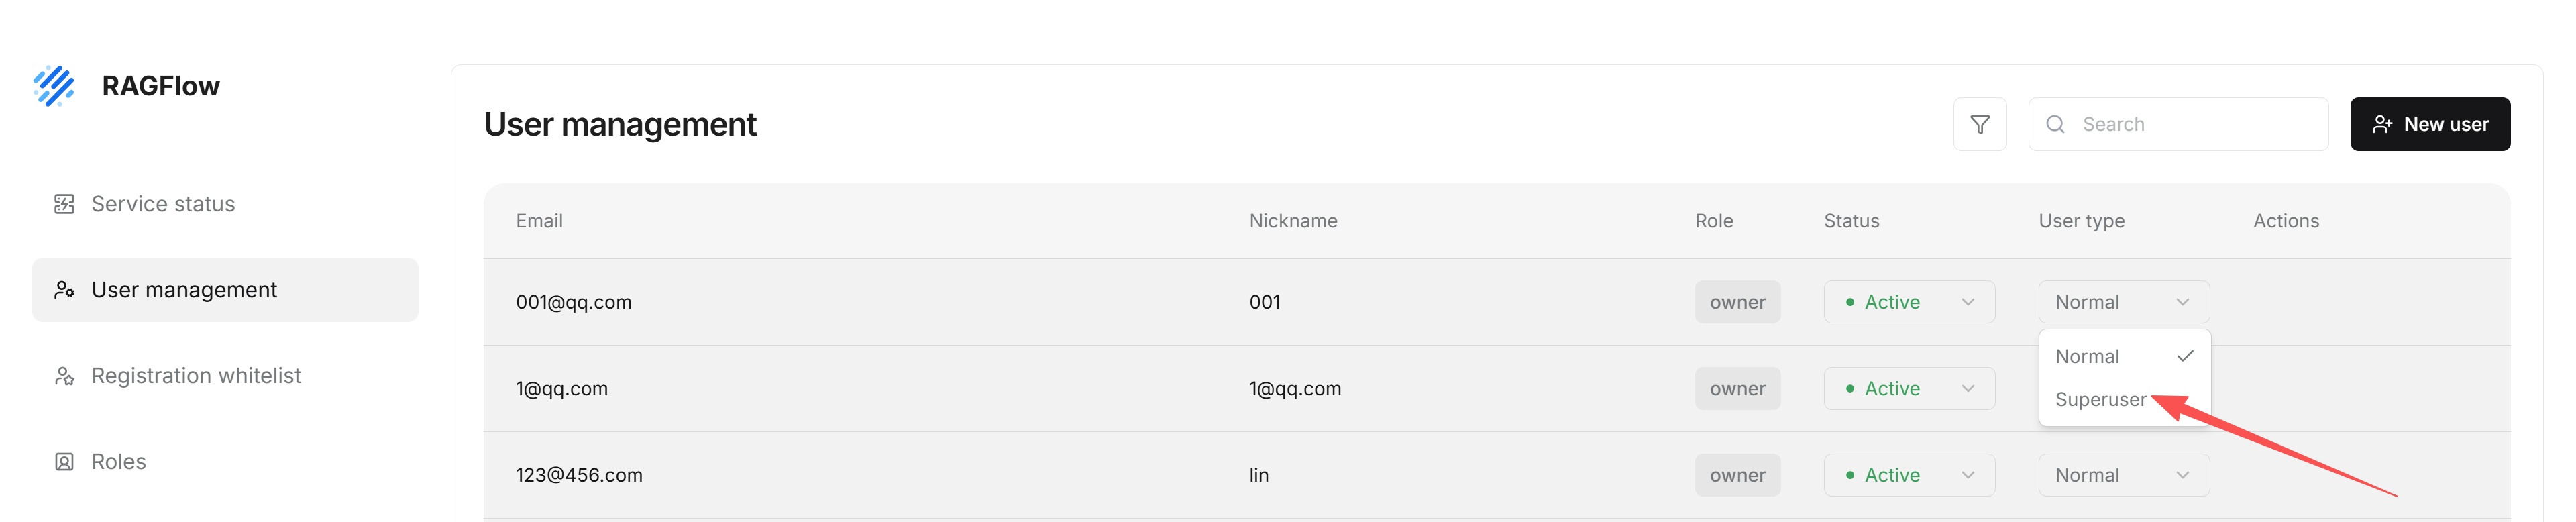-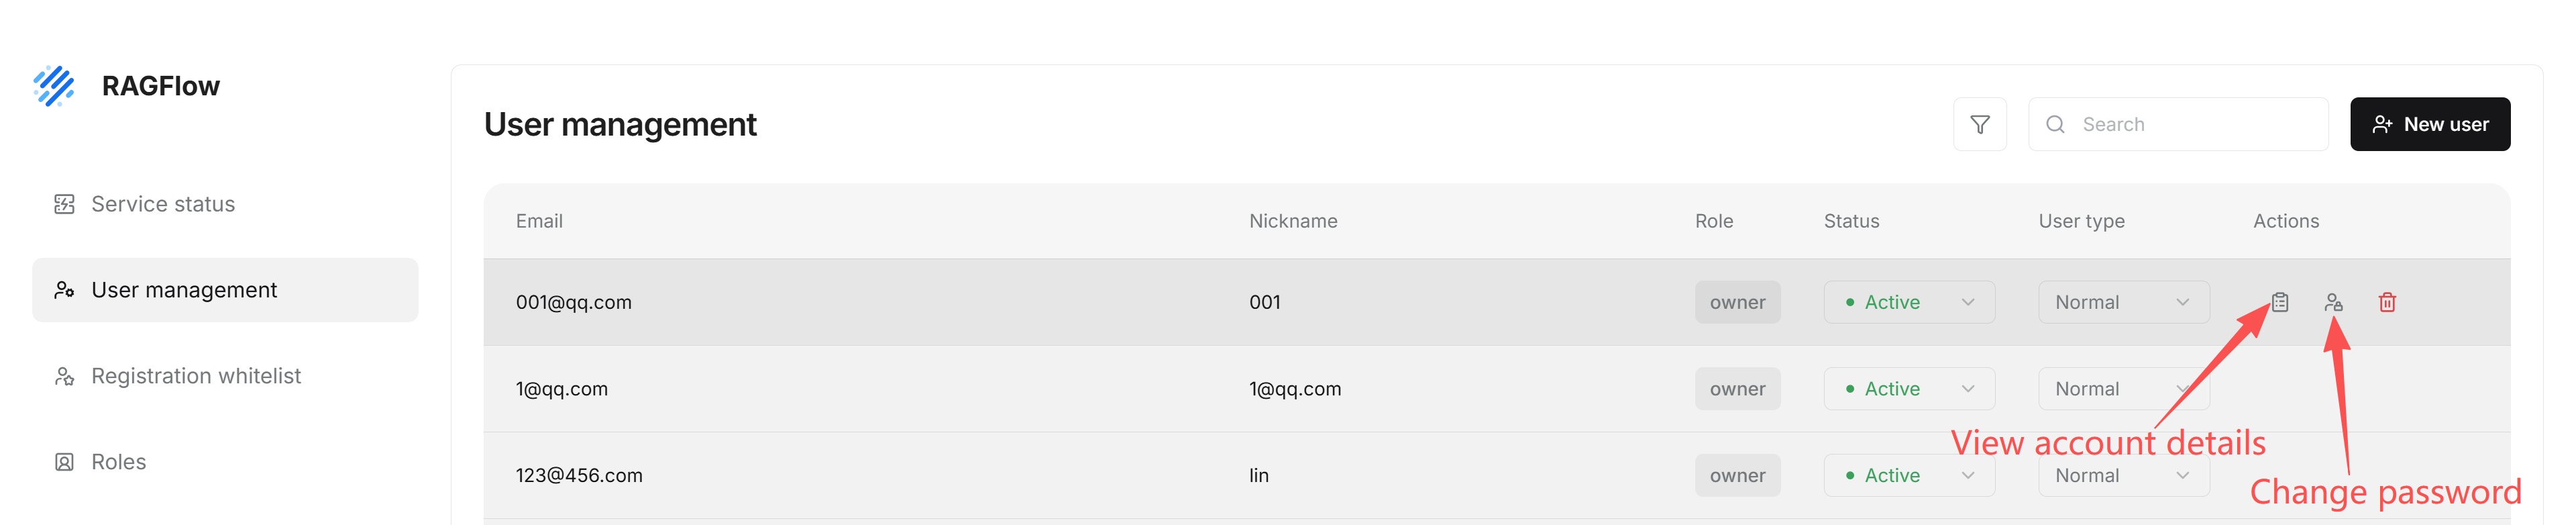+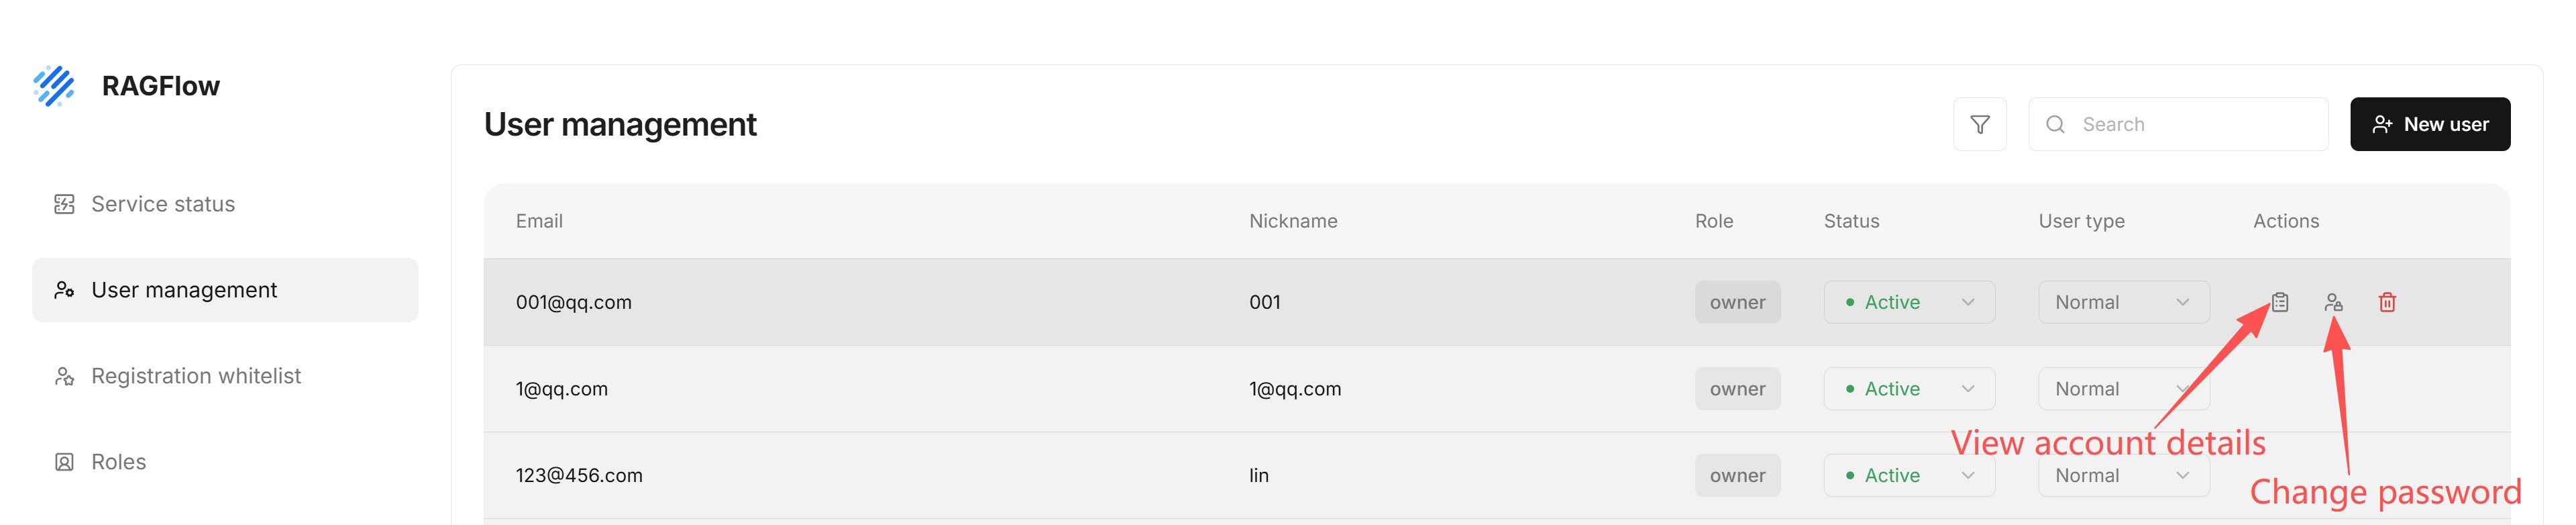-Use the search box in the upper-right corner to search users by `Email` or `Nickname`. You can also filter `Active` or `Inactive` users by `Status`. In Enterprise Edition, you can also filter users by `Role`.+Use the search box in the upper-right corner to search users by `Email` or `Nickname`. You can also filter `Active` or `Inactive` users by `Status`.-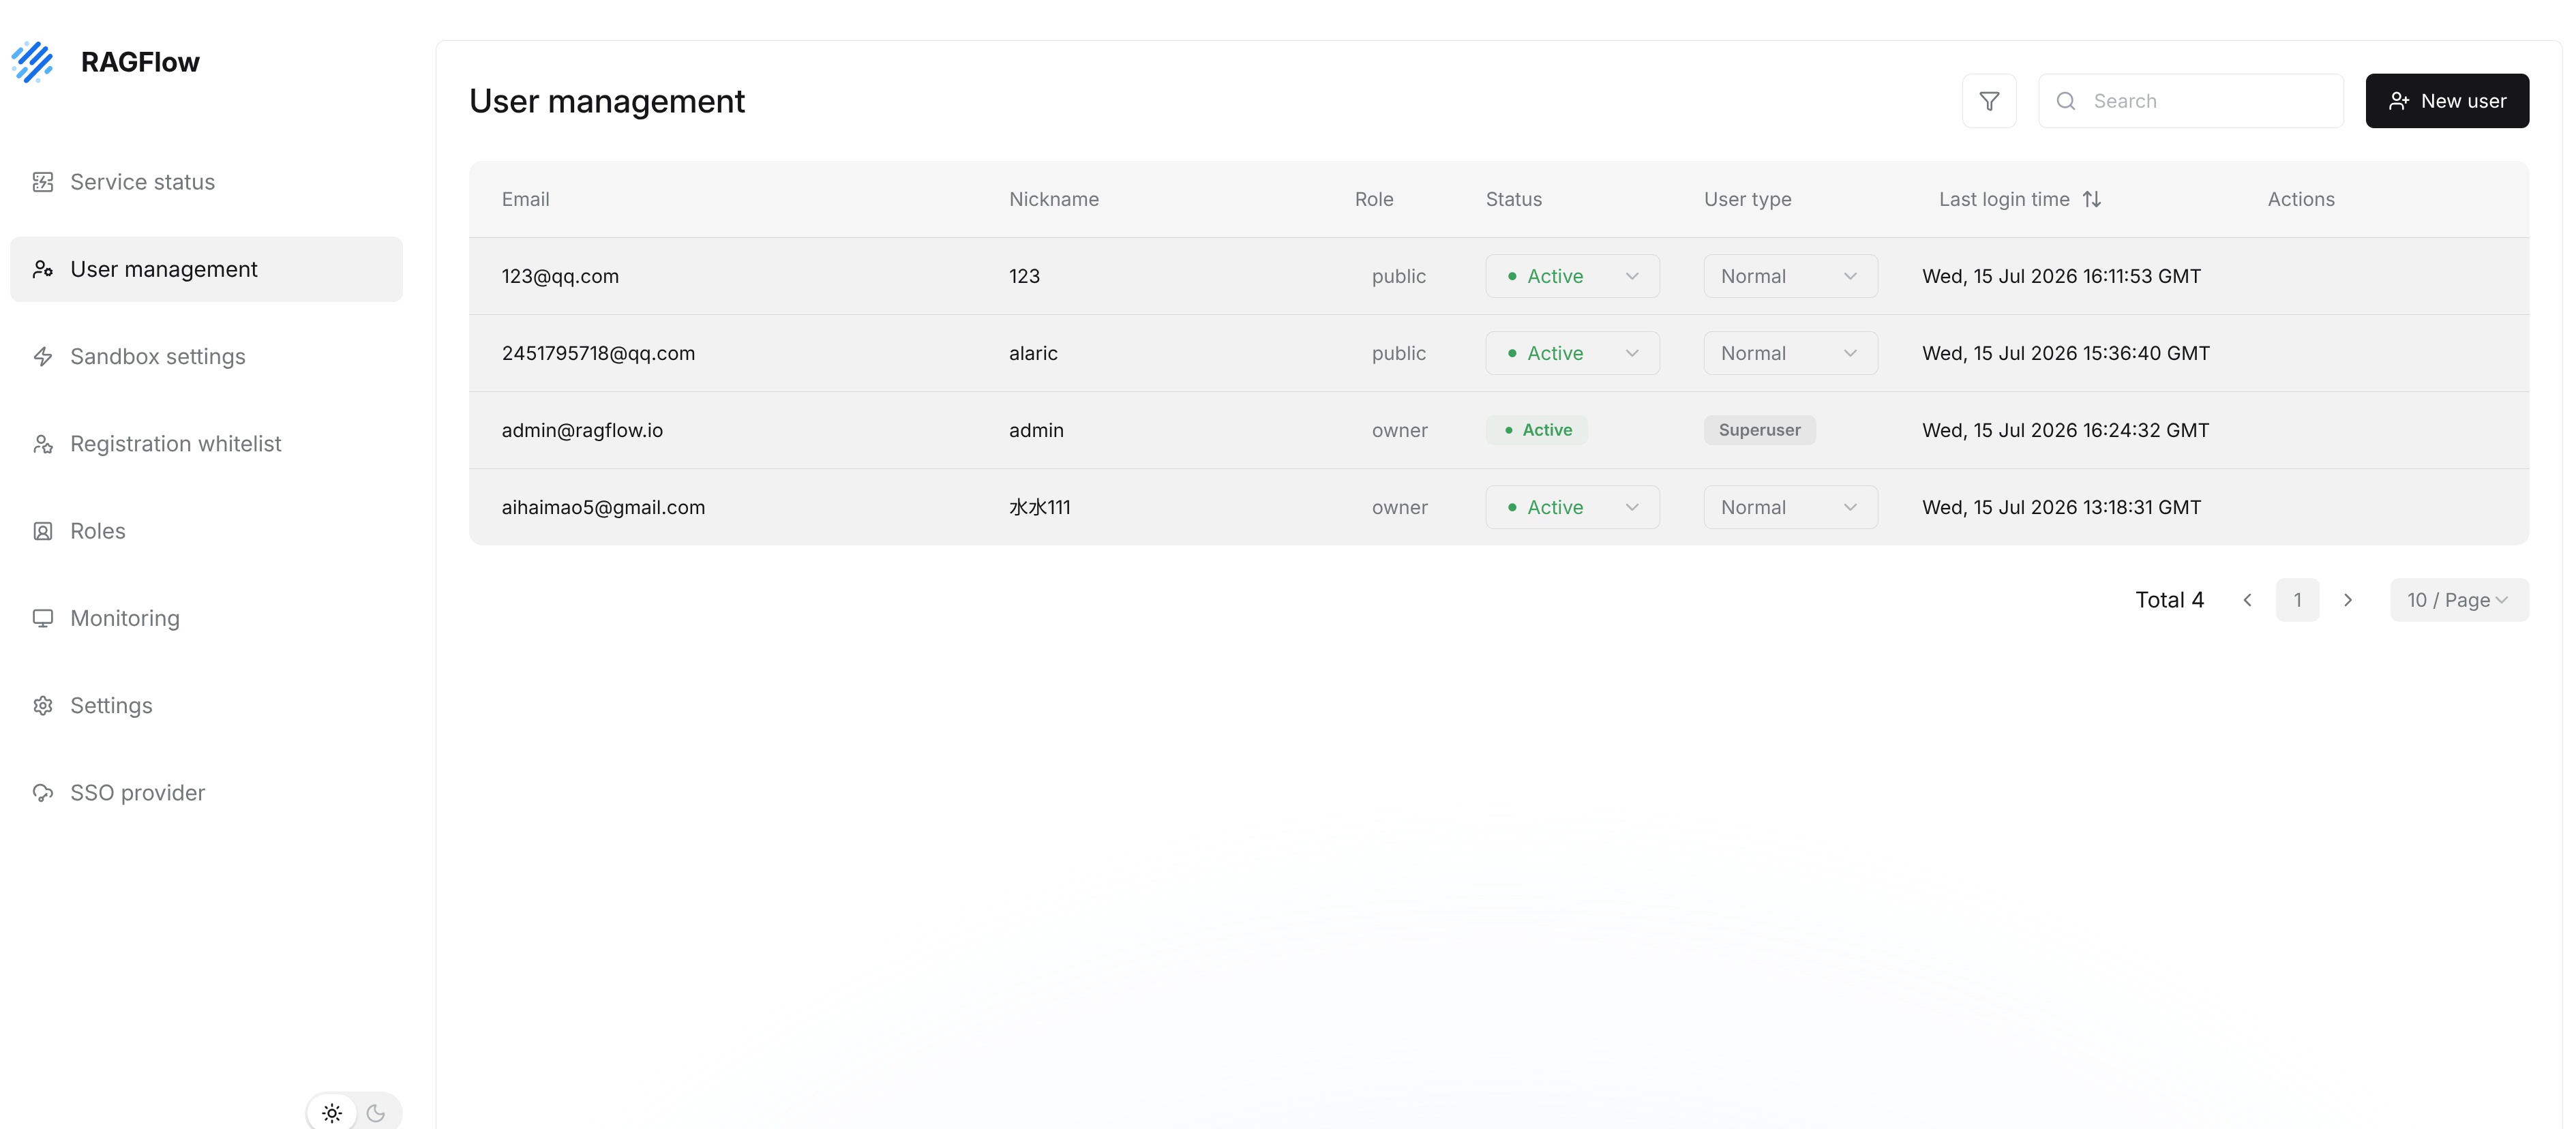+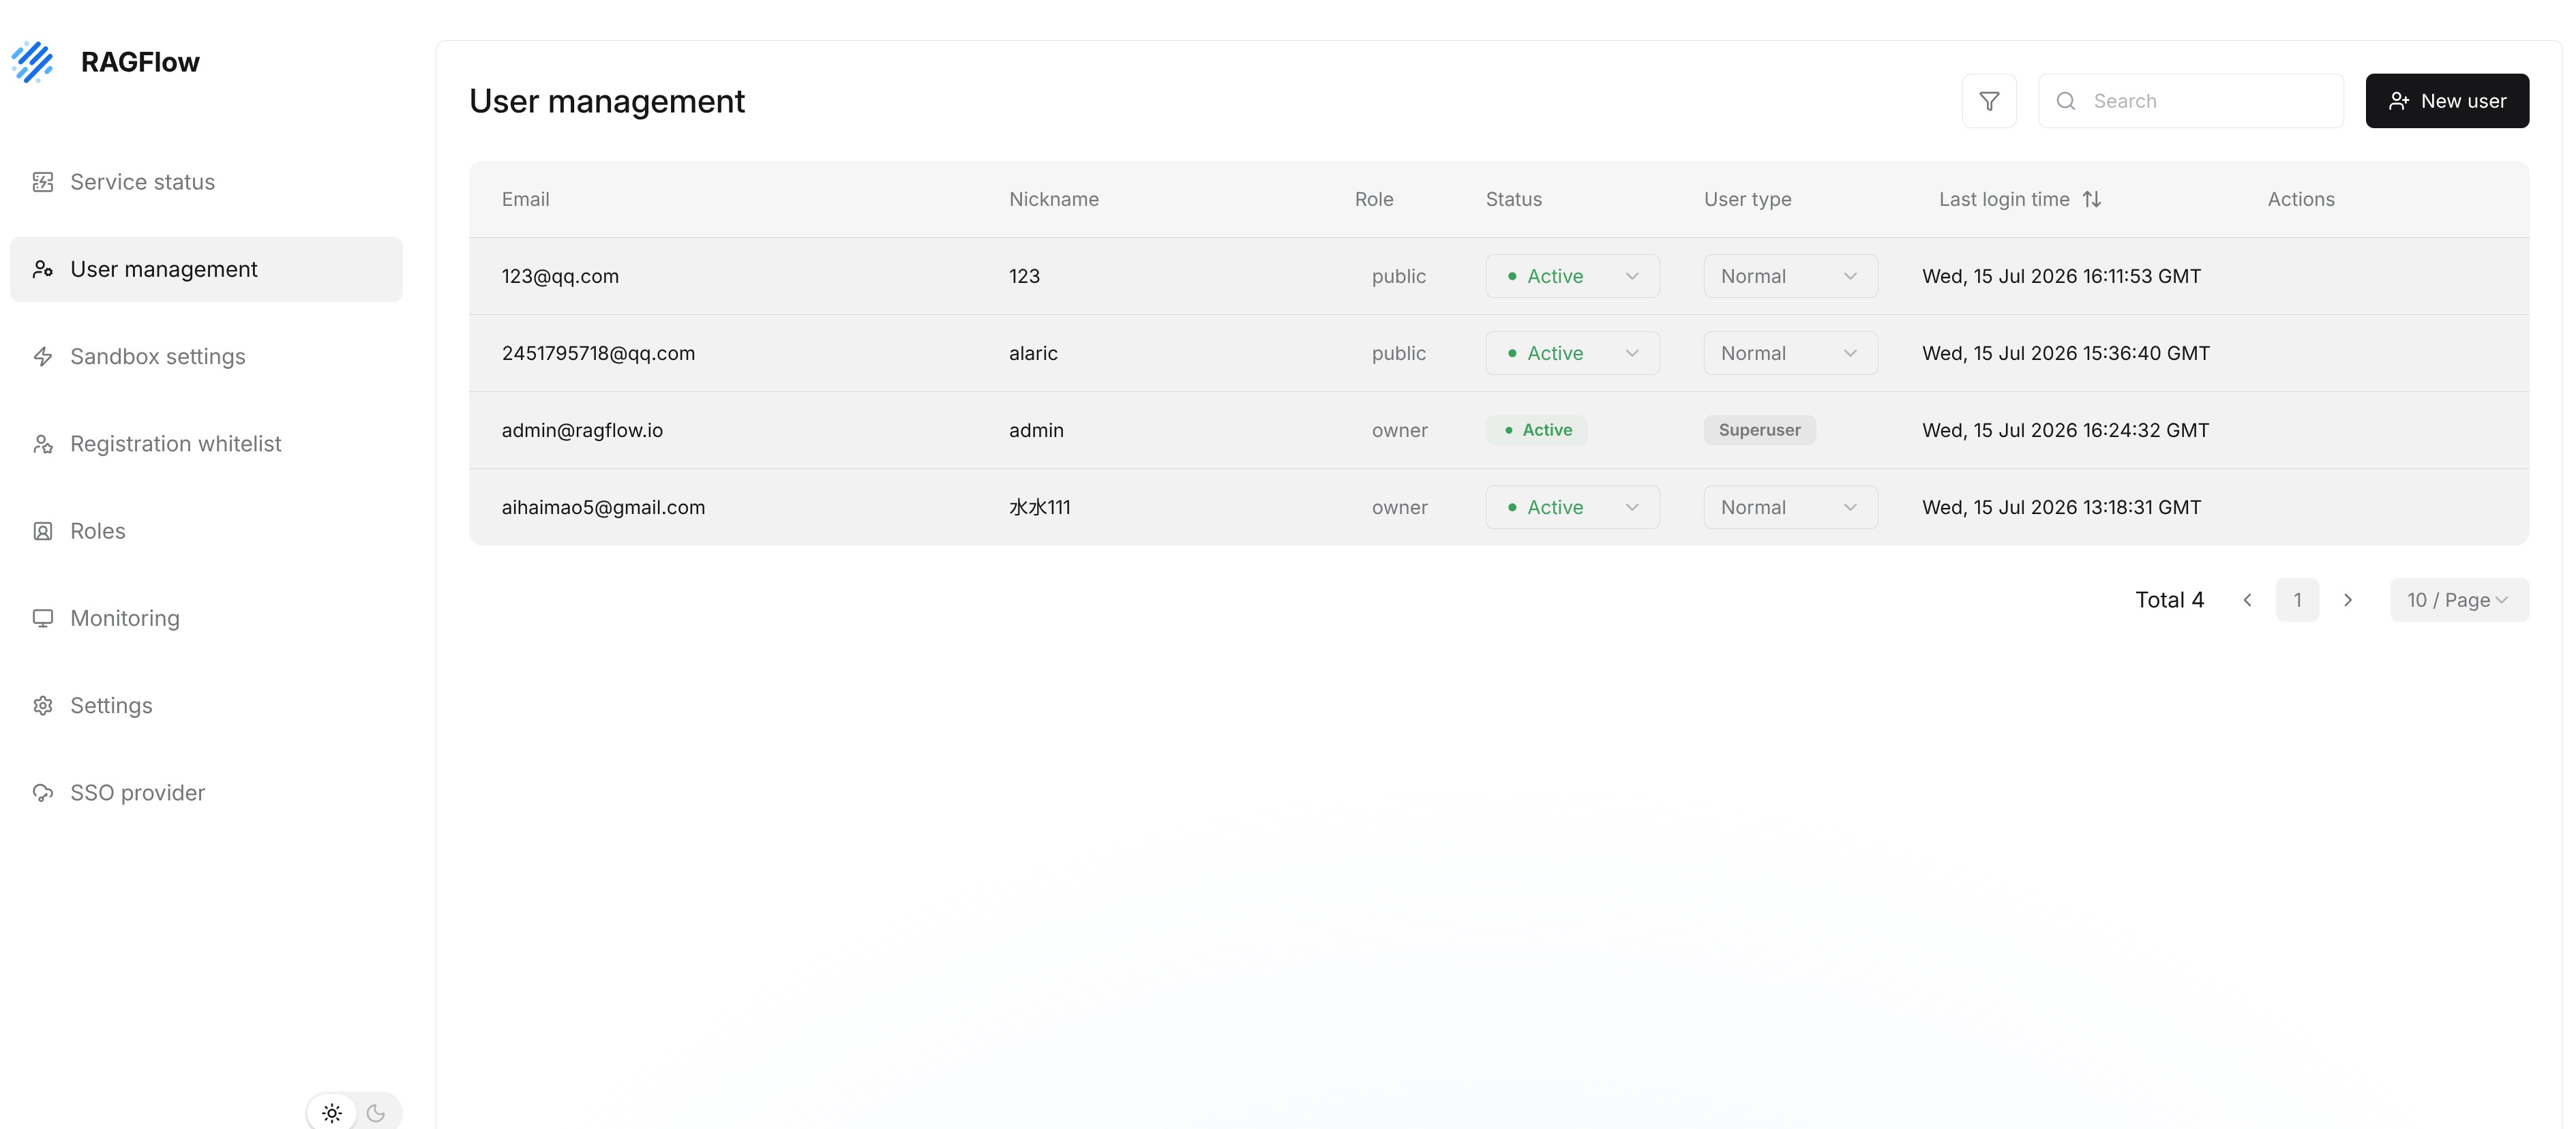-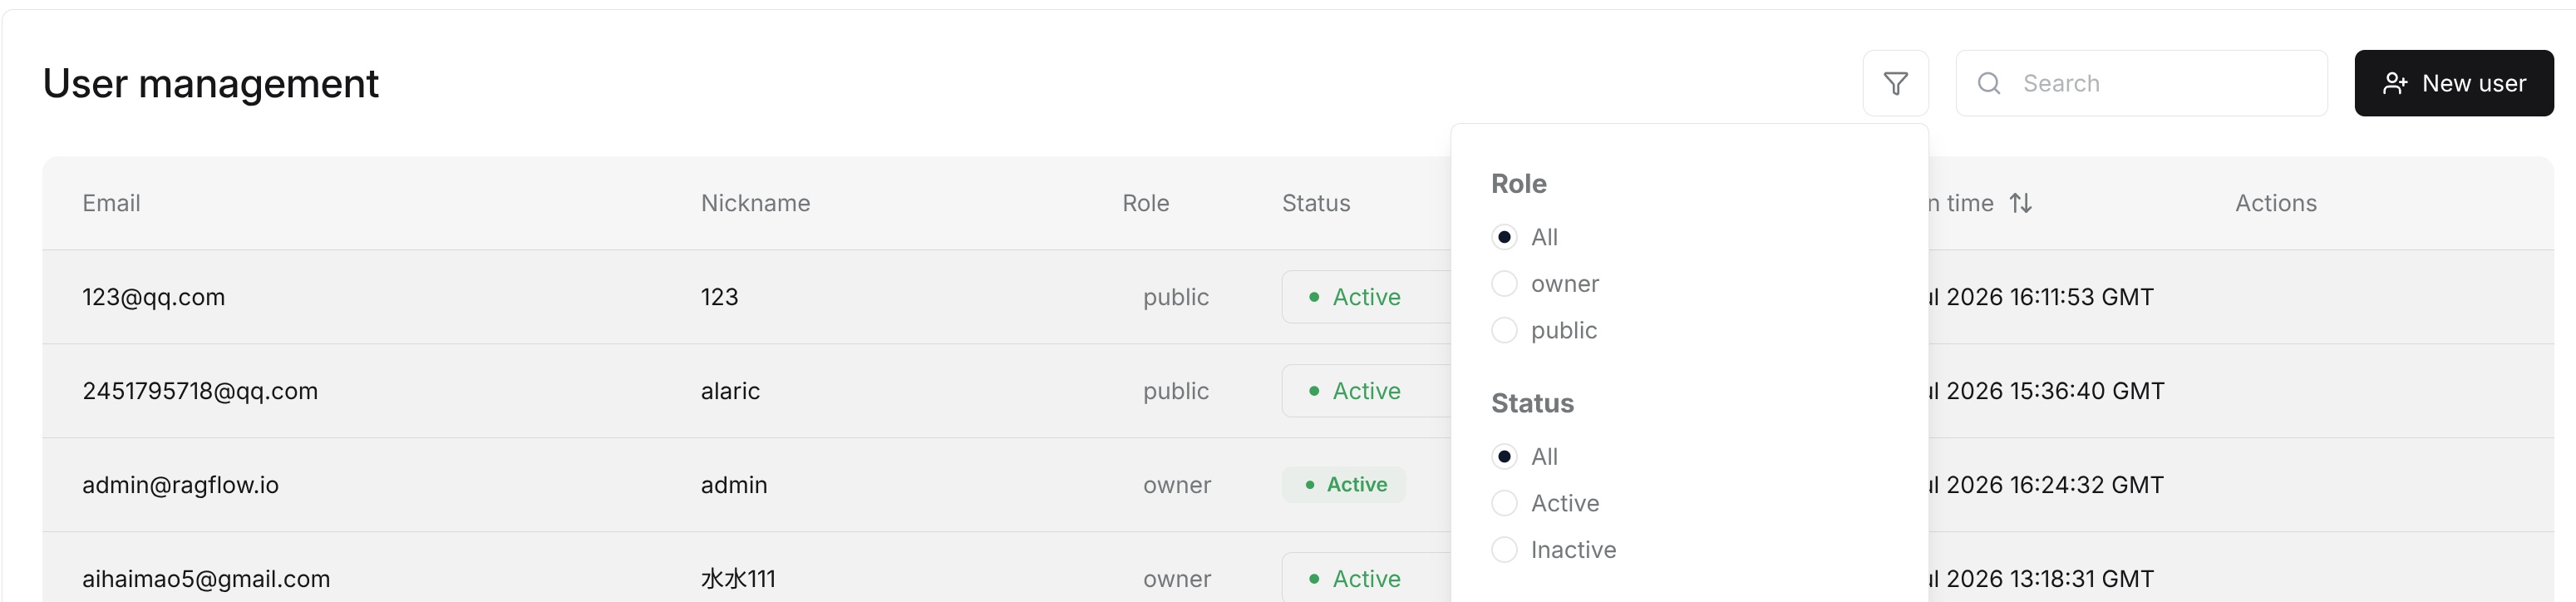+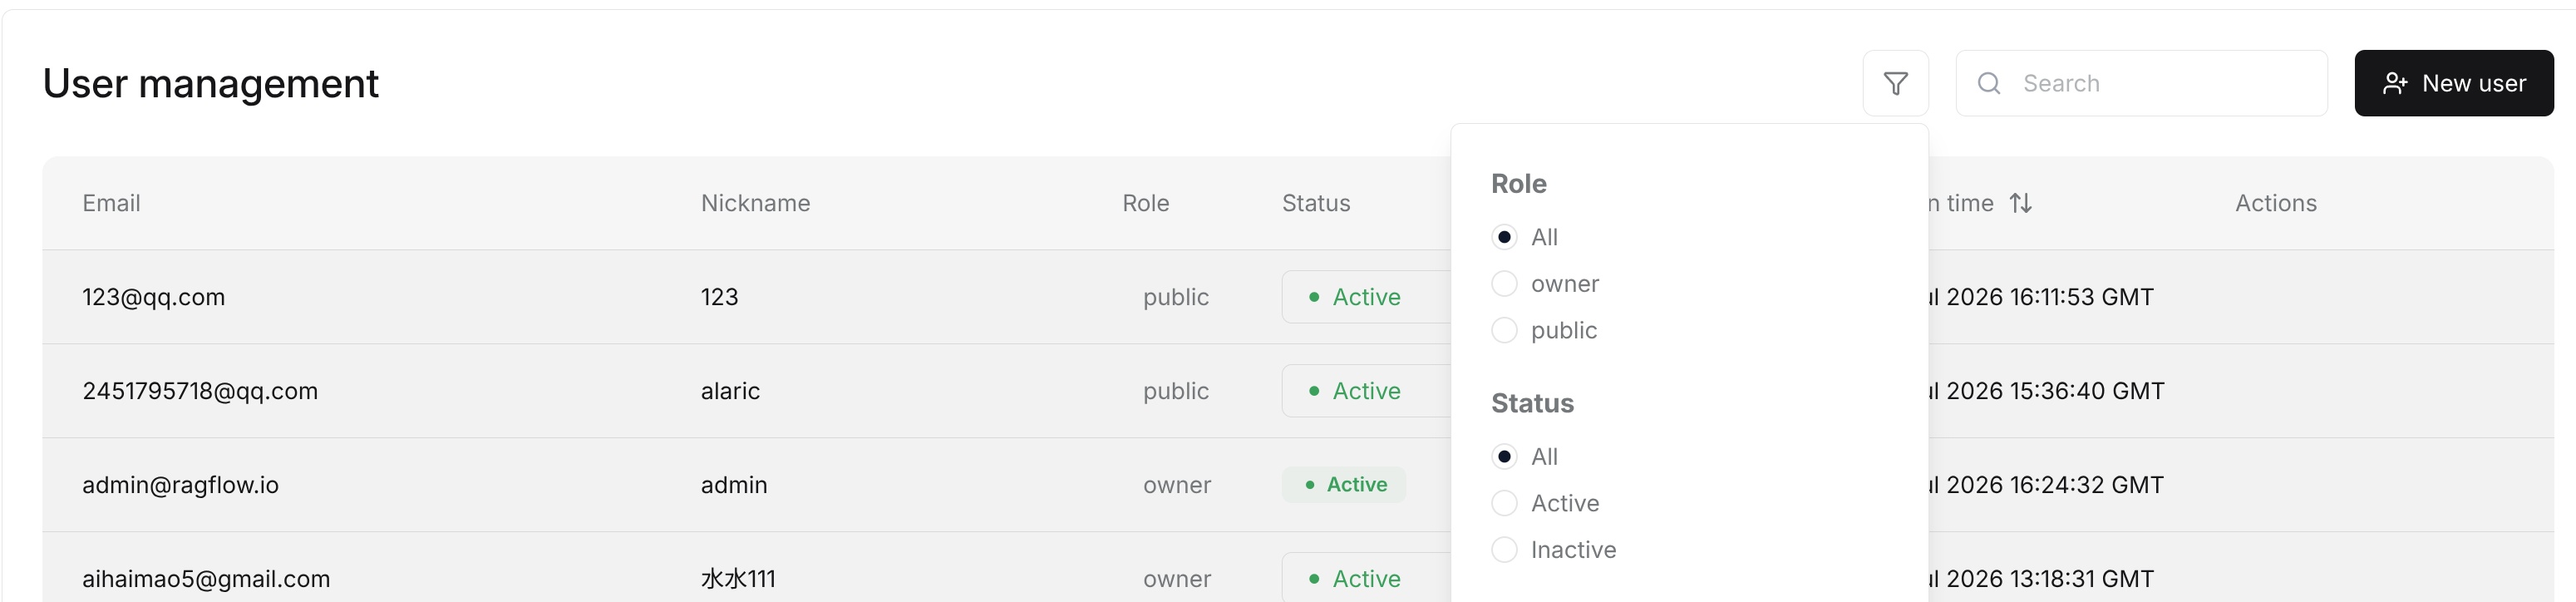## Create a New User-To create an account for a new member, go to **User management** and click **New user**. In the dialog, fill in `Email`, `Password`, and `Confirm password`. The current Enterprise Edition page also allows you to select a `Role` when creating a user.+To create an account for a new member, go to **User management** and click **New user**. In the dialog, fill in `Email`, `Password`, and `Confirm password`.1. Go to the **User management** page.2. Click **New user**.3. Enter the user's `Email`.4. Enter the initial password.5. Enter the same password again in `Confirm password`.-6. In Enterprise Edition, select a `Role` according to the user's responsibilities.-7. Click **Confirm** to create the account.+6. Click **Confirm** to create the account.-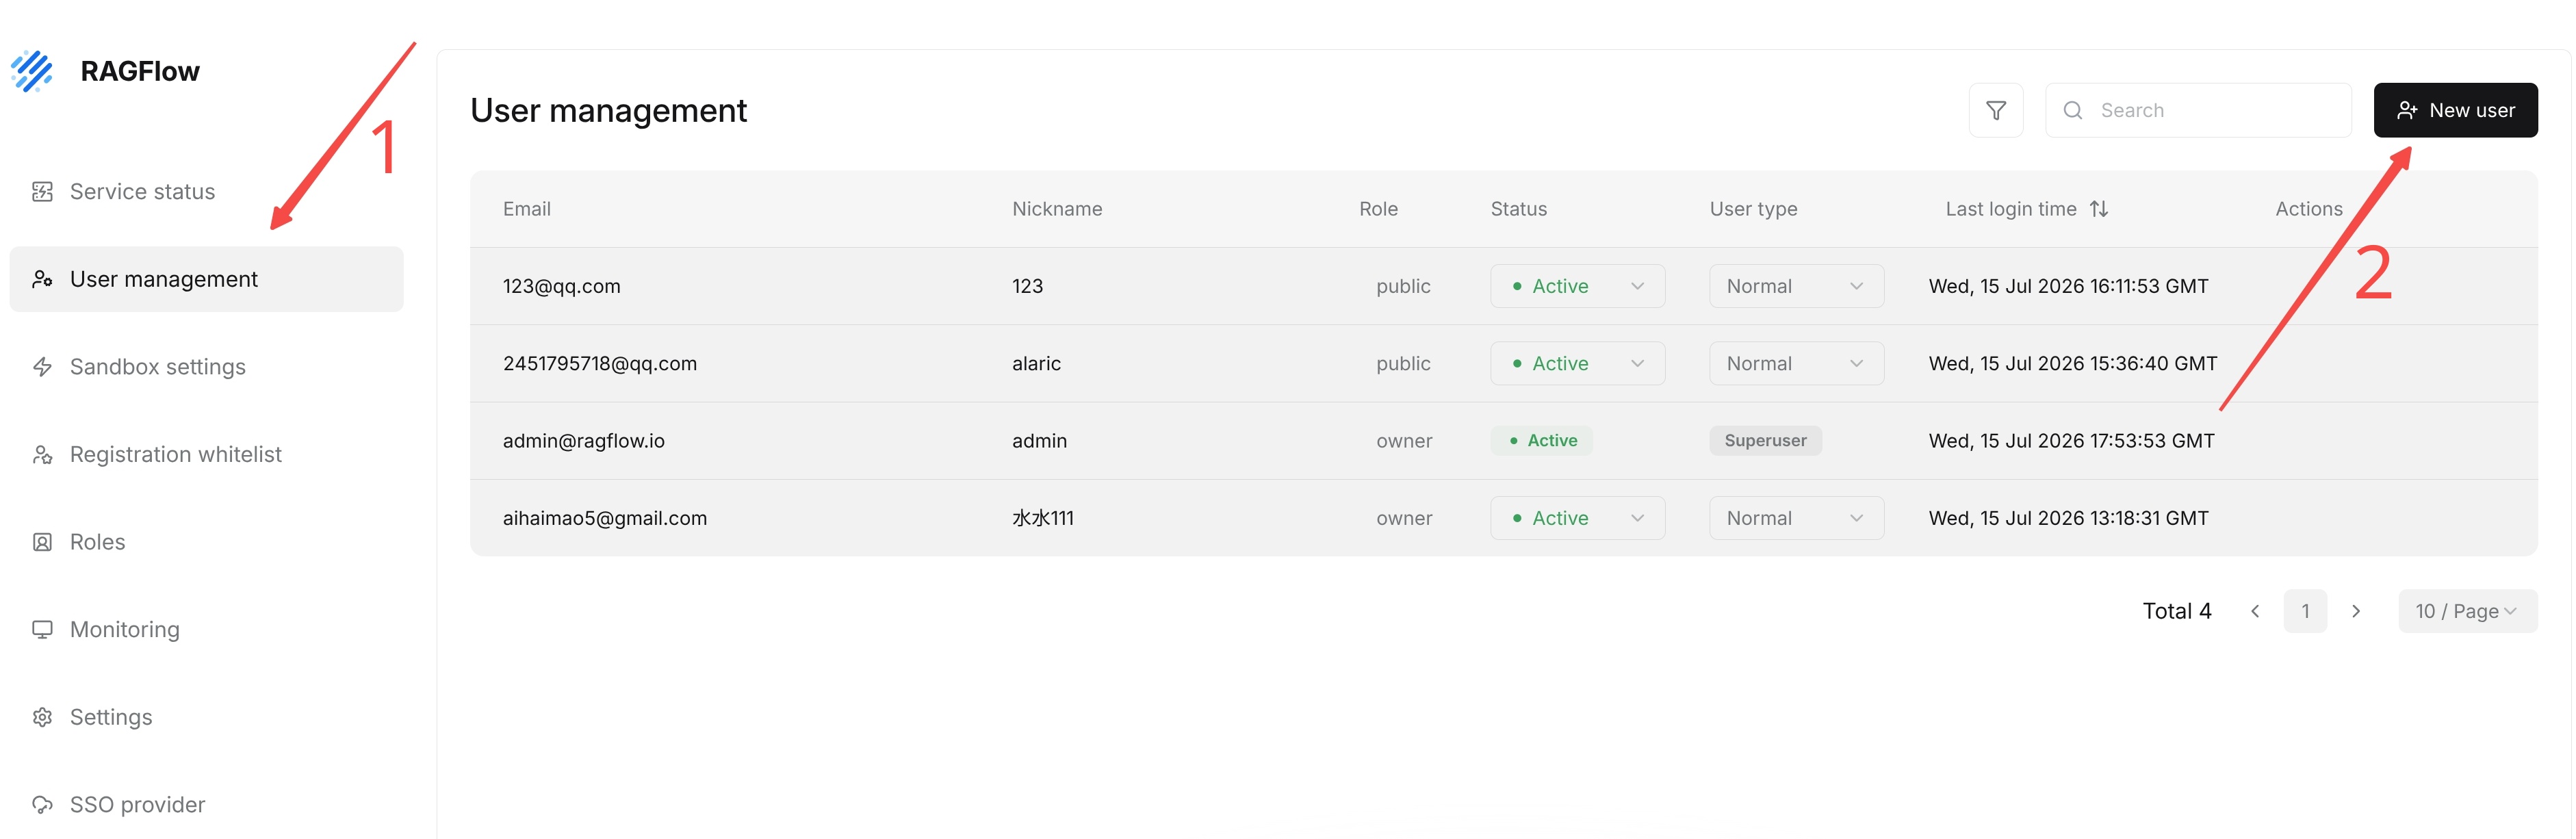+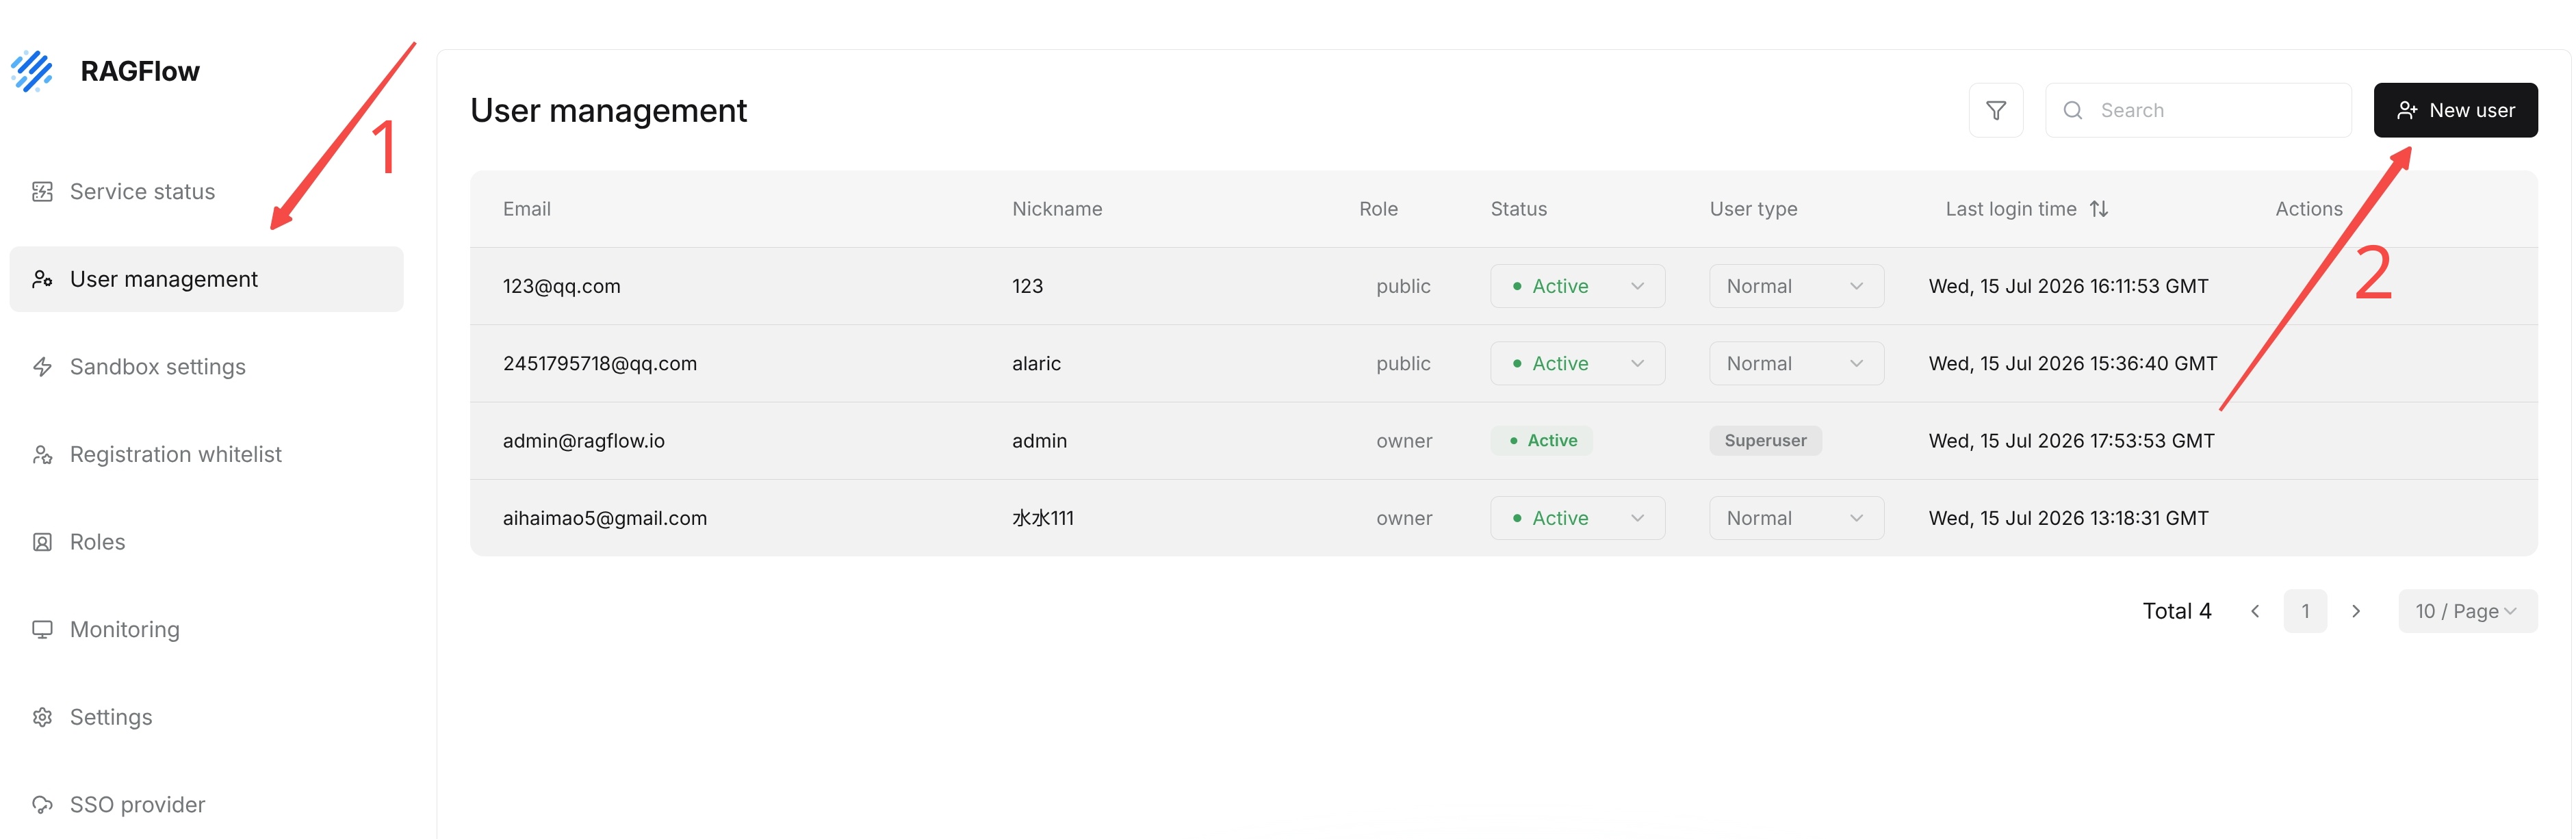-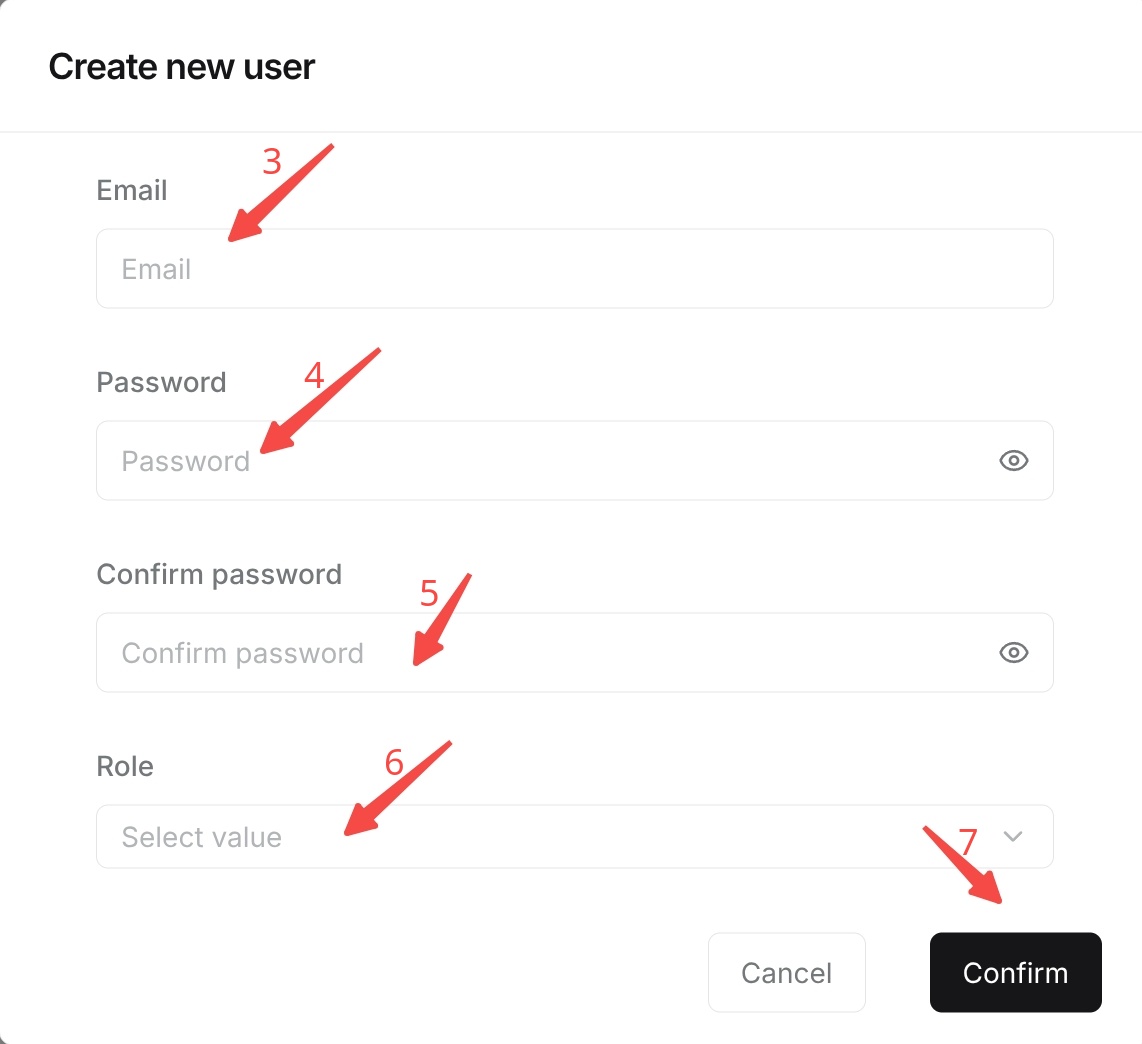+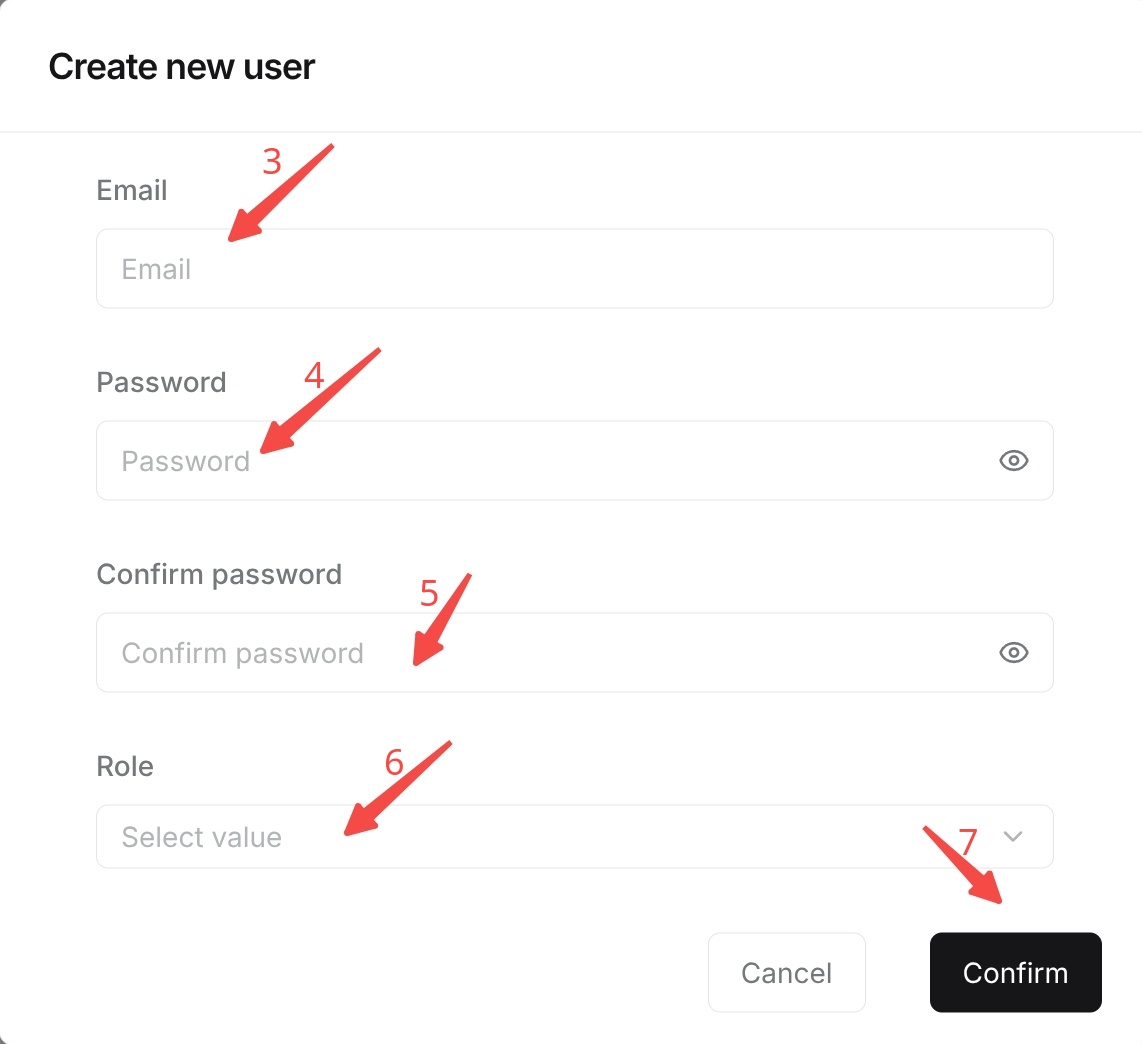-After creation, return to the user list and confirm that the account appears, and that its status and role match expectations. Then send the login information to the user through a secure channel.+After creation, return to the user list and confirm that the account appears and that its status matches expectations. Then send the login information to the user through a secure channel.**Caution:** `Email` must use a valid email format. After email verification is enabled, users must complete email verification before they can use the account normally. If email verification is not enabled, the system only validates the email format.-When creating a new user, the password and confirmation password must match. The frontend validation for the current create-user form requires at least 6 characters. Password reset requires a new password of at least 8 characters. In production environments, use a stronger unified password policy. In Enterprise Edition, `Role` affects the resources and operations a user can access, so confirm role permissions before creating the account.+When creating a new user, the password and confirmation password must match. The frontend validation for the current create-user form requires at least 6 characters. Password reset requires a new password of at least 8 characters. In production environments, use a stronger unified password policy.## Disable or Restore an Account@@ -55,7 +55,7 @@ The `Status` field in the user list controls whether an account can log in to th1. Go to the **User management** page and find the target user in the user list.2. In the `Status` column of that user's row, click the current status dropdown and select `Active` or `Inactive` as needed.-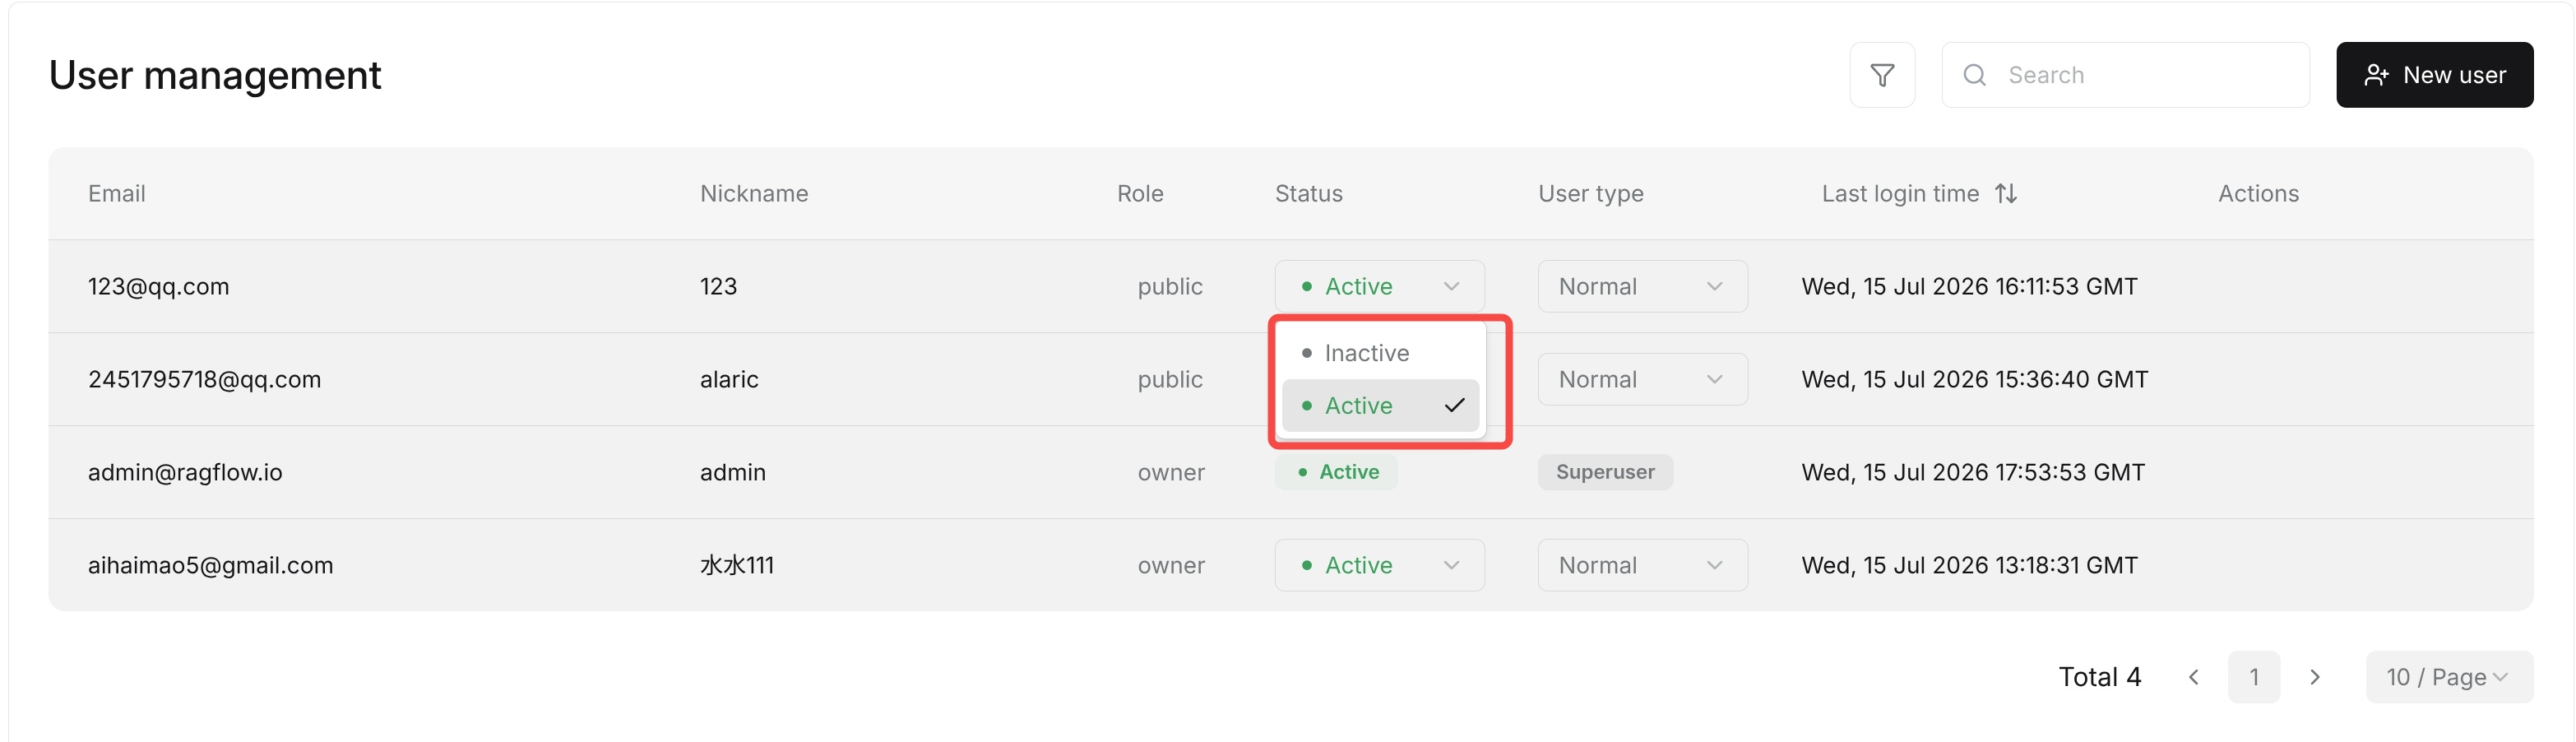+**Caution:** The currently logged-in administrator cannot disable their own account. Disabling an account does not delete user data; it only prevents the user from logging in. If you need to permanently remove a user, confirm that the account no longer needs to be retained before deleting it.@@ -68,7 +68,7 @@ The `Status` field in the user list controls whether an account can log in to th3. Select `Normal` or `Superuser`.4. Wait for the system to submit the change and refresh the user list.-+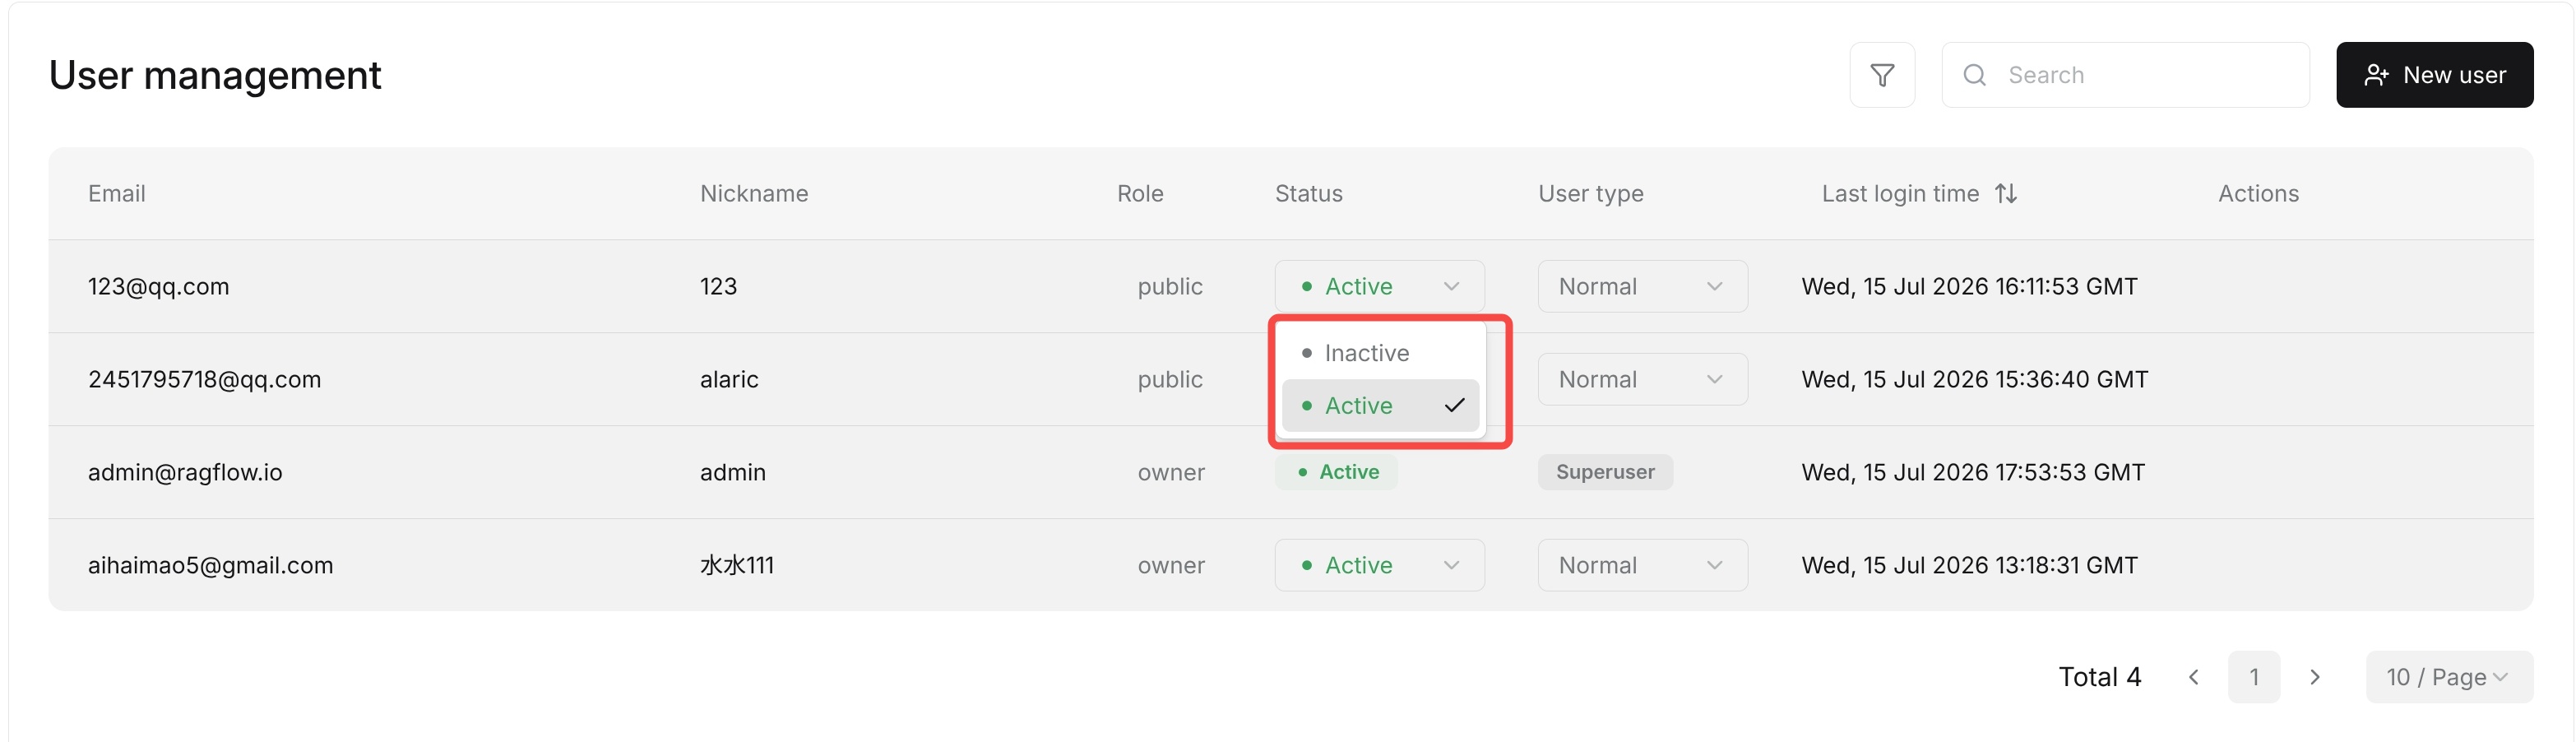**Caution:** The currently logged-in administrator cannot modify their own `Superuser` type in the list.@@ -81,9 +81,9 @@ When a user forgets their password or must be forced to change it, administrator3. Enter the new password and confirm it again.4. Click **Change password**.-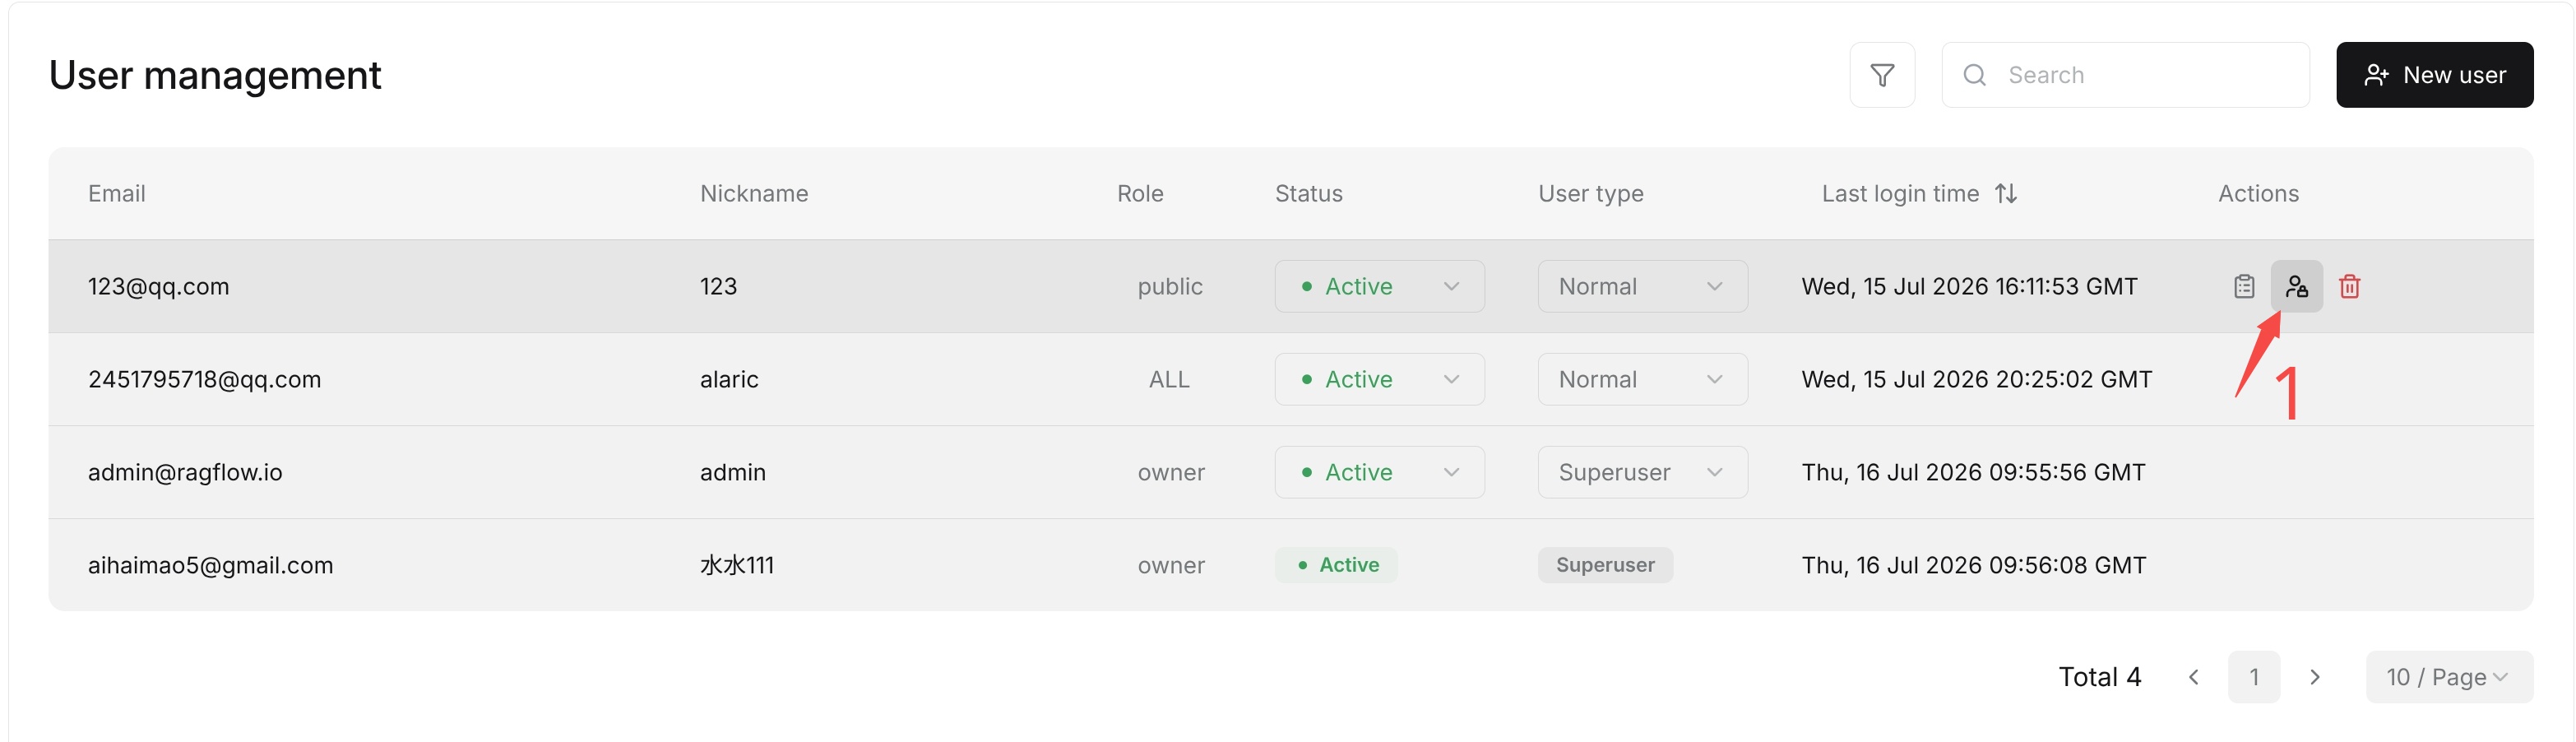+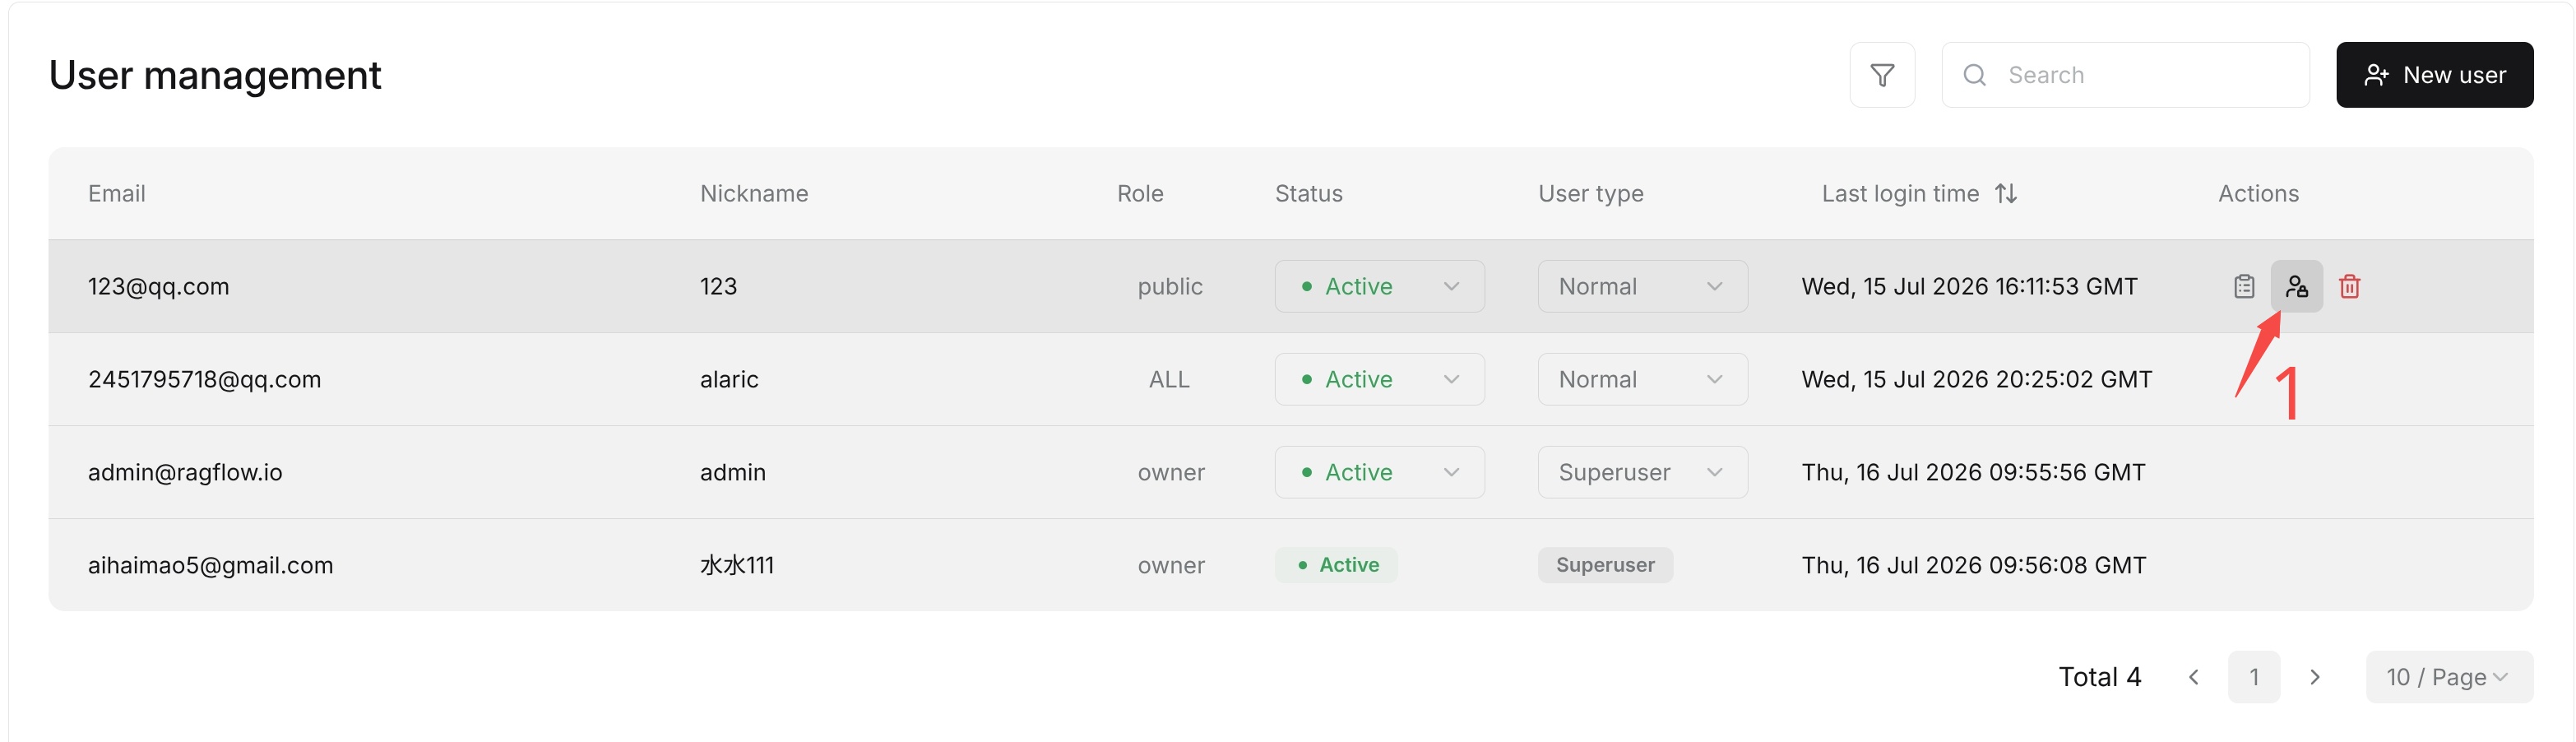-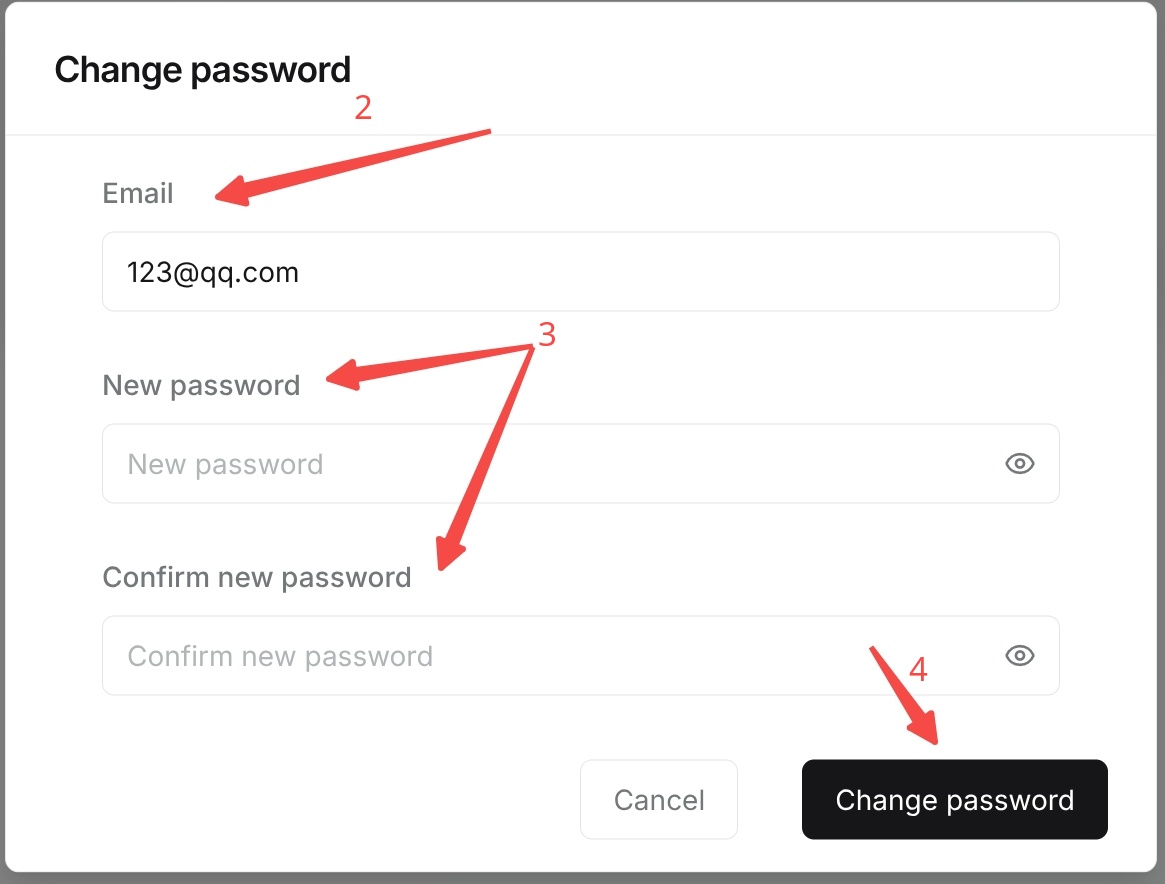+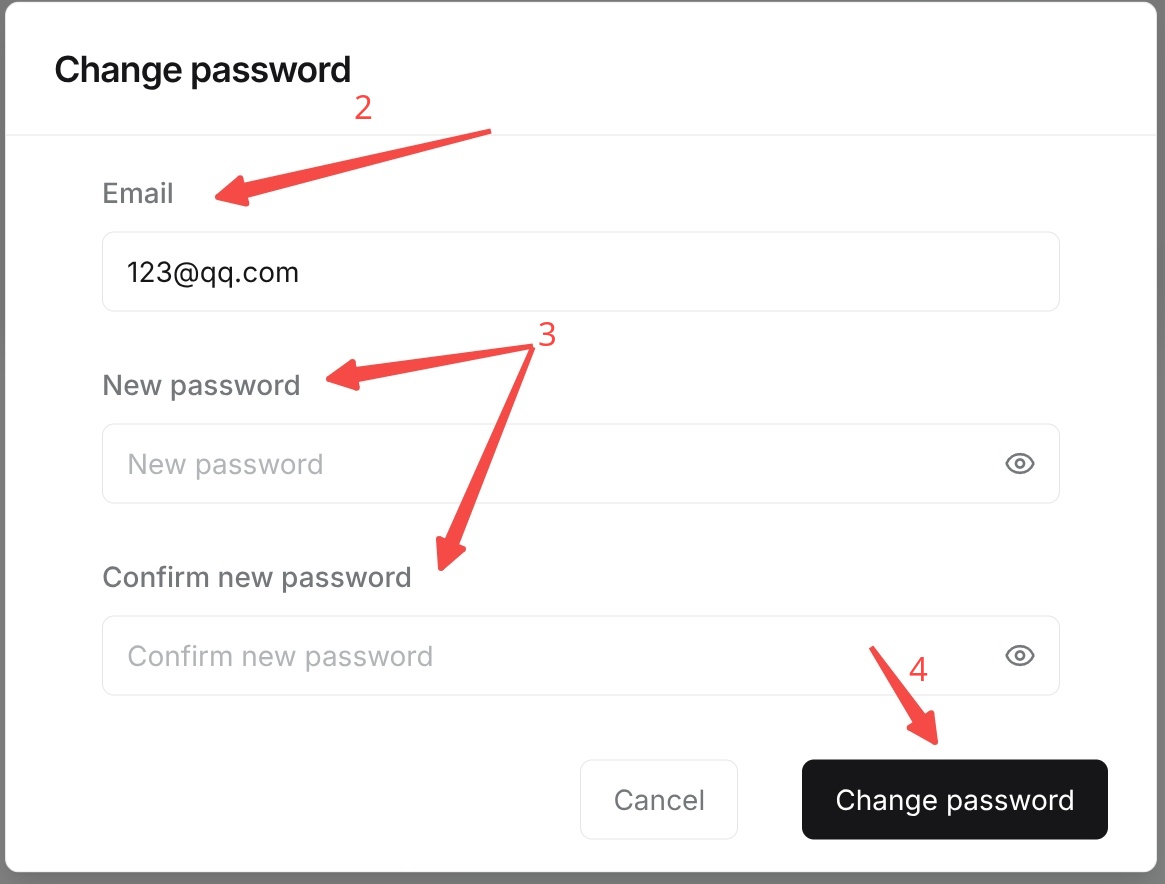**Caution:** The currently logged-in administrator cannot reset their own password through list **Actions**.@@ -95,7 +95,7 @@ When a user no longer needs system access and related resources have been handed2. Check the user's `Email` in the confirmation dialog.3. Click **Delete** to delete the user.-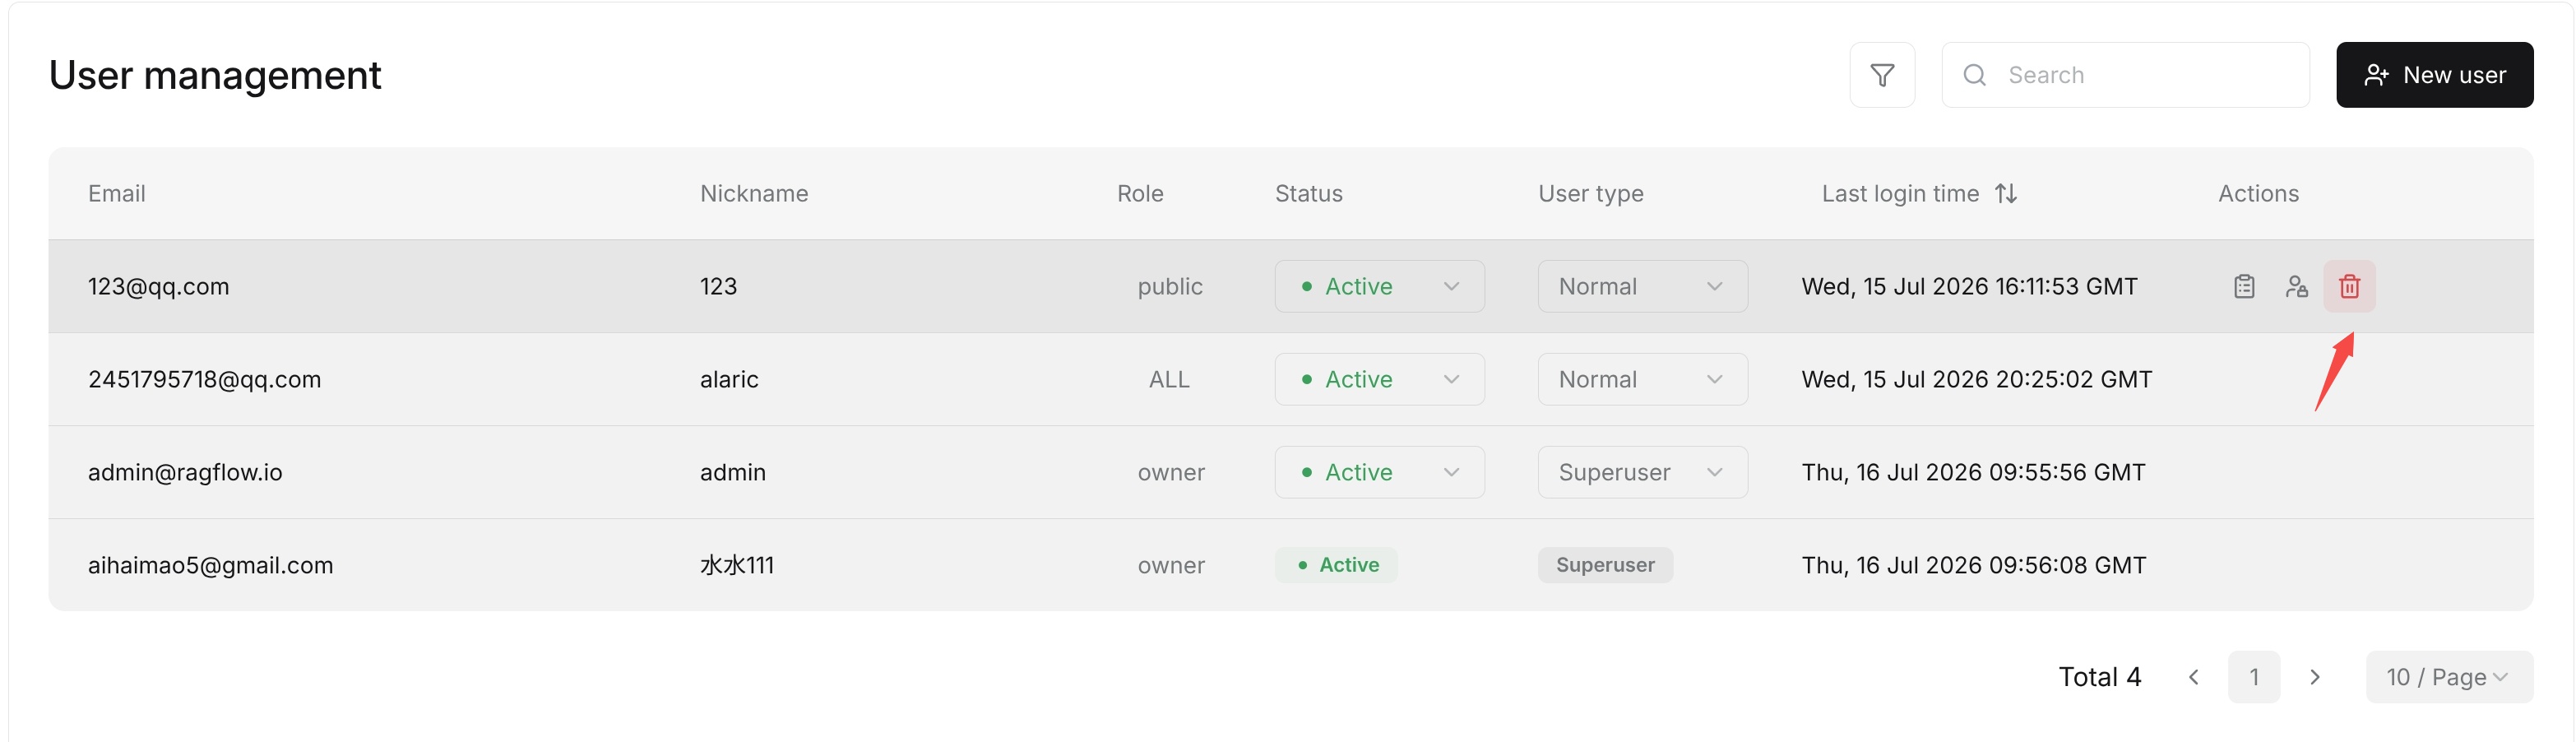+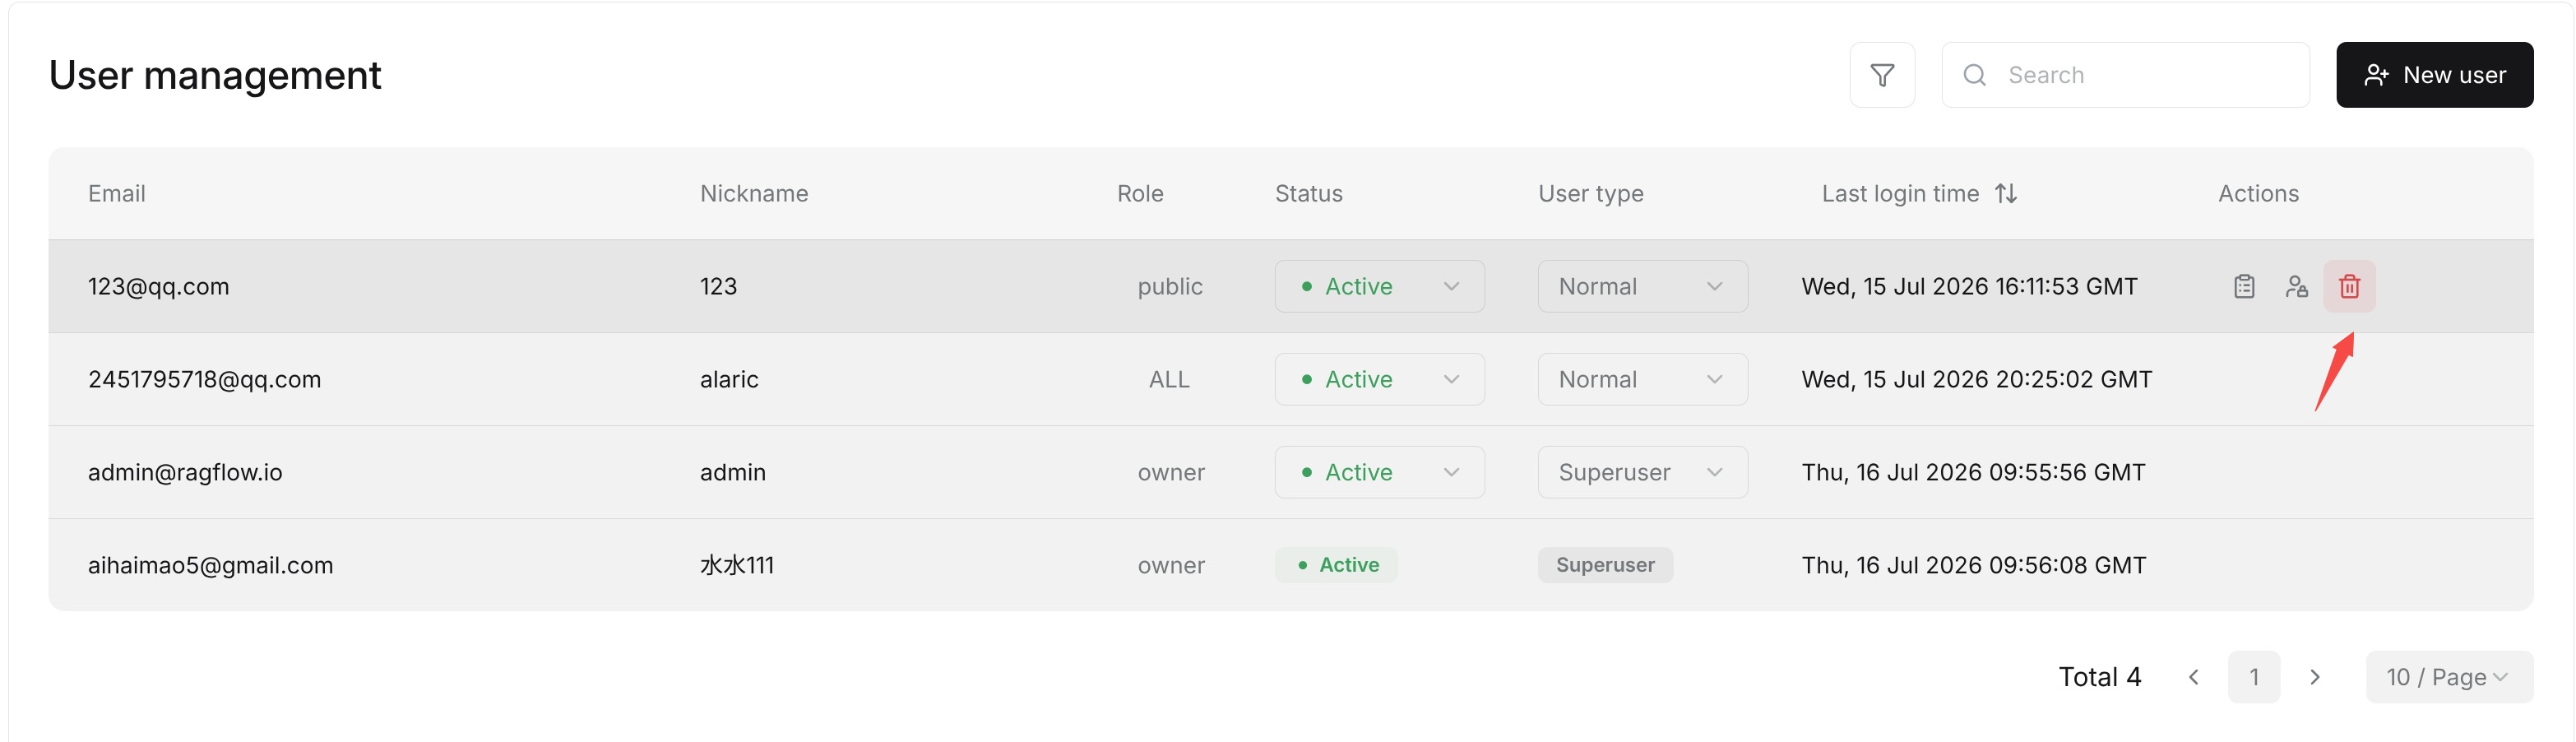**Caution:** The currently logged-in administrator cannot delete their own account through list **Actions**.@@ -103,8 +103,8 @@ Deleting a user is a high-risk operation. Before doing it, confirm whether the u## View User Details and Resource Impact-Click the detail button in **Actions** on the user list to enter the user detail page. The detail page displays the user's `Email`, account status, Enterprise Edition role, `Last login time`, `Create time`, `Last update time`, `Language`, `Is anonymous`, and `Is superuser`.+Click the detail button in **Actions** on the user list to enter the user detail page. The detail page displays the user's `Email`, account status, `Last login time`, `Create time`, `Last update time`, `Language`, `Is anonymous`, and `Is superuser`.-The current Enterprise Edition detail page also displays the user's associated `Dataset` and `Agent` resources by resource type. Before disabling, deleting, downgrading `Superuser`, or adjusting an Enterprise Edition role, administrators should check the detail page to confirm whether the user still has important resources or recent login activity.+**Caution:** Before disabling, deleting, or downgrading `Superuser`, administrators should check the detail page to confirm whether the user still has important resources or recent login activity.-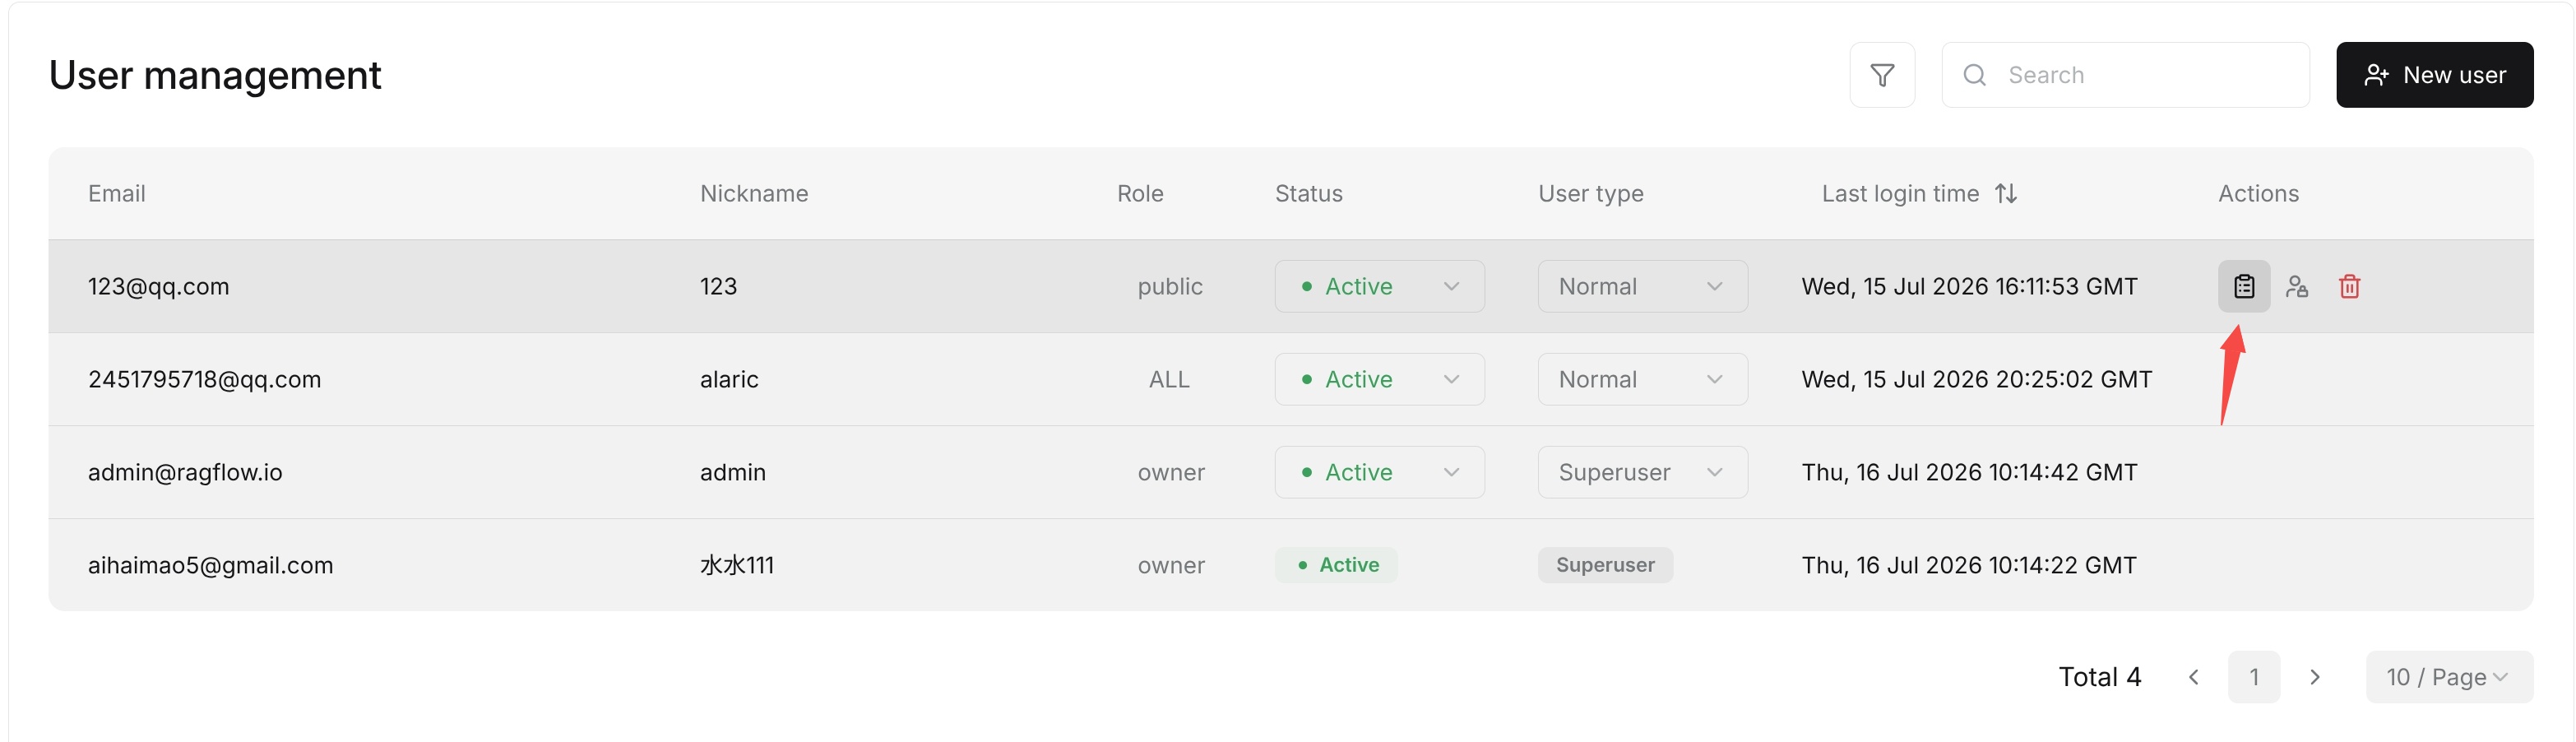+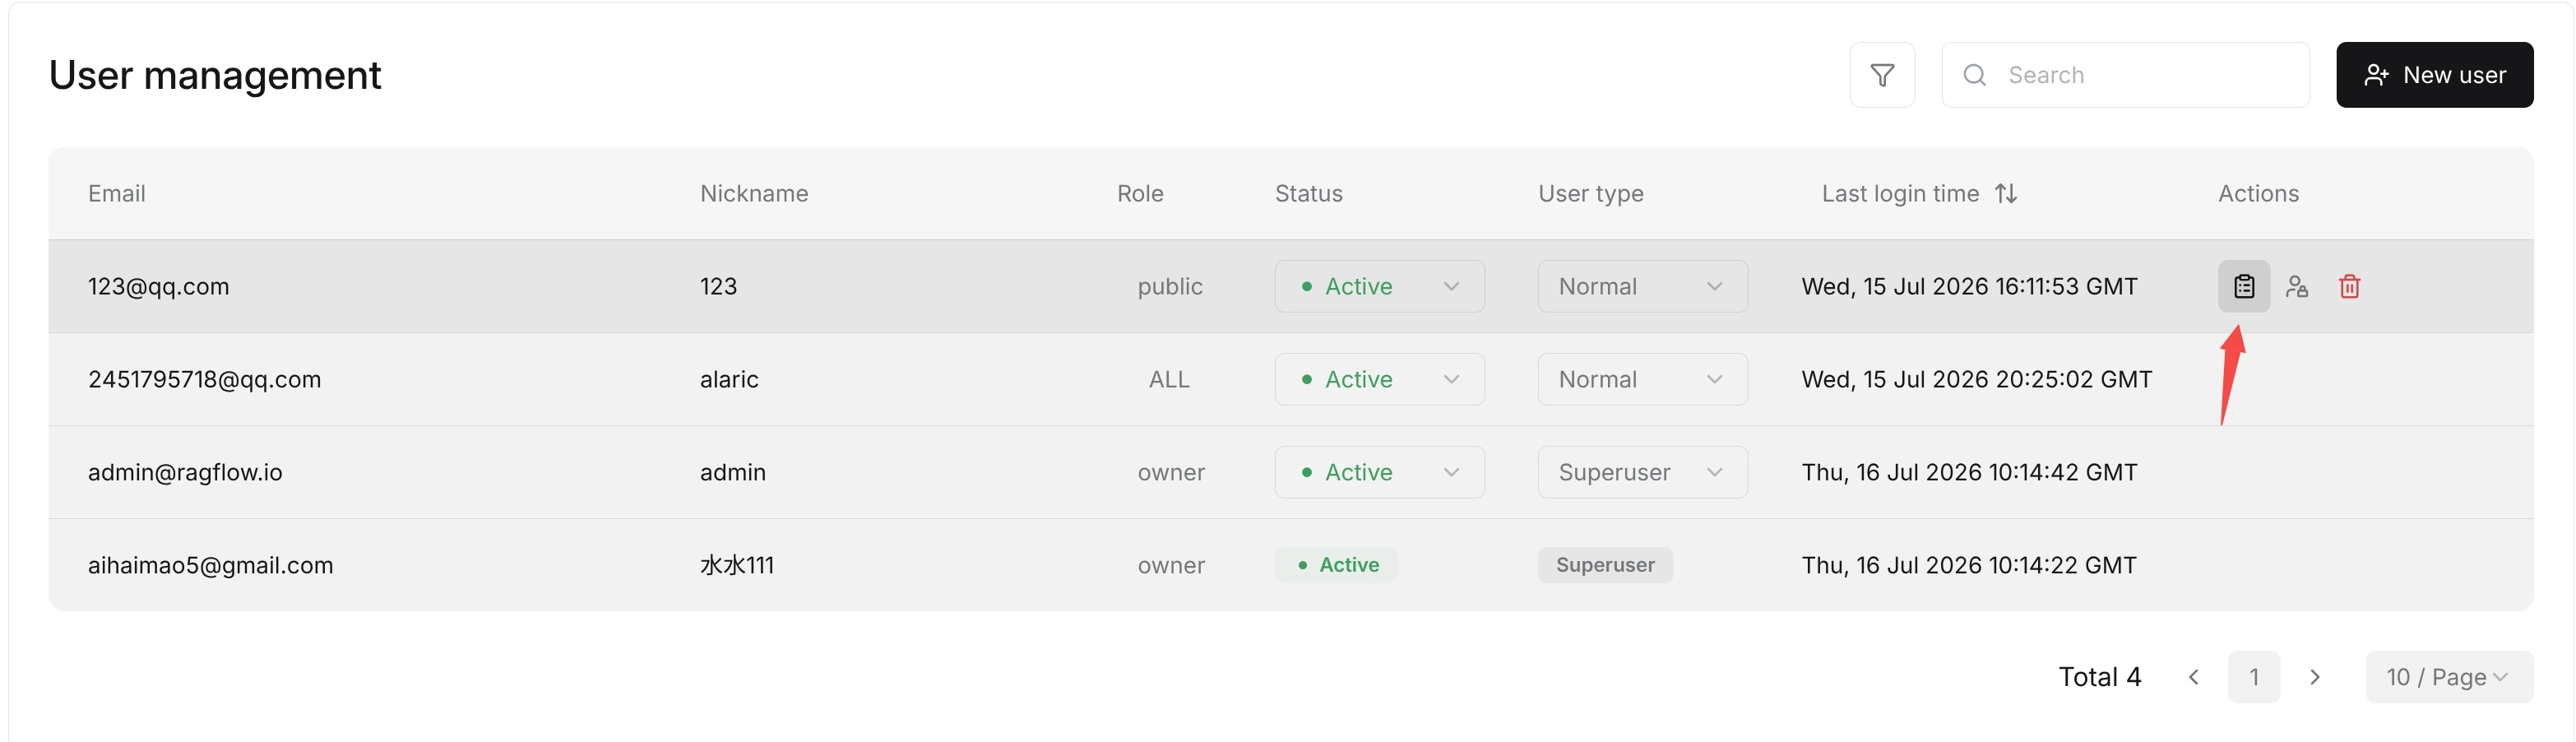diff --git a/docs/administrator/admin/admin_ui/view_monitoring_dashboard_enterprise.md b/docs/administrator/admin/admin_ui/view_monitoring_dashboard_enterprise.mddeleted file mode 100644index 76d911b5cb..0000000000--- a/docs/administrator/admin/admin_ui/view_monitoring_dashboard_enterprise.md+++ /dev/null@@ -1,68 +0,0 @@-----sidebar_position: 8-sidebar_label: "View Monitoring Dashboard (Enterprise Edition)"------# View Monitoring Dashboard (Enterprise Edition)--## Use Monitoring to View System Monitoring--Enterprise Edition provides a **Monitoring** page in the Admin UI for viewing system monitoring data and alert status. Administrators can query metrics, view alert rules, check target collection status, and view Prometheus runtime information on this page.--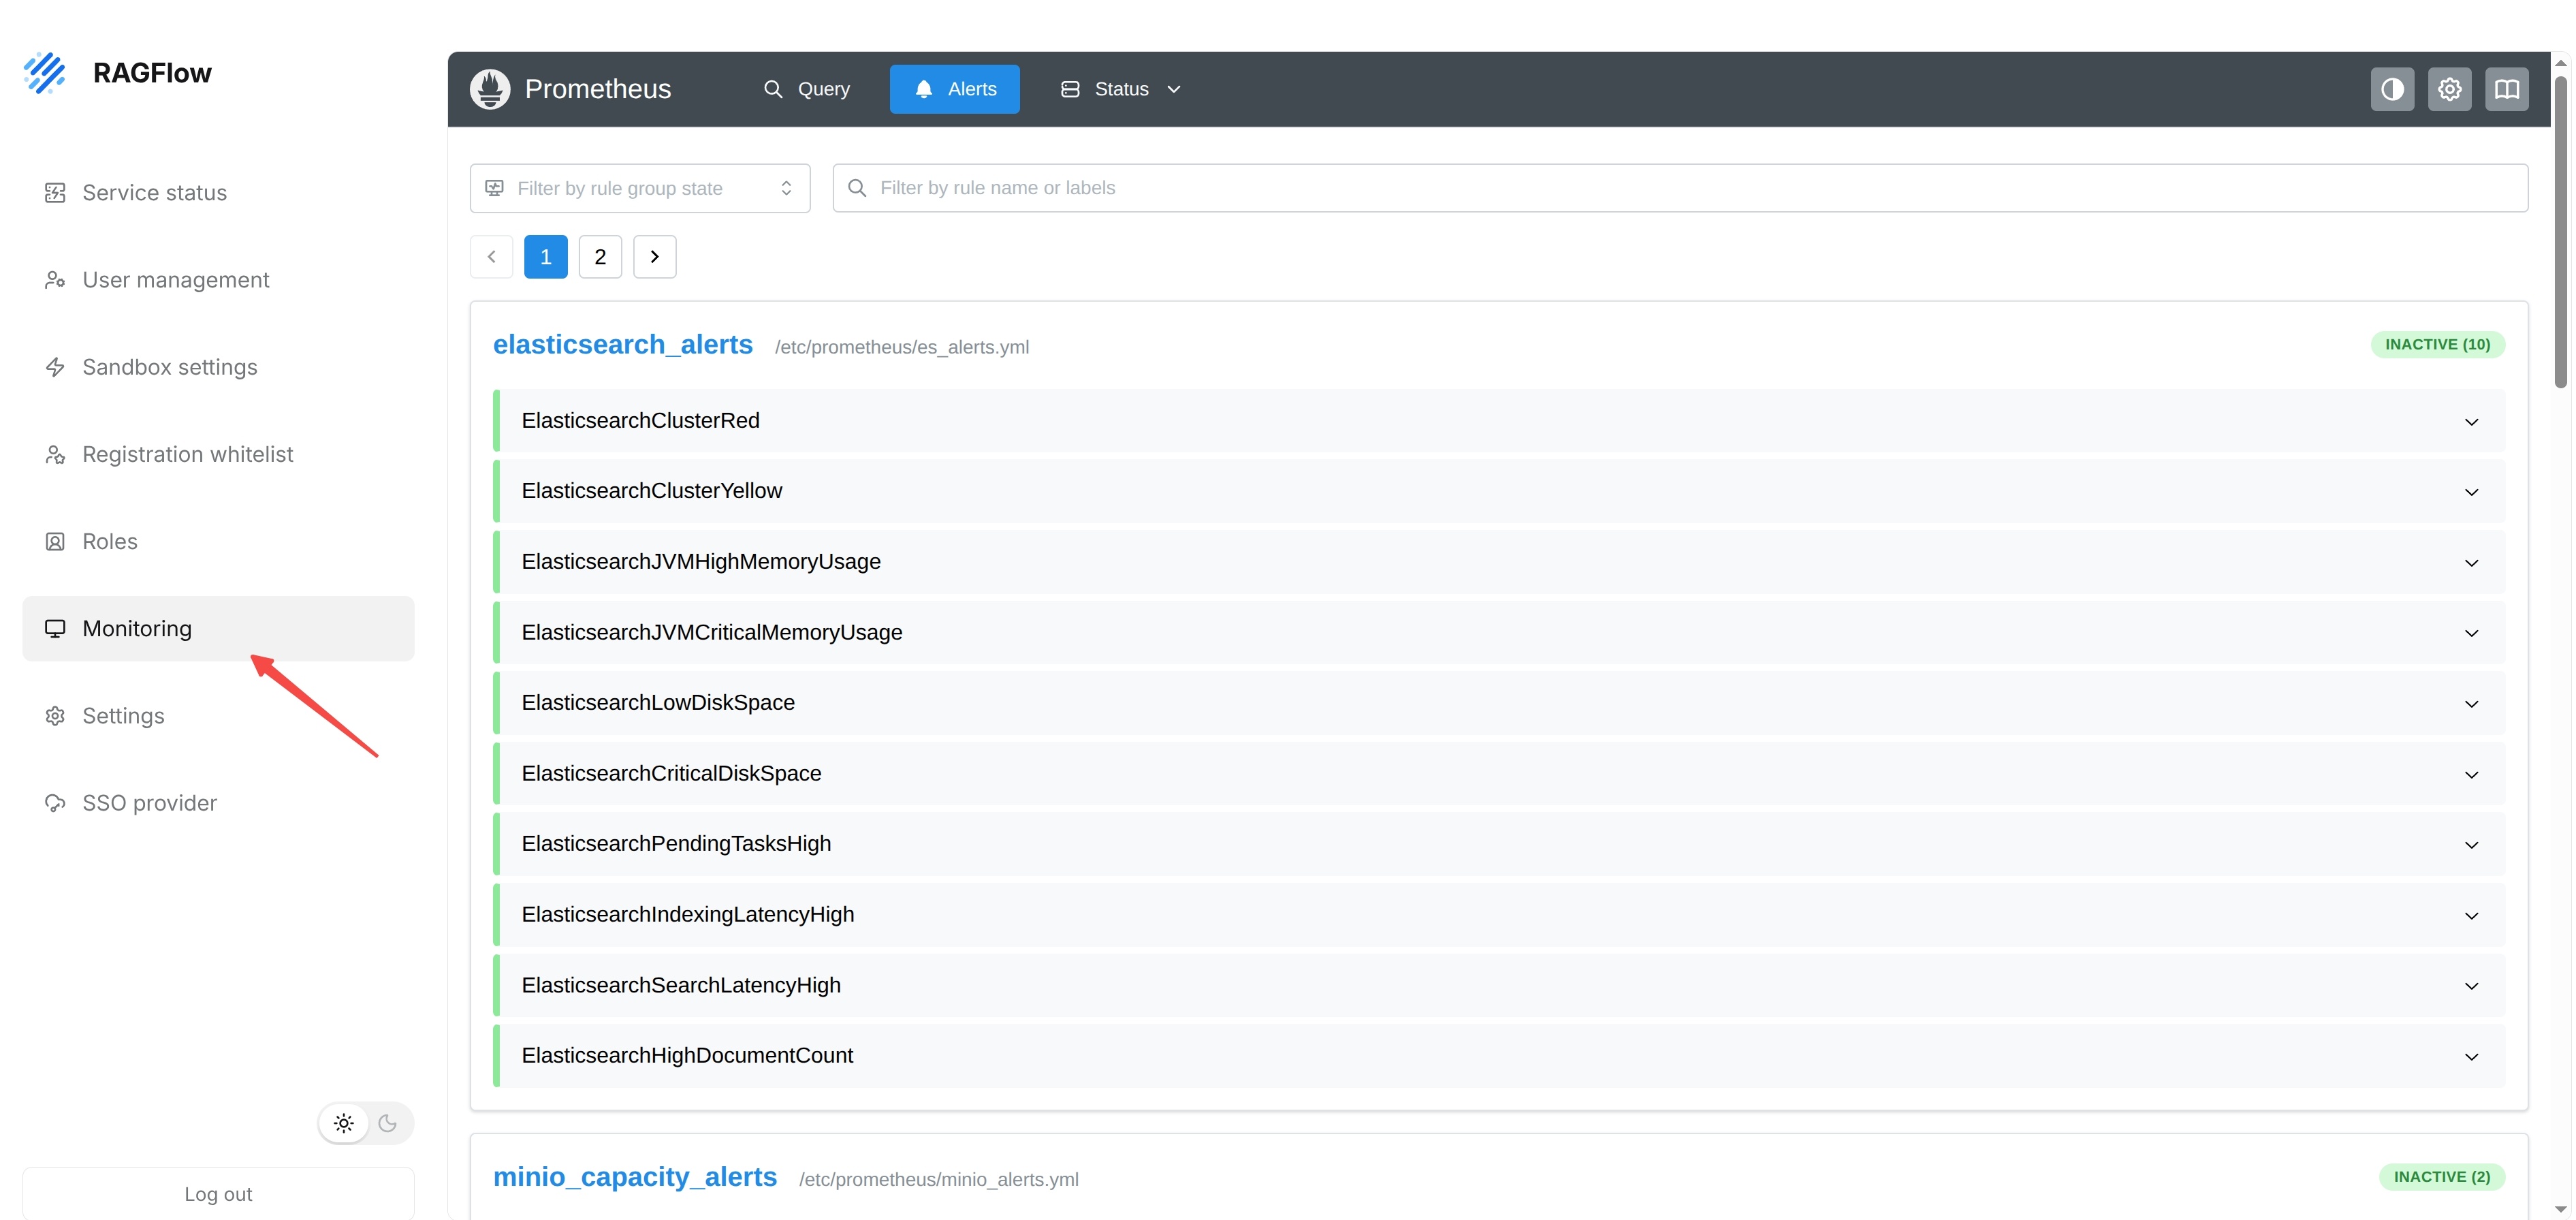--## Query Monitoring Metrics--Select **Query** at the top of the **Monitoring** page to enter the metric query page. The page provides an expression input box. Administrators can enter a Prometheus query expression and click **Execute**.--Query results can be viewed through **Table**, **Graph**, and **Explain**:--| View | Description |-| --- | --- |-| `Table` | View query results in table form. |-| `Graph` | View trend charts. |-| `Explain` | View an explanation of the query expression. |--The page also provides `Evaluation time`, which is used to view or adjust the query evaluation time. To query multiple expressions at the same time, click **Add query** to add a new query area.--1. Go to the **Monitoring** page.-2. Select **Query**.-3. Enter the query expression in the input box.-4. Click **Execute**.-5. Switch between **Table**, **Graph**, and **Explain** as needed to view results.-6. To add query conditions, click **Add query**.--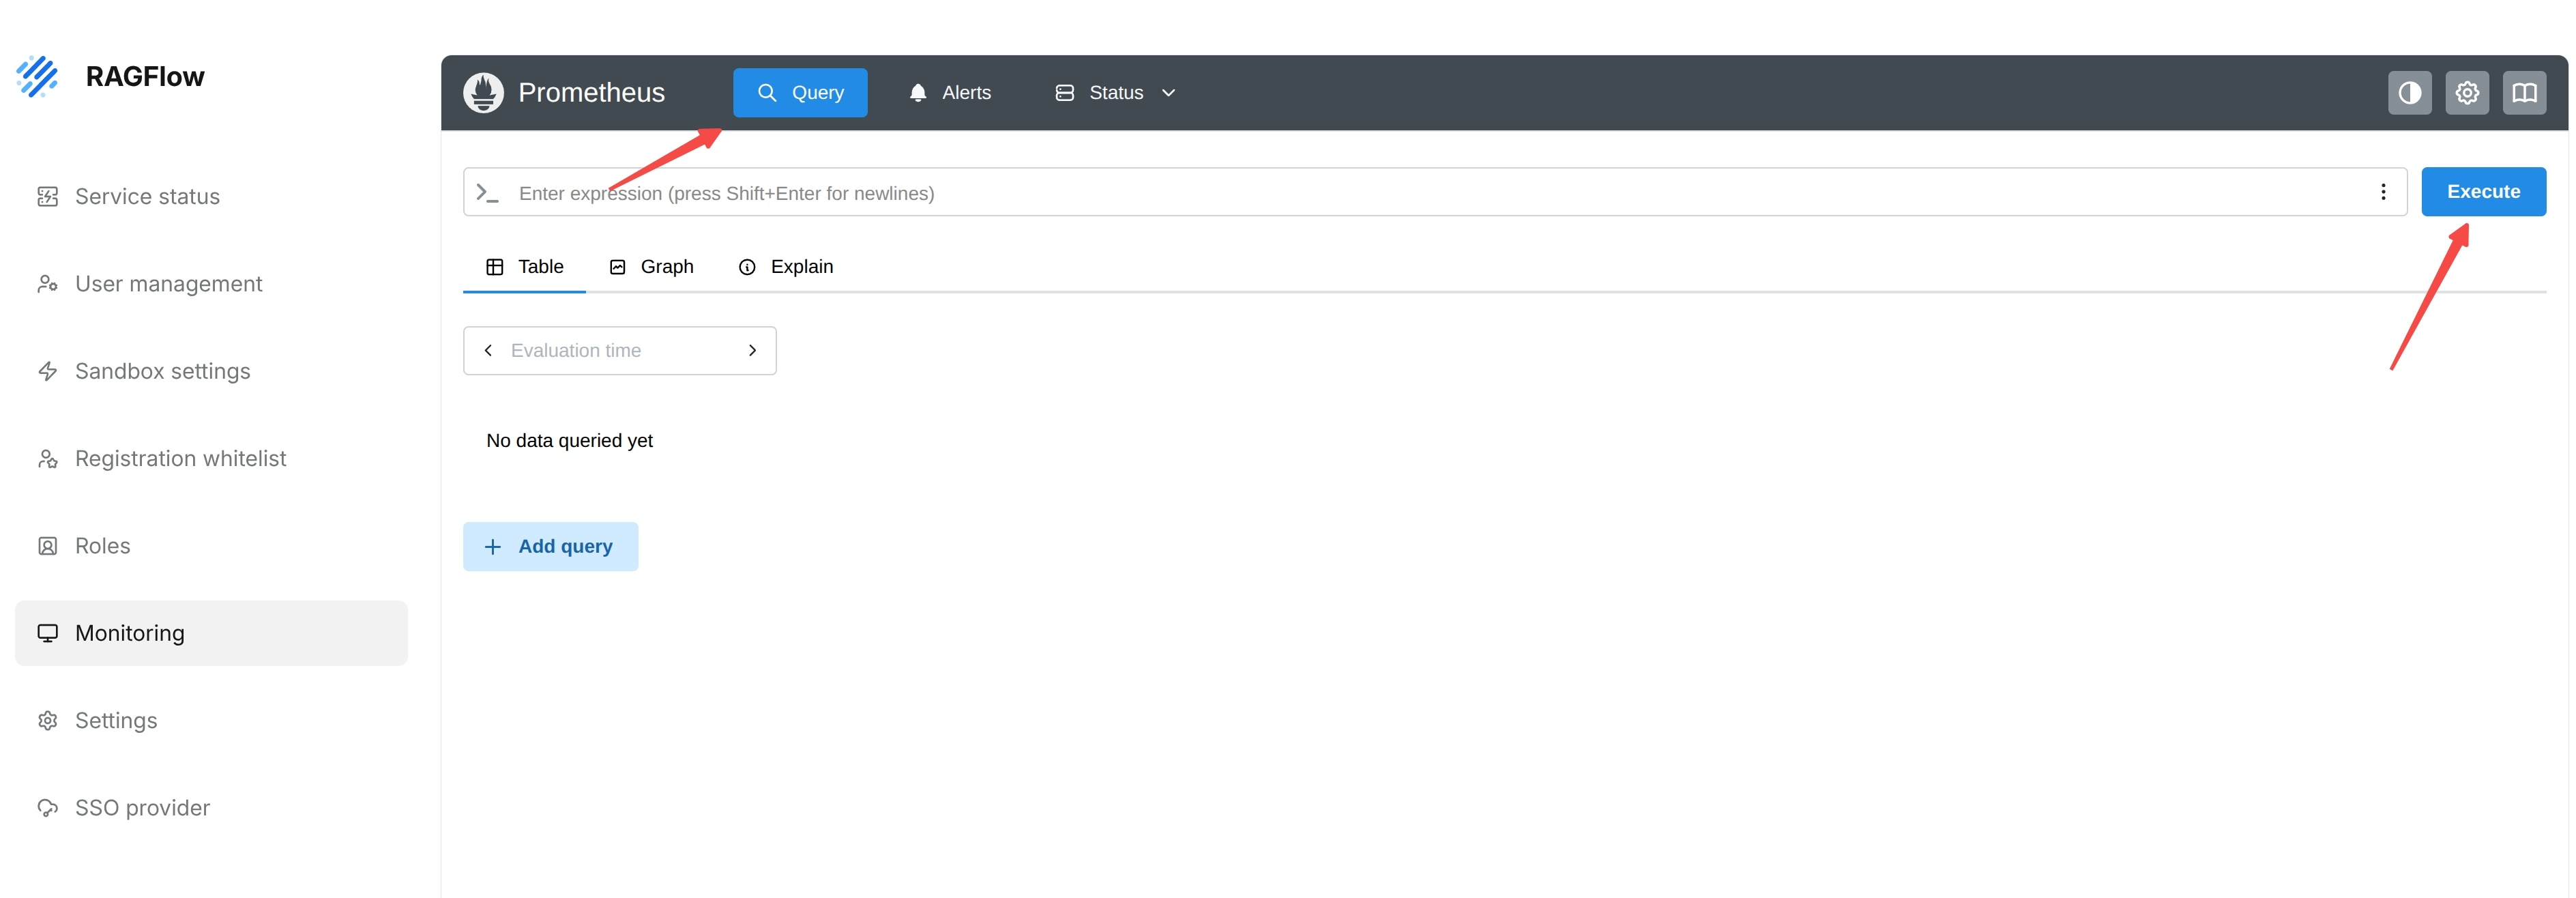--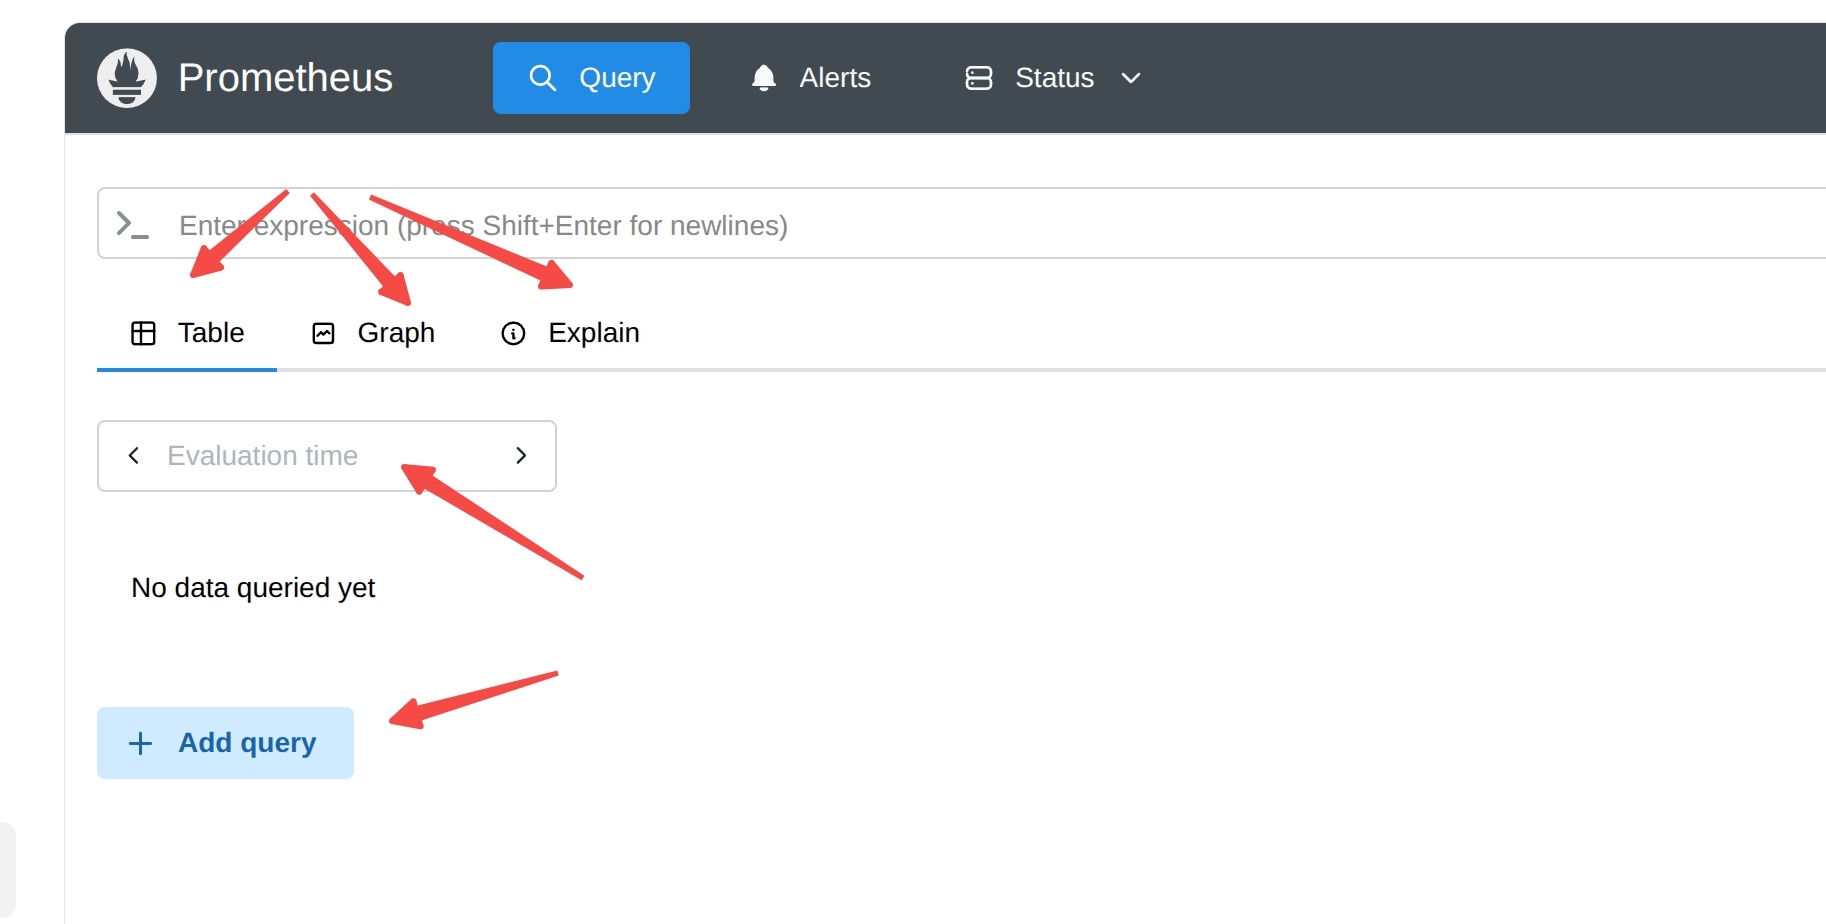--**Note:** The **Query** page is used to query monitoring metrics, not to modify business data. Query expressions must comply with Prometheus query rules. Complex queries may bring computing overhead, so avoid frequently running high-cost queries in production environments.--## View Alert Rules and Alert Status--Select **Alerts** to view alert rules currently configured in Prometheus. The page supports filtering alert groups by `rule group state` and searching rules by `rule name` or `labels`.--The alerts page displays content by rule group. Each rule group shows the rule group name, rule file path, and current status statistics, such as `INACTIVE` or `FIRING`. Administrators can expand a specific rule to check whether it is currently triggered.--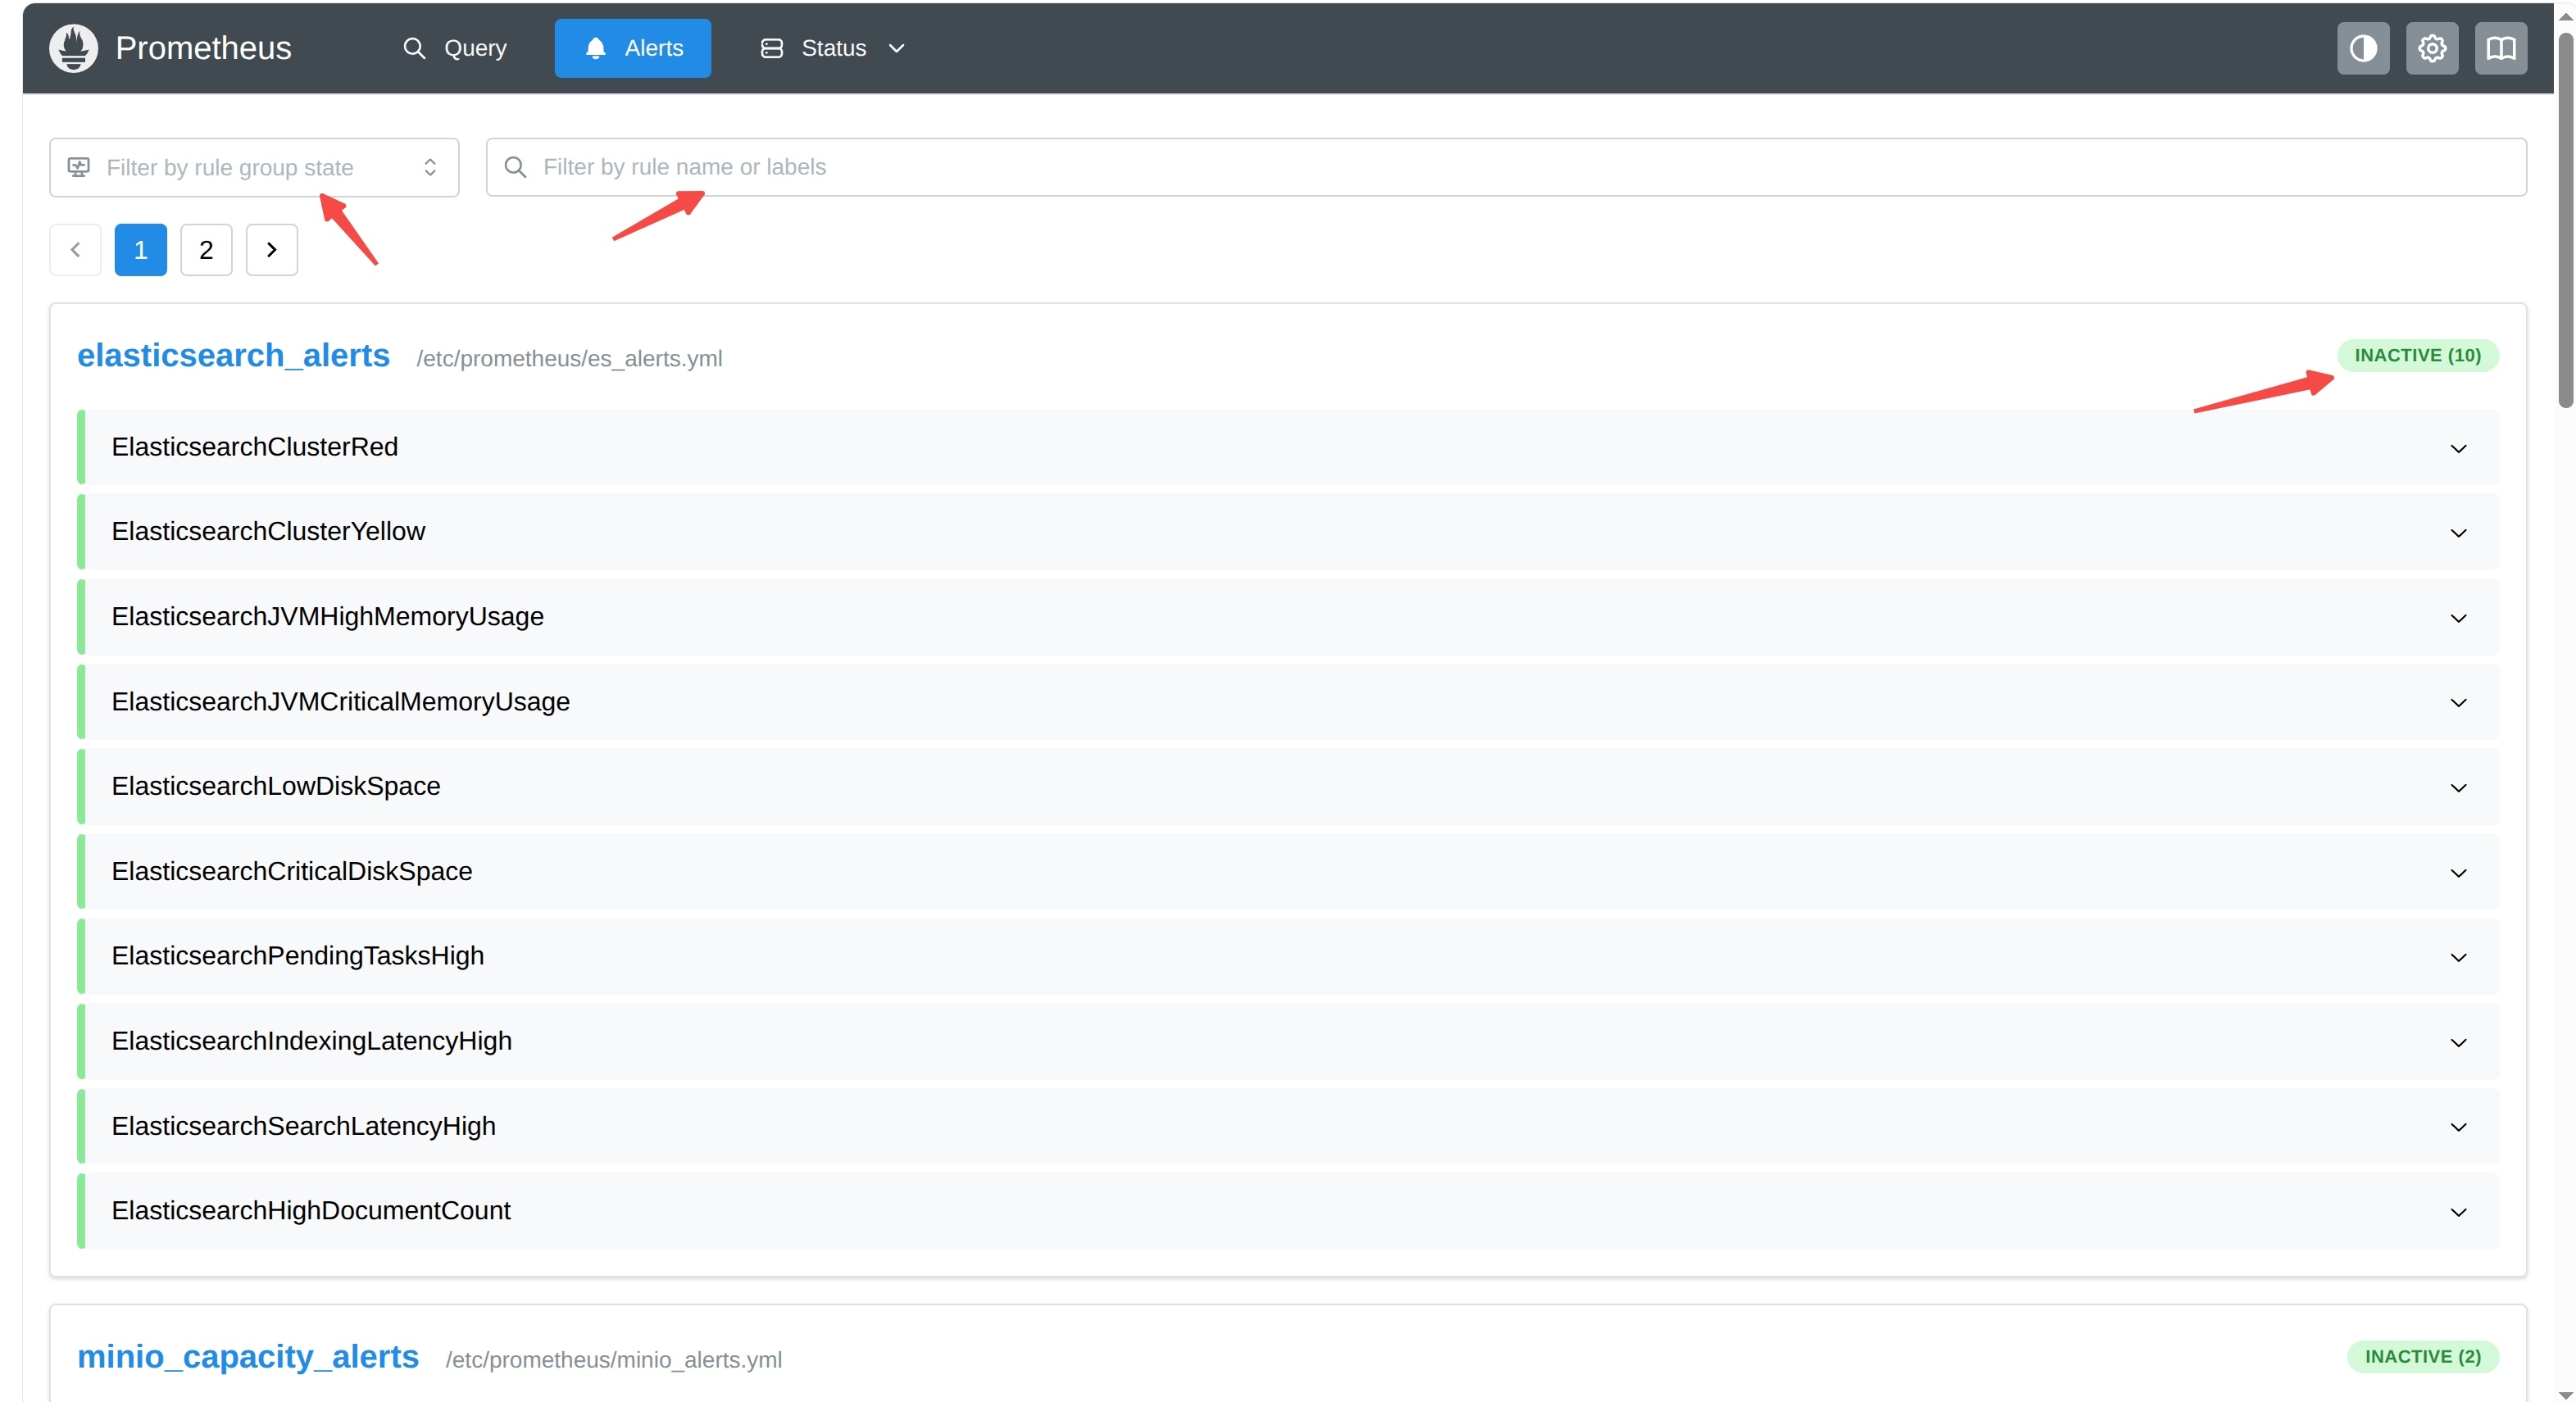--**Note:** The **Alerts** page displays alert rules loaded by Prometheus in the current deployment. `INACTIVE` means the rule is not currently triggered. `FIRING` means the rule is currently triggered, and administrators need to further troubleshoot with service status, logs, and the deployment environment. Query expressions must comply with Prometheus query rules. Complex queries may bring computing overhead, so avoid frequently running high-cost queries in production environments.--## View Prometheus Monitoring Status--Prometheus provides rich status pages. Administrators can use the **Status** menu to view collection targets, service discovery, rule execution, the time-series database, system configuration, and runtime status. This helps quickly confirm whether the monitoring service is running normally and assists in locating monitoring configuration or collection exceptions.--| Menu | Function | Main content | Administrator use | Notes |-| --- | --- | --- | --- | --- |-| `Target health` | View the health status of Prometheus collection targets. | Displays collection targets by `Job`, including `Endpoint`, `Labels`, `Last Scrape`, `State`, and other information. `State` is `UP` when target collection is normal. | Confirm whether Elasticsearch, MySQL, Redis, MinIO, RabbitMQ, Prometheus, and other components can be monitored normally. | `Target Health` only indicates metric collection status and does not fully represent business service status. If the status is `DOWN`, check the exporter, network connectivity, scrape address, and Prometheus configuration. |-| `Rule health` | View the runtime status of alerting rules and recording rules. | Displays rule groups, rule files, recent execution time (`Last Run`), execution duration (`Took`), execution period (`Every`), and rule status. | Confirm whether rules run at the expected interval and troubleshoot rule exceptions or invalid rules. | `OK` means the latest rule evaluation succeeded. |-| `Service discovery` | View Prometheus service discovery results. | Displays each job's `Discovered Labels` and `Target Labels`, and supports viewing the relabeling process. | Troubleshoot abnormal target discovery, incorrect label configuration, or abnormal metric classification. | When a new monitoring target does not take effect, check this page first. |-| `Runtime & build information` | View Prometheus runtime environment and build information. | Includes `Version`, `Build Date`, `Go Version`, `Start Time`, `Hostname`, `Storage Retention`, `Configuration Reload`, and other information. | Confirm the current runtime version, startup time, configuration loading status, and storage retention policy. | Commonly used to troubleshoot Prometheus service runtime status. |-| `TSDB status` | View the runtime status of the Prometheus time-series database (TSDB). | Includes `Series`, `Chunks`, `Label Pairs`, time range, labels, metrics, memory usage, and other statistics. | View monitoring data scale, storage status, and database runtime status. | The page provides operations such as `Delete Series` and `Clean Tombstones`. It is recommended only for status viewing. Do not execute delete or cleanup operations casually, or historical monitoring data may be lost. |-| `Command-line flags` | View the current Prometheus startup parameters. | Displays the configuration file path, listen address, storage path, retention time, query parameters, and other startup parameters. | Check whether the actual Prometheus startup parameters match deployment expectations. | Suitable for troubleshooting configuration file paths, data directories, listen ports, and similar issues. |-| `Configuration` | View the currently loaded Prometheus configuration. | Includes complete configuration content such as `global`, `scrape_configs`, `rule_files`, and `alerting`. | Confirm whether scrape jobs, scrape intervals, alert rules, and scrape configurations have been loaded correctly. | This page is for viewing only and does not support online modification. Reload or restart Prometheus after modifying the configuration. |-| `Alertmanager discovery` | View Alertmanager instances discovered by Prometheus. | Displays Alertmanager service addresses and connection status. | Confirm whether Prometheus has successfully connected to Alertmanager. | If Alertmanager is not configured, this page may be empty. |--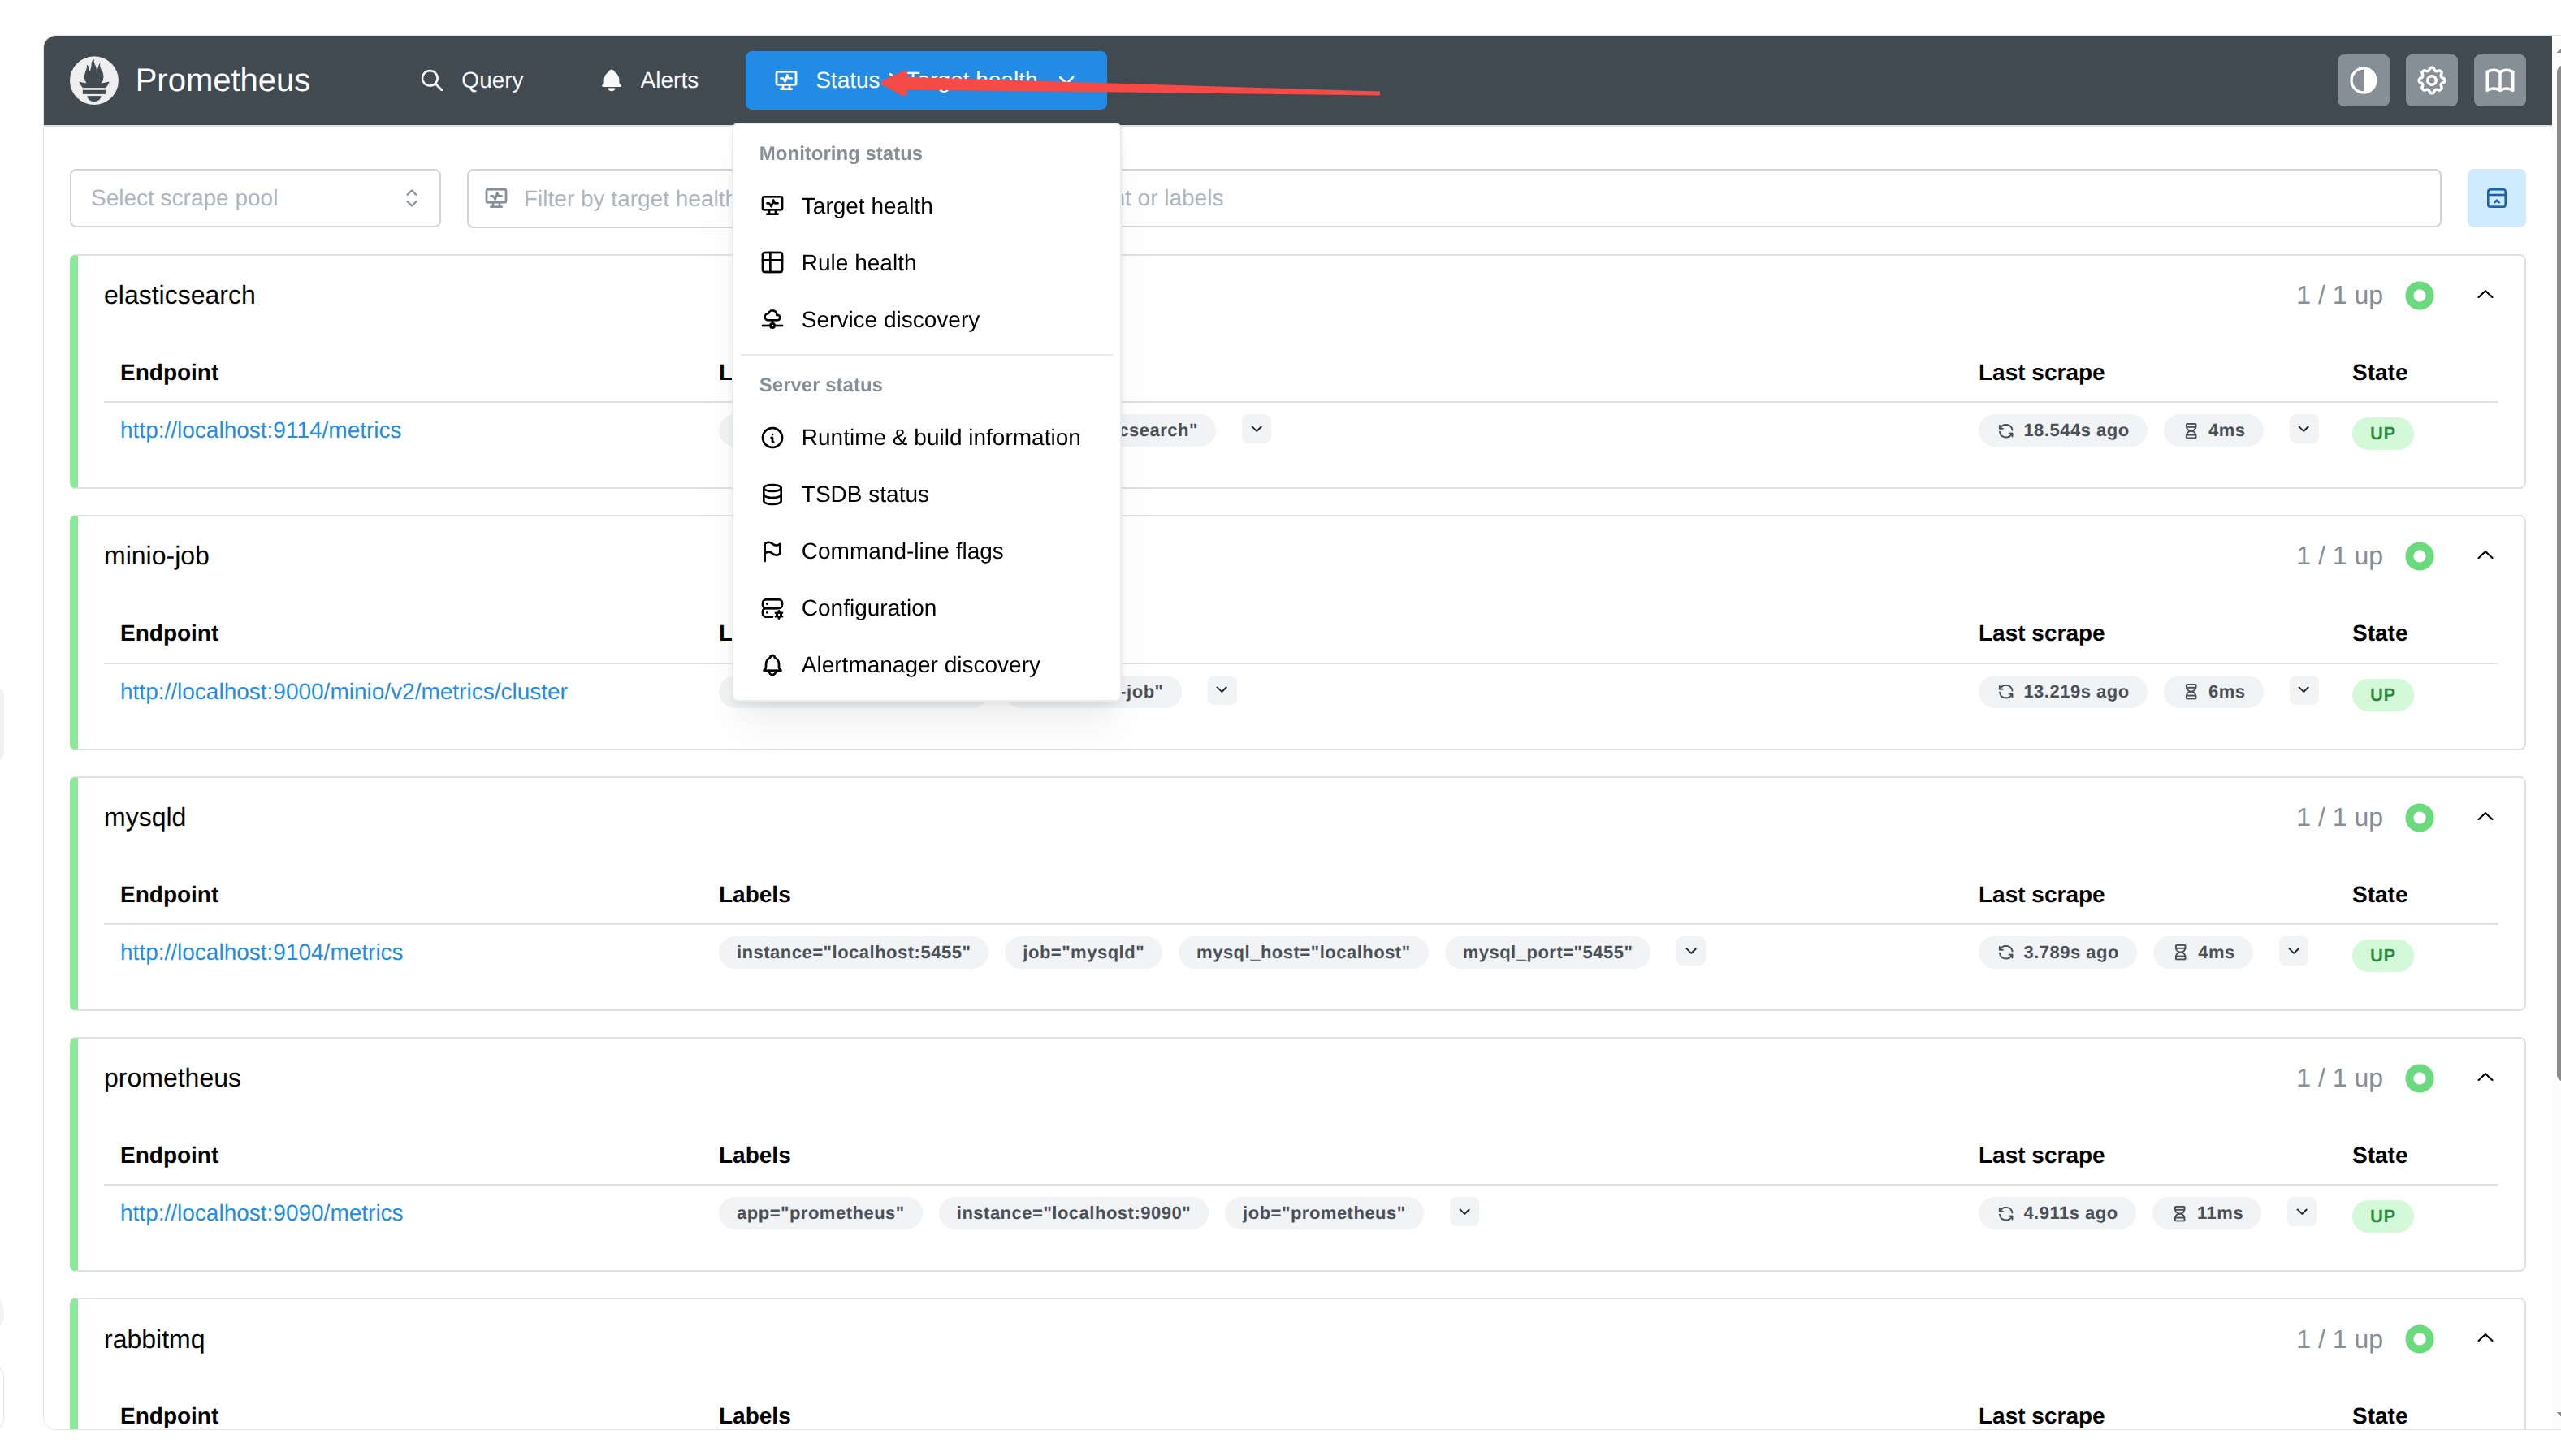--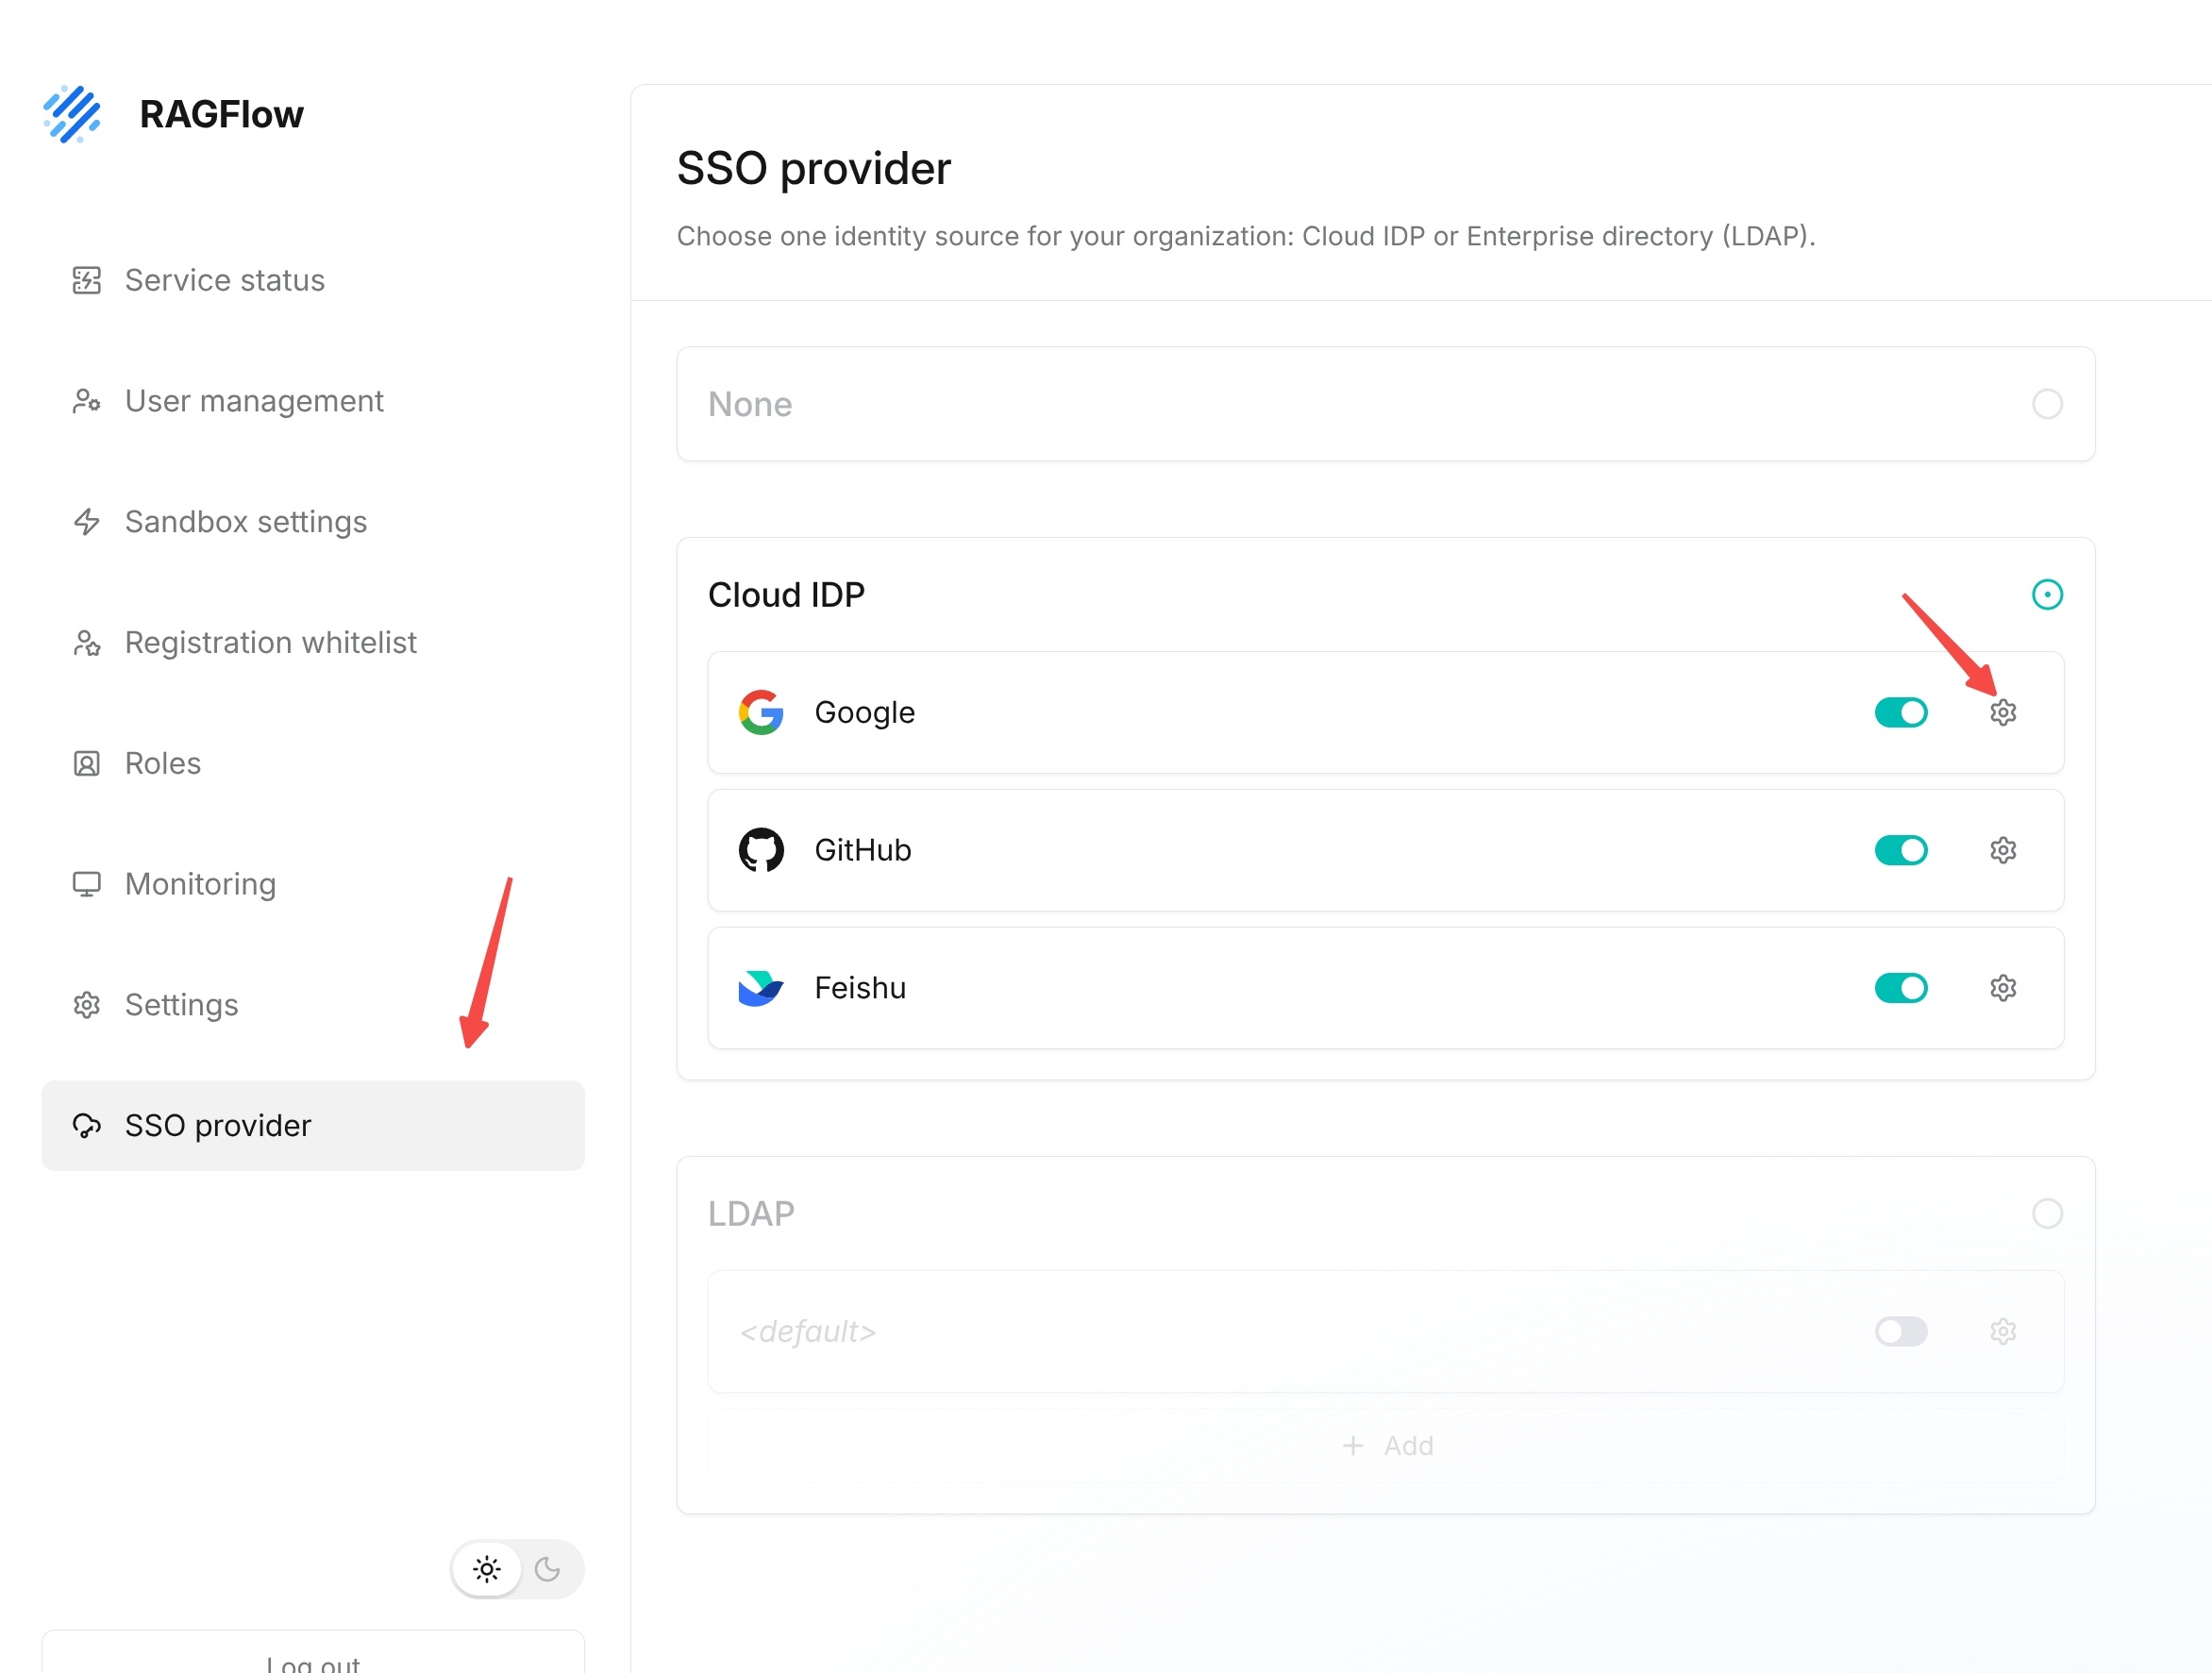diff --git a/docs/administrator/admin/ragflow_cli.md b/docs/administrator/admin/ragflow_cli.mdindex 240540c890..a54a7875b5 100644--- a/docs/administrator/admin/ragflow_cli.md+++ b/docs/administrator/admin/ragflow_cli.md@@ -1,5 +1,7 @@---sidebar_position: 2+title: RAGFlow CLI+sidebar_label: RAGFlow CLIslug: /admin_clisidebar_custom_props: {categoryIcon: LucideSquareTerminal@@ -35,7 +37,7 @@ The RAGFlow CLI is a command-line-based system administration tool that offers a- -p: RAGFlow admin server port-## Default administrative account+## Default Administrative Account- Username: [email protected]- Password: admin@@ -44,7 +46,7 @@ The RAGFlow CLI is a command-line-based system administration tool that offers aCommands are case-insensitive and must be terminated with a semicolon(;).-### Service manage commands+### Service Manage Commands`LIST SERVICES;`@@ -121,7 +123,7 @@ Commands are case-insensitive and must be terminated with a semicolon(;).- Lists the agents associated with the specified user.- [Example](#example-list-agents-of-user)-### System info+### System Info`SHOW VERSION;`- Display the current RAGFlow version.diff --git a/docs/administrator/configurations/config_ssl_cert.md b/docs/administrator/configurations/config_ssl_cert.mdindex f31e58743e..48a146af44 100644--- a/docs/administrator/configurations/config_ssl_cert.md+++ b/docs/administrator/configurations/config_ssl_cert.md@@ -1,11 +1,13 @@---sidebar_position: 1+title: Configure SSL Certificates+sidebar_label: Configure SSL Certificatesslug: /config_ssl_certsidebar_custom_props: {categoryIcon: LucideCog}----# Configure SSL certificates+# Configure SSL CertificatesConfigure SSL certificates for a RAGFlow instance deployed via Docker.@@ -13,7 +15,7 @@ Configure SSL certificates for a RAGFlow instance deployed via Docker.This guide details how to configure SSL certificates for a RAGFlow instance deployed via Docker, using the container name `docker-ragflow-cpu-1` as an example.-## 1. Prepare certificate files+## 1. Prepare Certificate FilesEnsure you have Nginx-formatted certificate files ready:@@ -29,7 +31,7 @@ cp XXXXX_bundle.pem fullchain.pemcp XXXXX.key privkey.pem```-## 2. Confirm container status+## 2. Confirm Container StatusVerify that your container is running:@@ -37,7 +39,7 @@ Verify that your container is running:docker ps```-## 3. Copy certificates to the container+## 3. Copy Certificates to the ContainerTransfer the files from your host machine to the container's temporary directory:@@ -46,7 +48,7 @@ docker cp ./fullchain.pem docker-ragflow-cpu-1:/tmp/fullchain.pemdocker cp ./privkey.pem docker-ragflow-cpu-1:/tmp/privkey.pem```-## 4. Deploy certificates inside the container+## 4. Deploy Certificates Inside the ContainerEnter the container's interactive terminal:@@ -66,7 +68,7 @@ chmod 644 /etc/nginx/ssl/fullchain.pemchmod 600 /etc/nginx/ssl/privkey.pem```-## 5. Switch Nginx to HTTPS configuration+## 5. Switch Nginx to HTTPS ConfigurationReplace the default HTTP configuration with the HTTPS template:@@ -74,13 +76,13 @@ Replace the default HTTP configuration with the HTTPS template:2. Back up the original configuration: `mv ragflow.conf ragflow.conf.bak`.3. Enable the HTTPS template: `cp /etc/nginx/ragflow.https.conf ./ragflow.conf`.-## 6. Edit the HTTPS template+## 6. Edit the HTTPS Template1. Open the configuration file: `vi ragflow.conf`.2. Ensure `ssl_certificate` and `ssl_certificate_key` paths point to your files in `/etc/nginx/ssl/`.3. Verify the Nginx syntax: `nginx -t`.-## 7. Apply the configuration+## 7. Apply the ConfigurationReload Nginx to apply changes:@@ -95,7 +97,7 @@ exitdocker restart docker-ragflow-cpu-1```-## Configuration persistence+## Configuration Persistence:::tip IMPORTANTChanges made via `docker cp` and `docker exec` are lost if the container is removed or stopped via `docker-compose down`.diff --git a/docs/administrator/configurations/configurations.md b/docs/administrator/configurations/configurations.mdindex 741dd07db9..7da35eafcc 100644--- a/docs/administrator/configurations/configurations.md+++ b/docs/administrator/configurations/configurations.md@@ -40,7 +40,7 @@ docker compose -f docker/docker-compose.yml up -dWe do not actively maintain **docker-compose-CN-oc9.yml**, **docker-compose-macos.yml**, so use them at your own risk. However, you are welcome to file a pull request to improve them.:::-## Docker environment variables+## Docker Environment VariablesThe [.env](https://github.com/infiniflow/ragflow/blob/main/docker/.env) file contains important environment variables for Docker.@@ -62,7 +62,7 @@ The [.env](https://github.com/infiniflow/ragflow/blob/main/docker/.env) file con- `KIBANA_PASSWORD`The password for Kibana. Defaults to `infini_rag_flow`.-### Resource management+### Resource Management- `MEM_LIMIT`The maximum amount of the memory, in bytes, that *a specific* Docker container can use while running. Defaults to `8073741824`.@@ -113,7 +113,7 @@ If you cannot download the RAGFlow Docker image, try the following mirrors.- `RAGFLOW_IMAGE=registry.cn-hangzhou.aliyuncs.com/infiniflow/ragflow:nightly`.:::-### Embedding service+### Embedding Service- `TEI_MODEL`The embedding model which text-embeddings-inference serves. Allowed values are one of `Qwen/Qwen3-Embedding-0.6B`(default), `BAAI/bge-m3`, and `BAAI/bge-small-en-v1.5`.@@ -126,23 +126,23 @@ If you cannot download the RAGFlow Docker image, try the following mirrors.- `TZ`The local time zone. Defaults to `Asia/Shanghai`.-### Hugging Face mirror site+### Hugging Face Mirror Site- `HF_ENDPOINT`The mirror site for huggingface.co. It is disabled by default. You can uncomment this line if you have limited access to the primary Hugging Face domain.-### MacOS+### macOS- `MACOS`Optimizations for macOS. It is disabled by default. You can uncomment this line if your OS is macOS.-### User registration+### User Registration- `REGISTER_ENABLED`- `1`: (Default) Enable user registration.- `0`: Disable user registration.-## Service configuration+## Service Configuration[service_conf.yaml.template](https://github.com/infiniflow/ragflow/blob/main/docker/service_conf.yaml.template) specifies the system-level configuration for RAGFlow and is used by its API server and task executor.@@ -166,7 +166,7 @@ If you cannot download the RAGFlow Docker image, try the following mirrors.- `password`: The password for MinIO.- `host`: The MinIO serving IP *and* port inside the Docker container. Defaults to `minio:9000`.-### `s3` (Tigris)+### `S3` (Tigris)To use [Tigris](https://www.tigrisdata.com) as an S3-compatible storage backend, set `STORAGE_IMPL=AWS_S3` in `.env` and configure the `s3:` section:diff --git a/docs/administrator/migration/backup_and_migration.md b/docs/administrator/migration/backup_and_migration.mdindex 10bac3f193..64b98d2e8e 100644--- a/docs/administrator/migration/backup_and_migration.md+++ b/docs/administrator/migration/backup_and_migration.md@@ -1,17 +1,19 @@---sidebar_position: 2+title: "Backup & Migration"+sidebar_label: "Backup & Migration"slug: /migrationsidebar_custom_props: {categoryIcon: LucideLocateFixed}----# Backup & migration+# Backup & Migration- [Data migration](#data-migration)- [Migrate from multi-bucket to single-bucket mode](#migrate-from-multi-bucket-to-single-bucket-mode)-## Data migration+## Data Migration:::info KUDOSThis document is contributed by our community contributor [TreeDy](https://github.com/Treedy2020). We may not actively maintain this document.@@ -19,7 +21,7 @@ This document is contributed by our community contributor [TreeDy](https://githuA common scenario is processing large datasets on a powerful instance (e.g., with a GPU) and then migrating the entire RAGFlow service to a different production environment (e.g., a CPU-only server). This guide explains how to safely back up and restore your data using our provided migration script.-### Identify your data+### Identify Your DataBy default, RAGFlow uses Docker volumes to store all persistent data, including your database, uploaded files, and search indexes. You can see these volumes by running:@@ -43,7 +45,7 @@ These volumes contain all the data you need to migrate.The volume name prefix (e.g., `docker_`) comes from the Docker Compose project name. By default it is `docker` (derived from the directory name). If you started RAGFlow with `docker compose -p <project_name>`, your volumes will be prefixed with `<project_name>_` instead, for example `ragflow_mysql_data`.:::-### Step 1: Stop RAGFlow services+### Step 1: Stop RAGFlow ServicesBefore starting the migration, you must stop all running RAGFlow services on the **source machine**. Navigate to the project's root directory and run:@@ -59,7 +61,7 @@ docker compose -p ragflow -f docker/docker-compose.yml down**Important:** Do **not** use the `-v` flag (e.g., `docker compose down -v`), as this will delete all your data volumes. The migration script includes a check and will prevent you from running it if services are active.-### Step 2: Back up your data+### Step 2: Back Up Your DataWe provide a convenient script to package all your data volumes into a single backup folder.@@ -91,11 +93,11 @@ bash docker/migration.sh -p ragflow backupbash docker/migration.sh -p ragflow backup my_ragflow_backup```-### Step 3: Transfer the backup folder+### Step 3: Transfer the Backup FolderCopy the entire backup folder (e.g., `backup/` or `my_ragflow_backup/`) from your source machine to the RAGFlow project directory on your **target machine**. You can use tools like `scp`, `rsync`, or a physical drive for the transfer.-### Step 4: Restore your data+### Step 4: Restore Your DataOn the **target machine**, ensure that RAGFlow services are not running. Then, use the migration script to restore your data from the backup folder.@@ -122,7 +124,7 @@ The script will automatically create the necessary Docker volumes and unpack the**Note:** If the script detects that Docker volumes with the same names already exist on the target machine, it will warn you that restoring will overwrite the existing data and ask for confirmation before proceeding.-### Step 5: Start RAGFlow services+### Step 5: Start RAGFlow ServicesOnce the restore process is complete, you can start the RAGFlow services on your new machine:@@ -147,7 +149,7 @@ docker compose -f docker/docker-compose.yml up -dYour RAGFlow instance is now running with all the data from your original machine.-## Migrate from multi-bucket to single-bucket mode+## Migrate from Multi-Bucket to Single-Bucket Mode:::info KUDOSThis document is contributed by our community contributor [arogan178](https://github.com/arogan178). We may not actively maintain this document.@@ -161,9 +163,9 @@ By default, RAGFlow creates one bucket per Knowledge Base (dataset) and one buckThe **Single Bucket Mode** allows you to configure RAGFlow to use a single bucket with a directory structure instead of multiple buckets.-### How it works+### How It Works-#### Default mode (Multiple buckets)+#### Default Mode (Multiple Buckets)```bucket: kb_12345/@@ -174,7 +176,7 @@ bucket: folder_abc/└── file_3.txt```-#### Single bucket mode (with prefix_path)+#### Single Bucket Mode (With Prefix_path)```bucket: ragflow-bucket/@@ -189,7 +191,7 @@ bucket: ragflow-bucket/### Configuration-#### MinIO configuration+#### MinIO ConfigurationEdit your `service_conf.yaml` or set environment variables:@@ -212,7 +214,7 @@ export MINIO_BUCKET=ragflow-bucketexport MINIO_PREFIX_PATH=ragflow```-#### S3 configuration (already supported)+#### S3 Configuration (Already Supported)```yamls3:@@ -224,7 +226,7 @@ s3:region_name: "us-east-1"```-#### Tigris configuration+#### Tigris Configuration[Tigris](https://www.tigrisdata.com) is an S3-compatible object storage service that works with RAGFlow's `AWS_S3` backend. Set `STORAGE_IMPL=AWS_S3` in your `.env` file:@@ -242,7 +244,7 @@ s3:See [S3 (Tigris)](/configurations#s3-tigris) for full setup instructions.-### IAM policy example+### Iam Policy ExampleWhen using single bucket mode, you only need permissions for one bucket:@@ -262,7 +264,7 @@ When using single bucket mode, you only need permissions for one bucket:}```-### Migration from multi-bucket to single bucket+### Migration from Multi-Bucket to Single BucketIf you're migrating from multi-bucket mode to single-bucket mode:@@ -283,9 +285,9 @@ mc ls old-minio/ | grep kb_ | while read -r line; dodone```-### Toggle between modes+### Toggle Between Modes-#### Enable single bucket mode+#### Enable Single Bucket Mode```yamlminio:@@ -293,7 +295,7 @@ minio:prefix_path: "ragflow"```-#### Disable (Use multi-bucket mode)+#### Disable (Use Multi-Bucket Mode)```yamlminio:@@ -304,19 +306,19 @@ minio:### Troubleshooting-#### Issue: Access Denied errors+#### Issue: Access Denied Errors**Solution**: Ensure your IAM policy grants access to the bucket specified in the configuration.-#### Issue: Files not found after switching modes+#### Issue: Files Not Found After Switching Modes**Solution**: The path structure changes between modes. You'll need to migrate existing data.-#### Issue: Connection fails with HTTPS+#### Issue: Connection Fails with HTTPS**Solution**: Ensure `secure: True` is set in the MinIO connection (automatically handled for port 443).-### Storage backends supported+### Storage Backends Supported- ✅ **MinIO** - Full support with single bucket mode- ✅ **AWS S3** - Full support with single bucket mode@@ -325,7 +327,7 @@ minio:- ✅ **Azure Blob** - Uses container-based structure (different paradigm)- ⚠️ **OpenDAL** - Depends on underlying storage backend-### Performance considerations+### Performance Considerations- **Single bucket mode** may have slightly better performance for bucket listing operations- **Multi-bucket mode** provides better isolation and organization for large deploymentsdiff --git a/docs/administrator/migration/database_schema_and_migration.md b/docs/administrator/migration/database_schema_and_migration.mdindex 487cd42ea9..269d414716 100644--- a/docs/administrator/migration/database_schema_and_migration.md+++ b/docs/administrator/migration/database_schema_and_migration.md@@ -1,12 +1,14 @@---sidebar_position: 1+title: Database Schema and Migration+sidebar_label: Database Schema and Migrationslug: /database_schema_and_migrationsidebar_custom_props: {categoryIcon: LucideLocateFixed}----# Database schema and migration+# Database Schema and MigrationSync schemas and migrate data using official RAGFlow scripts.@@ -17,11 +19,11 @@ RAGFlow handles schema updates and migrations automatically at startup. However,- [mysql_migration.py](#mysql_migrationpy): Migrates data between MySQL tables.- [db_schema_sync.py](#db_schema_syncpy): Syncs database schemas and manages changes using peewee-migrate.-## mysql_migration.py+## Mysql_migration.pyThe [mysql_migration.py](https://github.com/infiniflow/ragflow/blob/main/tools/scripts/mysql_migration.py) script is a specialized tool for re-organizing RAGFlow’s model-related data. It transitions data from older unified tables into a modern, multi-table structure to support advanced model management.-### Key functions+### Key Functions- **Sequential migration**: Moves data through three distinct stages—Provider, Instance, and Model—to maintain database integrity and satisfy dependencies.- **Flexible setup**: Connects to MySQL using either a YAML configuration file or direct command-line arguments.@@ -29,18 +31,18 @@ The [mysql_migration.py](https://github.com/infiniflow/ragflow/blob/main/tools/s- **Automated mapping**: Generates unique IDs and handles complex joins between legacy records and new table structures.- **Batch logging**: Processes records in sets of 100 and provides a final summary of total duration and row counts.-### When to use+### When to Use- **Version upgrades**: Essential when moving to RAGFlow v0.25 or later to ensure your models are correctly categorized in the new schema.- **Data normalization**: Necessary when consolidating multiple API keys or LLM providers into the updated system format.- **Kubernetes deployments**: Useful for setting up the database structure independently using the `--create-table-only` flag before main services start.- **Migration verification**: Used in dry-run mode to identify any legacy records that still need to be moved to the new tables.-## db_schema_sync.py+## Db_schema_sync.pyThe [db_schema_sync.py](https://github.com/infiniflow/ragflow/blob/main/tools/scripts/db_schema_sync.py) script is a synchronization utility that ensures your MySQL database structure matches the Peewee ORM models defined in the RAGFlow source code.-### Key functions+### Key Functions- **Change detection**: Compares Python model definitions in `api/db/db_models.py` against the live database to identify new tables, added fields, or type mismatches.- **Migration generation**: Automatically creates Python migration files (containing `migrate()` and `rollback()` logic) in version-specific directories (e.g., `tools/migrate/v0_26_4/`).@@ -48,7 +50,7 @@ The [db_schema_sync.py](https://github.com/infiniflow/ragflow/blob/main/tools/sc- **Execution management**: Applies pending migrations to the database to bring it up to date with the current software version.- **Safety controls**: Prevents accidental data loss by requiring an explicit `--drop` flag to generate `DROP COLUMN` statements for removed fields.-### When to use+### When to Use- **Version upgrades**: When moving to a new version of RAGFlow that introduces structural database changes.- **Development**: When modifying `db_models.py` and needing to update your local database without manual SQL.diff --git a/docs/administrator/tracing.mdx b/docs/administrator/tracing.mdxindex c9b4221e14..da80c5c0e8 100644--- a/docs/administrator/tracing.mdx+++ b/docs/administrator/tracing.mdx@@ -26,7 +26,7 @@ Langfuse stores traces, spans and prompt payloads in a purpose-built observabili----## 1. Collect your Langfuse credentials+## 1. Collect Your Langfuse Credentials1. Sign in to your Langfuse dashboard.2. Open **Settings ▸ Projects** and either create a new project or select an existing one.@@ -37,7 +37,7 @@ Langfuse stores traces, spans and prompt payloads in a purpose-built observabili----## 2. Add the keys to RAGFlow+## 2. Add the Keys to RAGFlowRAGFlow stores the credentials _per tenant_. You can configure them either via the web UI or the HTTP API.@@ -46,13 +46,12 @@ RAGFlow stores the credentials _per tenant_. You can configure them either via t3. Fill in you Langfuse **Host**, **Public Key** and **Secret Key**.4. Click **Save**.-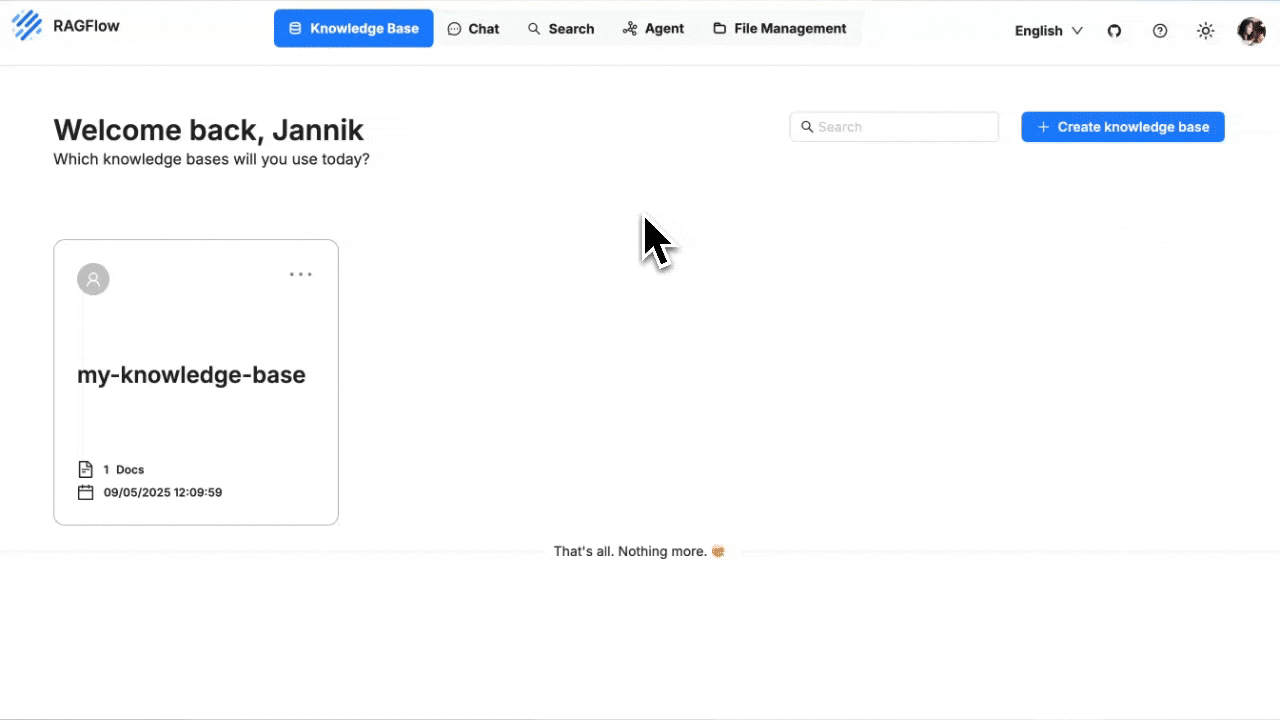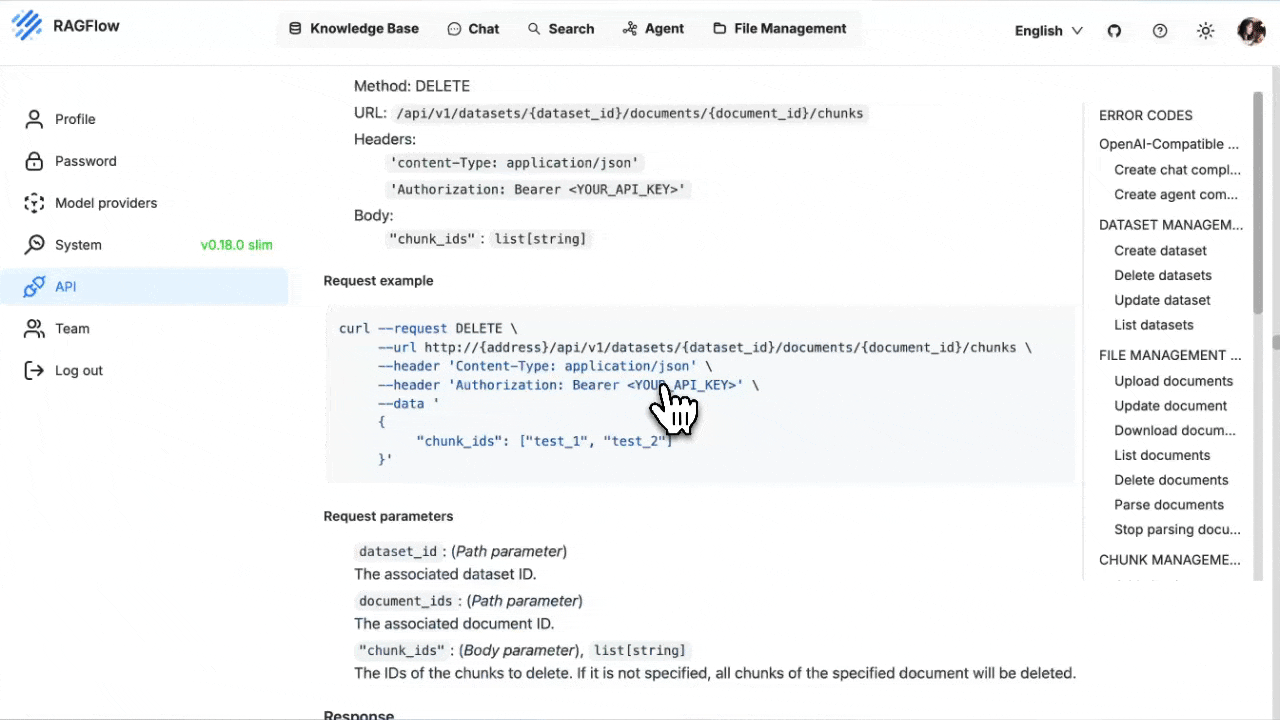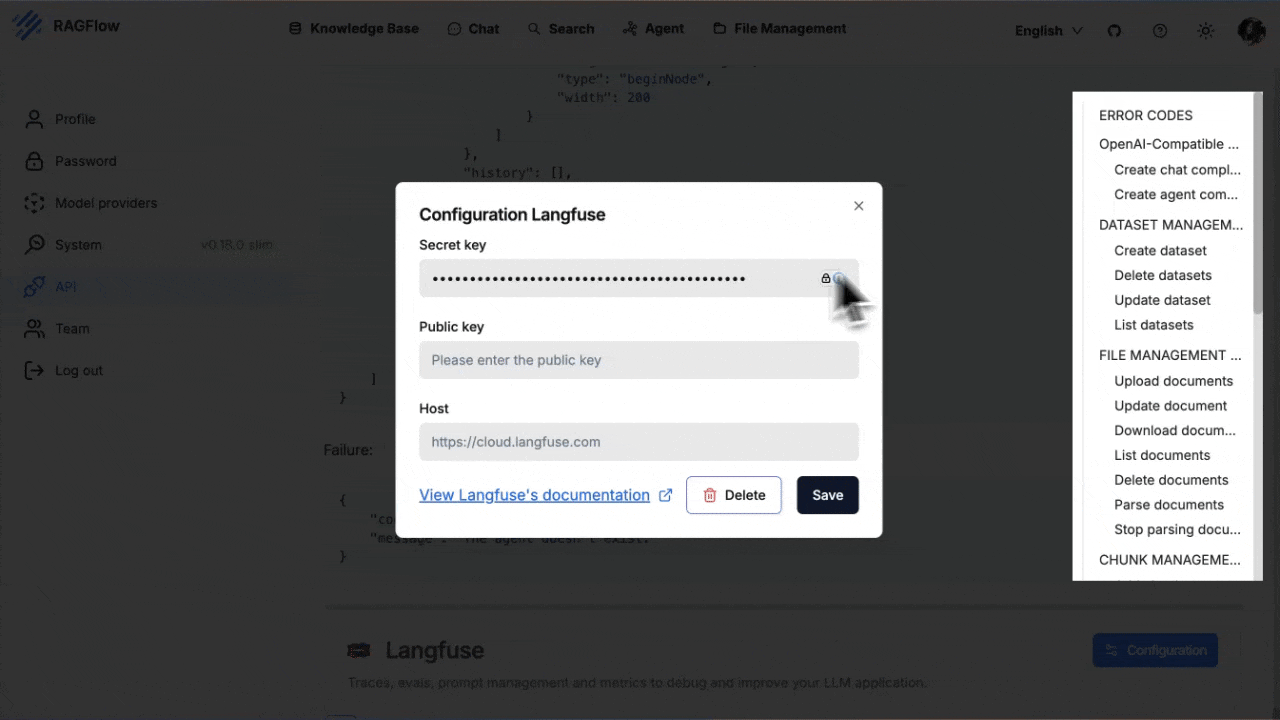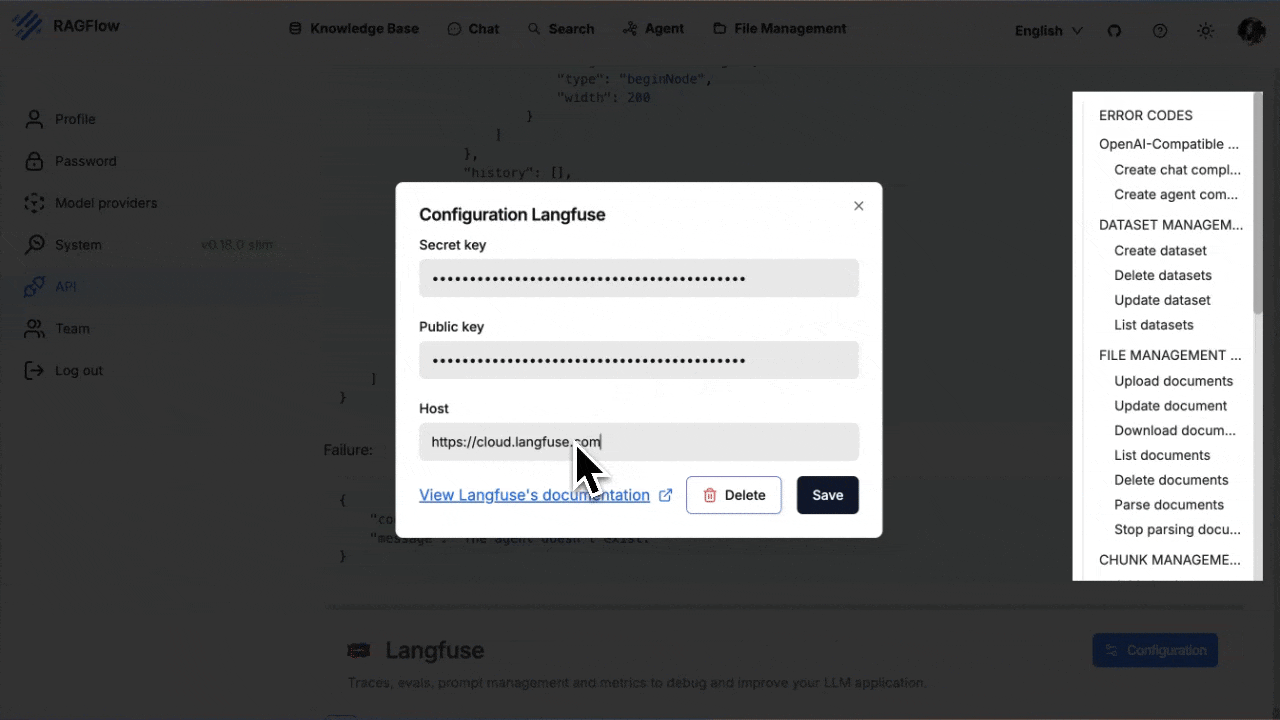Once saved, RAGFlow starts emitting traces automatically – no code change required.----## 3. Run a pipeline and watch the traces+## 3. Run a Pipeline and Watch the Traces1. Execute any chat or retrieval pipeline in RAGFlow (e.g. the Quickstart demo).2. Open your Langfuse project ▸ **Traces**.@@ -64,7 +63,6 @@ For every user request you will see:• **spans** for retrieval, ranking and generation steps• the complete **prompts**, **retrieved documents** and **LLM responses** as metadata-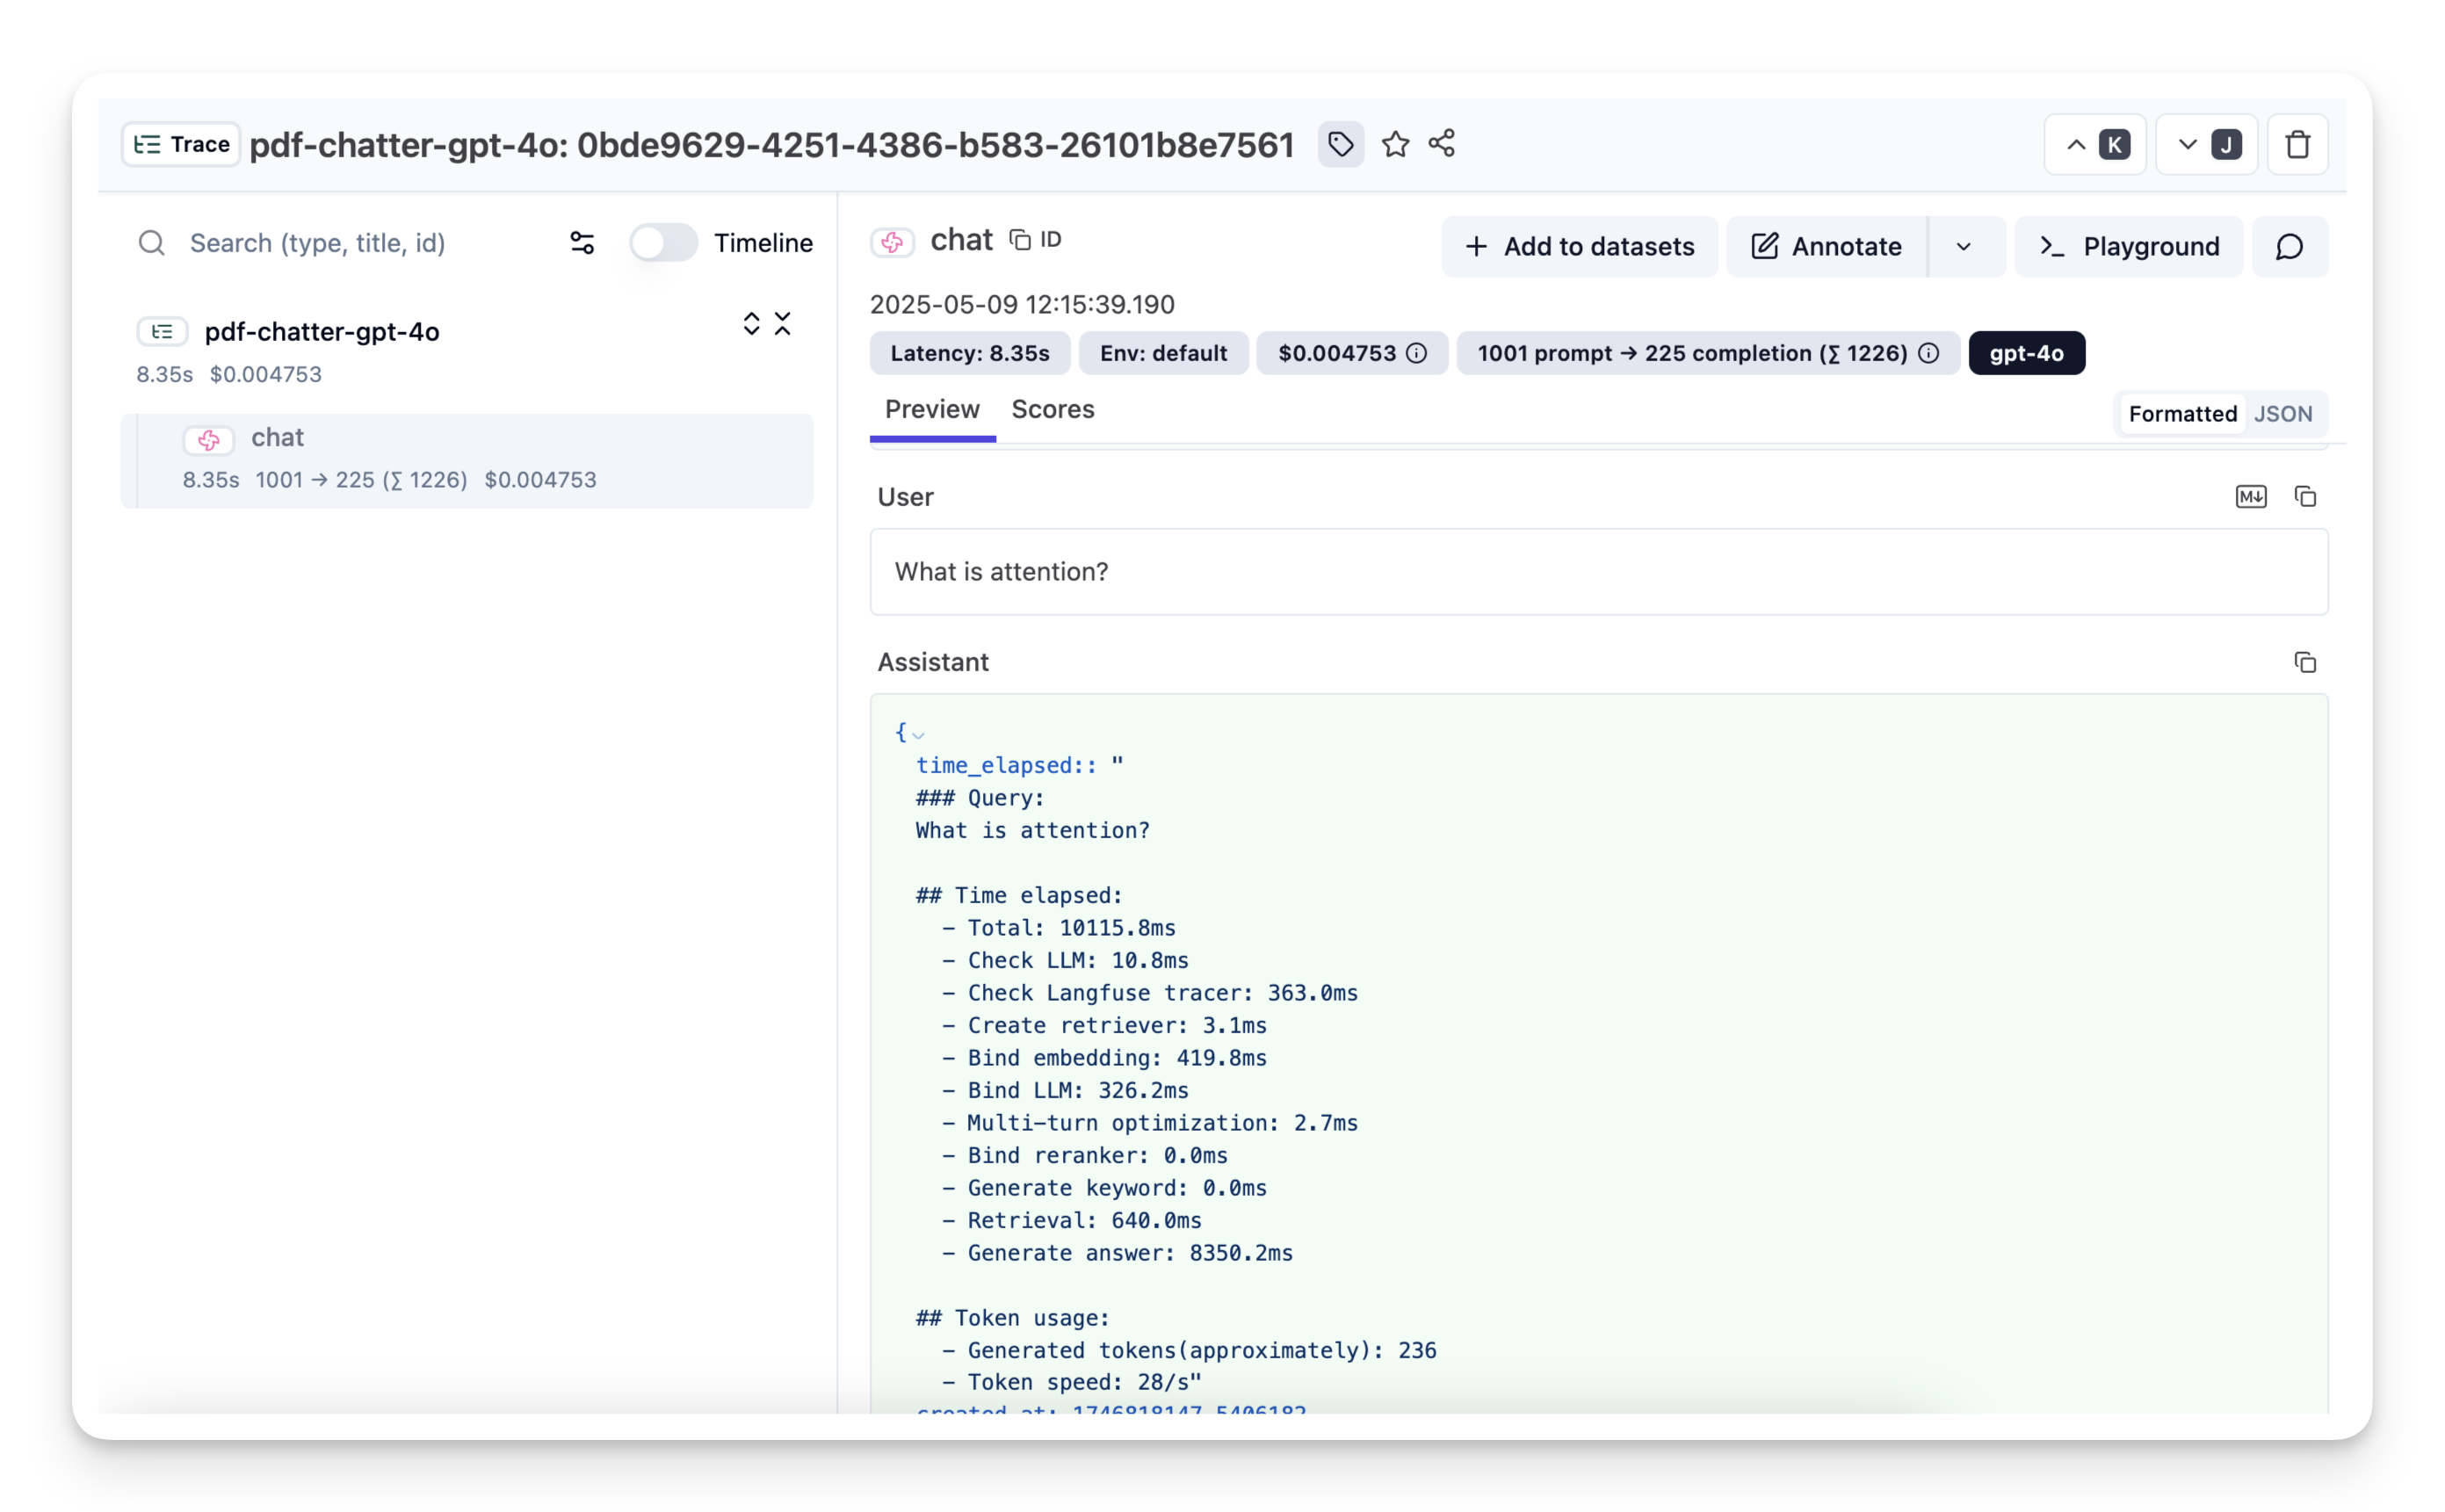([Example trace in Langfuse](https://cloud.langfuse.com/project/cloramnkj0002jz088vzn1ja4/traces/0bde9629-4251-4386-b583-26101b8e7561?timestamp=2025-05-09T19%3A15%3A37.797Z&display=details&observation=823997d8-ac40-40f3-8e7b-8aa6753b499e))diff --git a/docs/administrator/upgrade_ragflow.mdx b/docs/administrator/upgrade_ragflow.mdxindex 223d8115b4..269dd6af3e 100644--- a/docs/administrator/upgrade_ragflow.mdx+++ b/docs/administrator/upgrade_ragflow.mdx@@ -1,5 +1,7 @@---sidebar_position: 1+title: Upgrading+sidebar_label: Upgradingslug: /upgrade_ragflowsidebar_custom_props: {categoryIcon: LucideArrowBigUpDash@@ -15,7 +17,7 @@ Upgrade RAGFlow to `nightly` or the latest, published release.Upgrading RAGFlow in itself will *not* remove your uploaded/historical data. However, be aware that `docker compose -f docker/docker-compose.yml down -v` will remove Docker container volumes, resulting in data loss.:::-## Upgrade RAGFlow to `nightly`, the most recent, tested Docker image+## Upgrade RAGFlow to `nightly`, the Most Recent, Tested Docker Image`nightly` refers to the RAGFlow Docker image without embedding models.@@ -46,7 +48,7 @@ To upgrade RAGFlow, you must upgrade **both** your code **and** your Docker imagdocker compose -f docker/docker-compose.yml up -d```-## Upgrade RAGFlow to given release+## Upgrade RAGFlow to Given ReleaseTo upgrade RAGFlow, you must upgrade **both** your code **and** your Docker image:@@ -81,13 +83,13 @@ To upgrade RAGFlow, you must upgrade **both** your code **and** your Docker imagdocker compose -f docker/docker-compose.yml up -d```-## Frequently asked questions+## Frequently Asked Questions-### Do I need to back up my datasets before upgrading RAGFlow?+### Do I Need to Back Up My Datasets Before Upgrading RAGFlow?No, you do not need to. Upgrading RAGFlow in itself will *not* remove your uploaded data or dataset settings. However, be aware that `docker compose -f docker/docker-compose.yml down -v` will remove Docker container volumes, resulting in data loss.-### Upgrade RAGFlow in an offline environment (without Internet access)+### Upgrade RAGFlow in an Offline Environment (Without Internet Access)1. From an environment with Internet access, pull the required Docker image.2. Save the Docker image to a **.tar** file.diff --git a/docs/basics/agent_context_engine.md b/docs/basics/agent_context_engine.mdindex 4c4f9e2e25..b4085cbdf1 100644--- a/docs/basics/agent_context_engine.md+++ b/docs/basics/agent_context_engine.md@@ -1,9 +1,11 @@---sidebar_position: 2+title: "What Is Agent Context Engine?"+sidebar_label: "What Is Agent Context Engine?"slug: /what-is-agent-context-engine----# What is Agent context engine?+# What Is Agent Context Engine?From 2025, a silent revolution began beneath the dazzling surface of AI Agents. While the world marveled at agents that could write code, analyze data, and automate workflows, a fundamental bottleneck emerged: why do even the most advanced agents still stumble on simple questions, forget previous conversations, or misuse available tools?@@ -11,7 +13,7 @@ The answer lies not in the intelligence of the Large Language Model (LLM) itselfThis is where the Agent Context Engine comes in. It is not merely an incremental improvement but a foundational shift, representing the evolution of RAG from a singular technique into the core data and intelligence substrate for the entire Agent ecosystem.-## Beyond the hype: The reality of today's "intelligent" Agents+## Beyond the Hype: The Reality of Today's "Intelligent" AgentsToday, the “intelligence” behind most AI Agents hides a mountain of human labor. Developers must:- Hand-craft elaborate prompt templates@@ -33,7 +35,7 @@ At its core, an Agent Context Engine is built on a triumvirate of next-generatio3. The Tool Orchestrator: As MCP (Model Context Protocol) enables the connection of hundreds of internal services as tools, a new problem arises: tool selection. The Context Engine solves this with Tool Retrieval. Instead of dumping all tool descriptions into the prompt, it maintains an index of tools and—critically—an index of Skills (best practices on when and how to use tools). For a given task, it retrieves only the most relevant tools and instructions, transforming the LLM’s job from "searching a haystack" to "following a recipe."-## Why we need a dedicated engine? The case for a unified substrate+## Why Do We Need a Dedicated Engine? The Case for a Unified SubstrateThe necessity of an Agent Context Engine becomes clear when we examine the alternative: siloed, manually wired components.@@ -50,7 +52,7 @@ The shift from Context Engineering to a Context Platform/Engine marks the matura| Context maintenance | A development and operational burden, logic locked in code. | A manageable platform function, with visibility and control returned to the business. |-## RAGFlow: A resolute march toward the context engine of Agents+## RAGFlow: A Resolute March Toward the Context Engine of AgentsThis is the future RAGFlow is forging.diff --git a/docs/basics/rag.md b/docs/basics/rag.mdindex 470c6e0590..1d6e6dabad 100644--- a/docs/basics/rag.md+++ b/docs/basics/rag.md@@ -3,11 +3,11 @@ sidebar_position: 1slug: /what-is-rag----# What is Retrieval-Augmented-Generation (RAG)?+# What Is Retrieval-Augmented Generation (RAG)?Since large language models (LLMs) became the focus of technology, their ability to handle general knowledge has been astonishing. However, when questions shift to internal corporate documents, proprietary knowledge bases, or real-time data, the limitations of LLMs become glaringly apparent: they cannot access private information outside their training data. Retrieval-Augmented Generation (RAG) was born precisely to address this core need. Before an LLM generates an answer, it first retrieves the most relevant context from an external knowledge base and inputs it as "reference material" to the LLM, thereby guiding it to produce accurate answers. In short, RAG elevates LLMs from "relying on memory" to "having evidence to rely on," significantly improving their accuracy and trustworthiness in specialized fields and real-time information queries.-## Why RAG is important?+## Why Is RAG Important?Although LLMs excel in language understanding and generation, they have inherent limitations:@@ -22,11 +22,11 @@ The introduction of RAG provides LLMs with real-time, credible "factual groundinThis upgrades LLMs from "speaking from memory" to "speaking with documentation," significantly enhancing reliability in professional and enterprise-level applications.-## How RAG works?+## How Does RAG Work?Retrieval-Augmented Generation enables LLMs to generate higher-quality responses by leveraging real-time, external, or private data sources through the introduction of an information retrieval mechanism. Its workflow can be divided into following key steps:-### Data processing and vectorization+### Data Processing and VectorizationThe knowledge required by RAG comes from unstructured data in various formats, such as documents, database records, or API return content. This data typically needs to be chunked, then transformed into vectors via an embedding model, and stored in a vector database.@@ -38,25 +38,25 @@ Why is Chunking Needed? Indexing entire documents directly faces the following pTherefore, an intelligent chunking strategy is key to balancing information integrity, retrieval granularity, and computational efficiency.-### Retrieve relevant information+### Retrieve Relevant InformationThe user's query is also converted into a vector to perform semantic relevance searches (e.g., calculating cosine similarity) in the vector database, matching and recalling the most relevant text fragments.-### Context construction and answer generation+### Context Construction and Answer GenerationThe retrieved relevant content is added to the LLM's context as factual grounding, and the LLM finally generates the answer. Therefore, RAG can be seen as Context Engineering 1.0 for automated context construction.-## Deep dive into existing RAG architecture: beyond vector retrieval+## Deep Dive into Existing RAG Architecture: Beyond Vector RetrievalAn industrial-grade RAG system is far from being as simple as "vector search + LLM"; its complexity and challenges are primarily embedded in the retrieval process.-### Data complexity: multimodal document processing+### Data Complexity: Multimodal Document ProcessingCore Challenge: Corporate knowledge mostly exists in the form of multimodal documents containing text, charts, tables, and formulas. Simple OCR extraction loses a large amount of semantic information.Advanced Practice: Leading solutions, such as RAGFlow, tend to use Visual Language Models (VLM) or specialized parsing models like DeepDoc to "translate" multimodal documents into unimodal text rich in structural and semantic information. Converting multimodal information into high-quality unimodal text has become standard practice for advanced RAG.-### The complexity of chunking: the trade-off between precision and context+### The Complexity of Chunking: The Trade-Off Between Precision and ContextA simple "chunk-embed-retrieve" pipeline has an inherent contradiction:- Semantic Matching requires small text chunks to ensure clear semantic focus.@@ -66,7 +66,7 @@ This forces system design into a difficult trade-off between "precise but fragmeAdvanced Practice: Leading solutions, such as RAGFlow, employ semantic enhancement techniques like constructing semantic tables of contents and knowledge graphs. These not only address semantic fragmentation caused by physical chunking but also enable the discovery of relevant content across documents based on entity-relationship networks.-### Why is a vector database insufficient for serving RAG?+### Why Is a Vector Database Insufficient for Serving RAG?Vector databases excel at semantic similarity search, but RAG requires precise and reliable answers, demanding more capabilities from the retrieval system:- Hybrid Search: Relying solely on vector retrieval may miss exact keyword matches (e.g., product codes, regulation numbers). Hybrid search, combining vector retrieval with keyword retrieval (BM25), ensures both semantic breadth and keyword precision.@@ -75,14 +75,14 @@ Vector databases excel at semantic similarity search, but RAG requires precise aTherefore, the retrieval layer of RAG is a composite system based on vector search but must integrate capabilities like full-text search, re-ranking, and metadata filtering.-## RAG and memory: Retrieval from the same source but different streams+## RAG and Memory: Retrieval from the Same Source but Different StreamsWithin the agent framework, the essence of the memory mechanism is the same as RAG: both retrieve relevant information from storage based on current needs. The key difference lies in the data source:- RAG: Targets pre-existing static or dynamic private data provided by the user in advance (e.g., documents, databases).- Memory: Targets dynamic data generated or perceived by the agent in real-time during interaction (e.g., conversation history, environmental state, tool execution results).They are highly consistent at the technical base (e.g., vector retrieval, keyword matching) and can be seen as the same retrieval capability applied in different scenarios ("existing knowledge" vs. "interaction memory"). A complete agent system often includes both an RAG module for inherent knowledge and a Memory module for interaction history.-## RAG applications+## RAG ApplicationsRAG has demonstrated clear value in several typical scenarios:@@ -93,7 +93,7 @@ RAG has demonstrated clear value in several typical scenarios:3. Dynamic Knowledge Fusion and Decision SupportIn business scenarios requiring the synthesis of information from multiple sources, RAG evolves into a knowledge orchestration and reasoning support system for business decisions. Through a multi-path recall mechanism, it fuses knowledge from different systems and formats, maintaining factual consistency and logical controllability during the generation phase.-## The future of RAG+## The Future of RAGThe evolution of RAG is unfolding along several clear paths:diff --git a/docs/develop/_category_.json b/docs/develop/_category_.jsonindex 406b847f96..f1251a4996 100644--- a/docs/develop/_category_.json+++ b/docs/develop/_category_.json@@ -1,5 +1,5 @@{- "label": "Developer guides",+ "label": "Developer Guides","position": 5,"link": {"type": "generated-index",diff --git a/docs/develop/acquire_ragflow_api_key.md b/docs/develop/acquire_ragflow_api_key.mdindex f933bb5752..561ab30fa4 100644--- a/docs/develop/acquire_ragflow_api_key.md+++ b/docs/develop/acquire_ragflow_api_key.md@@ -1,11 +1,13 @@---sidebar_position: 4+title: Acquire RAGFlow API Key+sidebar_label: Acquire RAGFlow API Keyslug: /acquire_ragflow_api_keysidebar_custom_props: {categoryIcon: LucideKey}----# Acquire RAGFlow API key+# Acquire RAGFlow API KeyAn API key is required for the RAGFlow server to authenticate your HTTP/Python or MCP requests. This document provides instructions on obtaining a RAGFlow API key.diff --git a/docs/develop/build_docker_image.mdx b/docs/develop/build_docker_image.mdxindex ceeb27ee29..1a51010d43 100644--- a/docs/develop/build_docker_image.mdx+++ b/docs/develop/build_docker_image.mdx@@ -1,11 +1,13 @@---sidebar_position: 4+title: Build RAGFlow Docker Image+sidebar_label: Build RAGFlow Docker Imageslug: /build_docker_imagesidebar_custom_props: {categoryIcon: LucidePackage}----# Build RAGFlow Docker image+# Build RAGFlow Docker Imageimport Tabs from '@theme/Tabs';import TabItem from '@theme/TabItem';@@ -24,7 +26,7 @@ A guide explaining how to build a RAGFlow Docker image from its source code. By- Disk ≥ 50 GB- Docker ≥ 24.0.0 & Docker Compose ≥ v2.26.1-## Build a Docker image+## Build a Docker ImageThis image is approximately 2 GB in size and relies on external LLM and embedding services.@@ -42,11 +44,11 @@ cd ..docker build -f Dockerfile -t infiniflow/ragflow:nightly .```-## Launch a RAGFlow Service from Docker for MacOS+## Launch a RAGFlow Service from Docker for macOSAfter building the infiniflow/ragflow:nightly image, you are ready to launch a fully-functional RAGFlow service with all the required components, such as Elasticsearch, MySQL, MinIO, Redis, and more.-## Example: Apple M2 Pro (Sequoia)+## Example: Apple M2 Pro (sequoia)1. Edit Docker Compose Configurationdiff --git a/docs/develop/contributing.md b/docs/develop/contributing.mdindex e3f910672c..afaaafc706 100644--- a/docs/develop/contributing.md+++ b/docs/develop/contributing.md@@ -5,7 +5,7 @@ sidebar_custom_props: {categoryIcon: LucideBookA}----# Contribution guidelines+# Contribution GuidelinesGeneral guidelines for RAGFlow's community contributors.@@ -16,7 +16,7 @@ This document offers guidelines and major considerations for submitting your con- To report a bug, file a [GitHub issue](https://github.com/infiniflow/ragflow/issues/new/choose) with us.- For further questions, you can explore existing discussions or initiate a new one in [Discussions](https://github.com/orgs/infiniflow/discussions).-## What you can contribute+## What You Can ContributeThe list below mentions some contributions you can make, but it is not a complete list.@@ -27,9 +27,9 @@ The list below mentions some contributions you can make, but it is not a complet- Updates to existing documents, codes, or annotations.- Suggesting more user-friendly error codes-## File a pull request (PR)+## File a Pull Request (PR)-### General workflow+### General Workflow1. Fork our GitHub repository.2. Clone your fork to your local machine:@@ -42,18 +42,18 @@ The list below mentions some contributions you can make, but it is not a complet`git push origin my-branch.`6. Submit a pull request for review.-### Before filing a PR+### Before Filing a PR- Consider splitting a large PR into multiple smaller, standalone PRs to keep a traceable development history.- Ensure that your PR addresses just one issue, or keep any unrelated changes small.- Add test cases when contributing new features. They demonstrate that your code functions correctly and protect against potential issues from future changes.-### Describing your PR+### Describing Your PR- Ensure that your PR title is concise and clear, providing all the required information.- Refer to a corresponding GitHub issue in your PR description if applicable.- Include sufficient design details for *breaking changes* or *API changes* in your description.-### Reviewing & merging a PR+### Reviewing & Merging a PREnsure that your PR passes all Continuous Integration (CI) tests before merging it.\ No newline at end of filediff --git a/docs/develop/deepwiki.md b/docs/develop/deepwiki.mdindex c507185cb5..9d544c2e46 100644--- a/docs/develop/deepwiki.md+++ b/docs/develop/deepwiki.md@@ -16,17 +16,17 @@ An AI-generated, always-up-to-date knowledge base for understanding RAGFlow's coThe RAGFlow content on DeepWiki is maintained by DeepWiki, not by the RAGFlow team. It may lag behind the latest official release. Always refer to the official [RAGFlow documentation](https://ragflow.io/docs/dev/) and [source code](https://github.com/infiniflow/ragflow) for the most up-to-date information.:::-## What is DeepWiki?+## What Is DeepWiki?[DeepWiki](https://deepwiki.com) is an AI-powered tool that automatically reads a GitHub repository's source code, tests, and documentation to produce a structured, interactive wiki. It maps out architecture diagrams, module relationships, data flows, and design rationale — all without requiring manual documentation work.-## The RAGFlow DeepWiki page+## The RAGFlow DeepWiki PageThe RAGFlow project is indexed at:**[https://deepwiki.com/infiniflow/ragflow](https://deepwiki.com/infiniflow/ragflow)**-## Target audience+## Target AudienceThis resource is primarily intended for:@@ -38,7 +38,7 @@ This resource is primarily intended for:For general usage of RAGFlow (configuring knowledge bases, running chat, etc.), the [Guides](../guides/) section is a better starting point.:::-## What you can find on DeepWiki+## What You Can Find on DeepWiki| Topic | What to look for ||---|---|@@ -49,7 +49,7 @@ For general usage of RAGFlow (configuring knowledge bases, running chat, etc.),| **LLM / Embedding abstractions** | How `rag/llm/` wraps different model providers behind a unified interface || **API layer** | How `api/apps/` Blueprint routes map to internal service calls |-## Using DeepWiki alongside local development+## Using DeepWiki Alongside Local DevelopmentWhen you are making changes to the codebase, DeepWiki can help you quickly answer questions such as:@@ -59,11 +59,11 @@ When you are making changes to the codebase, DeepWiki can help you quickly answeYou can also ask DeepWiki questions in natural language using its built-in chat interface — it will ground its answers in the actual source code.-## Keeping the wiki current+## Keeping the Wiki CurrentDeepWiki re-indexes the repository automatically when the upstream `main` branch is updated. If you notice the indexed content lagging behind a recent release, you can trigger a manual re-index from the DeepWiki page.-## Related resources+## Related Resources- [Launch service from source](./launch_ragflow_from_source.md) — set up a local RAGFlow development environment.- [Build RAGFlow Docker image](./build_docker_image.mdx) — build a custom image after code changes.diff --git a/docs/develop/launch_ragflow_from_source.md b/docs/develop/launch_ragflow_from_source.mdindex c24f9561f7..c0019a902e 100644--- a/docs/develop/launch_ragflow_from_source.md+++ b/docs/develop/launch_ragflow_from_source.md@@ -1,15 +1,17 @@---sidebar_position: 3+title: Launch Service from Source+sidebar_label: Launch Service from Sourceslug: /launch_ragflow_from_sourcesidebar_custom_props: {categoryIcon: LucideMonitorPlay}----# Launch service from source+# Launch Service from SourceA guide explaining how to set up a RAGFlow service from its source code. By following this guide, you'll be able to debug using the source code.-## Target audience+## Target AudienceDevelopers who have added new features or modified existing code and wish to debug using the source code, *provided that* their machine has the target deployment environment set up.@@ -24,18 +26,18 @@ Developers who have added new features or modified existing code and wish to debIf you have not installed Docker on your local machine (Windows, Mac, or Linux), see the [Install Docker Engine](https://docs.docker.com/engine/install/) guide.:::-## Launch a service from source+## Launch a Service from SourceTo launch a RAGFlow service from source code:-### Clone the RAGFlow repository+### Clone the RAGFlow Repository```bashgit clone https://github.com/infiniflow/ragflow.gitcd ragflow/```-### Install Python dependencies+### Install Python Dependencies1. Install uv:@@ -56,7 +58,7 @@ cd ragflow/uv sync --python 3.13 --group test --frozen && uv pip install sdk/python --group test```-### Launch third-party services+### Launch Third-Party ServicesThe following command launches the 'base' services (MinIO, Elasticsearch, Redis, and MySQL) using Docker Compose:@@ -64,7 +66,7 @@ The following command launches the 'base' services (MinIO, Elasticsearch, Redis,docker compose -f docker/docker-compose-base.yml up -d```-### Update `host` and `port` Settings for Third-party Services+### Update `host` and `port` Settings for Third-Party Services1. Add the following line to `/etc/hosts` to resolve all hosts specified in **docker/service_conf.yaml.template** to `127.0.0.1`:@@ -74,7 +76,7 @@ docker compose -f docker/docker-compose-base.yml up -d2. In **docker/service_conf.yaml.template**, update mysql port to `5455` and es port to `1200`, as specified in **docker/.env**.-### Launch the RAGFlow backend service+### Launch the RAGFlow Backend Service1. Comment out the `nginx` line in **docker/entrypoint.sh**.@@ -107,7 +109,7 @@ docker compose -f docker/docker-compose-base.yml up -dpython api/ragflow_server.py;```-### Launch the RAGFlow frontend service+### Launch the RAGFlow Frontend Service1. Navigate to the `web` directory and install the frontend dependencies:@@ -132,11 +134,11 @@ docker compose -f docker/docker-compose-base.yml up -d-### Access the RAGFlow service+### Access the RAGFlow ServiceIn your web browser, enter `http://127.0.0.1:<PORT>/`, ensuring the port number matches that shown in the screenshot above.-### Stop the RAGFlow service when the development is done+### Stop the RAGFlow Service When the Development Is Done1. Stop the RAGFlow frontend service:```bashdiff --git a/docs/develop/mcp/launch_mcp_server.md b/docs/develop/mcp/launch_mcp_server.mdindex 306b3425cf..eada002861 100644--- a/docs/develop/mcp/launch_mcp_server.md+++ b/docs/develop/mcp/launch_mcp_server.md@@ -1,11 +1,13 @@---sidebar_position: 1+title: Launch RAGFlow MCP Server+sidebar_label: Launch RAGFlow MCP Serverslug: /launch_mcp_serversidebar_custom_props: {categoryIcon: LucideTvMinimalPlay}----# Launch RAGFlow MCP server+# Launch RAGFlow MCP ServerLaunch an MCP server from source or via Docker.@@ -31,11 +33,11 @@ Once a connection is established, an MCP server communicates with its client inIf you wish to try out our MCP server without upgrading RAGFlow, community contributor [yiminghub2024](https://github.com/yiminghub2024) 👏 shares their recommended steps [here](#launch-an-mcp-server-without-upgrading-ragflow).:::-## Launch an MCP server+## Launch an MCP ServerYou can start an MCP server either from source code or via Docker.-### Launch from source code+### Launch from Source Code1. Ensure that a RAGFlow server v0.18.0+ is properly running.2. Launch the MCP server:@@ -66,7 +68,7 @@ The RAGFlow MCP server supports two transports: the legacy SSE transport (served### Launch from Docker-#### 1. Enable MCP server+#### 1. Enable MCP ServerThe MCP server is designed as an optional component that complements the RAGFlow server and disabled by default. To enable MCP server:@@ -111,7 +113,7 @@ Where:If you set `mcp-mode` to `host`, you must add the `--no-transport-streamable-http-enabled` flag, because the streamable-HTTP transport is not yet supported in host mode.:::-#### 2. Launch a RAGFlow server with an MCP server+#### 2. Launch a RAGFlow Server with an MCP ServerRun `docker compose -f docker-compose.yml up` to launch the RAGFlow server together with the MCP server.@@ -166,7 +168,7 @@ Run `docker compose -f docker-compose.yml up` to launch the RAGFlow server toget...```-#### Launch an MCP server without upgrading RAGFlow+#### Launch an MCP Server Without Upgrading RAGFlow:::info KUDOSThis section is contributed by our community contributor [yiminghub2024](https://github.com/yiminghub2024). 👏@@ -186,7 +188,7 @@ This section is contributed by our community contributor [yiminghub2024](https:/docker compose -f docker-compose.yml up -d```-### Check MCP server status+### Check MCP Server StatusRun the following to check the logs the RAGFlow server and the MCP server:@@ -194,15 +196,15 @@ Run the following to check the logs the RAGFlow server and the MCP server:docker logs docker-ragflow-cpu-1```-## Security considerations+## Security ConsiderationsAs MCP technology is still at early stage and no official best practices for authentication or authorization have been established, RAGFlow currently uses [API key](../acquire_ragflow_api_key.md) to validate identity for the operations described earlier. However, in public environments, this makeshift solution could expose your MCP server to potential network attacks. Therefore, when running a local SSE server, it is recommended to bind only to localhost (`127.0.0.1`) rather than to all interfaces (`0.0.0.0`).For further guidance, see the [official MCP documentation](https://modelcontextprotocol.io/docs/concepts/transports#security-considerations).-## Frequently asked questions+## Frequently Asked Questions-### When to use an API key for authentication?+### When to Use an API Key for Authentication?The use of an API key depends on the operating mode of your MCP server.diff --git a/docs/develop/mcp/mcp_client_example.md b/docs/develop/mcp/mcp_client_example.mdindex 4393eb53be..8f79394ed3 100644--- a/docs/develop/mcp/mcp_client_example.md+++ b/docs/develop/mcp/mcp_client_example.md@@ -1,18 +1,19 @@---sidebar_position: 3+title: RAGFlow MCP Client Examples+sidebar_label: RAGFlow MCP Client Examplesslug: /mcp_clientsidebar_custom_props: {categoryIcon: LucideBookMarked}-----# RAGFlow MCP client examples+# RAGFlow MCP Client ExamplesPython and curl MCP client examples.-------## Example MCP Python client+## Example MCP Python ClientWe provide a *prototype* MCP client example for testing [here](https://github.com/infiniflow/ragflow/blob/main/mcp/client/client.py).@@ -32,7 +33,7 @@ async with sse_client("http://localhost:9382/sse", headers={"Authorization": "YO```:::-## Use curl to interact with the RAGFlow MCP server+## Use Curl to Interact with the RAGFlow MCP ServerWhen interacting with the MCP server via HTTP requests, follow this initialization sequence:@@ -47,7 +48,7 @@ For more information about this initialization process, see [here](https://modelIn the following sections, we will walk you through a complete tool calling process.-### 1. Obtain a session ID+### 1. Obtain a Session IDEach curl request with the MCP server must include a session ID:@@ -70,7 +71,7 @@ event: endpointdata: /messages/?session_id=5c6600ef61b845a788ddf30dceb25c54```-### 2. Send an `Initialize` request+### 2. Send an `Initialize` RequestThe client sends an `initialize` request with protocol version and capabilities:@@ -104,7 +105,7 @@ event: messagedata: {"jsonrpc":"2.0","id":1,"result":{"protocolVersion":"2025-03-26","capabilities":{"experimental":{"headers":{"host":"127.0.0.1:9382","user-agent":"curl/8.7.1","accept":"*/*","api_key":"ragflow-xxxxxxxxxxxx","accept-encoding":"gzip"}},"tools":{"listChanged":false}},"serverInfo":{"name":"docker-ragflow-cpu-1","version":"1.9.4"}}}```-### 3. Acknowledge readiness+### 3. Acknowledge ReadinessThe client confirms readiness with an `initialized` notification:@@ -121,7 +122,7 @@ curl -X POST "http://127.0.0.1:9382/messages/?session_id=$session_id" \_The connection is established between the client and the server, and further operations (such as tool listing) may proceed._-### 4. Tool listing+### 4. Tool Listing```bashcurl -X POST "http://127.0.0.1:9382/messages/?session_id=$session_id" \@@ -143,7 +144,7 @@ data: {"jsonrpc":"2.0","id":3,"result":{"tools":[{"name":"ragflow_retrieval","de```-### 5. Tool calling+### 5. Tool Calling```bashcurl -X POST "http://127.0.0.1:9382/messages/?session_id=$session_id" \@@ -172,7 +173,7 @@ data: {"jsonrpc":"2.0","id":4,"result":{...}}```-### A complete curl example+### A Complete Curl Example```bashsession_id="YOUR_SESSION_ID" && \diff --git a/docs/develop/mcp/mcp_tools.md b/docs/develop/mcp/mcp_tools.mdindex 1a8be9f807..e248d8294b 100644--- a/docs/develop/mcp/mcp_tools.md+++ b/docs/develop/mcp/mcp_tools.md@@ -1,11 +1,13 @@---sidebar_position: 2+title: RAGFlow MCP Tools+sidebar_label: RAGFlow MCP Toolsslug: /mcp_toolssidebar_custom_props: {categoryIcon: LucideToolCase}----# RAGFlow MCP tools+# RAGFlow MCP ToolsThe MCP server currently offers a specialized tool to assist users in searching for relevant information powered by RAGFlow DeepDoc technology:diff --git a/docs/develop/switch_doc_engine.md b/docs/develop/switch_doc_engine.mdindex 10ff68eb99..5a0266915a 100644--- a/docs/develop/switch_doc_engine.md+++ b/docs/develop/switch_doc_engine.md@@ -1,11 +1,13 @@---sidebar_position: 3+title: Switch Document Engine+sidebar_label: Switch Document Engineslug: /switch_doc_enginesidebar_custom_props: {categoryIcon: LucideShuffle}----# Switch document engine+# Switch Document EngineSwitch your doc engine from Elasticsearch to Infinity.diff --git a/docs/guides/_category_.json b/docs/guides/_category_.jsonindex a5551f8b8b..0bb70d3e4c 100644--- a/docs/guides/_category_.json+++ b/docs/guides/_category_.json@@ -1,5 +1,5 @@{- "label": "User guides",+ "label": "User Guides","position": 3,"link": {"type": "generated-index",diff --git a/docs/guides/agent/agent_overview/purpose_of_agent.md b/docs/guides/agent/agent_overview/purpose_of_agent.mdindex 82daa289c2..b72a4226e7 100644--- a/docs/guides/agent/agent_overview/purpose_of_agent.md+++ b/docs/guides/agent/agent_overview/purpose_of_agent.md@@ -1,5 +1,7 @@---sidebar_position: 1+title: Purpose of Agent+sidebar_label: Purpose of Agentslug: /purpose_of_agentsidebar_custom_props: {categoryIcon: RagAiAgentdiff --git a/docs/guides/agent/agent_overview/relationship_between_agent_and_knowledge_base_qa.md b/docs/guides/agent/agent_overview/relationship_between_agent_and_knowledge_base_qa.mdindex b237535cb0..74692fdc2e 100644--- a/docs/guides/agent/agent_overview/relationship_between_agent_and_knowledge_base_qa.md+++ b/docs/guides/agent/agent_overview/relationship_between_agent_and_knowledge_base_qa.md@@ -1,5 +1,7 @@---sidebar_position: 2+title: "Relationship Between Agent and Knowledge Base Q&A"+sidebar_label: "Relationship Between Agent and Knowledge Base Q&A"slug: /relationship_between_agent_and_knowledge_base_qasidebar_custom_props: {categoryIcon: RagAiAgentdiff --git a/docs/guides/agent/agent_quickstarts/sandbox_quickstart.md b/docs/guides/agent/agent_quickstarts/sandbox_quickstart.mdindex c174fcfec7..96bf8ba8a4 100644--- a/docs/guides/agent/agent_quickstarts/sandbox_quickstart.md+++ b/docs/guides/agent/agent_quickstarts/sandbox_quickstart.md@@ -1,11 +1,13 @@---sidebar_position: 20+title: Sandbox Quickstart+sidebar_label: Sandbox Quickstartslug: /sandbox_quickstartsidebar_custom_props: {categoryIcon: LucideCodesandbox}----# Sandbox quickstart+# Sandbox QuickstartRAGFlow's `CodeExec` agent component needs a sandbox provider to run Python and JavaScript code.@@ -17,7 +19,7 @@ The simplest setup flow is:4. Choose a provider and save the configuration.5. Test the connection in the same page.-## Admin page+## Admin PageConfigure sandbox providers from the admin page:@@ -26,9 +28,8 @@ Configure sandbox providers from the admin page:- `ssh`: Runs code on a remote machine over SSH.- `aliyun_codeinterpreter`, `e2b`, and `tenki`: Cloud providers.-<img width="2547" height="1475" alt="admin-sandbox-settings" src="https://github.com/user-attachments/assets/59ab948e-b98a-45a8-9db4-f1afbf6c3685" />-## Provider options+## Provider OptionsRAGFlow supports multiple sandbox providers. Configure the active provider in@@ -78,11 +79,11 @@ Notes:The error message `client version 1.43 is too old. Minimum supported API version is 1.44` indicates that your executor manager image's built-in Docker CLI version is lower than `29.1.0` required by the Docker daemon in use.:::-## Build Docker base images+## Build Docker Base ImagesThe sandbox uses isolated base images for secure containerized execution environments.-### Option 1: Build from source+### Option 1: Build from SourceBuild the runtime base images:@@ -103,7 +104,7 @@ Build the executor manager image:docker build -t sandbox-executor-manager:latest ./executor_manager```-### Option 2: Pull base images from Docker Hub+### Option 2: Pull Base Images from Docker HubIf you do not need to customize runtime dependencies, pull the published base images and tag them with the names used by standalone Docker Compose:@@ -148,11 +149,11 @@ docker compose -f docker-compose.yml up -d8. Click **Save**.9. Click **Test Connection** if needed.-## Environment variables+## Environment VariablesThe variables in `docker/.env` are grouped by scope.-### System-level variables+### System-Level VariablesThese variables apply to sandbox support in general:@@ -161,7 +162,7 @@ These variables apply to sandbox support in general:- `SANDBOX_ARTIFACT_BUCKET`: MinIO bucket used for files generated by sandbox code.- `SANDBOX_ARTIFACT_EXPIRE_DAYS`: Number of days before sandbox artifacts expire.-### Self-managed deployment defaults+### Self-Managed Deployment DefaultsThese variables are shown in Admin as deployment defaults for `self_managed`.Changing them requires restarting `sandbox-executor-manager`.@@ -175,7 +176,7 @@ Changing them requires restarting `sandbox-executor-manager`.- `SANDBOX_MAX_MEMORY`: Memory limit for each sandbox runtime container.- `SANDBOX_TIMEOUT`: Default execution timeout.-### Admin-managed runtime settings+### Admin-Managed Runtime SettingsProvider selection and runtime settings are configured in **Admin > Sandbox Settings**.@@ -191,9 +192,9 @@ For `self_managed`:- Runtime settings are editable in Admin- Deployment defaults come from `.env` and are shown as read-only values-## Running standalone+## Running Standalone-### Manual setup+### Manual Setup1. Initialize the environment variables:diff --git a/docs/guides/agent/agent_workflow/basic_component_configuration.md b/docs/guides/agent/agent_workflow/basic_component_configuration.mdindex a1ad36fcfe..e7ed7aafcd 100644--- a/docs/guides/agent/agent_workflow/basic_component_configuration.md+++ b/docs/guides/agent/agent_workflow/basic_component_configuration.md@@ -1,5 +1,7 @@---sidebar_position: 1+title: Basic Component Configuration+sidebar_label: Basic Component Configurationslug: /basic_component_configurationsidebar_custom_props: {categoryIcon: RagAiAgentdiff --git a/docs/guides/agent/agent_workflow/data_manipulation_components.md b/docs/guides/agent/agent_workflow/data_manipulation_components.mdindex 6c88a93ad9..c6de0f8a74 100644--- a/docs/guides/agent/agent_workflow/data_manipulation_components.md+++ b/docs/guides/agent/agent_workflow/data_manipulation_components.md@@ -1,5 +1,7 @@---sidebar_position: 3+title: Data Manipulation Components+sidebar_label: Data Manipulation Componentsslug: /data_manipulation_componentssidebar_custom_props: {categoryIcon: RagAiAgentdiff --git a/docs/guides/agent/agent_workflow/flow_control_components.md b/docs/guides/agent/agent_workflow/flow_control_components.mdindex 88e27de8be..daad36e28b 100644--- a/docs/guides/agent/agent_workflow/flow_control_components.md+++ b/docs/guides/agent/agent_workflow/flow_control_components.md@@ -1,5 +1,7 @@---sidebar_position: 2+title: Flow Control Components+sidebar_label: Flow Control Componentsslug: /flow_control_componentssidebar_custom_props: {categoryIcon: RagAiAgentdiff --git a/docs/guides/agent/agent_workflow/tool_components.md b/docs/guides/agent/agent_workflow/tool_components.mdindex f1f1541b97..d933e81d39 100644--- a/docs/guides/agent/agent_workflow/tool_components.md+++ b/docs/guides/agent/agent_workflow/tool_components.md@@ -1,5 +1,7 @@---sidebar_position: 4+title: Tool Components+sidebar_label: Tool Componentsslug: /tool_componentssidebar_custom_props: {categoryIcon: RagAiAgent@@ -535,7 +537,7 @@ The component returns generated file information and downloadable output variabl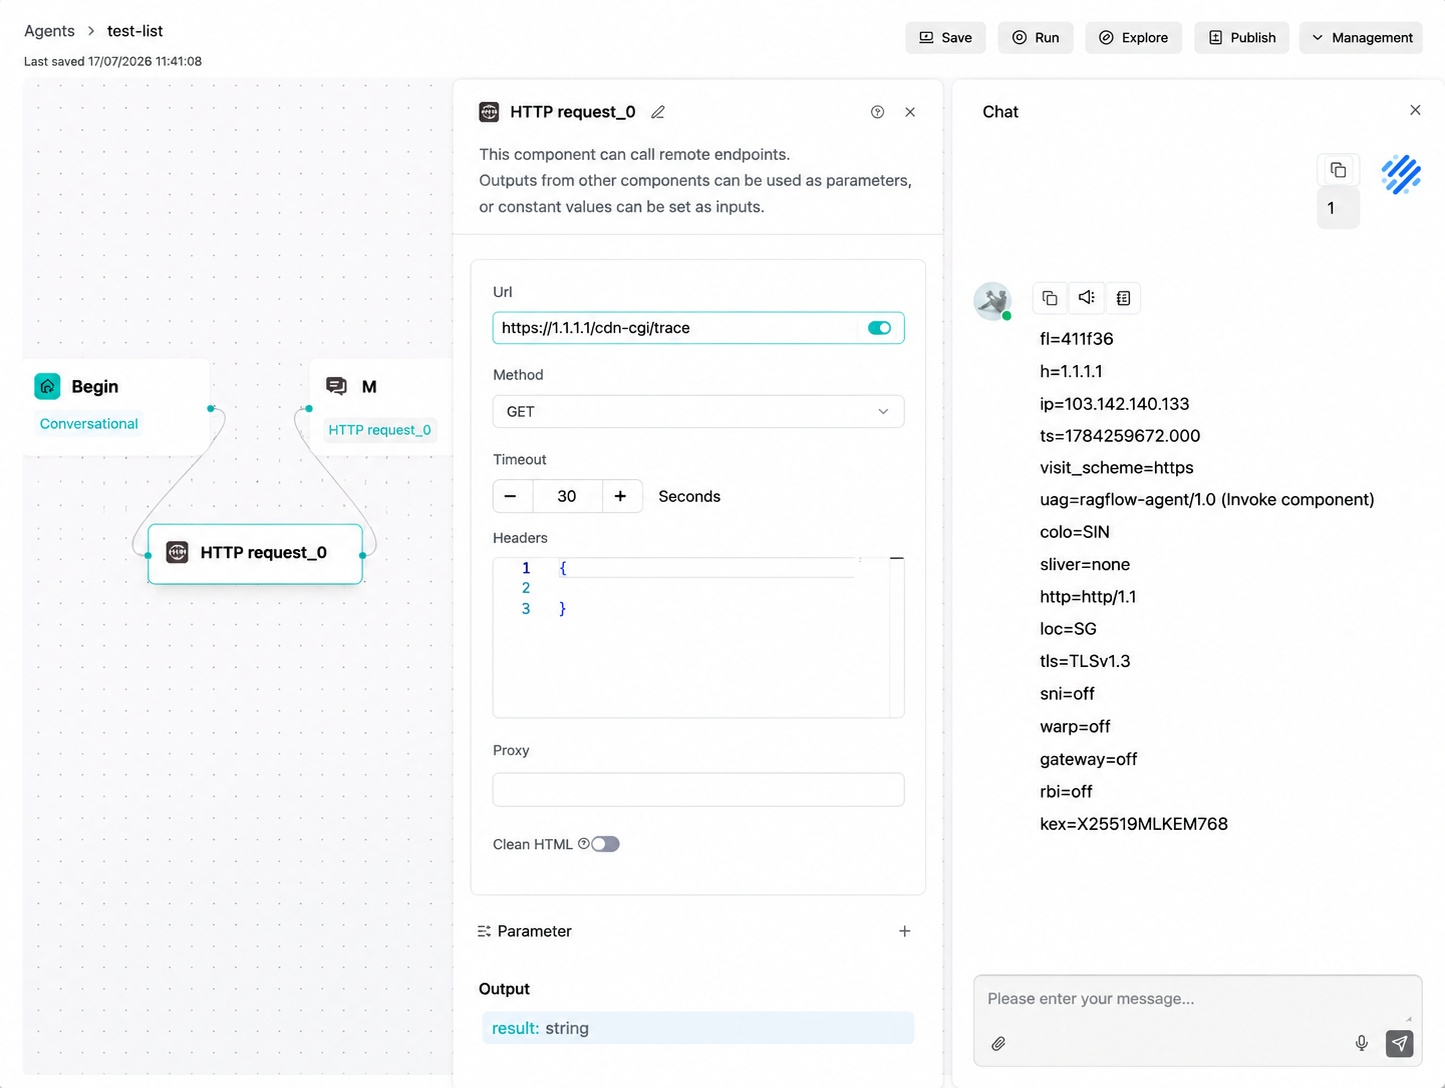-### Browser (Browser)+### BrowserBrowser performs browser-based automation tasks. It is suitable for opening pages, collecting page information and executing browser workflows that require visual interaction.diff --git a/docs/guides/agent/chapter_overview.md b/docs/guides/agent/chapter_overview.mddeleted file mode 100644index 8c291d4632..0000000000--- a/docs/guides/agent/chapter_overview.md+++ /dev/null@@ -1,14 +0,0 @@-----sidebar_position: 1-slug: /chapter_overview-sidebar_custom_props: {- categoryIcon: RagAiAgent-}------# Chapter Overview-This chapter introduces the creation, configuration, debugging and publishing methods of RAGFlow Agent. You can connect models, knowledge bases, tools and workflow control components through a visual canvas to build intelligent agent applications such as knowledge Q&A, business query, content processing and automated execution.--:::tip NOTE-Before using an Agent, please confirm that at least one available chat model has been configured. If the workflow needs to query knowledge bases, you also need to create knowledge bases in advance, upload files and complete parsing.-:::diff --git a/docs/guides/agent/creation_and_management/access_agent_page.md b/docs/guides/agent/creation_and_management/access_agent_page.mdindex 43e107c5fb..8f6f0df114 100644--- a/docs/guides/agent/creation_and_management/access_agent_page.md+++ b/docs/guides/agent/creation_and_management/access_agent_page.md@@ -1,5 +1,7 @@---sidebar_position: 1+title: Access Agent Page+sidebar_label: Access Agent Pageslug: /access_agent_pagesidebar_custom_props: {categoryIcon: RagAiAgentdiff --git a/docs/guides/agent/creation_and_management/create_from_blank_agent.md b/docs/guides/agent/creation_and_management/create_from_blank_agent.mdindex 372f8a361d..eb32cbe898 100644--- a/docs/guides/agent/creation_and_management/create_from_blank_agent.md+++ b/docs/guides/agent/creation_and_management/create_from_blank_agent.md@@ -1,5 +1,7 @@---sidebar_position: 3+title: Create from Blank Agent+sidebar_label: Create from Blank Agentslug: /create_from_blank_agentsidebar_custom_props: {categoryIcon: RagAiAgentdiff --git a/docs/guides/agent/creation_and_management/create_from_template.md b/docs/guides/agent/creation_and_management/create_from_template.mdindex 953b98d831..b0303e3182 100644--- a/docs/guides/agent/creation_and_management/create_from_template.md+++ b/docs/guides/agent/creation_and_management/create_from_template.md@@ -1,5 +1,7 @@---sidebar_position: 2+title: Create from Template+sidebar_label: Create from Templateslug: /create_from_templatesidebar_custom_props: {categoryIcon: RagAiAgentdiff --git a/docs/guides/agent/creation_and_management/save_agent.md b/docs/guides/agent/creation_and_management/save_agent.mdindex 09c1271ff1..d2eb382604 100644--- a/docs/guides/agent/creation_and_management/save_agent.md+++ b/docs/guides/agent/creation_and_management/save_agent.md@@ -1,5 +1,7 @@---sidebar_position: 5+title: Save Agent+sidebar_label: Save Agentslug: /save_agentsidebar_custom_props: {categoryIcon: RagAiAgentdiff --git a/docs/guides/agent/creation_and_management/search_copy_and_delete_agent.md b/docs/guides/agent/creation_and_management/search_copy_and_delete_agent.mdindex 7a0d661e8d..97b6efc4ae 100644--- a/docs/guides/agent/creation_and_management/search_copy_and_delete_agent.md+++ b/docs/guides/agent/creation_and_management/search_copy_and_delete_agent.md@@ -1,5 +1,7 @@---sidebar_position: 4+title: "Search, Copy and Delete Agent"+sidebar_label: "Search, Copy and Delete Agent"slug: /search_copy_and_delete_agentsidebar_custom_props: {categoryIcon: RagAiAgentdiff --git a/docs/guides/agent/embed_into_web_pages/embed_agent_via_webpage.md b/docs/guides/agent/embed_into_web_pages/embed_agent_via_webpage.mdindex 63667bf24a..d0dfbfee33 100644--- a/docs/guides/agent/embed_into_web_pages/embed_agent_via_webpage.md+++ b/docs/guides/agent/embed_into_web_pages/embed_agent_via_webpage.md@@ -1,15 +1,17 @@---sidebar_position: 1+title: Embed Agent Via Webpage+sidebar_label: Embed Agent Via Webpageslug: /embed_agent_via_webpagesidebar_custom_props: {categoryIcon: RagAiAgent}----# Embed Agent via Webpage+# Embed Agent Via WebpageYou can embed the Agent into third-party web pages using iframe.-Prerequisite: You must obtain an API Key. In Enterprise Edition, only Admin accounts can obtain the API Key.+Prerequisite: You must obtain an API Key.Steps:1. On the Agent page, click the target Agent to open its editing page.diff --git a/docs/guides/agent/import_and_export_agents/export_agent.md b/docs/guides/agent/import_and_export_agents/export_agent.mdindex d50ac0d3d0..8b908cd39f 100644--- a/docs/guides/agent/import_and_export_agents/export_agent.md+++ b/docs/guides/agent/import_and_export_agents/export_agent.md@@ -1,5 +1,7 @@---sidebar_position: 2+title: Export Agent+sidebar_label: Export Agentslug: /export_agentsidebar_custom_props: {categoryIcon: RagAiAgentdiff --git a/docs/guides/agent/import_and_export_agents/import_agent.md b/docs/guides/agent/import_and_export_agents/import_agent.mdindex f41f99acce..3f84650624 100644--- a/docs/guides/agent/import_and_export_agents/import_agent.md+++ b/docs/guides/agent/import_and_export_agents/import_agent.md@@ -1,5 +1,7 @@---sidebar_position: 1+title: Import Agent+sidebar_label: Import Agentslug: /import_agentsidebar_custom_props: {categoryIcon: RagAiAgentdiff --git a/docs/guides/agent/ingestion_pipeline/configure_chunker_component.md b/docs/guides/agent/ingestion_pipeline/configure_chunker_component.mdindex 399b80687c..4bcbb65895 100644--- a/docs/guides/agent/ingestion_pipeline/configure_chunker_component.md+++ b/docs/guides/agent/ingestion_pipeline/configure_chunker_component.md@@ -1,5 +1,7 @@---sidebar_position: 4+title: Configure the Chunker Component+sidebar_label: Configure the Chunker Componentslug: /configure_chunker_componentsidebar_custom_props: {categoryIcon: RagAiAgentdiff --git a/docs/guides/agent/ingestion_pipeline/configure_indexer_component.md b/docs/guides/agent/ingestion_pipeline/configure_indexer_component.mdindex 1ab344ee3e..875c3f9e79 100644--- a/docs/guides/agent/ingestion_pipeline/configure_indexer_component.md+++ b/docs/guides/agent/ingestion_pipeline/configure_indexer_component.md@@ -1,5 +1,7 @@---sidebar_position: 6+title: Configure the Indexer Component+sidebar_label: Configure the Indexer Componentslug: /configure_indexer_componentsidebar_custom_props: {categoryIcon: RagAiAgentdiff --git a/docs/guides/agent/ingestion_pipeline/configure_parser_component.md b/docs/guides/agent/ingestion_pipeline/configure_parser_component.mdindex b9ee6d857f..8aa89977f4 100644--- a/docs/guides/agent/ingestion_pipeline/configure_parser_component.md+++ b/docs/guides/agent/ingestion_pipeline/configure_parser_component.md@@ -1,5 +1,7 @@---sidebar_position: 3+title: Configure the Parser Component+sidebar_label: Configure the Parser Componentslug: /configure_parser_componentsidebar_custom_props: {categoryIcon: RagAiAgentdiff --git a/docs/guides/agent/ingestion_pipeline/configure_transformer_component.md b/docs/guides/agent/ingestion_pipeline/configure_transformer_component.mdindex 3a4f81c9a9..9c3ac33118 100644--- a/docs/guides/agent/ingestion_pipeline/configure_transformer_component.md+++ b/docs/guides/agent/ingestion_pipeline/configure_transformer_component.md@@ -1,5 +1,7 @@---sidebar_position: 5+title: Configure the Transformer Component+sidebar_label: Configure the Transformer Componentslug: /configure_transformer_componentsidebar_custom_props: {categoryIcon: RagAiAgentdiff --git a/docs/guides/agent/ingestion_pipeline/connect_the_pipeline_to_a_knowledge_base.md b/docs/guides/agent/ingestion_pipeline/connect_the_pipeline_to_a_knowledge_base.mdindex 7e5d4407c7..4996d97ee4 100644--- a/docs/guides/agent/ingestion_pipeline/connect_the_pipeline_to_a_knowledge_base.md+++ b/docs/guides/agent/ingestion_pipeline/connect_the_pipeline_to_a_knowledge_base.md@@ -1,5 +1,7 @@---sidebar_position: 8+title: Connect the Pipeline to a Knowledge Base+sidebar_label: Connect the Pipeline to a Knowledge Baseslug: /connect_the_pipeline_to_a_knowledge_basesidebar_custom_props: {categoryIcon: RagAiAgentdiff --git a/docs/guides/agent/ingestion_pipeline/create_ingestion_pipeline.md b/docs/guides/agent/ingestion_pipeline/create_ingestion_pipeline.mdindex ee05caa101..39682521e1 100644--- a/docs/guides/agent/ingestion_pipeline/create_ingestion_pipeline.md+++ b/docs/guides/agent/ingestion_pipeline/create_ingestion_pipeline.md@@ -1,5 +1,7 @@---sidebar_position: 2+title: Create an Ingestion Pipeline+sidebar_label: Create an Ingestion Pipelineslug: /create_ingestion_pipelinesidebar_custom_props: {categoryIcon: RagAiAgentdiff --git a/docs/guides/agent/ingestion_pipeline/test_run.md b/docs/guides/agent/ingestion_pipeline/test_run.mdindex 5dfe4937bb..54d761be6a 100644--- a/docs/guides/agent/ingestion_pipeline/test_run.md+++ b/docs/guides/agent/ingestion_pipeline/test_run.md@@ -1,5 +1,7 @@---sidebar_position: 7+title: Test Run+sidebar_label: Test Runslug: /test_runsidebar_custom_props: {categoryIcon: RagAiAgentdiff --git a/docs/guides/agent/ingestion_pipeline/understand_core_ingestion_pipeline_components.md b/docs/guides/agent/ingestion_pipeline/understand_core_ingestion_pipeline_components.mdindex f8a63d50eb..eef4effcdb 100644--- a/docs/guides/agent/ingestion_pipeline/understand_core_ingestion_pipeline_components.md+++ b/docs/guides/agent/ingestion_pipeline/understand_core_ingestion_pipeline_components.md@@ -1,5 +1,7 @@---sidebar_position: 1+title: Understand the Core Ingestion Pipeline Components+sidebar_label: Understand the Core Ingestion Pipeline Componentsslug: /understand_core_ingestion_pipeline_componentssidebar_custom_props: {categoryIcon: RagAiAgentdiff --git a/docs/guides/agent/understand_the_canvas/add_components.md b/docs/guides/agent/understand_the_canvas/add_components.mdindex 6e7443137b..8936582765 100644--- a/docs/guides/agent/understand_the_canvas/add_components.md+++ b/docs/guides/agent/understand_the_canvas/add_components.md@@ -1,5 +1,7 @@---sidebar_position: 1+title: Add Components+sidebar_label: Add Componentsslug: /add_componentssidebar_custom_props: {categoryIcon: RagAiAgentdiff --git a/docs/guides/agent/understand_the_canvas/component_connection_rules.md b/docs/guides/agent/understand_the_canvas/component_connection_rules.mdindex 69b029c92d..7720271454 100644--- a/docs/guides/agent/understand_the_canvas/component_connection_rules.md+++ b/docs/guides/agent/understand_the_canvas/component_connection_rules.md@@ -1,5 +1,7 @@---sidebar_position: 4+title: Component Connection Rules+sidebar_label: Component Connection Rulesslug: /component_connection_rulessidebar_custom_props: {categoryIcon: RagAiAgentdiff --git a/docs/guides/agent/understand_the_canvas/configuration_panel.md b/docs/guides/agent/understand_the_canvas/configuration_panel.mdindex d5d088732d..9d3f73d5e3 100644--- a/docs/guides/agent/understand_the_canvas/configuration_panel.md+++ b/docs/guides/agent/understand_the_canvas/configuration_panel.md@@ -1,5 +1,7 @@---sidebar_position: 5+title: Configuration Panel+sidebar_label: Configuration Panelslug: /configuration_panelsidebar_custom_props: {categoryIcon: RagAiAgentdiff --git a/docs/guides/agent/understand_the_canvas/save_and_run.md b/docs/guides/agent/understand_the_canvas/save_and_run.mdindex 54bac0ecc2..53ec24ea1e 100644--- a/docs/guides/agent/understand_the_canvas/save_and_run.md+++ b/docs/guides/agent/understand_the_canvas/save_and_run.md@@ -1,5 +1,7 @@---sidebar_position: 3+title: "Save & Run"+sidebar_label: "Save & Run"slug: /save_and_runsidebar_custom_props: {categoryIcon: RagAiAgentdiff --git a/docs/guides/agent/understand_the_canvas/use_variables.md b/docs/guides/agent/understand_the_canvas/use_variables.mdindex f96dda7920..1c8b9b536a 100644--- a/docs/guides/agent/understand_the_canvas/use_variables.md+++ b/docs/guides/agent/understand_the_canvas/use_variables.md@@ -1,5 +1,7 @@---sidebar_position: 2+title: Use Variables+sidebar_label: Use Variablesslug: /use_variablessidebar_custom_props: {categoryIcon: RagAiAgentdiff --git a/docs/guides/ai_search.md b/docs/guides/ai_search.mdindex 1f257d2911..54cdb7fbd7 100644--- a/docs/guides/ai_search.md+++ b/docs/guides/ai_search.md@@ -1,5 +1,7 @@---sidebar_position: 2+title: Search+sidebar_label: Searchslug: /ai_searchsidebar_custom_props: {categoryIcon: LucideSearch@@ -26,8 +28,8 @@ When debugging your chat assistant, you can use AI search as a reference to veri- Ensure that you have configured the system's default models on the **Model providers** page.- Ensure that the intended datasets are properly configured and the intended documents have finished file parsing.-## Frequently asked questions+## Frequently Asked Questions-### Key difference between an AI search and an AI chat?+### Key Difference Between an AI Search and an AI Chat?A chat is a multi-turn AI conversation where you can define your retrieval strategy (a weighted reranking score can be used to replace the weighted vector similarity in a hybrid search) and choose your chat model. In an AI chat, you can configure advanced RAG strategies, such as knowledge graphs, auto-keyword, and auto-question, for your specific case. Retrieved chunks are not displayed along with the answer.diff --git a/docs/guides/chat/best_practices/_category_.json b/docs/guides/chat/best_practices/_category_.jsonindex a0e97731fb..8aa1f9b9fb 100644--- a/docs/guides/chat/best_practices/_category_.json+++ b/docs/guides/chat/best_practices/_category_.json@@ -1,5 +1,5 @@{- "label": "Best practices",+ "label": "Best Practices","position": 7,"link": {"type": "generated-index",diff --git a/docs/guides/chat/best_practices/accelerate_question_answering.mdx b/docs/guides/chat/best_practices/accelerate_question_answering.mdxindex af4d2521b1..d00304fc8f 100644--- a/docs/guides/chat/best_practices/accelerate_question_answering.mdx+++ b/docs/guides/chat/best_practices/accelerate_question_answering.mdx@@ -1,9 +1,11 @@---sidebar_position: 1+title: Accelerate Answering+sidebar_label: Accelerate Answeringslug: /accelerate_question_answering----# Accelerate answering+# Accelerate Answeringimport APITable from '@site/src/components/APITable';A checklist to speed up question answering for your chat assistant.@@ -23,7 +25,6 @@ Please note that rerank models are essential in certain scenarios. There is alwa- Disabling **Keyword analysis** will reduce the time to receive an answer from the LLM.- When chatting with your chat assistant, click the light bulb icon above the *current* dialogue and scroll down the popup window to view the time taken for each task:- ```mdx-code-blockdiff --git a/docs/guides/chat/implement_deep_research.md b/docs/guides/chat/implement_deep_research.mdindex 21f58f1e9f..6dd1eee86c 100644--- a/docs/guides/chat/implement_deep_research.md+++ b/docs/guides/chat/implement_deep_research.md@@ -1,19 +1,20 @@---sidebar_position: 3+title: Implement Deep Research+sidebar_label: Implement Deep Researchslug: /implement_deep_researchsidebar_custom_props: {categoryIcon: LucideScanSearch}----# Implement deep research+# Implement Deep ResearchImplements deep research for agentic reasoning.----From v0.17.0 onward, RAGFlow supports integrating agentic reasoning in an AI chat. The following diagram illustrates the workflow of RAGFlow's deep research:+From v0.17.0 onward, RAGFlow supports integrating agentic reasoning in an AI chat.-To activate this feature:@@ -24,7 +25,3 @@ To activate this feature:2. Enter the correct Tavily API key to leverage Tavily-based web search: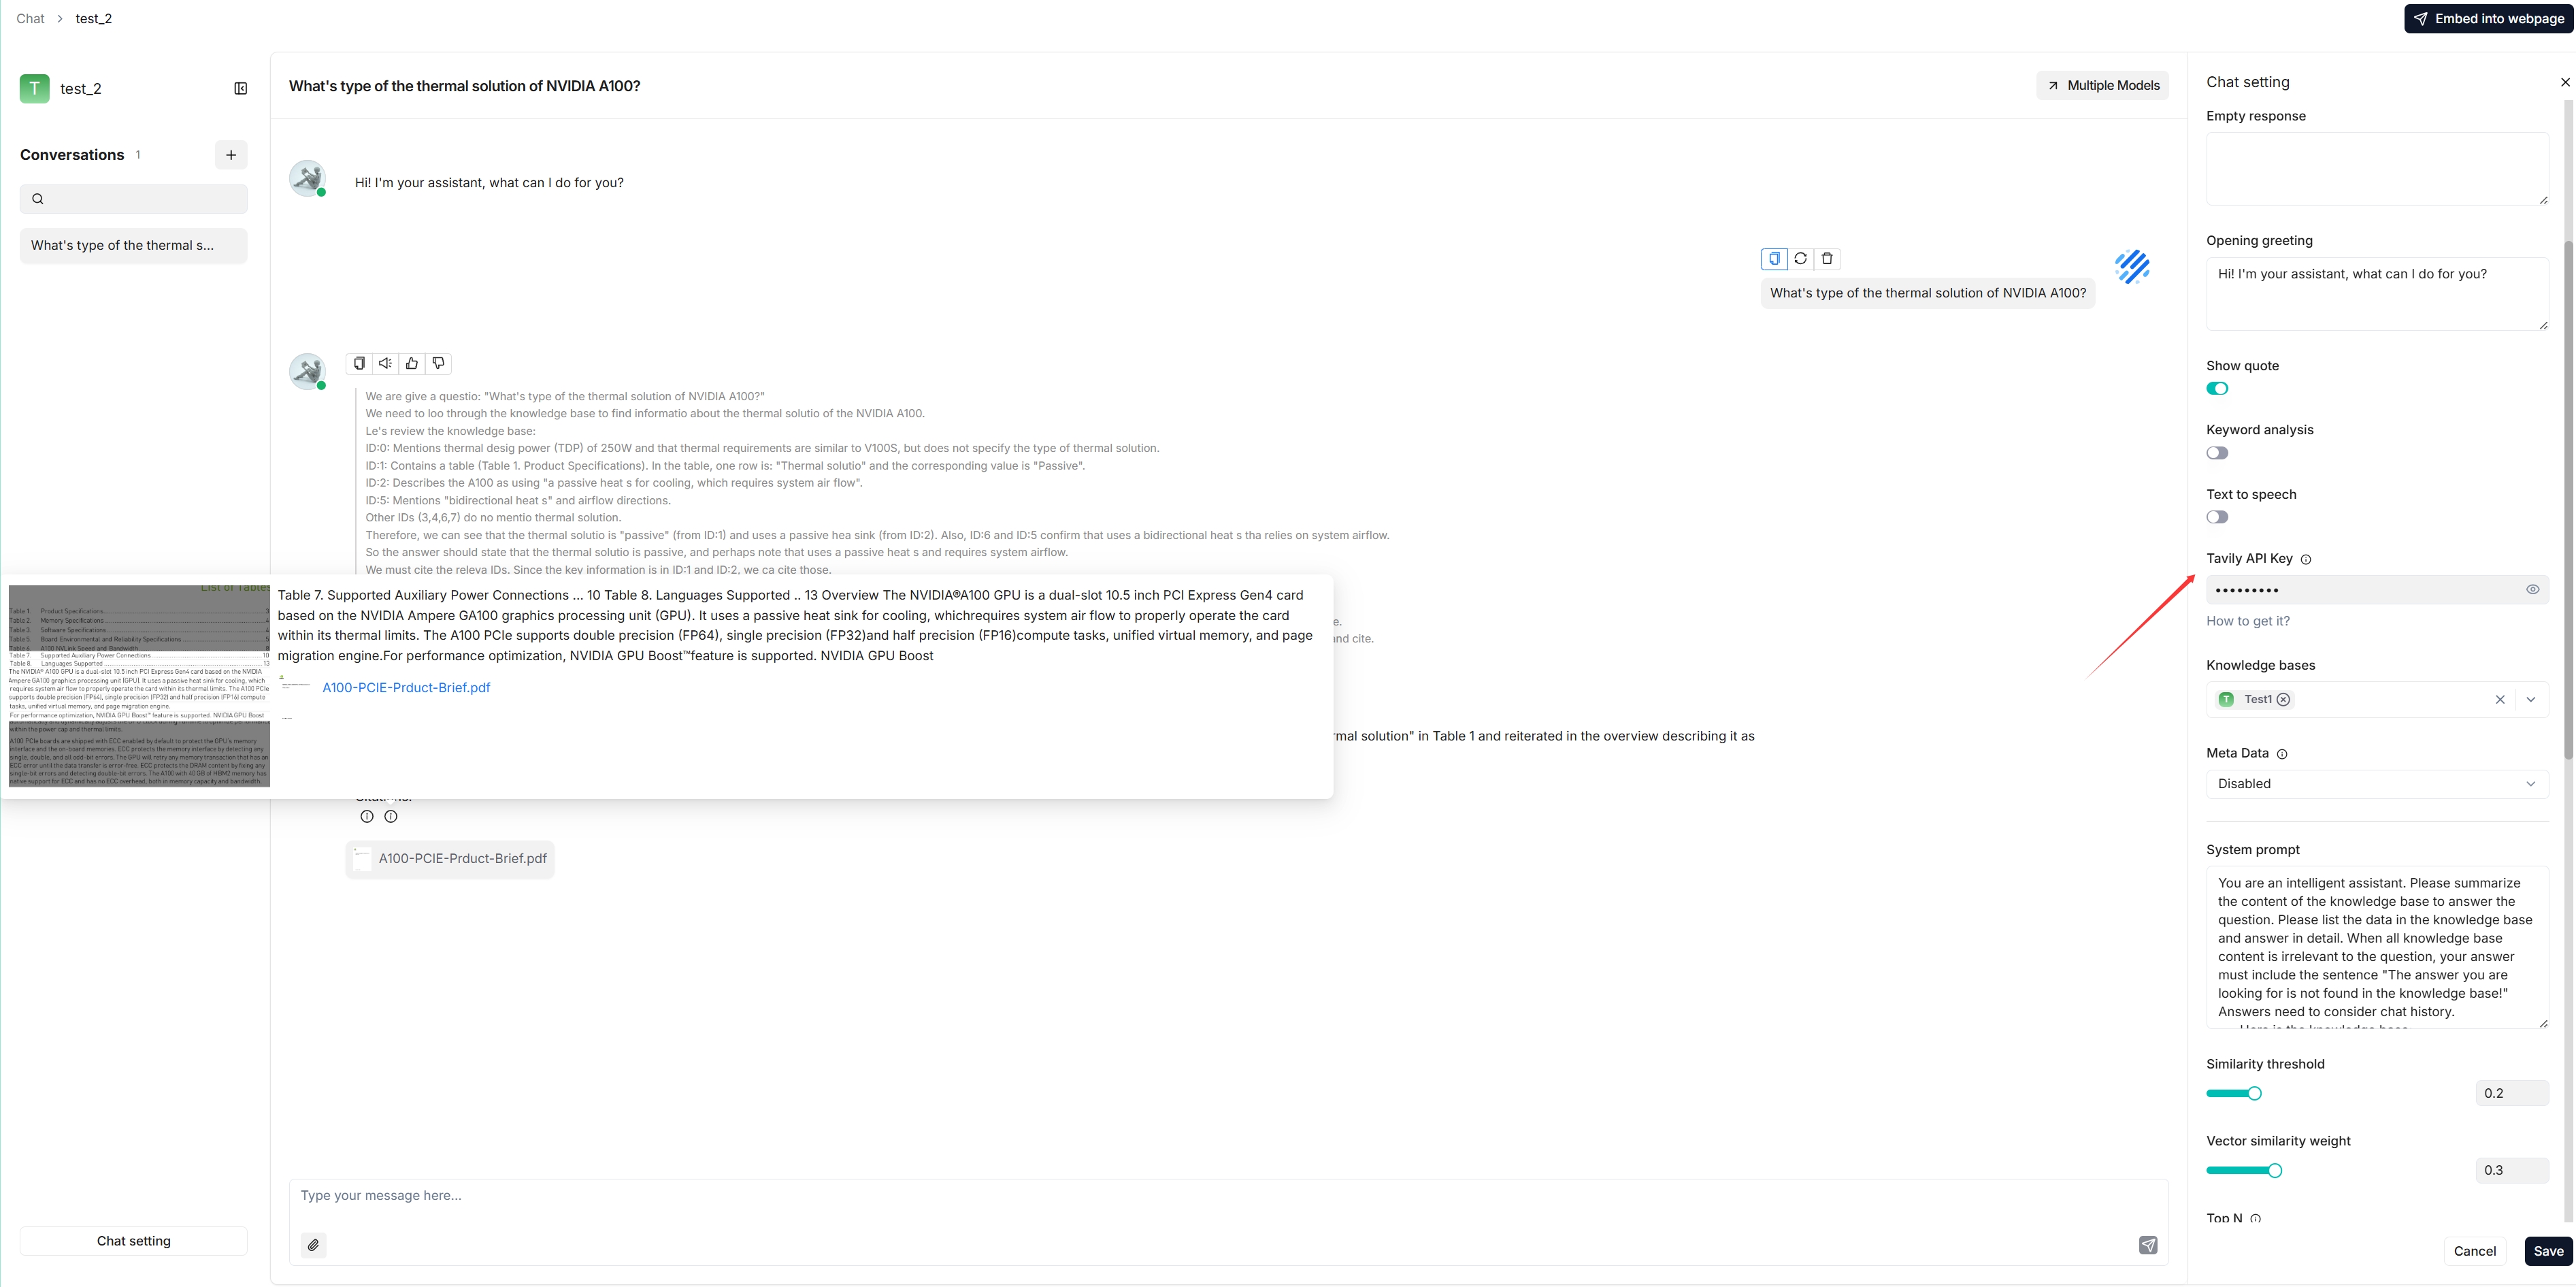--*The following is a screenshot of a conversation that integrates Deep research:*--\ No newline at end of filediff --git a/docs/guides/chat/set_chat_variables.md b/docs/guides/chat/set_chat_variables.mdindex 8f396345b7..22ab55508d 100644--- a/docs/guides/chat/set_chat_variables.md+++ b/docs/guides/chat/set_chat_variables.md@@ -1,11 +1,13 @@---sidebar_position: 4+title: Set Variables+sidebar_label: Set Variablesslug: /set_chat_variablessidebar_custom_props: {categoryIcon: LucideVariable}----# Set variables+# Set VariablesSet variables to be used together with the system prompt for your LLM.@@ -17,15 +19,15 @@ When configuring the system prompt for a chat model, variables play an importantIn RAGFlow, variables are closely linked with the system prompt. When you add a variable in the **Variable** section, include it in the system prompt. Conversely, when deleting a variable, ensure it is removed from the system prompt; otherwise, an error would occur.:::-## Where to set variables+## Where to Set Variables-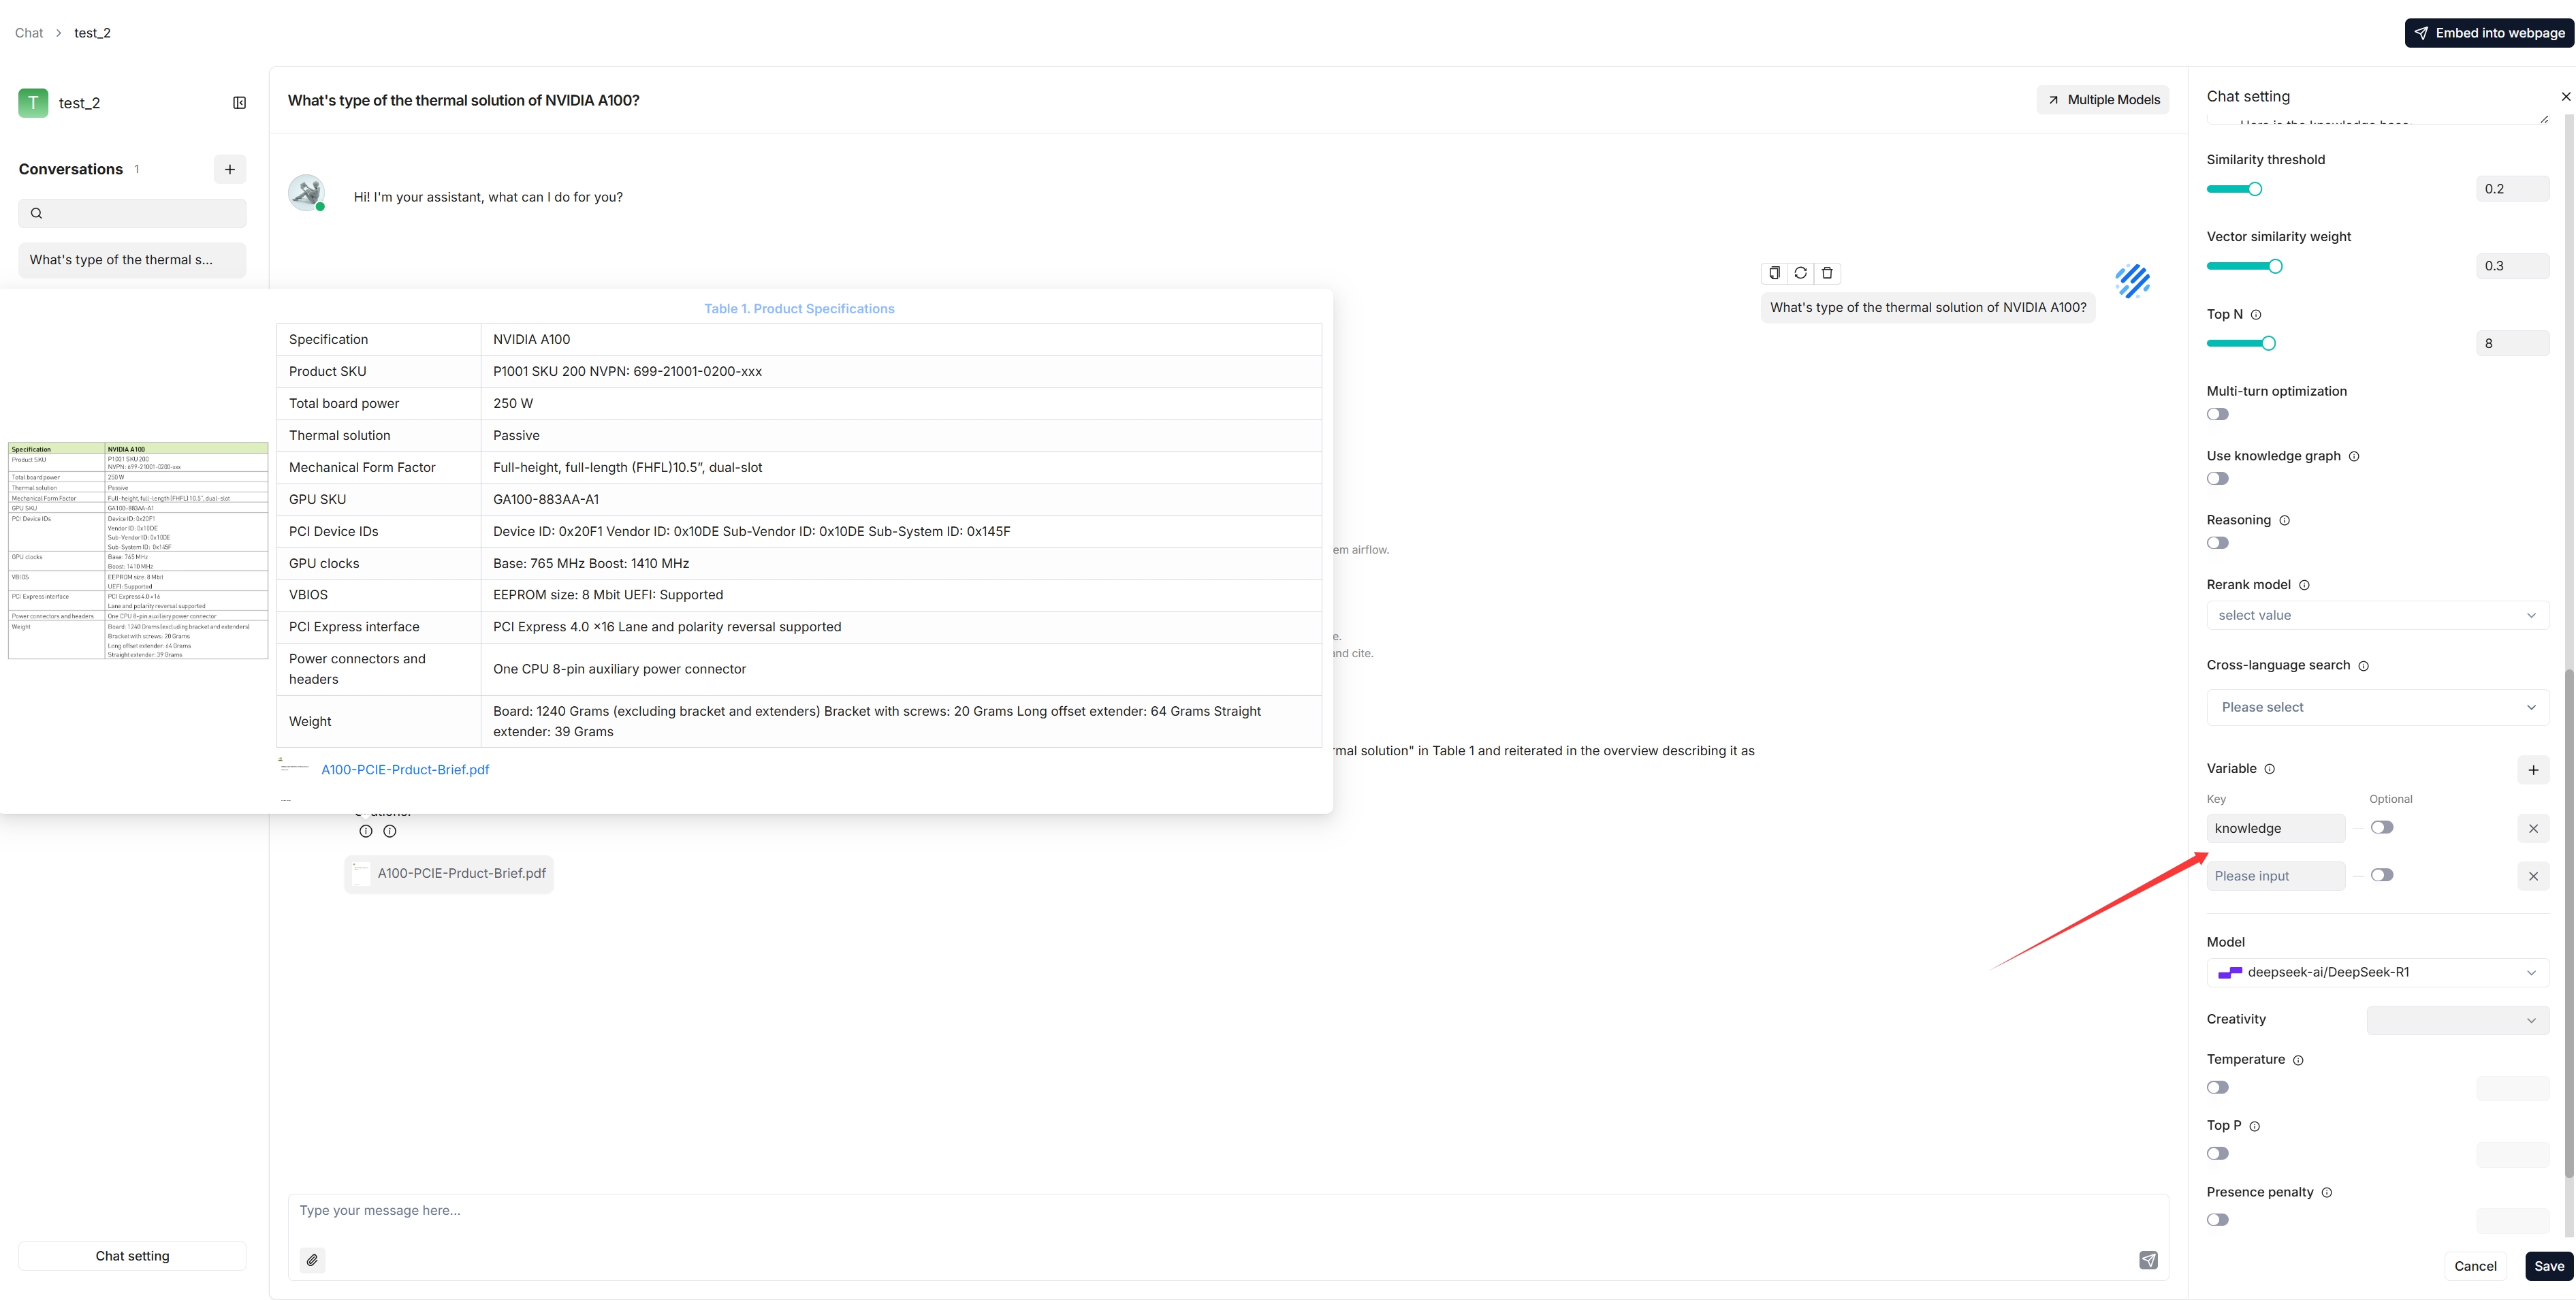+-## 1. Manage variables+## 1. Manage VariablesIn the **Variable** section, you add, remove, or update variables.-### `{knowledge}` - a reserved variable+### `{knowledge}` - A Reserved Variable`{knowledge}` is the system's reserved variable, representing the chunks retrieved from the dataset(s) specified by **Knowledge bases** under the **Assistant settings** tab. If your chat assistant is associated with certain datasets, you can keep it as is.@@ -35,14 +37,14 @@ It currently makes no difference whether `{knowledge}` is set as optional or maFrom v0.17.0 onward, you can start an AI chat without specifying datasets. In this case, we recommend removing the `{knowledge}` variable to prevent unnecessary reference and keeping the **Empty response** field empty to avoid errors.-### Custom variables+### Custom VariablesBesides `{knowledge}`, you can also define your own variables to pair with the system prompt. To use these custom variables, you must pass in their values through RAGFlow's official APIs. The **Optional** toggle determines whether these variables are required in the corresponding APIs:- **Disabled** (Default): The variable is mandatory and must be provided.- **Enabled**: The variable is optional and can be omitted if not needed.-## 2. Update system prompt+## 2. Update System PromptAfter you add or remove variables in the **Variable** section, ensure your changes are reflected in the system prompt to avoid inconsistencies or errors. Here's an example:diff --git a/docs/guides/chat/start_chat.md b/docs/guides/chat/start_chat.mdindex 501b9fabb7..02b51c0f7f 100644--- a/docs/guides/chat/start_chat.md+++ b/docs/guides/chat/start_chat.md@@ -1,11 +1,13 @@---sidebar_position: 1+title: Start AI Chat+sidebar_label: Start AI Chatslug: /start_chatsidebar_custom_props: {categoryIcon: LucideBot}----# Start AI chat+# Start AI ChatInitiate an AI-powered chat with a configured chat assistant.@@ -13,7 +15,7 @@ Initiate an AI-powered chat with a configured chat assistant.Chats in RAGFlow are based on a particular dataset or multiple datasets. Once you have created your dataset, finished file parsing, and [run a retrieval test](../dataset/run_retrieval_test.md), you can go ahead and start an AI conversation.-## Start an AI chat+## Start an AI ChatYou start an AI conversation by creating an assistant.@@ -94,11 +96,11 @@ You start an AI conversation by creating an assistant.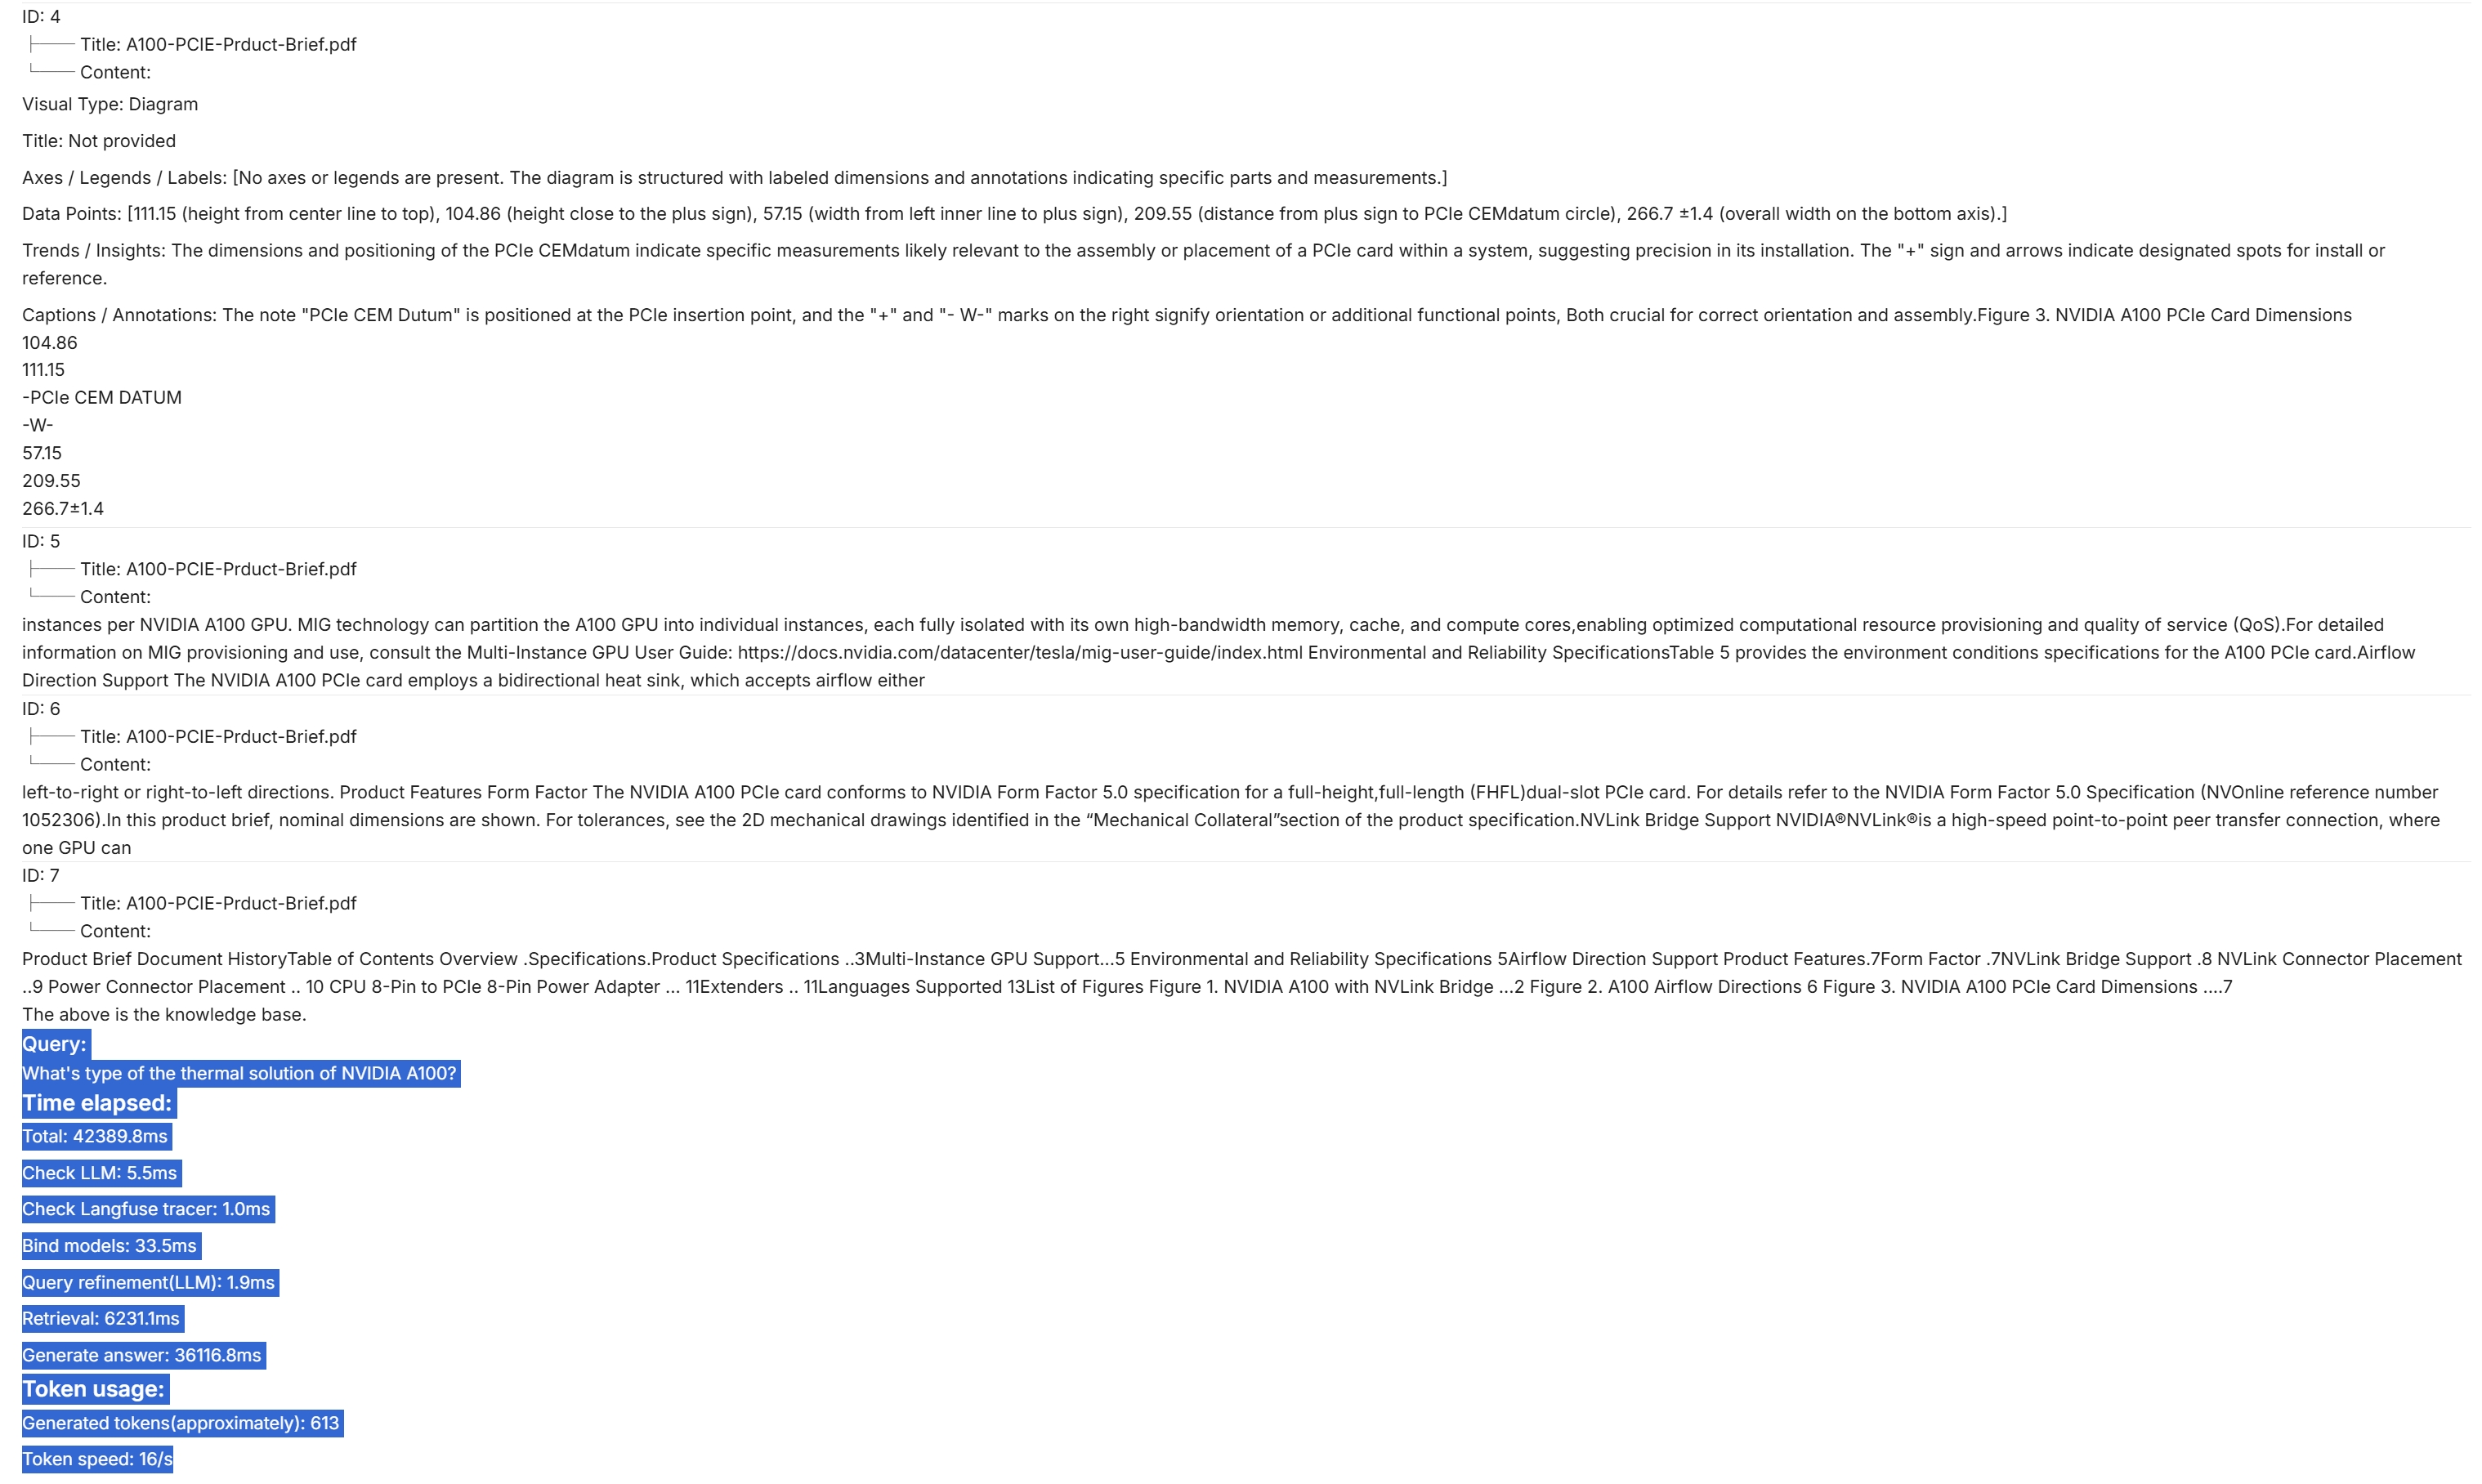:::-## Update settings of an existing chat assistant+## Update Settings of an Existing Chat Assistant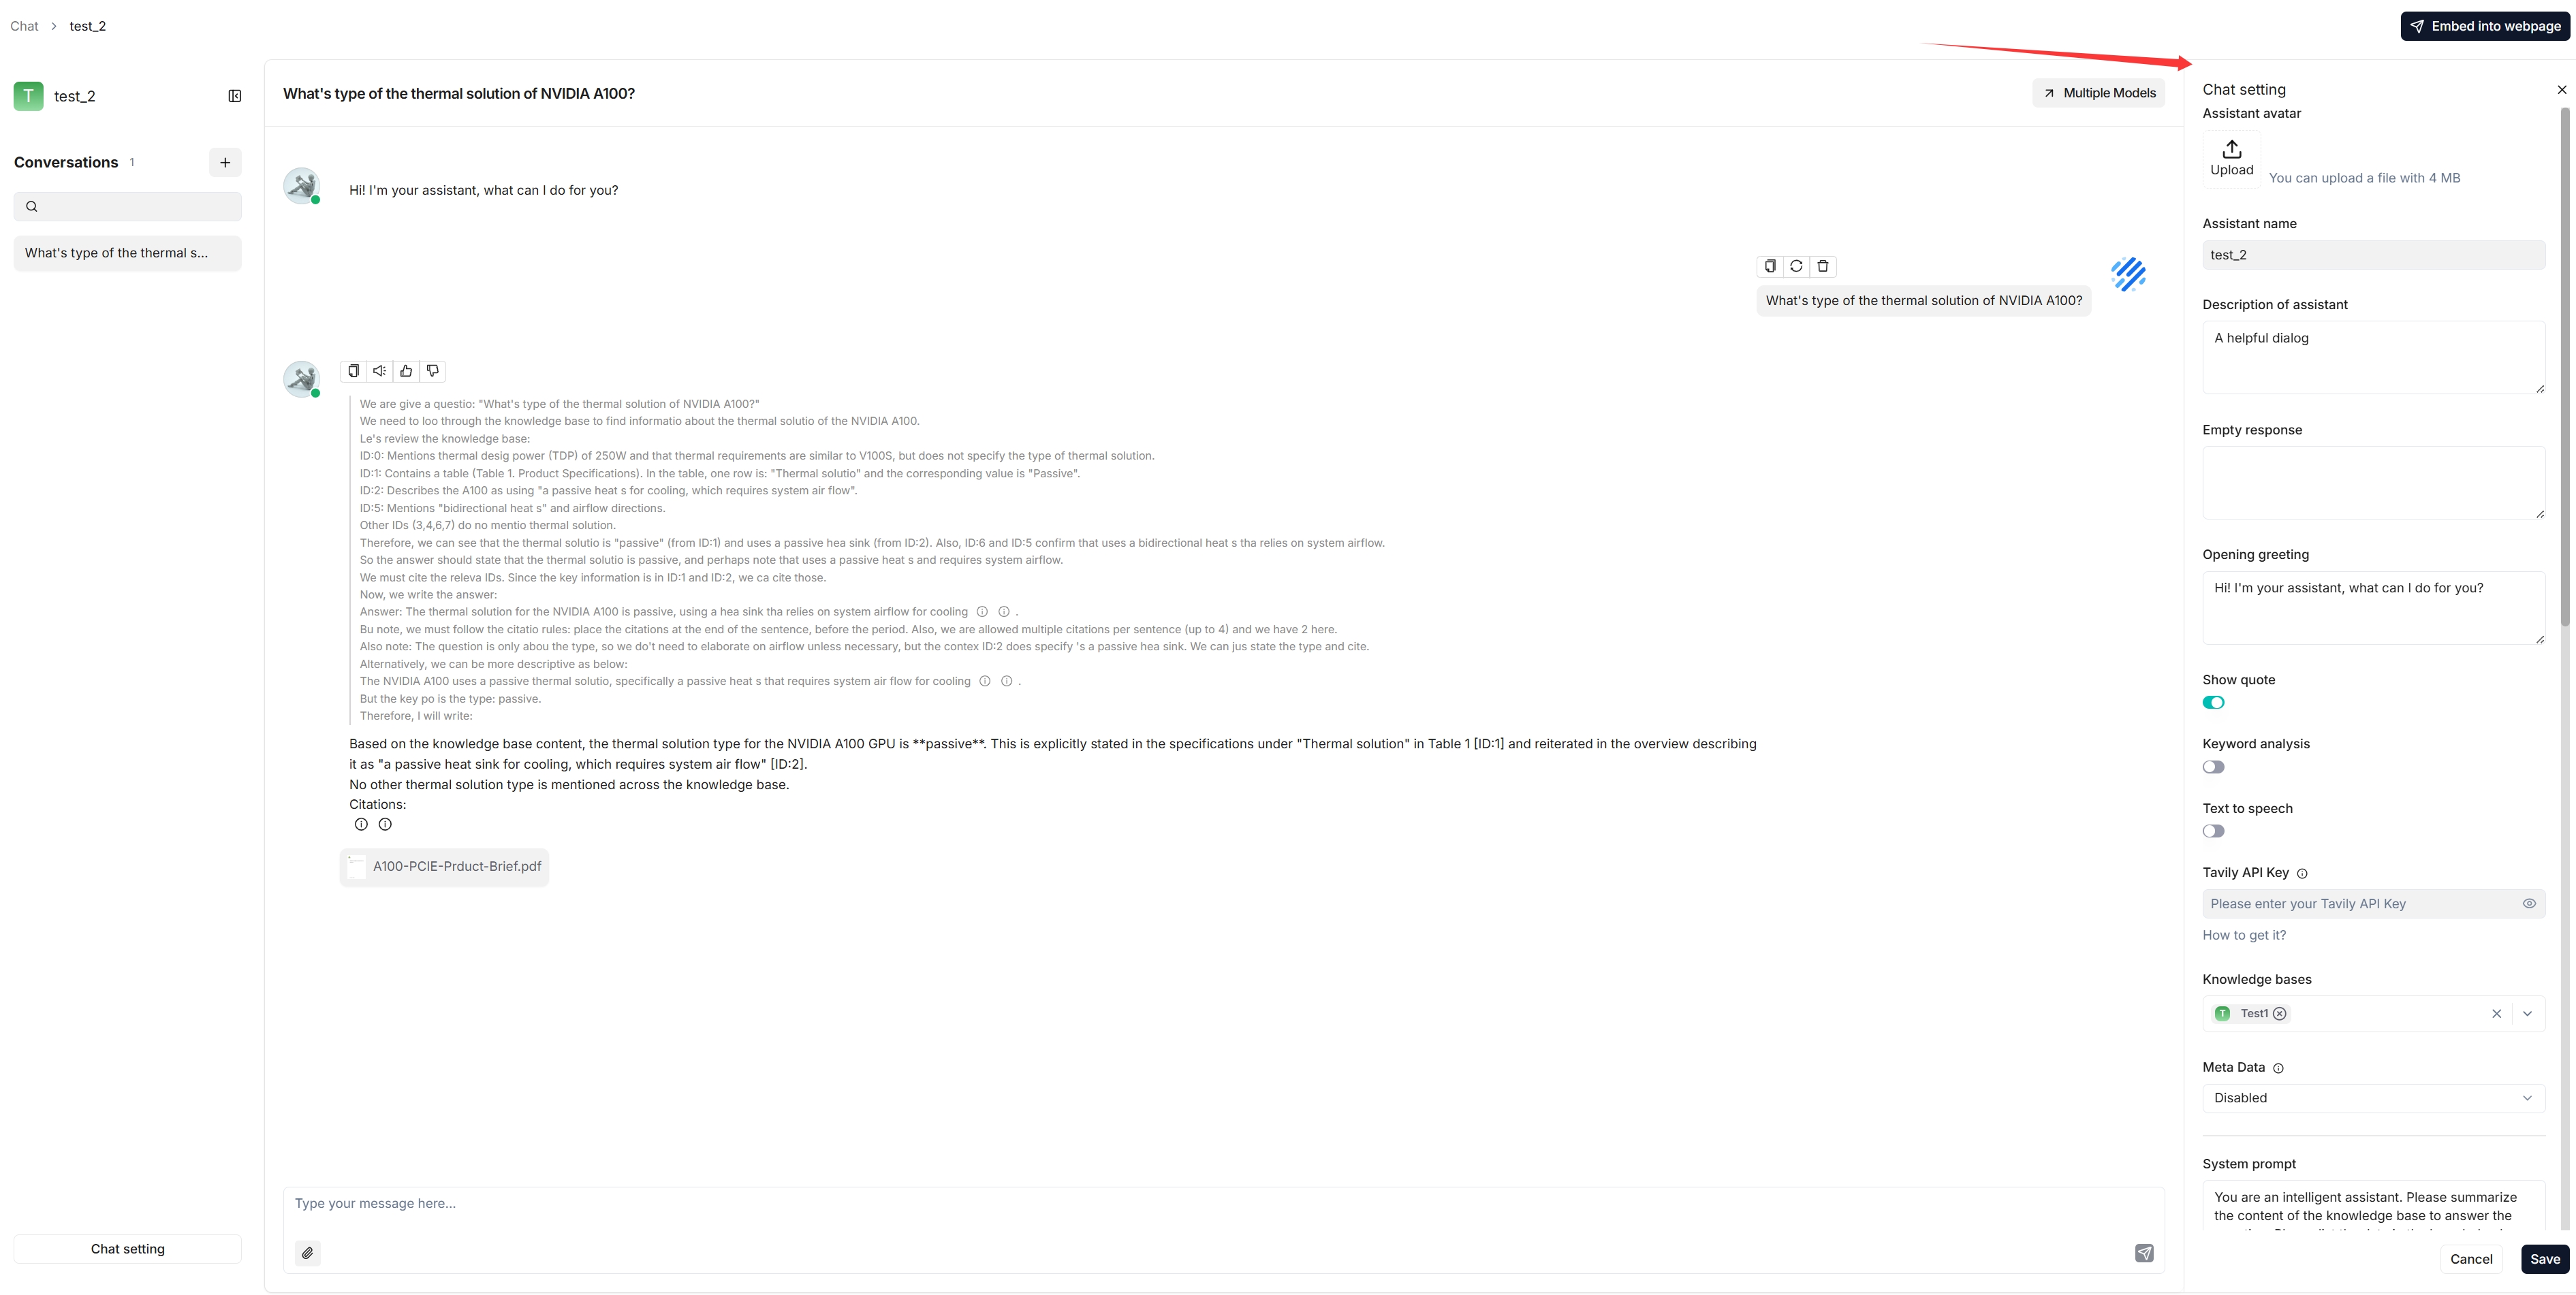-## Integrate chat capabilities into your application or webpage+## Integrate Chat Capabilities into Your Application or WebpageRAGFlow offers HTTP and Python APIs for you to integrate RAGFlow's capabilities into your applications. Read the following documents for more information:diff --git a/docs/guides/dataset/add_data_source/_category_.json b/docs/guides/dataset/add_data_source/_category_.jsonindex e4ba51baf4..5decae389f 100644--- a/docs/guides/dataset/add_data_source/_category_.json+++ b/docs/guides/dataset/add_data_source/_category_.json@@ -1,5 +1,5 @@{- "label": "Add data sources",+ "label": "Add Data Sources","position": 18,"link": {"type": "generated-index",diff --git a/docs/guides/dataset/add_data_source/add_bitbucket.md b/docs/guides/dataset/add_data_source/add_bitbucket.mdindex 1c31ddec3f..15f868e20d 100644--- a/docs/guides/dataset/add_data_source/add_bitbucket.md+++ b/docs/guides/dataset/add_data_source/add_bitbucket.md@@ -1,5 +1,7 @@---sidebar_position: 16+title: Add Bitbucket+sidebar_label: Add Bitbucketslug: /add_confluencesidebar_custom_props: {categoryIcon: SiGoogledrive@@ -22,9 +24,9 @@ Before starting, ensure you have the following:- **Repository URL:** The full URL of the repository you wish to index.- **Workspace ID:** The unique identifier for your Bitbucket workspace.-## Configuration steps+## Configuration Steps-### Define Bitbucket as an external data source+### Define Bitbucket as an External Data SourceNavigate to the **Connectors** or **External Data Source** section in the RAGFlow Admin Panel and select **Bitbucket**. Fill in the connector details in the popup window:@@ -41,7 +43,7 @@ Navigate to the **Connectors** or **External Data Source** section in the RAGFlo*RAGFlow validates the connection immediately and indexes all pull requests from the specified repos or projects.*-### Link to a dataset+### Link to a DatasetCredentials alone do not trigger indexing. You must link the data source to a specific dataset:diff --git a/docs/guides/dataset/add_data_source/add_confluence.md b/docs/guides/dataset/add_data_source/add_confluence.mdindex 273ceb107f..b41bf01355 100644--- a/docs/guides/dataset/add_data_source/add_confluence.md+++ b/docs/guides/dataset/add_data_source/add_confluence.md@@ -1,5 +1,7 @@---sidebar_position: 4+title: Add Confluence+sidebar_label: Add Confluenceslug: /add_confluencesidebar_custom_props: {categoryIcon: SiGoogledrive@@ -22,9 +24,9 @@ Before configuring the connector, obtain the following credentials from your Atl- **Atlassian API Token**: Generated via [Atlassian Account Settings](https://id.atlassian.com/manage-profile/security/api-tokens).- **Confluence base URL**: The instance URL (e.g., `https://<your-org>.atlassian.net/wiki`).-## Configuration steps+## Configuration Steps-### Define Confluence as an external data source+### Define Confluence as an External Data SourceNavigate to the **Connectors** or **External Data Source** section in the RAGFlow Admin Panel and select **Confluence**. Enter the following in the popup window:@@ -48,7 +50,7 @@ Once configuration is complete, click **Confirm** to save your changes.*RAGFlow validates the connection immediately.*-### Link to a dataset+### Link to a DatasetCredentials alone do not trigger indexing. You must link the data source to a specific dataset:diff --git a/docs/guides/dataset/add_data_source/add_discord.md b/docs/guides/dataset/add_data_source/add_discord.mdindex fb0adef0bb..39a9bf79d9 100644--- a/docs/guides/dataset/add_data_source/add_discord.md+++ b/docs/guides/dataset/add_data_source/add_discord.md@@ -1,5 +1,7 @@---sidebar_position: 7+title: Add Discord+sidebar_label: Add Discordslug: /add_discordsidebar_custom_props: {categoryIcon: SiGoogledrive@@ -19,7 +21,7 @@ This guide outlines how to ingest messages from your Discord servers into RAGFlo- Administrative privileges for the target Discord server.- Permissions to add data sources within your RAGFlow environment.-## Setting up a Discord bot+## Setting Up a Discord BotYou need a bot application to access and read messages from your server securely.@@ -29,7 +31,7 @@ You need a bot application to access and read messages from your server securely- Scroll down to the "Privileged Gateway Intents" section and toggle on "Message Content Intent" so the application can extract message text.- Click "Reset Token" to generate your bot token. Copy this token immediately and store it safely.-## Invite the bot to your server+## Invite the Bot to Your ServerThe bot must be authorized to view the specific channels you intend to sync.@@ -39,7 +41,7 @@ The bot must be authorized to view the specific channels you intend to sync.- Copy the resulting URL generated at the bottom of the screen.- Open this URL in your browser, select your desired server from the dropdown, and approve the authorization prompt.-## Configure the connection in RAGFlow+## Configure the Connection in RAGFlowWith the bot active in your server, you can finalize the integration inside RAGFlow.@@ -50,7 +52,7 @@ With the bot active in your server, you can finalize the integration inside RAGF- Save your settings to establish the connection.- Attach this newly created Discord data source to your target dataset to begin syncing your conversations.-### Link to a dataset+### Link to a Dataset1. Navigate to the **Dataset** tab.2. Select or create the target Dataset.diff --git a/docs/guides/dataset/add_data_source/add_github_repo.md b/docs/guides/dataset/add_data_source/add_github_repo.mdindex 578406fee1..beb6d3a178 100644--- a/docs/guides/dataset/add_data_source/add_github_repo.md+++ b/docs/guides/dataset/add_data_source/add_github_repo.md@@ -1,12 +1,14 @@---sidebar_position: 15+title: Add GitHub Repo+sidebar_label: Add GitHub Reposlug: /add_github_reposidebar_custom_props: {categoryIcon: SiGoogledrive}----# Add GitHub repo+# Add GitHub RepoLink your GitHub repo for pull request or issue synchronization.@@ -14,11 +16,11 @@ Link your GitHub repo for pull request or issue synchronization.This document explains how to link your GitHub repository to RAGFlow to synchronize pull requests and issues.-## 1. GitHub configuration+## 1. GitHub ConfigurationBefore configuring RAGFlow, you must prepare your GitHub account and generate the necessary credentials.-### Step a: Public email configuration+### Step A: Public Email ConfigurationTo ensure smooth identity matching and permission synchronization between your organization and the RAG engine, it is a best practice to make your email visible.@@ -26,7 +28,7 @@ To ensure smooth identity matching and permission synchronization between your o2. Uncheck "Keep my email addresses private".3. Go to **Public profile** and ensure your primary email is selected in the **Public email** dropdown.-### Step b: Generate a personal access token (PAT)+### Step B: Generate a Personal Access Token (PAT)1. Navigate to **Settings** > **Developer settings** > **Personal access tokens** > **Tokens (classic)**.2. Click **Generate new token (classic)**.@@ -35,7 +37,7 @@ To ensure smooth identity matching and permission synchronization between your o- **`workflow` (Optional):** Recommended if you intend to index GitHub Action logs or CI/CD metadata.4. **Copy the token:** Save this immediately; it will not be displayed again.-## 2. RAGFlow connector setup+## 2. RAGFlow Connector SetupOnce your GitHub token is ready, register the external data source within your RAGFlow instance.@@ -57,7 +59,7 @@ Once your GitHub token is ready, register the external data source within your RCurrently deleted or modified files are not synchronized automatically. This feature is coming soon. Thanks to Gisselle-Gonzalez for requesting [this feature](https://github.com/infiniflow/ragflow/issues/13708).:::-## 3. Dataset binding & ingestion+## 3. Dataset Binding & IngestionFinally, link the connector to a specific knowledge base to begin the RAG process.diff --git a/docs/guides/dataset/add_data_source/add_google_drive.md b/docs/guides/dataset/add_data_source/add_google_drive.mdindex 65d509305a..7a289ee431 100644--- a/docs/guides/dataset/add_data_source/add_google_drive.md+++ b/docs/guides/dataset/add_data_source/add_google_drive.md@@ -1,5 +1,7 @@---sidebar_position: 3+title: Add Google Drive+sidebar_label: Add Google Driveslug: /add_google_drivesidebar_custom_props: {categoryIcon: SiGoogledrive@@ -14,17 +16,17 @@ Add Google Drive as one of the data sources in RAGFlow.This document provides step-by-step instructions for integrating Google Drive as a data source in RAGFlow.-## 1. Create a Google Cloud project+## 1. Create a Google Cloud ProjectYou can either create a dedicated project for RAGFlow or use an existing Google Cloud external project. In this case, we create a Google Cloud project from scratch:1. Open the project creation page `https://console.cloud.google.com/projectcreate`:-+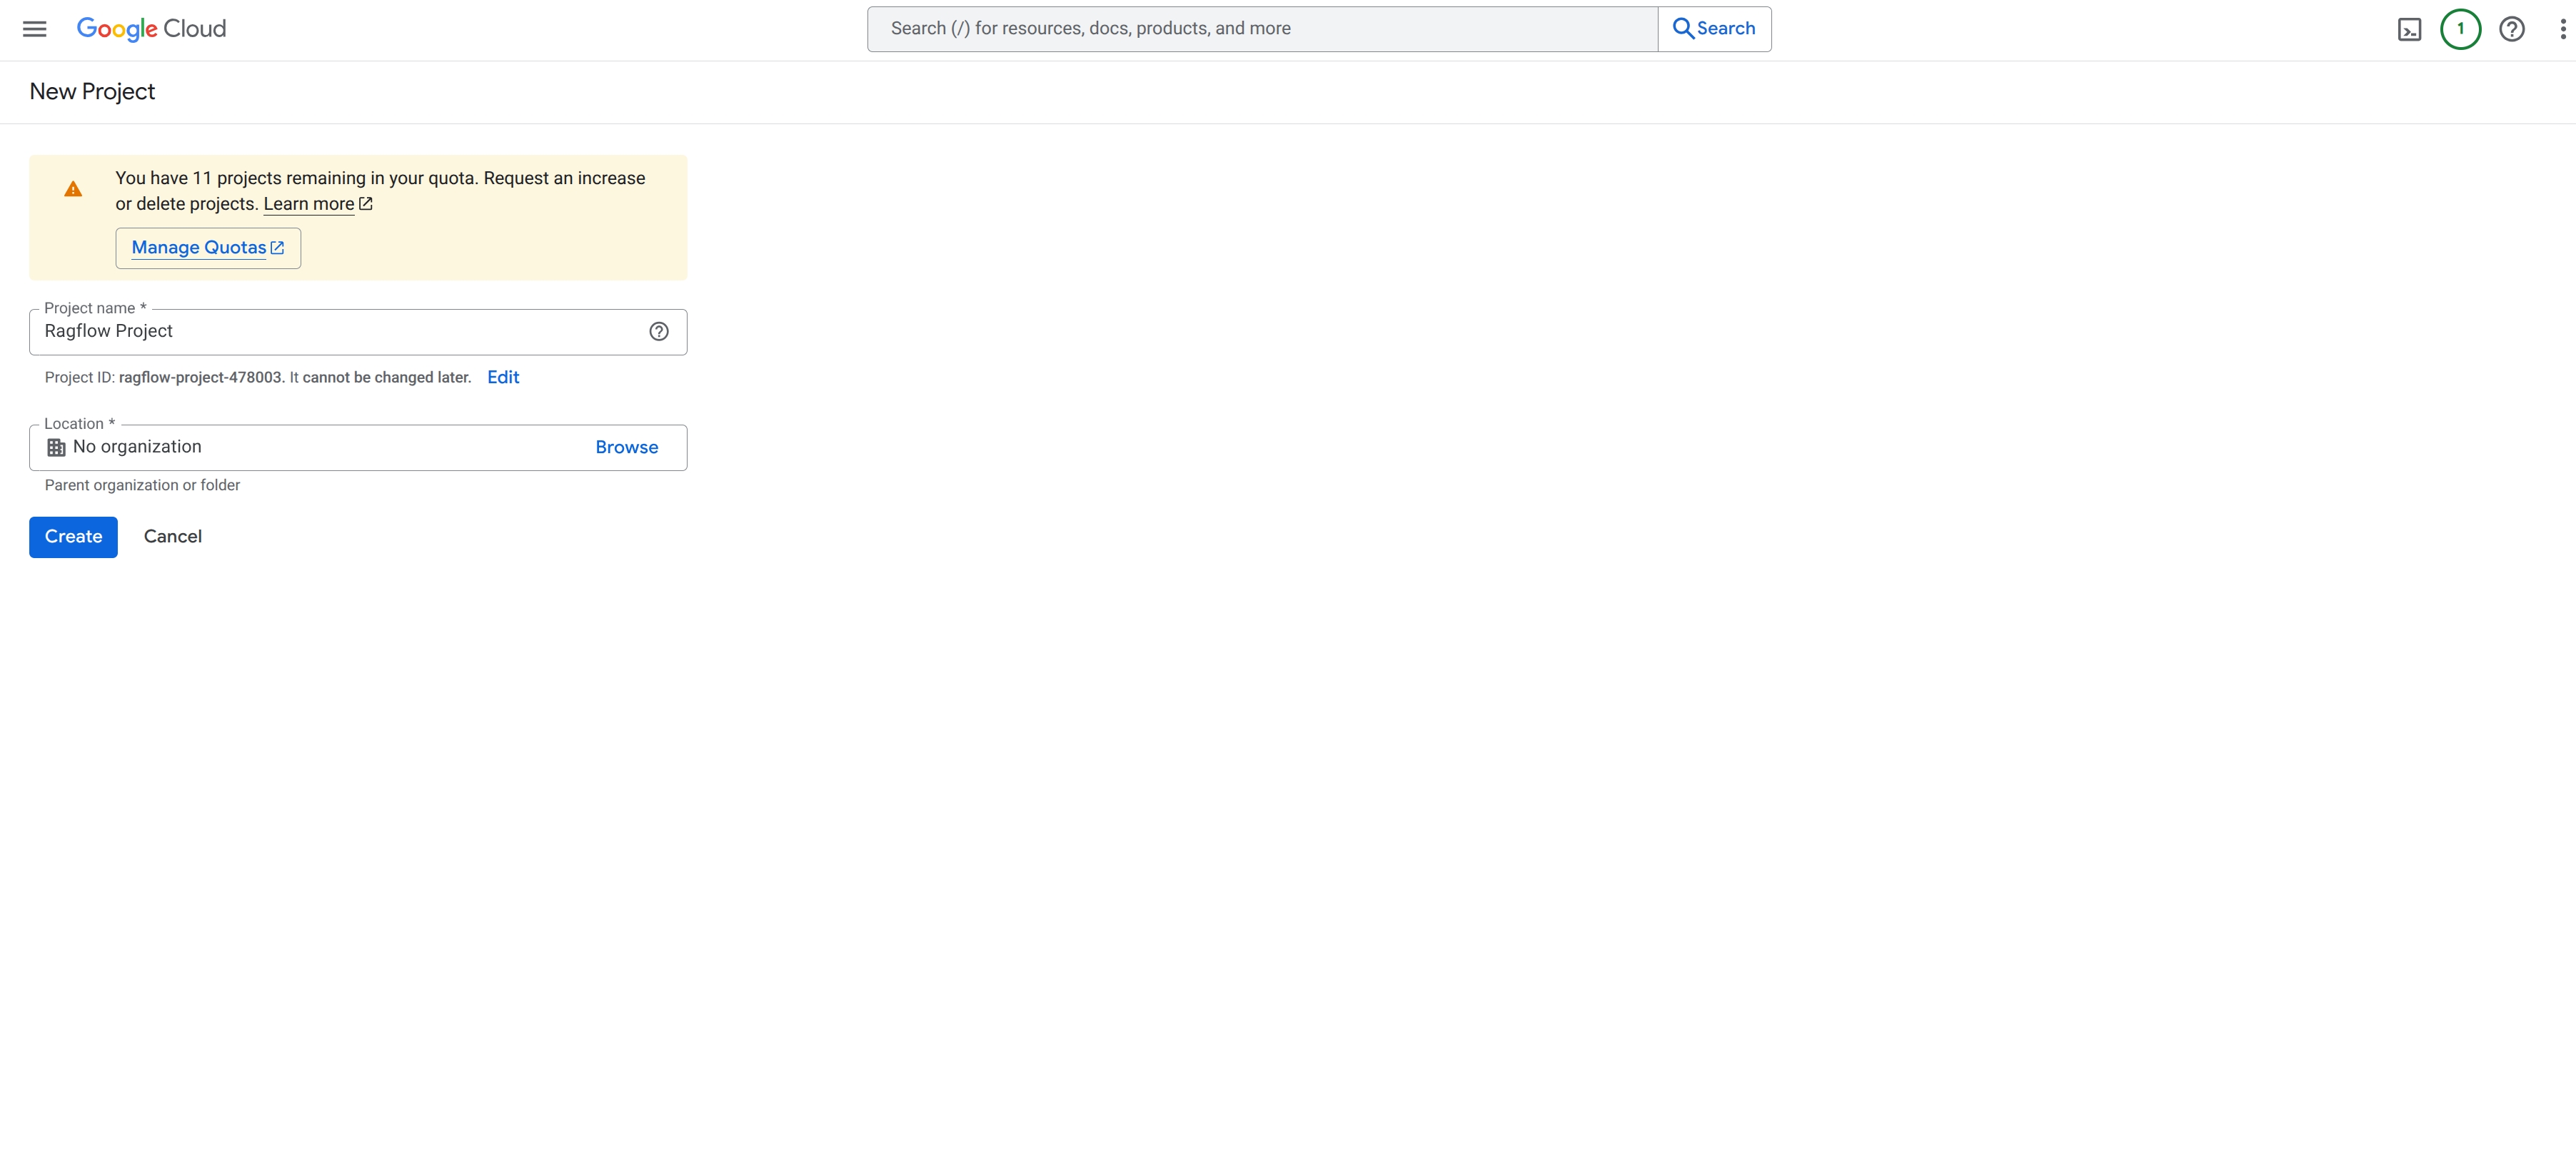2. Under **App Information**, provide an App name and your Gmail account as user support email:-+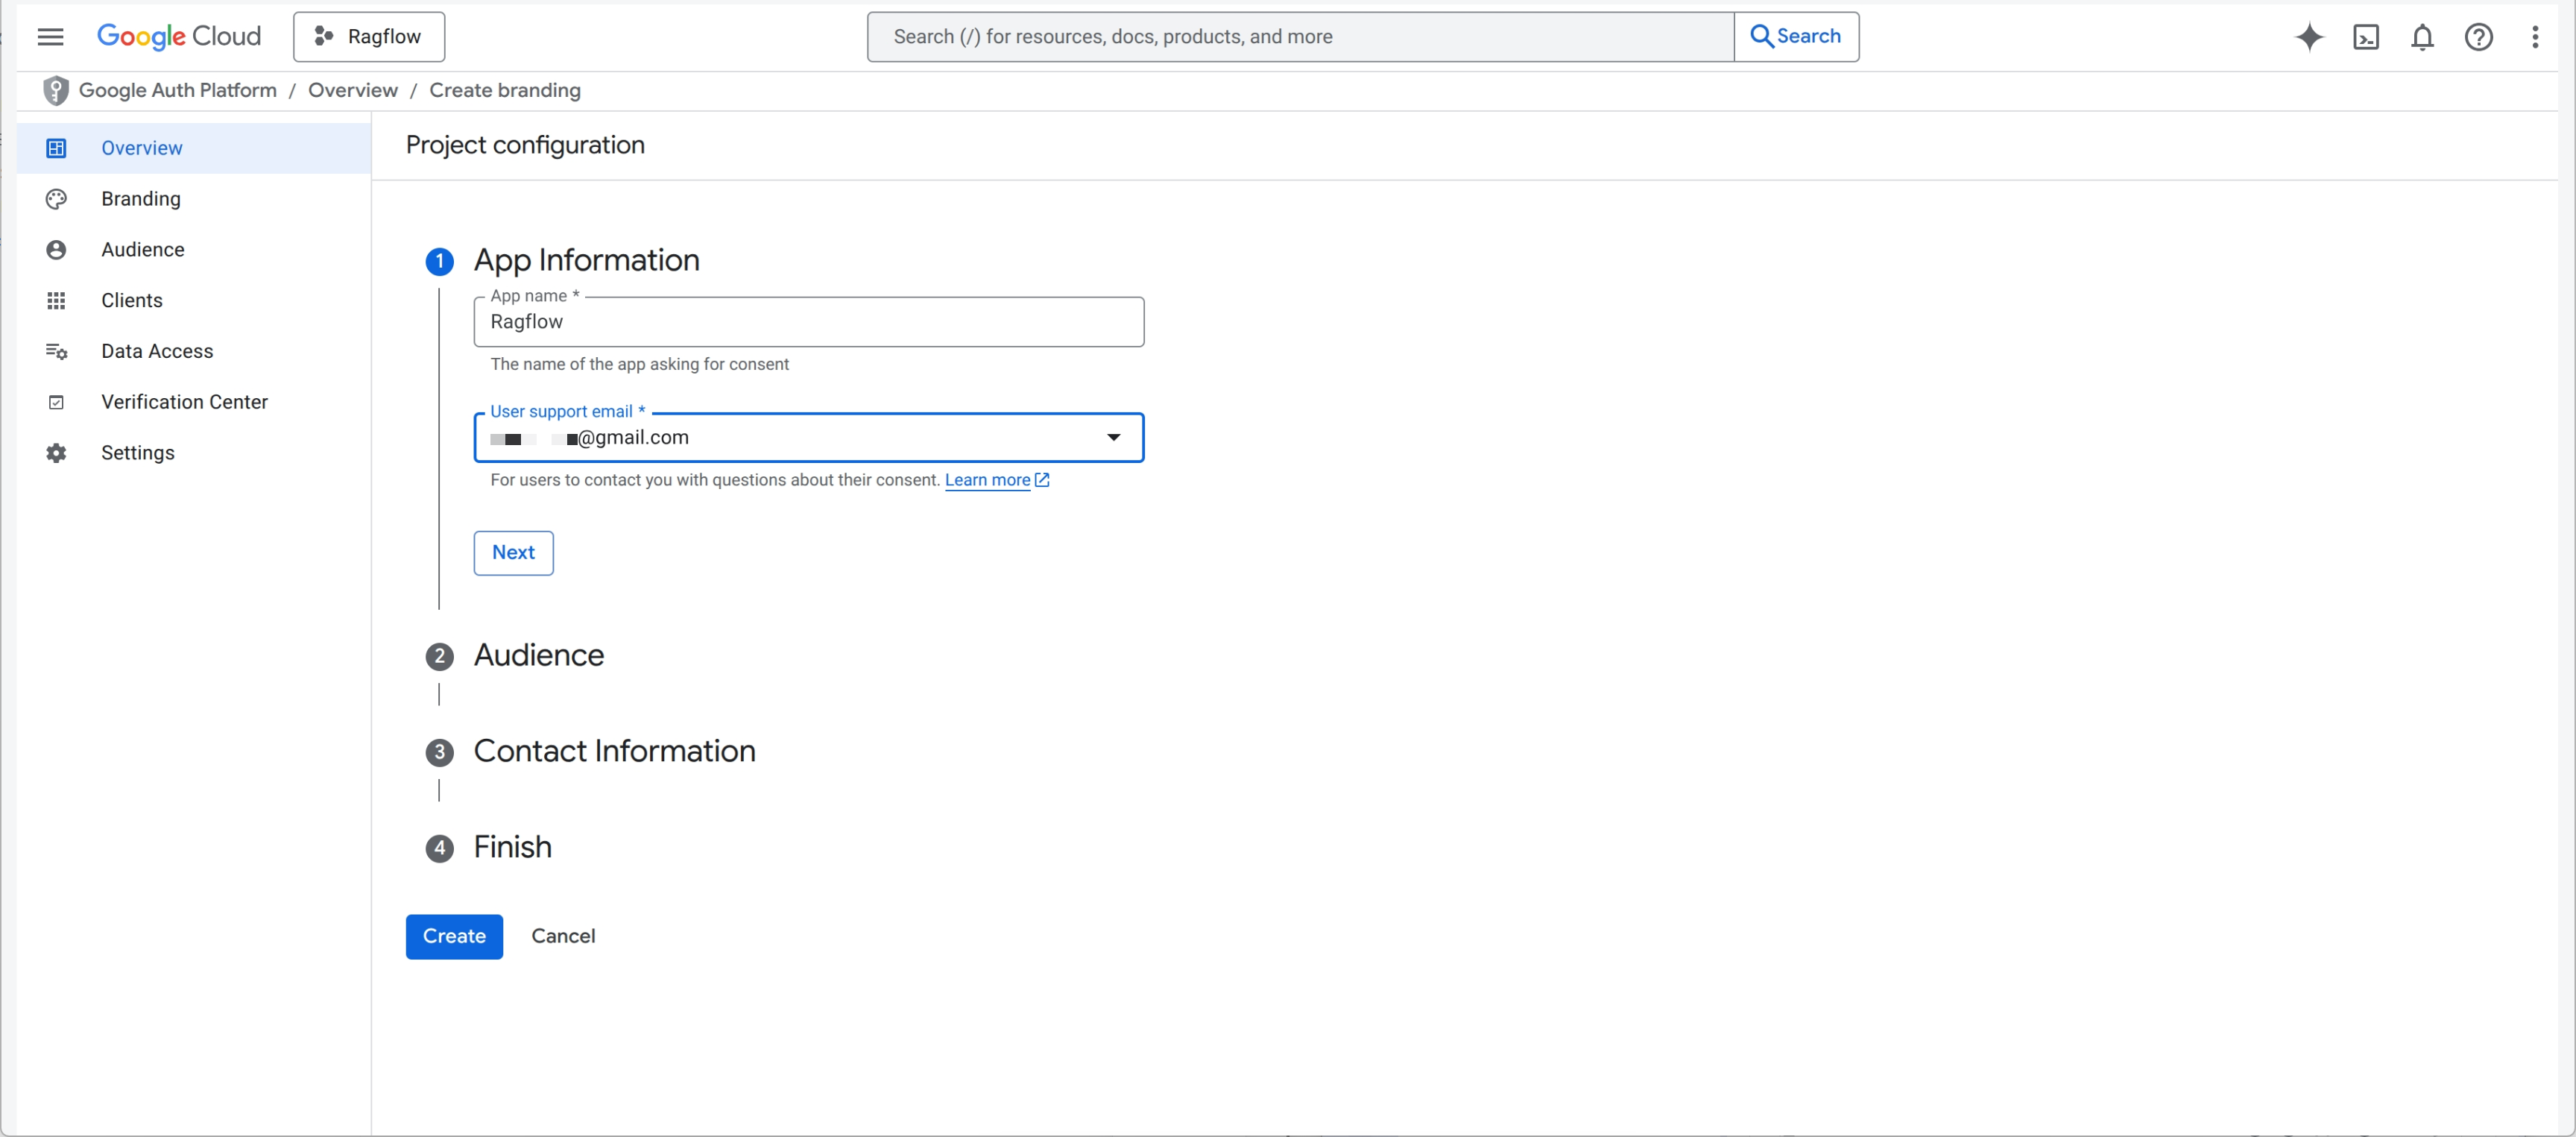3. Select **External**:_Your app will start in testing mode and will only be available to a selected list of users._-+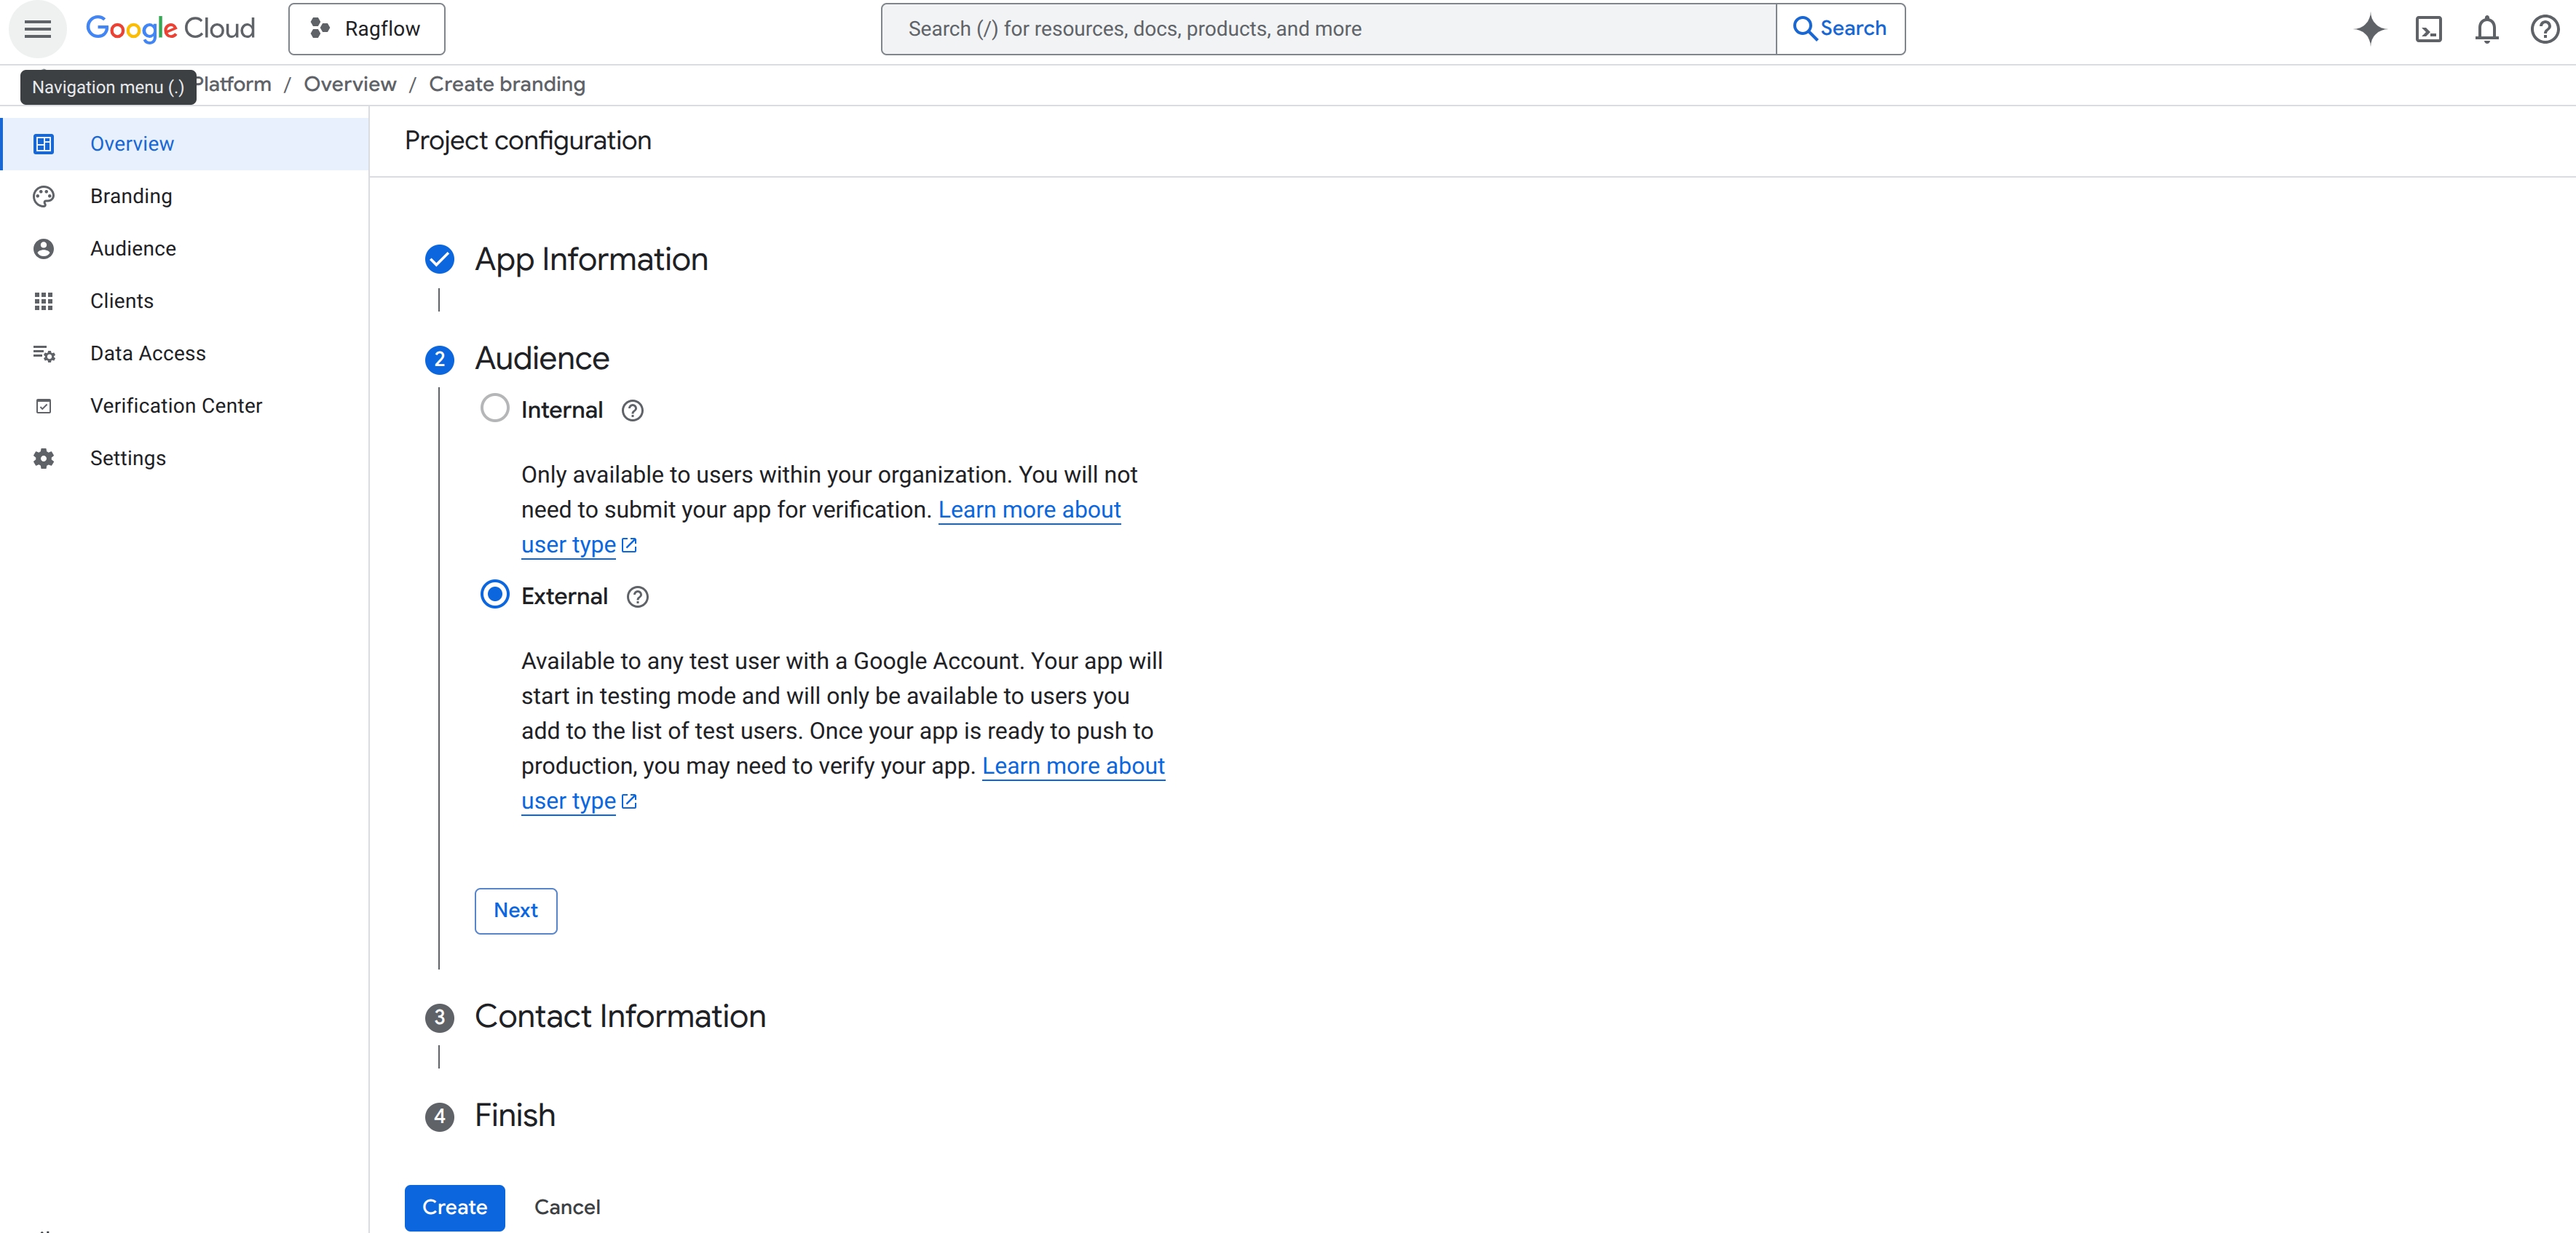4: Click **Create** to confirm creation.## 2. Configure OAuth Consent Screen@@ -33,27 +35,27 @@ You need to configure the OAuth Consent Screen because it is the step where you1. Go to **APIs & Services** → **OAuth consent screen**.2. Ensure **User Type** is set to **External**:--3. Under Under **Test Users**, click **+ Add users** to add test users:--+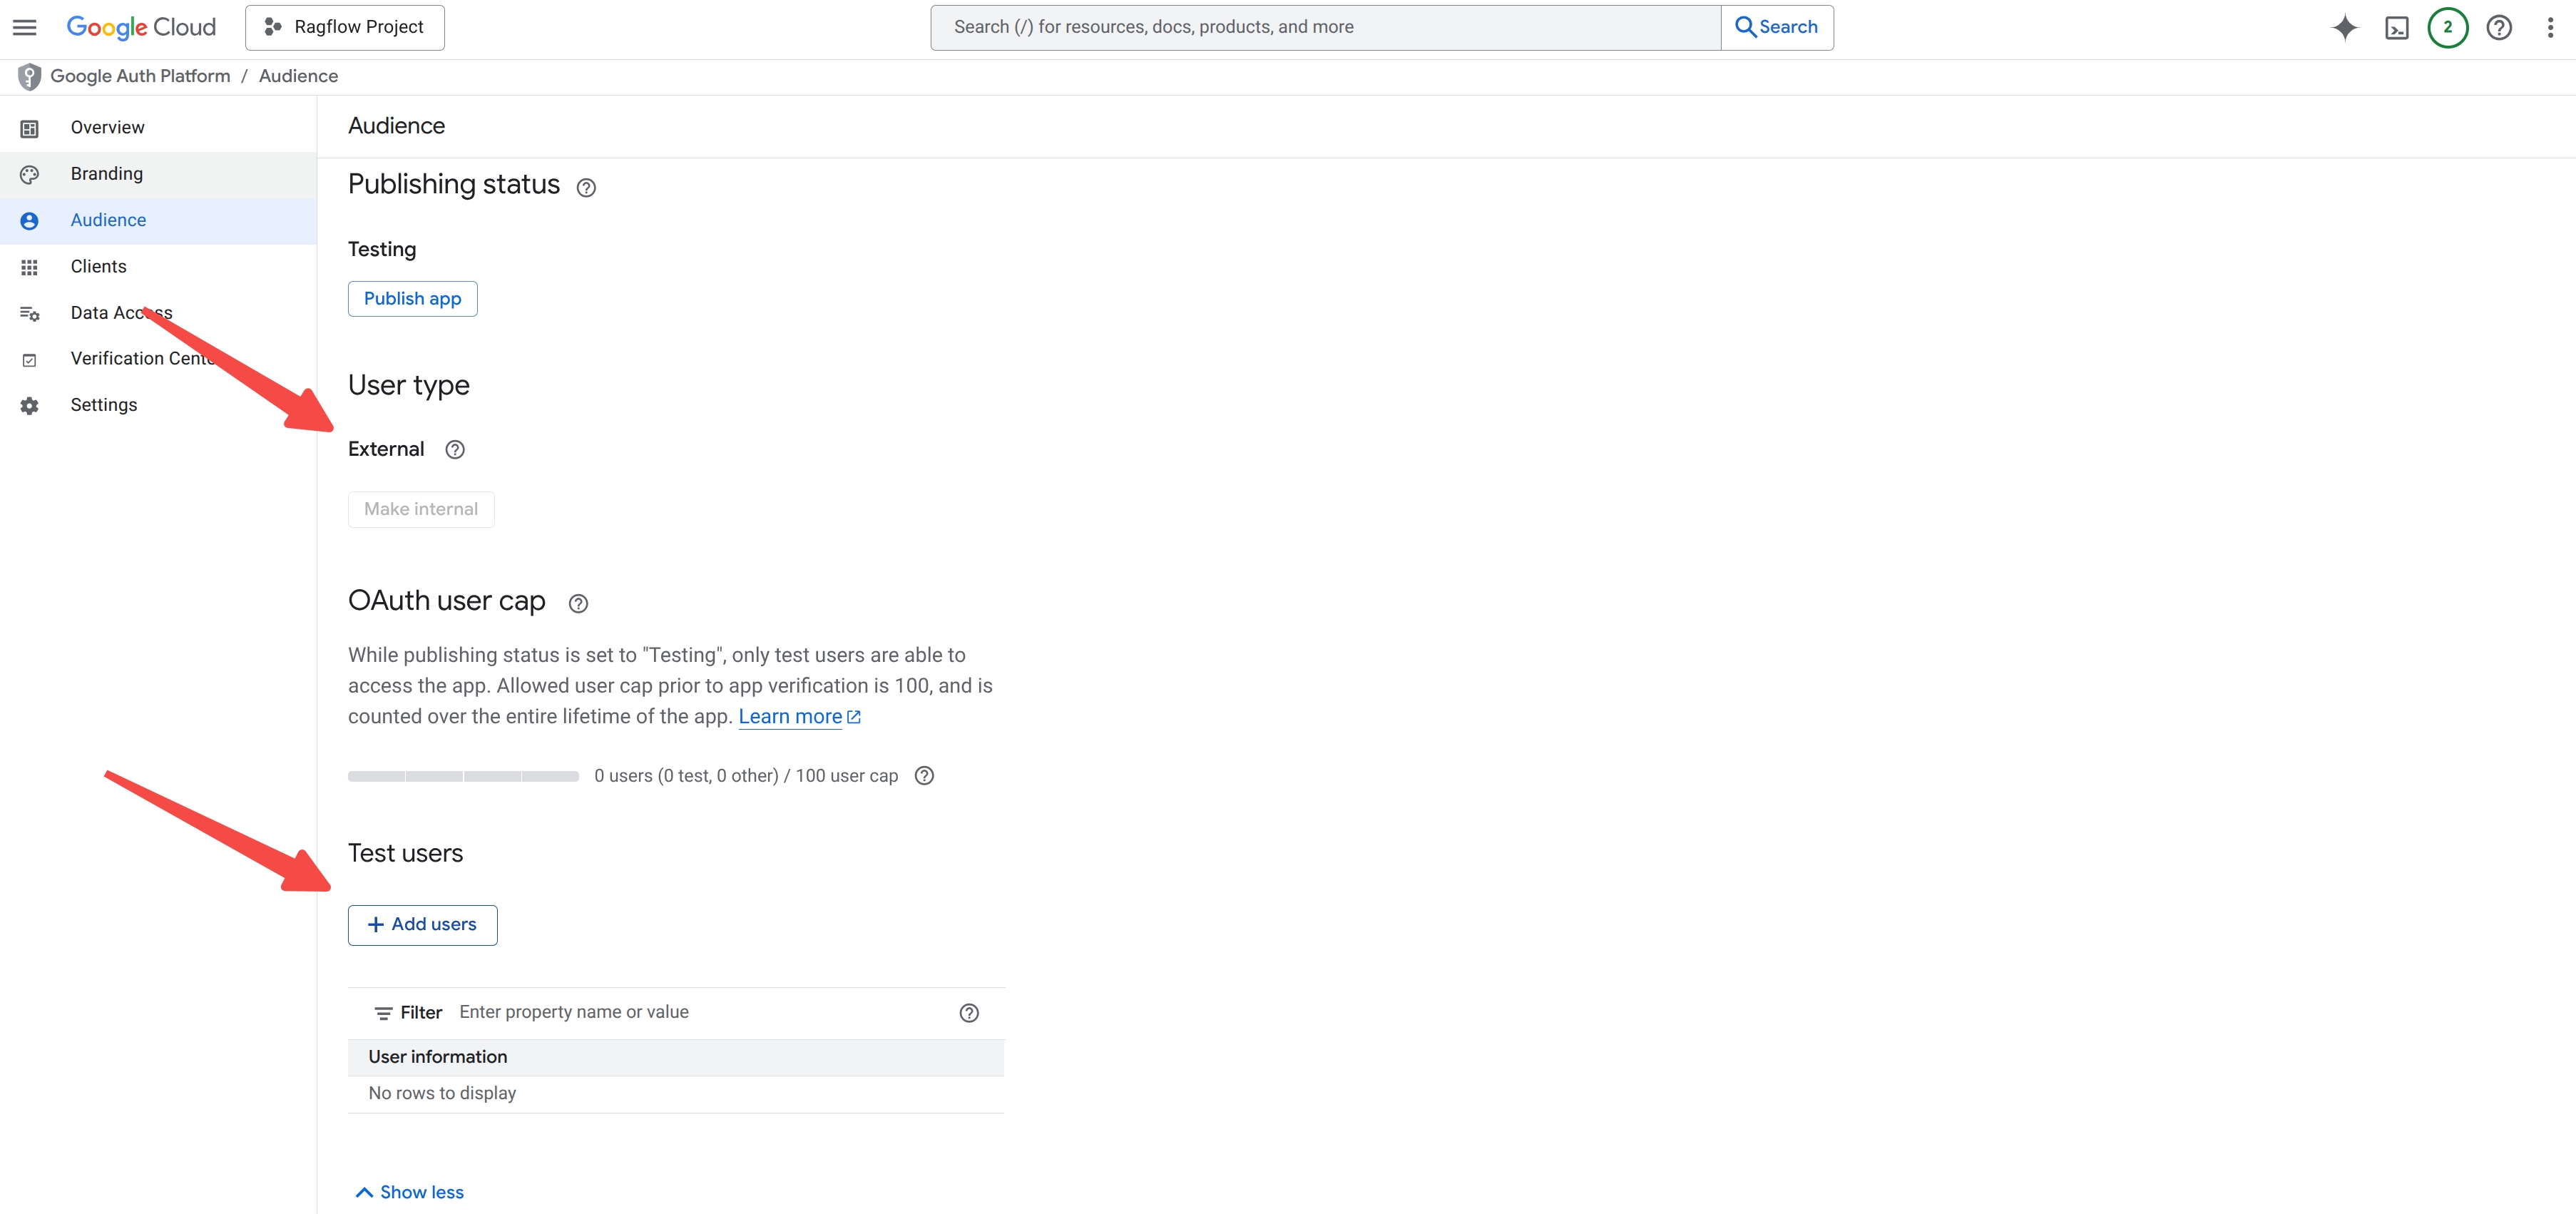+3. Under **Test Users**, click **+ Add users** to add test users:+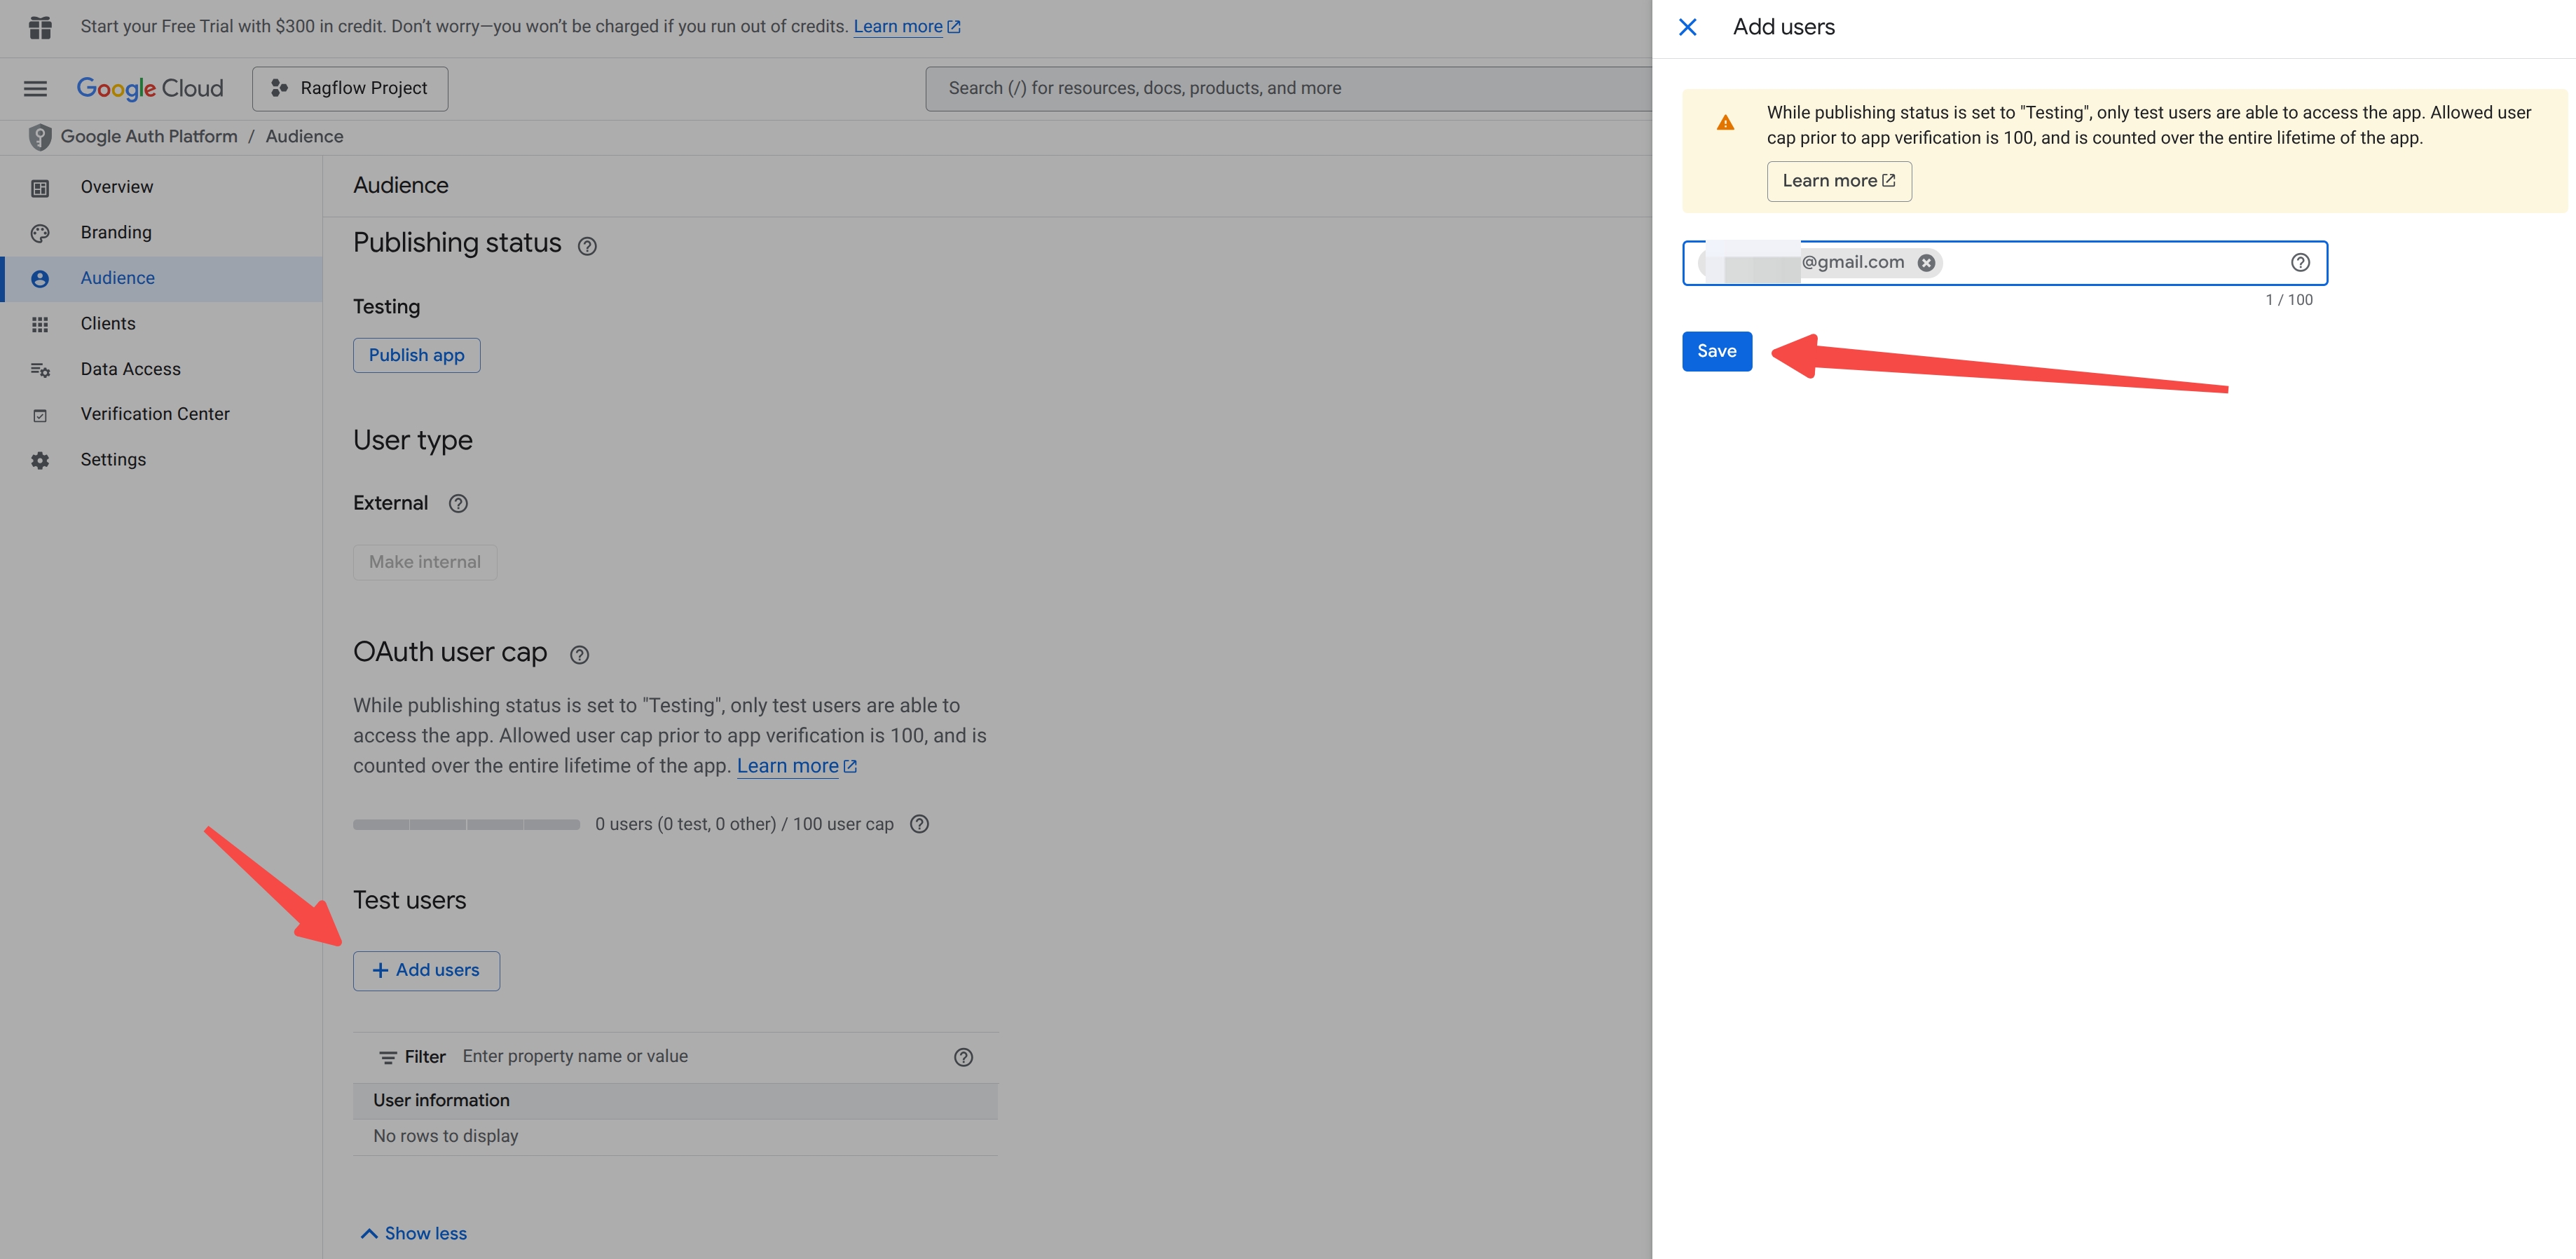+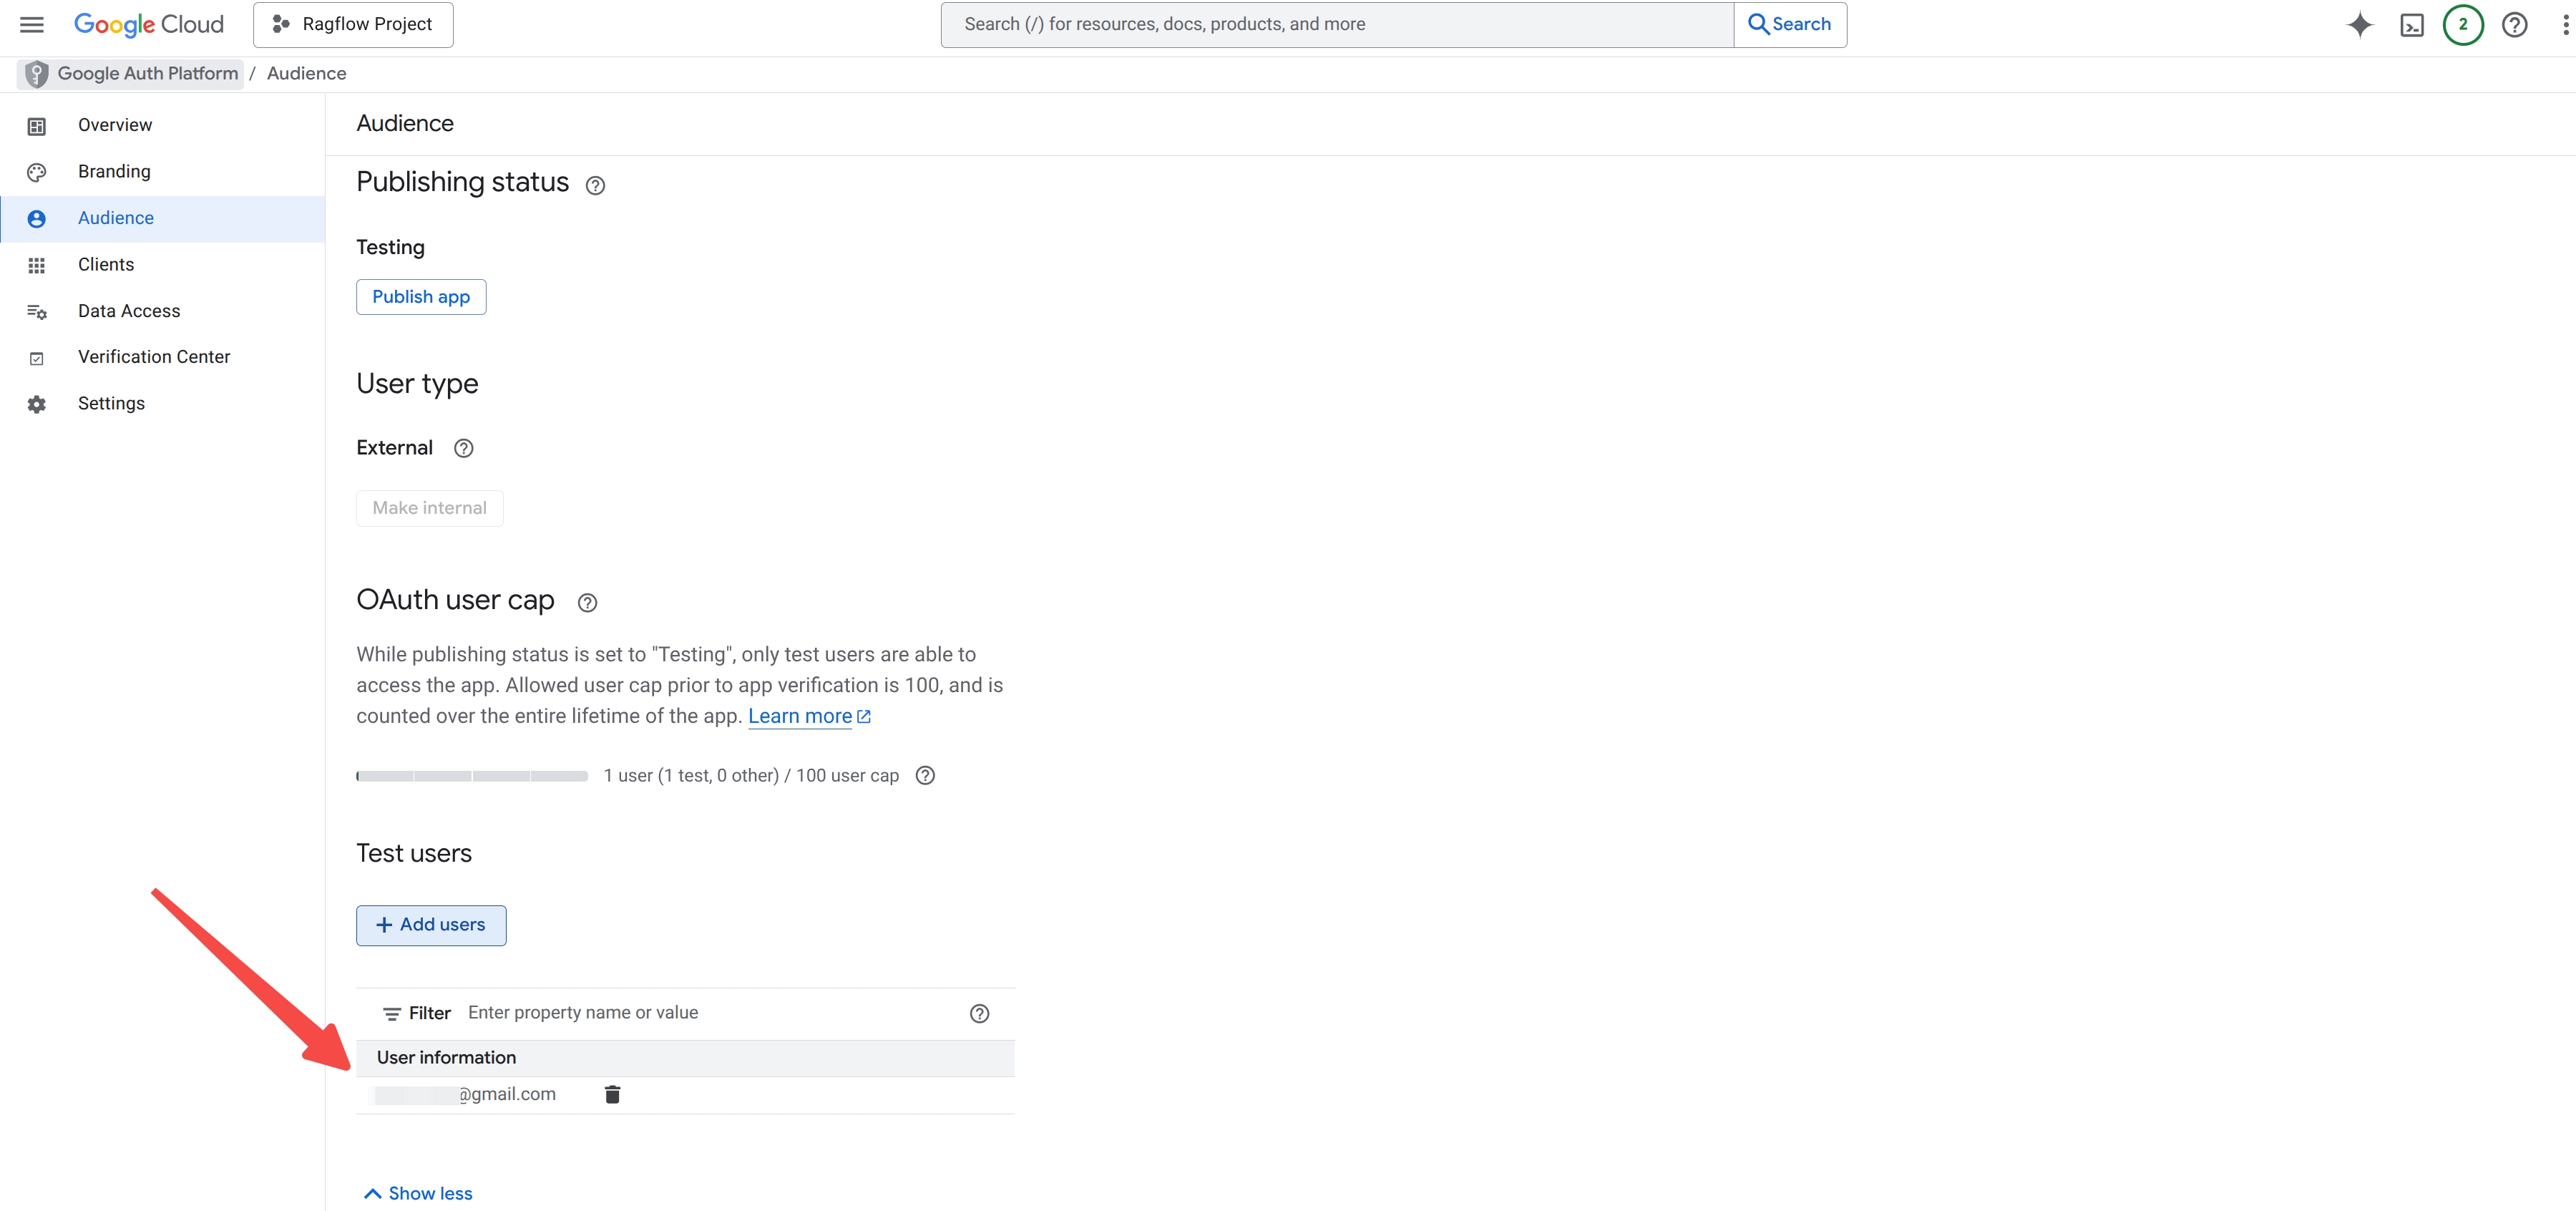## 3. Create OAuth Client Credentials1. Navigate to `https://console.cloud.google.com/auth/clients`.2. Select **Web Application** as **Application type** for the created project:-+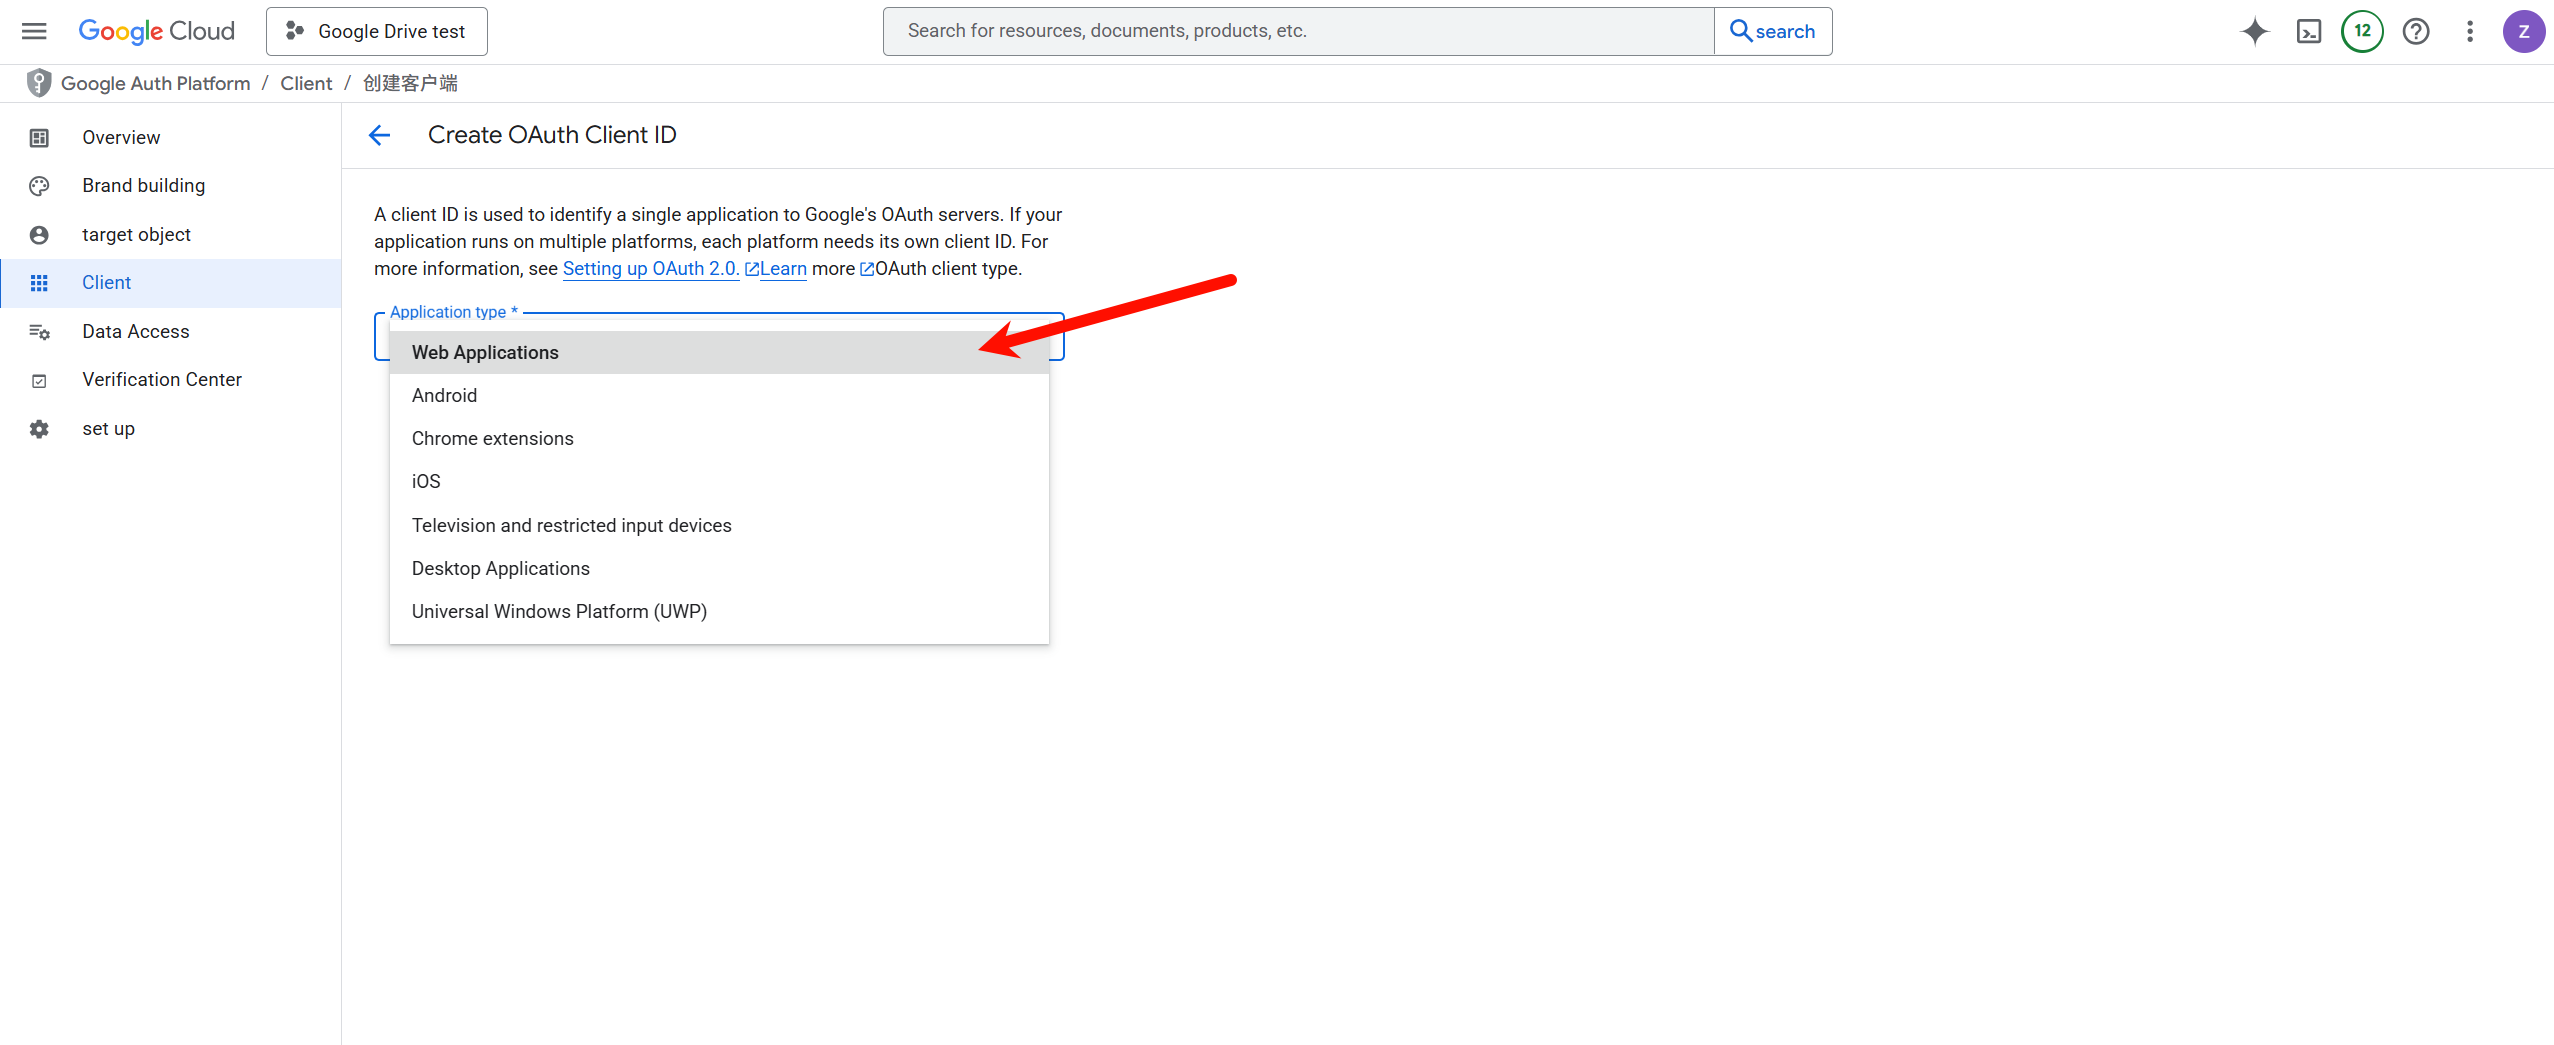3. Enter a client name.-4. Add `http://localhost:9380/api/v1/connectors/google-drive/oauth/web/callback` as **Authorised redirect URIs**:-5. Add **Authorised JavaScript origins**:+4. Add `http://localhost:9380/api/v1/connectors/google-drive/oauth/web/callback` as **Authorized redirect URIs**:+5. Add **Authorized JavaScript origins**:- If deploying RAGFlow from Docker, use `http://localhost:80`:- + 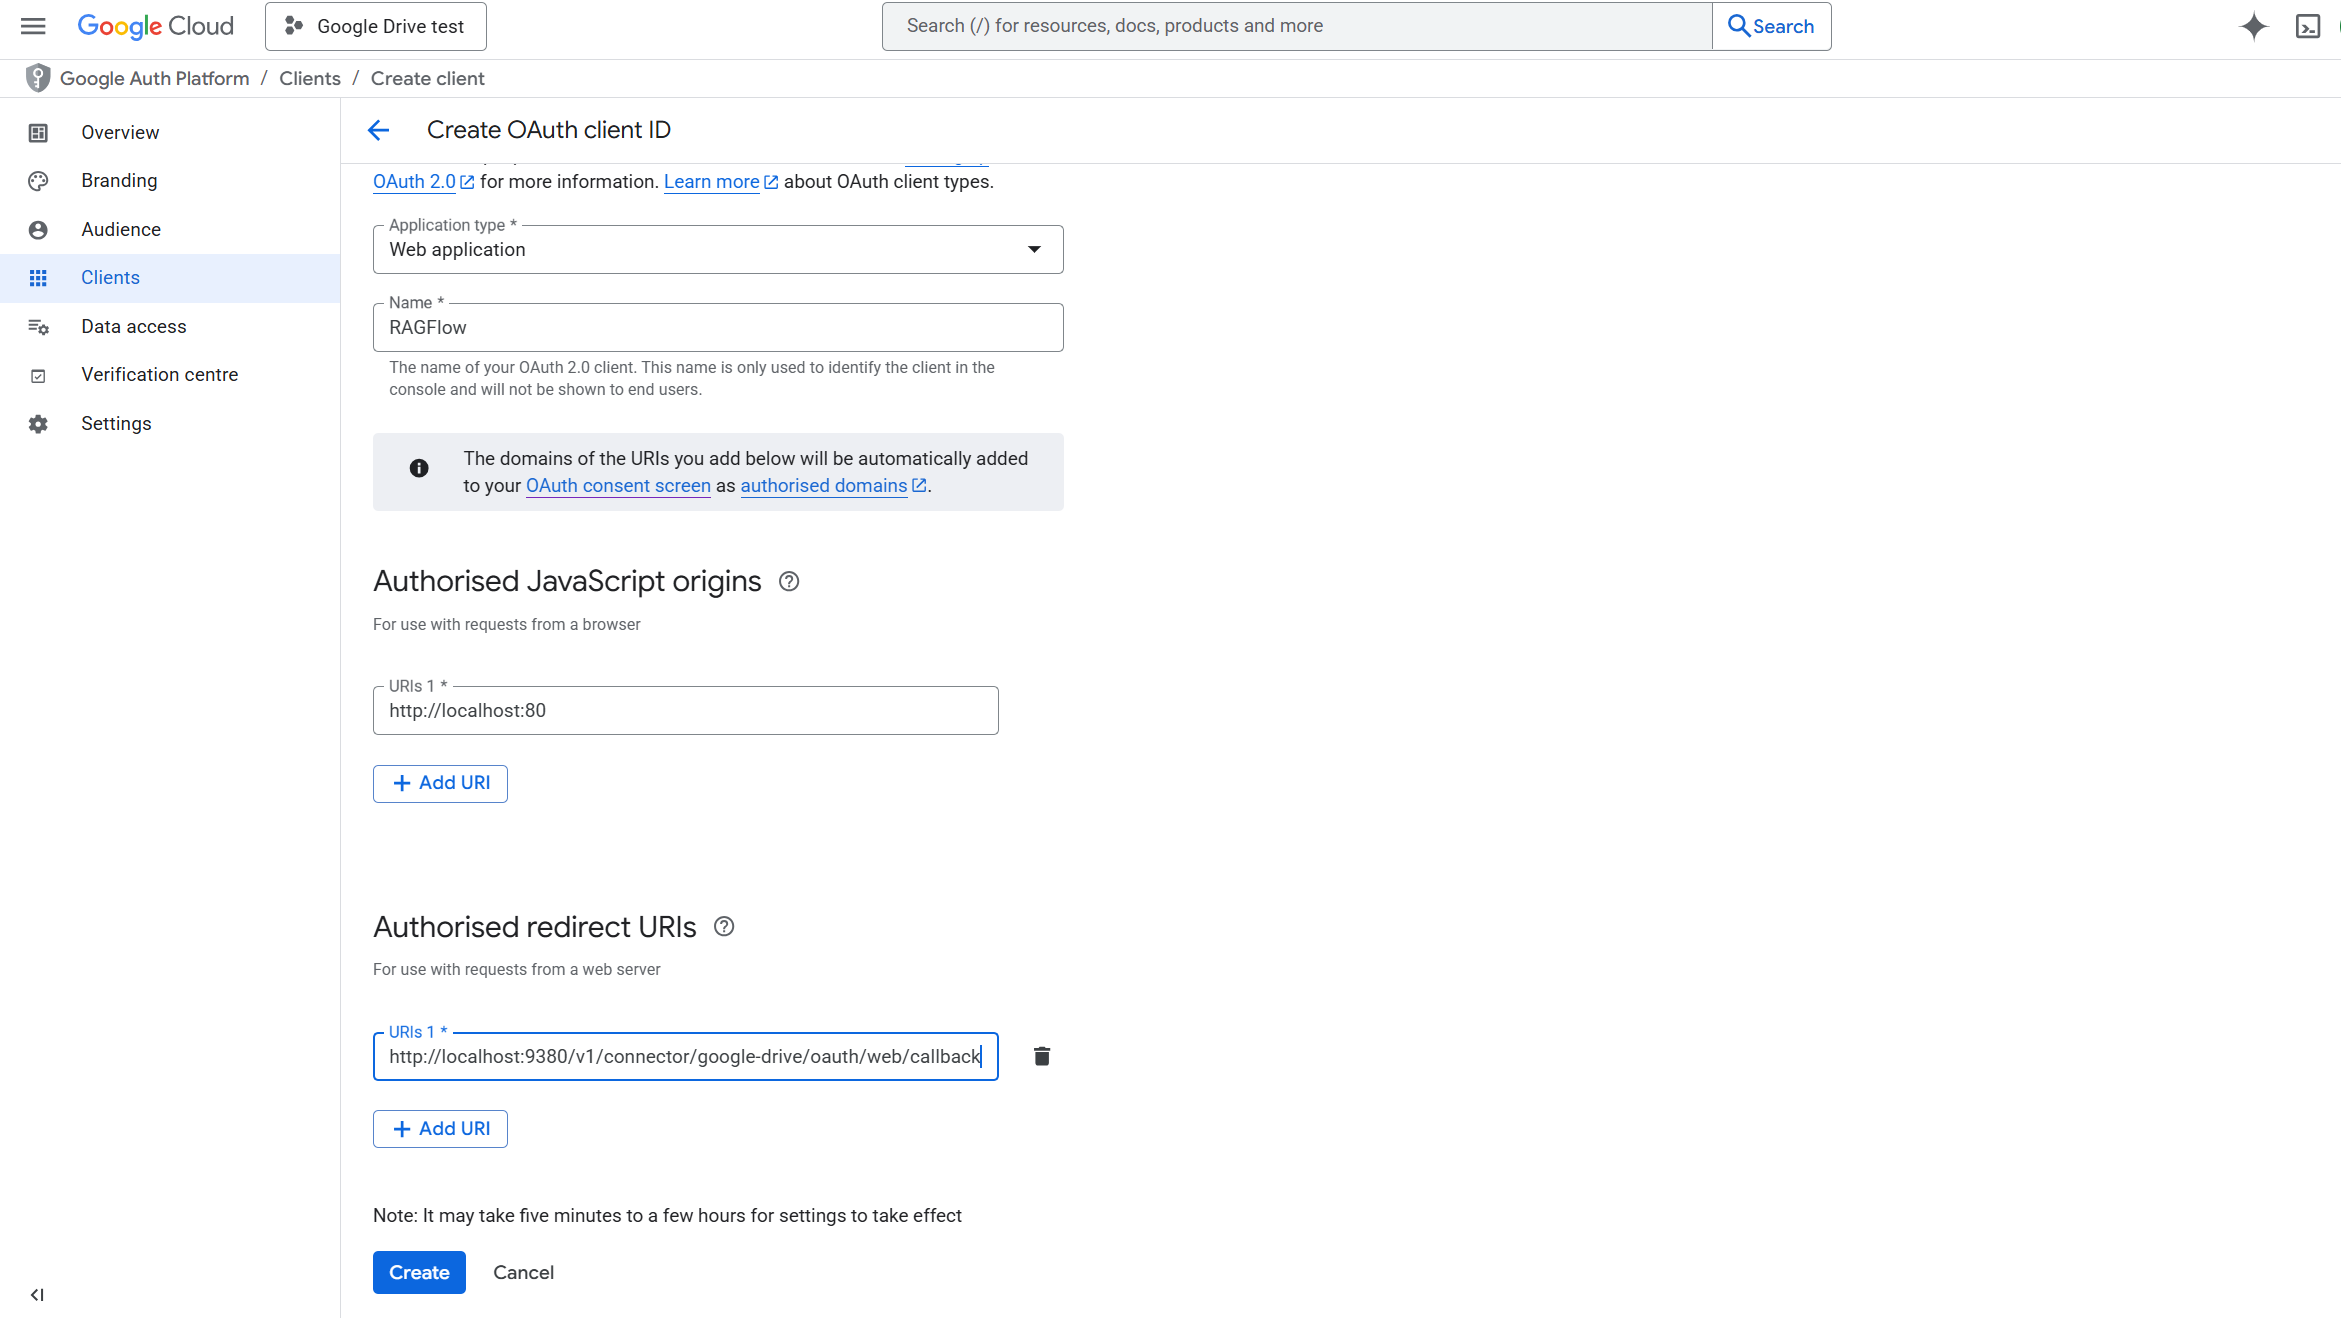- If building RAGFlow from source, use `http://localhost:9222`- + 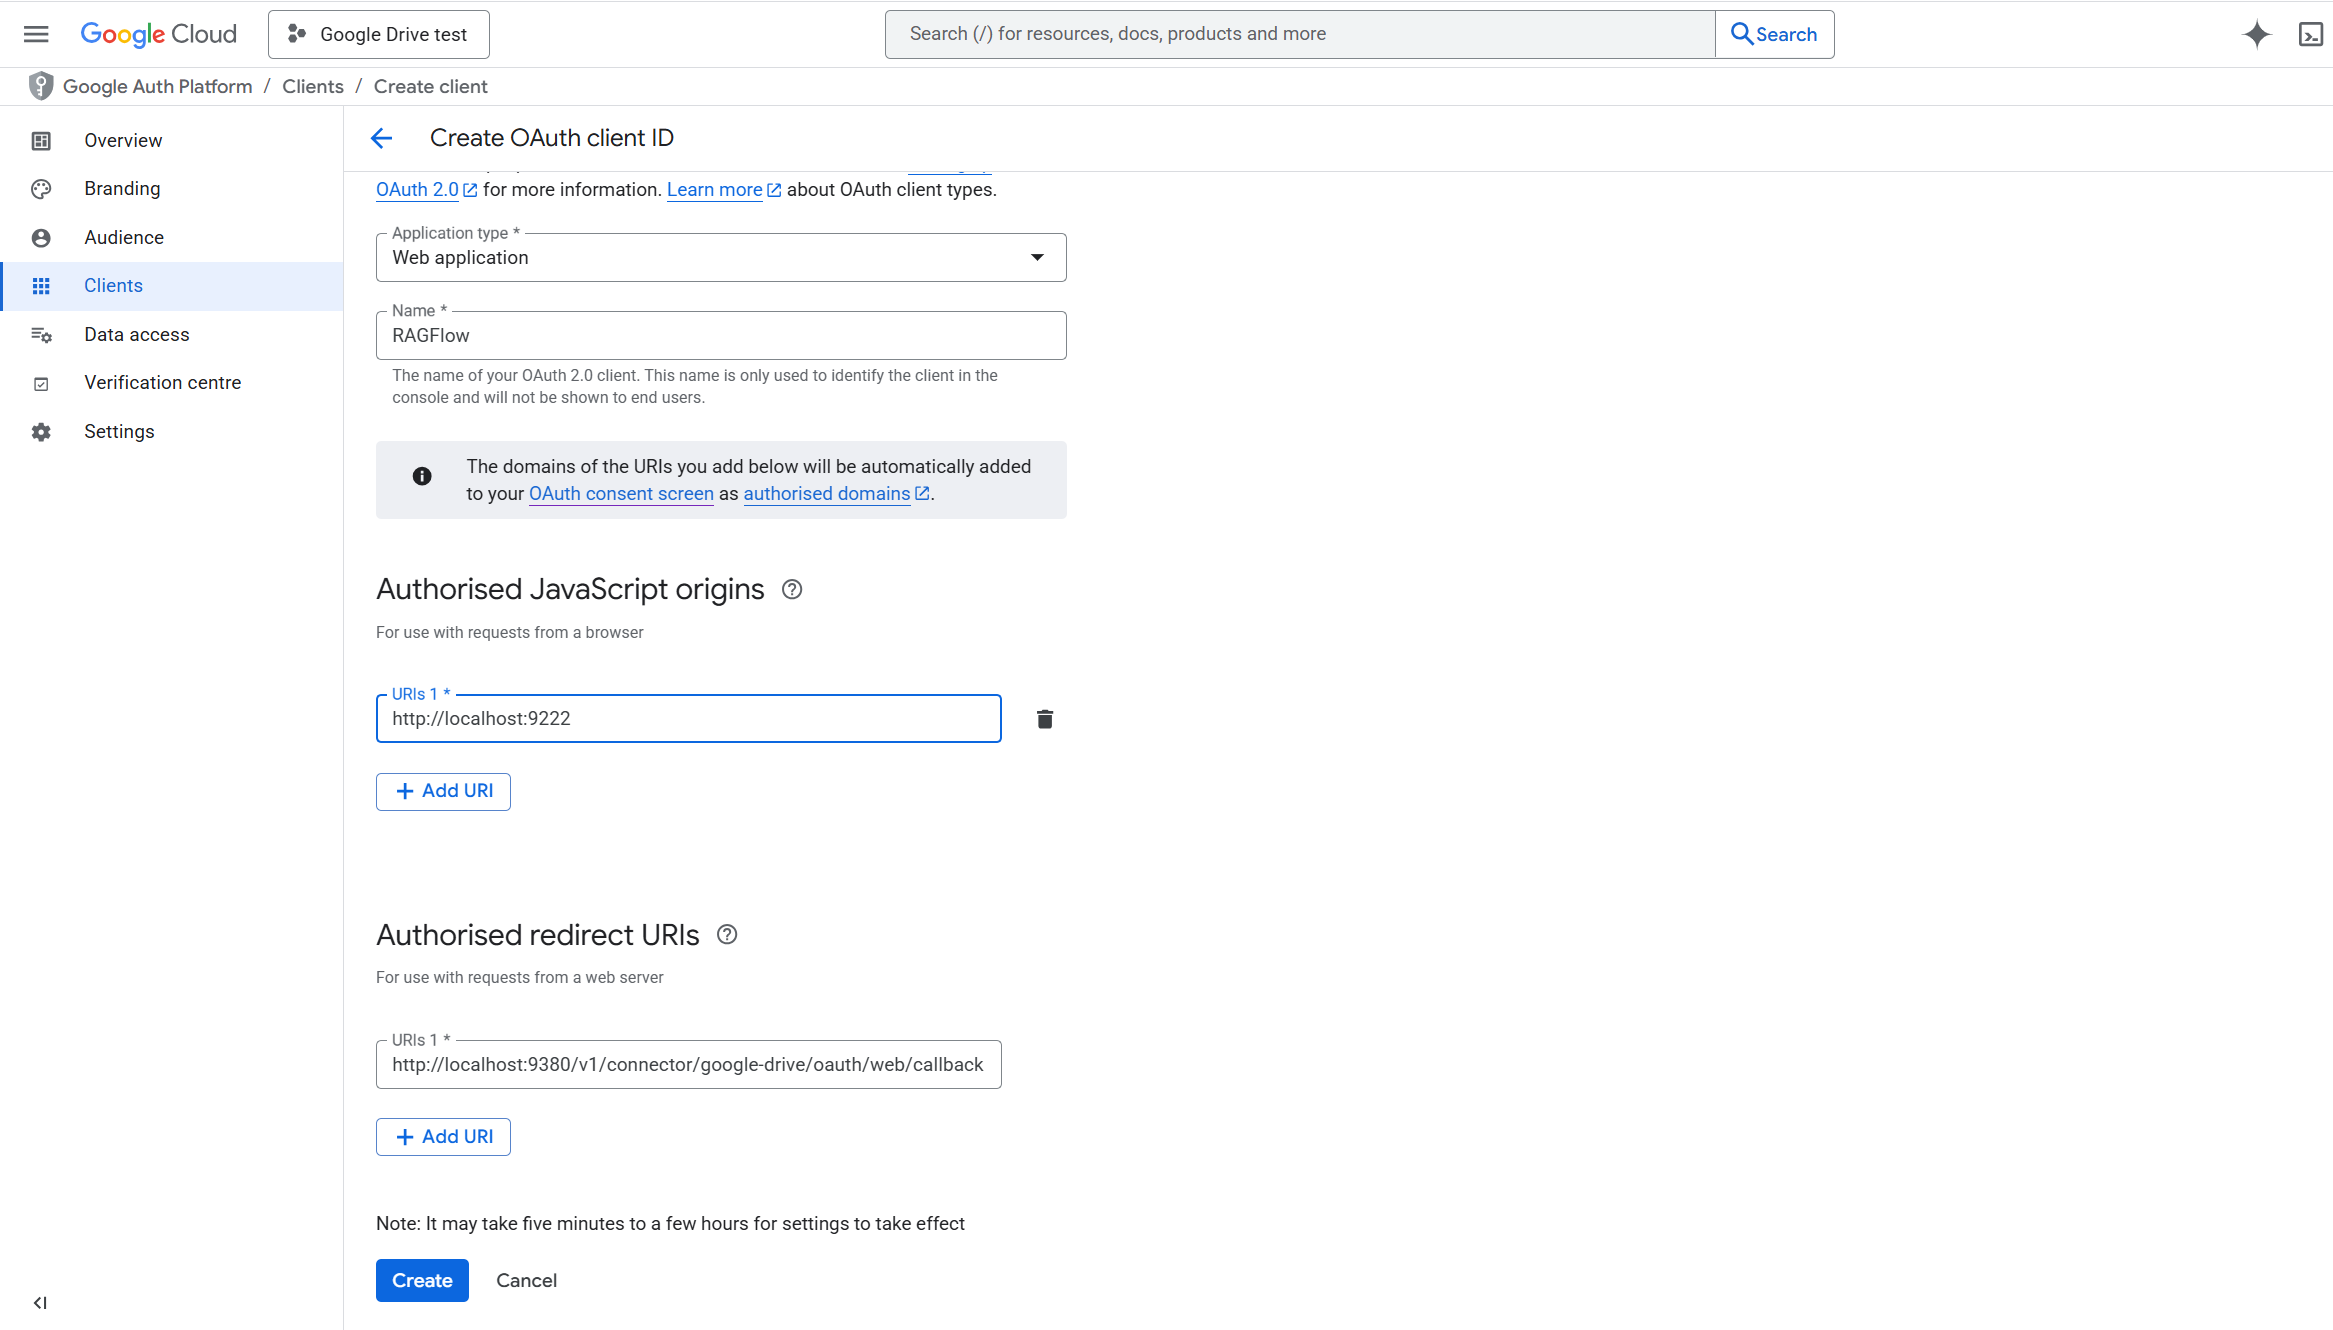6. After saving, click **Download JSON** in the popup window; this credential file will later be uploaded into RAGFlow.-+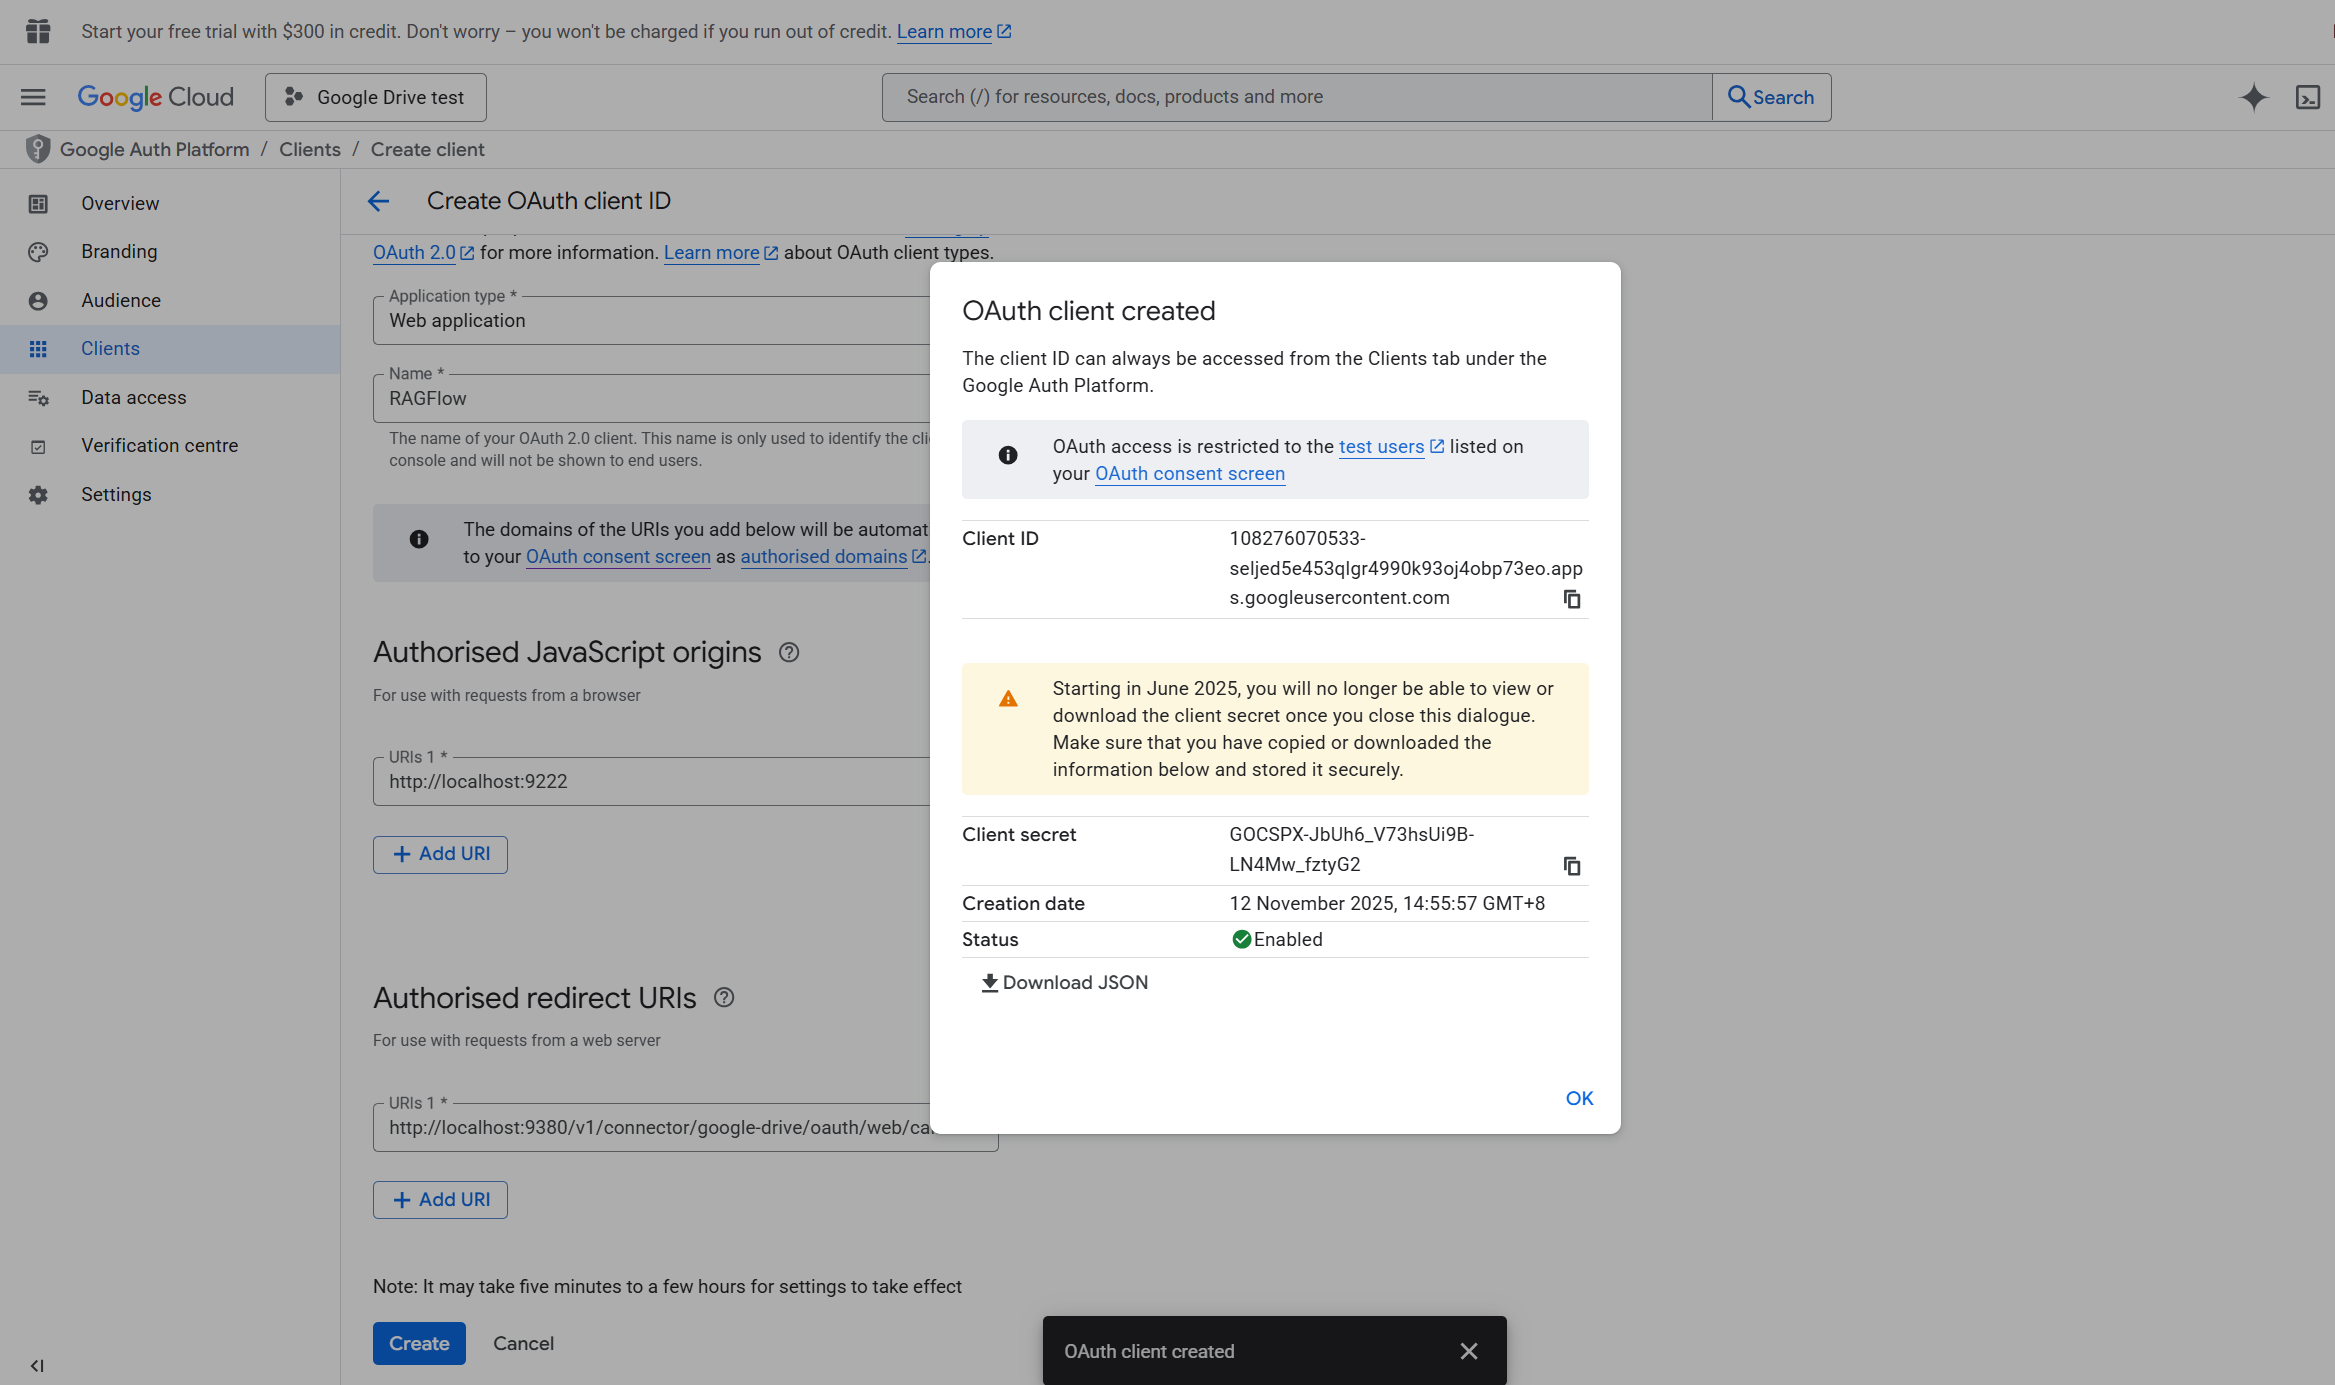## 4. Add Scopes@@ -68,19 +70,19 @@ https://www.googleapis.com/auth/admin.directory.group.readonlyhttps://www.googleapis.com/auth/admin.directory.user.readonly```--+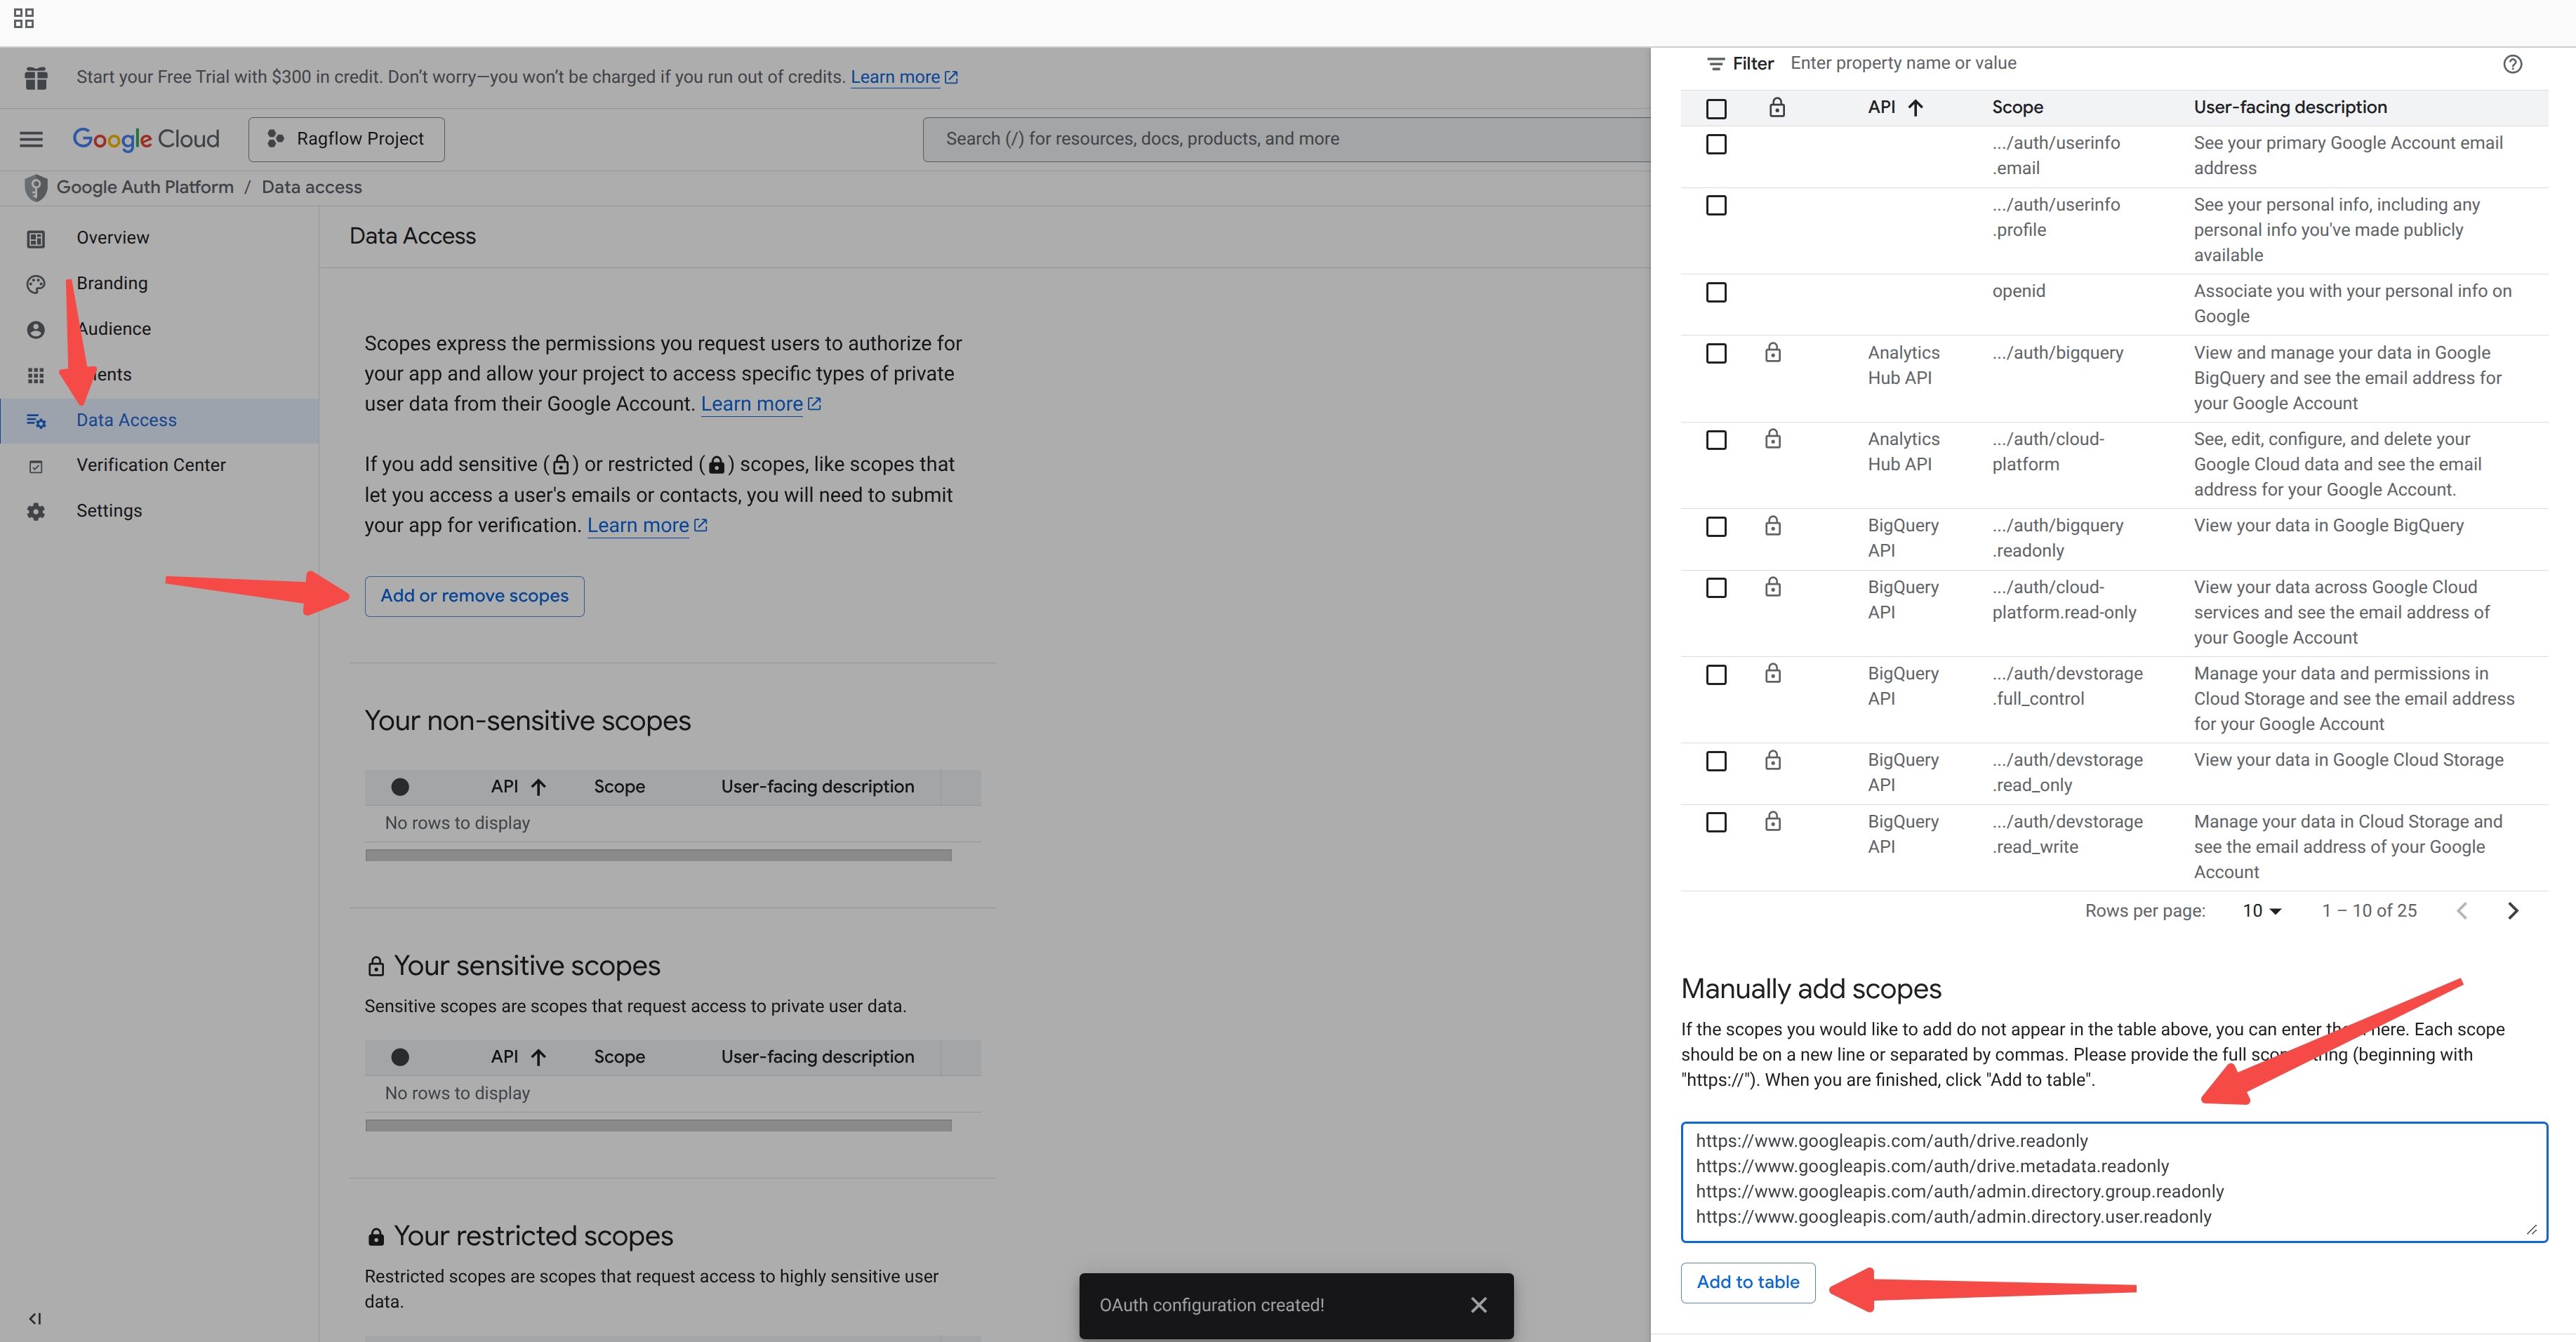+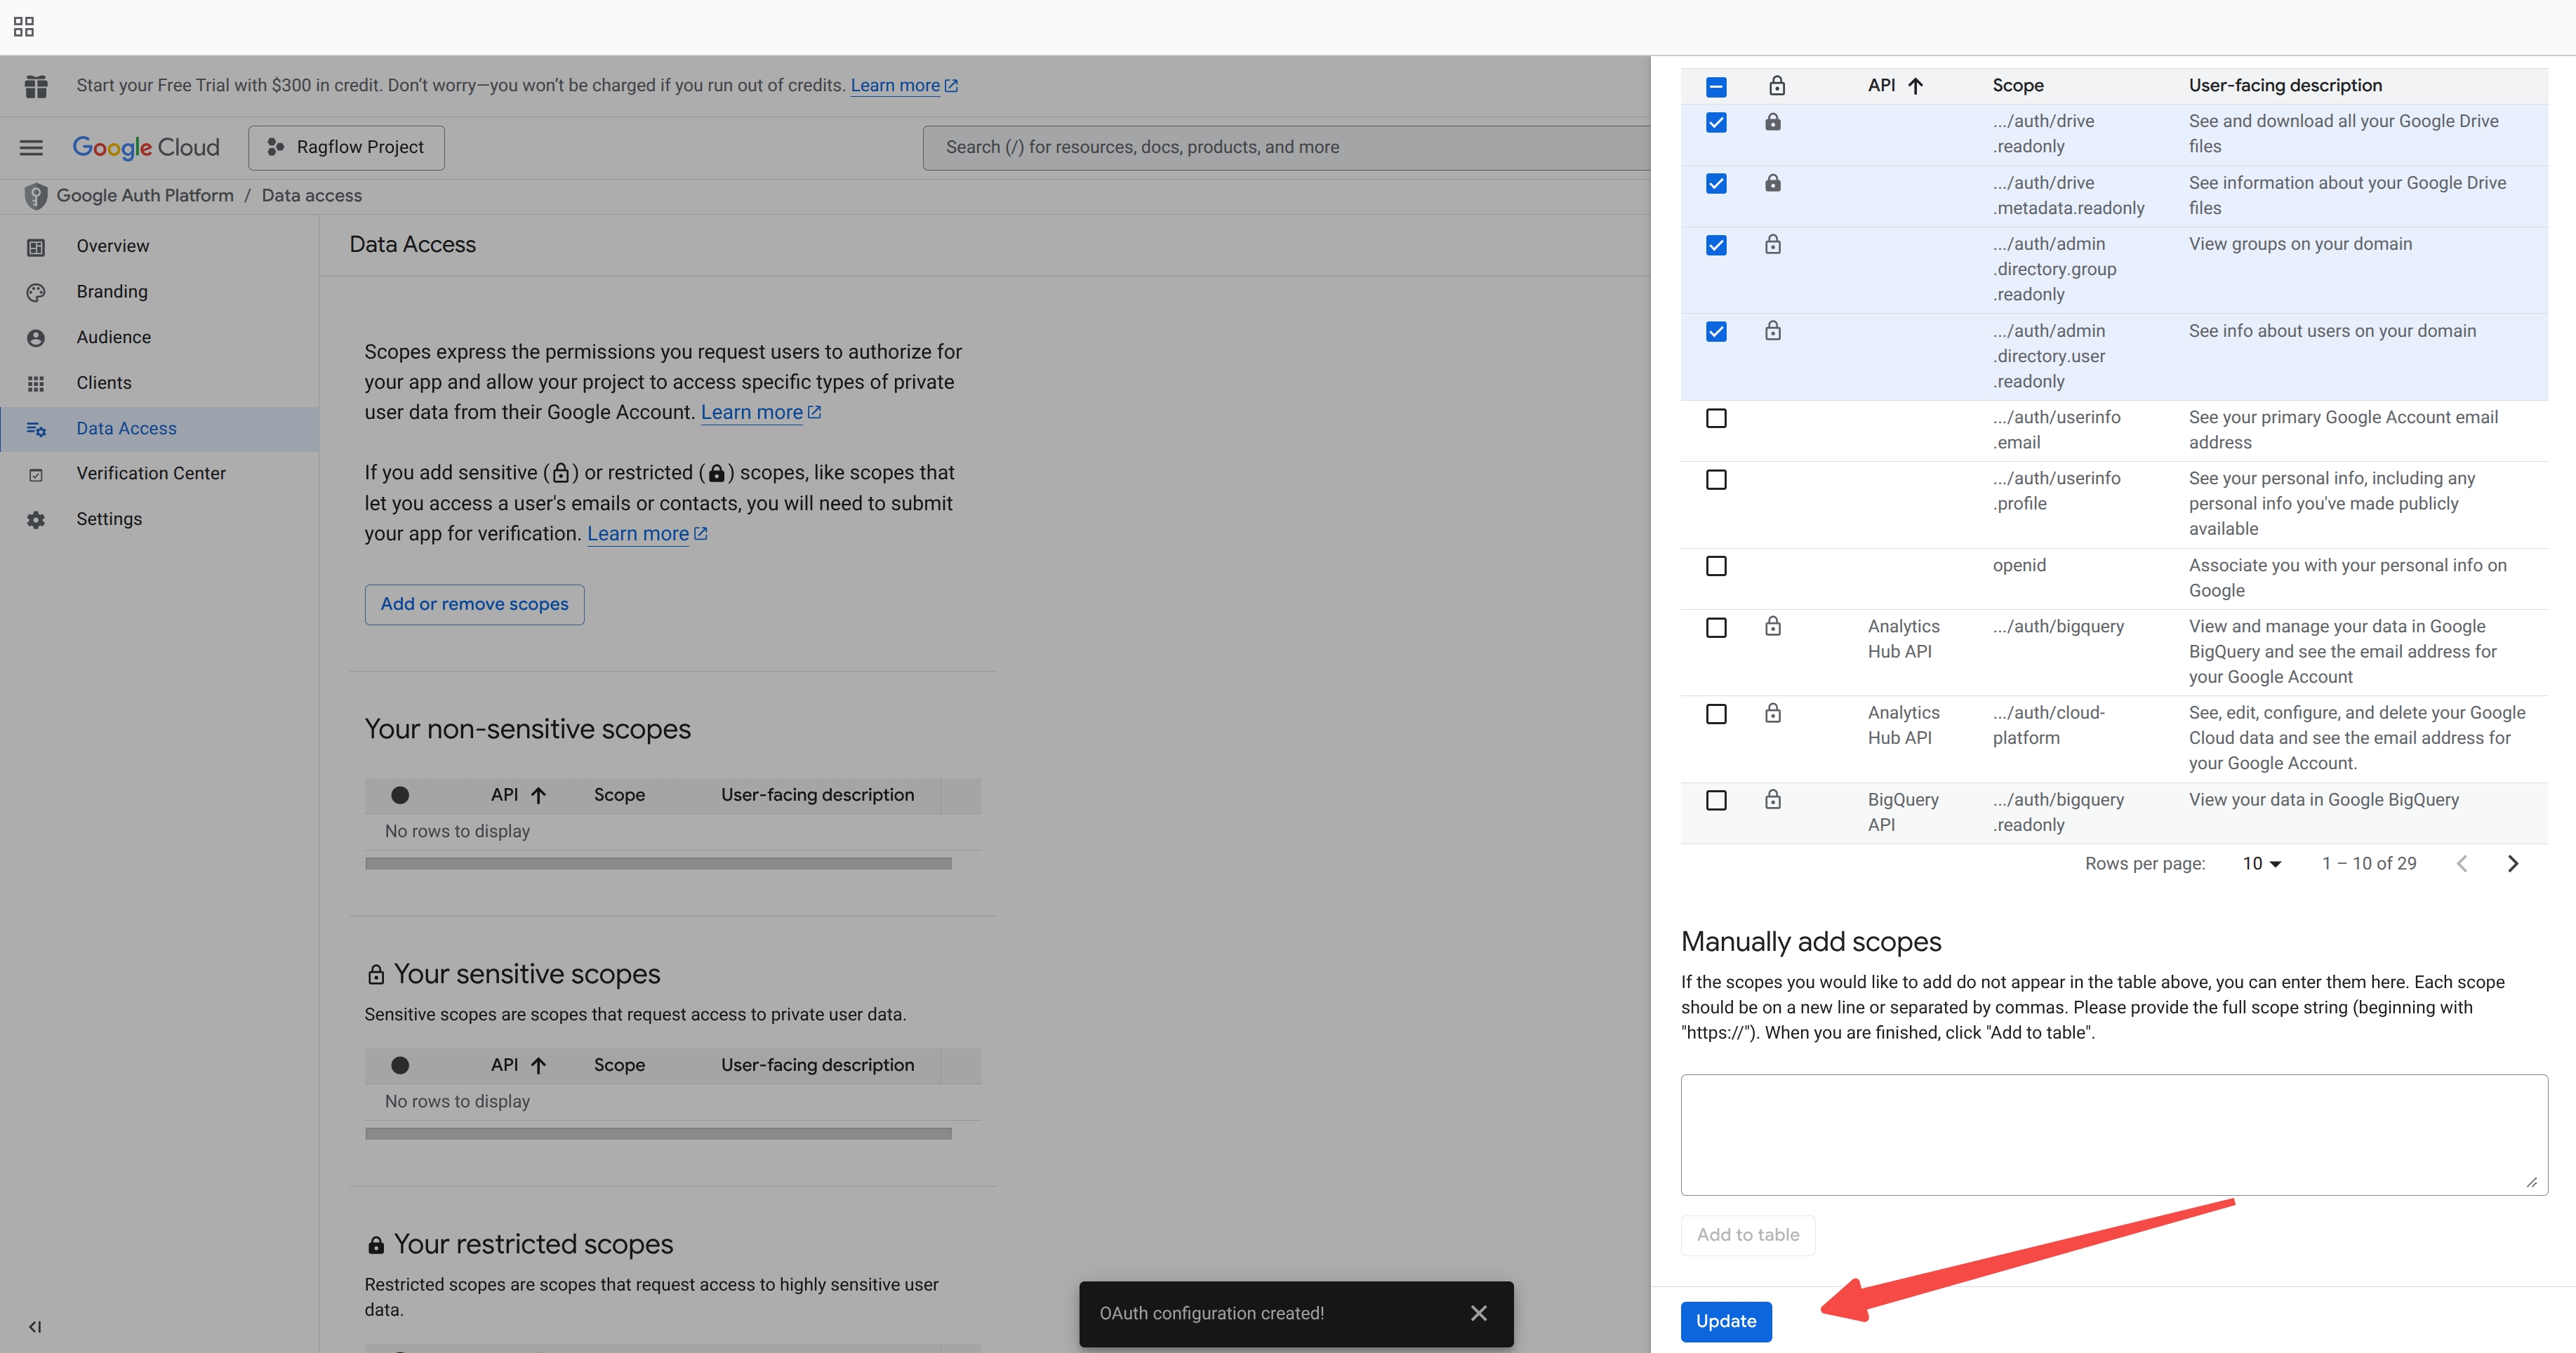2. Click **Save** to save your data access changes:-+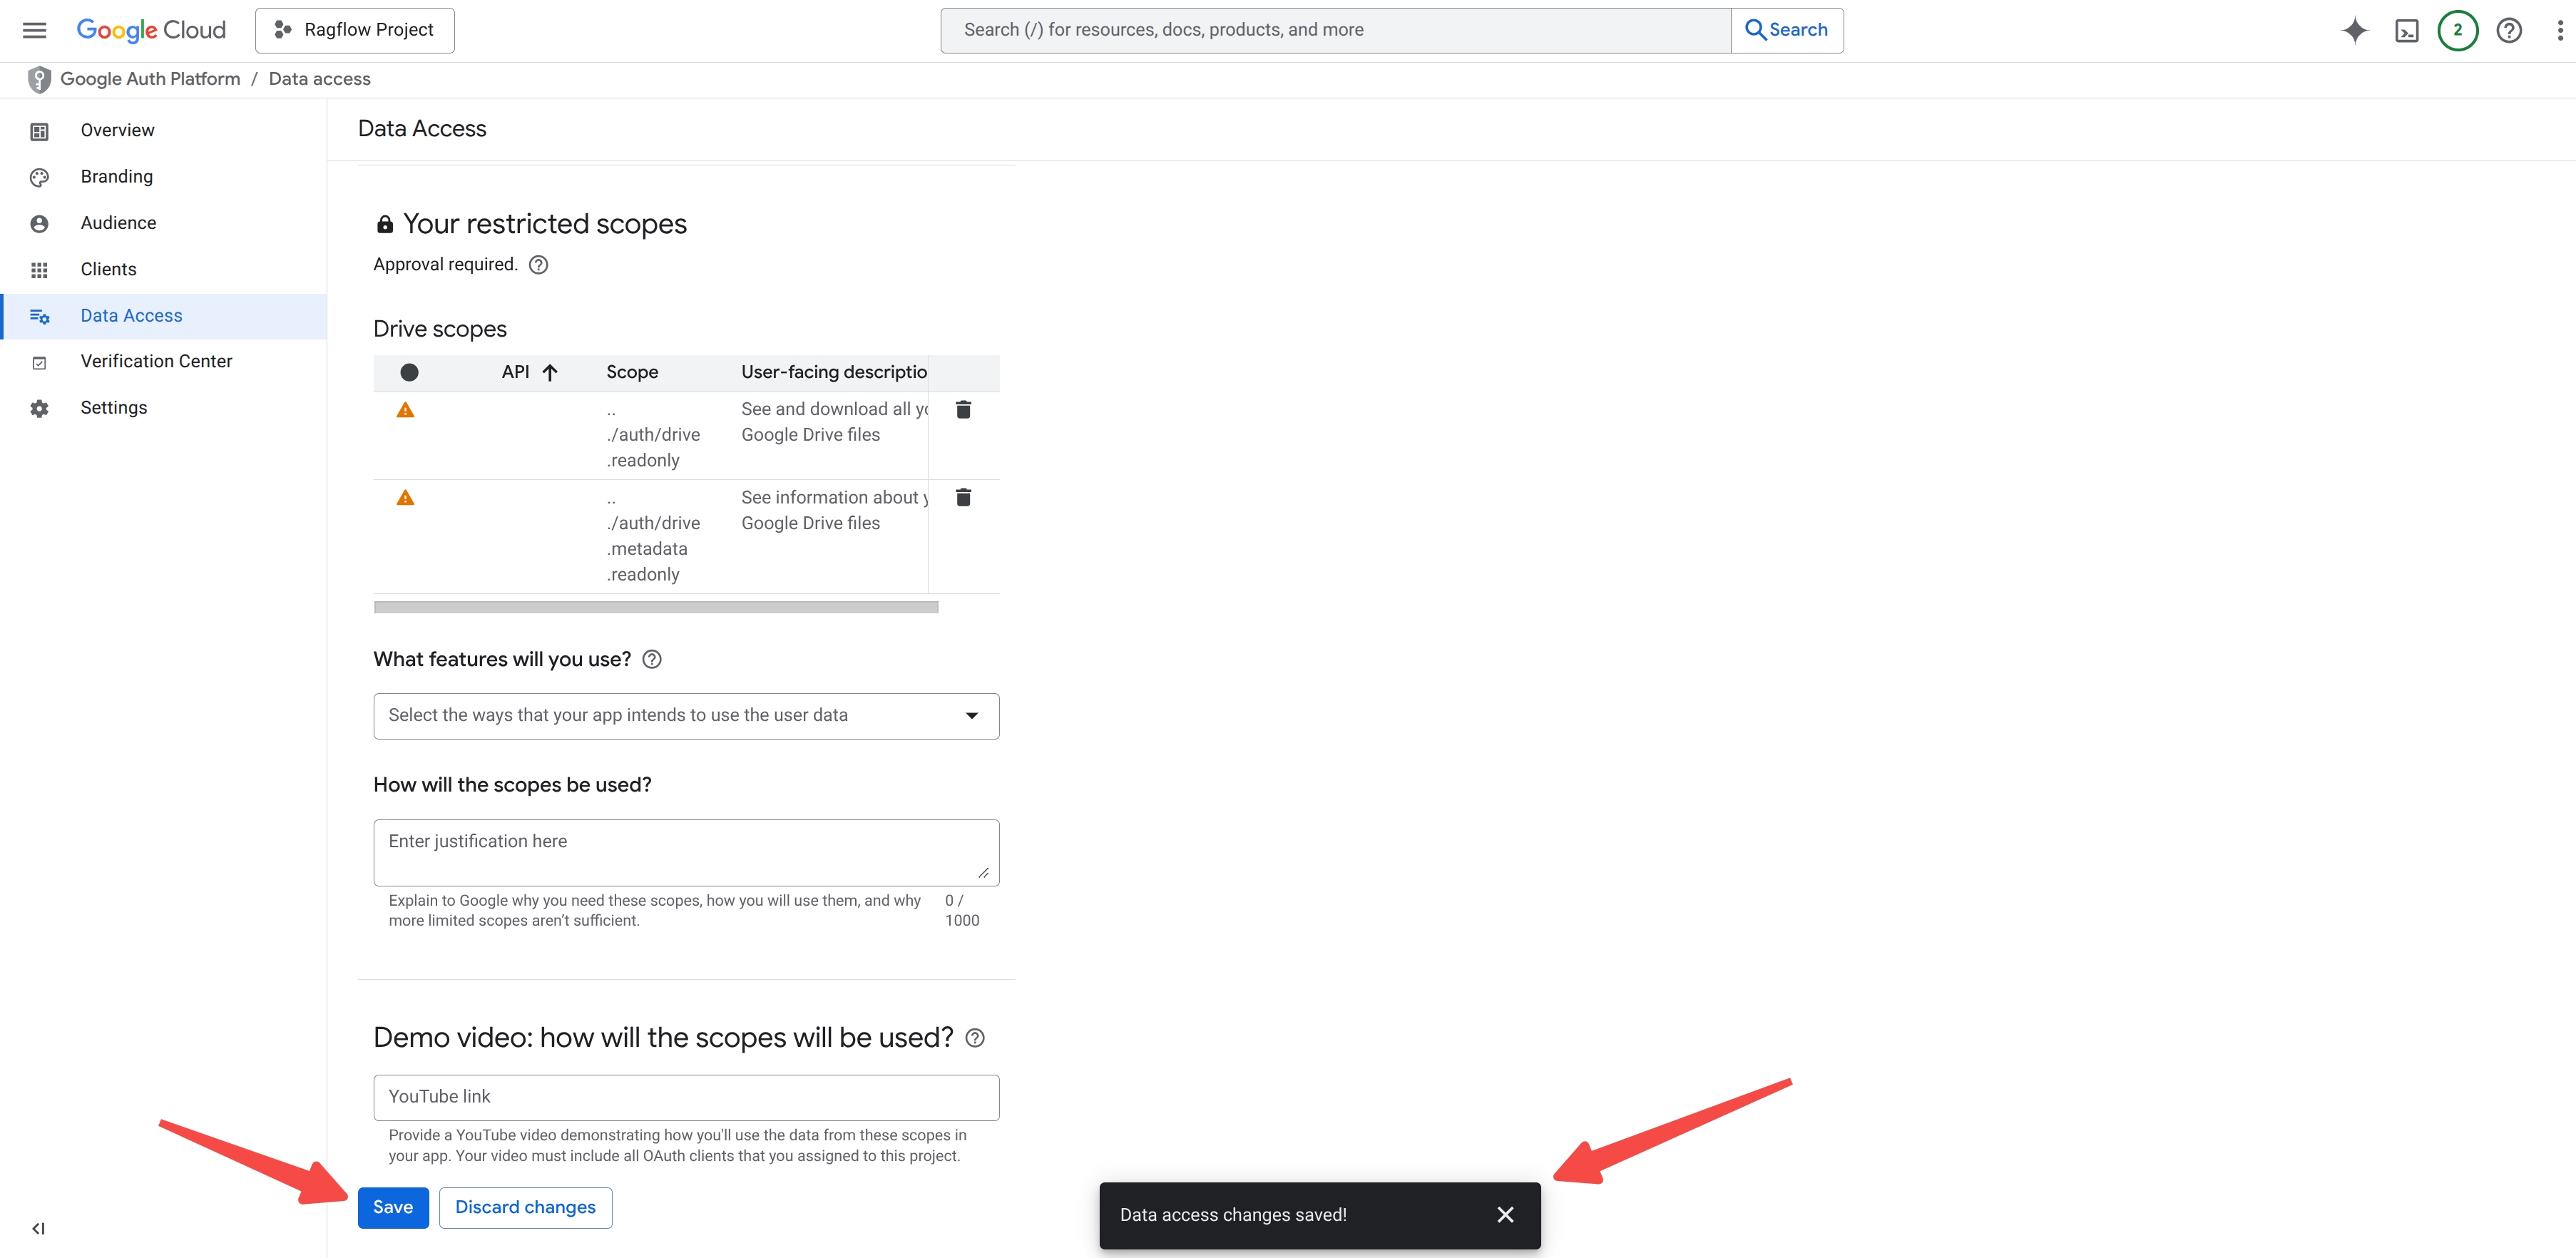-## 5. Enable required APIs+## 5. Enable Required APIsYou need to enable the required APIs (such as the Google Drive API) to formally grant your Google Cloud project permission to communicate with Google's services on behalf of your application. These APIs act as a gateway; even if you have valid OAuth credentials, Google will block requests to a disabled API. Enabling them ensures that when RAGFlow attempts to list or retrieve files, Google's servers recognize and authorize the request.1. Navigate to the Google API Library `https://console.cloud.google.com/apis/library`:-+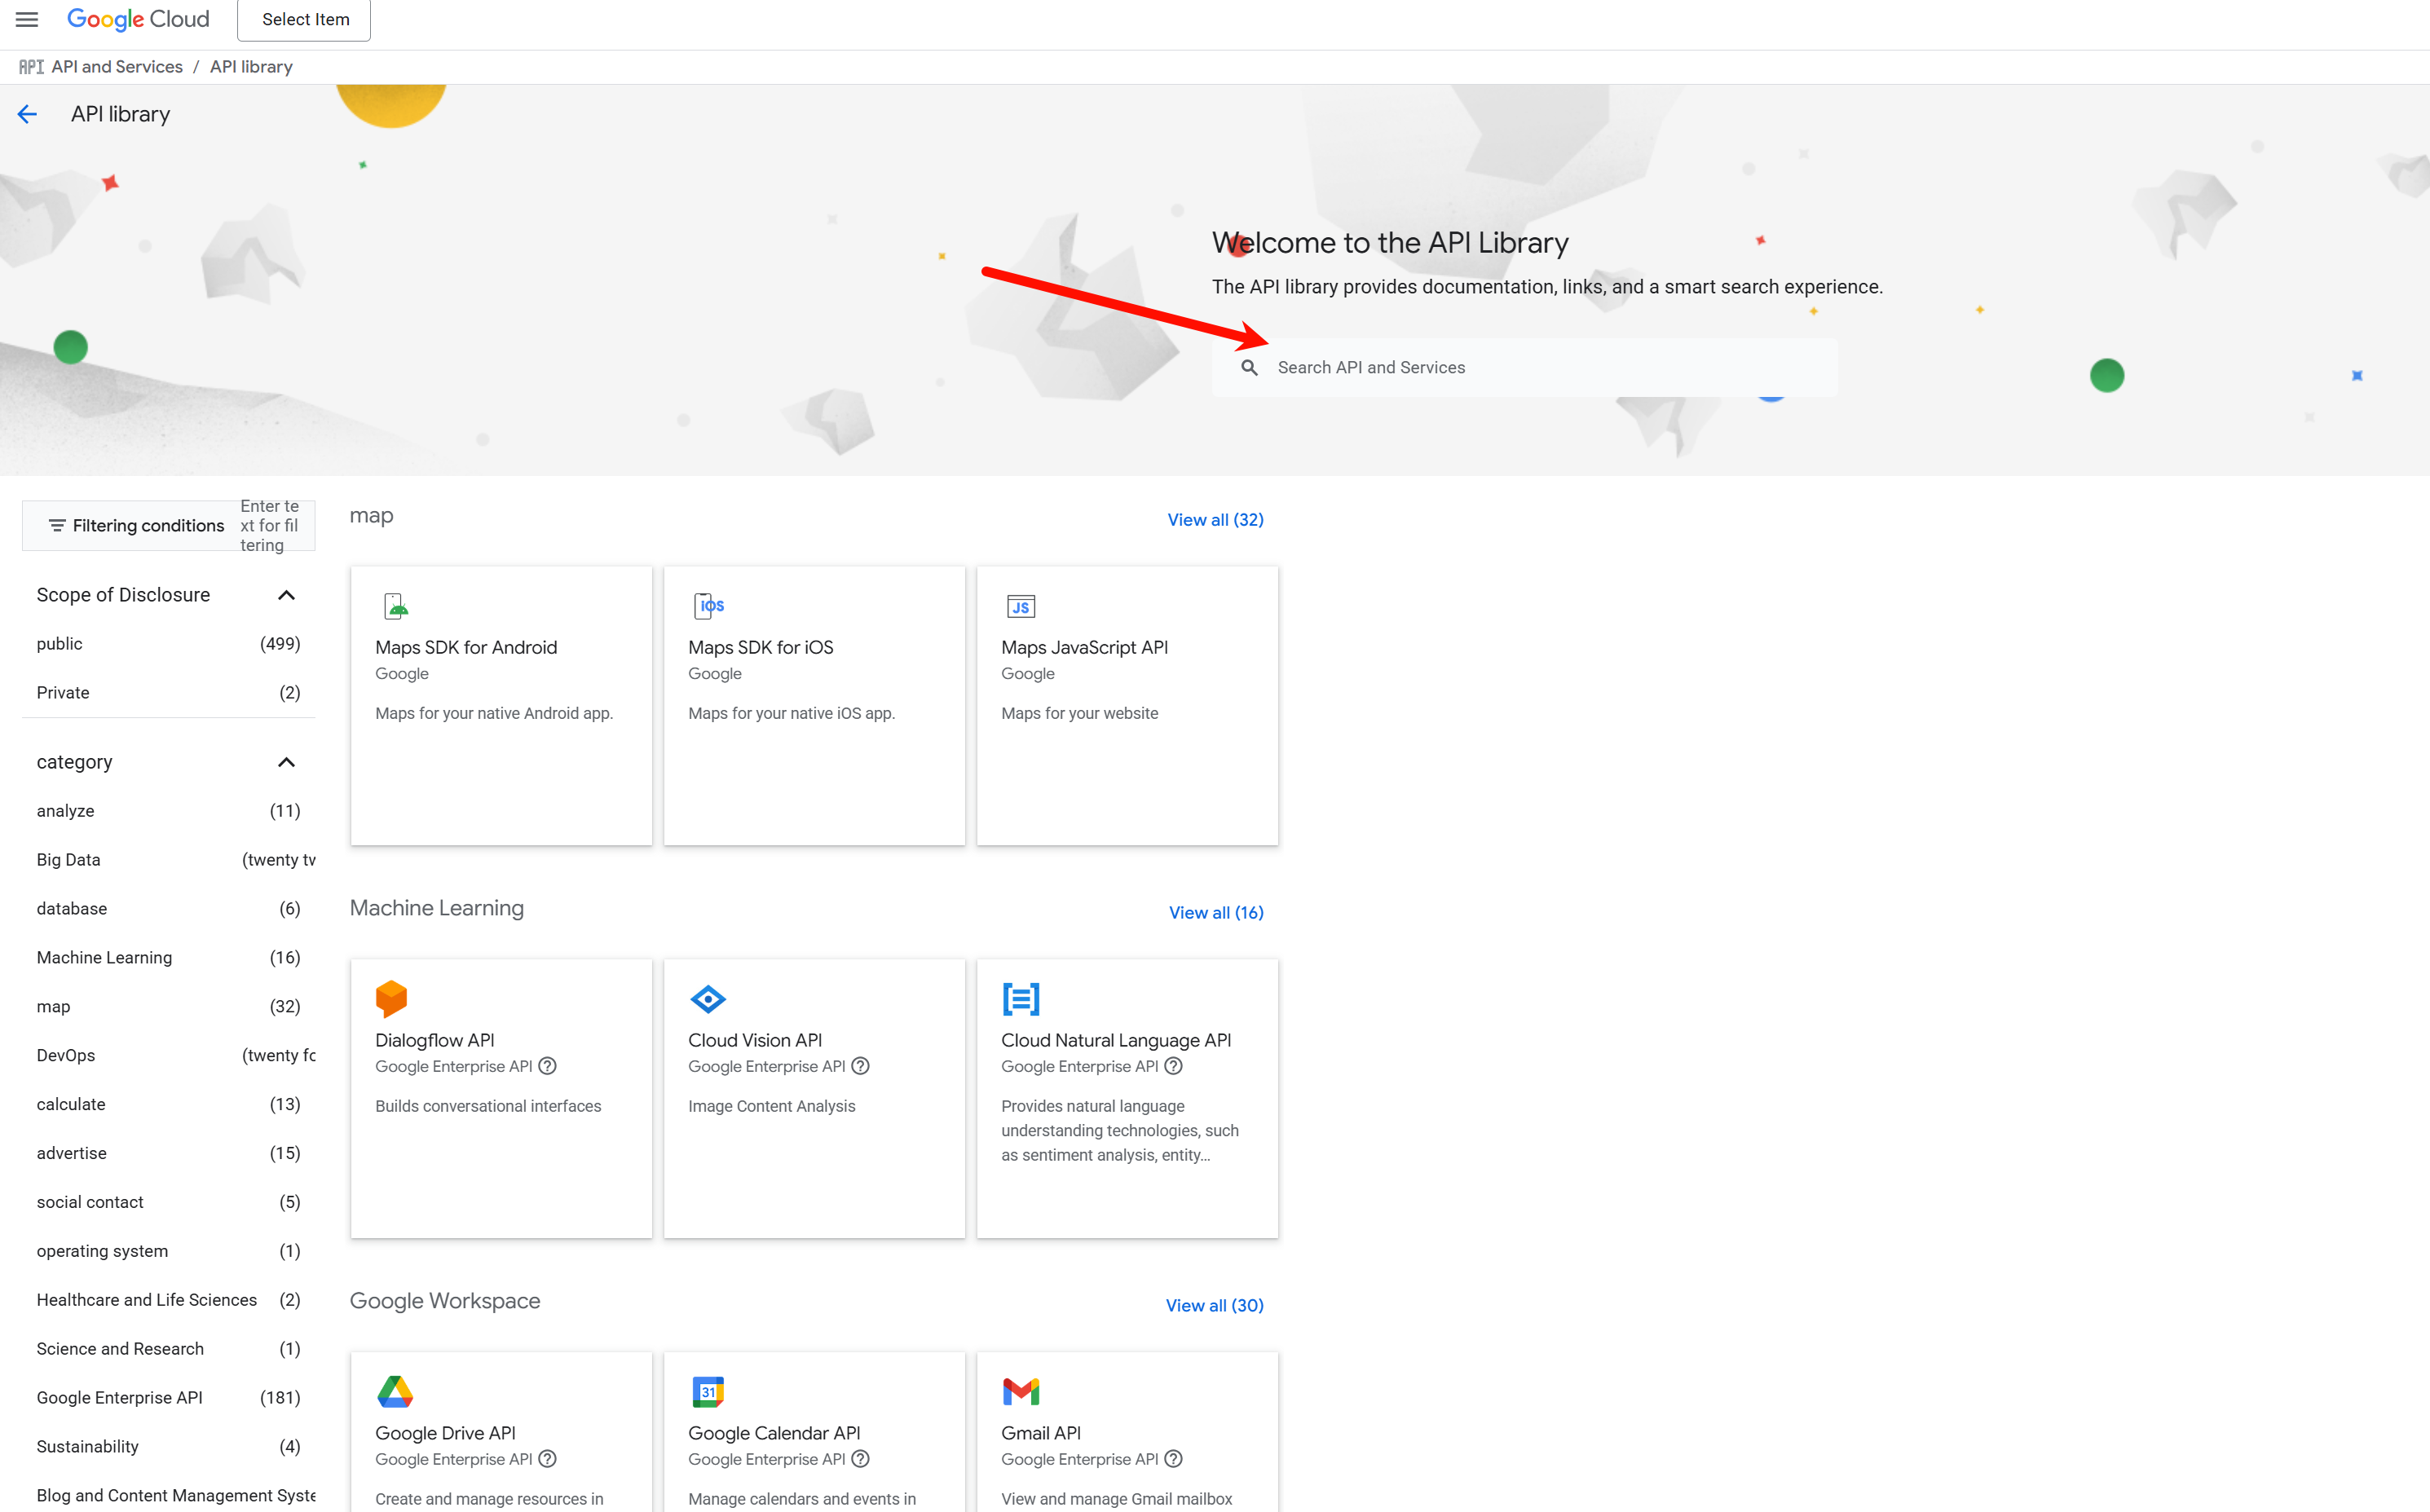2. Enable the following APIs:- Google Drive API@@ -88,26 +90,26 @@ You need to enable the required APIs (such as the Google Drive API) to formally- Google Sheets API- Google Docs API------+++++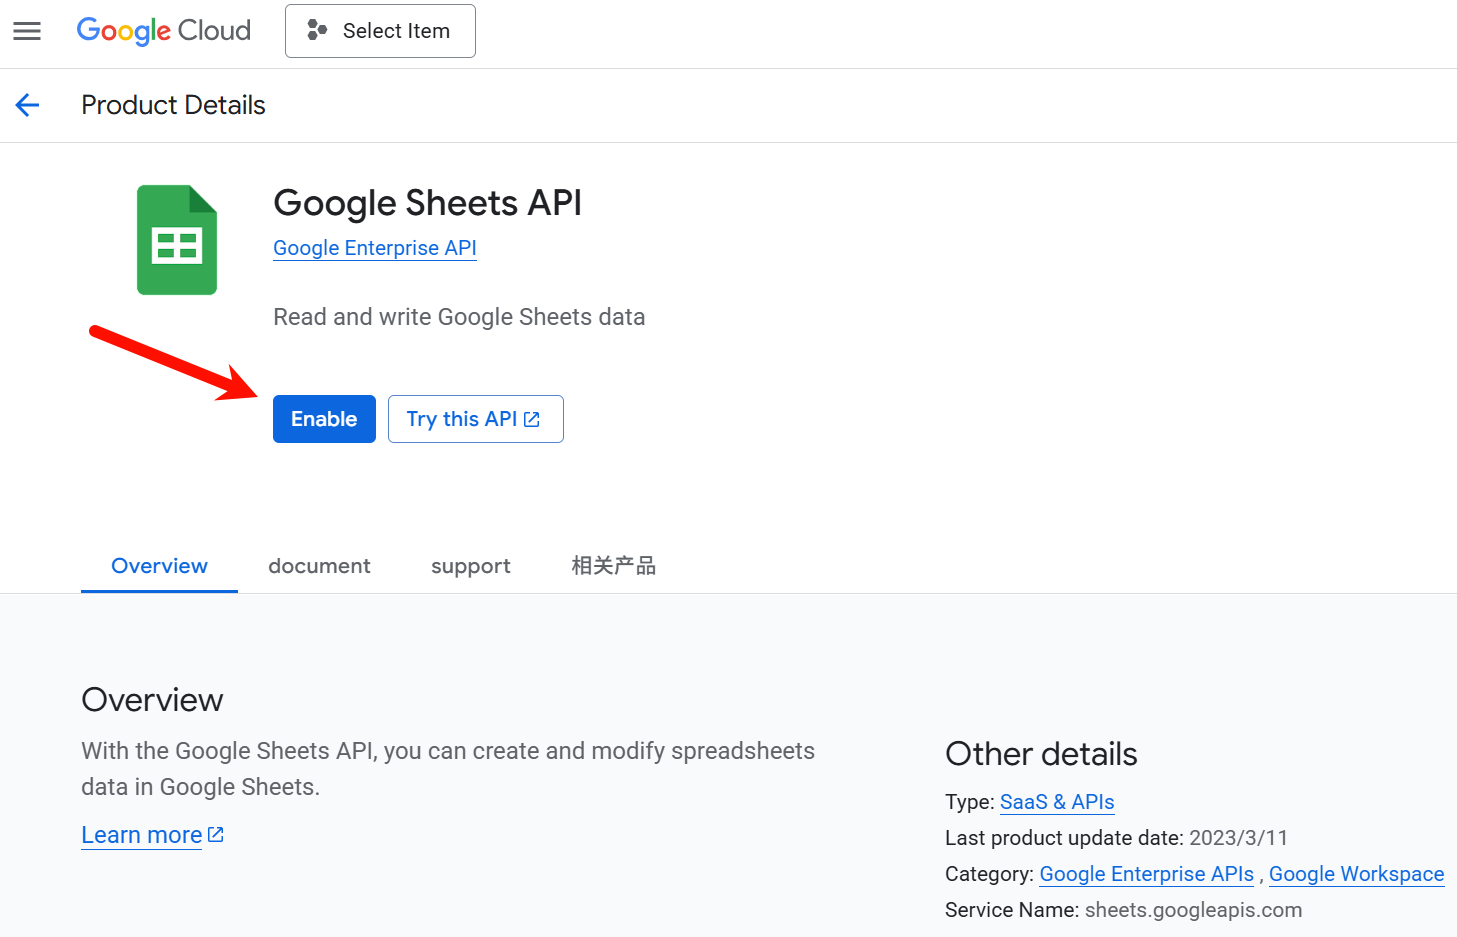+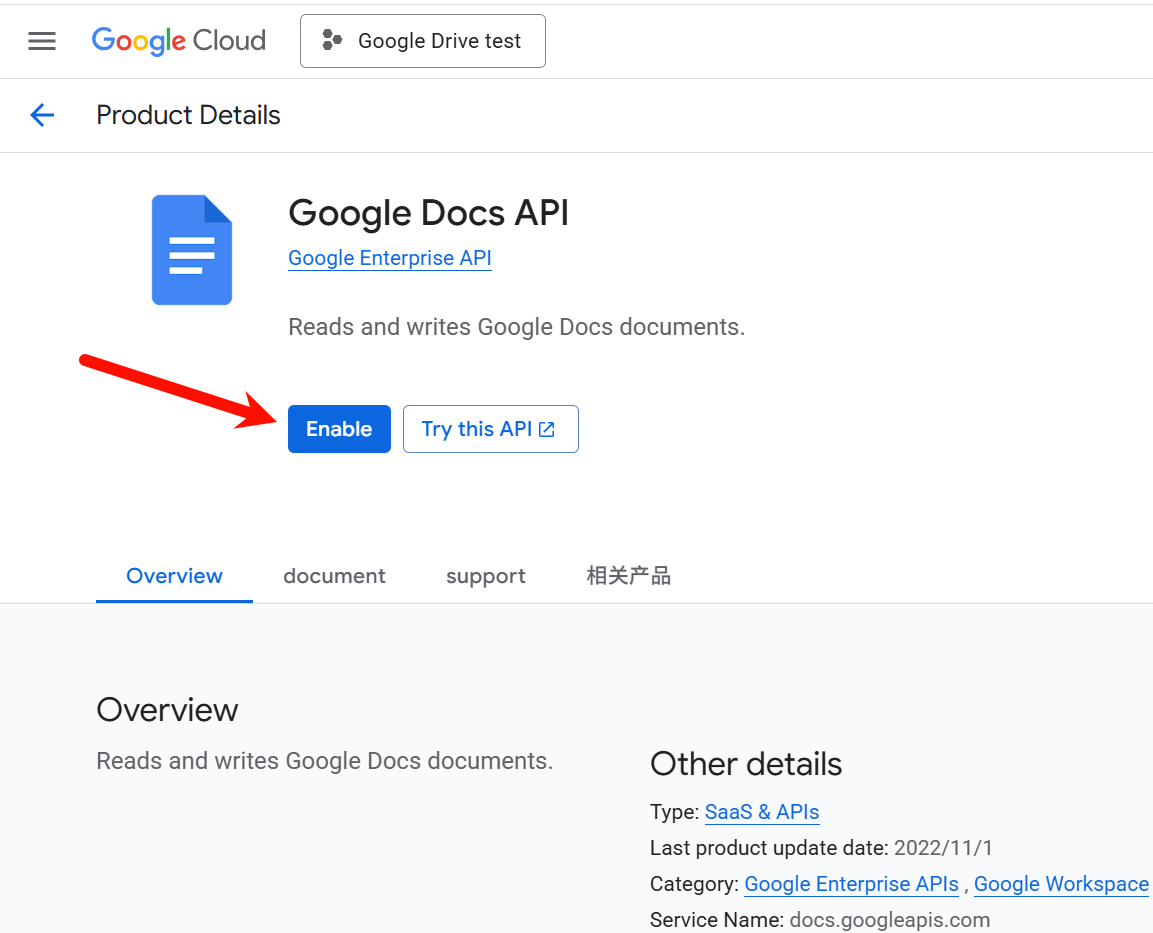-## 6. Add Google Drive as a data source in RAGFlow+## 6. Add Google Drive as a Data Source in RAGFlow1. Go to **Data Sources** inside RAGFlow and select **Google Drive**.-2. Under **OAuth Token JSON**, upload the previously downloaded JSON credentials you saved in [Section 2](#2-configure-oauth-consent-screen):-+2. Under **OAuth Token JSON**, upload the previously downloaded JSON credentials you saved in [Section 3](#3-create-oauth-client-credentials):+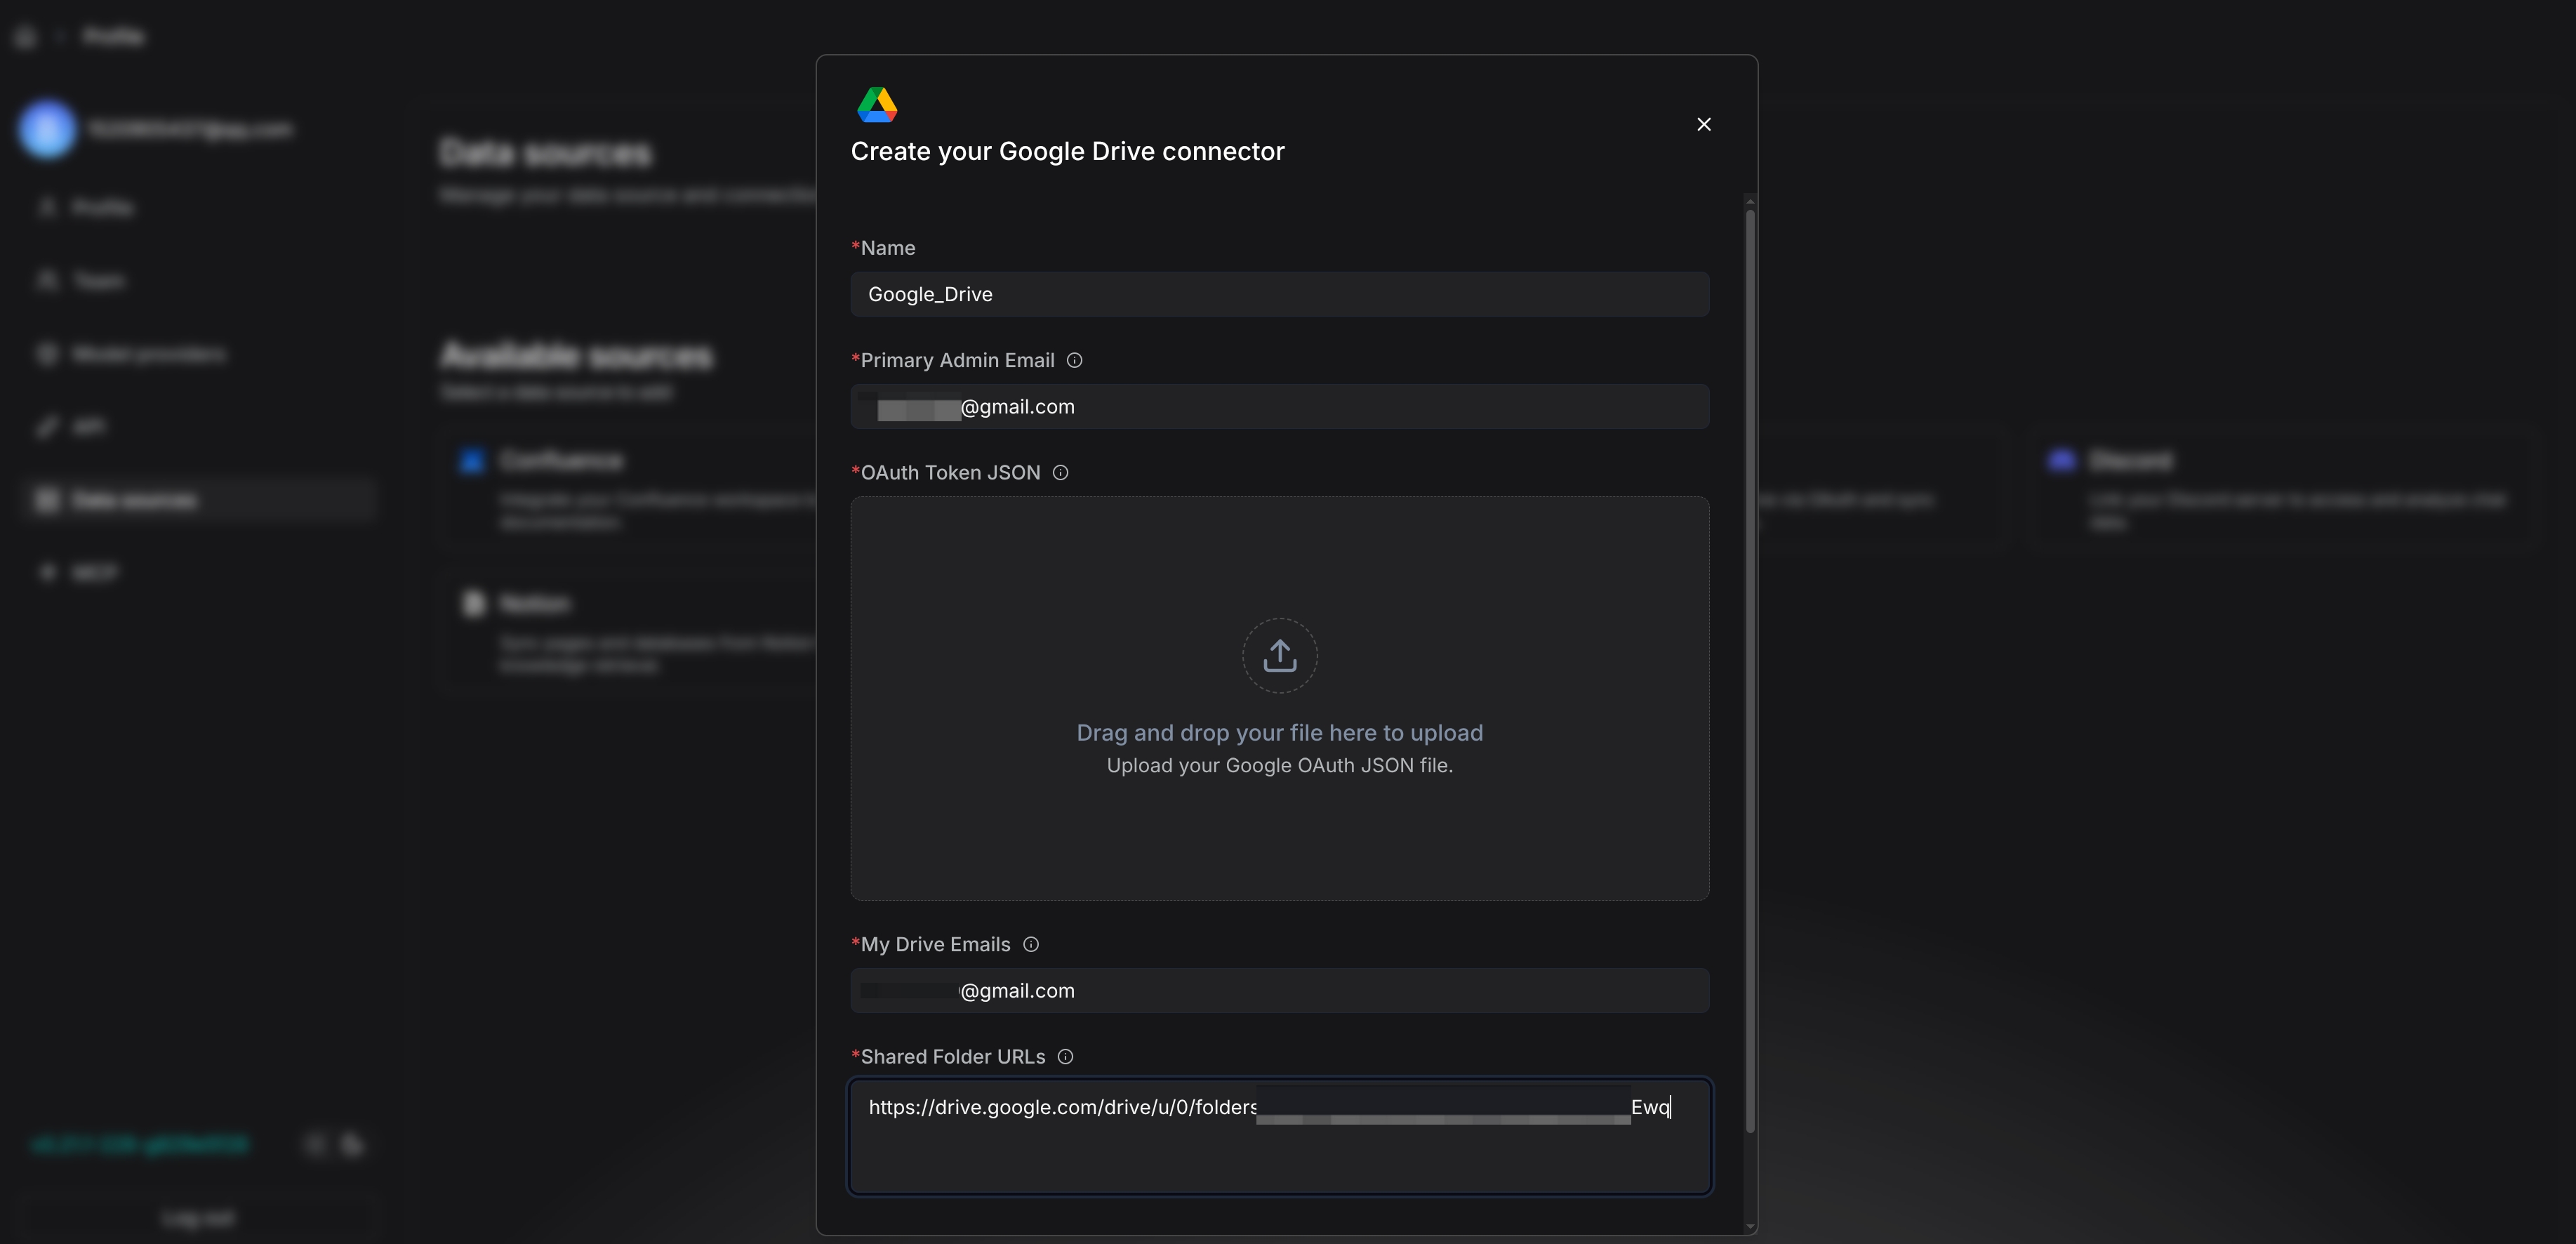3. Enter the url of the shared Google Drive folder link:-+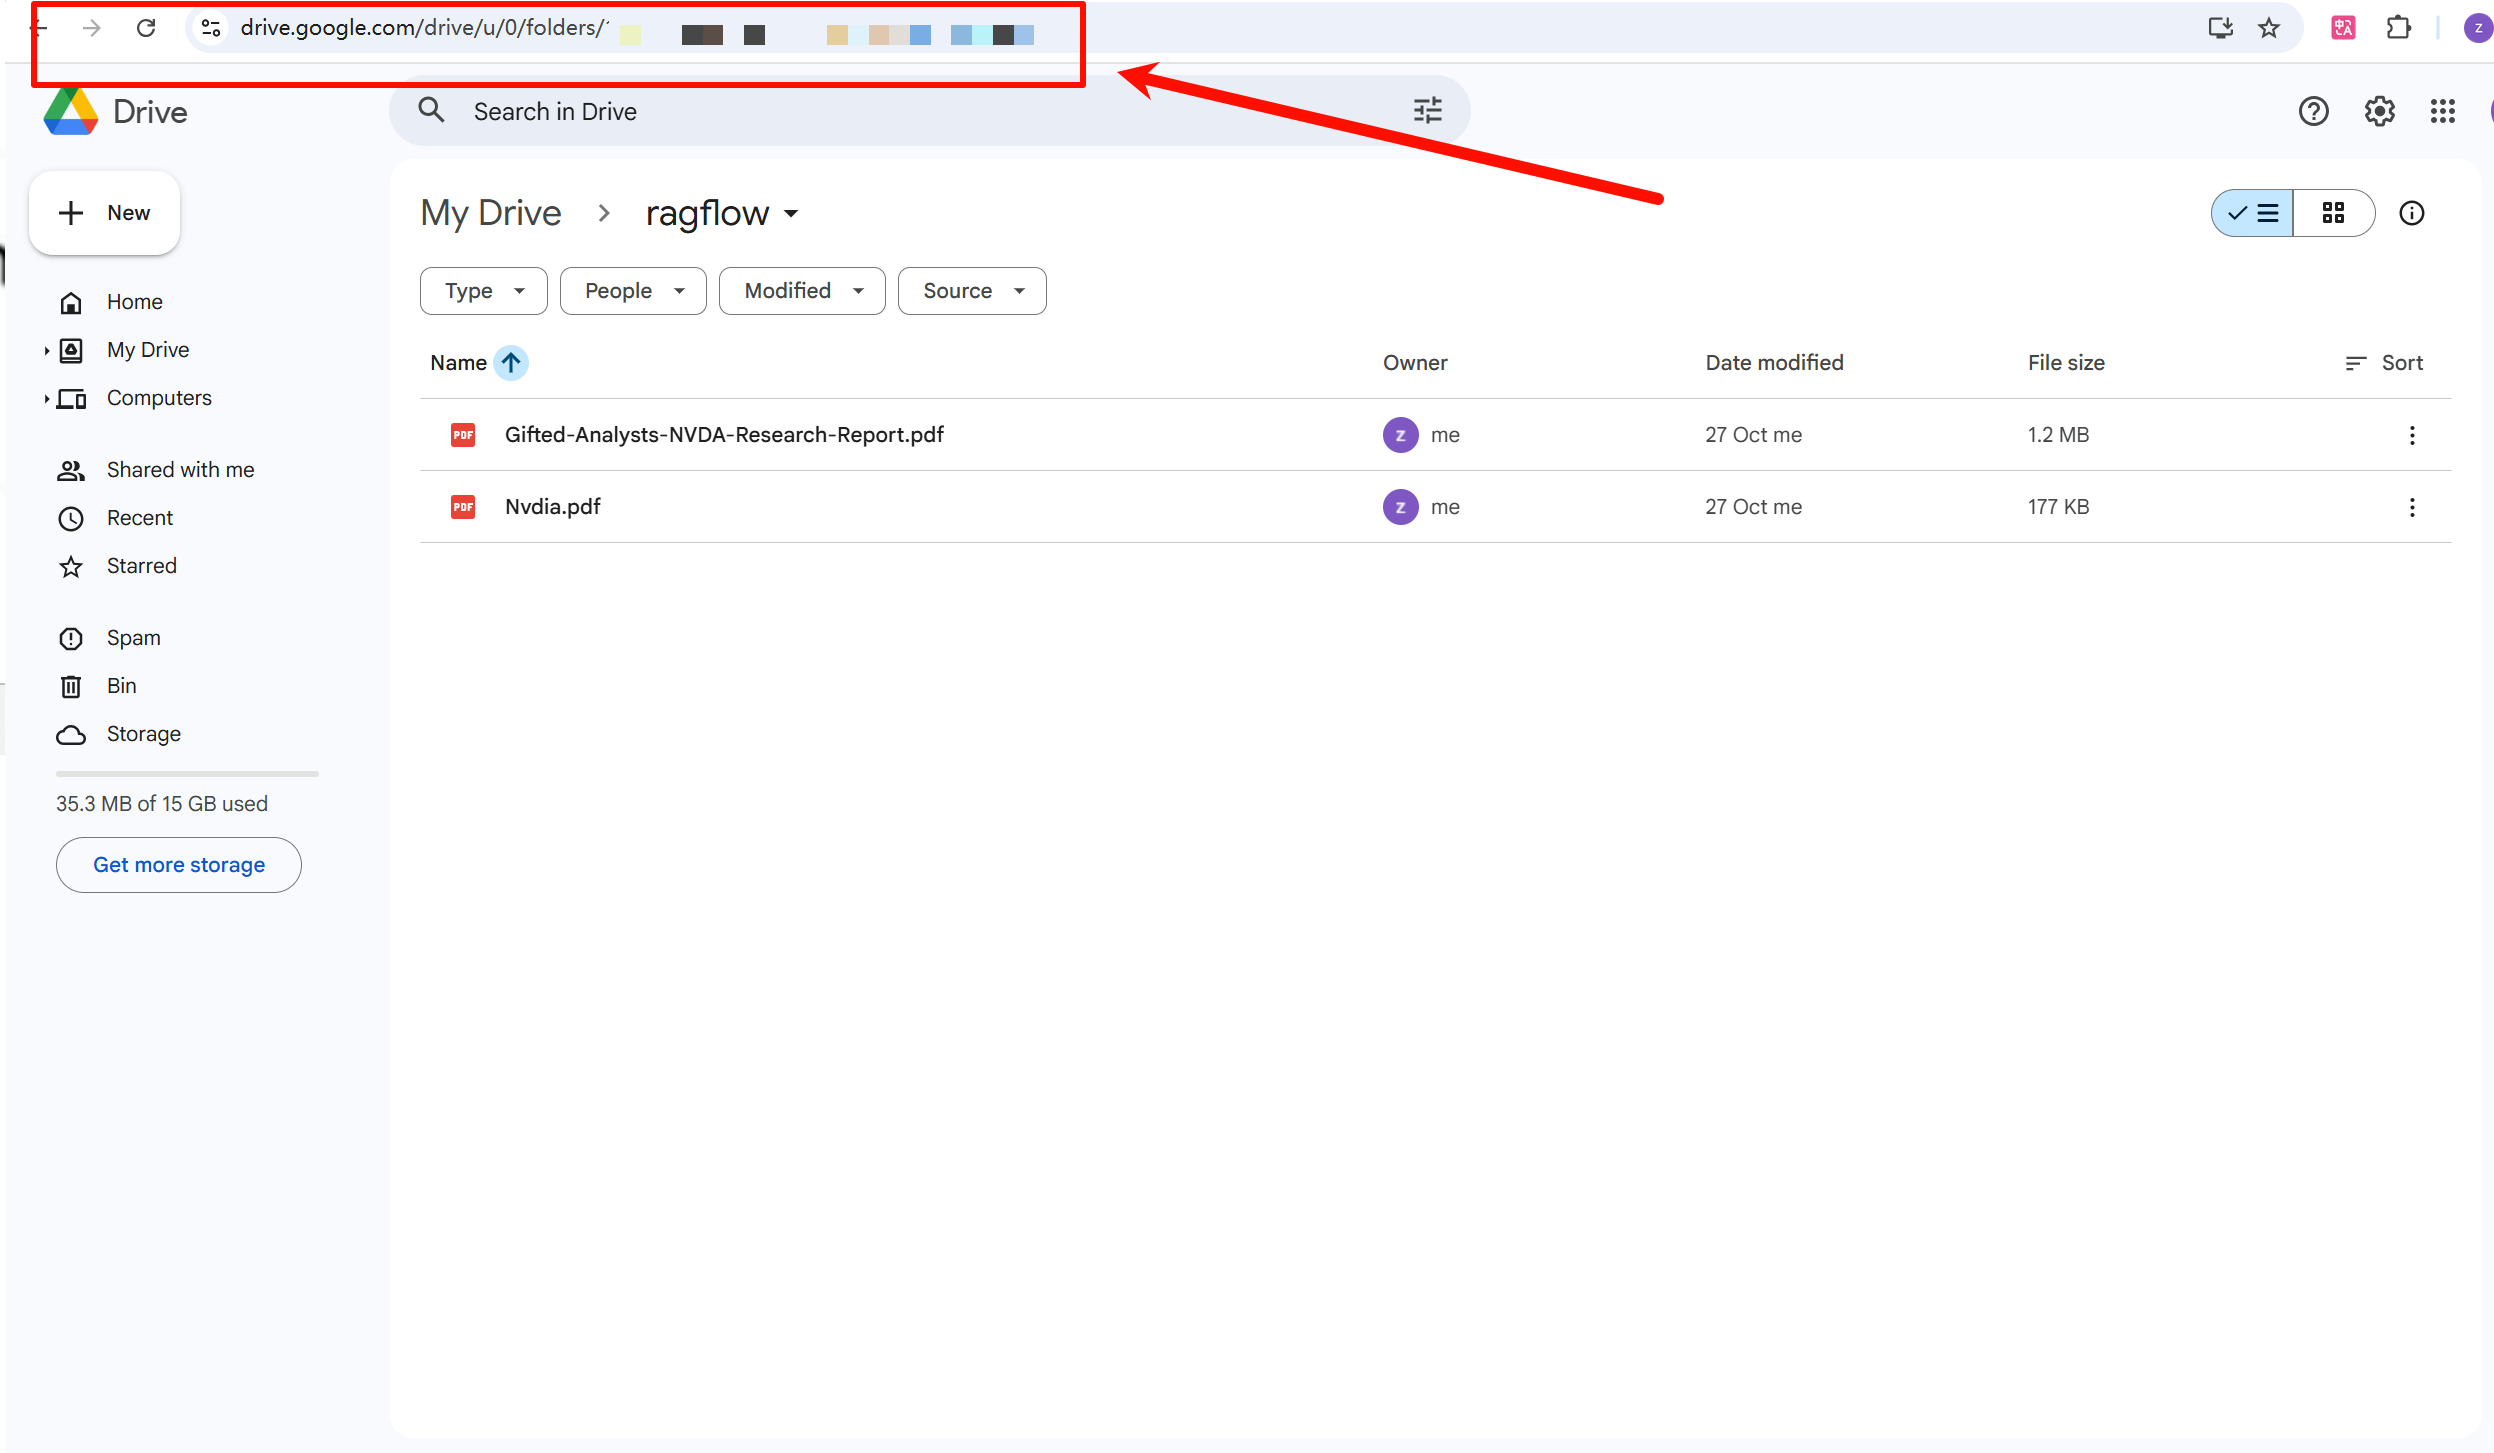4. Click **Authorize with Google**_A browser window appears showing that Google hasn't verified this app._-+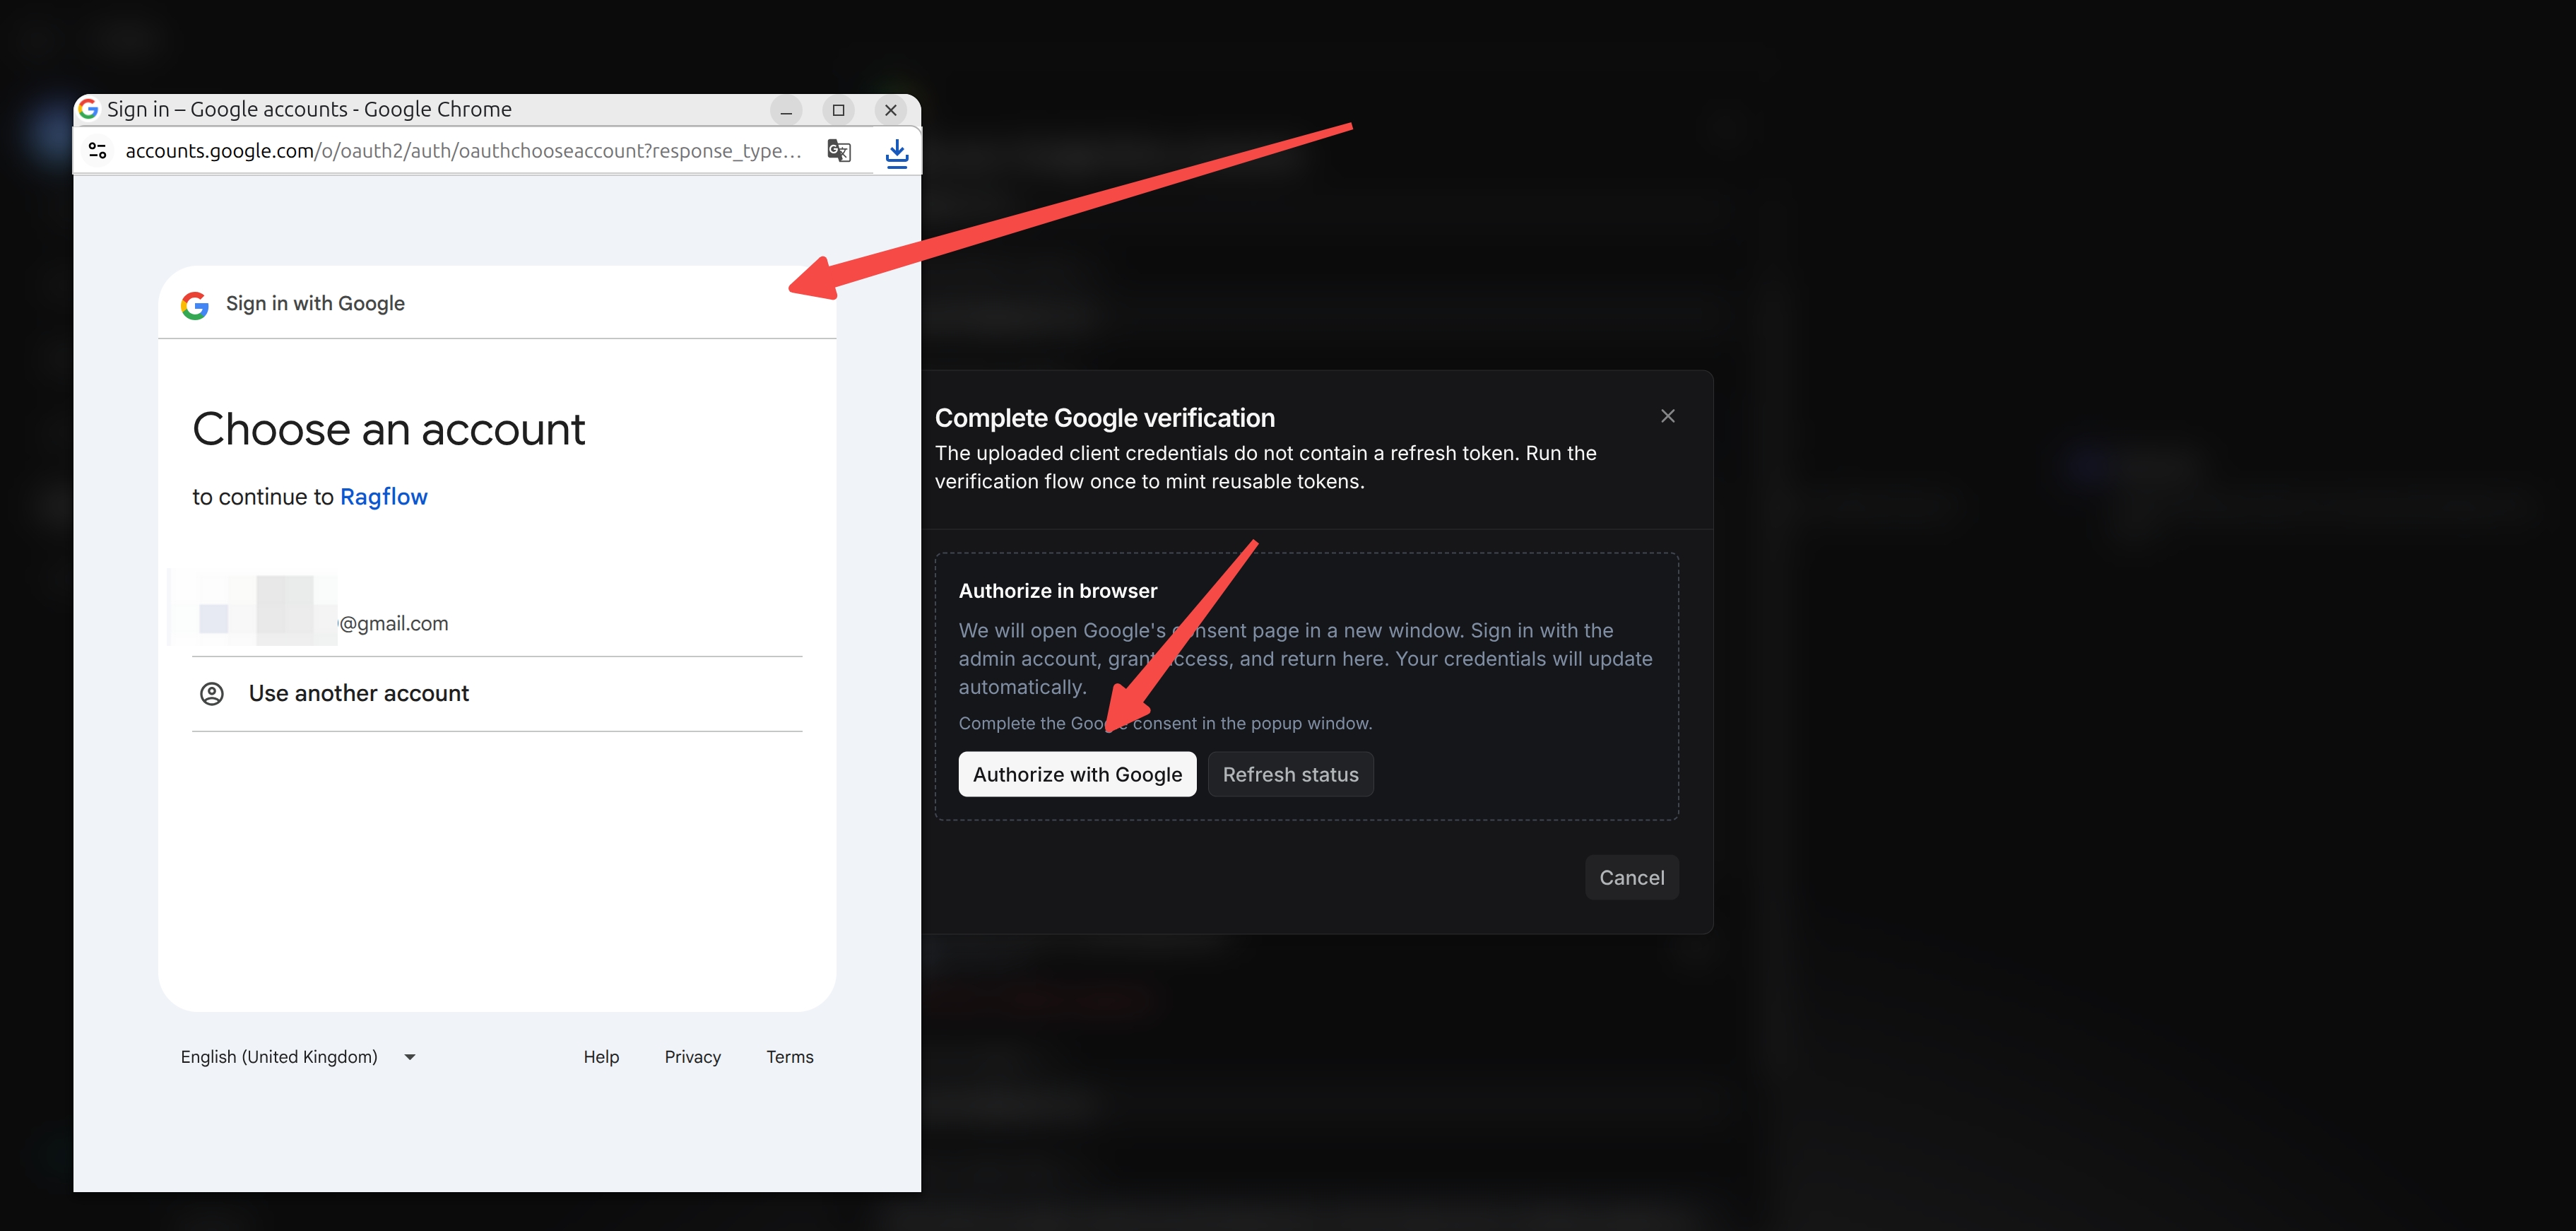5. Click **Continue** → **Select All** → **Continue**.6. When the authorization succeeds, select **OK** to add the data source.----\ No newline at end of file+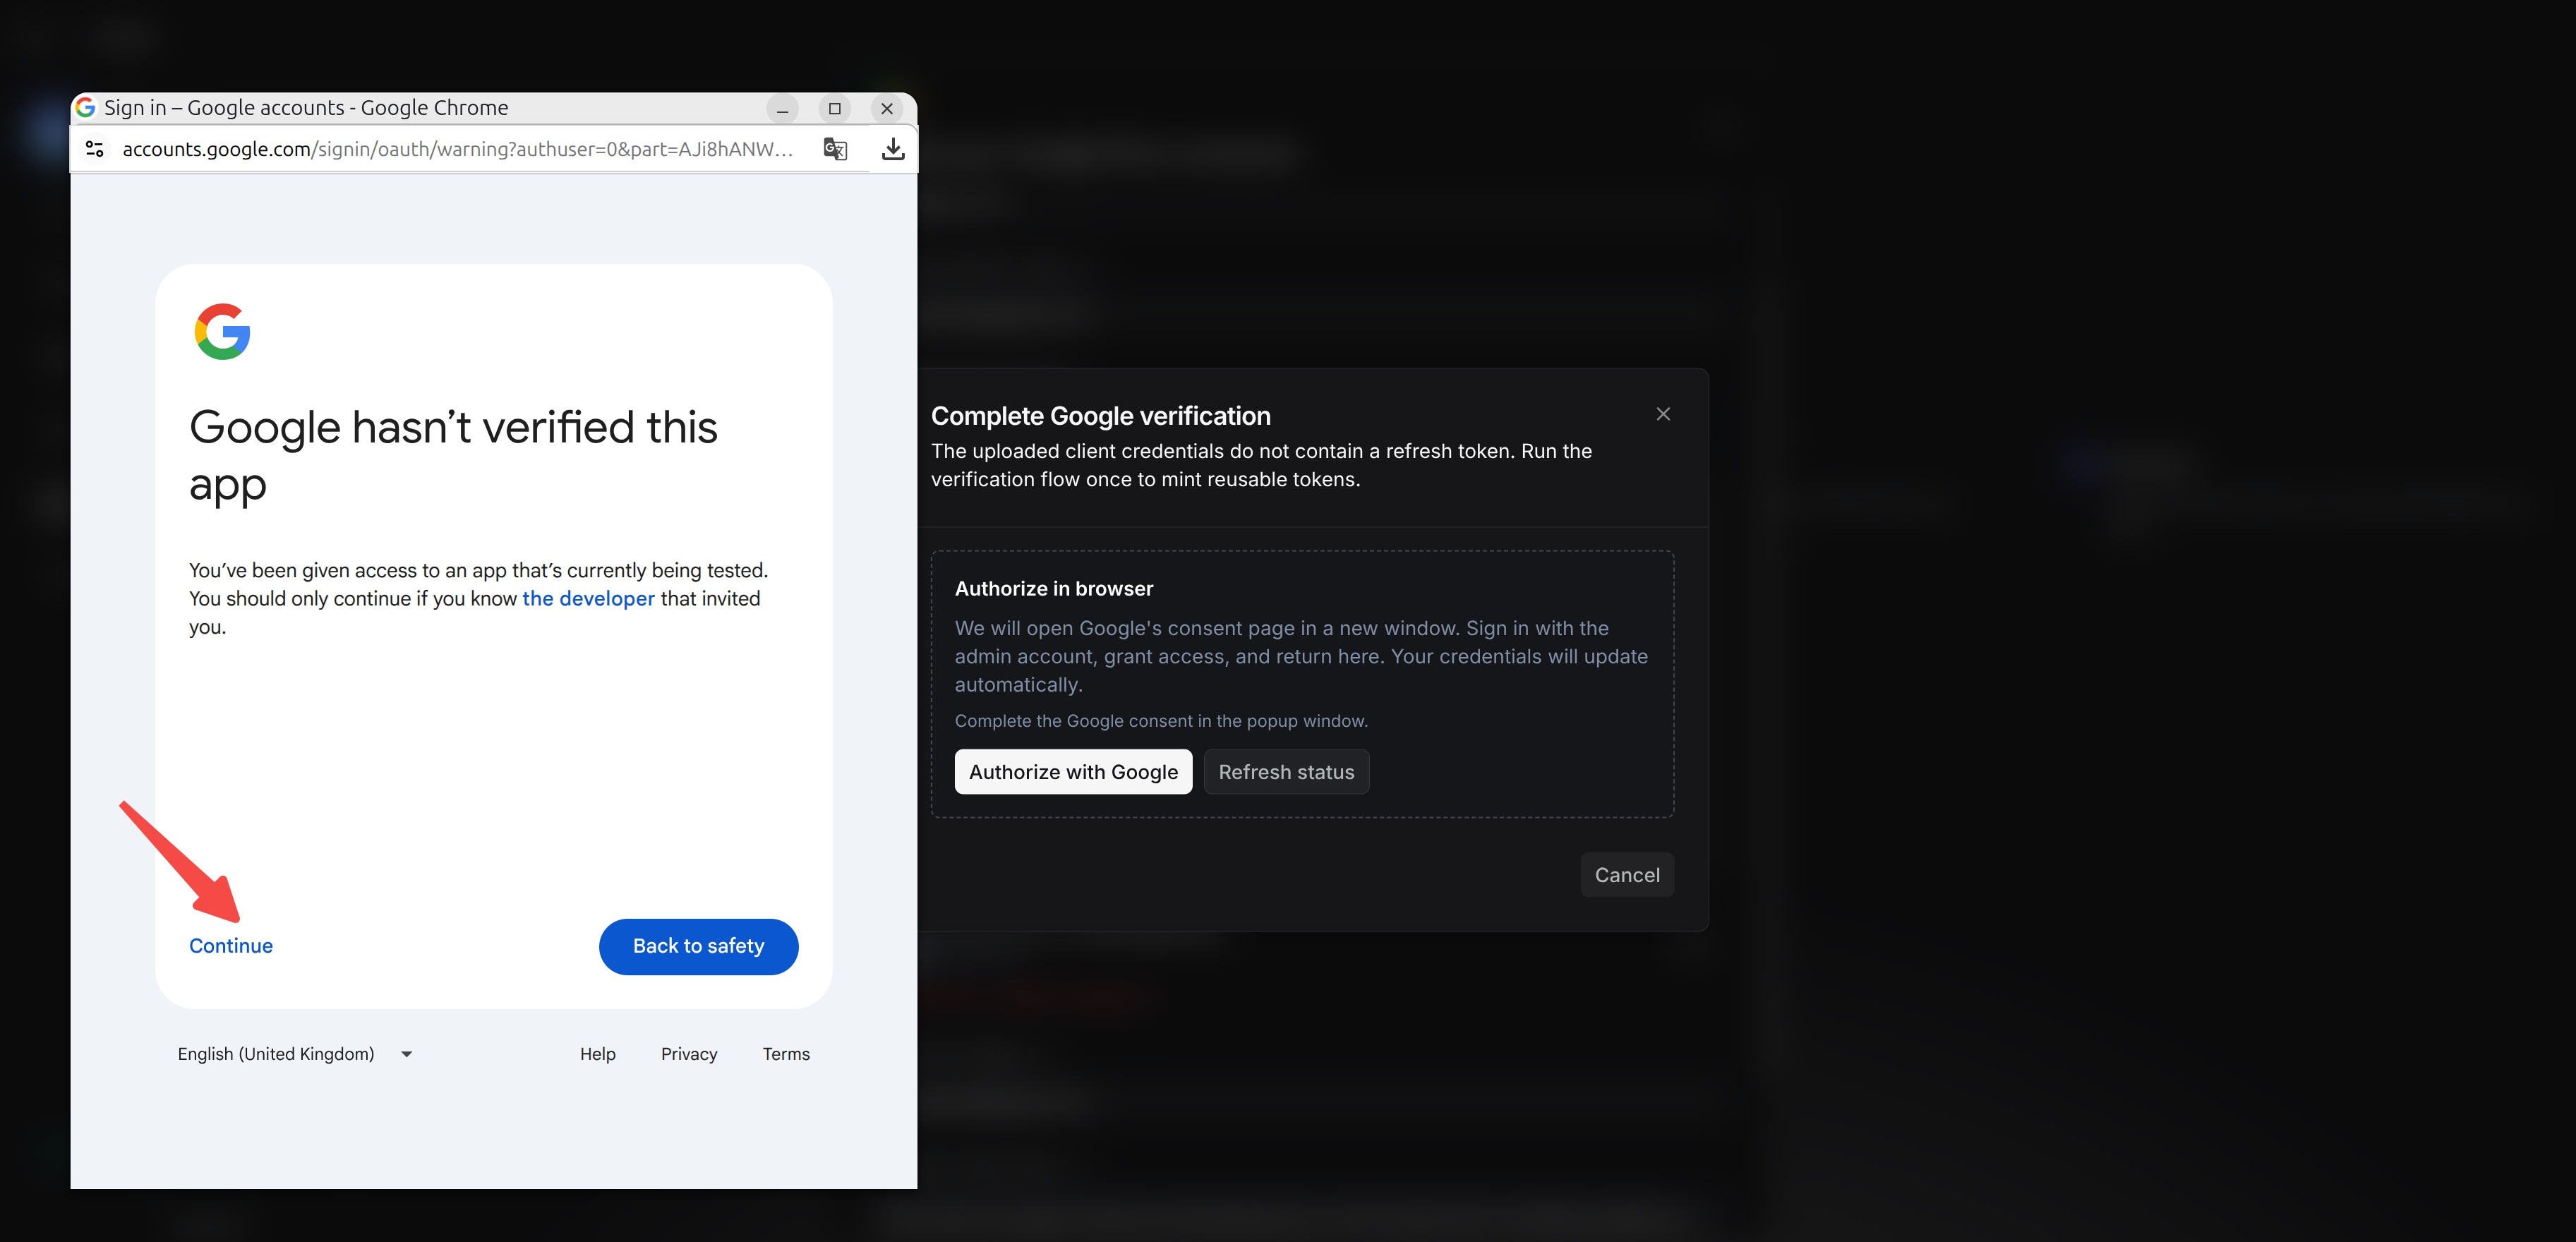+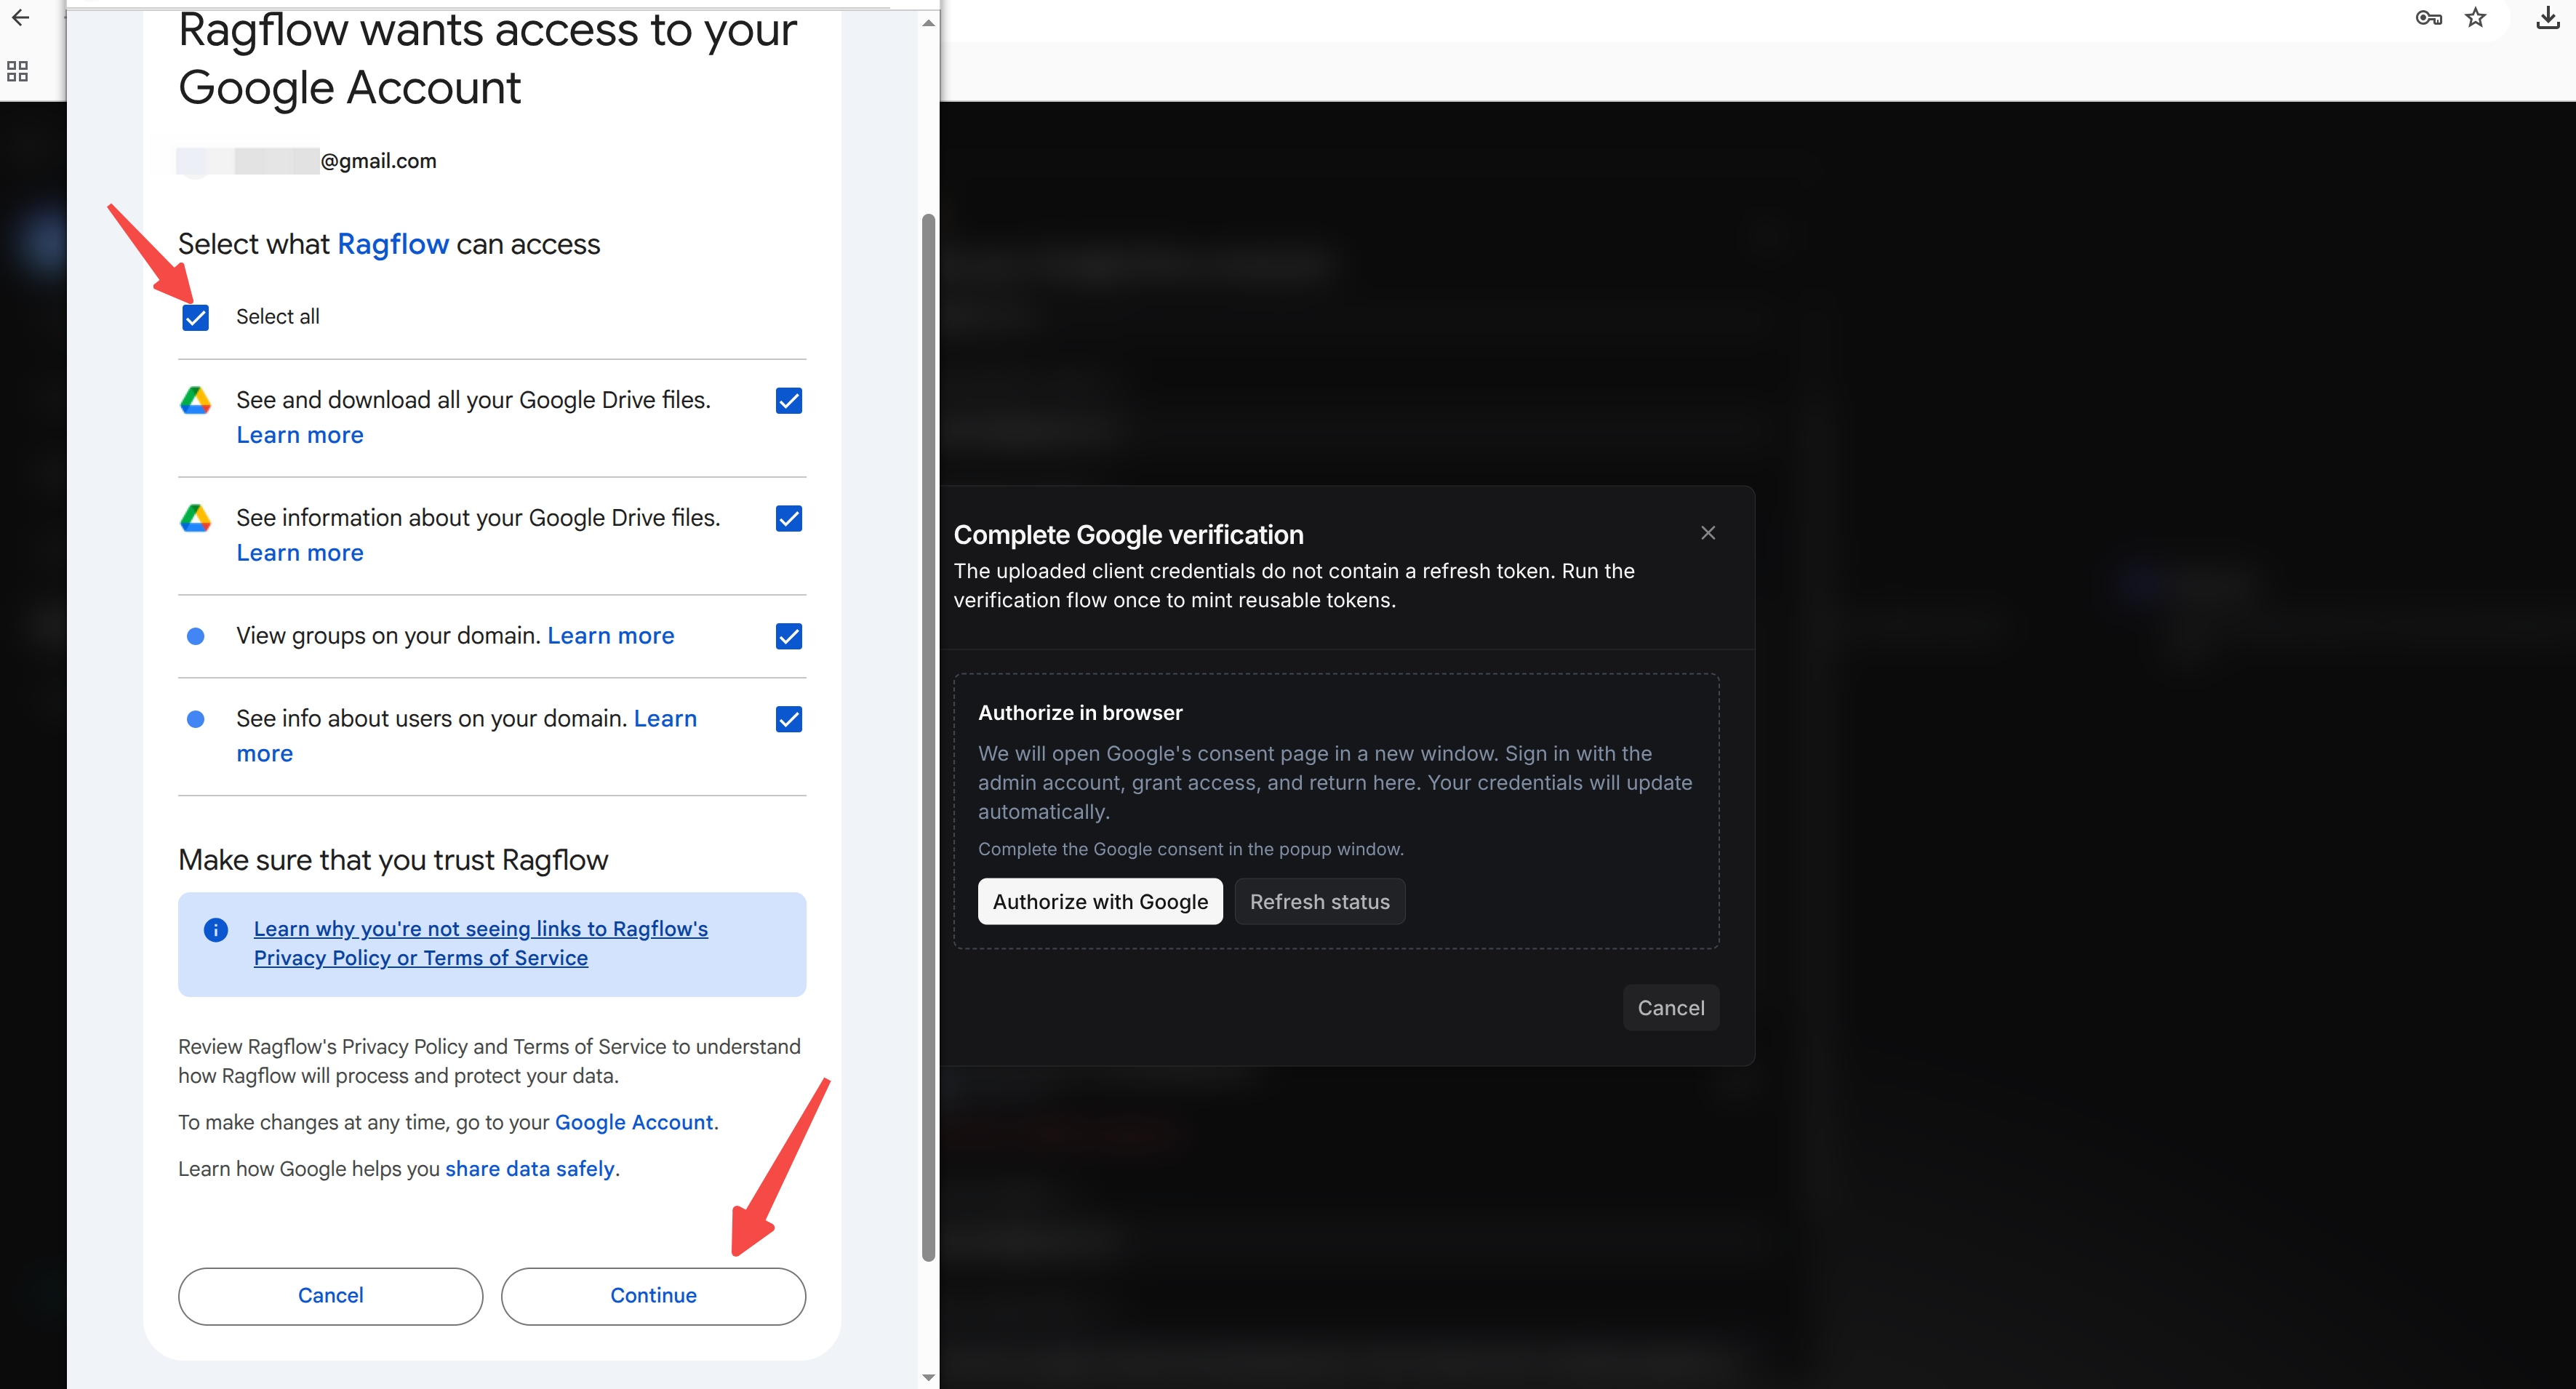+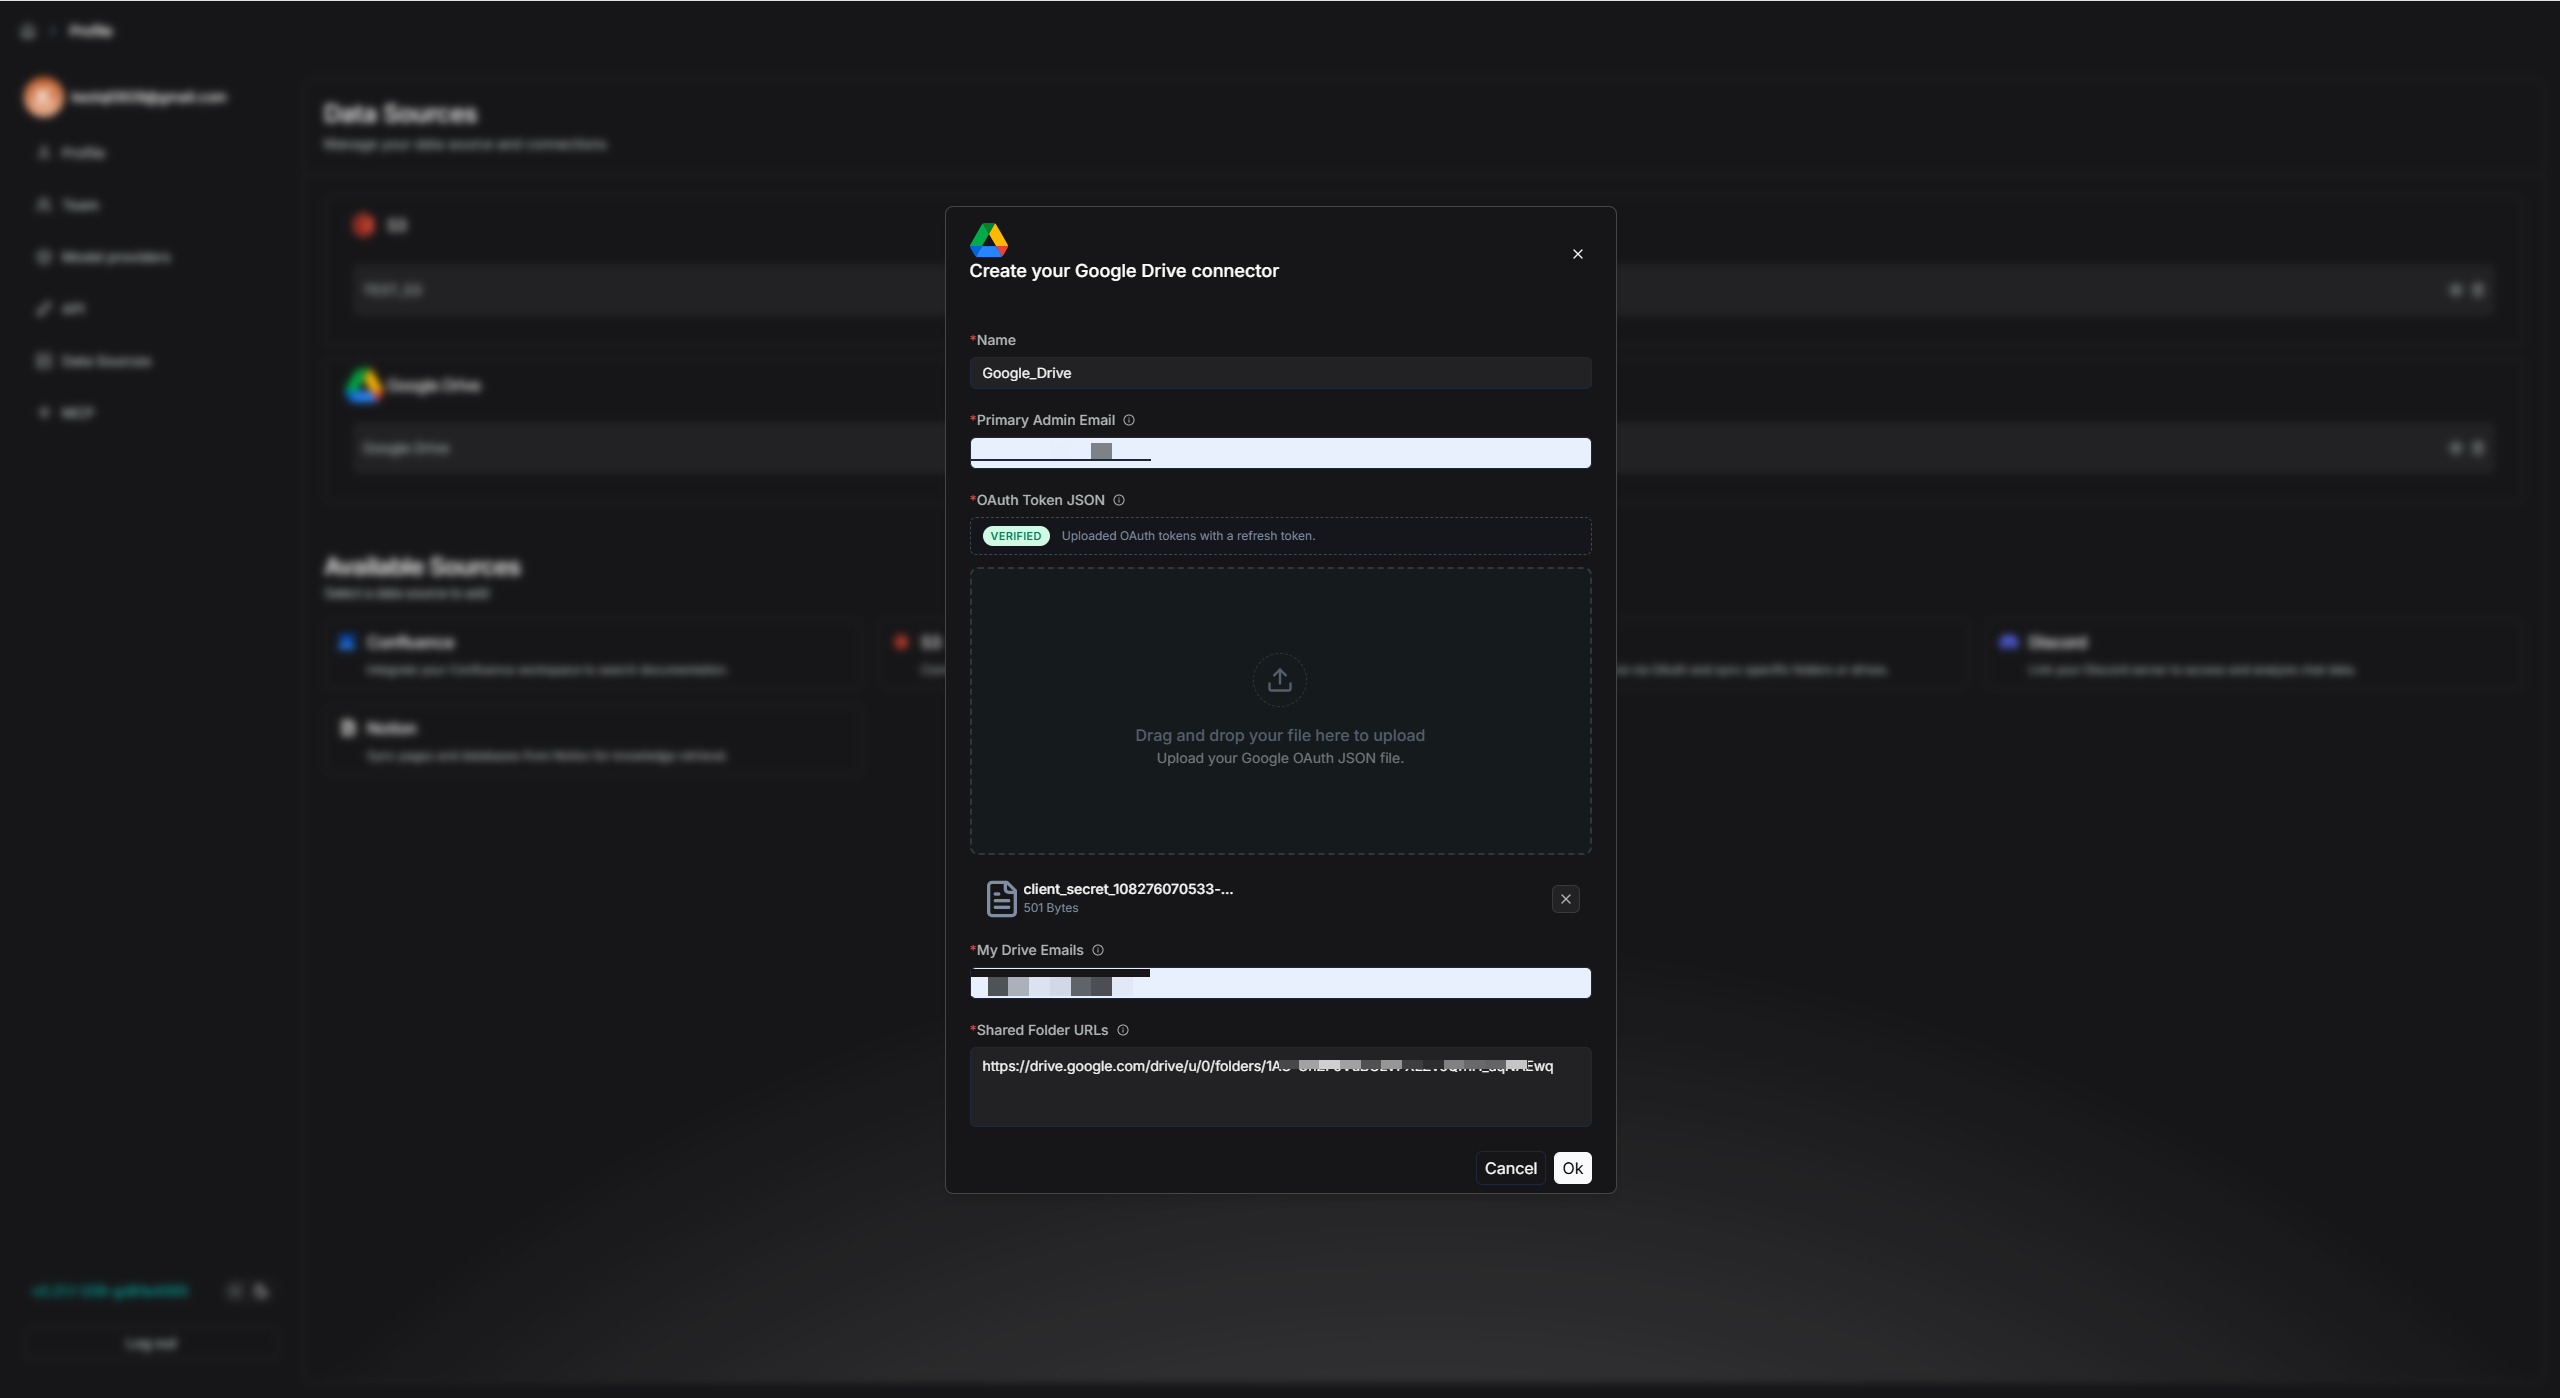+\ No newline at end of filediff --git a/docs/guides/dataset/add_data_source/add_notion.md b/docs/guides/dataset/add_data_source/add_notion.mdindex 4535b6f3d9..b3af4e9419 100644--- a/docs/guides/dataset/add_data_source/add_notion.md+++ b/docs/guides/dataset/add_data_source/add_notion.md@@ -1,5 +1,7 @@---sidebar_position: 5+title: Add Notion+sidebar_label: Add Notionslug: /add_notionsidebar_custom_props: {categoryIcon: SiGoogledrive@@ -18,7 +20,7 @@ Before you begin, ensure you have:----## Create an internal integration+## Create an Internal IntegrationTo allow RAGFlow to access your Notion data, you must first create an internal integration in the Notion developer portal to generate a secret token.@@ -32,7 +34,7 @@ To allow RAGFlow to access your Notion data, you must first create an internal i----## Grant access to your pages+## Grant Access to Your PagesBy default, an integration has no access to any pages in your workspace. You must explicitly share the pages you want RAGFlow to index.@@ -48,7 +50,7 @@ If you share a parent page, all its nested child pages and databases will automa----## Identify the root page id+## Identify the Root Page IDThe **Root Page Id** tells RAGFlow where to start indexing. You can find this in the URL of your Notion page.@@ -59,7 +61,7 @@ The **Root Page Id** tells RAGFlow where to start indexing. You can find this in----## Configure the notion connector in RAGFlow+## Configure the Notion Connector in RAGFlowOnce you have your token and ID, add the connector within the RAGFlow interface.@@ -73,7 +75,7 @@ Once configuration is complete, click **Confirm** to save your changes.*RAGFlow validates the connection immediately.*-### Link to a dataset+### Link to a DatasetCredentials alone do not trigger indexing. You must link the data source to a specific dataset:diff --git a/docs/guides/dataset/add_data_source/add_rss.md b/docs/guides/dataset/add_data_source/add_rss.mdindex be060bd7be..657a9dbebc 100644--- a/docs/guides/dataset/add_data_source/add_rss.md+++ b/docs/guides/dataset/add_data_source/add_rss.md@@ -1,5 +1,7 @@---sidebar_position: 9+title: Add RSS+sidebar_label: Add RSSslug: /add_rsssidebar_custom_props: {categoryIcon: SiGoogledrive@@ -29,7 +31,7 @@ Integrating an RSS data source provides the following advantages:- A valid RSS feed URL.- An existing dataset in RAGFlow.-## Find an RSS feed URL+## Find an RSS Feed URLBefore adding the data source, you need the direct URL of the RSS feed you want to monitor. You can typically find this in a few different ways:@@ -37,7 +39,7 @@ Before adding the data source, you need the direct URL of the RSS feed you want- **Try common URL paths**: Often, you can find the feed by appending common RSS paths to the website's main URL (e.g., `https://example.com/rss`, `https://example.com/feed`, or `https://example.com/atom.xml`).- **Check the page source**: Right-click on the webpage, select **View Page Source**, and press `Ctrl+F` (or `Cmd+F`) to search for `rss` or `application/rss+xml`. The URL will be listed in the `href` attribute of that tag.-## Add an RSS data source+## Add an RSS Data SourceTo add an RSS feed to your dataset, follow these steps:diff --git a/docs/guides/dataset/advanced/_category_.json b/docs/guides/dataset/advanced/_category_.jsonindex 59b6123040..a71322d2ba 100644--- a/docs/guides/dataset/advanced/_category_.json+++ b/docs/guides/dataset/advanced/_category_.json@@ -1,5 +1,5 @@{- "label": "Advanced enrichment",+ "label": "Advanced Enrichment","position": 8,"link": {"type": "generated-index",diff --git a/docs/guides/dataset/advanced/auto_metadata.md b/docs/guides/dataset/advanced/auto_metadata.mdindex 7814489d8e..ea8f03781e 100644--- a/docs/guides/dataset/advanced/auto_metadata.md+++ b/docs/guides/dataset/advanced/auto_metadata.md@@ -1,11 +1,13 @@---sidebar_position: 4+title: Auto-Extract Metadata+sidebar_label: Auto-Extract Metadataslug: /auto_metadatasidebar_custom_props: {categoryIcon: LucideFileCodeCorner}----# Auto-extract metadata+# Auto-Extract MetadataAutomatically extract metadata from uploaded files.@@ -27,18 +29,18 @@ Enabling TOC extraction requires significant memory, computational resources, an1. On your dataset's **Configuration** page, select an indexing model, which will be used to generate the knowledge graph, RAPTOR, auto-metadata, auto-keyword, and auto-question features for this dataset.-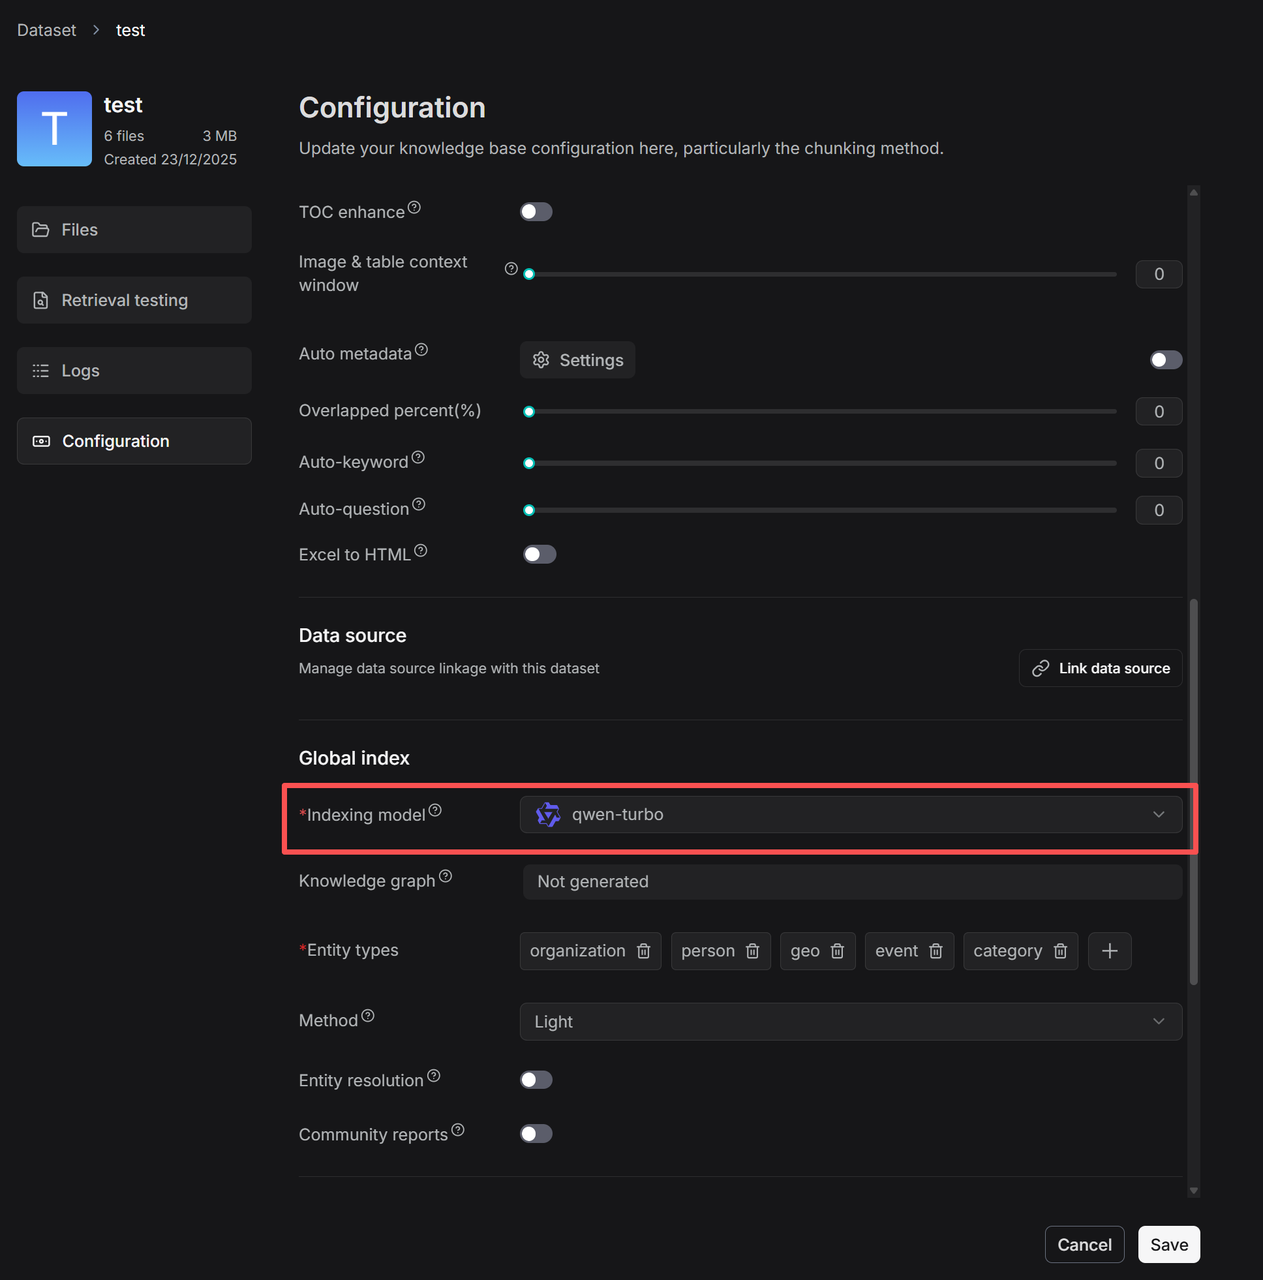+2. Click **Auto metadata** **>** **Settings** to go to the configuration page for automatic metadata generation rules._The configuration page for rules on automatically generating metadata appears._-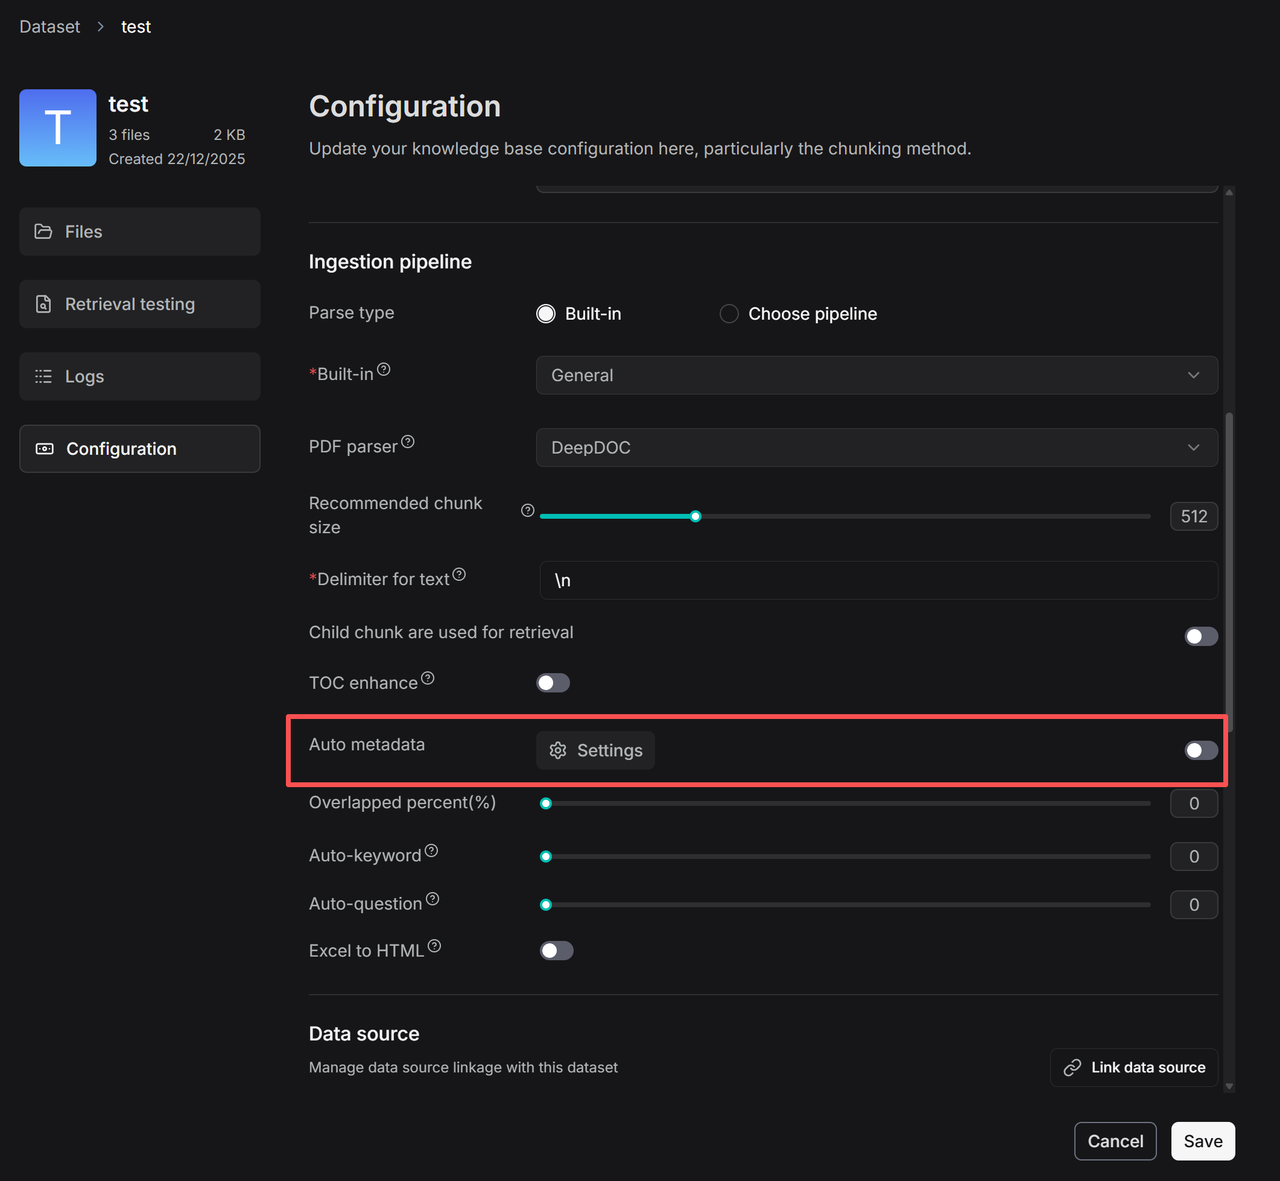+3. Click **+** to add new fields and enter the configuration page.-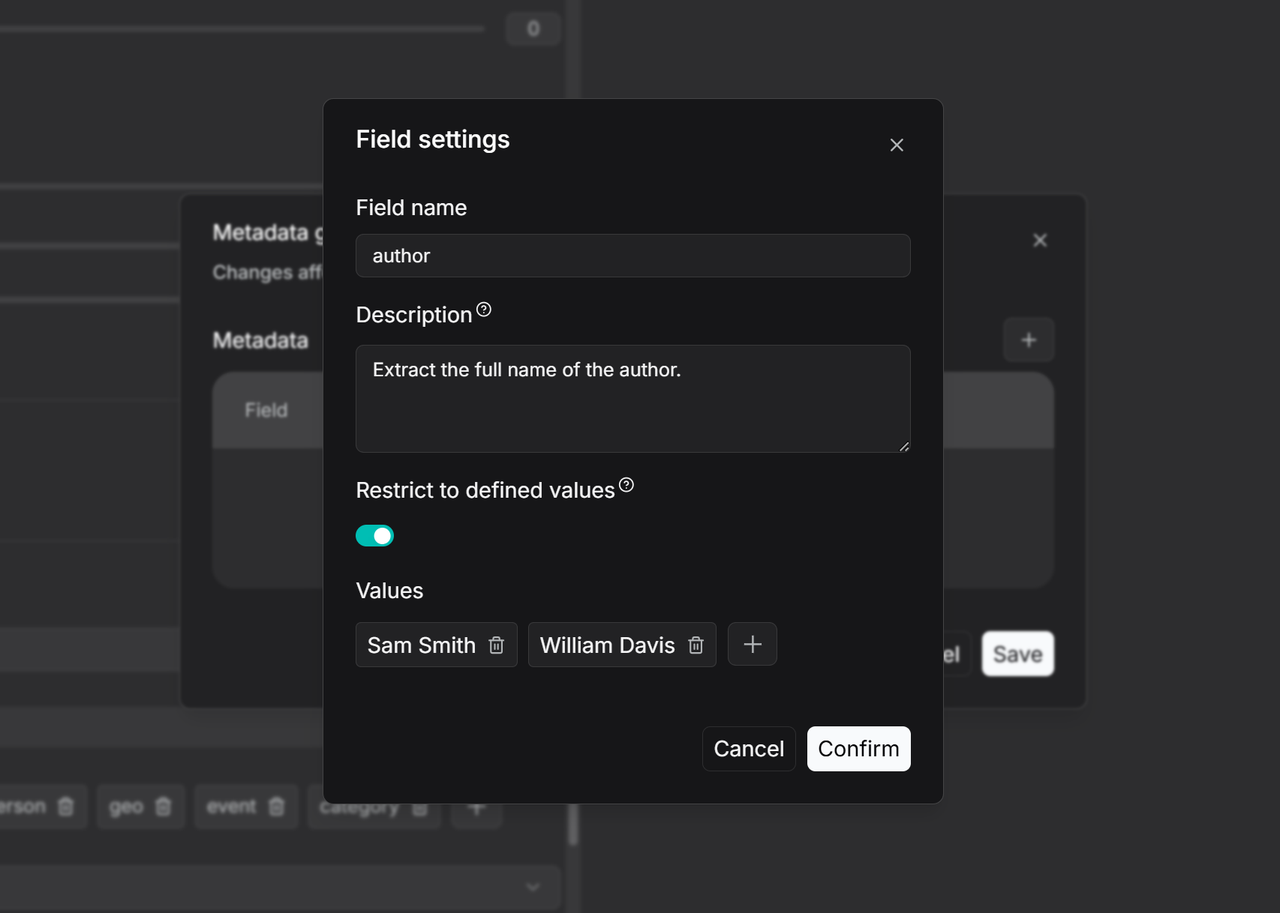+4. Enter a field name, such as Author, and add a description and examples in the Description section. This provides context to the large language model (LLM) for more accurate value extraction. If left blank, the LLM will extract values based only on the field name.@@ -46,5 +48,5 @@ Enabling TOC extraction requires significant memory, computational resources, an6. Once configured, turn on the Auto-metadata switch on the Configuration page. All newly uploaded files will have these rules applied during parsing. For files that have already been processed, you must re-parse them to trigger metadata generation. You can then use the filter function to check the metadata generation status of your files.-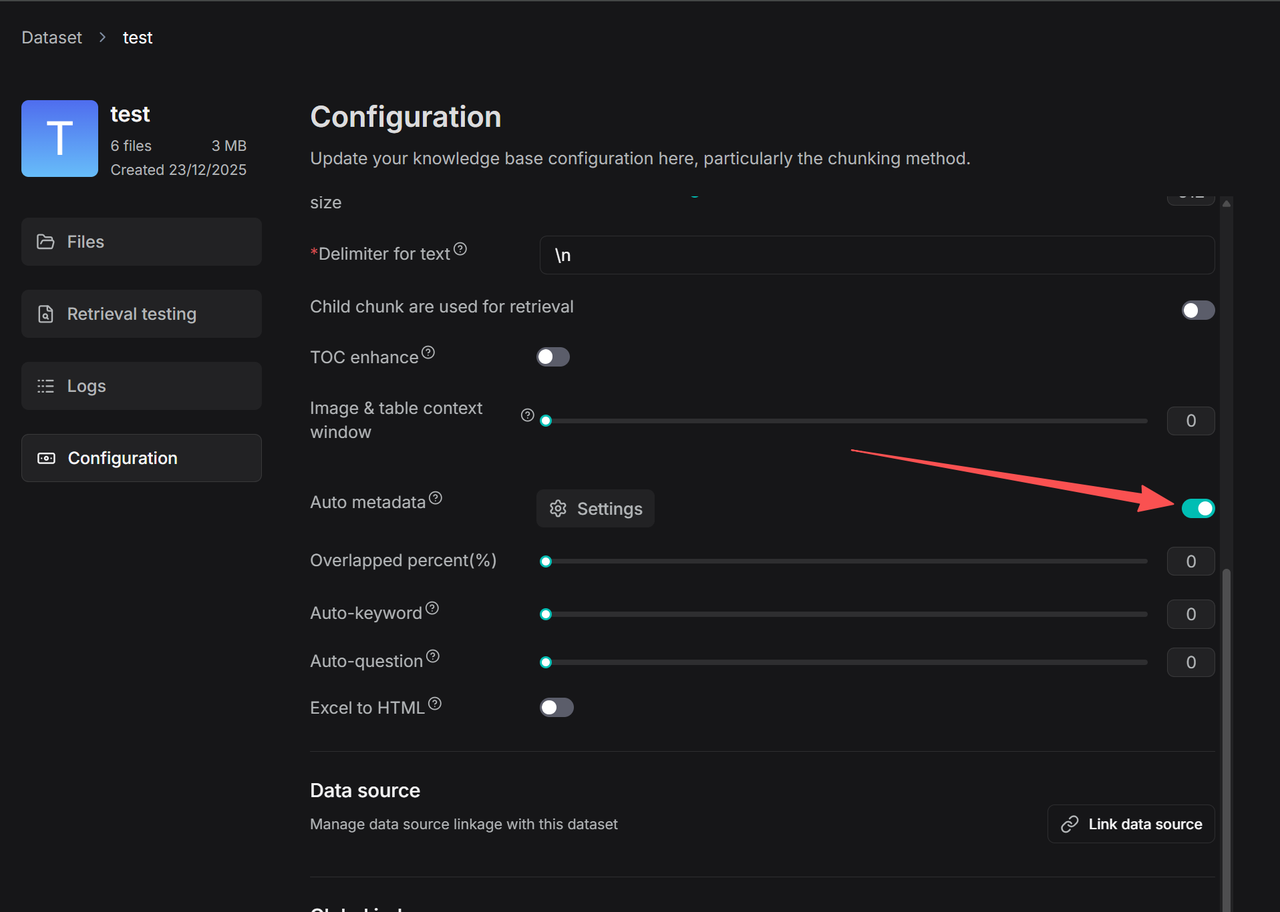+diff --git a/docs/guides/dataset/advanced/autokeyword_autoquestion.mdx b/docs/guides/dataset/advanced/autokeyword_autoquestion.mdxindex ae06006f11..51fe3cd483 100644--- a/docs/guides/dataset/advanced/autokeyword_autoquestion.mdx+++ b/docs/guides/dataset/advanced/autokeyword_autoquestion.mdx@@ -1,11 +1,13 @@---sidebar_position: 0+title: Auto-Keyword Auto-Question+sidebar_label: Auto-Keyword Auto-Questionslug: /autokeyword_autoquestionsidebar_custom_props: {categoryIcon: LucideSlidersHorizontal}----# Auto-keyword Auto-question+# Auto-Keyword Auto-Questionimport APITable from '@site/src/components/APITable';Use a chat model to generate keywords or questions from each chunk in the dataset.@@ -18,7 +20,7 @@ When selecting a chunking method, you can also enable auto-keyword or auto-questEnabling this feature increases document indexing time and uses extra tokens, as all created chunks will be sent to the chat model for keyword or question generation.:::-## What is Auto-keyword?+## What Is Auto-Keyword?Auto-keyword refers to the auto-keyword generation feature of RAGFlow. It uses a chat model to generate a set of keywords or synonyms from each chunk to correct errors and enhance retrieval accuracy. This feature is implemented as a slider under **Page rank** on the **Configuration** page of your dataset.@@ -33,7 +35,7 @@ Auto-keyword refers to the auto-keyword generation feature of RAGFlow. It uses a- An Auto-keyword value must be an integer. If you set it to a non-integer, say 1.7, it will be rounded down to the nearest integer, which in this case is 1.:::-## What is Auto-question?+## What Is Auto-Question?Auto-question is a feature of RAGFlow that automatically generates questions from chunks of data using a chat model. These questions (e.g. who, what, and why) also help correct errors and improve the matching of user queries. The feature usually works with FAQ retrieval scenarios involving product manuals or policy documents. And you can find this feature as a slider under **Page rank** on the **Configuration** page of your dataset.@@ -48,7 +50,7 @@ Auto-question is a feature of RAGFlow that automatically generates questions fro- An Auto-question value must be an integer. If you set it to a non-integer, say 1.7, it will be rounded down to the nearest integer, which in this case is 1.:::-## Tips from the community+## Tips from the CommunityThe Auto-keyword or Auto-question values relate closely to the chunking size in your dataset. However, if you are new to this feature and unsure which value(s) to start with, the following are some value settings we gathered from our community. While they may not be accurate, they provide a starting point at the very least.diff --git a/docs/guides/dataset/advanced/construct_knowledge_graph.md b/docs/guides/dataset/advanced/construct_knowledge_graph.mdindex 8c37417255..4769bb74ac 100644--- a/docs/guides/dataset/advanced/construct_knowledge_graph.md+++ b/docs/guides/dataset/advanced/construct_knowledge_graph.md@@ -1,19 +1,20 @@---sidebar_position: 1+title: Construct Knowledge Graph+sidebar_label: Construct Knowledge Graphslug: /construct_knowledge_graphsidebar_custom_props: {categoryIcon: LucideWandSparkles}----# Construct knowledge graph+# Construct Knowledge GraphGenerate a knowledge graph for your dataset.----To enhance multi-hop question-answering, RAGFlow adds a knowledge graph construction step between data extraction and indexing, as illustrated below. This step creates additional chunks from existing ones generated by your specified chunking method.+To enhance multi-hop question-answering, RAGFlow adds a knowledge graph construction step between data extraction and indexing. This step creates additional chunks from existing ones generated by your specified chunking method.-From v0.16.0 onward, RAGFlow supports constructing a knowledge graph on a dataset, allowing you to construct a *unified* graph across multiple files within your dataset. When a newly uploaded file starts parsing, the generated graph will automatically update.@@ -37,7 +38,7 @@ The system's default chat model is used to generate knowledge graph. Before proc## Configurations-### Entity types (*Required*)+### Entity Types (*Required*)The types of the entities to extract from your dataset. The default types are: **organization**, **person**, **event**, and **category**. Add or remove types to suit your specific dataset.@@ -48,14 +49,14 @@ The method to use to construct knowledge graph:- **General**: Use prompts provided by [GraphRAG](https://github.com/microsoft/graphrag) to extract entities and relationships.- **Light**: (Default) Use prompts provided by [LightRAG](https://github.com/HKUDS/LightRAG) to extract entities and relationships. This option consumes fewer tokens, less memory, and fewer computational resources.-### Entity resolution+### Entity ResolutionWhether to enable entity resolution. You can think of this as an entity deduplication switch. When enabled, the LLM will combine similar entities - e.g., '2025' and 'the year of 2025', or 'IT' and 'Information Technology' - to construct a more effective graph.- (Default) Disable entity resolution.- Enable entity resolution. This option consumes more tokens.-### Community reports+### Community ReportsIn a knowledge graph, a community is a cluster of entities linked by relationships. You can have the LLM generate an abstract for each community, known as a community report. See [here](https://www.microsoft.com/en-us/research/blog/graphrag-improving-global-search-via-dynamic-community-selection/) for more information. This indicates whether to generate community reports:@@ -85,20 +86,20 @@ In a knowledge graph, a community is a cluster of entities linked by relationshi- In the **Chat setting** panel of your chat app, switch on the **Use knowledge graph** toggle.- If you are using an agent, click the **Retrieval** agent component to specify the dataset(s) and switch on the **Use knowledge graph** toggle.-## Frequently asked questions+## Frequently Asked Questions-### Does the knowledge graph automatically update when I remove a related file?+### Does the Knowledge Graph Automatically Update When I Remove a Related File?Nope. The knowledge graph does *not* update *until* you regenerate a knowledge graph for your dataset.-### How to remove a generated knowledge graph?+### How to Remove a Generated Knowledge Graph?On the **Configuration** page of your dataset, find the **Knowledge graph** field and click the recycle bin button to the right of the field.-### Where is the created knowledge graph stored?+### Where Is the Created Knowledge Graph Stored?All chunks of the created knowledge graph are stored in RAGFlow's document engine: either Elasticsearch or [Infinity](https://github.com/infiniflow/infinity).-### How to export a created knowledge graph?+### How to Export a Created Knowledge Graph?Nope. Exporting a created knowledge graph is not supported. If you still consider this feature essential, please [raise an issue](https://github.com/infiniflow/ragflow/issues) explaining your use case and its importance.diff --git a/docs/guides/dataset/advanced/enable_raptor.md b/docs/guides/dataset/advanced/enable_raptor.mdindex ce21213d90..916632f5be 100644--- a/docs/guides/dataset/advanced/enable_raptor.md+++ b/docs/guides/dataset/advanced/enable_raptor.md@@ -1,11 +1,13 @@---sidebar_position: 2+title: Enable Raptor+sidebar_label: Enable Raptorslug: /enable_raptorsidebar_custom_props: {categoryIcon: LucideNetwork}----# Enable RAPTOR+# Enable RaptorA recursive abstractive method used in long-context knowledge retrieval and summarization, balancing broad semantic understanding with fine details.@@ -21,7 +23,7 @@ Our tests with this new approach demonstrate state-of-the-art (SOTA) results onEnabling RAPTOR requires significant memory, computational resources, and tokens.:::-## Basic principles+## Basic PrinciplesAfter the original documents are divided into chunks, the chunks are clustered by semantic similarity rather than by their original order in the text. Clusters are then summarized into higher-level chunks by your system's default chat model. This process is applied recursively, forming a tree structure with various levels of summarization from the bottom up. As illustrated in the figure below, the initial chunks form the leaf nodes (shown in blue) and are recursively summarized into a root node (shown in orange).@@ -57,7 +59,7 @@ Please summarize the following paragraphs... Paragraphs as following:The above is the content you need to summarize.```-### Max token+### Max TokenThe maximum number of tokens per generated summary chunk. Defaults to 256, with a maximum limit of 2048.@@ -67,11 +69,11 @@ In RAPTOR, chunks are clustered by their semantic similarity. The **Threshold**It defaults to 0.1, with a maximum limit of 1. A higher **Threshold** means fewer chunks in each cluster, while a lower one means more.-### Max cluster+### Max ClusterThe maximum number of clusters to create. Defaults to 64, with a maximum limit of 1024.-### Random seed+### Random SeedA random seed. Click **+** to change the seed value.diff --git a/docs/guides/dataset/advanced/extract_table_of_contents.md b/docs/guides/dataset/advanced/extract_table_of_contents.mdindex 5fe00557f5..dfe48ddfb2 100644--- a/docs/guides/dataset/advanced/extract_table_of_contents.md+++ b/docs/guides/dataset/advanced/extract_table_of_contents.md@@ -1,11 +1,13 @@---sidebar_position: 3+title: Extract Table of Contents+sidebar_label: Extract Table of Contentsslug: /enable_table_of_contentssidebar_custom_props: {categoryIcon: LucideTableOfContents}----# Extract table of contents+# Extract Table of ContentsExtract PageIndex, namely table of contents, from documents to provide long context RAG and improve retrieval.@@ -34,8 +36,8 @@ The system's default chat model is used to summarize clustered content. Before p- In the **Chat setting** panel of your chat app, switch on the **PageIndex** toggle.- If you are using an Agent, click the **Retrieval** agent component to specify the dataset(s) and switch on the **PageIndex** toggle.-## Frequently asked questions+## Frequently Asked Questions-### Will previously parsed files be searched using the directory enhancement feature once I enable `PageIndex`?+### Will Previously Parsed Files Be Searched Using the Directory Enhancement Feature Once I Enable `PageIndex`?No. Only files parsed after you enable **PageIndex** will be searched using the directory enhancement feature. To apply this feature to files parsed before enabling **PageIndex**, you must reparse them.diff --git a/docs/guides/dataset/best_practices/_category_.json b/docs/guides/dataset/best_practices/_category_.jsonindex f1fe9fa410..055a9c49e5 100644--- a/docs/guides/dataset/best_practices/_category_.json+++ b/docs/guides/dataset/best_practices/_category_.json@@ -1,5 +1,5 @@{- "label": "Best practices",+ "label": "Best Practices","position": 19,"link": {"type": "generated-index",diff --git a/docs/guides/dataset/best_practices/accelerate_doc_indexing.mdx b/docs/guides/dataset/best_practices/accelerate_doc_indexing.mdxindex 857026532f..9b48b33b9b 100644--- a/docs/guides/dataset/best_practices/accelerate_doc_indexing.mdx+++ b/docs/guides/dataset/best_practices/accelerate_doc_indexing.mdx@@ -1,9 +1,11 @@---sidebar_position: 1+title: Accelerate Indexing+sidebar_label: Accelerate Indexingslug: /accelerate_doc_indexing----# Accelerate indexing+# Accelerate Indexingimport APITable from '@site/src/components/APITable';A checklist to speed up document parsing and indexing.diff --git a/docs/guides/dataset/configure_child_chunking_strategy.md b/docs/guides/dataset/configure_child_chunking_strategy.mdindex 983cb4c11f..12d0902437 100644--- a/docs/guides/dataset/configure_child_chunking_strategy.md+++ b/docs/guides/dataset/configure_child_chunking_strategy.md@@ -1,11 +1,13 @@---sidebar_position: -4+title: Configure Child Chunking Strategy+sidebar_label: Configure Child Chunking Strategyslug: /configure_child_chunking_strategysidebar_custom_props: {categoryIcon: LucideGroup}----# Configure child chunking strategy+# Configure Child Chunking StrategySet parent-child chunking strategy to improve retrieval.@@ -26,7 +28,7 @@ Through this dual-layer structure of "precise localization + contextual suppleme1. On your dataset's **Configuration** page, find the **Child chunk are used for retrieval** toggle:-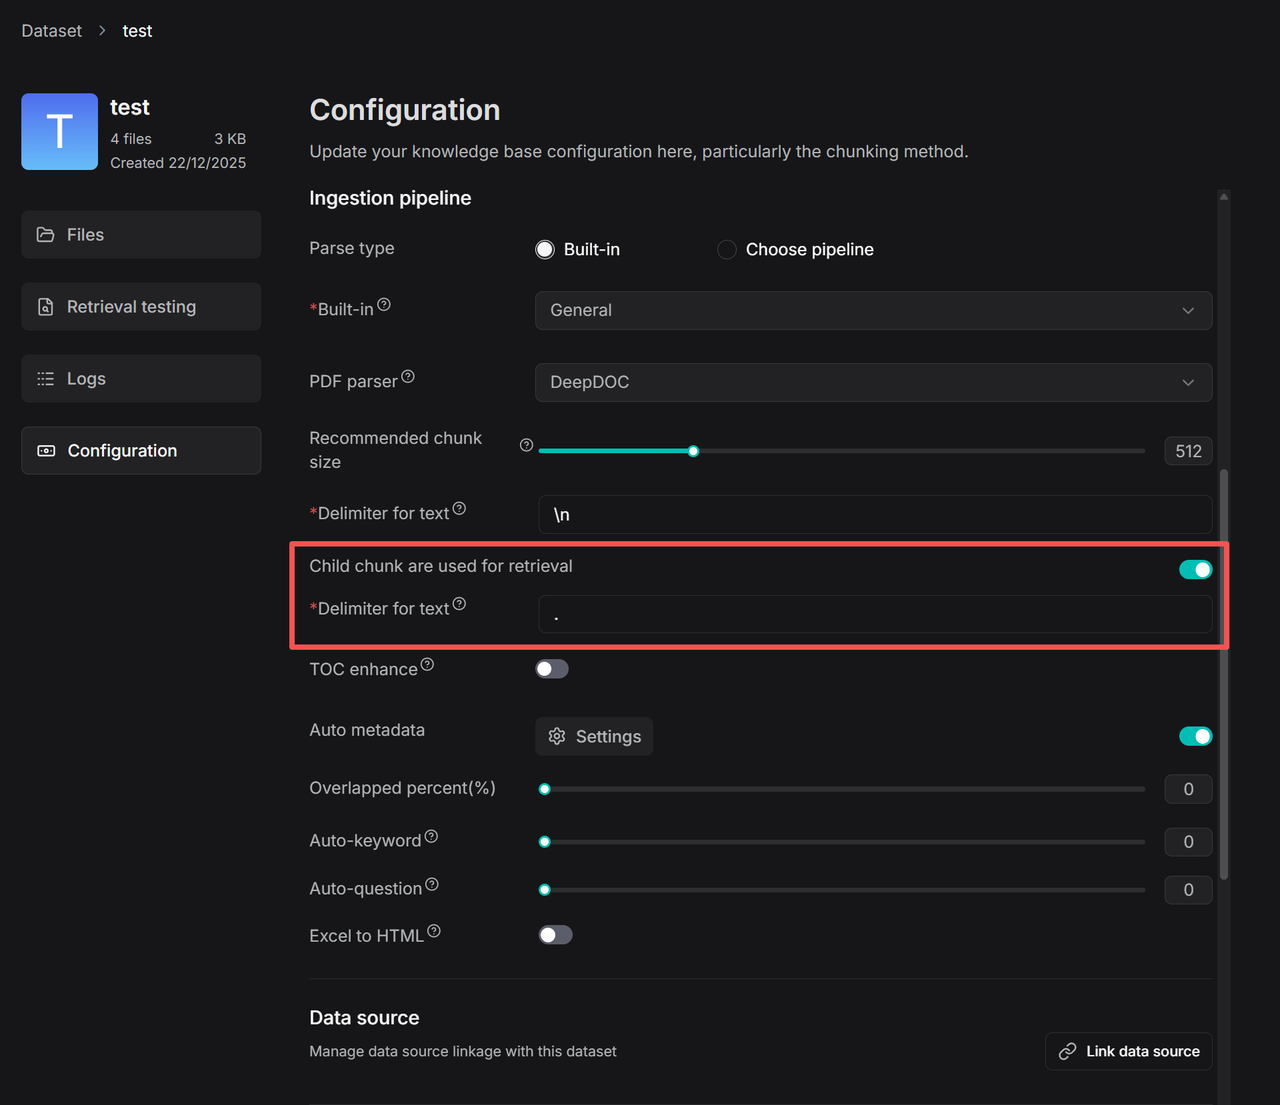+2. Set the delimiter for child chunks.@@ -34,3 +36,4 @@ Through this dual-layer structure of "precise localization + contextual suppleme3. This configuration applies to the **Chunker** component when it comes to ingestion pipeline settings: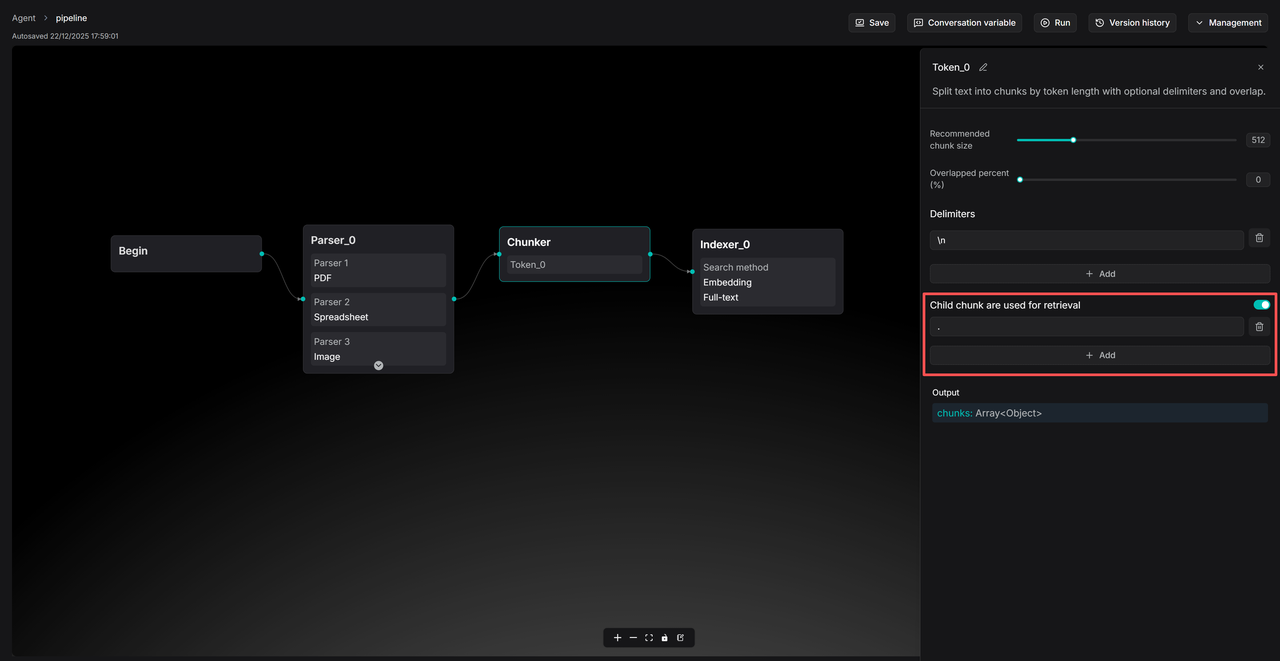+diff --git a/docs/guides/dataset/configure_knowledge_base.md b/docs/guides/dataset/configure_knowledge_base.mdindex c0909f1d23..ddd84ba418 100644--- a/docs/guides/dataset/configure_knowledge_base.md+++ b/docs/guides/dataset/configure_knowledge_base.md@@ -1,11 +1,13 @@---sidebar_position: -10+title: Configure Dataset+sidebar_label: Configure Datasetslug: /configure_knowledge_basesidebar_custom_props: {categoryIcon: LucideCog}----# Configure dataset+# Configure DatasetMost of RAGFlow's chat assistants and Agents are based on datasets. Each of RAGFlow's datasets serves as a knowledge source, *parsing* files uploaded from your local machine and file references generated in RAGFlow's File system into the real 'knowledge' for future AI chats. This guide demonstrates some basic usages of the dataset feature, covering the following topics:@@ -14,7 +16,7 @@ Most of RAGFlow's chat assistants and Agents are based on datasets. Each of RAGF- Search for a dataset- Delete a dataset-## Create dataset+## Create DatasetWith multiple datasets, you can build more flexible, diversified question answering. To create your first dataset:@@ -22,7 +24,7 @@ With multiple datasets, you can build more flexible, diversified question answer_Each time a dataset is created and a file is uploaded to it, a folder with the same name is generated in the **root/.knowledgebase** directory._-## Configure dataset+## Configure DatasetThe following screenshot shows the configuration page of a dataset. A proper configuration of your dataset is crucial for future AI chats. For example, choosing the wrong embedding model or chunking method would cause unexpected semantic loss or mismatched answers in chats.@@ -37,7 +39,7 @@ This section covers the following topics:- Intervene with file parsing results- Run retrieval testing-### Select chunking method+### Select Chunking MethodRAGFlow offers multiple built-in chunking template to facilitate chunking files of different layouts and ensure semantic integrity. From the **Built-in** chunking method dropdown under **Parse type**, you can choose the default template that suits the layouts and formats of your files. The following table shows the descriptions and the compatible file formats of each supported chunk template:@@ -74,7 +76,7 @@ You can also change a file's chunking method on the **Files** page.</details>-### Select embedding model+### Select Embedding ModelAn embedding model converts chunks into embeddings. It cannot be changed once the dataset has chunks. To switch to a different embedding model, you must delete all existing chunks in the dataset. The obvious reason is that we *must* ensure that files in a specific dataset are converted to embeddings using the *same* embedding model (ensure that they are compared in the same embedding space).@@ -82,14 +84,14 @@ An embedding model converts chunks into embeddings. It cannot be changed once thSome embedding models are optimized for specific languages, so performance may be compromised if you use them to embed documents in other languages.:::-### Upload file+### Upload File- RAGFlow's File system allows you to link a file to multiple datasets, in which case each target dataset holds a reference to the file.- In **Knowledge Base**, you are also given the option of uploading a single file or a folder of files (bulk upload) from your local machine to a dataset, in which case the dataset holds file copies.While uploading files directly to a dataset seems more convenient, we *highly* recommend uploading files to RAGFlow's File system and then linking them to the target datasets. This way, you can avoid permanently deleting files uploaded to the dataset.-### Parse file+### Parse FileFile parsing is a crucial topic in dataset configuration. The meaning of file parsing in RAGFlow is twofold: chunking files based on file layout and building embedding and full-text (keyword) indexes on these chunks. After having selected the chunking method and embedding model, you can start parsing a file:@@ -98,7 +100,7 @@ File parsing is a crucial topic in dataset configuration. The meaning of file pa- As shown above, RAGFlow allows you to use a different chunking method for a particular file, offering flexibility beyond the default method.- As shown above, RAGFlow allows you to enable or disable individual files, offering finer control over dataset-based AI chats.-### Intervene with file parsing results+### Intervene with File Parsing ResultsRAGFlow features visibility and explainability, allowing you to view the chunking results and intervene where necessary. To do so:@@ -124,7 +126,7 @@ You can add keywords to a file chunk to increase its ranking for queries contain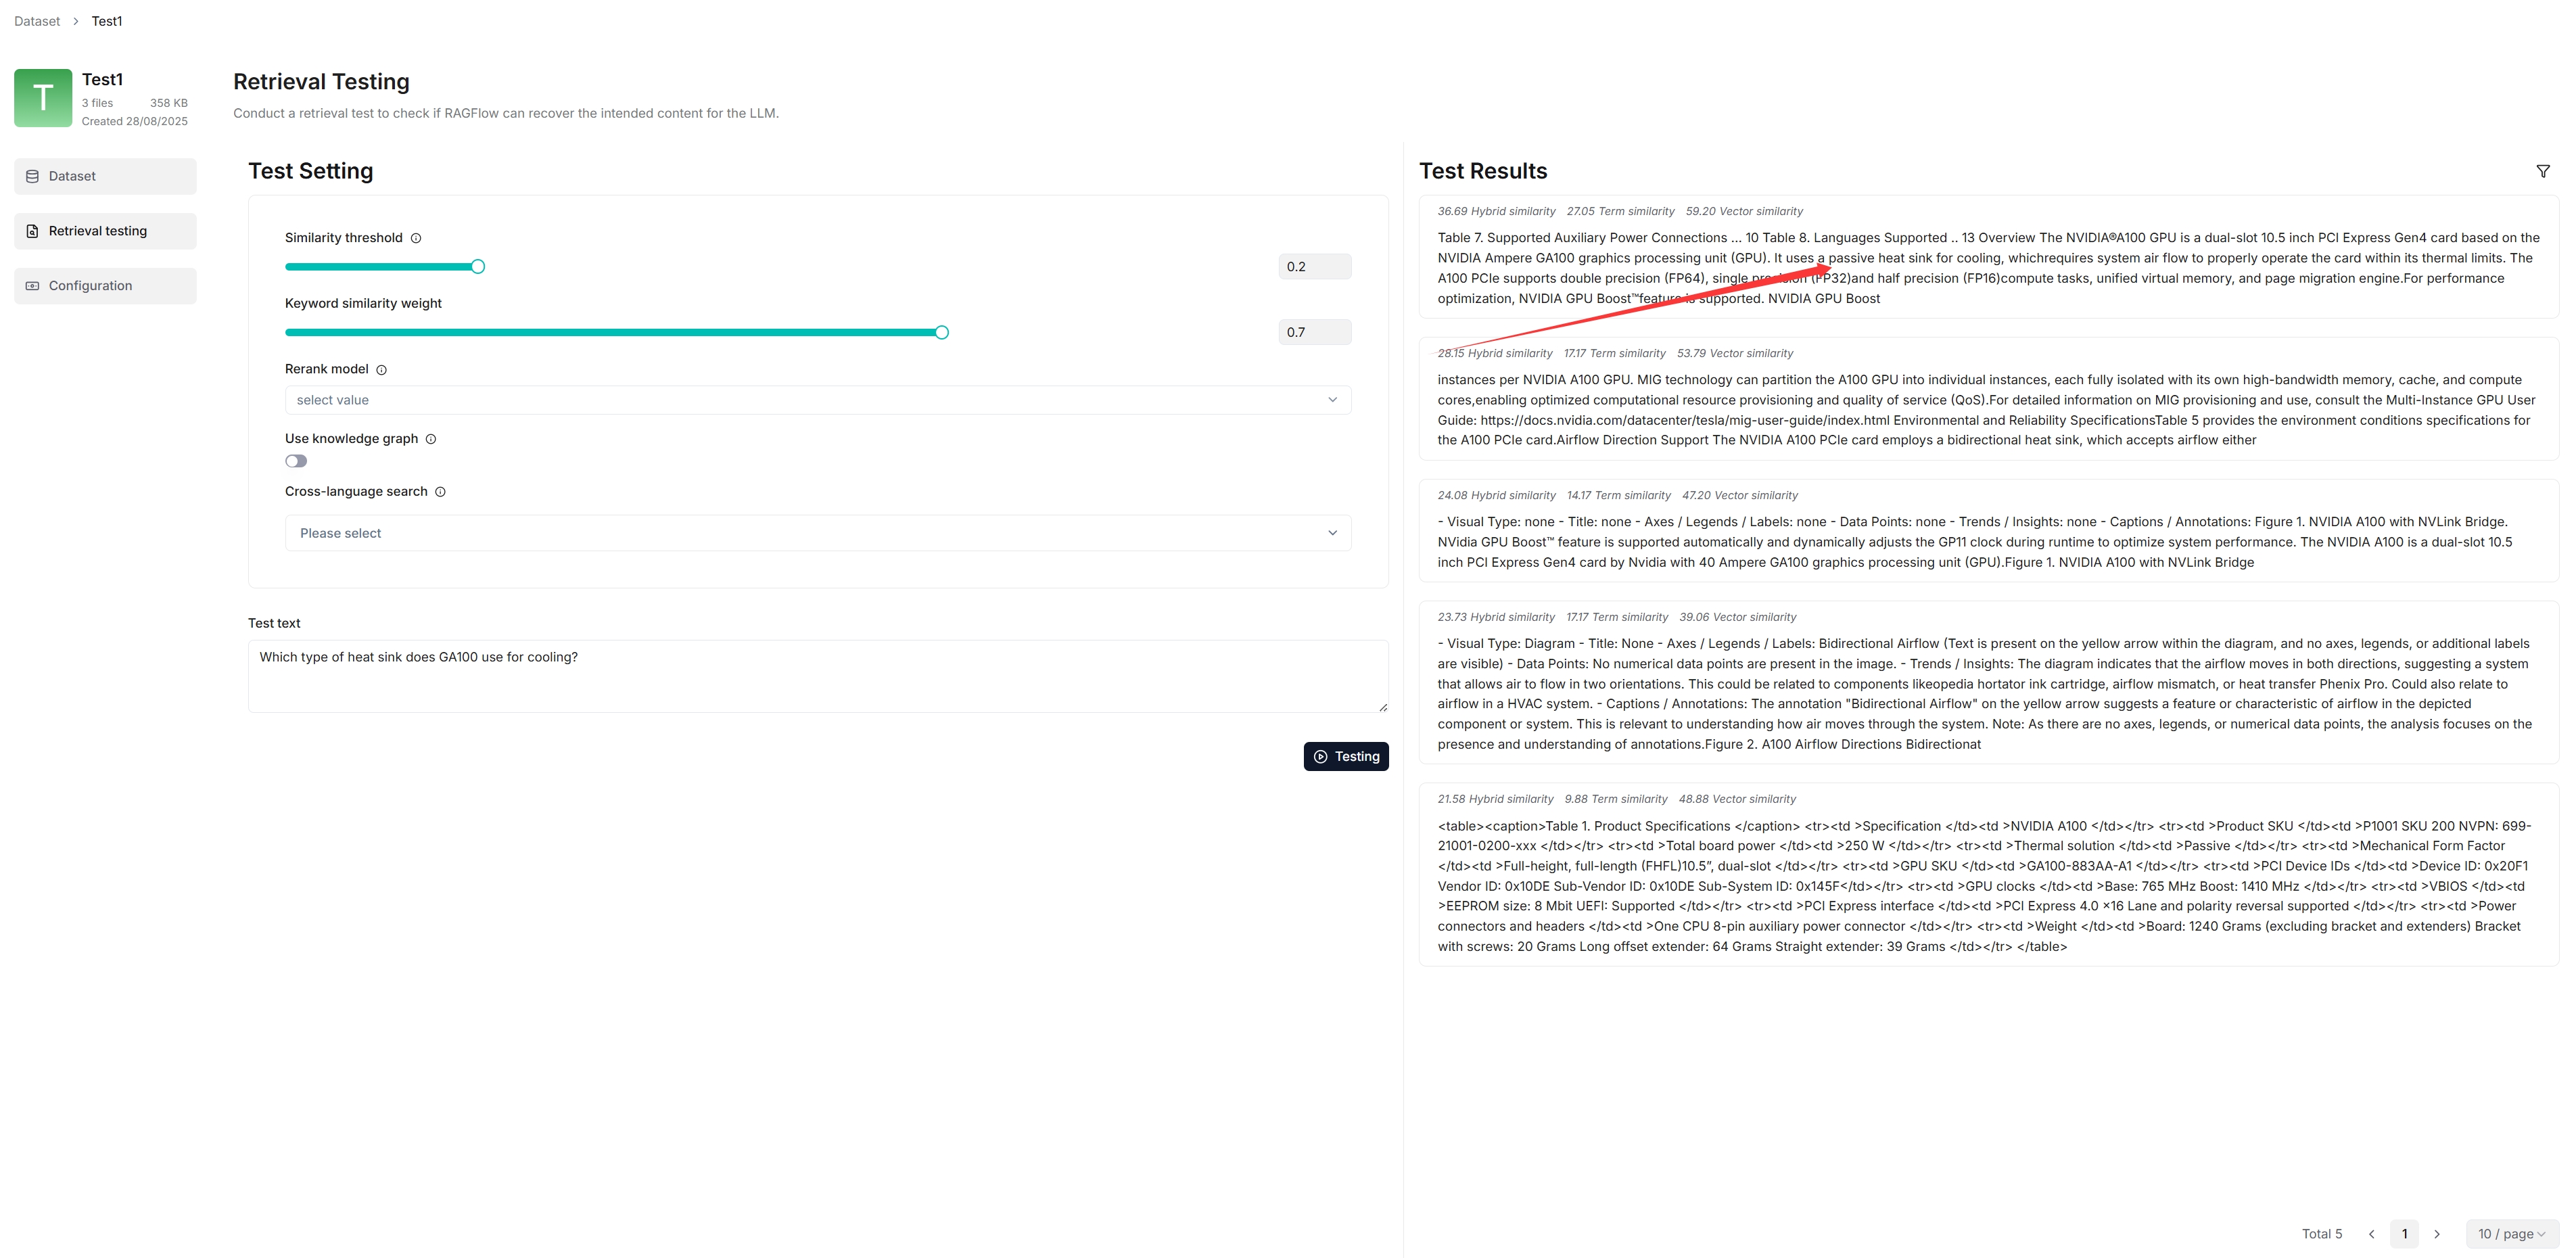-### Run retrieval testing+### Run Retrieval TestingRAGFlow uses multiple recall of both full-text search and vector search in its chats. Prior to setting up an AI chat, consider adjusting the following parameters to ensure that the intended information always turns up in answers:@@ -133,13 +135,13 @@ RAGFlow uses multiple recall of both full-text search and vector search in its cSee [Run retrieval test](./run_retrieval_test.md) for details.-## Search for dataset+## Search for DatasetAs of RAGFlow v0.26.4, the search feature is still in a rudimentary form, supporting only dataset search by name.-## Delete dataset+## Delete DatasetYou are allowed to delete a dataset. Hover your mouse over the three dot of the intended dataset card and the **Delete** option appears. Once you delete a dataset, the associated folder under **root/.knowledge** directory is AUTOMATICALLY REMOVED. The consequence is:diff --git a/docs/guides/dataset/enable_excel2html.md b/docs/guides/dataset/enable_excel2html.mdindex 9f4f20bec0..ac60f1c635 100644--- a/docs/guides/dataset/enable_excel2html.md+++ b/docs/guides/dataset/enable_excel2html.md@@ -1,5 +1,7 @@---sidebar_position: 4+title: Enable Excel2HTML+sidebar_label: Enable Excel2HTMLslug: /enable_excel2htmlsidebar_custom_props: {categoryIcon: LucideToggleRight@@ -37,8 +39,8 @@ Works with complex tables that cannot be represented as key-value pairs. Example3. Leave **Excel to HTML** disabled if your dataset has no spreadsheet tables or if its spreadsheet tables can be represented as key-value pairs.4. If question-answering regarding complex tables is unsatisfactory, check if **Excel to HTML** is enabled.-## Frequently asked questions+## Frequently Asked Questions-### Should I enable this feature for PDFs with complex tables?+### Should I Enable This Feature for PDFs with Complex Tables?Nope. This feature applies to spreadsheet files only. Enabling **Excel to HTML** does not affect your PDFs.\ No newline at end of filediff --git a/docs/guides/dataset/manage_metadata.md b/docs/guides/dataset/manage_metadata.mdindex 79b42a4762..3242782573 100644--- a/docs/guides/dataset/manage_metadata.md+++ b/docs/guides/dataset/manage_metadata.md@@ -1,11 +1,13 @@---sidebar_position: -5+title: Manage Metadata+sidebar_label: Manage Metadataslug: /manage_metadatasidebar_custom_props: {categoryIcon: LucideCode}----# Manage metadata+# Manage MetadataManage metadata for your dataset and for your individual documents.@@ -18,7 +20,7 @@ From v0.23.0 onwards, RAGFlow allows you to manage metadata both at the dataset1. Click on **Metadata** within your dataset to access the **Manage Metadata** page.-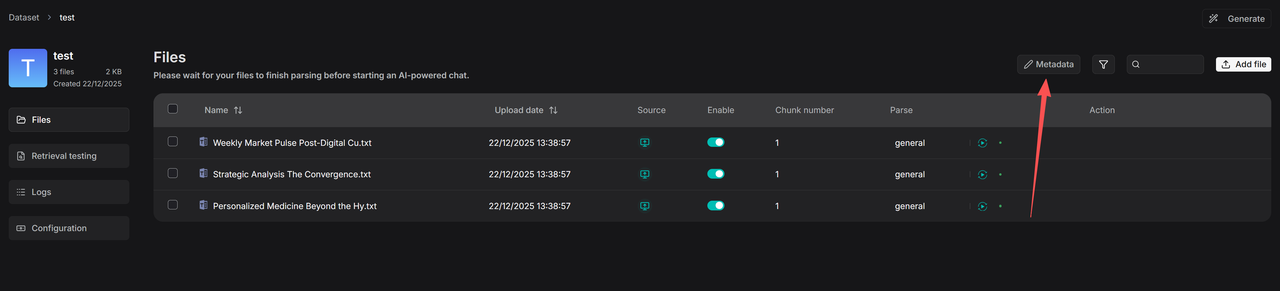+2. On the **Manage Metadata** page, you can do either of the following:@@ -27,20 +29,20 @@ From v0.23.0 onwards, RAGFlow allows you to manage metadata both at the dataset_The configuration page for rules on automatically generating metadata appears._-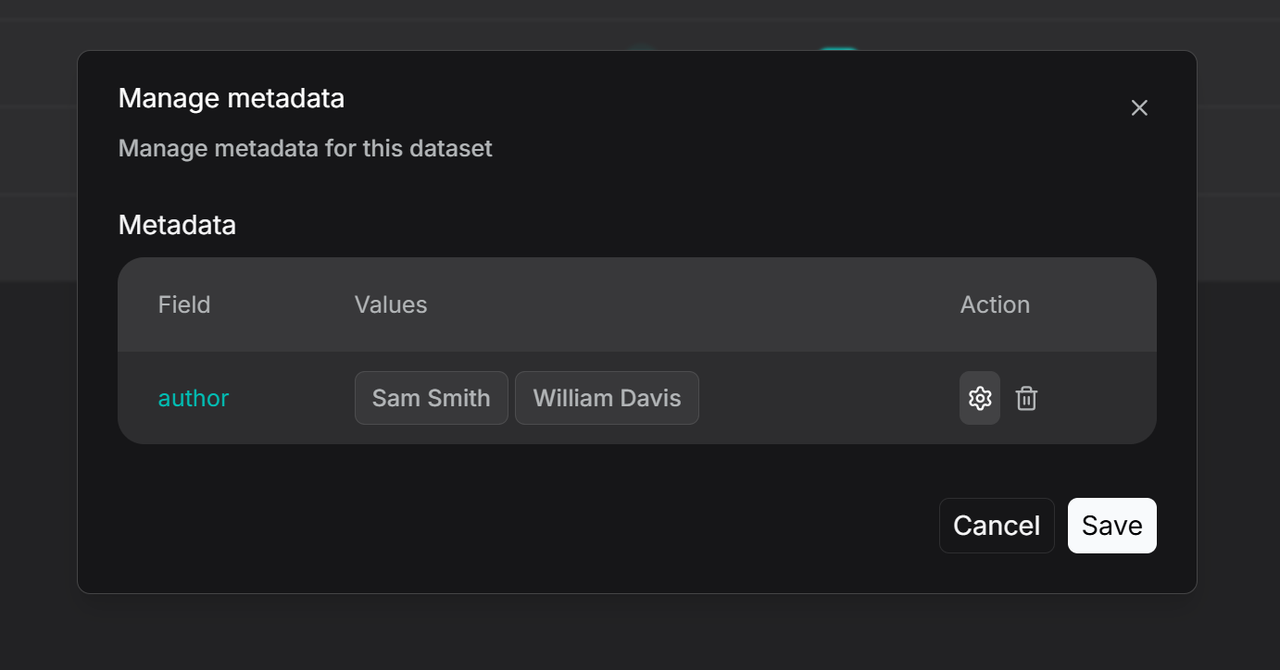+3. To manage metadata for a single file, navigate to the file's details page as shown below. Click on the parsing method (e.g., **General**), then select **Set Metadata** to view or edit the file's metadata. Here, you can add, delete, or modify metadata fields for this specific file. Any edits made here will be reflected in the global statistics on the main Metadata management page for the knowledge base.-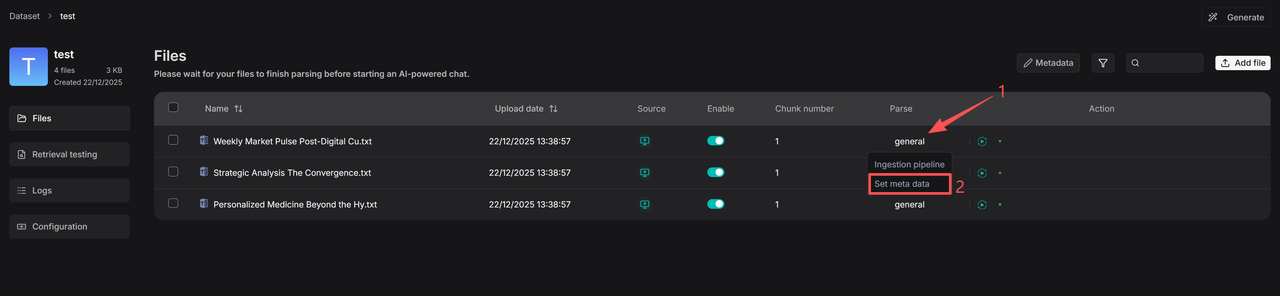-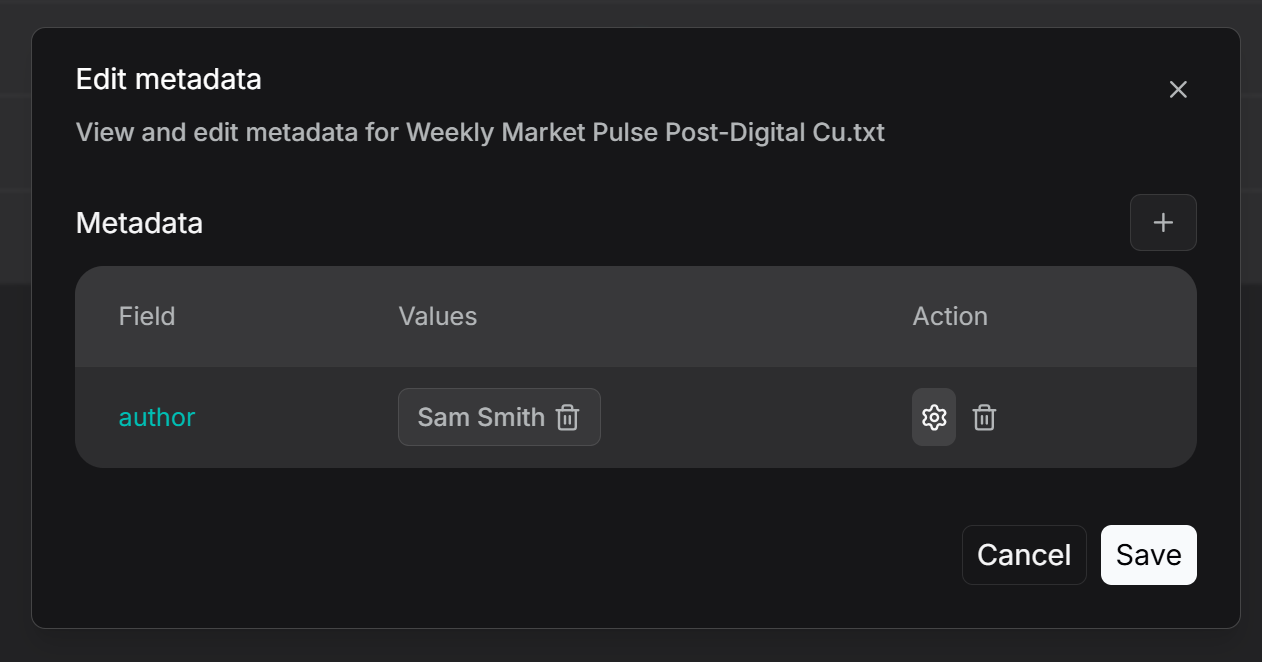++4. The filtering function operates at two levels: knowledge base management and retrieval. Within the dataset, click the Filter button to view the number of files associated with each value under existing metadata fields. By selecting specific values, you can display all linked files.-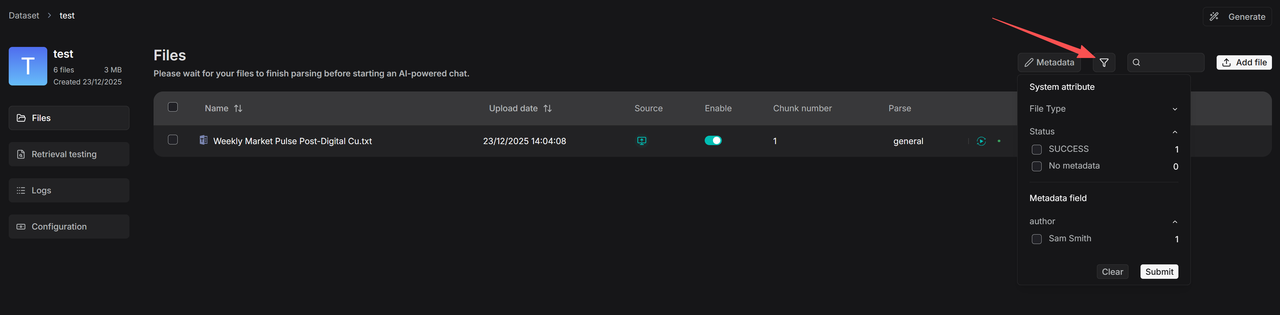+5. Metadata filtering is also supported during the retrieval stage. In Chat, for example, you can set metadata filtering rules after configuring a knowledge base:-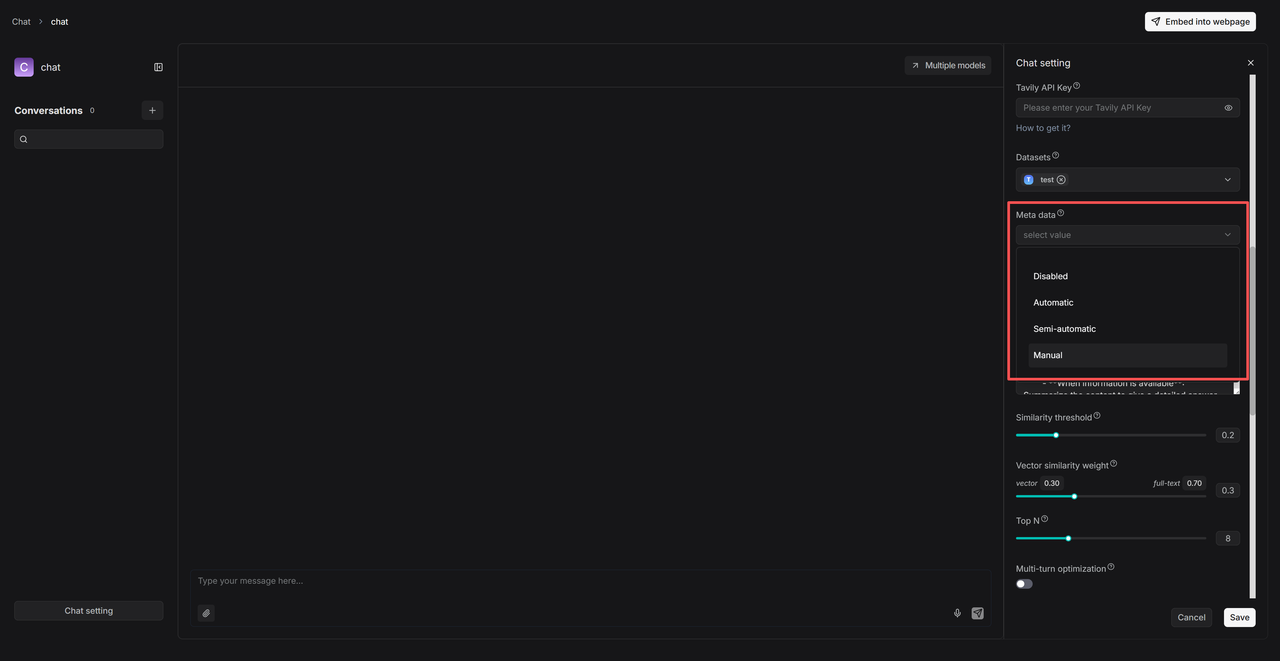+- **Automatic** Mode: The system automatically filters documents based on the user's query and the existing metadata in the knowledge base.- **Semi-automatic** Mode: Users first define the filtering scope at the field level (e.g., for **Author**), and then the system automatically filters within that preset range.diff --git a/docs/guides/dataset/run_retrieval_test.md b/docs/guides/dataset/run_retrieval_test.mdindex 807d68278f..6c83e2a435 100644--- a/docs/guides/dataset/run_retrieval_test.md+++ b/docs/guides/dataset/run_retrieval_test.md@@ -1,11 +1,13 @@---sidebar_position: 10+title: Run Retrieval Test+sidebar_label: Run Retrieval Testslug: /run_retrieval_testsidebar_custom_props: {categoryIcon: LucideTextSearch}----# Run retrieval test+# Run Retrieval TestConduct a retrieval test on your dataset to check whether the intended chunks can be retrieved.@@ -27,15 +29,15 @@ In contrast, chunks created from [knowledge graph construction](./advanced/const## Configurations-### Similarity threshold+### Similarity ThresholdThis sets the bar for retrieving chunks: chunks with similarities below the threshold will be filtered out. By default, the threshold is set to 0.2. This means that only chunks with hybrid similarity score of 20 or higher will be retrieved.-### Vector similarity weight+### Vector Similarity WeightThis sets the weight of vector similarity in the composite similarity score, whether used with vector cosine similarity or a reranking score. By default, it is set to 0.3, making the weight of the other component 0.7 (1 - 0.3).-### Rerank model+### Rerank Model- If left empty, RAGFlow will use a combination of weighted keyword similarity and weighted vector cosine similarity.- If a rerank model is selected, weighted keyword similarity will be combined with weighted vector reranking score.@@ -44,7 +46,7 @@ This sets the weight of vector similarity in the composite similarity score, wheUsing a rerank model will significantly increase the time to receive a response.:::-### Use knowledge graph+### Use Knowledge GraphIn a knowledge graph, an entity description, a relationship description, or a community report each exists as an independent chunk. This switch indicates whether to add these chunks to the retrieval.@@ -62,7 +64,7 @@ The switch is disabled by default. When enabled, RAGFlow performs the followingUsing a knowledge graph in a retrieval test will significantly increase the time to receive a response.:::-### Cross-language search+### Cross-Language SearchTo perform a [cross-language search](../../references/glossary.mdx#cross-language-search), select one or more target languages from the dropdown menu. The system’s default chat model will then translate your query entered in the Test text field into the selected target language(s). This translation ensures accurate semantic matching across languages, allowing you to retrieve relevant results regardless of language differences.@@ -71,7 +73,7 @@ To perform a [cross-language search](../../references/glossary.mdx#cross-languag- If no target language is selected, the system will search only in the language of your query, which may cause relevant information in other languages to be missed.:::-### Test text+### Test TextThis field is where you put in your testing query.@@ -80,18 +82,16 @@ This field is where you put in your testing query.1. Navigate to the **Retrieval testing** page of your dataset, enter your query in **Test text**, and click **Testing** to run the test.2. If the results are unsatisfactory, tune the options listed in the Configuration section and rerun the test.- *The following is a screenshot of a retrieval test conducted without using knowledge graph. It demonstrates a hybrid search combining weighted keyword similarity and weighted vector cosine similarity. The overall hybrid similarity score is 28.56, calculated as 25.17 (term similarity score) x 0.7 + 36.49 (vector similarity score) x 0.3:*- + A retrieval test without a knowledge graph uses hybrid search, combining weighted keyword similarity and weighted vector cosine similarity.- *The following is a screenshot of a retrieval test conducted using a knowledge graph. It shows that only vector similarity is used for knowledge graph-generated chunks:*- + A retrieval test using a knowledge graph uses vector similarity for knowledge graph-generated chunks.:::caution WARNINGIf you have adjusted the default settings, such as keyword similarity weight or similarity threshold, to achieve the optimal results, be aware that these changes will not be automatically saved. You must apply them to your chat assistant settings or the **Retrieval** agent component settings.:::-## Frequently asked questions+## Frequently Asked Questions-### Is an LLM used when the Use Knowledge Graph switch is enabled?+### Is an LLM Used When the Use Knowledge Graph Switch Is Enabled?Yes, your LLM will be involved to analyze your query and extract the related entities and relationship from the knowledge graph. This also explains why additional tokens and time will be consumed.diff --git a/docs/guides/dataset/select_pdf_parser.md b/docs/guides/dataset/select_pdf_parser.mdindex 4a74d3b5b6..5d6f2b26b1 100644--- a/docs/guides/dataset/select_pdf_parser.md+++ b/docs/guides/dataset/select_pdf_parser.md@@ -1,11 +1,13 @@---sidebar_position: -3+title: Select PDF Parser+sidebar_label: Select PDF Parserslug: /select_pdf_parsersidebar_custom_props: {categoryIcon: LucideFileText}----# Select PDF parser+# Select PDF ParserSelect a visual model for parsing your PDFs.@@ -82,12 +84,12 @@ All MinerU environment variables are optional. When set, these values are used tThird-party visual models are marked **Experimental**, because we have not fully tested these models for the aforementioned data extraction tasks.:::-## Frequently asked questions+## Frequently Asked Questions-### When should I select DeepDoc or a third-party visual model as the PDF parser?+### When Should I Select DeepDoc or a Third-Party Visual Model as the PDF Parser?Use a visual model to extract data if your PDFs contain formatted or image-based text rather than plain text. DeepDoc is the default visual model but can be time-consuming. You can also choose a lightweight or high-performance VLM depending on your needs and hardware capabilities.-### Can I select a visual model to parse my DOCX files?+### Can I Select a Visual Model to Parse My DOCX Files?No, you cannot. This dropdown menu is for PDFs only. To use this feature, convert your DOCX files to PDF first.diff --git a/docs/guides/dataset/set_context_window.md b/docs/guides/dataset/set_context_window.mdindex 20d9cb597e..37f9a2e921 100644--- a/docs/guides/dataset/set_context_window.md+++ b/docs/guides/dataset/set_context_window.md@@ -1,11 +1,13 @@---sidebar_position: -8+title: Set Context Window Size+sidebar_label: Set Context Window Sizeslug: /set_context_windowsidebar_custom_props: {categoryIcon: LucideListChevronsUpDown}----# Set context window size+# Set Context Window SizeSet context window size for images and tables to improve long-context RAG performances.@@ -19,7 +21,7 @@ To address this, RAGFlow 0.23.0 introduces the **Image & table context window**1. On your dataset's **Configuration** page, find the **Image & table context window** slider:-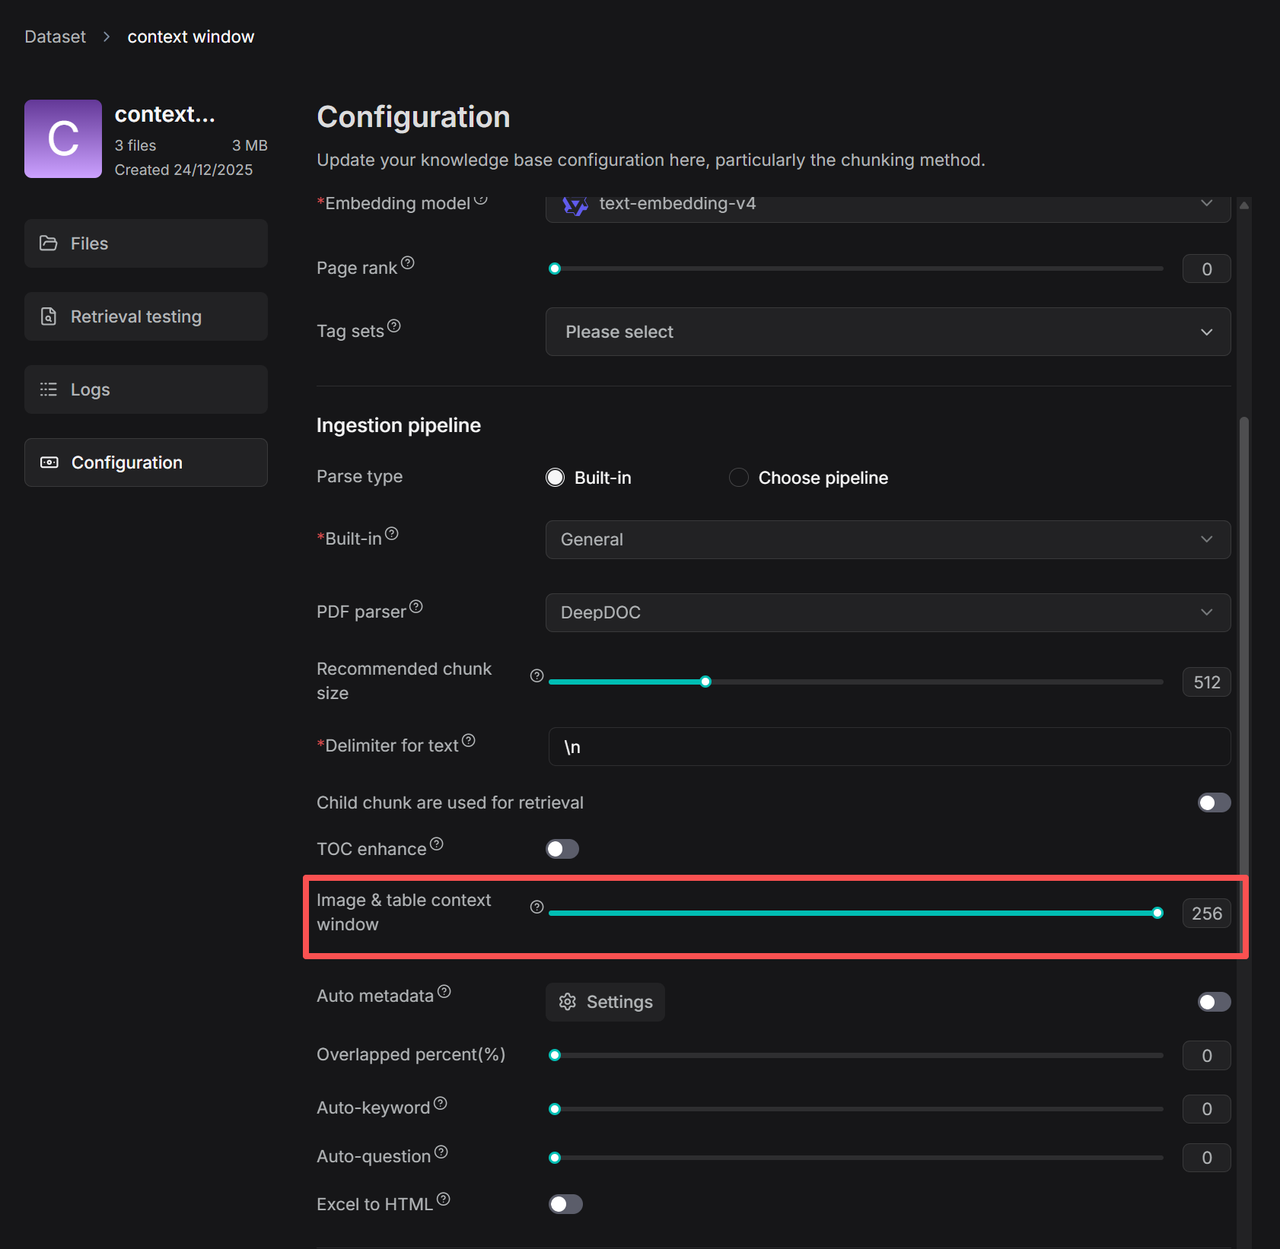+2. Adjust the number of context tokens according to your needs.diff --git a/docs/guides/dataset/set_metadata.md b/docs/guides/dataset/set_metadata.mdindex 6ff853e93a..8a42f4a1fa 100644--- a/docs/guides/dataset/set_metadata.md+++ b/docs/guides/dataset/set_metadata.md@@ -1,11 +1,13 @@---sidebar_position: -7+title: Set Metadata+sidebar_label: Set Metadataslug: /set_metadatasidebar_custom_props: {categoryIcon: LucideCode}----# Set metadata+# Set MetadataManually add metadata to an uploaded file@@ -27,8 +29,8 @@ Ensure that your metadata is in JSON format; otherwise, your updates will not be[Retrieve chunks](../../references/http_api_reference.md#retrieve-chunks)-## Frequently asked questions+## Frequently Asked Questions-### Can I set metadata for multiple documents at once?+### Can I Set Metadata for Multiple Documents at Once?From v0.23.0 onwards, you can set metadata for each document individually or have the LLM auto-generate metadata for multiple files. See [Extract metadata](./advanced/auto_metadata.md) for details.diff --git a/docs/guides/dataset/set_page_rank.md b/docs/guides/dataset/set_page_rank.mdindex de22072ca6..432394d896 100644--- a/docs/guides/dataset/set_page_rank.md+++ b/docs/guides/dataset/set_page_rank.md@@ -1,11 +1,13 @@---sidebar_position: -2+title: Set Page Rank+sidebar_label: Set Page Rankslug: /set_page_ranksidebar_custom_props: {categoryIcon: LucideStickyNote}----# Set page rank+# Set Page RankCreate a step-retrieval strategy using page rank.@@ -34,7 +36,7 @@ The page rank value must be an integer. Range: [0,100]If you set the page rank value to a non-integer, say 1.7, it will be rounded down to the nearest integer, which in this case is 1.:::-## Scoring mechanism+## Scoring MechanismIf you configure a chat assistant's **similarity threshold** to 0.2, only chunks with a hybrid score greater than 0.2 x 100 = 20 will be retrieved and sent to the chat model for content generation. This initial filtering step is crucial for narrowing down relevant information.diff --git a/docs/guides/dataset/use_tag_sets.md b/docs/guides/dataset/use_tag_sets.mdindex af9134b201..d0595ba7dd 100644--- a/docs/guides/dataset/use_tag_sets.md+++ b/docs/guides/dataset/use_tag_sets.md@@ -1,11 +1,13 @@---sidebar_position: 6+title: Use Tag Set+sidebar_label: Use Tag Setslug: /use_tag_setssidebar_custom_props: {categoryIcon: LucideTags}----# Use tag set+# Use Tag SetUse a tag set to auto-tag chunks in your datasets.@@ -19,11 +21,11 @@ To use this feature, ensure you have at least one properly configured tag set, sAuto-tagging applies in situations where chunks are so similar to each other that the intended chunks cannot be distinguished from the rest. For example, when you have a few chunks about iPhone and a majority about iPhone case or iPhone accessaries, it becomes difficult to retrieve those chunks about iPhone without additional information.-## 1. Create tag set+## 1. Create Tag SetYou can consider a tag set as a closed set, and the tags to attach to the chunks in your dataset are *exclusively* from the specified tag set. You use a tag set to "inform" RAGFlow which chunks to tag and which tags to apply.-### Prepare a tag table file+### Prepare a Tag Table FileA tag set can comprise one or multiple table files in XLSX, CSV, or TXT formats. Each table file in the tag set contains two columns, **Description** and **Tag**:@@ -37,7 +39,7 @@ As a rule of thumb, consider including the following entries in your tag table:- User queries that fail to retrieve the correct responses using other methods, ensuring their tags match the intended chunks in your dataset.:::-### Create a tag set+### Create a Tag Set:::danger IMPORTANTA tag set is *not* involved in document indexing or retrieval. Do not specify a tag set when configuring your chat assistant or agent.@@ -46,12 +48,10 @@ A tag set is *not* involved in document indexing or retrieval. Do not specify a1. Click **+ Create dataset** to create a dataset.2. Navigate to the **Configuration** page of the created dataset, select **Built-in** in **Ingestion pipeline**, then choose **Tag** as the default chunking method from the **Built-in** drop-down menu.3. Go back to the **Files** page and upload and parse your table file in XLSX, CSV, or TXT formats.- _A tag cloud appears under the **Tag view** section, indicating the tag set is created:_- -4. Click the **Table** tab to view the tag frequency table:- + A tag cloud appears under the **Tag view** section, indicating the tag set is created.+4. Click the **Table** tab to view the tag frequency table.-## 2. Tag chunks+## 2. Tag ChunksOnce a tag set is created, you can apply it to your dataset:@@ -65,14 +65,14 @@ Once a tag set is created, you can apply it to your dataset:3. Re-parse your documents to start the auto-tagging process._In an AI chat scenario using auto-tagged datasets, each query will be tagged using the corresponding tag set(s) and chunks with these tags will have a higher chance to be retrieved._-## 3. Update tag set+## 3. Update Tag SetCreating a tag set is *not* for once and for all. Oftentimes, you may find it necessary to update or delete existing tags or add new entries.- You can update the existing tag set in the tag frequency table.- To add new entries, you can add and parse new table files in XLSX, CSV, or TXT formats.-### Update tag set in tag frequency table+### Update Tag Set in Tag Frequency Table1. Navigate to the **Configuration** page in your tag set.2. Click the **Table** tab under **Tag view** to view the tag frequency table, where you can update tag names or delete tags.@@ -81,7 +81,7 @@ Creating a tag set is *not* for once and for all. Oftentimes, you may find it neWhen a tag set is updated, you must re-parse the documents in your dataset so that their tags can be updated accordingly.:::-### Add new table files+### Add New Table Files1. Navigate to the **Configuration** page in your tag set.2. Navigate to the **Dataset** page and upload and parse your table file in XLSX, CSV, or TXT formats.@@ -90,16 +90,16 @@ When a tag set is updated, you must re-parse the documents in your dataset so thIf you add new table files to your tag set, it is at your own discretion whether to re-parse your documents in your datasets.:::-## Frequently asked questions+## Frequently Asked Questions-### Can I reference more than one tag set?+### Can I Reference More Than One Tag Set?Yes, you can. Usually one tag set suffices. When using multiple tag sets, ensure they are independent of each other; otherwise, consider merging your tag sets.-### Difference between a tag set and a standard dataset?+### Difference Between a Tag Set and a Standard Dataset?A standard dataset is a dataset. It will be searched by RAGFlow's document engine and the retrieved chunks will be fed to the LLM. In contrast, a tag set is used solely to attach tags to chunks within your dataset. It does not directly participate in the retrieval process, and you should not choose a tag set when selecting datasets for your chat assistant or agent.-### Difference between auto-tag and auto-keyword?+### Difference Between Auto-Tag and Auto-Keyword?Both features enhance retrieval in RAGFlow. The auto-keyword feature relies on the LLM and consumes a significant number of tokens, whereas the auto-tag feature is based on vector similarity and predefined tag set(s). You can view the keywords applied in the auto-keyword feature as an open set, as they are generated by the LLM. In contrast, a tag set can be considered a user-defined close set, requiring upload tag set(s) in specified formats before use.diff --git a/docs/guides/file/batch_move_and_delete.md b/docs/guides/file/batch_move_and_delete.mdindex e822d66fb5..5a7def73ff 100644--- a/docs/guides/file/batch_move_and_delete.md+++ b/docs/guides/file/batch_move_and_delete.md@@ -2,6 +2,7 @@sidebar_position: 4slug: /file_management/batch_move_and_deletesidebar_label: Batch Move and Delete+title: Batch Move and Deletesidebar_custom_props: {categoryIcon: LucideFolderDot}diff --git a/docs/guides/file/file.md b/docs/guides/file/file.mdindex bf2f4d2dfd..58226f29bb 100644--- a/docs/guides/file/file.md+++ b/docs/guides/file/file.md@@ -2,6 +2,7 @@sidebar_position: 1slug: /file_management/files_and_folderssidebar_label: Files and Folders+title: Files and Folderssidebar_custom_props: {categoryIcon: LucideFolderDot}@@ -26,6 +27,8 @@ RAGFlow file management lets you build your own file system through nested foldeAfter clicking **Add File** in the upper-right corner of the page, select **Upload File** to open the upload window. The upload control contains two tabs: **File** and **Folder**. You can select one or more files, or upload an entire folder.+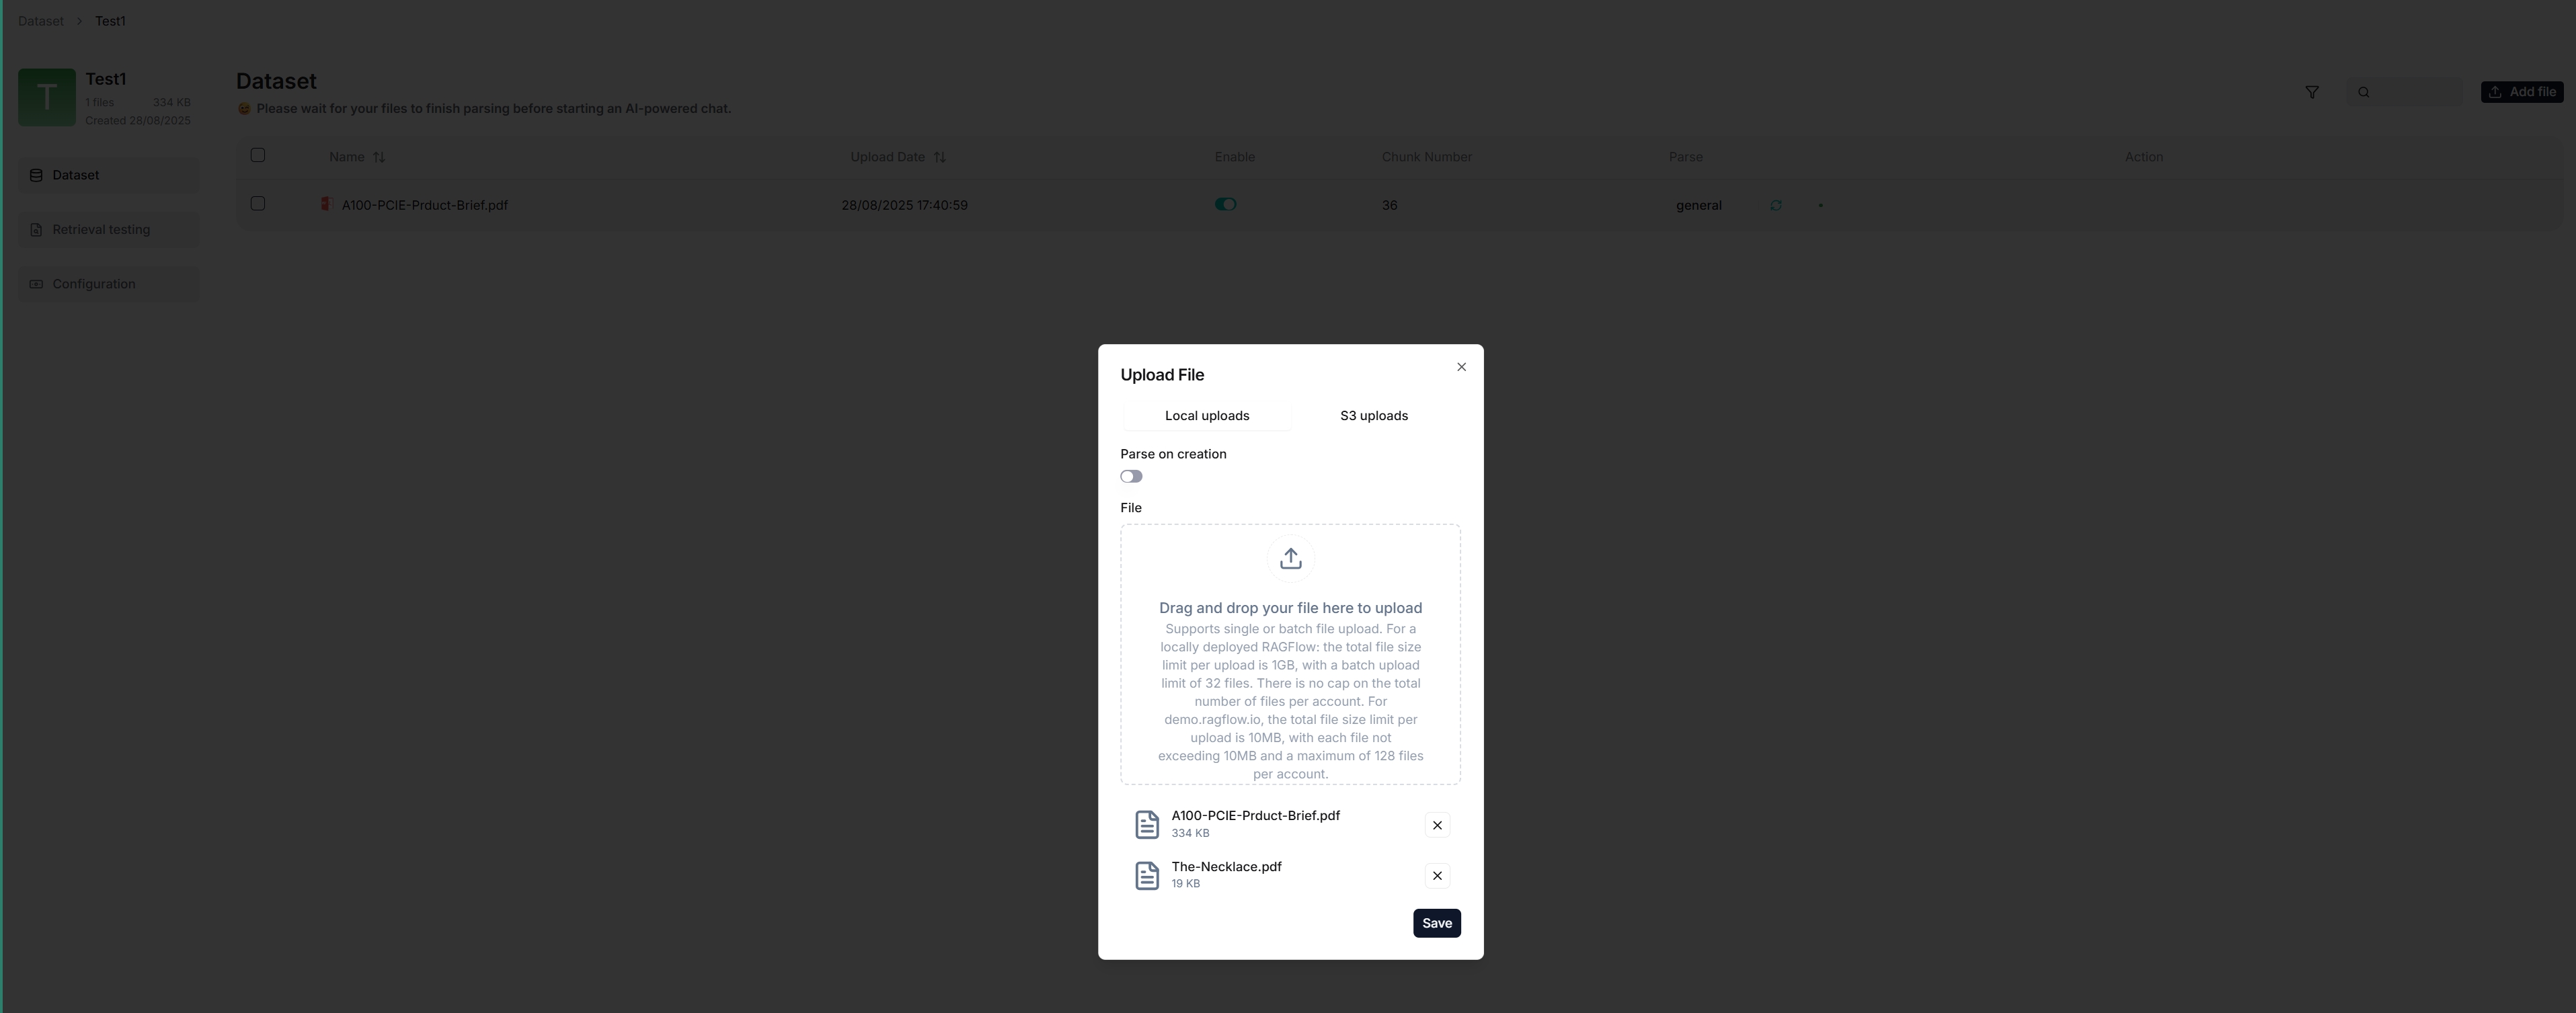+### Upload File1. Go to the **File** page and confirm that the current directory is the target save location.@@ -34,6 +37,8 @@ After clicking **Add File** in the upper-right corner of the page, select **Uplo4. Confirm the list of files to be uploaded. If you selected a file by mistake, click the delete button on the right side of the file row to remove it.5. Click **Confirm** or **Save**, then wait for the upload progress to complete.+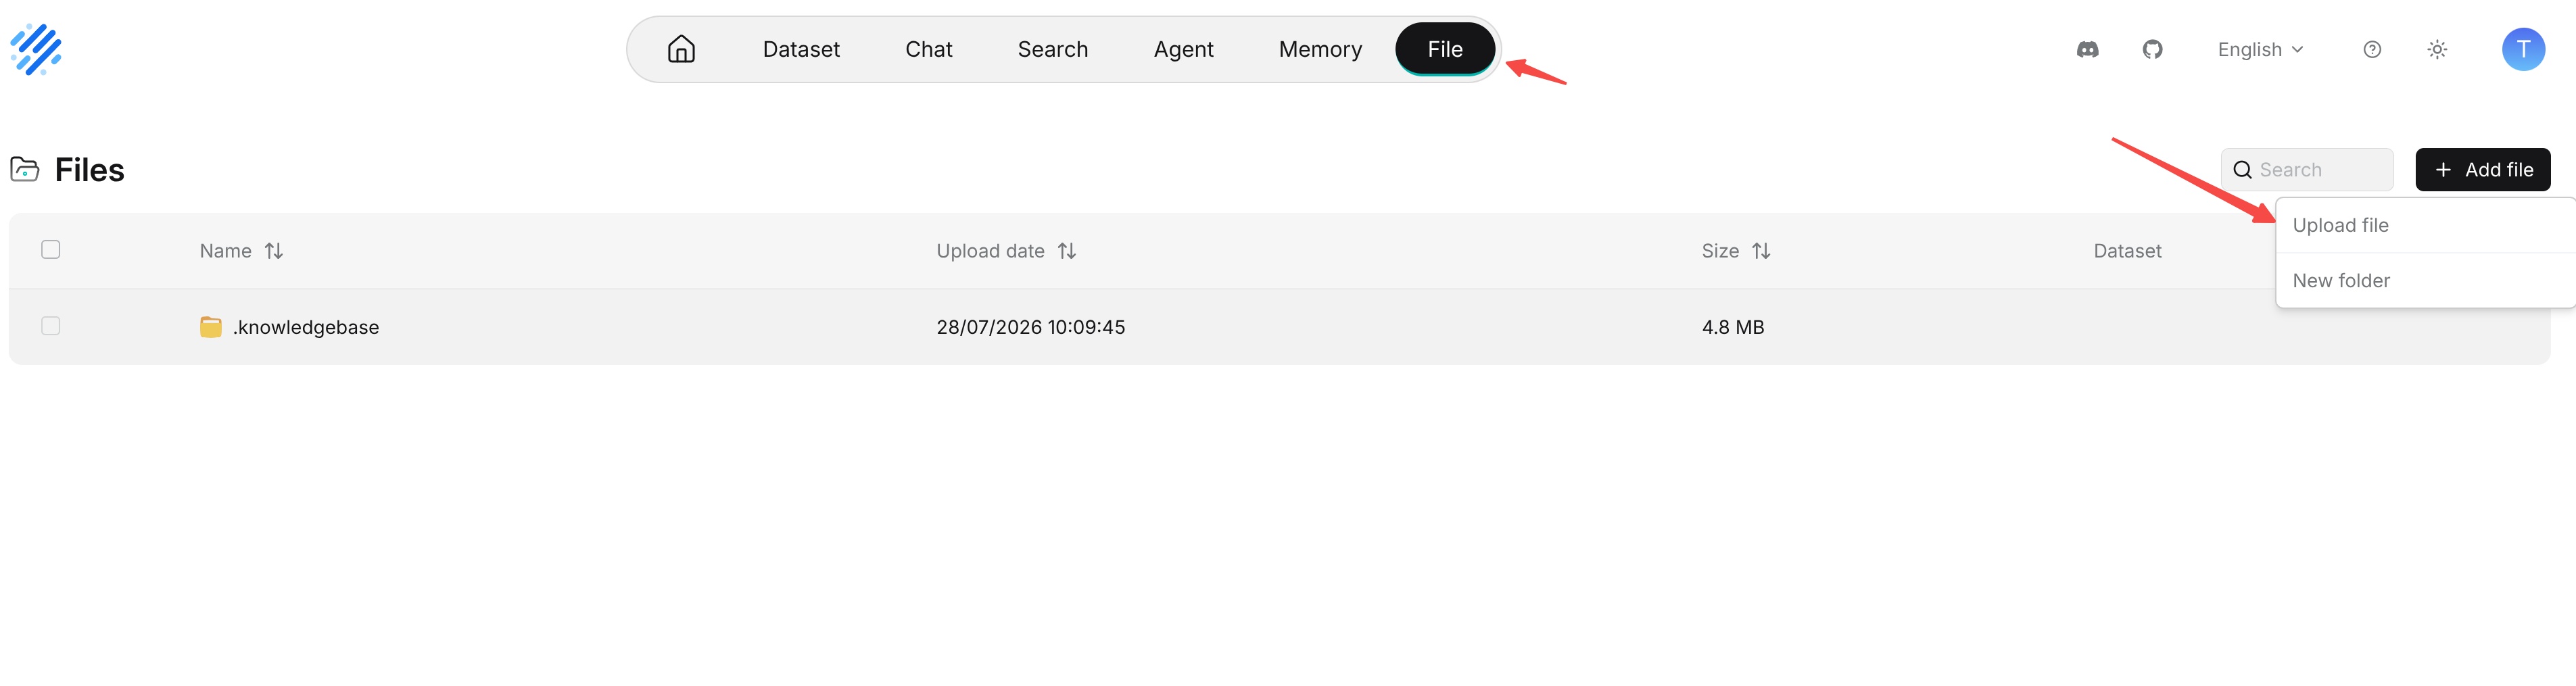+### Upload Folder1. Click **Add File**, then select **Upload File**.@@ -41,5 +46,7 @@ After clicking **Add File** in the upper-right corner of the page, select **Uplo3. Click the **Upload Folder** area and select a local folder. The system will upload the files inside that folder.4. After the upload is complete, check the result in the current directory or the corresponding folder.+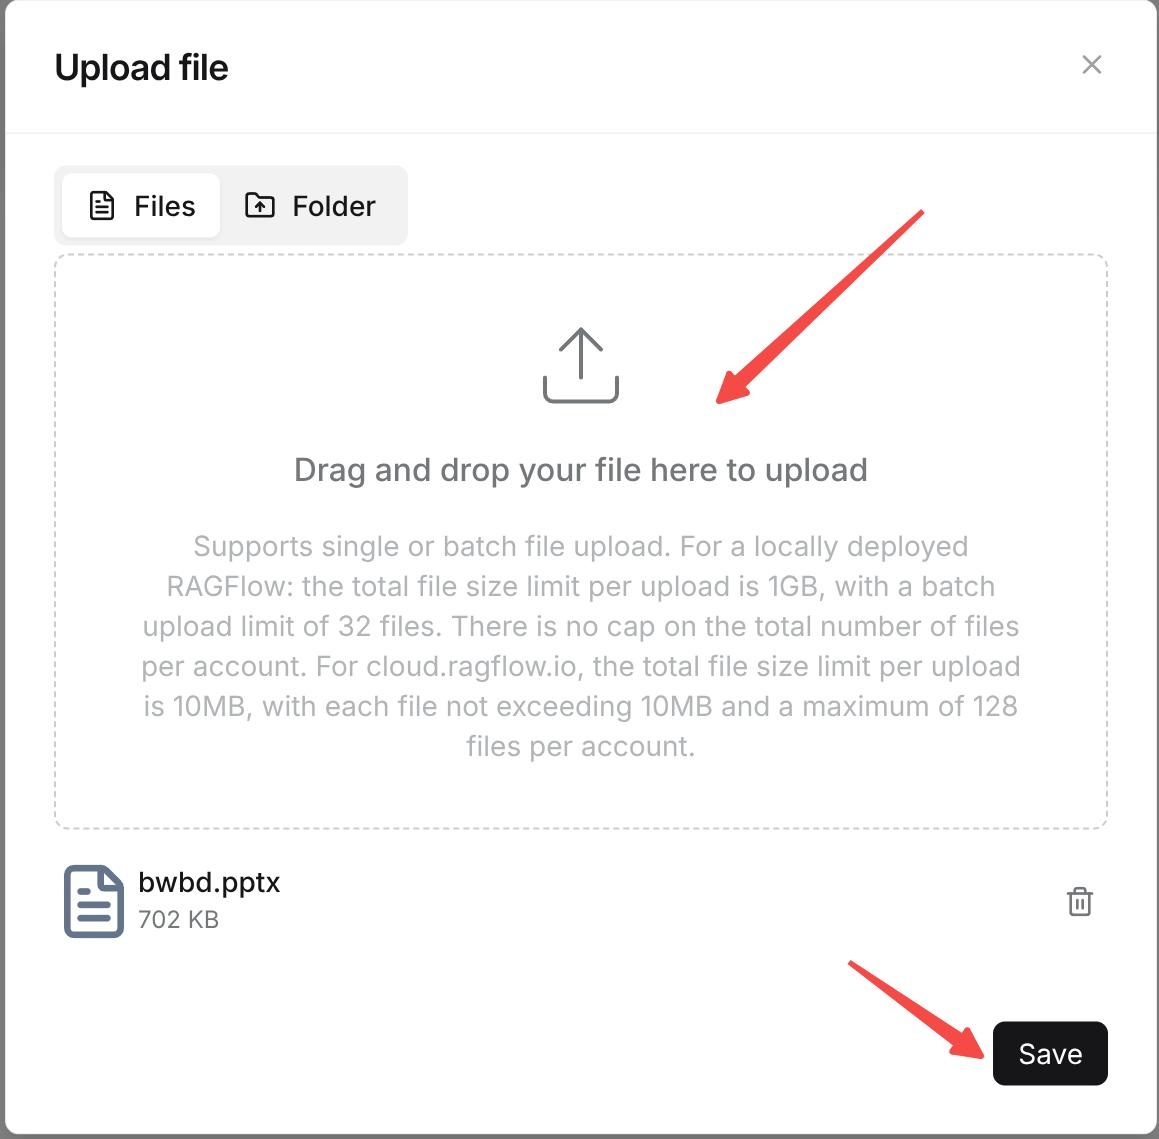+The upload process displays progress. If an upload failure message appears, check the file size, network connection, login status, and whether the file format is allowed by the current deployment.diff --git a/docs/guides/file/file_operations.md b/docs/guides/file/file_operations.mdindex 30a9745295..96a431483b 100644--- a/docs/guides/file/file_operations.md+++ b/docs/guides/file/file_operations.md@@ -2,6 +2,7 @@sidebar_position: 2slug: /file_management/file_operationssidebar_label: File Operations+title: File Operationssidebar_custom_props: {categoryIcon: LucideFolderDot}@@ -11,6 +12,8 @@ sidebar_custom_props: {After you hover over a file row, the **Operations** column displays the available operation buttons. The available operations for folders and regular files are slightly different. For files from external data sources, some operations, such as moving, renaming, or deleting, may be restricted by the data source permissions.+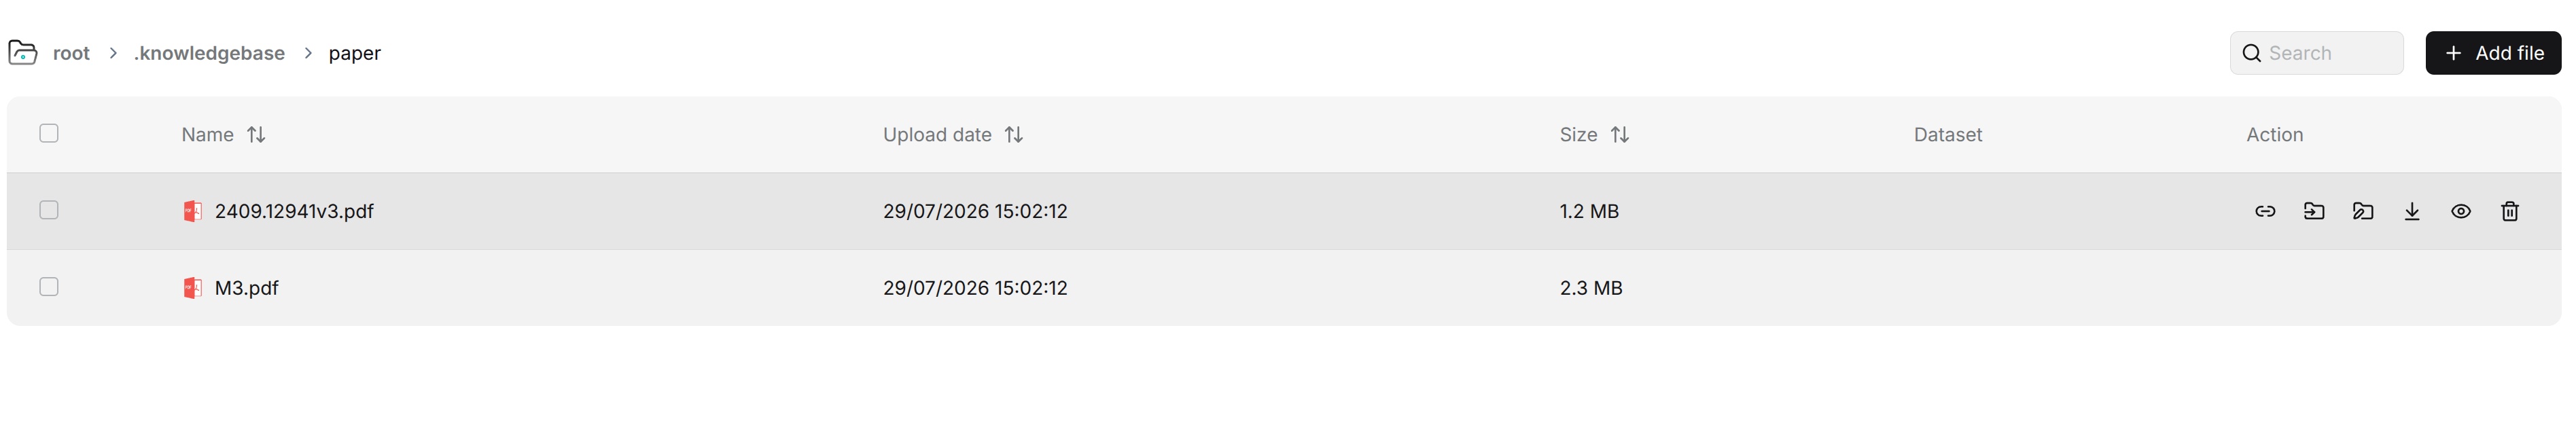+**Add to Knowledge Base**: Applies to files. Associates the file with one or more knowledge bases, allowing the knowledge base to use the file as a data source.**Move**: Applies to files or folders. After selecting a target folder and saving, the system moves the selected item to the target directory.diff --git a/docs/guides/file/link_knowledge_base.md b/docs/guides/file/link_knowledge_base.mdindex 2c7e025dbf..e899b4c721 100644--- a/docs/guides/file/link_knowledge_base.md+++ b/docs/guides/file/link_knowledge_base.md@@ -2,6 +2,7 @@sidebar_position: 3slug: /file_management/link_knowledge_basesidebar_label: Link Knowledge Base+title: Link Knowledge Basesidebar_custom_props: {categoryIcon: LucideFolderDot}@@ -11,6 +12,10 @@ sidebar_custom_props: {The file management page allows you to add files directly to a knowledge base. After the association is created, you can continue operations such as parsing, chunking, and retrieval from the knowledge base side. The specific processing status is subject to the knowledge base document page.+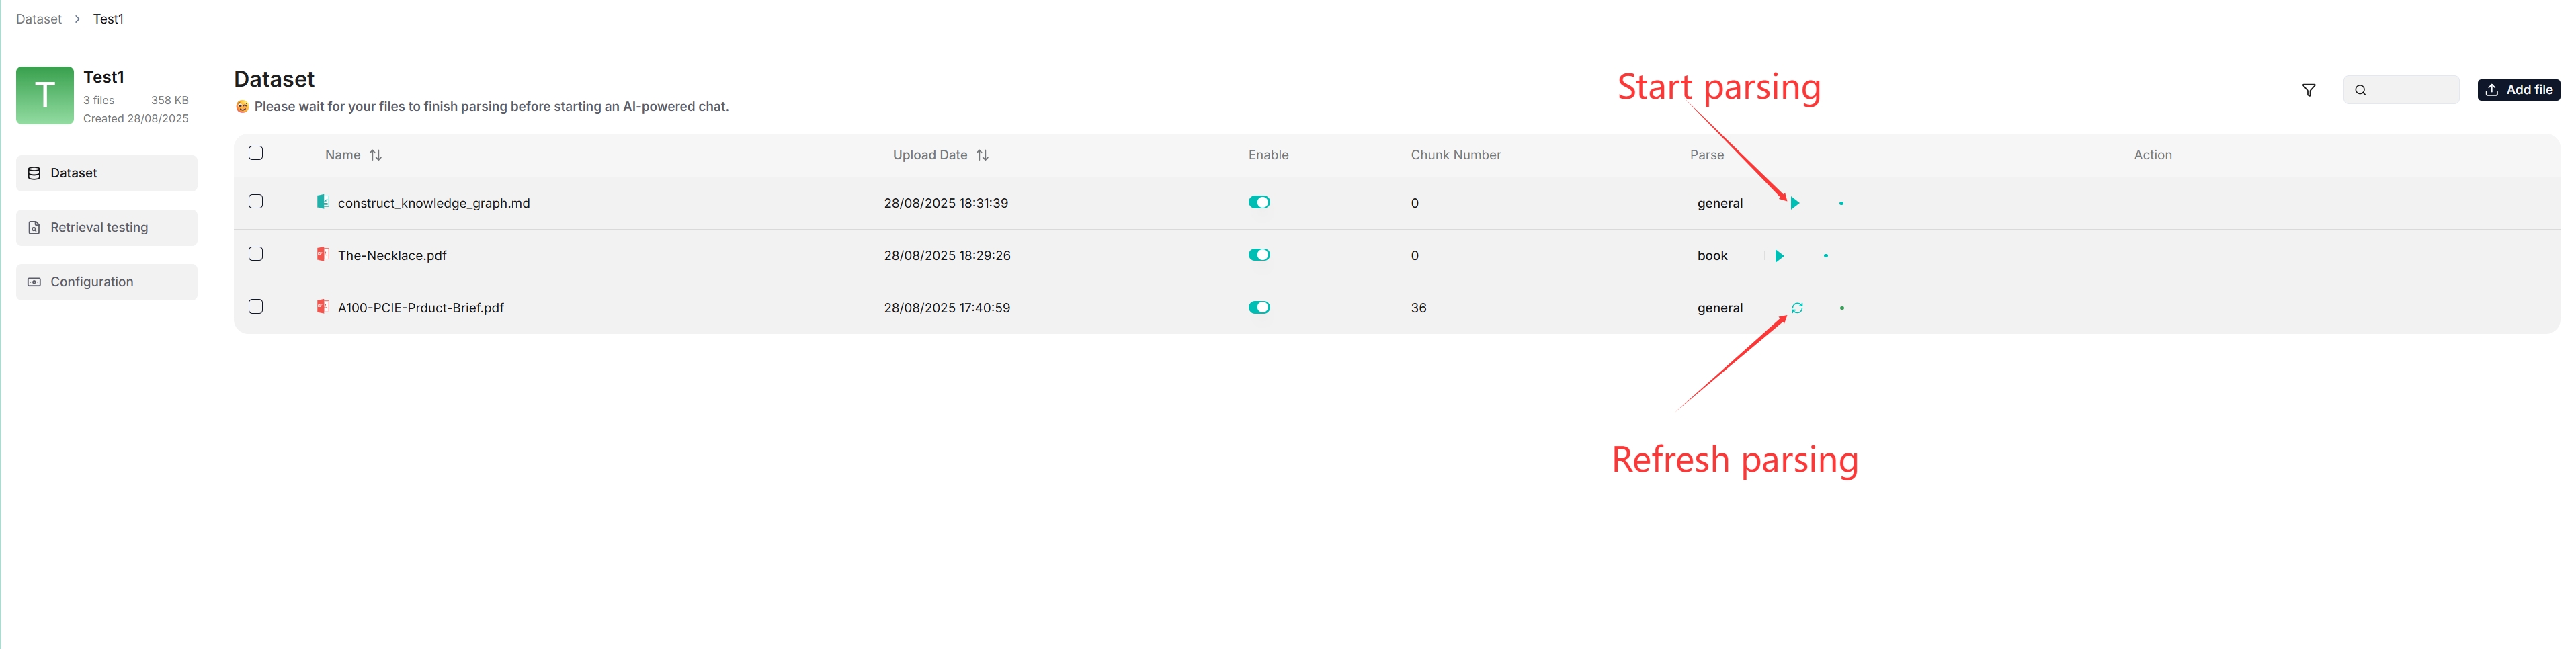++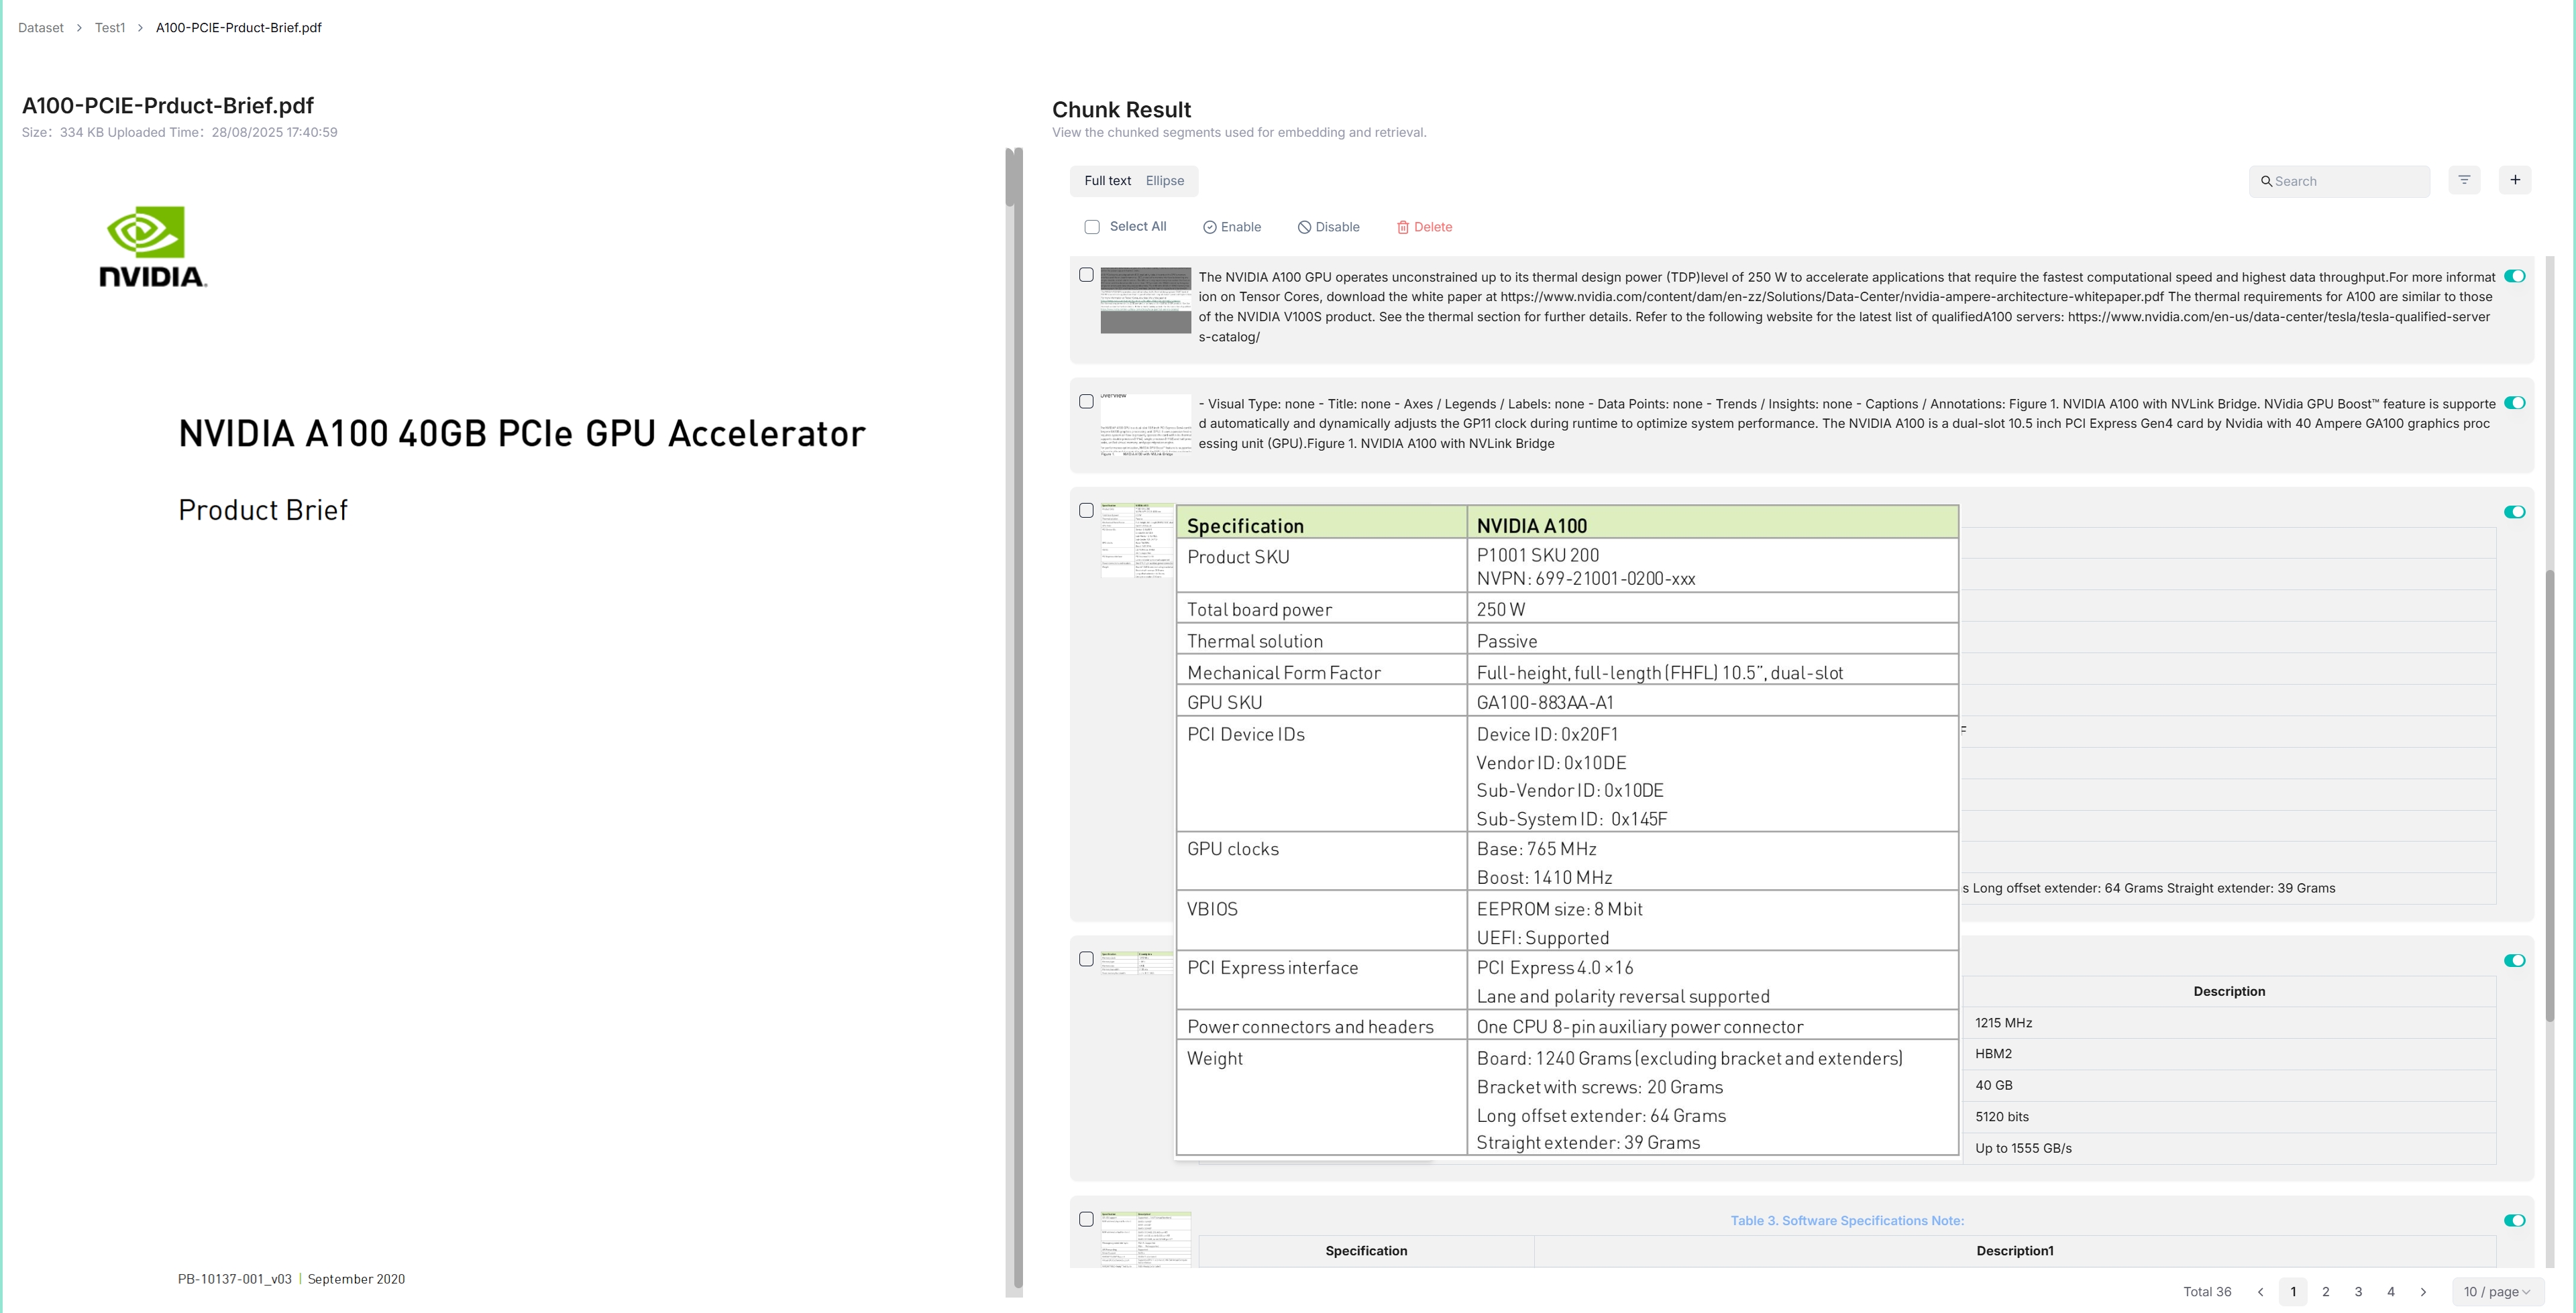+## Link a Single File1. Find the target file in the file list.@@ -18,6 +23,8 @@ The file management page allows you to add files directly to a knowledge base. A3. In the pop-up window, select one or more knowledge bases.4. Click **Save** to save the association.+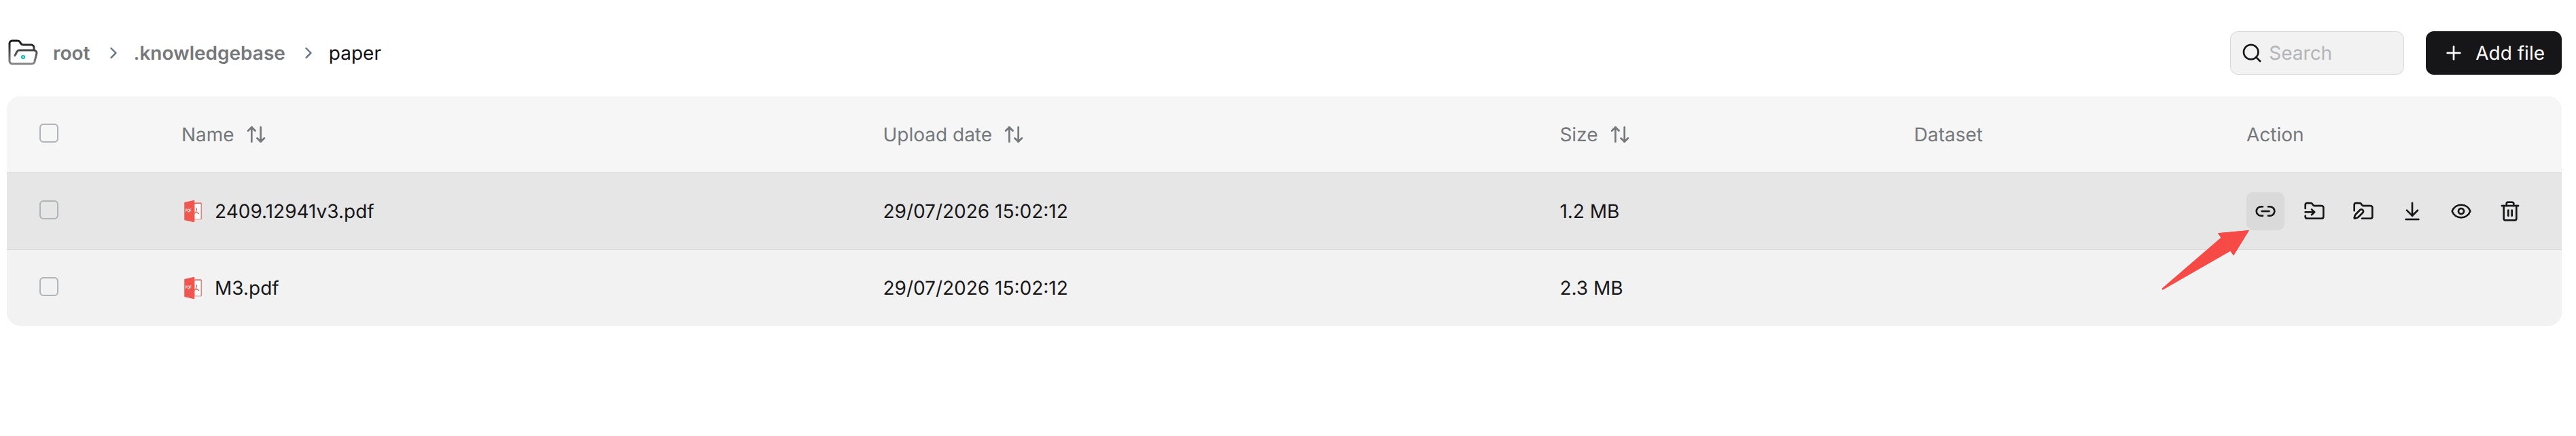+## Batch Link1. Select multiple files that need to be linked.diff --git a/docs/guides/manage_files.md b/docs/guides/manage_files.mddeleted file mode 100644index 70ae7765b0..0000000000--- a/docs/guides/manage_files.md+++ /dev/null@@ -1,92 +0,0 @@-----sidebar_position: 6-slug: /manage_files-sidebar_custom_props: {- categoryIcon: LucideFolderDot-}-----# Files--RAGFlow's file management allows you to upload files individually or in bulk. You can then link an uploaded file to multiple target datasets. This guide showcases some basic usages of the file management feature.--:::info IMPORTANT-Compared to uploading files directly to various datasets, uploading them to RAGFlow's file management and then linking them to different datasets is *not* an unnecessary step, particularly when you want to delete some parsed files or an entire dataset but retain the original files.-:::--## Create folder--RAGFlow's file management allows you to establish your file system with nested folder structures. To create a folder in the root directory of RAGFlow:----:::caution NOTE-Each dataset in RAGFlow has a corresponding folder under the **root/.knowledgebase** directory. You are not allowed to create a subfolder within it.-:::--## Upload file--RAGFlow's file management supports file uploads from your local machine, allowing both individual and bulk uploads:------## Preview file--RAGFlow's file management supports previewing files in the following formats:--- Documents (PDF, DOCS)-- Tables (XLSX)-- Pictures (JPEG, JPG, PNG, TIF, GIF)----## Link file to datasets--RAGFlow's file management allows you to *link* an uploaded file to multiple datasets, creating a file reference in each target dataset. Therefore, deleting a file in your file management will AUTOMATICALLY REMOVE all related file references across the datasets.----You can link your file to one dataset or multiple datasets at one time:----## Move file to a specific folder----## Search files or folders--**File Management** only supports file name and folder name filtering in the current directory (files or folders in the child directory will not be retrieved).----## Rename file or folder--RAGFlow's file management allows you to rename a file or folder:-----## Delete files or folders--RAGFlow's file management allows you to delete files or folders individually or in bulk.--To delete a file or folder:----To bulk delete files or folders:----> - You are not allowed to delete the **root/.knowledgebase** folder.-> - Deleting files that have been linked to datasets will **AUTOMATICALLY REMOVE** all associated file references across the datasets.--## Download uploaded file--RAGFlow's file management allows you to download an uploaded file:----> As of RAGFlow v0.26.4, bulk download is not supported, nor can you download an entire folder.diff --git a/docs/guides/memory/configure_memory.md b/docs/guides/memory/configure_memory.mdindex 76268293b8..e551a07eb1 100644--- a/docs/guides/memory/configure_memory.md+++ b/docs/guides/memory/configure_memory.md@@ -1,12 +1,14 @@---sidebar_position: 3slug: /configure_memory+title: Configure Memory+sidebar_label: Configure Memorysidebar_custom_props: {categoryIcon: LucideBox}----## Configure Memory+# Configure MemoryThe configuration page is used to maintain a memory's basic information, model configuration, capacity configuration, and advanced settings. After making changes, click **Confirm** to save them, or click **Cancel** to discard unsaved content.diff --git a/docs/guides/memory/connect_to_an_agent.md b/docs/guides/memory/connect_to_an_agent.mdindex c6ef2ce124..21cddc3b66 100644--- a/docs/guides/memory/connect_to_an_agent.md+++ b/docs/guides/memory/connect_to_an_agent.md@@ -1,12 +1,14 @@---sidebar_position: 4slug: /connect_to_an_agent+title: Connect to an Agent+sidebar_label: Connect to an Agentsidebar_custom_props: {categoryIcon: LucideBox}----## Connect to an Agent+# Connect to an AgentA memory must be connected to an Agent before historical messages can be written during Agent execution or historical context can be retrieved when answering. Usually, both directions, **write to memory** and **retrieve from memory**, need to be configured.@@ -18,6 +20,10 @@ A memory must be connected to an Agent before historical messages can be written4. Select the target memory. If historical records need to be distinguished by user, configure the user ID.5. Save the Agent and run a test. After it runs, return to the memory's **Messages** page to check whether new messages have been generated.+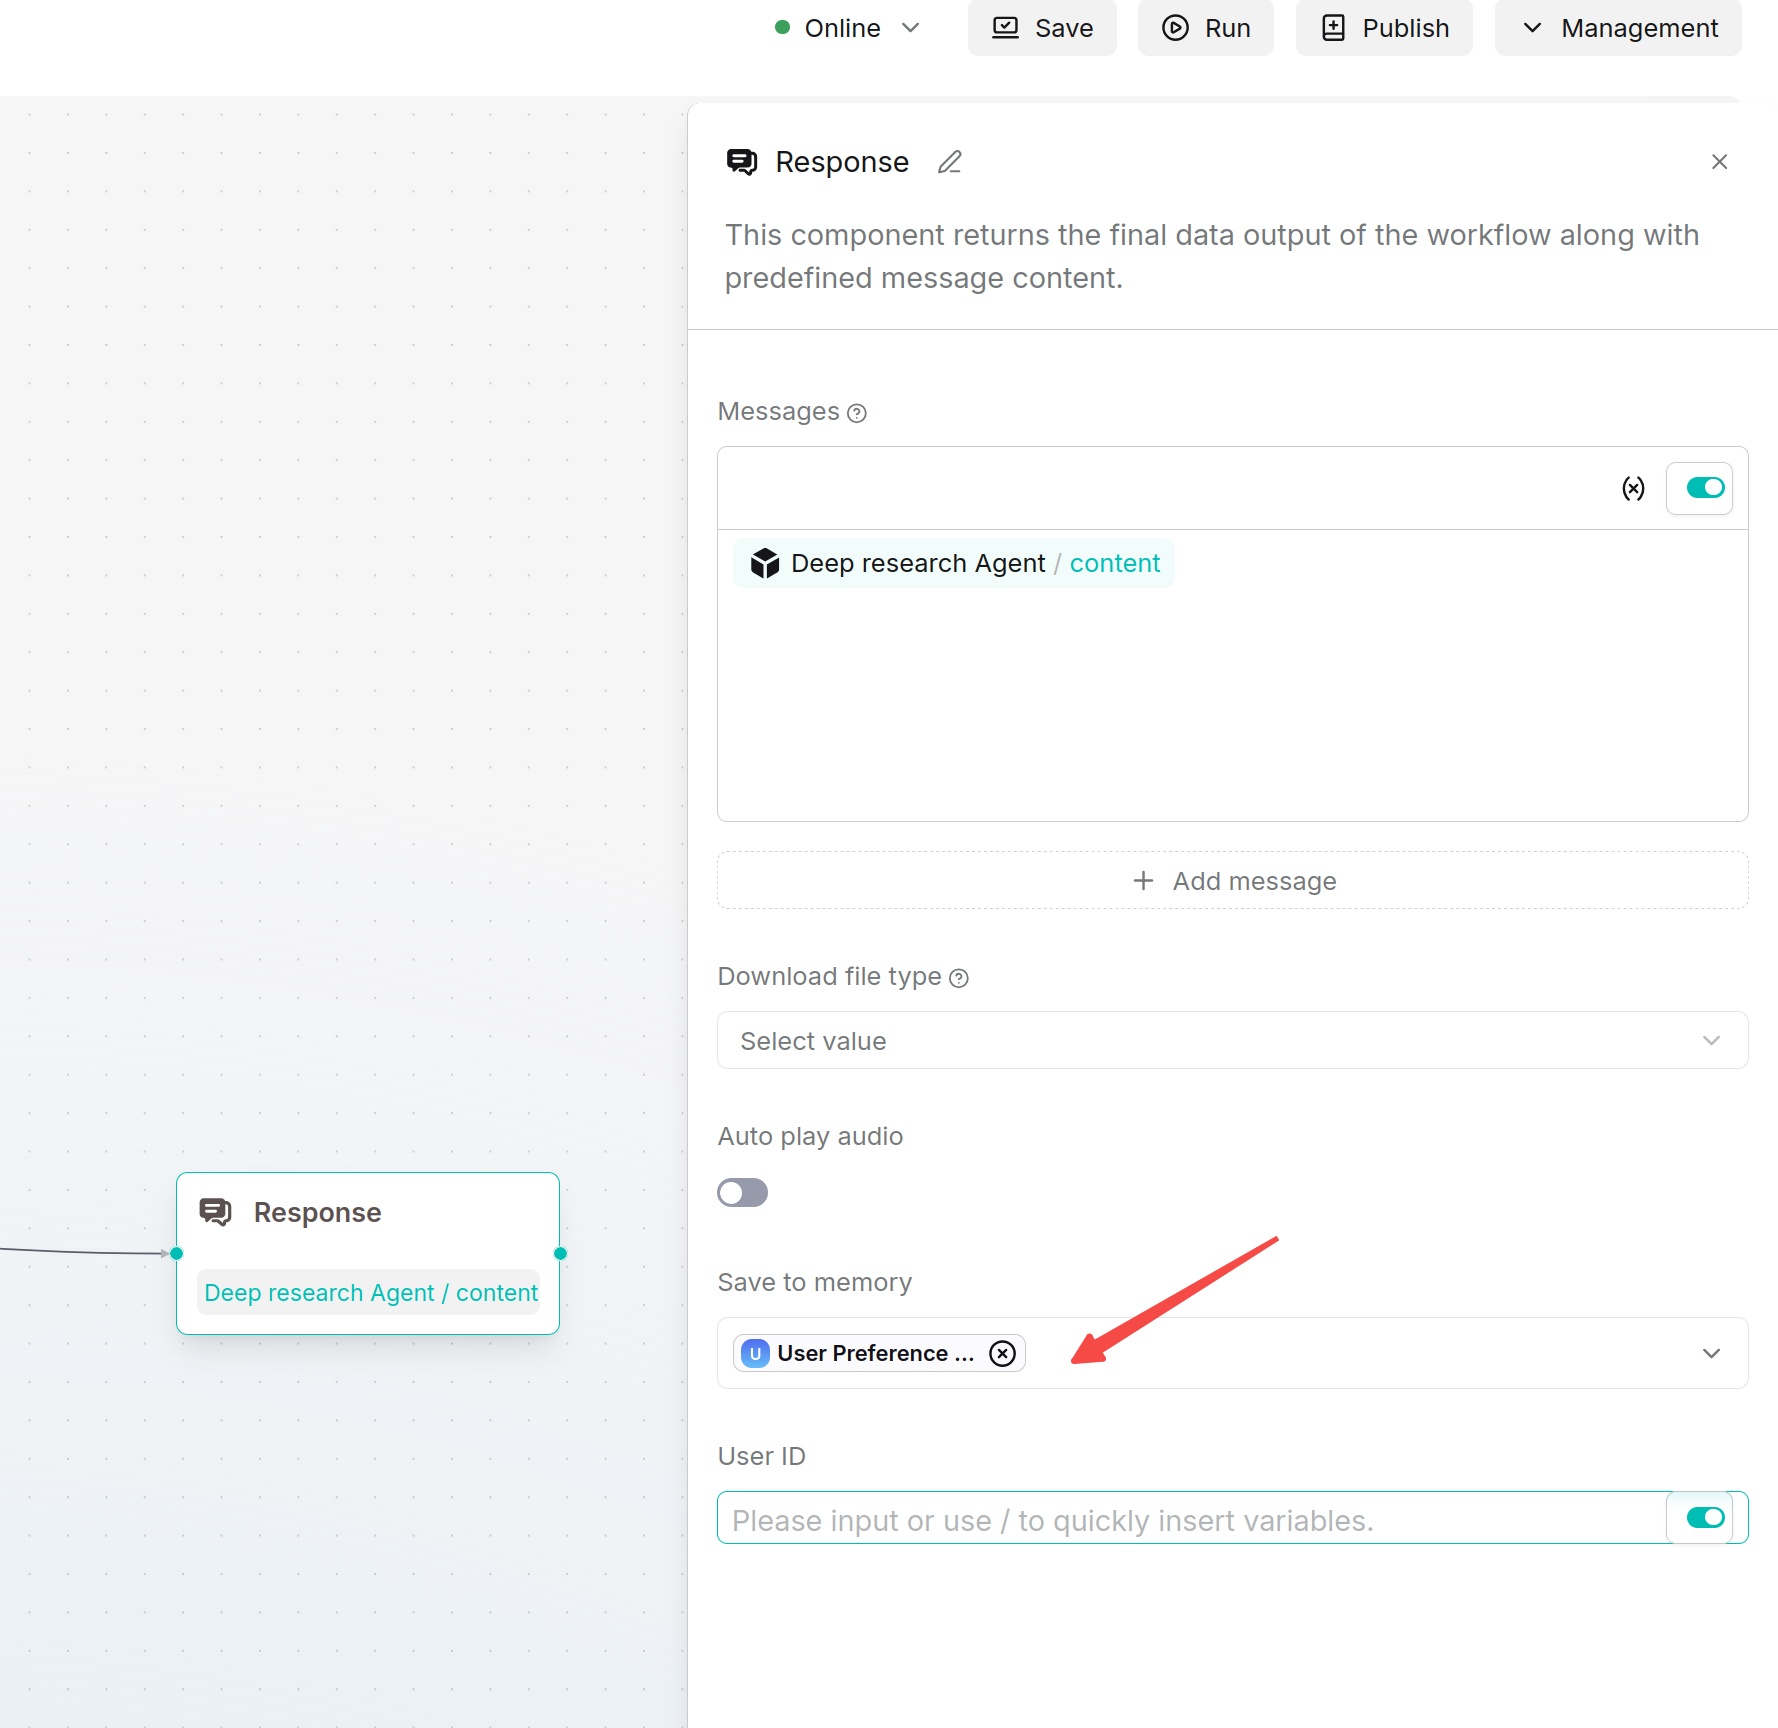++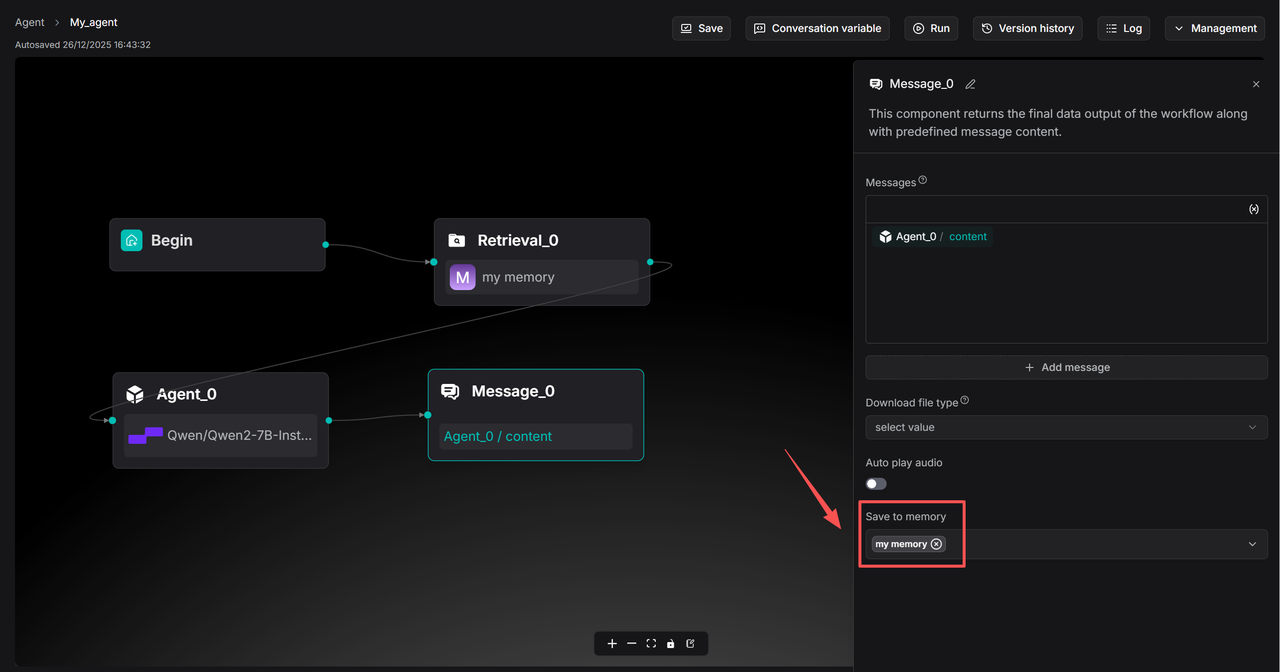+### Let an Agent Retrieve from Memory1. Select or add the **Retrieval** component on the Agent canvas.@@ -26,3 +32,7 @@ A memory must be connected to an Agent before historical messages can be written4. Adjust **Similarity threshold**, **Vector similarity weight**, and **Top N** as needed.5. Connect the retrieval result to a subsequent large language model or answer component, so that the Agent can use the retrieved historical context.6. Save and run a test, and check whether the answer correctly references historical memories.++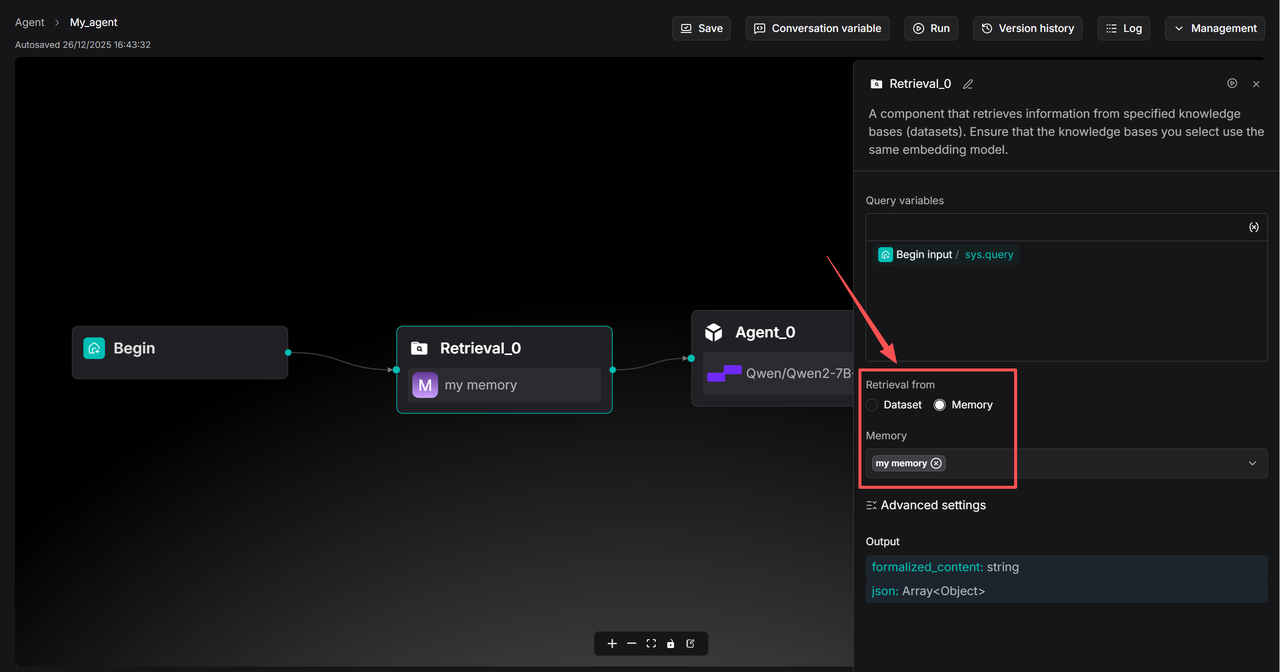++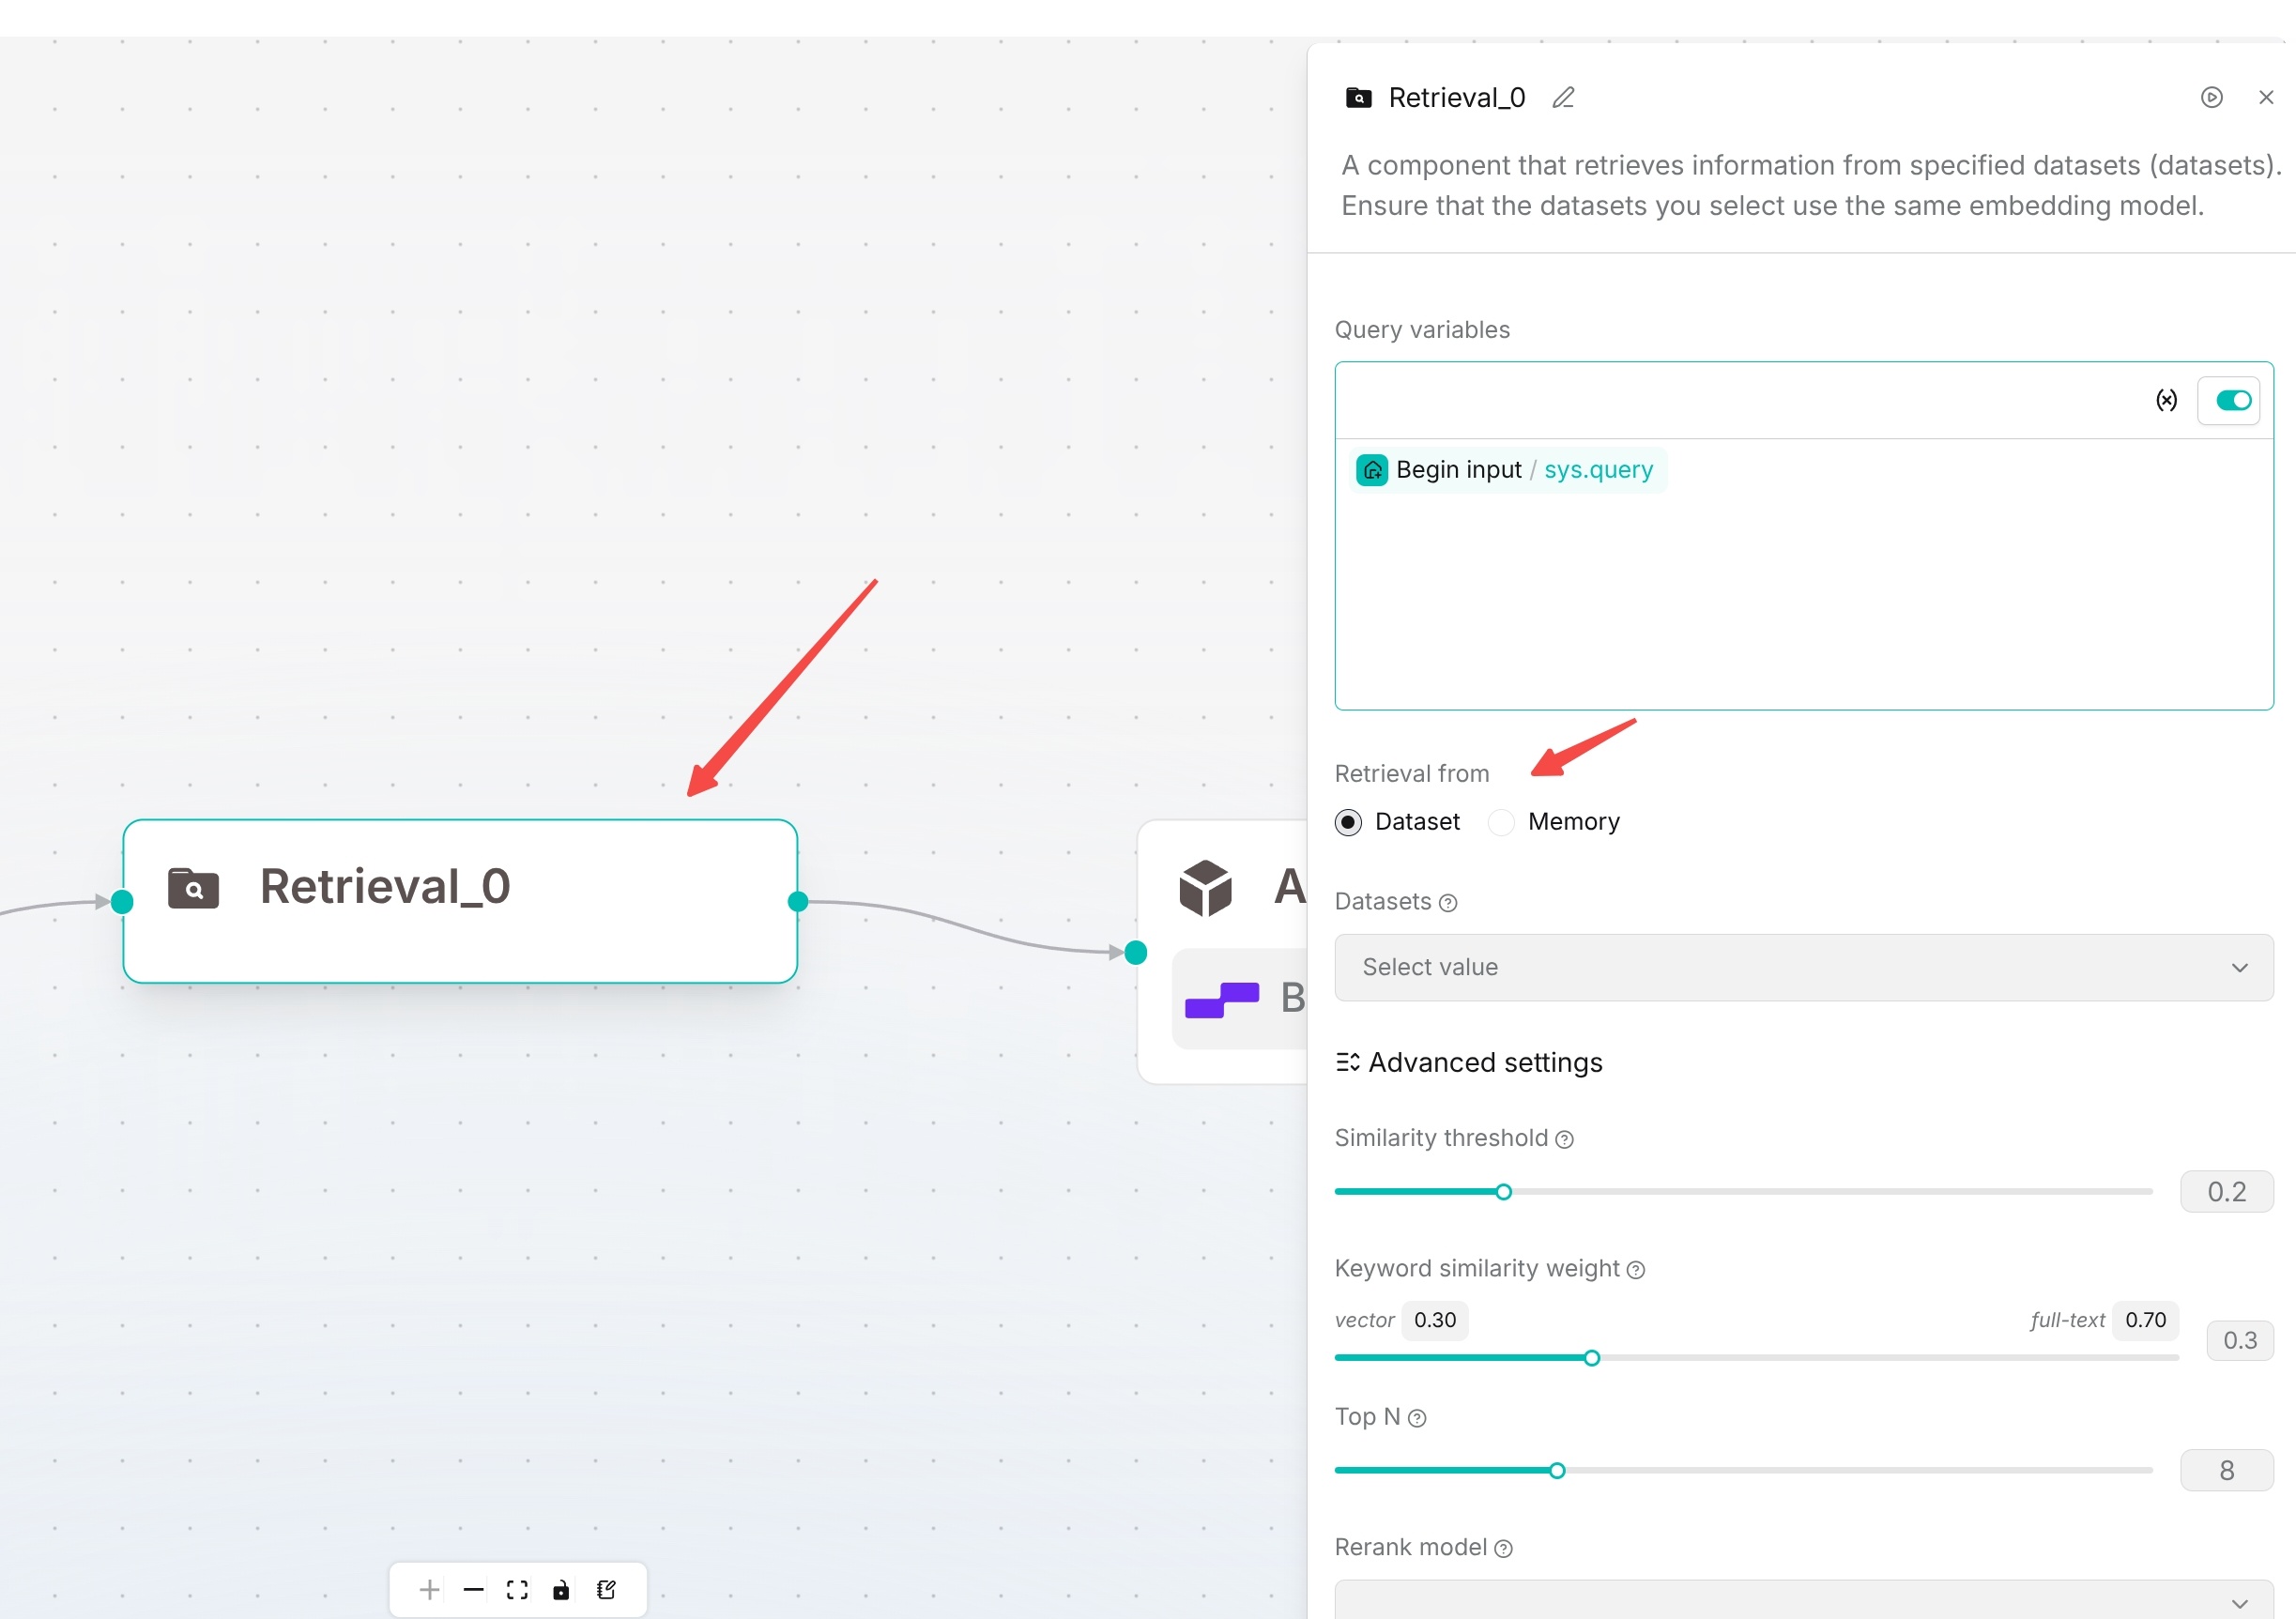diff --git a/docs/guides/memory/create_memory.md b/docs/guides/memory/create_memory.mdindex b0fd8d9eb1..c5aa92c0a3 100644--- a/docs/guides/memory/create_memory.md+++ b/docs/guides/memory/create_memory.md@@ -2,6 +2,7 @@sidebar_position: 1slug: /use_memorysidebar_label: Create Memory+title: Create Memorysidebar_custom_props: {categoryIcon: LucideBox}@@ -11,10 +12,15 @@ sidebar_custom_props: {This chapter describes how to create and configure memories in RAGFlow, view and manage messages, and save and retrieve memories in Agents. Memories are used to save conversation content and extraction results generated during Agent execution, helping Agents reuse historical context in subsequent conversations or tasks.+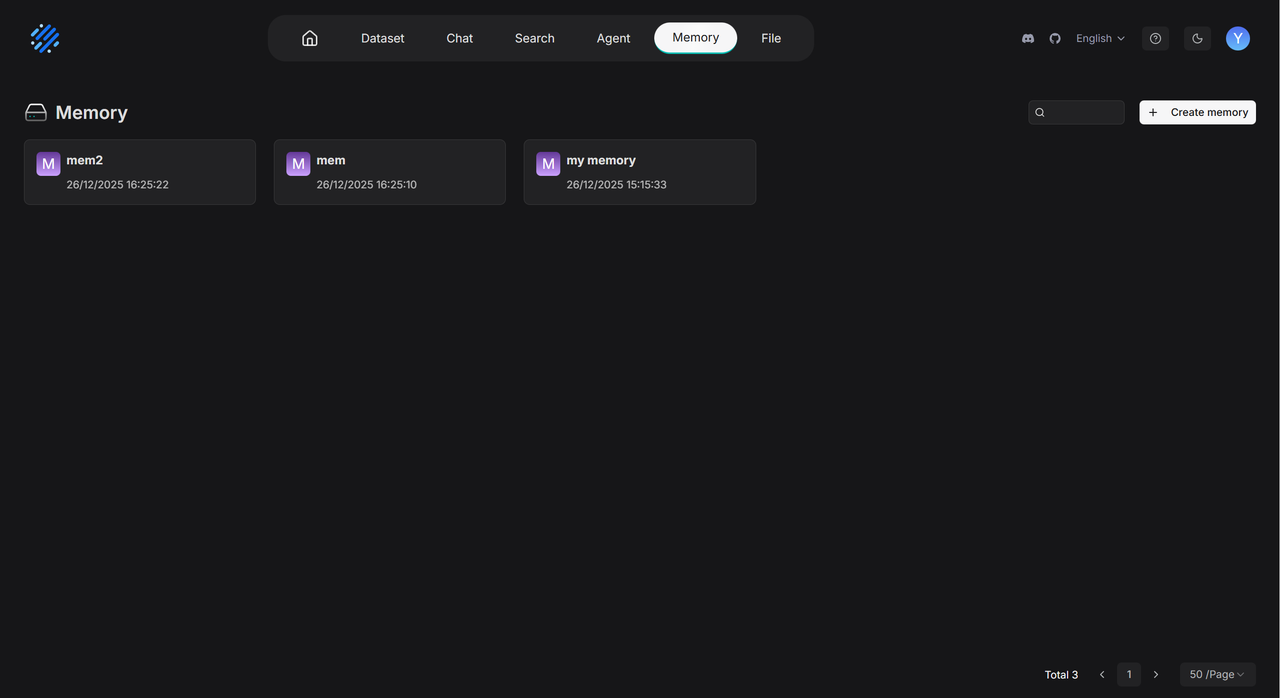+## Create Memory1. Go to the **Memory** page.2. Click **Create memory**.3. Enter the memory name.4. Select the memory type, embedding model, and large language model.-5. After confirmation, enter the memory list or details page.+5. Click **Confirm** to create the memory.+6. After confirmation, enter the memory list or details page.++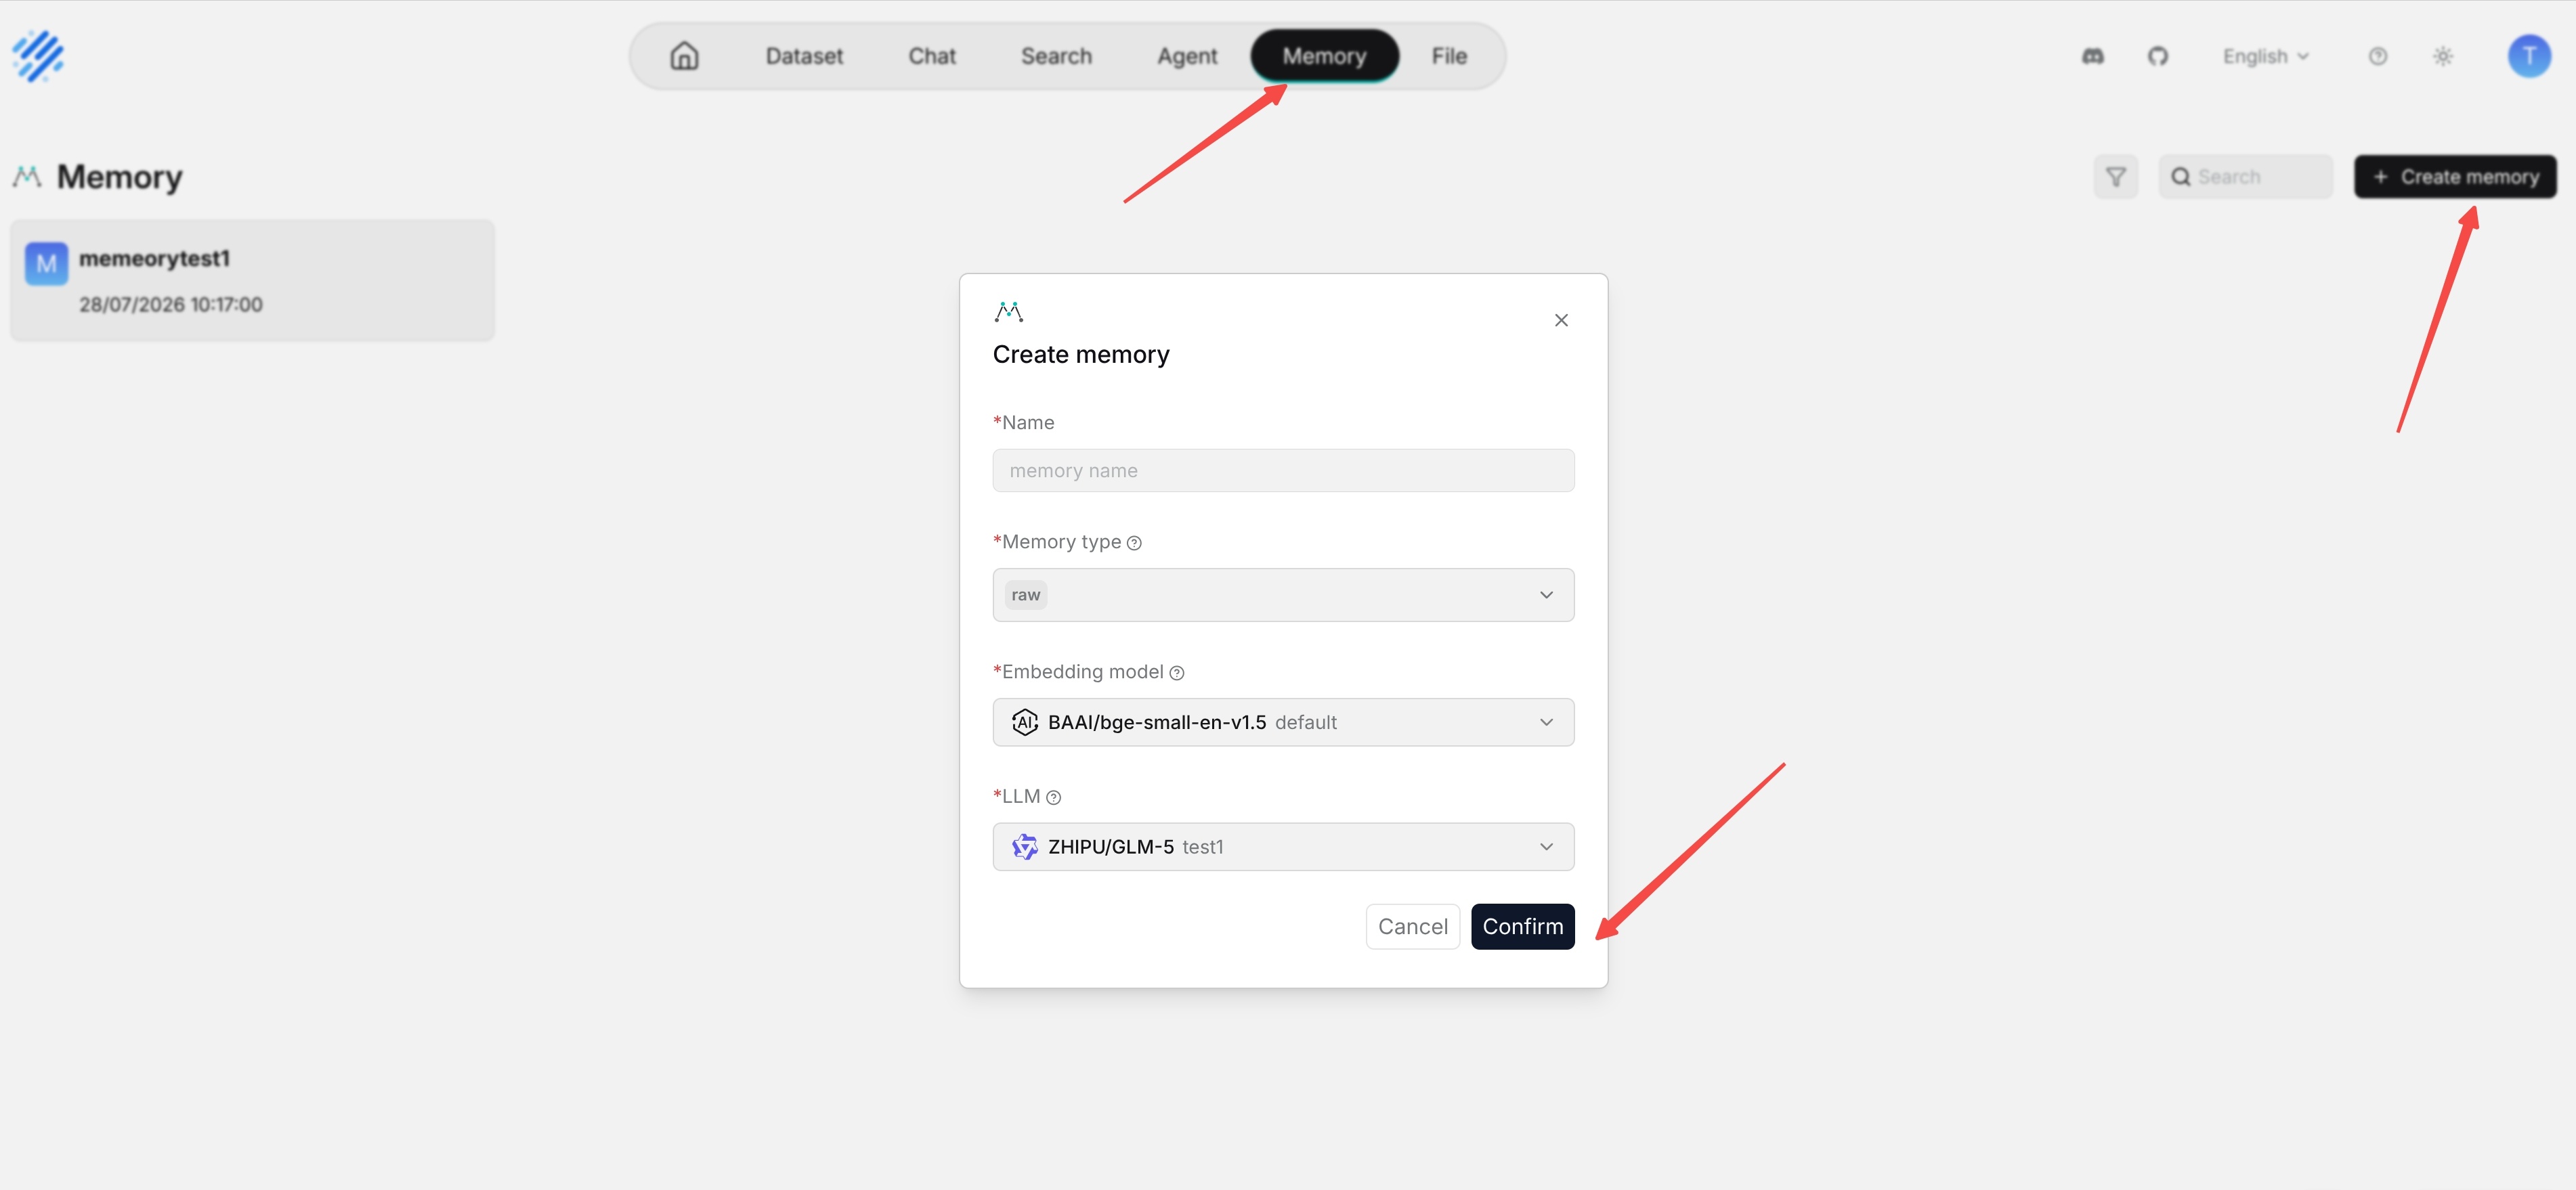diff --git a/docs/guides/memory/message_page.md b/docs/guides/memory/message_page.mdindex be763dcc13..5d5cb74cdf 100644--- a/docs/guides/memory/message_page.md+++ b/docs/guides/memory/message_page.md@@ -1,15 +1,19 @@---sidebar_position: 2slug: /message_page+title: Message Page+sidebar_label: Message Pagesidebar_custom_props: {categoryIcon: LucideBox}----## Message Page+# Message PageThe message page is used to view messages written to memory and control whether messages participate in subsequent retrieval. The left side provides **Messages** and **Configurations** entries, and the right side displays the message list, search, and filters.+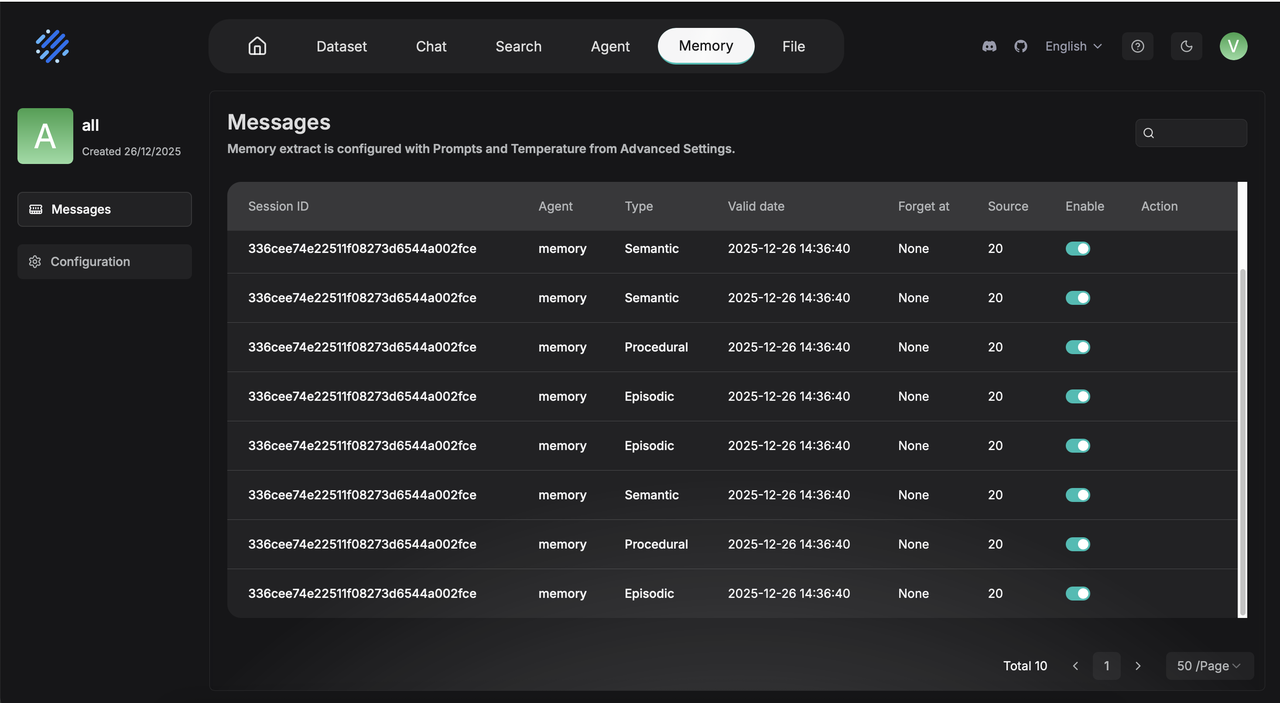+Memory extraction uses the prompts and temperature in **Advanced Settings** on the configuration page. If the extraction result does not meet expectations, check these configurations first.Users can search messages in the current memory's message list, or narrow the search scope through conditional filters.diff --git a/docs/guides/models/deploy_local_llm.mdx b/docs/guides/models/deploy_local_llm.mdxindex 2109ab5588..cb92aea31c 100644--- a/docs/guides/models/deploy_local_llm.mdx+++ b/docs/guides/models/deploy_local_llm.mdx@@ -1,11 +1,13 @@---sidebar_position: 2+title: Deploy Local Models+sidebar_label: Deploy Local Modelsslug: /deploy_local_llmsidebar_custom_props: {categoryIcon: LucideMonitorCog}----# Deploy local models+# Deploy Local Modelsimport Tabs from '@theme/Tabs';import TabItem from '@theme/TabItem';@@ -21,7 +23,7 @@ RAGFlow seamlessly integrates with Ollama and Xinference, without the need for fThis user guide does not intend to cover much of the installation or configuration details of Ollama or Xinference; its focus is on configurations inside RAGFlow. For the most current information, you may need to check out the official site of Ollama or Xinference.:::-## Deploy local models using Ollama+## Deploy Local Models Using Ollama[Ollama](https://github.com/ollama/ollama) enables you to run open-source large language models that you deployed locally. It bundles model weights, configurations, and data into a single package, defined by a Modelfile, and optimizes setup and configurations, including GPU usage.@@ -30,7 +32,7 @@ This user guide does not intend to cover much of the installation or configurati- For a complete list of supported models and variants, see the [Ollama model library](https://ollama.com/library).:::-### 1. Deploy Ollama using Docker+### 1. Deploy Ollama Using DockerOllama can be [installed from binaries](https://ollama.com/download) or [deployed with Docker](https://hub.docker.com/r/ollama/ollama). Here are the instructions to deploy with Docker:@@ -60,7 +62,7 @@ $ sudo docker exec ollama ollama pull bge-m3> success```-### 2. Find Ollama URL and ensure it is accessible+### 2. Find Ollama URL and Ensure It Is Accessible- If RAGFlow runs in Docker, the localhost is mapped within the RAGFlow Docker container as `host.docker.internal`. If Ollama runs on the same host machine, the right URL to use for Ollama would be `http://host.docker.internal:11434/' and you should check that Ollama is accessible from inside the RAGFlow container with:```bash@@ -85,10 +87,9 @@ $ curl http://${IP_OF_OLLAMA_MACHINE}:11434/In RAGFlow, click on your logo on the top right of the page **>** **Model providers** and add Ollama to RAGFlow:--### 4. Complete basic Ollama settings+### 4. Complete Basic Ollama SettingsIn the popup window, complete basic settings for Ollama:@@ -114,7 +115,7 @@ Click on your logo **>** **Model providers** **>** **System Model Settings** toUpdate your model(s) accordingly in **Chat Configuration**.-## Deploy a local model using Xinference+## Deploy a Local Model Using XinferenceXorbits Inference ([Xinference](https://github.com/xorbitsai/inference)) enables you to unleash the full potential of cutting-edge AI models.@@ -125,17 +126,17 @@ Xorbits Inference ([Xinference](https://github.com/xorbitsai/inference)) enablesTo deploy a local model, e.g., **Mistral**, using Xinference:-### 1. Check firewall settings+### 1. Check Firewall SettingsEnsure that your host machine's firewall allows inbound connections on port 9997.-### 2. Start an Xinference instance+### 2. Start an Xinference Instance```bash$ xinference-local --host 0.0.0.0 --port 9997```-### 3. Launch your local model+### 3. Launch Your Local ModelLaunch your local model (**Mistral**), ensuring that you replace `${quantization}` with your chosen quantization method:@@ -146,9 +147,8 @@ $ xinference launch -u mistral --model-name mistral-v0.1 --size-in-billions 7 --In RAGFlow, click on your logo on the top right of the page **>** **Model providers** and add Xinference to RAGFlow:--### 5. Complete basic Xinference settings+### 5. Complete Basic Xinference SettingsEnter an accessible base URL, such as `http://<your-xinference-endpoint-domain>:9997/v1`.> For rerank model, please use the `http://<your-xinference-endpoint-domain>:9997/v1/rerank` as the base URL.@@ -163,13 +163,13 @@ Click on your logo **>** **Model providers** **>** **System Model Settings** toUpdate your chat model accordingly in **Chat Configuration**:-## Deploy a local model using IPEX-LLM+## Deploy a Local Model Using IPEX-LLM[IPEX-LLM](https://github.com/intel-analytics/ipex-llm) is a PyTorch library for running LLMs on local Intel CPUs or GPUs (including iGPU or discrete GPUs like Arc, Flex, and Max) with low latency. It supports Ollama on Linux and Windows systems.To deploy a local model, e.g., **Qwen2**, using IPEX-LLM-accelerated Ollama:-### 1. Check firewall settings+### 1. Check Firewall SettingsEnsure that your host machine's firewall allows inbound connections on port 11434. For example:@@ -177,7 +177,7 @@ Ensure that your host machine's firewall allows inbound connections on port 1143sudo ufw allow 11434/tcp```-### 2. Launch Ollama service using IPEX-LLM+### 2. Launch Ollama Service Using IPEX-LLM#### 2.1 Install IPEX-LLM for Ollama@@ -223,7 +223,7 @@ For detailed information about installing IPEX-LLM for Ollama, see [Run llama.cp*A symbolic link to Ollama appears in your current directory, and you can use this executable file following standard Ollama commands.*-#### 2.3 Launch Ollama service+#### 2.3 Launch Ollama Service1. Set the environment variable `OLLAMA_NUM_GPU` to `999` to ensure that all layers of your model run on the Intel GPU; otherwise, some layers may default to CPU.2. For optimal performance on Intel Arc™ A-Series Graphics with Linux OS (Kernel 6.2), set the following environment variable before launching the Ollama service:@@ -272,19 +272,17 @@ For detailed information about installing IPEX-LLM for Ollama, see [Run llama.cpTo enable the Ollama service to accept connections from all IP addresses, use `OLLAMA_HOST=0.0.0.0 ./ollama serve` rather than simply `./ollama serve`.:::-*The console displays messages similar to the following:*+The console displays service startup messages.--### 3. Pull and Run Ollama model+### 3. Pull and Run Ollama Model-#### 3.1 Pull Ollama model+#### 3.1 Pull Ollama ModelWith the Ollama service running, open a new terminal and run `./ollama pull <model_name>` (Linux) or `ollama.exe pull <model_name>` (Windows) to pull the desired model. e.g., `qwen2:latest`:--#### 3.2 Run Ollama model+#### 3.2 Run Ollama Model<TabsdefaultValue="linux"@@ -323,7 +321,7 @@ ubuntu 22.04/24.04```bashpip install vllm```-### 5.1 RUN VLLM WITH BEST PRACTISE+### 5.1 Run vLLM with Best Practise```bashnohup vllm serve /data/Qwen3-8B --served-model-name Qwen3-8B-FP8 --dtype auto --port 1025 --gpu-memory-utilization 0.90 --tool-call-parser hermes --enable-auto-tool-choice > /var/log/vllm_startup1.log 2>&1 &@@ -338,23 +336,23 @@ Starting vLLM API server 0 on http://0.0.0.0:1025Started server process [19177]Application startup complete.```-### 5.2 INTERGRATEING RAGFLOW WITH VLLM CHAT/EM/RERANK LLM WITH WEBUI+### 5.2 Intergrateing RAGFlow with vLLM Chat/Em/Rerank LLM with WebUI-setting->model providers->search->vllm->add ,configure as follow:+Go to **Settings** → **Model Providers** → **Search** → **vLLM** → **Add**; configure as follows: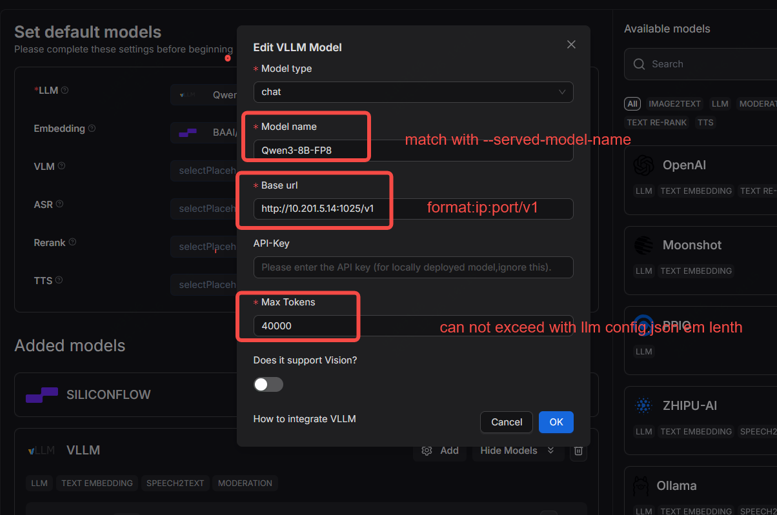-select vllm chat model as default llm model as follow:+Select the vLLM chat model as the default LLM model: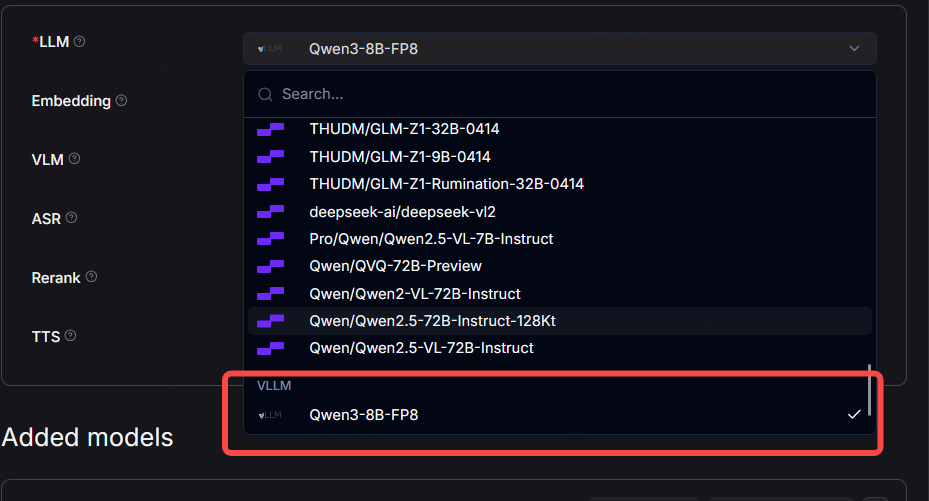-### 5.3 chat with vllm chat model-create chat->create conversations-chat as follow:+### 5.3 Chat with vLLM Chat Model+Create a chat and start a conversation as follows: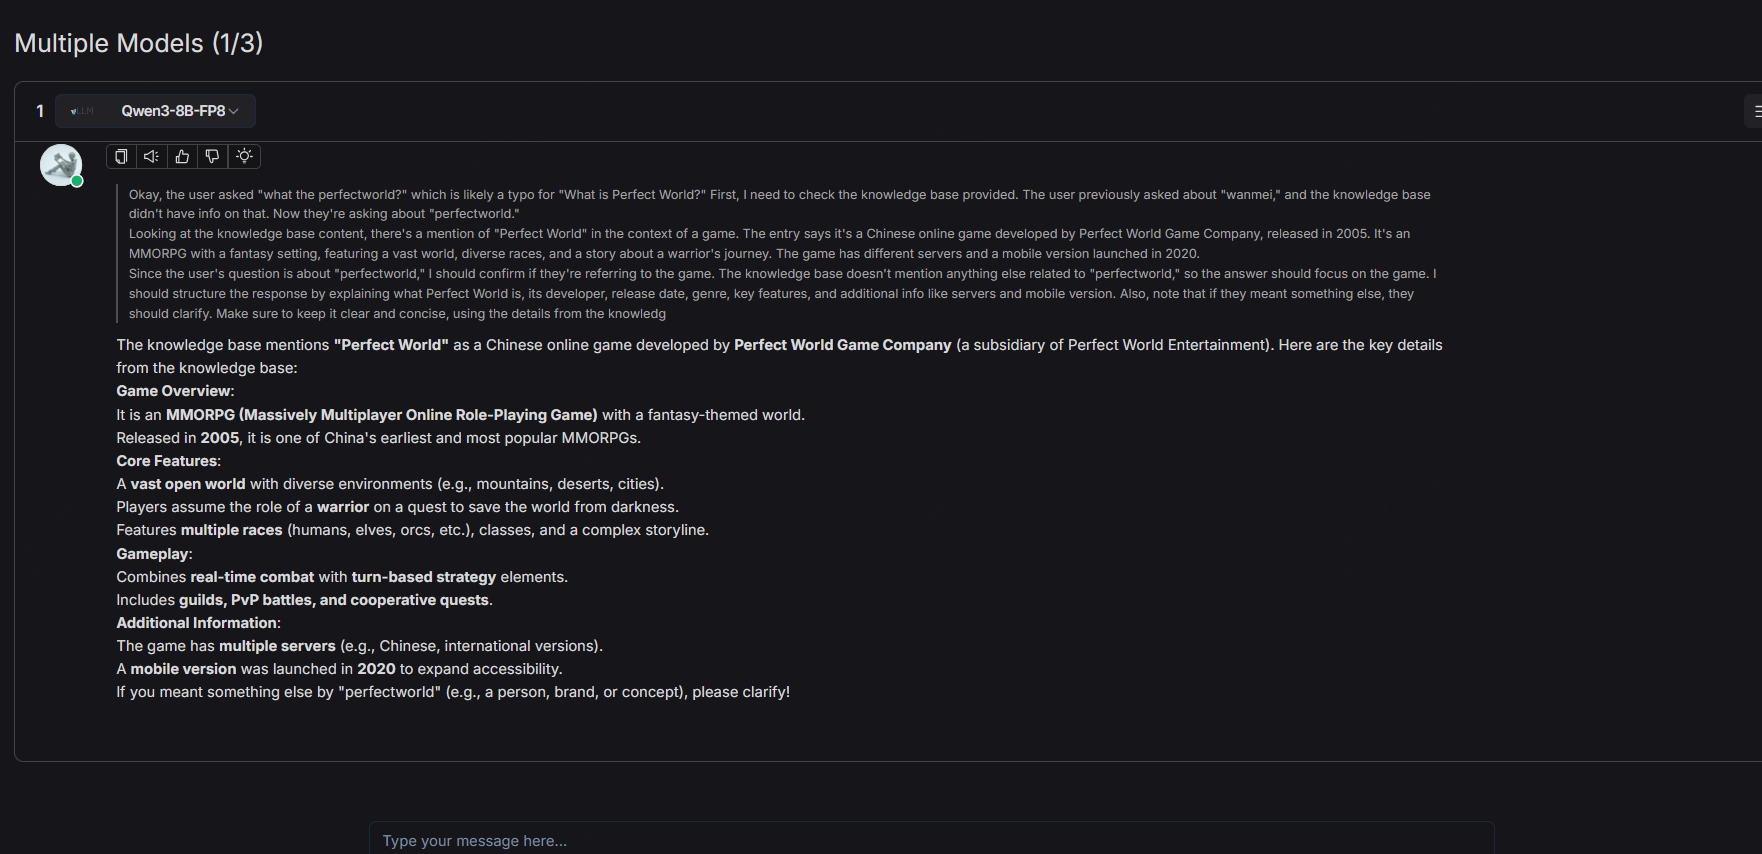### 6. Deploy GPUStackubuntu 22.04/24.04-### 6.1 RUN GPUStack WITH BEST PRACTISE+### 6.1 Run GPUStack with Best Practise```bashsudo docker run -d --name gpustack \@@ -374,7 +372,7 @@ root@gpustack-prod:~# docker psCONTAINER ID IMAGE COMMAND CREATED STATUS PORTS NAMESabf59be84b1a gpustack/gpustack "/usr/bin/entrypoint…" 6 hours ago Up 6 hours 0.0.0.0:80->80/tcp, [::]:80->80/tcp, 0.0.0.0:10161->10161/tcp, [::]:10161->10161/tcp gpustack```-### 6.2 INTERGRATEING RAGFLOW WITH GPUSTACK CHAT/EM/RERANK LLM WITH WEBUI+### 6.2 Intergrateing RAGFlow with GPUStack Chat/Em/Rerank LLM with WebUIsetting->model providers->search->gpustack->add ,configure as follow:diff --git a/docs/guides/models/llm_api_key_setup.md b/docs/guides/models/llm_api_key_setup.mdindex b39d3bb994..d102c14bcc 100644--- a/docs/guides/models/llm_api_key_setup.md+++ b/docs/guides/models/llm_api_key_setup.md@@ -1,15 +1,17 @@---sidebar_position: 1+title: Configure Model API Key+sidebar_label: Configure Model API Keyslug: /llm_api_key_setupsidebar_custom_props: {categoryIcon: LucideKey}----# Configure model API key+# Configure Model API KeyRAGFlow model provider management allows you to connect online models, local models, and OpenAI-compatible models to RAGFlow for use in knowledge bases, chats, search, and agents.-## Get model API key+## Get Model API KeyRAGFlow supports most mainstream LLMs. Please refer to [Supported Models](../../guides/models/supported_models.mdx) for a complete list of supported models. You will need to apply for your model API key online.@@ -17,15 +19,15 @@ RAGFlow supports most mainstream LLMs. Please refer to [Supported Models](../../If you find your online LLM is not on the list, don't feel disheartened. The list is expanding, and you can [file a feature request](https://github.com/infiniflow/ragflow/issues/new?assignees=&labels=feature+request&projects=&template=feature_request.yml&title=%5BFeature+Request%5D%3A+) with us! Alternatively, if you have customized or locally-deployed models, you can [bind them to RAGFlow using Ollama, Xinference, or LocalAI](./deploy_local_llm.mdx).:::-## Add a model provider instance+## Add a Model Provider Instance-### Select a model provider+### Select a Model ProviderGo to **User settings** **>** **Model providers**. In **Available models**, select a provider and complete its configuration. After the configuration succeeds, the provider is marked as **Configured**.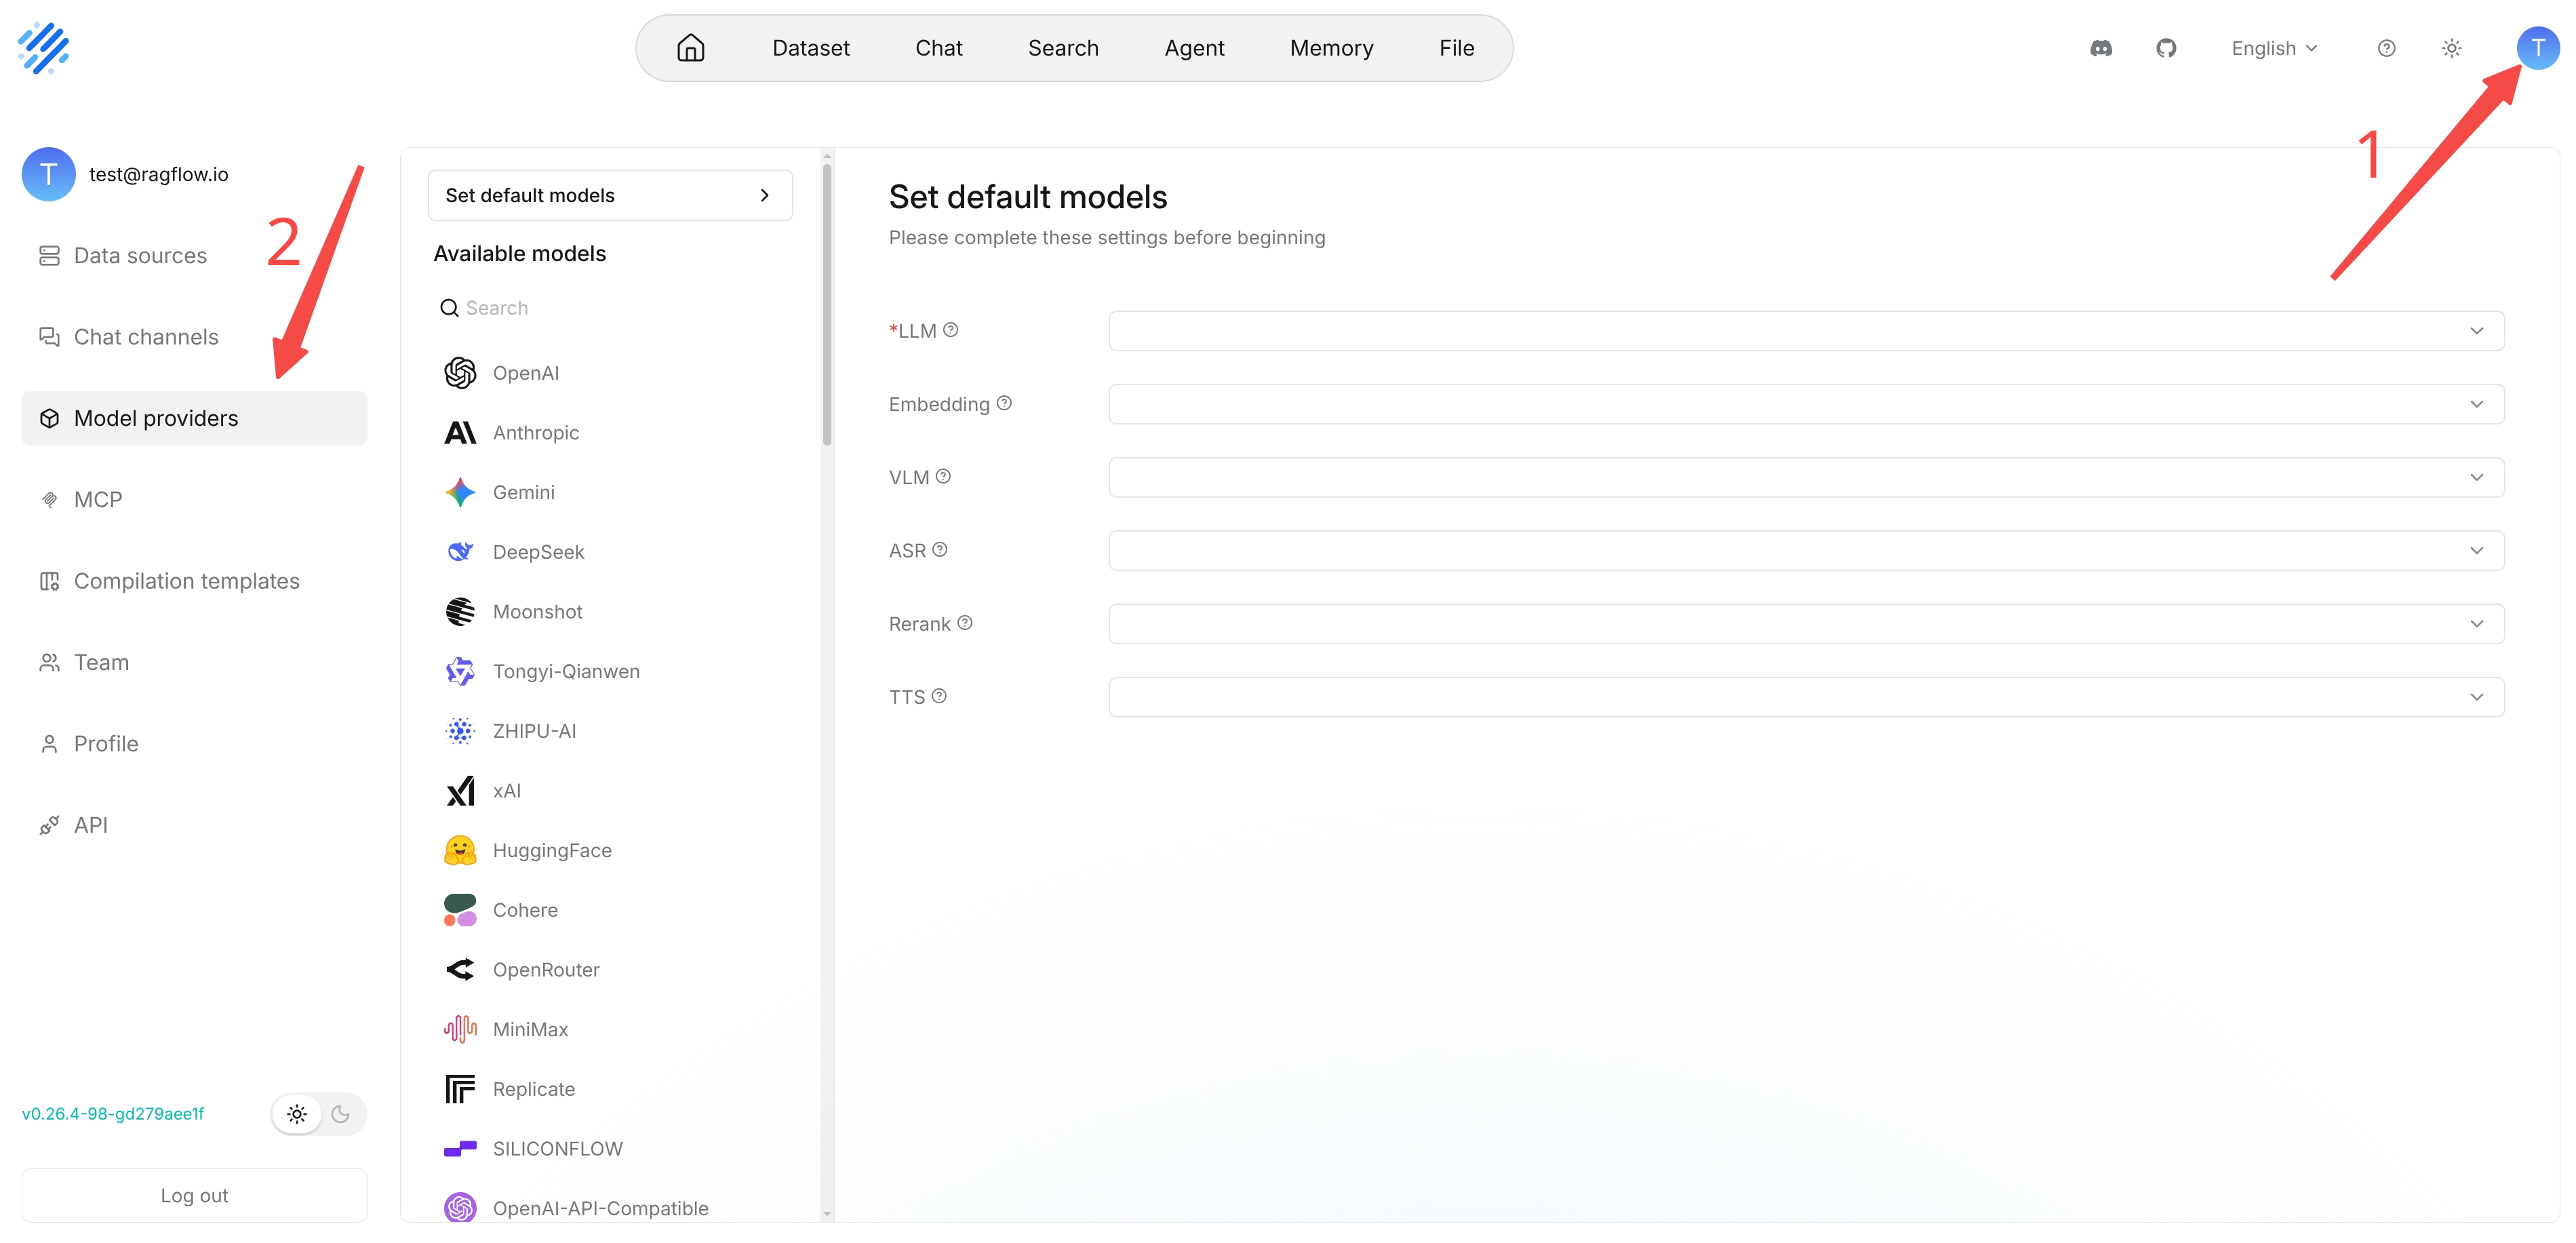-### Create a model provider instance and configure connection information+### Create a Model Provider Instance and Configure Connection InformationAn instance stores a set of connection settings under a provider. You can create separate instances for test environments, production environments, local models, or proxy gateways to avoid mixing configurations for different purposes.When you configure a provider for the first time, the right pane prompts you to create an instance first. After the instance is saved, you can continue to fill in **API Key** and **Base URL** and add models.@@ -47,25 +49,25 @@ To configure a model provider:Do not expose your API Key. An incorrect Base URL causes connection verification or model calls to fail. When using a compatible API, confirm whether the path must include `/v1`.:::-### Verify the connection+### Verify the ConnectionAfter filling in **API Key** and **Base URL**, verify the connection first. If verification fails, check the API Key, Base URL, network connection, account quota, and model availability.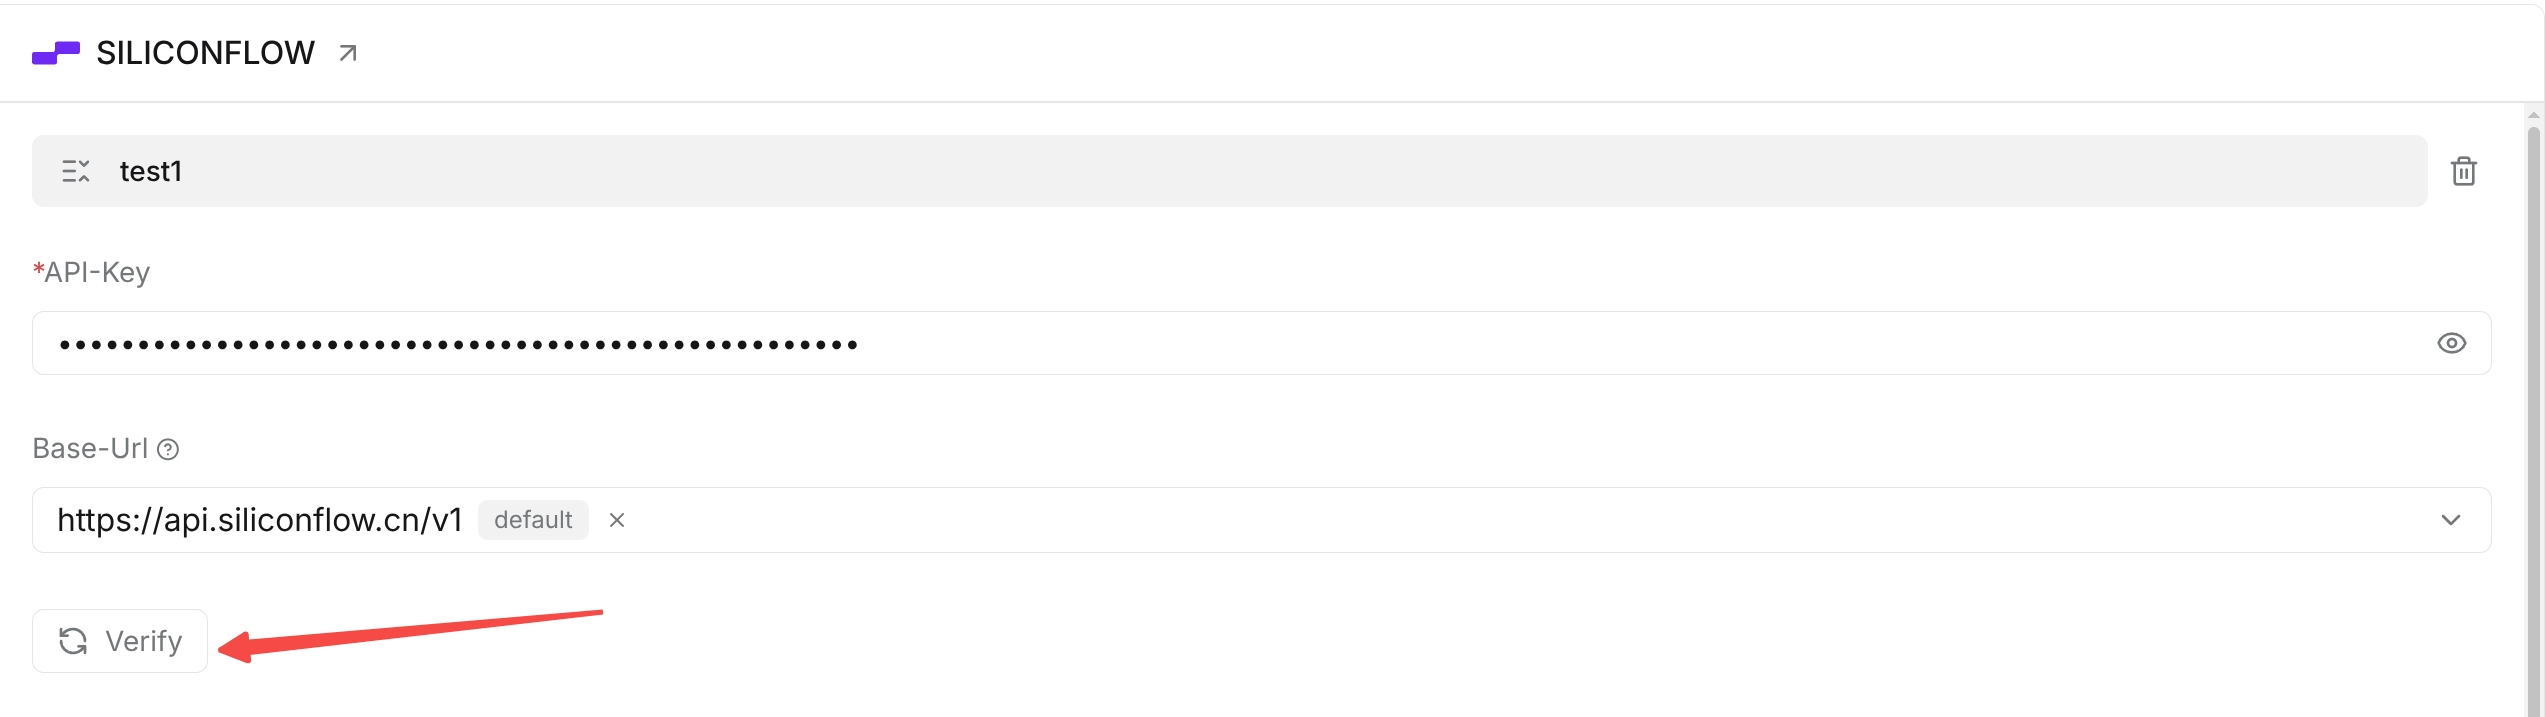-## Add models to an instance+## Add Models to an InstanceAfter you add a model provider instance and the connection verification succeeds, you can add and configure models for this instance. Add the model types required by your business, such as large language models (LLMs), embedding models, vision-language models (VLMs), automatic speech recognition models (ASR), rerank models, and text-to-speech models (TTS).After adding models, you can set them as the default models for the corresponding model types.-### Add models from the list+### Add Models from the ListAfter the model instance connection succeeds, RAGFlow automatically displays some models supported by the model provider. You can search for the models you need and add them one by one, or add the models in the current list in batch.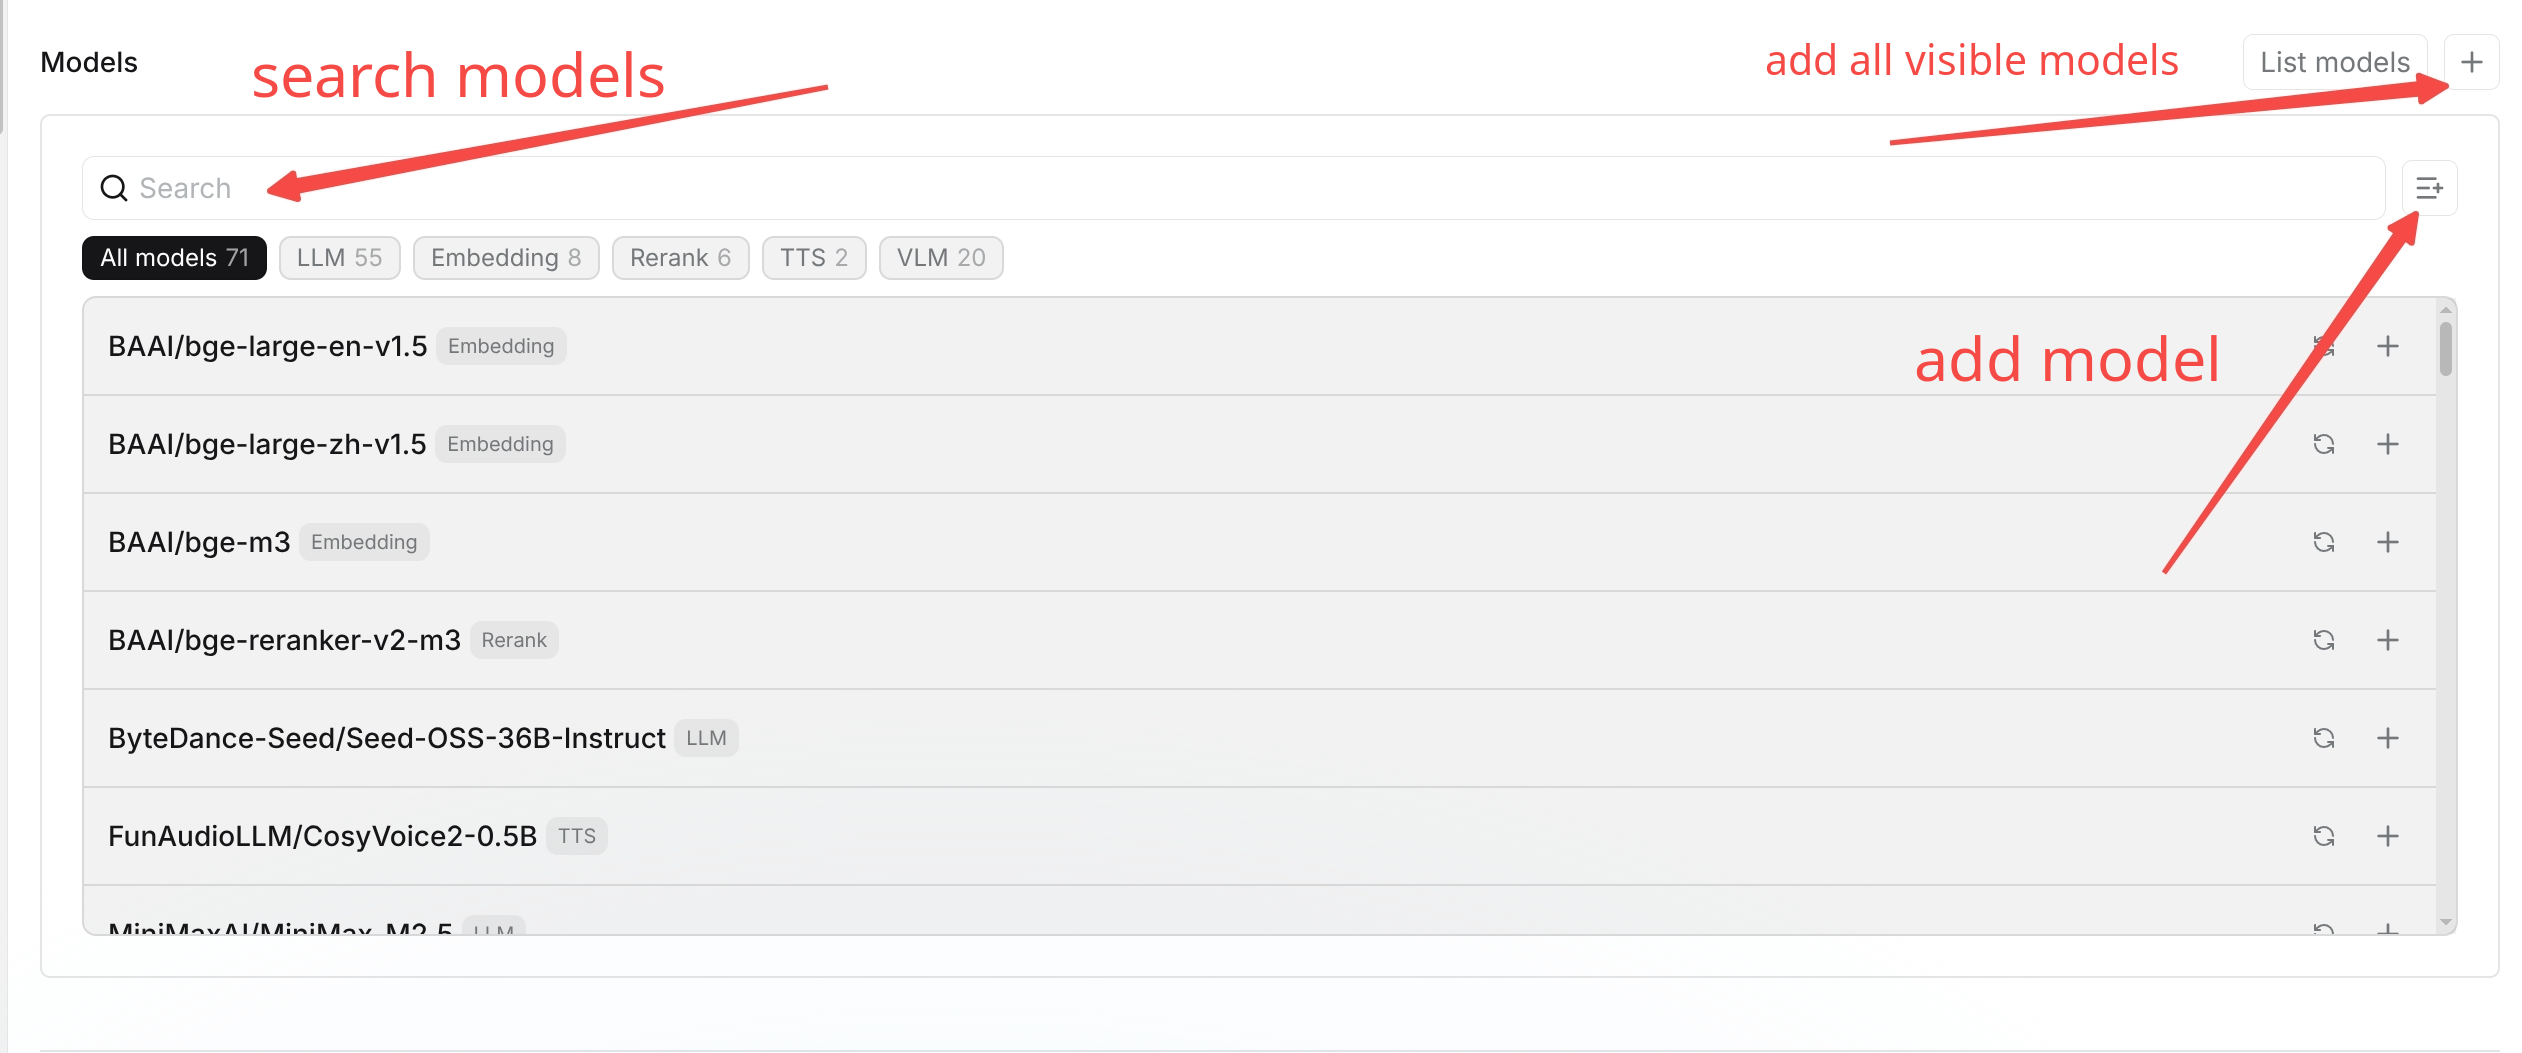-### Add a custom model+### Add a Custom ModelIf the required model is not shown in the list but is actually supported by the model provider, you can add it manually as a custom model. When adding a custom model, fill in the model name and select the model type.@@ -84,7 +86,7 @@ To add a custom model: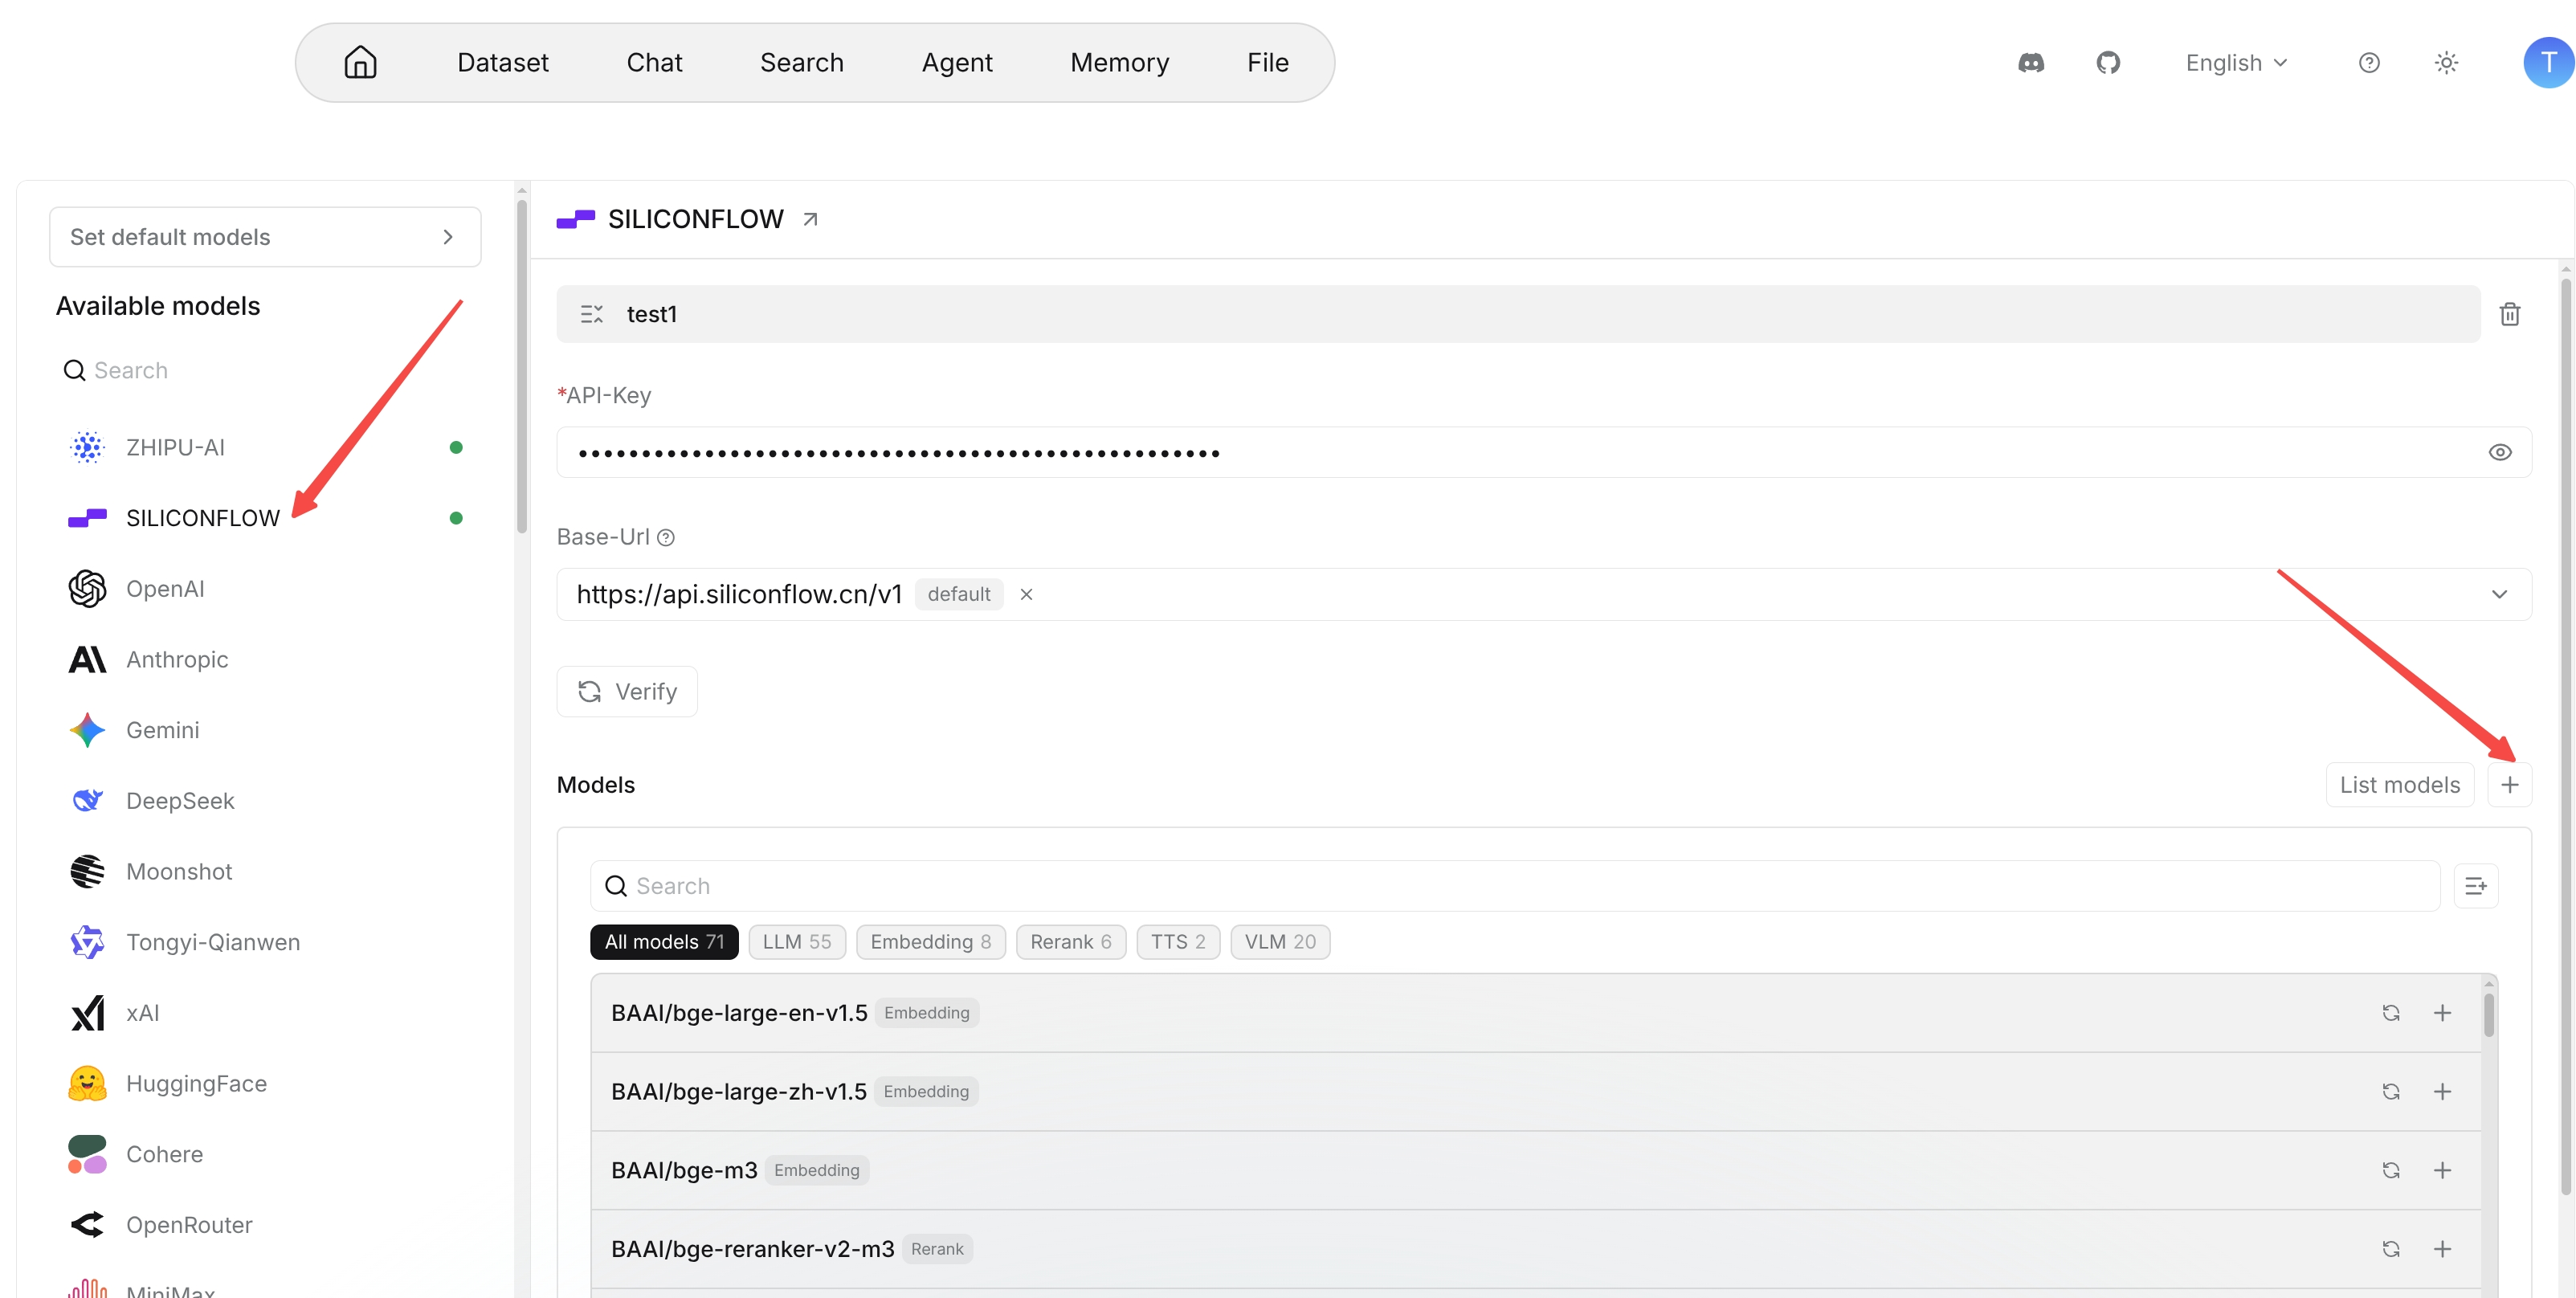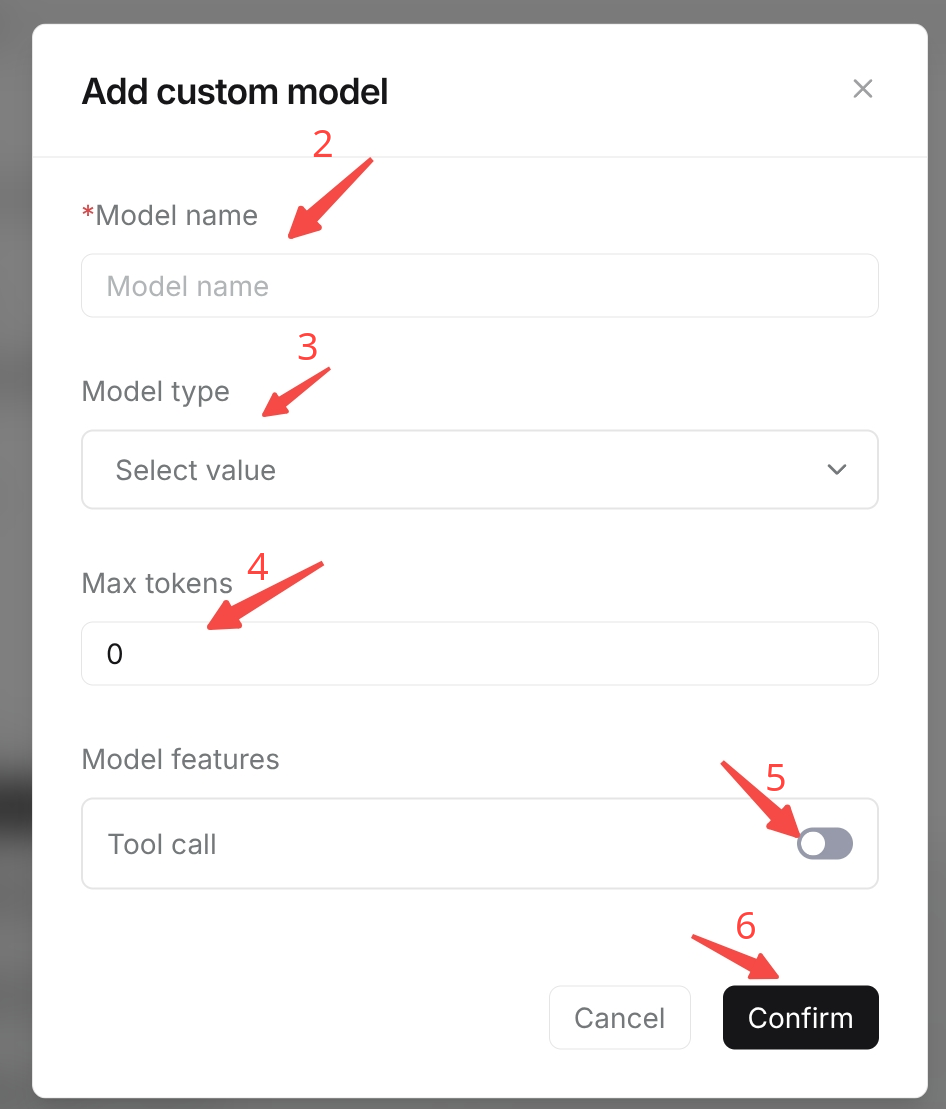-## Set default models+## Set Default ModelsDefault models are used when RAGFlow needs to select a model automatically and no model has been specified separately. Set default models after adding and verifying models to avoid selecting unavailable models on business pages.@@ -97,7 +99,7 @@ If you have configured a rerank model, it is also recommended to set a default r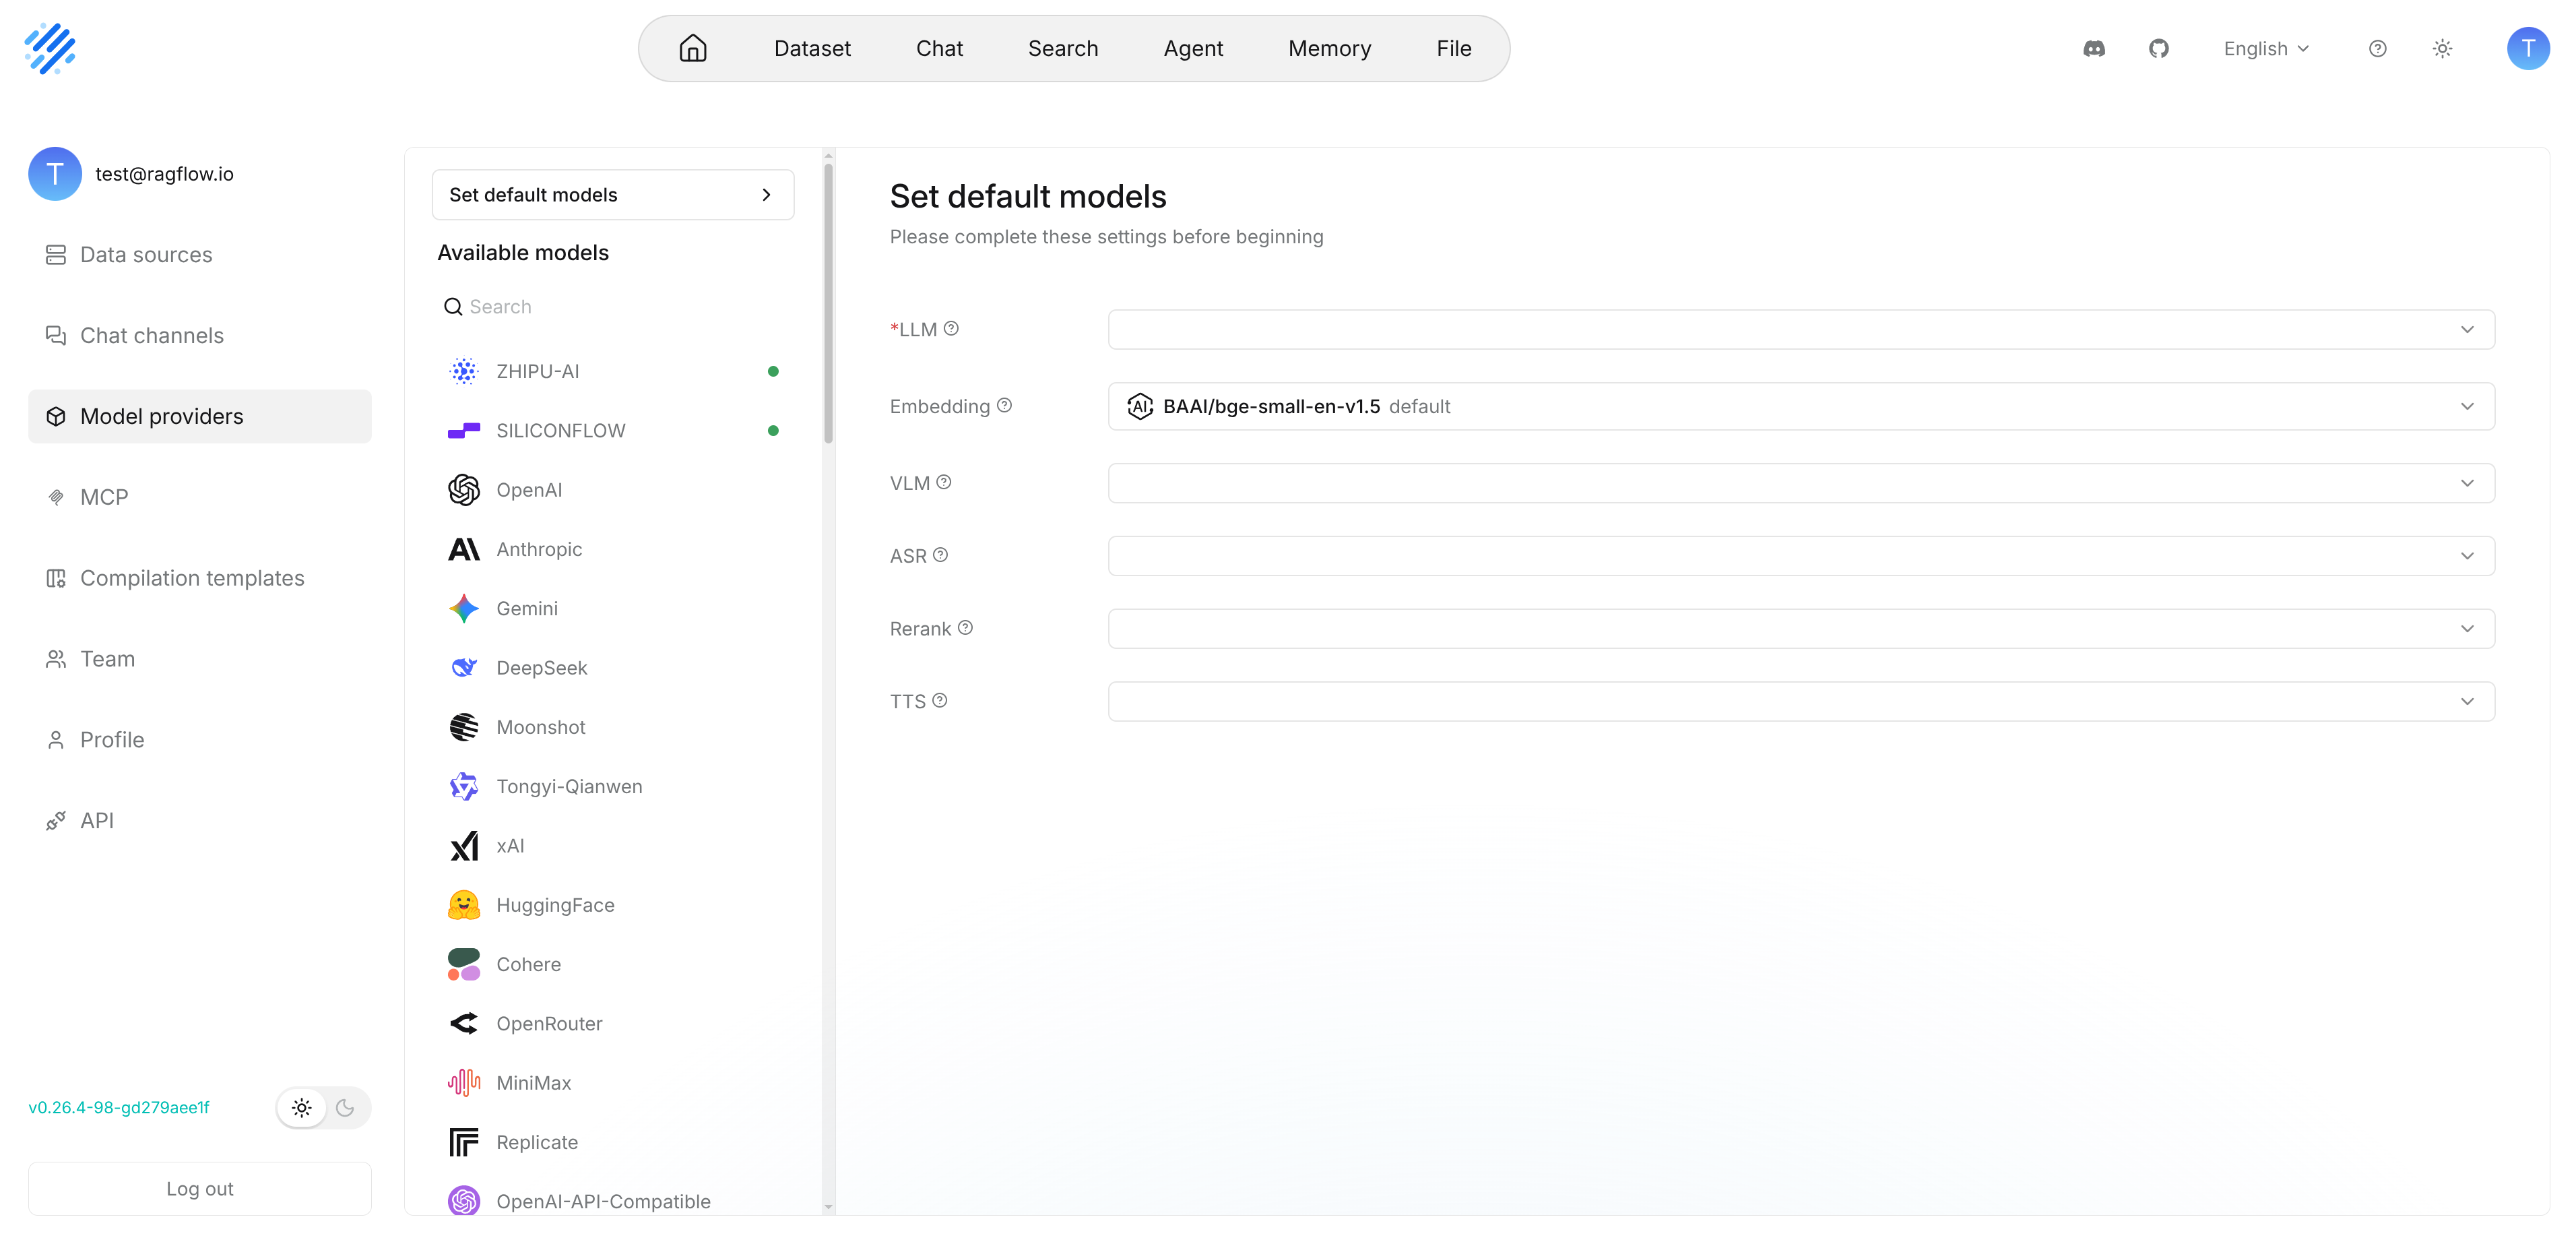-## Model types and usage+## Model Types and Usage| Model type | Full name | Main function | Input | Output | Typical scenarios || --- | --- | --- | --- | --- | --- |@@ -117,6 +119,6 @@ The following model types usually work together for retrieval and generation:3. **Moderation**: The moderation model is used to identify non-compliant, harmful, or sensitive content in text or images. It can review user input and model output to reduce the risk of generating or spreading non-compliant content.-## Supported model list+## Supported Model ListSee [Supported Models](./supported_models.mdx).diff --git a/docs/guides/models/supported_models.mdx b/docs/guides/models/supported_models.mdxindex 7515a89164..16a11e4408 100644--- a/docs/guides/models/supported_models.mdx+++ b/docs/guides/models/supported_models.mdx@@ -1,11 +1,13 @@---sidebar_position: 3+title: Model Providers+sidebar_label: Model Providersslug: /supported_modelssidebar_custom_props: {categoryIcon: LucideBox}----# Model providers+# Model Providersimport APITable from '@site/src/components/APITable';@@ -84,7 +86,7 @@ A complete list of model providers supported by RAGFlow, which will continue toIf your model is not listed here but has APIs compatible with those of OpenAI, click **OpenAI-API-Compatible** on the **Model providers** page to configure your model.:::-## Example: AI Badgr (OpenAI-compatible)+## Example: AI Badgr (OpenAI-Compatible)You can use **AI Badgr** with RAGFlow via the existing OpenAI-API-Compatible provider.diff --git a/docs/guides/team/permission_system_overview/_category_.json b/docs/guides/team/permission_system_overview/_category_.jsonindex 018811fa4c..55acc4ddaf 100644--- a/docs/guides/team/permission_system_overview/_category_.json+++ b/docs/guides/team/permission_system_overview/_category_.json@@ -1,5 +1,5 @@{- "label": "Permission system overview",+ "label": "Permission System Overview","position": 1,"link": {"type": "generated-index",diff --git a/docs/guides/team/permission_system_overview/index.md b/docs/guides/team/permission_system_overview/index.mdindex 3b6fb384a3..13fddf0a0a 100644--- a/docs/guides/team/permission_system_overview/index.md+++ b/docs/guides/team/permission_system_overview/index.md@@ -5,8 +5,9 @@ sidebar_custom_props: {categoryIcon: LucideUserCog}sidebar_label: Overview+title: Overview----# Permission system overview+# Permission System OverviewRAGFlow manages team collaboration and resource permissions through three layers: team membership, resource sharing scope, and resource operation permissions.diff --git a/docs/guides/team/permission_system_overview/permission_effective_rules.md b/docs/guides/team/permission_system_overview/permission_effective_rules.mdindex e03dcac6fc..0fa4c689bd 100644--- a/docs/guides/team/permission_system_overview/permission_effective_rules.md+++ b/docs/guides/team/permission_system_overview/permission_effective_rules.md@@ -1,9 +1,10 @@---sidebar_position: 5-sidebar_label: "Permission effective rules"+sidebar_label: Permission Effective Rules+title: Permission Effective Rules----## Permission effective rules+# Permission Effective RulesWhen a user performs an operation on a resource, RAGFlow evaluates permissions in the following order:@@ -13,6 +14,6 @@ When a user performs an operation on a resource, RAGFlow evaluates permissions i4. Whether the target document has additional document-level **Read**, **Write**, or **Manage** permission requirements.5. Whether the current operation is allowed by the permission table for that resource type.-The resource owner always has all permissions. If a resource is set to **Only me**, only the owner can access it. If a resource is set to **Team**, only team members who meet the permission conditions can access it. In RAGFlow Enterprise, the system also checks collaborator configuration for members, departments, and groups.+The resource owner always has all permissions. If a resource is set to **Only me**, only the owner can access it. If a resource is set to **Team**, only team members who meet the permission conditions can access it.If finer-grained permissions exist, such as document-level permissions in a knowledge base, those permissions continue to apply on top of resource access permission.diff --git a/docs/guides/team/permission_system_overview/resource_operation_permissions.md b/docs/guides/team/permission_system_overview/resource_operation_permissions.mdindex 850f1a500f..318a4a67f8 100644--- a/docs/guides/team/permission_system_overview/resource_operation_permissions.md+++ b/docs/guides/team/permission_system_overview/resource_operation_permissions.md@@ -1,9 +1,10 @@---sidebar_position: 4-sidebar_label: "Resource operation permissions"+sidebar_label: Resource Operation Permissions+title: Resource Operation Permissions----## Resource operation permissions+# Resource Operation PermissionsResource operation permissions define what a user can do after the resource becomes visible to the user.diff --git a/docs/guides/team/permission_system_overview/resource_sharing_scope.md b/docs/guides/team/permission_system_overview/resource_sharing_scope.mdindex 470b61d82a..fd130a1334 100644--- a/docs/guides/team/permission_system_overview/resource_sharing_scope.md+++ b/docs/guides/team/permission_system_overview/resource_sharing_scope.md@@ -1,12 +1,13 @@---sidebar_position: 3-sidebar_label: "Resource sharing scope"+sidebar_label: Resource Sharing Scope+title: Resource Sharing Scope----## Resource sharing scope+# Resource Sharing ScopeSharing scope controls the visible scope of a resource, that is, which users can access the current resource.-In the open-source edition, supported resources can usually be set to **Only me** or **Team**. In RAGFlow Enterprise, resources can be authorized more finely by adding collaborators such as members, departments, or groups.+In the open-source edition, supported resources can usually be set to **Only me** or **Team**.A resource set to **Team** is not necessarily visible to every user in every case. The system still checks whether the user belongs to the resource owner's team, whether the resource supports team sharing, and whether the user's operation is allowed by the corresponding permission rules.diff --git a/docs/guides/team/permission_system_overview/team_and_resource_permissions.md b/docs/guides/team/permission_system_overview/team_and_resource_permissions.mdindex 83105ec901..c8ffbd19b2 100644--- a/docs/guides/team/permission_system_overview/team_and_resource_permissions.md+++ b/docs/guides/team/permission_system_overview/team_and_resource_permissions.md@@ -1,9 +1,10 @@---sidebar_position: 2-sidebar_label: "Team and resource permissions"+sidebar_label: Team and Resource Permissions+title: Team and Resource Permissions----## Team and resource permissions+# Team and Resource PermissionsTeam membership and resource permissions are separate concepts.diff --git a/docs/guides/team/permission_system_overview/team_member_management.md b/docs/guides/team/permission_system_overview/team_member_management.mdindex 2747f61a1f..aef372f110 100644--- a/docs/guides/team/permission_system_overview/team_member_management.md+++ b/docs/guides/team/permission_system_overview/team_member_management.md@@ -1,9 +1,10 @@---sidebar_position: 1-sidebar_label: "Team member management"+sidebar_label: Team Member Management+title: Team Member Management----## Team member management+# Team Member ManagementEach user has a personal workspace. The team page of that workspace is displayed with the current user's nickname and **workspace** as its title.diff --git a/docs/guides/team/resource_operation_permission_rules/_category_.json b/docs/guides/team/resource_operation_permission_rules/_category_.jsondeleted file mode 100644index a84059c1ca..0000000000--- a/docs/guides/team/resource_operation_permission_rules/_category_.json+++ /dev/null@@ -1,11 +0,0 @@-{- "label": "Resource operation permission rules",- "position": 4,- "link": {- "type": "generated-index",- "description": "Resource operation permission rules."- },- "customProps": {- "categoryIcon": "LucideKeyRound"- }-}diff --git a/docs/guides/team/resource_operation_permission_rules/agent_permissions.md b/docs/guides/team/resource_operation_permission_rules/agent_permissions.mddeleted file mode 100644index d6b853c06e..0000000000--- a/docs/guides/team/resource_operation_permission_rules/agent_permissions.md+++ /dev/null@@ -1,39 +0,0 @@-----sidebar_position: 3-sidebar_label: "Agent permissions"------## Agent permissions--Agent settings include a sharing scope such as **Only me** or **Team**. Agent operation permissions determine whether the user can view, debug, run, update, or delete an Agent.--| Operation | No permission | Read | Write | Manage | Owner |-| --- | --- | --- | --- | --- | --- |-| Create Agent | Y | Y | Y | Y | Y |-| List visible Agents and return `operator_permission` | X | Y | Y | Y | Y |-| Get user-visible Agents and tags | X | Y | Y | Y | Y |-| View Agent details | X | Y | Y | Y | Y |-| Access session list | X | Y | Y | Y | Y |-| View a single session | X | Y | Y | Y | Y |-| View component form configuration | X | Y | Y | Y | Y |-| View version list | X | Y | Y | Y | Y |-| Read a single version | X | Y | Y | Y | Y |-| View `webhooktrace` | X | Y | Y | Y | Y |-| View component connection configuration file | X | Y | Y | Y | Y |-| Download Agent-related files | X | Y | Y | Y | Y |-| Get prompts | X | Y | Y | Y | Y |-| Create session | X | X | Y | Y | Y |-| Create a single session | X | X | Y | Y | Y |-| Batch delete sessions | X | X | Y | Y | Y |-| Upload Agent | X | X | Y | Y | Y |-| Component debugging | X | X | Y | Y | Y |-| Test database connection | X | X | Y | Y | Y |-| Read running logs | X | X | Y | Y | Y |-| Chat conversation entry | X | X | Y | Y | Y |-| Chat running entry | X | X | Y | Y | Y |-| Update Agent or DSL | X | X | Y | Y | Y |-| Update canvas tags | X | X | X | Y | Y |-| Delete Agent | X | X | X | X | Y |-| Dataflow or pipeline rerun | - | - | - | - | - |-| Webhook running entry | N/A | N/A | N/A | N/A | N/A |-| Webhook test entry | N/A | N/A | N/A | N/A | N/A |diff --git a/docs/guides/team/resource_operation_permission_rules/chat_application_permissions.md b/docs/guides/team/resource_operation_permission_rules/chat_application_permissions.mddeleted file mode 100644index 76a1f58a92..0000000000--- a/docs/guides/team/resource_operation_permission_rules/chat_application_permissions.md+++ /dev/null@@ -1,49 +0,0 @@-----sidebar_position: 2-sidebar_label: "Chat application permissions"------## Chat application permissions--Chat application permissions control viewing, configuration, creation, deletion, generation, and retrieval operations for chat assistants.--### Chat management--| Operation | No permission | Read | Write | Manage | Owner |-| --- | --- | --- | --- | --- | --- |-| Get chat list | X | Y | Y | Y | Y |-| Get chat details | X | Y | Y | Y | Y |-| Full update of chat configuration | X | X | X | Y | Y |-| Partial update of chat configuration | X | X | X | Y | Y |-| Create chat application configuration | X | X | X | X | Y |-| Batch delete chats through `ids`, `delete_all`, or request-body `chat_id` | X | X | X | X | Y |-| Delete a single chat | X | X | X | X | Y |--### Sessions and messages--| Operation | No permission | Read | Write | Manage | Owner |-| --- | --- | --- | --- | --- | --- |-| Create session | X | Y | Y | Y | Y |-| List sessions | X | Y | Y | Y | Y |-| Get a single session | X | Y | Y | Y | Y |-| Like, dislike, or submit feedback | X | Y | Y | Y | Y |-| Batch delete sessions | X | X | Y | Y | Y |-| Update session name or information | X | X | Y | Y | Y |-| Delete a message and its reply or reference | X | X | Y | Y | Y |--For read permission, session operations are limited to the user's own sessions. Write permission can cover all sessions. Batch deletion and message deletion with write permission are limited to the user's own sessions; manage permission and owner permission cover all sessions.--### Chat generation and retrieval--| Operation | No permission | Read | Write | Manage | Owner |-| --- | --- | --- | --- | --- | --- |-| TTS returns audio stream | X | Y | Y | Y | Y |-| Audio to text | X | Y | Y | Y | Y |-| Main chat completion API, including SSE and non-SSE | X | Y | Y | Y | Y |-| OpenAI-compatible chat completion | X | Y | Y | Y | Y |-| Shared chatbot conversation entry | X | Y | Y | Y | Y |-| Get recommended questions | X | Y | Y | Y | Y |-| Legacy completion API | X | Y | Y | Y | Y |-| Legacy recommended questions | X | Y | Y | Y | Y |--For the main chat completion API, read permission applies to the user's own sessions, while manage permission applies to all sessions.diff --git a/docs/guides/team/resource_operation_permission_rules/index.md b/docs/guides/team/resource_operation_permission_rules/index.mddeleted file mode 100644index ad5acfc1e0..0000000000--- a/docs/guides/team/resource_operation_permission_rules/index.md+++ /dev/null@@ -1,17 +0,0 @@-----sidebar_position: 4-slug: /resource_operation_permission_rules-sidebar_custom_props: {- categoryIcon: LucideKeyRound-}-sidebar_label: Overview-----# Resource operation permission rules--Resource operation permission rules define what users can do with shared resources.-------After a resource is shared, operation permissions determine whether a user can view, configure, use, or manage that resource. Different resource types use different operation tables. The resource owner always has the highest permission.--In the tables below, **Y** means the operation is allowed and **X** means the operation is not allowed.diff --git a/docs/guides/team/resource_operation_permission_rules/knowledge_base_operation_permissions.md b/docs/guides/team/resource_operation_permission_rules/knowledge_base_operation_permissions.mddeleted file mode 100644index 555c213078..0000000000--- a/docs/guides/team/resource_operation_permission_rules/knowledge_base_operation_permissions.md+++ /dev/null@@ -1,85 +0,0 @@-----sidebar_position: 1-sidebar_label: "Knowledge base operation permissions"------## Knowledge base operation permissions--Knowledge base permissions are determined jointly by knowledge base-level permissions and document-level permissions. Knowledge base permissions include **Read permission**, **Write permission**, and **Manage permission**. Documents in a knowledge base can also have no permission, read permission, write permission, or manage permission.--### File and file permission operations--The following operations require document read permission or higher. If the user has no permission on the target document, the operation is not allowed even when the user has knowledge base-level permission.--| Operation | No document permission | Document read | Document write | Document manage | Owner |-| --- | --- | --- | --- | --- | --- |-| View parsing logs | X | Y | Y | Y | Y |-| View file information | X | Y | Y | Y | Y |-| Download file | X | Y | Y | Y | Y |-| View chunk | X | Y | Y | Y | Y |-| View file configuration | X | Y | Y | Y | Y |-| View metadata | X | Y | Y | Y | Y |-| Preview document | X | Y | Y | Y | Y |--The following operations require document write permission or higher.--| Operation | No document permission | Document read | Document write | Document manage | Owner |-| --- | --- | --- | --- | --- | --- |-| Enable or disable file | X | X | Y | Y | Y |-| Edit metadata | X | X | Y | Y | Y |-| Batch update metadata | X | X | Y | Y | Y |-| Parse or cancel parsing | X | X | Y | Y | Y |-| Enable or disable chunk | X | X | Y | Y | Y |-| Add chunk | X | X | Y | Y | Y |-| Modify chunk | X | X | Y | Y | Y |-| Delete chunk | X | X | Y | Y | Y |--The following operations require document manage permission.--| Operation | No document permission | Document read | Document write | Document manage | Owner |-| --- | --- | --- | --- | --- | --- |-| Modify file configuration | X | X | X | Y | Y |-| Rename file | X | X | X | Y | Y |--### Knowledge base permission operations--The following knowledge base operations are available to users with knowledge base read permission or higher.--| Operation | No KB permission | KB read | KB write | KB manage | Owner |-| --- | --- | --- | --- | --- | --- |-| View knowledge graph | X | Y | Y | Y | Y |-| Duplicate | X | Y | Y | Y | Y |-| View dataset card | X | Y | Y | Y | Y |-| View metadata configuration | X | Y | Y | Y | Y |-| `trace_index` | X | Y | Y | Y | Y |-| Metadata aggregation | X | Y | Y | Y | Y |-| Knowledge base tag aggregation | X | Y | Y | Y | Y |-| View knowledge base parsing overview | X | Y | Y | Y | Y |-| View knowledge base tag | X | Y | Y | Y | Y |--The following knowledge base operations require knowledge base manage permission or owner permission.--| Operation | No KB permission | KB read | KB write | KB manage | Owner |-| --- | --- | --- | --- | --- | --- |-| Delete file | X | X | X | Y | Y |-| Add file | X | X | X | Y | Y |-| Generate RAPTOR | X | X | X | Y | Y |-| Generate index | X | X | X | Y | Y |-| Delete index | X | X | X | Y | Y |-| Generate knowledge graph | X | X | X | Y | Y |-| Delete knowledge graph | X | X | X | Y | Y |-| Re-embed | X | X | X | Y | Y |-| Delete knowledge base tag | X | X | X | Y | Y |-| Rename knowledge base tag | X | X | X | Y | Y |-| Modify knowledge base configuration | X | X | X | Y | Y |-| Delete knowledge base | X | X | X | Y | Y |--### Knowledge base permission judgment order--When a user performs a knowledge base or document operation, permissions are evaluated in the following order:--1. Whether the user has formally joined the team that owns the knowledge base.-2. Whether the knowledge base sharing scope allows team access.-3. Whether the user has knowledge base-level **Read**, **Write**, or **Manage** permission.-4. Whether the user has target document-level **Read**, **Write**, or **Manage** permission.-5. Whether the current operation is allowed by the permission table.diff --git a/docs/guides/team/resource_operation_permission_rules/mcp_permissions.md b/docs/guides/team/resource_operation_permission_rules/mcp_permissions.mddeleted file mode 100644index d63d6eb03f..0000000000--- a/docs/guides/team/resource_operation_permission_rules/mcp_permissions.md+++ /dev/null@@ -1,31 +0,0 @@-----sidebar_position: 4-sidebar_label: "MCP permissions"------## MCP permissions--MCP permission rules control MCP server creation, connection testing, listing, details, configuration, deletion, and export.--| Operation | No permission | Read | Write | Manage | Owner |-| --- | --- | --- | --- | --- | --- |-| Create MCP server | Y | Y | Y | Y | Y |-| Test MCP connection | Y | Y | Y | Y | Y |-| Batch import MCP server | Y | Y | Y | Y | Y |-| List visible MCP servers | X | Y | Y | Y | Y |-| View MCP details | X | Y | Y | Y | Y |-| Update MCP configuration | X | X | Y | Y | Y |-| Delete MCP server | X | X | X | X | Y |-| Export or download MCP configuration | X | X | X | X | Y |--Creating an MCP server creates a new resource and does not require an existing MCP permission. The owner permission is created after the resource is created.--Testing MCP connection is currently not strictly restricted by existing permission checks in the backend. If this behavior changes, a permission check should be added at the point where MCP permissions can be changed.--Batch import creates resources and does not use `operator_permission` from an existing MCP server.--Listing visible MCP servers returns visible results, including `operator_permission`. If an MCP server is visible, its details can be read.--Updating MCP configuration includes updating URL, headers, variables, and tools. Manage permission is recommended for this operation.--Deleting an MCP server is recommended to be owner-only. Exporting or downloading MCP configuration is also recommended to be owner-only because the configuration may contain sensitive values such as `authorization_token`.diff --git a/docs/guides/team/resource_operation_permission_rules/memory_permissions.md b/docs/guides/team/resource_operation_permission_rules/memory_permissions.mddeleted file mode 100644index a33e093e06..0000000000--- a/docs/guides/team/resource_operation_permission_rules/memory_permissions.md+++ /dev/null@@ -1,34 +0,0 @@-----sidebar_position: 5-sidebar_label: "Memory permissions"------## Memory permissions--Memory settings include a sharing scope. Memory permissions cover memory configuration, memory messages, SDK-related message access, and message status operations.--### Memory operations--| Resource | Operation | No permission | Read | Write | Manage | Owner |-| --- | --- | --- | --- | --- | --- | --- |-| MEMORY | Create memory | Y | Y | Y | Y | Y |-| MEMORY | List memory | X | Y | Y | Y | Y |-| MEMORY | View memory configuration | X | Y | Y | Y | Y |-| MEMORY | View memory message list | X | Y | Y | Y | Y |-| MEMORY | Modify memory basic configuration | X | X | X | Y | Y |-| MEMORY | Delete memory | X | X | X | X | Y |--Creating a memory creates a new resource. The frontend creation entry is on the memories list page. Listing memories returns accessible memories, including private and shared memories. Modifying memory basic configuration includes fields such as name, model, and prompts.--### Message operations--| Resource | Operation | No permission | Read | Write | Manage | Owner |-| --- | --- | --- | --- | --- | --- | --- |-| MESSAGE | Search messages | X | Y | Y | Y | Y |-| MESSAGE | Get a specified message | X | Y | Y | Y | Y |-| MESSAGE | View message content | X | Y | Y | Y | Y |-| MESSAGE | Add message to memory | X | X | Y | Y | Y |-| MESSAGE | Delete a single message | X | X | Y | Y | Y |-| MESSAGE | Update a single message status | X | X | Y | Y | Y |--Message search can be performed by memory, Agent, or session. Getting specified messages applies to memory messages and SDK availability. Adding a message to memory has no direct frontend button and is mainly used by the backend SDK.diff --git a/docs/guides/team/resource_operation_permission_rules/model_permissions.md b/docs/guides/team/resource_operation_permission_rules/model_permissions.mddeleted file mode 100644index de3f40e006..0000000000--- a/docs/guides/team/resource_operation_permission_rules/model_permissions.md+++ /dev/null@@ -1,34 +0,0 @@-----sidebar_position: 7-sidebar_label: "Model permissions"------## Model permissions--Model permissions use provider-level and owner-level checks. The table below uses **No permission**, **Read permission**, and **Owner** columns.--| Operation | No permission | Read permission | Owner |-| --- | --- | --- | --- |-| List providers | X | Y | Y |-| Add provider | X | Y | Y |-| Delete provider | X | X | Y |-| View models under a provider | X | X | Y |-| View a single model | X | X | Y |-| Create instance | X | X | Y |-| Verify connection or API key | X | X | Y |-| List instances | X | X | Y |-| View a single instance | X | X | Y |-| Get models under an instance | X | X | Y |-| Create instance model scope | X | X | Y |-| Delete instance model scope | X | X | Y |-| View model support status | X | X | Y |-| Create model support status | X | X | Y |-| Delete model support status | X | X | Y |-| Batch delete instances | X | X | Y |-| View system default model | X | X | Y |-| View current user's default model | X | X | Y |-| Set or get default model | X | X | Y |--Listing providers lists the current user's own providers and system providers. Adding a provider follows the permission matrix. Deleting a provider is not related to ordinary read permissions.--Viewing the system default model must determine whether the default model belongs to the current user. Viewing the current user's default model must determine whether the model is the user's own default value. Setting or getting the default model follows the initial permission design.diff --git a/docs/guides/team/resource_operation_permission_rules/permission_effective_rules.md b/docs/guides/team/resource_operation_permission_rules/permission_effective_rules.mddeleted file mode 100644index 9d117a722c..0000000000--- a/docs/guides/team/resource_operation_permission_rules/permission_effective_rules.md+++ /dev/null@@ -1,14 +0,0 @@-----sidebar_position: 8-sidebar_label: "Permission effective rules"------## Permission effective rules--Resource permissions take effect according to the following general rules:--- The resource owner always has all permissions.-- If the sharing scope is **Only me**, only the owner can access the resource.-- If the sharing scope is **Team**, only team members who meet the permission conditions can access the resource.-- In RAGFlow Enterprise, the system checks collaborator configuration for **Member**, **Department**, and **Group** collaborators.-- If finer-grained permissions exist, such as document-level permissions in a knowledge base, those permissions continue to apply on top of resource access permission.diff --git a/docs/guides/team/resource_operation_permission_rules/search_permissions.md b/docs/guides/team/resource_operation_permission_rules/search_permissions.mddeleted file mode 100644index 87ee3ae963..0000000000--- a/docs/guides/team/resource_operation_permission_rules/search_permissions.md+++ /dev/null@@ -1,25 +0,0 @@-----sidebar_position: 6-sidebar_label: "Search permissions"------## Search permissions--Search permissions control creating Search applications, listing and viewing Search applications, Q&A, related questions, mind map generation, editing, and deletion.--| Operation | No permission | Read | Write | Manage | Owner |-| --- | --- | --- | --- | --- | --- |-| Create Search | Y | Y | Y | Y | Y |-| Search list | X | Y | Y | Y | Y |-| Search details | X | Y | Y | Y | Y |-| Search Q&A | X | X | Y | Y | Y |-| Get related questions | X | X | Y | Y | Y |-| Generate mind map | X | X | Y | Y | Y |-| Edit Search | X | X | X | Y | Y |-| Delete Search | X | X | X | X | Y |--Creating Search creates a new resource and creates the owner record afterward. The Search list currently relies on the ENABLE role check and is not fully connected to ACL sharing. Search details are currently connected only by ID; changing this to a READ operation is recommended.--For Search Q&A, related questions, and mind map generation, effective use recommends a READ operation check rather than only checking whether the resource can be created.--Editing Search includes adjusting knowledge base configuration and should require manage permission. Deleting Search is recommended to be owner-only, and current behavior is generally consistent with `created_by`.diff --git a/docs/guides/team/sharing_scope_configuration/_category_.json b/docs/guides/team/sharing_scope_configuration/_category_.jsonindex 87bfaf24b2..414bdaf510 100644--- a/docs/guides/team/sharing_scope_configuration/_category_.json+++ b/docs/guides/team/sharing_scope_configuration/_category_.json@@ -1,5 +1,5 @@{- "label": "Sharing scope configuration",+ "label": "Sharing Scope Configuration","position": 3,"link": {"type": "generated-index",diff --git a/docs/guides/team/sharing_scope_configuration/collaborator_permission_configuration.md b/docs/guides/team/sharing_scope_configuration/collaborator_permission_configuration.mddeleted file mode 100644index ef6666717e..0000000000--- a/docs/guides/team/sharing_scope_configuration/collaborator_permission_configuration.md+++ /dev/null@@ -1,24 +0,0 @@-----sidebar_position: 3-sidebar_label: "Collaborator permission configuration"------## Collaborator permission configuration--In RAGFlow Enterprise, you can configure permissions separately for different collaborator objects, including **Member**, **Department**, and **Group**. Each collaborator can have an independent permission level.--To configure collaborator permissions:--1. Open the resource's **Permission Management** page.-2. Click **Add**.-3. Add a member, department, or group as a collaborator.-4. In the collaborator's **Permission** field, select the required permission level.-5. Save the configuration. The permission takes effect immediately.--| Permission | Description |-| --- | --- |-| Read permission | Allows users to view and use the resource, but does not allow them to modify resource content or configuration. |-| Write permission | Allows users to edit resource content, such as adding, modifying, or deleting content in the resource, but does not allow them to modify resource permissions or management configuration. |-| Manage permission | Grants resource management permissions. Users can manage resource configuration, collaborator permissions, and other management operations. |--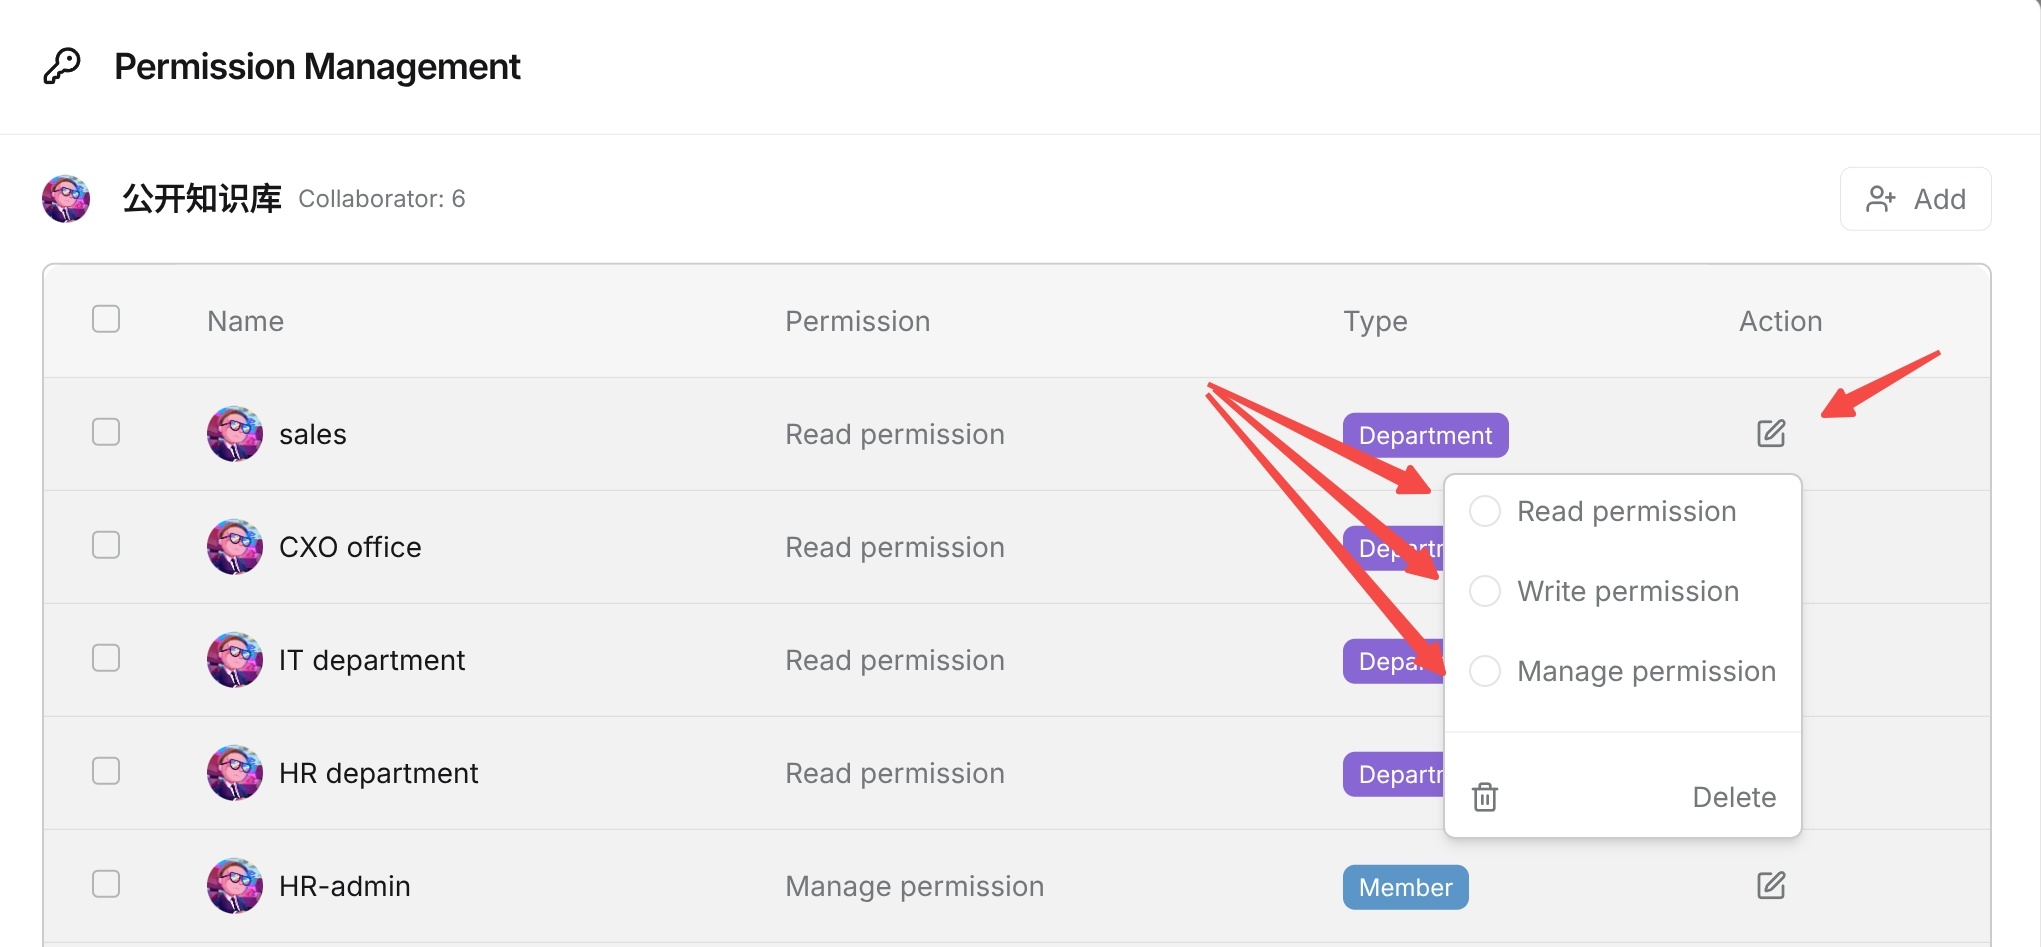diff --git a/docs/guides/team/sharing_scope_configuration/document_level_permissions_enterprise_edition.md b/docs/guides/team/sharing_scope_configuration/document_level_permissions_enterprise_edition.mddeleted file mode 100644index 9d7e4886a2..0000000000--- a/docs/guides/team/sharing_scope_configuration/document_level_permissions_enterprise_edition.md+++ /dev/null@@ -1,35 +0,0 @@-----sidebar_position: 4-sidebar_label: "Document-level permissions (Enterprise edition)"------## Document-level permissions (Enterprise edition)--Document-level permissions refine knowledge base permissions. The knowledge base owner can configure different collaborator permissions for different documents in the same knowledge base.--For example, the same team member may have read permission on a knowledge base but no permission on a specific document in it. The same member may also have write permission on a specific document, allowing operations such as enabling or disabling that document.--### Configure operations--In the **Files** list of a knowledge base, each document row provides a key icon in the **Action** column. Click the key icon to open the document's **Permission Management** dialog.--Use this dialog to configure collaborator permissions for the selected document.--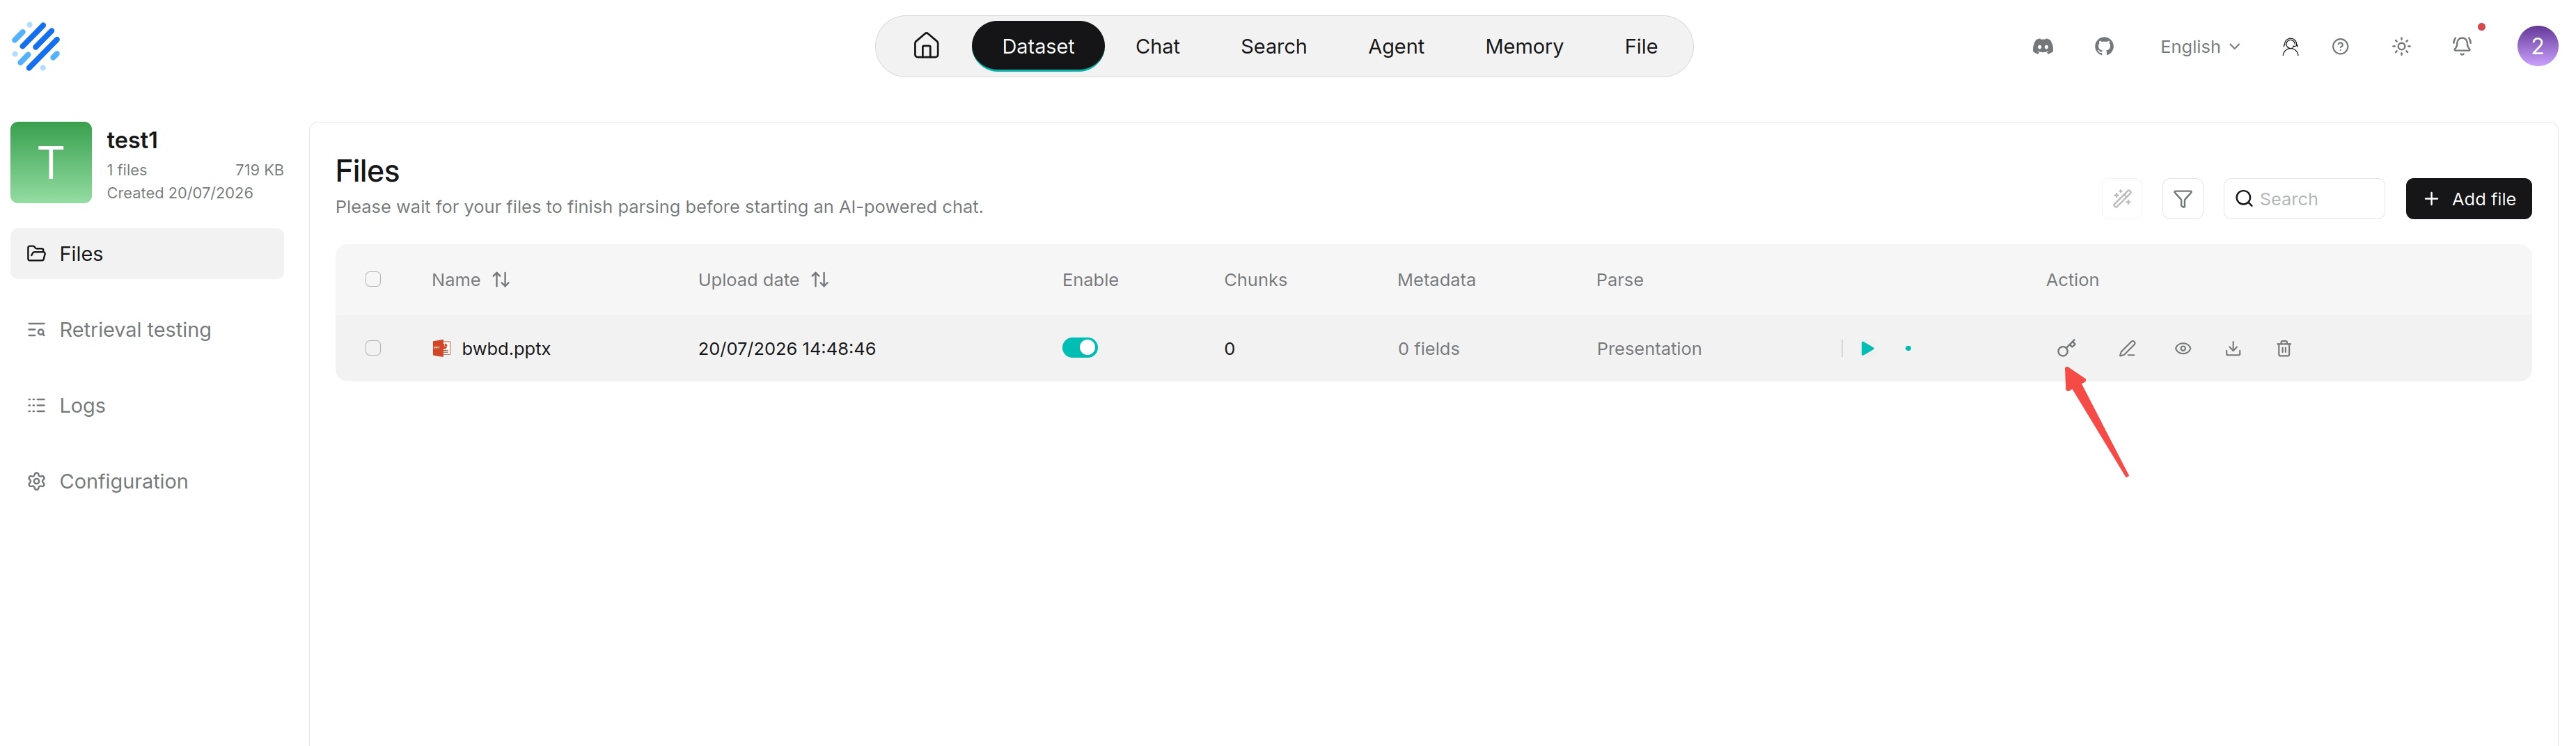--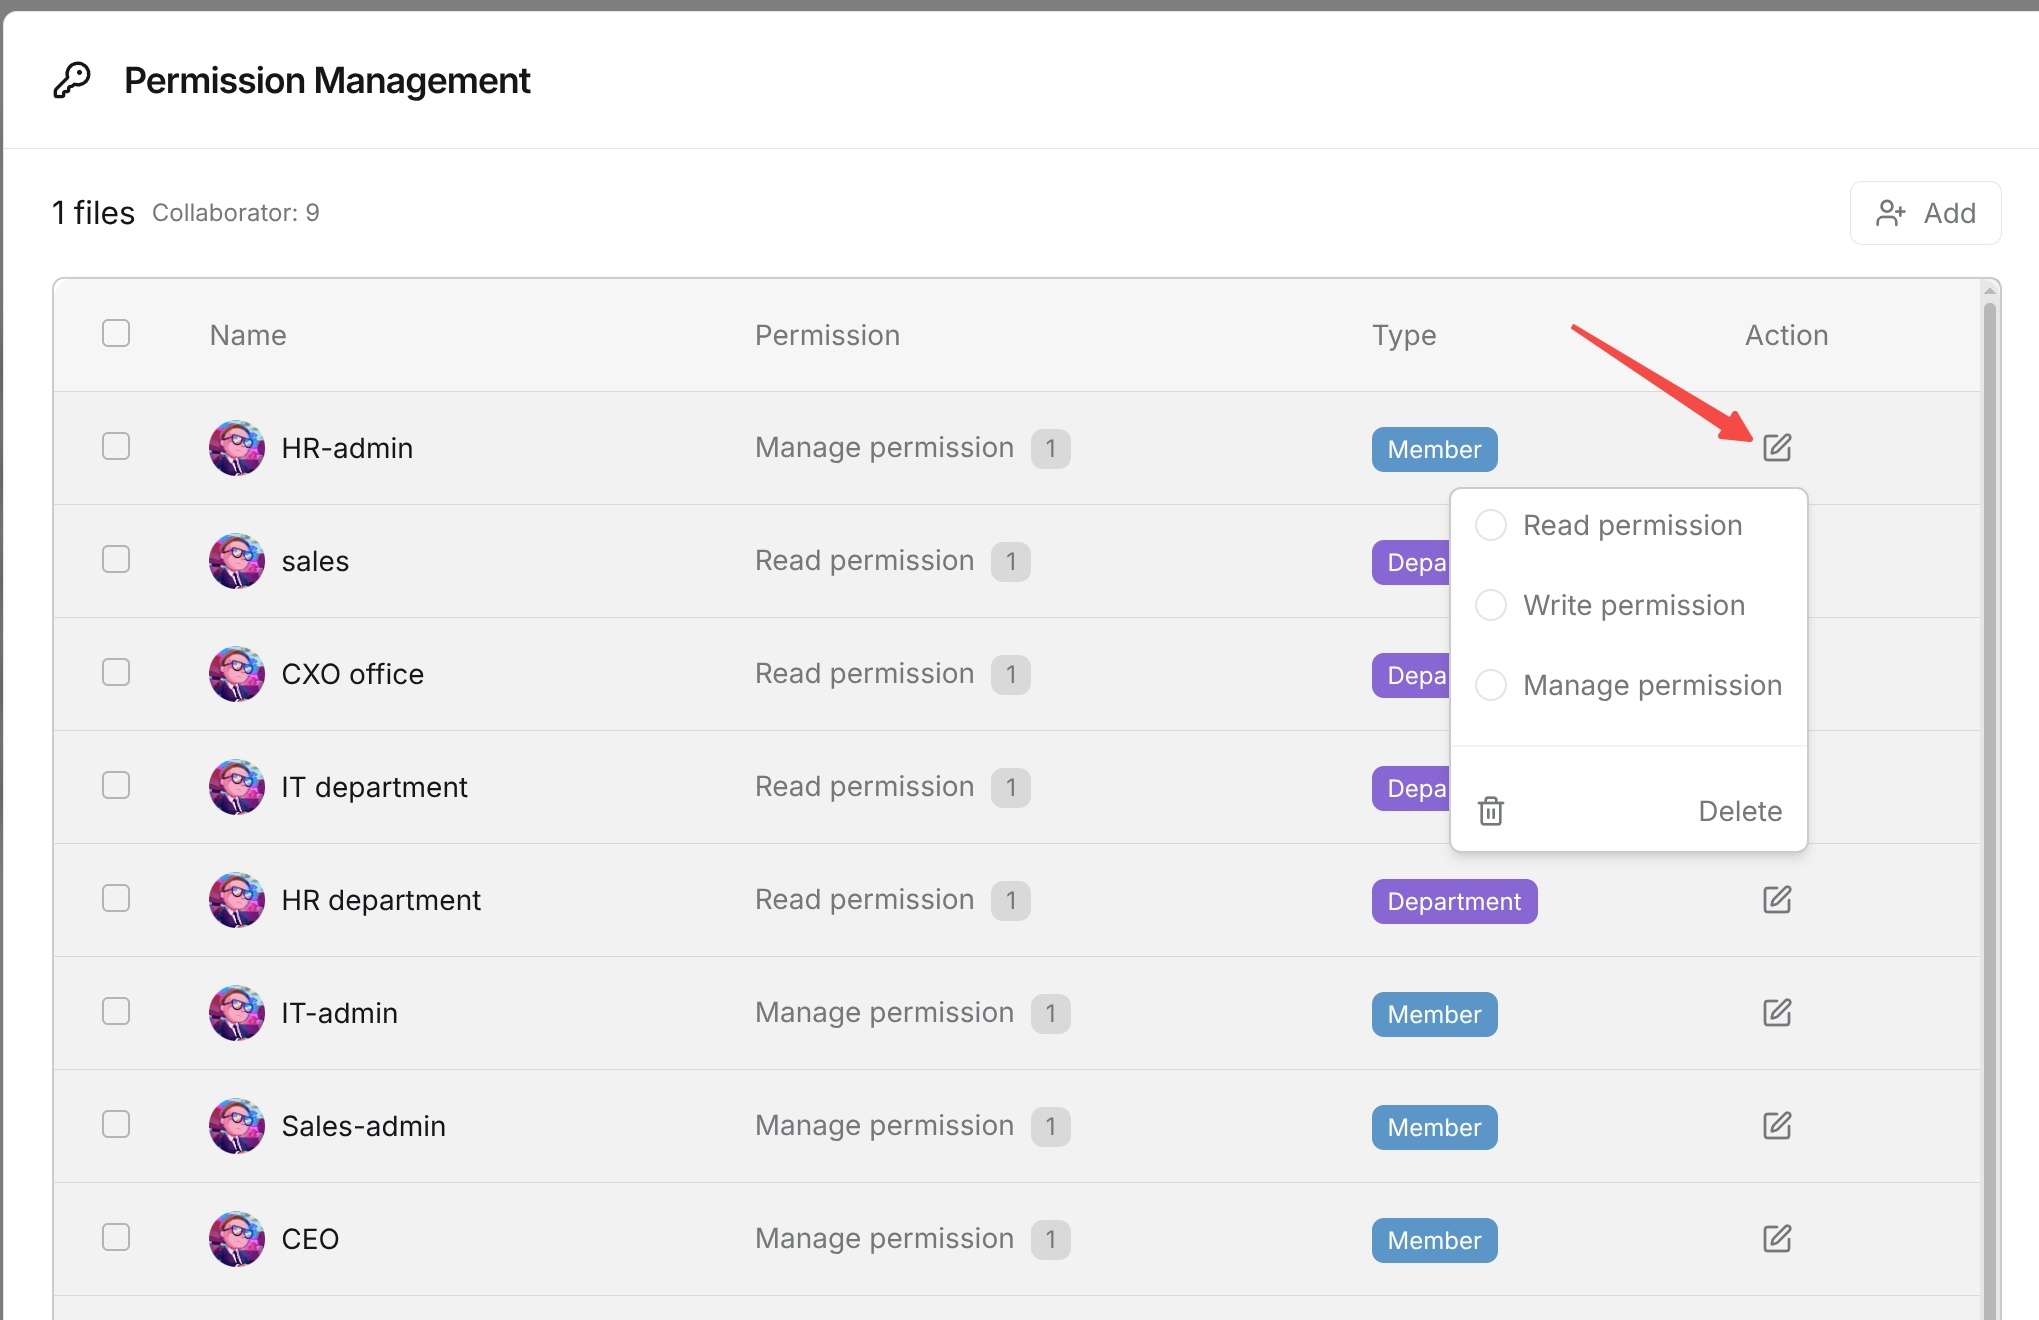---### Document permission levels--Document-level permission management also uses **Read permission**, **Write permission**, and **Manage permission**.--| Permission | Description |-| --- | --- |-| Read permission | Allows read-only operations such as viewing document information, previewing documents, downloading documents, viewing chunks, and viewing parsing logs. |-| Write permission | Allows document status change operations, such as enabling or disabling documents. |-| Manage permission | Allows higher-level document management actions and covers operations within the read and write permission scopes. |--Resource owners have the highest permission on documents.--If a document has not finished parsing or is being parsed, buttons in the **Action** column may be disabled. In this case, even if the user has the required permission, they must wait until parsing is complete before performing the corresponding operation.diff --git a/docs/guides/team/sharing_scope_configuration/enterprise_edition_sharing_scope_configuration.md b/docs/guides/team/sharing_scope_configuration/enterprise_edition_sharing_scope_configuration.mddeleted file mode 100644index 99b9e961a9..0000000000--- a/docs/guides/team/sharing_scope_configuration/enterprise_edition_sharing_scope_configuration.md+++ /dev/null@@ -1,26 +0,0 @@-----sidebar_position: 2-sidebar_label: "Enterprise edition sharing scope configuration"------## Enterprise edition sharing scope configuration--RAGFlow Enterprise supports finer-grained team permission management and team permission control. After a resource is set to **Team**, it does not automatically authorize all team members to access the resource.--Administrators can add collaborators to a resource and grant permissions to **Member**, **Department**, or **Group** collaborators. Only authorized users can access the resource.--Departments and groups are created by administrators based on the enterprise's actual organization structure. Their names and hierarchy may vary between enterprises.--Collaborators can be one of the following object types:--| Type | Description |-| --- | --- |-| Member | Specifies an individual team member. |-| Department | Specifies a department. Members in the department can inherit the corresponding permissions. |-| Group | Specifies a user group. Members in the group can inherit the corresponding permissions. |--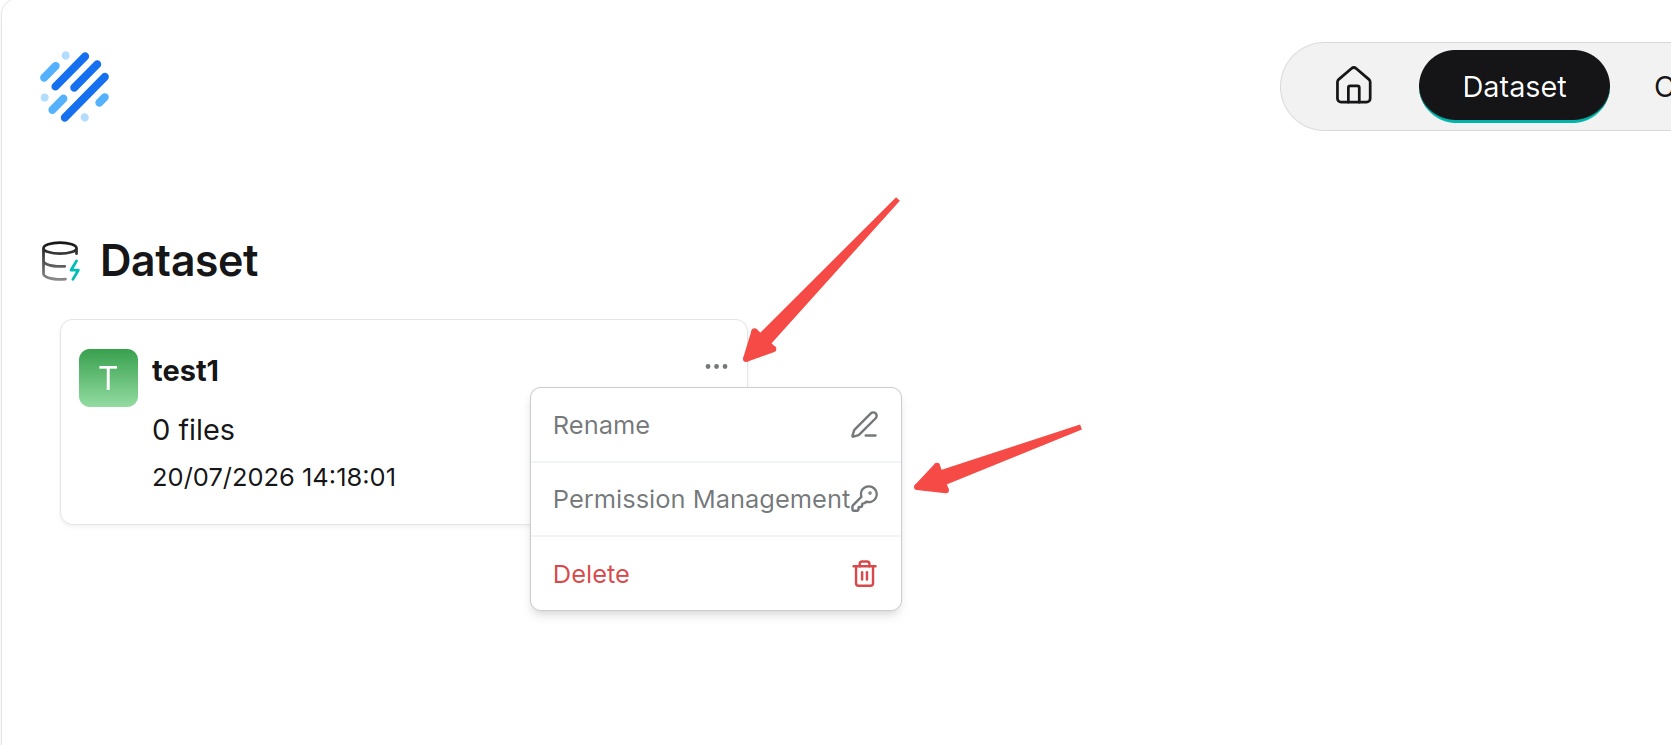--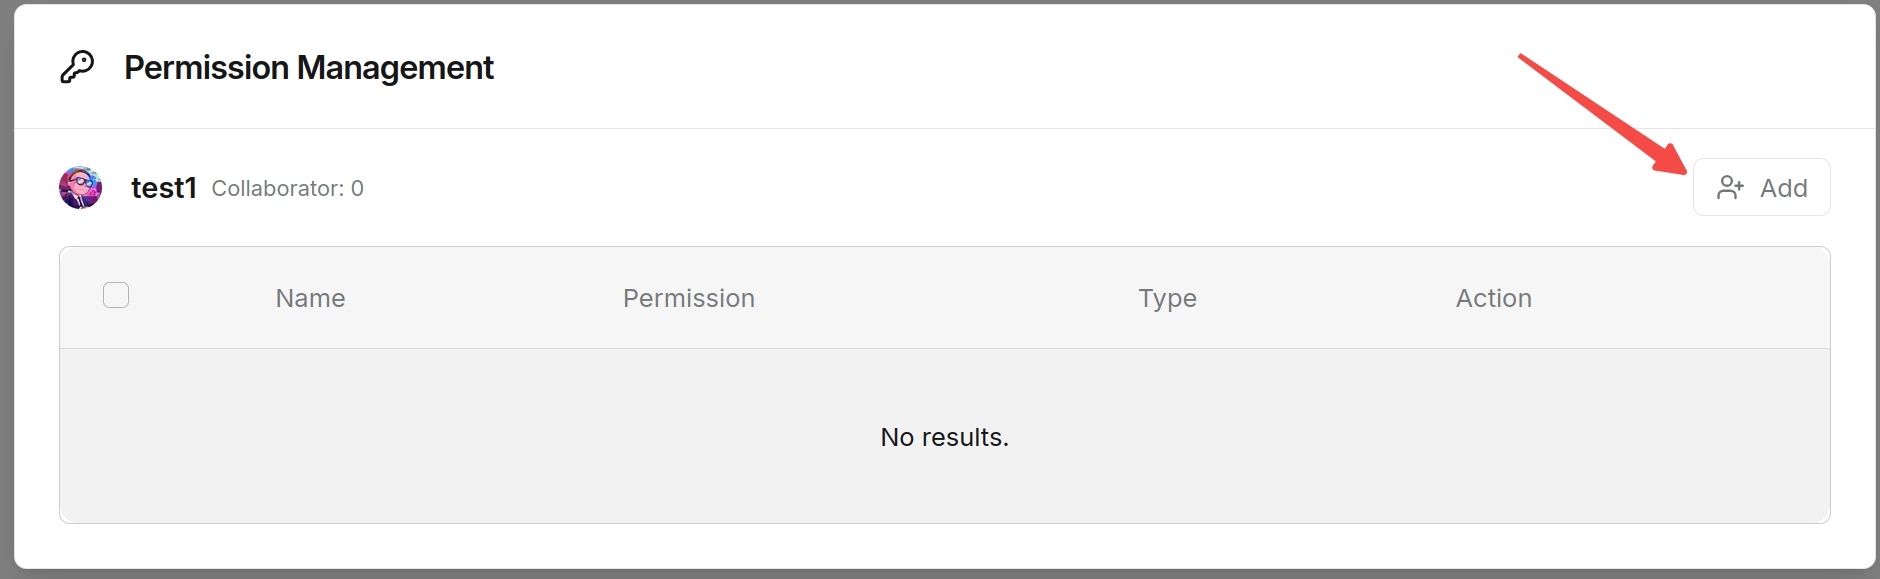--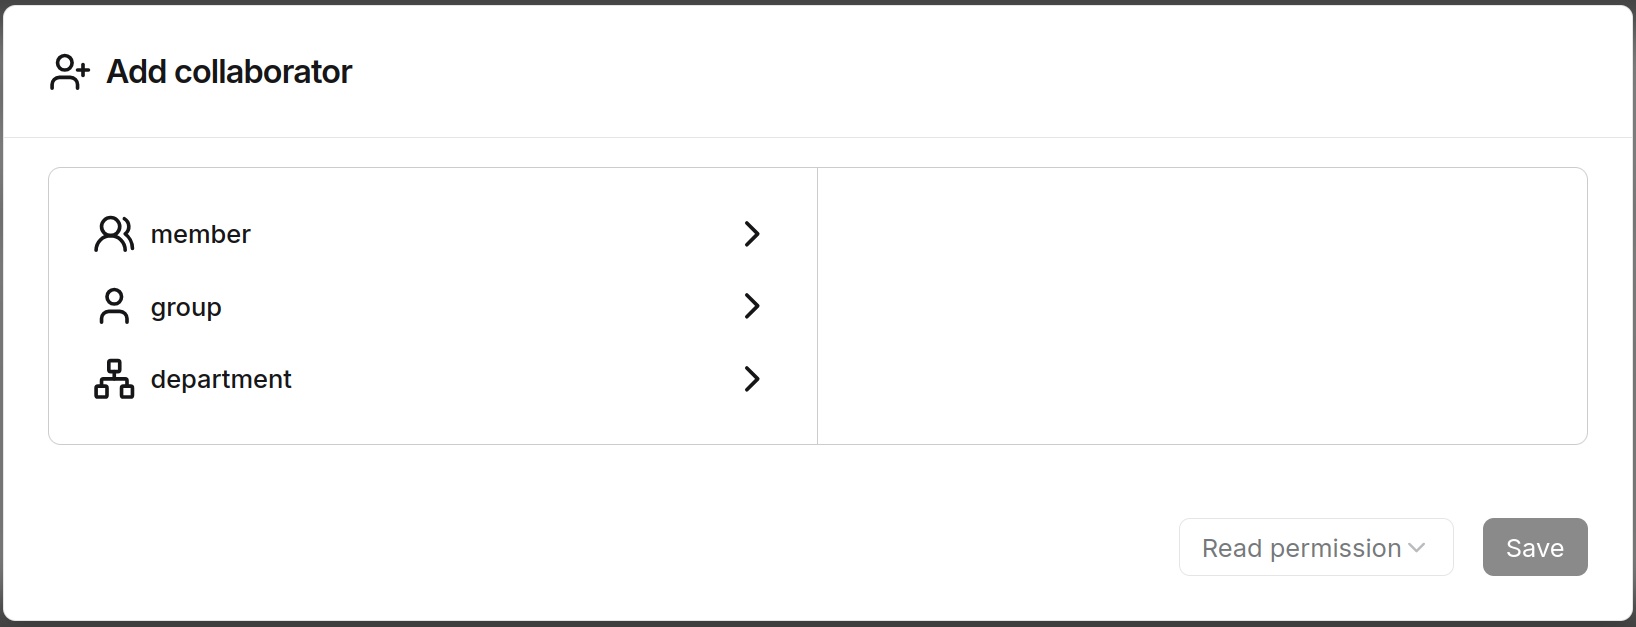diff --git a/docs/guides/team/sharing_scope_configuration/index.md b/docs/guides/team/sharing_scope_configuration/index.mdindex 3576a10eb9..9fef108fcf 100644--- a/docs/guides/team/sharing_scope_configuration/index.md+++ b/docs/guides/team/sharing_scope_configuration/index.md@@ -5,8 +5,9 @@ sidebar_custom_props: {categoryIcon: LucideShare2}sidebar_label: Overview+title: Overview----# Sharing scope configuration+# Sharing Scope ConfigurationConfigure the visible scope of resources in RAGFlow.diff --git a/docs/guides/team/sharing_scope_configuration/open_source_edition_sharing_scope_configuration.md b/docs/guides/team/sharing_scope_configuration/open_source_edition_sharing_scope_configuration.mdindex 1b569dc13d..2a92402bdf 100644--- a/docs/guides/team/sharing_scope_configuration/open_source_edition_sharing_scope_configuration.md+++ b/docs/guides/team/sharing_scope_configuration/open_source_edition_sharing_scope_configuration.md@@ -1,9 +1,10 @@---sidebar_position: 1-sidebar_label: "Open-source edition sharing scope configuration"+sidebar_label: Open-Source Edition Sharing Scope Configuration+title: Open-Source Edition Sharing Scope Configuration----## Open-source edition sharing scope configuration+# Open-Source Edition Sharing Scope ConfigurationIn the open-source edition, the sharing scope is configured through the **Permissions** field on the resource configuration page. Select one of the following options based on your business needs:diff --git a/docs/guides/team/sharing_scope_configuration/share_agents.md b/docs/guides/team/sharing_scope_configuration/share_agents.mdindex ac826ac52f..44a18f5c97 100644--- a/docs/guides/team/sharing_scope_configuration/share_agents.md+++ b/docs/guides/team/sharing_scope_configuration/share_agents.md@@ -1,9 +1,10 @@---sidebar_position: 7-sidebar_label: "Share Agents"+sidebar_label: Share Agents+title: Share Agents----## Share Agents+# Share AgentsTo share an Agent:diff --git a/docs/guides/team/sharing_scope_configuration/share_chat_assistants.md b/docs/guides/team/sharing_scope_configuration/share_chat_assistants.mddeleted file mode 100644index 7a77e0698c..0000000000--- a/docs/guides/team/sharing_scope_configuration/share_chat_assistants.md+++ /dev/null@@ -1,8 +0,0 @@-----sidebar_position: 6-sidebar_label: "Share chat assistants"------## Share chat assistants--Sharing chat assistants is currently exclusive to RAGFlow Enterprise.diff --git a/docs/guides/team/sharing_scope_configuration/share_knowledge_bases.md b/docs/guides/team/sharing_scope_configuration/share_knowledge_bases.mdindex 1363dd8b2a..d232f090a6 100644--- a/docs/guides/team/sharing_scope_configuration/share_knowledge_bases.md+++ b/docs/guides/team/sharing_scope_configuration/share_knowledge_bases.md@@ -1,9 +1,10 @@---sidebar_position: 5-sidebar_label: "Share knowledge bases"+sidebar_label: Share Knowledge Bases+title: Share Knowledge Bases----## Share knowledge bases+# Share Knowledge BasesShare a knowledge base by changing its **Permissions** from **Only me** to **Team**.diff --git a/docs/guides/team/sharing_scope_configuration/share_memories.md b/docs/guides/team/sharing_scope_configuration/share_memories.mdindex 12a49b34b9..f38a7eb72a 100644--- a/docs/guides/team/sharing_scope_configuration/share_memories.md+++ b/docs/guides/team/sharing_scope_configuration/share_memories.md@@ -1,9 +1,10 @@---sidebar_position: 9-sidebar_label: "Share memories"+sidebar_label: Share Memories+title: Share Memories----## Share memories+# Share MemoriesTo share a memory:diff --git a/docs/guides/team/sharing_scope_configuration/share_models.md b/docs/guides/team/sharing_scope_configuration/share_models.mddeleted file mode 100644index 6eff998d77..0000000000--- a/docs/guides/team/sharing_scope_configuration/share_models.md+++ /dev/null@@ -1,8 +0,0 @@-----sidebar_position: 8-sidebar_label: "Share models"------## Share models--Sharing models is currently exclusive to RAGFlow Enterprise.diff --git a/docs/guides/team/team_management/_category_.json b/docs/guides/team/team_management/_category_.jsonindex 5f29151b87..158039c9fa 100644--- a/docs/guides/team/team_management/_category_.json+++ b/docs/guides/team/team_management/_category_.json@@ -1,5 +1,5 @@{- "label": "Team management",+ "label": "Team Management","position": 2,"link": {"type": "generated-index",diff --git a/docs/guides/team/team_management/accept_or_decline_an_invitation.md b/docs/guides/team/team_management/accept_or_decline_an_invitation.mdindex ac0eabad93..5f06aba2f1 100644--- a/docs/guides/team/team_management/accept_or_decline_an_invitation.md+++ b/docs/guides/team/team_management/accept_or_decline_an_invitation.md@@ -1,9 +1,10 @@---sidebar_position: 6-sidebar_label: "Accept or decline an invitation"+sidebar_label: Accept or Decline an Invitation+title: Accept or Decline an Invitation----## Accept or decline an invitation+# Accept or Decline an InvitationWhen another team owner invites you to join a team, you can process the invitation on the **Team** page.diff --git a/docs/guides/team/team_management/enter_the_team_page.md b/docs/guides/team/team_management/enter_the_team_page.mdindex fc0b510c6b..acdc65ad7a 100644--- a/docs/guides/team/team_management/enter_the_team_page.md+++ b/docs/guides/team/team_management/enter_the_team_page.md@@ -1,9 +1,10 @@---sidebar_position: 1-sidebar_label: "Enter the Team page"+sidebar_label: Enter the Team Page+title: Enter the Team Page----## Enter the Team page+# Enter the Team PageClick your avatar in the upper-right corner of the page, then select **Team** in the left-side panel to access the **Team** page.diff --git a/docs/guides/team/team_management/enterprise_role_permissions.md b/docs/guides/team/team_management/enterprise_role_permissions.mddeleted file mode 100644index a530e00097..0000000000--- a/docs/guides/team/team_management/enterprise_role_permissions.md+++ /dev/null@@ -1,12 +0,0 @@-----sidebar_position: 10-sidebar_label: "Enterprise role permissions"------## Enterprise role permissions--Enterprise role permissions are separate from the team page.--The Enterprise role page supports listing roles, creating roles, editing role descriptions, deleting roles, and configuring available actions by resource type. The fixed action types include **enable**, **read**, **write**, and **share**.--Enterprise roles are different from team roles such as `owner`, `invite`, and `normal`.diff --git a/docs/guides/team/team_management/faq.md b/docs/guides/team/team_management/faq.mdindex 8d367bf3e4..4bf5504c9a 100644--- a/docs/guides/team/team_management/faq.md+++ b/docs/guides/team/team_management/faq.md@@ -1,11 +1,12 @@---sidebar_position: 11-sidebar_label: "FAQ"+sidebar_label: FAQ+title: FAQ----## FAQ+# FAQ-### Why does inviting a member fail?+### Why Does Inviting a Member Fail?Common causes include:@@ -14,18 +15,18 @@ Common causes include:- The user has already been invited.- The current user is not the team owner.-### Why can't an invited user see team resources?+### Why Can't an Invited User See Team Resources?The invited user must first click **Agree** to join the team. The target resource must also be set to **Team** or otherwise authorized to the user.-### Why can a team member only see some knowledge bases after joining a team?+### Why Can a Team Member Only See Some Knowledge Bases After Joining a Team?Only knowledge bases whose permissions allow team access are visible to joined team members.-### Why can't a team member delete a shared knowledge base?+### Why Can't a Team Member Delete a Shared Knowledge Base?Deleting a shared knowledge base generally requires the current user to be the creator of the knowledge base. Team sharing grants access and use permissions, but it does not automatically grant delete permission.-### Are Team roles the same as Enterprise roles?+### Are Team Roles the Same as Enterprise Roles?No. Team roles describe membership in a workspace. Enterprise roles describe administrative resource action permissions.diff --git a/docs/guides/team/team_management/index.md b/docs/guides/team/team_management/index.mdindex 3bae393f4e..e3c8461698 100644--- a/docs/guides/team/team_management/index.md+++ b/docs/guides/team/team_management/index.md@@ -5,10 +5,11 @@ sidebar_custom_props: {categoryIcon: LucideLogOut}sidebar_label: Overview+title: Overview----# Team management+# Team Management-Manage team members, team invitations, joined teams, departments, and groups.+Manage team members, team invitations, and joined teams.---@@ -20,5 +21,4 @@ By default, each RAGFlow user is assigned a single team named after the user's n:::tip NOTE- Team members cannot invite users to your team. Only the team owner can invite users or remove members.-- Sharing added models with team members is only available in RAGFlow Enterprise.:::diff --git a/docs/guides/team/team_management/invite_members.md b/docs/guides/team/team_management/invite_members.mdindex 8a38150264..afc65f9867 100644--- a/docs/guides/team/team_management/invite_members.md+++ b/docs/guides/team/team_management/invite_members.md@@ -1,9 +1,10 @@---sidebar_position: 3-sidebar_label: "Invite members"+sidebar_label: Invite Members+title: Invite Members----## Invite members+# Invite MembersThe team owner can invite RAGFlow users to join the team.diff --git a/docs/guides/team/team_management/leave_a_joined_team.md b/docs/guides/team/team_management/leave_a_joined_team.mdindex 1eca083303..46effb991c 100644--- a/docs/guides/team/team_management/leave_a_joined_team.md+++ b/docs/guides/team/team_management/leave_a_joined_team.md@@ -1,9 +1,10 @@---sidebar_position: 7-sidebar_label: "Leave a joined team"+sidebar_label: Leave a Joined Team+title: Leave a Joined Team----## Leave a joined team+# Leave a Joined TeamA user with the `normal` role can leave a joined team if the team is not the user's own workspace.diff --git a/docs/guides/team/team_management/manage_departments.md b/docs/guides/team/team_management/manage_departments.mddeleted file mode 100644index 1055476c67..0000000000--- a/docs/guides/team/team_management/manage_departments.md+++ /dev/null@@ -1,30 +0,0 @@-----sidebar_position: 8-sidebar_label: "Manage departments"------## Manage departments--In RAGFlow Enterprise, administrators can create departments according to the enterprise's actual organization structure. Departments can be used as collaborator objects when configuring resource permissions.--### Add or remove department members--Administrators can add users to a department or remove users from a department. Members in a department can inherit the corresponding resource permission when the department is added as a collaborator.--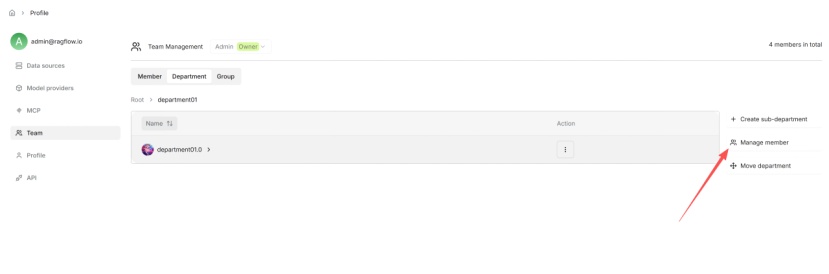--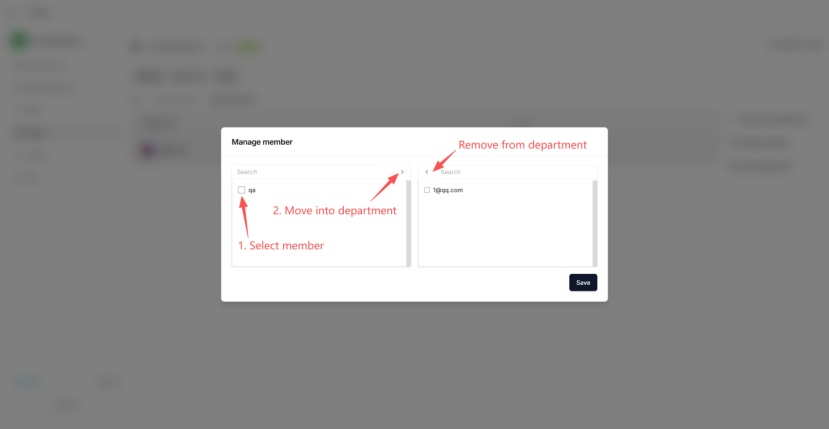---### Move departments--Administrators can move departments to adjust the organization hierarchy. Department names and levels may vary between enterprises.--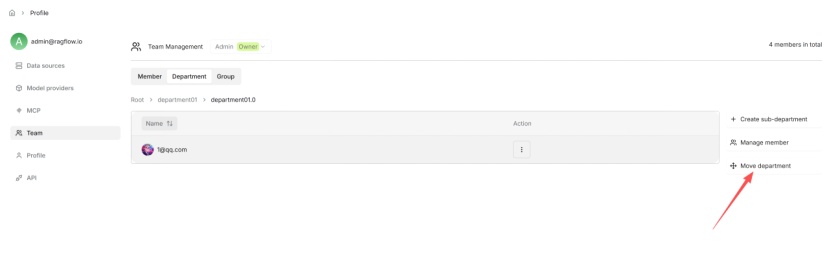---### Manage groups--In RAGFlow Enterprise, administrators can create groups to organize users for permission configuration and resource collaboration. A group can be added as a collaborator, and users in the group can inherit the group's corresponding permission.--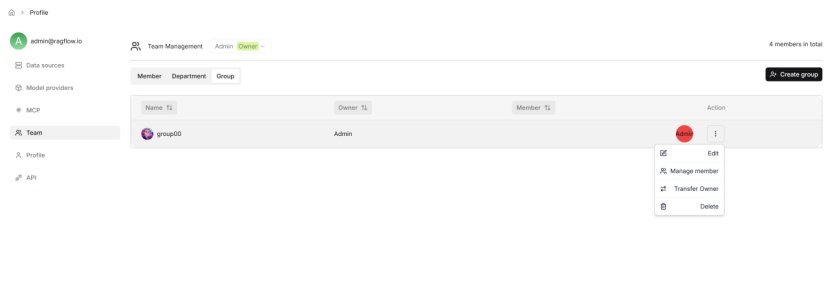diff --git a/docs/guides/team/team_management/remove_members.md b/docs/guides/team/team_management/remove_members.mdindex 863bf75d29..8eea7644d4 100644--- a/docs/guides/team/team_management/remove_members.md+++ b/docs/guides/team/team_management/remove_members.md@@ -1,9 +1,10 @@---sidebar_position: 4-sidebar_label: "Remove members"+sidebar_label: Remove Members+title: Remove Members----## Remove members+# Remove MembersThe team owner can remove members from the team.diff --git a/docs/guides/team/team_management/resource_sharing_from_the_team_perspective.md b/docs/guides/team/team_management/resource_sharing_from_the_team_perspective.mdindex 7424ad2968..73b2a6b6f8 100644--- a/docs/guides/team/team_management/resource_sharing_from_the_team_perspective.md+++ b/docs/guides/team/team_management/resource_sharing_from_the_team_perspective.md@@ -1,9 +1,10 @@---sidebar_position: 9-sidebar_label: "Resource sharing from the team perspective"+sidebar_label: Resource Sharing from the Team Perspective+title: Resource Sharing from the Team Perspective----## Resource sharing from the team perspective+# Resource Sharing from the Team PerspectiveJoining a team does not automatically grant access to all resources in that team. The resource itself must be shared with the team or authorized to the user.diff --git a/docs/guides/team/team_management/view_current_workspace_members.md b/docs/guides/team/team_management/view_current_workspace_members.mdindex 361ed498e2..21506d4d3a 100644--- a/docs/guides/team/team_management/view_current_workspace_members.md+++ b/docs/guides/team/team_management/view_current_workspace_members.md@@ -1,9 +1,10 @@---sidebar_position: 2-sidebar_label: "View current workspace members"+sidebar_label: View Current Workspace Members+title: View Current Workspace Members----## View current workspace members+# View Current Workspace MembersThe **Team members** list displays members in the current workspace. The owner is not included in the ordinary member list returned by the backend member query.diff --git a/docs/guides/team/team_management/view_joined_teams.md b/docs/guides/team/team_management/view_joined_teams.mdindex b695ea8315..5a8faa6d0f 100644--- a/docs/guides/team/team_management/view_joined_teams.md+++ b/docs/guides/team/team_management/view_joined_teams.md@@ -1,9 +1,10 @@---sidebar_position: 5-sidebar_label: "View joined teams"+sidebar_label: View Joined Teams+title: View Joined Teams----## View joined teams+# View Joined TeamsThe **Joined teams** list displays other workspaces that the current user has joined or has been invited to join.