
RAGFlow is an agent-native database: a Retrieval-Augmented Generation (RAG) engine that grew into context infrastructure.
Go agent-harnessagent-native-databaseagentic-aiagentic-retrievalagentic-searchaiai-agentscontext-enginecontext-engineeringcontext-managementharness-engineeringknowledge-compilationragretrieval-augmented-generationretrieval-harnesssearch-harness
docs: Updated Agent documentation, examples, images, links, and formatting. (#21471)
YanZhang6f4b2eb087bd
diff --git a/docs/guides/agent/_category_.json b/docs/guides/agent/_category_.jsonindex 72c5d12b86..5d384e7857 100644--- a/docs/guides/agent/_category_.json+++ b/docs/guides/agent/_category_.json@@ -3,7 +3,7 @@"position": 5,"link": {"type": "generated-index",- "description": "RAGFlow v0.8.0 introduces an agent mechanism, featuring a no-code workflow editor on the front end and a comprehensive graph-based task orchestration framework on the backend."+ "description": "Build visual Agent workflows for knowledge retrieval, model reasoning, tool calls, branching, iteration, and data processing."},"customProps": {"categoryIcon": "RagAiAgent"diff --git a/docs/guides/agent/agent_overview.md b/docs/guides/agent/agent_overview.mdindex 4384e3f98a..da4a5a7fad 100644--- a/docs/guides/agent/agent_overview.md+++ b/docs/guides/agent/agent_overview.md@@ -11,7 +11,7 @@ sidebar_custom_props: {# Agent Overview## Purpose of Agent-Agent is the business workflow orchestration capability in RAGFlow. Users can add components on a no-code canvas and define execution order via connections. Components can be executed sequentially, or enter different paths according to conditional branches, classification results or loop logic.+Use Agent to build automated workflows by connecting components on a visual canvas. Connections define the execution order; conditions, categories, and loops control which steps run.Agents are commonly used in the following scenarios:- Answering user questions based on knowledge bases.@@ -27,3 +27,7 @@ Agents are commonly used in the following scenarios:The `Retrieval` component can be used inside an Agent to query knowledge bases. Retrieval can also be used as a tool under the Agent component, allowing the LLM to autonomously decide when to perform retrieval.For example, an after-sales Agent can first use `Categorize` to judge the type of user questions, then use `Retrieval` to query product materials. If the user requests installation reservation, an HTTP request is used to call the external work order system. Finally, the `Message` component outputs the result.++## Try a complete workflow++Follow [Build a Customer Support Agent](./quickstarts/build_customer_support_agent.md) for a complete example with sample content, prompts, two branches, and expected test results.diff --git a/docs/guides/agent/agent_workflow/basic_component.md b/docs/guides/agent/agent_workflow/basic_component.mdindex c3d7bb9b5b..fad5ec7e9e 100644--- a/docs/guides/agent/agent_workflow/basic_component.md+++ b/docs/guides/agent/agent_workflow/basic_component.md@@ -22,11 +22,20 @@ sidebar_custom_props: {- **Task**: Started as a task. This is suitable for non-conversational automated workflows.- **Webhook**: Triggered by external HTTP requests. This is suitable for system integration, automation tasks, and third-party callbacks.-When `Webhook` mode is selected, the system generates the current Agent's Webhook URL. You can continue to configure the request method, security authentication, request schema, and response method.+For external HTTP requests, select **Webhook** and follow the [Webhook configuration](#webhook-configuration) below.++### Webhook Configuration++1. In Begin, select **Webhook**, copy the URL, and choose the allowed request methods.+2. Under **Security**, select the authentication method and enter its credentials. For Token authentication, set **Token header** to `X-Webhook-Token` and enter **Token value**; the caller must send the same header and value. External requests also need `Authorization: Bearer <RAGFlow API key>` from an account with access to the Agent.+3. Under **Schema**, select **application/json** and define the required request fields. Insert these fields into downstream components through the variable selector. Multipart file uploads are not supported and return HTTP `501`.+4. Under **Response**, choose **Accepted response** to acknowledge the request and continue in the background, or **Final response** to return the completed workflow's messages. Save and test.++For example, add a required string body field named `question`, connect **Begin → Message**, and insert that field into Message. Send `{"question":"Hello"}` with the configured authentication and `Content-Type: application/json`. With **Final response**, the result should contain Hello.### Opening Greeting-In `Conversational` mode, you can set the first message that the Agent says to the user in **Opening greeting**. The opening greeting should describe what the Agent can handle, and should not be written as a lengthy product introduction.+In **Conversational** mode, enable **Opening switch** and enter an **Opening greeting** that briefly describes the questions or tasks the Agent can handle.Example:@@ -44,7 +53,7 @@ In the **Input** area of the right configuration panel for the `Begin` componentCommon fields are as follows:- **Name**: The variable display name.-- **Type**: The variable type, including single-line text, paragraph text, dropdown options, file upload, number, and Boolean.+- **Type**: The variable type, including single-line text, paragraph text, dropdown options, file upload, number, Boolean, and JSON object.- **Key**: The variable key, used by subsequent components for reference.- **Optional**: Whether the input is optional.@@ -64,7 +73,13 @@ Variable types::::tip NOTE-Files uploaded through the `Begin` component are used only as input for the current workflow. They are not automatically saved to knowledge bases, and they do not use knowledge base parsing, OCR, or chunking capabilities. File content can be passed to subsequent components as variables, and is limited by the model context length.+Files uploaded through **Begin** are available to the workflow without being added to a knowledge base.++- For documents, add a **File upload** input and select a parser. Reference the parsed content through `sys.files` in subsequent components.+- For images, select a vision-capable model in the Agent component to analyze the uploaded image. Image uploads are not automatically converted to text.+- Video uploads are not supported in Begin.++Keep uploaded content within the selected model's context limit.:::@@ -89,9 +104,9 @@ Configuration steps:3. Set **Creativity** as needed, or keep **Precise**.4. Describe the role, constraints, and output format in **System prompt**.5. Write the task in **User prompt**, and insert variables by typing `/`.-6. If retrieval, SQL, HTTP, MCP, or sub-Agents are required, add **Tools** or **Agent**.-7. Set the output variable name.-8. Save and run tests.+6. Add Retrieval, Execute SQL, or other tools offered by **Tools**, select MCP tools, or add sub-agents under **Agent**. For a fixed HTTP call, connect a separate **HTTP Request** workflow node.+7. Review the `content` output, or enable structured output and configure its schema when needed.+8. Click **Save**, then **Run** to check the result.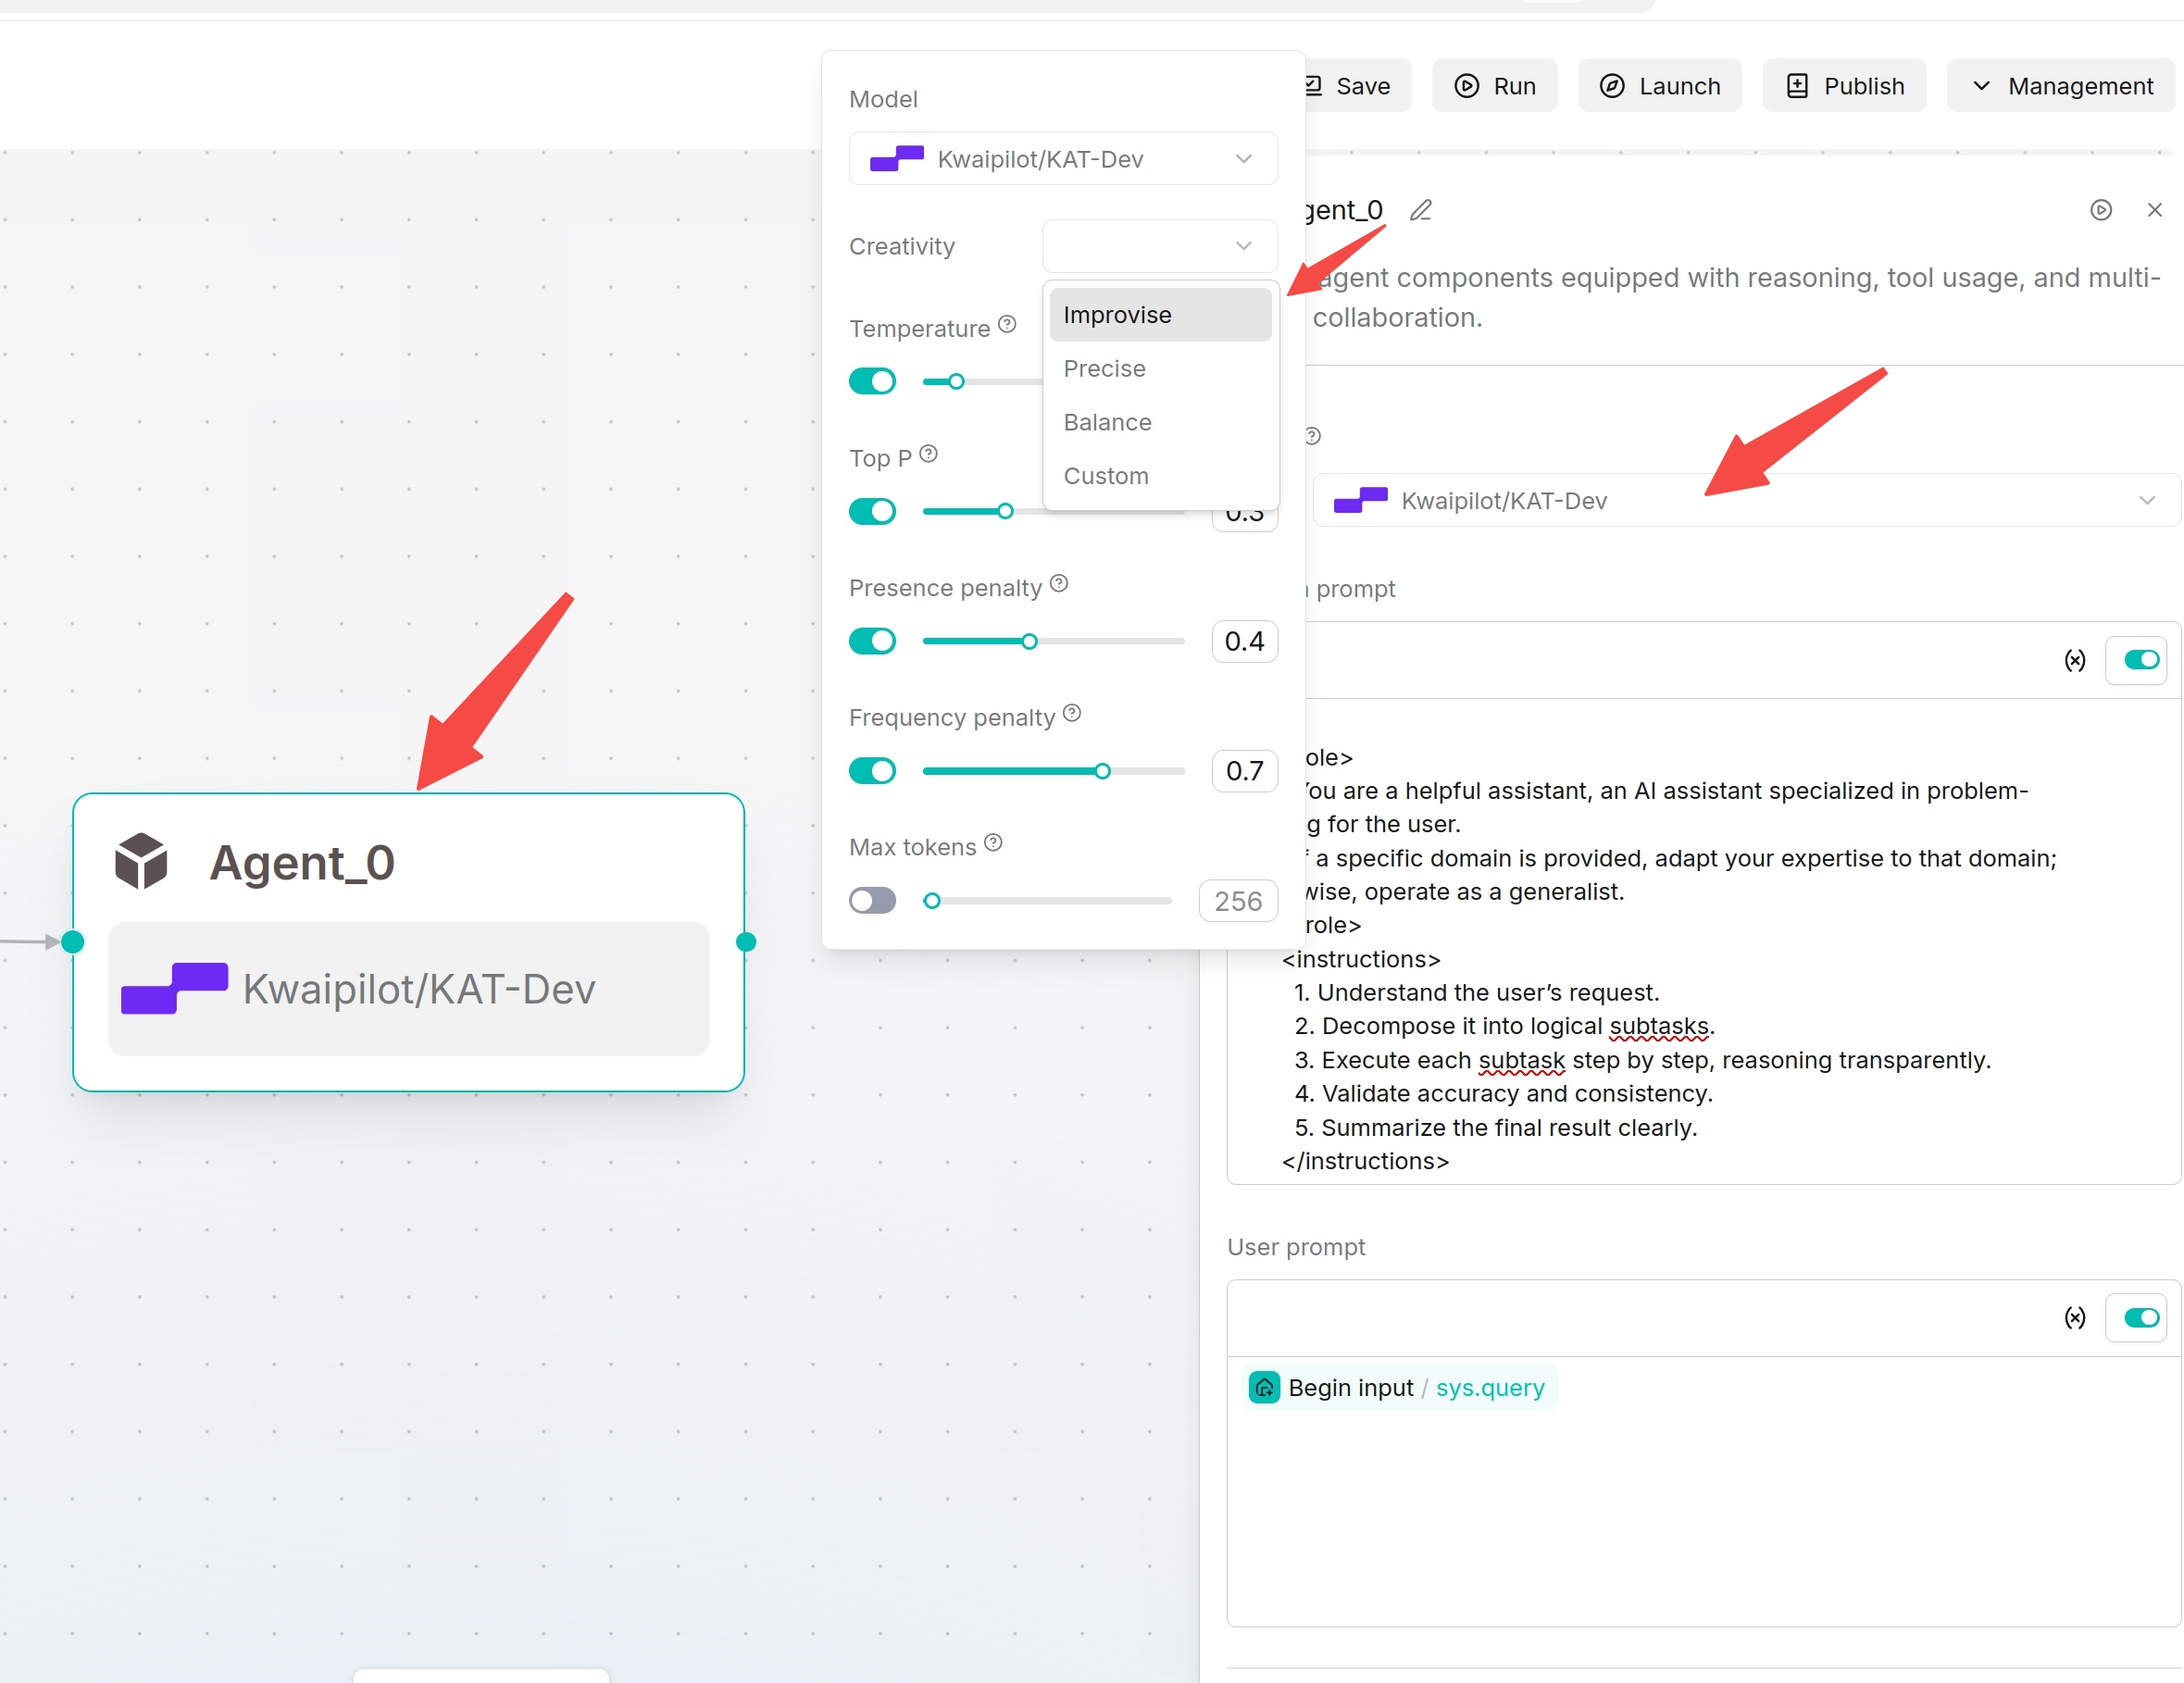@@ -101,21 +116,21 @@ The system prompt is used to define the model role and behavior boundaries. TheIf the Agent component follows a knowledge retrieval component, you usually need to reference `formalized_content` in the user prompt so that the model answers based on the retrieval results.-Example:+For example, in **User prompt**, enter `Question: ` and use the variable selector to insert `sys.query`. On a new line, enter `Reference: ` and insert the preceding Retrieval component's `formalized_content`. Add the instruction `Answer using the reference. If it does not contain the answer, say so.`-> Please answer `/sys.query` based on `/Retrieval_0.formalized_content`. If the retrieval results are insufficient, clearly state that confirmation cannot be obtained from the knowledge base, and do not fabricate answers.+Use the variable selector to insert references. Component names in examples are illustrative; select the matching component on your own canvas rather than typing its name.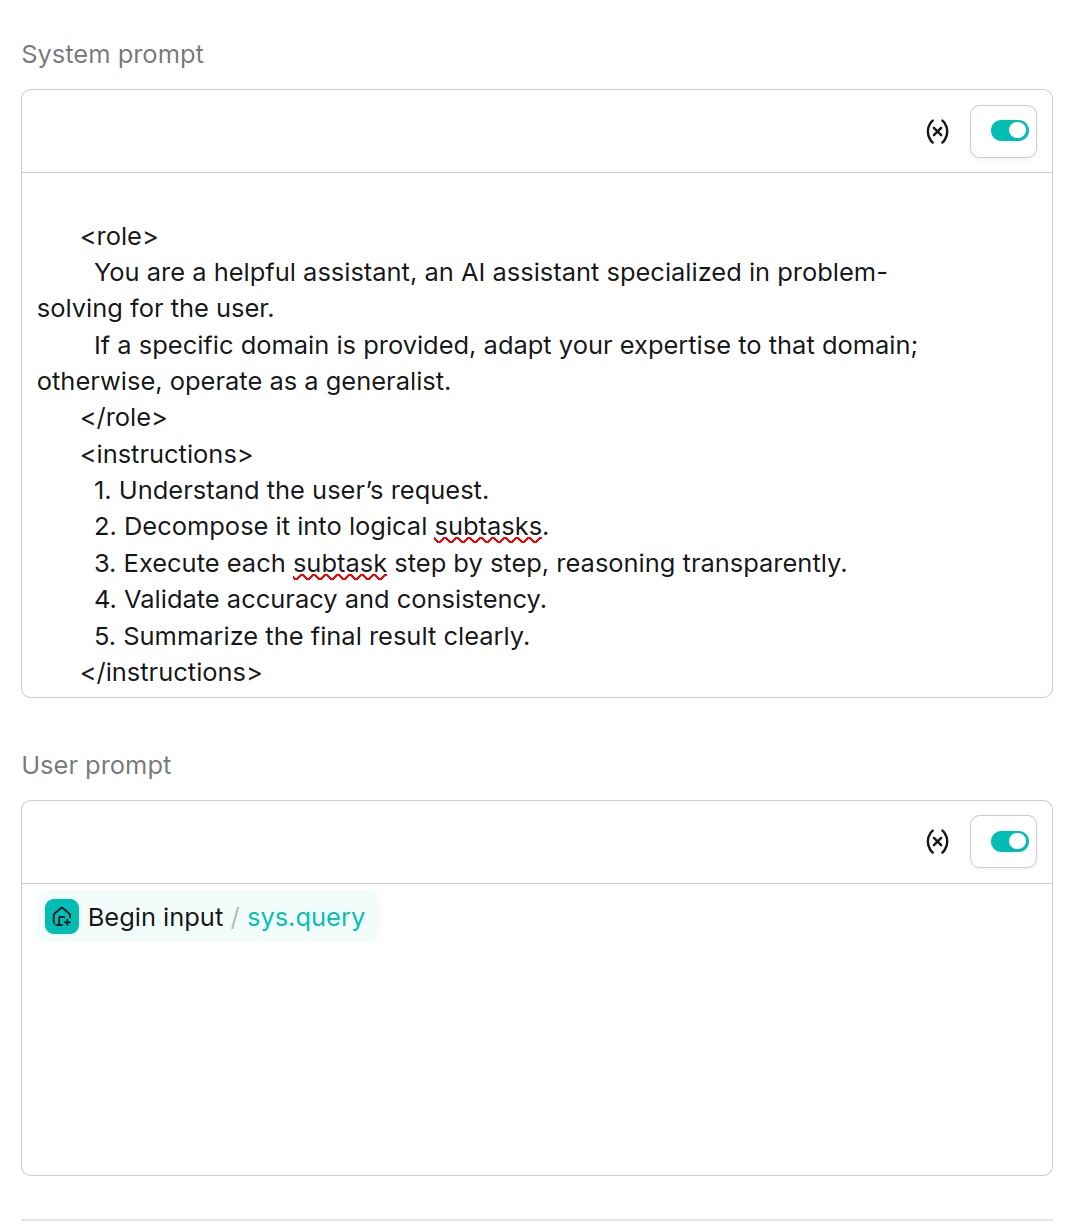### Tools and Sub-Agents-When tools or sub-agents are added under an Agent component, the current Agent acts as a planner and determines when to call these capabilities. Tools can be knowledge retrieval (`Retrieval`), Execute SQL, HTTP Request, MCP Server, or other available components. Sub-agents are used to split complex tasks and assign them to different roles for collaboration.+When tools or sub-agents are added under an Agent component, the current Agent acts as a planner and determines when to call these capabilities. The built-in tool selector includes knowledge retrieval (`Retrieval`), Execute SQL, Code, search, and other listed tools. MCP tools are selected on the MCP tab. **HTTP Request** is available as a workflow node and is not listed in the Agent component's built-in tool selector. Sub-agents are used to split complex tasks and assign them to different roles for collaboration.-It is recommended to describe tool trigger conditions in the system prompt. For example: "Call knowledge base retrieval first when product documents are involved" or "Call the HTTP API when order status is involved".+Describe when to use each selected tool in **System prompt**. For example: "Use Retrieval for product questions; if no relevant content is found, ask the user for more details.":::tip NOTE-Tool calling, sub-agents, reflection rounds, and a larger message window size all increase response time. For regular Q&A, prefer a simple workflow. Enable tools and multi-agent planning only when planning is truly required.+Additional tool calls, reflection rounds, and conversation history can increase response time. Start with a simple workflow for regular Q&A, then add tools or sub-agents when the task needs them.:::@@ -123,7 +138,7 @@ Tool calling, sub-agents, reflection rounds, and a larger message window size al### Advanced Settings-Advanced settings are used to control context management, exception handling, output format, and other runtime behavior for the Agent node. In most cases, keep the default configuration. When you need to optimize Agent execution results or adapt to a specific business scenario, adjust these settings based on actual requirements.+Use **Advanced settings** to adjust conversation history and citations.Parameter description:@@ -131,9 +146,10 @@ Parameter description:| --- | --- | --- || Message window size | Sets the number of historical messages retained by the Agent during reasoning. A larger window provides more context, but increases token consumption. | Keep the default value in general. Increase it for multi-turn conversations, and decrease it for single-turn tasks. || Citation | Specifies whether to return citation information in answers. When the Agent uses knowledge bases or retrieval results to generate answers, source citations can be enabled to make it easier to view the basis for the answer. | Recommended for knowledge base Q&A scenarios. |-| Max retries | The maximum number of retries after Agent execution fails. When model calls or tool calls fail, the system automatically retries. | Keep the default value. Increase it when the network is unstable. |-| Delay after error | The waiting time, in seconds, before each retry. This helps avoid another failure caused by continuous requests within a short time. | Keep the default value in general. |-| Exception handling method | Sets how the Agent handles exceptions during execution. Different options determine whether execution continues, exception information is returned, or another handling policy is used after an error occurs. | Select based on business requirements. Keep the default value if there are no special requirements. |++If an Agent run fails, check the error details in the run results, correct the cause, and run again.++**Max reflection rounds** appears after you add tools or sub-agents. **Tool timeout** appears after you select MCP tools.`Output` is used to configure the output content of the Agent node.@@ -142,7 +158,7 @@ Parameter description:| `content` | The natural language text returned by the Agent. This is the default output. || `structured` | Structured data returned by the Agent. After structured output is enabled, results can be output according to a predefined JSON Schema, making it easier for subsequent nodes to read and process. |-For structured output, after enabling **Structured output**, click **Configuration** to configure the output structure. Users can define the returned data format according to JSON Schema, such as specifying field names, data types, and required fields. The Agent tries to return results according to the configured structure, making it easier to pass data to nodes such as Code, HTTP Request, SQL, and condition judgment for automated processing.+For structured output, after enabling **Structured output**, click **Configuration** to configure the output structure. Users can define the returned data format according to JSON Schema, such as specifying field names, data types, and required fields. The Agent tries to return results according to the configured structure, making it easier to pass data to nodes such as Code, HTTP Request, Execute SQL, and Switch for automated processing.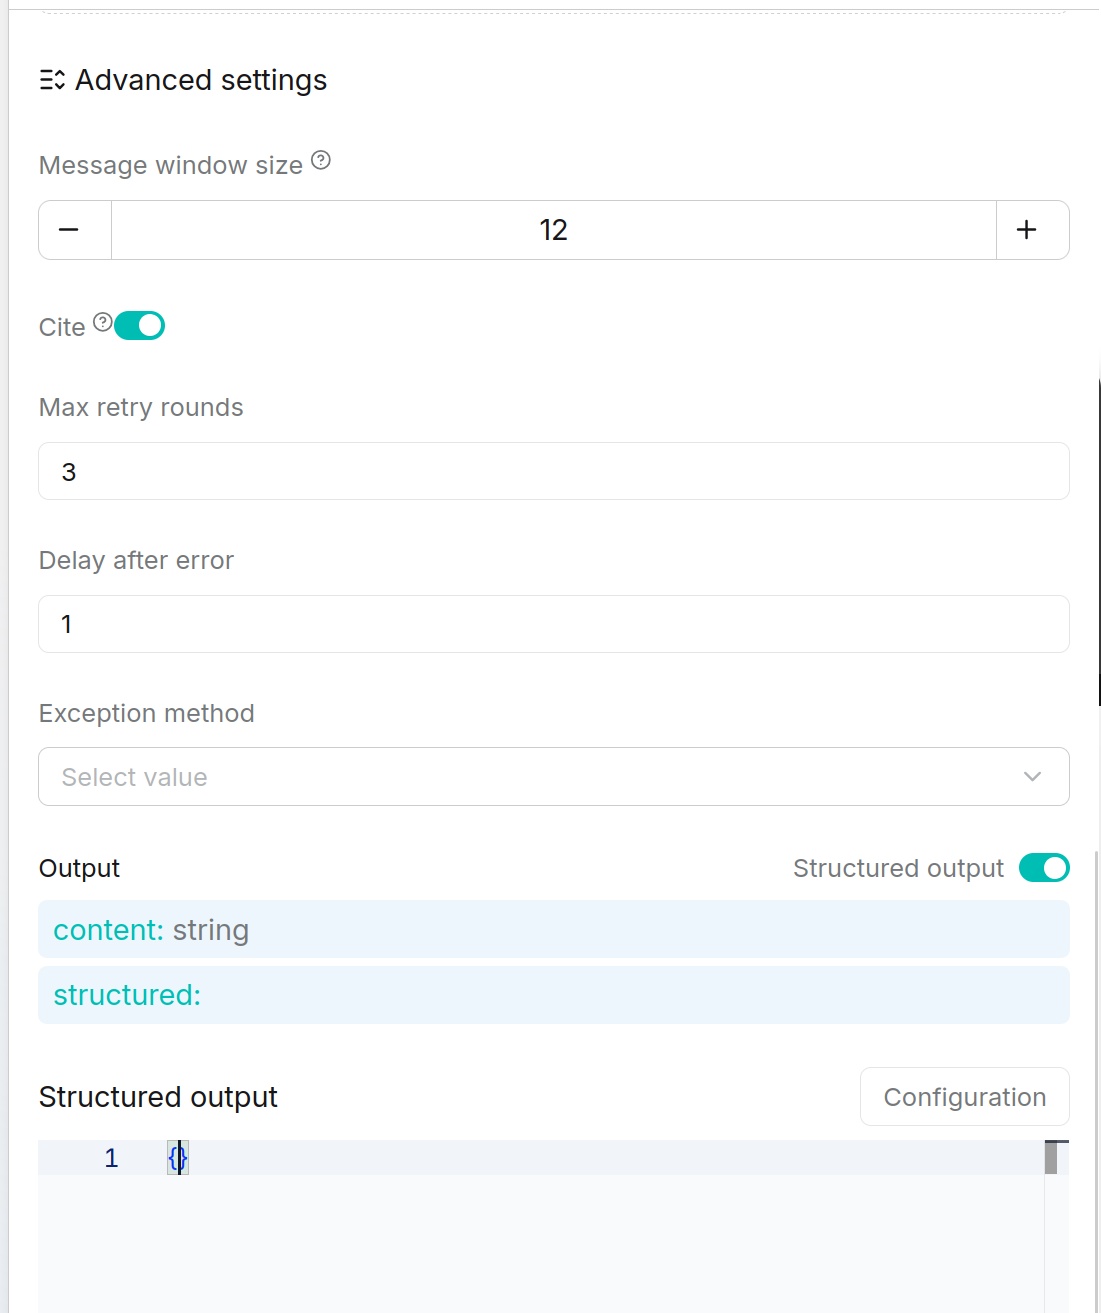@@ -155,10 +171,9 @@ Configuration steps:1. Click the knowledge retrieval component.2. In **Query variable**, select the query source. `sys.query` is commonly used.3. In **Retrieval source**, select one or more knowledge bases, or select **Memory**.-4. Adjust **Similarity threshold**, **Keyword similarity weight**, and **Top N** as needed.+4. Expand **Advanced settings** and adjust **Similarity threshold**, **Keyword similarity weight**, **Rerank candidate count**, and **Top N** as needed. Select a **Rerank model** if required.5. For cross-language retrieval, select a **Cross-language search** language.-6. For graph multi-hop Q&A, enable **Use knowledge graph**.-7. Click **Run** to test the retrieval results.+6. Click **Run** to test the retrieval results.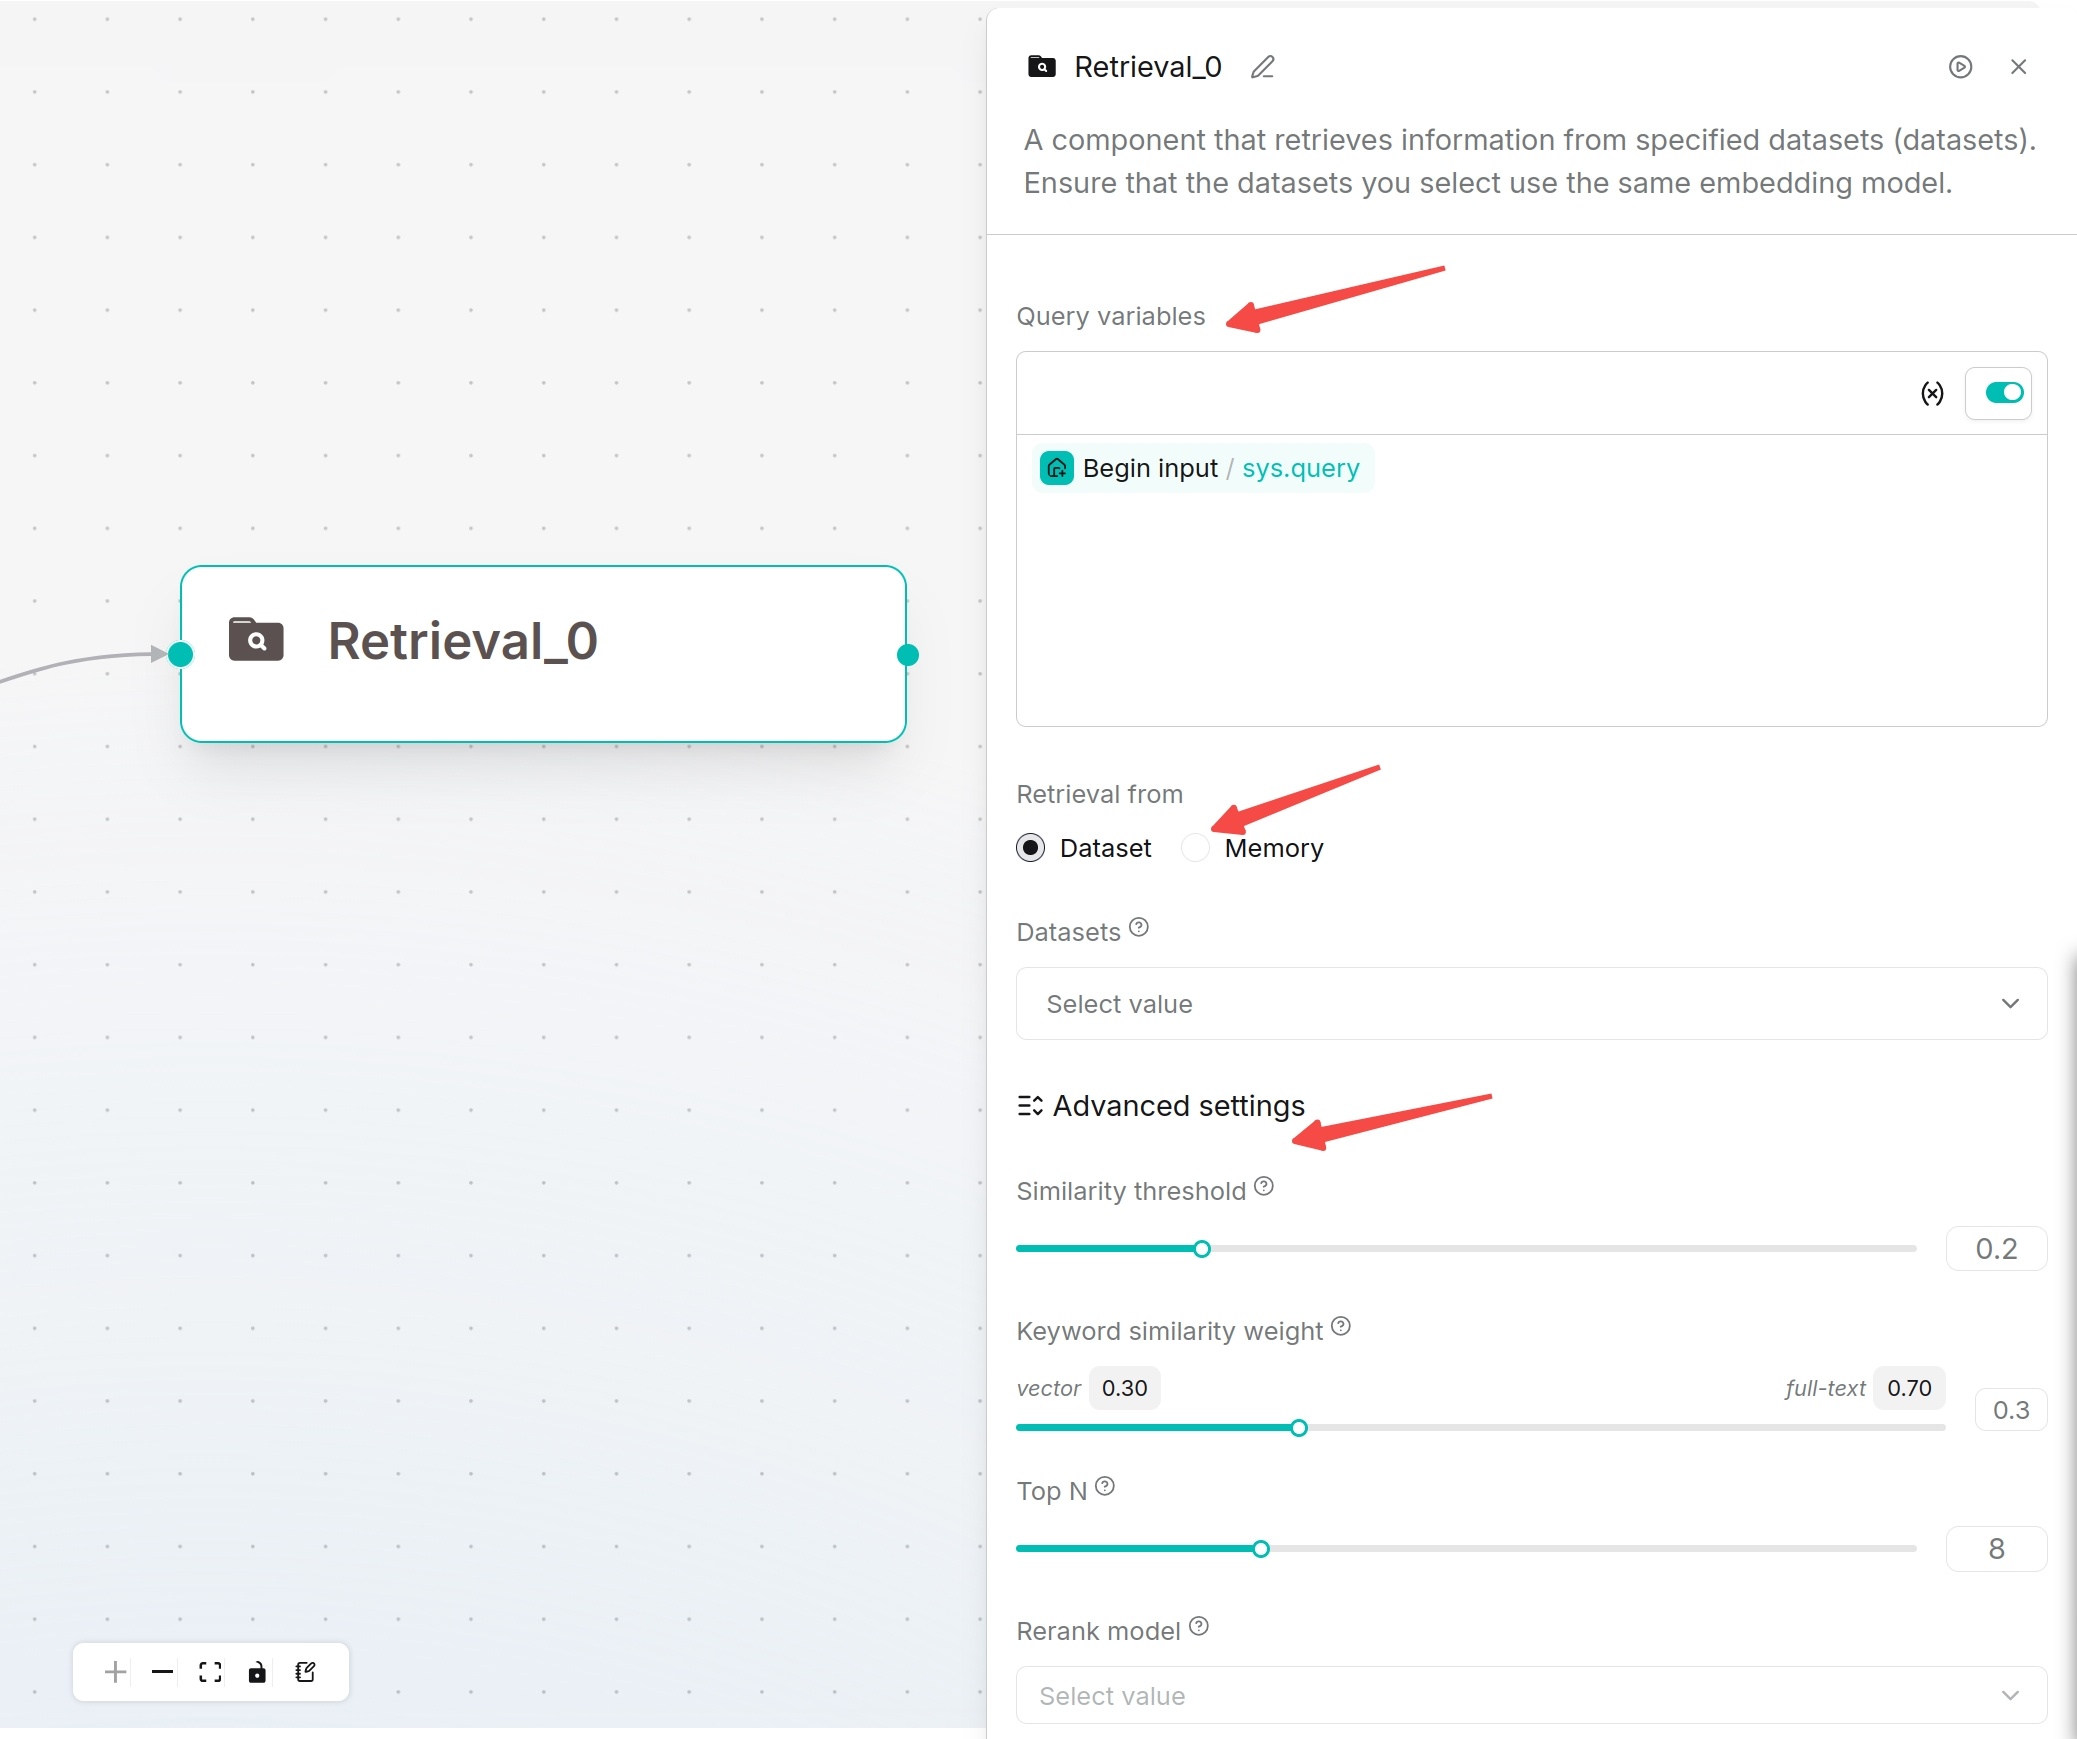@@ -168,13 +183,16 @@ Configuration steps:**Similarity threshold** is used to filter low-relevance chunks. The higher the threshold, the stricter the returned content, but useful information may be missed.-**Keyword similarity weight** is used to control the weight of vector similarity in the overall similarity score. When retrieving from multiple knowledge bases together, make sure they use the same embedding model.+**Keyword similarity weight** controls the full-text keyword weight in the combined retrieval score. Its default is `0.7`, with a corresponding vector weight of `1 - 0.7 = 0.3`. The panel shows both weights. Increasing the keyword weight favors keyword matching; decreasing it favors vector similarity. When retrieving from multiple knowledge bases together, make sure they use the same embedding model.++**Rerank candidate count** controls the number of retrieval candidates available for reranking. The default shown in the panel is `64`. This is separate from **Top N**, which limits the results passed to downstream components.++The initial **Similarity threshold** is `0.2` (displayed as `20` in the percentage-based control), and the initial **Top N** is `8`. The recommendations below are tuning suggestions rather than defaults. **Meta data** filters can also constrain retrieval; check the selected datasets and filter conditions when relevant content is missing.**Top N** specifies the number of chunks sent to subsequent components. Too few chunks may result in insufficient information, while too many chunks may increase response time and context pressure.Enabling a **Rerank model** usually improves the sorting of knowledge retrieval results, but also adds model call latency. For Agents that are sensitive to speed, you can leave reranking disabled at first.-`Similarity threshold` is used to filter low-relevance chunks. The higher the threshold, the stricter the returned content, but useful information may be missed.### Configuration Suggestions@@ -185,8 +203,8 @@ Retrieval parameters directly affect answer coverage, accuracy, and response tim| Parameter | Suggested Value | Scenario | Description || --- | --- | --- | --- || Top N | 3-5 | FAQ and short knowledge entries | Faster responses for clear answers. |-| Top N | 5-10 | Product documentation and help centers | Default recommended range. |+| Top N | 5-10 | Product documentation and help centers | A suggested range to test with representative questions. || Top N | 10-20 | Legal contracts and long document analysis | More context with higher token consumption. || Similarity threshold | 0.2 | Loose recall | Questions with diverse expressions. |-| Similarity threshold | 0.5 | General Q&A | Default starting value. |+| Similarity threshold | 0.5 | General Q&A | A stricter tuning example; the initial value is 0.2. || Similarity threshold | 0.8 | Strict precise matching | Scenarios that require exact terminology matching. |diff --git a/docs/guides/agent/agent_workflow/data_manipulation_components.md b/docs/guides/agent/agent_workflow/data_manipulation_components.mdindex c6ef6bc673..e1b20ec487 100644--- a/docs/guides/agent/agent_workflow/data_manipulation_components.md+++ b/docs/guides/agent/agent_workflow/data_manipulation_components.md@@ -19,6 +19,40 @@ Configuration:2. **Code**: Select Python or JavaScript and write business logic.3. **Return Value**: Define output data returned to downstream components.+### Minimal example++Add two **Input** parameters, `first` and `second`, and bind them to text variables. Define one **Return Value** named `result` with type string. Use either example:++```python+def main(first: str, second: str):+ return first + second+```++```javascript+async function main(args) {+ return args.first + args.second;+}+```++In **Test run**, enter `Hello, ` for `first` and `world!` for `second`. The expected output is `result: "Hello, world!"`. In a downstream **Message**, use the variable selector to insert this Code component's `result`.++The returned value is assigned to one output. To return several fields, return an object and configure that output as an object rather than defining several outputs.++### Read the output++| Output | Meaning | Use |+| --- | --- | --- |+| Output, such as `result` | The value returned by `main`, validated against the configured type. | Calculations and downstream data processing. |+| `content` | Text representation of the returned value. | Prompts and text display. |+| `actual_type` | The detected return type. | Diagnose a type mismatch. |+| `attachments` | Files collected from execution, when present. | File output and download handling. |++### If the test fails++- Check that Input names match the Python function arguments or JavaScript `args` properties.+- Check that the returned value matches the Return Value type. Printing a value does not replace returning it.+- For missing packages, unavailable runners, or connection errors, ask an administrator to check the active provider. See the [Sandbox FAQ](../../../administrator/sandbox/faq.md).+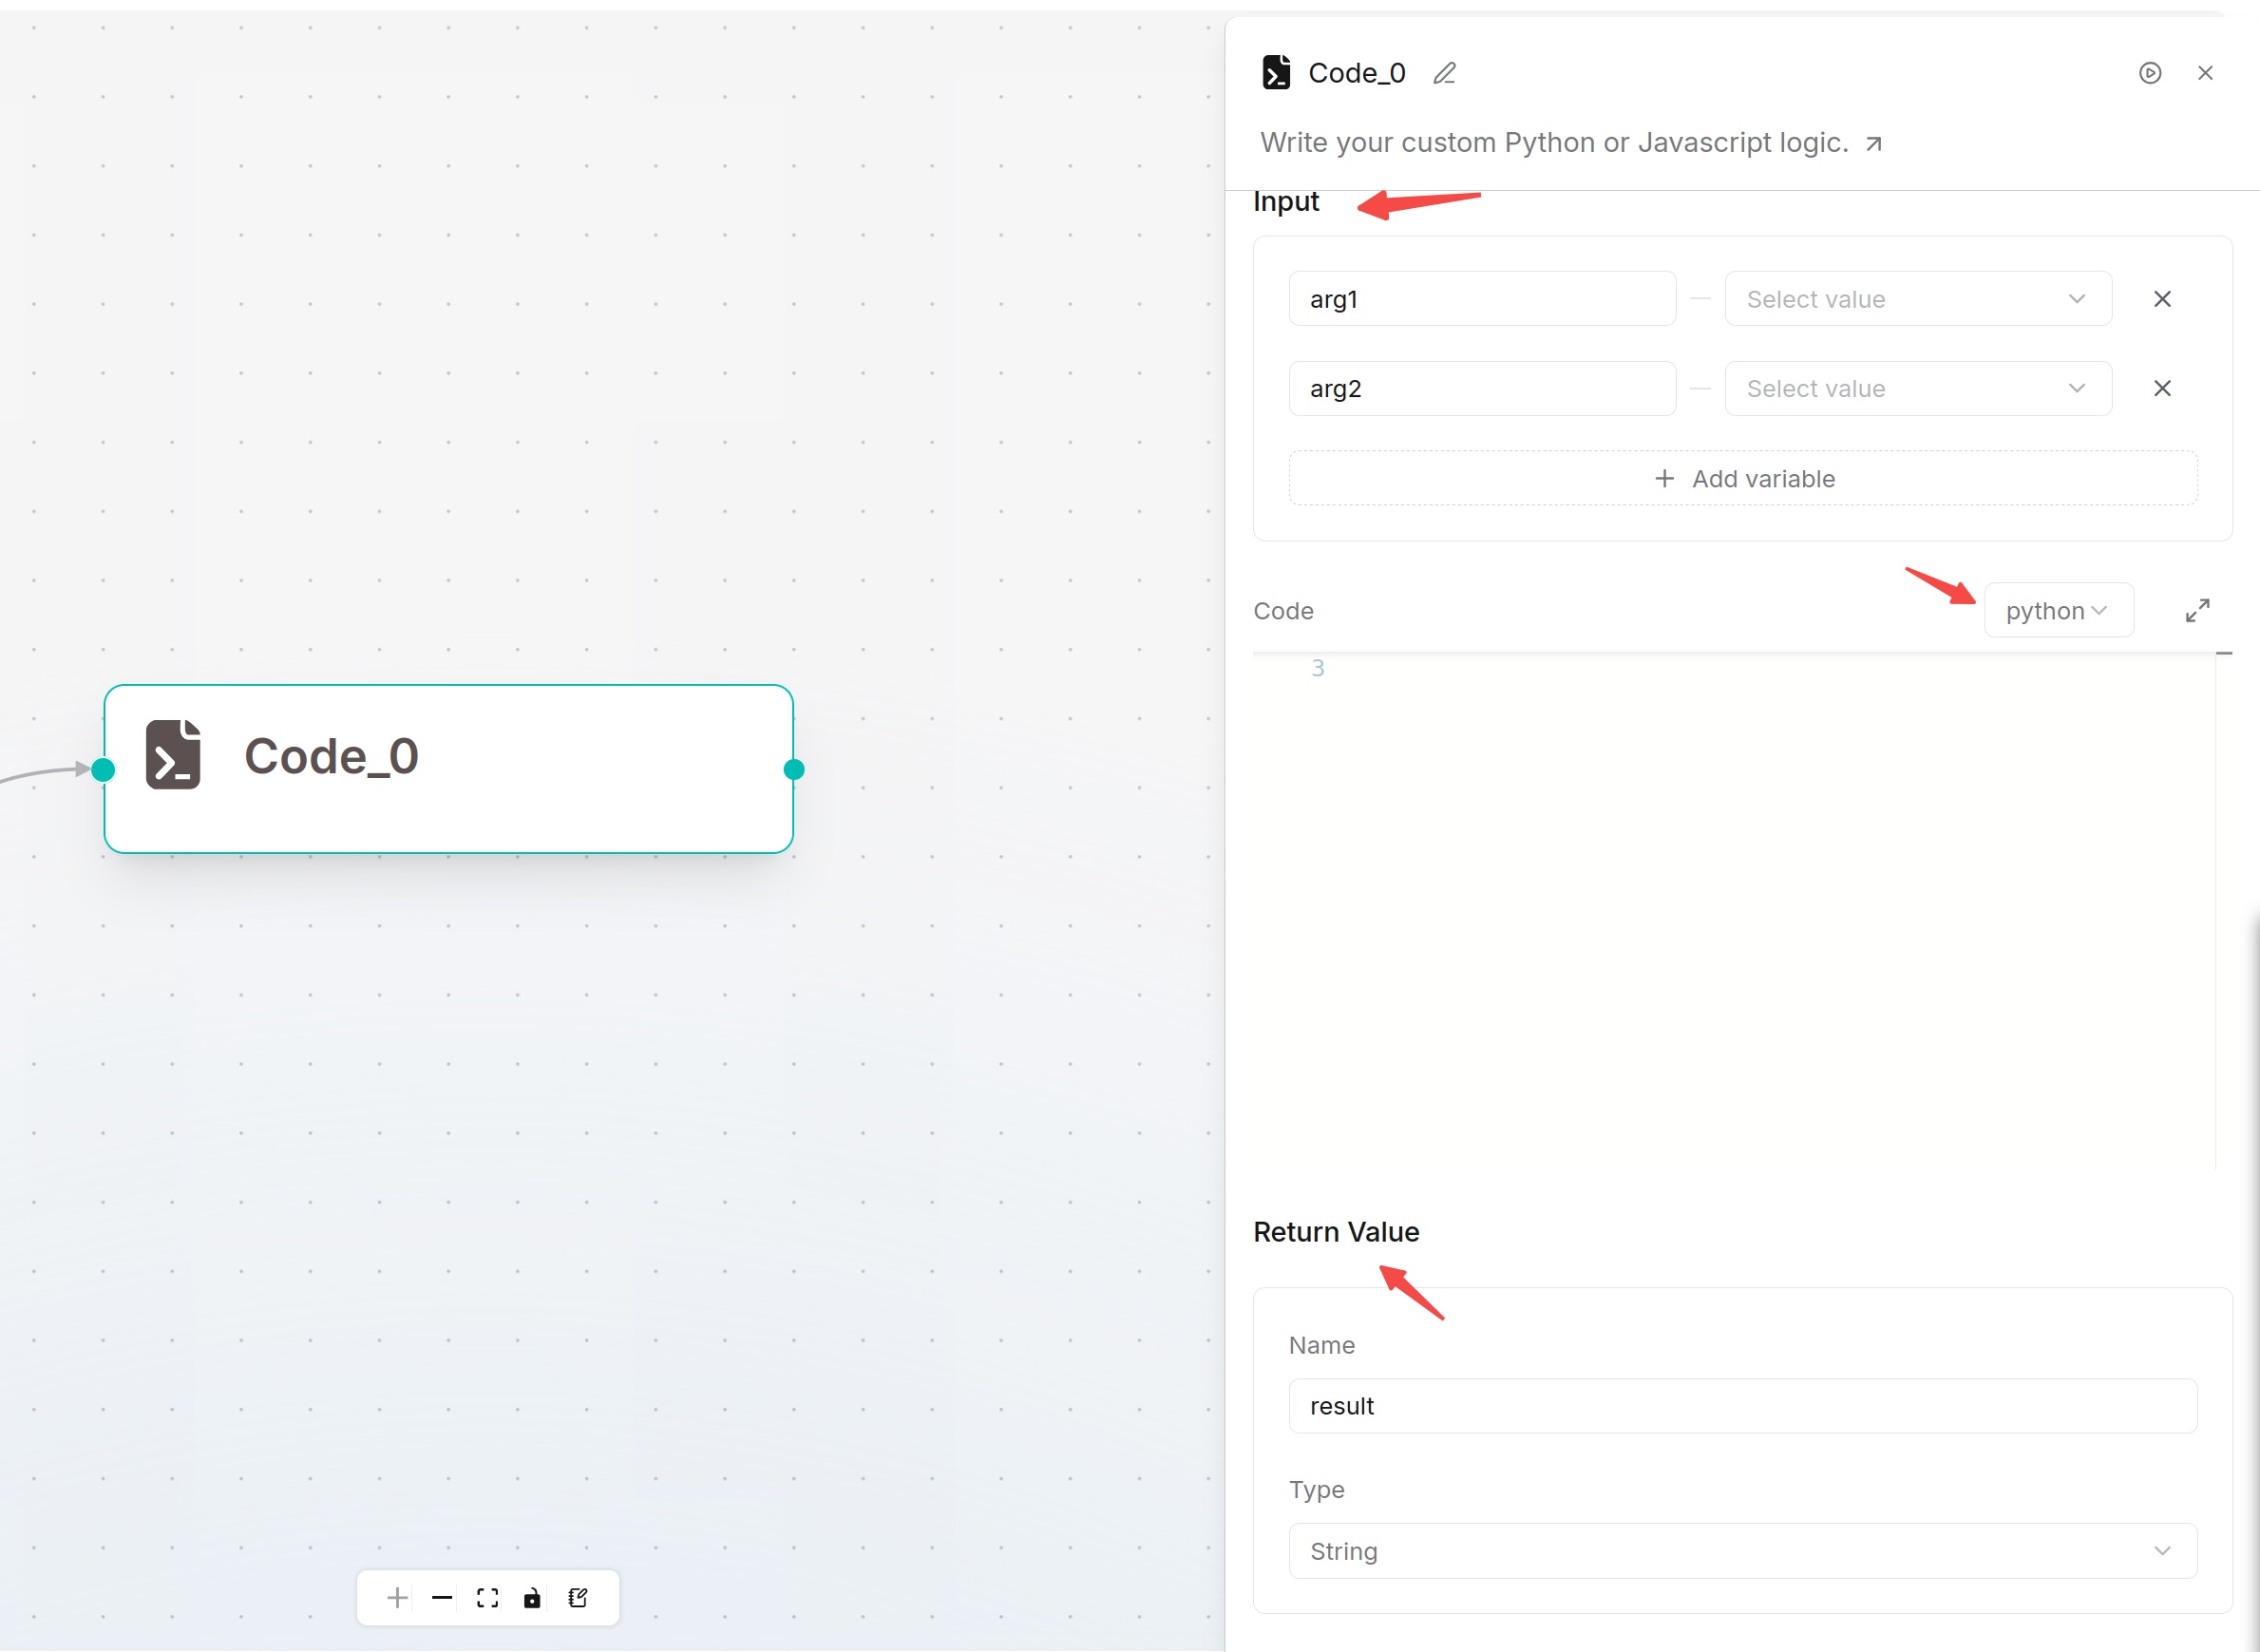@@ -31,146 +65,123 @@ Processing Modes:Configure script content with variables inserted via `/`. Output results can be referenced by subsequent nodes.+| Mode | Configure | Output |+| --- | --- | --- |+| Split | Select the input variable and delimiters. | `result`: an array of text segments. |+| Merge | Enter **Script** and insert variables with `/`. | `result`: the completed text. |++For example, splitting `red,blue` with a comma produces `["red", "blue"]`. A downstream **Iteration** can process that array. In Merge mode, a Script containing `Hello, ` followed by an inserted name variable produces a single greeting.+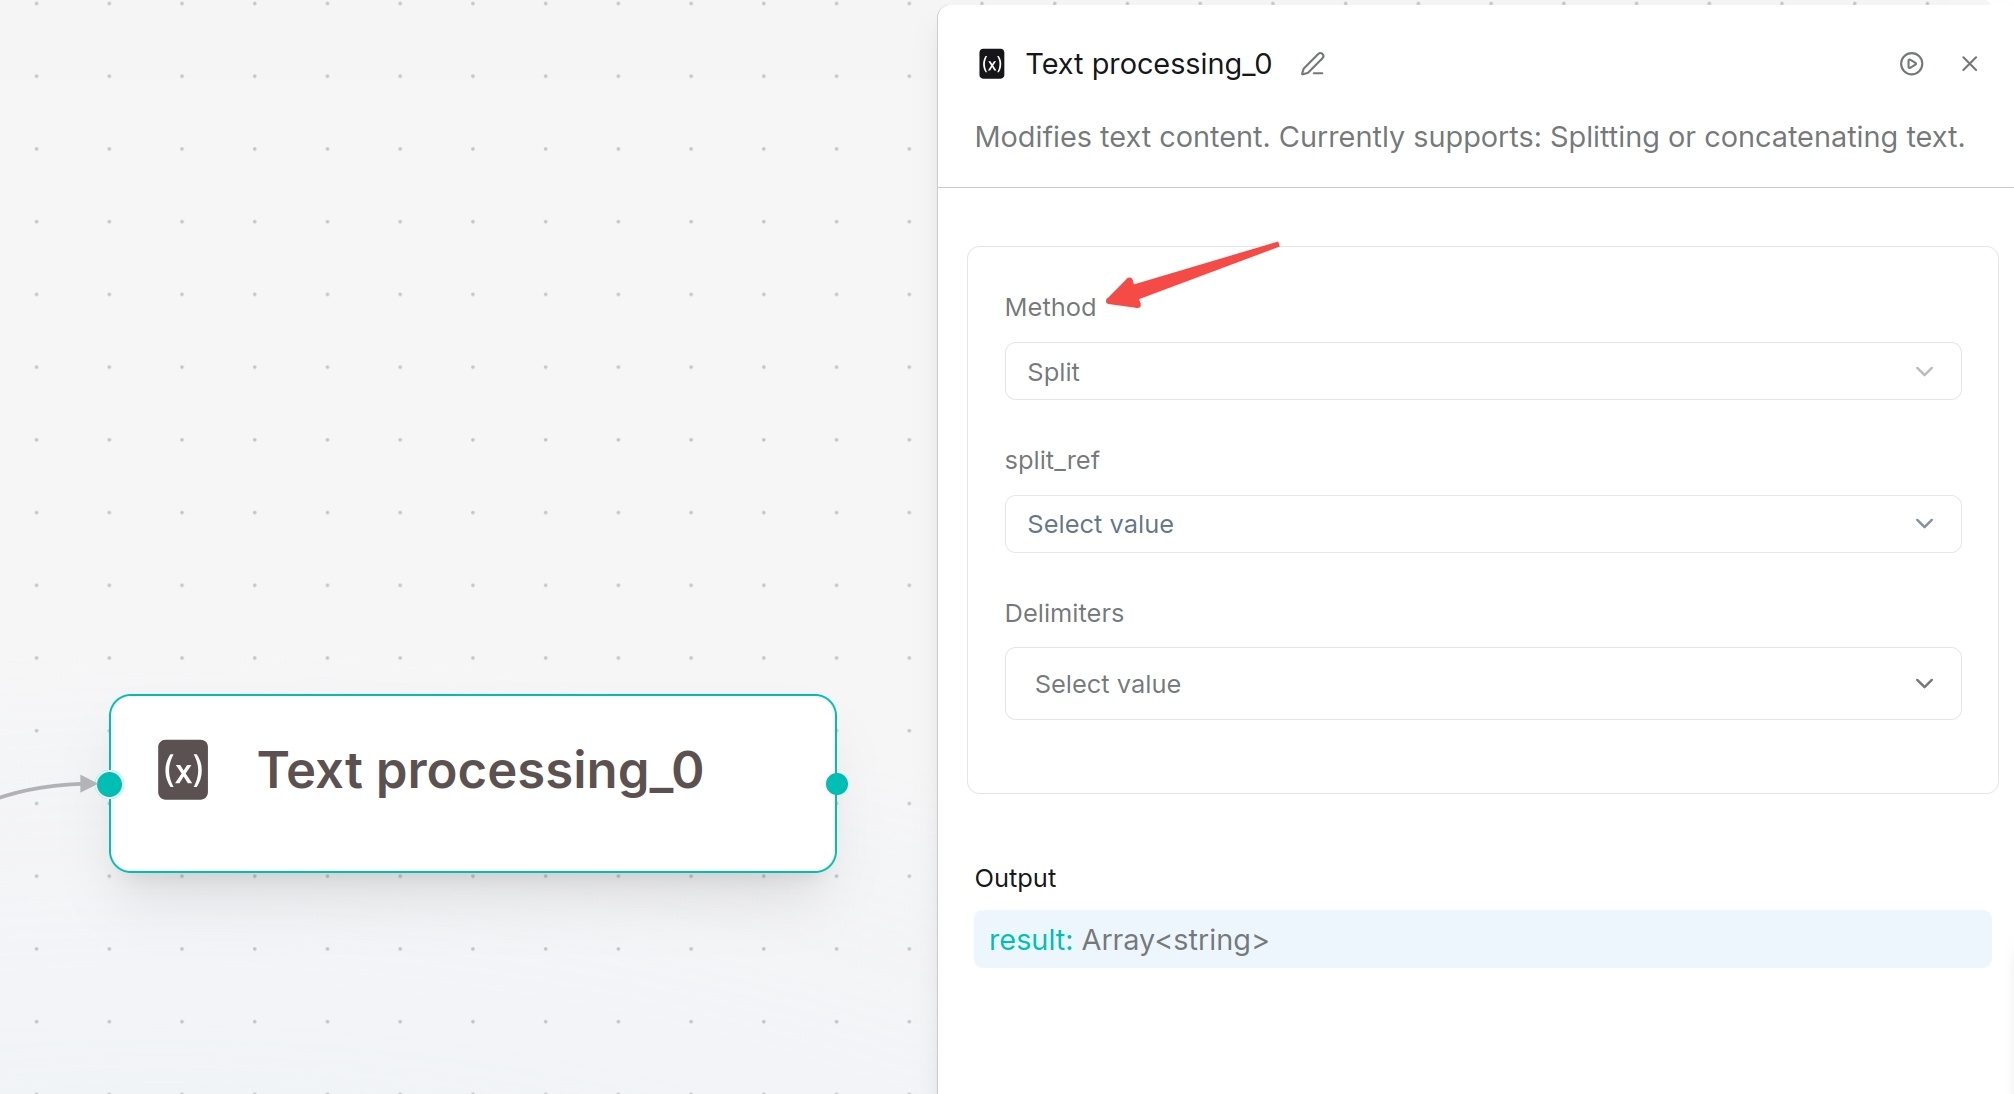-## Data Operation Component-Data Operation processes structured objects returned by upstream tools, code or database nodes to clean data for downstream usage.+## Data Operations Component+The **Data operations** component transforms structured objects returned by upstream tools, code, or database components for use in subsequent steps.Configuration Steps:-1. Add and select the Data Operation component on canvas.+1. Add and select **Data operations** on the canvas.2. Select target data variables in Query variables.3. Click `+` to add multiple input variables. Query variables are mandatory.-4. Select processing operation in Operations and fill corresponding configurations.-5. Save and run tests.+4. Select an operation under **Operations** and fill in the fields below.+5. Click **Save**, then **Run** to check the result.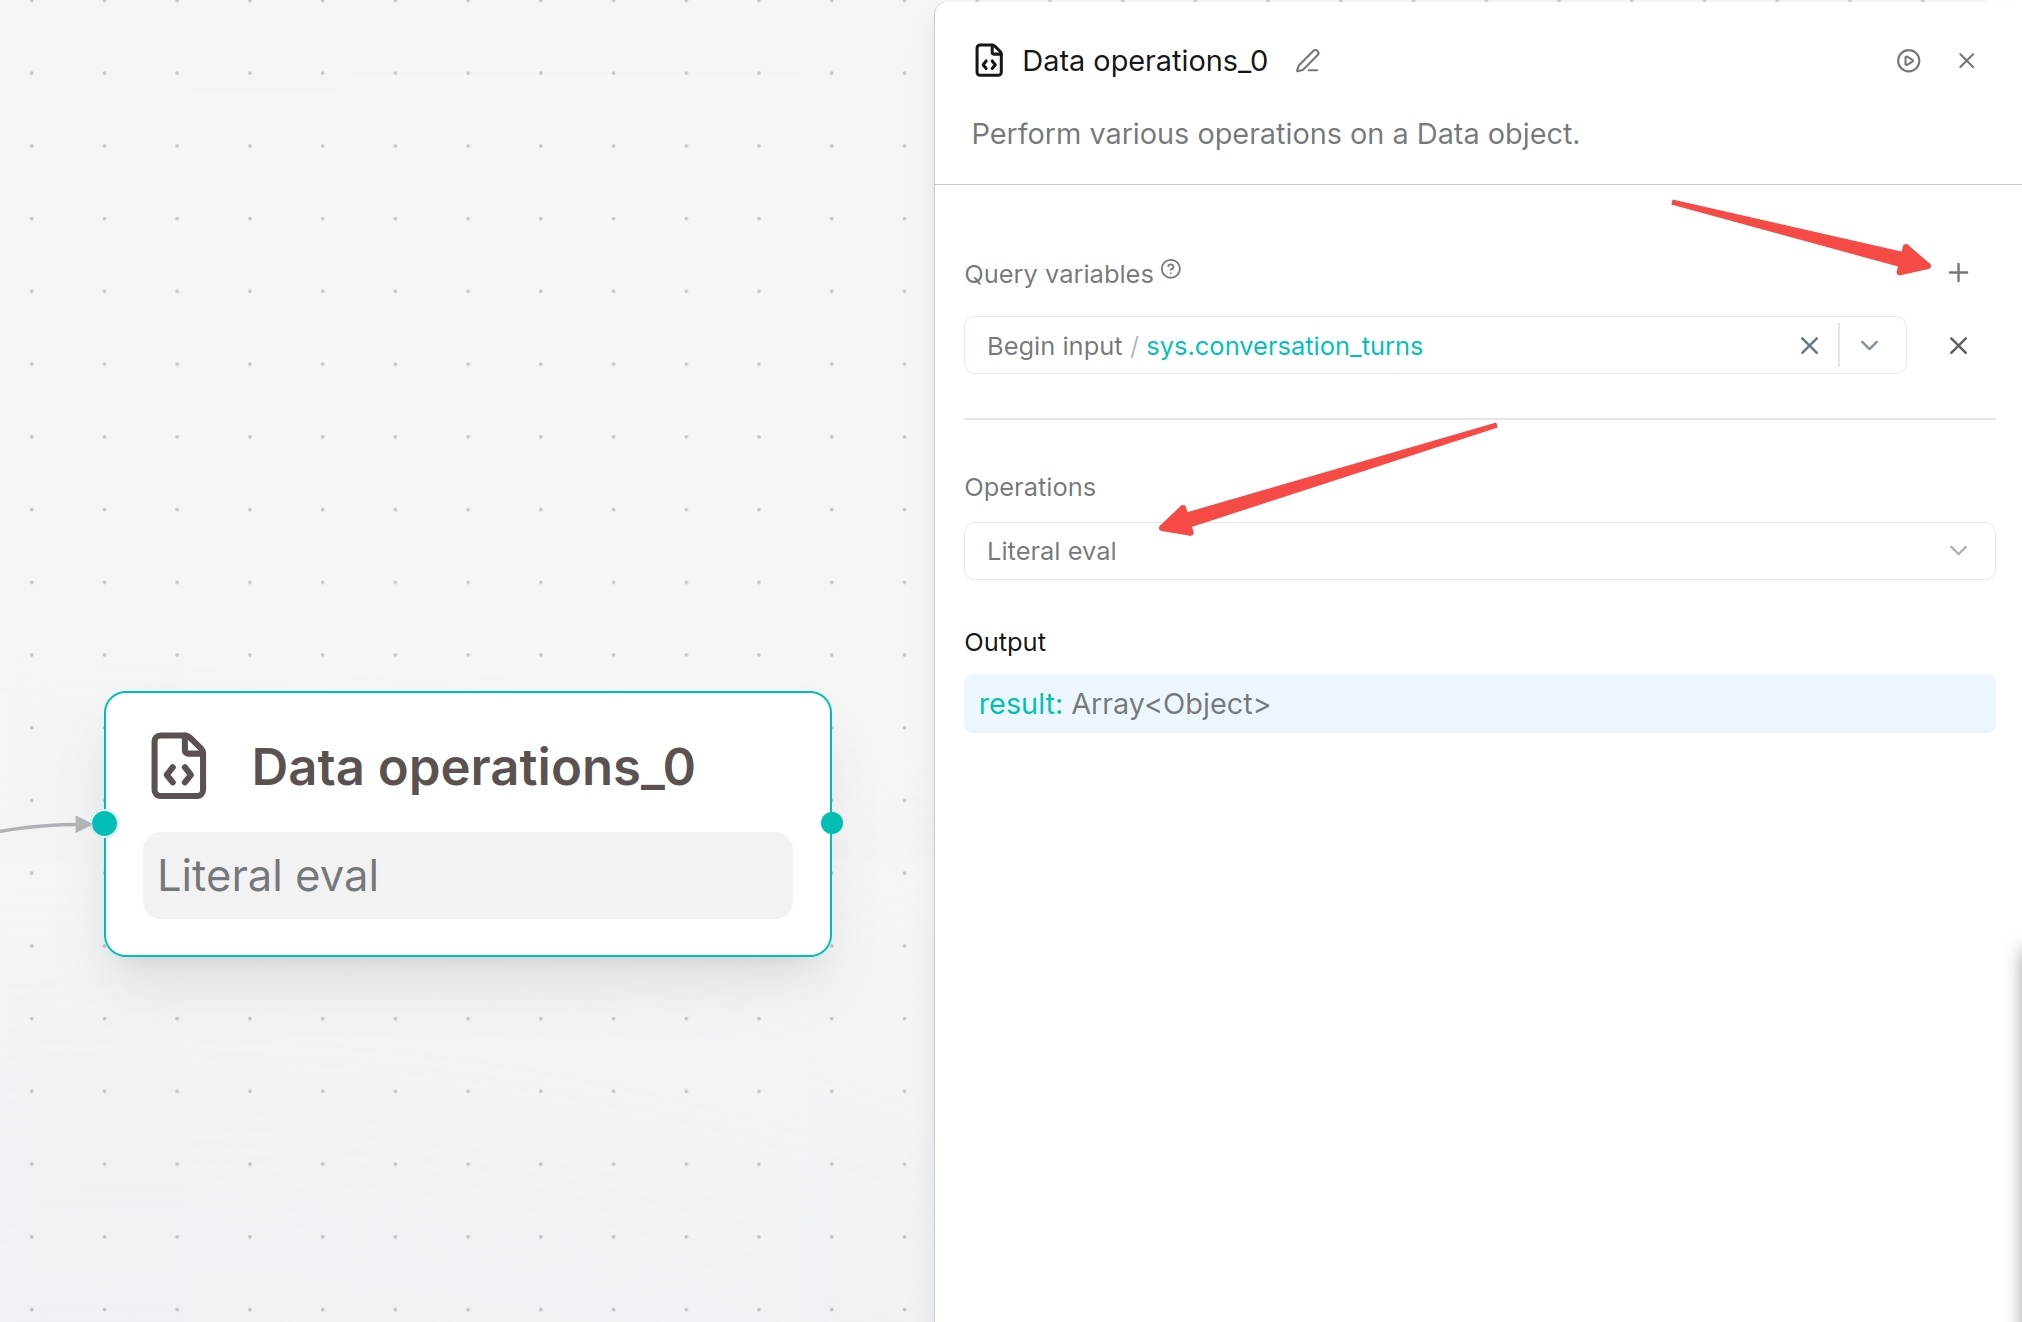Output: Processed data stored in variable `result`.-Supported Operations:-| Operation | Function | Scenario |+Supported operations:+| Operation | Function | Example || ---- | ---- | ---- |-| Select keys | Keep only specified fields | Extract required fields for downstream nodes |-| Literal eval | Convert string-formatted list/dict/bool/number into actual data types | Parse serialized structured strings |-| Combine | Merge multiple objects into one | Aggregate outputs from multiple upstream nodes |-| Filter values | Filter data matching conditions | Filter array/object collections |-| Append or update | Add new fields or overwrite existing field values | Supplement or modify object attributes |-| Remove keys | Delete specified fields | Remove unnecessary sensitive or unused fields |-| Rename keys | Rename object field keys | Unify field naming standards |+| Select keys | Keep specified fields | Select `name` from `{"name":"Ada","age":30}` to keep `{"name":"Ada"}`. |+| Literal eval | Parse values stored as text | Convert the value `"[1,2]"` in a field to the array `[1,2]`. |+| Combine | Merge input objects | Combine `{"name":"Ada"}` and `{"city":"Paris"}` into one object with both fields. |+| Filter values | Keep matching objects | Set `status` **Equals** `active` to keep only objects with that field value. |+| Append or update | Add or replace a field | Set `city` to `Paris`; an existing `city` value is replaced. |+| Remove keys | Delete specified fields | Remove `age` from `{"name":"Ada","age":30}` to keep `{"name":"Ada"}`. |+| Rename keys | Change field names | Rename `name` to `customer_name`; its value stays the same. |-## Variable Assignor Component-Variable Assignor writes or updates variables during workflow execution. It can save upstream results to target variables and support overwrite, clear, append and arithmetic operations for numbers, arrays and objects.+## Variable Assigner Component+Variable Assigner updates a target variable during workflow execution. Available operations depend on the selected variable type.Configuration Steps:-1. Click the **Variable Assigner** component and add a new variable rule under **Variables**.+1. Click the **Variable assigner** component and add a new variable rule under **Variables**.2. Select the target variable to be updated.-3. Select an assignment operation, such as **Overwrite**, **Set**, **Append**, or **Add**.+3. Select an operation from the list available for that variable type.4. If the selected operation requires a value, select a variable from the right panel or enter a fixed value.5. To update multiple variables at once, continue adding variable rules. The system will execute them sequentially in the order they are added.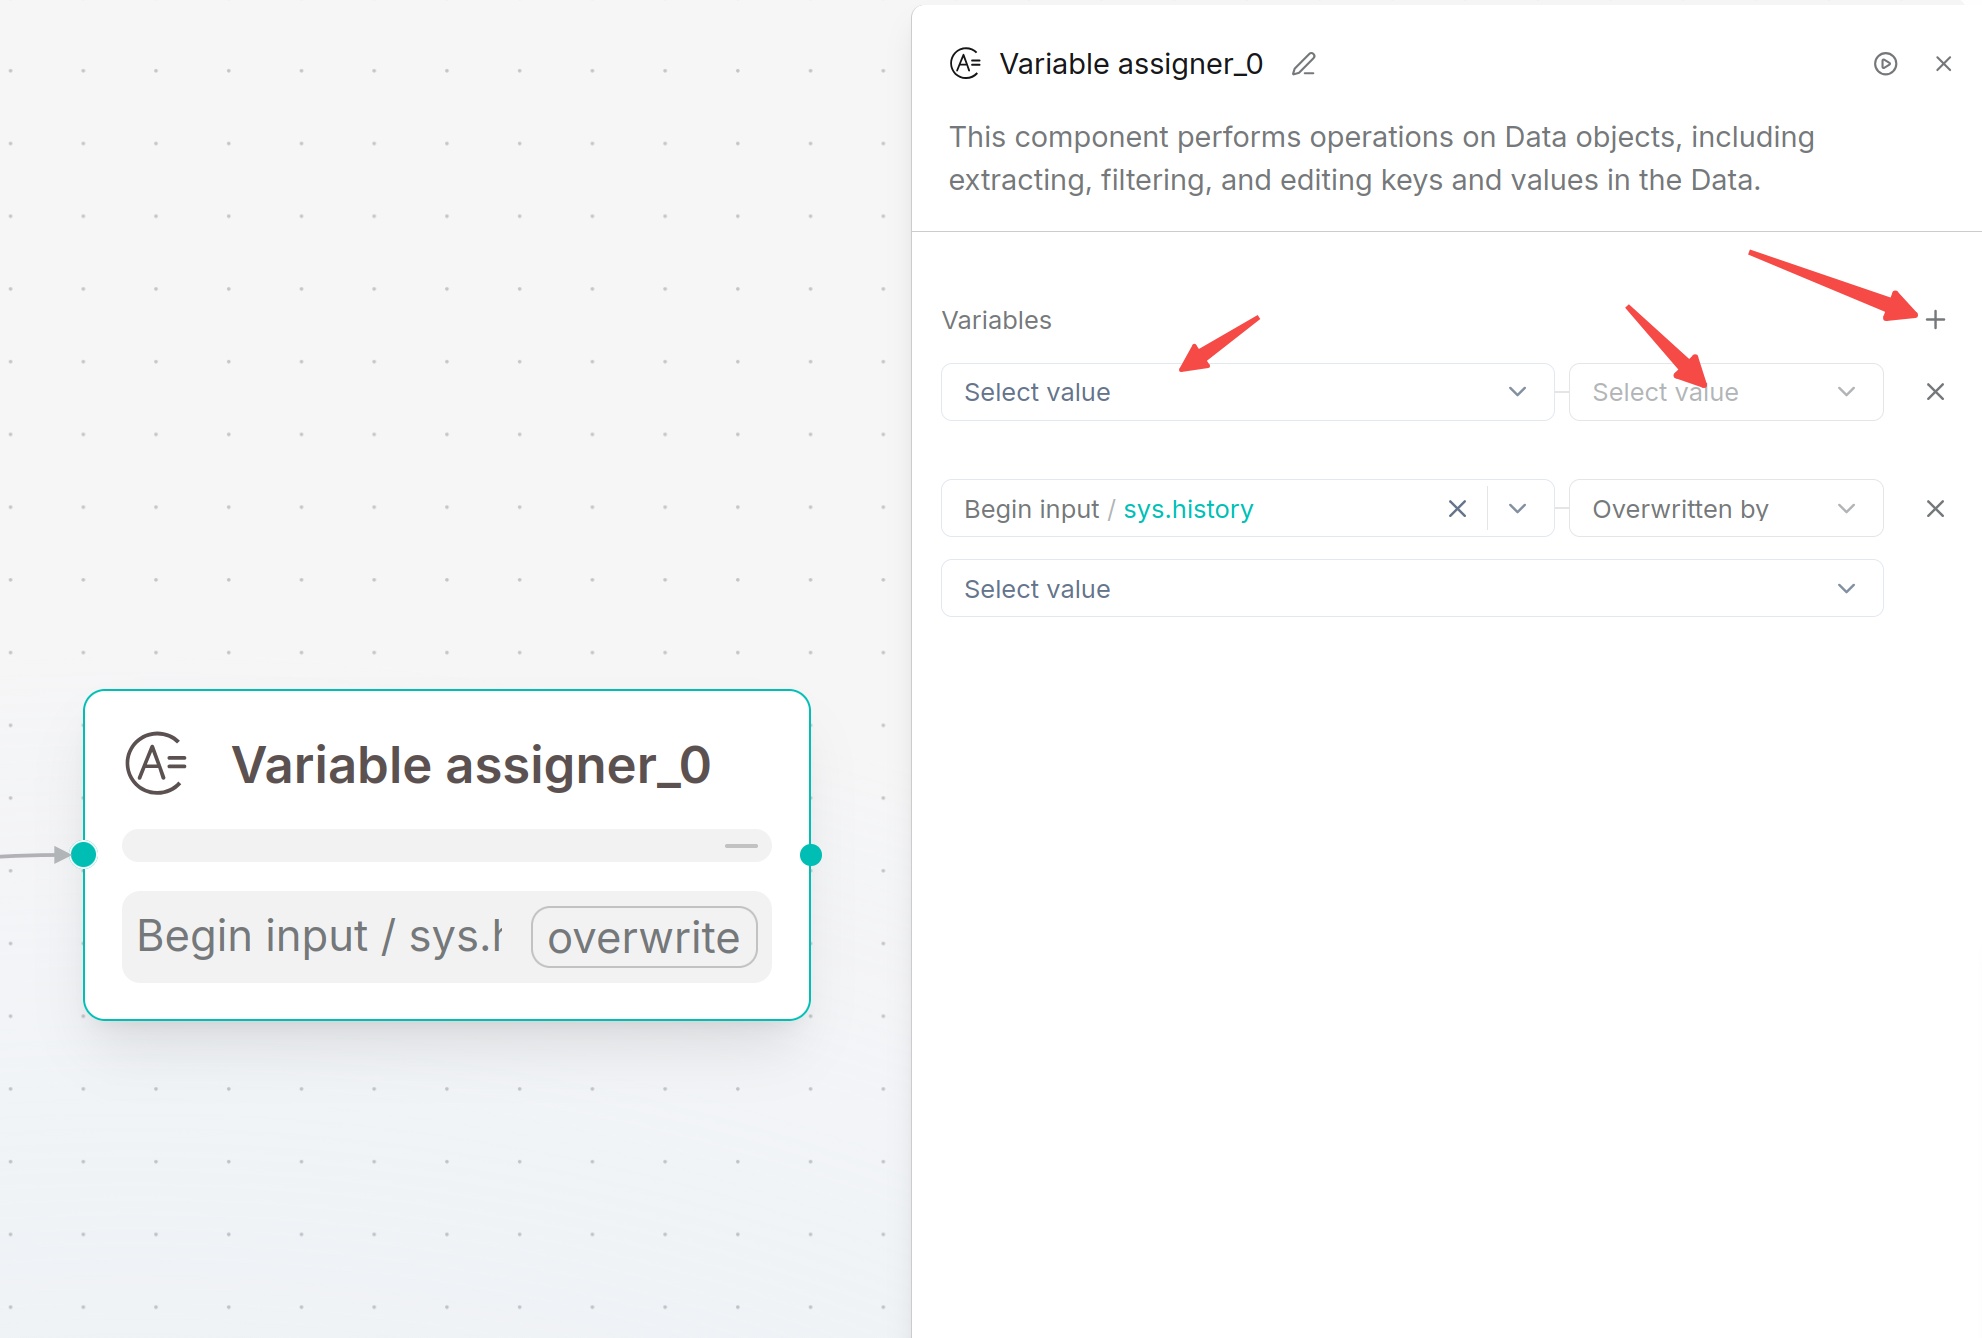-Parameter Description:+Parameter description:| Parameter | Type | Required | Description ||---|---|---|---|-| Target Variable | Variable | Yes | Select the variable to be written or updated. Supports component output variables, system variables, environment variables, session variables, and other variable types. |+| Target Variable | Variable | Yes | Select a target from the variable selector, such as a Begin input or Conversation variable. The selected type determines the available operations. || Operation | Enum | Yes | Select the operation to be performed on the target variable. The system will automatically display available operations based on the variable type. || Value | Variable / Constant | Conditional | The value used for the operation. You can select another variable or enter a fixed value (depending on the supported operation type). Some operations do not require a value. |-Supported Operations:-| Operation | Requires Value | Description |-| ---- | ---- | ---- |-| Overwritten by | Yes | Overwrite target variable with another variable's value |-| Set | Yes | Assign fixed constant value to target variable |-| Clear | No | Empty the target variable |+Supported operations by target type:++| Target type | Available operations |+| --- | --- |+| Text | **Overwritten by**, **Clear**, **Set** |+| Number | **Overwritten by**, **Clear**, **Set**, **Add**, **Subtract**, **Multiply**, **Divide** |+| Array | **Overwritten by**, **Clear**, **Append**, **Extend**, **Remove first**, **Remove last** |++**Overwritten by** uses another variable; **Set** assigns a constant. **Append** adds one element, while **Extend** adds elements from another array. **Clear**, **Remove first**, and **Remove last** do not require a value. Fill the value or variable selector shown for other operations.-## List Operation Component-List Operation processes array data, supporting element extraction, head/tail fetching, filtering, sorting and deduplication. Suitable for array outputs from Begin, HTTP Request, Code and SQL.+## List Operations Component+The **List operations** component extracts, filters, sorts, or deduplicates array data. Select an array from an upstream component; parse HTTP Request text into an array before using it here.-Configuration Steps:-1. Add the **List** component to the canvas and select it.+Configuration steps:+1. Add the **List operations** component to the canvas and select it.2. In the **Query variables** section of the right configuration panel, select the array variable to be processed. Click the dropdown menu and choose an array-type variable from the **Begin** node, upstream nodes, or session variables.3. Select the list processing method in **Operations**.-4. configure the corresponding parameters based on the selected operation.+4. Configure the parameters for the selected operation.5. Enable **Strict mode** if required.6. Save the configuration, then click **Run** on the page to test and view the execution results.7. The processed result will be output through the component and can be referenced by subsequent nodes.-Parameter Description:+Parameter description:| Parameter | Required | Description ||---|---|---|| Query variables | Yes | Select the array variable to be processed. || Operations | Yes | Select the list processing operation. |-| Strict mode | No | When enabled, the system performs strict validation during processing and returns an error if an exception occurs. When disabled, the system processes according to the configured rules. |+| Strict mode | No | For Nth, Head, and Tail, returns an error when N is outside the valid range. When off, Nth can return an empty array and Head/Tail can return the available items. || Operation Parameters | Conditional | Configure the corresponding parameters based on the selected operation, such as N, filter conditions, or sorting rules. |-Supported Operations:-| Operation | Description | Use Case |-|---|---|---|-| Nth | Retrieves an element at a specified position from the list. | Get the Nth item from the list. |-| Head | Retrieves one or more elements from the beginning of the list. | Get the first N items from the list. |-| Tail | Retrieves one or more elements from the end of the list. | Get the last N items from the list. |-| Filter | Filters elements in the list based on conditions. | Keep data that meets the specified conditions. |-| Sort | Sorts the elements in the list. | Sort by specified fields or order. |-| Drop duplicates | Removes duplicate elements from the list. | Deduplicate the list data. |--Operation Configuration Description:+Supported operations:| Operation | Description | Configuration ||---|---|---|-| Nth | Retrieves an element at a specified position from the list. | Configure **N** to specify the element index (starting from 0). |+| Nth | Retrieves an element at a specified position from the list. | Set **N** to a positive position starting from `1`: `N=1` selects the first item. The result is an array containing that item. || Head | Retrieves elements from the beginning of the list. | Configure the return count **N** to return the first N elements. || Tail | Retrieves elements from the end of the list. | Configure the return count **N** to return the last N elements. || Filter | Filters list elements based on conditions. | Configure filter conditions and retain only elements that meet the requirements. || Sort | Sorts elements in the list. | Configure the sorting field and order (ascending or descending). || Drop duplicates | Removes duplicate elements from the list. | No additional configuration required. Returns the deduplicated list. |-Strict Mode:-- Enabled: Return error when input data format is abnormal-- Disabled: Handle abnormal data with default tolerance+For example, with `["red","blue"]`, **Nth** with `N=3` returns an empty array when Strict mode is off and an error when on. **Head** with `N=3` returns both items when off and an error when on.+## Variable Aggregator Component-Variable Aggregator combines multiple independent variables into one output group for unified reference by downstream nodes. Widely used in multi-branch conditional workflows to collect data from different branches.+Variable Aggregator selects a value from candidate variables in each group, providing a common output for downstream nodes after conditional branches. It does not combine all candidate values into an array or merge them into an object.-Configuration Steps:-1. Add the **Variable Aggregator** component to the canvas and select it.+Configuration steps:+1. Add the **Variable aggregator** component to the canvas and select it.2. In the **Variable Group** (default: **Group0**), click **Select value** and choose the variables to be aggregated.3. Click **Add** to add additional variables to aggregate.4. To create a new variable group, click the **+** icon. To delete a variable group, click the delete button.5. Save the configuration, then click **Run** at the top of the page to test the execution result.-6. The aggregated variables will be output through the corresponding variable group name (for example, **Group0**) and can be referenced by subsequent nodes.+6. The selected value is output under the corresponding group name (for example, **Group0**) and can be referenced by subsequent nodes.> **Note**>-> A variable group can contain multiple variables. Multiple variable groups can also be created based on different business requirements for separate aggregation.--Parameter Description:-| Parameter | Required | Description |-|---|---|---|-| Group | Yes | Variable group used to store variables to be aggregated. A default group **Group0** is created automatically, and additional variable groups can be added. |-| Select value | Yes | Select the variables to be aggregated. Supports system variables, **Begin** node inputs, session variables, or output variables from upstream nodes. |-| Add | No | Continue adding variables to the current variable group. |-| + | No | Create a new variable group. |-| Delete | No | Delete the current variable group. |--Output Result:-| Output | Description |-|---|---|-| Group0 (or other variable group name) | Outputs the variables after aggregation in the current variable group. The output can be directly referenced by subsequent nodes. |--Usage Instructions:-| Operation | Description |-|---|---|-| Add Variable | Select variables in **Select value**, then click **Add** to continue adding multiple variables. |-| Create Variable Group | Click the **+** icon to create a new variable group. |-| Delete Variable Group | Click the delete button for the variable group to remove the current group. |-| Reference Output | Subsequent nodes can directly reference the variable group (for example, **Group0**) as an input. |+> Each group selects the first value in configuration order, skipping missing values, `false`, `0`, empty text, and empty collections. If all values are skipped, the group returns no value. Use separate groups for separate outputs; use Variable assigner when `0` or `false` must be retained.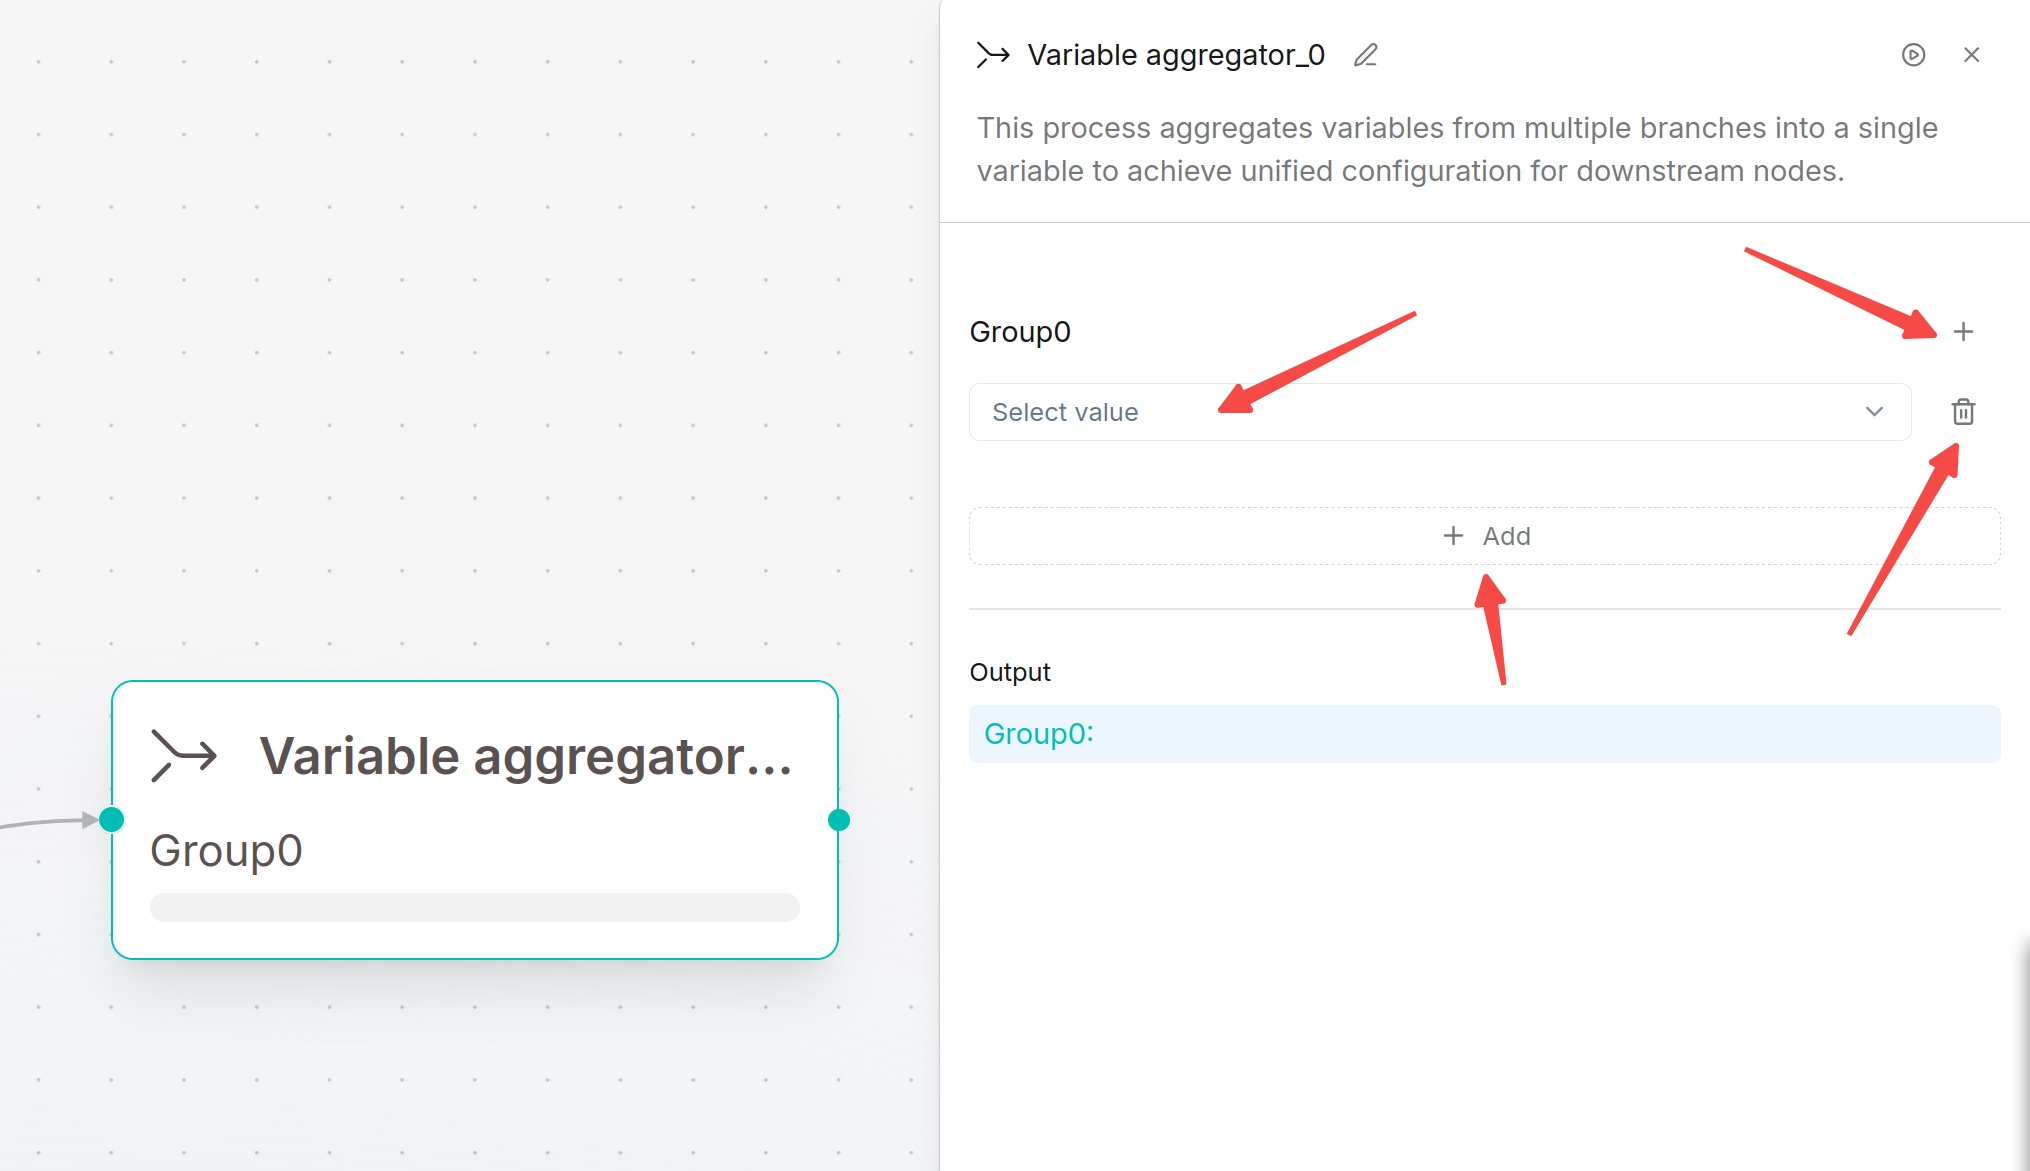diff --git a/docs/guides/agent/agent_workflow/dialogue_component.md b/docs/guides/agent/agent_workflow/dialogue_component.mdindex 31cbbfb807..3dd975a798 100644--- a/docs/guides/agent/agent_workflow/dialogue_component.md+++ b/docs/guides/agent/agent_workflow/dialogue_component.md@@ -10,21 +10,23 @@ sidebar_custom_props: {# Dialogue Component-## Reply Message Component+## Message Component-The message is used to output static or dynamic messages to users, and is usually used as the final component of a workflow. It can directly write fixed text, or insert upstream variables.+Message displays text to the user. Add it at the end of a workflow or branch, then enter fixed text or insert upstream variables.### Configuration MethodWrite the output content in the message. Type `/` or click the variable button to insert component outputs.-If multiple messages are added, the system randomly selects one of them to send. When the `Begin` component selects `Webhook` and the response method is `Final response`, the reply message component can set an HTTP status code in the range of 200 to 399.+If multiple messages are added, they are combined and sent together. When the `Begin` component selects `Webhook` and the response method is `Final response`, Message can set an HTTP status code in the range of 200 to 399.-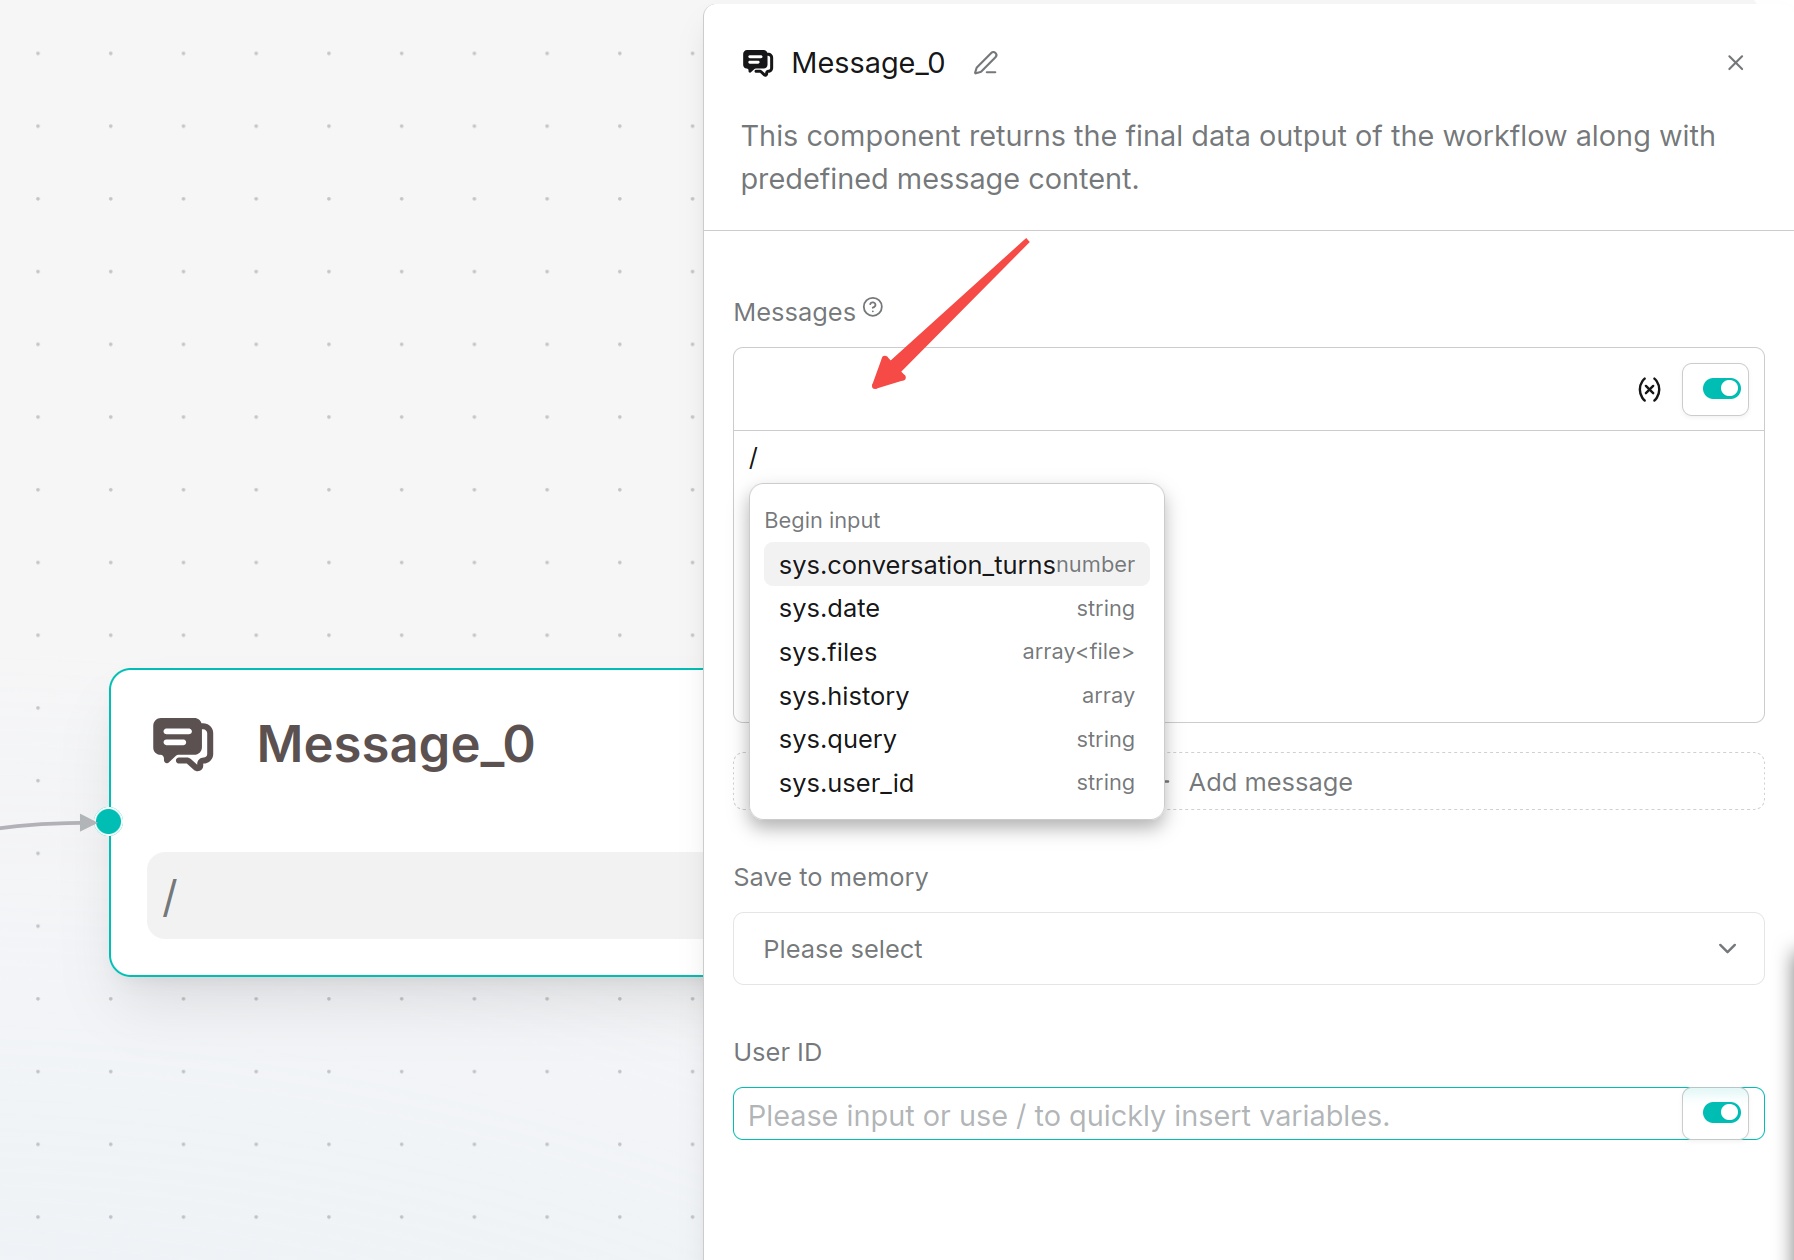+### Save to Memory-The reply message component can choose to save to memory, storing the conversation in the specified memory. After enabling **User ID**, conversations can be associated with user IDs, and subsequent knowledge retrieval can query related memories by user ID.+1. In Message, select a memory under **Save to Memory**. [Create a memory](../../memory/create_memory.md) first if needed.+2. Enter a stable **User ID**, such as `customer-001`, or insert a variable containing it. Run the Agent, then check the memory's **Messages** page.+3. In Retrieval, select **Memory**, choose the same memory, and use the same **User ID** to retrieve that user's records. Set the query to `sys.query` and pass `formalized_content` to the next Agent component.### Applicable Scenarios@@ -34,13 +36,13 @@ This component is suitable for outputting final answers, branch hints, fallbackThe message outputs the configured text or variable content to the conversation window, webhook response, or embedded page.-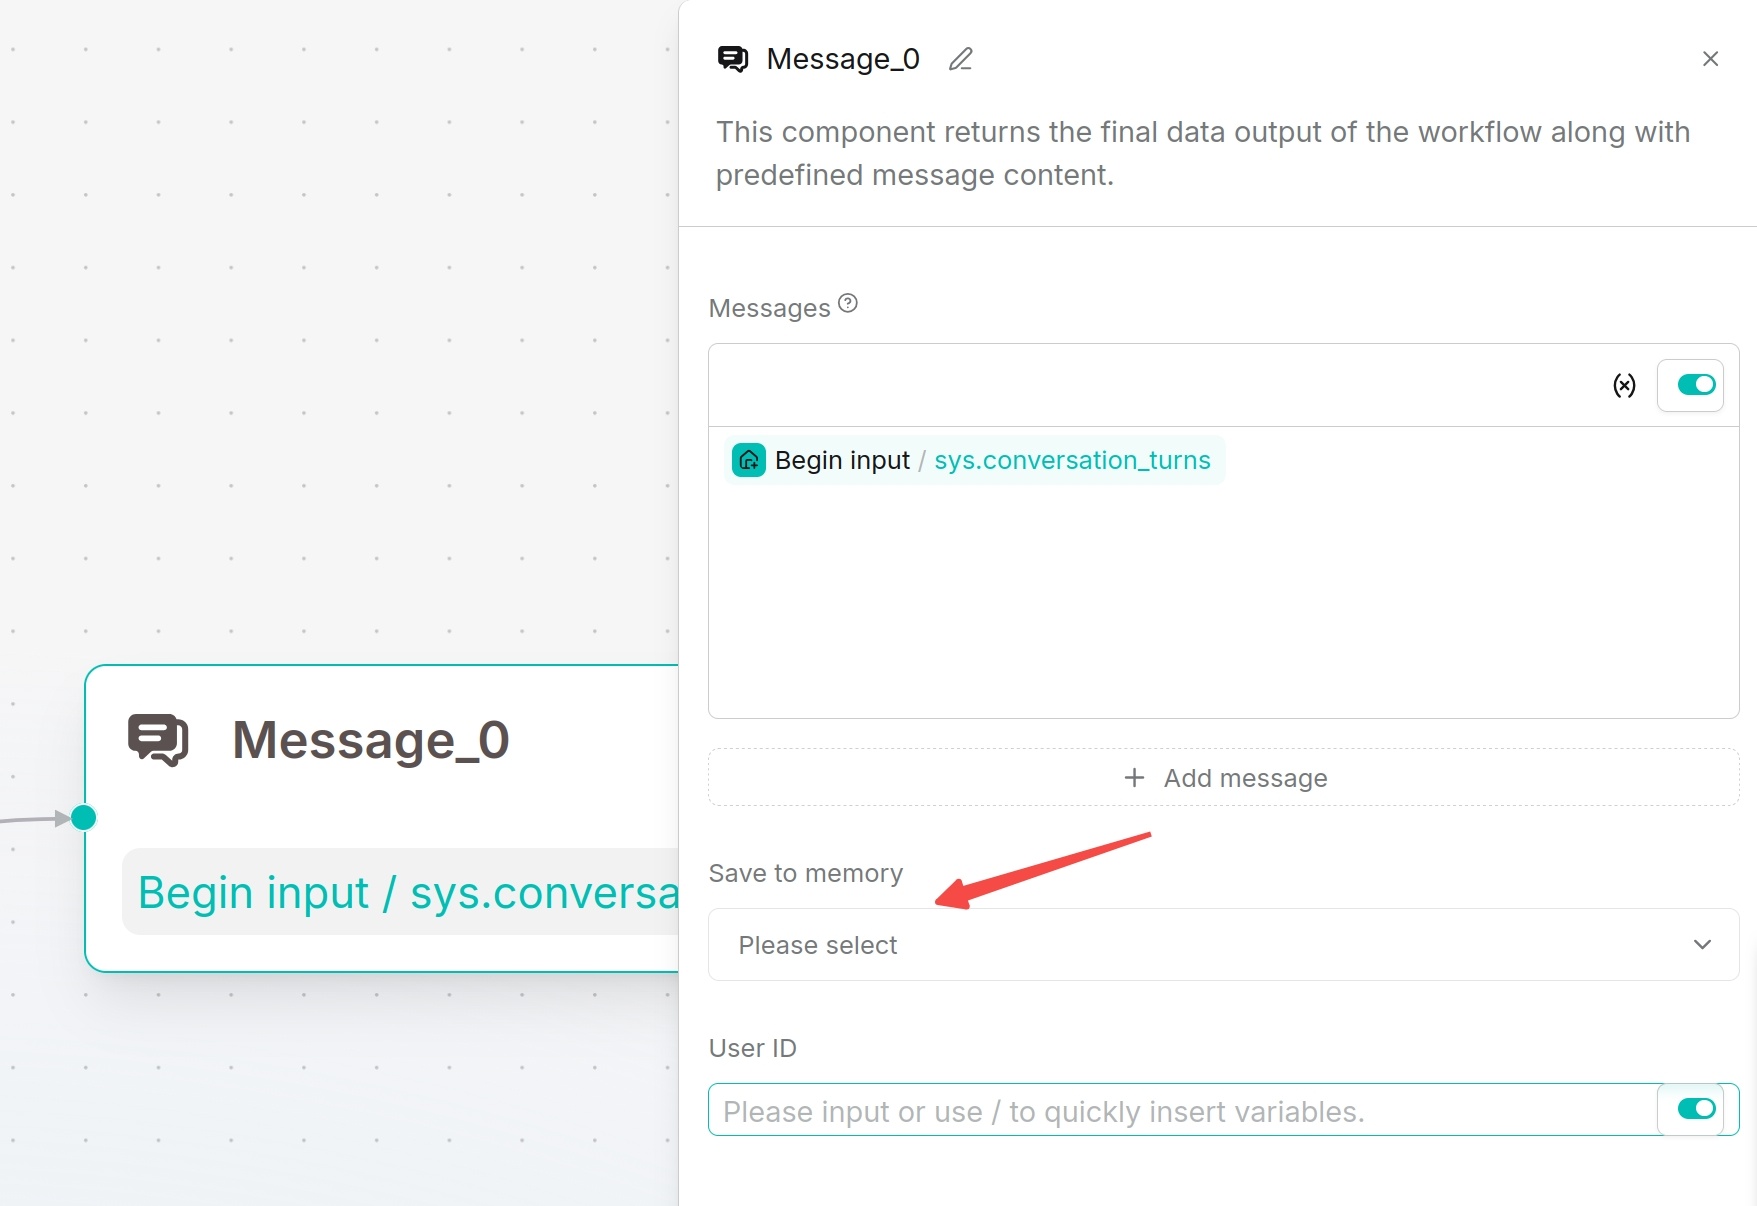+## Await Response ComponentAwait Response pauses the workflow and waits for users to supplement information. Suitable for multi-turn dialogue, form collection, confirmation operations or file upload requirements.### Configuration Method-Define prompt messages to guide users. Input supports the same variable types as Begin: single-line text, paragraph text, dropdown options, file upload, number and boolean.+Define prompt messages to guide users. Input supports the same variable types as Begin: single-line text, paragraph text, dropdown options, file upload, number, boolean, and JSON object. A File input also displays a parser setting.Recommendations:- Dropdown options: Select business categories@@ -48,4 +50,18 @@ Recommendations:- File upload: Receive contracts, reports or screenshots- Boolean: Confirm continue/cancel operations+### Example: collect appointment details++To collect details for an installation visit, enable **Guiding question** and enter `Please enter your name and preferred installation time.` Add these Input fields:++| Name | Type | Key | Optional |+| --- | --- | --- | --- |+| Name | Single-line text | `customer_name` | Off |+| Preferred installation time | Single-line text | `appointment_time` | Off |+| Notes | Paragraph text | `notes` | On |++**Name** is the label shown to the user; **Key** identifies the value for later references. Turning **Optional** off makes a field required.++Connect a **Message** after Await Response. Insert `customer_name` and `appointment_time` from the Await Response outputs using the variable selector. Run the workflow, submit the form, and check that execution resumes with those values. This example collects installation preferences; it does not book a service visit.+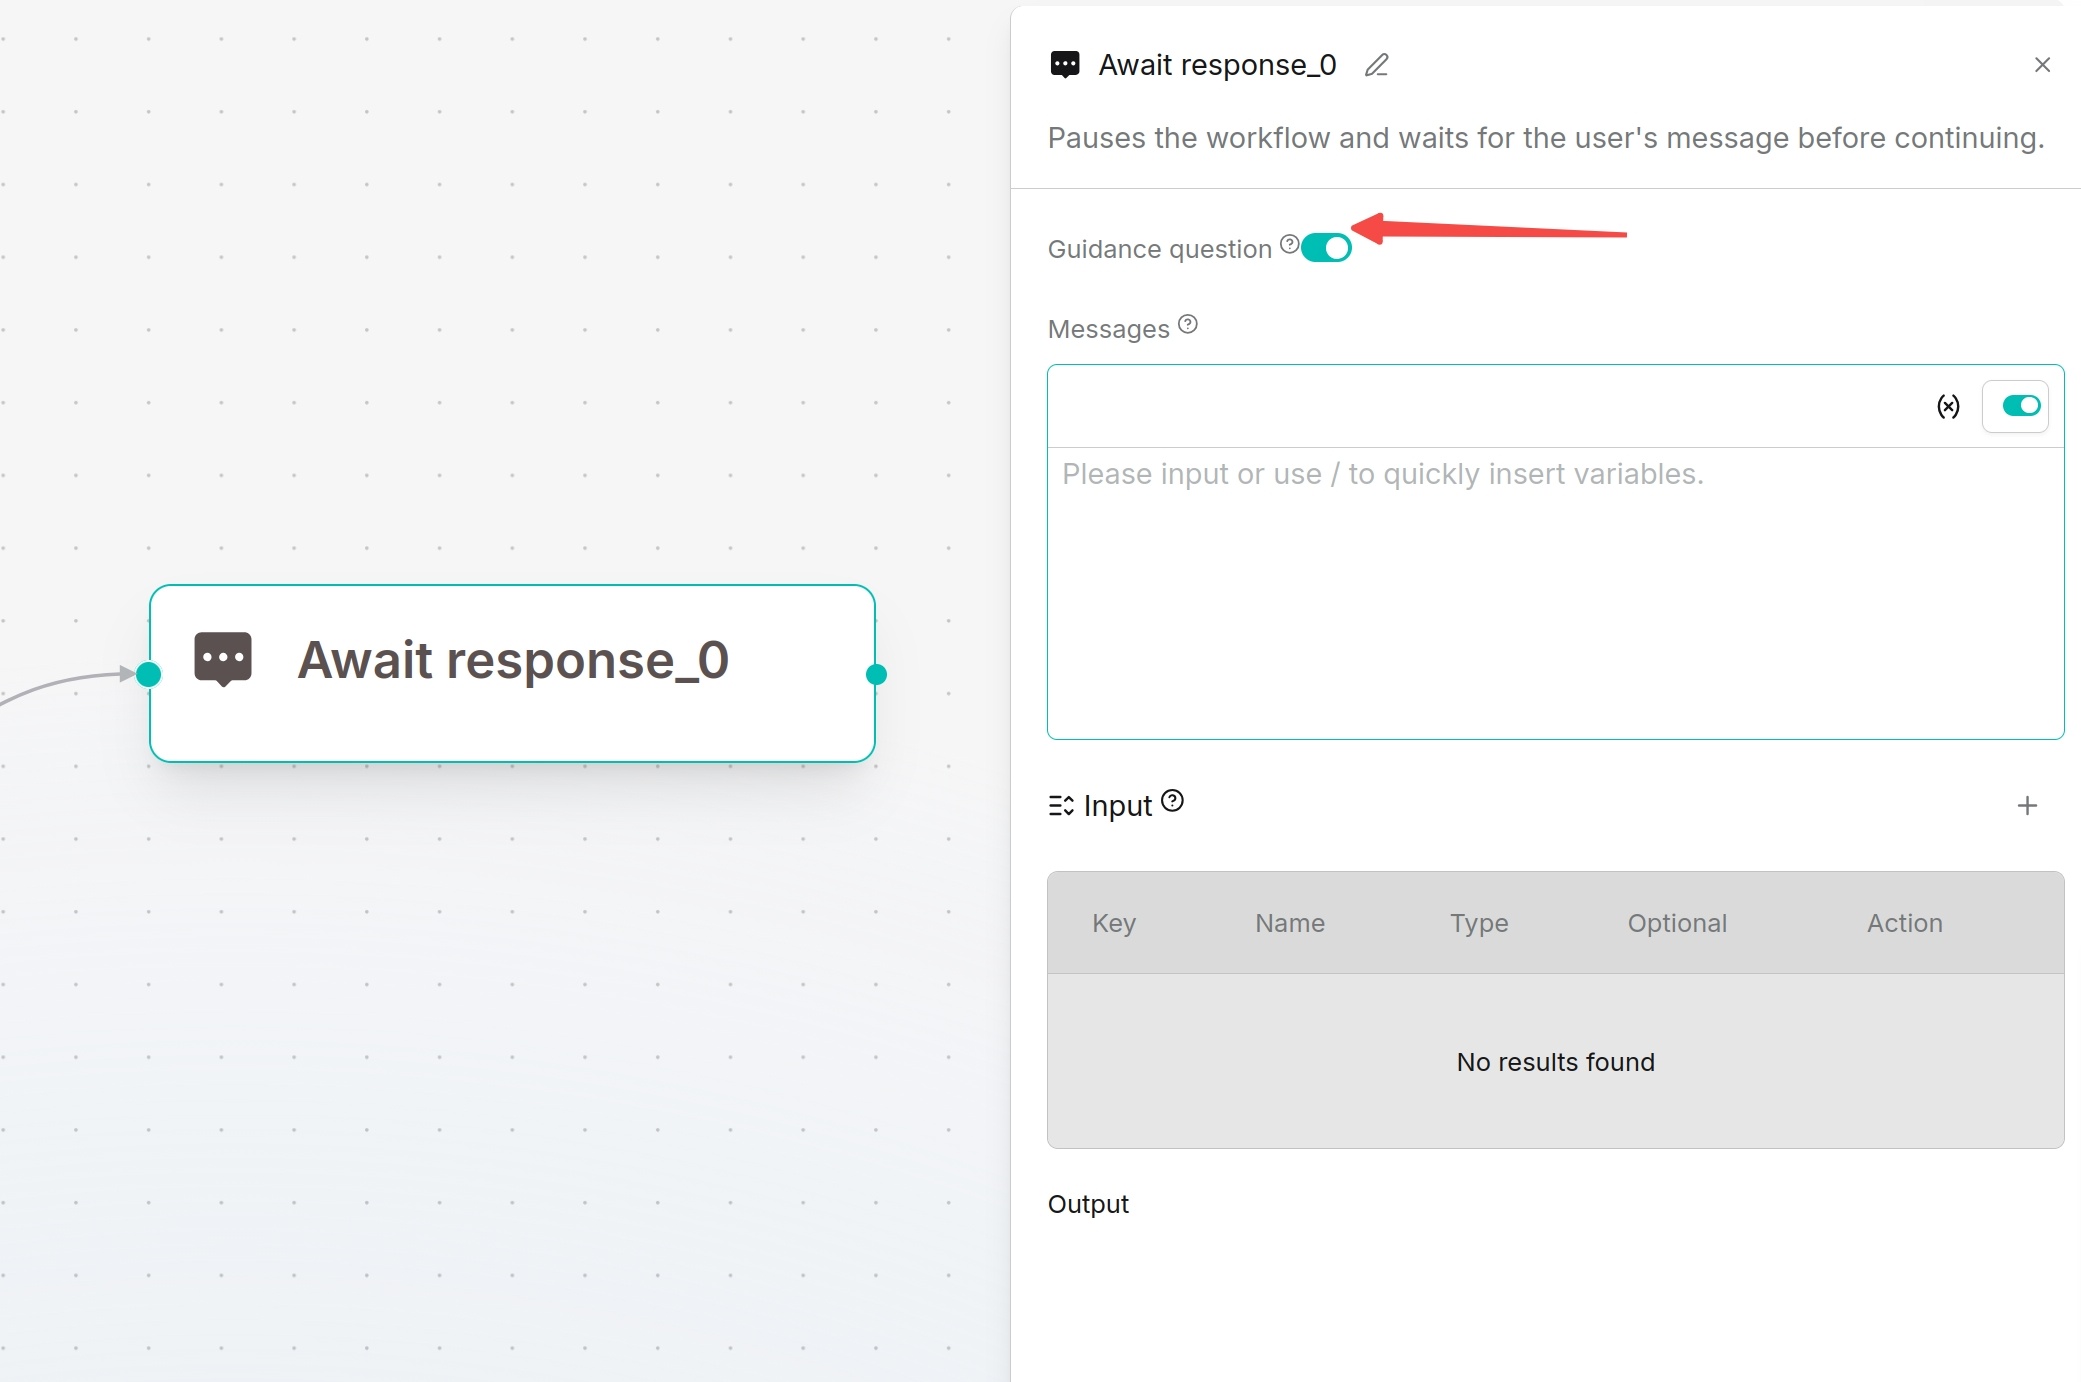diff --git a/docs/guides/agent/agent_workflow/flow_components.md b/docs/guides/agent/agent_workflow/flow_components.mdindex fd91123178..0edfbc21fb 100644--- a/docs/guides/agent/agent_workflow/flow_components.md+++ b/docs/guides/agent/agent_workflow/flow_components.md@@ -20,53 +20,83 @@ At least one Case must be defined. Each Case can contain multiple conditions comSwitch is rule-based judgment for structured data and clear conditions. Categorize uses LLM-based classification for natural language intent recognition.:::+### Example: route an order by quantity++Connect **Begin → Switch**, with a Message on each Switch branch.++1. In Begin, add a required **Number** input with key `quantity` and name Quantity.+2. In Switch, add a Case. Use the variable selector to choose Begin's `quantity`, select **Greater equal**, and enter the constant `10`. Connect this Case to a Message containing `Bulk order`.+3. Connect the default branch to a second Message containing `Standard order`.+4. Save and click **Run**. Entering `12` should display Bulk order; entering `2` should display Standard order.+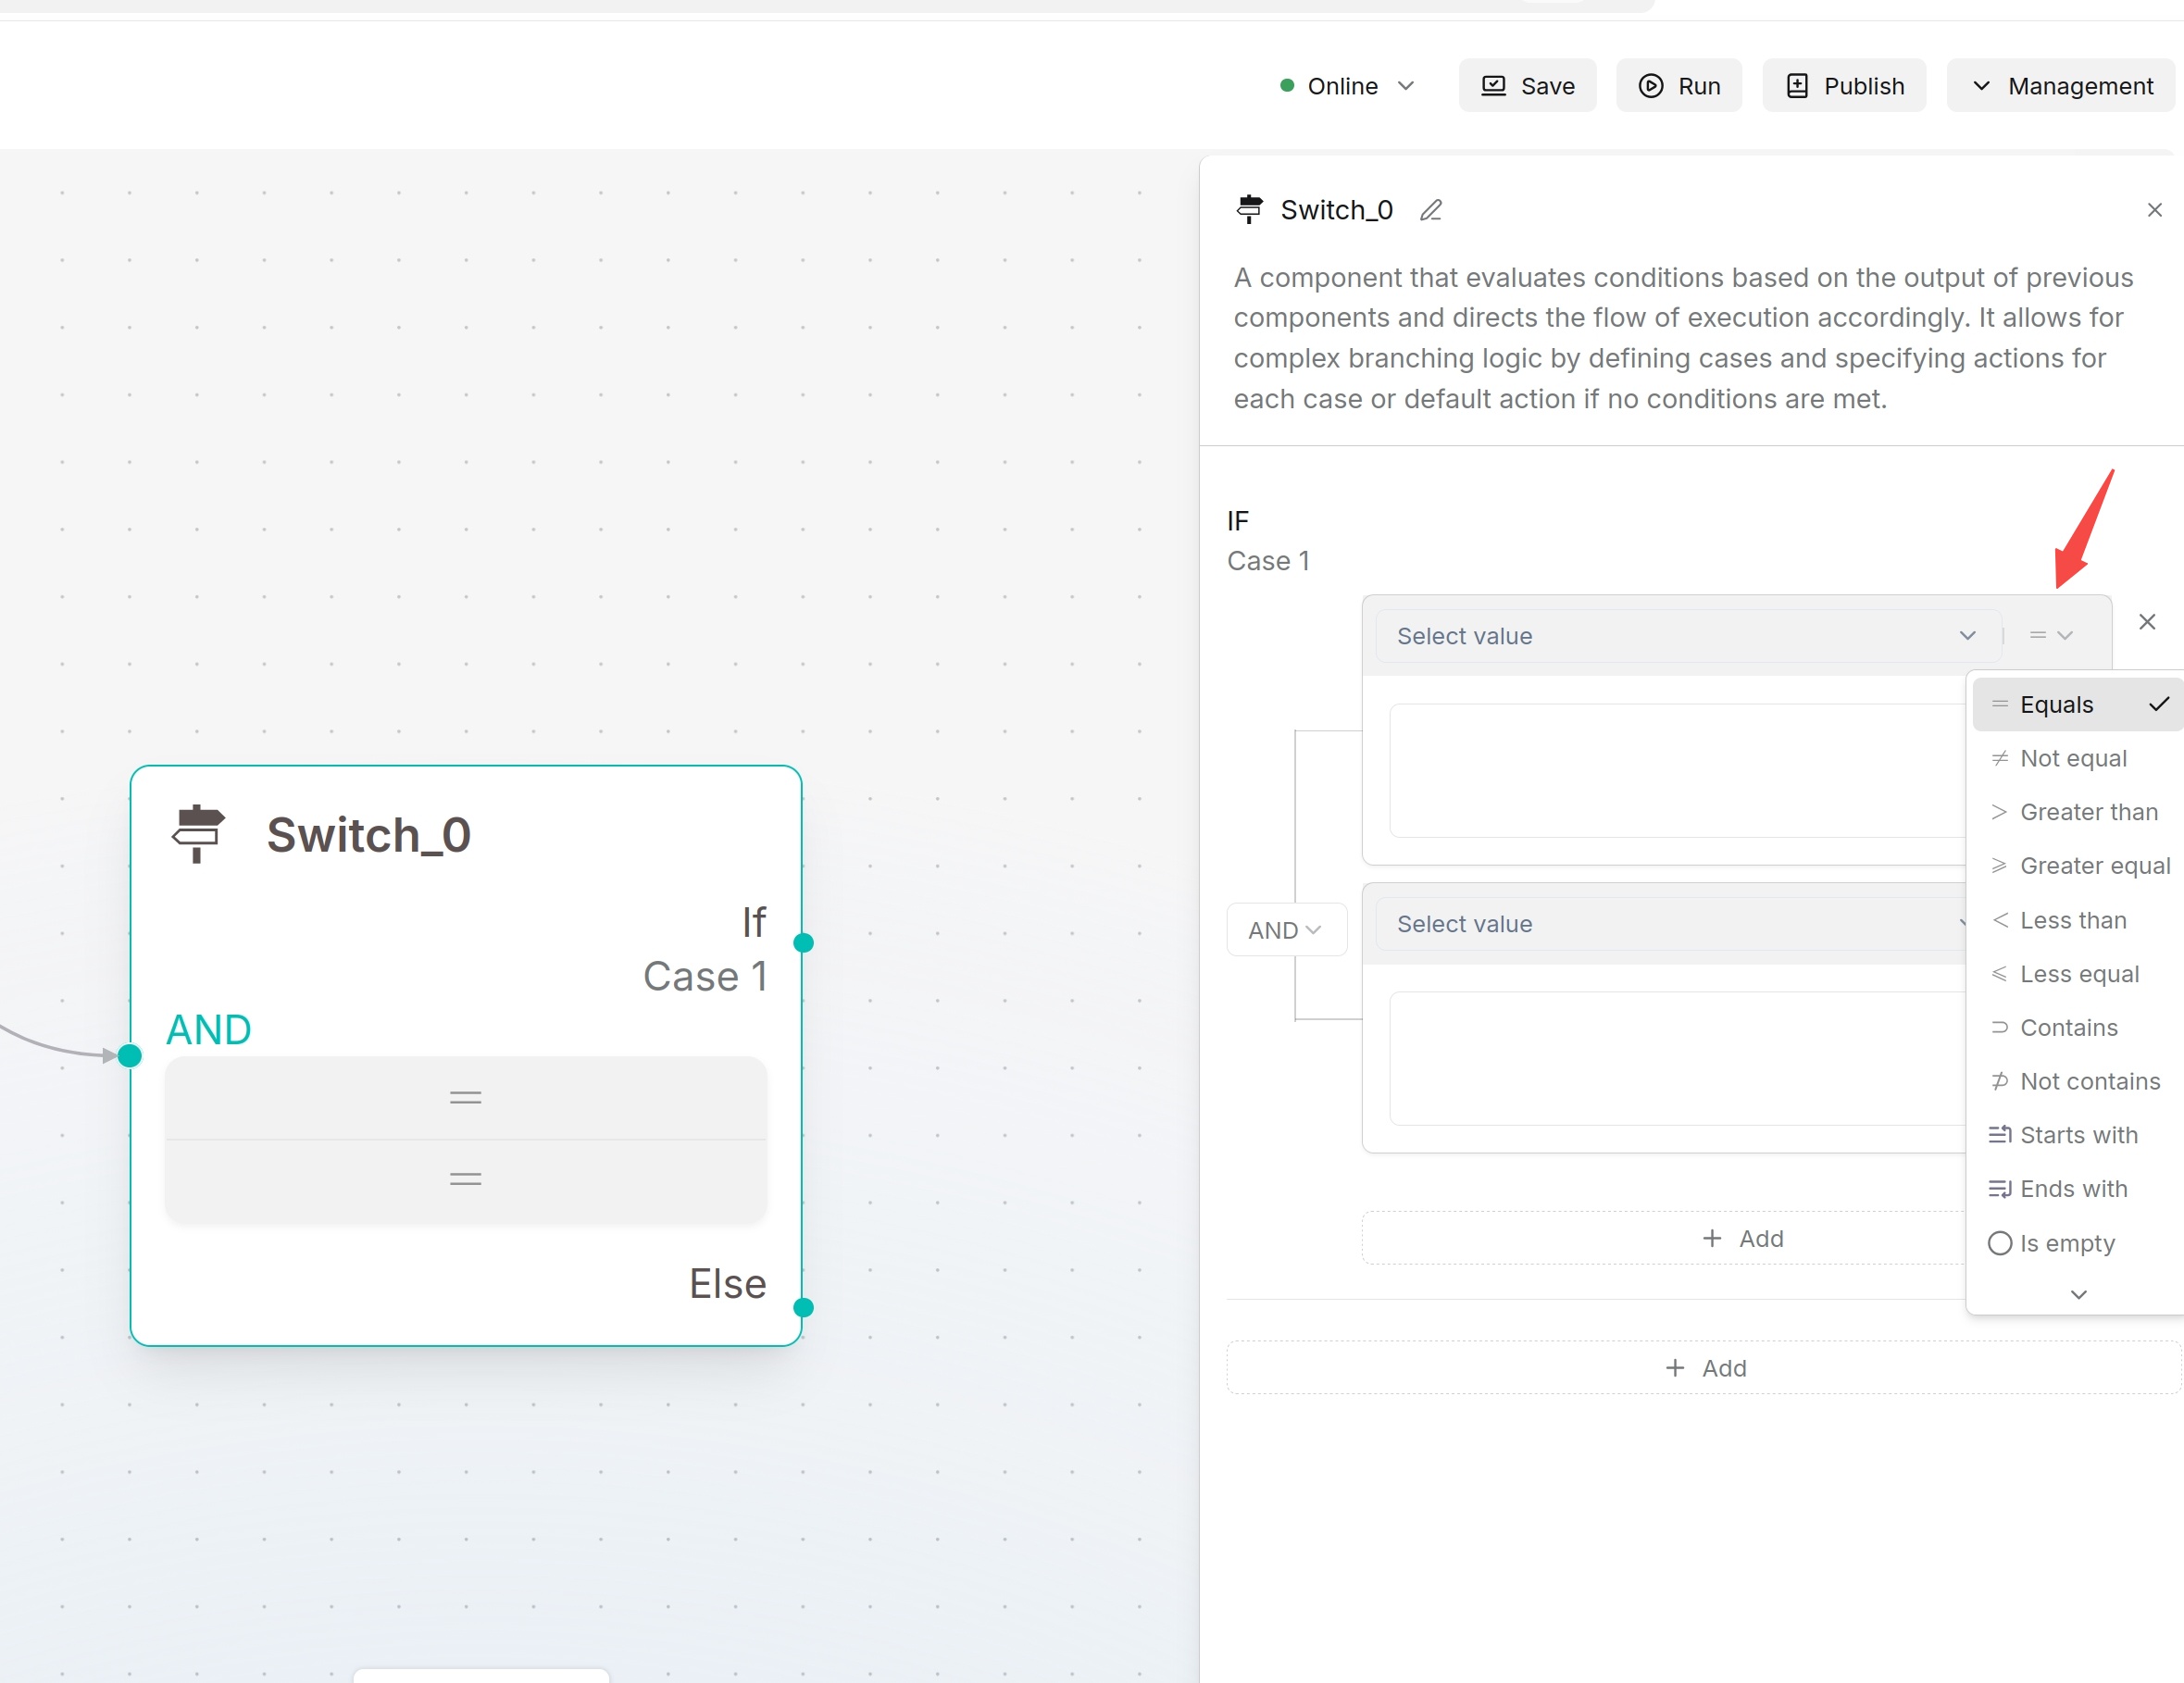-### Iteration-The Iteration component iterates over an array and repeatedly executes the same processing logic for each element. It is suitable for scenarios such as batch file processing or processing multiple data items with the same logic.+## Iteration Component+Iteration runs the same steps for each item in an array, such as a list of files or records.-#### Configuration-When configuring the Iteration component, set **Query variables** and **Output**.-- **Query variables**: Specifies the array variable to iterate over. You can select an array output from an upstream component or a system variable, such as `sys.files` or `sys.history`. The Iteration component processes each element in the array in sequence and executes the configured internal workflow.-- **Internal workflow**: Add the components to be repeatedly executed inside the Iteration area. In each iteration, the internal workflow processes the current array element until all elements in the array have been processed.-- **Output**: Defines the results returned by each iteration. You can add one or more output fields and select variables generated by components inside the Iteration as their values. After all iterations are completed, the component aggregates the results and makes them available to downstream components.+### Configuration+When configuring the Iteration component, set **Query variables**, **Maximum concurrency**, and **Output**.+- **Query variables**: Select an upstream array or a system array such as `sys.files`.+- **Maximum concurrency**: Defaults to `0`. Both `0` and `1` run sequentially; larger values enable bounded concurrency. Results retain input order.+- **Internal workflow**: Add the steps that process each item inside Iteration.+- **Output**: Name each output and select a result from an inner component. Iteration collects these results into arrays.-> **Note**->-> The Iteration component is suitable when the input is an array and each element can be processed independently. For example, by selecting `sys.files`, you can process multiple files uploaded by the user one by one.+### Example: label each color-## Loop Component-Iteration splits text into fragments and executes the same set of internal components for each fragment. Suitable for long-text translation, paragraph-wise summarization, batch generation and item-by-item list processing.+Connect **Begin → Text processing → Iteration → Message**. Inside Iteration, connect its start node to another Text processing component.++1. Leave Begin without additional inputs. Set the outer Text processing component to **Split**, select `sys.query`, and use a comma as the delimiter.+2. In Iteration, select the Split component's `result` as **Query variables** and set **Maximum concurrency** to `1`.+3. Set the inner Text processing component to **Merge**. In **Script**, enter `Color: ` and insert the iteration start node's `item` through the variable selector.+4. In Iteration's **Output**, add a field named `colors` and select the inner Text processing component's `result`. In the outer Message, insert Iteration's `colors` output.+5. Save and run with `red,blue`. The output should contain Color: red and Color: blue in that order.-### Internal Workflow:-Iteration contains built-in `Loop Item`. Components dragged inside Iteration can only be accessed within the loop. Reference `Loop Item` to obtain current fragment data.+## Loop Component+Loop repeats an internal workflow using loop variables, a termination condition, and a maximum loop count. It is suitable for tasks that refine a result across multiple rounds. Loop does not automatically split text into fragments; use Iteration to process an existing array of items.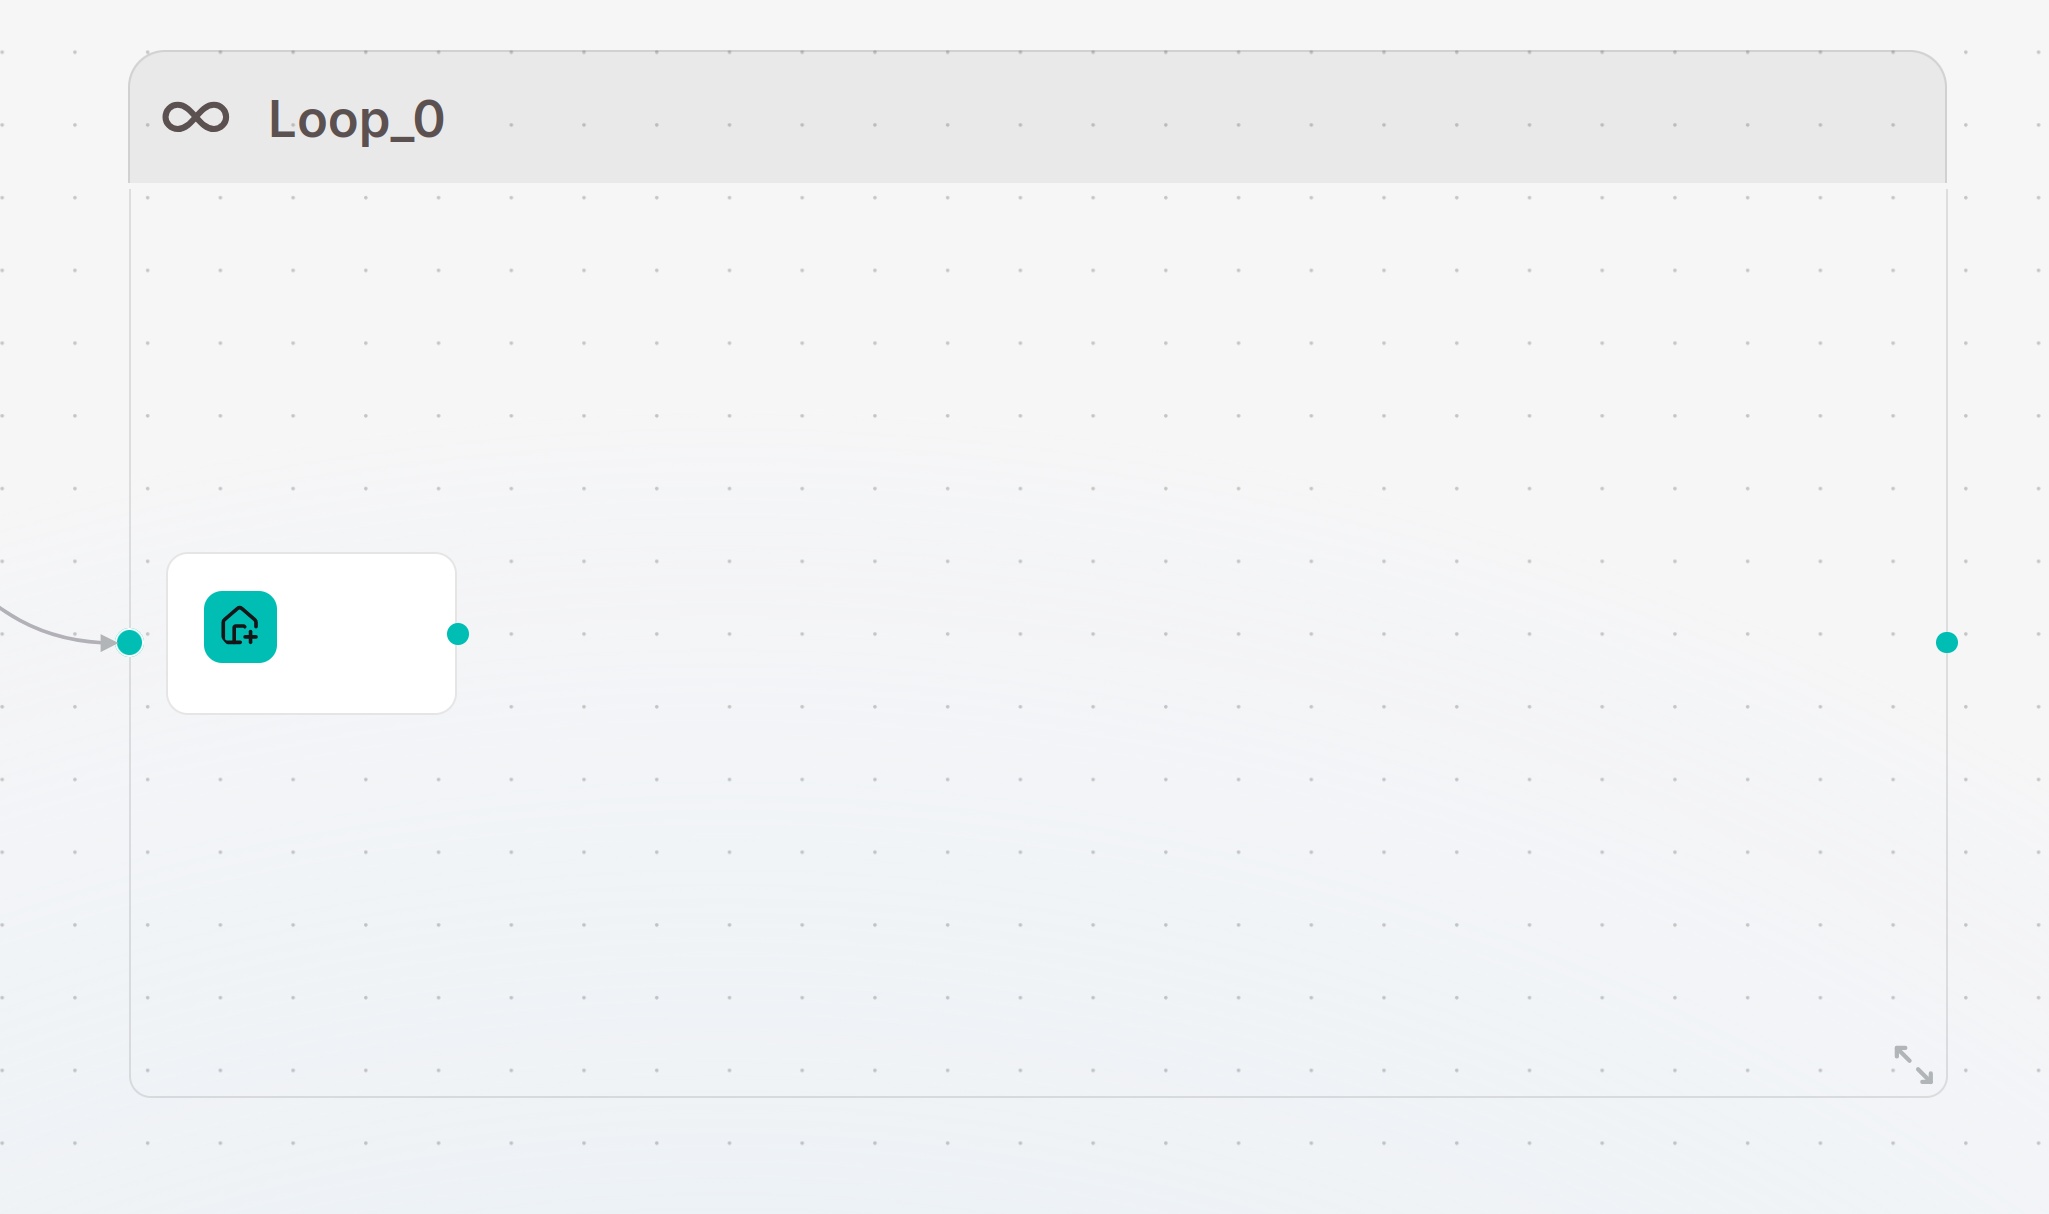### Configuration Method-###### **Configuration**When configuring the Loop component, you need to set the loop variables, loop termination condition, and maximum loop count.- **Loop variables**: Define the variables used during the loop. Set the variable name, type, and initial value. Other components within the loop can read or update these variables.- **Loop termination condition**: Defines the condition for exiting the loop. When the condition is met, the Loop stops. Otherwise, it continues to the next iteration.-- **Maximum loop count**: Limits the maximum number of loop iterations to prevent an infinite loop if the termination condition is never met. The Loop automatically stops when the maximum loop count is reached.+- **Maximum loop count**: Sets how many times the workflow can repeat. The default is `10`, with a supported range of `1`–`100`. After importing a workflow, check this field and set a positive limit. A missing value or `0` leaves the loop without a count limit, so it stops only when its termination condition is met.:::tip NOTEConfigure both termination condition and maximum loop count to avoid long-running infinite loops.:::+### Example: repeat three times++Connect **Begin → Loop → Message**. Inside Loop, connect its start node to **Variable assigner**.++1. Leave Begin without additional inputs. In Loop, add a **Number** loop variable named `counter`, select a constant initial value of `0`, and set **Maximum loop count** to `5`.+2. Set the termination condition to `counter` **Greater equal** the constant `3`.+3. In Variable assigner, select the Loop variable `counter`, choose **Add**, and enter the constant `1`.+4. Set the outer Message to `Loop completed`. Save and click **Run** to start the workflow. The run results should show three executions of Variable assigner, followed by Loop completed.## Categorize ComponentCategorize uses LLM to judge user intent or input category and branch the workflow based on classification results.### Configuration Method-1. Select content to classify in Query variable / Input.-2. Select model and Creativity.-3. Configure message window size (keep default for single-turn classification).-4. Add at least two Categories.-5. Fill clear Name, Description and Examples for each category.-6. Connect downstream components for each classification result on the canvas.+1. Select the input in **Query variables**, usually `sys.query`.+2. Select **Model**.+3. Set **Message window size**. The panel defaults to `1`.+4. Click **Add category** and enter a name, **Description**, and **Examples**.+5. Connect each category to its downstream component on the canvas.++The output `category_name` contains the selected category name.### Classification Recommendations-Use easy-to-understand category names, such as Product Consultation, Installation Reservation, After-sales Fault, and Other Questions. Examples improve classification stability; provide two or three typical samples for each category.+For workflows that route inputs to different paths, configure two or more categories. Use easy-to-understand category names, such as Product Consultation, Installation Reservation, After-sales Fault, and Other Questions. Examples improve classification stability; provide two or three typical samples for each category.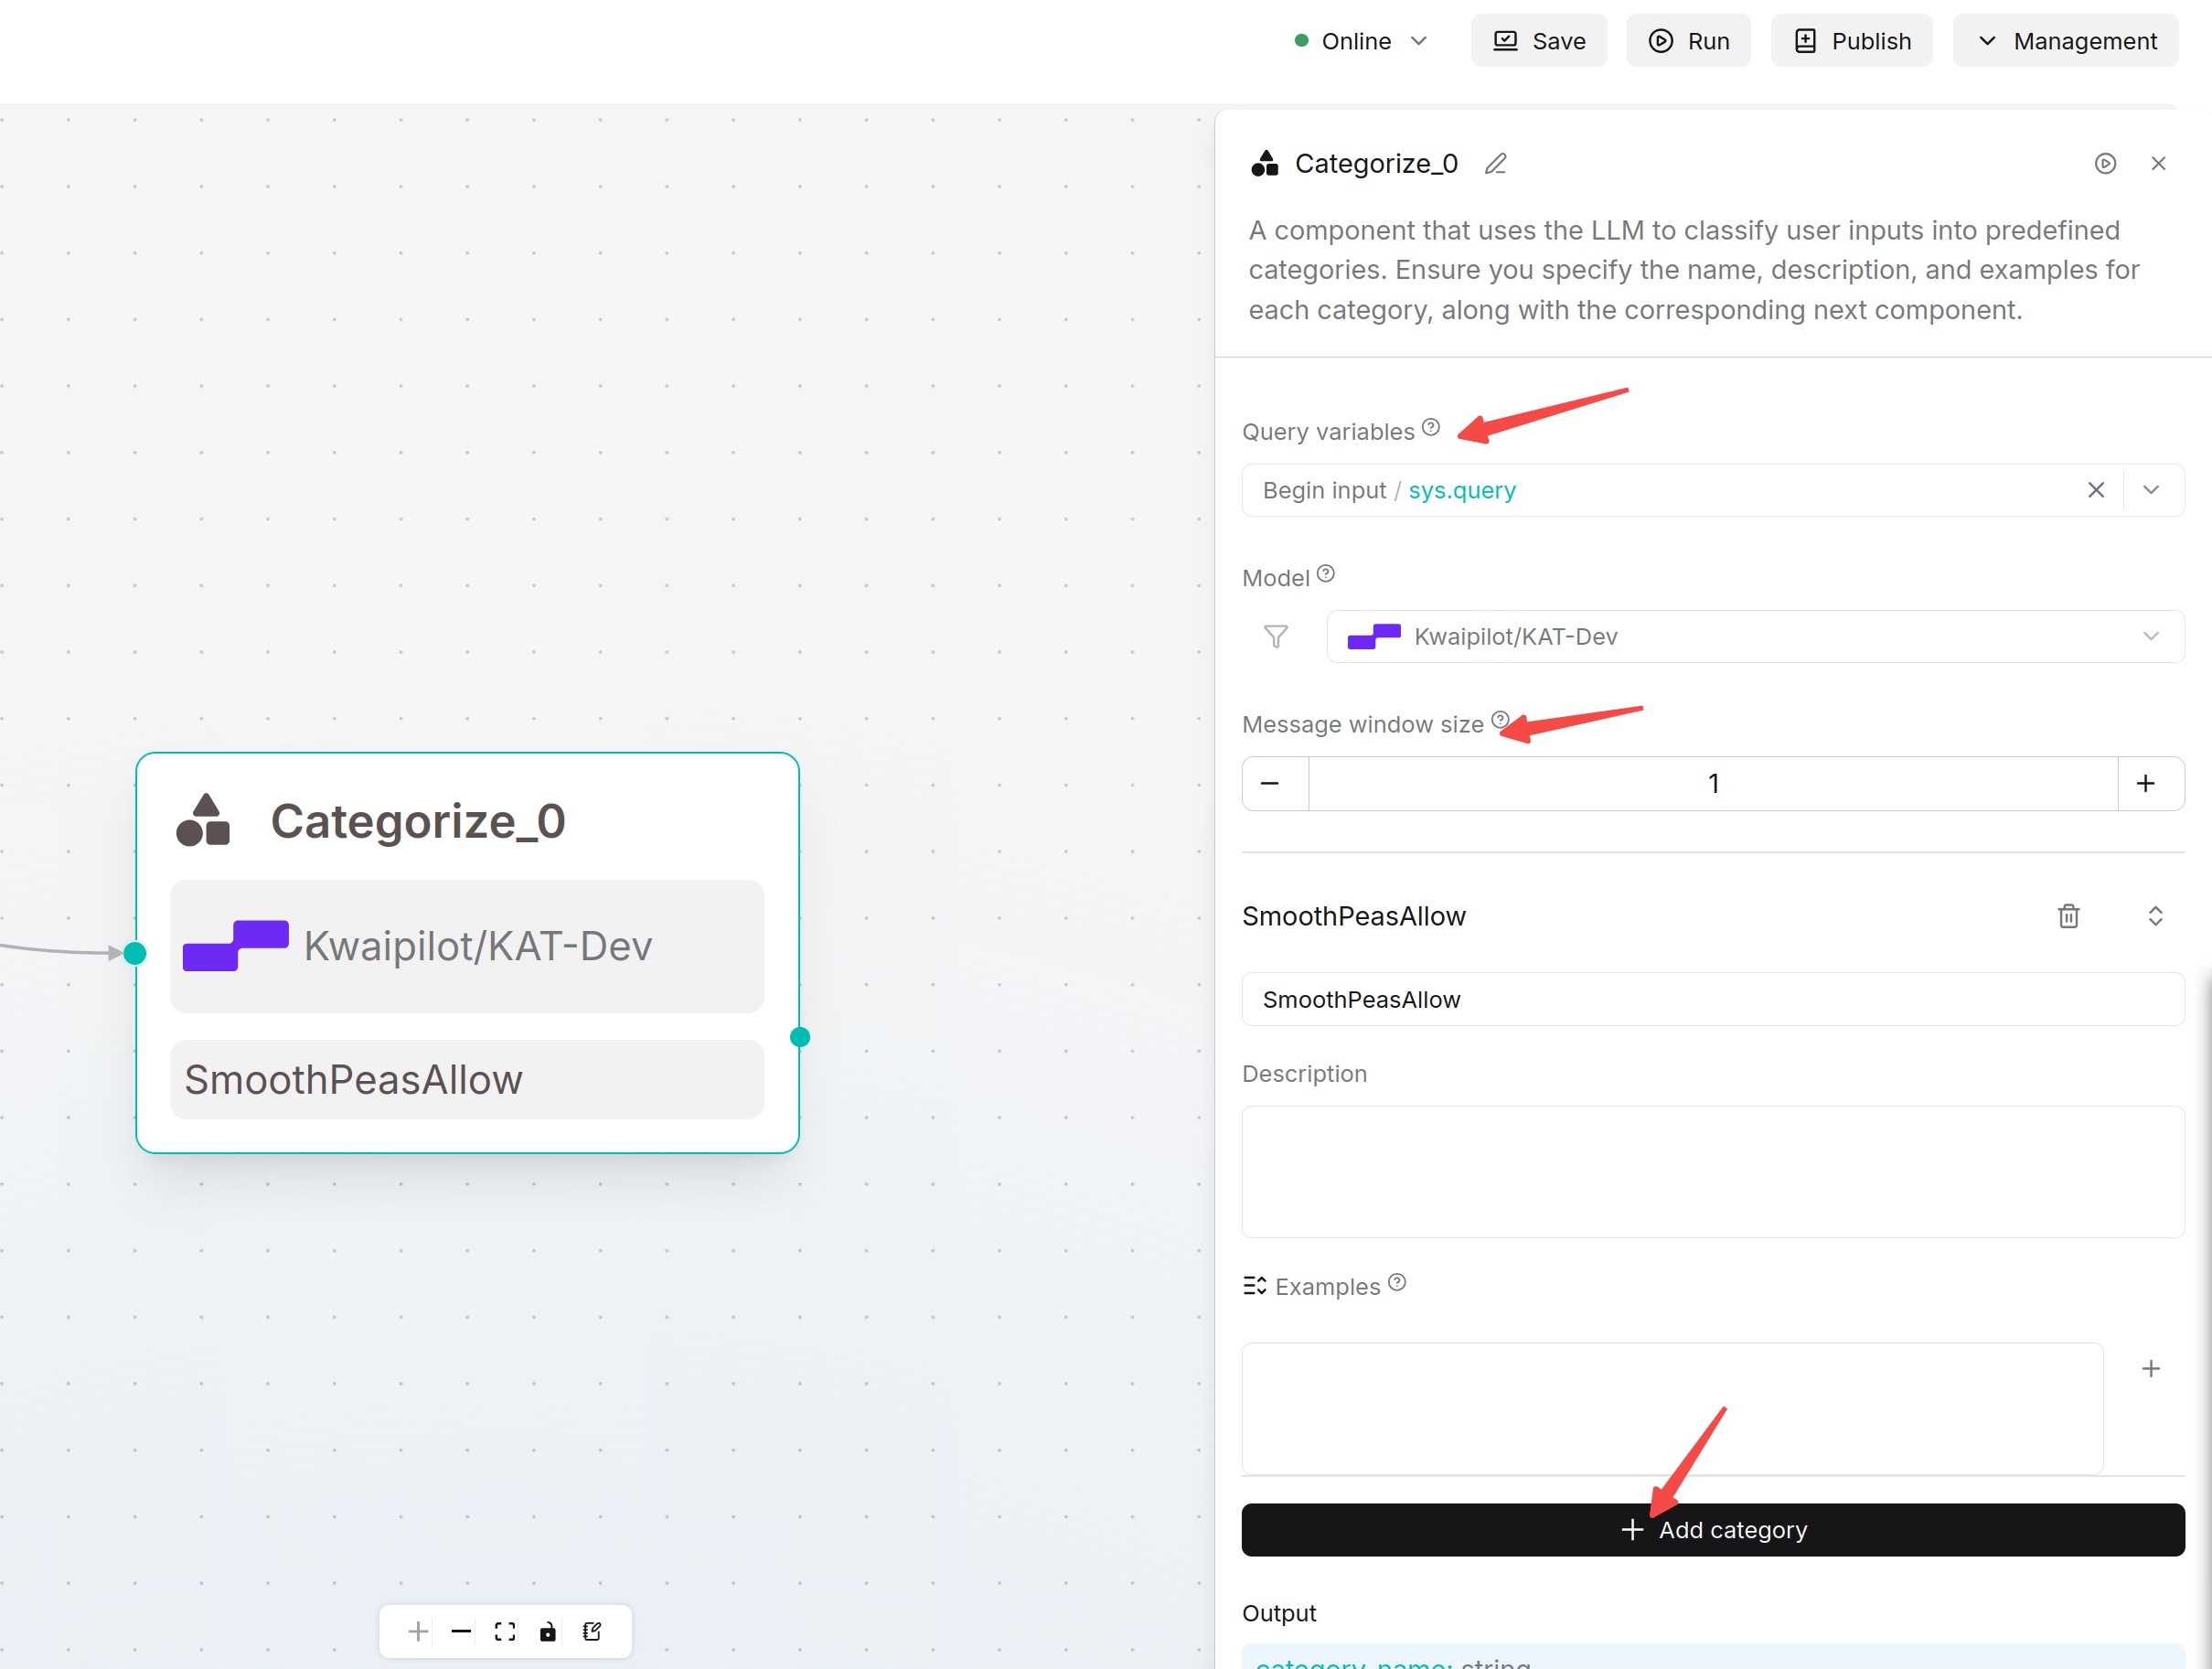++### Example: route a support request++Connect **Begin → Categorize**, with a Message on each category branch.++1. Leave Begin without additional inputs. In Categorize, select `sys.query` as **Query variables** and select a configured chat model.+2. Add **Product help** with description `Product features and setup questions` and example `How do I reset Model A?`. Add **Appointment** with description `Requests to arrange a service visit` and example `I want to book an installation`.+3. Connect Product help to a Message containing `Product support`; connect Appointment to a Message containing `Appointment request`.+4. Save and test both example questions. The first should display Product support and the second Appointment request. If either is misclassified, refine the descriptions and examples.diff --git a/docs/guides/agent/agent_workflow/tool_components.md b/docs/guides/agent/agent_workflow/tool_components.mdindex 9aff9c961a..04f6230ad2 100644--- a/docs/guides/agent/agent_workflow/tool_components.md+++ b/docs/guides/agent/agent_workflow/tool_components.md@@ -10,7 +10,9 @@ sidebar_custom_props: {# Tool Components-Tool components connect external search, databases, HTTP APIs, email sending, document generation, financial queries, and browser automation capabilities to Agents. When building Agents, first understand each tool's purpose and security boundaries.+Tool components connect external search, databases, HTTP APIs, email sending, document generation, financial queries, and web content extraction capabilities to Agents. When building Agents, first understand each tool's purpose and security boundaries.++In the tables below, **No** means manual input is optional; keep any default shown. Conditions are stated in the description. Replace bracketed placeholders with your own settings; **Leave blank** is an instruction, not text to enter.## Tool Selection Suggestions@@ -20,7 +22,7 @@ Tool components connect external search, databases, HTTP APIs, email sending, do| Academic search | Google Scholar, ArXiv, PubMed, BGPT | Retrieve papers, medical literature, and research materials. || Data and financial queries | Execute SQL, Yahoo Finance, WenCai | Query databases, market data, or financial screening results. || Content output | Email, Document Generator | Send emails or generate downloadable documents. |-| Browser automation | Browser | Access web pages, read page content, or perform multi-step browser tasks. |+| Web content extraction | Browser | Extract page content using natural-language instructions. |## Web Page and Information Retrieval@@ -36,14 +38,11 @@ Tavily is a web search service for LLMs. It is suitable for retrieving general w| Topic | string | No | general | Search type. Options are `general` or `news`. || Include Domains | array[string] | No | Empty list | Keep only results from these domains, such as `www.nasa.gov`. || Exclude Domains | array[string] | No | Empty list | Exclude results from these domains. |-| API Key | string | No | Empty | Tavily API key. |+| API Key | string | Conditional | Empty | Enter a Tavily key unless your administrator has configured one for the service. || Search Depth | string | No | basic | Search depth. Options are `basic` or `advanced`. || Max Results | integer | No | 6 | Maximum number of results. || Days | integer | No | 14 | Time range in days for news retrieval. || Include Answer | boolean | No | false | Whether to request Tavily's answer field. |-| Include Raw Content | boolean | No | false | Whether to request raw page content. |-| Include Images | boolean | No | false | Whether to request images. |-| Include Image Descriptions | boolean | No | false | Whether to request image descriptions. |#### Supported Parameter Values@@ -58,15 +57,17 @@ Tavily is a web search service for LLMs. It is suitable for retrieving general w| Configuration Item | Example Value || --- | --- |-| URLs | `["https://www.ragflow.io/docs/dev/"]` |-| Extract Depth | basic |-| Format | markdown |-| API Key | |-| Include Images | false |+| Query | RAGFlow knowledge retrieval |+| Topic | general |+| Search Depth | basic |+| Max Results | 6 |+| API Key | `<Tavily API key>` |#### Output Result-The output usually contains search result summaries, titles, links, snippets, and optional image information. `formalized_content` is commonly passed to the Agent to generate answers, while JSON is used by subsequent nodes to read structured fields.+The output usually contains search result titles, links, and snippets. `formalized_content` is commonly passed to the Agent to generate answers, while JSON is used by subsequent nodes to read structured fields.++For a simple search workflow, connect **Begin → Tavily Search → Agent → Message**. Use `sys.query` as **Query**, insert Tavily Search's `formalized_content` into the Agent's user prompt, and insert the Agent's `content` into Message. Ask a focused question and check that the search output contains relevant sources before assessing the final answer.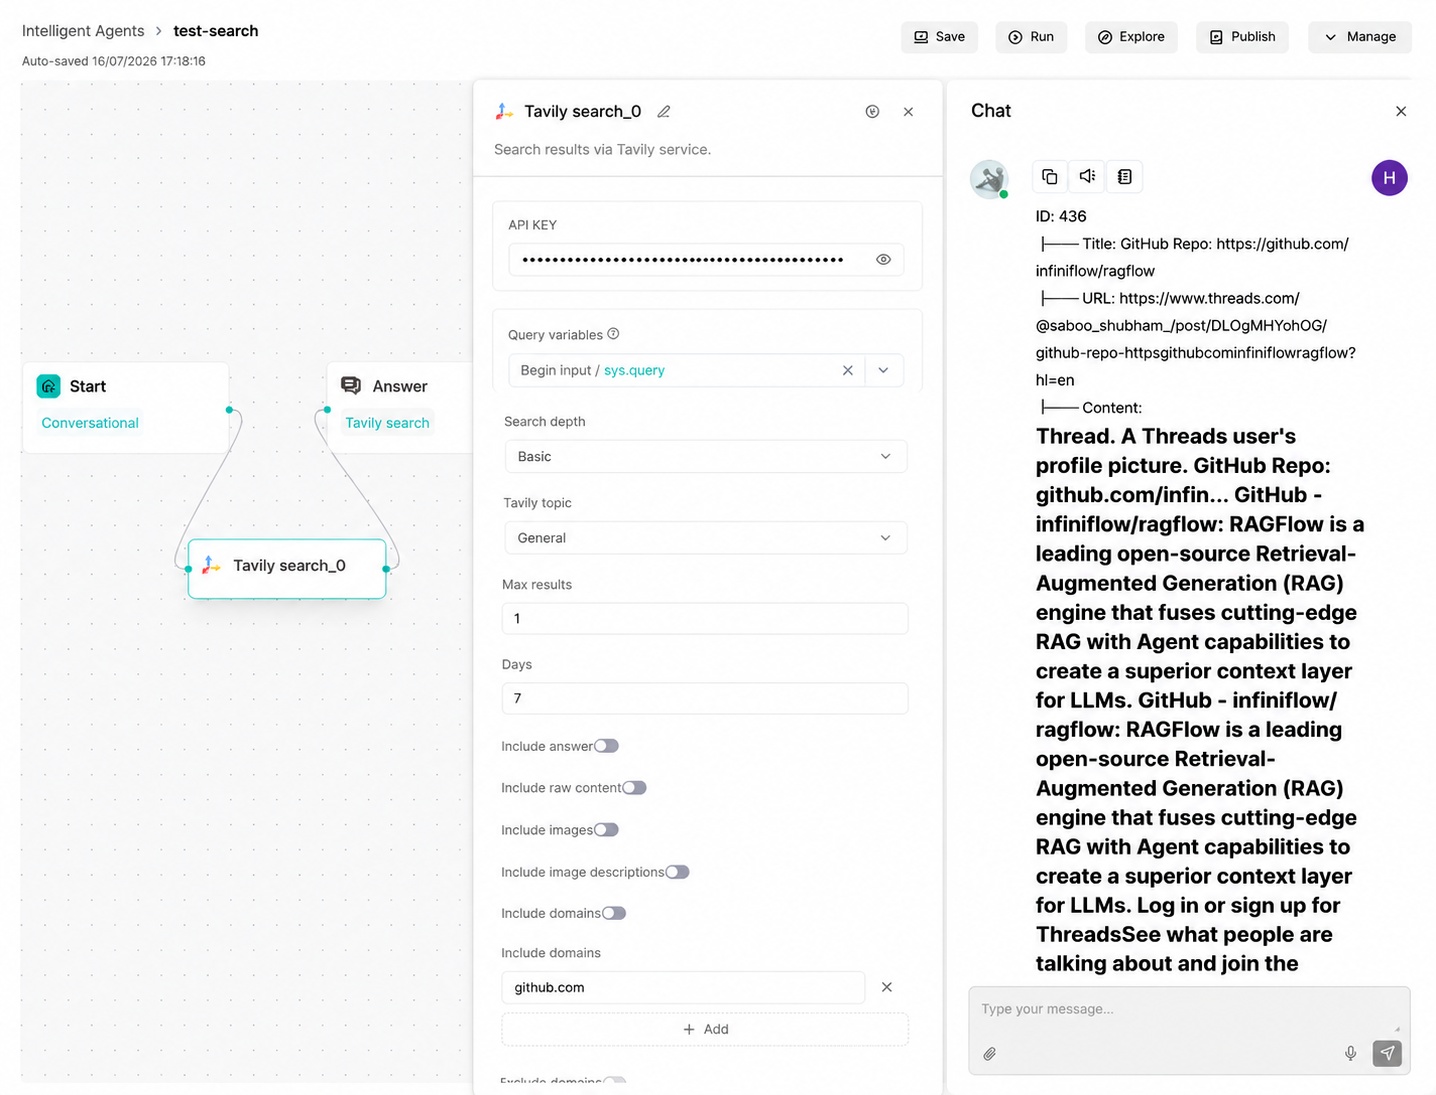@@ -81,8 +82,7 @@ Tavily Extract reads the body content of one or more known URLs. A common workfl| URLs | array[string] | Yes | Empty list | URL list to extract. If input is a string, it is split by English commas. || Extract Depth | string | No | basic | `advanced` can extract more tables and embedded content, with higher cost and latency. || Format | string | No | markdown | Extraction result format. Options are `markdown` or `text`. |-| API Key | string | No | Empty | Tavily API key. |-| Include Images | boolean | No | false | Whether to include images. |+| API Key | string | Conditional | Empty | Enter a Tavily key unless your administrator has configured one for the service. |#### Supported Parameter Values@@ -100,15 +100,44 @@ Tavily Extract reads the body content of one or more known URLs. A common workfl| URLs | `["https://www.ragflow.io/docs/dev/"]` || Extract Depth | basic || Format | markdown |-| API Key | |-| Include Images | false |+| API Key | `<your API key>` |#### Output Result-The output contains the page body, title, URL, and extraction status. `formalized_content` is commonly used as Agent context, while JSON preserves the structured extraction result for each URL.+The output `json` contains the extracted page results. Select the required page content from `json` and pass it to the Agent prompt.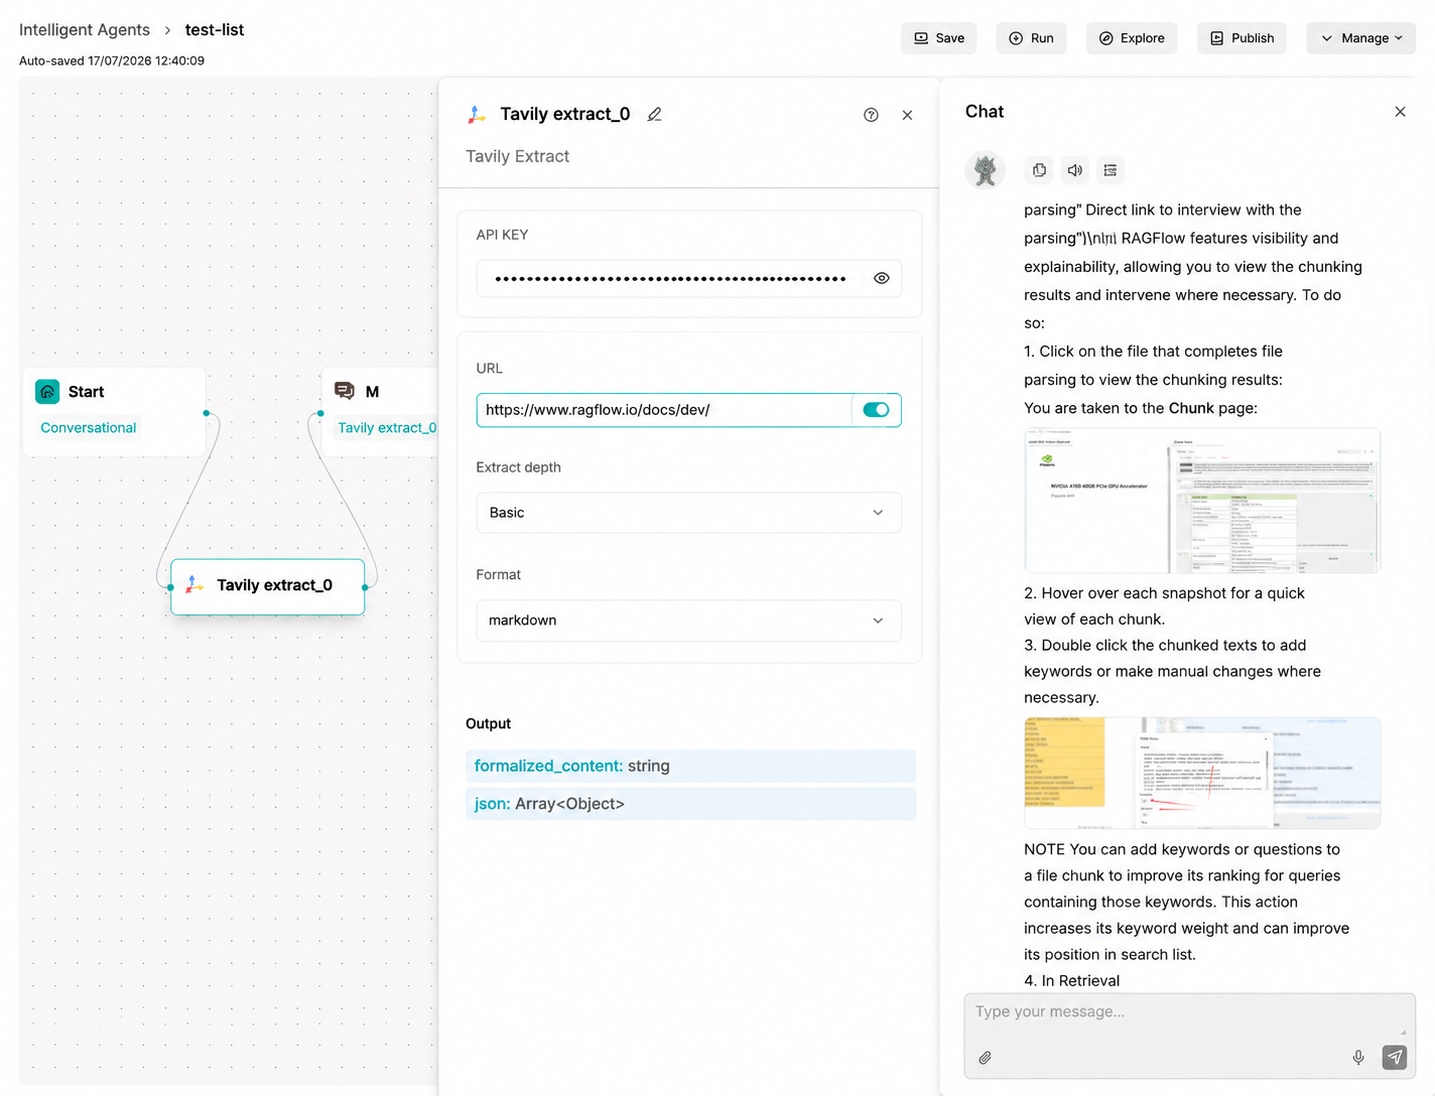+### Querit Search++Querit Search finds web pages for a query. Configure **API Key** and **Query**, then adjust these options as needed:++| Setting | Description |+| --- | --- |+| Result count | Maximum number of documents. Defaults to `10`. |+| Chunks per document | Number of content chunks requested for each document. |+| Sites to include / Sites to exclude | Limit results to selected sites or exclude them. |+| Time range | Restrict results by date. |+| Countries to include / Languages to include | Restrict results by country or language. |++For example, set **Query** to `RAGFlow knowledge retrieval`, **Result count** to `5`, and leave the optional filters empty. If the component API key is empty, the server uses `QUERIT_API_KEY` when configured.++The outputs are `formalized_content` for downstream prompts and `json` for the raw response.++### Querit Contents++Querit Contents retrieves content from known URLs. Pass links from a search component or enter them directly.++| Setting | Description |+| --- | --- |+| API Key | Querit API key. Uses the server's `QUERIT_API_KEY` if empty. |+| URLs | One to ten absolute HTTP or HTTPS URLs. |+| Format | `markdown` (default), `text`, or `html`. |+| Crawl timeout | Per-page timeout in seconds. Defaults to `10`. |+| Include page metadata | Request additional page metadata. |++For example, use `https://www.ragflow.io` as the URL and keep **Format** set to `markdown`. The output is `json`, containing the raw response. Select the required content from that response before passing it to an Agent.+Google Search obtains Google organic search results through SerpApi. It is suitable for web retrieval that requires country and language targeting.@@ -131,7 +160,7 @@ Google Search obtains Google organic search results through SerpApi. It is suita| Query | RAGFlow official documentation || Start | 0 || Num | 6 |-| API Key | |+| API Key | `<your API key>` || Country | cn || Language | en |@@ -150,24 +179,22 @@ DuckDuckGo is a privacy-focused search engine component. It does not require a s| Parameter | Type | Required | Default Value | Description || --- | --- | --- | --- | --- || Query | string | Yes | Current user input | Search keywords. |-| Channel | string | No | general | Message channel: `general` or `news`. |-| Top N | integer | Node configuration | 10 | Maximum number of returned results. |+| Channel | string | No | text | Select `text` for web pages or `news` for news results. |+| Top N | integer | No | 10 | Maximum number of returned results. |#### Configuration Example| Configuration Item | Example Value || --- | --- || Query | RAGFlow open source |-| Channel | general |+| Channel | text || Top N | 10 |#### Output ResultThe output contains titles, links, and summaries returned by DuckDuckGo. It can be used for web material summarization, news lead organization, or subsequent page extraction.-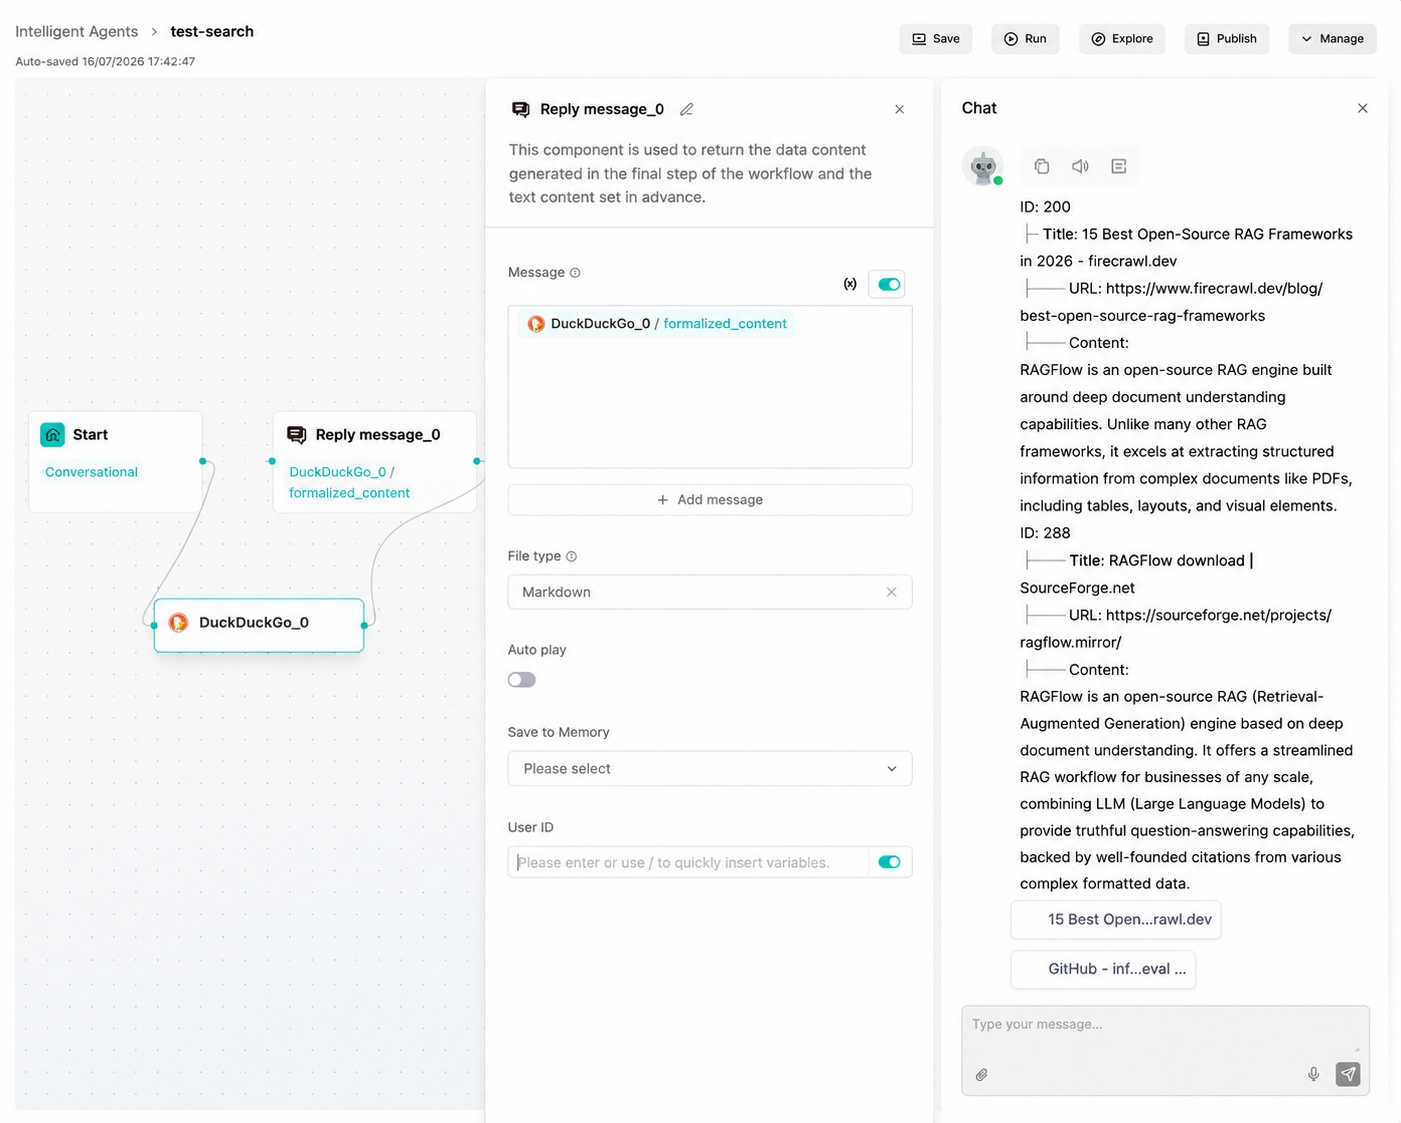--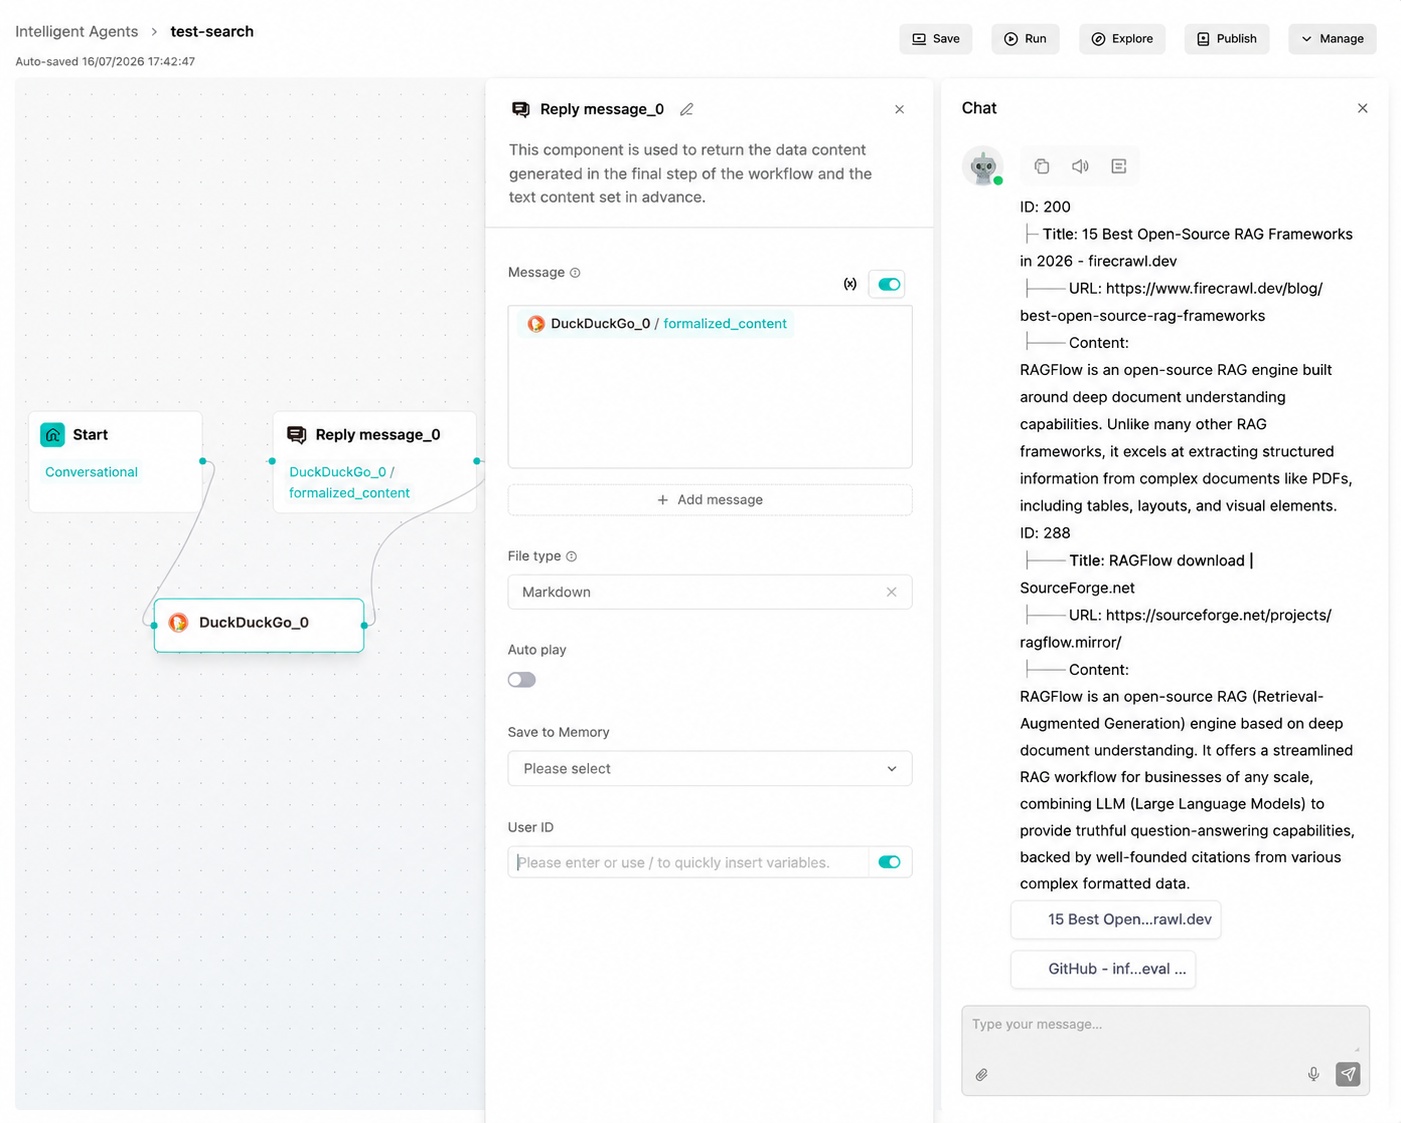+### SearXNG@@ -203,10 +230,9 @@ Keenable is a web search API for AI Agents. By default, it supports a public fre| --- | --- | --- | --- | --- || query | string | Yes | `{sys.query}` | Search keywords. || site | string | No | Empty | Limit results to a single domain, such as `techcrunch.com`. |-| api_key | string | Node configuration | Empty | Optional Keenable API key. |-| mode | string | Node configuration | pro | `pro` for deeper retrieval or `realtime` for low latency. `realtime` requires an API key. |-| top_n | integer | Node configuration | 10 | Maximum number of results. |-| KEENABLE_API_URL | Environment variable | Deployment configuration | `https://api.keenable.ai` | Service API base URL. Production environments must use HTTPS. Local loopback addresses can use HTTP. |+| api_key | string | Conditional | Empty | Optional in pro mode; required in realtime mode. |+| mode | string | No | pro | `pro` for deeper retrieval or `realtime` for low latency. `realtime` requires an API key. |+| top_n | integer | No | 10 | Maximum number of results. |#### Configuration Example@@ -214,10 +240,9 @@ Keenable is a web search API for AI Agents. By default, it supports a public fre| --- | --- || Query | RAGFlow Agent workflow || Site | github.com |-| API Key | |+| API Key | Leave blank for pro mode || Mode | pro || Top N | 10 |-| Keenable API URL | `https://api.keenable.ai` |#### Output Result@@ -236,15 +261,15 @@ Sofya is a web search API for AI Agents. It returns the text of the result pages| query | string | Yes | `{sys.query}` | Search keywords. || topic | string | No | general | `general` for web search or `news` for current events. || freshness | string | No | any | Limit results by recency: `day`, `week`, `month`, `year`, or `any`. |-| api_key | string | Node configuration | Empty | Sofya API key. |-| search_depth | string | Node configuration | basic | `basic` returns the content of the result pages. `snippets` returns search snippets only, which is faster and cheaper. |-| top_n | integer | Node configuration | 10 | Maximum number of results, up to 20. |+| api_key | string | Yes | Empty | Sofya API key. |+| search_depth | string | No | basic | `basic` returns the content of the result pages. `snippets` returns search snippets only, which is faster and cheaper. |+| top_n | integer | No | 10 | Maximum number of results, up to 20. |#### Configuration Example| Configuration Item | Example Value || --- | --- |-| Query | RAGFlow Go release |+| Query | RAGFlow release || API Key | `<your-sofya-api-key>` || Search Depth | basic || Top N | 10 |@@ -265,8 +290,8 @@ Search1API searches the web or the news through one API and lets you choose the| channel | string | No | general | `general` for web search or `news` for news search. The Agent can override the node value. || search_service | string | No | google | The search service to query. The Agent can override the node value with any service the channel supports. || time_range | string | No | any | Limit results by recency: `day`, `week`, `month`, `year`, or `any`. |-| api_key | string | Node configuration | Empty | Search1API API key. |-| top_n | integer | Node configuration | 10 | Maximum number of results, up to 50. |+| api_key | string | Yes | Empty | Search1API API key. |+| top_n | integer | No | 10 | Maximum number of results, up to 50. |#### Supported Parameter Values@@ -281,7 +306,7 @@ If the Agent switches to a channel that does not offer the node's search service| Configuration Item | Example Value || --- | --- |-| Query | RAGFlow Go release |+| Query | RAGFlow release || API Key | `<your-search1api-api-key>` || Channel | general || Search Service | google |@@ -300,7 +325,7 @@ Search1API Crawl reads one web page and returns its title and full content. A co| Field | Type | Required | Default Value | Description || --- | --- | --- | --- | --- || url | string | Yes | Empty | The absolute HTTP or HTTPS URL of the page to read. As an Agent tool, the Agent supplies the URL. |-| api_key | string | Node configuration | Empty | Search1API API key. |+| api_key | string | Yes | Empty | Search1API API key. |#### Configuration Example@@ -321,8 +346,8 @@ The Wikipedia component searches encyclopedia entries and extracts entry summari| Field | Type | Required | Default Value | Description || --- | --- | --- | --- | --- || query | string | Yes | `{sys.query}` | Specific entry topic or keyword. |-| top_n | integer | Node configuration | 10 | Maximum number of search entries. |-| language | string | Node configuration | en | Wikipedia language code, such as `zh`, `en`, or `ja`. |+| top_n | integer | No | 10 | Maximum number of search entries. |+| language | string | No | en | Wikipedia language code, such as `zh`, `en`, or `ja`. |#### Configuration Example@@ -347,7 +372,7 @@ The GitHub component searches repositories through the GitHub Repository Search| Field | Type | Required | Default Value | Description || --- | --- | --- | --- | --- || query | string | Yes | `{sys.query}` | GitHub repository search syntax or keywords. |-| top_n | integer | Node configuration | 10 | Maximum number of returned repositories. |+| top_n | integer | No | 10 | Maximum number of returned repositories. |#### Configuration Example@@ -358,9 +383,9 @@ The GitHub component searches repositories through the GitHub Repository Search#### Output Result-The output contains repository, issue, code, or user search entries, usually including names, links, summaries, update times, and other information. The output includes repository names, links, descriptions, and stars.+The output contains matching repository names, links, descriptions, and star counts.-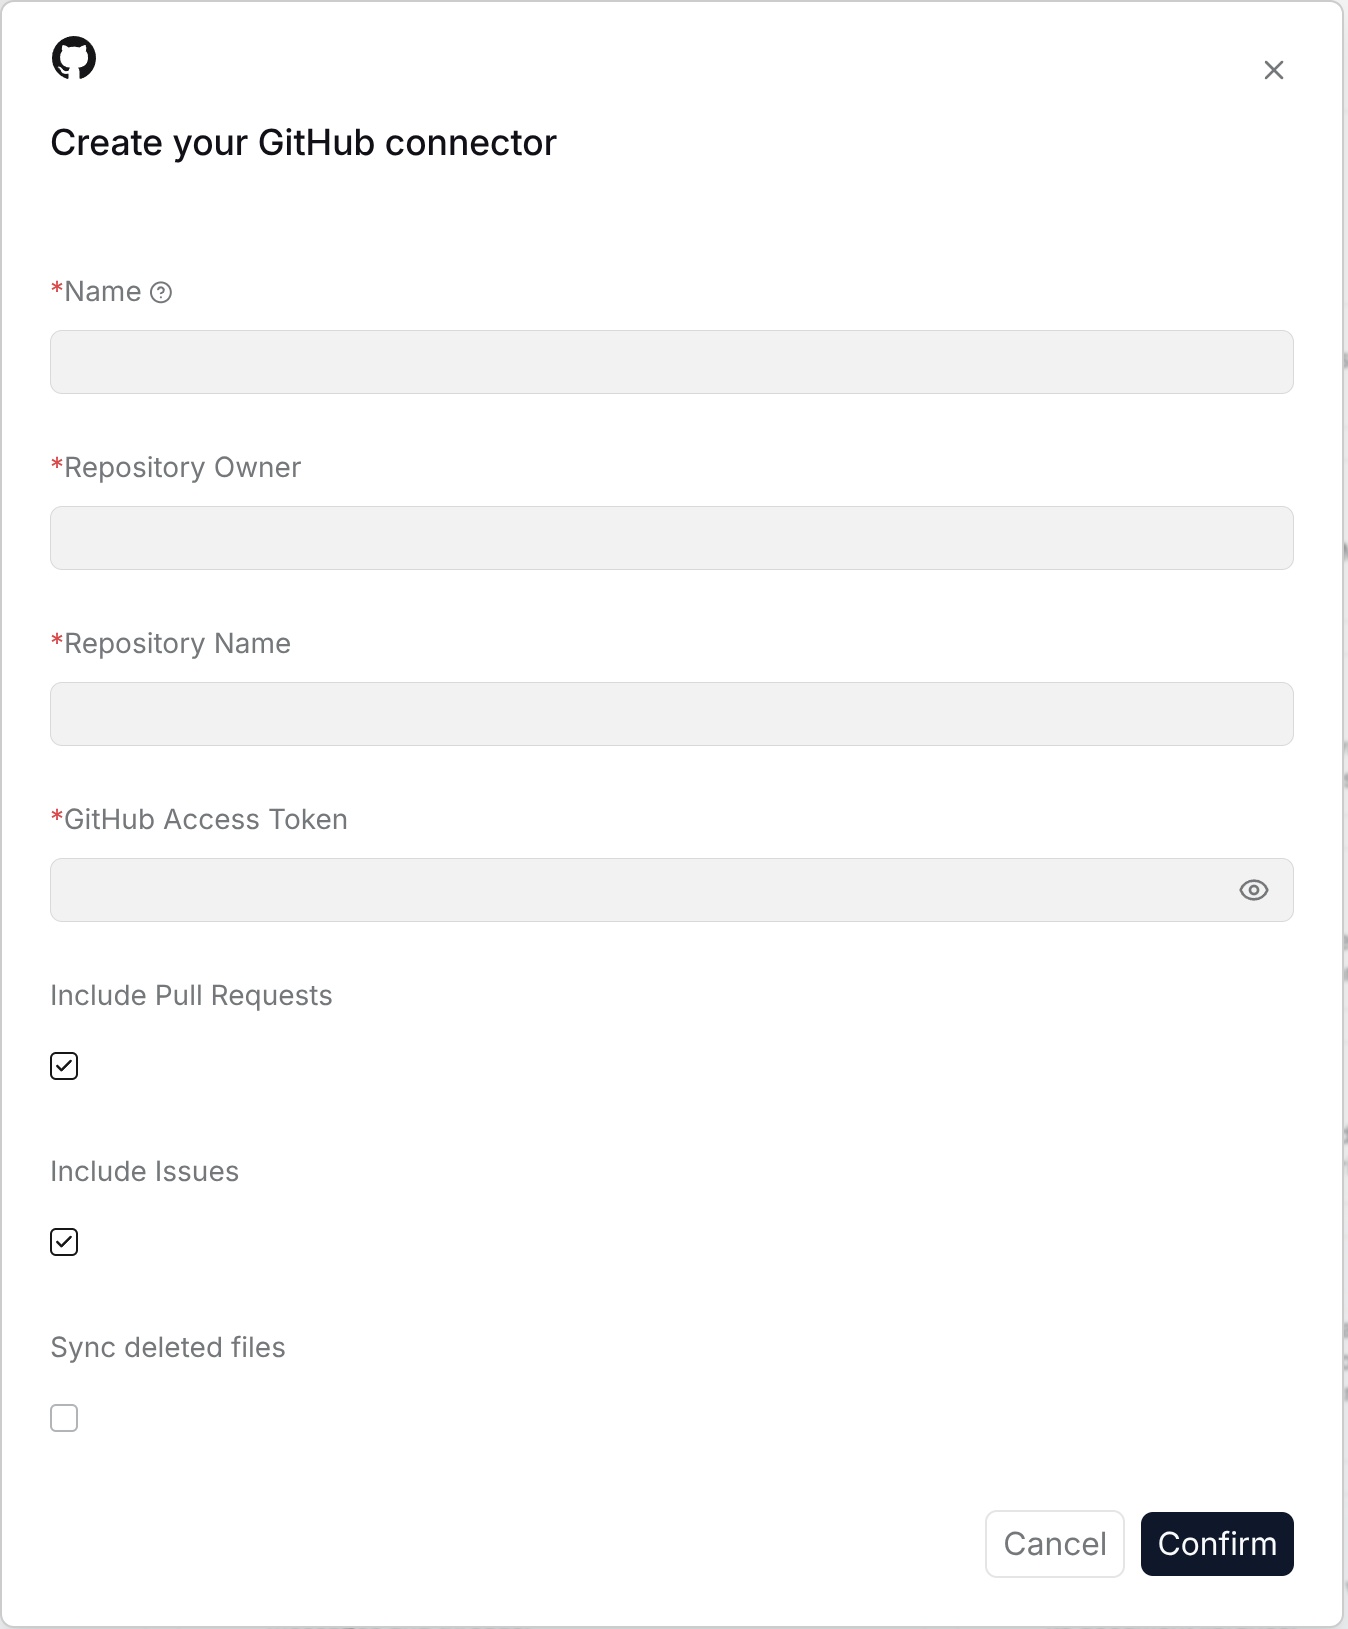+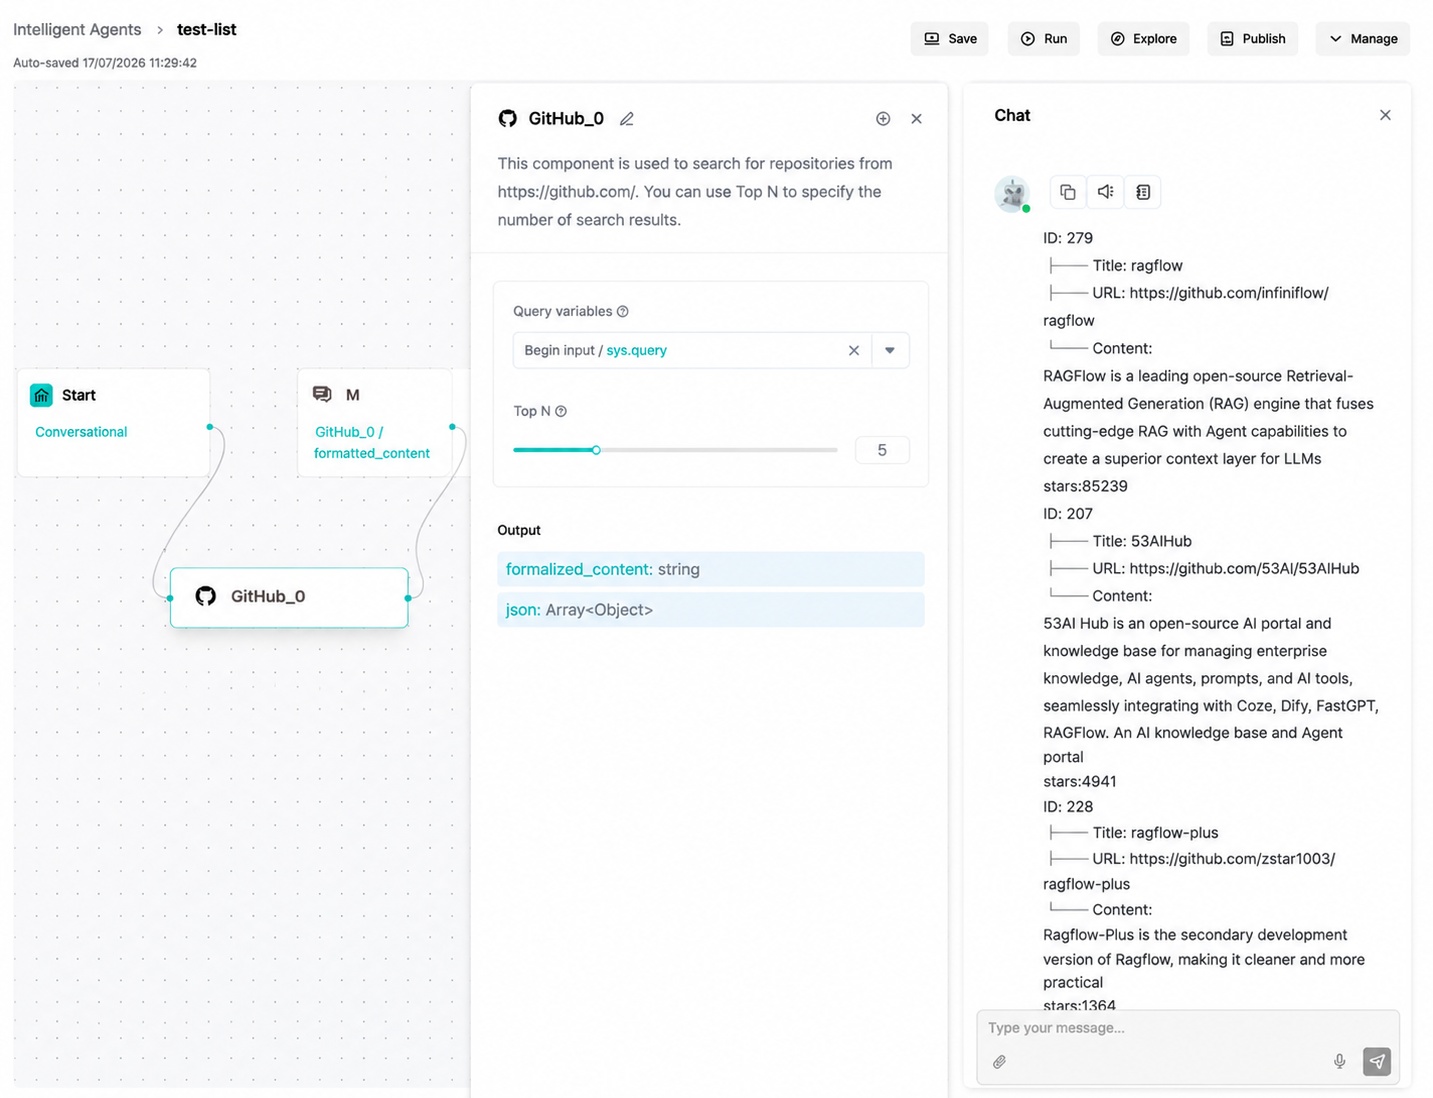## Academic Literature Retrieval@@ -373,11 +398,11 @@ Google Scholar is used to retrieve papers, dissertations, books, abstracts, and| Field | Type | Required | Default Value | Description || --- | --- | --- | --- | --- || query | string | Yes | `{sys.query}` | Paper topic or keyword. |-| top_n | integer | Node configuration | 12 | Maximum number of papers. |-| sort_by | string | Node configuration | relevance | Sorting method: `date` or `relevance`. |-| year_low | integer/null | Node configuration | null | Earliest publication year. |-| year_high | integer/null | Node configuration | null | Latest publication year. |-| patents | boolean | Node configuration | true | Whether to include patents. |+| top_n | integer | No | 12 | Maximum number of papers. |+| sort_by | string | No | relevance | Sorting method: `date` or `relevance`. |+| year_low | integer/null | No | Unset | Earliest publication year. |+| year_high | integer/null | No | Unset | Latest publication year. |+| patents | boolean | No | true | Whether to include patents. |#### Configuration Example@@ -386,8 +411,8 @@ Google Scholar is used to retrieve papers, dissertations, books, abstracts, and| Query | retrieval augmented generation evaluation || Top N | 12 || Sort By | relevance |-| Year Low | null |-| Year High | null |+| Year Low | Leave blank |+| Year High | Leave blank || Patents | true |#### Output Result@@ -405,8 +430,8 @@ ArXiv is used to retrieve open preprints across fields such as computer science,| Field | Type | Required | Default Value | Description || --- | --- | --- | --- | --- || query | string | Yes | `{sys.query}` | Retrieval keywords. |-| top_n | integer | Node configuration | 12 | Maximum number of returned papers. |-| sort_by | string | Node configuration | submittedDate | Sorting method: `submittedDate`, `lastUpdatedDate`, or `relevance`. |+| top_n | integer | No | 12 | Maximum number of returned papers. |+| sort_by | string | No | submittedDate | Sorting method: `submittedDate`, `lastUpdatedDate`, or `relevance`. |#### Configuration Example@@ -420,8 +445,6 @@ ArXiv is used to retrieve open preprints across fields such as computer science,The output contains paper titles, authors, abstracts, publication times, categories, and paper links. It can be used by the Agent to generate paper summaries or research comparisons.-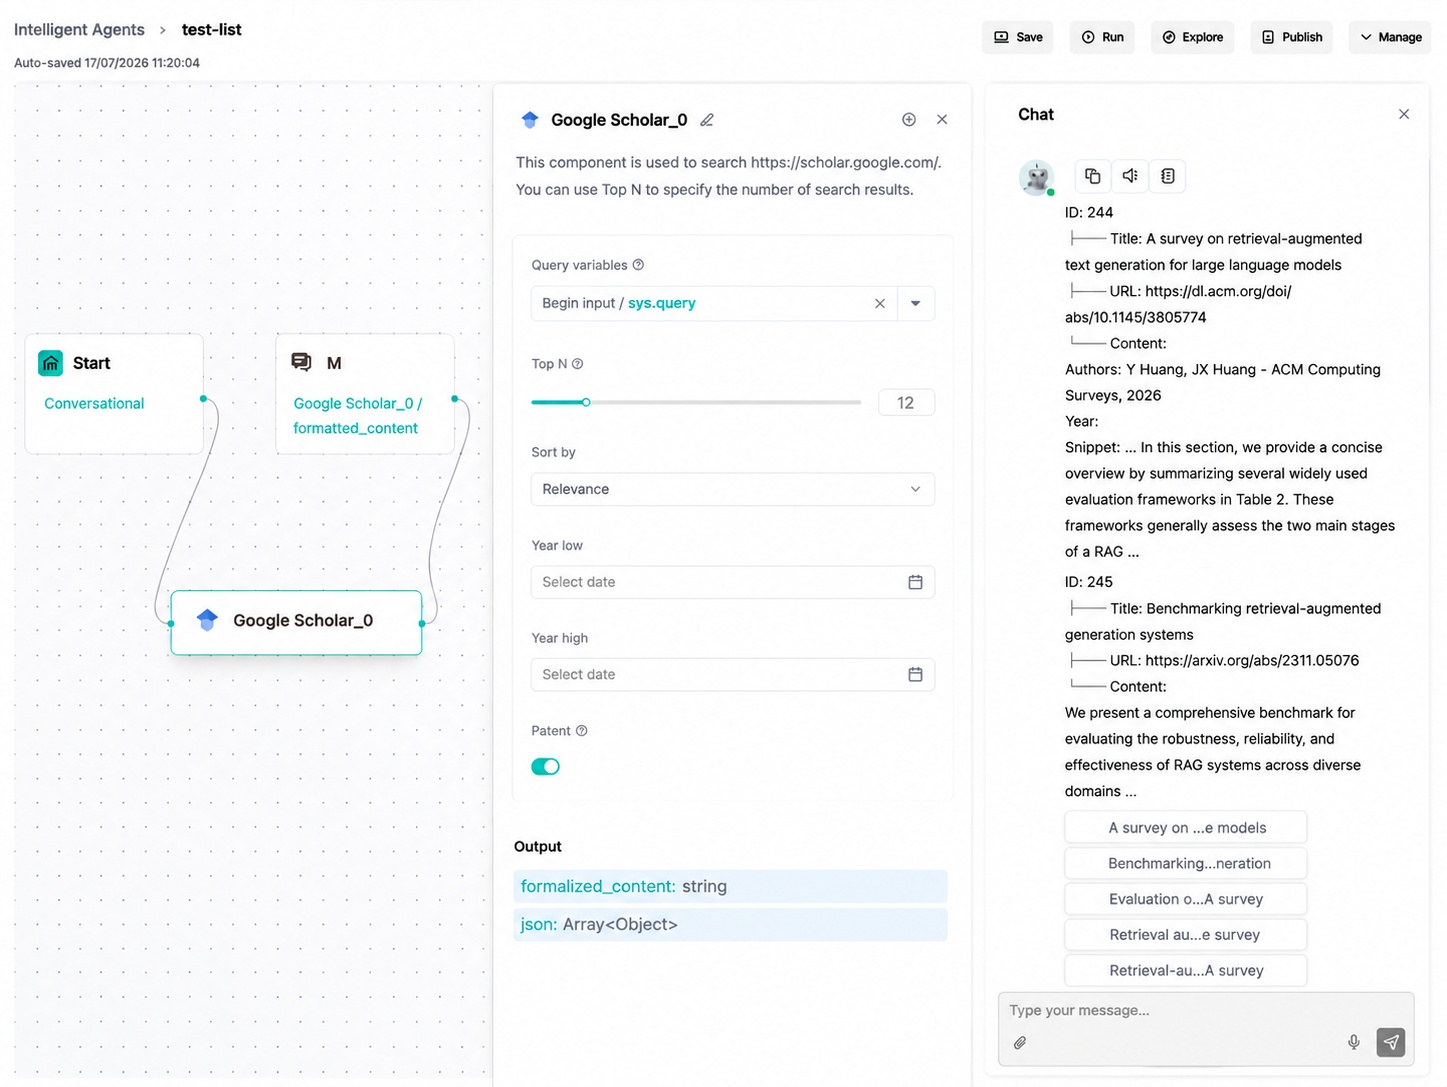-### PubMedPubMed is used to retrieve life science and biomedical literature. The component queries through NCBI E-utilities and returns titles, authors, journals, DOIs, abstracts, and other information.@@ -431,8 +454,8 @@ PubMed is used to retrieve life science and biomedical literature. The component| Field | Type | Required | Default Value | Description || --- | --- | --- | --- | --- || query | string | Yes | `{sys.query}` | PubMed search term. Medical subject headings or Boolean retrieval expressions are supported. |-| top_n | integer | Node configuration | 12 | Maximum number of papers. |-| email | string | Node configuration | `[email protected]` | NCBI Entrez contact email. Replace it with a real maintainer email in production. |+| top_n | integer | No | 12 | Maximum number of papers. |+| email | string | No | `[email protected]` | NCBI Entrez contact email. Replace it with a real maintainer email in production. |#### Configuration Example@@ -457,9 +480,9 @@ BGPT retrieves scientific papers and returns structured evidence, including rese| Field | Type | Required | Default Value | Description || --- | --- | --- | --- | --- || query | string | Yes | `{sys.query}` | Natural-language scientific retrieval question. |-| top_n | integer | Node configuration | 10 | Maximum number of results. |-| api_key | string | Node configuration | Empty | Optional API key. If not configured, the public service path is used. |-| days_back | integer/null | Node configuration | null | Optional. Limits retrieval to content from the most recent number of days. |+| top_n | integer | No | 10 | Maximum number of results. |+| api_key | string | No | Empty | Optional API key. If not configured, the public service path is used. |+| days_back | integer/null | No | Unset | Optional. Limits retrieval to content from the most recent number of days. |#### Configuration Example@@ -467,8 +490,8 @@ BGPT retrieves scientific papers and returns structured evidence, including rese| --- | --- || Query | Does sleep deprivation impair working memory in adults? || Top N | 10 |-| API Key | |-| Days Back | null |+| API Key | Leave blank (optional) |+| Days Back | Leave blank |#### Output Result@@ -482,7 +505,7 @@ The output contains biomedical knowledge retrieval results and summaries, whichExecute SQL connects to an external database and executes SQL statements. The result is formatted as text or table content.-To protect system security, the database address must pass server-side security checks. To connect to a local or internal database, first confirm that the deployment environment allows access.+Use a database address that the RAGFlow server can reach. If the connection is rejected, check the address, credentials, and network access settings.#### Parameter Description@@ -492,7 +515,7 @@ To protect system security, the database address must pass server-side security| db_type | string | Yes | mysql | Supports `mysql`, `postgres`, `mariadb`, `mssql`, `trino`, and `oceanbase`. || database | string | Yes | Empty | Database name. Trino uses `catalog.schema` or `catalog`. || username | string | Yes | Empty | Database account. |-| host | string | Yes | Empty | Database address, which must pass server-side security checks. |+| host | string | Yes | Empty | Database address reachable from the RAGFlow server. || port | integer | Yes | 3306 | Database port. || password | string | Conditionally required | Empty | Database password. It can be empty for Trino. || max_records | integer | No | 1024 | Maximum number of records returned per statement. |@@ -510,9 +533,11 @@ To protect system security, the database address must pass server-side security#### Configuration Example+Ask your administrator to prepare a MySQL test database named `demo_sql` with a `products` table containing `id`, `name`, and `stock`. Use two sample rows: `(1, Model A, 12)` and `(2, Model B, 0)`. The account needs permission to read this table.+| Configuration Item | Example Value || --- | --- |-| SQL | `SELECT * FROM XXX;` |+| SQL | `SELECT id, name FROM products WHERE stock > 0 ORDER BY id;` || Database Type | mysql || Database | demo_sql || Username | ragflow_reader |@@ -521,6 +546,10 @@ To protect system security, the database address must pass server-side security| Password | `<read-only database account password>` || Max Records | 10 |+Replace `<host>`, the username, and the password with your test database connection details; change `demo_sql` if your database has a different name.++Connect **Begin → Execute SQL → Message**. Configure Execute SQL as above, then insert its `formalized_content` output into Message through the variable selector. Save and click **Run**. The result should contain only `1, Model A`, because Model B has no stock.+#### Output ResultThe output contains SQL execution results, field names, and record content. You can pass formatted text to the Agent for explanation, or let subsequent nodes read structured results.@@ -529,26 +558,21 @@ The output contains SQL execution results, field names, and record content. You### Yahoo Finance-The Yahoo Finance component queries stock quotes, company profiles, historical market data, financial statements, and news through `yfinance`, and outputs the selected content as a Markdown report.+The Yahoo Finance component queries stock quotes, company profiles, historical market data, financial statements, and news. It returns the selected content as a Markdown report.#### Parameter Description| Field | Type | Required | Default Value | Description || --- | --- | --- | --- | --- || stock_code | string | Yes | `{sys.query}` | Stock code or company name. Use exchange-standard codes when possible. |-| info | boolean | Node configuration | true | Output company and quote information. |-| history | boolean | Node configuration | false | Output historical market data. |-| count | boolean | Node configuration | false | Share count switch defined by the code. |-| financials | boolean | Node configuration | false | Output earnings dates and other financial calendar events returned by Yahoo Finance. |-| income_stmt | boolean | Node configuration | false | Income statement switch defined by the code. |-| balance_sheet | boolean | Node configuration | false | Output balance sheet and quarterly balance sheet. |-| cash_flow_statement | boolean | Node configuration | false | Output cash flow statement and quarterly cash flow statement. |-| news | boolean | Node configuration | true | Output related news. |--#### Supported Values--| Parameter | Supported Value | Description |-| --- | --- | --- |+| info | boolean | No | true | Output company and quote information. |+| history | boolean | No | false | Output historical market data. |+| count | boolean | No | false | Include share-count statistics. |+| financials | boolean | No | false | Output earnings dates and other financial calendar events returned by Yahoo Finance. |+| income_stmt | boolean | No | false | Include annual and quarterly income statements. |+| balance_sheet | boolean | No | false | Output balance sheet and quarterly balance sheet. |+| cash_flow_statement | boolean | No | false | Output cash flow statement and quarterly cash flow statement. |+| news | boolean | No | true | Output related news. |#### Configuration Example@@ -566,7 +590,7 @@ The Yahoo Finance component queries stock quotes, company profiles, historical m#### Output Result-The output contains a financial query report and structured market data, which can be used by subsequent Agents to generate market overviews or indicator explanations.+The output `report` is a Markdown report containing the selected financial information. Insert `report` into a downstream Agent prompt to generate a market overview or explain indicators.### WenCaiWenCai is used to screen financial data such as stocks, indices, funds, Hong Kong stocks, U.S. stocks, futures, and other instruments based on natural-language conditions.@@ -576,8 +600,8 @@ WenCai is used to screen financial data such as stocks, indices, funds, Hong Kon| Field | Type | Required | Default Value | Description || --- | --- | --- | --- | --- || query | string | Yes | `{sys.query}` | Stock selection or financial condition, such as "A-shares with P/E ratio below 20". |-| top_n | integer | Node configuration | 10 | Maximum number of results. The frontend default may be 20. |-| query_type | string | Node configuration | stock | Supports `stock`, `zhishu`, `fund`, `hkstock`, `usstock`, `threeboard`, `conbond`, `insurance`, `futures`, `lccp`, and `foreign_exchange`. |+| top_n | integer | No | 20 | Maximum number of results. |+| query_type | string | No | stock | Supports `stock`, `zhishu`, `fund`, `hkstock`, `usstock`, `threeboard`, `conbond`, `insurance`, `futures`, `lccp`, and `foreign_exchange`. |#### Supported Query Types@@ -609,7 +633,7 @@ The output contains a financial data list that matches the natural-language scre:::tip NOTE-Before using the WenCai component, confirm that the WenCai query service is available in the current environment. If the service is not enabled, the component will not return real financial data.+Configure the WenCai query service before using this component.:::@@ -627,12 +651,12 @@ The Email component sends HTML emails through SMTP. Configure the recipients, CC| cc_email | string | No | Empty | CC email addresses. Separate multiple addresses with English commas. || content | string | No | Empty | Email body, sent as HTML content. || subject | string | No | Empty | Email subject. |-| smtp_server | string | Node configuration | Empty | SMTP server address. |-| smtp_port | integer | Node configuration | 465 | SMTP port. Port 465 uses SSL, and other ports use STARTTLS. |-| email | string | Node configuration | Empty | Sender email address. |-| smtp_username | string | Node configuration | Empty | SMTP login account. If empty, the sender email address is used. |-| password | string | Node configuration | Empty | SMTP authorization code or password. |-| sender_name | string | Node configuration | Empty | Sender display name. |+| smtp_server | string | Yes | Empty | SMTP server address. |+| smtp_port | integer | No | 465 | SMTP port. Port 465 uses SSL, and other ports use STARTTLS. |+| email | string | Yes | Empty | Sender email address. |+| smtp_username | string | No | Empty | SMTP login account. If empty, the sender email address is used. |+| password | string | Yes | Empty | SMTP authorization code or password. |+| sender_name | string | No | Empty | Sender display name. |:::tip NOTE@@ -645,15 +669,15 @@ Although some SMTP fields are displayed as optional in the UI, a valid SMTP serv| Configuration Item | Example Value || --- | --- || To Email | [email protected] |-| CC Email | |+| CC Email | Leave blank (optional) || Content | `<p>This is a test email sent by RAGFlow.</p>` || Subject | RAGFlow email tool test |-| SMTP Server | |+| SMTP Server | `<your SMTP server>` || SMTP Port | 465 |-| Email | |-| SMTP Username | |-| Password | |-| Sender Name | |+| Email | `<your sender email>` |+| SMTP Username | Leave blank to use the sender email |+| Password | `<your SMTP authorization code or password>` |+| Sender Name | Leave blank (optional) |#### Output Result@@ -661,52 +685,59 @@ The output contains sending status and error information. `success` being `true`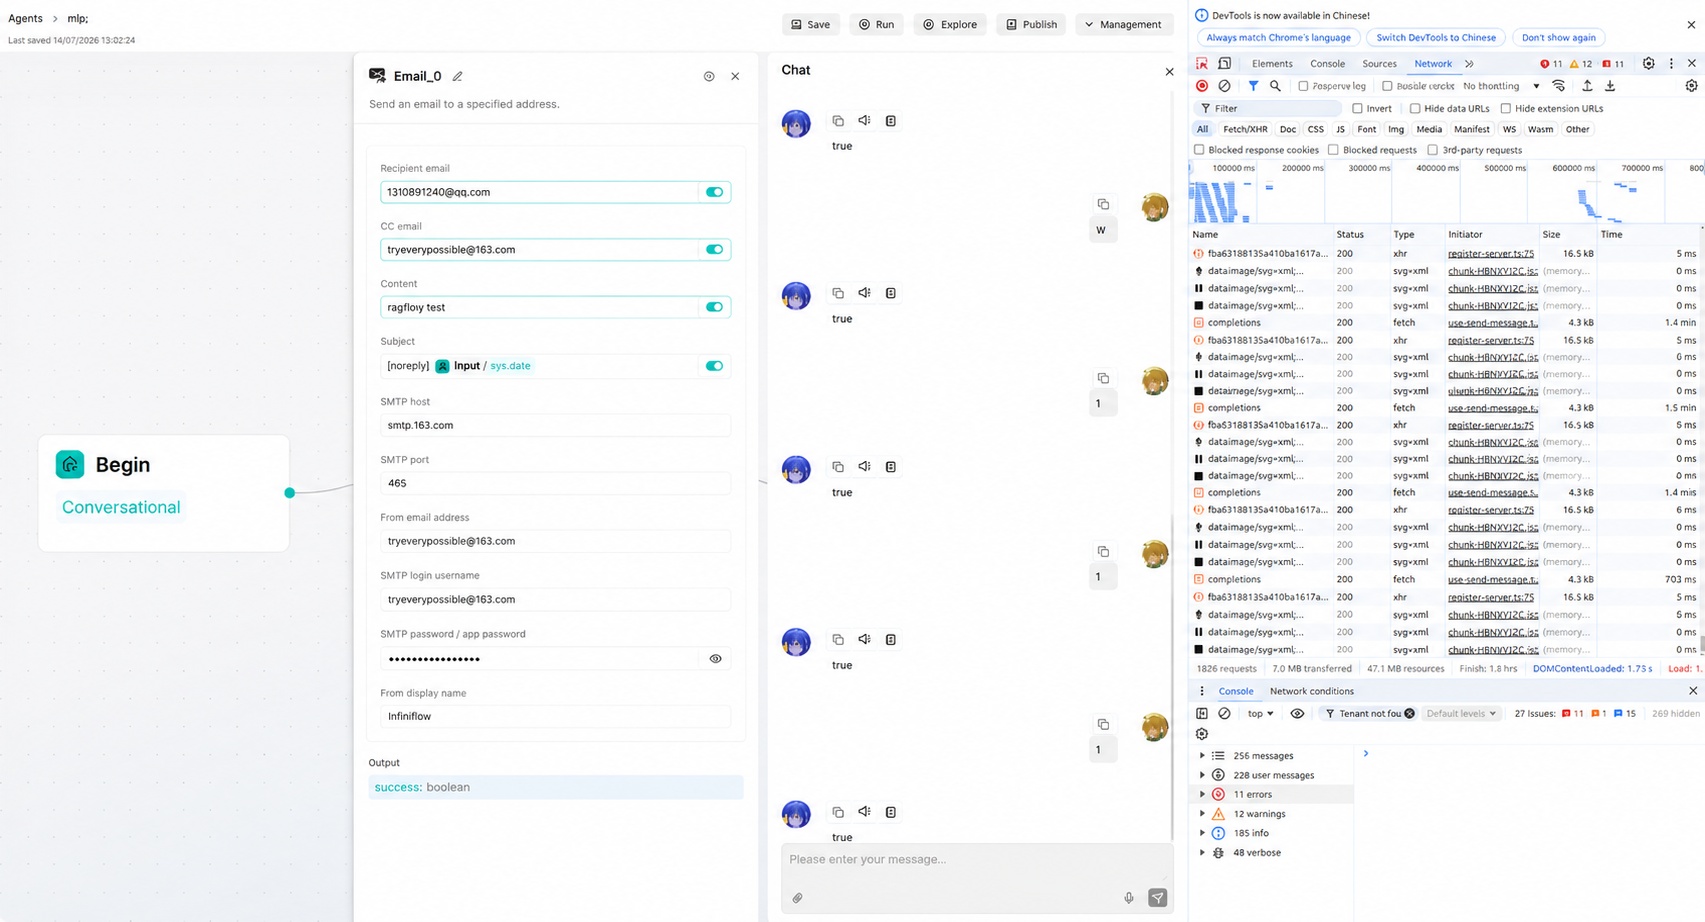-### HTTP Request+### MCP tools-The HTTP Request component calls external HTTP APIs, allowing business systems, third-party services, or self-built APIs to be connected to Agent workflows.+MCP connects an Agent to tools provided by a configured MCP server. Add MCP tools through the **Agent** component's tool selector; they are not a standalone HTTP Request node.-#### Parameter Description+1. Open **User settings > MCP > Add MCP**, enter the server URL and authentication, refresh **Tools available**, and click **Save**. See [Connect an external MCP server](../../../develop/mcp/connect_an_external_mcp_to_ragflow.md).+2. Open the **Agent** component, use its tool selector to choose the server, and select the tools to expose.+3. Describe when to use those tools in **System prompt**, then run a small test task.-| Field | Type | Required | Default Value | Description |-| --- | --- | --- | --- | --- |-| url | string | Yes | Empty | API address. Canvas variables can be used. |-| method | string | Yes | get | Supports `get`, `post`, and `put`. |-| headers | string/object | No | Empty | Request headers in JSON object format. Variables can be used in values. |-| variables | array[object] | No | `[]` | Request parameter list. Each item usually contains `key`, `value`, and `ref`. |-| timeout | integer | No | 60 | Request timeout in seconds. |-| proxy | string | No | Empty | Optional HTTP/HTTPS proxy address. |-| clean_html | boolean | No | false | Whether to clean HTML tags from the response. |-| body | string | No | Empty | Raw request body. |-| content_type | string | No | Empty | POST/PUT default to `application/json`. |+The running user must have permission to use the selected server. Tool arguments and results follow each server's tool schema; downstream Agent output remains the Agent's response. If a call fails, check server access, authentication, and required arguments.-#### Supported Values+### HTTP Request-| Parameter | Supported Value | Description |-| --- | --- | --- |-| Method | GET | GET request. |-| Method | POST | POST request. |-| Method | PUT | PUT request. |-| Proxy | HTTP | HTTP proxy. |-| Proxy | HTTPS | HTTPS proxy address. |+The HTTP Request component calls external HTTP APIs, allowing business systems, third-party services, or self-built APIs to be connected to Agent workflows.++#### Configuration++| Setting | Description |+| --- | --- |+| Url | API address. Insert canvas variables as needed. |+| Method | Select GET, POST, or PUT. |+| Timeout | Request timeout in seconds. Defaults to `60`. |+| Headers | Request headers as a JSON object. |+| Proxy | Optional proxy address. |+| Clean HTML | Remove HTML markup from the response. |+| Parameter | Click `+` to add request parameters and set their values using constants or variables. |#### Configuration Example-| Configuration Item | Example Value |+| Setting | Example Value || --- | --- |-| URL | `https://1.1.1.1/cdn-cgi/trace` |+| Url | `https://httpbin.org/get` || Method | GET |+| Timeout | 60 || Headers | `{}` |-| Variables | `[]` |-| Timeout | 30 |-| Proxy | |-| Clean HTML | false |-| Data Type | json |-| Body | |-| Content Type | |+| Parameter | `topic` = `ragflow` |#### Output Result-The output contains response status code, response headers, and response body. Text responses can be passed to the Agent for summarization, while JSON responses can be read by subsequent nodes.+The `result` output contains the response body as text. Pass the text to an Agent for summarization, or parse a JSON response body before accessing its fields.++If a URL is rejected, the output can contain `_ERROR` with a null `result`. Check for errors before consuming the response. Other request failures can surface as component execution errors.++#### Example: request, response, and next step++Connect **Begin → HTTP Request → Message**. Set **URL** to `https://httpbin.org/get`, **Method** to GET, and add a parameter named `topic` with the fixed value `ragflow`.++If the service is accessible from the server, its JSON response body includes:++```json+{"args": {"topic": "ragflow"}}+```++The component returns that body as the string `result`. In **Message**, insert HTTP Request's `result` to display it. To use only `args.topic`, first parse `result` in a Code component. If the test returns `_ERROR`, resolve that failure before consuming the result.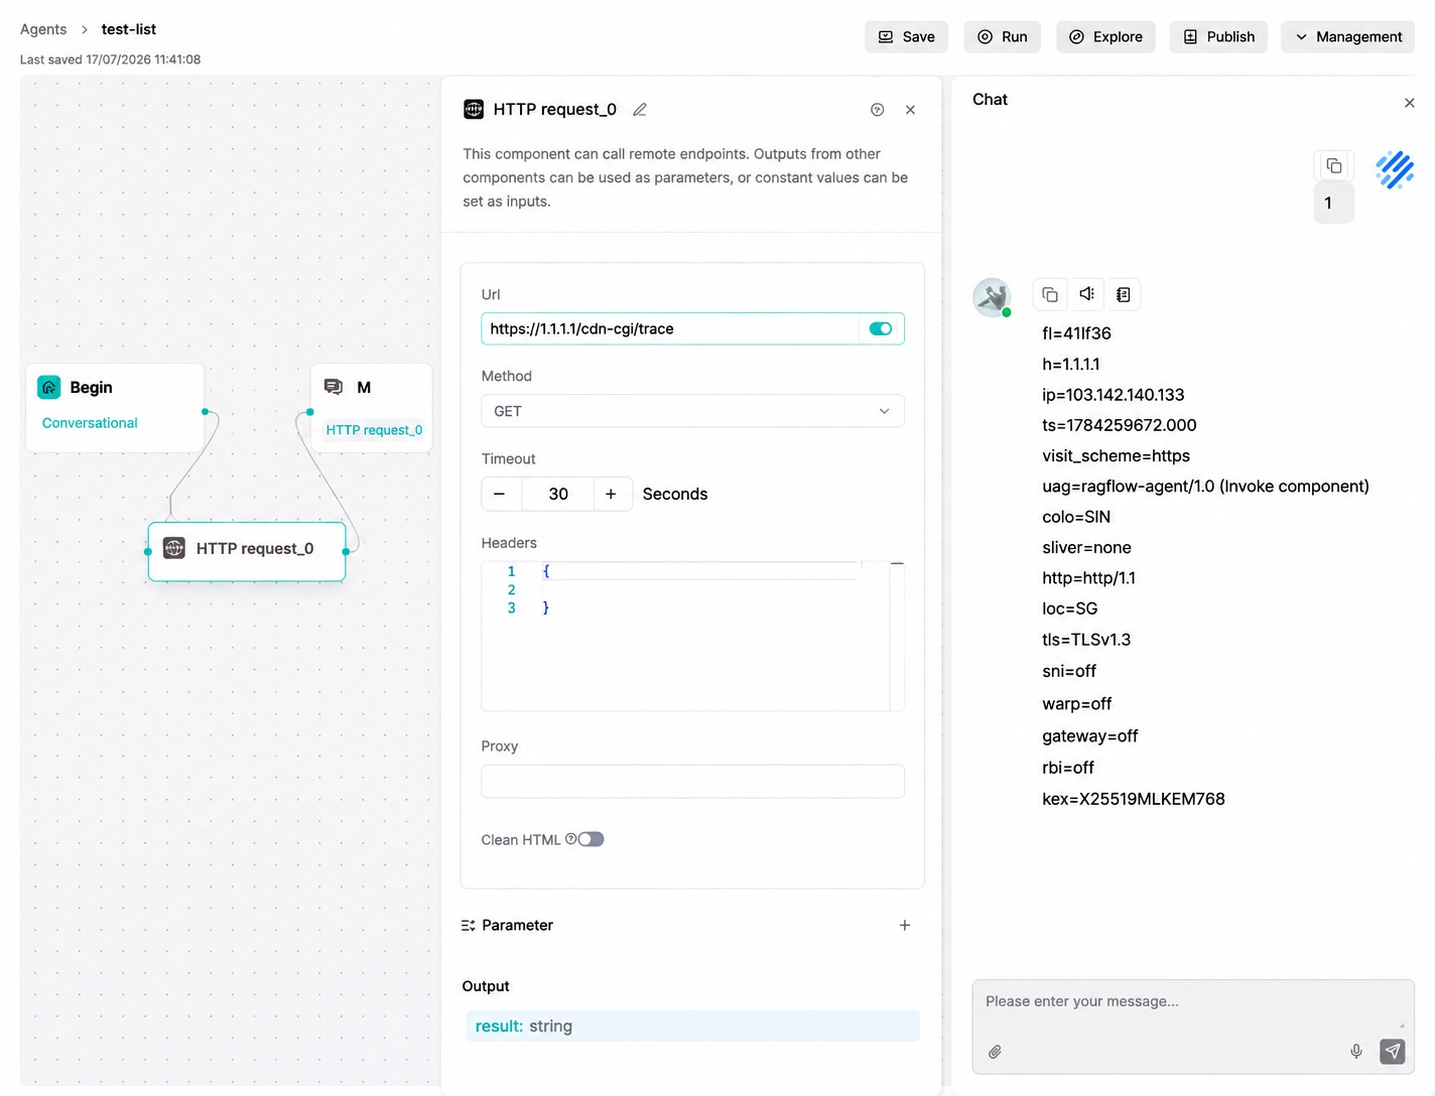@@ -725,29 +756,16 @@ The Document Generator component outputs Markdown content as PDF, DOCX, TXT, Mar| filename | string | No | Empty | File name. If empty, it is generated automatically, and illegal file name characters are cleaned. || header_text | string | No | Empty | Header text. Applies to PDF/DOCX. || footer_text | string | No | Empty | Footer text. Applies to PDF/DOCX. |-| watermark_text | string | No | Empty | Watermark text. Supported by PDF/DOCX/HTML according to the implementation. |+| watermark_text | string | No | Empty | Watermark text. Available for PDF, DOCX, and HTML. || add_page_numbers | boolean | No | true | Whether to add page numbers. Mainly used for PDF/DOCX. || add_timestamp | boolean | No | true | Whether to add generation time. |-| include_download_info_in_content | boolean | No | false | Whether to keep the download information marker in the content. || font_size | number | No | 12 | Font size, which must be greater than or equal to 12. |-#### Supported Values--| Parameter | Supported Value | Description |-|---------------|-----------------|------------------------------------------------|-| Output Format | pdf | PDF document. |-| Output Format | docx | Word document. |-| Output Format | html | HTML document. |-| Output Format | txt | Text file. |-| Output Format | markdown | Markdown file. |-| Font Size | >=12 | Font size must be greater than or equal to 12. |-#### Configuration Example| Configuration Item | Example Value ||-----------------------------------------------------------------|------------------------|-| Content | `# RAGFlow Agent |-| Test This document is generated by the DocGenerator component.` | |+| Content | `# RAGFlow Agent` || Output Format | pdf || Filename | ragflow-agent-test.pdf || Header Text | RAGFlow |@@ -755,53 +773,41 @@ The Document Generator component outputs Markdown content as PDF, DOCX, TXT, Mar| Watermark Text | DRAFT || Add Page Numbers | true || Add Timestamp | true |-| Include Download Info In Content | false || Font Size | 12 |#### Output Result-The output contains generated file attachment information, download links, and file names. Users can preview, download, or pass the file to subsequent nodes for further processing.+Use `download` to display the generated file in a Message. The other outputs identify the file and describe its name, type, and size.-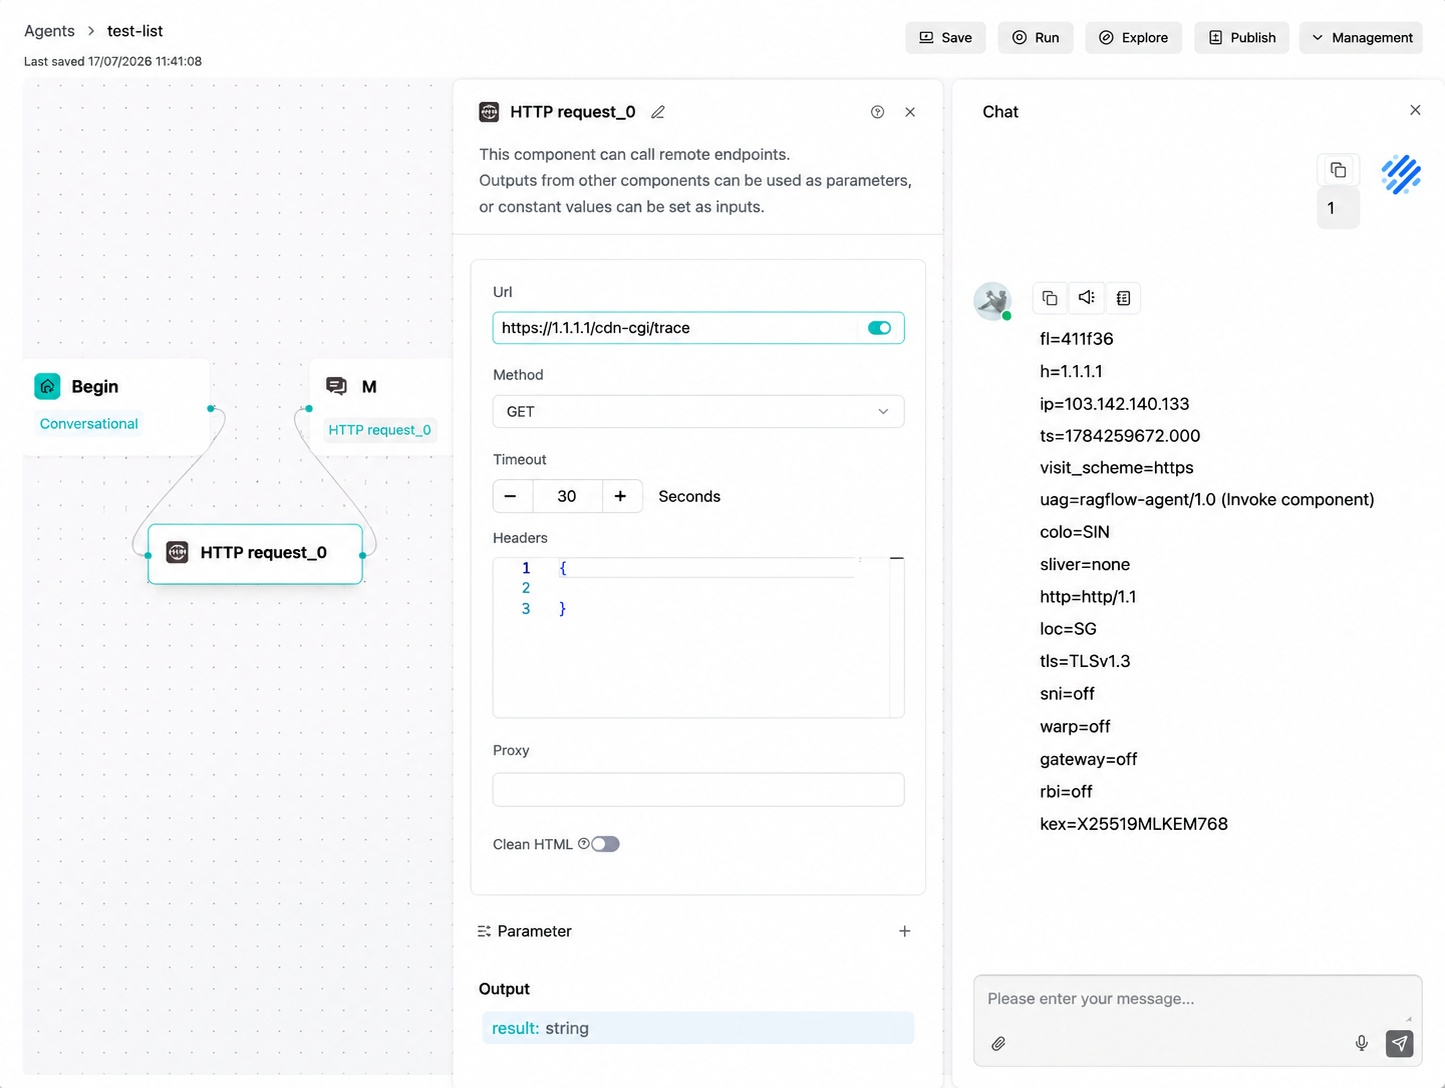+#### Example: generate a downloadable PDF++1. Connect **Begin → Document Generator → Message**. Begin needs no additional inputs.+2. In Document Generator, set **Content** to `# Sample report`, **Output Format** to **PDF**, and **Filename** to `sample-report.pdf`. Keep the other settings at their defaults.+3. In Message, open the variable selector and insert Document Generator's `download` output.+4. Save and click **Run**. The conversation should show a downloadable file named `sample-report.pdf`; open it to check that it contains the heading Sample report.### Browser (Browser)-Browser is an LLM-driven browser automation component. It can access web pages, perform multi-step operations, read page content, upload source files, and collect downloaded files based on natural-language tasks. It depends on the configured model and the browser automation dependencies in the runtime environment.+Browser uses a configured chat model and a natural-language instruction to extract web page content.#### Parameter Description| Field | Type | Required | Default Value | Description || --- | --- | --- | --- | --- |-| llm_id | string | Yes | Empty | Configured chat model ID used by Browser. |-| prompts | string | Yes | `{sys.query}` | Natural-language browser task. Canvas variables are supported. |-| headless | boolean | No | true | Whether to run the browser in headless mode. |-| enable_default_extensions | boolean | No | false | Whether to enable default `browser-use` extensions. |-| chromium_sandbox | boolean | No | false | Whether to enable the Chromium sandbox. In Docker root environments, keep this disabled in general. |-| upload_sources | array/string | No | `[]` | File IDs, URLs, or upstream variable references for the browser task. |--#### Supported Values--| Parameter | Supported Value | Description |-| --- | --- | --- |-| Upload Sources | File ID | File ID uploaded to RAGFlow. |-| Upload Sources | URL | Accessible file or web page URL. |-| Upload Sources | Upstream variable reference | File or resource reference from a previous node. |+| Model | Selection | Yes | None | Select a configured chat model from the dropdown. |+| prompts | string | Yes | `{sys.query}` | Extraction instruction. Canvas variables are supported. |+| headless | boolean | No | true | Whether to run the browser without a visible window. |#### Configuration Example| Configuration Item | Example Value || --- | --- |-| LLM ID | `<configured chat model ID>` |-| Prompt | Open https://www.ragflow.io, identify the main navigation items, and return them as a concise bullet list. |-| Max Steps | 10 |+| Model | Select an available chat model |+| Prompt | Extract the main navigation labels from https://www.ragflow.io and return a concise bullet list. || Headless | true |-| Enable Default Extensions | false |-| Chromium Sandbox | false |-| Persist Session | true |-| Upload Sources | `[]` |-| URL | |-| Timeout | 0 |#### Output Result-The output contains the browser task execution summary, extracted page content, and any generated download file information. Avoid assigning Browser tasks that involve login, payment, or irreversible submissions.+`content` contains the extracted text. Insert this field into a downstream Agent prompt or Message.++Test a small extraction task and check the returned content before connecting downstream components.diff --git a/docs/guides/agent/best_practices/accelerate_agent_question_answering.md b/docs/guides/agent/best_practices/accelerate_agent_question_answering.mdnew file mode 100644index 0000000000..5a5d311f81--- /dev/null+++ b/docs/guides/agent/best_practices/accelerate_agent_question_answering.md@@ -0,0 +1,21 @@+---+sidebar_position: 8+title: Improve Agent Response Time+slug: /accelerate_agent_question_answering+---++# Improve Agent Response Time++Use a representative question and inspect component results and execution logs to find the slow step. Change one setting at a time, then compare both response time and answer quality.++| Slow step | What to check |+| --- | --- |+| Agent generation | Keep prompts focused, request a concise answer, and reduce unnecessary history. Use a faster model for simple formatting or classification tasks. |+| Planning and tool calls | Remove tools or sub-agents that the task does not need. Keep reflection and multi-step planning for tasks that benefit from them. |+| Retrieval | Compare with and without a Rerank model. Adjust Rerank candidate count and Top N while checking that the evidence needed for the answer is still returned. |+| External tools | Inspect individual tool durations, response sizes, timeouts, and provider errors before increasing retries. |+| Iteration | For independent items, try a bounded Maximum concurrency greater than `1`. Respect model and service rate limits. |++If the selected model provides reasoning settings, adjust them and compare response time and answer quality.++Retest a normal question, a question with no matching knowledge, and a tool failure after tuning. A faster answer is useful only if routing, evidence, and error handling still work.diff --git a/docs/guides/agent/creation_and_management.md b/docs/guides/agent/creation_and_management.mdindex 3ca019697f..bd17f573d6 100644--- a/docs/guides/agent/creation_and_management.md+++ b/docs/guides/agent/creation_and_management.md@@ -18,37 +18,31 @@ After logging into RAGFlow, click **Agent** in the top navigation bar to enter t## Create from TemplateRAGFlow provides Agent templates for different business scenarios. When creating from a template, the system presets common components and connections. Users only need to modify models, knowledge bases, prompts, interface addresses or output content.-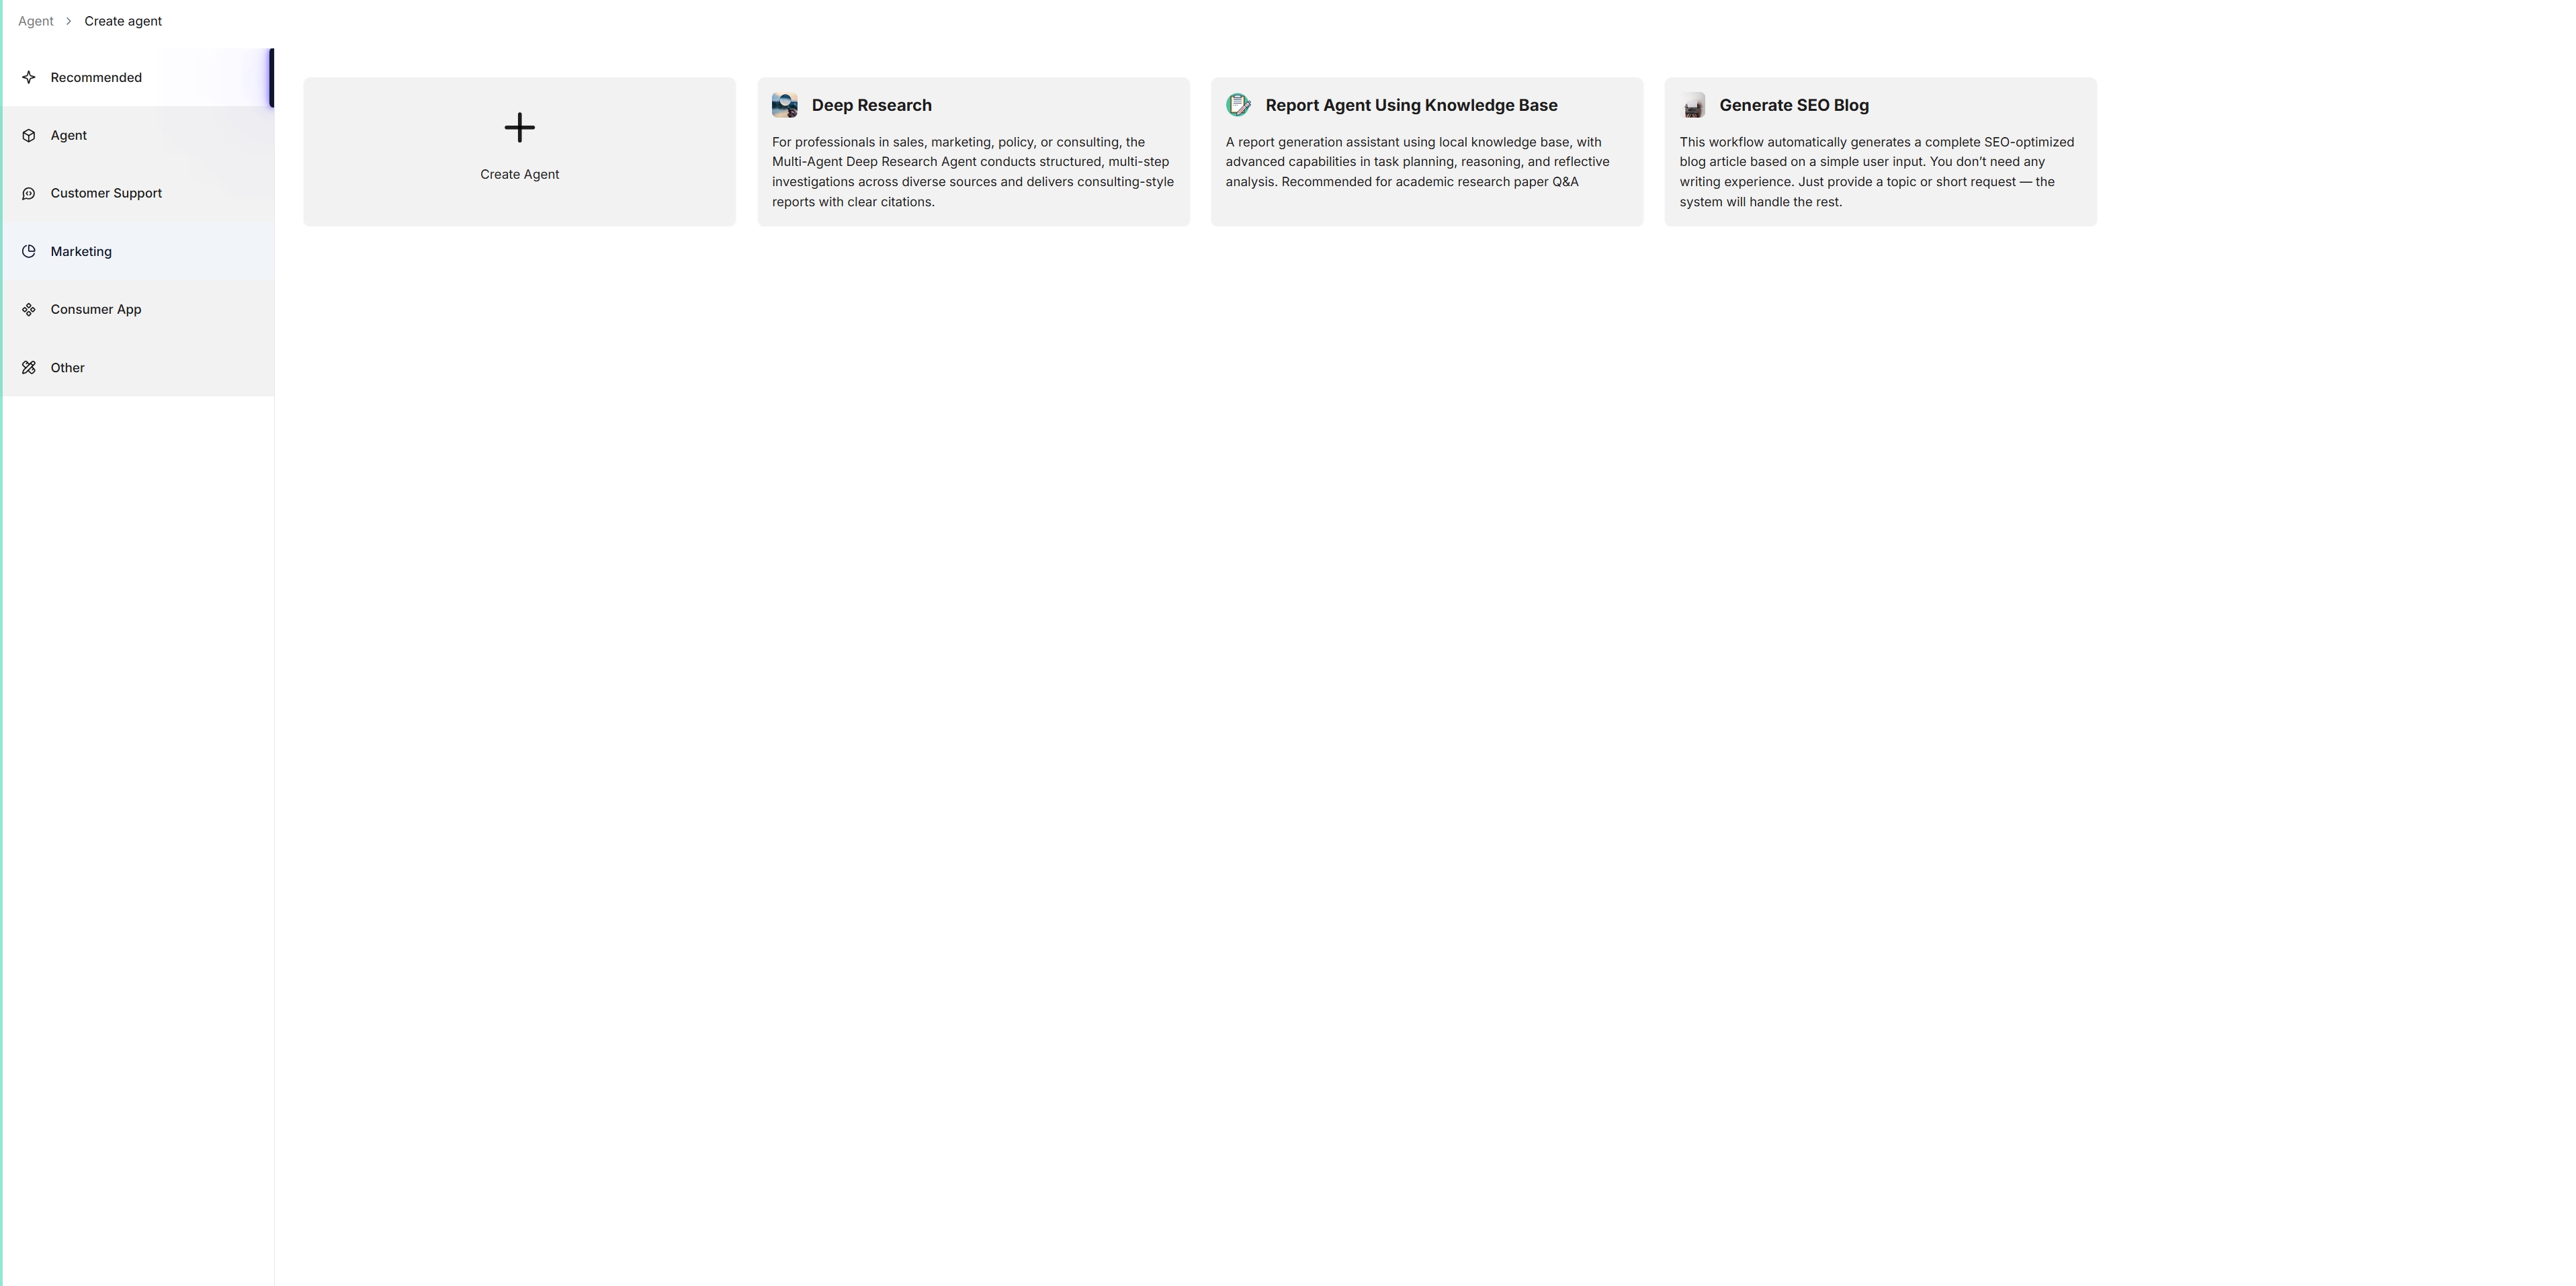-Steps:1. Enter the Agent page.-2. Click **Create agent**.+2. Open **Create agent > Create from template**.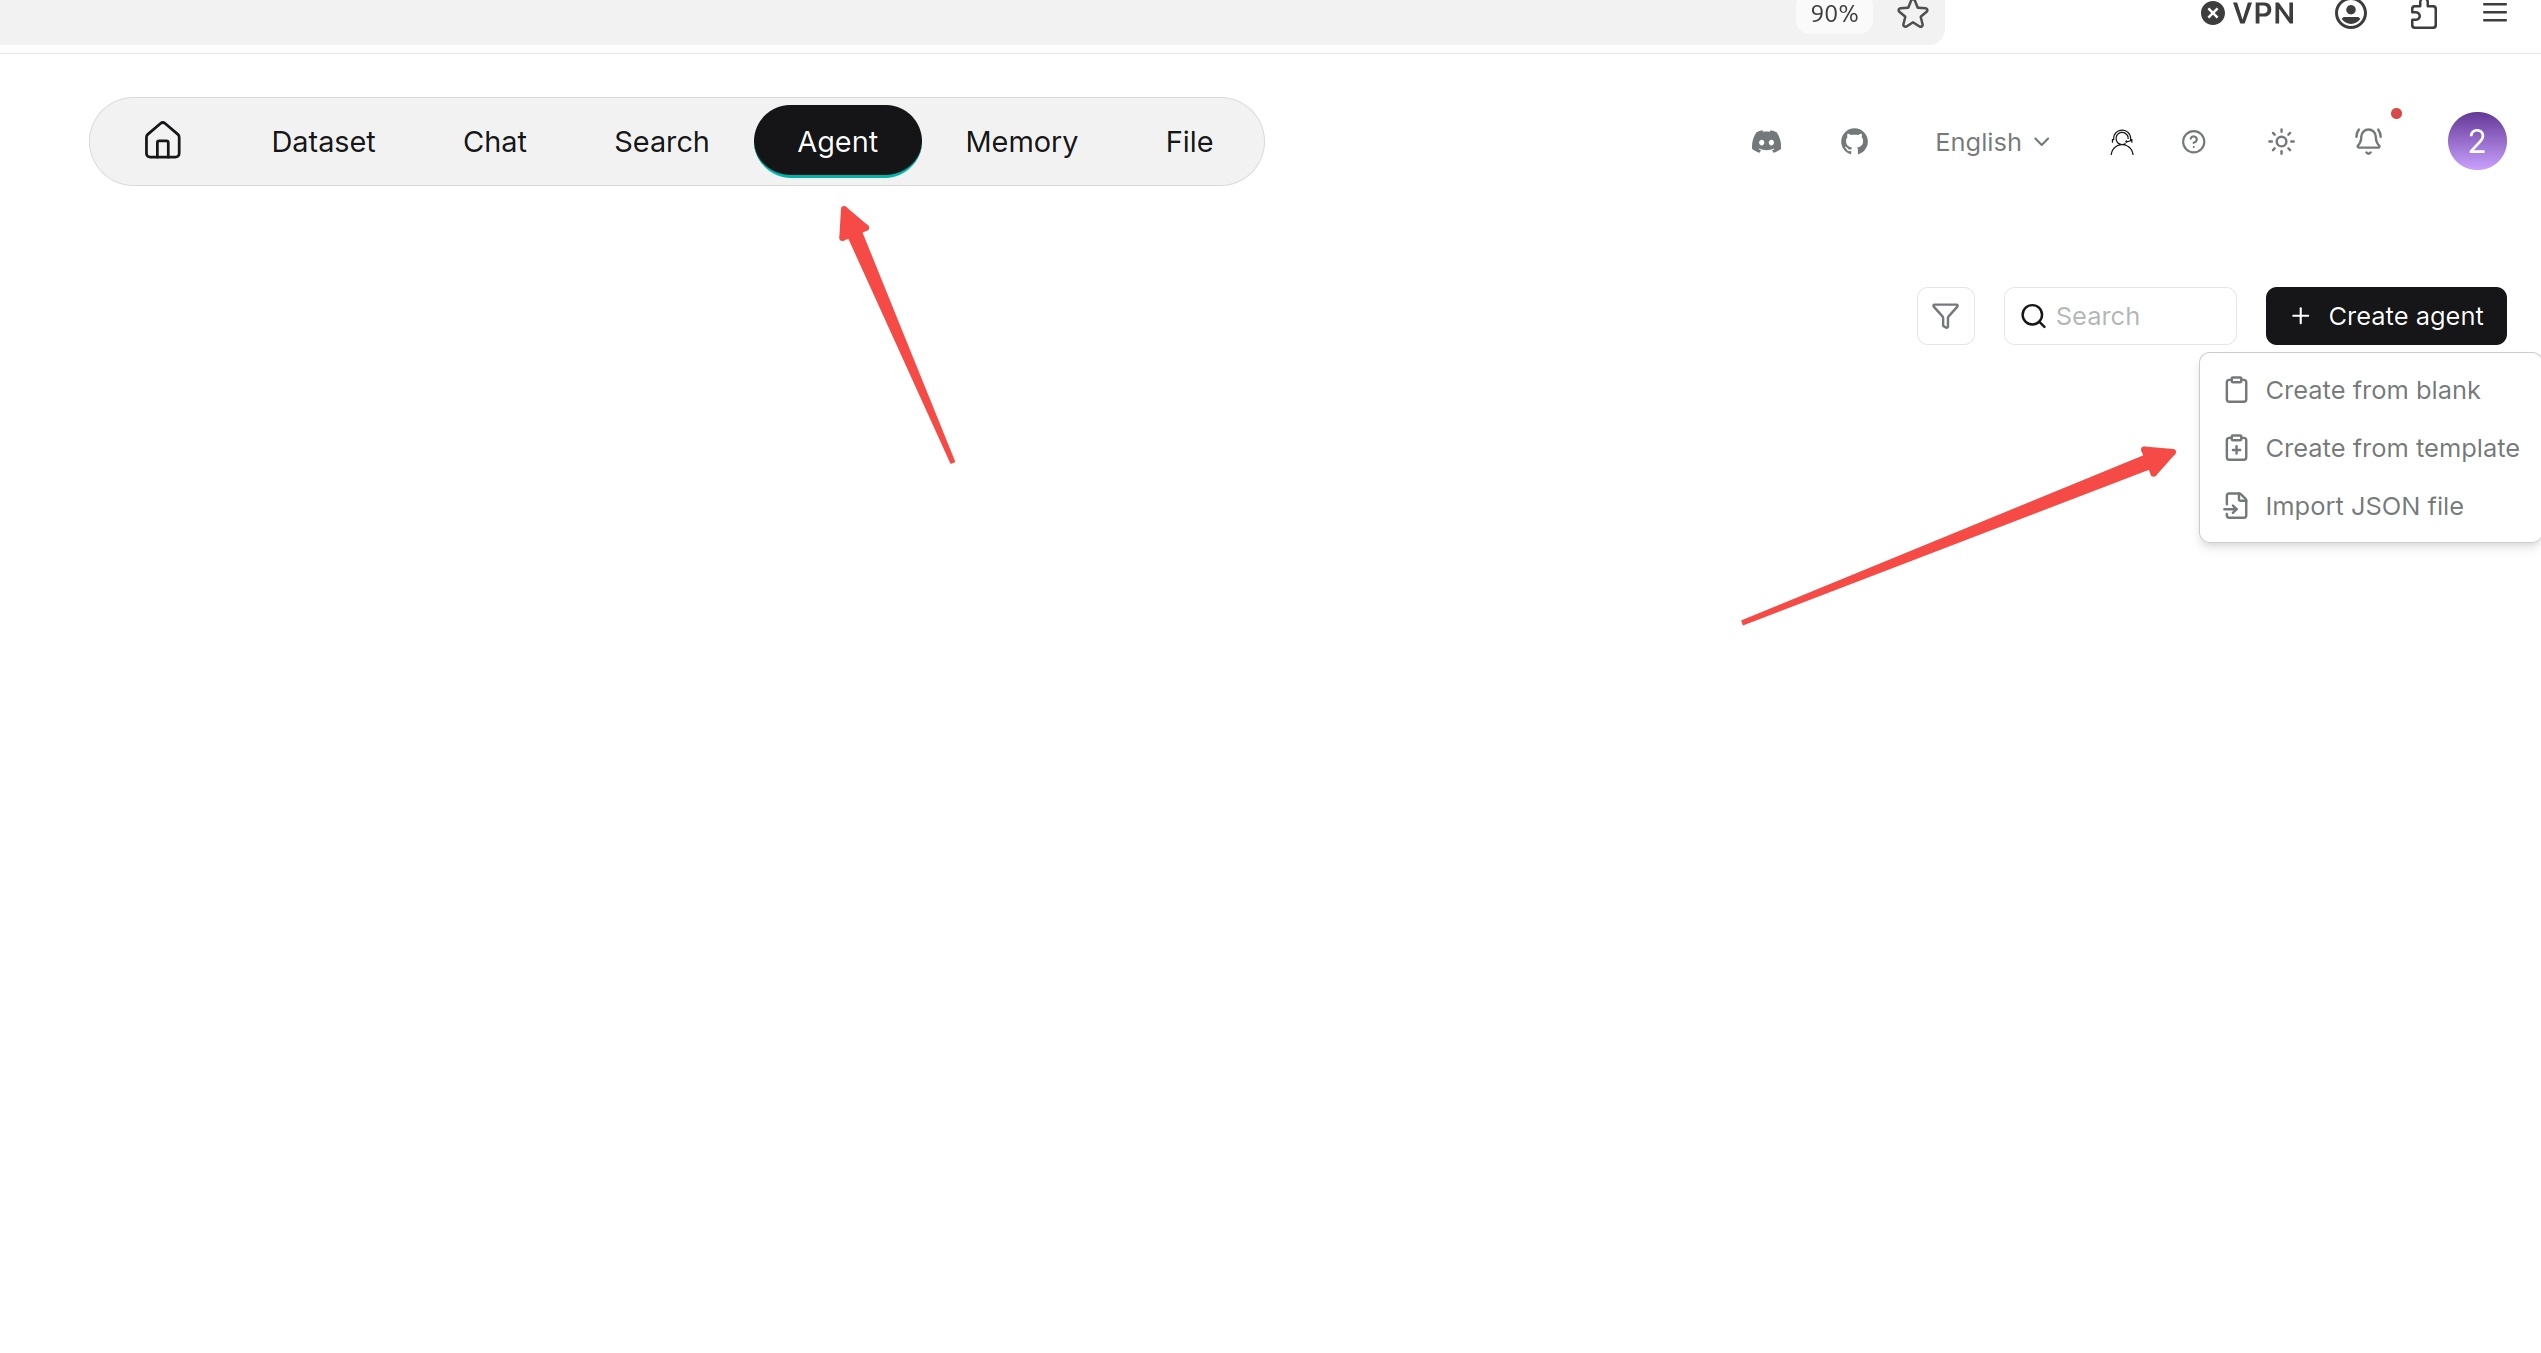3. Select an appropriate template on the template page, such as Deep Research, Knowledge Base Q&A, Data Analysis or E-commerce Customer Service template.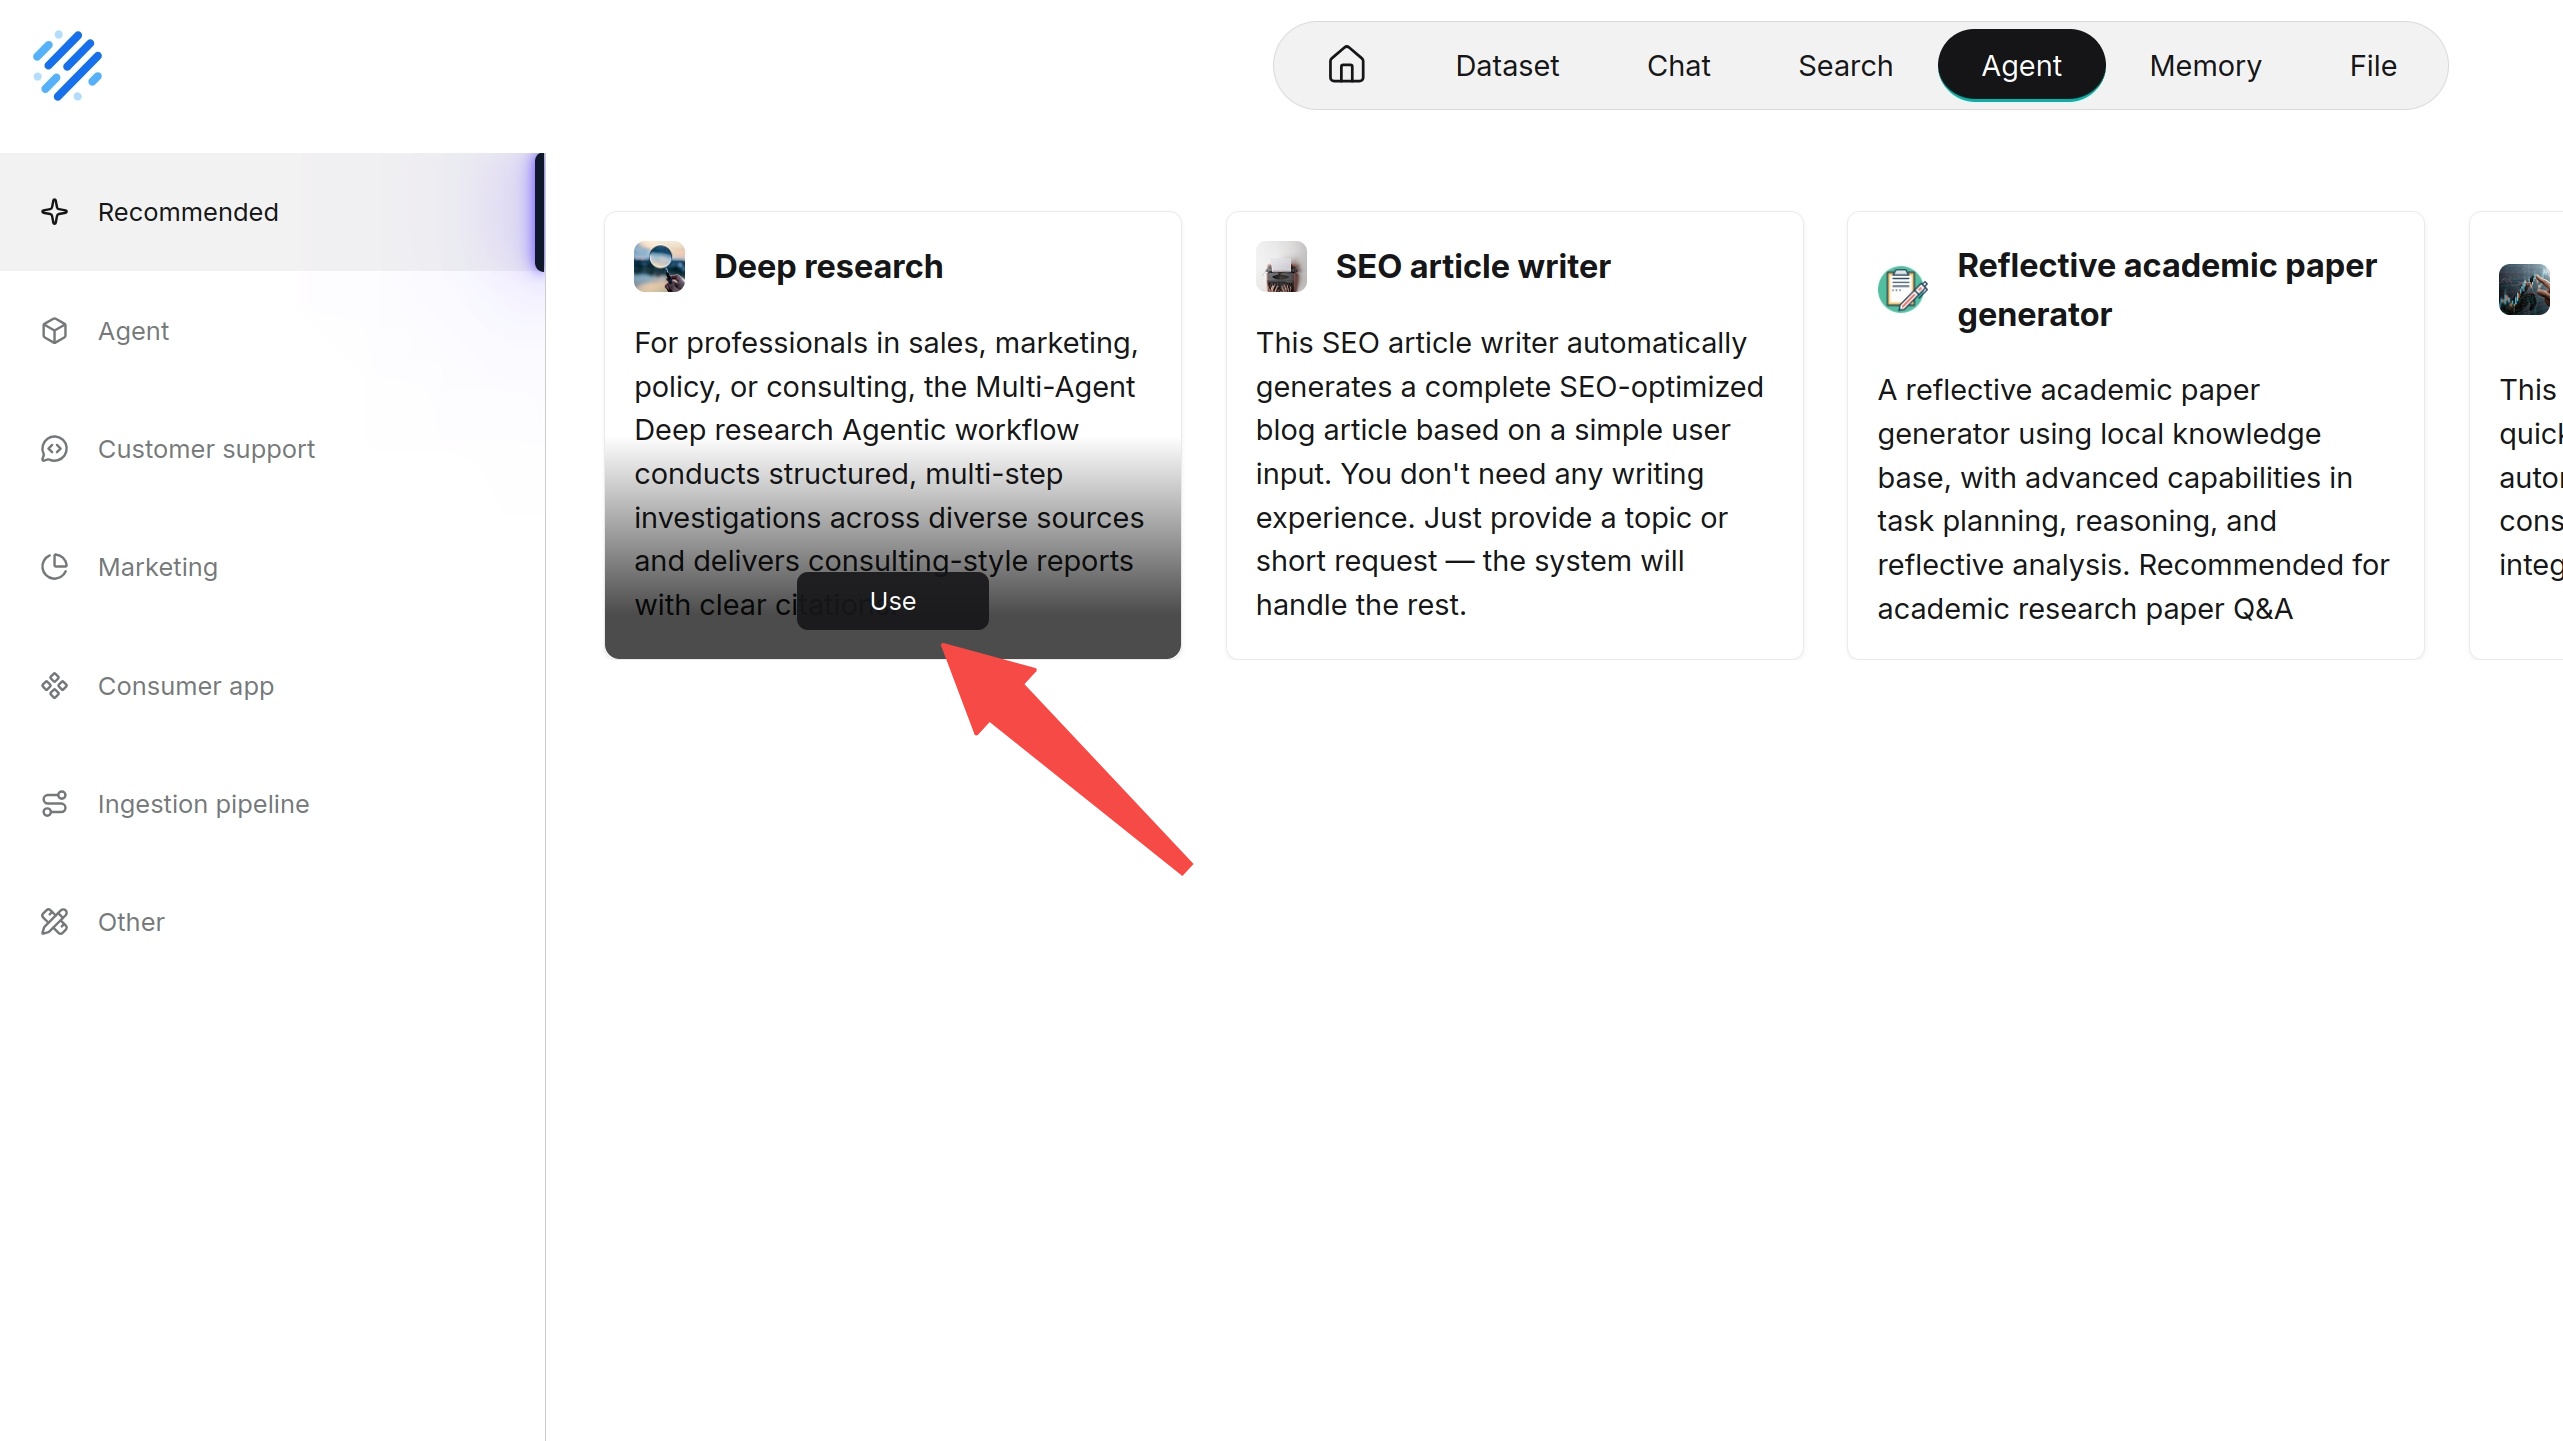4. Enter the Agent name.-5. Click **OK**.--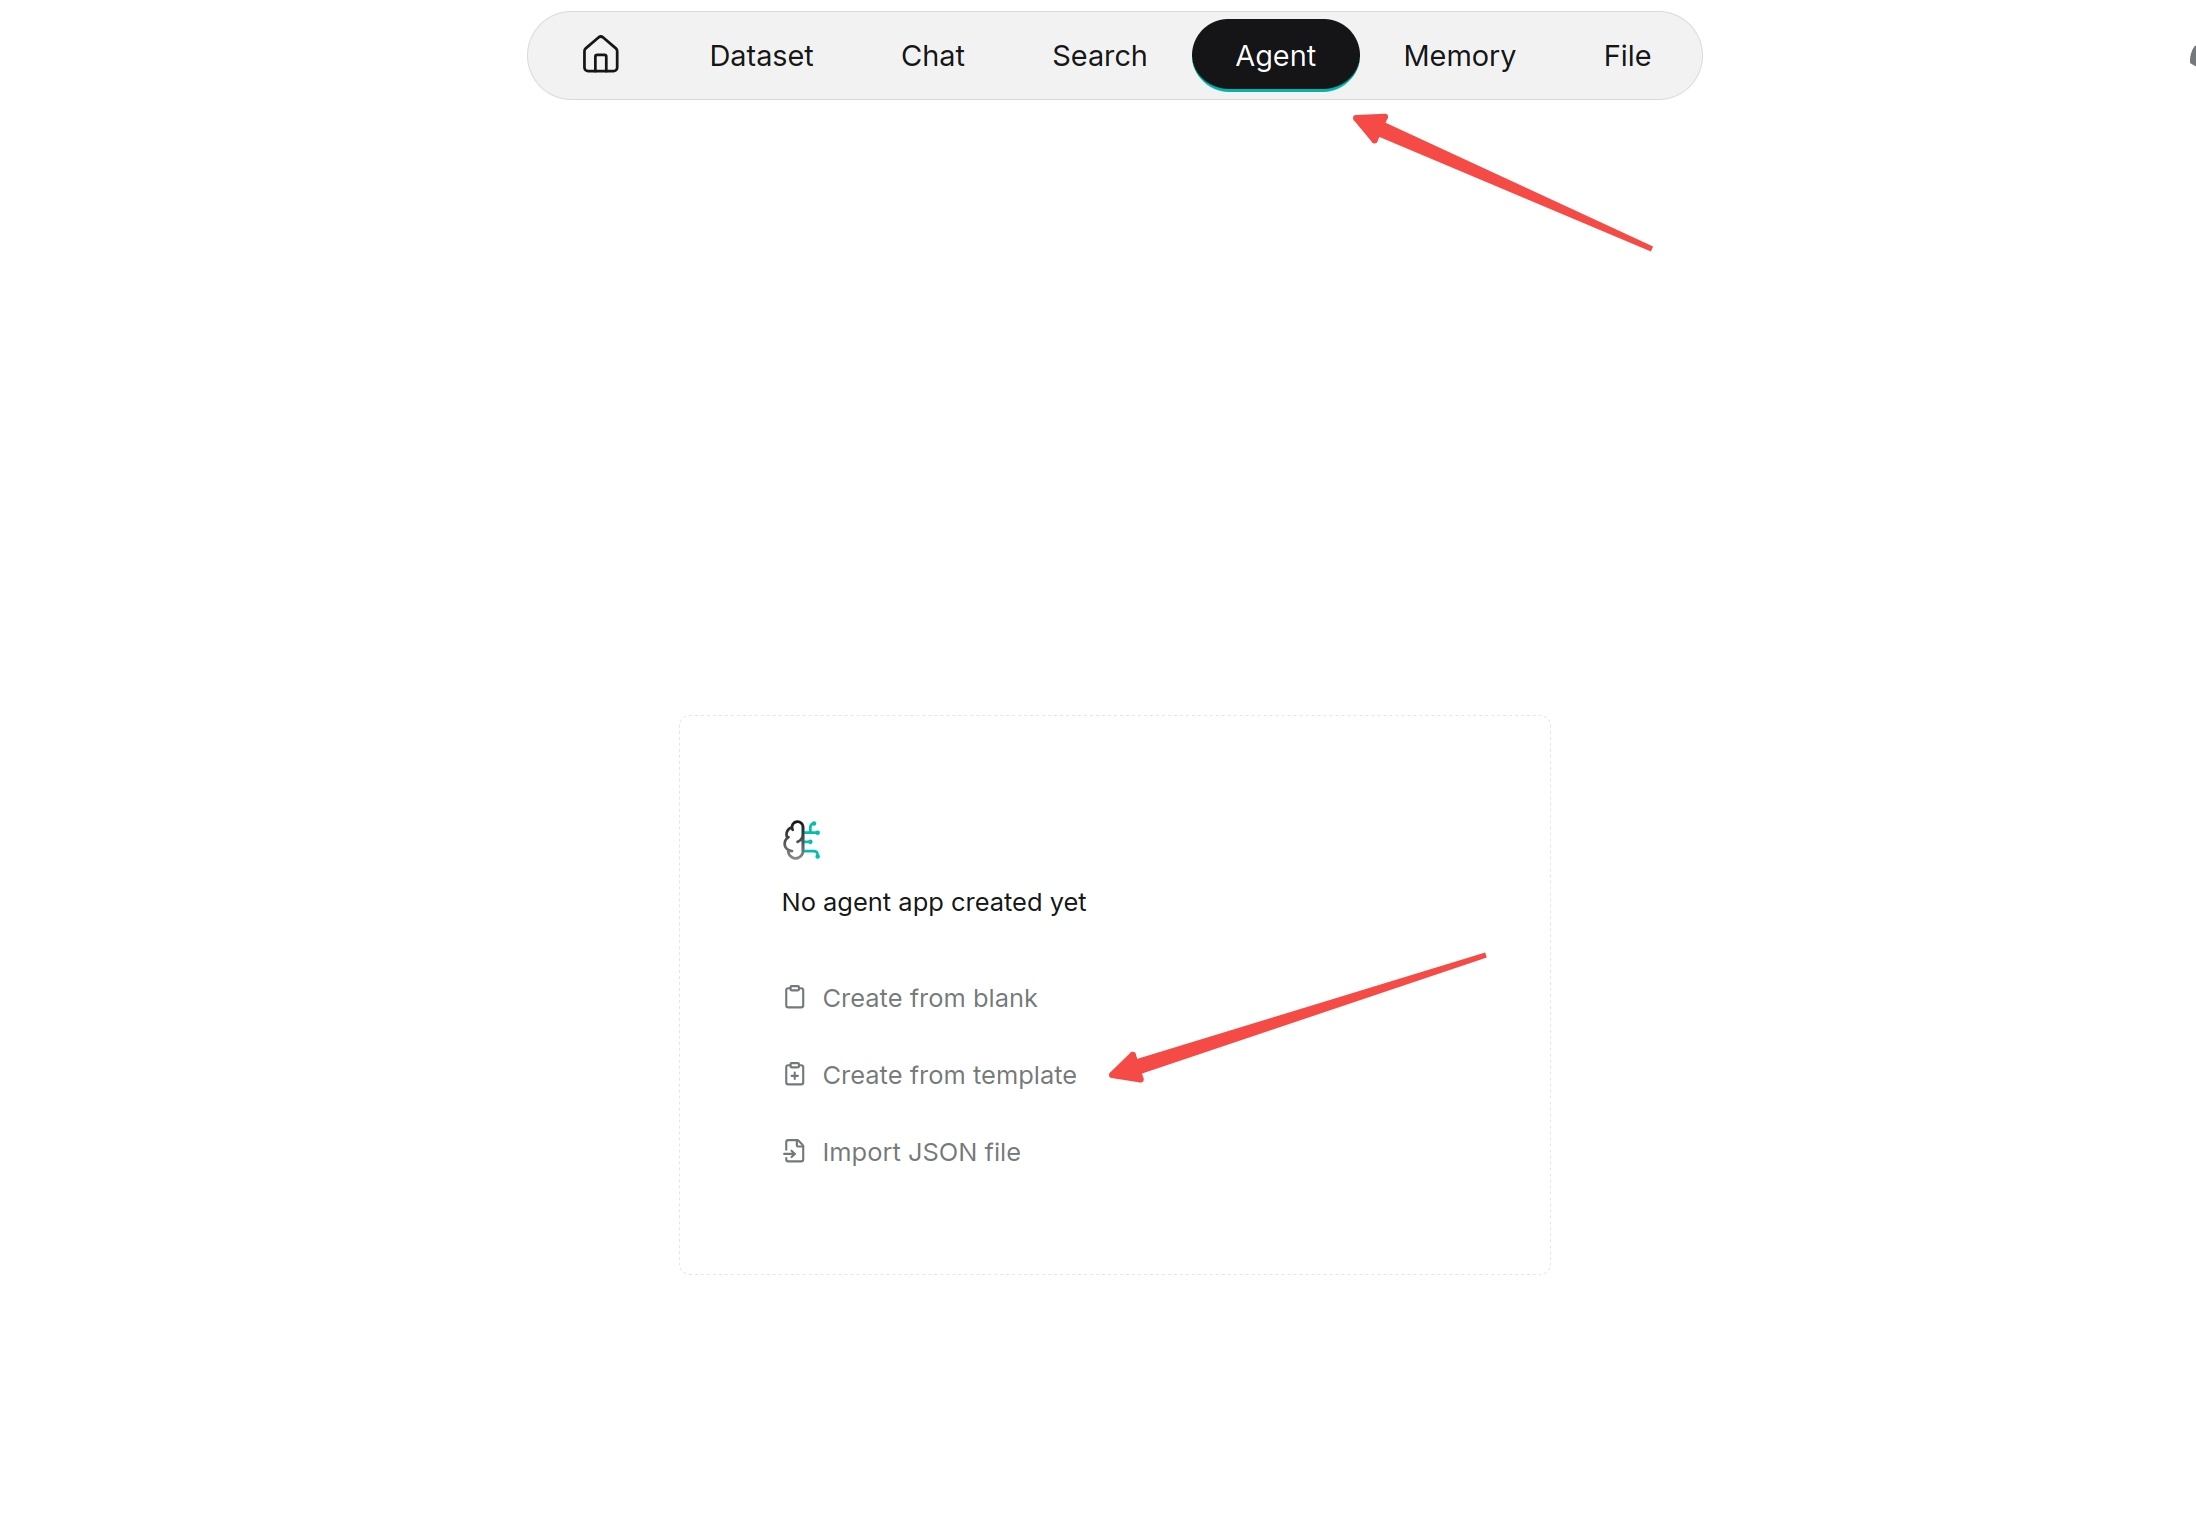+5. Confirm the creation.6. After entering the canvas, check the configuration of each component and save.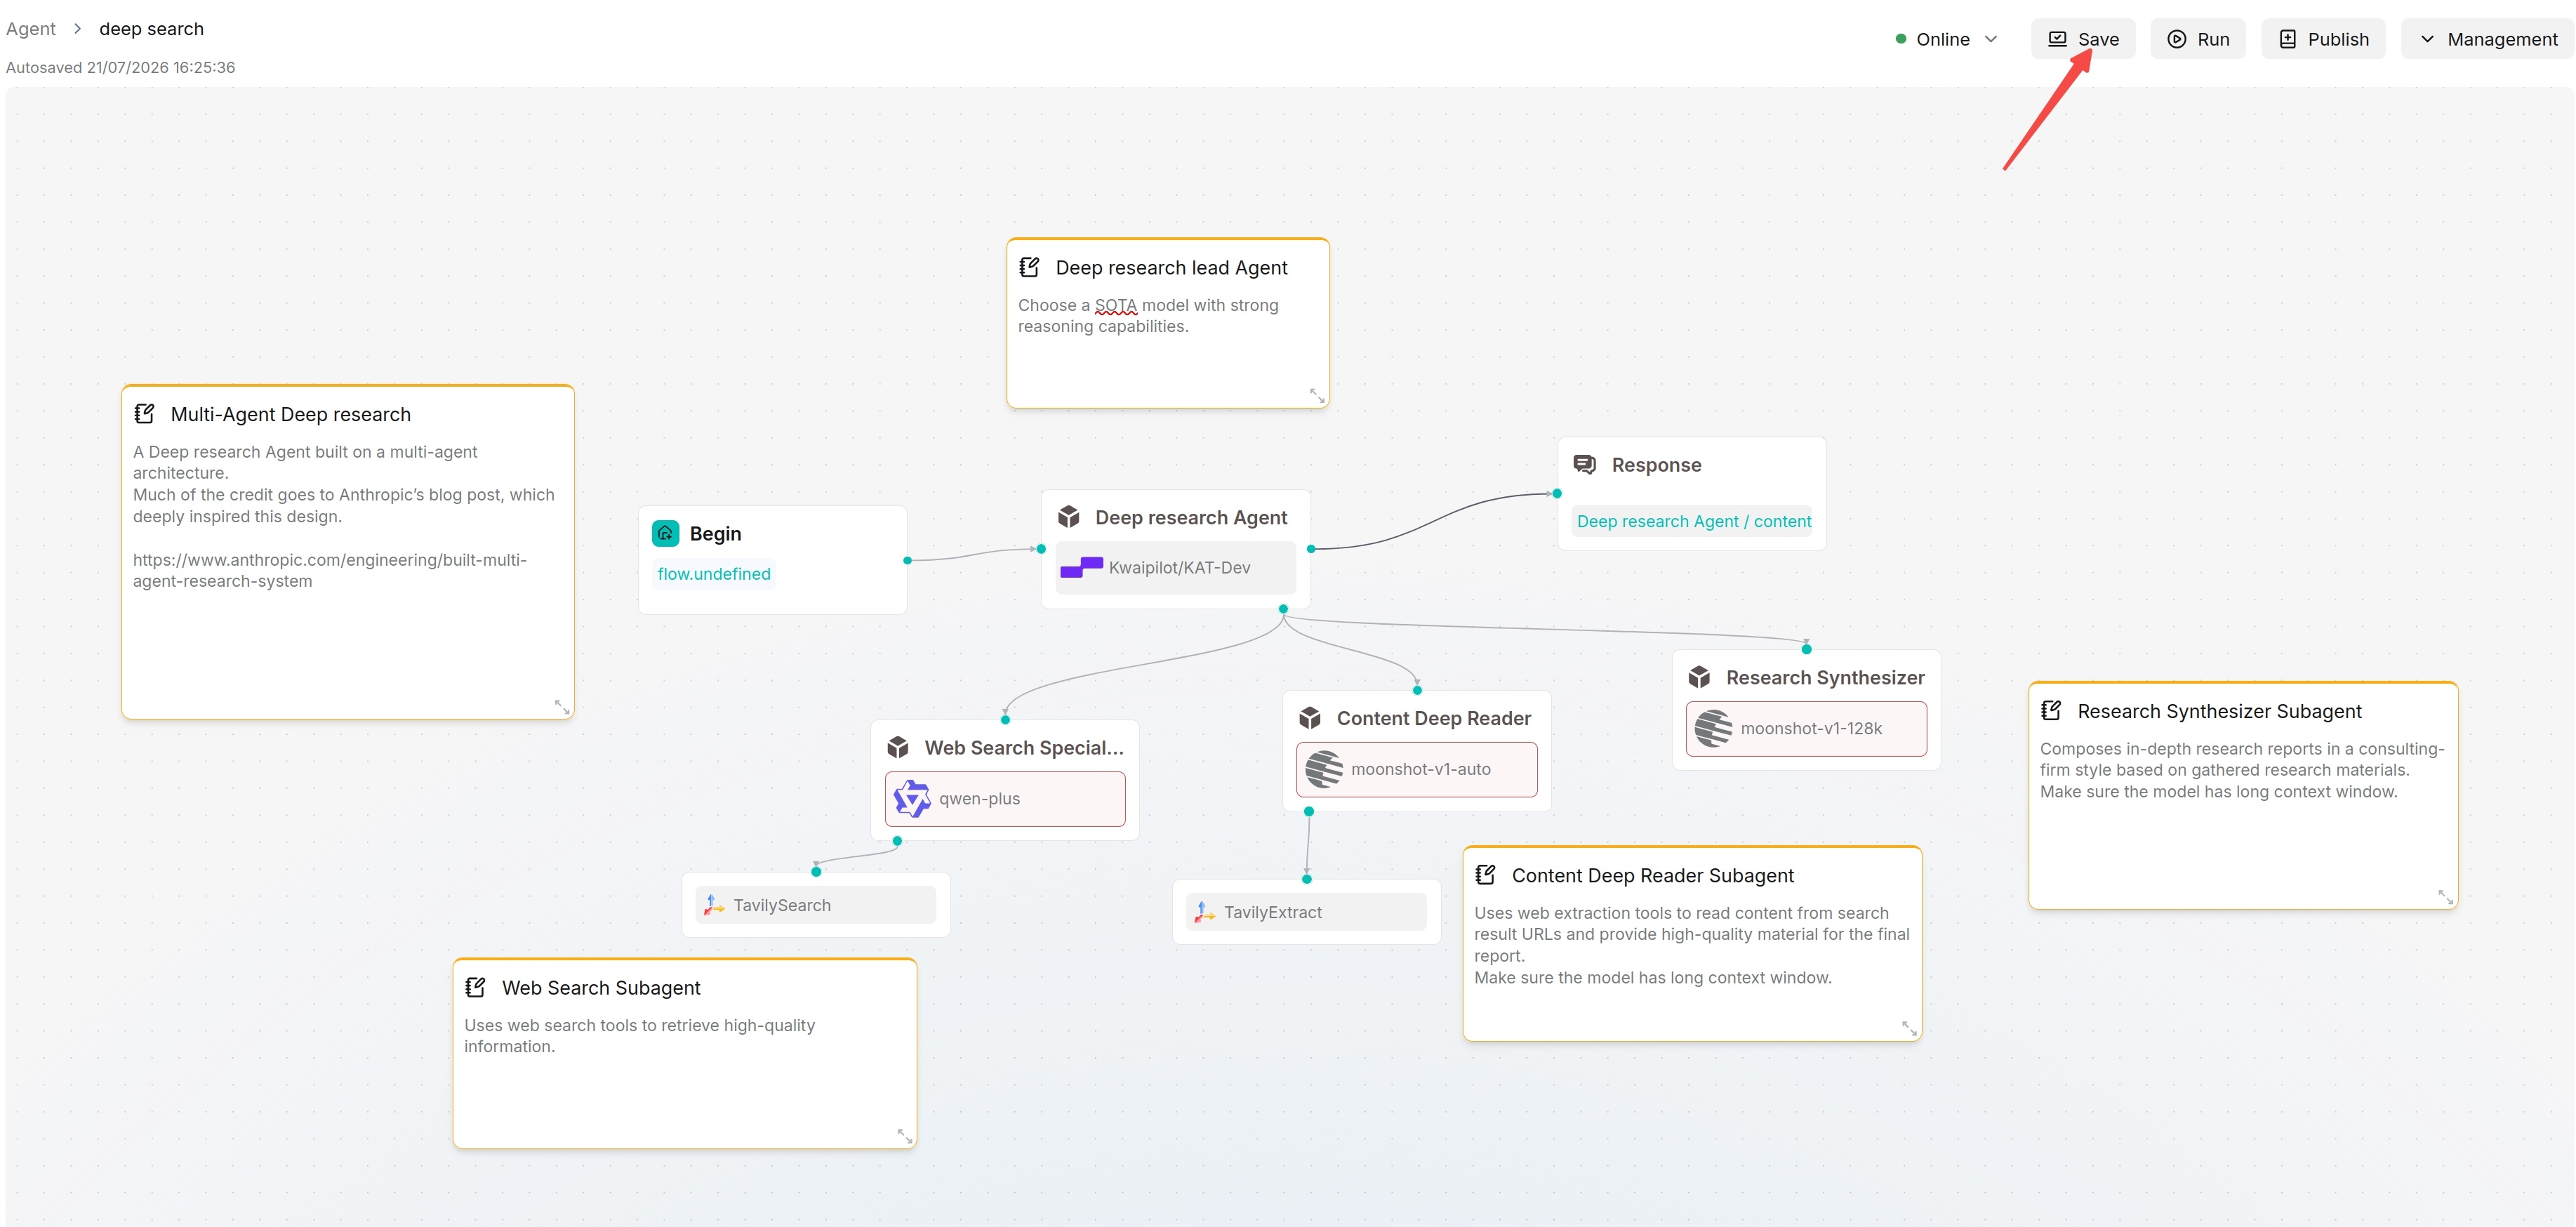## Create from Blank Agent-When creating a blank Agent, the canvas contains a default `Begin` component. Users can click the plus sign next to the Begin component or other components to add downstream components.+A blank Workflow starts with **Begin**. Use a component's outgoing connection point to add downstream components. An Ingestion pipeline starts with **Begin → Parser**; see [Create an Ingestion Pipeline](./ingestion_pipeline/create_ingestion_pipeline.md) for its setup.Steps:1. Enter the Agent page.-2. Click **Create agent**.-3. Select blank creation.+2. Open **Create agent**.+3. Select **Create from blank**.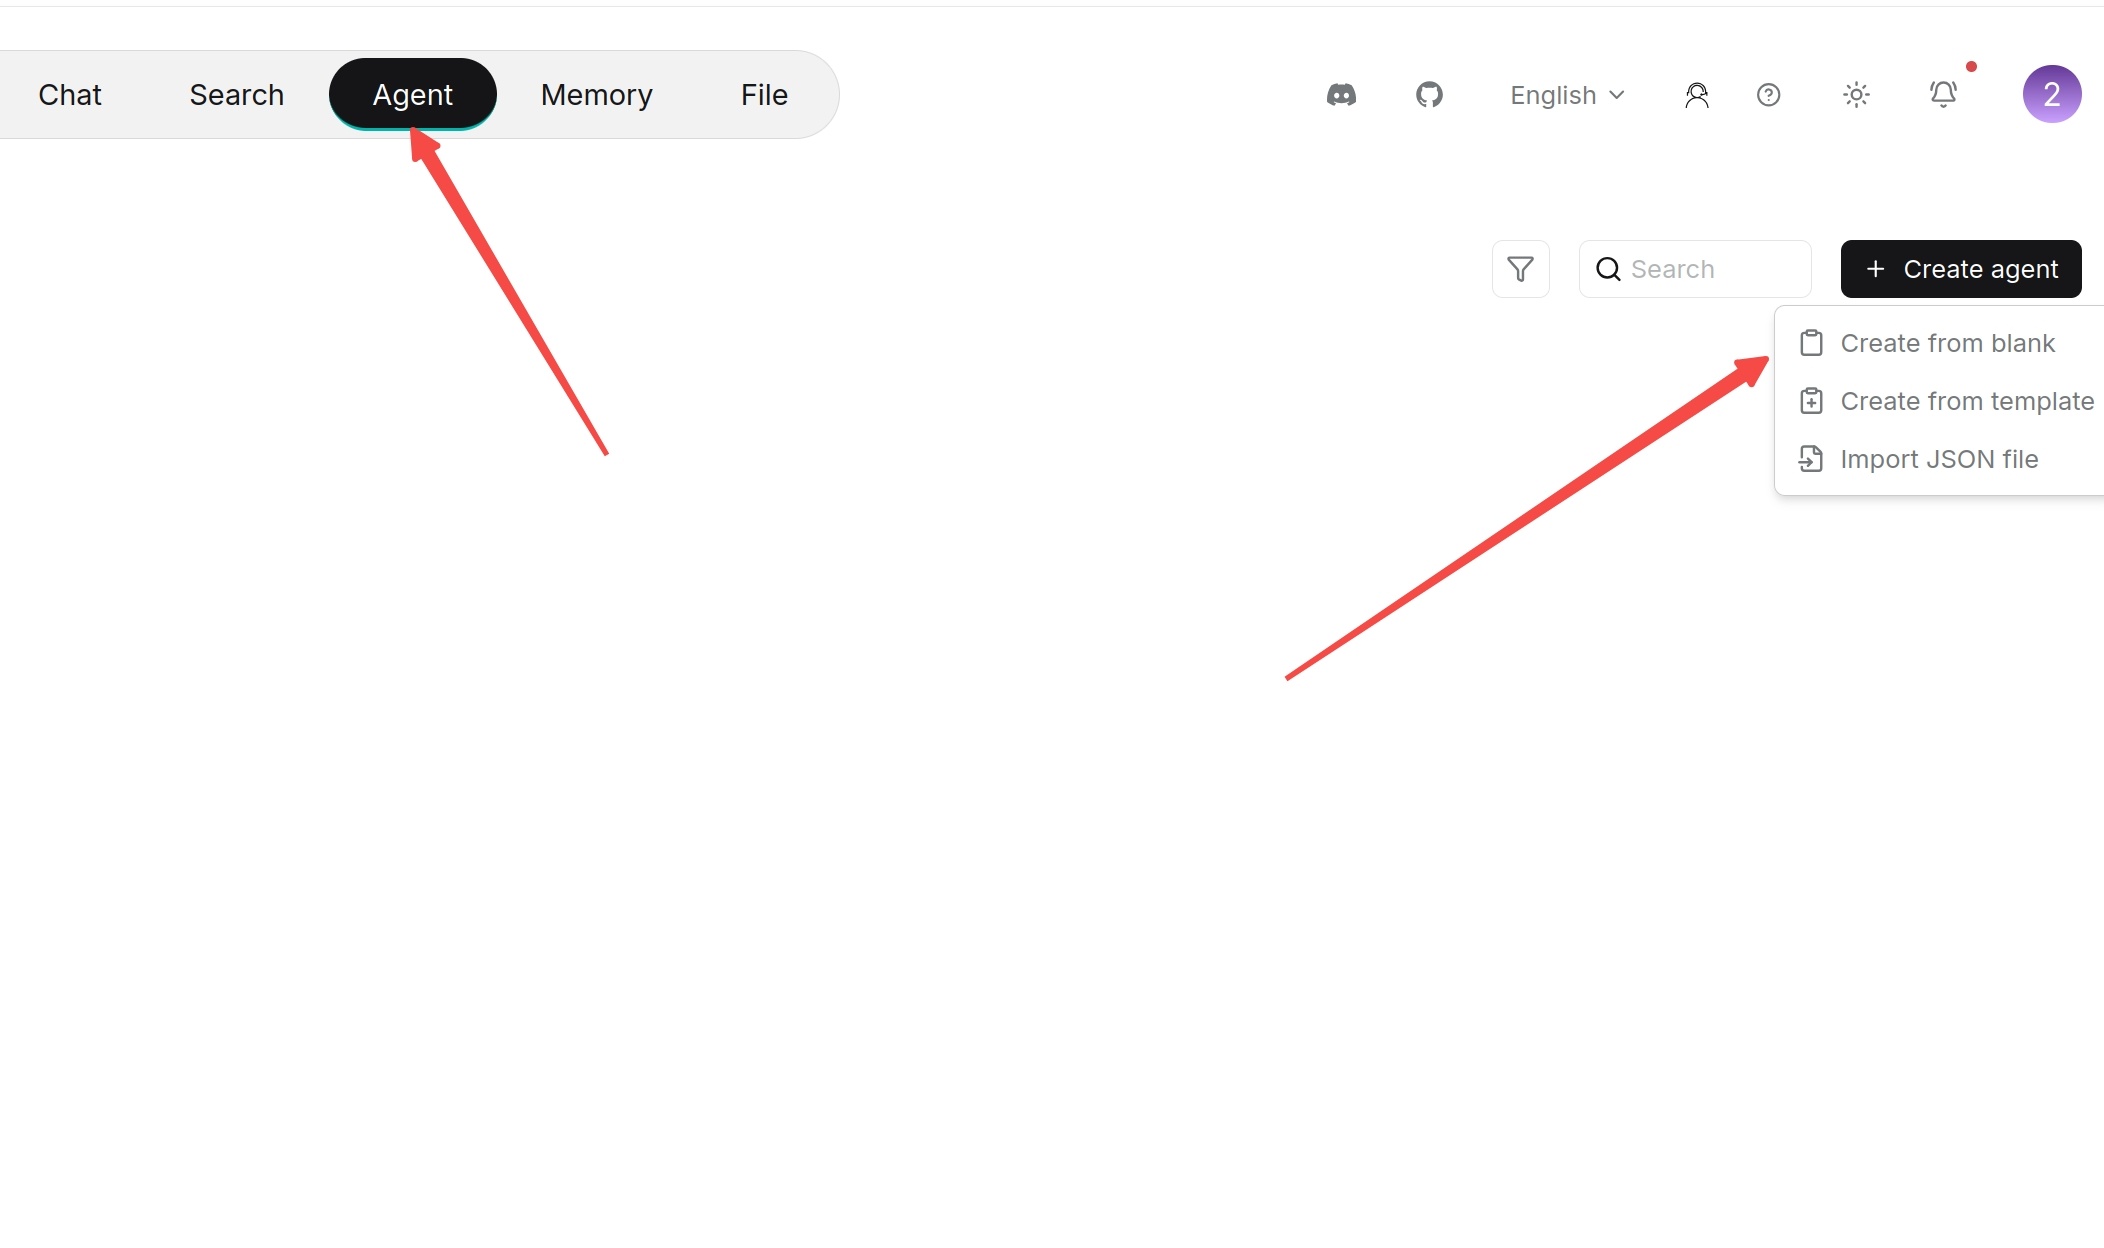-4. Enter the Agent name and select the agent type.--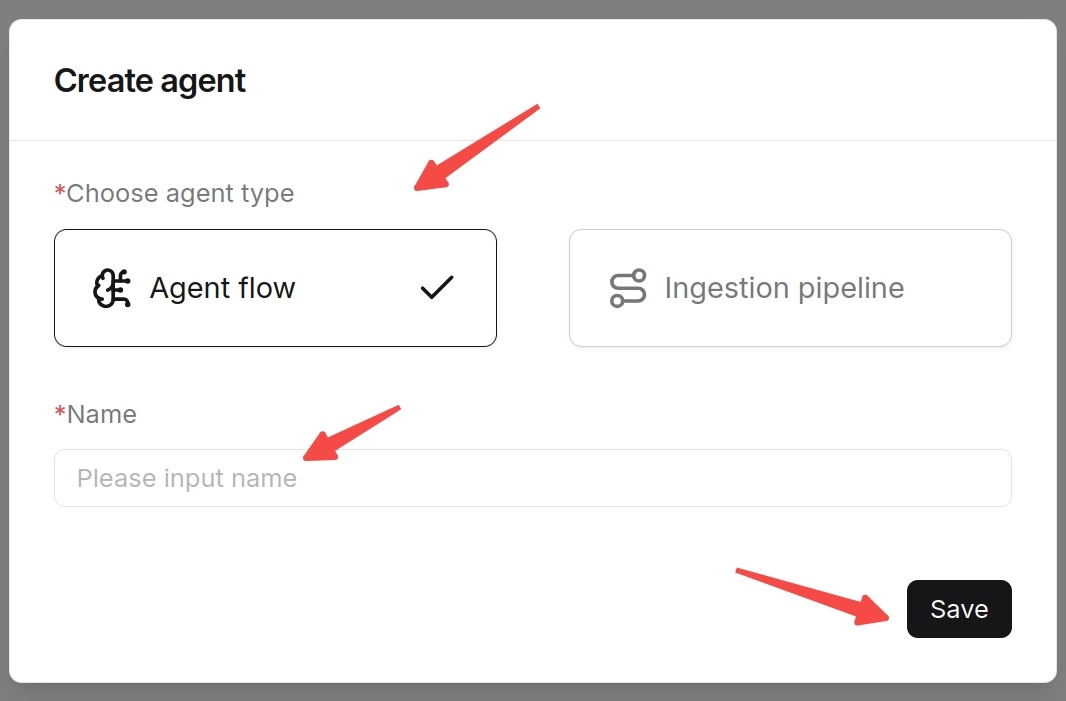-5. Enter the canvas.-6. Click the plus sign next to the `Begin` component, and add components according to business processes.+4. Select **Workflow**, **Ingestion pipeline**, or **Compilation operator**, enter **Name**, and click **Confirm**. Choose Workflow for a conversational Agent.+5. Open the created card to enter its canvas. For **Compilation operator**, configure the template group and model as described in [Configure the Compiler Component](./ingestion_pipeline/understand_core_ingestion_pipeline_components.md#configure-the-compiler-component).+6. For a Workflow, click the outgoing connection point on **Begin** and add the next component.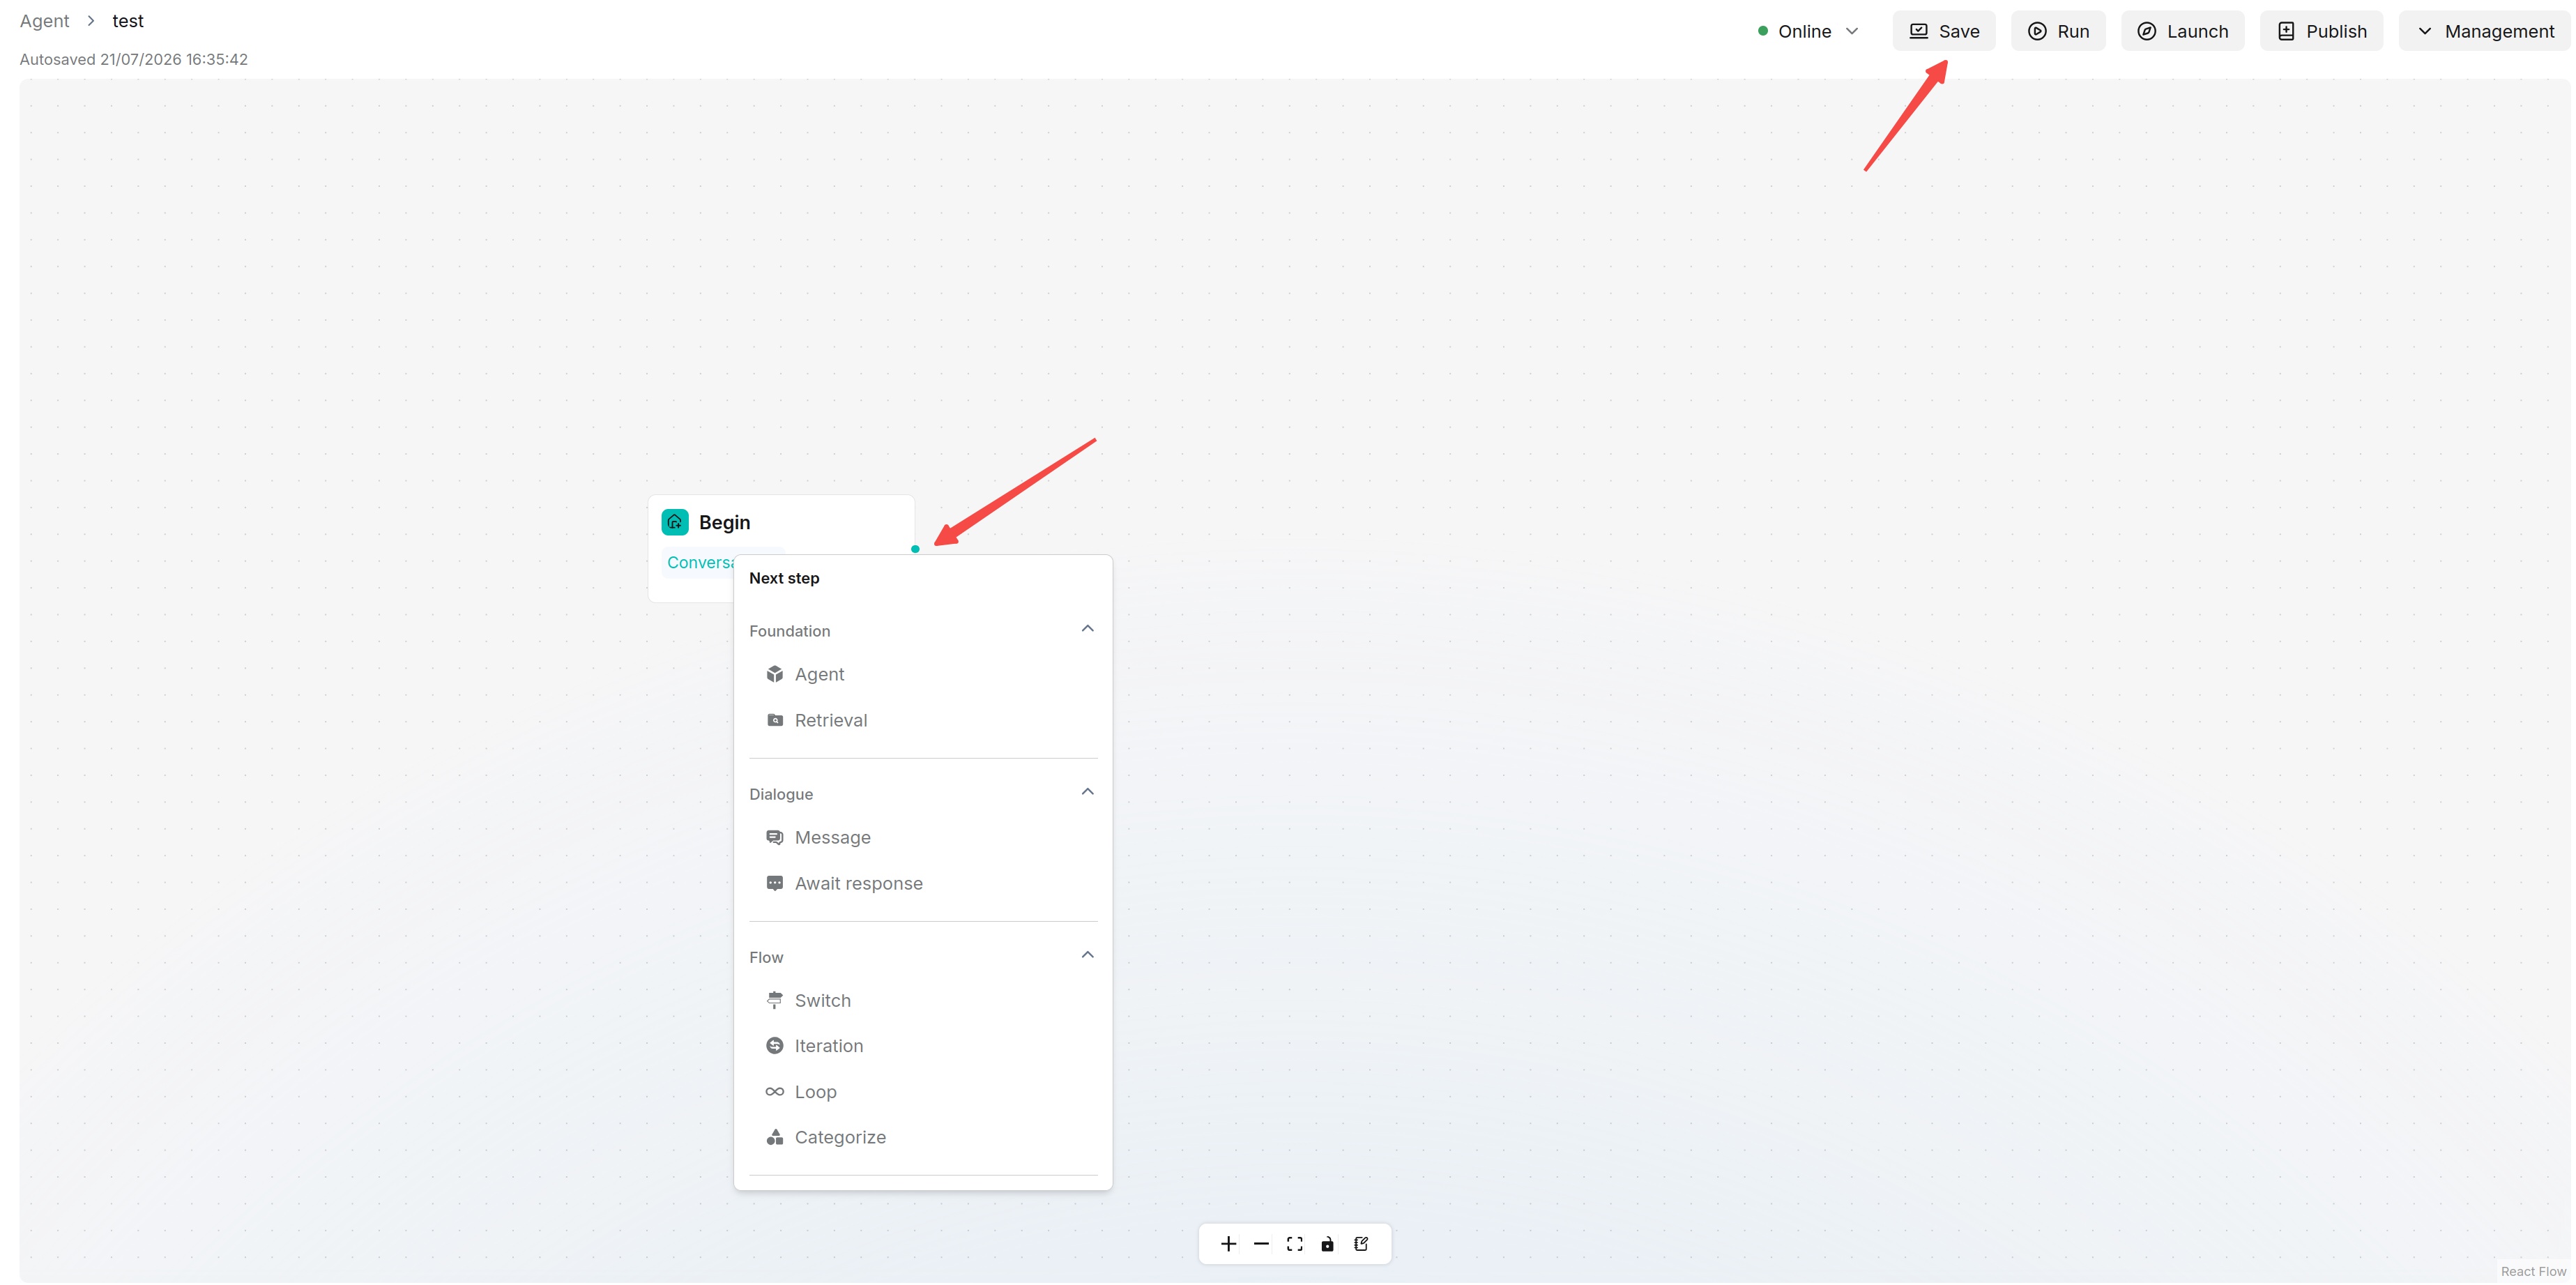7. Configure each component.@@ -58,7 +52,30 @@ Steps:The `Begin` component is the start of the workflow. Each Agent can only have one Begin component and it cannot be deleted. After creation, configure Begin first, then configure subsequent components.:::## Search, Copy and Delete Agent-In the Agent list, you can search for target Agents by name. If copy, delete or other operation entries are available on the interface, confirm the Agent name and permission scope before operation. Deletion is usually irreversible. Please confirm whether the Agent is referenced by embedded web pages, API calls or other workflows.+- **Search**: Enter the Agent name in the list's search box.+- **Copy**: Open the Agent, choose **Management > Export**, then [import the JSON](./import_and_export_agents.md#import-agent) with a different name.+- **Delete**: Open the card's **…** menu, select **Delete**, and confirm the Agent name. Deletion removes the Agent and its saved versions. Export a copy first if you need to keep its configuration.++## Save and Publish++The editor shows the latest autosave time.++- **Save**: Save the editing configuration.+- **Run**: Test the workflow in the editor.+- **Launch**: Open the conversation page in Conversational mode.+- **Publish**: Create a published version after checking the test results.++## Management++The Workflow canvas provides these entries under **Management**:++| Entry | Purpose |+| --- | --- |+| Conversation variable | Configure variables used in a conversation. |+| Version history | Browse recorded versions and inspect their canvas configurations. A history entry alone does not indicate a published version. |+| Log | Search execution records by **ID/Title** and date. View state, version, and other record details, or use **Export current page**. |+| Export | Export the Agent configuration. |+| Settings | Open Agent settings. |+| Embed into webpage | Open the website embedding options. |-## Save Agent-Click **Save** in time after editing the canvas. Saving only records the current configuration. Whether it immediately affects published or embedded Agents depends on the version publishing mechanism and deployment strategy. Re-run tests before external usage.+Available controls differ for other Agent types. Ingestion pipeline creation and validation are covered in the [pipeline guide](./ingestion_pipeline/create_ingestion_pipeline.md).diff --git a/docs/guides/agent/embed_into_web_pages.md b/docs/guides/agent/embed_into_web_pages.mdindex 57f97782ec..a3a28beedf 100644--- a/docs/guides/agent/embed_into_web_pages.md+++ b/docs/guides/agent/embed_into_web_pages.md@@ -11,16 +11,18 @@ sidebar_custom_props: {# Embed into Web Pages## Embed Agent Via Webpage-You can embed the Agent into third-party web pages using iframe.+Embed a **Workflow** Agent in a website as a fullscreen chat or floating widget.-Prerequisite: You must obtain an API Key.+Follow these steps to embed an Agent from a self-managed deployment. Obtain an API key under **User settings > API** before configuring the embed; see [Acquire a RAGFlow API key](../../develop/acquire_ragflow_api_key.md).Steps:1. On the Agent page, click the target Agent to open its editing page.-2. Click **Manage > Embed Webpage** in the upper right corner of the canvas to open the iframe window.+2. Click **Management > Embed into webpage** in the upper right corner of the canvas to open the embedding settings.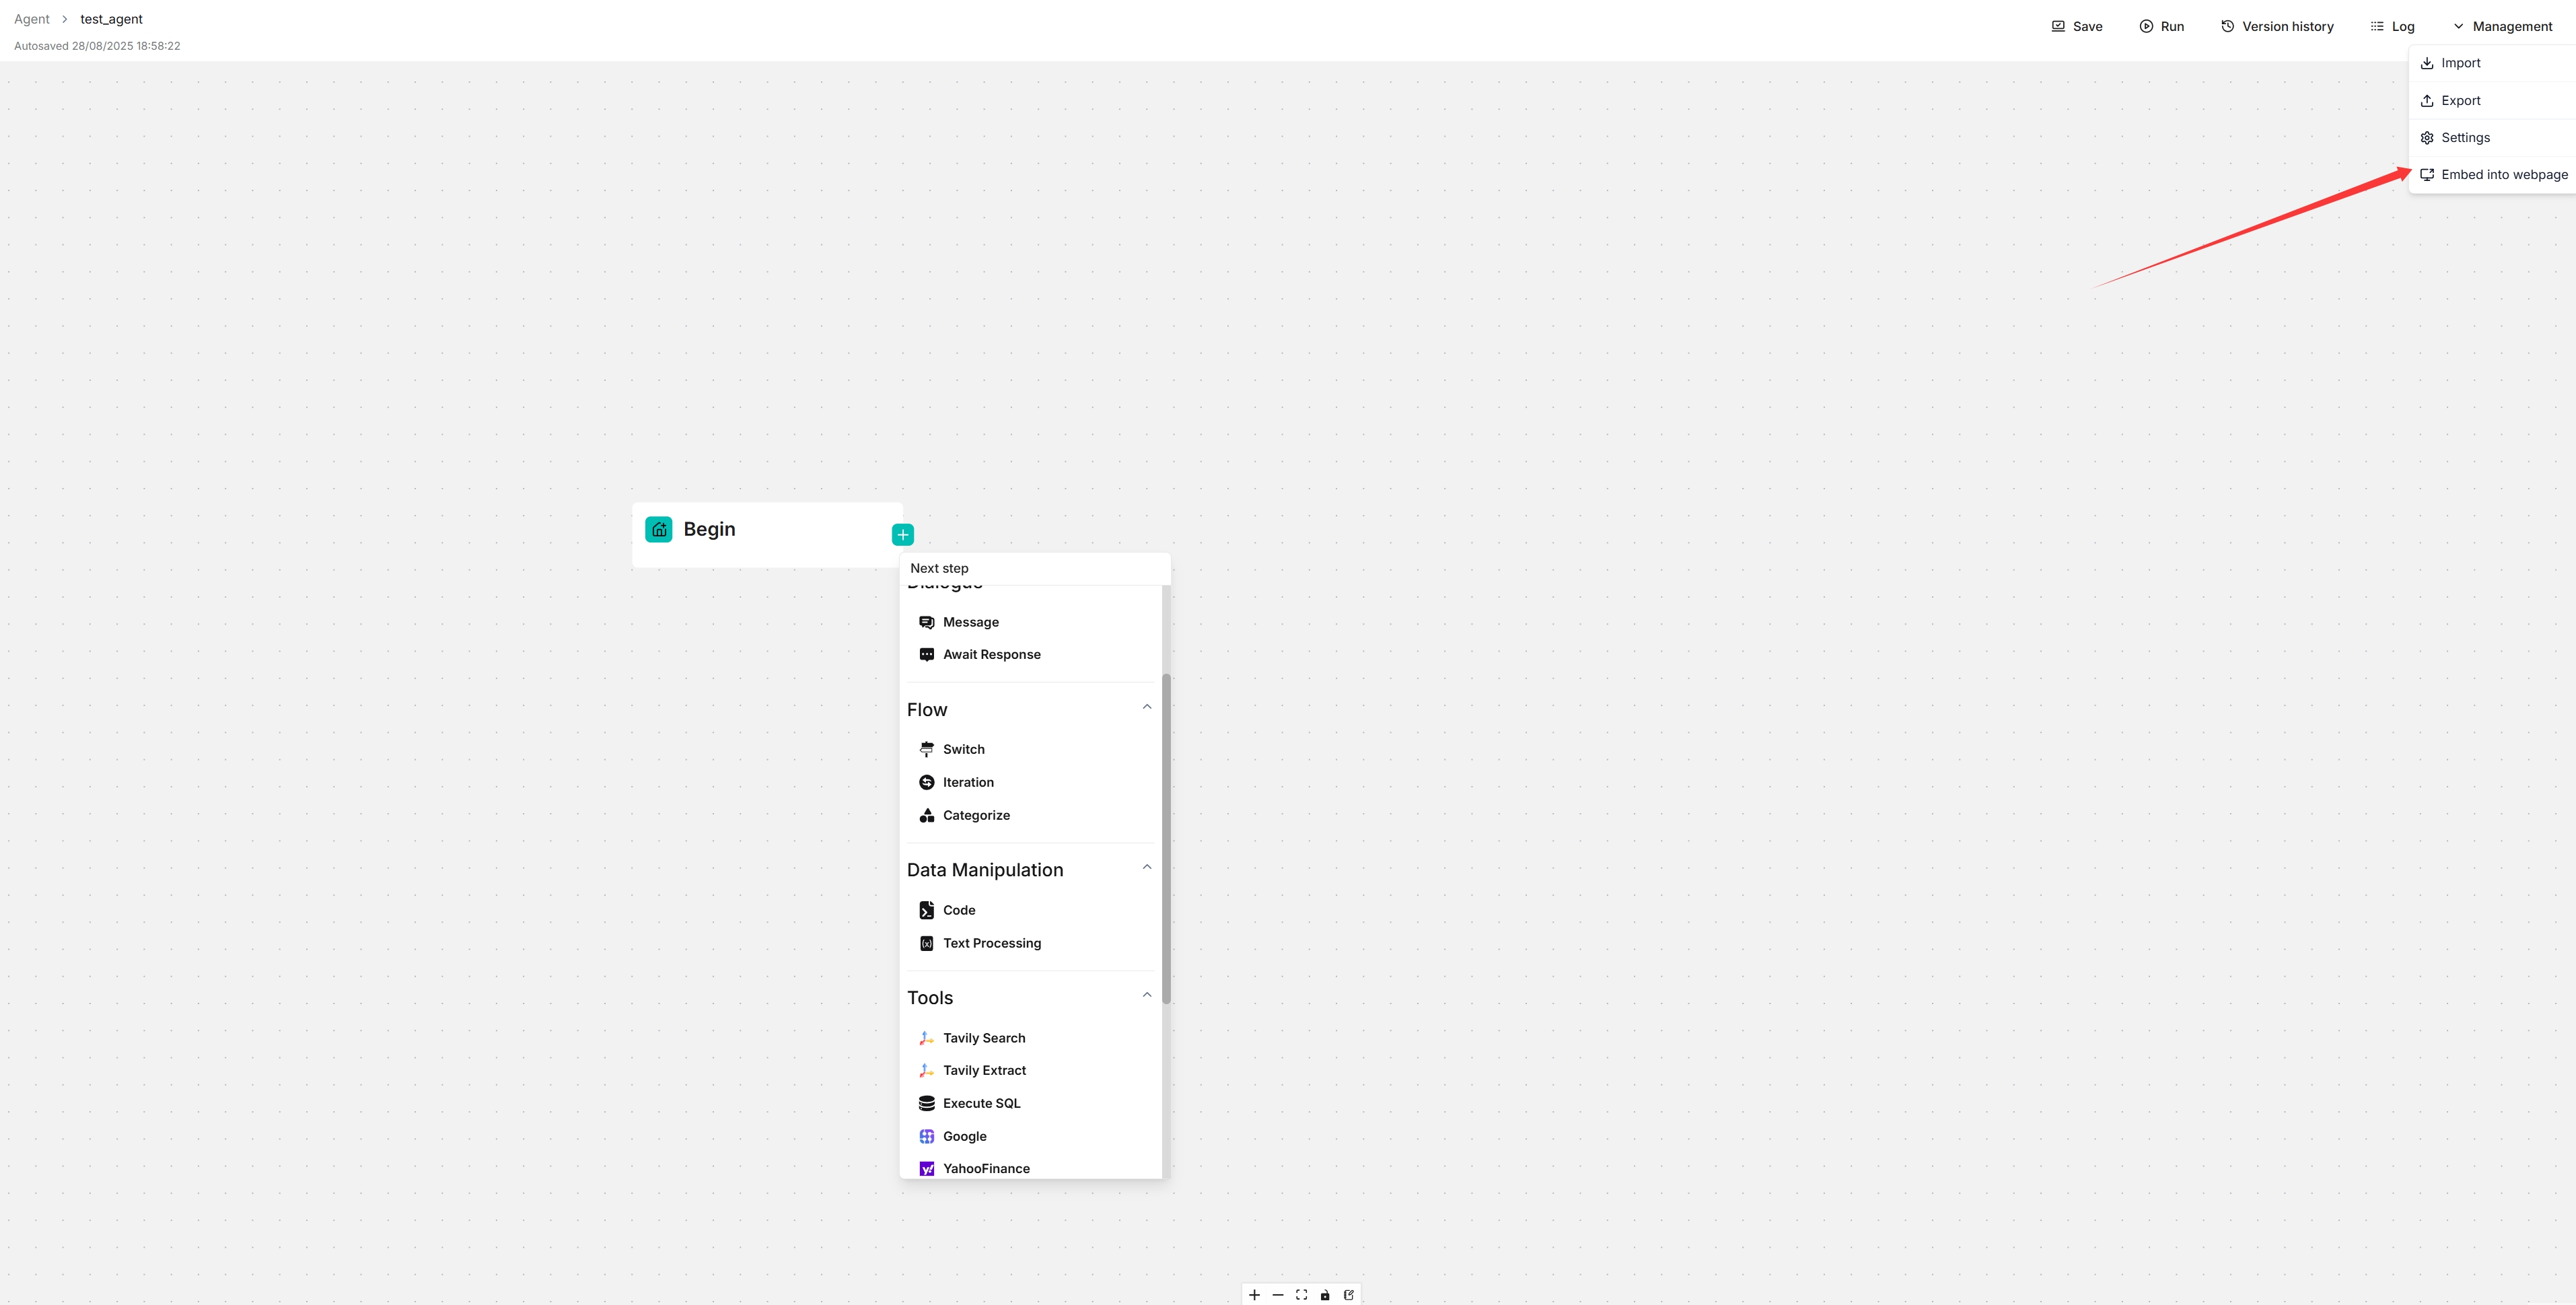-3. Copy the iframe code and embed it into your webpage.+3. In **Embed Setup**, choose **Fullscreen chat (traditional iframe)** or **Floating widget (Intercom-style)**.+4. Set **Language**, **User ID**, and display options as needed. Enable **Published** to use the published version of the Agent.+5. For a floating widget, use **Widget Customization** to adjust its title, text, and colors. Click **Save widget settings** to save the settings.+6. Copy **Embed code** into your webpage. Use **Open in new tab** to preview the result.-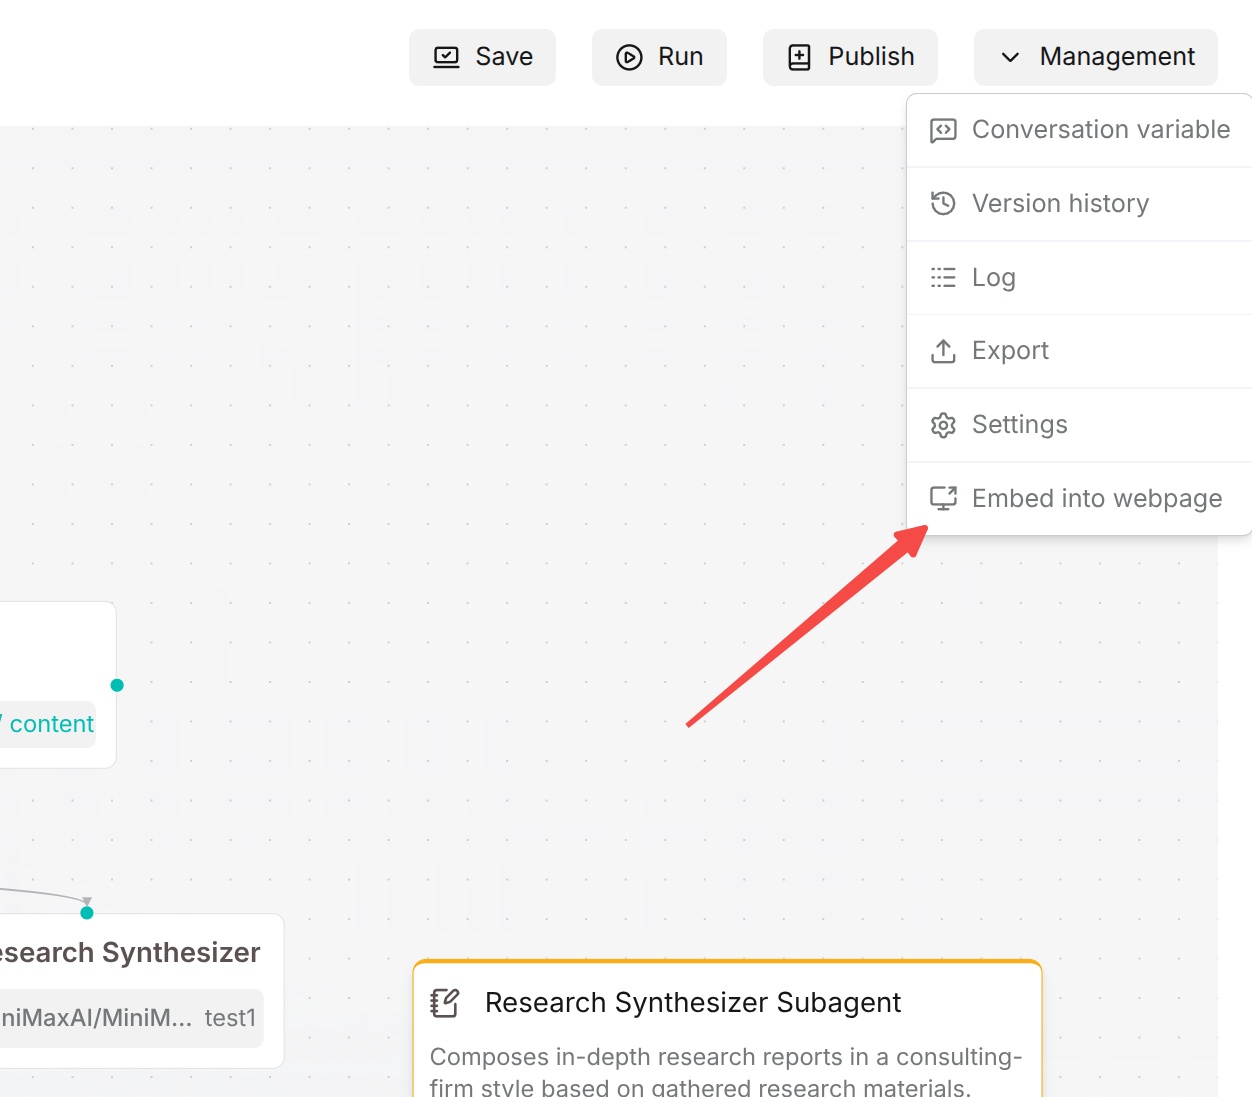-> **Note:** Currently, only **Workflow** agents can be embedded in web pages. **Ingestion pipeline** and **Compilation Operator** agents do not support web embedding.\ No newline at end of file+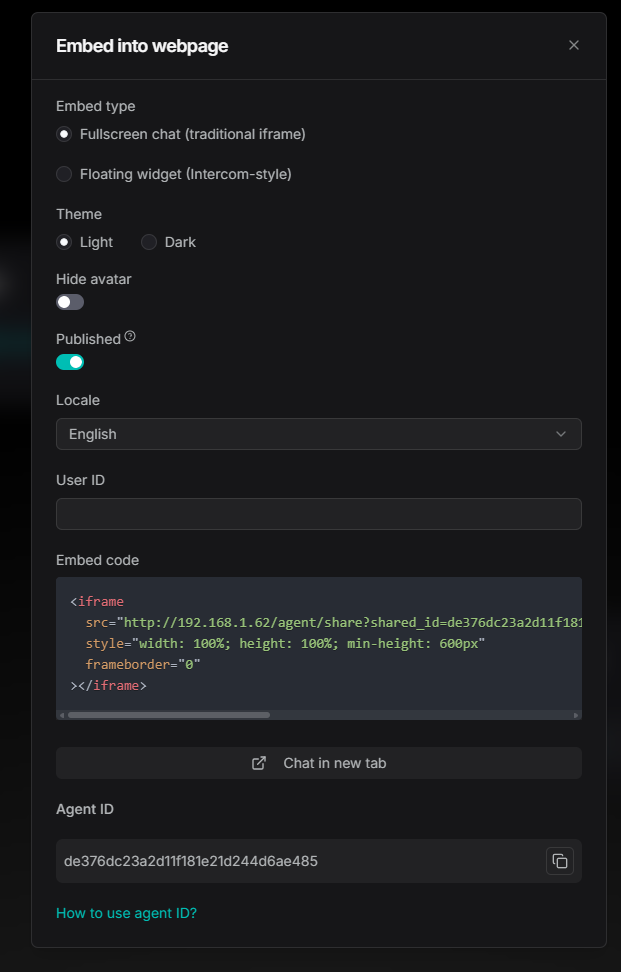diff --git a/docs/guides/agent/import_and_export_agents.md b/docs/guides/agent/import_and_export_agents.mdindex 45a088b0ef..eb674e8589 100644--- a/docs/guides/agent/import_and_export_agents.md+++ b/docs/guides/agent/import_and_export_agents.md@@ -11,15 +11,20 @@ sidebar_custom_props: {# Import and Export Agents## Import Agent-- First-time import: Upload the JSON file, fill in corresponding information, drag or click to upload the file, then save.-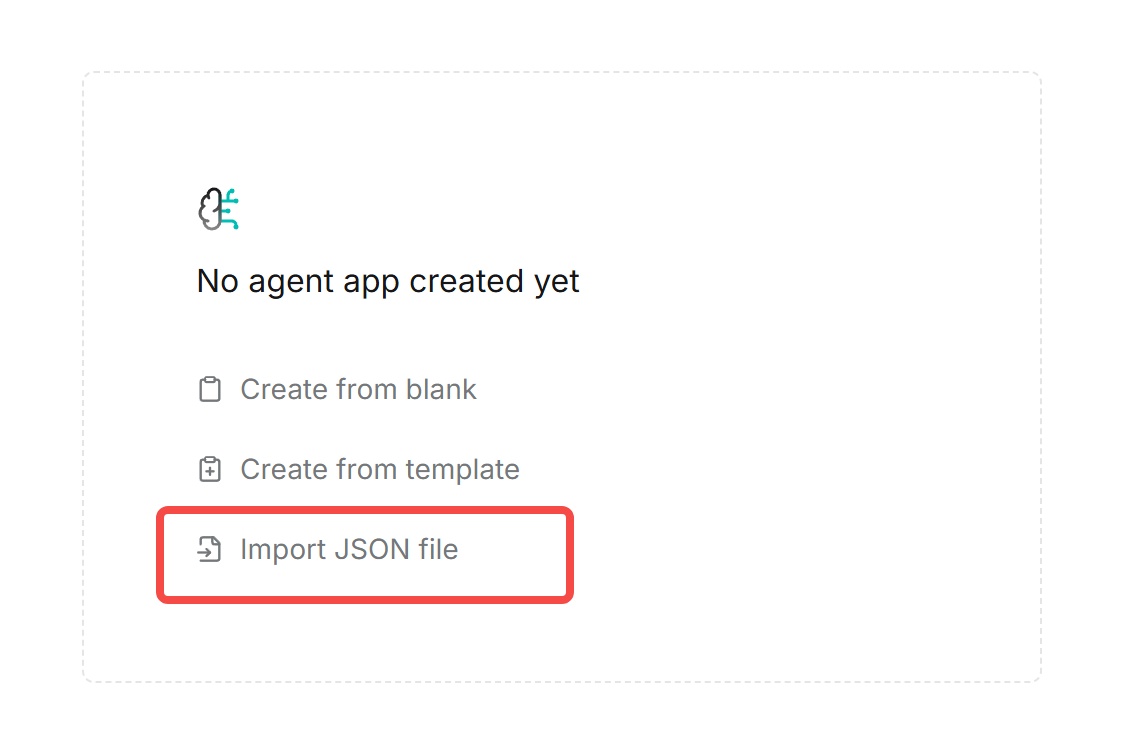-- Non-first-time import: Upload the JSON file, fill in corresponding information, drag or click to upload the file, then save.--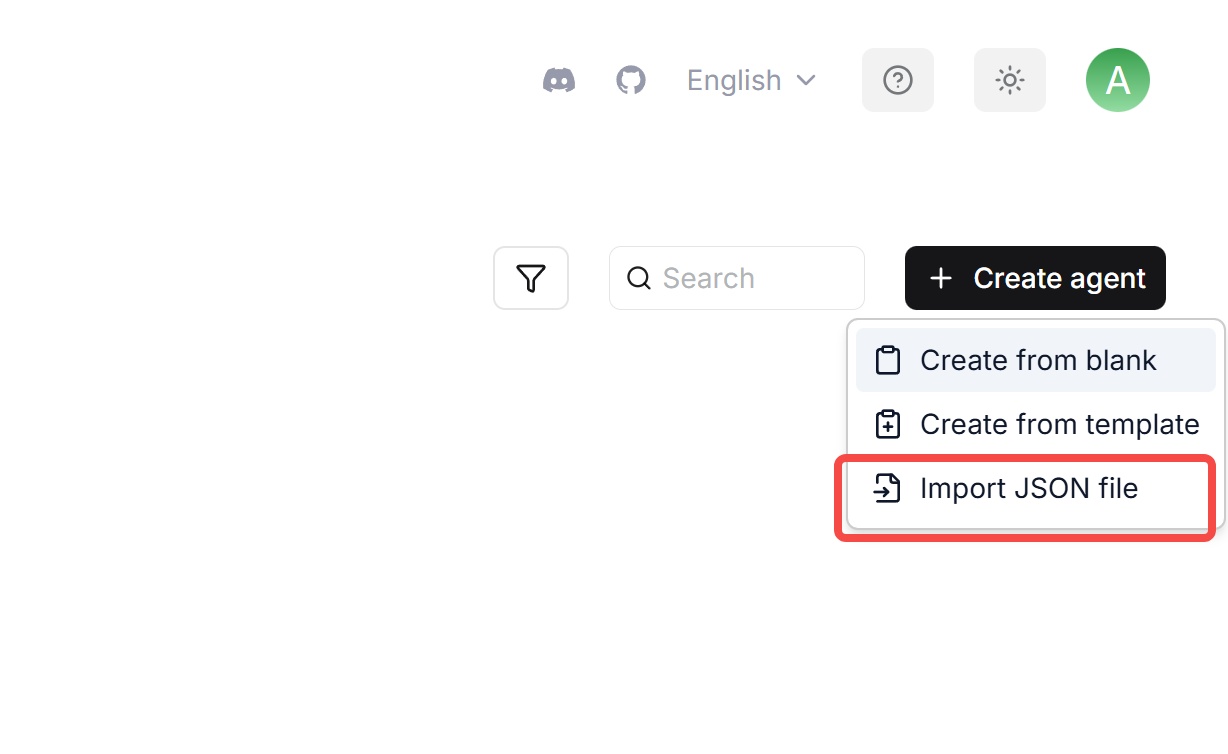+1. On the **Agent** page, open **Create agent > Import JSON file**. On an empty list, click **Import JSON file** directly.+2. Enter **Name** and upload one Agent JSON file under **DSL**.+3. Click **Save**, then open the imported Agent to check its configuration.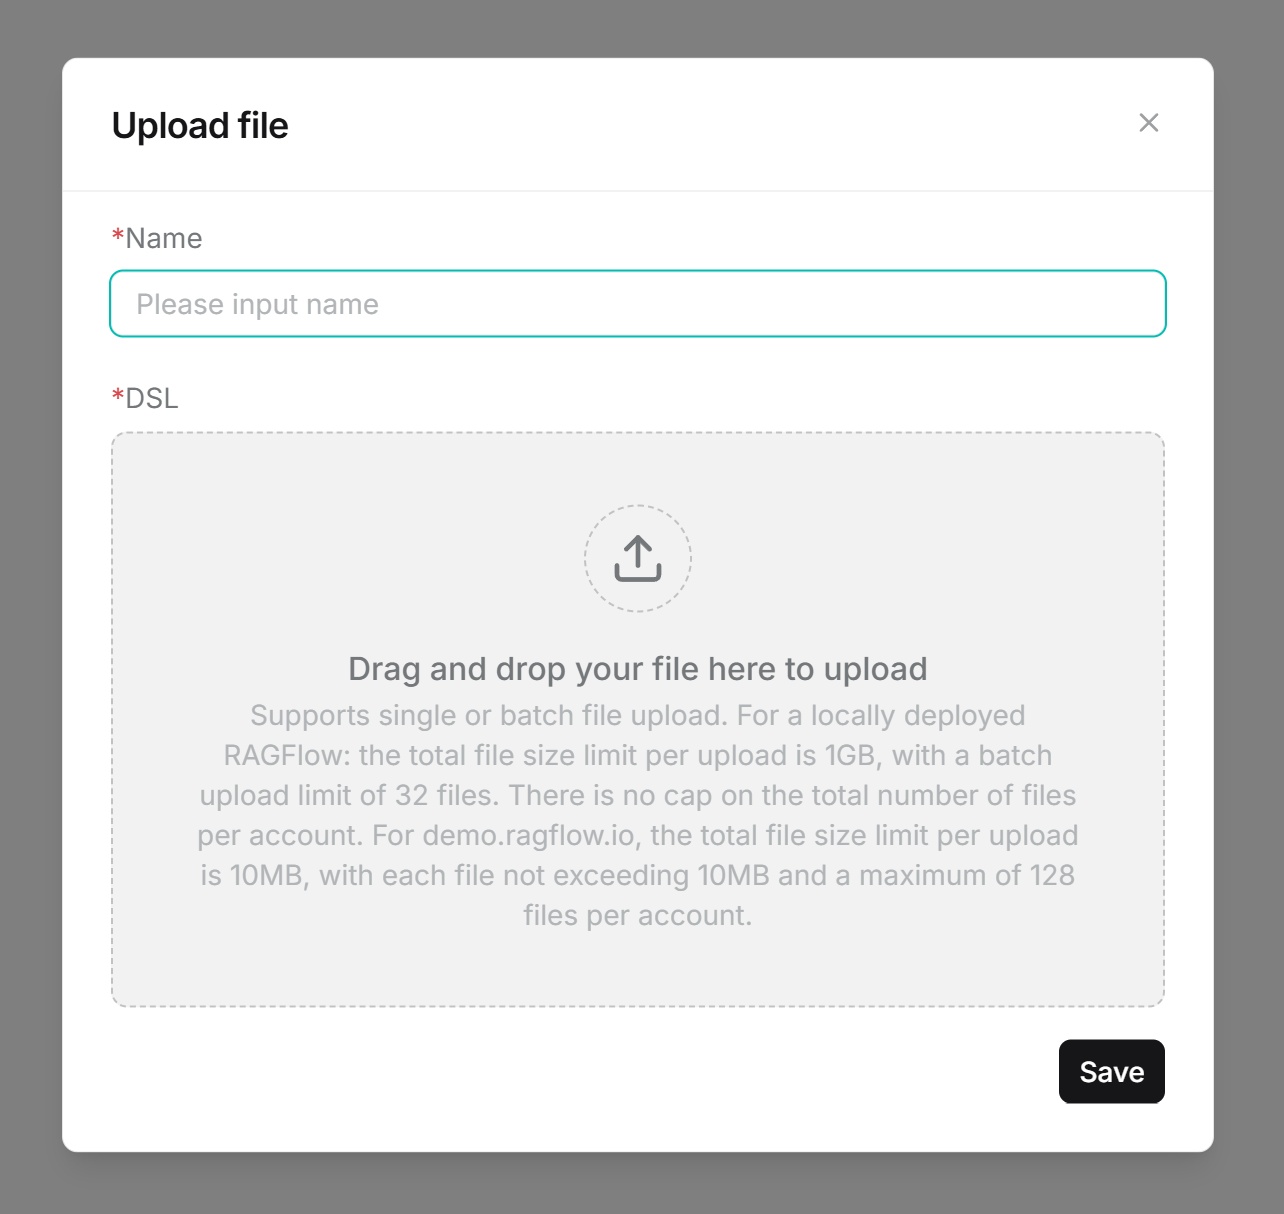+## Export Agent-Open an Agent, click **Manage** in the upper right corner, then click export.+Open an Agent, click **Management** in the upper right corner, then select **Export**.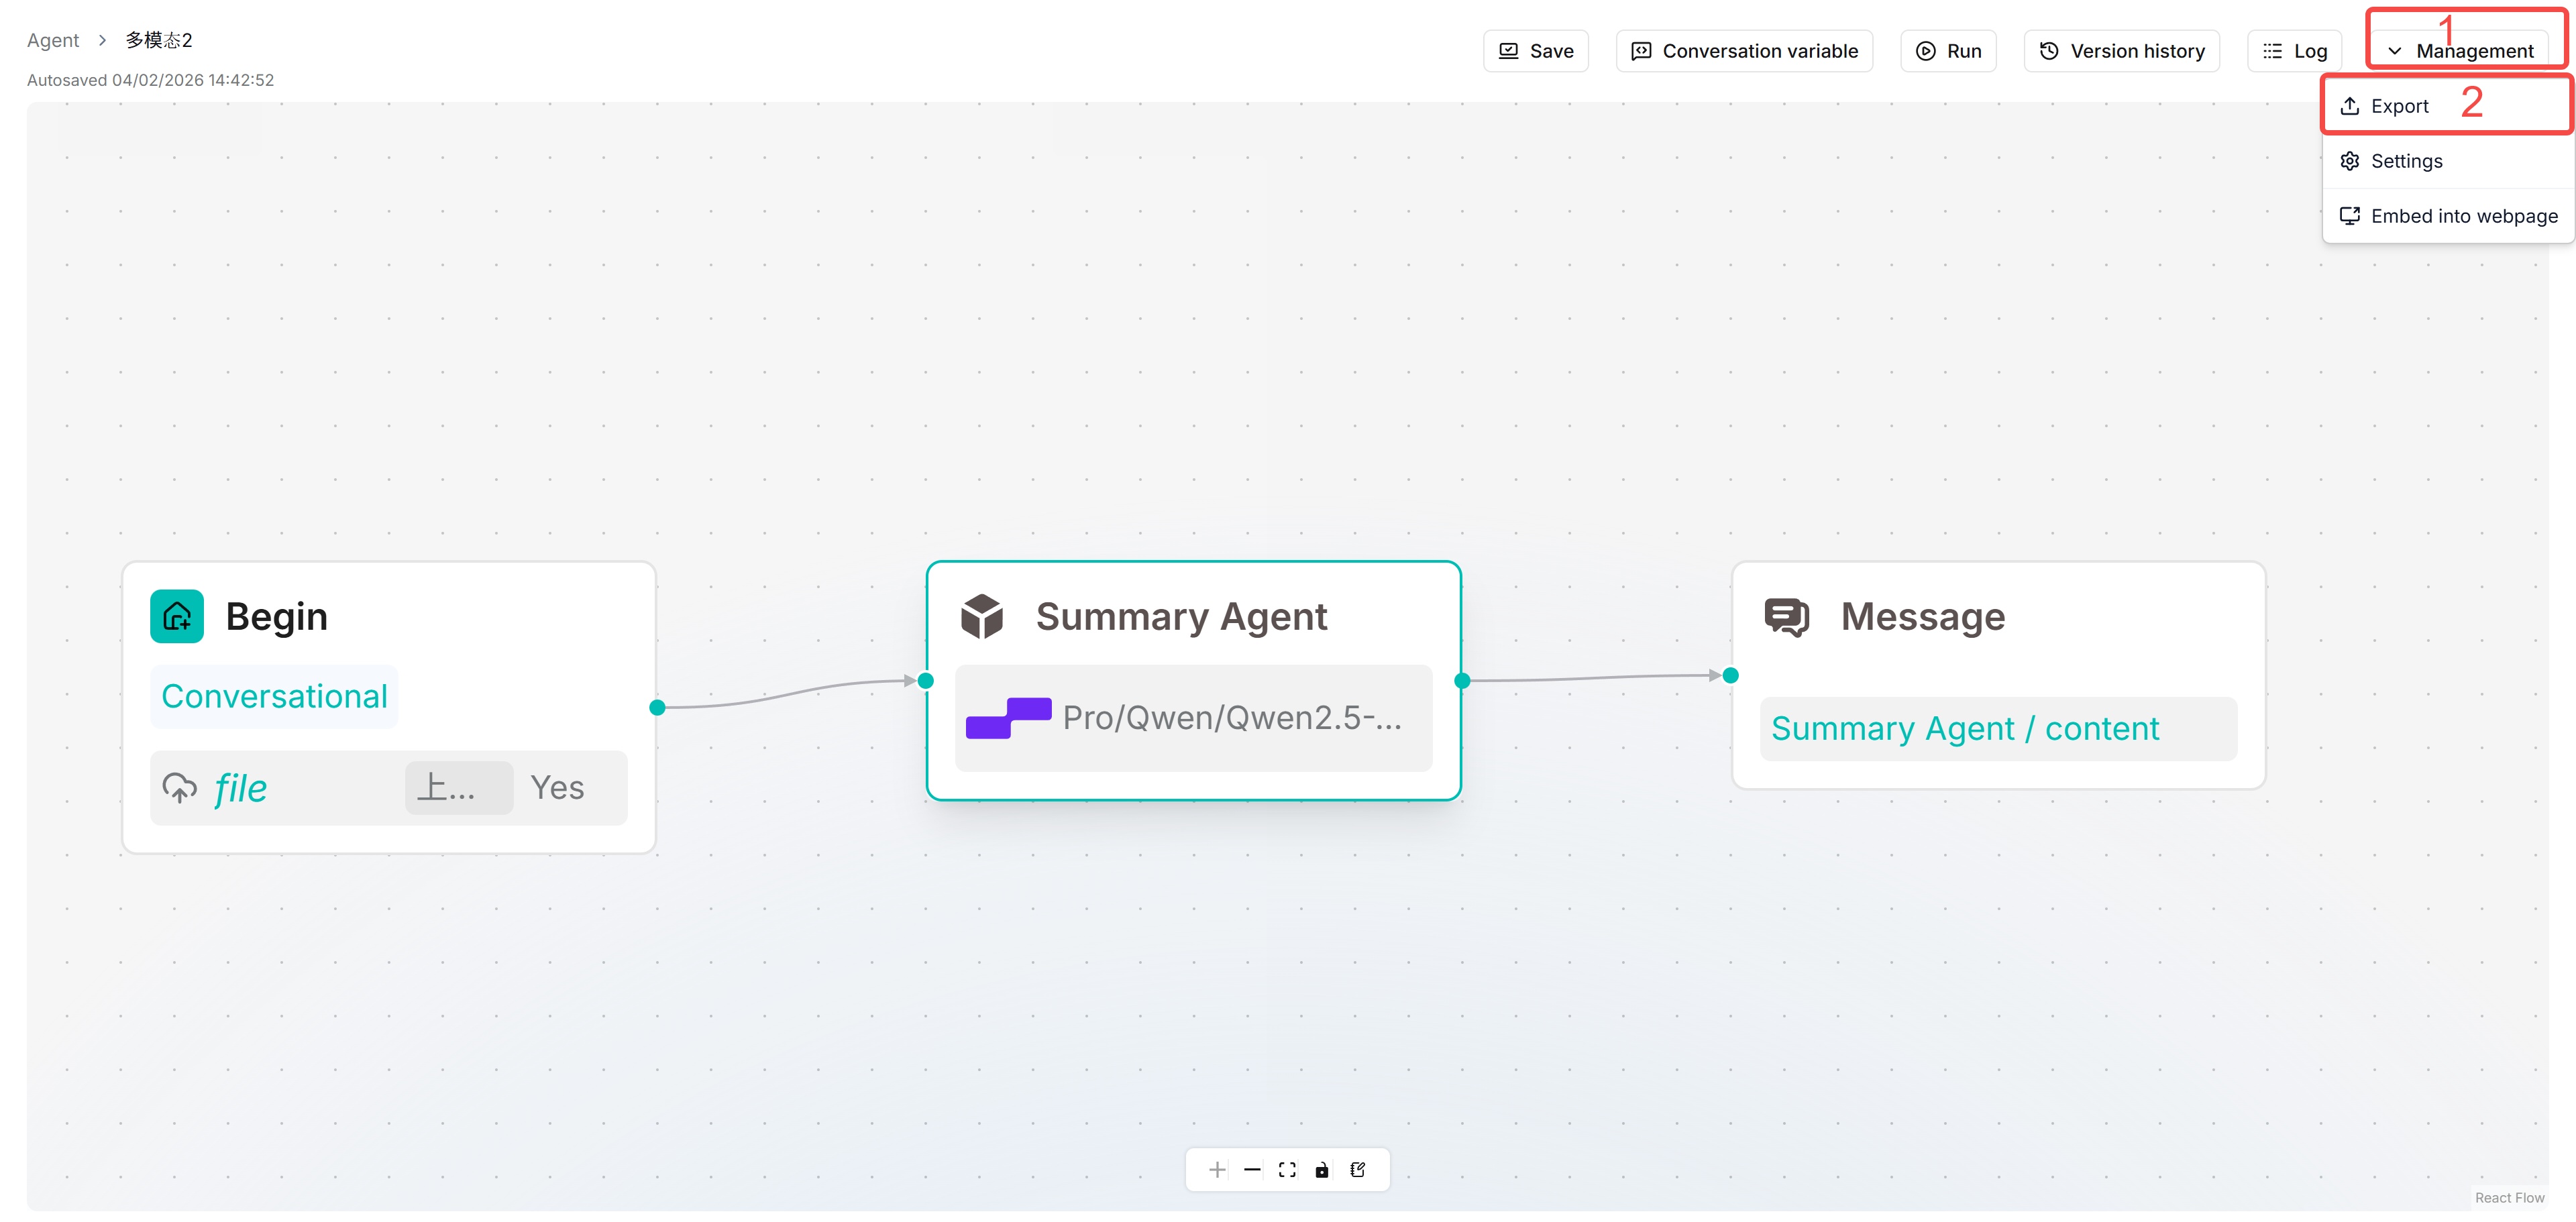++## Check imported dependencies++After importing, reselect models, datasets, memories, MCP servers, and compilation template groups that are available to the importing account. Importing a JSON configuration does not create or transfer those resources. Check **Checklist**, save, and validate the workflow or pipeline before use.++The exporter clears API keys for selected tool types. Re-enter the required keys after import. It does not guarantee that every password, token, header, or secret in a configuration has been removed; inspect the exported JSON before sharing it.diff --git a/docs/guides/agent/ingestion_pipeline/configure_chunker_component.md b/docs/guides/agent/ingestion_pipeline/configure_chunker_component.mdindex 4bcbb65895..8a4cc853e4 100644--- a/docs/guides/agent/ingestion_pipeline/configure_chunker_component.md+++ b/docs/guides/agent/ingestion_pipeline/configure_chunker_component.md@@ -10,22 +10,36 @@ sidebar_custom_props: {# Configure the Chunker Component-The Chunker component intelligently splits text. Its goal is to prevent overflow of the AI context window and improve semantic accuracy in hybrid search.+After **Parser**, choose **Token Chunker** or **Title Chunker** through the outgoing connection point. After Token Chunker, add **Transformer** or **Compiler** to enrich the chunks, or **Indexer** to index them.-There are two core methods, which can be used sequentially:+## Token Chunker-Token-based chunking (default):+Use token-based chunking for text without reliable section structure.-- **Chunk size**: Defaults to 512 tokens, balancing retrieval quality and model compatibility.-- **Overlap**: Set the overlap percentage to copy the end of one chunk to the beginning of the next chunk, improving semantic continuity.-- **Delimiter**: Uses `\n` (line break) by default to split first at natural paragraph boundaries and avoid cutting in the middle of sentences.+| Setting | Description |+| --- | --- |+| Delimiters / One | Choose delimiter-based splitting or keep the content as one chunk. |+| Recommended chunk size | Target chunk length in tokens. Defaults to `512` in Delimiters mode. |+| Overlapped percent (%) | Adds overlapping text between adjacent chunks. Defaults to `0`. |+| Image & table context window | Number of tokens taken before and after an image or table as context. Defaults to `0`; the slider ranges from `0` to `256`. |+| Delimiters | Defaults to `\n`, `!`, `?`, `;`, `。`, `;`, `!`, and `?`. Add or remove entries as needed. |+| Child chunk are used for retrieval | Splits parent chunks into smaller retrieval chunks using **Child delimiters**. Disabled by default. For line-based child chunks, enable it and add `\n`. |-Title-based chunking (hierarchical):+The output is `chunks`, an array of objects that downstream components can process.-- Best suited for structured documents such as manuals, papers and legal contracts.-- The system splits documents by chapter and section structure.-- Each chunk represents a complete structural unit.+## Title Chunker-:::caution IMPORTANT-In the current design, if both token-based and title-based methods are used, connect the **Token Chunker** component first, and then connect the **Title Chunker** component. Connecting the **Title Chunker** directly to the **Parser** may cause formatting errors for emails, images, spreadsheets and text files.-:::+Use Title Chunker for documents with clear headings, such as manuals and papers. Check that the resulting chunks keep each heading with its content.+++1. Choose **Hierarchy** to retain the heading path in each chunk, or **Group** to split at a selected heading level and group adjacent sections.+2. Select the heading level and configure the matching rules. Use **Add Rule** for another heading pattern and **Add regular expressions** for additional levels within a rule.+3. Set **Chunk token cap**. It defaults to `512`; the slider supports `128`–`8000`. Content exceeding the cap is split further at sentence boundaries.+4. In Hierarchy mode, adjust these options as needed:++| Setting | Description |+| --- | --- |+| Separate parent-heading content | Keeps content directly below a parent heading in a separate chunk. Disabled by default. |+| Set first chunk as global context | Uses the first section as shared context across the heading hierarchy. Disabled by default. |++For Markdown headings, add `^# ` for level 1 and `^## ` for level 2, then select level 2. In Hierarchy mode, check that each subsection retains its parent heading. Use the output `chunks` in downstream components.diff --git a/docs/guides/agent/ingestion_pipeline/configure_indexer_component.md b/docs/guides/agent/ingestion_pipeline/configure_indexer_component.mdindex 4062dd5cd9..c767408939 100644--- a/docs/guides/agent/ingestion_pipeline/configure_indexer_component.md+++ b/docs/guides/agent/ingestion_pipeline/configure_indexer_component.md@@ -10,32 +10,31 @@ sidebar_custom_props: {# Configure the Indexer Component-The **Indexer** component indexes data for optimal retrieval. It is the final step, writing processed data into the configured document engine.+**Indexer** prepares chunk data for full-text and embedding search. Connect it after the Chunker or Transformer and use the pipeline with a knowledge base to index documents.-Key configurations:+## Search method-Search method:+The panel displays the configured methods as labels:-- **Full-text**: Keyword search for exact matches, such as code and names.-- **Embedding**: Semantic search using vector similarity.-- **Hybrid** (recommended): Combines both methods for the best recall.+- **Embedding**: Vector representations for semantic search.+- **Full-text**: Tokenized text for keyword search.-Retrieval strategy:+Using both supports hybrid retrieval. **Hybrid** is not a separate option in this panel.-- **Processed text** (default): Indexes chunked text.-- **Questions**: Indexes generated questions. This usually produces higher similarity matches than text-to-text matching.-- **Enhanced context**: Indexes summaries instead of raw text. Suitable for broad topic matching.+## Filename embedding weight-Filename weight:+Controls the contribution of the document filename to chunk embeddings. Defaults to `0.1`; the UI slider ranges from `0` to `0.5`.-- A slider for including the document filename as semantic information in retrieval.+## Field-Embedding model:+Select the content to embed:-- Automatically uses the model set when creating the knowledge base.+- **Processed text** (default): Chunk text.+- **Questions**: Questions generated for the chunk.+- **Augmented context**: The generated summary.-:::caution IMPORTANT-To search across multiple knowledge bases at the same time, all selected knowledge bases must use the same embedding model.-:::+For Questions or Augmented context, first enable the corresponding function in Transformer. This setting selects embedding content; it does not replace the configured search methods.-+## Embedding model++The model comes from the connected knowledge base, rather than an independent model selector in this panel. Knowledge bases searched together must use the same embedding model.diff --git a/docs/guides/agent/ingestion_pipeline/configure_parser_component.md b/docs/guides/agent/ingestion_pipeline/configure_parser_component.mdindex 4958883b9d..87d23370a8 100644--- a/docs/guides/agent/ingestion_pipeline/configure_parser_component.md+++ b/docs/guides/agent/ingestion_pipeline/configure_parser_component.md@@ -12,129 +12,59 @@ sidebar_custom_props: {The **Parser** component converts your files into structured text while preserving layout, tables, headers and other formatting.-It supports 8 file categories and more than 23 formats, including PDF, images, audio, video, email, spreadsheets (Excel), Word, PPT, HTML and Markdown.--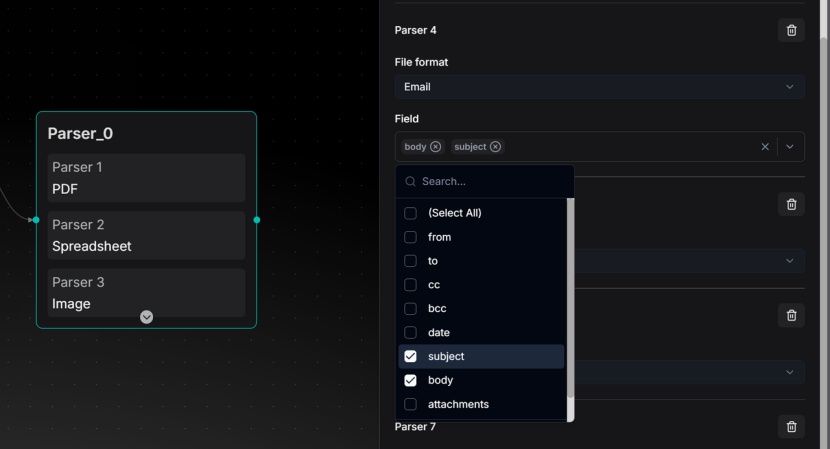+The initial configuration lists 12 file categories: **PDF**, **Spreadsheet**, **Image**, **Email**, **Markdown**, **Text & Code**, **HTML**, **DOC**, **DOCX**, **PPTX**, **Video**, and **Audio**. Configure the options for each required category.Key configurations:For PDF files, select one of the following:-- **DeepDoc** (default): RAGFlow's built-in model. Best suited for scanned documents or complex layouts with tables.-- **MinerU**: Industry-leading for complex elements such as mathematical formulas and complex layouts.+- **DeepDoc** (default): RAGFlow's built-in model. Use for scanned documents or complex layouts with tables.+- **MinerU**: Parses mathematical formulas, tables, and complex page layouts.- **Naive**: Simple text extraction. Use it for clean, text-based PDFs without complex elements.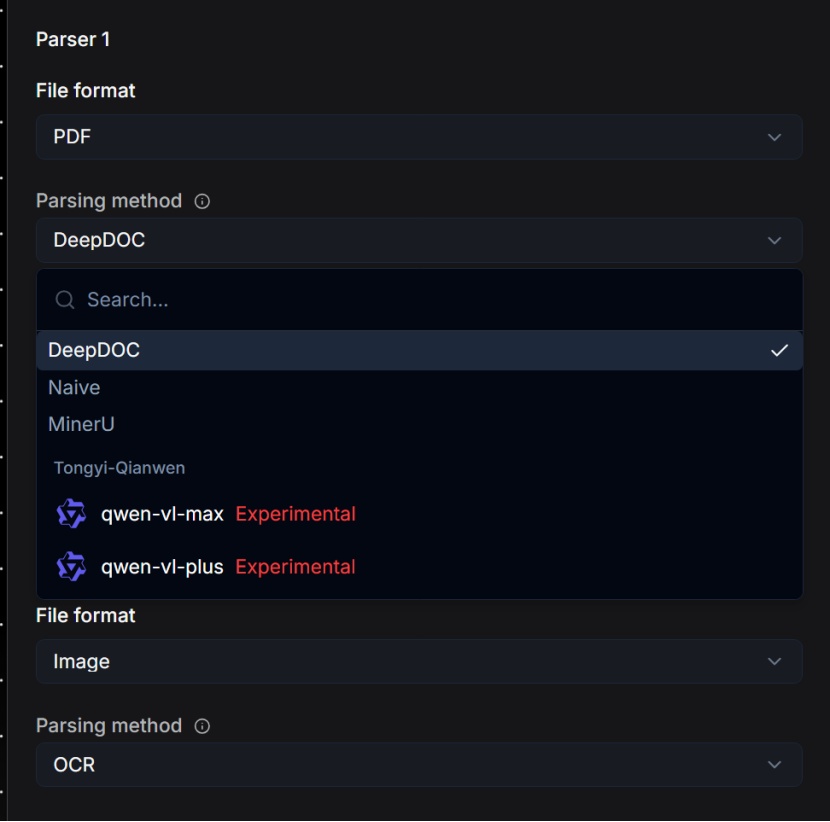### MinerU formula and table controls-When a MinerU model is selected for PDF, **Formula recognition** and **Table-recognition** are saved on that Parser component's PDF setup as-`mineru_formula_enable` and `mineru_table_enable`. Both default to enabled when-omitted; an explicit `false` requests disabling the corresponding control,-subject to the API and backend capabilities below.--- **`/file_parse`, pipeline and VLM backends:** RAGFlow forwards both controls- as the `formula_enable` and `table_enable` multipart fields.-- **`/file_parse`, hybrid backends:** Table recognition follows the table- control. The formula control applies to **inline formulas only**; MinerU- still recognizes block formulas.-- **V1 upload/job API:** This protocol has no formula/table switches. Omitted- or enabled controls keep the existing job request. Disabling either control- fails with an explicit error before a file is uploaded or a job is created;- use a `/file_parse` server when these controls are required.--For example, the component-scoped PDF configuration below disables formulas-while retaining table recognition:--```json-{- "pdf": {- "parse_method": "<tenant MinerU model ID>",- "mineru_formula_enable": false,- "mineru_table_enable": true- }-}-```--### Tenant SoMark and OpenDataLoader models--The Go Parser can use an enrolled **SoMark** or **OpenDataLoader** OCR model-by tenant-model ID or by `model@instance@provider` reference, for example:--```json-{- "pdf": {- "parse_method": "SoMark-model@production@SoMark"- }-}-```+When using MinerU for PDF, **Formula recognition** and **Table recognition** are enabled by default. Turn off the corresponding option when it is not needed.-`layout_recognizer` also accepts a reference. Selection follows the existing PDF-model rule: a model reference in `parse_method` takes precedence; otherwise the-reference in `layout_recognizer` is used.+Available controls depend on the connected MinerU service. Some services continue to recognize block formulas even when formula recognition is disabled. If parsing reports that an option is unsupported, ask an administrator to check the service configuration.-The selected model and instance must be active, OCR-capable and owned by the-current tenant/provider. The Parser resolves the instance endpoint and key on-each execution, so credential changes apply without resaving the pipeline.-SoMark supports ordinary instance key/base-URL storage; OpenDataLoader also-supports its provider-card JSON configuration, including nested `api_key` maps.+### SoMark and OpenDataLoader models-For an explicit reference, a missing endpoint, inaccessible/disabled model or-invalid instance configuration is an error. The Parser never substitutes another-instance, a global environment credential or a generic VLM. An empty optional-key remains empty. Transport SSRF protections still apply.+To use **SoMark** or **OpenDataLoader**, first add and enable the OCR model in model settings, then select it in the PDF parser options. The selected model must be available to your account.-SoMark's non-secret per-model format/feature settings supply defaults; explicit-pipeline options override them. An explicit `false` is retained. Resolved-credentials stay on the per-run parser object, not in saved pipeline settings.--Bare engine names (`somark`, `opendataloader`) continue to use their existing-parser-specific setup/environment configuration.+If the model is unavailable or its connection settings are incomplete, parsing fails rather than switching to a different model. Check model access and ask an administrator to verify the connection.### Other file typesFor image files:-- **OCR** is on by default. **OCR model** starts with **DeepDoc** for local- OCR. Select an added **PaddleOCR** or **PaddleOCR.local** model to use- that tenant model's instance instead; select **DeepDoc** again to return to- local OCR.-- If the model list cannot be loaded, the field displays an error and preserves- the saved selection. A successful empty list is shown separately; **DeepDoc**- remains available in either case.-- Turning **OCR** off skips both local and selected-model OCR without clearing- the saved selection. **Enable vision enhancement** independently controls VLM- descriptions: selecting an OCR model never enables vision enhancement.-- SVG files have their document text read directly; they are not submitted to- PaddleOCR or a VLM.-- Image attachments and extracted text continue through the picture pipeline's- OneChunker and Tokenizer. An unavailable, disabled, inaccessible, or failing- selected model is reported in Parser warnings, without falling back to another- OCR instance. An image with no OCR text or vision description has no searchable- text and is discarded by the Tokenizer.--For Go Parser configuration, the image family stores `ocr_enabled` and optional-`ocr_model_id` (an enrolled tenant model ID, not a provider name). An omitted or-empty `ocr_model_id` keeps local OCR. The selected model must be an active OCR-model on an active PaddleOCR instance belonging to the pipeline's tenant.-Self-hosted instances need a configured base URL. A cloud instance without one-uses the public catalog endpoint and logs a warning with tenant, model and-instance IDs, not credentials. Server-wide endpoint environment variables do not-replace an explicitly selected instance.+- **OCR** is enabled by default. To turn it off, first enable **Enable vision enhancement**. Keep at least one of these options enabled so that images can produce searchable text.+- **OCR model** selects local DeepDOC or an available configured PaddleOCR model. The model must be available to the canvas owner.+- **Enable vision enhancement** separately controls image descriptions. Enabling OCR does not enable vision enhancement.+- SVG text is read directly.+- Check parsing warnings if text recognition fails. A configuration with both OCR and vision enhancement disabled is rejected.For email files:- Select specific fields to parse, such as `subject` and `body`, for precise extraction.++For spreadsheets:-- Output in HTML format, preserving row and column structure.+- Preserves table content and row/column structure in the parsed items.For Word/PPT:-- Output in JSON format, preserving document hierarchy, such as headings, paragraphs and slides.+- Preserves document structure, such as headings, paragraphs, and slides, in the parsed items.For text and markup (HTML/MD):-- Formatting tags are automatically removed and clean text is output.+- Extracts document content as structured items for downstream chunking.+++### Output++Select the `json` output to use the parsed content. It contains structured items such as paragraphs and tables. Connect **Token Chunker** or **Title Chunker** after Parser to split this content into `chunks` for Transformer, Compiler, or Indexer.diff --git a/docs/guides/agent/ingestion_pipeline/configure_transformer_component.md b/docs/guides/agent/ingestion_pipeline/configure_transformer_component.mdindex 18479d793e..6569d1f974 100644--- a/docs/guides/agent/ingestion_pipeline/configure_transformer_component.md+++ b/docs/guides/agent/ingestion_pipeline/configure_transformer_component.md@@ -10,43 +10,29 @@ sidebar_custom_props: {# Configure the Transformer Component-The **Transformer** component is designed to bridge the "semantic gap". In general, it uses AI models to add semantic metadata, making your content easier to discover during retrieval.+**Transformer** uses a chat model to generate summaries, keywords, questions, tags, or metadata for document chunks. These additions provide more ways to find relevant content during retrieval.-It has four generation types:+Enable one or more of the following options:- **Summary**: Creates a concise overview.-- **Keywords**: Extracts key terms.-- **Questions**: Generates questions that each text chunk can answer.+- **Auto keywords**: Extracts key terms.+- **Auto-question**: Generates questions that each text chunk can answer.+- **Tags**: Assigns relevant tags from the selected **Tag file**. Set the maximum number of tags to extract.- **Metadata**: Custom metadata extraction.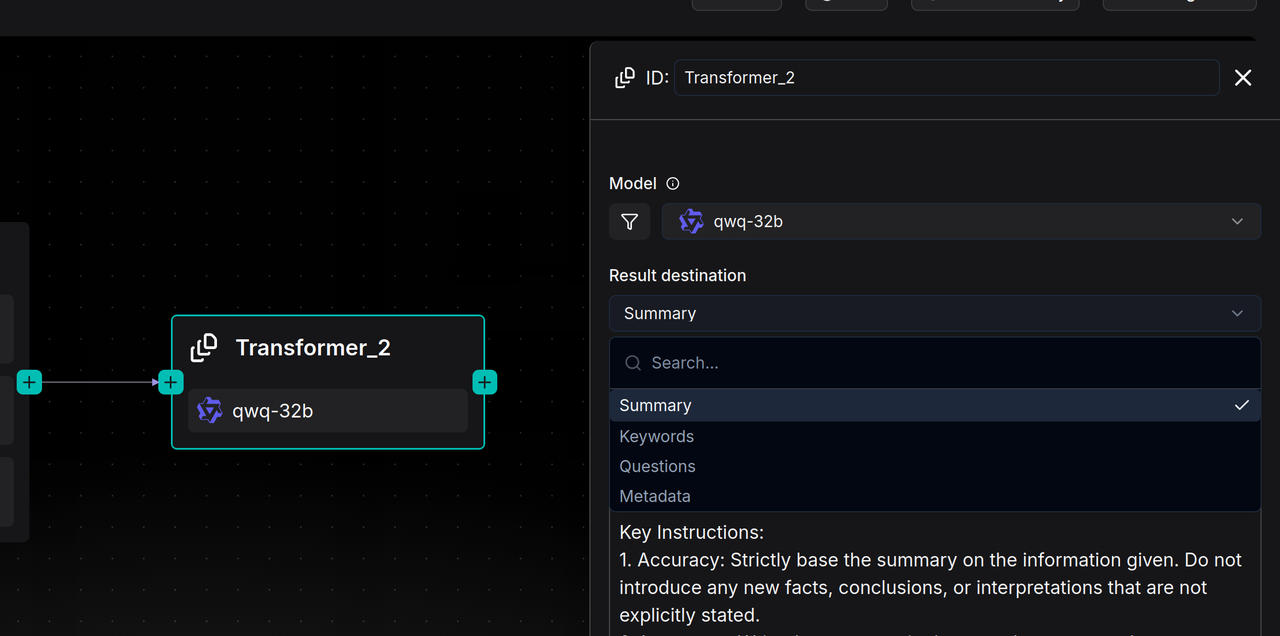-If you have multiple **Transformer** components, make sure to separate the **Transformer** component for each function, for example, one for summaries and another for keywords.+A single **Transformer** can enable multiple options; a separate component is not required for each function.Key configurations:-Model mode (select one):--- **Improvise**: More creative, suitable for question generation.-- **Precise**: Strictly faithful to the text, suitable for summary and keyword extraction.-- **Balanced**: A middle ground suitable for most scenarios.--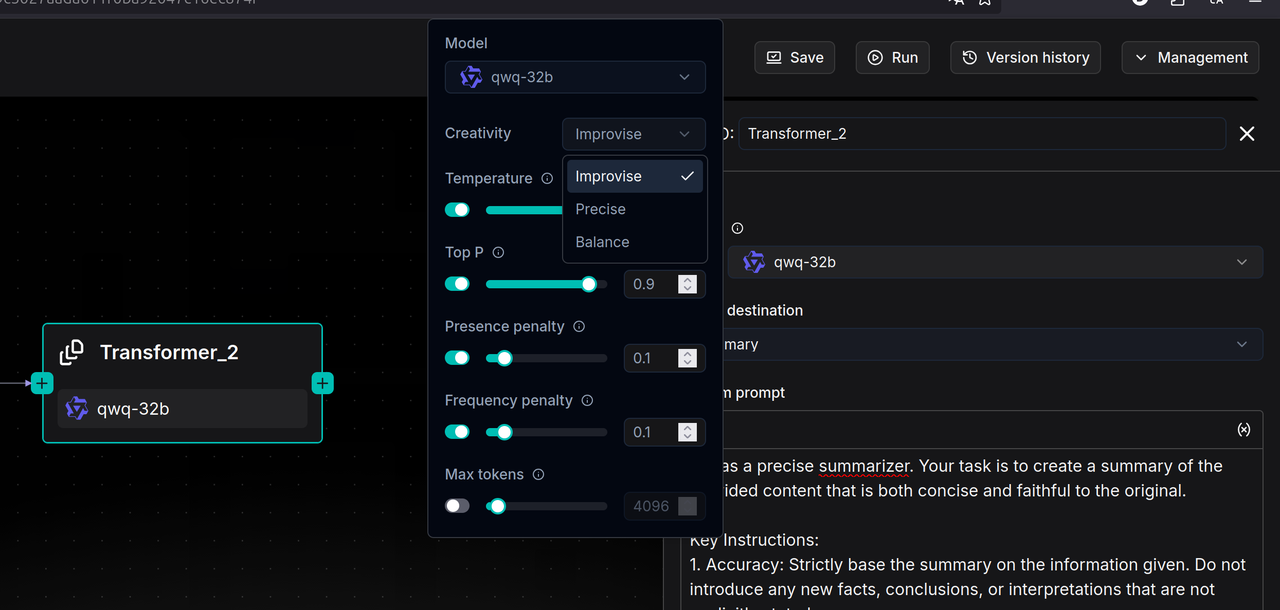+**Model**: Select a configured chat model.Prompt engineering:-- The system prompt for each generation type is open and customizable.--Connection:--- The **Transformer** can be connected after the **Parser** to process the entire document, or after the **Chunker** to process each chunk.--Variable reference:--- Nodes do not automatically obtain content. In the user prompt, manually reference upstream variables by typing `/` and selecting a specific output, such as `/{Parser.output}` or `/{Chunker.output}`.--Chained connection:+- Customize **System prompt** where the selected option provides it.-- When chaining **Transformer** components, if variables are referenced correctly, the second **Transformer** component processes the output of the first one, for example, generating keywords from a summary.+Connection and input:-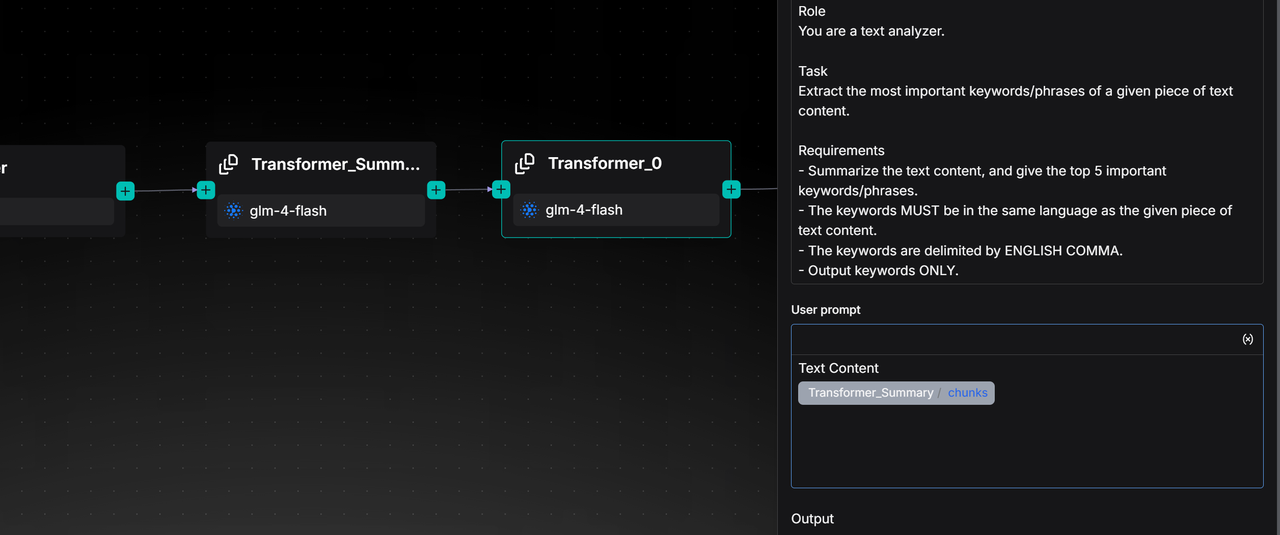+- Connect **Transformer** to an upstream node that provides document chunks. It enriches those chunks with the enabled extraction results.+- After **Transformer**, add **Indexer** for indexing or **Compiler** for knowledge compilation. Generated summaries are stored alongside the original chunk text.diff --git a/docs/guides/agent/ingestion_pipeline/create_ingestion_pipeline.md b/docs/guides/agent/ingestion_pipeline/create_ingestion_pipeline.mdindex e84c4f83bd..dbecb8c14b 100644--- a/docs/guides/agent/ingestion_pipeline/create_ingestion_pipeline.md+++ b/docs/guides/agent/ingestion_pipeline/create_ingestion_pipeline.md@@ -10,8 +10,13 @@ sidebar_custom_props: {# Create an Ingestion Pipeline-1. Go to the **Agent** page.-2. Click **Create Agent** and start from a blank canvas or a prebuilt template. Templates are recommended for beginners.+1. Open **Agent > Create agent > Create from blank**.+2. Select **Ingestion pipeline**, enter a name, and click **Confirm**.+3. Open the created card. The canvas starts with **Begin → Parser**.+4. Configure Parser, then use its outgoing connection point to add **Token Chunker** or **Title Chunker**.+5. From Token Chunker, add **Transformer** if enrichment is needed, then add **Indexer**. A basic flow is **Begin → Parser → Token Chunker → Transformer → Indexer**.+6. Configure each component, review **Checklist**, and click **Save**.--3. On the canvas, drag, drop and connect components from the right panel to design your flow, for example: Parser → Chunker → Transformer → Indexer.+Use each component's outgoing connection point to add the next step. After Transformer, choose Indexer or Compiler.++See [Validate the pipeline](./test_run.md) before processing a collection of documents.diff --git a/docs/guides/agent/ingestion_pipeline/test_run.md b/docs/guides/agent/ingestion_pipeline/test_run.mdindex 54d761be6a..0e184fa540 100644--- a/docs/guides/agent/ingestion_pipeline/test_run.md+++ b/docs/guides/agent/ingestion_pipeline/test_run.md@@ -1,15 +1,20 @@---sidebar_position: 7-title: Test Run-sidebar_label: Test Run+title: Validate the Pipeline+sidebar_label: Validate the Pipelineslug: /test_runsidebar_custom_props: {categoryIcon: RagAiAgent}----# Test Run+# Validate the Pipeline-On the pipeline canvas, click **Run** to upload a sample file and view step-by-step results.+Save the pipeline, then parse a sample document in a connected knowledge base to check the results.-+1. Review **Checklist**, resolve configuration issues, and click **Save**.+2. [Connect the pipeline to a knowledge base](./connect_the_pipeline_to_a_knowledge_base.md). Use a dedicated test knowledge base to avoid affecting existing documents.+3. Upload a small sample file and start parsing from the knowledge base's document controls.+4. Check the document's parsing status and resulting chunks. Confirm that content, chunk boundaries, and enabled enrichment results meet your needs before processing more files.++If parsing fails, use the reported error to check the parser, model access, and component settings.diff --git a/docs/guides/agent/ingestion_pipeline/understand_core_ingestion_pipeline_components.md b/docs/guides/agent/ingestion_pipeline/understand_core_ingestion_pipeline_components.mdindex eef4effcdb..aeda637426 100644--- a/docs/guides/agent/ingestion_pipeline/understand_core_ingestion_pipeline_components.md+++ b/docs/guides/agent/ingestion_pipeline/understand_core_ingestion_pipeline_components.md@@ -13,6 +13,17 @@ sidebar_custom_props: {The Ingestion Pipeline is composed of the following core components:- **Parser component**: Reads and understands your files, such as PDFs, images, emails and other file types, and extracts text and structure.-- **Transformer component**: Enhances text by using AI to add summaries, keywords or questions, improving search.-- **Chunker component**: Splits long text into optimally sized fragments, or chunks, to improve AI retrieval.+- **Transformer component**: Enriches chunks with summaries, keywords, questions, tags, or metadata. Multiple functions can be enabled in one node.+- **Chunker component**: Splits long text into smaller sections, or chunks, for retrieval.+- **Compiler component**: Organizes chunks into a knowledge tree, mind map, or wiki using a compilation template group and model.- **Indexer component**: The final step. Sends the processed data to the document engine, supporting hybrid full-text and vector search.++A typical flow is **Begin → Parser → Token Chunker → Transformer → Indexer**. Transformer is optional. The outgoing connection menu also provides **Compiler** after Token Chunker or Transformer for knowledge compilation.++## Configure the Compiler Component++1. Prepare a template group through **Agent > Create agent > Create from blank > Compilation operator**. See [template configuration](../../knowledge_compilation/basic_information_configuration.md). Then add **Compiler** after Token Chunker, Title Chunker, or Transformer; one Compiler is allowed per canvas.+2. Select an accessible **Compilation template group** and chat model. Choose templates for the result you need, such as a knowledge tree or wiki. **Compilation operator** configurations use the same settings.+3. Connect **Compiler → Indexer** to index the original and generated chunks. Save and [validate the pipeline](./test_run.md) with a sample document.++Example: **Begin → Parser → Token Chunker → Compiler → Indexer**. After parsing, check the generated content and retrieval results. If the template group or model is unavailable after import, select an accessible one.diff --git a/docs/guides/agent/quickstarts/build_customer_support_agent.md b/docs/guides/agent/quickstarts/build_customer_support_agent.mdnew file mode 100644index 0000000000..83fa20de43--- /dev/null+++ b/docs/guides/agent/quickstarts/build_customer_support_agent.md@@ -0,0 +1,55 @@+---+sidebar_position: 7+title: Build a Customer Support Agent+slug: /build_customer_support_agent+---++# Build a Customer Support Agent++Build a workflow that answers product questions through retrieval and collects customer details for an installation visit.++## Prepare++- Configure a chat model.+- Create a knowledge base containing a short product guide, and finish parsing it. For a repeatable test, include: “Model A supports Wi-Fi. To reset it, hold the reset button for five seconds.”++## Build the workflow++1. [Create a blank Workflow Agent](../creation_and_management.md#create-from-blank-agent) named `Customer support demo`.+2. After **Begin**, add **Categorize**. Use `sys.query` as the query variable and select the chat model.+3. Add two categories:++| Name | Description | Example |+| --- | --- | --- |+| Product help | Product features, setup, and troubleshooting. | How do I reset Model A? |+| Appointment | Requests to arrange a service appointment. | I want to arrange an installation. |++### Product help branch++1. Connect **Product help → Retrieval → Agent → Message**.+2. In Retrieval, select the product knowledge base and use `sys.query` as the query.+3. In Agent, select the chat model and use this **System prompt**:++```text+Answer product questions using the provided product guide.+If the guide does not contain the answer, say so and ask for clarification.+```++4. In **User prompt**, enter `Question: ` and insert `sys.query`. On a new line, enter `Product guide: ` and insert Retrieval's `formalized_content`. Open the variable selector with `/` and select the components on your canvas. Names in this example are illustrative; do not type them as variable references.+5. In Message, insert the Agent's `content` output.++### Appointment branch++Connect **Appointment → Await Response → Message**. Follow the [form example](../agent_workflow/dialogue_component.md#example-collect-appointment-details) to collect the customer's name and preferred installation time, then display them in Message. This branch collects installation preferences; it does not book a service visit.++## Test++Save, then click **Run** and test each path:++| Input | Expected result |+| --- | --- |+| How do I reset Model A? | Product help branch; the answer mentions holding reset for five seconds. |+| Does Model A support Bluetooth? | Product help branch; the answer says the guide does not establish this. |+| I want to arrange an installation. | Appointment branch; a form appears and the submitted name and time are displayed. |++If routing is wrong, refine the category descriptions and examples. If retrieval is empty, check parsing status, knowledge-base selection, and the query. If the answer ignores retrieved text, check the Agent's variable references. Publish only after both branches work as intended.diff --git a/docs/guides/agent/understand_the_canvas.md b/docs/guides/agent/understand_the_canvas.mdindex 29f75d1af6..d7aa4b1adf 100644--- a/docs/guides/agent/understand_the_canvas.md+++ b/docs/guides/agent/understand_the_canvas.md@@ -11,7 +11,7 @@ sidebar_custom_props: {# Understand the Canvas## Add Components-Click the plus sign next to any component on the canvas to select the next component. Common components include `Begin`, `Agent`, `Retrieval`, `Message`, `Await response`, `Switch`, `Iteration`, `Categorize`, `Code`, `Text processing`, `Execute SQL`, `HTTP Request`, and pipeline-related components such as `Parser`, `Title chunker`, `Token chunker`, `Transformer`, and `Indexer`.+Click the plus sign next to any component on the canvas to select the next component. Workflow and Ingestion pipeline canvases offer different component menus. Workflow components include `Begin`, `Agent`, `Retrieval`, `Message`, `Await response`, `Switch`, `Iteration`, `Categorize`, `Code`, `Text processing`, `Execute SQL`, `HTTP Request`, while Ingestion pipeline components include `Parser`, `Title chunker`, `Token chunker`, `Transformer`, `Compiler`, and `Indexer`.After adding a component, click the component itself to open the configuration panel on the right. Fields in the configuration panel define input data, processing logic, output variables, and references for subsequent steps.@@ -20,7 +20,7 @@ After adding a component, click the component itself to open the configuration p## Use VariablesComponents on the Agent canvas support variable references to implement data transmission between components. Variable sources include system variables, global variables defined in the Begin component, and outputs from upstream components.-In input boxes supporting variable references, type `/` or click the variable button next to the input box to open the variable selector.+In fields that support variables, type `/` or click the variable button to open the variable selector, then choose the required variable. This inserts a reference to the component on your canvas; names shown in examples are illustrative and should not be typed as references.Common variables:| Variable | Description |@@ -32,8 +32,8 @@ Common variables:Operation Steps:1. Enter the Agent page and open the target canvas for editing.-2. Select a component supporting variable references, e.g. Agent, Retrieval, Message, Code, HTTP Request, SQL.-3. On the right configuration panel, click the input box that needs variable reference, such as System Prompt, User Prompt, Query, etc.+2. Select a component supporting variable references, e.g. Agent, Retrieval, Message, Code, HTTP Request, Execute SQL.+3. On the right configuration panel, click the input box that needs variable reference, such as **System prompt**, **User prompt**, or **Query variables**.4. Open the variable selector via either method:- Type `/` inside the input box- Click the variable icon next to the input box (may display as `{}`, `+` or other icons in different versions)@@ -46,11 +46,15 @@ Operation Steps: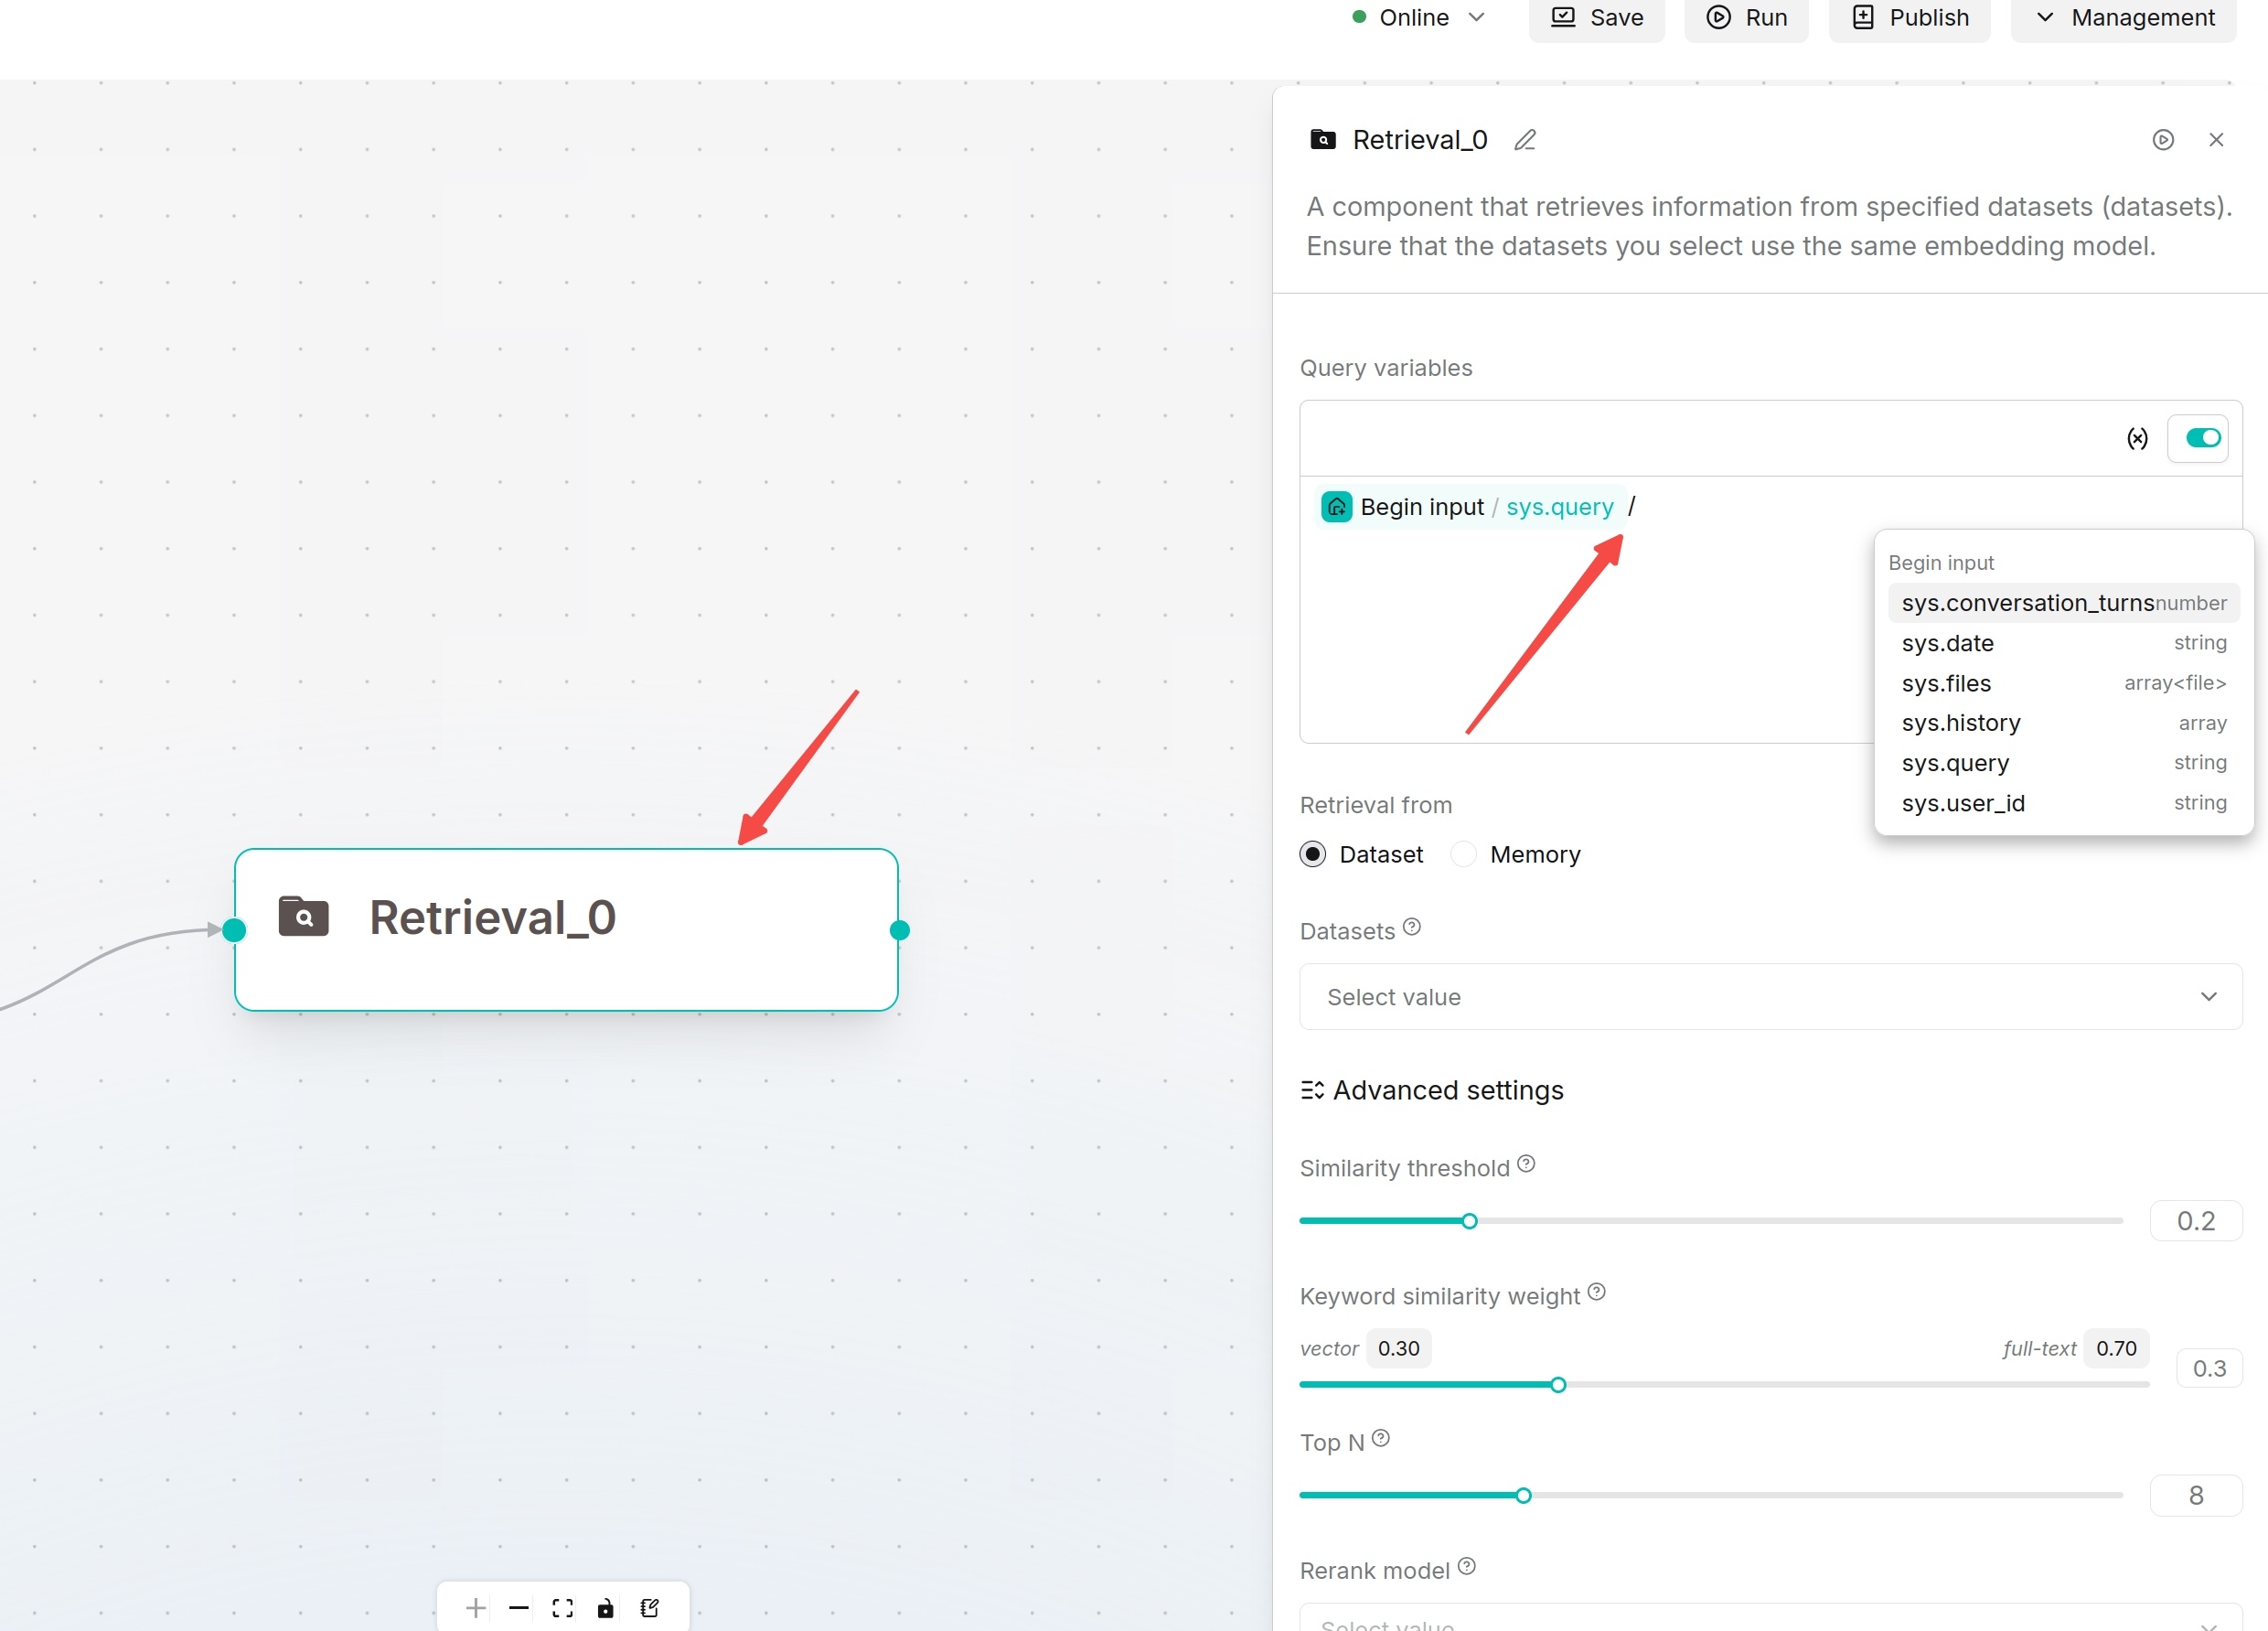## Save & Run-After configuration, click **Save** to save the Agent. During debugging, click **Run** at the top of the canvas, enter test questions and observe the execution result of each component. If a component returns no output, check input variables, model configuration, knowledge base permissions, external interface addresses or tool configuration.+For a **Workflow**, click **Save** after configuration. During debugging, click **Run** at the top of the canvas, enter test questions and observe the execution result of each component. If a component returns no output, check input variables, model configuration, knowledge base permissions, external interface addresses or tool configuration.++For an **Ingestion pipeline**, save the configuration and [validate it with a test knowledge base](./ingestion_pipeline/test_run.md).## Component Connection RulesConnections define component execution order. Sequential components run along a single path. Branch components such as `Switch` and `Categorize` route workflows to different exits according to conditions. `Iteration` executes sub-processes in loops. Components not connected to the execution path will not run. Before deleting a component, check upstream/downstream connections and variable references to avoid missing inputs for subsequent nodes.## Configuration Panel-Click any canvas component to open the right-side configuration panel, which displays fields, input variables, output variables and runtime parameters. Recommended workflow: confirm which variable the component reads → configure processing logic → verify downstream nodes reference correct outputs.+Click any canvas component to open the right-side configuration panel, which displays fields, input variables, output variables and execution settings. Recommended workflow: confirm which variable the component reads → configure processing logic → verify downstream nodes reference correct outputs.++For slow workflows, see [Improve Agent Response Time](./best_practices/accelerate_agent_question_answering.md).