
RAGFlow is an agent-native database: a Retrieval-Augmented Generation (RAG) engine that grew into context infrastructure.
Go agent-harnessagent-native-databaseagentic-aiagentic-retrievalagentic-searchaiai-agentscontext-enginecontext-engineeringcontext-managementharness-engineeringknowledge-compilationragretrieval-augmented-generationretrieval-harnesssearch-harness
docs: Update documentation to match the latest UI and functionality (#21600)
YanZhang8b4839c7451b
diff --git a/docs/administrator/management/admin_ui/manage_user_accounts.md b/docs/administrator/management/admin_ui/manage_user_accounts.mdindex 1015675403..a566ac1093 100644--- a/docs/administrator/management/admin_ui/manage_user_accounts.md+++ b/docs/administrator/management/admin_ui/manage_user_accounts.md@@ -91,9 +91,13 @@ When a user forgets their password or must be forced to change it, administratorWhen a user no longer needs system access and related resources have been handed over, administrators can delete the user from **Actions** in the user list. Before deletion, the page displays a confirmation dialog and shows the `Email` of the user to be deleted.-1. Find the target user on the **User management** page. Hover over the user row to display **Actions**, then click the delete button.-2. Check the user's `Email` in the confirmation dialog.-3. Click **Delete** to delete the user.+Before deleting a user, set their account status to **Inactive**. If their user type is **Superuser**, change it to **Normal** first. The backend rejects deletion of active accounts and Superuser accounts.++1. Find the target user on the **User management** page and set **Status** to **Inactive**.+2. If **User type** is **Superuser**, change it to **Normal**.+3. Hover over the user row to display **Actions**, then click the delete button.+4. Check the user's `Email` in the confirmation dialog.+5. Click **Delete** to delete the user.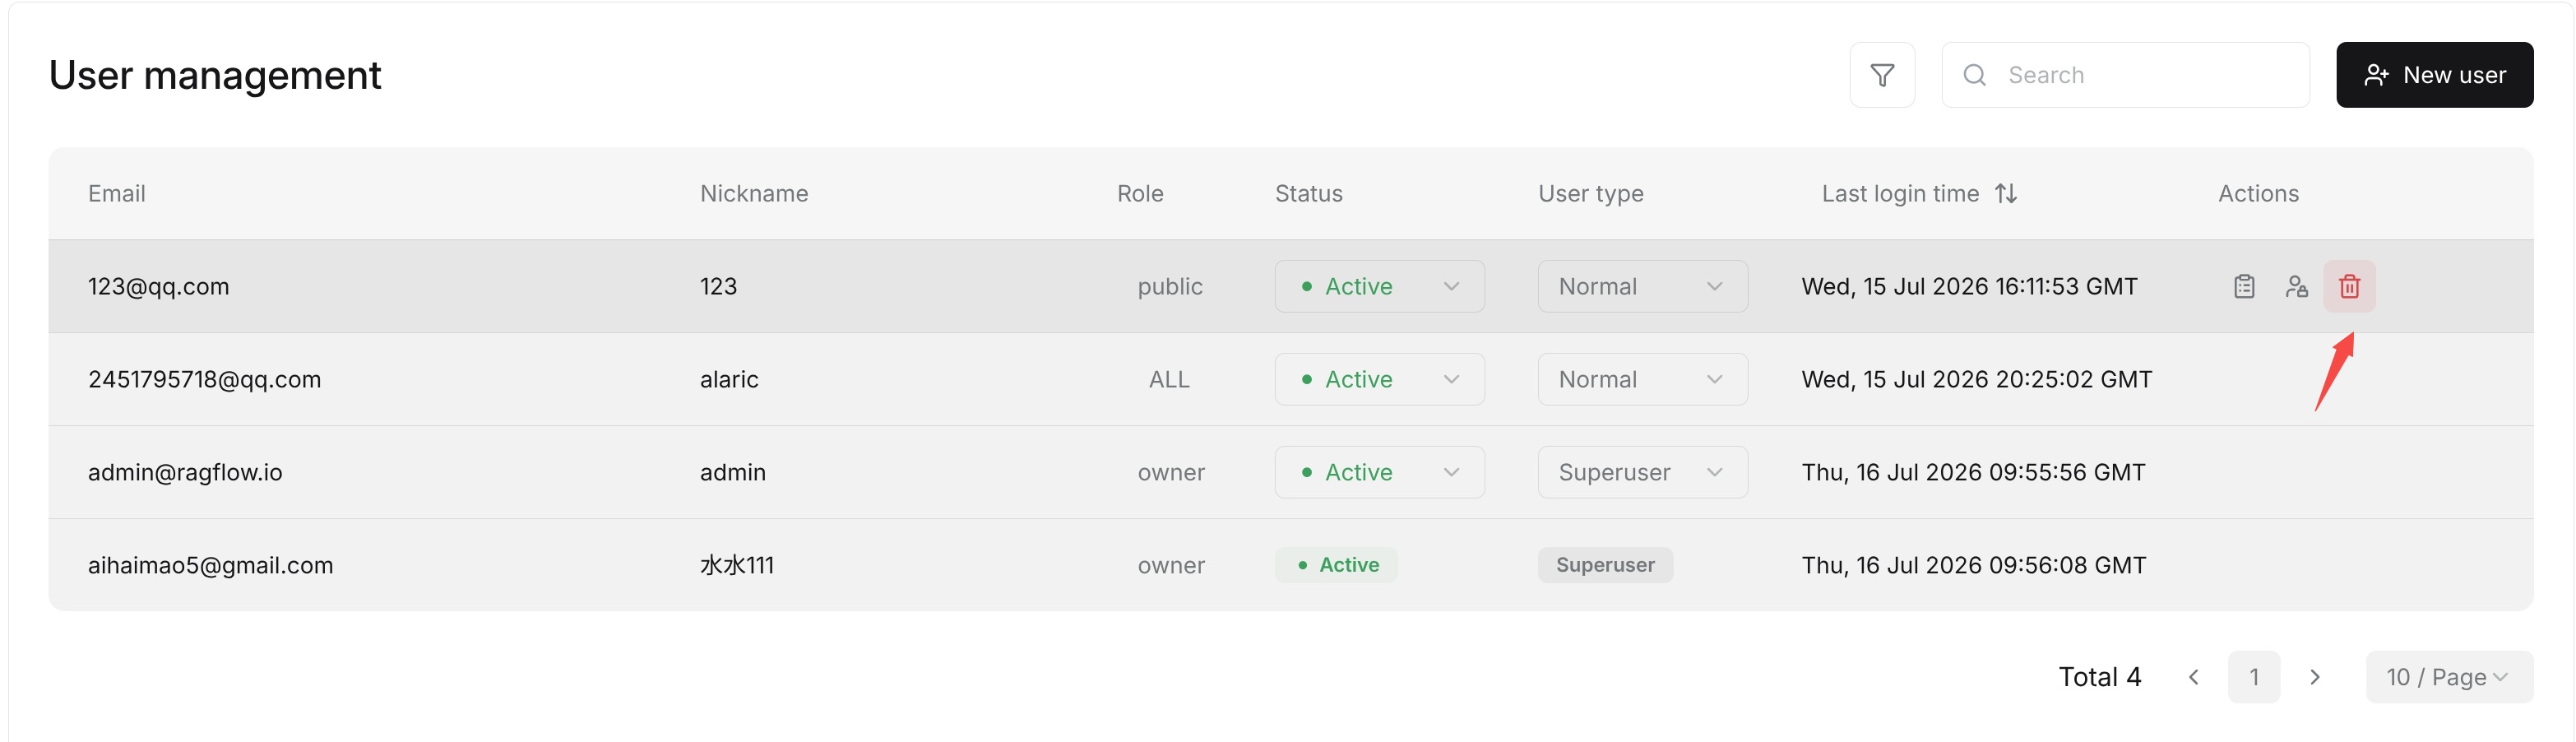diff --git a/docs/guides/dataset/artifacts_knowledge_artifact_generation_and_management.md b/docs/guides/dataset/artifacts_knowledge_artifact_generation_and_management.mdindex 7318d39863..da50189007 100644--- a/docs/guides/dataset/artifacts_knowledge_artifact_generation_and_management.md+++ b/docs/guides/dataset/artifacts_knowledge_artifact_generation_and_management.md@@ -11,4 +11,4 @@ sidebar_custom_props:Artifacts are generated by **Knowledge Compilation**. Knowledge Compilation further organizes and processes knowledge content based on documents and parsing results in the dataset, and generates corresponding knowledge artifacts according to the knowledge compilation template used. Different knowledge compilation templates can generate different forms of artifacts, such as **Wiki**, **Navigation**, and **Graph**. Generated artifacts can be viewed and browsed through the **Artifacts** entry in the dataset.-Creation and maintenance of artifacts are not completed on the **Artifacts** page. For knowledge compilation template configuration, artifact generation, update, regeneration, and **To Skill** operations, see [**Knowledge Compilation**](../knowledge_compilation/overview.md).+Creation and maintenance of artifacts are not completed on the **Artifacts** page. For knowledge compilation template configuration, artifact generation, update, and regeneration, see [**Knowledge Compilation**](../knowledge_compilation/overview.md).diff --git a/docs/guides/dataset/notes_and_faqs.md b/docs/guides/dataset/notes_and_faqs.mdindex ac0e2e82a9..b88e7ad36b 100644--- a/docs/guides/dataset/notes_and_faqs.md+++ b/docs/guides/dataset/notes_and_faqs.md@@ -55,12 +55,10 @@ During retrieval testing, hybrid search is used to retrieve chunks created by th- If no rerank model is selected, weighted keyword similarity is combined with weighted vector cosine similarity.- If a rerank model is selected, weighted keyword similarity is combined with weighted vector rerank score.-- By contrast, chunks created by knowledge graph construction are retrieved using only vector cosine similarity.### Prerequisites- Your files have been uploaded and successfully parsed before running retrieval testing.-- A knowledge graph must be successfully built before **Use Knowledge Graph** is enabled.### Configuration@@ -81,17 +79,9 @@ This setting controls the weight of vector similarity in the comprehensive simil#### Use Knowledge Graph-In a knowledge graph, entity descriptions, relationship descriptions, or community reports each exist as independent chunks. This switch indicates whether these chunks are added to retrieval. By default, this switch is disabled. After it is enabled, RAGFlow performs the following operations during retrieval testing:+In dataset retrieval testing, **Use Knowledge Graph** (`use_kg`) does not currently enable graph-based retrieval. Setting `use_kg` to `true` does not add graph traversal, entity or relationship retrieval, or community-report retrieval. The request continues through the ordinary hybrid retrieval path.-1. Uses the LLM to extract entities and entity types from your query.-2. Based on the extracted entity types, retrieves the top N entities from the graph according to their PageRank values.-3. Uses embeddings of the extracted query entities to find similar entities and their N-hop relationships in the graph.-4. Uses the query embedding to retrieve similar relationships from the graph.-5. Sorts the retrieved entities and relationships by multiplying each entity's PageRank value by its similarity score with the query, and returns the top n as the final retrieval results.-6. Retrieves reports for communities involving most entities in the final retrieval.-7. Sends the retrieved entity descriptions, relationship descriptions, and top 1 community report to the LLM for content generation.--> Important: Using the knowledge graph in retrieval testing significantly increases the time required to receive a response.+Knowledge graph generation and viewing are separate capabilities. You can still generate and view graph artifacts through Knowledge Compilation. Searchable compilation chunks may participate in ordinary retrieval according to the knowledge-compilation inclusion and scope settings; `use_kg` does not control their inclusion. See the [retrieval API reference](../../references/http_api_reference.md#retrieve-chunks) for these settings.#### Cross-Language Search@@ -108,9 +98,7 @@ This field is used to enter your test query.1. Navigate to the dataset's **Retrieval Testing** page, enter your query in **Test text**, and click **Test** to run the test.2. If the results are unsatisfactory, adjust the options listed in the configuration section and run the test again.-The following screenshot shows retrieval testing without using the knowledge graph. It demonstrates hybrid search that combines weighted keyword similarity and weighted vector cosine similarity. The overall hybrid similarity score is 28.56, calculated as `25.17` term similarity score multiplied by `0.7` plus `36.49` vector similarity score multiplied by `0.3`.--The following screenshot shows retrieval testing using the knowledge graph. It shows that chunks generated by the knowledge graph use only vector similarity.+For example, hybrid retrieval combines weighted keyword similarity and weighted vector cosine similarity. A term similarity score of `25.17` multiplied by `0.7` plus a vector similarity score of `36.49` multiplied by `0.3` gives an overall score of approximately `28.57`.> Warning: If you adjusted default settings, such as keyword similarity weight or similarity threshold, to obtain the best results, note that these changes are not saved automatically. You must apply them to your chat assistant settings or the **Retrieval Agent** component settings.@@ -118,7 +106,7 @@ The following screenshot shows retrieval testing using the knowledge graph. It s#### Is an LLM Used When the Use Knowledge Graph Switch Is Enabled?-Yes. Your LLM participates in analyzing your query and extracting relevant entities and relationships from the knowledge graph. This also explains why extra tokens and time are consumed.+In dataset retrieval testing, `use_kg` does not trigger graph retrieval or additional LLM calls for that step, even when set to `true`. Other enabled features, such as cross-language search or keyword extraction, may still call an LLM independently.#### Why does it take longer for RAGFlow to parse a document than LangChain?diff --git a/docs/guides/knowledge_compilation/apply_knowledge_compilation_template.md b/docs/guides/knowledge_compilation/apply_knowledge_compilation_template.mdindex d2e6eeaecd..b4d9e0facf 100644--- a/docs/guides/knowledge_compilation/apply_knowledge_compilation_template.md+++ b/docs/guides/knowledge_compilation/apply_knowledge_compilation_template.md@@ -41,35 +41,15 @@ If CompilationTemplate is modified, completed documents are not automatically re## View Knowledge Artifacts-After knowledge compilation is complete, enter the corresponding knowledge base and select **Artifacts** from the left sidebar. In the upper-right corner of the Artifacts page, select the artifact type you want to view from the drop-down list, such as **Wiki**, **To Skills**, **Tree/Page index**, **Graph**, **Mind map**, or **Timeline**, to view the corresponding generated results.+After knowledge compilation is complete, enter the corresponding knowledge base and select **Artifacts** from the left sidebar. In the upper-right corner of the Artifacts page, select the artifact type you want to view from the drop-down list, such as **Wiki**, **Tree/Page index**, **Graph**, **Mind map**, or **Timeline**, to view the corresponding generated results.Knowledge artifacts can be divided by generation scope into document-level and knowledge-base-level artifacts:- **Document-level knowledge artifacts**: Graph, Tree, PageIndex, MindMap, and Timeline can generate corresponding document-level results. Click a file name in the files list to view its artifacts.-- **Knowledge-base-level knowledge artifacts**: Some knowledge artifacts support further generation of knowledge-base-level results based on documents in the knowledge base. After executing a knowledge-base-level generation task, you can view the generated results in Artifacts. Wiki is generated as a knowledge-base-level artifact. After knowledge compilation for related documents is complete, you need to go to the Artifacts page of the knowledge base and click generate. The system then generates Wiki based on the compilation results in the current knowledge base.+- **Knowledge-base-level knowledge artifacts**: After a document completes a Pipeline that produces compilation results, the system automatically schedules the corresponding knowledge-base-level processing. Wiki pages are generated and merged from the document-level Wiki compilation results in the background. Open **Artifacts > Wiki** to view the results when processing is complete.-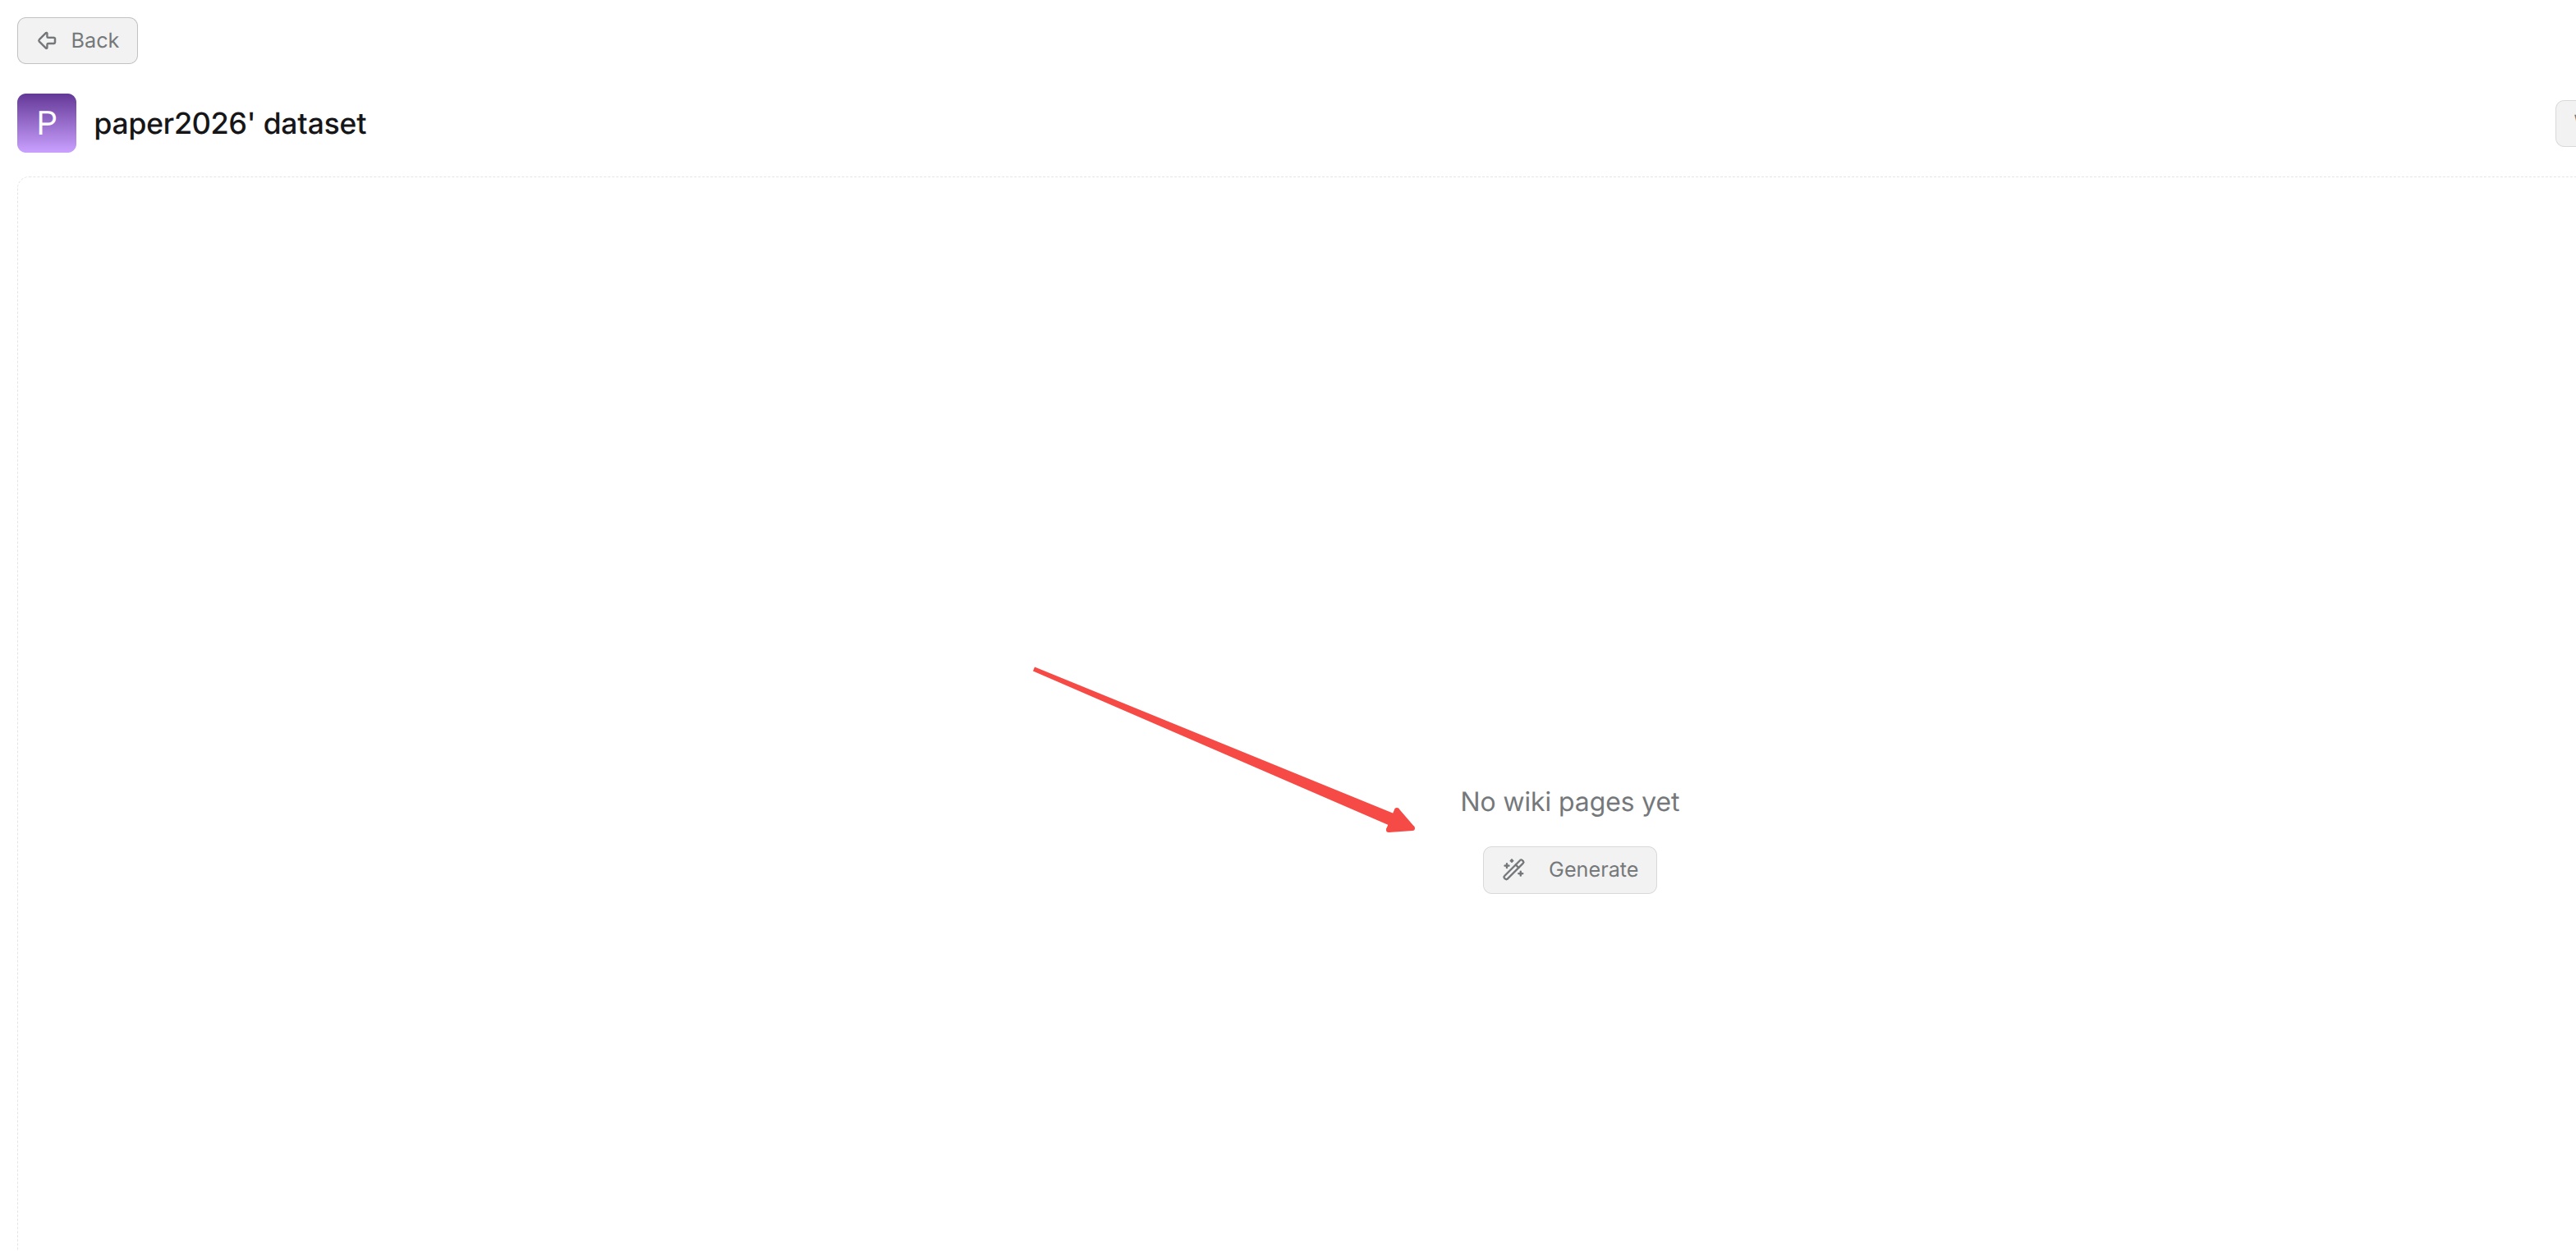---When a knowledge-base-level knowledge artifact generation task is executed, the system generates corresponding knowledge-base-level logs. You can use the logs to view the task execution status and related runtime information. When a generation task fails or the result is abnormal, check it together with the log information.--## Convert Knowledge Artifacts to Skills (To Skills)--After viewing a knowledge artifact, you can use the **To Skills** feature to further organize and convert the artifact into reusable **Skills** that can be used by agents.--**Steps:**--- Go to the **Artifacts** page of the knowledge base and open the knowledge artifact you want to convert.-- Select **To Skills** from the drop-down menu in the upper-right corner of the page.-- The system extracts and organizes relevant content from the current knowledge artifact and generates corresponding **Skills**.-- After generation is complete, the generated Skills are displayed in the **Skills** list. Click a Skill to view its details on the right.--The generated Skill typically includes a name, description, and rules, methods, or instructions extracted and organized from the knowledge artifact, which can be used by agents when performing relevant tasks.--> **Note**->-> **To Skills** does not modify the original knowledge artifact. Instead, it generates reusable Skills based on the existing knowledge artifact.+Document parsing and knowledge-base-level compilation complete separately. A document can finish parsing while its knowledge-base-level artifacts are still being processed. Check the compilation status and knowledge-base-level logs if results have not appeared or processing fails. The Ingestor service must be running for background compilation to proceed.## Knowledge Artifact Check@@ -88,18 +68,14 @@ For different knowledge artifact types, focus on the following checks:## Update Knowledge Artifacts-After knowledge artifacts are generated, the system continuously detects document changes in the knowledge base. When documents are added to or removed from the knowledge base, the corresponding knowledge artifacts are not automatically regenerated. Instead, an update prompt is displayed to remind users to synchronize the latest knowledge base content.--When document changes are detected, an **Update** button appears in the upper-left corner of the knowledge artifact page, and the number of documents to update is displayed next to the button.--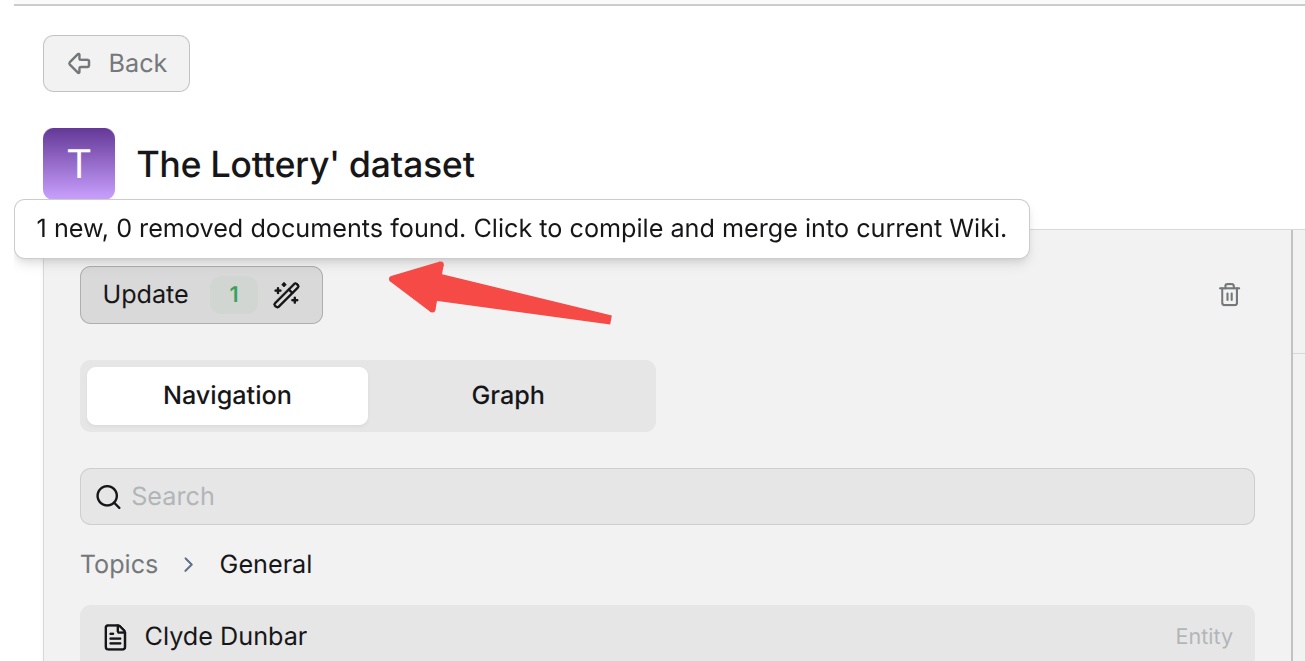+The system automatically schedules knowledge-base-level artifact updates when documents finish compilation or documents with compilation results are deleted directly through the knowledge base's document management operations. No manual **Generate** or **Update** action on the Artifacts page is required.-Hover over the update prompt area to view the specific document changes:+- **New documents**: Upload the documents and run the Pipeline containing Compiler with the required templates. After document processing completes, the system automatically incorporates the compilation results into the corresponding knowledge-base-level artifacts. Uploading a file without running the Pipeline does not generate knowledge artifacts.+- **Reparsed documents**: After a document completes the Pipeline again, the system automatically updates the corresponding knowledge-base-level artifacts from its latest compilation results.+- **Documents deleted from the knowledge base**: When you delete a compiled document directly from the knowledge base's **Files** page, the system automatically schedules removal of its contributions from the corresponding knowledge-base-level artifacts.-- **New documents**: Documents uploaded to the knowledge base after the knowledge artifact was generated and not yet included in the current knowledge artifact.-- **Removed documents**: Documents deleted from the knowledge base after the knowledge artifact was generated, but whose related content has not yet been synchronized and removed from the current knowledge artifact.-- **Number indicator**: Indicates the current number of documents detected as pending update.+Deleting a user account is a separate operation. Documents removed as part of account deletion may leave content in existing knowledge-base-level artifacts in knowledge bases that are retained. Do not assume that account deletion automatically removes those contributions.-After confirming that synchronization is needed, click **Update**. The system updates the knowledge artifact based on the current document changes in the knowledge base, keeping it consistent with the latest documents in the knowledge base.+Updates run in the background and may take time to appear. Check the compilation status and knowledge-base-level logs to confirm completion or investigate a failure.-Note: Uploading or deleting knowledge base documents alone does not immediately update existing knowledge artifacts. After the update prompt appears, you need to manually click **Update** to complete synchronization.+Changing a compilation template alone does not recompile completed documents. Reparse the affected documents with the updated template; their knowledge-base-level artifacts are then updated automatically after document processing completes.diff --git a/docs/guides/knowledge_compilation/faq.md b/docs/guides/knowledge_compilation/faq.mdindex 2404fbd5f7..e2f1035259 100644--- a/docs/guides/knowledge_compilation/faq.md+++ b/docs/guides/knowledge_compilation/faq.md@@ -12,11 +12,9 @@ sidebar_custom_props: {## 1. Why can't I see Wiki in Artifacts after knowledge compilation is complete?-Wiki is generated differently from other knowledge artifacts.+Wiki is a knowledge-base-level knowledge artifact. After a document completes a Pipeline configured with a Wiki compilation template, the system automatically schedules Wiki generation and merging in the background. Document parsing can finish before this knowledge-base-level processing completes.-Graph, Tree, PageIndex, MindMap, and Timeline are document-level knowledge artifacts. Their corresponding results can be viewed after knowledge compilation is complete.--Wiki is a knowledge-base-level knowledge artifact. After document knowledge compilation is complete, you still need to go to the Artifacts page of the knowledge base and click generate. The system then generates Wiki based on the compilation results in the current knowledge base.+Open **Artifacts > Wiki** after background compilation completes. No manual generation step is required. If Wiki pages do not appear, confirm that Compiler uses a Wiki template, the document processing succeeded, and the Ingestor service is running. Check the compilation status and knowledge-base-level logs for pending processing or errors.## 2. Why are no corresponding knowledge artifacts generated after knowledge compilation?diff --git a/docs/guides/memory/configure_memory.md b/docs/guides/memory/configure_memory.mdindex 65cda71497..389cefea29 100644--- a/docs/guides/memory/configure_memory.md+++ b/docs/guides/memory/configure_memory.md@@ -18,12 +18,16 @@ On the memory page, click the target memory **> Configurations** to view and updThe name, avatar, and description are mainly used to distinguish memories. Fill them in according to the page prompts. The avatar image must not exceed 4 MB.-The embedding model and large language model are the basic configuration for memory extraction and retrieval. The embedding model is used to convert memory content into vectors and supports subsequent similarity retrieval. The large language model is used to analyze conversation content and extract structured memories. After messages have already been written to a memory, frequent model changes are not recommended.+The embedding model and large language model are the basic configuration for memory extraction and retrieval. The embedding model is used to convert memory content into vectors and supports subsequent similarity retrieval. The large language model is used to analyze conversation content and extract structured memories.++Once a memory contains messages, you cannot change its embedding model, the associated embedding model instance, or its memory types. Saving a change to any of these settings is rejected. Choose these settings before writing messages; create a new memory if you need a different configuration while retaining the existing memory's messages. The large language model can still be changed, but changing it does not automatically re-extract existing messages.### Memory TypeMultiple memory types can be selected, but **Raw (`raw`)** is required and cannot be removed. When multiple types are selected, the system saves or extracts memories at different levels according to the selected types.+Memory types can be changed only while the memory is empty.+- **Raw (`raw`)**: Saves the original conversation content between the user and the Agent. It is suitable for scenarios where the complete context needs to be traced, and it is also the basis for extracting other types of memory.- **Semantic (`semantic`)**: Extracts relatively stable facts, preferences, attributes, or background information, such as user preferences, customer profiles, and common requirements. It is suitable for long-term reuse.- **Episodic (`episodic`)**: Extracts experience records with time, conversation, or event context, such as a communication, a task execution result, or a staged event. It is suitable for tracing historical processes.diff --git a/docs/references/http_api_reference.md b/docs/references/http_api_reference.mdindex 04aedffa10..08561b0fa2 100644--- a/docs/references/http_api_reference.md+++ b/docs/references/http_api_reference.md@@ -7,7 +7,7 @@ sidebar_custom_props: {---# HTTP API-A complete reference for RAGFlow's RESTful API, including migration notes for the 1.0 Go backend. Before proceeding, please ensure you [have your RAGFlow API key ready for authentication](https://ragflow.io/docs/dev/acquire_ragflow_api_key).+A complete reference for RAGFlow's RESTful API, including migration notes for RAGFlow 1.0. Before proceeding, please ensure you [have your RAGFlow API key ready for authentication](https://ragflow.io/docs/dev/acquire_ragflow_api_key).In the standard response envelope, `message` is always a non-empty string. Successful responses default to `"success"`; error responses contain a description of the error.@@ -53,23 +53,19 @@ RAGFlow responses may contain both an HTTP status code and a business code in th## Migrate to 1.0-RAGFlow 1.0 moves the public REST API from the Python backend to Go. The canonical endpoints documented below remain available.+RAGFlow 1.0 updates the public REST API. Use the canonical endpoints documented below.The following changes require client updates:-| Area | RAGFlow 1.0 Go change | Client action |+| Area | RAGFlow 1.0 change | Client action ||------|------------------------|---------------|| Dataset parser selection | Dataset create and update use `parse_type` with `parser_id` (BuiltIn) or `pipeline_id` (Pipeline); responses use the canonical value `general` instead of the legacy `chunk_method: "naive"`. | Replace `chunk_method` with `"parse_type": 1` and `"parser_id": "<builtin parser>"`. For the general parser, send `"parser_id": "general"`. |-| Dataset parser configuration | Go stores and returns component-scoped parser settings. Most legacy top-level `parser_config` fields are not mapped into that component structure. | Read the returned component map and send component-scoped keys when changing parser settings. |-| Errors and authentication | Some validation business codes, messages, and authentication HTTP statuses differ from Python. | Branch on documented codes rather than exact message text. |--:::note-Go responses include `X-API-Source: go`, which can be used to verify the serving backend during rollout.-:::+| Dataset parser configuration | RAGFlow stores and returns component-scoped parser settings. Most legacy top-level `parser_config` fields are not mapped into that component structure. | Read the returned component map and send component-scoped keys when changing parser settings. |+| Errors and authentication | Some validation business codes, messages, and authentication HTTP statuses differ from earlier releases. | Branch on documented codes rather than exact message text. |### Removed API aliases-The following paths remain available only on the Python backend. They are not registered by the RAGFlow 1.0 Go backend.+The following endpoint aliases are not available in RAGFlow 1.0. Use their replacements below.| Removed endpoint | Replacement endpoint ||-----------------------------------------------------------------------------------|-------------------------------------------------------------------------------------|@@ -260,7 +256,7 @@ Failure:### Create OpenAI-compatible agent completion:::caution REMOVED ALIAS-RAGFlow 1.0 Go does not serve `POST /api/v1/agents_openai/{agent_id}/chat/completions`. Use the endpoint below and move `agent_id` into the request body.+RAGFlow 1.0 does not serve `POST /api/v1/agents_openai/{agent_id}/chat/completions`. Use the endpoint below and move `agent_id` into the request body.:::**POST** `/api/v1/agents/chat/completions`@@ -2524,7 +2520,7 @@ curl --request POST \Selects which searchable knowledge-compilation chunks to include: `"dataset"` for dataset artifacts, `"document"` for document artifacts, or `"all"` for both. Defaults to `"dataset"` when omitted, `null`, or an empty string. Ordinary source chunks remain eligible. When `"include_knowledge_compilation"` is `false`, all compiled chunks are excluded regardless of scope. Unsupported scope values and non-string values return an argument error. Intermediate wiki rows and disabled chunks remain excluded.With `"document_ids"` or metadata filtering, document artifacts and source chunks are limited to the selected documents; dataset artifacts must reference a selected document in their `source_doc_ids`. This parameter is also supported by `POST /api/v1/datasets/search` and `POST /api/v1/datasets/{dataset_id}/search`.- `"use_kg"`: `boolean`- Whether to search chunks related to the generated knowledge graph for multi-hop queries. Defaults to `False`. Before enabling this, ensure you have successfully constructed a knowledge graph for the specified datasets. See [here](../guides/knowledge_compilation/built_in_templates_and_dedicated_configuration.md#graph) for details.+ Defaults to `false`. For this endpoint (`POST /api/v1/retrieval`), setting this to `true` does not enable multi-hop graph retrieval; the request continues through ordinary hybrid retrieval. The same limitation applies to `POST /api/v1/datasets/search` and `POST /api/v1/datasets/{dataset_id}/search`. To control whether searchable knowledge-compilation chunks are included in ordinary retrieval, use `"include_knowledge_compilation"` and `"knowledge_compilation_scope"`. Knowledge graph generation and viewing through Knowledge Compilation are separate capabilities.- `"rerank_id"`: `string`The ID of the rerank model.- `"keyword"`: `boolean`