
RAGFlow is an agent-native database: a Retrieval-Augmented Generation (RAG) engine that grew into context infrastructure.
Go agent-harnessagent-native-databaseagentic-aiagentic-retrievalagentic-searchaiai-agentscontext-enginecontext-engineeringcontext-managementharness-engineeringknowledge-compilationragretrieval-augmented-generationretrieval-harnesssearch-harness
docs: add search docs (#19057)
YanZhang9d00ee013e87
diff --git a/docs/guides/ai_search.md b/docs/guides/ai_search.mddeleted file mode 100644index 2758f44a5e..0000000000--- a/docs/guides/ai_search.md+++ /dev/null@@ -1,35 +0,0 @@-----sidebar_position: 4-title: Search-sidebar_label: Search-slug: /ai_search-sidebar_custom_props: {- categoryIcon: LucideSearch-}-----# Search--Conduct an AI search.-------An AI search is a single-turn AI conversation using a predefined retrieval strategy (a hybrid search of weighted keyword similarity and weighted vector similarity) and the system's default chat model. It does not involve advanced RAG strategies like knowledge graph, auto-keyword, or auto-question. The related chunks are listed below the chat model's response in descending order based on their similarity scores.--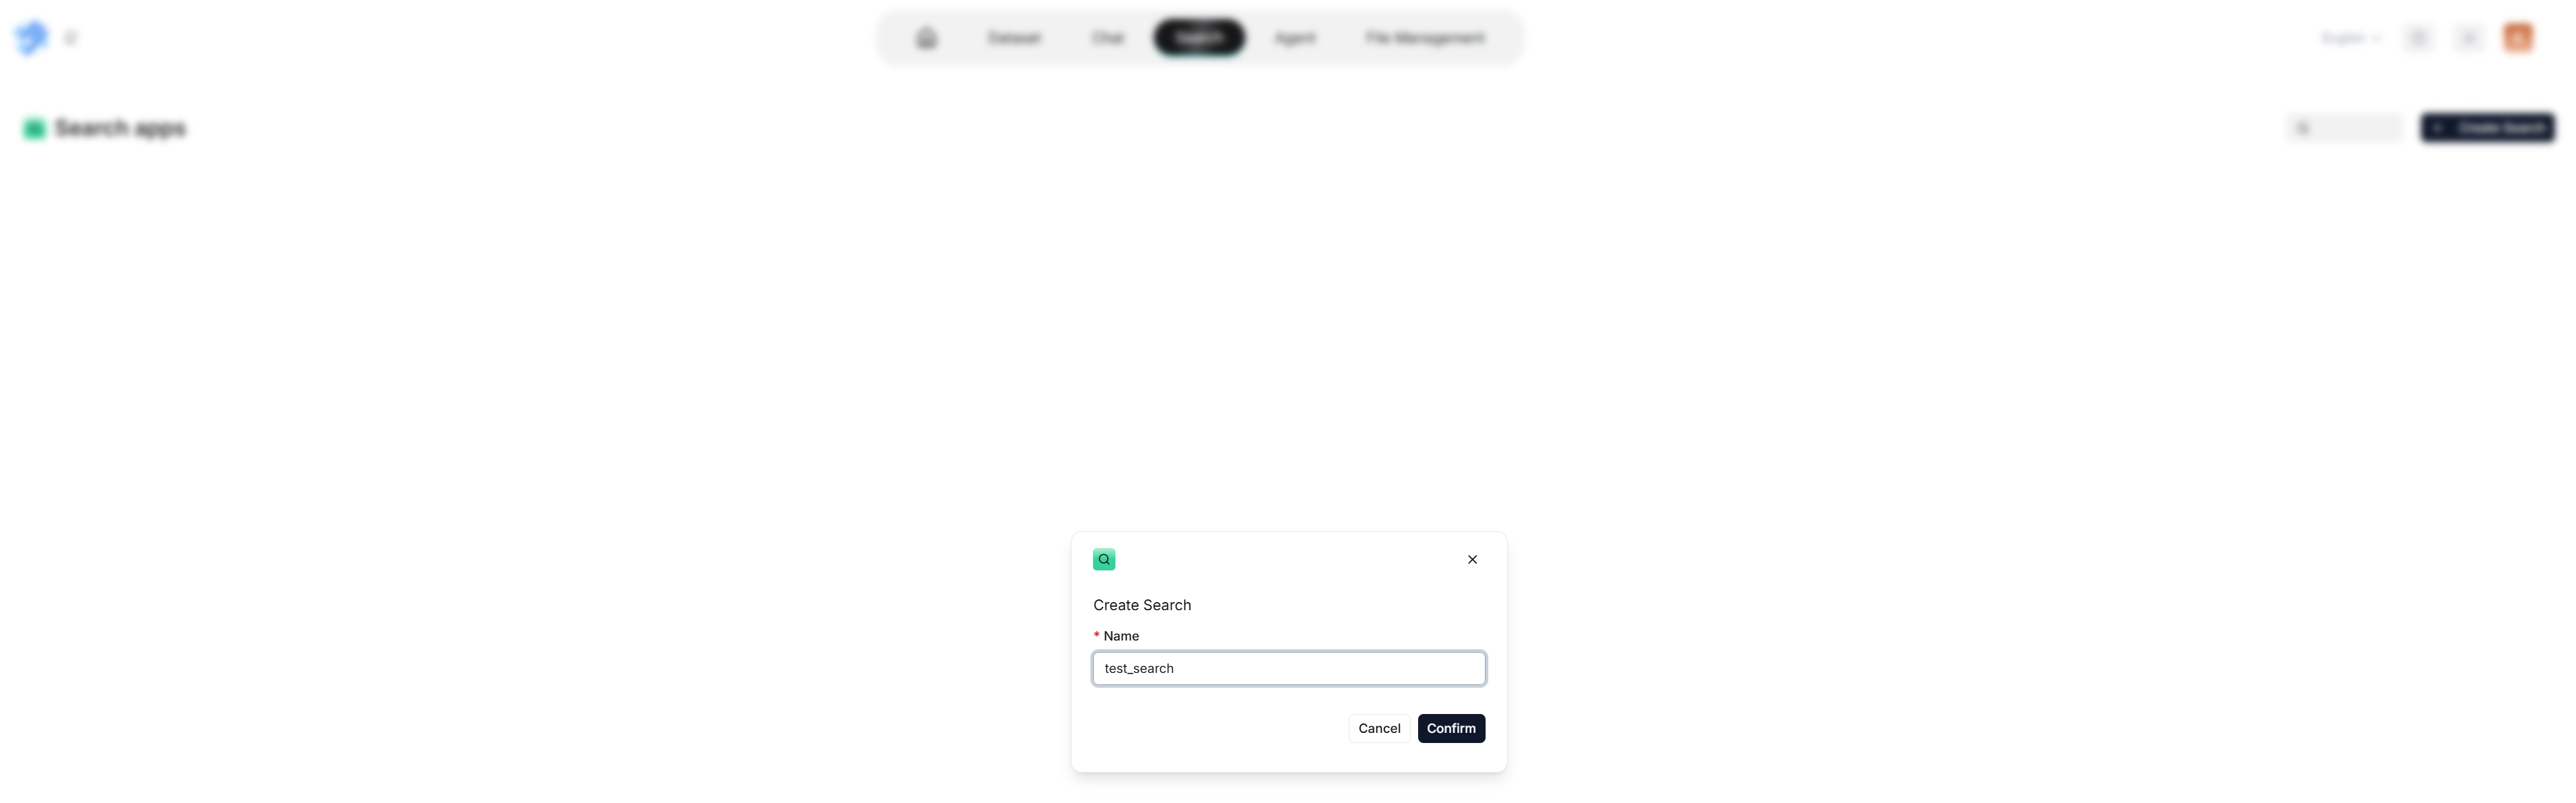--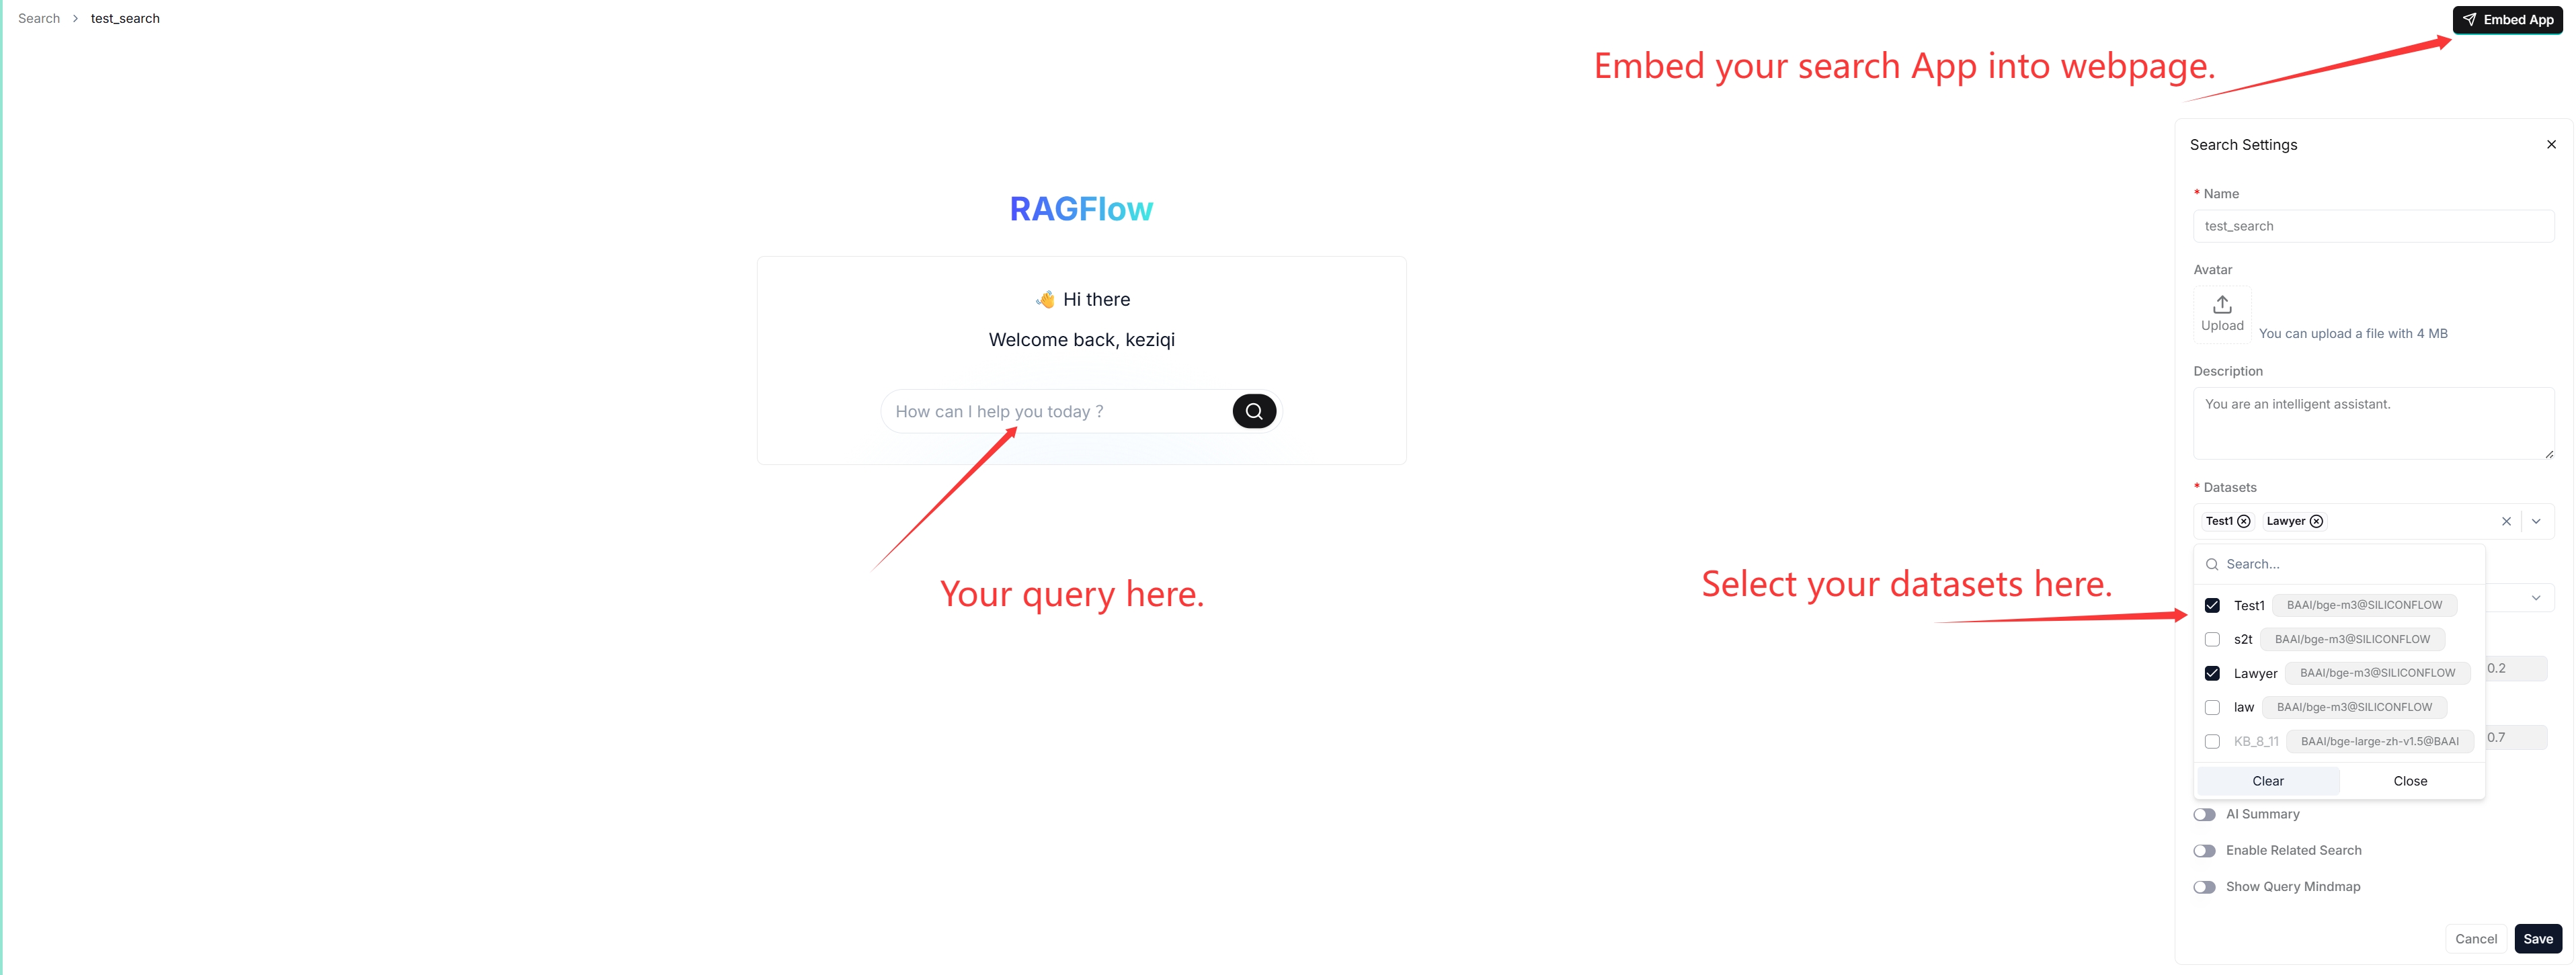--:::tip NOTE-When debugging your chat assistant, you can use AI search as a reference to verify your model settings and retrieval strategy.-:::--## Prerequisites--- Ensure that you have configured the system's default models on the **Model providers** page.-- Ensure that the intended datasets are properly configured and the intended documents have finished file parsing.--## Frequently Asked Questions--### Key Difference Between an AI Search and an AI Chat?--A chat is a multi-turn AI conversation where you can define your retrieval strategy (a weighted reranking score can be used to replace the weighted vector similarity in a hybrid search) and choose your chat model. In an AI chat, you can configure advanced RAG strategies, such as knowledge graphs, auto-keyword, and auto-question, for your specific case. Retrieved chunks are not displayed along with the answer.diff --git a/docs/guides/search/_category_.json b/docs/guides/search/_category_.jsonnew file mode 100644index 0000000000..0865056a0c--- /dev/null+++ b/docs/guides/search/_category_.json@@ -0,0 +1,11 @@+{+ "label": "Search",+ "position": 4,+ "link": {+ "type": "generated-index",+ "description": "Learn how to create, configure, and use Search."+ },+ "customProps": {+ "categoryIcon": "LucideSearch"+ }+}diff --git a/docs/guides/search/create_search.md b/docs/guides/search/create_search.mdnew file mode 100644index 0000000000..54efc36da3--- /dev/null+++ b/docs/guides/search/create_search.md@@ -0,0 +1,22 @@+---+sidebar_position: 1+title: Create a Search+sidebar_label: Create a Search+slug: /create_search+sidebar_custom_props:+ categoryIcon: LucideSearch+---++# Create a Search++Search provides retrieval capabilities for knowledge bases, helping users quickly find relevant content in parsed knowledge bases. Users can enter natural-language questions and narrow the search scope by configuring document filters, the number of results, and other options.++Search also supports features such as AI Summary, Related Search, and Query Mind Map. These features summarize search results, generate related questions, and present the topic structure of the current query as a mind map, helping users further understand and explore knowledge content.++The following sections describe how to create, configure, and use Search.++1. Go to the **Search** page from the top navigation bar.+2. Click **Create Search**.+3. Enter a name for the Search and confirm.+4. Open the newly created Search and go to **Search Settings**.+5. Under **Datasets**, select at least one knowledge base and click **OK** to save.diff --git a/docs/guides/search/faq.md b/docs/guides/search/faq.mdnew file mode 100644index 0000000000..4eb74c168a--- /dev/null+++ b/docs/guides/search/faq.md@@ -0,0 +1,46 @@+---+sidebar_position: 3+title: FAQ+sidebar_label: FAQ+slug: /search_faq+sidebar_custom_props:+ categoryIcon: LucideSearch+---++# FAQ++**What are the main differences between Search and Chat?**++Search is designed for knowledge retrieval. It retrieves and displays relevant content from selected knowledge bases based on the user's query, helping users quickly locate the information they need.++Chat is designed for knowledge-based question answering. In addition to retrieving relevant knowledge, it uses an LLM to understand questions and generate answers. It also supports multi-turn conversations and capabilities such as Agentic Retrieval, making it suitable for scenarios that require information synthesis, reasoning, and natural-language responses.++**Why can't I find content that already exists in the knowledge base?**++The relevant chunks may not meet the **Similarity threshold**, or the query may differ significantly from the wording in the source content. Try lowering the similarity threshold, adjusting the **Vector similarity weight**, or using more specific keywords.++Also make sure that the target knowledge base has been added to the current Search and that the relevant documents have been successfully parsed and indexed.++**Why do my search results contain a lot of irrelevant content?**++Try increasing the **Similarity threshold** to filter out less relevant results.++If your query relies mainly on keywords, proper nouns, or identifiers, you can also decrease the **Vector similarity weight** to give full-text retrieval more weight in hybrid retrieval.++**How should I set the Vector similarity weight?**++This parameter controls the balance between vector retrieval and full-text retrieval.++For semantic search scenarios, you can increase the Vector weight. If you mainly search for product names, identifiers, technical terms, or other content that requires exact matching, you can increase the Full-text weight. In most cases, it is recommended to start with the default value and adjust it based on actual search results.++**Why does Search become slower after I enable the Rerank model?**++When the **Rerank model** is enabled, the system uses the rerank model to further evaluate the relevance of retrieved candidates and reorder them. This introduces additional model calls and processing time.++If result ranking quality is more important, you can enable Rerank. If response speed is more important, you can disable it or reduce **Rerank candidates**.++**Is a higher Similarity threshold always better?**++No. A higher threshold can reduce less relevant results, but it may also filter out useful content, resulting in fewer or even no search results.++Adjust the threshold according to your knowledge base and actual search results to achieve a balance between retrieval coverage and result relevance.diff --git a/docs/guides/search/search_settings.md b/docs/guides/search/search_settings.mdnew file mode 100644index 0000000000..891c5ed95c--- /dev/null+++ b/docs/guides/search/search_settings.md@@ -0,0 +1,104 @@+---+sidebar_position: 2+title: Search Settings+sidebar_label: Search Settings+slug: /search_settings+sidebar_custom_props:+ categoryIcon: LucideSearch+---++# Search Settings++Search Settings allow you to configure the knowledge sources, retrieval strategy, and presentation of search results. After completing the configuration, click **Save**.++## Datasets++Select the knowledge bases that Search will use. When a user submits a query, the system retrieves relevant content from the selected knowledge bases.++You can select one or more knowledge bases. When multiple knowledge bases are selected, Search retrieves relevant content from all of them simultaneously.++Select knowledge bases based on the intended use case of the Search. Avoid adding large numbers of knowledge bases that are unrelated to the search topic, as this may increase the number of irrelevant results.++## Show chunk metadata++Controls whether chunk metadata is displayed in search results.++When enabled, search results can display metadata associated with each chunk in addition to its text. This helps users identify the source of the content and further filter or evaluate the results.++If you are mainly interested in the content itself, you can leave this option disabled. Enable it if you need to inspect or verify the sources of the results.++## Similarity threshold++Sets the minimum similarity threshold for search results. It is used to filter out chunks that have low relevance to the query.++Only content with a similarity score that meets or exceeds the threshold is included in the search results.++- Increase the threshold: Filtering becomes stricter, and the results are generally more relevant, but some useful content may be omitted.+- Decrease the threshold: More content can be retrieved, but the number of irrelevant results may also increase.++If there are too many results and their relevance is low, try increasing this value. If Search frequently fails to return the expected content, try decreasing it.++## Vector similarity weight++Sets the relative weights of vector similarity and full-text search in hybrid retrieval.++For example, a value of `0.3` means:++- Vector = `0.3`+- Full-text = `0.7`++Vector search focuses more on semantic similarity between the query and the document, while full-text search focuses more on matching keywords, terms, and other textual elements.++Therefore:++- Increase the vector weight: Gives greater priority to semantic matching. This is suitable when a user's wording differs from that of the source text.+- Decrease the vector weight: Gives greater priority to full-text matching. This is suitable for exact matches involving proper nouns, product models, identifiers, fixed terminology, and similar content.++You can generally start with the default value and adjust it based on actual search performance.++## Rerank candidates++Sets the number of candidate chunks that enter the reranking stage.++The system first retrieves candidate content from the knowledge bases and then determines which results to display from among those candidates. This parameter controls the candidate pool available for subsequent ranking or reranking.++For example, a value of `100` means that up to 100 candidate chunks are selected for subsequent processing.++- Increase the value: Expands the candidate pool and reduces the likelihood that highly relevant content will be missed during initial retrieval, but increases processing overhead.+- Decrease the value: Generally improves search speed, but the smaller candidate pool may omit some relevant content.++For large knowledge bases or use cases that require broader retrieval coverage, you can increase this value as appropriate.++## Rerank model++Controls whether a rerank model is used to rerank the retrieved results.++When enabled, you must select an available rerank model. The system uses the model to further evaluate the relevance between the query and the candidate chunks, and then reorders the search results.++Reranking can generally improve the quality of the final result ordering, but it introduces additional model calls and increases search latency.++Enable it if search accuracy is the priority. Leave it disabled if response speed is more important or no rerank model has been configured.++## AI summary++Controls whether an AI-generated summary is produced for the search results.++When enabled, the system uses a model to summarize the retrieved content. This helps users quickly understand the main information in the search results without reading every chunk individually.++This feature requires a model call and may therefore increase result-generation time and model usage costs.++## Enable related search++Controls whether related searches are generated for the current query.++When enabled, the system can suggest related searches based on the current query and its search results, helping users continue exploring information related to the current topic.++This feature is suitable for content exploration, research, and open-ended searches. If you only need to view the results for the current query, you can leave it disabled.++## Show query mindmap++Controls whether a mind map for the current query is displayed.++When enabled, the system organizes and presents information from the query and related searches as a mind map, helping users quickly understand the relationships between topics and the overall structure of the subject.++This feature is more suitable for knowledge exploration and searches involving complex topics. It is generally unnecessary for simple factual queries.