
RAGFlow is an agent-native database: a Retrieval-Augmented Generation (RAG) engine that grew into context infrastructure.
Go agent-harnessagent-native-databaseagentic-aiagentic-retrievalagentic-searchaiai-agentscontext-enginecontext-engineeringcontext-managementharness-engineeringknowledge-compilationragretrieval-augmented-generationretrieval-harnesssearch-harness
docs: add dataset docs & fix broken links in docs (#18553)
YanZhanga4f754a47272
diff --git a/docs/faq.mdx b/docs/faq.mdxindex 57ca3f950d..7ed73c8a45 100644--- a/docs/faq.mdx+++ b/docs/faq.mdx@@ -582,13 +582,29 @@ You can control the batch size for document parsing and embedding by setting the### How to accelerate the question-answering speed of my chat assistant?+To reduce response latency, consider the following:+- Use a faster LLM with lower inference latency.+- Reduce the number of retrieved chunks by adjusting retrieval parameters such as **Top N**.+- Keep prompts concise and avoid unnecessary context.+- Disable optional features that require additional model calls when they are not needed.+- Use a reranker only when it provides a meaningful improvement in retrieval quality.+- Make sure the deployed model service has sufficient computing resources and low network latency.+See [here](./guides/chat/best_practices/accelerate_question_answering.mdx).---### How to accelerate the question-answering speed of my Agent?-See [here](./guides/agent/best_practices/accelerate_agent_question_answering.md).+Agent response time depends on the number of components, model calls, and external services involved in the workflow.+To improve response speed:+- Use faster models for components that do not require strong reasoning capabilities.+- Reduce unnecessary LLM, retrieval, tool, and HTTP calls.+- Simplify the Agent workflow and avoid excessively long execution paths.+- Limit the number of iterations in loops or reasoning-intensive components.+- Reduce the amount of context passed between components where possible.+- Run independent operations in parallel when the workflow supports it.+- Make sure external APIs and model services used by the Agent have low latency.### How to use MinerU to parse PDF documents?diff --git a/docs/guides/chat/start_chat.md b/docs/guides/chat/start_chat.mdindex ebcfc26b99..cddbf323e4 100644--- a/docs/guides/chat/start_chat.md+++ b/docs/guides/chat/start_chat.md@@ -13,7 +13,7 @@ Initiate an AI-powered chat with a configured chat assistant.----Chats in RAGFlow are based on a particular dataset or multiple datasets. Once you have created your dataset, finished file parsing, and [run a retrieval test](../dataset/run_retrieval_test.md), you can go ahead and start an AI conversation.+Chats in RAGFlow are based on a particular dataset or multiple datasets. Once you have created your dataset, finished file parsing, and [run a retrieval test](../dataset/retrieval_testing.md), you can go ahead and start an AI conversation.## Start an AI Chatdiff --git a/docs/guides/dataset/artifacts_knowledge_artifact_generation_and_management.md b/docs/guides/dataset/artifacts_knowledge_artifact_generation_and_management.mdnew file mode 100644index 0000000000..7db0b40417--- /dev/null+++ b/docs/guides/dataset/artifacts_knowledge_artifact_generation_and_management.md@@ -0,0 +1,15 @@+---+sidebar_position: 8+title: Artifacts: Knowledge Artifact Generation and Management+sidebar_label: Artifacts: Knowledge Artifact Generation and Management+slug: /artifacts_knowledge_artifact_generation_and_management+sidebar_custom_props: {+ categoryIcon: LucideDatabaseZap+}+---++# Artifacts: Knowledge Artifact Generation and Management++Artifacts are generated by **Knowledge Compilation**. Knowledge Compilation further organizes and processes knowledge content based on documents and parsing results in the dataset, and generates corresponding knowledge artifacts according to the knowledge compilation template used. Different knowledge compilation templates can generate different forms of artifacts, such as **Wiki**, **Navigation**, and **Graph**. Generated artifacts can be viewed and browsed through the **Artifacts** entry in the dataset.++Creation and maintenance of artifacts are not completed on the **Artifacts** page. For knowledge compilation template configuration, artifact generation, update, regeneration, and **To Skill** operations, see **Knowledge Compilation**.diff --git a/docs/guides/dataset/chunk_parsing_results_and_knowledge_fragment_management.md b/docs/guides/dataset/chunk_parsing_results_and_knowledge_fragment_management.mdnew file mode 100644index 0000000000..6dd0fc658b--- /dev/null+++ b/docs/guides/dataset/chunk_parsing_results_and_knowledge_fragment_management.md@@ -0,0 +1,67 @@+---+sidebar_position: 5+title: Chunk: Parsing Results and Knowledge Fragment Management+sidebar_label: Chunk: Parsing Results and Knowledge Fragment Management+slug: /chunk_parsing_results_and_knowledge_fragment_management+sidebar_custom_props: {+ categoryIcon: LucideDatabaseZap+}+---++# Chunk: Parsing Results and Knowledge Fragment Management++Chunks are the retrievable knowledge fragments generated after document parsing. They are the basic units used by RAGFlow for retrieval and Q&A. Chunk management is used to view, search, filter, edit, add, enable, disable, and delete chunks.++## View Parsing Results++After document parsing is completed, click the document name on the **Files** page to enter the document parsing result page. The parsing result page displays chunks generated from the document. You can use this page to check whether document content has been correctly parsed, split, and stored.++## View Chunk List++The chunk list displays the chunks generated for the current document. Each chunk usually includes body text, keywords, questions, enabled status, and related operations. For documents that support source preview, the chunk list can be linked with source content. After clicking chunk text, the document preview area jumps to the corresponding source location, making it convenient to compare with the original document and check parsing and splitting results.++For document types that cannot locate source text, parsing results are mainly viewed through chunk body text.++## Search and Filter Chunk++When a document contains many chunks, use the search and filter functions in the toolbar to quickly locate target content. You can enter keywords to search chunks or filter chunks by enabled status. For chunks with long body text, you can switch between full display and collapsed display as needed to browse parsing results.++### View Chunk Details++After opening chunk details, you can further view the body text and related information for the knowledge fragment, such as:++- **Body text**: The main text actually stored in the chunk and used for retrieval. After clicking the chunk body, the document preview area jumps to the corresponding source location.+- **Keywords**: Keywords related to the current chunk, used to enhance content retrieval.+- **Questions**: Questions generated or configured based on chunk content, used to enhance recall for related questions.+- **Enabled status**: Determines whether the current chunk participates in dataset retrieval.++When viewing a chunk, you can check it together with its corresponding source document to confirm whether the chunk content is complete, semantically coherent, and suitable for retrieval.++### Edit Chunk++If parsing results are inaccurate or content needs to be supplemented, you can edit chunks manually. Double-click a chunk to open the edit parsing block window. You can view and modify:++- **Content**: The body text of the chunk.+- **Keywords**: Keywords related to chunk content. Keywords can be added or deleted to enhance retrieval for the chunk.+- **Questions**: Questions associated with the chunk.+- **Tags**: Tags added to the chunk, used to mark and manage knowledge fragments.++After saving the edit, the updated chunk content is used for later retrieval.++### Add Chunk++If you need to add extra knowledge fragments manually, you can add chunks on the chunk management page. Added chunks are stored under the current document and can be used as content sources for dataset retrieval and Q&A.++When adding a chunk, you usually need to enter the chunk content and configure keywords, questions, tags, or enabled status as needed.++### Enable and Disable Chunk++The enabled status of a chunk determines whether it participates in dataset retrieval. A disabled chunk remains in the parsing result but is not recalled during retrieval.++If a chunk contains outdated, incorrect, or temporarily unnecessary content, you can disable it. If the content needs to participate in retrieval again, enable it again.++### Delete Chunk++Deleting a chunk removes it from the current document's parsing results. It no longer participates in later retrieval or Q&A.++Before deleting, confirm that the chunk is no longer needed. If you only want to temporarily exclude it from retrieval, use disable instead.diff --git a/docs/guides/dataset/configuration.md b/docs/guides/dataset/configuration.mdnew file mode 100644index 0000000000..0233277028--- /dev/null+++ b/docs/guides/dataset/configuration.md@@ -0,0 +1,185 @@+---+sidebar_position: 3+title: Configuration+sidebar_label: Configuration+slug: /dataset_configuration+sidebar_custom_props: {+ categoryIcon: LucideDatabaseZap+}+---++# Configuration++## Basic Information++The configuration page is used to maintain the core configuration of a dataset. Basic information includes **Name**, **Language**, **Avatar**, **Description**, **Embedding model**, **PageRank**, and **Tag sets**.++- **Name**: The dataset name. It can still be modified after creation and is used in list cards and the detail page title.+- **Language**: The primary language of the dataset. The language setting affects language assumptions during parsing and model processing.+- **Avatar**: The dataset avatar. Image uploads are supported, and the maximum image size is 4 MB.+- **Description**: The dataset description, used to describe the material scope, business purpose, or maintenance notes.+- **Embedding model**: The model used to vectorize chunks. Changing the embedding model after content has already been parsed usually affects the index and should be handled carefully.+- **PageRank**: Sets the dataset's PageRank score. During retrieval, this score is added to the hybrid similarity score of matched chunks in the dataset, increasing their ranking weight. This is suitable when content from a specific dataset needs higher priority during retrieval across multiple datasets.+- **Tag sets**: Used to associate one or more tag sets with a dataset and add tags to chunks in bulk based on text similarity. During retrieval, queries are also automatically associated with corresponding tags, improving retrieval accuracy with tag information. A tag set must be generated as a sample before use.++## Parsing Method++The parsing method determines how a dataset processes uploaded documents and how documents are converted into chunks. **Parse type** in configuration provides two entries: **Built-in** and **Pipeline**.++### Built-in Parsing++**Built-in** means using RAGFlow's built-in document parsing capabilities. Users can choose a suitable parsing method based on the document type. The system then reads document content, splits it into chunks, and generates the structure required for retrieval according to the selected method.++The following built-in parsing methods are available:++- **General**: A general-purpose parsing method suitable for most conventional documents. It identifies document content and creates chunks according to the configured chunking rules.+- **Q&A**: Designed for data organized as question-answer pairs. Each Q&A pair is treated as an individual chunk.+- **Manual**: Designed for PDFs with a clear hierarchical section structure, such as product manuals and operation guides. Documents are chunked based on their section structure.+- **Table**: Designed for structured tabular data such as XLSX and CSV/TXT files. Each row is typically treated as an individual chunk.+- **Paper**: Designed for PDF papers, research reports, and other academic documents. Documents are chunked based on structural elements such as abstracts, sections, and subsections.+- **Book**: Designed for DOCX, PDF, and TXT books or other long documents with a chapter-based structure.+- **Laws**: Designed for legal documents in DOCX, PDF, and TXT formats. Chunk boundaries are identified based on the structural characteristics of legal documents.+- **Presentation**: Designed for presentations in PDF and PPTX formats. Each page or slide is typically treated as an individual chunk.+- **One**: Treats the entire document as a single chunk. This method is suitable for relatively short documents when the complete context needs to be preserved.+- **Tag**: Used to create a tag set. A dataset using this method provides tags for chunks and queries in other datasets and does not directly participate in the RAG retrieval process.++> **Tip:** On the built-in parsing configuration page, click **Built-in pipeline introduction** on the right to view the supported file formats, detailed chunking rules, and examples for each parsing method.++Selection suggestion: choose the parsing method based on the form of the material itself. Use **General** first for regular documents; use **Table** first for tabular materials; choose the corresponding method for Q&A collections, manuals, papers, images, audio, and emails to reduce later chunk adjustment costs.++### Chunk and Parsing Configuration++After selecting a **Built-in** parsing method, you can further configure document parsing, chunk splitting, and content enhancement parameters. Reasonable configuration helps improve the accuracy and recall of later retrieval.++Different built-in methods display different configuration items. Use the current interface as the source of truth.++#### Document Parsing Configuration++- **PDF parser**: Specifies the parser used when parsing PDF documents. Different parsers differ in text recognition, table structure recognition, layout analysis, processing speed, and other aspects. Choose one based on the content type and parsing requirements of the PDF. The system provides the following PDF parsers by default:+ - **DeepDoc**: The default PDF parser in RAGFlow. It can perform OCR, table structure recognition (TSR), document layout understanding (DLR), and other tasks. It is suitable for PDFs that contain complex layouts, images, scanned content, or tables. Because additional document analysis is required, parsing may take relatively longer.+ - **Naive**: Suitable for PDFs mainly composed of plain text. This method skips OCR, TSR, DLR, and other processing, reducing unnecessary parsing overhead. If a PDF contains scanned pages, complex layouts, or tables, this method is not recommended.+ - **Docling**: An open-source document processing tool that can parse documents such as PDFs and extract structured content.+ - **TCADPParser**: Tencent's open-source document parsing tool, which can be used for PDF content parsing.++In addition to the built-in parsers above, you can also use a vision-language model (VLM) that supports PDF parsing. To use a third-party vision model to parse PDFs, first configure the default VLM under **Model Providers > Set default model**. After configuration, select the corresponding model from the **PDF parser** drop-down list.++Usually, some vision models whose names contain identifiers such as **VL** or **V** support PDF parsing. For documents with complex layouts or mixed text and images, a more capable vision model may produce better parsing results, but it also incurs additional model calls and token consumption. The specific support and parsing effect depend on the model used.++#### Chunk Splitting Configuration++The following configurations are mainly used for built-in methods that need to split text according to specified rules, such as **General**.++- **Recommended chunk size**: Sets the recommended target size when generating chunks. Smaller chunks can provide more fine-grained retrieval results but may lack context. Larger chunks can preserve more context, but retrieval result granularity is relatively coarse.+- **Delimiter for text**: Sets the delimiter used for text splitting. The system splits text based on the delimiter and chunk size. It is recommended to set an appropriate delimiter based on the original paragraph and line-break structure to preserve semantic completeness as much as possible.+- **Overlapped percent (%)**: Sets the content overlap ratio between adjacent chunks. Increasing overlap appropriately can reduce context loss caused by split boundaries, but an overly high overlap ratio increases repeated content.+- **Child chunk are used for retrieval**: Controls whether finer-grained child chunks participate in retrieval. This is suitable for long documents where fine-grained recall needs to be improved.++#### Page and Multimodal Content Configuration++- **Page Index**: Controls whether Page Index-related capabilities are used to process document page information.+- **Image & table context window**: Sets the context range between images or tables and surrounding text. Increasing this value appropriately can preserve more related context when processing images or tables.++#### Content Enhancement Configuration++Some built-in methods provide the following content enhancement configurations, such as **General**, **Manual**, **Paper**, **Book**, and **Laws**.++- **Auto metadata**: Controls whether metadata is generated automatically. After it is enabled, the generation method for metadata can be further configured through **Settings**.+- **Auto-keyword**: Sets the number of keywords automatically generated for chunks to supplement chunk semantic information.+- **Auto-question**: Sets the number of questions automatically generated based on chunk content to supplement query expressions that may match the current chunk.++#### Table Parsing Configuration++When **Table** is selected, the interface provides a dedicated **Column mode** configuration used to control how table columns participate in generating chunk content and metadata.++- **Auto**: The system processes table columns according to the default rules. By default, all columns are included in the chunk text and are also saved as metadata.+- **Manual**: Manually configures the table columns that need to participate in processing. This configuration mainly targets structured table data and differs from chunk splitting configuration for ordinary text-based built-in methods.++#### Other Format Processing Configuration++Some built-in methods may also provide configuration for specific file formats, for example:++- **Excel to HTML**: Controls whether Excel content is converted into HTML for processing, preserving table structure information.++Different built-in methods use different parsing logic, so not all configuration items appear at the same time. After selecting a built-in method, configure only the parameters displayed in the current interface. In general, for ordinary text documents, focus on chunk splitting parameters such as **Recommended chunk size**, **Delimiter for text**, and **Overlapped percent (%)**. For PDFs, papers, books, manuals, or legal documents, focus on **PDF parser** and the corresponding content enhancement configuration. For table data, focus on **Column mode**. When you need to further enrich retrieval information, use content enhancement features such as **Auto metadata**, **Auto-keyword**, and **Auto-question** according to actual requirements.++After configuration is complete, click **Save** to save the settings. When documents are parsed later, the system processes them according to the currently selected built-in method and its configuration.++### Pipeline: Custom Parsing++**Pipeline** means using a custom **Ingestion Pipeline** as the dataset's parsing method. It is suitable for scenarios that require custom document processing logic or complex processing flows.++The pipeline must be created and configured in **Agent > Ingestion Pipeline** in advance. In the dataset, you do not need to configure the processing nodes inside the pipeline again. You only need to select the created pipeline.++Usage:++1. Create and configure an **Ingestion Pipeline** in **Agent > Pipeline**.+2. Go to **Dataset > Configuration** and select **Pipeline** as the parsing method.+3. Select the pipeline to use from the pipeline list.+4. Save the configuration. Afterward, documents in the dataset are processed according to the selected pipeline.++If no pipeline is currently available, you can use the entry provided in the pipeline area to go to **Agent** and create one.++> Note: For pipeline creation, node configuration, and flow orchestration, see **Agent > Pipeline**.++### Auto Metadata: Automatic Metadata Configuration++**Auto Metadata** is used to configure metadata automatically generated during document parsing. The system supports two types of metadata: **Generation** and **Built-in**. You can configure them separately as needed.++> Note: Changes in **Metadata generation settings** only take effect for newly parsed documents later. They do not automatically update documents that have already completed parsing. To apply the new configuration to existing documents, parse the relevant documents again.++#### Generation: Custom Metadata Generation++**Generation** is used to customize metadata fields that need to be generated from document content. Click **Add** to add a field and configure the following items as needed:++- **Field**: The metadata field name.+- **Description**: The field description, used to explain the information to extract or generate from the document.+- **Type**: The field's data type.+- **Values**: The allowed values for the field, used to restrict the generated result's value range.++After saving, the system generates corresponding metadata from document content during subsequent document parsing based on these field definitions.++#### Built-in: Built-in Metadata++**Built-in** provides system-predefined metadata fields. You do not need to manually create or configure field rules. Use the switch on the right side of each corresponding field to choose whether to generate that metadata during document parsing. The following built-in fields are currently supported:++- **update_time**: Records the document update time.+- **file_name**: Records the document file name.++Select the fields to use, enable their switches, and then click **Save** to save the configuration. Generated metadata can be used in document management and retrieval filtering. To view or edit generated metadata, see **Metadata Management**.++### Table Column Role Configuration++When a dataset uses **Table** as the built-in parsing method, you can use **Column mode** to set the purpose of each table column during parsing and retrieval. A column can be included in chunk text for indexing, used only as metadata, or used for both.++#### Auto++When **Auto** is selected, all columns are included in chunk text and are also stored as metadata. This is RAGFlow's default setting. This mode is suitable when you do not need to distinguish the purpose of each column and want all table content to participate in retrieval and also be available as metadata.++#### Manual++When **Manual** is selected, RAGFlow identifies columns in the table and displays them one by one according to the original table column names. For example, **CRIM**, **ZN**, **INDUS**, **CHAS**, and similar names in the interface come from the column names in the current table. They are not predefined RAGFlow fields.++Users can assign one of the following roles to each column through the drop-down menu on the right side of each column name:++- **Indexing**: Includes the column content in chunk text for vector retrieval and full-text retrieval. This is suitable for columns that contain the main retrieval content.+- **Metadata**: Saves the column only as metadata and does not include it in chunk text. This column can be used as a filter field to narrow the retrieval scope.+- **Both**: Uses the column for both indexing and metadata. The column is included in chunk text and participates in vector retrieval and full-text retrieval, and can also be used as metadata for filtering.++For example, if a table contains four columns, **Title**, **Content**, **Category**, and **Year**, you can set them according to actual use:++- **Title -> Both**: The title participates in retrieval and can also be used as metadata.+- **Content -> Indexing**: The body text is mainly used for content retrieval.+- **Category -> Metadata**: Used to filter retrieval results by category.+- **Year -> Metadata**: Used to filter retrieval results by year.++In this way, fields that do not need to participate in content retrieval can be prevented from entering chunk text, while these fields are still preserved as retrieval filter conditions.++> Note: Column role configuration applies to the column structure of a table, not to individual cells. After configuration is modified, the new settings apply to subsequently parsed documents. For documents that have already completed parsing, the documents must be parsed again before the new column roles take effect.++### Associated Data Sources++The **Data source** area is used to associate the current dataset with data sources that have already been added.++Click **Link data source** and select the data source to associate from existing data sources. After association, the current dataset can use the data provided by that data source. This area is only used to establish and manage the association between the dataset and data sources. It does not provide data source creation or connection configuration.++> Tip: To add a new data source, or configure data source connection information, synchronization methods, and other settings, see the data source-related chapters. After adding the data source, return to the dataset configuration page to associate it.diff --git a/docs/guides/dataset/configure_child_chunking_strategy.md b/docs/guides/dataset/configure_child_chunking_strategy.mddeleted file mode 100644index 81ec4c2206..0000000000--- a/docs/guides/dataset/configure_child_chunking_strategy.md+++ /dev/null@@ -1,38 +0,0 @@-----sidebar_position: -4-title: Configure Child Chunking Strategy-sidebar_label: Configure Child Chunking Strategy-slug: /configure_child_chunking_strategy-sidebar_custom_props: {- categoryIcon: LucideGroup-}-----# Configure Child Chunking Strategy--Set parent-child chunking strategy to improve retrieval.-------A persistent challenge in practical RAG applications lies in a structural tension within the traditional "chunk-embed-retrieve" pipeline: a single text chunk is tasked with both semantic matching (recall) and contextual understanding (utilization)—two inherently conflicting objectives. Recall demands fine-grained, precise chunks, while answer generation requires coherent, informationally complete context.--To resolve this tension, RAGFlow previously introduced the Table of Contents (TOC) enhancement feature, which uses a large language model (LLM) to generate document structure and automatically supplements missing context during retrieval based on that TOC. In version 0.23.0, this capability has been systematically integrated into the Ingestion Pipeline, and a novel parent-child chunking mechanism has been introduced.--Under this mechanism, a document is first segmented into larger parent chunks, each maintaining a relatively complete semantic unit to ensure logical and background integrity. Each parent chunk can then be further subdivided into multiple child chunks for precise recall. During retrieval, the system first locates the most relevant text segments based on the child chunks while automatically associating and recalling their parent chunk. This approach maintains high recall relevance while providing ample semantic background for the generation phase.--For instance, when processing a *Compliance Handbook*, a user query about "liability for breach" might precisely retrieve a child chunk stating, "The penalty for breach is 20% of the total contract value," but without context, it cannot clarify whether this clause applies to "minor breach" or "material breach." Leveraging the parent-child chunking mechanism, the system returns this child chunk along with its parent chunk, which contains the complete section of the clause. This allows the LLM to make accurate judgments based on broader context, avoiding misinterpretation.--Through this dual-layer structure of "precise localization + contextual supplementation," RAGFlow ensures retrieval accuracy while significantly enhancing the reliability and completeness of generated answers.---## Procedure--1. On your dataset's **Configuration** page, find the **Child chunk are used for retrieval** toggle:--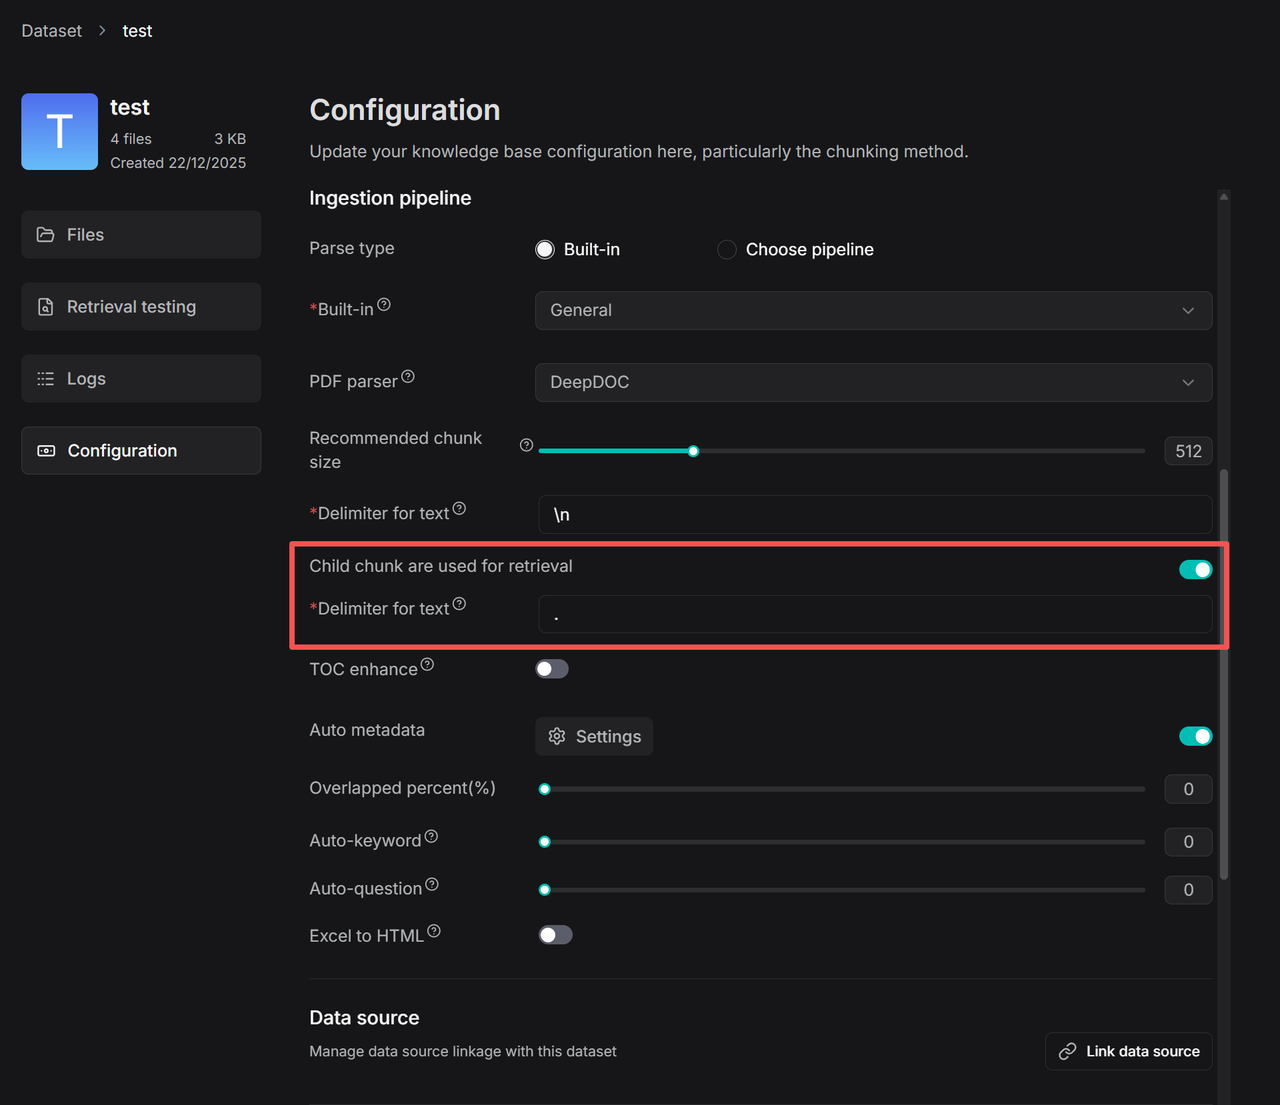---2. Set the delimiter for child chunks.--3. This configuration applies to the **Chunker** component when it comes to ingestion pipeline settings:--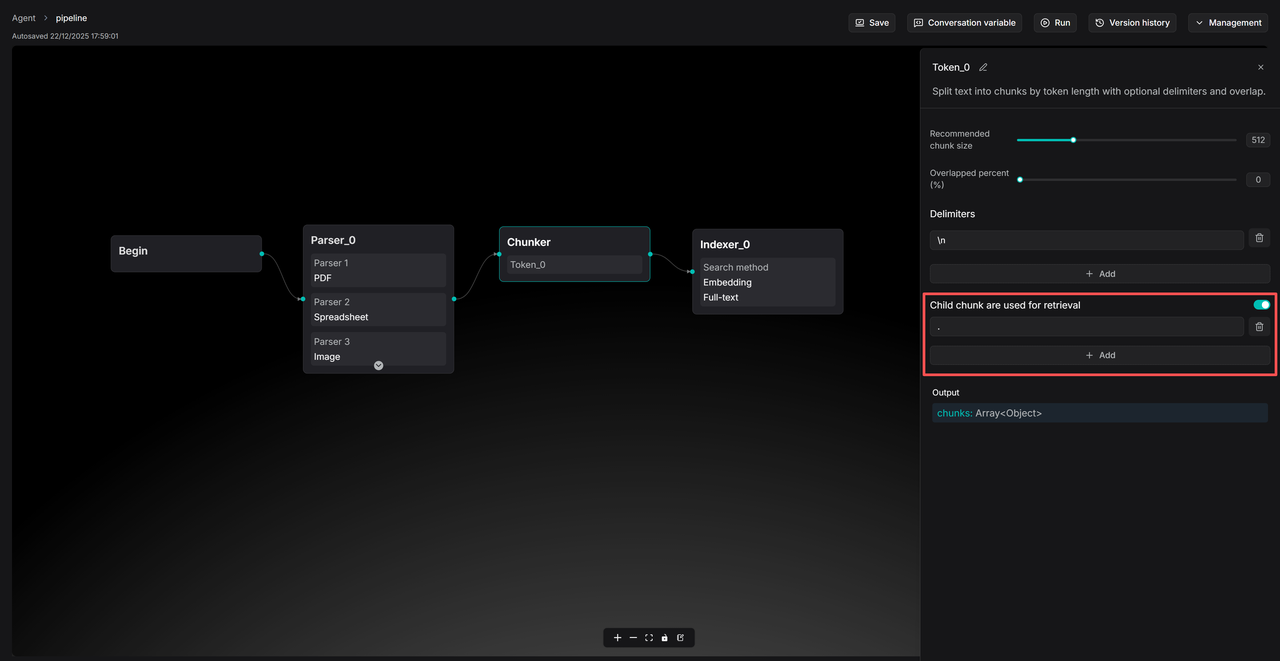diff --git a/docs/guides/dataset/configure_knowledge_base.md b/docs/guides/dataset/configure_knowledge_base.mddeleted file mode 100644index cac1835474..0000000000--- a/docs/guides/dataset/configure_knowledge_base.md+++ /dev/null@@ -1,151 +0,0 @@-----sidebar_position: -10-title: Configure Dataset-sidebar_label: Configure Dataset-slug: /configure_knowledge_base-sidebar_custom_props: {- categoryIcon: LucideCog-}-----# Configure Dataset--Most of RAGFlow's chat assistants and Agents are based on datasets. Each of RAGFlow's datasets serves as a knowledge source, *parsing* files uploaded from your local machine and file references generated in RAGFlow's File system into the real 'knowledge' for future AI chats. This guide demonstrates some basic usages of the dataset feature, covering the following topics:--- Create a dataset-- Configure a dataset-- Search for a dataset-- Delete a dataset--## Create Dataset--With multiple datasets, you can build more flexible, diversified question answering. To create your first dataset:--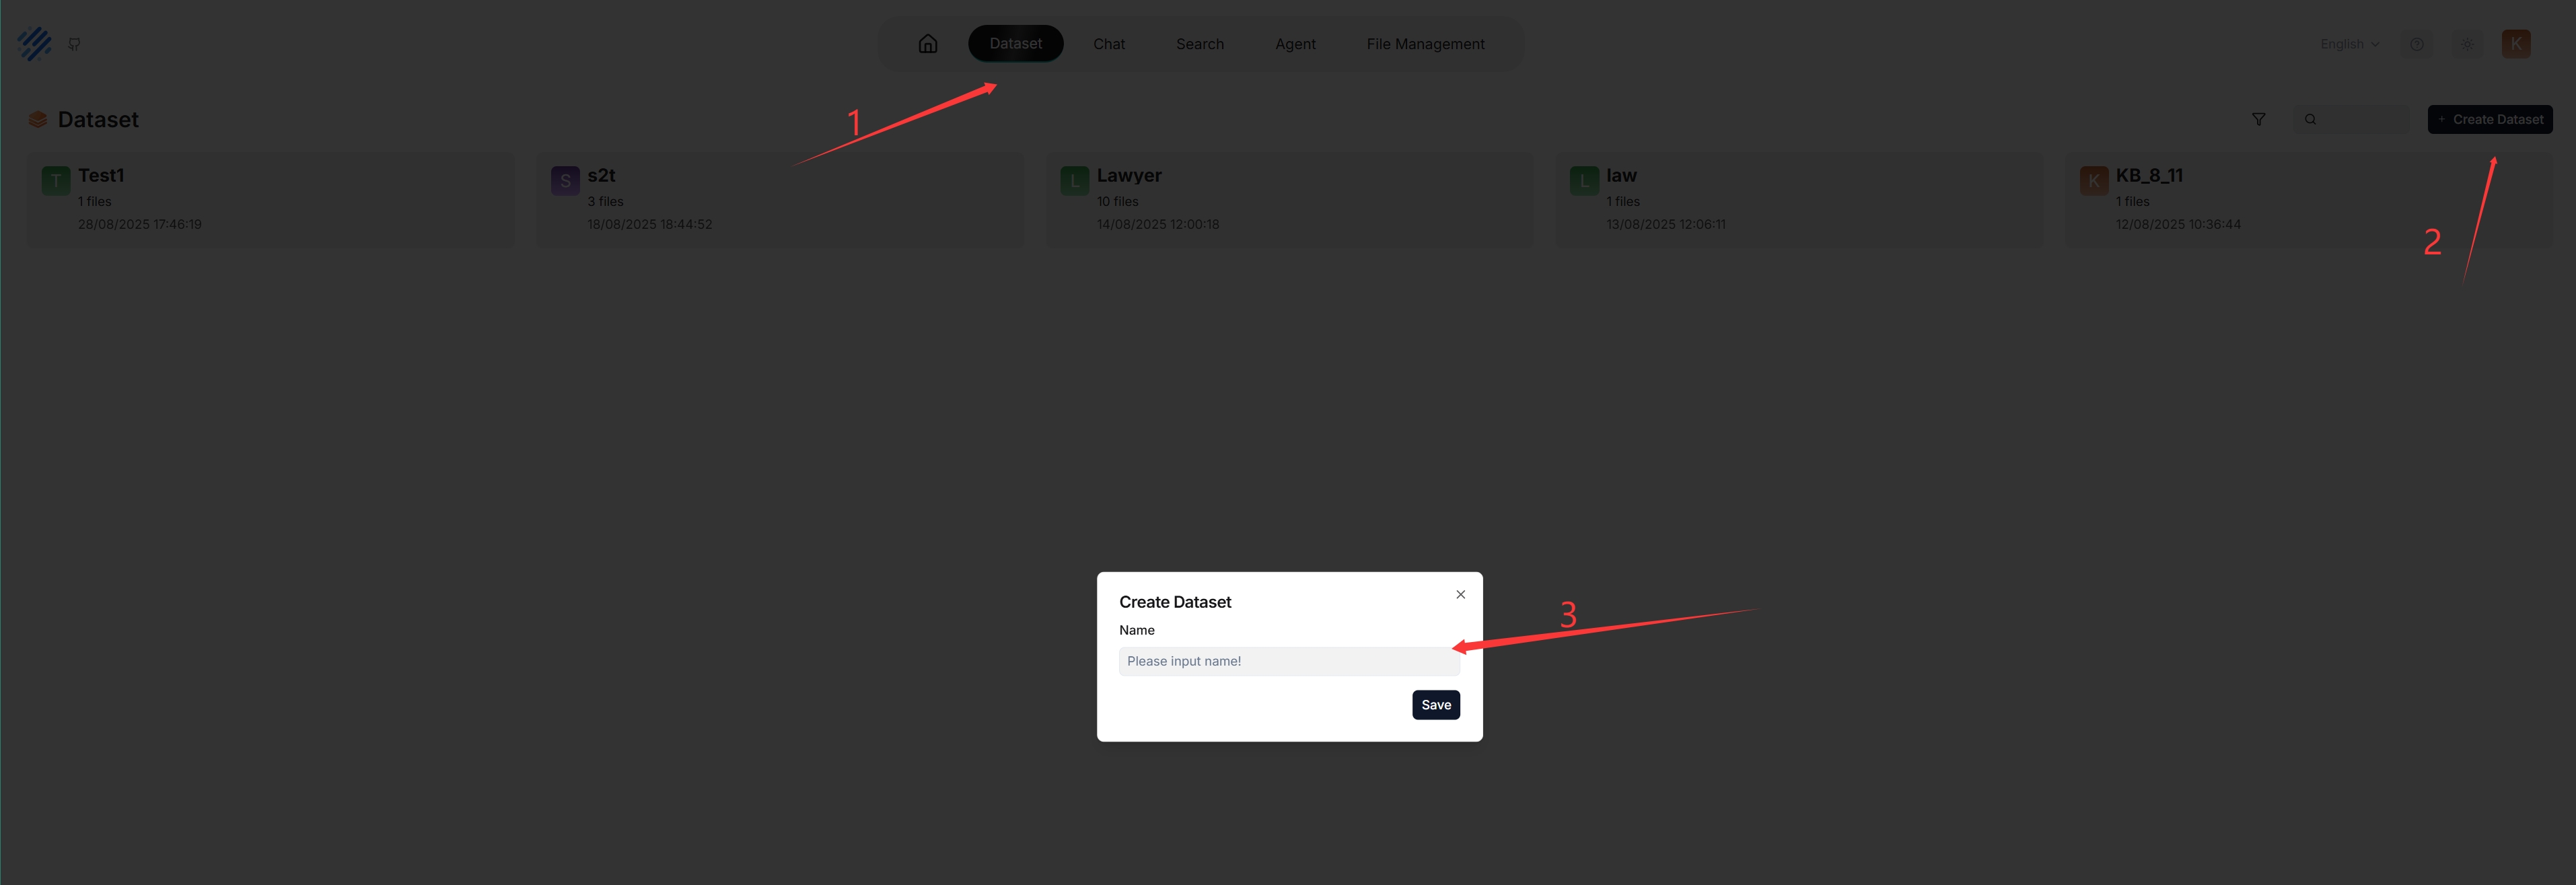--_Each time a dataset is created and a file is uploaded to it, a folder with the same name is generated in the **root/.knowledgebase** directory._--## Configure Dataset--The following screenshot shows the configuration page of a dataset. A proper configuration of your dataset is crucial for future AI chats. For example, choosing the wrong embedding model or chunking method would cause unexpected semantic loss or mismatched answers in chats.--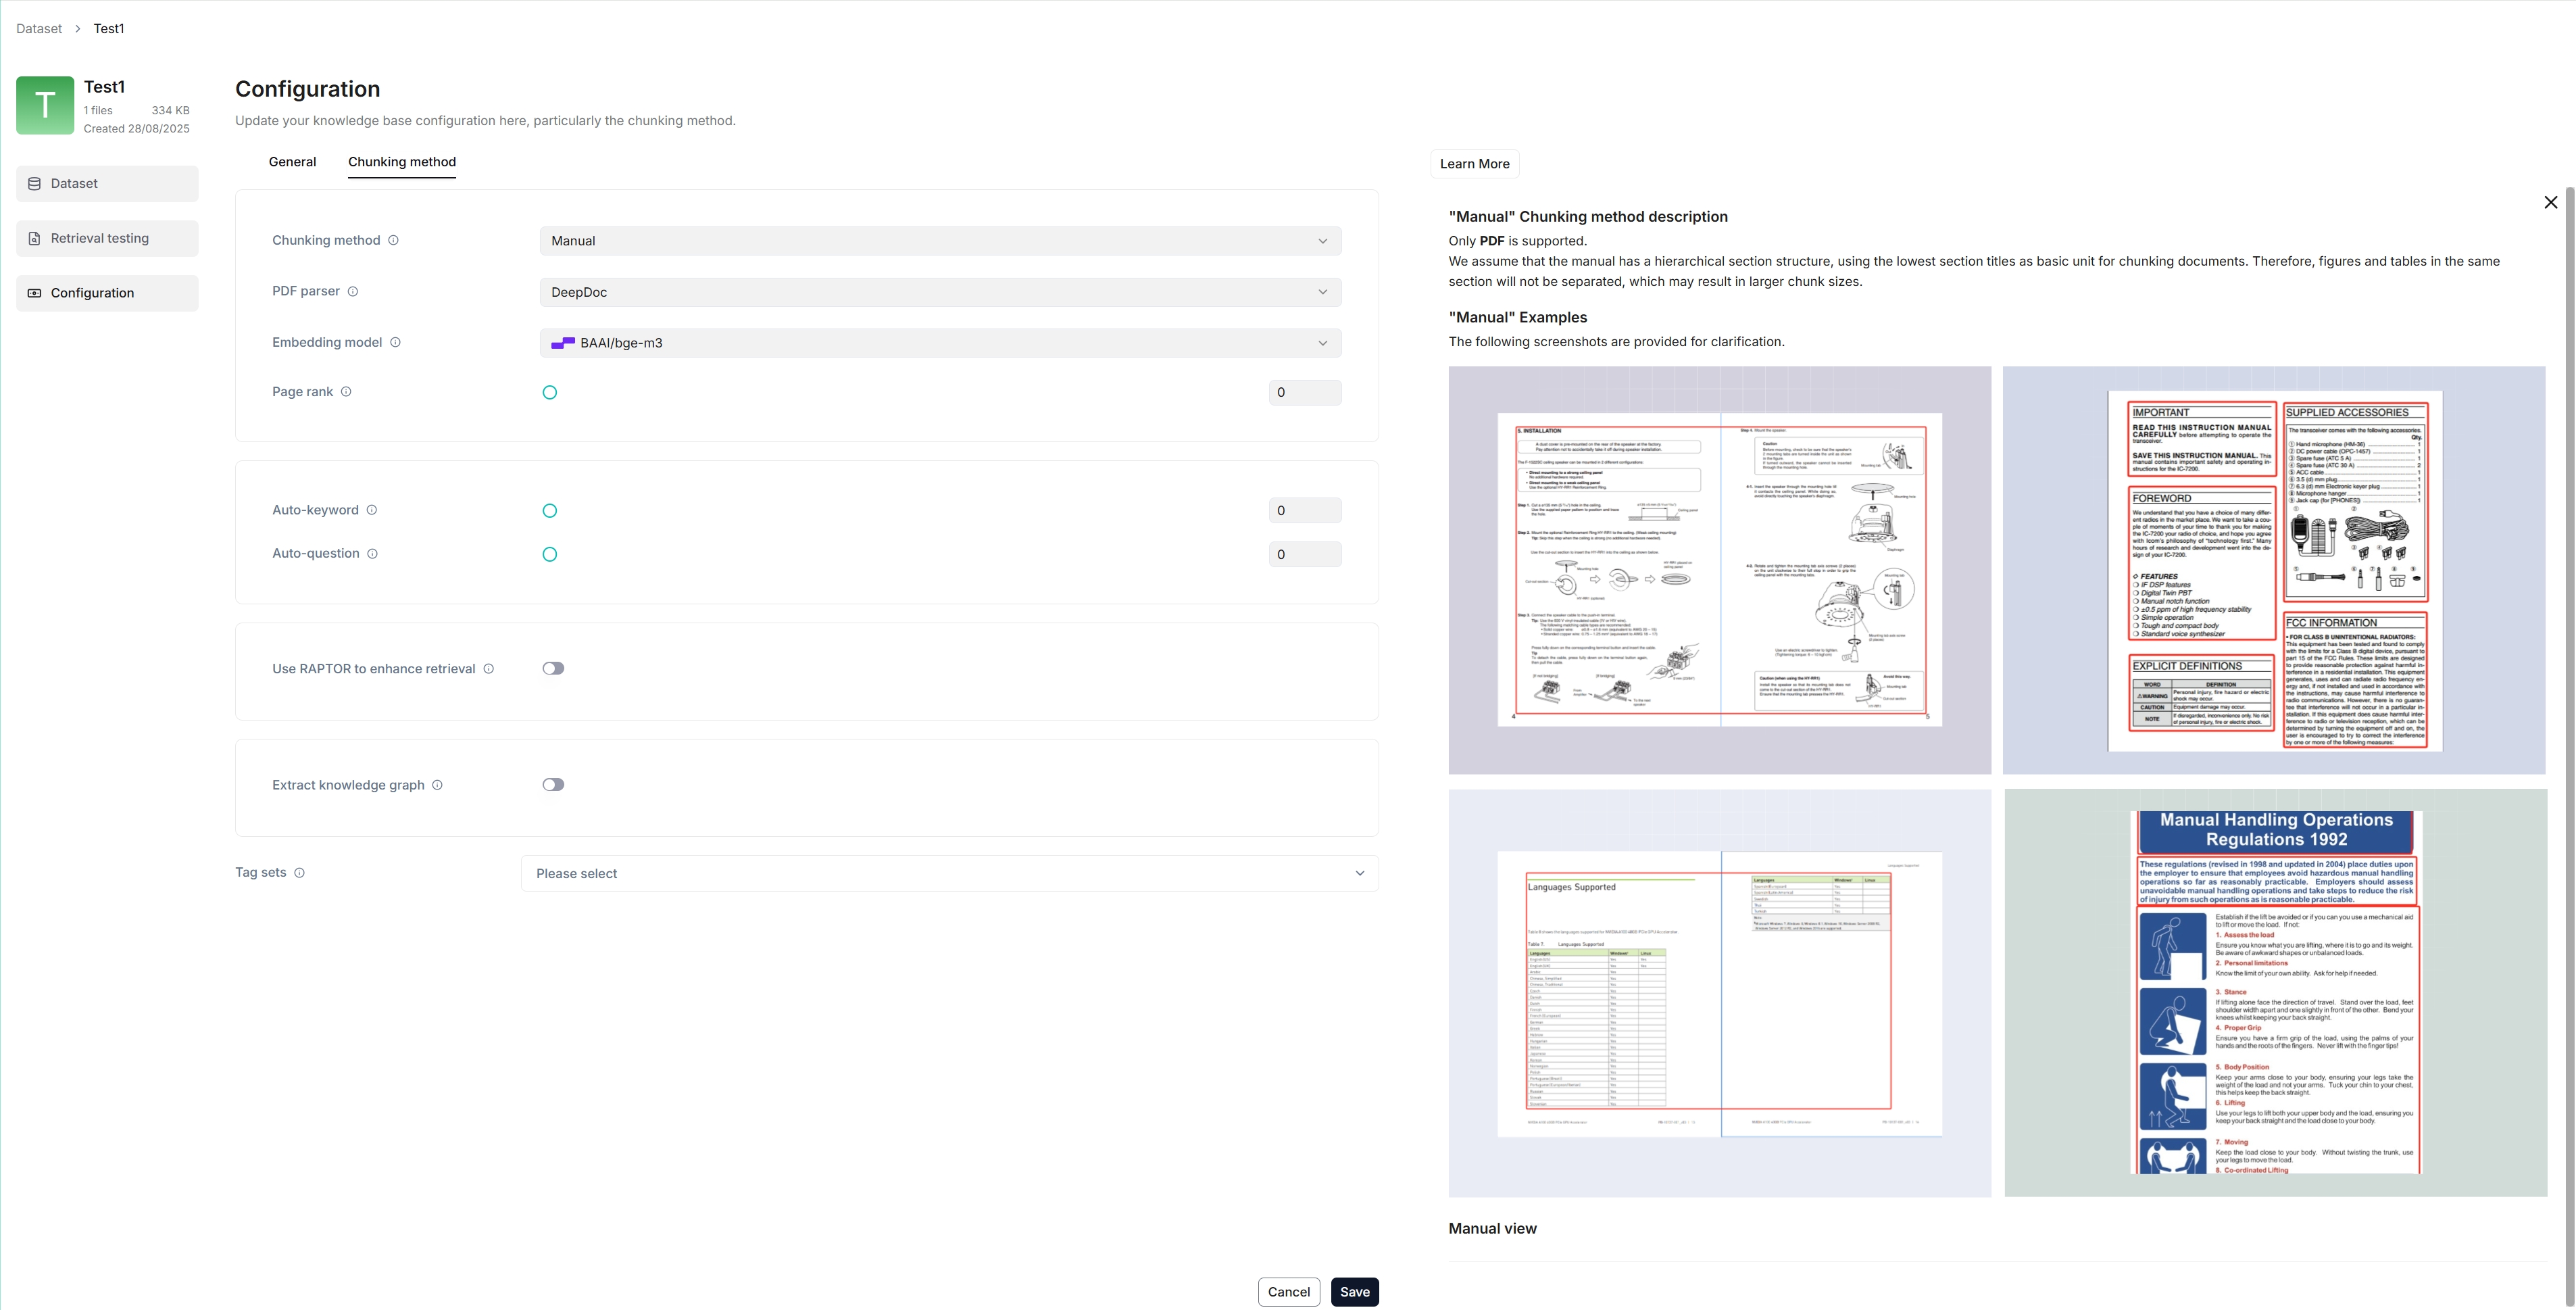--This section covers the following topics:--- Select chunking method-- Select embedding model-- Upload file-- Parse file-- Intervene with file parsing results-- Run retrieval testing--### Select Chunking Method--RAGFlow offers multiple built-in chunking template to facilitate chunking files of different layouts and ensure semantic integrity. From the **Built-in** chunking method dropdown under **Parse type**, you can choose the default template that suits the layouts and formats of your files. The following table shows the descriptions and the compatible file formats of each supported chunk template:--| **Template** | Description | File format |-|--------------|-------------------------------------------------------------------------------|---------------------------------------------------------------------------------------------------------|-| General | Files are consecutively chunked based on a preset chunk token number. | MD, MDX, DOCX, XLSX, XLS (Excel 97-2003), PPT, PDF, TXT, JPEG, JPG, PNG, TIF, GIF, CSV, JSON, EML, HTML |-| Q&A | Retrieves relevant information and generates answers to respond to questions. | XLSX, XLS (Excel 97-2003), CSV/TXT |-| Resume | Enterprise edition only. You can also try it out on cloud.ragflow.io. | DOCX, PDF, TXT |-| Manual | | PDF |-| Table | The table mode uses TSI technology for efficient data parsing. | XLSX, XLS (Excel 97-2003), CSV/TXT |-| Paper | | PDF |-| Book | | DOCX, PDF, TXT |-| Laws | | DOCX, PDF, TXT |-| Presentation | | PDF, PPTX |-| Picture | | JPEG, JPG, PNG, TIF, GIF |-| One | Each document is chunked in its entirety (as one). | DOCX, XLSX, XLS (Excel 97-2003), PDF, TXT |-| Tag | The dataset functions as a tag set for the others. | XLSX, CSV/TXT |--You can also change a file's chunking method on the **Files** page.--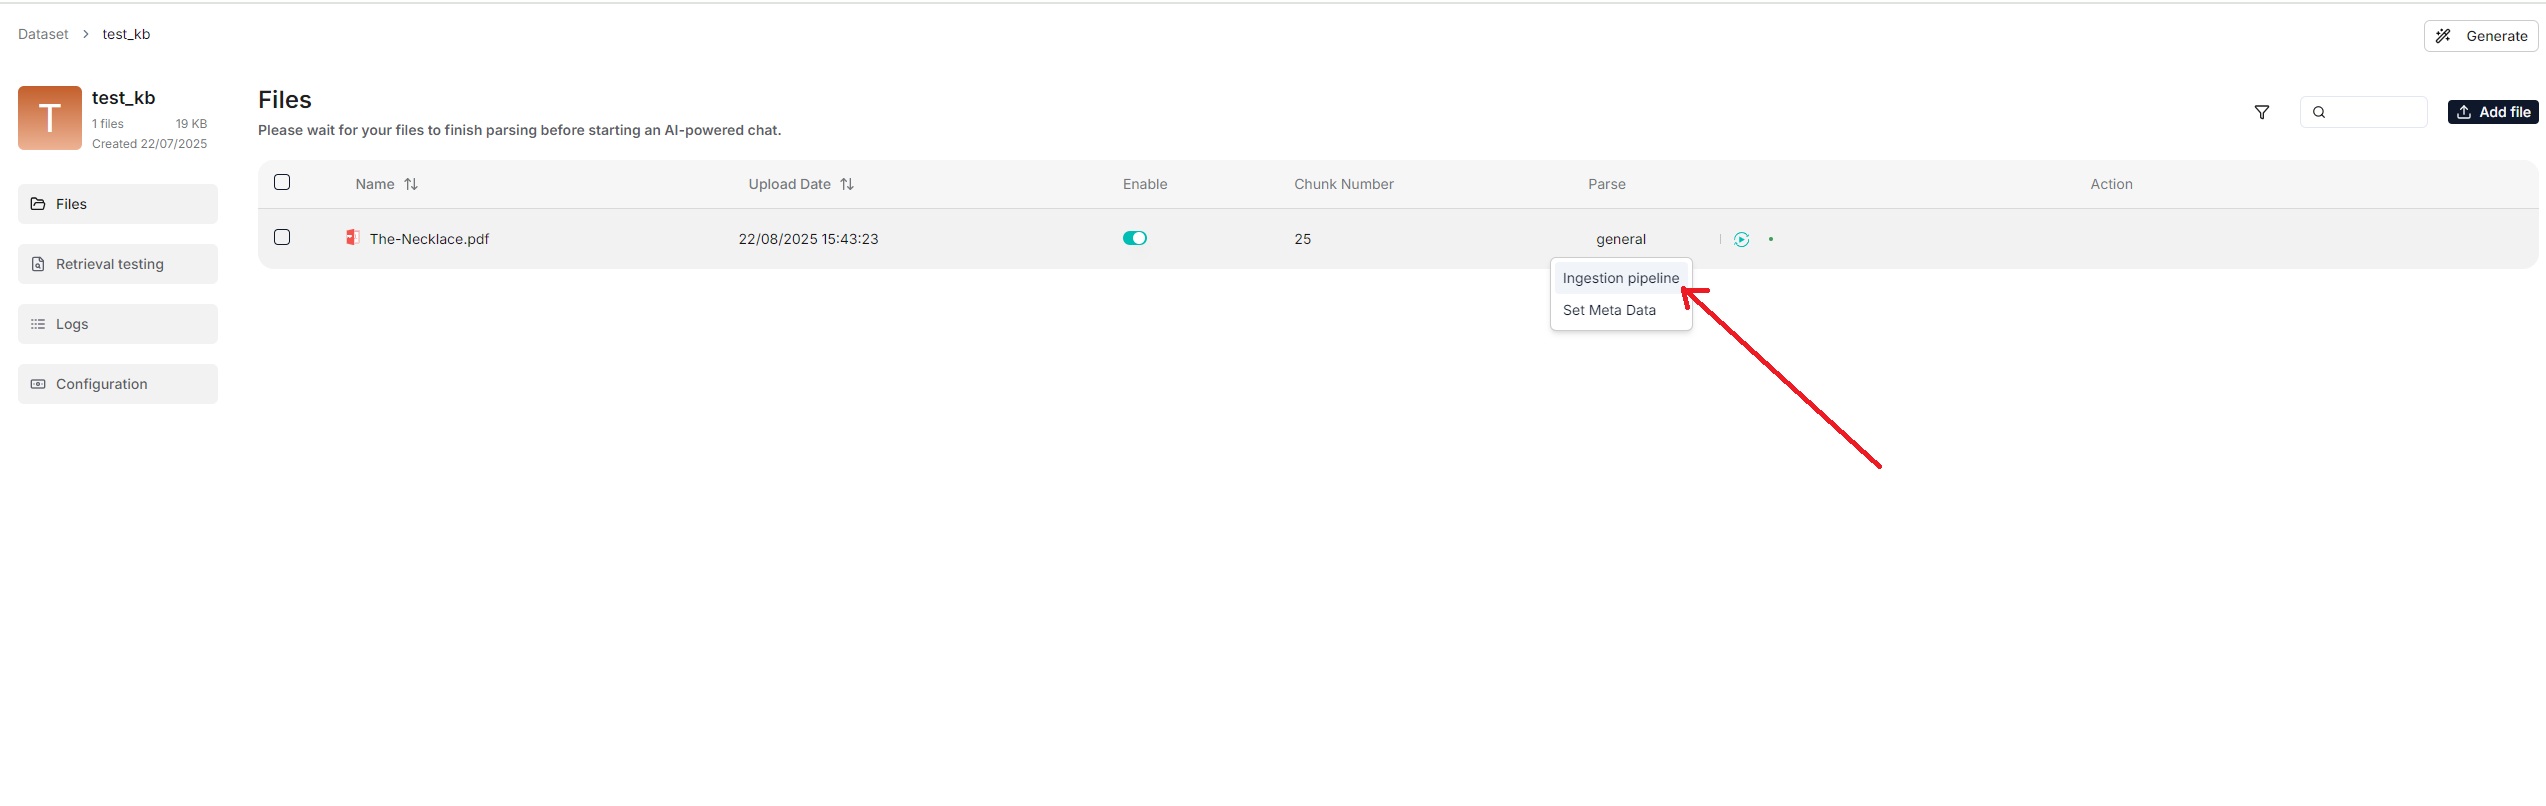--<details>- <summary>From v0.21.0 onward, RAGFlow supports ingestion pipeline for customized data ingestion and cleansing workflows.</summary>-- To use a customized data pipeline:-- 1. On the **Agent** page, click **+ Create agent** > **Create from blank**.- 2. Select **Ingestion pipeline** and name your data pipeline in the popup, then click **Save** to show the data pipeline canvas.- 3. After updating your data pipeline, click **Save** on the top right of the canvas.- 4. Navigate to the **Configuration** page of your dataset, select **Choose pipeline** in **Ingestion pipeline**.-- *Your saved data pipeline will appear in the dropdown menu below.*--</details>--### Select Embedding Model--An embedding model converts chunks into embeddings. It cannot be changed once the dataset has chunks. To switch to a different embedding model, you must delete all existing chunks in the dataset. The obvious reason is that we *must* ensure that files in a specific dataset are converted to embeddings using the *same* embedding model (ensure that they are compared in the same embedding space).--:::danger IMPORTANT-Some embedding models are optimized for specific languages, so performance may be compromised if you use them to embed documents in other languages.-:::--### Upload File--- RAGFlow's File system allows you to link a file to multiple datasets, in which case each target dataset holds a reference to the file.-- In **Knowledge Base**, you are also given the option of uploading a single file or a folder of files (bulk upload) from your local machine to a dataset, in which case the dataset holds file copies.--While uploading files directly to a dataset seems more convenient, we *highly* recommend uploading files to RAGFlow's File system and then linking them to the target datasets. This way, you can avoid permanently deleting files uploaded to the dataset.--### Parse File--File parsing is a crucial topic in dataset configuration. The meaning of file parsing in RAGFlow is twofold: chunking files based on file layout and building embedding and full-text (keyword) indexes on these chunks. After having selected the chunking method and embedding model, you can start parsing a file:--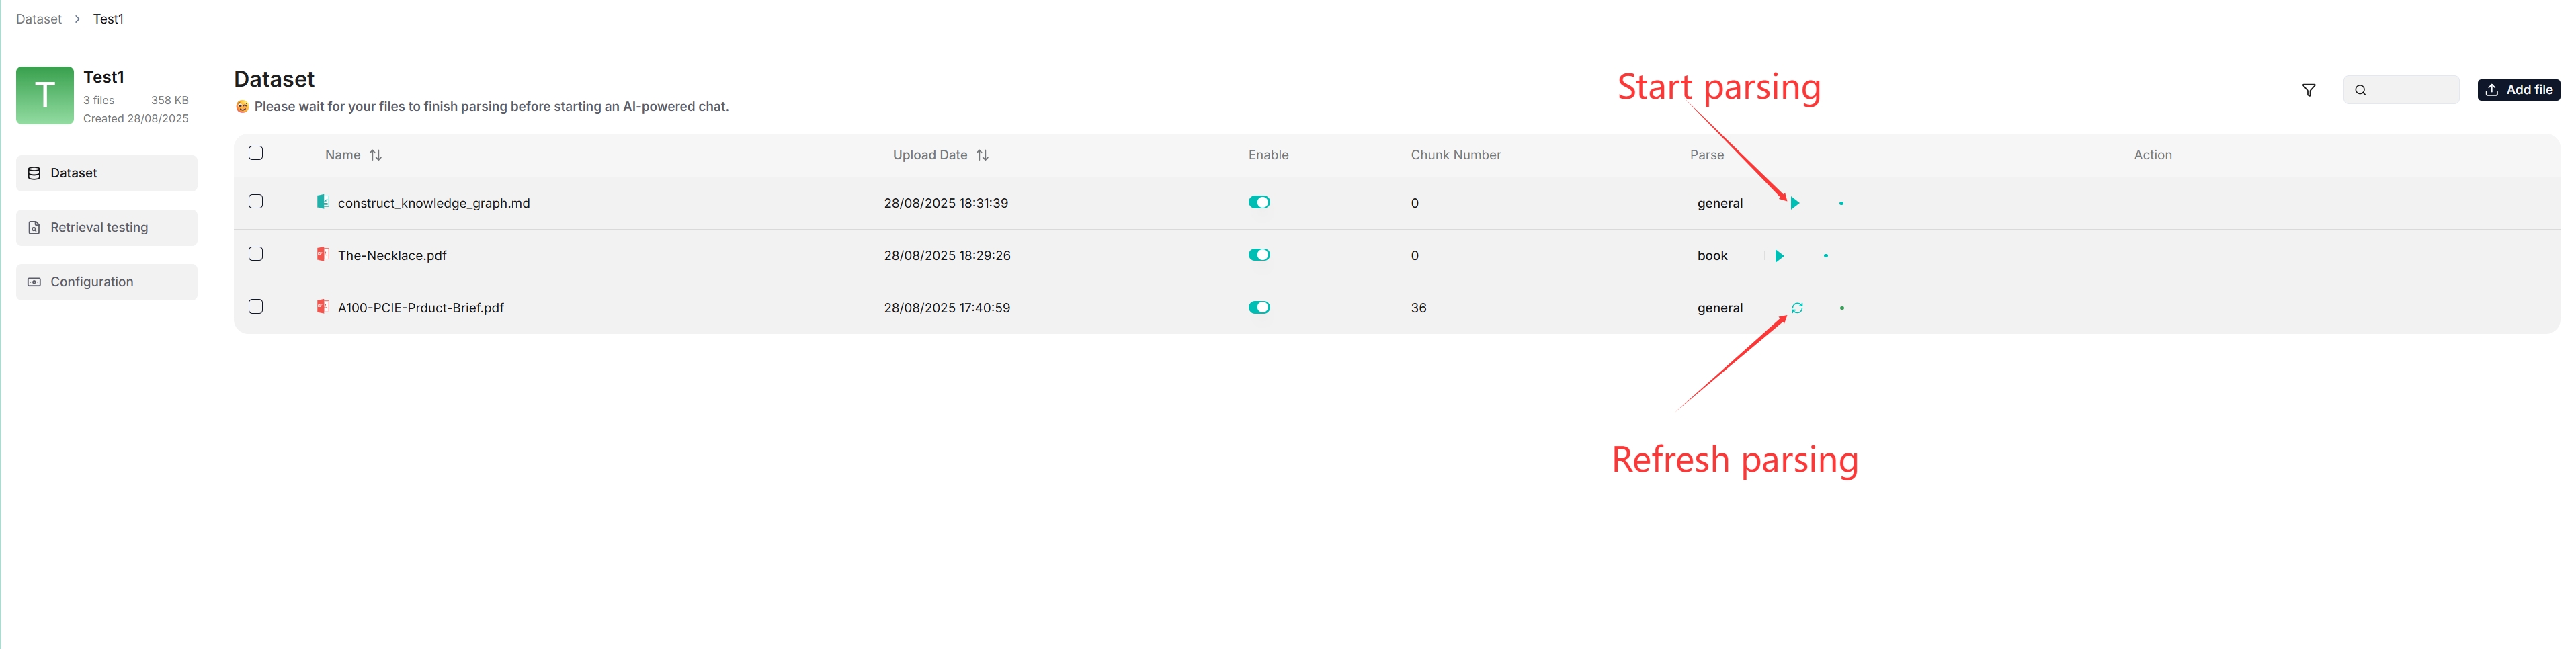--- As shown above, RAGFlow allows you to use a different chunking method for a particular file, offering flexibility beyond the default method.-- As shown above, RAGFlow allows you to enable or disable individual files, offering finer control over dataset-based AI chats.--### Intervene with File Parsing Results--RAGFlow features visibility and explainability, allowing you to view the chunking results and intervene where necessary. To do so:--1. Click on the file that completes file parsing to view the chunking results:-- _You are taken to the **Chunk** page:_-- 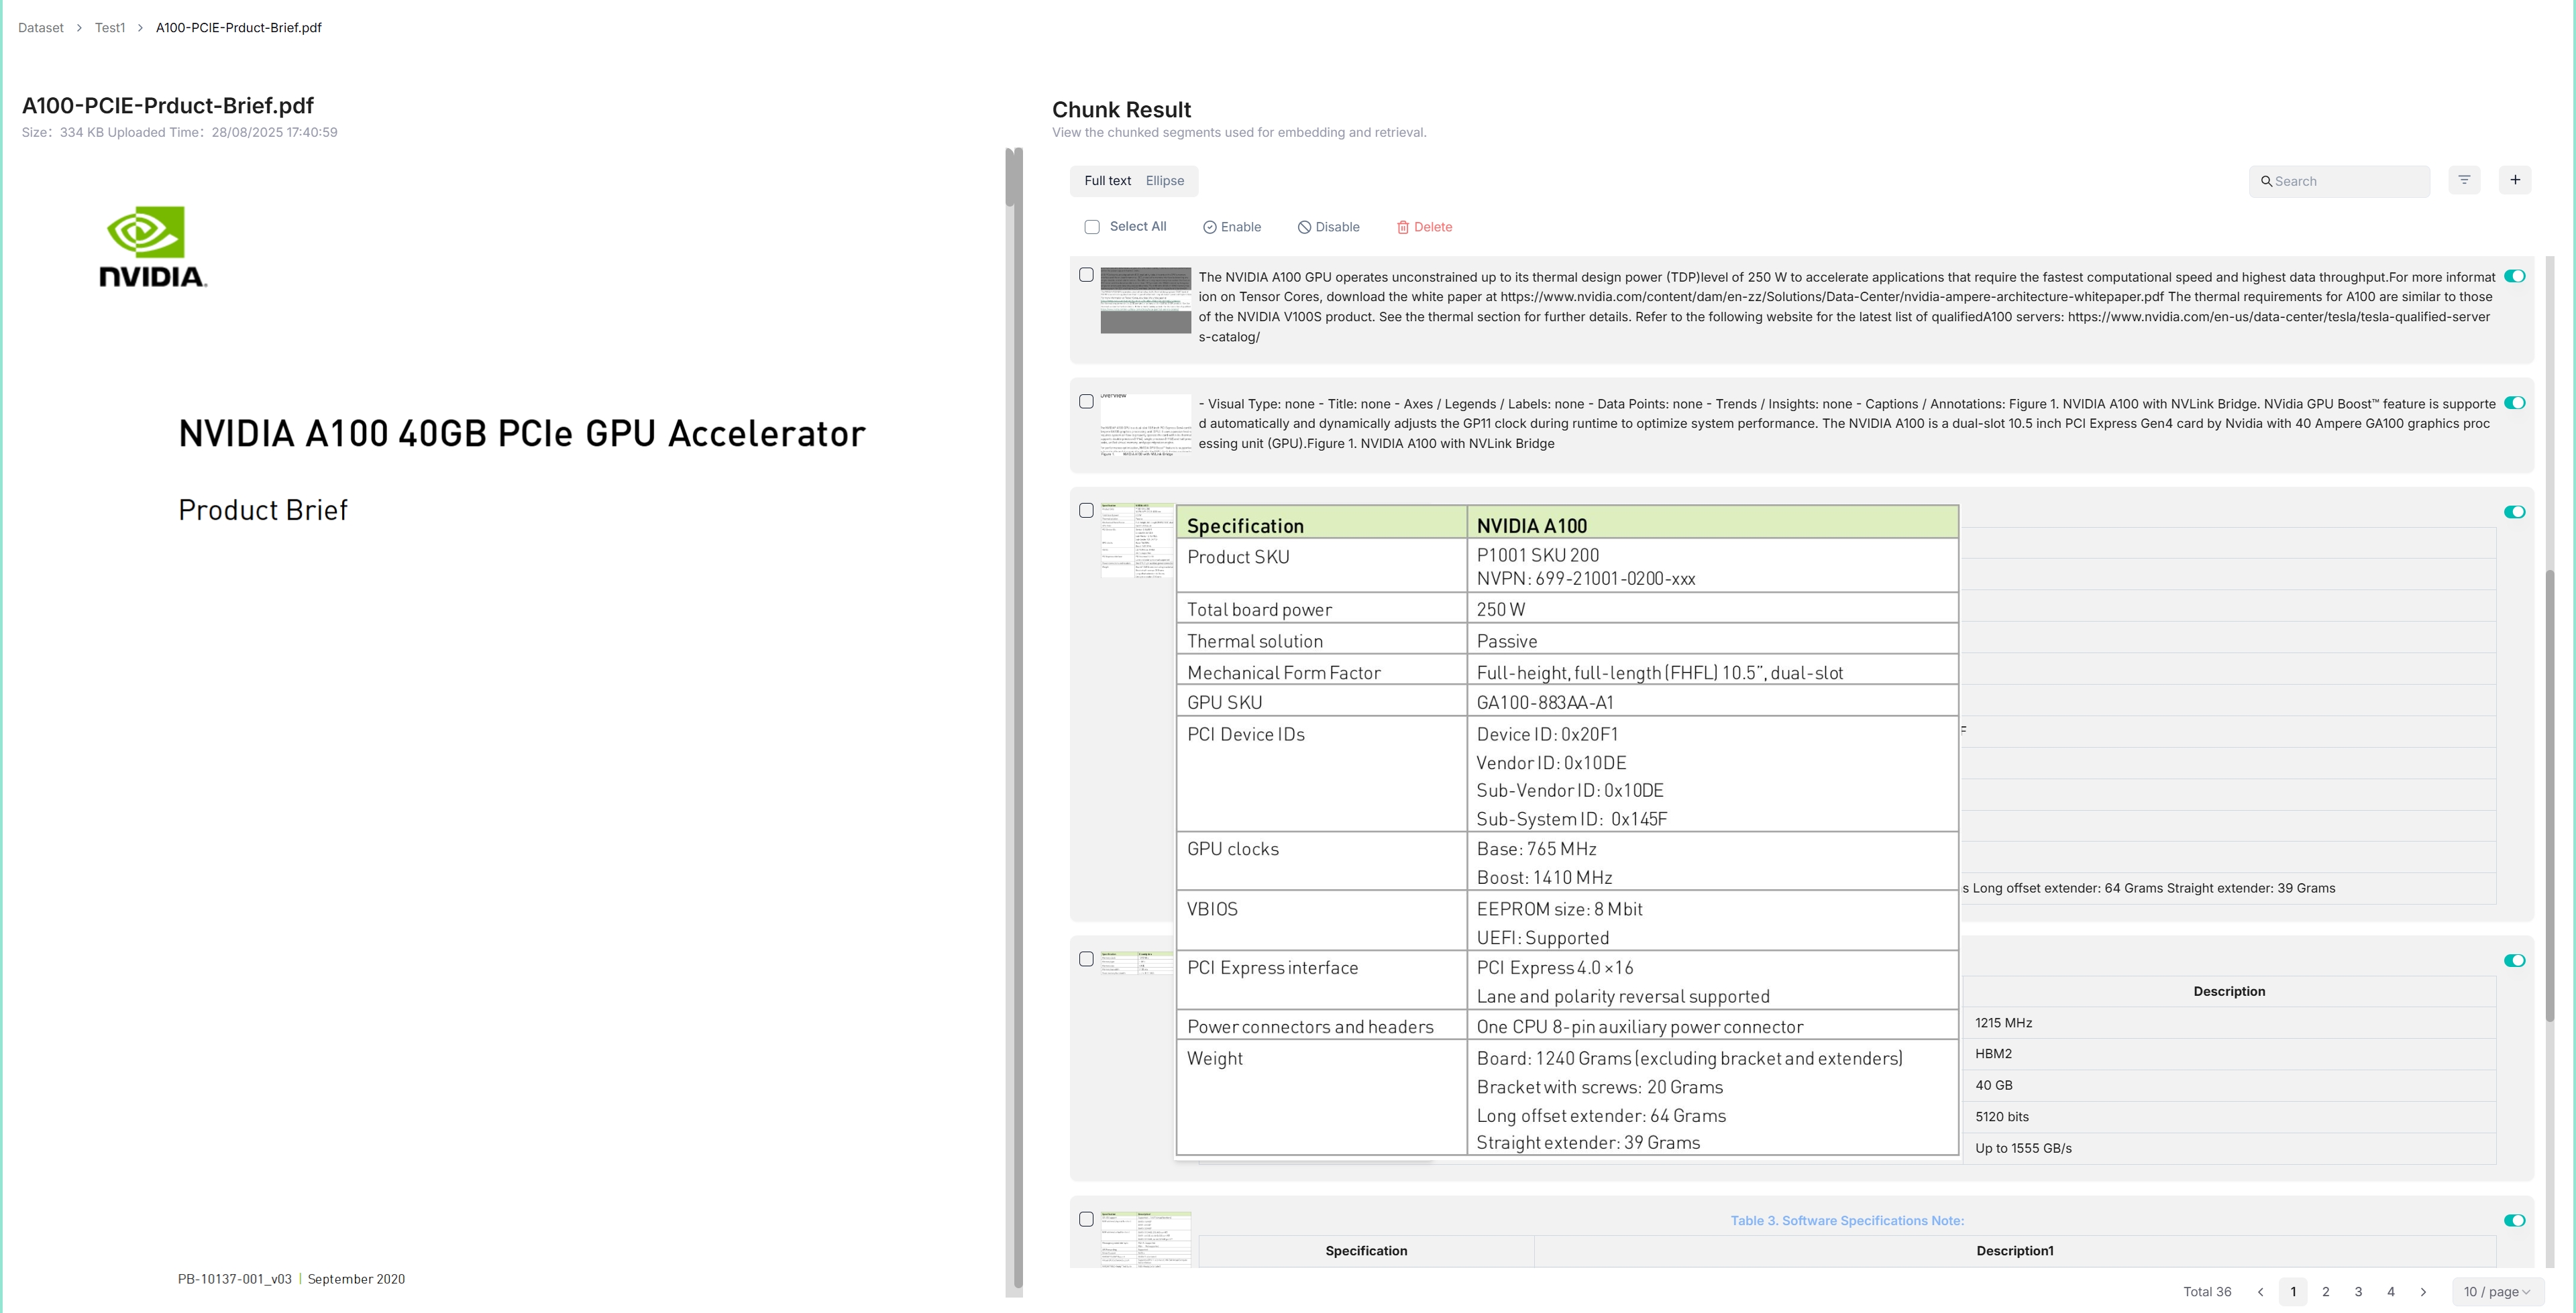--2. Hover over each snapshot for a quick view of each chunk.--3. Double-click the chunked texts to add keywords, questions, tags, or make *manual* changes where necessary:-- 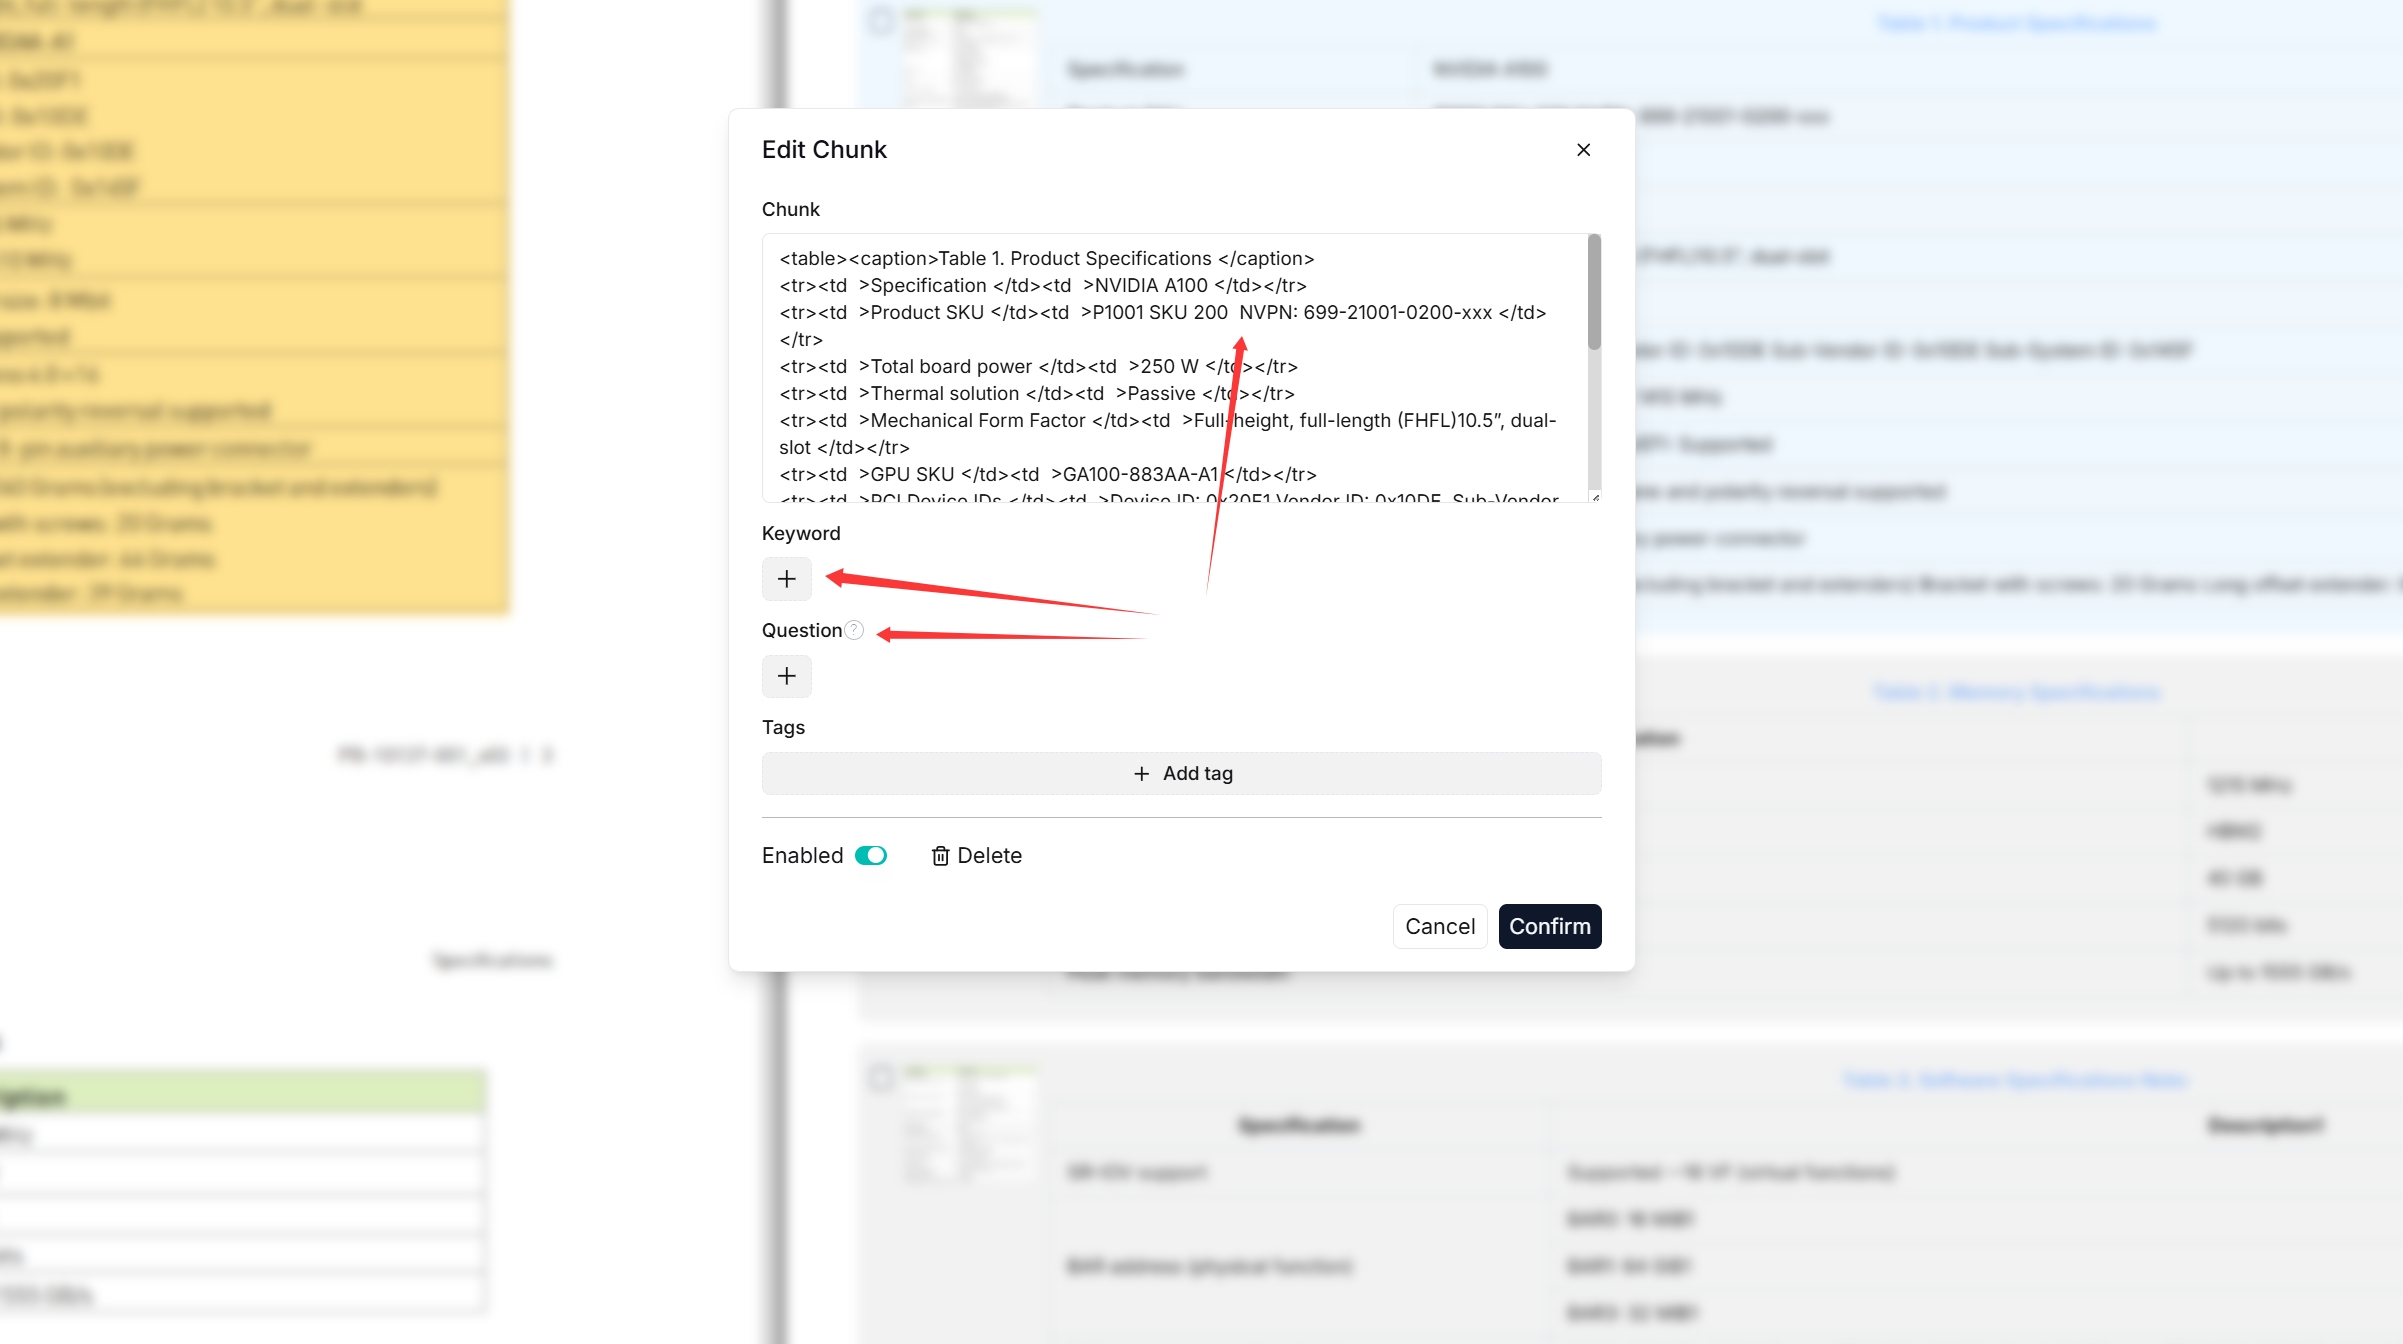--:::caution NOTE-You can add keywords to a file chunk to increase its ranking for queries containing those keywords. This action increases its keyword weight and can improve its position in search list.-:::--4. In Retrieval testing, ask a quick question in **Test text** to double-check if your configurations work:-- _As you can tell from the following, RAGFlow responds with truthful citations._-- 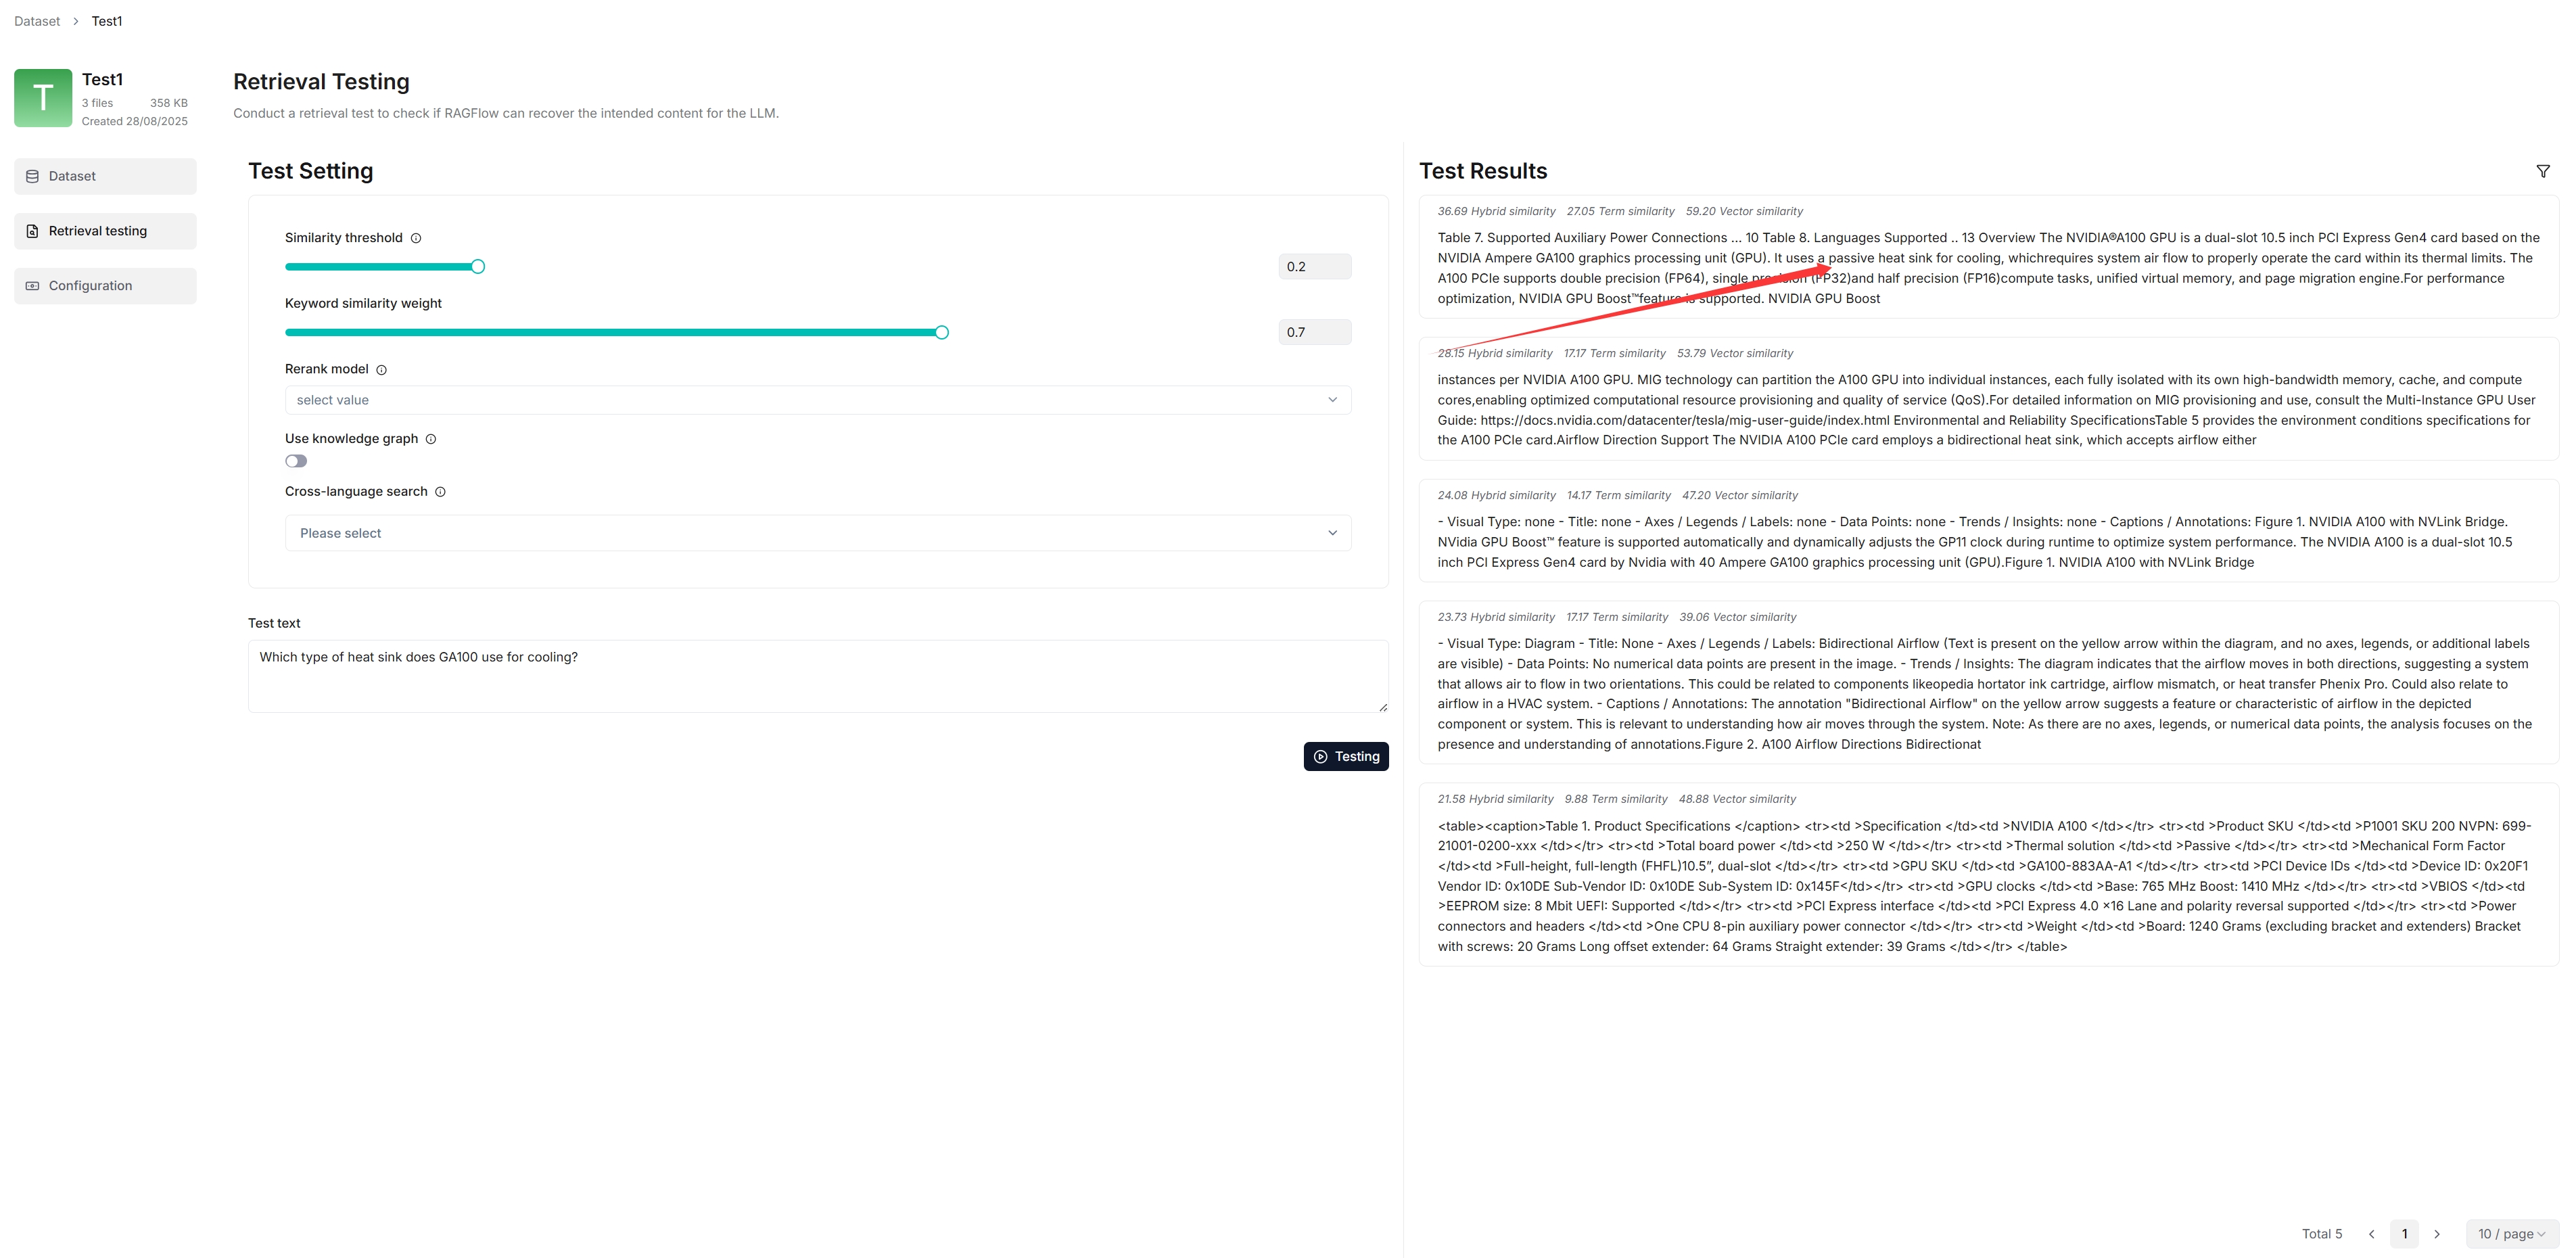--### Run Retrieval Testing--RAGFlow uses multiple recall of both full-text search and vector search in its chats. Prior to setting up an AI chat, consider adjusting the following parameters to ensure that the intended information always turns up in answers:--- Similarity threshold: Chunks with similarities below the threshold will be filtered. By default, it is set to 0.2.-- Vector similarity weight: The percentage by which vector similarity contributes to the overall score. By default, it is set to 0.3.--See [Run retrieval test](./run_retrieval_test.md) for details.--## Search for Dataset--As of RAGFlow v0.27.0, the search feature is still in a rudimentary form, supporting only dataset search by name.----## Delete Dataset--You are allowed to delete a dataset. Hover your mouse over the three dot of the intended dataset card and the **Delete** option appears. Once you delete a dataset, the associated folder under **root/.knowledge** directory is AUTOMATICALLY REMOVED. The consequence is:--- The files uploaded directly to the dataset are gone;-- The file references, which you created from within RAGFlow's File system, are gone, but the associated files still exist.--diff --git a/docs/guides/dataset/dataset_list_and_creation.md b/docs/guides/dataset/dataset_list_and_creation.mdnew file mode 100644index 0000000000..f27e9b3204--- /dev/null+++ b/docs/guides/dataset/dataset_list_and_creation.md@@ -0,0 +1,31 @@+---+sidebar_position: 2+title: Dataset List and Creation+sidebar_label: Dataset List and Creation+slug: /dataset_list_and_creation+sidebar_custom_props: {+ categoryIcon: LucideDatabaseZap+}+---++# Dataset List and Creation++## Create Dataset++On the dataset list page, click **Create dataset** to open the creation popup. When creating a dataset, you need to set **Name**, **Embedding model**, and **Parse type**, and then, based on the selected parse type, further select a **Built-in** parsing method or an existing **Pipeline**.++1. Fill in **Name**. The name cannot be empty. It is recommended to use a name that reflects the business or material scope.+2. Select **Embedding model**. The drop-down list displays embedding models that have been added to the system and are currently available. Select the model used to vectorize documents in the dataset.+3. Select **Parse type**. RAGFlow provides the following two types of document parsing:+ - **Built-in**: Uses RAGFlow's built-in document parsing methods. The system provides multiple preset parsing methods. You can choose a suitable method based on the document content and structure, such as general documents, Q&A, tables, papers, books, presentations, and so on. This is suitable when you want to directly use the system's preset parsing rules to process documents.+ - **Pipeline**: Uses a custom pipeline to parse documents. The pipeline must be created and configured in **Agent** in advance. You can customize the document parsing and processing flow according to actual requirements. After creation, you can select the corresponding pipeline when creating a dataset.+4. When **Built-in** is selected, continue selecting the specific built-in parsing method. When **Pipeline** is selected, select the pipeline used to process documents.+5. Click **Save** to complete creation. Creating a dataset is only the first step. After creation, it is recommended to go to the dataset configuration page and further check and configure language, parsing method, auto metadata, data source associations, and other options based on the actual scenario before uploading documents in bulk.++## View Dataset List++After entering **Datasets** from the left menu, the page displays the datasets accessible to the current user as cards, including datasets created by the user and datasets shared by other users. Each dataset card displays basic information such as the dataset avatar or initials, name, document count, and creation time, making it easy to quickly understand the dataset content and status.++Click a dataset card to enter its detail page and view and manage documents, chunks, and related configuration. If there are many datasets, use the pagination feature at the bottom of the page to switch pages and adjust the number of datasets displayed per page.++Click **Create dataset** to create a new dataset. During creation, configure the dataset name, embedding model, document parsing method, and other information.diff --git a/docs/guides/dataset/dataset_overview.md b/docs/guides/dataset/dataset_overview.mdnew file mode 100644index 0000000000..9abd392ecf--- /dev/null+++ b/docs/guides/dataset/dataset_overview.md@@ -0,0 +1,39 @@+---+sidebar_position: 1+title: Dataset Overview+sidebar_label: Dataset Overview+slug: /dataset_overview+sidebar_custom_props: {+ categoryIcon: LucideDatabaseZap+}+---++# Dataset Overview++## What Is a Dataset++A dataset is the workspace in RAGFlow that carries knowledge sources and retrieval content. A dataset usually corresponds to a group of business materials, a document collection, or an external data source. In a dataset, users import files, parse files, split them into chunks, maintain metadata, and validate recall. Later, modules such as chats, search, and Agents use this content for retrieval augmentation.++In terms of responsibility, a dataset is more than a "folder". It converts raw documents into retrievable chunks, stores the enabled status of documents and chunks, maintains metadata, and provides foundational data for knowledge artifacts and log tracing.++## Basic Workflow++The following briefly introduces the basic dataset workflow and helps you quickly understand the overall process from creating a dataset to testing retrieval results. The specific operations, configuration items, and feature descriptions involved in each step are described in detail in later sections.++1. Create a dataset and select an embedding model and parsing method.+2. Complete dataset configuration under **Configuration**.+3. Upload or add documents under **Document Management**.+4. Parse documents and generate chunks.+5. Check and adjust chunks and metadata.+6. Use **Retrieval Testing** to test retrieval results.+7. Adjust parsing or retrieval configuration based on the test results.++## Dataset Page Overview++The following briefly introduces the main entries on the dataset detail page and helps you quickly understand the purpose of each page. The specific operations, configuration items, and usage methods for each feature are described in detail in later sections.++- **File list**: The default entry on the dataset detail page. It is used to manage documents, parsing status, enabled status, chunk count, metadata field count, and document-level operations in the dataset.+- **Retrieval Testing**: Used to enter test questions and adjust retrieval parameters to verify the recall effect of the current dataset. Test parameter adjustments are not saved automatically and must be applied separately in **Chat Assistant** or the **Retrieval Agent** component.+- **Artifacts**: Used to view entries for knowledge artifacts related to the current dataset, such as **Wiki**, **Navigation**, and **Graph**. This dataset manual only introduces the entry and viewing method. For generation and updates, see **Knowledge Compilation**.+- **Logs**: Used to view document parsing and dataset-level task records, including document logs and dataset-level logs.+- **Configuration**: Used to maintain the dataset's basic information, embedding model, parsing method, data source associations, and other configurations.diff --git a/docs/guides/dataset/enable_excel2html.md b/docs/guides/dataset/enable_excel2html.mddeleted file mode 100644index fcb362a96f..0000000000--- a/docs/guides/dataset/enable_excel2html.md+++ /dev/null@@ -1,46 +0,0 @@-----sidebar_position: 4-title: Enable Excel2HTML-sidebar_label: Enable Excel2HTML-slug: /enable_excel2html-sidebar_custom_props: {- categoryIcon: LucideToggleRight-}-----# Enable Excel2HTML--Convert complex Excel spreadsheets into HTML tables.-------When using the **General** chunking method, you can enable the **Excel to HTML** toggle to convert spreadsheet files into HTML tables. If it is disabled, spreadsheet tables will be represented as key-value pairs. For complex tables that cannot be simply represented this way, you must enable this feature.--:::caution WARNING-The feature is disabled by default. If your dataset contains spreadsheets with complex tables, and you do not enable this feature, RAGFlow will not throw an error but your tables are likely to be garbled.-:::--## Scenarios--Works with complex tables that cannot be represented as key-value pairs. Examples include spreadsheet tables with multiple columns, tables with merged cells, or multiple tables within one sheet. In such cases, consider converting these spreadsheet tables into HTML tables.--## Considerations--- The Excel2HTML feature applies only to spreadsheet files (XLSX or XLS (Excel 97-2003)).-- This feature is associated with the **General** chunking method. In other words, it is available *only when* you select the **General** chunking method.-- When this feature is enabled, spreadsheet tables with more than 12 rows will be split into chunks of 12 rows each.--## Procedure--1. On your dataset's **Configuration** page, select **General** as the chunking method.-- _The **Excel to HTML** toggle appears._--2. Enable **Excel to HTML** if your dataset contains complex spreadsheet tables that cannot be represented as key-value pairs.-3. Leave **Excel to HTML** disabled if your dataset has no spreadsheet tables or if its spreadsheet tables can be represented as key-value pairs.-4. If question-answering regarding complex tables is unsatisfactory, check if **Excel to HTML** is enabled.--## Frequently Asked Questions--### Should I Enable This Feature for PDFs with Complex Tables?--Nope. This feature applies to spreadsheet files only. Enabling **Excel to HTML** does not affect your PDFs.diff --git a/docs/guides/dataset/files_dataset_document_management.md b/docs/guides/dataset/files_dataset_document_management.mdnew file mode 100644index 0000000000..3561cb8db7--- /dev/null+++ b/docs/guides/dataset/files_dataset_document_management.md@@ -0,0 +1,142 @@+---+sidebar_position: 4+title: Files: Dataset Document Management+sidebar_label: Files: Dataset Document Management+slug: /files_dataset_document_management+sidebar_custom_props: {+ categoryIcon: LucideDatabaseZap+}+---++# Files: Dataset Document Management++## Document Management Overview++Document management is used to upload, add, parse, search, filter, enable, disable, delete, and maintain documents in a dataset. Documents become retrievable content only after parsing generates chunks. On the document management page, you can complete the complete process from importing files to parsing, checking results, maintaining metadata, and maintaining chunks.++## Document List++The document list is used to view the basic status of each document in the current dataset. The main fields in the list include **Name**, **Size**, **Source**, **Enabled**, **Chunks**, **Metadata**, **Parse**, **Status**, and **Action**.++- **Name**: The document name.+- **Size**: The document file size.+- **Source**: The document source, such as local upload, associated data source, or file management.+- **Enabled**: Whether the document participates in dataset retrieval. After a document is disabled, it remains in the dataset but is not used as a retrieval source.+- **Chunks**: The number of chunks generated for the document. A value of `0` usually means the document has not been parsed, parsing failed, or no usable content was produced after parsing.+- **Metadata**: The number of document-level metadata fields. Click this field to view or edit document metadata.+- **Parse**: Displays the current parsing method or provides entries related to adjusting the parsing method and starting parsing.+- **Status**: Displays the document parsing task status, used to determine whether the document is waiting for parsing, being parsed, parsed successfully, or failed.+- **Action**: Provides operations such as renaming the document, viewing information, downloading, and deleting.++## Add Documents++### Upload Local Documents++Click **Add file** and select **Upload file** to upload documents from the local machine to the current dataset. After upload, the documents appear in the document list.++1. Go to the **Files** page of the target dataset.+2. Click **Add file** and select **Upload file**.+3. Select the local documents to add to the dataset.+4. Choose whether to enable **Parse on creation** as needed.+5. After confirming the upload, view the document status in the document list.++### Add Documents from an Associated Data Source++If a dataset has already been associated with an external data source in configuration, documents in the data source can be added to the dataset from the document management page. After addition, the documents enter the dataset document list. They still need to complete parsing before generating chunks, metadata, and retrieval content.++Operation steps:++1. Go to the **Files** page of the target dataset.+2. Click **Add file** and select the associated data source entry.+3. Select the documents to add.+4. Confirm the addition and view the document status in the document list.++### Add Documents from File Management++Documents can also be added from RAGFlow's file management module. This method is suitable when files have already been uploaded to file management and need to be referenced by a dataset.++After documents are added to the dataset, subsequent parsing and enabling status are still managed on the dataset's **Files** page. Documents that have not been parsed cannot generate chunks or participate in retrieval.++## Parse Documents++Document parsing converts source files into chunks, metadata, and other data available for retrieval. By default, documents use the current dataset configuration's parsing method. For documents that require special handling, you can also change the parsing method of a single document.++### Start Parsing++You can start parsing after documents are uploaded or added.++1. Select one or more documents in the document list.+2. Click **Run** or the corresponding parsing entry.+3. If the document has old chunks or existing auto metadata, handle them according to the interface prompt.+4. After confirming the operation, the system starts the parsing task.++### View Parsing Status++You can view the current parsing status of each document in the document list and view parsing progress and related information through **Logs**. Common statuses include waiting, running, completed, failed, and canceled.++If parsing fails, view the related information in **Logs**, troubleshoot the problem, and run parsing again.++### Parse Again++If parsing configuration changes or parsing results need to be updated, you can parse a document again. Common scenarios that require parsing again include:++- The parsing method or its parameters changed.+- Chunk splitting configuration changed.+- Auto metadata configuration changed.+- Table column role configuration changed.+- The source document was updated or replaced.+- Existing parsing results are incorrect and need to be regenerated.++Parsing again may regenerate chunks and metadata. Before operating, confirm whether old results need to be retained, overwritten, or updated according to the interface prompt.++### Change the Parsing Method of a Single Document++The parsing method in dataset configuration is the default parsing configuration for documents. If a document needs a different parsing method, you can change it separately in the document list or document detail page.++This adjustment only applies to the current document and does not affect the default parsing configuration of the dataset.++## Search and Filter Documents++**Search documents**: You can enter keywords in the document list to search by document name or related content. Search helps quickly locate target documents when there are many documents.++**Filter documents**: The document list supports filtering by parsing status, enabled status, source, and other conditions. The number of documents matching each condition is displayed on the right side of each filter item. You can select one or more conditions as needed.++**Metadata field** is used to further filter documents based on document metadata. The system displays metadata fields available for filtering in the current dataset. For table documents using the **Table** parsing method, columns set to **Metadata** or **Both** in column role configuration can appear here as metadata fields.++You can search field names in the search box under **Metadata field**, or expand a specific field and select corresponding values as filter conditions. After setup, click **Submit** to apply filter conditions. Click **Clear** to clear the current filter conditions.++> Note: The fields actually displayed in **Metadata field** depend on the document metadata in the current dataset, so available filter fields may vary between datasets.++## Batch Operations++After selecting the checkboxes on the left side of the document list, a batch operation bar appears, allowing multiple documents to be processed at the same time.++- **Enabled**: Batch-enable selected documents.+- **Disabled**: Batch-disable selected documents.+- **Run**: Batch-parse selected documents and process old chunks and auto metadata application when needed.+- **Cancel**: Cancel running parsing tasks.+- **Metadata**: Maintain metadata for selected documents in bulk.+- **Delete**: Delete selected documents.++## Single-Document Operations++### View and Manage Documents++Click the document name to enter the document detail page and view document information, parsing results, chunks, and metadata.++- **View parsing results**: Click the document name to enter document details and view chunks and related information generated by parsing.+- **View metadata**: View or edit document-level metadata.+- **Download**: Download the source document.+- **Rename**: Rename the document.++### Enable and Disable Documents++The enabled status determines whether a document participates in dataset retrieval. After a document is disabled, its chunks are no longer used as retrieval sources, but the document and parsing results remain in the dataset.++If you want to temporarily remove a document from retrieval without deleting it, disable the document. If you need to restore retrieval, enable it again.++### Delete Documents++Deleting a document removes it from the current dataset. The corresponding chunks, metadata, and parsing results are also removed and no longer participate in later retrieval or Q&A.++Before deleting, confirm that the document and its parsing results are no longer needed.diff --git a/docs/guides/dataset/logs.md b/docs/guides/dataset/logs.mdnew file mode 100644index 0000000000..5b153e917f--- /dev/null+++ b/docs/guides/dataset/logs.md@@ -0,0 +1,59 @@+---+sidebar_position: 9+title: Logs: Logs+sidebar_label: Logs: Logs+slug: /dataset_logs+sidebar_custom_props: {+ categoryIcon: LucideDatabaseZap+}+---++# Logs: Logs++## Log Overview++**Logs** is used to view execution records of tasks related to the current dataset. The top of the page displays statistics such as **Total files**, **Processing**, and **Downloading**. The lower area is divided into document logs and dataset-level logs by log type. Document logs focus on the processing process of a single document. Dataset-level logs focus on tasks within the entire dataset scope. When troubleshooting, first determine whether the problem occurs in a single document or the entire dataset, then go to the corresponding logs to view details.++## Document Logs++Document logs are used to view and trace task execution related to a single document, such as document parsing, task cancellation, and task success or failure. When a document has not completed parsing for a long time, parsing fails, or the number of generated chunks is abnormal, use document logs to view task status and execution details.++Document logs mainly include:++- **ID**: The unique identifier of the log record or task.+- **Filename**: The name of the document executing the current task.+- **Source**: The document source.+- **Ingestion pipeline**: The parsing method or pipeline used when processing the document.+- **Start date**: The task start time.+- **Task**: The task type, such as **Parse**.+- **Status**: The current task execution status.+- **Operations**: Operation entry. You can view log details for the current task, including execution process and error information.++If parsing fails for only one document, a document stays processing for a long time, or the number of chunks is abnormal, it is recommended to check that document's logs first.++## Dataset-Level Logs++Dataset-level logs are used to view task execution records whose processing object is the entire dataset. Unlike document logs for single-document parsing tasks, dataset-level logs mainly record dataset-level processing tasks, such as **Knowledge Graph**, **RAPTOR**, **Artifact**, **Skill**, **Mind Map**, and **Timeline**.++Dataset-level logs mainly include:++- **ID**: The unique identifier of the task record.+- **Start date**: The task start time.+- **Processing type**: The processing type, used to indicate the current dataset-level task, such as **Knowledge Graph**, **RAPTOR**, or **Artifact**.+- **Status**: The current task execution status.+- **Operations**: Operation entry. You can view log details and execution information for the current task.++When a dataset-level processing task fails, does not complete for a long time, or needs execution confirmation, view the corresponding task record and log details here.++> Tip: For tasks executed on a single document, such as document parsing, view document logs. For tasks executed on the entire dataset, such as **Knowledge Graph**, **RAPTOR**, and **Artifact**, view dataset-level logs.++## Log Troubleshooting Suggestions++When task execution is abnormal or does not complete for a long time, first select the corresponding logs based on task type, then troubleshoot based on task status and log details.++- **Document processing tasks**: View document logs. Document logs record processing tasks for specific documents. Use information such as **Filename**, **Source**, **Ingestion pipeline**, **Task**, and **Status** to confirm which document and processing flow has the exception. For documents processed with **Data Pipeline**, you can also use the entry in **Operations** to view the corresponding pipeline execution result.+- **Dataset-level processing tasks**: View dataset-level logs. Dataset-level tasks such as **Knowledge Graph**, **RAPTOR**, **Artifact**, **Skill**, **Mind Map**, and **Timeline** are recorded here. Use **Processing type** and **Status** to find the corresponding task, and view log details through **Operations**.+- **Task execution failed**: When **Status** is **Failed**, open the corresponding task log details and view the specific error information.+- **Task does not complete for a long time**: When a task stays in **Pending**, **Running**, or **Schedule** for a long time, first confirm the current task status and start time, then view log details to determine whether the task is still running normally.++> Note: Document logs and dataset-level logs record different types of processing tasks. They are not parent-child logs or summary logs. When troubleshooting, select the corresponding log based on the actual task.diff --git a/docs/guides/dataset/manage_metadata.md b/docs/guides/dataset/manage_metadata.mddeleted file mode 100644index 4da1ece204..0000000000--- a/docs/guides/dataset/manage_metadata.md+++ /dev/null@@ -1,51 +0,0 @@-----sidebar_position: -5-title: Manage Metadata-sidebar_label: Manage Metadata-slug: /manage_metadata-sidebar_custom_props: {- categoryIcon: LucideCode-}-----# Manage Metadata--Manage metadata for your dataset and for your individual documents.-------From v0.23.0 onwards, RAGFlow allows you to manage metadata both at the dataset level and for individual files.---## Procedure--1. Click on **Metadata** within your dataset to access the **Manage Metadata** page.--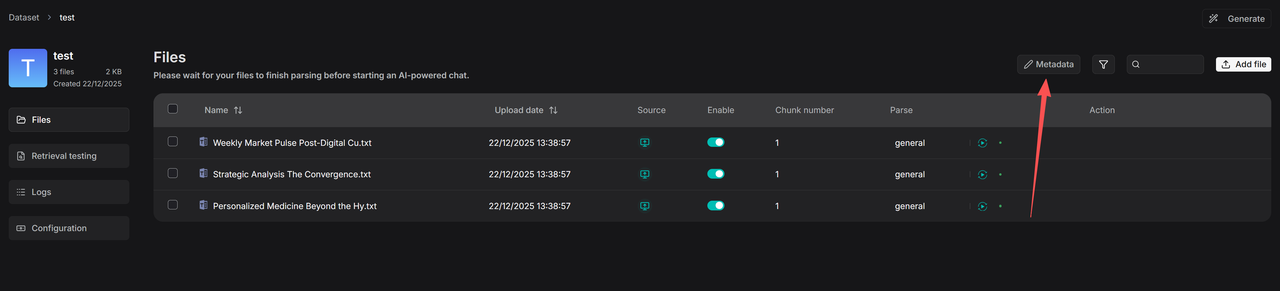---2. On the **Manage Metadata** page, you can do either of the following:- - Edit Values: You can modify existing values. If you rename two values to be identical, they will be automatically merged.- - Delete: You can delete specific values or entire fields. These changes will apply to all associated files.-- _The configuration page for rules on automatically generating metadata appears._--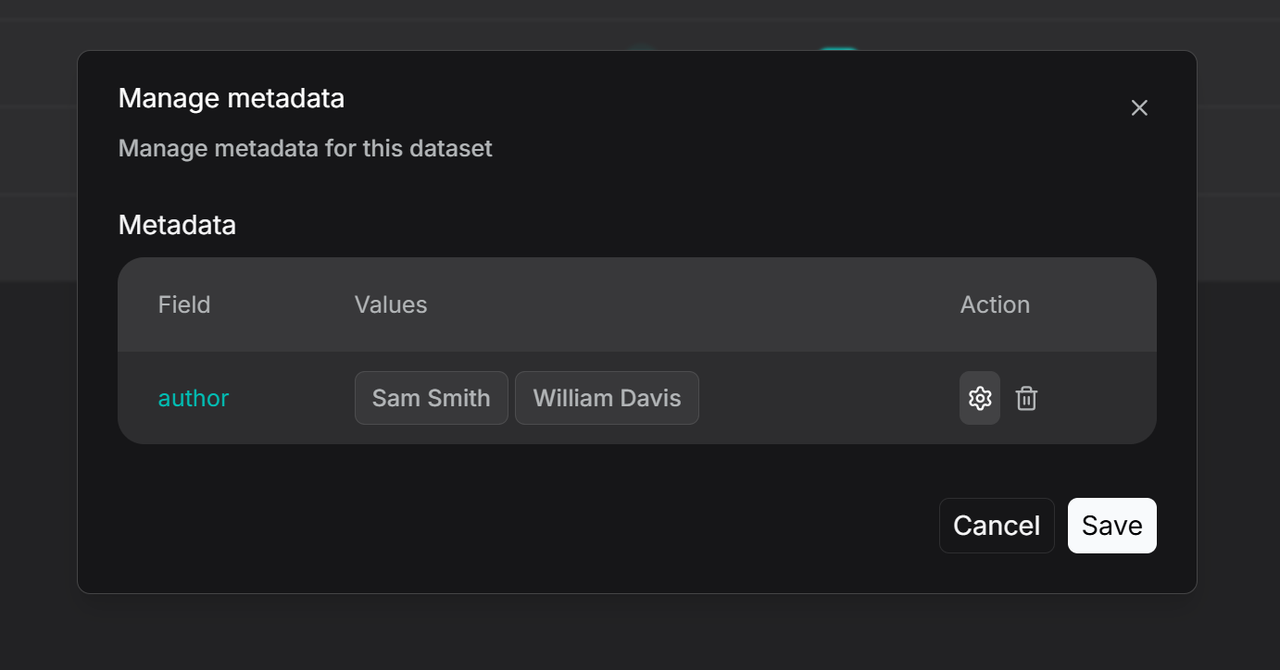--3. To manage metadata for a single file, navigate to the file's details page as shown below. Click on the parsing method (e.g., **General**), then select **Set Metadata** to view or edit the file's metadata. Here, you can add, delete, or modify metadata fields for this specific file. Any edits made here will be reflected in the global statistics on the main Metadata management page for the knowledge base.--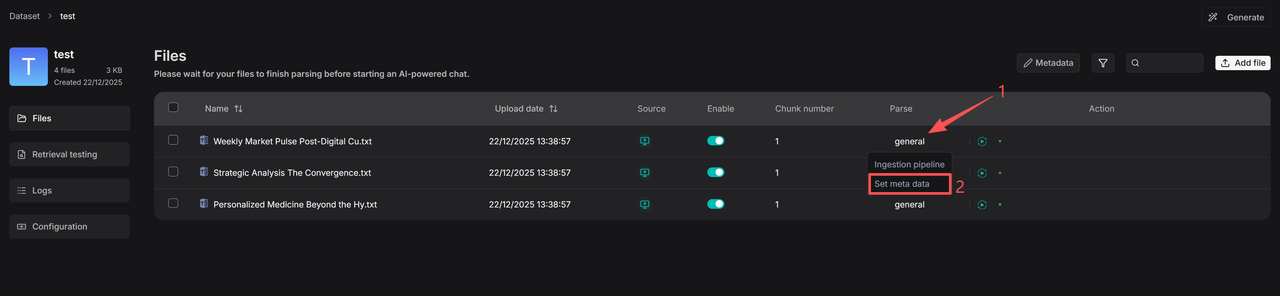-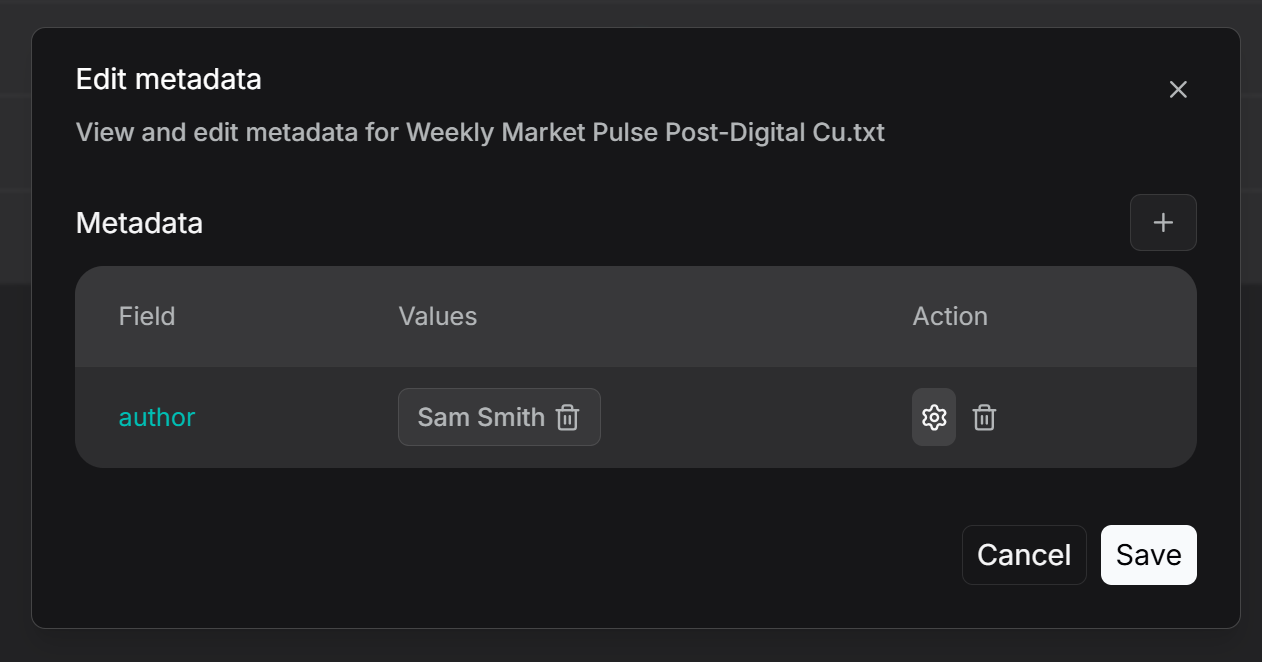--4. The filtering function operates at two levels: knowledge base management and retrieval. Within the dataset, click the Filter button to view the number of files associated with each value under existing metadata fields. By selecting specific values, you can display all linked files.--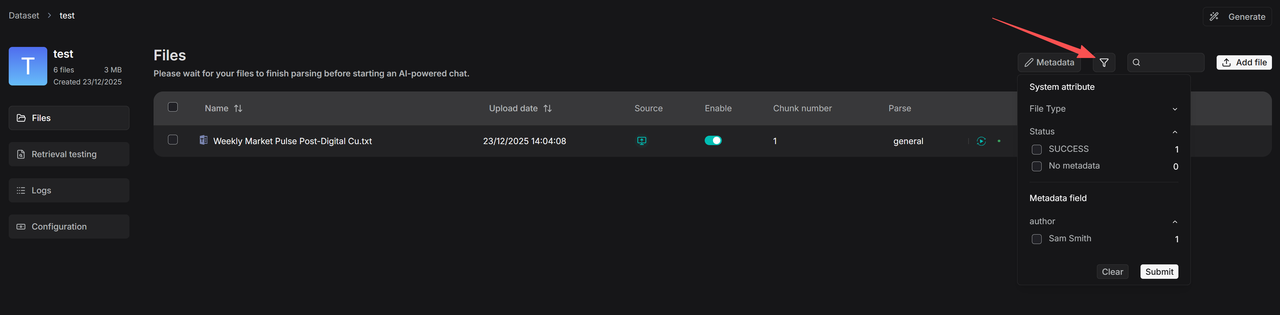--5. Metadata filtering is also supported during the retrieval stage. In Chat, for example, you can set metadata filtering rules after configuring a knowledge base:--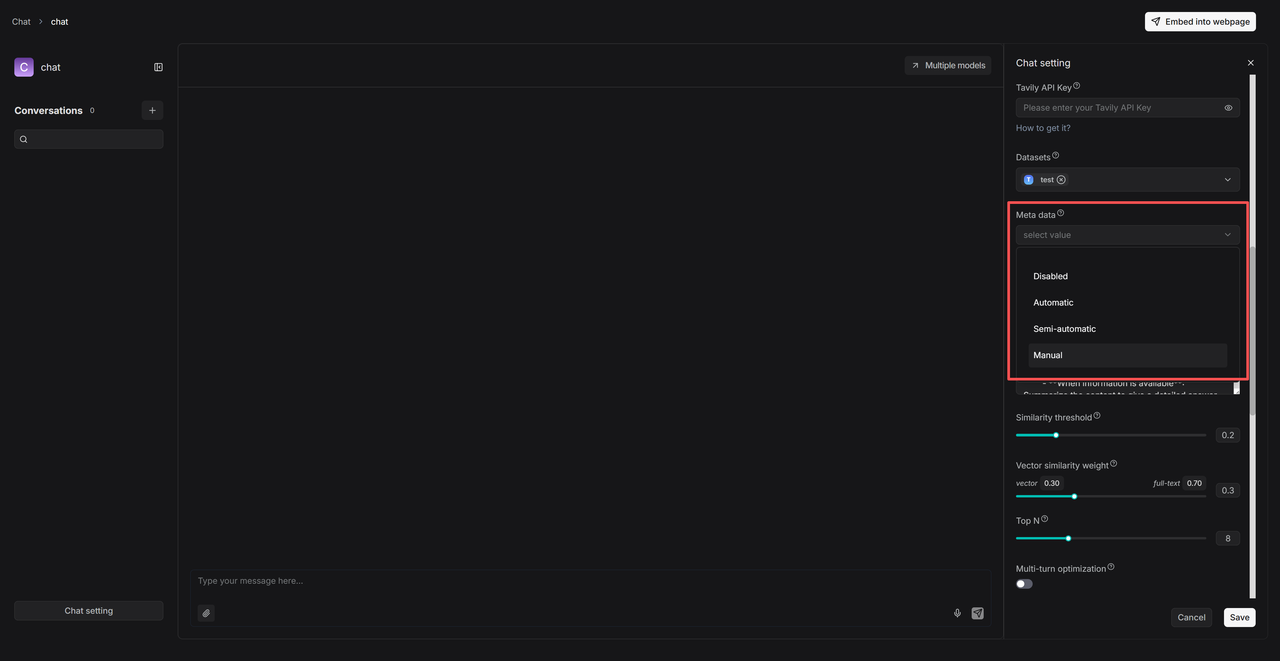--- **Automatic** Mode: The system automatically filters documents based on the user's query and the existing metadata in the knowledge base.-- **Semi-automatic** Mode: Users first define the filtering scope at the field level (e.g., for **Author**), and then the system automatically filters within that preset range.-- **Manual** Mode: Users manually set precise, value-specific filter conditions, supported by operators such as **Equals**, **Not equals**, **In**, **Not in**, and more.--diff --git a/docs/guides/dataset/metadata_management.md b/docs/guides/dataset/metadata_management.mdnew file mode 100644index 0000000000..9bd4cc85a4--- /dev/null+++ b/docs/guides/dataset/metadata_management.md@@ -0,0 +1,43 @@+---+sidebar_position: 6+title: Metadata: Metadata Management+sidebar_label: Metadata: Metadata Management+slug: /metadata_management+sidebar_custom_props: {+ categoryIcon: LucideDatabaseZap+}+---++# Metadata: Metadata Management++## Metadata Overview++Metadata is structured information associated with documents or chunks. It is used to describe the source, category, time, owner, business attributes, or other supplementary information of content. Metadata can be used for document management, filtering, retrieval range restriction, and result analysis.++Metadata may come from system built-in fields, automatic generation during parsing, table column role configuration, or manual maintenance.++## View and Manage Metadata++In document management or document details, you can view and maintain metadata related to documents. Metadata is displayed in list form, including **Field**, **Type**, **Values**, and related operations.++## Add Metadata++You can add metadata manually for documents. When adding metadata, you need to specify the field name, data type, and value. To improve subsequent filtering and retrieval, keep field names, data types, and value formats consistent.++## Automatically Generate Metadata++After **Auto Metadata** is enabled in dataset configuration, the system can automatically generate metadata during document parsing according to the configured generation rules. Automatically generated metadata usually comes from document content, source information, or built-in parsing information.++Changes to auto metadata configuration only affect newly parsed documents. If you need to apply new metadata rules to existing documents, parse the relevant documents again.++## Use Metadata to Filter Documents++On the document list page, you can use **Metadata field** to filter documents. The available fields and values depend on the metadata already present in the current dataset.++For table documents, columns configured as **Metadata** or **Both** can be used as metadata filter fields.++## Metadata and Retrieval++Metadata can also be used to restrict the retrieval range. After metadata conditions are configured, retrieval only searches content that meets the metadata conditions.++When using metadata, keep field names, data types, and value formats unified and accurate. Metadata conditions that are too strict or inaccurate field values may exclude relevant content from the retrieval scope.diff --git a/docs/guides/dataset/notes_and_faqs.md b/docs/guides/dataset/notes_and_faqs.mdnew file mode 100644index 0000000000..82304ac7e2--- /dev/null+++ b/docs/guides/dataset/notes_and_faqs.md@@ -0,0 +1,119 @@+---+sidebar_position: 10+title: Notes and FAQs+sidebar_label: Notes and FAQs+slug: /dataset_notes_and_faqs+sidebar_custom_props: {+ categoryIcon: LucideDatabaseZap+}+---++# Notes and FAQs++## Do I Need to Parse Again After Modifying Parsing Configuration?++Usually yes. Parsing configuration affects how documents are converted into chunks. For parsed documents, modifying configuration does not necessarily rewrite old chunks automatically. If you want the new configuration to apply to existing documents, parse the relevant documents again.++## When Do Metadata Changes Take Effect?++After metadata is manually modified, interface filters can usually use the new values directly. If metadata participates in retrieval filtering or affects indexing results, you may need to combine it with re-parsing, index refresh, or re-testing to confirm the final effect.++## What Should I Do If Document Parsing Fails?++It is recommended to troubleshoot in the order of **document status -> configuration -> Logs**. First confirm whether the document is still parsing or has failed, then check the parsing method, model, and data source configuration, and finally open document log details to view the error cause.++## What Should I Do If Retrieval Testing Cannot Retrieve Content?++It is recommended to troubleshoot in the order of **document status -> chunk -> metadata -> retrieval parameters**. First confirm that the document has been parsed successfully and generated usable chunks. Then check whether metadata has filter conditions that exclude related chunks. Finally, check retrieval parameters such as **Similarity threshold**, **Vector similarity weight**, and **Top K**.++Common causes include documents not yet parsed, no usable chunks generated, metadata filters being too strict, **Similarity threshold** being too high, or **Top K** being too small.++## Why Can't I See Artifacts?++Artifacts are related to knowledge compilation results. If the dataset has no usable chunks or knowledge compilation has not been completed, expected artifacts may not appear. First confirm that documents have been parsed successfully, then refer to **Knowledge Compilation** to generate or update artifacts.++## Run Retrieval Testing++Run retrieval testing on your dataset to check whether the expected chunks can be retrieved.++After files are uploaded and parsed, it is recommended to run retrieval testing before configuring a chat assistant. Running retrieval testing is never unnecessary or redundant. Like fine-tuning a precision instrument, RAGFlow requires careful adjustment to deliver the best Q&A performance. Your dataset settings, chat assistant configuration, and specified small and large models all significantly affect the final result. Running retrieval testing can verify whether expected chunks can be retrieved, allowing you to quickly identify areas that need improvement or locate issues that need to be resolved. For example, when debugging a Q&A system, if you know that the correct chunks can be retrieved, you can focus elsewhere. In issue #5627, the issue was found to be caused by LLM limitations.++During retrieval testing, hybrid search is used to retrieve chunks created by the chunking method you specified. This search combines weighted keyword similarity with weighted vector cosine similarity or weighted rerank score, depending on your settings:++- If no rerank model is selected, weighted keyword similarity is combined with weighted vector cosine similarity.+- If a rerank model is selected, weighted keyword similarity is combined with weighted vector rerank score.+- By contrast, chunks created by knowledge graph construction are retrieved using only vector cosine similarity.++### Prerequisites++- Your files have been uploaded and successfully parsed before running retrieval testing.+- A knowledge graph must be successfully built before **Use Knowledge Graph** is enabled.++### Configuration++#### Similarity Threshold++This setting is the threshold for retrieving chunks. Chunks with similarity below the threshold are filtered out. By default, the threshold is set to `0.2`. This means only chunks with a hybrid similarity score of 20 or higher are retrieved.++#### Vector Similarity Weight++This setting controls the weight of vector similarity in the comprehensive similarity score, whether it is combined with vector cosine similarity or rerank score. By default, it is set to `0.3`, so the other component's weight is `0.7` (`1 - 0.3`).++#### Rerank Model++- If left empty, RAGFlow uses a combination of weighted keyword similarity and weighted vector cosine similarity.+- If a rerank model is selected, weighted keyword similarity is combined with weighted vector rerank score.++> Important: Using a rerank model significantly increases the time required to receive a response.++#### Use Knowledge Graph++In a knowledge graph, entity descriptions, relationship descriptions, or community reports each exist as independent chunks. This switch indicates whether these chunks are added to retrieval. By default, this switch is disabled. After it is enabled, RAGFlow performs the following operations during retrieval testing:++1. Uses the LLM to extract entities and entity types from your query.+2. Based on the extracted entity types, retrieves the top N entities from the graph according to their PageRank values.+3. Uses embeddings of the extracted query entities to find similar entities and their N-hop relationships in the graph.+4. Uses the query embedding to retrieve similar relationships from the graph.+5. Sorts the retrieved entities and relationships by multiplying each entity's PageRank value by its similarity score with the query, and returns the top n as the final retrieval results.+6. Retrieves reports for communities involving most entities in the final retrieval.+7. Sends the retrieved entity descriptions, relationship descriptions, and top 1 community report to the LLM for content generation.++> Important: Using the knowledge graph in retrieval testing significantly increases the time required to receive a response.++#### Cross-Language Search++To perform cross-language search, select one or more target languages from the drop-down menu. Then the system's default chat model translates the query you entered in the test text field into the selected target languages. This translation ensures accurate cross-language semantic matching, allowing you to retrieve relevant results regardless of language differences.++> Tip: When selecting target languages, make sure these languages exist in the dataset to ensure effective search. If no target language is selected, the system searches only in the language of your query, which may cause relevant information in other languages to be missed.++#### Test Text++This field is used to enter your test query.++### Operation Steps++1. Navigate to the dataset's **Retrieval Testing** page, enter your query in **Test text**, and click **Test** to run the test.+2. If the results are unsatisfactory, adjust the options listed in the configuration section and run the test again.++The following screenshot shows retrieval testing without using the knowledge graph. It demonstrates hybrid search that combines weighted keyword similarity and weighted vector cosine similarity. The overall hybrid similarity score is 28.56, calculated as `25.17` term similarity score multiplied by `0.7` plus `36.49` vector similarity score multiplied by `0.3`.++The following screenshot shows retrieval testing using the knowledge graph. It shows that chunks generated by the knowledge graph use only vector similarity.++> Warning: If you adjusted default settings, such as keyword similarity weight or similarity threshold, to obtain the best results, note that these changes are not saved automatically. You must apply them to your chat assistant settings or the **Retrieval Agent** component settings.++### FAQ++#### Is an LLM Used When the Use Knowledge Graph Switch Is Enabled?++Yes. Your LLM participates in analyzing your query and extracting relevant entities and relationships from the knowledge graph. This also explains why extra tokens and time are consumed.++## Best Practices: Index Acceleration++A checklist for accelerating document parsing and indexing.++Please note that some of your settings may consume a large amount of time. If you often find document parsing time-consuming, use the following checklist:++- On the dataset configuration page, turn off **Use RAPTOR to enhance retrieval**.+- Extracting the knowledge graph (GraphRAG) is time-consuming.+- On the dataset configuration page, disable **Auto keyword** and **Auto question**, because both depend on the LLM.+- v0.17.0+: If all PDFs in your dataset are pure text and do not require GPU-intensive processing such as OCR (optical character recognition), TSR (table structure recognition), or DLA (document layout analysis), select **Naive** instead of **DeepDoc** or other time-consuming large model options in the **Document parser** drop-down menu. This significantly reduces document parsing time.diff --git a/docs/guides/dataset/retrieval_testing.md b/docs/guides/dataset/retrieval_testing.mdnew file mode 100644index 0000000000..5ad7cad7e5--- /dev/null+++ b/docs/guides/dataset/retrieval_testing.md@@ -0,0 +1,67 @@+---+sidebar_position: 7+title: Retrieval Testing: Retrieval Test+sidebar_label: Retrieval Testing: Retrieval Test+slug: /retrieval_testing+sidebar_custom_props: {+ categoryIcon: LucideDatabaseZap+}+---++# Retrieval Testing: Retrieval Test++## Retrieval Testing Overview++**Retrieval Testing** is used to verify whether a dataset can recall the expected chunks based on user queries. After documents complete parsing, it is recommended to use typical questions in **Retrieval Testing** to test retrieval results first. Confirm whether the recalled chunks are correct, whether the content is complete, and whether the ranking is reasonable before using the dataset in **Chat**, **Search**, or **Agent**.++Retrieval testing can also help troubleshoot Q&A result problems. If the correct chunk can already be recalled but the final answer is still unsatisfactory, further check the model, prompt, or application configuration. If the target chunk is not recalled, continue checking document parsing, chunks, metadata, and retrieval parameters.++> Tip: Documents used for testing must have completed parsing and be enabled.++## Configure Retrieval Parameters++The **Setting** area on the **Retrieval testing** page is used to adjust retrieval parameters for the current test. You can modify parameters and run tests repeatedly to compare recall results under different configurations. The main parameters include:++- **Similarity threshold**: Candidate chunks below this threshold are filtered out. Raising the threshold narrows the recall range and makes results stricter; lowering the threshold expands the recall range. The default value is `0.2`.+- **Vector similarity weight**: The weight of vector similarity in the comprehensive similarity calculation. The other part of the weight is used for full-text or keyword similarity. For example, when this is set to `0.3`, the other part is `0.7`.+- **Rerank model**: The reranking model used to further calculate relevance and sort candidate results. If no rerank model is selected, retrieval results combine keyword similarity and vector cosine similarity. If selected, reranking results participate in the comprehensive score. Using a rerank model may increase retrieval latency.+- **Cross-language search**: Select one or more target languages so a query can match related content in other languages in the dataset. If no language is selected, retrieval is mainly performed in the current language.+- **Metadata**: Restricts the retrieval range by metadata conditions. After it is set, retrieval is performed only in content that meets the metadata conditions.+- **Top**: Sets the maximum number of candidate results returned. For example, if **Top 10** is selected, up to 10 eligible results are returned.++> Note: Parameter changes in **Retrieval Testing** are only used for the current test and are not automatically synchronized to **Chat Assistant** or **Agent**. After suitable parameters are determined, configure the corresponding parameters in the application that actually uses the dataset or in the **Retrieval** component.++## Execute Retrieval Testing++Enter the query to test under the **Setting** area, then click **Run** to execute retrieval. It is recommended to use questions close to real user expressions and prepare multiple types of queries to check recall for different content.++After the test is executed, chunks matching the current retrieval parameters are displayed in the **Results** area on the right.++## View Retrieval Results++After executing a test, recalled chunks are displayed in the **Results** area on the right, together with the total number of results for the test. Each result mainly displays the recalled chunk content, relevance information, and source document, and is sorted according to the current retrieval configuration.++When viewing retrieval results, focus on:++- Whether the target chunk is successfully recalled.+- Whether the recalled chunk comes from the correct document.+- Whether the chunk content is related to the query and contains the information needed to answer the question.+- Whether highly relevant content appears near the top.+- Whether many chunks unrelated to the query are recalled.+- Whether required content is excluded by metadata or other filter conditions.++The upper-right corner of **Results** provides a **File** filter. You can select a specified document and view only retrieval results from that document. When a dataset contains many documents, this helps check recall for a specific document.++The focus of retrieval testing is not to compare a single score in isolation, but to confirm whether the needed chunks can be accurately recalled and reasonably ranked under the current retrieval configuration.++## Adjust Retrieval Results++If retrieval results do not meet expectations, first determine whether the problem is a content problem or a retrieval configuration problem, then adjust accordingly.++If the target content does not appear in retrieval results at all, check whether the document was parsed successfully, whether the target content has generated corresponding chunks, and whether metadata conditions exclude the related content.++If the target chunk can be recalled but many irrelevant results also appear, raise **Similarity threshold** appropriately to narrow the recall range. If retrieval results rely more on semantic expression or keyword matching, adjust **Vector similarity weight** to rebalance vector retrieval and full-text retrieval. If the target chunk can already be recalled but ranking is unsatisfactory, try configuring **Rerank model** to rerank candidate results.++If you need to see more or fewer candidate results, adjust **Top**. For cross-language datasets, also check whether **Cross-language search** includes the target languages to retrieve. It is recommended to use multiple representative queries for repeated testing and determine final parameters based on the overall recall result instead of adjusting configuration based only on a single test.++Debugging suggestion: when retrieval results are unsatisfactory, troubleshoot in the order of document parsing -> chunk -> metadata -> retrieval parameters. First confirm that the knowledge content itself has correctly entered the dataset, then adjust retrieval parameters. This helps locate the problem faster.diff --git a/docs/guides/dataset/run_retrieval_test.md b/docs/guides/dataset/run_retrieval_test.mddeleted file mode 100644index 6f8baee529..0000000000--- a/docs/guides/dataset/run_retrieval_test.md+++ /dev/null@@ -1,97 +0,0 @@-----sidebar_position: 10-title: Run Retrieval Test-sidebar_label: Run Retrieval Test-slug: /run_retrieval_test-sidebar_custom_props: {- categoryIcon: LucideTextSearch-}-----# Run Retrieval Test--Conduct a retrieval test on your dataset to check whether the intended chunks can be retrieved.-------After your files are uploaded and parsed, it is recommended that you run a retrieval test before proceeding with the chat assistant configuration. Running a retrieval test is *not* an unnecessary or superfluous step at all! Just like fine-tuning a precision instrument, RAGFlow requires careful tuning to deliver optimal question answering performance. Your dataset settings, chat assistant configurations, and the specified large and small models can all significantly impact the final results. Running a retrieval test verifies whether the intended chunks can be recovered, allowing you to quickly identify areas for improvement or pinpoint any issue that needs addressing. For instance, when debugging your question answering system, if you know that the correct chunks can be retrieved, you can focus your efforts elsewhere. For example, in issue [#5627](https://github.com/infiniflow/ragflow/issues/5627), the problem was found to be due to the LLM's limitations.--During a retrieval test, chunks created from your specified chunking method are retrieved using a hybrid search. This search combines weighted keyword similarity with either weighted vector cosine similarity or a weighted reranking score, depending on your settings:--- If no rerank model is selected, weighted keyword similarity will be combined with weighted vector cosine similarity.-- If a rerank model is selected, weighted keyword similarity will be combined with weighted vector reranking score.--In contrast, chunks created from [knowledge graph construction](./advanced/construct_knowledge_graph.md) are retrieved solely using vector cosine similarity.--## Prerequisites--- Your files are uploaded and successfully parsed before running a retrieval test.-- A knowledge graph must be successfully built before enabling **Use knowledge graph**.--## Configurations--### Similarity Threshold--This sets the bar for retrieving chunks: chunks with similarities below the threshold will be filtered out. By default, the threshold is set to 0.2. This means that only chunks with hybrid similarity score of 20 or higher will be retrieved.--### Vector Similarity Weight--This sets the weight of vector similarity in the composite similarity score, whether used with vector cosine similarity or a reranking score. By default, it is set to 0.3, making the weight of the other component 0.7 (1 - 0.3).--### Rerank Model--- If left empty, RAGFlow will use a combination of weighted keyword similarity and weighted vector cosine similarity.-- If a rerank model is selected, weighted keyword similarity will be combined with weighted vector reranking score.--:::danger IMPORTANT-Using a rerank model will significantly increase the time to receive a response.-:::--### Use Knowledge Graph--In a knowledge graph, an entity description, a relationship description, or a community report each exists as an independent chunk. This switch indicates whether to add these chunks to the retrieval.--The switch is disabled by default. When enabled, RAGFlow performs the following during a retrieval test:--1. Extract entities and entity types from your query using the LLM.-2. Retrieve top N entities from the graph based on their PageRank values, using the extracted entity types.-3. Find similar entities and their N-hop relationships from the graph using the embeddings of the extracted query entities.-4. Retrieve similar relationships from the graph using the query embedding.-5. Rank these retrieved entities and relationships by multiplying each one's PageRank value with its similarity score to the query, returning the top n as the final retrieval.-6. Retrieve the report for the community involving the most entities in the final retrieval.- *The retrieved entity descriptions, relationship descriptions, and the top 1 community report are sent to the LLM for content generation.*--:::danger IMPORTANT-Using a knowledge graph in a retrieval test will significantly increase the time to receive a response.-:::--### Cross-Language Search--To perform a [cross-language search](../../references/glossary.mdx#cross-language-search), select one or more target languages from the dropdown menu. The system’s default chat model will then translate your query entered in the Test text field into the selected target language(s). This translation ensures accurate semantic matching across languages, allowing you to retrieve relevant results regardless of language differences.--:::tip NOTE-- When selecting target languages, please ensure that these languages are present in the dataset to guarantee an effective search.-- If no target language is selected, the system will search only in the language of your query, which may cause relevant information in other languages to be missed.-:::--### Test Text--This field is where you put in your testing query.--## Procedure--1. Navigate to the **Retrieval testing** page of your dataset, enter your query in **Test text**, and click **Testing** to run the test.-2. If the results are unsatisfactory, tune the options listed in the Configuration section and rerun the test.-- A retrieval test without a knowledge graph uses hybrid search, combining weighted keyword similarity and weighted vector cosine similarity.-- A retrieval test using a knowledge graph uses vector similarity for knowledge graph-generated chunks.--:::caution WARNING-If you have adjusted the default settings, such as keyword similarity weight or similarity threshold, to achieve the optimal results, be aware that these changes will not be automatically saved. You must apply them to your chat assistant settings or the **Retrieval** agent component settings.-:::--## Frequently Asked Questions--### Is an LLM Used When the Use Knowledge Graph Switch Is Enabled?--Yes, your LLM will be involved to analyze your query and extract the related entities and relationship from the knowledge graph. This also explains why additional tokens and time will be consumed.diff --git a/docs/guides/dataset/select_pdf_parser.md b/docs/guides/dataset/select_pdf_parser.mddeleted file mode 100644index c7bd88ec6f..0000000000--- a/docs/guides/dataset/select_pdf_parser.md+++ /dev/null@@ -1,95 +0,0 @@-----sidebar_position: -3-title: Select PDF Parser-sidebar_label: Select PDF Parser-slug: /select_pdf_parser-sidebar_custom_props: {- categoryIcon: LucideFileText-}-----# Select PDF Parser--Select a visual model for parsing your PDFs.-------RAGFlow isn't one-size-fits-all. It is built for flexibility and supports deeper customization to accommodate more complex use cases. From v0.17.0 onwards, RAGFlow decouples DeepDoc-specific data extraction tasks from chunking methods **for PDF files**. This separation enables you to autonomously select a visual model for OCR (Optical Character Recognition), TSR (Table Structure Recognition), and DLR (Document Layout Recognition) tasks that balances speed and performance to suit your specific use cases. If your PDFs contain only plain text, you can opt to skip these tasks by selecting the **Naive** option, to reduce the overall parsing time.--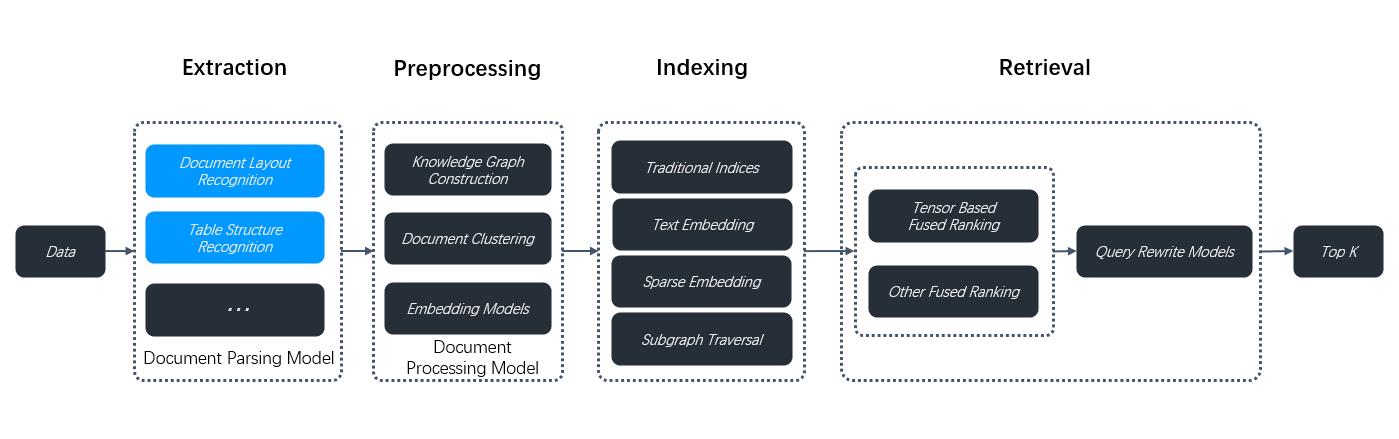--## Prerequisites--- The PDF parser dropdown menu appears only when you select a chunking method compatible with PDFs, including:- - **General**- - **Manual**- - **Paper**- - **Book**- - **Laws**- - **Presentation**- - **One**-- To use a third-party visual model for parsing PDFs, ensure you have set a default VLM under **Set default models** on the **Model providers** page.--## Quickstart--1. On your dataset's **Configuration** page, select a chunking method, say **General**.-- _The **PDF parser** dropdown menu appears._--2. Select the option that works best with your scenario:--- DeepDoc: (Default) The default visual model performing OCR, TSR, and DLR tasks on PDFs, but can be time-consuming.-- Naive: Skip OCR, TSR, and DLR tasks if _all_ your PDFs are plain text.-- [MinerU](https://github.com/opendatalab/MinerU): (Experimental) An open-source tool that converts PDF into machine-readable formats.-- [Docling](https://github.com/docling-project/docling): (Experimental) An open-source document processing tool for gen AI.-- [OpenDataLoader](https://github.com/opendataloader-project/opendataloader-pdf): (Experimental) A deterministic, local-first PDF parser with structured JSON + Markdown output. Runs as a standalone service container so no Java runtime is needed on the RAGFlow host.-- A third-party visual model from a specific model provider.--:::danger IMPORTANT-Starting from v0.22.0, RAGFlow includes MinerU (≥ 2.6.3) as an optional PDF parser of multiple backends. Please note that RAGFlow acts only as a *remote client* for MinerU, calling the MinerU API to parse documents and reading the returned files. To use this feature:-:::--1. Prepare a reachable MinerU API service (FastAPI server).-2. In the **.env** file or from the **Model providers** page in the UI, configure RAGFlow as a remote client to MinerU:- - `MINERU_APISERVER`: The MinerU API endpoint (e.g., `http://mineru-host:8886`).- - `MINERU_BACKEND`: The MinerU backend:- - `"pipeline"` (default)- - `"vlm-http-client"`- - `"vlm-transformers"`- - `"vlm-vllm-engine"`- - `"vlm-mlx-engine"`- - `"vlm-vllm-async-engine"`- - `"vlm-lmdeploy-engine"`.- - `MINERU_SERVER_URL`: (optional) The downstream vLLM HTTP server (e.g., `http://vllm-host:30000`). Applicable when `MINERU_BACKEND` is set to `"vlm-http-client"`.- - `MINERU_OUTPUT_DIR`: (optional) The local directory for holding the outputs of the MinerU API service (zip/JSON) before ingestion.- - `MINERU_DELETE_OUTPUT`: Whether to delete temporary output when a temporary directory is used:- - `1`: Delete.- - `0`: Retain.-3. In the web UI, navigate to your dataset's **Configuration** page and find the **Ingestion pipeline** section:- - If you decide to use a chunking method from the **Built-in** dropdown, ensure it supports PDF parsing, then select **MinerU** from the **PDF parser** dropdown.- - If you use a custom ingestion pipeline instead, select **MinerU** in the **PDF parser** section of the **Parser** component.--To use an external Docling Serve instance (instead of local in-process Docling), set:--- `DOCLING_SERVER_URL`: The Docling Serve API endpoint (for example, `http://docling-host:5001`).--When `DOCLING_SERVER_URL` is set, RAGFlow sends PDF content to Docling Serve (`/v1/convert/source`, with fallback to `/v1alpha/convert/source`) and ingests the returned markdown/text. If the variable is not set, RAGFlow keeps using local Docling (`USE_DOCLING=true` + installed package) behavior.--- `DOCLING_FORMULA_ENRICHMENT`: (local Docling) Set to `1` to convert formulas to LaTeX (accurate but slow). Default `0` — formulas are still extracted as their original text.--:::note-All MinerU environment variables are optional. When set, these values are used to auto-provision a MinerU OCR model for the tenant on first use. To avoid auto-provisioning, skip the environment variable settings and only configure MinerU from the **Model providers** page in the UI.-:::--:::caution WARNING-Third-party visual models are marked **Experimental**, because we have not fully tested these models for the aforementioned data extraction tasks.-:::--## Frequently Asked Questions--### When Should I Select DeepDoc or a Third-Party Visual Model as the PDF Parser?--Use a visual model to extract data if your PDFs contain formatted or image-based text rather than plain text. DeepDoc is the default visual model but can be time-consuming. You can also choose a lightweight or high-performance VLM depending on your needs and hardware capabilities.--### Can I Select a Visual Model to Parse My DOCX Files?--No, you cannot. This dropdown menu is for PDFs only. To use this feature, convert your DOCX files to PDF first.diff --git a/docs/guides/dataset/set_context_window.md b/docs/guides/dataset/set_context_window.mddeleted file mode 100644index a42bf3960f..0000000000--- a/docs/guides/dataset/set_context_window.md+++ /dev/null@@ -1,29 +0,0 @@-----sidebar_position: -8-title: Set Context Window Size-sidebar_label: Set Context Window Size-slug: /set_context_window-sidebar_custom_props: {- categoryIcon: LucideListChevronsUpDown-}-----# Set Context Window Size--Set context window size for images and tables to improve long-context RAG performances.-------RAGFlow leverages built-in DeepDoc, along with external document models like MinerU and Docling, to parse document layouts. In previous versions, images and tables extracted based on document layout were treated as independent chunks. Consequently, if a search query did not directly match the content of an image or table, these elements would not be retrieved. However, real-world documents frequently interweave charts and tables with surrounding text, which often describes them. Therefore, recalling charts based on this contextual text is an essential capability.--To address this, RAGFlow 0.23.0 introduces the **Image & table context window** feature. Inspired by key principles of the research-focused, open-source multimodal RAG project RAG-Anything, this functionality allows surrounding text and adjacent visuals to be grouped into a single chunk based on a user-configurable window size. This ensures they are retrieved together, significantly improving the recall accuracy for charts and tables.--## Procedure--1. On your dataset's **Configuration** page, find the **Image & table context window** slider:--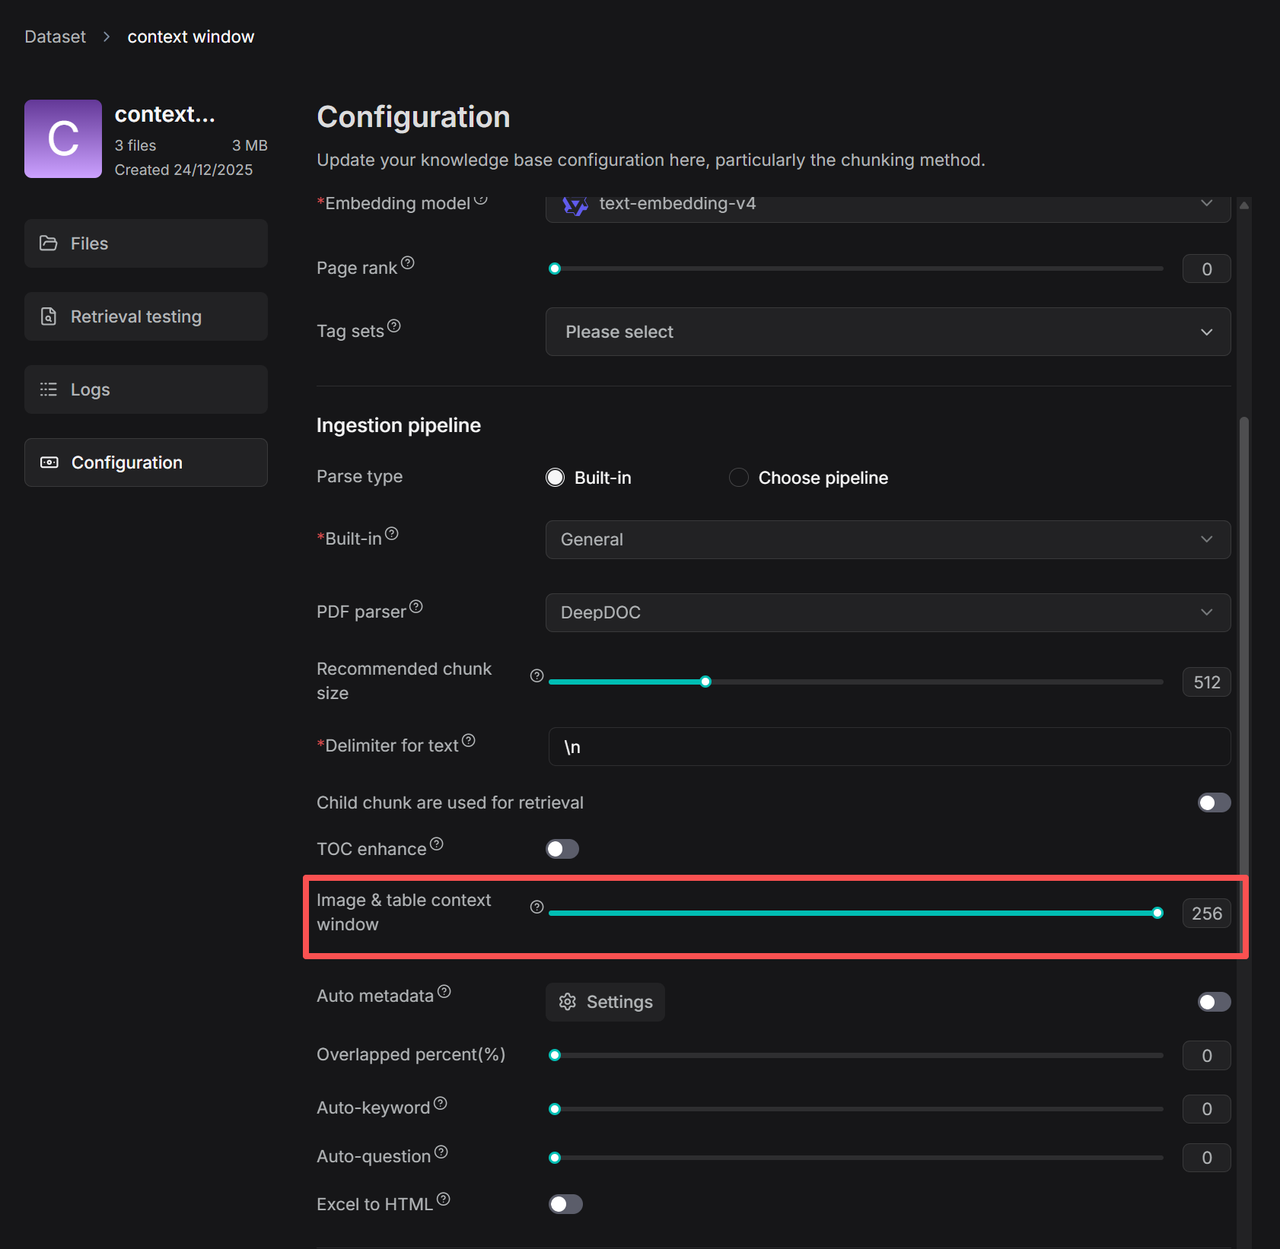---2. Adjust the number of context tokens according to your needs.-- *The number in the red box indicates that approximately **N tokens** of text from above and below the image/table will be captured and inserted into the image or table chunk as contextual information. The capture process intelligently optimizes boundaries at punctuation marks to preserve semantic integrity. *diff --git a/docs/guides/dataset/set_metadata.md b/docs/guides/dataset/set_metadata.mddeleted file mode 100644index 8a42f4a1fa..0000000000--- a/docs/guides/dataset/set_metadata.md+++ /dev/null@@ -1,36 +0,0 @@-----sidebar_position: -7-title: Set Metadata-sidebar_label: Set Metadata-slug: /set_metadata-sidebar_custom_props: {- categoryIcon: LucideCode-}-----# Set Metadata--Manually add metadata to an uploaded file-------On the **Dataset** page of your dataset, you can add metadata to any uploaded file. This approach enables you to 'tag' additional information like URL, author, date, and more to an existing file. In an AI-powered chat, such information will be sent to the LLM with the retrieved chunks for content generation.--For example, if you have a dataset of HTML files and want the LLM to cite the source URL when responding to your query, add a `"url"` parameter to each file's metadata.----:::tip NOTE-Ensure that your metadata is in JSON format; otherwise, your updates will not be applied.-:::--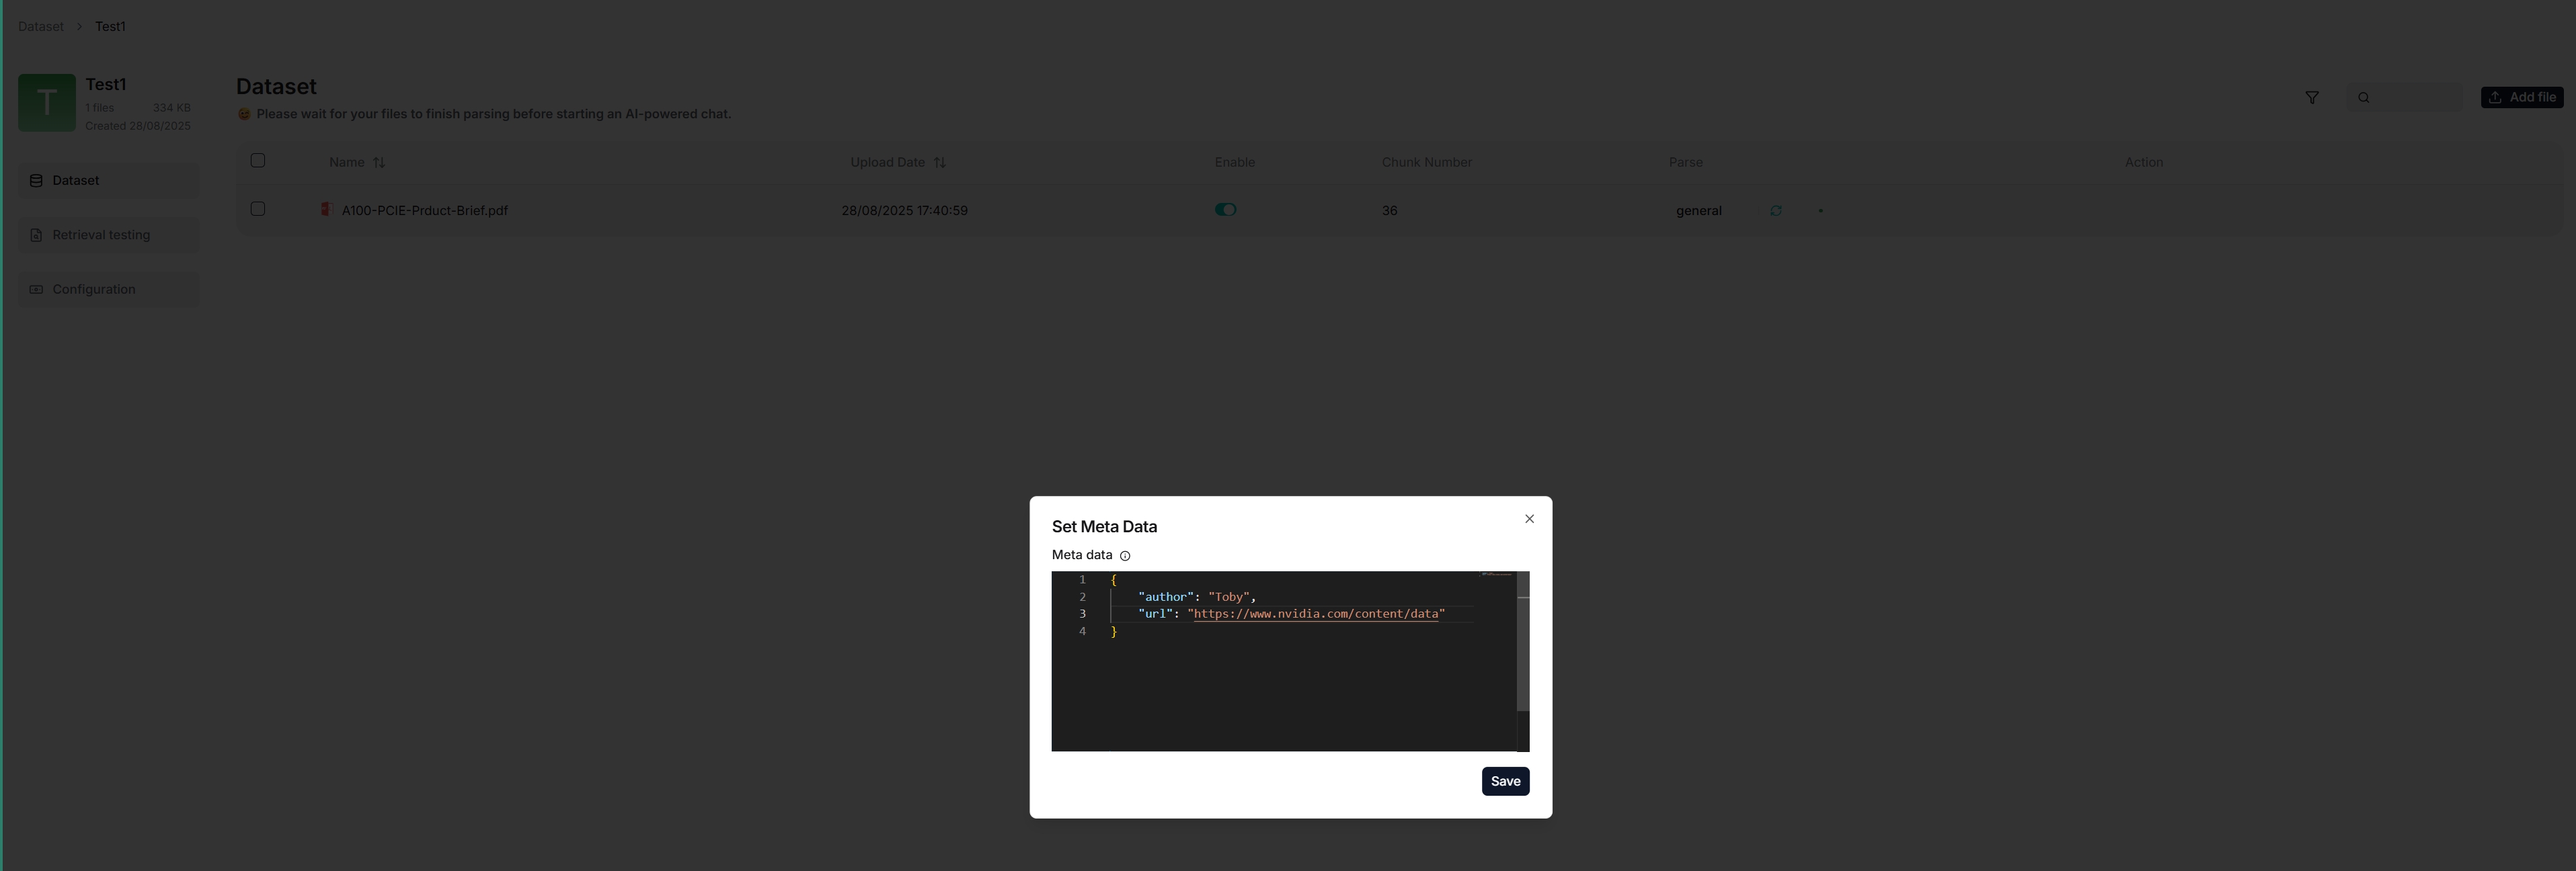--## Related APIs--[Retrieve chunks](../../references/http_api_reference.md#retrieve-chunks)--## Frequently Asked Questions--### Can I Set Metadata for Multiple Documents at Once?--From v0.23.0 onwards, you can set metadata for each document individually or have the LLM auto-generate metadata for multiple files. See [Extract metadata](./advanced/auto_metadata.md) for details.diff --git a/docs/guides/dataset/set_page_rank.md b/docs/guides/dataset/set_page_rank.mddeleted file mode 100644index 8c3a2a2e28..0000000000--- a/docs/guides/dataset/set_page_rank.md+++ /dev/null@@ -1,43 +0,0 @@-----sidebar_position: -2-title: Set Page Rank-sidebar_label: Set Page Rank-slug: /set_page_rank-sidebar_custom_props: {- categoryIcon: LucideStickyNote-}-----# Set Page Rank--Create a step-retrieval strategy using page rank.-------## Scenario--In an AI-powered chat, you can configure a chat assistant or an agent to respond using knowledge retrieved from multiple specified datasets (datasets), provided that they employ the same embedding model. In situations where you prefer information from certain dataset(s) to take precedence or to be retrieved first, you can use RAGFlow's page rank feature to increase the ranking of chunks from these datasets. For example, if you have configured a chat assistant to draw from two datasets, dataset A for 2024 news and dataset B for 2023 news, but wish to prioritize news from year 2024, this feature is particularly useful.--:::info NOTE-It is important to note that this 'page rank' feature operates at the level of the entire dataset rather than on individual files or documents.-:::--## Configuration--On the **Configuration** page of your dataset, drag the slider under **Page rank** to set the page rank value for your dataset. You are also allowed to input the intended page rank value in the field next to the slider.--:::info NOTE-The page rank value must be an integer. Range: [0,100]--- 0: Disabled (Default)-- A specific value: enabled-:::--:::tip NOTE-If you set the page rank value to a non-integer, say 1.7, it will be rounded down to the nearest integer, which in this case is 1.-:::--## Scoring Mechanism--If you configure a chat assistant's **similarity threshold** to 0.2, only chunks with a hybrid score greater than 0.2 x 100 = 20 will be retrieved and sent to the chat model for content generation. This initial filtering step is crucial for narrowing down relevant information.--If you have assigned a page rank of 1 to dataset A (2024 news) and 0 to dataset B (2023 news), the final hybrid scores of the retrieved chunks will be adjusted accordingly. A chunk retrieved from dataset A with an initial score of 50 will receive a boost of 1 x 100 = 100 points, resulting in a final score of 50 + 1 x 100 = 150. In this way, chunks retrieved from dataset A will always precede chunks from dataset B.diff --git a/docs/guides/dataset/use_tag_sets.md b/docs/guides/dataset/use_tag_sets.mddeleted file mode 100644index e9aa382bcf..0000000000--- a/docs/guides/dataset/use_tag_sets.md+++ /dev/null@@ -1,105 +0,0 @@-----sidebar_position: 6-title: Use Tag Set-sidebar_label: Use Tag Set-slug: /use_tag_sets-sidebar_custom_props: {- categoryIcon: LucideTags-}-----# Use Tag Set--Use a tag set to auto-tag chunks in your datasets.-------Retrieval accuracy is the touchstone for a production-ready RAG framework. In addition to retrieval-enhancing approaches like auto-keyword, auto-question, and knowledge graph, RAGFlow introduces an auto-tagging feature to address semantic gaps. The auto-tagging feature automatically maps tags in the user-defined tag sets to relevant chunks within your dataset based on similarity with each chunk. This automation mechanism allows you to apply an additional "layer" of domain-specific knowledge to existing datasets, which is particularly useful when dealing with a large number of chunks.--To use this feature, ensure you have at least one properly configured tag set, specify the tag set(s) on the **Configuration** page of your dataset, and then re-parse your documents to initiate the auto-tagging process. During this process, each chunk in your dataset is compared with every entry in the specified tag set(s), and tags are automatically applied based on similarity.--## Scenarios--Auto-tagging applies in situations where chunks are so similar to each other that the intended chunks cannot be distinguished from the rest. For example, when you have a few chunks about iPhone and a majority about iPhone case or iPhone accessaries, it becomes difficult to retrieve those chunks about iPhone without additional information.--## 1. Create Tag Set--You can consider a tag set as a closed set, and the tags to attach to the chunks in your dataset are *exclusively* from the specified tag set. You use a tag set to "inform" RAGFlow which chunks to tag and which tags to apply.--### Prepare a Tag Table File--A tag set can comprise one or multiple table files in XLSX, CSV, or TXT formats. Each table file in the tag set contains two columns, **Description** and **Tag**:--- The first column provides descriptions of the tags listed in the second column. These descriptions can be example chunks or example queries. Similarity will be calculated between each entry in this column and every chunk in your dataset.-- The **Tag** column includes tags to pair with the description entries. Multiple tags should be separated by a comma (,).--:::tip NOTE-As a rule of thumb, consider including the following entries in your tag table:--- Descriptions of intended chunks, along with their corresponding tags.-- User queries that fail to retrieve the correct responses using other methods, ensuring their tags match the intended chunks in your dataset.-:::--### Create a Tag Set--:::danger IMPORTANT-A tag set is *not* involved in document indexing or retrieval. Do not specify a tag set when configuring your chat assistant or agent.-:::--1. Click **+ Create dataset** to create a dataset.-2. Navigate to the **Configuration** page of the created dataset, select **Built-in** in **Ingestion pipeline**, then choose **Tag** as the default chunking method from the **Built-in** drop-down menu.-3. Go back to the **Files** page and upload and parse your table file in XLSX, CSV, or TXT formats.- A tag cloud appears under the **Tag view** section, indicating the tag set is created.-4. Click the **Table** tab to view the tag frequency table.--## 2. Tag Chunks--Once a tag set is created, you can apply it to your dataset:--1. Navigate to the **Configuration** page of your dataset.-2. Select the tag set from the **Tag sets** dropdown and click **Save** to confirm.-- :::tip NOTE- If the tag set is missing from the dropdown, check that it has been created or configured correctly.- :::--3. Re-parse your documents to start the auto-tagging process.- _In an AI chat scenario using auto-tagged datasets, each query will be tagged using the corresponding tag set(s) and chunks with these tags will have a higher chance to be retrieved._--## 3. Update Tag Set--Creating a tag set is *not* for once and for all. Oftentimes, you may find it necessary to update or delete existing tags or add new entries.--- You can update the existing tag set in the tag frequency table.-- To add new entries, you can add and parse new table files in XLSX, CSV, or TXT formats.--### Update Tag Set in Tag Frequency Table--1. Navigate to the **Configuration** page in your tag set.-2. Click the **Table** tab under **Tag view** to view the tag frequency table, where you can update tag names or delete tags.--:::danger IMPORTANT-When a tag set is updated, you must re-parse the documents in your dataset so that their tags can be updated accordingly.-:::--### Add New Table Files--1. Navigate to the **Configuration** page in your tag set.-2. Navigate to the **Dataset** page and upload and parse your table file in XLSX, CSV, or TXT formats.--:::danger IMPORTANT-If you add new table files to your tag set, it is at your own discretion whether to re-parse your documents in your datasets.-:::--## Frequently Asked Questions--### Can I Reference More Than One Tag Set?--Yes, you can. Usually one tag set suffices. When using multiple tag sets, ensure they are independent of each other; otherwise, consider merging your tag sets.--### Difference Between a Tag Set and a Standard Dataset?--A standard dataset is a dataset. It will be searched by RAGFlow's document engine and the retrieved chunks will be fed to the LLM. In contrast, a tag set is used solely to attach tags to chunks within your dataset. It does not directly participate in the retrieval process, and you should not choose a tag set when selecting datasets for your chat assistant or agent.--### Difference Between Auto-Tag and Auto-Keyword?--Both features enhance retrieval in RAGFlow. The auto-keyword feature relies on the LLM and consumes a significant number of tokens, whereas the auto-tag feature is based on vector similarity and predefined tag set(s). You can view the keywords applied in the auto-keyword feature as an open set, as they are generated by the LLM. In contrast, a tag set can be considered a user-defined close set, requiring upload tag set(s) in specified formats before use.diff --git a/docs/guides/models/deploy_local_llm.mdx b/docs/guides/models/deploy_local_llm.mdxindex 6cdb705b25..8e1995c885 100644--- a/docs/guides/models/deploy_local_llm.mdx+++ b/docs/guides/models/deploy_local_llm.mdx@@ -309,8 +309,8 @@ With the Ollama service running, open a new terminal and run `./ollama pull <modTo enable IPEX-LLM accelerated Ollama in RAGFlow, you must also complete the configurations in RAGFlow. The steps are identical to those outlined in the *Deploy a local model using Ollama* section:-1. [Add Ollama](#4-add-ollama)-2. [Complete basic Ollama settings](#5-complete-basic-ollama-settings)+1. [Add Ollama](#3-add-ollama)+2. [Complete basic Ollama settings](#4-complete-basic-ollama-settings)3. [Update System Model Settings](#6-update-system-model-settings)4. [Update Chat Configuration](#7-update-chat-configuration)diff --git a/docs/references/glossary.mdx b/docs/references/glossary.mdxindex dce691c666..7faec62ad6 100644--- a/docs/references/glossary.mdx+++ b/docs/references/glossary.mdx@@ -25,4 +25,4 @@ Cross-language search (also known as cross-lingual retrieval) is a feature introBy enabling cross-language search, users can effortlessly access a broader range of information regardless of language barriers, significantly enhancing the system’s usability and inclusiveness.-This feature is available in the retrieval test and chat assistant settings. See [Run retrieval test](../guides/dataset/run_retrieval_test.md) and [Start AI chat](../guides/chat/start_chat.md) for further details.\ No newline at end of file+This feature is available in the retrieval test and chat assistant settings. See [Run retrieval test](../guides/dataset/retrieval_testing.md) and [Start AI chat](../guides/chat/start_chat.md) for further details.diff --git a/docs/references/http_api_reference.md b/docs/references/http_api_reference.mdindex 25b1592dfc..77ff56d121 100644--- a/docs/references/http_api_reference.md+++ b/docs/references/http_api_reference.md@@ -2890,7 +2890,7 @@ curl --request POST \- `"or"`: Return results that satisfy *any* condition.- `"conditions"`: (*Body parameter*), `array`A list of metadata filter conditions.- - `"name"`: `string` - The metadata field name to filter by, e.g., `"author"`, `"company"`, `"url"`. Ensure this parameter before use. See [Set metadata](../guides/dataset/set_metadata.md) for details.+ - `"name"`: `string` - The metadata field name to filter by, e.g., `"author"`, `"company"`, `"url"`. Ensure this parameter before use. See [Set metadata](../guides/dataset/metadata_management.md) for details.- `comparison_operator`: `string` - The comparison operator. Can be one of:- `"contains"`- `"not contains"`diff --git a/docs/release_notes.md b/docs/release_notes.mdindex 6ea2147a3d..f094a9f09c 100644--- a/docs/release_notes.md+++ b/docs/release_notes.md@@ -665,8 +665,8 @@ Released on September 10, 2025.- Agent:- Agent Performance Optimized: Improves planning and reflection speed for simple tasks; optimizes concurrent tool calls for parallelizable scenarios, significantly reducing overall response time.- - Four framework-level prompt blocks are available in the **System prompt** section, enabling customization and overriding of prompts at the framework level, thereby enhancing flexibility and control. See [here](./guides/agent/agent_component_reference/agent.mdx#system-prompt).- - **Execute SQL** component enhanced: Replaces the original variable reference component with a text input field, allowing users to write free-form SQL queries and reference variables. See [here](./guides/agent/agent_component_reference/execute_sql.md).+ - Four framework-level prompt blocks are available in the **System prompt** section, enabling customization and overriding of prompts at the framework level, thereby enhancing flexibility and control. See [here](./guides/agent/agent_workflow/basic_component.md#prompt-configuration).+ - **Execute SQL** component enhanced: Replaces the original variable reference component with a text input field, allowing users to write free-form SQL queries and reference variables. See [here](./guides/agent/agent_workflow/tool_components.md#execute-sql).- Chat: Re-enables **Reasoning** and **Cross-language search**.### Newly supported models@@ -859,9 +859,9 @@ Released on May 26, 2025.#### Added documents-- [Select PDF parser](./guides/dataset/select_pdf_parser.md)-- [Enable Excel2HTML](./guides/dataset/enable_excel2html.md)-- [Code component](./guides/agent/agent_component_reference/code.mdx)+- [Select PDF parser](./guides/dataset/configuration.md#document-parsing-configuration)+- [Enable Excel2HTML]+- [Code component](./guides/agent/agent_workflow/data_manipulation_components.md#code-component)## v0.18.0@@ -891,7 +891,7 @@ From this release onwards, built-in rerank models have been removed because they#### Added documents-- [Set page rank](./guides/dataset/set_page_rank.md)+- [Set page rank](./guides/dataset/configuration.md#basic-information)- [Enable RAPTOR](./guides/dataset/advanced/enable_raptor.md)- [Set variables for your chat assistant](./guides/chat/set_chat_variables.md)- [Launch RAGFlow MCP server](./develop/mcp/launch_mcp_server.md)@@ -955,7 +955,7 @@ Released on March 11, 2025.#### Added documents-- [Use tag set](./guides/dataset/use_tag_sets.md)+- [Use tag set](./guides/dataset/configuration.md#basic-information)## v0.17.0@@ -967,7 +967,7 @@ Released on March 3, 2025.- AI chat: Leverages Tavily-based web search to enhance contexts in agentic reasoning. To activate this, enter the correct Tavily API key under the **Assistant settings** tab of your chat assistant dialogue.- AI chat: Supports starting a chat without specifying datasets.- AI chat: HTML files can also be previewed and referenced, in addition to PDF files.-- Dataset: Adds a **PDF parser**, aka **Document parser**, dropdown menu to dataset configurations. This includes a DeepDoc model option, which is time-consuming, a much faster **naive** option (plain text), which skips DLA (Document Layout Analysis), OCR (Optical Character Recognition), and TSR (Table Structure Recognition) tasks, and several currently *experimental* large model options. See [here](./guides/dataset/select_pdf_parser.md).+- Dataset: Adds a **PDF parser**, aka **Document parser**, dropdown menu to dataset configurations. This includes a DeepDoc model option, which is time-consuming, a much faster **naive** option (plain text), which skips DLA (Document Layout Analysis), OCR (Optical Character Recognition), and TSR (Table Structure Recognition) tasks, and several currently *experimental* large model options. See [here](./guides/dataset/configuration.md#document-parsing-configuration).- Agent component: **(x)** or a forward slash `/` can be used to insert available keys (variables) in the system prompt field of the **Generate** or **Template** component.- Object storage: Supports using Aliyun OSS (Object Storage Service) as a file storage option.- Models: Updates the supported model list for Tongyi-Qianwen (Qwen), adding DeepSeek-specific models; adds ModelScope as a model provider.@@ -995,7 +995,7 @@ Adds a key option `"meta_fields"` to the [Update document](./references/python_a#### Added documents-- [Run retrieval test](./guides/dataset/run_retrieval_test.md)+- [Run retrieval test](./guides/dataset/retrieval_testing.md)## v0.16.0@@ -1005,9 +1005,9 @@ Released on February 6, 2025.- Supports DeepSeek R1 and DeepSeek V3.- GraphRAG refactor: Knowledge graph is dynamically built on an entire dataset rather than on an individual file, and automatically updated when a newly uploaded file starts parsing. See [here](./guides/dataset/advanced/construct_knowledge_graph.md).-- Adds an **Iteration** agent component and a **Research report generator** agent template. See [here](./guides/agent/agent_component_reference/iteration.mdx).+- Adds an **Iteration** agent component and a **Research report generator** agent template. See [here](./guides/agent/agent_workflow/flow_components.md#iteration).- New UI language: Portuguese.-- Allows setting metadata for a specific file in a dataset to enhance AI-powered chats. See [here](./guides/dataset/set_metadata.md).+- Allows setting metadata for a specific file in a dataset to enhance AI-powered chats. See [here](./guides/dataset/metadata_management.md).- Upgrades RAGFlow's document engine [Infinity](https://github.com/infiniflow/infinity) to v0.6.0.dev3.- Supports GPU acceleration for DeepDoc (see [docker-compose-gpu.yml](https://github.com/infiniflow/ragflow/blob/main/docker/docker-compose-gpu.yml)).- Supports creating and referencing a **Tag** dataset as a key milestone towards bridging the semantic gap between query and response.@@ -1020,21 +1020,21 @@ The **Tag dataset** feature is *unavailable* on the [Infinity](https://github.co#### Added documents-- [Construct knowledge graph](./guides/dataset/advanced/construct_knowledge_graph.md)-- [Set metadata](./guides/dataset/set_metadata.md)-- [Begin component](./guides/agent/agent_component_reference/begin.md)-- [Generate component](./guides/agent/agent_component_reference/generate.mdx)-- [Interact component](./guides/agent/agent_component_reference/interact.mdx)-- [Retrieval component](./guides/agent/agent_component_reference/retrieval.mdx)-- [Categorize component](./guides/agent/agent_component_reference/categorize.mdx)-- [Keyword component](./guides/agent/agent_component_reference/keyword.mdx)-- [Message component](./guides/agent/agent_component_reference/message.md)-- [Rewrite component](./guides/agent/agent_component_reference/rewrite.mdx)-- [Switch component](./guides/agent/agent_component_reference/switch.mdx)-- [Concentrator component](./guides/agent/agent_component_reference/concentrator.mdx)-- [Template component](./guides/agent/agent_component_reference/template.mdx)-- [Iteration component](./guides/agent/agent_component_reference/iteration.mdx)-- [Note component](./guides/agent/agent_component_reference/note.mdx)+- [Construct knowledge graph]+- [Set metadata](./guides/dataset/metadata_management.md)+- [Begin component](./guides/agent/agent_workflow/basic_component.md#begin-component)+- [Generate component]+- [Interact component]+- [Retrieval component](./guides/agent/agent_workflow/basic_component.md#retrieval-component)+- [Categorize component](./guides/agent/agent_workflow/flow_components.md#categorize-component)+- [Keyword component]+- [Message component](./guides/agent/agent_workflow/dialogue_component.md#reply-message-component)+- [Rewrite component]+- [Switch component](./guides/agent/agent_workflow/flow_components.md#switch-component)+- [Concentrator component]+- [Template component]+- [Iteration component](./guides/agent/agent_workflow/flow_components.md#iteration)+- [Note component]## v0.15.1@@ -1146,7 +1146,7 @@ From this release onwards, **service_config.yaml.template** replaces **service_cThis approach eliminates the need to manually update **service_config.yaml** after making changes to **.env**, facilitating dynamic environment configurations.:::danger IMPORTANT-Ensure that you [upgrade **both** your code **and** Docker image to this release](./administrator/upgrade_ragflow.mdx#upgrade-ragflow-to-the-most-recent-officially-published-release) before trying this new approach.+Ensure that you [upgrade **both** your code **and** Docker image to this release](./administrator/upgrade_ragflow.mdx#upgrade-ragflow-to-given-release) before trying this new approach.:::### API changes@@ -1166,7 +1166,7 @@ Ensure that you [upgrade **both** your code **and** Docker image to this release#### Added documents- [Configurations](https://ragflow.io/docs/dev/configurations)-- [Manage team members](./guides/team/manage_team_members.md)+- [Manage team members](./guides/team/team_management/index.md)- [Run health check on RAGFlow's dependencies](https://ragflow.io/docs/dev/run_health_check)## v0.13.0