RAGFlow is an agent-native database: a Retrieval-Augmented Generation (RAG) engine that grew into context infrastructure.
Go agent-harnessagent-native-databaseagentic-aiagentic-retrievalagentic-searchaiai-agentscontext-enginecontext-engineeringcontext-managementharness-engineeringknowledge-compilationragretrieval-augmented-generationretrieval-harnesssearch-harness
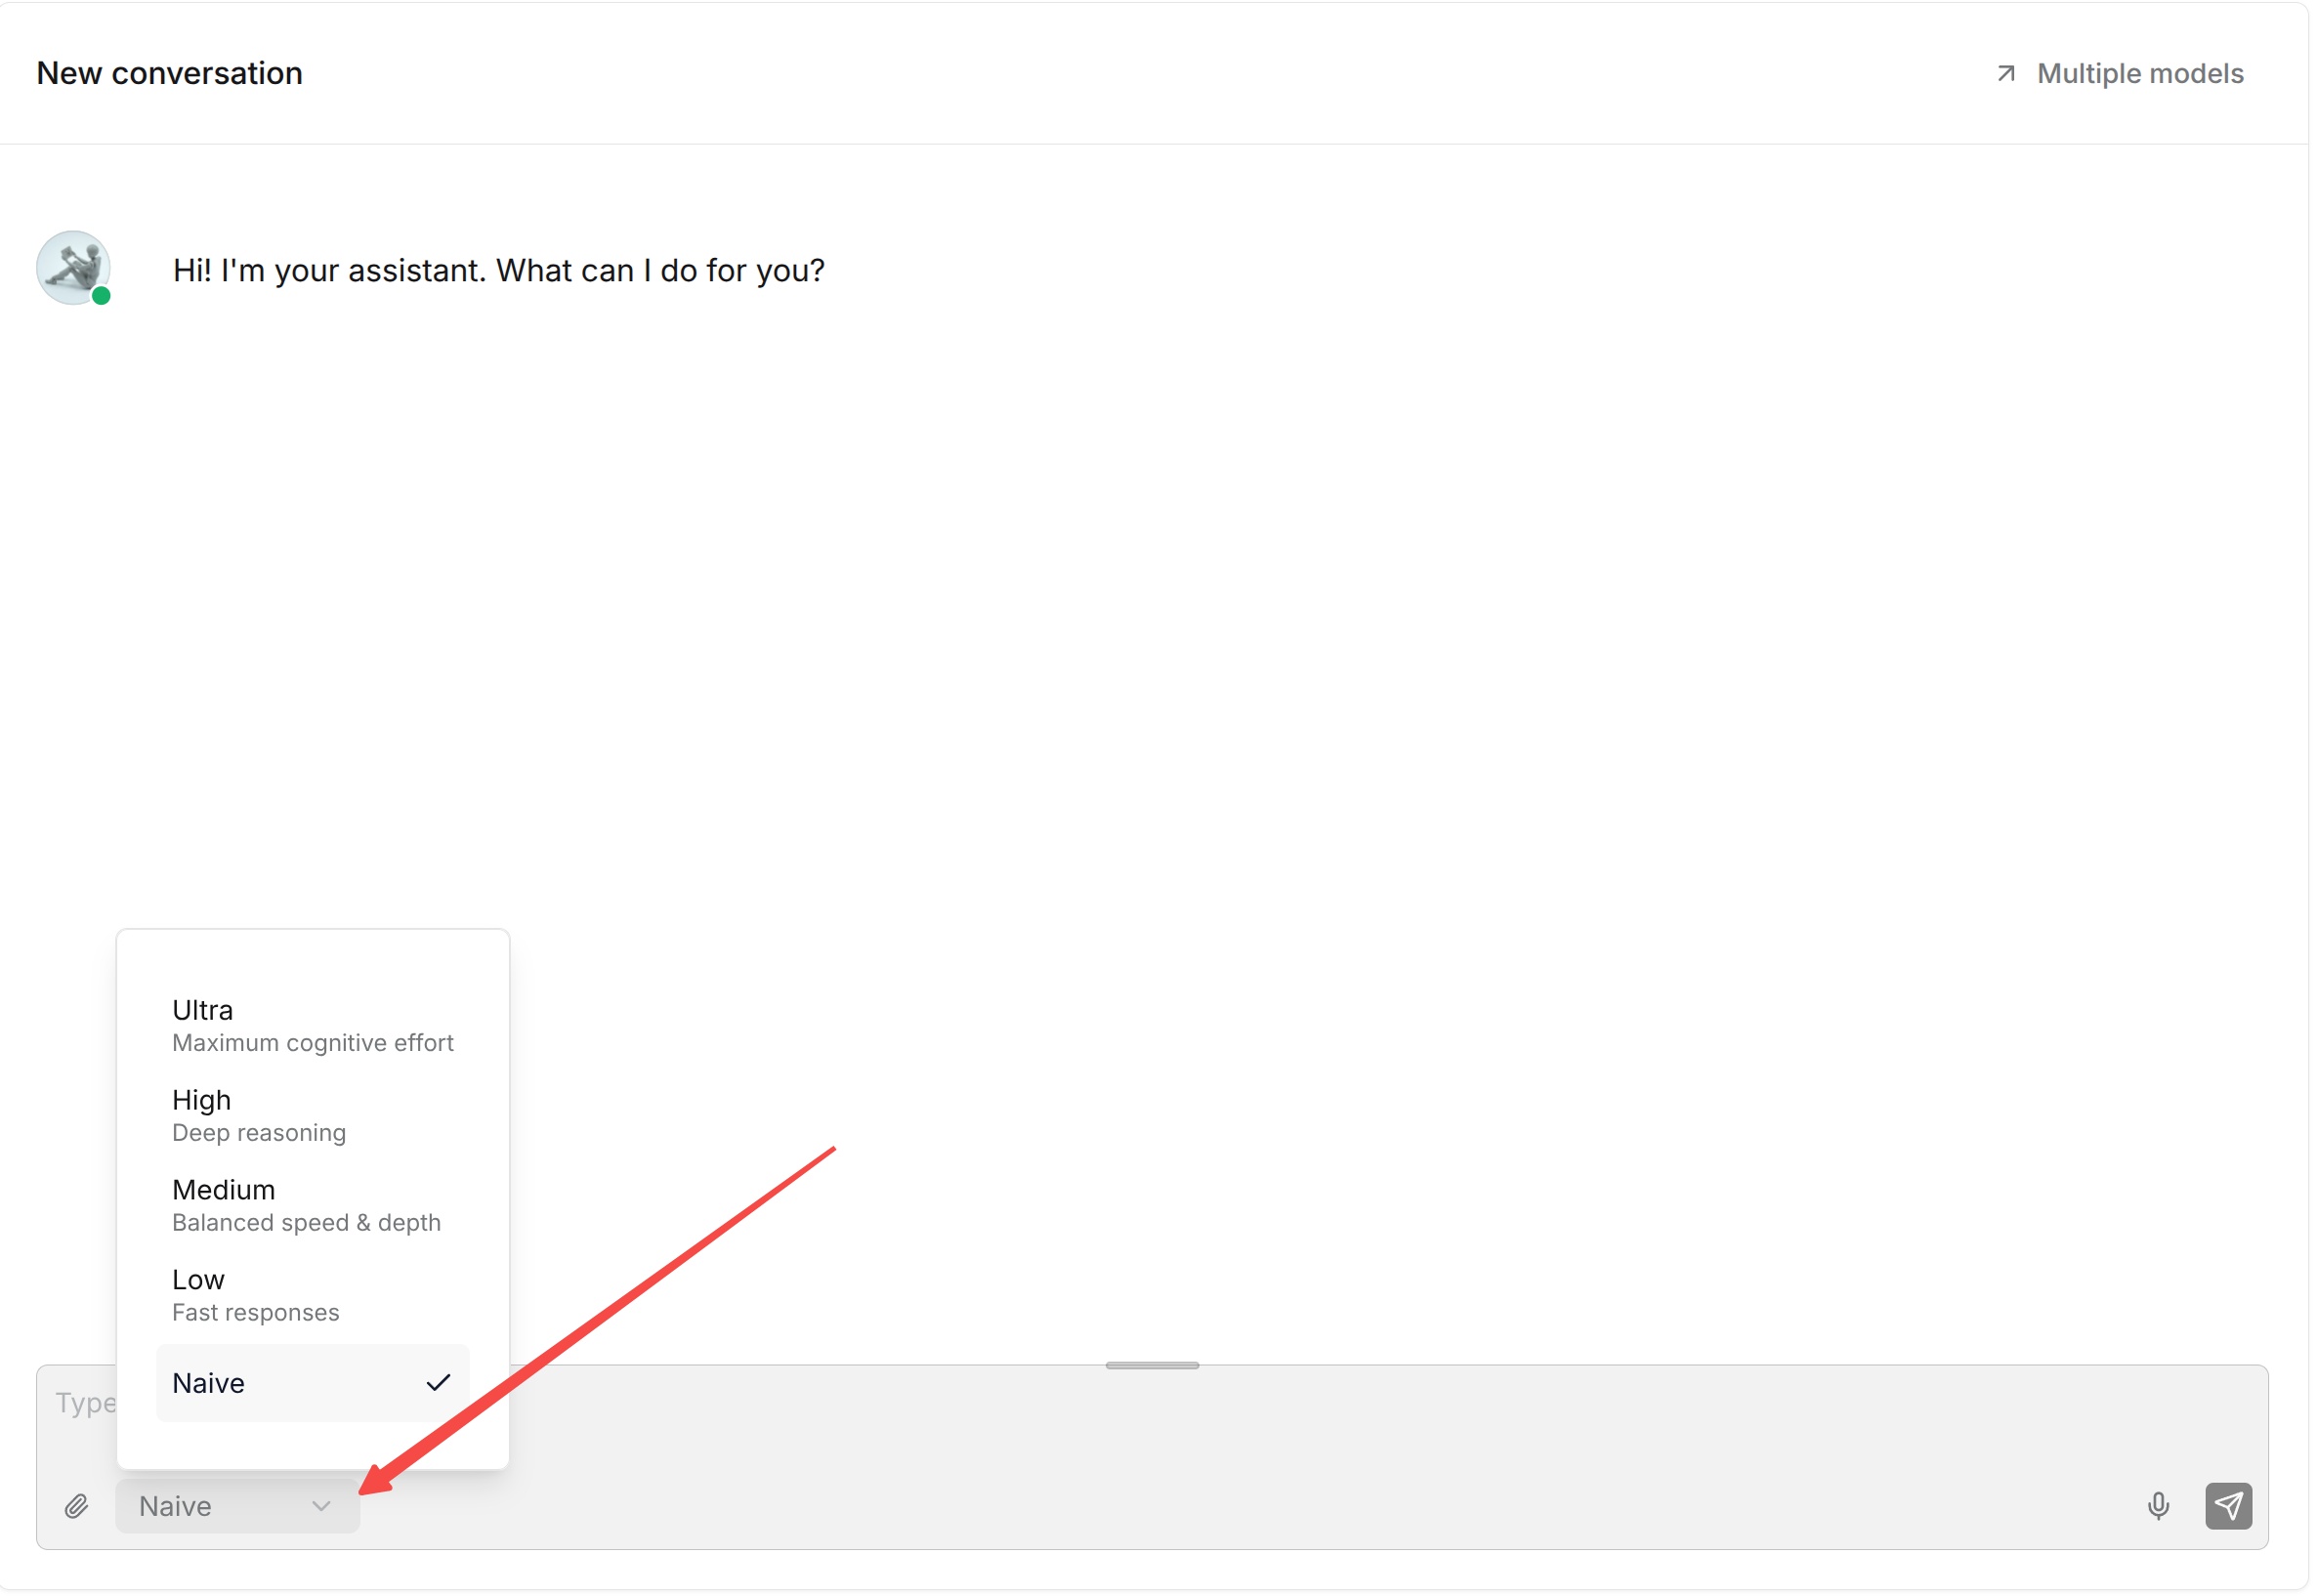
docs(chat): describe the two remaining thinking modes (#20916)
Caobaining1b350526d3fe2
diff --git a/docs/guides/chat/chat_configuration.md b/docs/guides/chat/chat_configuration.mdindex 0e27592707..211151d009 100644--- a/docs/guides/chat/chat_configuration.md+++ b/docs/guides/chat/chat_configuration.md@@ -84,23 +84,20 @@ Choose a configuration according to the scenario:An empty response is triggered only when retrieval finds no usable content. If any usable result exists, the system normally continues model generation; it does not decide based on whether the final answer is complete.-The Thinking mode also affects this process. Higher Thinking modes perform more retrieval and reasoning before returning an empty response. **Low** makes a quick determination, **Medium** performs standard processing, and **High** or **Ultra** conducts multiple rounds of deeper retrieval. An empty response is returned only when the system ultimately determines that it cannot answer.+The Thinking mode also affects this process. **Agentic** investigates the data with its own retrieval tools before answering, so it performs more retrieval and reasoning than **Naive** before returning an empty response. An empty response is returned only when the system ultimately determines that it cannot answer.## Select a Thinking Mode-Thinking mode determines how deeply Chat investigates available data before answering.+Thinking mode determines how Chat investigates available data before answering.-Before asking a question, select **Naive**, **Low**, **Medium**, **High**, or **Ultra** from the Thinking menu near the message box.+Before asking a question, select **Naive** or **Agentic** from the Thinking menu near the message box.Retrieval means searching for evidence before answering. If a dataset is associated with the Chat, the system retrieves relevant chunks. If web search is enabled, or the current version provides PageIndex or Graph capabilities, those sources can also be used as supplemental evidence. The final answer should be based on the retrieved content.-- **None**: Performs retrieval without complex analysis. Use it for straightforward factual questions when identifiers, terms, or locations are clearly present in a document. It generally uses one query and responds fastest. It can be used together with empty responses and citations.-- **Low**: Performs slightly more retrieval than **None** while remaining fast. It is suitable for enhanced basic retrieval, but not for multi-step comparisons or complex judgments.-- **Medium** (recommended starting point): Suitable for most formal dataset Q&A, questions with multiple conditions or context, and summaries of multiple paragraphs. It first clarifies or rewrites the question, then retrieves and integrates evidence.-- **High**: Suitable for complex Q&A, cross-chapter or cross-document questions, process and policy explanations, comparisons, and multi-condition judgments. It splits the problem more actively and checks whether the evidence is sufficient, so it may take longer and invoke the model more often.-- **Ultra**: Suitable for version-difference analysis, multi-document research, complex attribution, multi-hop relationships, and questions whose answers are distributed across several documents. It performs the most retrieval and analysis, generally takes the longest, and is not recommended as the default configuration for everyday Q&A.+- **Naive**: Performs retrieval without complex analysis. Use it for straightforward factual questions when identifiers, terms, or locations are clearly present in a document. It generally uses one query and responds fastest. It can be used together with empty responses and citations.+- **Agentic**: Hands the turn to a retrieval agent that searches the corpus itself — locating passages, reading documents in depth, and combining evidence across several of them — before answering. Use it for cross-document questions, comparisons, and multi-step research. It takes longer and invokes the model more often.-If you are unsure which mode to choose, start with **Medium** for formal business Q&A. For simple questions or when speed is critical, use **None** or **Low**. If the answer is incomplete or requires cross-document comparison, move up to **High** or **Ultra**.+If you are unsure which mode to choose, use **Naive** for straightforward questions or when speed is critical, and **Agentic** when the answer is incomplete or requires cross-document comparison.