
💡 All-in-one AI framework for semantic search, LLM orchestration and language model workflows
Python agentsaiai-agentsembeddingsinformation-retrievallanguage-modellarge-language-modelsllmnlppythonragretrieval-augmented-generationsearchsearch-enginesemantic-searchsentence-embeddingstransformerstxtaivector-databasevector-search
Add documentation site #75
davidmezzetti34fd08958f87
diff --git a/.github/workflows/docs.yml b/.github/workflows/docs.ymlnew file mode 100644index 00000000..872f684a--- /dev/null+++ b/.github/workflows/docs.yml@@ -0,0 +1,16 @@+name: docs+on:+ push:+ branches:+ - master+jobs:+ deploy:+ runs-on: ubuntu-latest+ steps:+ - uses: actions/checkout@v2+ - uses: actions/setup-python@v2+ with:+ python-version: 3.6+ - run: pip install mkdocs-material+ - run: mkdocs gh-deploy --force+\ No newline at end of filediff --git a/README.md b/README.mdindex f57fccde..dee829c6 100644--- a/README.md+++ b/README.md@@ -29,23 +29,29 @@--------------------------------------------------------------------------------------------------------------------------------------------------------txtai builds an AI-powered index over sections of text. txtai supports building text indices to perform similarity searches and create extractive question-answering based systems. txtai also has functionality for zero-shot classification.+txtai executes machine-learning workflows to transform data and build AI-powered text indices to perform similarity search.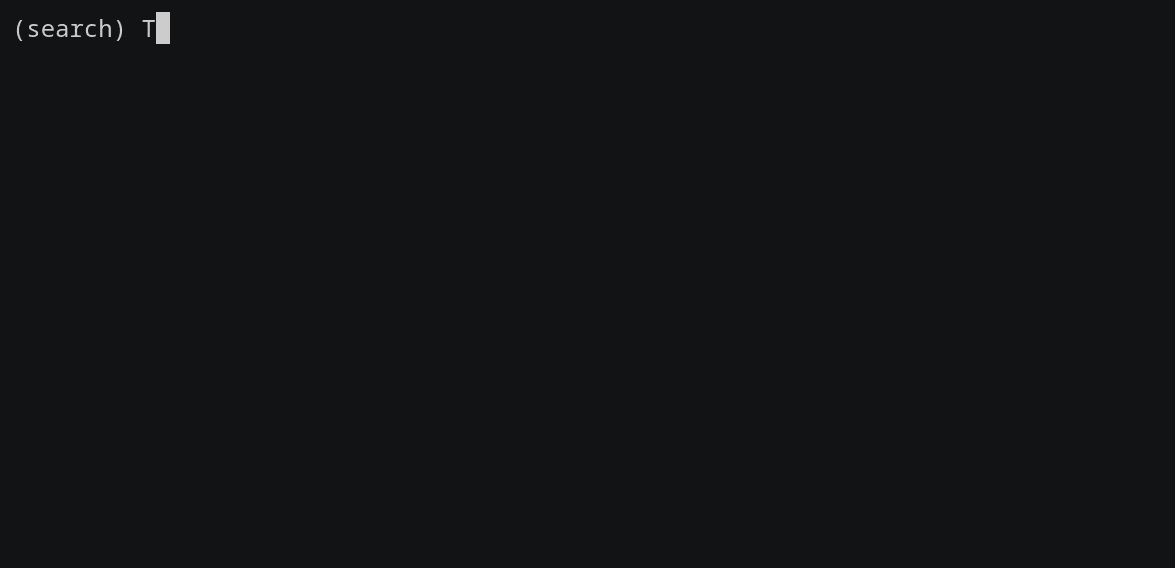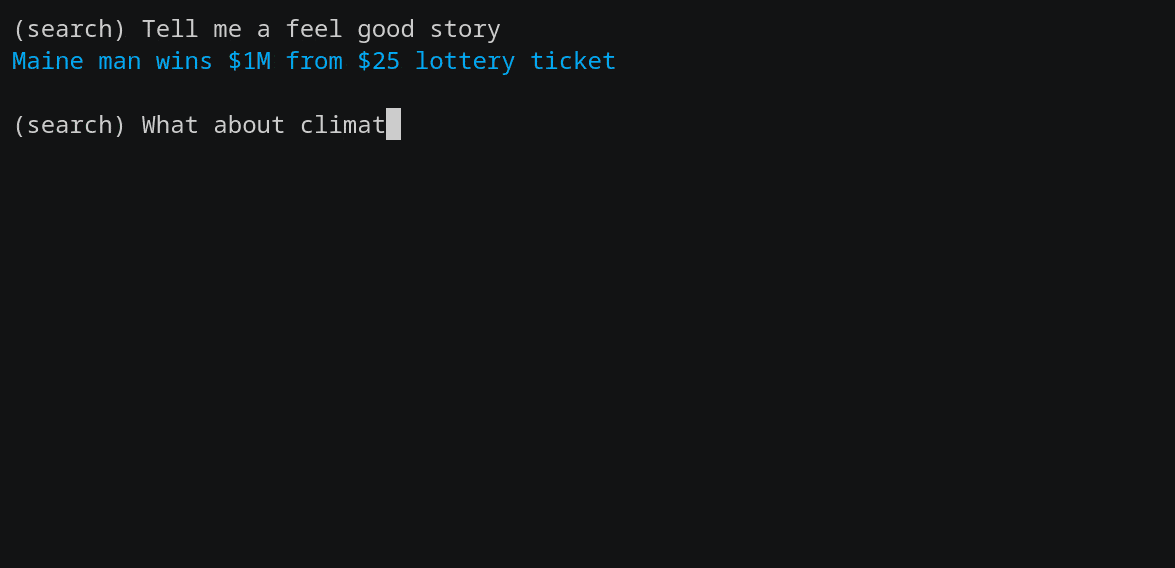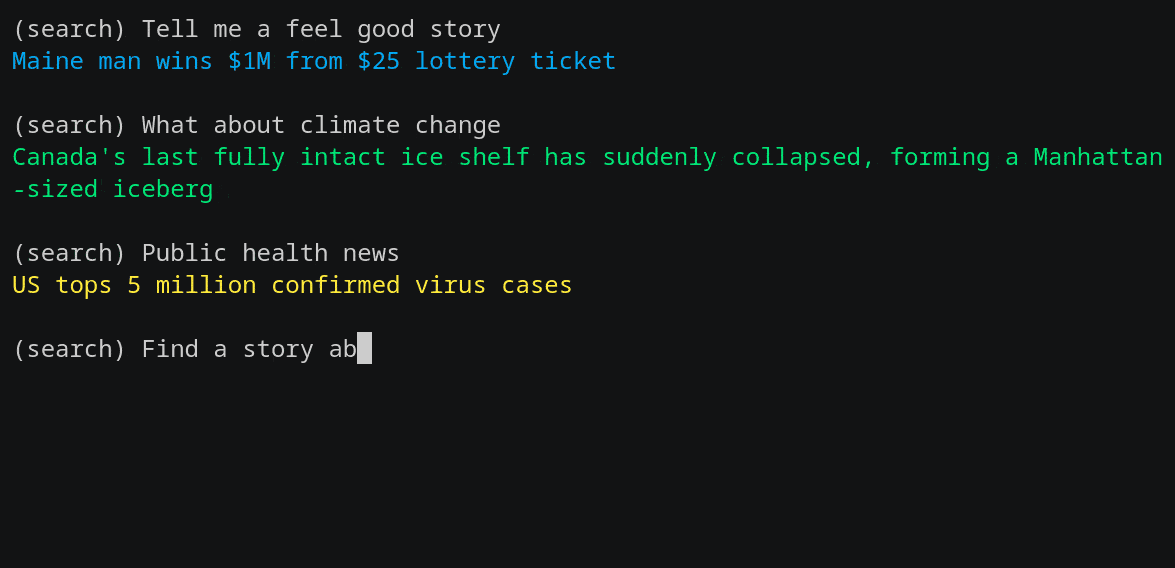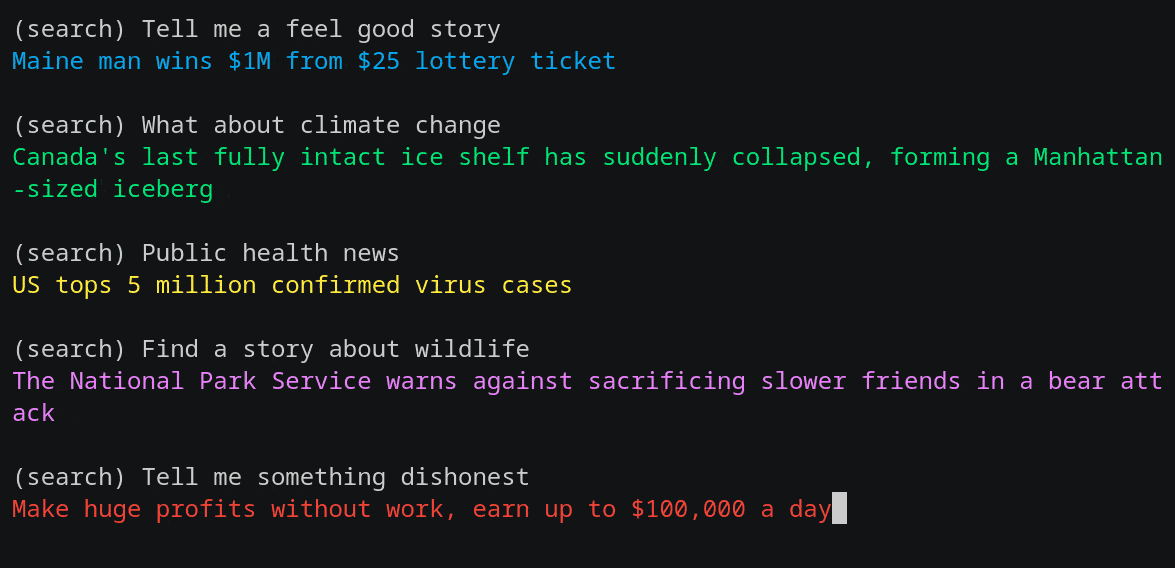-NeuML uses txtai and/or the concepts behind it to power all of our Natural Language Processing (NLP) applications. Example applications:+Summary of txtai features:-- [paperai](https://github.com/neuml/paperai) - AI-powered literature discovery and review engine for medical/scientific papers-- [tldrstory](https://github.com/neuml/tldrstory) - AI-powered understanding of headlines and story text-- [neuspo](https://neuspo.com) - Fact-driven, real-time sports event and news site-- [codequestion](https://github.com/neuml/codequestion) - Ask coding questions directly from the terminal+- 🔎 Large-scale similarity search with multiple index backends ([Faiss](https://github.com/facebookresearch/faiss), [Annoy](https://github.com/spotify/annoy), [Hnswlib](https://github.com/nmslib/hnswlib))+- 📄 Create embeddings for text snippets, documents, audio and images. Supports word and transformer vectors.+- 💡 Machine-learning pipelines to run extractive question-answering, zero-shot labeling, transcription, translation, summarization and text extraction+- ↪️️ Workflows that join multiple pipelines together to execute higher level business logic. txtai processes can be microservices or full-fledged indexing workflows.+- 🔗 API that supports [JavaScript](https://github.com/neuml/txtai.js), [Java](https://github.com/neuml/txtai.java), [Rust](https://github.com/neuml/txtai.rs) and [Go](https://github.com/neuml/txtai.go)+- ☁️ Cloud-native architecture that scales out with container orchestration systems (e.g. Kubernetes)-txtai is built on the following stack:+NeuML uses txtai and/or the concepts behind it to power all of our Natural Language Processing (NLP) applications. Applications include:-- [sentence-transformers](https://github.com/UKPLab/sentence-transformers)-- [transformers](https://github.com/huggingface/transformers)-- [faiss](https://github.com/facebookresearch/faiss)-- Python 3.6++| Application | Description |+|:----------|:-------------|+| [paperai](https://github.com/neuml/paperai) | AI-powered literature discovery and review engine for medical/scientific papers |+| [tldrstory](https://github.com/neuml/tldrstory) | AI-powered understanding of headlines and story text |+| [neuspo](https://neuspo.com) | Fact-driven, real-time sports event and news site |+| [codequestion](https://github.com/neuml/codequestion) | Ask coding questions directly from the terminal |++txtai is built with Python 3.6+, [Hugging Face Transformers](https://github.com/huggingface/transformers), [Sentence Transformers](https://github.com/UKPLab/sentence-transformers) and [FastAPI](https://github.com/tiangolo/fastapi)## Installation@@ -57,21 +63,23 @@ You can also install txtai directly from GitHub. Using a Python Virtual Environmpip install git+https://github.com/neuml/txtai-Python 3.6+ is supported--Windows and macOS systems have the following prerequisites. No additional steps for Linux.+Python 3.6+ is supported. txtai has the following environment specific prerequisites.-### Windows+### Linux-Install [C++ Build Tools](https://visualstudio.microsoft.com/visual-cpp-build-tools/)+Optional audio transcription requires a [system library to be installed](https://github.com/bastibe/python-soundfile#installation)### macOSRun `brew install libomp` see [this link](https://github.com/kyamagu/faiss-wheels#prerequisite)+### Windows++Install [C++ Build Tools](https://visualstudio.microsoft.com/visual-cpp-build-tools/)+## Examples-The examples directory has a series of examples and notebooks giving an overview of txtai. See the list of notebooks below.+The examples directory has a series of notebooks and applications giving an overview of txtai. See the sections below.### Notebooks@@ -92,271 +100,16 @@ The examples directory has a series of examples and notebooks giving an overview| [Similarity search with images](https://github.com/neuml/txtai/blob/master/examples/13_Similarity_search_with_images.ipynb) | Embed images and text into the same space for search | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/13_Similarity_search_with_images.ipynb) || [Run pipeline workflows](https://github.com/neuml/txtai/blob/master/examples/14_Run_pipeline_workflows.ipynb) | Simple yet powerful constructs to efficiently process data | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/14_Run_pipeline_workflows.ipynb) |-## Configuration--The following sections cover available settings for each txtai component. See the example notebooks for detailed examples on how to use each txtai component.--### Embeddings--An Embeddings instance is the engine that provides similarity search. Embeddings can be used to run ad-hoc similarity comparisions or build/search large indices.--Embeddings parameters are set through the constructor. Examples below.--```python-# Transformers embeddings model-Embeddings({"method": "transformers",- "path": "sentence-transformers/bert-base-nli-mean-tokens"})--# Word embeddings model-Embeddings({"path": vectors,- "storevectors": True,- "scoring": "bm25",- "pca": 3,- "quantize": True})-```--#### method-```yaml-method: transformers|words-```--Sets the sentence embeddings method to use. When set to _transformers_, the embeddings object builds sentence embeddings using the sentence transformers. Otherwise a word embeddings model is used. Defaults to words.--#### path-```yaml-path: string-```--Required field that sets the path for a vectors model. When method set to _transformers_, this must be a path to a Hugging Face transformers model. Otherwise,-it must be a path to a local word embeddings model.--#### tokenize-```yaml-tokenize: boolean-```--Enables string tokenization (defaults to true). This method applies tokenization rules that work best with English language text and help increase the-quality of English language sentence embeddings. This should be disabled when working with non-English text.--#### storevectors-```yaml-storevectors: boolean-```--Enables copying of a vectors model set in path into the embeddings models output directory on save. This option enables a fully encapsulated index with no external file dependencies.--#### scoring-```yaml-scoring: bm25|tfidf|sif-```--For word embedding models, a scoring model allows building weighted averages of word vectors for a given sentence. Supports BM25, tf-idf and SIF (smooth inverse frequency) methods. If a scoring method is not provided, mean sentence embeddings are built.--#### pca-```yaml-pca: int-```--Removes _n_ principal components from generated sentence embeddings. When enabled, a TruncatedSVD model is built to help with dimensionality reduction. After pooling of vectors creates a single sentence embedding, this method is applied.--#### backend-```yaml-backend: annoy|faiss|hnsw-```--Approximate Nearest Neighbor (ANN) index backend for storing generated sentence embeddings. Defaults to Faiss for Linux/macOS and Annoy for Windows. Faiss currently is not supported on Windows.--Backend-specific settings are set with a corresponding configuration object having the same name as the backend (i.e. annoy, faiss, or hnsw). None of these are required and are set to defaults if omitted.--#### annoy-```yaml-annoy:- ntrees: number of trees (int) - defaults to 10- searchk: search_k search setting (int) - defaults to -1-```--See [Annoy documentation](https://github.com/spotify/annoy#full-python-api) for more information on these parameters.--#### faiss-```yaml-faiss:- components: Comma separated list of components - defaults to None- nprobe: search probe setting (int) - defaults to 6-```--See Faiss documentation on the [index factory](https://github.com/facebookresearch/faiss/wiki/The-index-factory) and [search](https://github.com/facebookresearch/faiss/wiki/Faster-search) for more information on these parameters.--#### hnsw-```yaml-hnsw:- efconstruction: ef_construction param for init_index (int) - defaults to 200- m: M param for init_index (int) - defaults to 16- randomseed: random-seed param for init_index (init) - defaults to 100- efsearch: ef search param (int) - defaults to None and not set-```--See [Hnswlib documentation](https://github.com/nmslib/hnswlib/blob/master/ALGO_PARAMS.md) for more information on these parameters.--#### quantize-```yaml-quantize: boolean-```--Enables quanitization of generated sentence embeddings. If the index backend supports it, sentence embeddings will be stored with 8-bit precision vs 32-bit.-Only Faiss currently supports quantization.--### Pipelines--txtai provides a light wrapper around a couple of the Hugging Face pipelines. All pipelines have the following common parameters.--#### path-```yaml-path: string-```--Required path to a Hugging Face model--#### quantize-```yaml-quantize: boolean-```--Enables dynamic quantization of the Hugging Face model. This is a runtime setting and doesn't save space. It is used to improve the inference time performance of models.--#### gpu-```yaml-gpu: boolean-```--Enables GPU inference.--#### model-```yaml-model: Hugging Face pipeline or txtai pipeline-```--Shares the underlying model of the passed in pipeline with this pipeline. This allows having variations of a pipeline without having to store multiple copies of the full model in memory.--### Extractor--An Extractor pipeline is a combination of an embeddings query and an Extractive QA model. Filtering the context for a QA model helps maximize performance of the model.--Extractor parameters are set as constructor arguments. Examples below.--```python-Extractor(embeddings, path, quantize, gpu, model, tokenizer)-```--#### embeddings-```yaml-embeddings: Embeddings object instance-```--Embeddings object instance. Used to query and find candidate text snippets to run the question-answer model against.--#### tokenizer-```yaml-tokenizer: Tokenizer function-```--Optional custom tokenizer function to parse input queries--### Labels--A Labels pipeline uses a zero shot classification model to apply labels to input text.--Labels parameters are set as constructor arguments. Examples below.--```python-Labels()-Labels("roberta-large-mnli")-```--### Similarity--A Similarity pipeline is also a zero shot classifier model where the labels are the queries. The results are transposed to get scores per query/label vs scores per input text.--Similarity parameters are set as constructor arguments. Examples below.--```python-Similarity()-Similarity("roberta-large-mnli")-```--### API--txtai has a full-featured API that can optionally be enabled for any txtai process. All functionality found in txtai can be accessed via the API. The following is an example configuration and startup script for the API.--Note that this configuration file enables all functionality (embeddings, extractor, labels, similarity). It is suggested that separate processes are used for each instance of a txtai component.--```yaml-# Index file path-path: /tmp/index--# Allow indexing of documents-writable: True--# Embeddings settings-embeddings:- method: transformers- path: sentence-transformers/bert-base-nli-mean-tokens--# Extractor settings-extractor:- path: distilbert-base-cased-distilled-squad--# Labels settings-labels:--# Similarity settings-similarity:-```--Assuming this YAML content is stored in a file named index.yml, the following command starts the API process.--```-CONFIG=index.yml uvicorn "txtai.api:app"-```--uvicorn is a full-featured production ready server with support for SSL and more. See the [uvicorn deployment guide](https://www.uvicorn.org/deployment/) for details.--#### Docker--A Dockerfile with commands to install txtai, all dependencies and default configuration is available in this repository.--The Dockerfile can be copied from the docker directory on GitHub locally. The following commands show how to run the API process.--```bash-docker build -t txtai.api -f docker/api.Dockerfile .-docker run --name txtai.api -p 8000:8000 --rm -it txtai.api--# Alternatively, if nvidia-docker is installed, the build will support GPU runtimes-docker run --name txtai.api --runtime=nvidia -p 8000:8000 --rm -it txtai.api-```--This will bring up an API instance without having to install Python, txtai or any dependencies on your machine!--#### Differences between Python and API--The txtai API provides all the major functionality found in this project. But there are differences due to the nature of JSON and differences across the supported programming languages.--| Difference | Python | API | Reason |-|:-------------|:-------------|:------|:---------|-| Return Types | tuples | objects | Consistency across languages. For example, (id, score) in Python is {"id": value, "score": value} via API |-| Extractor | extract() | extractor.extract() | Extractor pipeline is a callable object in Python |-| Labels | labels() | labels.label() | Labels pipeline is a callable object in Python that supports both string and list input |-| Similarity | similarity() | similarity.similarity() | Similarity pipeline a callable object in Python that supports both string and list input |--#### Supported language bindings+### Applications-The following programming languages have txtai bindings:+| Application | Description |+|:----------|:-------------|+| [Demo query shell](https://github.com/neuml/txtai/blob/master/examples/demo.py) | Example application for search and indexing |+| [Image search](https://github.com/neuml/txtai/blob/master/examples/images.py) | Streamlit image search application |-- [JavaScript](https://github.com/neuml/txtai.js)-- [Java](https://github.com/neuml/txtai.java)-- [Rust](https://github.com/neuml/txtai.rs)-- [Go](https://github.com/neuml/txtai.go)+### Documentation-See each of the projects above for details on how to install and use. Please add an issue to request additional language bindings!+Full documentation on txtai including configuration settings for pipelines, workflows, indexing and the API can be found here - [https://neuml.github.io/txtai](https://neuml.github.io/txtai)### Contributingdiff --git a/docs/api.md b/docs/api.mdnew file mode 100644index 00000000..ae485be5--- /dev/null+++ b/docs/api.md@@ -0,0 +1,74 @@+# API++txtai has a full-featured API that can optionally be enabled for any txtai process. All functionality found in txtai can be accessed via the API. The following is an example configuration and startup script for the API.++Note that this configuration file enables all functionality (embeddings, extractor, labels, similarity). It is suggested that separate processes are used for each instance of a txtai component.++```yaml+# Index file path+path: /tmp/index++# Allow indexing of documents+writable: True++# Embeddings settings+embeddings:+ method: transformers+ path: sentence-transformers/bert-base-nli-mean-tokens++# Extractor settings+extractor:+ path: distilbert-base-cased-distilled-squad++# Labels settings+labels:++# Similarity settings+similarity:+```++Assuming this YAML content is stored in a file named index.yml, the following command starts the API process.++```+CONFIG=index.yml uvicorn "txtai.api:app"+```++uvicorn is a full-featured production ready server with support for SSL and more. See the [uvicorn deployment guide](https://www.uvicorn.org/deployment/) for details.++## Docker++A Dockerfile with commands to install txtai, all dependencies and default configuration is available in this repository.++The Dockerfile can be copied from the docker directory on GitHub locally. The following commands show how to run the API process.++```bash+docker build -t txtai.api -f docker/api.Dockerfile .+docker run --name txtai.api -p 8000:8000 --rm -it txtai.api++# Alternatively, if nvidia-docker is installed, the build will support GPU runtimes+docker run --name txtai.api --runtime=nvidia -p 8000:8000 --rm -it txtai.api+```++This will bring up an API instance without having to install Python, txtai or any dependencies on your machine!++## Differences between Python and API++The txtai API provides all the major functionality found in this project. But there are differences due to the nature of JSON and differences across the supported programming languages.++| Difference | Python | API | Reason |+|:-------------|:-------------|:------|:---------|+| Return Types | tuples | objects | Consistency across languages. For example, (id, score) in Python is {"id": value, "score": value} via API |+| Extractor | extract() | extractor.extract() | Extractor pipeline is a callable object in Python |+| Labels | labels() | labels.label() | Labels pipeline is a callable object in Python that supports both string and list input |+| Similarity | similarity() | similarity.similarity() | Similarity pipeline a callable object in Python that supports both string and list input |++## Supported language bindings++The following programming languages have txtai bindings:++- [JavaScript](https://github.com/neuml/txtai.js)+- [Java](https://github.com/neuml/txtai.java)+- [Rust](https://github.com/neuml/txtai.rs)+- [Go](https://github.com/neuml/txtai.go)++See each of the projects above for details on how to install and use. Please add an issue to request additional language bindings!diff --git a/docs/embeddings.md b/docs/embeddings.mdnew file mode 100644index 00000000..81671dbb--- /dev/null+++ b/docs/embeddings.md@@ -0,0 +1,108 @@+# Embeddings++An Embeddings instance is the engine that provides similarity search. Embeddings can be used to run ad-hoc similarity comparisions or build/search large indices.++Embeddings parameters are set through the constructor. Examples below.++```python+# Transformers embeddings model+Embeddings({"method": "transformers",+ "path": "sentence-transformers/bert-base-nli-mean-tokens"})++# Word embeddings model+Embeddings({"path": vectors,+ "storevectors": True,+ "scoring": "bm25",+ "pca": 3,+ "quantize": True})+```++## method+```yaml+method: transformers|words+```++Sets the sentence embeddings method to use. When set to _transformers_, the embeddings object builds sentence embeddings using the sentence transformers. Otherwise a word embeddings model is used. Defaults to words.++## path+```yaml+path: string+```++Required field that sets the path for a vectors model. When method set to _transformers_, this must be a path to a Hugging Face transformers model. Otherwise,+it must be a path to a local word embeddings model.++## tokenize+```yaml+tokenize: boolean+```++Enables string tokenization (defaults to true). This method applies tokenization rules that work best with English language text and help increase the+quality of English language sentence embeddings. This should be disabled when working with non-English text.++## storevectors+```yaml+storevectors: boolean+```++Enables copying of a vectors model set in path into the embeddings models output directory on save. This option enables a fully encapsulated index with no external file dependencies.++## scoring+```yaml+scoring: bm25|tfidf|sif+```++For word embedding models, a scoring model allows building weighted averages of word vectors for a given sentence. Supports BM25, tf-idf and SIF (smooth inverse frequency) methods. If a scoring method is not provided, mean sentence embeddings are built.++## pca+```yaml+pca: int+```++Removes _n_ principal components from generated sentence embeddings. When enabled, a TruncatedSVD model is built to help with dimensionality reduction. After pooling of vectors creates a single sentence embedding, this method is applied.++## backend+```yaml+backend: annoy|faiss|hnsw+```++Approximate Nearest Neighbor (ANN) index backend for storing generated sentence embeddings. Defaults to Faiss for Linux/macOS and Annoy for Windows. Faiss currently is not supported on Windows.++Backend-specific settings are set with a corresponding configuration object having the same name as the backend (i.e. annoy, faiss, or hnsw). None of these are required and are set to defaults if omitted.++## annoy+```yaml+annoy:+ ntrees: number of trees (int) - defaults to 10+ searchk: search_k search setting (int) - defaults to -1+```++See [Annoy documentation](https://github.com/spotify/annoy#full-python-api) for more information on these parameters.++## faiss+```yaml+faiss:+ components: Comma separated list of components - defaults to None+ nprobe: search probe setting (int) - defaults to 6+```++See Faiss documentation on the [index factory](https://github.com/facebookresearch/faiss/wiki/The-index-factory) and [search](https://github.com/facebookresearch/faiss/wiki/Faster-search) for more information on these parameters.++## hnsw+```yaml+hnsw:+ efconstruction: ef_construction param for init_index (int) - defaults to 200+ m: M param for init_index (int) - defaults to 16+ randomseed: random-seed param for init_index (init) - defaults to 100+ efsearch: ef search param (int) - defaults to None and not set+```++See [Hnswlib documentation](https://github.com/nmslib/hnswlib/blob/master/ALGO_PARAMS.md) for more information on these parameters.++## quantize+```yaml+quantize: boolean+```++Enables quanitization of generated sentence embeddings. If the index backend supports it, sentence embeddings will be stored with 8-bit precision vs 32-bit.+Only Faiss currently supports quantization.diff --git a/docs/examples.md b/docs/examples.mdnew file mode 100644index 00000000..48be5553--- /dev/null+++ b/docs/examples.md@@ -0,0 +1,29 @@+# Examples++The examples directory has a series of notebooks and applications giving an overview of txtai. See the sections below.++## Notebooks++| Notebook | Description | |+|:----------|:-------------|------:|+| [Introducing txtai](https://github.com/neuml/txtai/blob/master/examples/01_Introducing_txtai.ipynb) | Overview of the functionality provided by txtai | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/01_Introducing_txtai.ipynb) |+| [Build an Embeddings index with Hugging Face Datasets](https://github.com/neuml/txtai/blob/master/examples/02_Build_an_Embeddings_index_with_Hugging_Face_Datasets.ipynb) | Index and search Hugging Face Datasets | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/02_Build_an_Embeddings_index_with_Hugging_Face_Datasets.ipynb) |+| [Build an Embeddings index from a data source](https://github.com/neuml/txtai/blob/master/examples/03_Build_an_Embeddings_index_from_a_data_source.ipynb) | Index and search a data source with word embeddings | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/03_Build_an_Embeddings_index_from_a_data_source.ipynb) |+| [Add semantic search to Elasticsearch](https://github.com/neuml/txtai/blob/master/examples/04_Add_semantic_search_to_Elasticsearch.ipynb) | Add semantic search to existing search systems | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/04_Add_semantic_search_to_Elasticsearch.ipynb) |+| [Extractive QA with txtai](https://github.com/neuml/txtai/blob/master/examples/05_Extractive_QA_with_txtai.ipynb) | Introduction to extractive question-answering with txtai | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/05_Extractive_QA_with_txtai.ipynb) |+| [Extractive QA with Elasticsearch](https://github.com/neuml/txtai/blob/master/examples/06_Extractive_QA_with_Elasticsearch.ipynb) | Run extractive question-answering queries with Elasticsearch | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/06_Extractive_QA_with_Elasticsearch.ipynb) |+| [Apply labels with zero shot classification](https://github.com/neuml/txtai/blob/master/examples/07_Apply_labels_with_zero_shot_classification.ipynb) | Use zero shot learning for labeling, classification and topic modeling | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/07_Apply_labels_with_zero_shot_classification.ipynb) |+| [API Gallery](https://github.com/neuml/txtai/blob/master/examples/08_API_Gallery.ipynb) | Using txtai in JavaScript, Java, Rust and Go | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/08_API_Gallery.ipynb) |+| [Building abstractive text summaries](https://github.com/neuml/txtai/blob/master/examples/09_Building_abstractive_text_summaries.ipynb) | Run abstractive text summarization | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/09_Building_abstractive_text_summaries.ipynb) |+| [Extract text from documents](https://github.com/neuml/txtai/blob/master/examples/10_Extract_text_from_documents.ipynb) | Extract text from PDF, Office, HTML and more | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/10_Extract_text_from_documents.ipynb) |+| [Transcribe audio to text](https://github.com/neuml/txtai/blob/master/examples/11_Transcribe_audio_to_text.ipynb) | Convert audio files to text | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/11_Transcribe_audio_to_text.ipynb) |+| [Translate text between languages](https://github.com/neuml/txtai/blob/master/examples/12_Translate_text_between_languages.ipynb) | Streamline machine translation and language detection | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/12_Translate_text_between_languages.ipynb) |+| [Similarity search with images](https://github.com/neuml/txtai/blob/master/examples/13_Similarity_search_with_images.ipynb) | Embed images and text into the same space for search | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/13_Similarity_search_with_images.ipynb) |+| [Run pipeline workflows](https://github.com/neuml/txtai/blob/master/examples/14_Run_pipeline_workflows.ipynb) | Simple yet powerful constructs to efficiently process data | [](https://colab.research.google.com/github/neuml/txtai/blob/master/examples/14_Run_pipeline_workflows.ipynb) |++## Applications++| Application | Description |+|:----------|:-------------|+| [Demo query shell](https://github.com/neuml/txtai/blob/master/examples/demo.py) | Example application for search and indexing |+| [Image search](https://github.com/neuml/txtai/blob/master/examples/images.py) | Streamlit image search application |diff --git a/docs/images/logo.png b/docs/images/logo.pngnew file mode 100644index 00000000..bbd50559Binary files /dev/null and b/docs/images/logo.png differdiff --git a/docs/index.md b/docs/index.mdnew file mode 100644index 00000000..2e88c099--- /dev/null+++ b/docs/index.md@@ -0,0 +1,56 @@+#++<p align="center">+ <img src="https://raw.githubusercontent.com/neuml/txtai/master/logo.png"/>+</p>++<h3 align="center">+ <p>AI-powered search engine</p>+</h3>++<p align="center">+ <a href="https://github.com/neuml/txtai/releases">+ <img src="https://img.shields.io/github/release/neuml/txtai.svg?style=flat&color=success" alt="Version"/>+ </a>+ <a href="https://github.com/neuml/txtai/releases">+ <img src="https://img.shields.io/github/release-date/neuml/txtai.svg?style=flat&color=blue" alt="GitHub Release Date"/>+ </a>+ <a href="https://github.com/neuml/txtai/issues">+ <img src="https://img.shields.io/github/issues/neuml/txtai.svg?style=flat&color=success" alt="GitHub issues"/>+ </a>+ <a href="https://github.com/neuml/txtai">+ <img src="https://img.shields.io/github/last-commit/neuml/txtai.svg?style=flat&color=blue" alt="GitHub last commit"/>+ </a>+ <a href="https://github.com/neuml/txtai/actions?query=workflow%3Abuild">+ <img src="https://github.com/neuml/txtai/workflows/build/badge.svg" alt="Build Status"/>+ </a>+ <a href="https://coveralls.io/github/neuml/txtai?branch=master">+ <img src="https://img.shields.io/coveralls/github/neuml/txtai" alt="Coverage Status">+ </a>+</p>++-------------------------------------------------------------------------------------------------------------------------------------------------------++txtai executes machine-learning workflows to transform data and build AI-powered text indices to perform similarity search.++++Summary of txtai features:++- 🔎 Large-scale similarity search with multiple index backends ([Faiss](https://github.com/facebookresearch/faiss), [Annoy](https://github.com/spotify/annoy), [Hnswlib](https://github.com/nmslib/hnswlib))+- 📄 Create embeddings for text snippets, documents, audio and images. Supports word and transformer vectors.+- 💡 Machine-learning pipelines to run extractive question-answering, zero-shot labeling, transcription, translation, summarization and text extraction+- ↪️️ Workflows that join multiple pipelines together to execute higher level business logic. txtai processes can be microservices or full-fledged indexing workflows.+- 🔗 API that supports [JavaScript](https://github.com/neuml/txtai.js), [Java](https://github.com/neuml/txtai.java), [Rust](https://github.com/neuml/txtai.rs) and [Go](https://github.com/neuml/txtai.go)+- ☁️ Cloud-native architecture that scales out with container orchestration systems (e.g. Kubernetes)++NeuML uses txtai and/or the concepts behind it to power all of our Natural Language Processing (NLP) applications. Applications include:++| Application | Description |+|:----------|:-------------|+| [paperai](https://github.com/neuml/paperai) | AI-powered literature discovery and review engine for medical/scientific papers |+| [tldrstory](https://github.com/neuml/tldrstory) | AI-powered understanding of headlines and story text |+| [neuspo](https://neuspo.com) | Fact-driven, real-time sports event and news site |+| [codequestion](https://github.com/neuml/codequestion) | Ask coding questions directly from the terminal |++txtai is built with Python 3.6+, [Hugging Face Transformers](https://github.com/huggingface/transformers), [Sentence Transformers](https://github.com/UKPLab/sentence-transformers) and [FastAPI](https://github.com/tiangolo/fastapi)diff --git a/docs/install.md b/docs/install.mdnew file mode 100644index 00000000..d18f756a--- /dev/null+++ b/docs/install.md@@ -0,0 +1,23 @@+# Installation++The easiest way to install is via pip and PyPI++ pip install txtai++You can also install txtai directly from GitHub. Using a Python Virtual Environment is recommended.++ pip install git+https://github.com/neuml/txtai++Python 3.6+ is supported. txtai has the following environment specific prerequisites.++## Linux++Optional audio transcription requires a [system library to be installed](https://github.com/bastibe/python-soundfile#installation)++## macOS++Run `brew install libomp` see [this link](https://github.com/kyamagu/faiss-wheels#prerequisite)++## Windows++Install [C++ Build Tools](https://visualstudio.microsoft.com/visual-cpp-build-tools/)diff --git a/docs/pipelines/extractor.md b/docs/pipelines/extractor.mdnew file mode 100644index 00000000..fd83c955--- /dev/null+++ b/docs/pipelines/extractor.md@@ -0,0 +1,23 @@+# Extractor++An Extractor pipeline is a combination of an embeddings query and an Extractive QA model. Filtering the context for a QA model helps maximize performance of the model.++Extractor parameters are set as constructor arguments. Examples below.++```python+Extractor(embeddings, path, quantize, gpu, model, tokenizer)+```++## embeddings+```yaml+embeddings: Embeddings object instance+```++Embeddings object instance. Used to query and find candidate text snippets to run the question-answer model against.++## tokenizer+```yaml+tokenizer: Tokenizer function+```++Optional custom tokenizer function to parse input queriesdiff --git a/docs/pipelines/labels.md b/docs/pipelines/labels.mdnew file mode 100644index 00000000..d3fe14d9--- /dev/null+++ b/docs/pipelines/labels.md@@ -0,0 +1,10 @@+# Labels++A Labels pipeline uses a zero shot classification model to apply labels to input text.++Labels parameters are set as constructor arguments. Examples below.++```python+Labels()+Labels("roberta-large-mnli")+```diff --git a/docs/pipelines/overview.md b/docs/pipelines/overview.mdnew file mode 100644index 00000000..fdd65962--- /dev/null+++ b/docs/pipelines/overview.md@@ -0,0 +1,31 @@+# Pipelines++txtai provides a light wrapper around a couple of the Hugging Face pipelines. All pipelines have the following common parameters.++### path+```yaml+path: string+```++Required path to a Hugging Face model++### quantize+```yaml+quantize: boolean+```++Enables dynamic quantization of the Hugging Face model. This is a runtime setting and doesn't save space. It is used to improve the inference time performance of models.++### gpu+```yaml+gpu: boolean+```++Enables GPU inference.++### model+```yaml+model: Hugging Face pipeline or txtai pipeline+```++Shares the underlying model of the passed in pipeline with this pipeline. This allows having variations of a pipeline without having to store multiple copies of the full model in memory.diff --git a/docs/pipelines/similarity.md b/docs/pipelines/similarity.mdnew file mode 100644index 00000000..87f4c765--- /dev/null+++ b/docs/pipelines/similarity.md@@ -0,0 +1,10 @@+## Similarity++A Similarity pipeline is also a zero shot classifier model where the labels are the queries. The results are transposed to get scores per query/label vs scores per input text.++Similarity parameters are set as constructor arguments. Examples below.++```python+Similarity()+Similarity("roberta-large-mnli")+```diff --git a/mkdocs.yml b/mkdocs.ymlnew file mode 100644index 00000000..5f04c505--- /dev/null+++ b/mkdocs.yml@@ -0,0 +1,21 @@+site_name: txtai+theme:+ name: material+ logo: images/logo.png+ favicon: images/logo.png+ palette:+ primary: blue+ accent: blue+repo_name: neuml/txtai+repo_url: https://github.com/neuml/txtai+nav:+ - Home: index.md+ - Installation: install.md+ - Examples: examples.md+ - Embeddings: embeddings.md+ - Pipelines:+ - Overview: pipelines/overview.md+ - Extractor: pipelines/extractor.md+ - Labels: pipelines/labels.md+ - Similarity: pipelines/similarity.md+ - API: api.md