
💡 All-in-one AI framework for semantic search, LLM orchestration and language model workflows
Python agentsaiai-agentsembeddingsinformation-retrievallanguage-modellarge-language-modelsllmnlppythonragretrieval-augmented-generationsearchsearch-enginesemantic-searchsentence-embeddingstransformerstxtaivector-databasevector-search
Update documentation to use more current LLMs, closes #995
davidmezzetti4d6c0ecc4778
diff --git a/README.md b/README.mdindex d369be07..a9d6f92d 100644--- a/README.md+++ b/README.md@@ -132,7 +132,7 @@ Agents connect embeddings, pipelines, workflows and other agents together to auttxtai agents are built on top of the [smolagents](https://github.com/huggingface/smolagents) framework. This supports all LLMs txtai supports (Hugging Face, llama.cpp, OpenAI / Claude / AWS Bedrock via LiteLLM).-See the links below to learn more.+Check out this [Agent Quickstart Example](https://github.com/neuml/txtai/blob/master/examples/agent_quickstart.py). Additional examples are listed below.| Notebook | Description | ||:----------|:-------------|------:|@@ -199,7 +199,7 @@ See the table below for the current recommended models. These models all allow c| [Image Captions](https://neuml.github.io/txtai/pipeline/image/caption) | [BLIP](https://hf.co/Salesforce/blip-image-captioning-base) || [Labels - Zero Shot](https://neuml.github.io/txtai/pipeline/text/labels) | [BART-Large-MNLI](https://hf.co/facebook/bart-large) || [Labels - Fixed](https://neuml.github.io/txtai/pipeline/text/labels) | Fine-tune with [training pipeline](https://neuml.github.io/txtai/pipeline/train/trainer) |-| [Large Language Model (LLM)](https://neuml.github.io/txtai/pipeline/text/llm) | [Llama 3.1 Instruct](https://hf.co/meta-llama/Llama-3.1-8B-Instruct) |+| [Large Language Model (LLM)](https://neuml.github.io/txtai/pipeline/text/llm) | [gpt-oss-20b](https://huggingface.co/openai/gpt-oss-20b) || [Summarization](https://neuml.github.io/txtai/pipeline/text/summary) | [DistilBART](https://hf.co/sshleifer/distilbart-cnn-12-6) || [Text-to-Speech](https://neuml.github.io/txtai/pipeline/audio/texttospeech) | [ESPnet JETS](https://hf.co/NeuML/ljspeech-jets-onnx) || [Transcription](https://neuml.github.io/txtai/pipeline/audio/transcription) | [Whisper](https://hf.co/openai/whisper-base) |diff --git a/docs/agent/configuration.md b/docs/agent/configuration.mdindex 0c3b3205..0d4f05c5 100644--- a/docs/agent/configuration.md+++ b/docs/agent/configuration.md@@ -34,7 +34,7 @@ def today() -> str:return datetime.today().isoformat()agent = Agent(- model="hugging-quants/Meta-Llama-3.1-8B-Instruct-AWQ-INT4",+ model="Qwen/Qwen3-4B-Instruct-2507",tools=[today, wikipedia, arxiv, "websearch"],)```diff --git a/docs/agent/index.md b/docs/agent/index.mdindex 52d474dd..d5be6e15 100644--- a/docs/agent/index.md+++ b/docs/agent/index.md@@ -41,7 +41,7 @@ def today() -> str:return datetime.today().isoformat()agent = Agent(- model="hugging-quants/Meta-Llama-3.1-8B-Instruct-AWQ-INT4",+ model="Qwen/Qwen3-4B-Instruct-2507",tools=[today, wikipedia, arxiv, "websearch"],max_steps=10,)@@ -83,7 +83,7 @@ Agents can also be tools. This enables the concept of building "Agent Teams" to```pythonfrom txtai import Agent, LLM-llm = LLM("hugging-quants/Meta-Llama-3.1-8B-Instruct-AWQ-INT4")+llm = LLM("Qwen/Qwen3-4B-Instruct-2507")websearcher = Agent(model=llm,@@ -133,15 +133,14 @@ This provides another level of intelligence to the process. Instead of just a si```pythonagent("""-Work with your team and build a comprehensive report on fundamental-concepts about Signal Processing.+Research fundamental concepts about Signal Processing and build a comprehensive report.Write the output in Markdown.""")```# More examples-See the links below to learn more.+Check out this [Agent Quickstart Example](https://github.com/neuml/txtai/blob/master/examples/agent_quickstart.py). Additional examples are listed below.| Notebook | Description | ||:----------|:-------------|------:|diff --git a/docs/api/configuration.md b/docs/api/configuration.mdindex 4619f967..46d4abe5 100644--- a/docs/api/configuration.md+++ b/docs/api/configuration.md@@ -51,7 +51,7 @@ agent:- websearchllm:- path: hugging-quants/Meta-Llama-3.1-8B-Instruct-AWQ-INT4+ path: Qwen/Qwen3-4B-Instruct-2507```## Pipelinediff --git a/docs/faq.md b/docs/faq.mdindex 1afa0610..8b4df4ac 100644--- a/docs/faq.md+++ b/docs/faq.md@@ -68,8 +68,8 @@ import torchfrom transformers import AutoModelForCausalLM, AutoTokenizerfrom txtai import LLM-# Load Phi 3.5-mini-path = "microsoft/Phi-3.5-mini-instruct"+# Load Qwen3 0.6B+path = "Qwen/Qwen3-0.6B"model = AutoModelForCausalLM.from_pretrained(path,torch_dtype=torch.bfloat16,diff --git a/docs/models.md b/docs/models.mdindex 39385f87..da2e37c5 100644--- a/docs/models.md+++ b/docs/models.md@@ -10,7 +10,7 @@ See the table below for the current recommended models. These models all allow c| [Image Captions](./pipeline/image/caption.md) | [BLIP](https://hf.co/Salesforce/blip-image-captioning-base) || [Labels - Zero Shot](./pipeline/text/labels.md) | [BART-Large-MNLI](https://hf.co/facebook/bart-large) || [Labels - Fixed](./pipeline/text/labels.md) | Fine-tune with [training pipeline](./pipeline/train/trainer.md) |-| [Large Language Model (LLM)](./pipeline/text/llm.md) | [Llama 3.1 Instruct](https://hf.co/meta-llama/Llama-3.1-8B-Instruct) |+| [Large Language Model (LLM)](./pipeline/text/llm.md) | [gpt-oss-20b](https://huggingface.co/openai/gpt-oss-20b) || [Summarization](./pipeline/text/summary.md) | [DistilBART](https://hf.co/sshleifer/distilbart-cnn-12-6) || [Text-to-Speech](./pipeline/audio/texttospeech.md) | [ESPnet JETS](https://hf.co/NeuML/ljspeech-jets-onnx) || [Transcription](./pipeline/audio/transcription.md) | [Whisper](https://hf.co/openai/whisper-base) |diff --git a/docs/observability.md b/docs/observability.mdindex acbdab9a..a05b2524 100644--- a/docs/observability.md+++ b/docs/observability.md@@ -88,13 +88,13 @@ with mlflow.start_run():# Create RAG pipelinerag = RAG(wiki,- "hugging-quants/Meta-Llama-3.1-8B-Instruct-AWQ-INT4",+ "openai/gpt-oss-20b",system="You are a friendly assistant. You answer questions from users.",template=template,context=10)- rag("Tell me about the Roman Empire", maxlength=2048)+ rag("Tell me about the Roman Empire", maxlength=2048, stripthink=True)```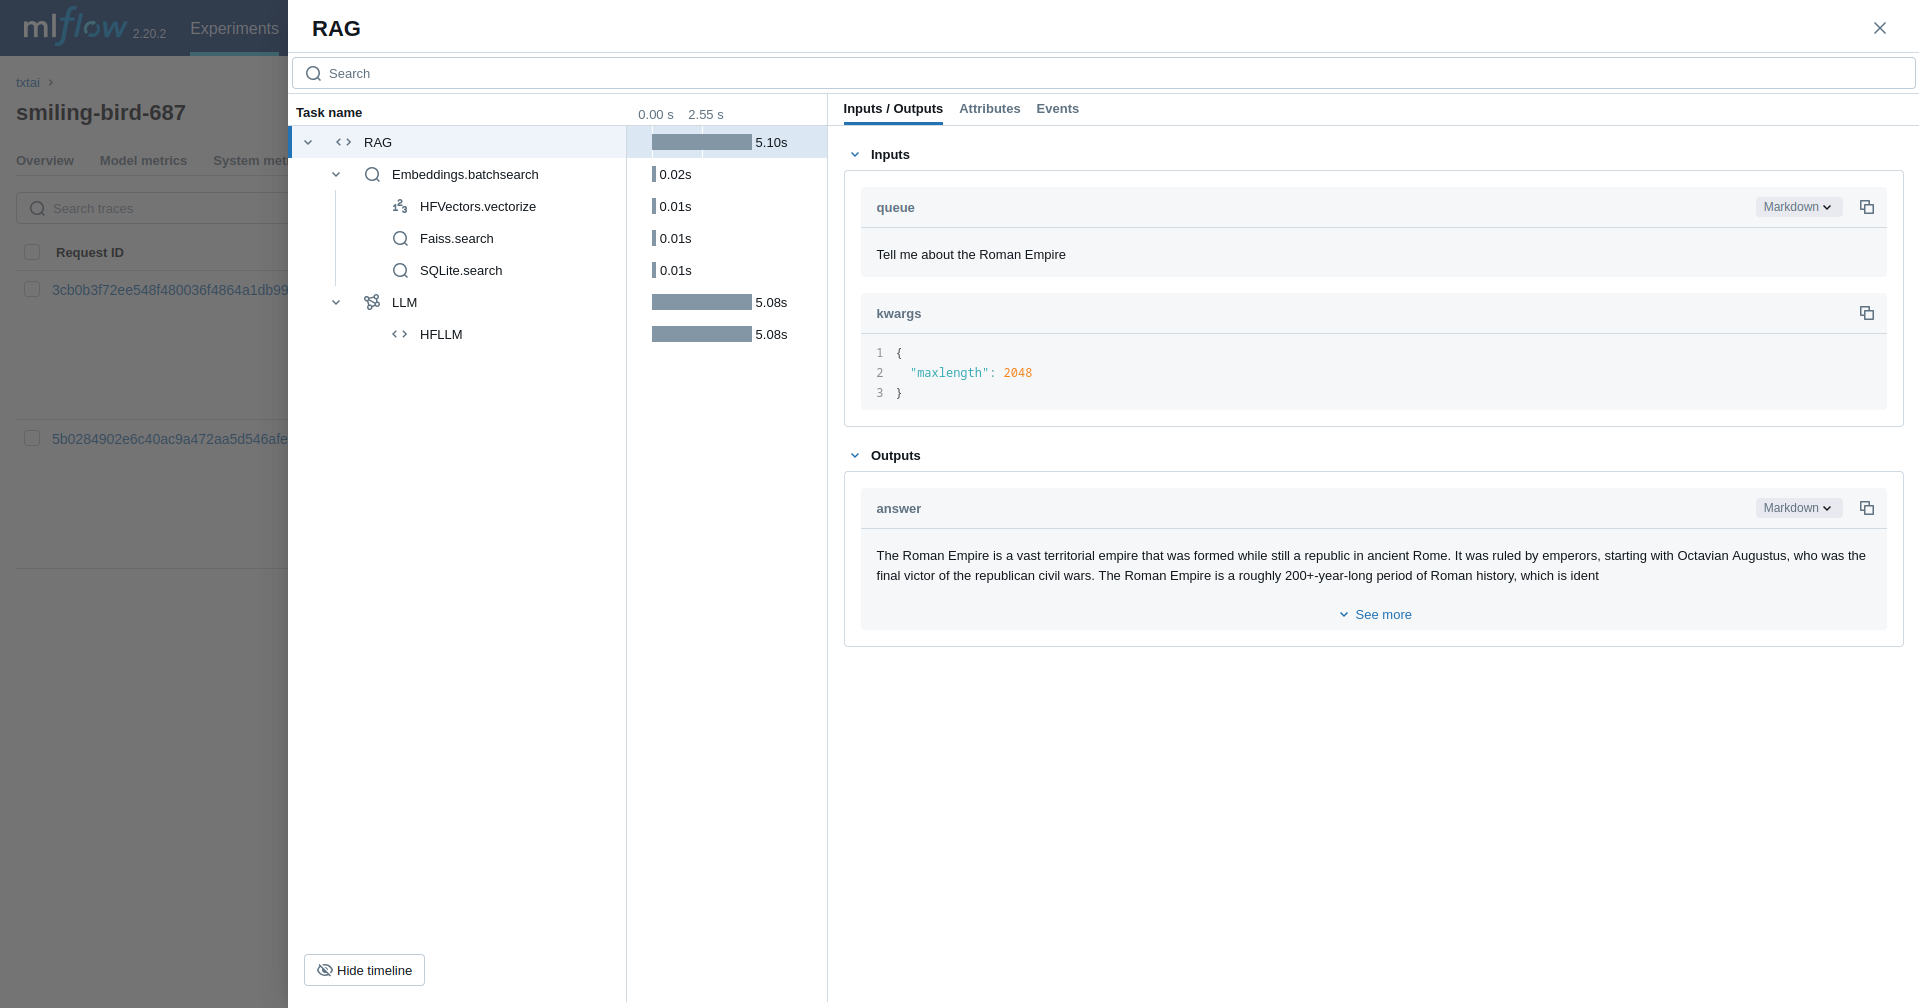@@ -155,7 +155,7 @@ embeddings.load(provider="huggingface-hub", container="neuml/txtai-astronomy")agent = Agent(tools=[search],- llm="hugging-quants/Meta-Llama-3.1-8B-Instruct-AWQ-INT4",+ llm="Qwen/Qwen3-4B-Instruct-2507",max_iterations=10,)diff --git a/docs/pipeline/text/llm.md b/docs/pipeline/text/llm.mdindex e8f66896..086728bd 100644--- a/docs/pipeline/text/llm.md+++ b/docs/pipeline/text/llm.md@@ -61,27 +61,28 @@ See the [LiteLLM documentation](https://litellm.vercel.app/docs/providers) for tfrom txtai import LLM# Transformers-llm = LLM("meta-llama/Meta-Llama-3.1-8B-Instruct")-llm = LLM("meta-llama/Meta-Llama-3.1-8B-Instruct", method="transformers")+llm = LLM("openai/gpt-oss-20b")+llm = LLM("openai/gpt-oss-20b", method="transformers")# llama.cpp-llm = LLM("microsoft/Phi-3-mini-4k-instruct-gguf/Phi-3-mini-4k-instruct-q4.gguf")-llm = LLM("microsoft/Phi-3-mini-4k-instruct-gguf/Phi-3-mini-4k-instruct-q4.gguf",+llm = LLM("unsloth/gpt-oss-20b-GGUF/gpt-oss-20b-Q4_K_M.gguf")+llm = LLM("unsloth/gpt-oss-20b-GGUF/gpt-oss-20b-Q4_K_M.gguf",method="llama.cpp")# LiteLLM-llm = LLM("ollama/llama3.1")-llm = LLM("ollama/llama3.1", method="litellm")+llm = LLM("ollama/gpt-oss")+llm = LLM("ollama/gpt-oss", method="litellm")# Custom Ollama endpoint-llm = LLM("ollama/llama3.1", api_base="http://localhost:11434")+llm = LLM("ollama/gpt-oss", api_base="http://localhost:11434")# Custom OpenAI-compatible endpoint-llm = LLM("openai/llama3.1", api_base="http://localhost:4000")+llm = LLM("openai/gpt-oss", api_base="http://localhost:4000")# LLM APIs - must also set API key via environment variable-llm = LLM("gpt-4o")-llm = LLM("claude-3-5-sonnet-20240620")+llm = LLM("gpt-5.1")+llm = LLM("claude-opus-4-5-20251101")+llm = LLM("gemini/gemini-3-pro-preview")```Models can be externally loaded and passed to pipelines. This is useful for models that are not yet supported by Transformers and/or need special initialization.@@ -92,8 +93,8 @@ import torchfrom transformers import AutoModelForCausalLM, AutoTokenizerfrom txtai import LLM-# Load Phi 3.5-mini-path = "microsoft/Phi-3.5-mini-instruct"+# Load Qwen3 0.6B+path = "Qwen/Qwen3-0.6B"model = AutoModelForCausalLM.from_pretrained(path,torch_dtype=torch.bfloat16,@@ -148,7 +149,7 @@ Similar to the Python example above, the underlying [Hugging Face pipeline param```yamlllm:- path: microsoft/Phi-3.5-mini-instruct+ path: Qwen/Qwen3-0.6Btorch_dtype: torch.bfloat16```diff --git a/docs/pipeline/text/rag.md b/docs/pipeline/text/rag.mdindex ec0fead7..04e253c4 100644--- a/docs/pipeline/text/rag.md+++ b/docs/pipeline/text/rag.md@@ -30,8 +30,8 @@ data = [embeddings = Embeddings(content=True)embeddings.index(data)-# Create and run pipeline-rag = RAG(embeddings, "google/flan-t5-base", template="""+# Create the RAG pipeline+rag = RAG(embeddings, "Qwen/Qwen3-0.6B", template="""Answer the following question using the provided context.Question:@@ -41,11 +41,15 @@ rag = RAG(embeddings, "google/flan-t5-base", template="""{context}""")-rag("What was won?")+# Run RAG pipeline+# LLM options can be passed as additional arguments+# - Set the default role to user and inputs are converted to chat messages+# - Thinking text is removed when `stripthink=True`+rag("What was won?", defaultrole="user", stripthink=True)-# Instruction tuned models typically require string prompts to+# Instruction tuned models require string prompts to# follow a specific chat template set by the model-rag = RAG(embeddings, "meta-llama/Meta-Llama-3.1-8B-Instruct", template="""+rag = RAG(embeddings, "Qwen/Qwen3-0.6B", template="""<|im_start|>systemYou are a friendly assistant.<|im_end|><|im_start|>user@@ -59,13 +63,13 @@ rag = RAG(embeddings, "meta-llama/Meta-Llama-3.1-8B-Instruct", template="""<|im_start|>assistant""")-rag("What was won?")+rag("What was won?", stripthink=True)# Inputs are automatically converted to chat messages when a# system prompt is providedrag = RAG(embeddings,- "meta-llama/Meta-Llama-3.1-8B-Instruct",+ "openai/gpt-oss-20b",system="You are a friendly assistant",template="""Answer the following question using the provided context.@@ -76,26 +80,12 @@ rag = RAG(Context:{context}""")-rag("What was won?")--# LLM options can be passed as additional arguments-rag = RAG(embeddings, "meta-llama/Meta-Llama-3.1-8B-Instruct", template="""- Answer the following question using the provided context.-- Question:- {question}-- Context:- {context}-""")--# Set the default role to user and string inputs are converted to chat messages-rag("What was won?", defaultrole="user")+rag("What was won?", stripthink=True)```See the [Embeddings](../../../embeddings) and [LLM](../llm) pages for additional configuration options.-See the links below for more detailed examples.+Check out this [RAG Quickstart Example](https://github.com/neuml/txtai/blob/master/examples/rag_quickstart.py). Additional examples are listed below.| Notebook | Description | ||:----------|:-------------|------:|@@ -137,7 +127,7 @@ embeddings:content: Truerag:- path: google/flan-t5-base+ path: Qwen/Qwen3-0.6Btemplate: |Answer the following question using the provided context.@@ -146,6 +136,8 @@ rag:Context:{context}+ defaultrole: user+ stripthink: Trueworkflow:search:diff --git a/docs/usecases.md b/docs/usecases.mdindex c99e7a58..ff51908d 100644--- a/docs/usecases.md+++ b/docs/usecases.md@@ -44,7 +44,7 @@ Agents connect embeddings, pipelines, workflows and other agents together to auttxtai agents are built on top of the [smolagents](https://github.com/huggingface/smolagents) framework. This supports all LLMs txtai supports (Hugging Face, llama.cpp, OpenAI / Claude / AWS Bedrock via LiteLLM).-See the links below to learn more.+Check out this [Agent Quickstart Example](https://github.com/neuml/txtai/blob/master/examples/agent_quickstart.py). Additional examples are listed below.| Notebook | Description | ||:----------|:-------------|------:|diff --git a/docs/workflow/index.md b/docs/workflow/index.mdindex ee540805..f03b745f 100644--- a/docs/workflow/index.md+++ b/docs/workflow/index.md@@ -133,7 +133,7 @@ Workflows can connect multiple LLM prompting tasks together.```yamlllm:- path: google/flan-t5-xl+ path: openai/gpt-oss-20bworkflow:llm:@@ -168,7 +168,7 @@ Any txtai pipeline/workflow task can be connected in workflows with LLMs.```yamlllm:- path: google/flan-t5-xl+ path: openai/gpt-oss-20btranslation: