
💡 All-in-one AI framework for semantic search, LLM orchestration and language model workflows
Python agentsaiai-agentsembeddingsinformation-retrievallanguage-modellarge-language-modelsllmnlppythonragretrieval-augmented-generationsearchsearch-enginesemantic-searchsentence-embeddingstransformerstxtaivector-databasevector-search
Add RAG Quickstart Example, closes #991
davidmezzettid3d26a5ebd92
diff --git a/README.md b/README.mdindex 08430fbf..d369be07 100644--- a/README.md+++ b/README.md@@ -87,7 +87,7 @@ curl -X GET "http://localhost:8000/search?query=positive"## Use Cases-The following sections introduce common txtai use cases. A comprehensive set of over 60 [example notebooks and applications](https://neuml.github.io/txtai/examples) are also available.+The following sections introduce common txtai use cases. A comprehensive set of over 70 [example notebooks and applications](https://neuml.github.io/txtai/examples) are also available.### Semantic Search@@ -132,7 +132,7 @@ Agents connect embeddings, pipelines, workflows and other agents together to auttxtai agents are built on top of the [smolagents](https://github.com/huggingface/smolagents) framework. This supports all LLMs txtai supports (Hugging Face, llama.cpp, OpenAI / Claude / AWS Bedrock via LiteLLM).-See the link below to learn more.+See the links below to learn more.| Notebook | Description | ||:----------|:-------------|------:|@@ -147,7 +147,7 @@ Retrieval augmented generation (RAG) reduces the risk of LLM hallucinations by c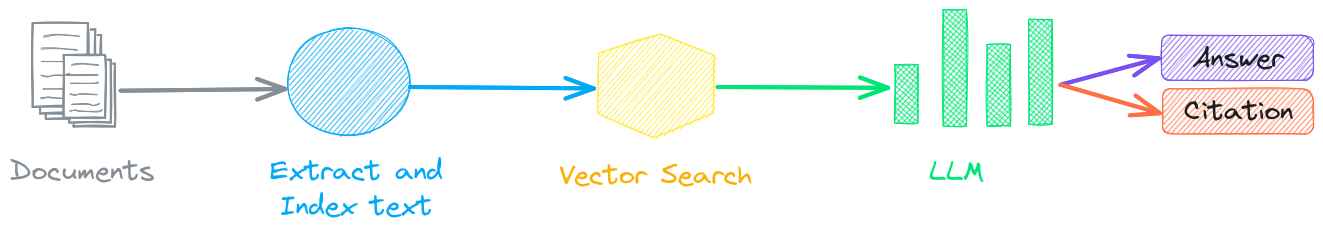-A novel feature of txtai is that it can provide both an answer and source citation.+Check out this [RAG Quickstart Example](https://github.com/neuml/txtai/blob/master/examples/rag_quickstart.py). Additional examples are listed below.| Notebook | Description | ||:----------|:-------------|------:|diff --git a/docs/agent/index.md b/docs/agent/index.mdindex f61486bb..52d474dd 100644--- a/docs/agent/index.md+++ b/docs/agent/index.md@@ -141,7 +141,7 @@ Write the output in Markdown.# More examples-See the link below to learn more.+See the links below to learn more.| Notebook | Description | ||:----------|:-------------|------:|diff --git a/docs/usecases.md b/docs/usecases.mdindex 53a2977d..c99e7a58 100644--- a/docs/usecases.md+++ b/docs/usecases.md@@ -1,6 +1,6 @@# Use Cases-The following sections introduce common txtai use cases. A comprehensive set of over 60 [example notebooks and applications](../examples) are also available.+The following sections introduce common txtai use cases. A comprehensive set of over 70 [example notebooks and applications](../examples) are also available.## Semantic Search@@ -44,7 +44,7 @@ Agents connect embeddings, pipelines, workflows and other agents together to auttxtai agents are built on top of the [smolagents](https://github.com/huggingface/smolagents) framework. This supports all LLMs txtai supports (Hugging Face, llama.cpp, OpenAI / Claude / AWS Bedrock via LiteLLM).-See the link below to learn more.+See the links below to learn more.| Notebook | Description | ||:----------|:-------------|------:|@@ -59,7 +59,7 @@ Retrieval augmented generation (RAG) reduces the risk of LLM hallucinations by c-A novel feature of txtai is that it can provide both an answer and source citation.+Check out this [RAG Quickstart Example](https://github.com/neuml/txtai/blob/master/examples/rag_quickstart.py). Additional examples are listed below.| Notebook | Description | ||:----------|:-------------|------:|diff --git a/examples/rag_quickstart.py b/examples/rag_quickstart.pynew file mode 100644index 00000000..9db9603d--- /dev/null+++ b/examples/rag_quickstart.py@@ -0,0 +1,70 @@+"""+RAG Quick Start+Easy to use way to get started with RAG using YOUR data++For a complete application see this: https://github.com/neuml/rag++TxtAI has many example notebooks covering everything the framework provides+Examples: https://neuml.github.io/txtai/examples++Install TxtAI+ pip install txtai[pipeline-data]+"""++# pylint: disable=C0103+import os++from txtai import Embeddings, RAG+from txtai.pipeline import Textractor++# Step 1: Collect files from local directory+#+# Defaults to "data". Set to whereever your files are.+path = "data"+files = [os.path.join(path, f) for f in os.listdir(path) if os.path.isfile(os.path.join(path, f))]++# Step 2: Text Extraction / Chunking+#+# Using section based chunking here. More complex options available such as semantic chunking, iterative chunking etc.+# Documentation: https://neuml.github.io/txtai/pipeline/data/textractor+# Supports Chonkie chunking as well: https://docs.chonkie.ai/oss/chunkers/overview+textractor = Textractor(backend="docling", sections=True)+chunks = []+for f in files:+ for chunk in textractor(f):+ chunks.append((f, chunk))++# Step 3: Build an embeddings database+#+# The `path` parameter sets the vector embeddings model. Supports Hugging Face models, llama.cpp, Ollama, vLLM and more.+# Documentation: https://neuml.github.io/txtai/embeddings/+embeddings = Embeddings(content=True, path="Qwen/Qwen3-Embedding-0.6B", maxlength=2048)+embeddings.index(chunks)++# Step 4: Create RAG pipeline+#+# Combines an embeddings database and an LLM.+# Supports Hugging Face models, llama.cpp, Ollama, vLLM and more+# Documentation: https://neuml.github.io/txtai/pipeline/text/rag++# User prompt template+template = """+ Answer the following question using the provided context.++ Question:+ {question}++ Context:+ {context}+"""++rag = RAG(+ embeddings,+ "Qwen/Qwen3-0.6B",+ system="You are a friendly assistant",+ template=template,+ output="flatten",+)++question = "Summarize the main advancements made by BERT"+print(rag(question, maxlength=2048, stripthink=True))