
💡 All-in-one AI framework for semantic search, LLM orchestration and language model workflows
Python agentsaiai-agentsembeddingsinformation-retrievallanguage-modellarge-language-modelsllmnlppythonragretrieval-augmented-generationsearchsearch-enginesemantic-searchsentence-embeddingstransformerstxtaivector-databasevector-search
Update documentation
davidmezzettideaf1e7eafaa
diff --git a/README.md b/README.mdindex 75a0dad8..27b023d0 100644--- a/README.md+++ b/README.md@@ -38,18 +38,18 @@ Traditional search systems use keywords to find data. Semantic search applicatio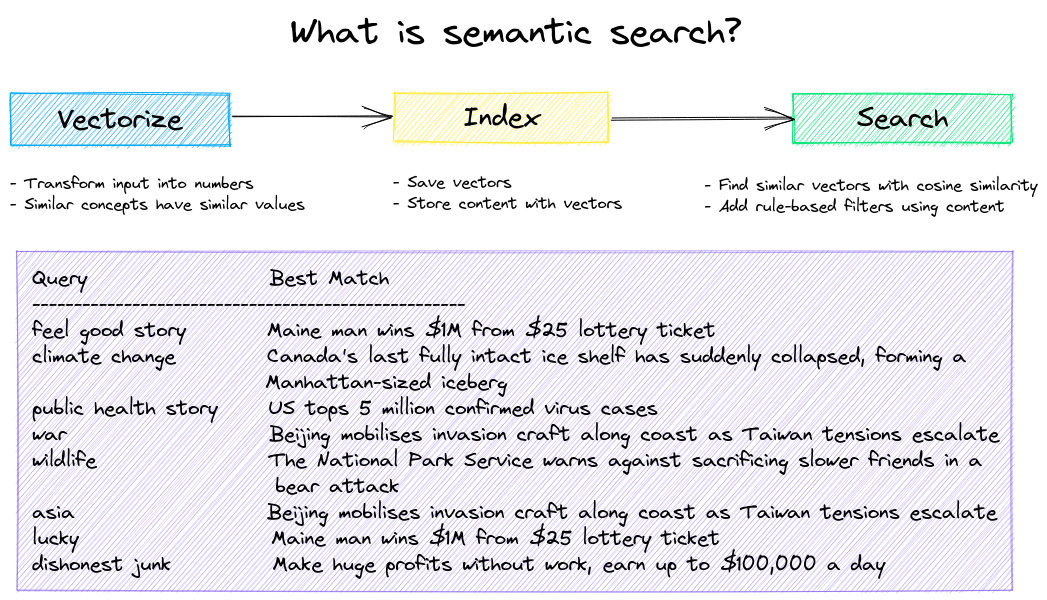-Backed by state-of-the-art machine learning models, data is transformed into vector representations for search (also known as embeddings). Innovation is happening at a rapid pace, models can understand concepts in documents, audio, images and more.+Backed by state-of-the-art machine learning models, data is transformed into vector representations for search (also known as embeddings). Innovation is happening at a rapid pace, models can understand concepts in documents, audio, images and video. Work with micromodels all the way up to large language models (LLMs).Summary of txtai features:-- 🔎 Large-scale similarity search with multiple index backends ([Faiss](https://github.com/facebookresearch/faiss), [Annoy](https://github.com/spotify/annoy), [Hnswlib](https://github.com/nmslib/hnswlib))-- 📄 Create embeddings for text snippets, documents, audio, images and video. Supports transformers and word vectors.-- 💡 Machine-learning pipelines to run extractive question-answering, zero-shot labeling, transcription, translation, summarization and text extraction-- ↪️️ Workflows that join pipelines together to aggregate business logic. txtai processes can be microservices or full-fledged indexing workflows.+- 🔎 Large-scale similarity search with multiple index backends ([Faiss](https://github.com/facebookresearch/faiss), [Annoy](https://github.com/spotify/annoy), [Hnswlib](https://github.com/nmslib/hnswlib)) and support for external vector databases+- 📄 Create embeddings for text snippets, documents, audio, images and video+- 💡 Machine-learning pipelines that run question-answering, labeling, transcription, translation, summarization, LLM prompts and more+- ↪️️ Workflows to join pipelines together and aggregate business logic. txtai processes can be microservices or full-fledged indexing workflows.- ⚙️ Build with Python or YAML. API bindings available for [JavaScript](https://github.com/neuml/txtai.js), [Java](https://github.com/neuml/txtai.java), [Rust](https://github.com/neuml/txtai.rs) and [Go](https://github.com/neuml/txtai.go).- ☁️ Cloud-native architecture that scales out with container orchestration systems (e.g. Kubernetes)-Applications range from similarity search to complex NLP-driven data extractions to generate structured databases. Semantic workflows transform and find data driven by user intent.+Applications range from similarity search to NLP-driven data extractions that generate structured data. Semantic workflows transform and find data driven by user intent.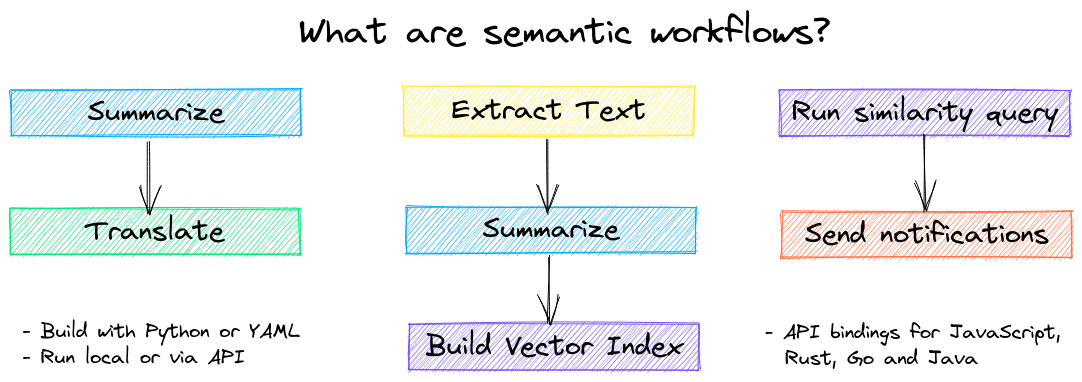diff --git a/docs/index.md b/docs/index.mdindex 72aead07..ed932d67 100644--- a/docs/index.md+++ b/docs/index.md@@ -40,18 +40,18 @@ Traditional search systems use keywords to find data. Semantic search applicatio-Backed by state-of-the-art machine learning models, data is transformed into vector representations for search (also known as embeddings). Innovation is happening at a rapid pace, models can understand concepts in documents, audio, images and more.+Backed by state-of-the-art machine learning models, data is transformed into vector representations for search (also known as embeddings). Innovation is happening at a rapid pace, models can understand concepts in documents, audio, images and video. Work with micromodels all the way up to large language models (LLMs).Summary of txtai features:-- 🔎 Large-scale similarity search with multiple index backends ([Faiss](https://github.com/facebookresearch/faiss), [Annoy](https://github.com/spotify/annoy), [Hnswlib](https://github.com/nmslib/hnswlib))-- 📄 Create embeddings for text snippets, documents, audio, images and video. Supports transformers and word vectors.-- 💡 Machine-learning pipelines to run extractive question-answering, zero-shot labeling, transcription, translation, summarization and text extraction-- ↪️️ Workflows that join pipelines together to aggregate business logic. txtai processes can be microservices or full-fledged indexing workflows.+- 🔎 Large-scale similarity search with multiple index backends ([Faiss](https://github.com/facebookresearch/faiss), [Annoy](https://github.com/spotify/annoy), [Hnswlib](https://github.com/nmslib/hnswlib)) and support for external vector databases+- 📄 Create embeddings for text snippets, documents, audio, images and video+- 💡 Machine-learning pipelines that run question-answering, labeling, transcription, translation, summarization, LLM prompts and more+- ↪️️ Workflows to join pipelines together and aggregate business logic. txtai processes can be microservices or full-fledged indexing workflows.- ⚙️ Build with Python or YAML. API bindings available for [JavaScript](https://github.com/neuml/txtai.js), [Java](https://github.com/neuml/txtai.java), [Rust](https://github.com/neuml/txtai.rs) and [Go](https://github.com/neuml/txtai.go).- ☁️ Cloud-native architecture that scales out with container orchestration systems (e.g. Kubernetes)-Applications range from similarity search to complex NLP-driven data extractions to generate structured databases. Semantic workflows transform and find data driven by user intent.+Applications range from similarity search to NLP-driven data extractions that generate structured data. Semantic workflows transform and find data driven by user intent.